diff --git a/docs.json b/docs.json
index a7da9cf8..684a0aa2 100644
--- a/docs.json
+++ b/docs.json
@@ -31,6 +31,14 @@
}
},
"redirects": [
+ {
+ "source": "/en/openapi/go-sdk",
+ "destination": "/en/developer/go-sdk"
+ },
+ {
+ "source": "/zh/openapi/go-sdk",
+ "destination": "/zh/developer/go-sdk"
+ },
{
"source": "/en/monitors/targets/overview",
"destination": "/en/monitors/quickstart/quickstart"
@@ -429,7 +437,7 @@
},
{
"source": "/en/flashduty/rum/android-error-event",
- "destination": "/en/rum/error-tracking/erro-reporting/android"
+ "destination": "/en/rum/error-tracking/error-reporting/android"
},
{
"source": "/en/flashduty/rum/android-sdk-integration",
@@ -497,11 +505,11 @@
},
{
"source": "/en/flashduty/rum/ios-error-event",
- "destination": "/en/rum/error-tracking/erro-reporting/ios"
+ "destination": "/en/rum/error-tracking/error-reporting/ios"
},
{
"source": "/en/flashduty/rum/ios-error-tracking",
- "destination": "/en/rum/error-tracking/erro-reporting/ios"
+ "destination": "/en/rum/error-tracking/error-reporting/ios"
},
{
"source": "/en/flashduty/rum/ios-sdk-integration",
@@ -601,7 +609,7 @@
},
{
"source": "/en/flashduty/rum/web-error-event",
- "destination": "/en/rum/error-tracking/erro-reporting/web"
+ "destination": "/en/rum/error-tracking/error-reporting/web"
},
{
"source": "/en/flashduty/rum/web-sdk-integration",
@@ -1089,7 +1097,7 @@
},
{
"source": "/zh/flashduty/rum/android-error-event",
- "destination": "/zh/rum/error-tracking/erro-reporting/android"
+ "destination": "/zh/rum/error-tracking/error-reporting/android"
},
{
"source": "/zh/flashduty/rum/android-sdk-integration",
@@ -1153,7 +1161,7 @@
},
{
"source": "/zh/flashduty/rum/ios-error-event",
- "destination": "/zh/rum/error-tracking/erro-reporting/ios"
+ "destination": "/zh/rum/error-tracking/error-reporting/ios"
},
{
"source": "/zh/flashduty/rum/ios-sdk-integration",
@@ -1467,6 +1475,26 @@
"source": "/zh/api-reference/on-call/status-pages/statuspage-read-page-list",
"destination": "/zh/api-reference/on-call/status-pages/status-page-read-page-list"
},
+ {
+ "source": "/zh/stsatuspage",
+ "destination": "/zh/statuspage"
+ },
+ {
+ "source": "/zh/rum/error-tracking/erro-reporting/:slug*",
+ "destination": "/zh/rum/error-tracking/error-reporting/:slug*"
+ },
+ {
+ "source": "/zh/rum/error-tracking/error-reporting",
+ "destination": "/zh/rum/error-tracking/error-reporting/web"
+ },
+ {
+ "source": "/en/rum/error-tracking/error-reporting",
+ "destination": "/en/rum/error-tracking/error-reporting/web"
+ },
+ {
+ "source": "/en/rum/error-tracking/erro-reporting/:slug*",
+ "destination": "/en/rum/error-tracking/error-reporting/:slug*"
+ },
{
"source": "/account/info",
"destination": "/zh/api-reference/platform/account/account-read-info"
@@ -2956,7 +2984,7 @@
"icon": "house",
"pages": [
"zh/home",
- "zh/stsatuspage"
+ "zh/statuspage"
]
},
{
@@ -3190,345 +3218,346 @@
"group": "告警集成",
"expanded": false,
"pages": [
+ "zh/on-call/integration/alert-integration/overview",
"zh/on-call/integration/alert-integration/alert-sources/standard-alert",
"zh/on-call/integration/alert-integration/alert-sources/email",
"zh/on-call/integration/alert-integration/alert-sources/http-pull",
"zh/on-call/integration/alert-integration/alert-sources/db-pull",
- "zh/on-call/integration/alert-integration/alert-sources/prometheus",
- "zh/on-call/integration/alert-integration/alert-sources/grafana",
- "zh/on-call/integration/alert-integration/alert-sources/datadog",
- "zh/on-call/integration/alert-integration/alert-sources/new-relic",
- "zh/on-call/integration/alert-integration/alert-sources/sumo-logic",
- "zh/on-call/integration/alert-integration/alert-sources/fortisiem",
- "zh/on-call/integration/alert-integration/alert-sources/ns1",
- "zh/on-call/integration/alert-integration/alert-sources/site24x7",
- "zh/on-call/integration/alert-integration/alert-sources/healthchecks-io",
- "zh/on-call/integration/alert-integration/alert-sources/cronitor",
- "zh/on-call/integration/alert-integration/alert-sources/uptimerobot",
- "zh/on-call/integration/alert-integration/alert-sources/pingdom",
- "zh/on-call/integration/alert-integration/alert-sources/coralogix",
- "zh/on-call/integration/alert-integration/alert-sources/gitguardian",
"zh/on-call/integration/alert-integration/alert-sources/aikido",
- "zh/on-call/integration/alert-integration/alert-sources/cato",
- "zh/on-call/integration/alert-integration/alert-sources/rollbar",
- "zh/on-call/integration/alert-integration/alert-sources/trigger-dev",
- "zh/on-call/integration/alert-integration/alert-sources/duplicati",
- "zh/on-call/integration/alert-integration/alert-sources/robotalp",
- "zh/on-call/integration/alert-integration/alert-sources/formant",
- "zh/on-call/integration/alert-integration/alert-sources/powerjob",
- "zh/on-call/integration/alert-integration/alert-sources/dolphinscheduler",
+ "zh/on-call/integration/alert-integration/alert-sources/airbrake",
"zh/on-call/integration/alert-integration/alert-sources/alertsite",
- "zh/on-call/integration/alert-integration/alert-sources/robusta",
- "zh/on-call/integration/alert-integration/alert-sources/pgdash",
- "zh/on-call/integration/alert-integration/alert-sources/infisical",
- "zh/on-call/integration/alert-integration/alert-sources/fivetran",
- "zh/on-call/integration/alert-integration/alert-sources/datto-rmm",
- "zh/on-call/integration/alert-integration/alert-sources/pulseway",
- "zh/on-call/integration/alert-integration/alert-sources/securityscorecard",
- "zh/on-call/integration/alert-integration/alert-sources/jfrog-xray",
- "zh/on-call/integration/alert-integration/alert-sources/lacework",
- "zh/on-call/integration/alert-integration/alert-sources/moesif",
- "zh/on-call/integration/alert-integration/alert-sources/rbltracker",
- "zh/on-call/integration/alert-integration/alert-sources/uptimeobserver",
- "zh/on-call/integration/alert-integration/alert-sources/dash0",
- "zh/on-call/integration/alert-integration/alert-sources/elastic",
- "zh/on-call/integration/alert-integration/alert-sources/mongodb-atlas",
- "zh/on-call/integration/alert-integration/alert-sources/checkly",
- "zh/on-call/integration/alert-integration/alert-sources/prtg",
- "zh/on-call/integration/alert-integration/alert-sources/netdata",
- "zh/on-call/integration/alert-integration/alert-sources/stackrox",
- "zh/on-call/integration/alert-integration/alert-sources/trivy-operator",
- "zh/on-call/integration/alert-integration/alert-sources/honeycomb",
- "zh/on-call/integration/alert-integration/alert-sources/panther",
+ "zh/on-call/integration/alert-integration/alert-sources/aliyun-arms",
+ "zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-event",
+ "zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics",
+ "zh/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op",
+ "zh/on-call/integration/alert-integration/alert-sources/aliyun-prometheus",
+ "zh/on-call/integration/alert-integration/alert-sources/aliyun-sls",
+ "zh/on-call/integration/alert-integration/alert-sources/amazon-inspector",
+ "zh/on-call/integration/alert-integration/alert-sources/apcupsd",
+ "zh/on-call/integration/alert-integration/alert-sources/apimetrics",
+ "zh/on-call/integration/alert-integration/alert-sources/appdynamics",
+ "zh/on-call/integration/alert-integration/alert-sources/appsignal",
+ "zh/on-call/integration/alert-integration/alert-sources/argocd",
+ "zh/on-call/integration/alert-integration/alert-sources/atatus",
+ "zh/on-call/integration/alert-integration/alert-sources/auth0",
+ "zh/on-call/integration/alert-integration/alert-sources/auvik",
+ "zh/on-call/integration/alert-integration/alert-sources/aws-cloudwatch",
+ "zh/on-call/integration/alert-integration/alert-sources/aws-eventbridge",
+ "zh/on-call/integration/alert-integration/alert-sources/aws-health",
+ "zh/on-call/integration/alert-integration/alert-sources/aws-security-hub",
"zh/on-call/integration/alert-integration/alert-sources/axiom",
+ "zh/on-call/integration/alert-integration/alert-sources/azure-monitor",
+ "zh/on-call/integration/alert-integration/alert-sources/azure-service-health",
+ "zh/on-call/integration/alert-integration/alert-sources/baidu-bcm",
+ "zh/on-call/integration/alert-integration/alert-sources/bgpalerter",
+ "zh/on-call/integration/alert-integration/alert-sources/bigpanda",
+ "zh/on-call/integration/alert-integration/alert-sources/bitdefender",
+ "zh/on-call/integration/alert-integration/alert-sources/bleemeo",
+ "zh/on-call/integration/alert-integration/alert-sources/blueking",
+ "zh/on-call/integration/alert-integration/alert-sources/blumira",
+ "zh/on-call/integration/alert-integration/alert-sources/bugsnag",
+ "zh/on-call/integration/alert-integration/alert-sources/calibre",
+ "zh/on-call/integration/alert-integration/alert-sources/canarytokens",
+ "zh/on-call/integration/alert-integration/alert-sources/catchpoint",
+ "zh/on-call/integration/alert-integration/alert-sources/cato",
+ "zh/on-call/integration/alert-integration/alert-sources/censys",
+ "zh/on-call/integration/alert-integration/alert-sources/centreon",
+ "zh/on-call/integration/alert-integration/alert-sources/cert-spotter",
+ "zh/on-call/integration/alert-integration/alert-sources/cfengine",
+ "zh/on-call/integration/alert-integration/alert-sources/check-point-smartevent",
+ "zh/on-call/integration/alert-integration/alert-sources/checkly",
"zh/on-call/integration/alert-integration/alert-sources/checkmk",
+ "zh/on-call/integration/alert-integration/alert-sources/chronosphere",
+ "zh/on-call/integration/alert-integration/alert-sources/circonus",
+ "zh/on-call/integration/alert-integration/alert-sources/cloudamqp",
+ "zh/on-call/integration/alert-integration/alert-sources/cloudflare",
+ "zh/on-call/integration/alert-integration/alert-sources/clustercontrol",
+ "zh/on-call/integration/alert-integration/alert-sources/consul",
+ "zh/on-call/integration/alert-integration/alert-sources/contrast",
+ "zh/on-call/integration/alert-integration/alert-sources/coralogix",
+ "zh/on-call/integration/alert-integration/alert-sources/coroot",
+ "zh/on-call/integration/alert-integration/alert-sources/cronicle",
+ "zh/on-call/integration/alert-integration/alert-sources/cronitor",
+ "zh/on-call/integration/alert-integration/alert-sources/crowdsec",
+ "zh/on-call/integration/alert-integration/alert-sources/crowdstrike",
+ "zh/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale",
+ "zh/on-call/integration/alert-integration/alert-sources/ctyun",
+ "zh/on-call/integration/alert-integration/alert-sources/cubeapm",
+ "zh/on-call/integration/alert-integration/alert-sources/dash0",
+ "zh/on-call/integration/alert-integration/alert-sources/datadog",
+ "zh/on-call/integration/alert-integration/alert-sources/datto-rmm",
+ "zh/on-call/integration/alert-integration/alert-sources/dbmarlin",
+ "zh/on-call/integration/alert-integration/alert-sources/dead-mans-snitch",
+ "zh/on-call/integration/alert-integration/alert-sources/dependency-track",
+ "zh/on-call/integration/alert-integration/alert-sources/dingtalk-alert",
"zh/on-call/integration/alert-integration/alert-sources/dkron",
- "zh/on-call/integration/alert-integration/alert-sources/auvik",
+ "zh/on-call/integration/alert-integration/alert-sources/dolphinscheduler",
"zh/on-call/integration/alert-integration/alert-sources/domotz",
- "zh/on-call/integration/alert-integration/alert-sources/ntopng",
- "zh/on-call/integration/alert-integration/alert-sources/honeybadger",
- "zh/on-call/integration/alert-integration/alert-sources/kener",
- "zh/on-call/integration/alert-integration/alert-sources/peekaping",
- "zh/on-call/integration/alert-integration/alert-sources/vigil",
- "zh/on-call/integration/alert-integration/alert-sources/ofelia",
- "zh/on-call/integration/alert-integration/alert-sources/dependency-track",
- "zh/on-call/integration/alert-integration/alert-sources/openobserve",
- "zh/on-call/integration/alert-integration/alert-sources/postman",
- "zh/on-call/integration/alert-integration/alert-sources/contrast",
- "zh/on-call/integration/alert-integration/alert-sources/censys",
- "zh/on-call/integration/alert-integration/alert-sources/jumpcloud",
- "zh/on-call/integration/alert-integration/alert-sources/zenoss",
- "zh/on-call/integration/alert-integration/alert-sources/semgrep",
- "zh/on-call/integration/alert-integration/alert-sources/sonarqube",
- "zh/on-call/integration/alert-integration/alert-sources/level",
- "zh/on-call/integration/alert-integration/alert-sources/juniper-mist",
+ "zh/on-call/integration/alert-integration/alert-sources/dotcom-monitor",
+ "zh/on-call/integration/alert-integration/alert-sources/duplicati",
+ "zh/on-call/integration/alert-integration/alert-sources/dynatrace",
+ "zh/on-call/integration/alert-integration/alert-sources/ecloud-cm",
+ "zh/on-call/integration/alert-integration/alert-sources/edge-delta",
+ "zh/on-call/integration/alert-integration/alert-sources/elastalert2",
+ "zh/on-call/integration/alert-integration/alert-sources/elastic",
+ "zh/on-call/integration/alert-integration/alert-sources/emqx",
"zh/on-call/integration/alert-integration/alert-sources/extrahop",
- "zh/on-call/integration/alert-integration/alert-sources/ohdear",
- "zh/on-call/integration/alert-integration/alert-sources/appsignal",
+ "zh/on-call/integration/alert-integration/alert-sources/fail2ban",
+ "zh/on-call/integration/alert-integration/alert-sources/falco",
+ "zh/on-call/integration/alert-integration/alert-sources/fastnetmon",
+ "zh/on-call/integration/alert-integration/alert-sources/firebase-crashlytics",
+ "zh/on-call/integration/alert-integration/alert-sources/firefly",
+ "zh/on-call/integration/alert-integration/alert-sources/fivetran",
+ "zh/on-call/integration/alert-integration/alert-sources/flashcat",
"zh/on-call/integration/alert-integration/alert-sources/fleet",
- "zh/on-call/integration/alert-integration/alert-sources/veracode-sca",
- "zh/on-call/integration/alert-integration/alert-sources/dbmarlin",
- "zh/on-call/integration/alert-integration/alert-sources/redash",
- "zh/on-call/integration/alert-integration/alert-sources/sublime",
- "zh/on-call/integration/alert-integration/alert-sources/cloudamqp",
- "zh/on-call/integration/alert-integration/alert-sources/canarytokens",
- "zh/on-call/integration/alert-integration/alert-sources/intersight",
- "zh/on-call/integration/alert-integration/alert-sources/insightidr",
- "zh/on-call/integration/alert-integration/alert-sources/upguard",
- "zh/on-call/integration/alert-integration/alert-sources/tracee",
- "zh/on-call/integration/alert-integration/alert-sources/airbrake",
- "zh/on-call/integration/alert-integration/alert-sources/opensearch",
- "zh/on-call/integration/alert-integration/alert-sources/logrocket",
- "zh/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor",
- "zh/on-call/integration/alert-integration/alert-sources/gitlab",
- "zh/on-call/integration/alert-integration/alert-sources/hookdeck",
- "zh/on-call/integration/alert-integration/alert-sources/bugsnag",
- "zh/on-call/integration/alert-integration/alert-sources/raygun",
- "zh/on-call/integration/alert-integration/alert-sources/librenms",
- "zh/on-call/integration/alert-integration/alert-sources/last9",
- "zh/on-call/integration/alert-integration/alert-sources/signoz",
- "zh/on-call/integration/alert-integration/alert-sources/veeam-one",
- "zh/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console",
- "zh/on-call/integration/alert-integration/alert-sources/raritan-px",
- "zh/on-call/integration/alert-integration/alert-sources/whatsup-gold",
"zh/on-call/integration/alert-integration/alert-sources/flowmon-ads",
- "zh/on-call/integration/alert-integration/alert-sources/aws-health",
- "zh/on-call/integration/alert-integration/alert-sources/azure-service-health",
+ "zh/on-call/integration/alert-integration/alert-sources/flowtriq",
+ "zh/on-call/integration/alert-integration/alert-sources/fluxcd",
+ "zh/on-call/integration/alert-integration/alert-sources/formant",
+ "zh/on-call/integration/alert-integration/alert-sources/fortimonitor",
+ "zh/on-call/integration/alert-integration/alert-sources/fortisiem",
+ "zh/on-call/integration/alert-integration/alert-sources/gatus",
"zh/on-call/integration/alert-integration/alert-sources/gcp-personalized-service-health",
- "zh/on-call/integration/alert-integration/alert-sources/nut",
- "zh/on-call/integration/alert-integration/alert-sources/apcupsd",
- "zh/on-call/integration/alert-integration/alert-sources/centreon",
- "zh/on-call/integration/alert-integration/alert-sources/opsview",
- "zh/on-call/integration/alert-integration/alert-sources/microsoft-sentinel",
- "zh/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud",
- "zh/on-call/integration/alert-integration/alert-sources/aws-security-hub",
- "zh/on-call/integration/alert-integration/alert-sources/amazon-inspector",
- "zh/on-call/integration/alert-integration/alert-sources/fail2ban",
- "zh/on-call/integration/alert-integration/alert-sources/suricata",
+ "zh/on-call/integration/alert-integration/alert-sources/ghost-inspector",
+ "zh/on-call/integration/alert-integration/alert-sources/gitguardian",
+ "zh/on-call/integration/alert-integration/alert-sources/github",
+ "zh/on-call/integration/alert-integration/alert-sources/gitlab",
+ "zh/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring",
+ "zh/on-call/integration/alert-integration/alert-sources/google-scc",
+ "zh/on-call/integration/alert-integration/alert-sources/grafana",
+ "zh/on-call/integration/alert-integration/alert-sources/graylog",
+ "zh/on-call/integration/alert-integration/alert-sources/guance",
+ "zh/on-call/integration/alert-integration/alert-sources/hackerone",
+ "zh/on-call/integration/alert-integration/alert-sources/harbor",
+ "zh/on-call/integration/alert-integration/alert-sources/harness",
+ "zh/on-call/integration/alert-integration/alert-sources/healthchecks-io",
+ "zh/on-call/integration/alert-integration/alert-sources/hertzbeat",
+ "zh/on-call/integration/alert-integration/alert-sources/hetrixtools",
+ "zh/on-call/integration/alert-integration/alert-sources/honeybadger",
+ "zh/on-call/integration/alert-integration/alert-sources/honeycomb",
+ "zh/on-call/integration/alert-integration/alert-sources/hookdeck",
+ "zh/on-call/integration/alert-integration/alert-sources/hosted-graphite",
+ "zh/on-call/integration/alert-integration/alert-sources/huawei-aom",
+ "zh/on-call/integration/alert-integration/alert-sources/huawei-apm",
+ "zh/on-call/integration/alert-integration/alert-sources/huawei-ces",
+ "zh/on-call/integration/alert-integration/alert-sources/huawei-lts",
+ "zh/on-call/integration/alert-integration/alert-sources/hund",
+ "zh/on-call/integration/alert-integration/alert-sources/hyperdx",
+ "zh/on-call/integration/alert-integration/alert-sources/hyperping",
"zh/on-call/integration/alert-integration/alert-sources/ibm-qradar",
- "zh/on-call/integration/alert-integration/alert-sources/opnsense",
- "zh/on-call/integration/alert-integration/alert-sources/observium",
"zh/on-call/integration/alert-integration/alert-sources/icinga",
- "zh/on-call/integration/alert-integration/alert-sources/sensu",
- "zh/on-call/integration/alert-integration/alert-sources/sysdig",
- "zh/on-call/integration/alert-integration/alert-sources/circonus",
+ "zh/on-call/integration/alert-integration/alert-sources/imperva",
+ "zh/on-call/integration/alert-integration/alert-sources/infisical",
+ "zh/on-call/integration/alert-integration/alert-sources/influxdata",
+ "zh/on-call/integration/alert-integration/alert-sources/insightidr",
"zh/on-call/integration/alert-integration/alert-sources/instana",
- "zh/on-call/integration/alert-integration/alert-sources/logicmonitor",
- "zh/on-call/integration/alert-integration/alert-sources/uptime-com",
- "zh/on-call/integration/alert-integration/alert-sources/sematext",
- "zh/on-call/integration/alert-integration/alert-sources/fortimonitor",
- "zh/on-call/integration/alert-integration/alert-sources/uptrends",
- "zh/on-call/integration/alert-integration/alert-sources/searchstax",
- "zh/on-call/integration/alert-integration/alert-sources/logpoint",
- "zh/on-call/integration/alert-integration/alert-sources/hetrixtools",
- "zh/on-call/integration/alert-integration/alert-sources/mackerel",
- "zh/on-call/integration/alert-integration/alert-sources/thousandeyes",
+ "zh/on-call/integration/alert-integration/alert-sources/instatus",
+ "zh/on-call/integration/alert-integration/alert-sources/intersight",
+ "zh/on-call/integration/alert-integration/alert-sources/jdcloud",
+ "zh/on-call/integration/alert-integration/alert-sources/jfrog-xray",
+ "zh/on-call/integration/alert-integration/alert-sources/jiankongbao",
+ "zh/on-call/integration/alert-integration/alert-sources/jumpcloud",
+ "zh/on-call/integration/alert-integration/alert-sources/juniper-mist",
+ "zh/on-call/integration/alert-integration/alert-sources/kapacitor",
+ "zh/on-call/integration/alert-integration/alert-sources/keep",
+ "zh/on-call/integration/alert-integration/alert-sources/kener",
"zh/on-call/integration/alert-integration/alert-sources/kentik",
- "zh/on-call/integration/alert-integration/alert-sources/github",
- "zh/on-call/integration/alert-integration/alert-sources/tailscale",
- "zh/on-call/integration/alert-integration/alert-sources/logz-io",
- "zh/on-call/integration/alert-integration/alert-sources/split-io",
- "zh/on-call/integration/alert-integration/alert-sources/firefly",
- "zh/on-call/integration/alert-integration/alert-sources/hackerone",
- "zh/on-call/integration/alert-integration/alert-sources/dotcom-monitor",
+ "zh/on-call/integration/alert-integration/alert-sources/komodor",
+ "zh/on-call/integration/alert-integration/alert-sources/kscloud-monitor",
"zh/on-call/integration/alert-integration/alert-sources/kuvasz",
- "zh/on-call/integration/alert-integration/alert-sources/thinkst-canary",
- "zh/on-call/integration/alert-integration/alert-sources/falco",
- "zh/on-call/integration/alert-integration/alert-sources/blumira",
- "zh/on-call/integration/alert-integration/alert-sources/bitdefender",
- "zh/on-call/integration/alert-integration/alert-sources/snyk",
+ "zh/on-call/integration/alert-integration/alert-sources/lacework",
+ "zh/on-call/integration/alert-integration/alert-sources/langsmith",
+ "zh/on-call/integration/alert-integration/alert-sources/lark-alert",
+ "zh/on-call/integration/alert-integration/alert-sources/last9",
+ "zh/on-call/integration/alert-integration/alert-sources/level",
+ "zh/on-call/integration/alert-integration/alert-sources/librenms",
+ "zh/on-call/integration/alert-integration/alert-sources/limacharlie",
+ "zh/on-call/integration/alert-integration/alert-sources/loadster",
+ "zh/on-call/integration/alert-integration/alert-sources/loggly",
+ "zh/on-call/integration/alert-integration/alert-sources/logicmonitor",
+ "zh/on-call/integration/alert-integration/alert-sources/logpoint",
+ "zh/on-call/integration/alert-integration/alert-sources/logrocket",
+ "zh/on-call/integration/alert-integration/alert-sources/logz-io",
+ "zh/on-call/integration/alert-integration/alert-sources/mackerel",
+ "zh/on-call/integration/alert-integration/alert-sources/meraki",
+ "zh/on-call/integration/alert-integration/alert-sources/metoro",
+ "zh/on-call/integration/alert-integration/alert-sources/mezmo",
+ "zh/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud",
+ "zh/on-call/integration/alert-integration/alert-sources/microsoft-sentinel",
+ "zh/on-call/integration/alert-integration/alert-sources/moesif",
+ "zh/on-call/integration/alert-integration/alert-sources/mongodb-atlas",
+ "zh/on-call/integration/alert-integration/alert-sources/monit",
+ "zh/on-call/integration/alert-integration/alert-sources/monitive",
+ "zh/on-call/integration/alert-integration/alert-sources/monte-carlo",
+ "zh/on-call/integration/alert-integration/alert-sources/nagios",
+ "zh/on-call/integration/alert-integration/alert-sources/netbeez",
+ "zh/on-call/integration/alert-integration/alert-sources/netdata",
+ "zh/on-call/integration/alert-integration/alert-sources/new-relic",
+ "zh/on-call/integration/alert-integration/alert-sources/nobl9",
+ "zh/on-call/integration/alert-integration/alert-sources/nodeping",
+ "zh/on-call/integration/alert-integration/alert-sources/ns1",
+ "zh/on-call/integration/alert-integration/alert-sources/ntopng",
+ "zh/on-call/integration/alert-integration/alert-sources/nut",
+ "zh/on-call/integration/alert-integration/alert-sources/obkio",
+ "zh/on-call/integration/alert-integration/alert-sources/observium",
+ "zh/on-call/integration/alert-integration/alert-sources/oceanbase",
+ "zh/on-call/integration/alert-integration/alert-sources/oci-monitoring",
+ "zh/on-call/integration/alert-integration/alert-sources/odown",
+ "zh/on-call/integration/alert-integration/alert-sources/ofelia",
+ "zh/on-call/integration/alert-integration/alert-sources/ohdear",
"zh/on-call/integration/alert-integration/alert-sources/okta",
- "zh/on-call/integration/alert-integration/alert-sources/statuspage",
- "zh/on-call/integration/alert-integration/alert-sources/instatus",
- "zh/on-call/integration/alert-integration/alert-sources/statuspal",
- "zh/on-call/integration/alert-integration/alert-sources/hund",
- "zh/on-call/integration/alert-integration/alert-sources/argocd",
- "zh/on-call/integration/alert-integration/alert-sources/crowdstrike",
- "zh/on-call/integration/alert-integration/alert-sources/fluxcd",
- "zh/on-call/integration/alert-integration/alert-sources/harness",
- "zh/on-call/integration/alert-integration/alert-sources/komodor",
- "zh/on-call/integration/alert-integration/alert-sources/twilio",
- "zh/on-call/integration/alert-integration/alert-sources/pandora-fms",
- "zh/on-call/integration/alert-integration/alert-sources/openstatus",
+ "zh/on-call/integration/alert-integration/alert-sources/open-falcon",
"zh/on-call/integration/alert-integration/alert-sources/opennms",
- "zh/on-call/integration/alert-integration/alert-sources/stripe",
- "zh/on-call/integration/alert-integration/alert-sources/dead-mans-snitch",
- "zh/on-call/integration/alert-integration/alert-sources/oci-monitoring",
- "zh/on-call/integration/alert-integration/alert-sources/hyperdx",
- "zh/on-call/integration/alert-integration/alert-sources/consul",
- "zh/on-call/integration/alert-integration/alert-sources/firebase-crashlytics",
- "zh/on-call/integration/alert-integration/alert-sources/cert-spotter",
- "zh/on-call/integration/alert-integration/alert-sources/crowdsec",
- "zh/on-call/integration/alert-integration/alert-sources/cfengine",
- "zh/on-call/integration/alert-integration/alert-sources/mezmo",
- "zh/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale",
- "zh/on-call/integration/alert-integration/alert-sources/bigpanda",
- "zh/on-call/integration/alert-integration/alert-sources/loggly",
- "zh/on-call/integration/alert-integration/alert-sources/catchpoint",
- "zh/on-call/integration/alert-integration/alert-sources/check-point-smartevent",
+ "zh/on-call/integration/alert-integration/alert-sources/openobserve",
+ "zh/on-call/integration/alert-integration/alert-sources/opensearch",
+ "zh/on-call/integration/alert-integration/alert-sources/openstatus",
+ "zh/on-call/integration/alert-integration/alert-sources/opmanager",
+ "zh/on-call/integration/alert-integration/alert-sources/opnsense",
+ "zh/on-call/integration/alert-integration/alert-sources/opsgenie",
+ "zh/on-call/integration/alert-integration/alert-sources/opsview",
"zh/on-call/integration/alert-integration/alert-sources/ossec",
- "zh/on-call/integration/alert-integration/alert-sources/zeek",
- "zh/on-call/integration/alert-integration/alert-sources/chronosphere",
- "zh/on-call/integration/alert-integration/alert-sources/cubeapm",
- "zh/on-call/integration/alert-integration/alert-sources/red-hat-openshift",
+ "zh/on-call/integration/alert-integration/alert-sources/pagerduty",
+ "zh/on-call/integration/alert-integration/alert-sources/pandora-fms",
+ "zh/on-call/integration/alert-integration/alert-sources/panther",
"zh/on-call/integration/alert-integration/alert-sources/papertrail",
- "zh/on-call/integration/alert-integration/alert-sources/zabbix",
- "zh/on-call/integration/alert-integration/alert-sources/flashcat",
- "zh/on-call/integration/alert-integration/alert-sources/open-falcon",
- "zh/on-call/integration/alert-integration/alert-sources/uptime-kuma",
+ "zh/on-call/integration/alert-integration/alert-sources/peekaping",
+ "zh/on-call/integration/alert-integration/alert-sources/pgdash",
+ "zh/on-call/integration/alert-integration/alert-sources/phare",
+ "zh/on-call/integration/alert-integration/alert-sources/pingdom",
+ "zh/on-call/integration/alert-integration/alert-sources/postman",
+ "zh/on-call/integration/alert-integration/alert-sources/powerjob",
"zh/on-call/integration/alert-integration/alert-sources/projectdiscovery",
- "zh/on-call/integration/alert-integration/alert-sources/statuscake",
+ "zh/on-call/integration/alert-integration/alert-sources/prometheus",
+ "zh/on-call/integration/alert-integration/alert-sources/prtg",
"zh/on-call/integration/alert-integration/alert-sources/pulsetic",
- "zh/on-call/integration/alert-integration/alert-sources/edge-delta",
- "zh/on-call/integration/alert-integration/alert-sources/loadster",
- "zh/on-call/integration/alert-integration/alert-sources/cronicle",
- "zh/on-call/integration/alert-integration/alert-sources/atatus",
- "zh/on-call/integration/alert-integration/alert-sources/calibre",
- "zh/on-call/integration/alert-integration/alert-sources/uptimia",
- "zh/on-call/integration/alert-integration/alert-sources/clustercontrol",
- "zh/on-call/integration/alert-integration/alert-sources/hertzbeat",
- "zh/on-call/integration/alert-integration/alert-sources/nobl9",
+ "zh/on-call/integration/alert-integration/alert-sources/pulseway",
+ "zh/on-call/integration/alert-integration/alert-sources/raritan-px",
+ "zh/on-call/integration/alert-integration/alert-sources/raygun",
+ "zh/on-call/integration/alert-integration/alert-sources/rbltracker",
+ "zh/on-call/integration/alert-integration/alert-sources/red-hat-openshift",
+ "zh/on-call/integration/alert-integration/alert-sources/redash",
+ "zh/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor",
+ "zh/on-call/integration/alert-integration/alert-sources/rizhiyi",
+ "zh/on-call/integration/alert-integration/alert-sources/robotalp",
+ "zh/on-call/integration/alert-integration/alert-sources/robusta",
+ "zh/on-call/integration/alert-integration/alert-sources/rollbar",
+ "zh/on-call/integration/alert-integration/alert-sources/rum-alert",
+ "zh/on-call/integration/alert-integration/alert-sources/searchstax",
+ "zh/on-call/integration/alert-integration/alert-sources/securityscorecard",
+ "zh/on-call/integration/alert-integration/alert-sources/sematext",
+ "zh/on-call/integration/alert-integration/alert-sources/semgrep",
+ "zh/on-call/integration/alert-integration/alert-sources/sensu",
+ "zh/on-call/integration/alert-integration/alert-sources/sentry",
"zh/on-call/integration/alert-integration/alert-sources/sevone",
- "zh/on-call/integration/alert-integration/alert-sources/hosted-graphite",
- "zh/on-call/integration/alert-integration/alert-sources/netbeez",
- "zh/on-call/integration/alert-integration/alert-sources/coroot",
- "zh/on-call/integration/alert-integration/alert-sources/apimetrics",
- "zh/on-call/integration/alert-integration/alert-sources/gatus",
- "zh/on-call/integration/alert-integration/alert-sources/metoro",
- "zh/on-call/integration/alert-integration/alert-sources/odown",
- "zh/on-call/integration/alert-integration/alert-sources/bleemeo",
- "zh/on-call/integration/alert-integration/alert-sources/whatap",
- "zh/on-call/integration/alert-integration/alert-sources/fastnetmon",
- "zh/on-call/integration/alert-integration/alert-sources/updown",
- "zh/on-call/integration/alert-integration/alert-sources/hyperping",
- "zh/on-call/integration/alert-integration/alert-sources/statusgator",
+ "zh/on-call/integration/alert-integration/alert-sources/signoz",
"zh/on-call/integration/alert-integration/alert-sources/simple-observability",
- "zh/on-call/integration/alert-integration/alert-sources/xitoring",
- "zh/on-call/integration/alert-integration/alert-sources/phare",
- "zh/on-call/integration/alert-integration/alert-sources/monitive",
- "zh/on-call/integration/alert-integration/alert-sources/tideways",
- "zh/on-call/integration/alert-integration/alert-sources/wormly",
- "zh/on-call/integration/alert-integration/alert-sources/obkio",
- "zh/on-call/integration/alert-integration/alert-sources/flowtriq",
- "zh/on-call/integration/alert-integration/alert-sources/tactical-rmm",
- "zh/on-call/integration/alert-integration/alert-sources/bgpalerter",
- "zh/on-call/integration/alert-integration/alert-sources/imperva",
- "zh/on-call/integration/alert-integration/alert-sources/wazuh",
- "zh/on-call/integration/alert-integration/alert-sources/auth0",
- "zh/on-call/integration/alert-integration/alert-sources/twingate",
- "zh/on-call/integration/alert-integration/alert-sources/langsmith",
- "zh/on-call/integration/alert-integration/alert-sources/nodeping",
- "zh/on-call/integration/alert-integration/alert-sources/influxdata",
- "zh/on-call/integration/alert-integration/alert-sources/kapacitor",
- "zh/on-call/integration/alert-integration/alert-sources/graylog",
+ "zh/on-call/integration/alert-integration/alert-sources/site24x7",
"zh/on-call/integration/alert-integration/alert-sources/skywalking",
- "zh/on-call/integration/alert-integration/alert-sources/elastalert2",
- "zh/on-call/integration/alert-integration/alert-sources/keep",
- "zh/on-call/integration/alert-integration/alert-sources/aliyun-arms",
- "zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-event",
- "zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics",
- "zh/on-call/integration/alert-integration/alert-sources/aliyun-sls",
- "zh/on-call/integration/alert-integration/alert-sources/aliyun-prometheus",
- "zh/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op",
- "zh/on-call/integration/alert-integration/alert-sources/aws-cloudwatch",
- "zh/on-call/integration/alert-integration/alert-sources/aws-eventbridge",
- "zh/on-call/integration/alert-integration/alert-sources/azure-monitor",
- "zh/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring",
- "zh/on-call/integration/alert-integration/alert-sources/google-scc",
- "zh/on-call/integration/alert-integration/alert-sources/tencent-cls",
- "zh/on-call/integration/alert-integration/alert-sources/tencent-css",
- "zh/on-call/integration/alert-integration/alert-sources/tencent-cm",
- "zh/on-call/integration/alert-integration/alert-sources/tencent-eventbridge",
- "zh/on-call/integration/alert-integration/alert-sources/baidu-bcm",
- "zh/on-call/integration/alert-integration/alert-sources/ctyun",
- "zh/on-call/integration/alert-integration/alert-sources/ecloud-cm",
- "zh/on-call/integration/alert-integration/alert-sources/huawei-ces",
- "zh/on-call/integration/alert-integration/alert-sources/huawei-lts",
- "zh/on-call/integration/alert-integration/alert-sources/huawei-apm",
- "zh/on-call/integration/alert-integration/alert-sources/huawei-aom",
- "zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics",
- "zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-event",
- "zh/on-call/integration/alert-integration/alert-sources/volcengine-tls",
- "zh/on-call/integration/alert-integration/alert-sources/pagerduty",
- "zh/on-call/integration/alert-integration/alert-sources/opsgenie",
- "zh/on-call/integration/alert-integration/alert-sources/dynatrace",
- "zh/on-call/integration/alert-integration/alert-sources/appdynamics",
+ "zh/on-call/integration/alert-integration/alert-sources/snyk",
"zh/on-call/integration/alert-integration/alert-sources/solarwinds",
"zh/on-call/integration/alert-integration/alert-sources/solarwinds-orion",
+ "zh/on-call/integration/alert-integration/alert-sources/sonarqube",
+ "zh/on-call/integration/alert-integration/alert-sources/split-io",
"zh/on-call/integration/alert-integration/alert-sources/splunk",
"zh/on-call/integration/alert-integration/alert-sources/splunk-observability",
- "zh/on-call/integration/alert-integration/alert-sources/sentry",
- "zh/on-call/integration/alert-integration/alert-sources/opmanager",
- "zh/on-call/integration/alert-integration/alert-sources/blueking",
- "zh/on-call/integration/alert-integration/alert-sources/guance",
- "zh/on-call/integration/alert-integration/alert-sources/jiankongbao",
- "zh/on-call/integration/alert-integration/alert-sources/oceanbase",
- "zh/on-call/integration/alert-integration/alert-sources/zilliz",
- "zh/on-call/integration/alert-integration/alert-sources/zstack",
- "zh/on-call/integration/alert-integration/alert-sources/cloudflare",
- "zh/on-call/integration/alert-integration/alert-sources/meraki",
- "zh/on-call/integration/alert-integration/alert-sources/monit",
- "zh/on-call/integration/alert-integration/alert-sources/rum-alert",
- "zh/on-call/integration/alert-integration/alert-sources/harbor",
+ "zh/on-call/integration/alert-integration/alert-sources/stackrox",
+ "zh/on-call/integration/alert-integration/alert-sources/statuscake",
+ "zh/on-call/integration/alert-integration/alert-sources/statusgator",
+ "zh/on-call/integration/alert-integration/alert-sources/statuspage",
+ "zh/on-call/integration/alert-integration/alert-sources/statuspal",
+ "zh/on-call/integration/alert-integration/alert-sources/stripe",
+ "zh/on-call/integration/alert-integration/alert-sources/sublime",
+ "zh/on-call/integration/alert-integration/alert-sources/sumo-logic",
+ "zh/on-call/integration/alert-integration/alert-sources/suricata",
+ "zh/on-call/integration/alert-integration/alert-sources/sysdig",
+ "zh/on-call/integration/alert-integration/alert-sources/tactical-rmm",
+ "zh/on-call/integration/alert-integration/alert-sources/tailscale",
+ "zh/on-call/integration/alert-integration/alert-sources/tencent-cls",
+ "zh/on-call/integration/alert-integration/alert-sources/tencent-cm",
+ "zh/on-call/integration/alert-integration/alert-sources/tencent-css",
+ "zh/on-call/integration/alert-integration/alert-sources/tencent-eventbridge",
+ "zh/on-call/integration/alert-integration/alert-sources/thinkst-canary",
+ "zh/on-call/integration/alert-integration/alert-sources/thousandeyes",
+ "zh/on-call/integration/alert-integration/alert-sources/tideways",
+ "zh/on-call/integration/alert-integration/alert-sources/tracee",
+ "zh/on-call/integration/alert-integration/alert-sources/trigger-dev",
+ "zh/on-call/integration/alert-integration/alert-sources/trivy-operator",
+ "zh/on-call/integration/alert-integration/alert-sources/twilio",
+ "zh/on-call/integration/alert-integration/alert-sources/twingate",
"zh/on-call/integration/alert-integration/alert-sources/ucloud-cloudwatch",
- "zh/on-call/integration/alert-integration/alert-sources/jdcloud",
- "zh/on-call/integration/alert-integration/alert-sources/kscloud-monitor",
- "zh/on-call/integration/alert-integration/alert-sources/volcengine-rtc",
+ "zh/on-call/integration/alert-integration/alert-sources/updown",
+ "zh/on-call/integration/alert-integration/alert-sources/upguard",
+ "zh/on-call/integration/alert-integration/alert-sources/uptime-com",
+ "zh/on-call/integration/alert-integration/alert-sources/uptime-kuma",
+ "zh/on-call/integration/alert-integration/alert-sources/uptimeobserver",
+ "zh/on-call/integration/alert-integration/alert-sources/uptimerobot",
+ "zh/on-call/integration/alert-integration/alert-sources/uptimia",
+ "zh/on-call/integration/alert-integration/alert-sources/uptrends",
+ "zh/on-call/integration/alert-integration/alert-sources/veeam-one",
+ "zh/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console",
+ "zh/on-call/integration/alert-integration/alert-sources/veracode-sca",
+ "zh/on-call/integration/alert-integration/alert-sources/vigil",
+ "zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-event",
+ "zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics",
"zh/on-call/integration/alert-integration/alert-sources/volcengine-dial",
- "zh/on-call/integration/alert-integration/alert-sources/nagios",
- "zh/on-call/integration/alert-integration/alert-sources/emqx",
- "zh/on-call/integration/alert-integration/alert-sources/rizhiyi",
- "zh/on-call/integration/alert-integration/alert-sources/dingtalk-alert",
- "zh/on-call/integration/alert-integration/alert-sources/lark-alert",
+ "zh/on-call/integration/alert-integration/alert-sources/volcengine-rtc",
+ "zh/on-call/integration/alert-integration/alert-sources/volcengine-tls",
+ "zh/on-call/integration/alert-integration/alert-sources/wazuh",
"zh/on-call/integration/alert-integration/alert-sources/wecom-alert",
- "zh/on-call/integration/alert-integration/alert-sources/ghost-inspector",
- "zh/on-call/integration/alert-integration/alert-sources/monte-carlo",
- "zh/on-call/integration/alert-integration/alert-sources/limacharlie"
+ "zh/on-call/integration/alert-integration/alert-sources/whatap",
+ "zh/on-call/integration/alert-integration/alert-sources/whatsup-gold",
+ "zh/on-call/integration/alert-integration/alert-sources/wormly",
+ "zh/on-call/integration/alert-integration/alert-sources/xitoring",
+ "zh/on-call/integration/alert-integration/alert-sources/zabbix",
+ "zh/on-call/integration/alert-integration/alert-sources/zeek",
+ "zh/on-call/integration/alert-integration/alert-sources/zenoss",
+ "zh/on-call/integration/alert-integration/alert-sources/zilliz",
+ "zh/on-call/integration/alert-integration/alert-sources/zstack"
]
},
{
"group": "变更集成",
"pages": [
+ "zh/on-call/integration/change-integration/apollo",
+ "zh/on-call/integration/change-integration/argo-rollouts",
+ "zh/on-call/integration/change-integration/argocd",
+ "zh/on-call/integration/change-integration/awx",
+ "zh/on-call/integration/change-integration/azure-devops",
+ "zh/on-call/integration/change-integration/bitbucket",
+ "zh/on-call/integration/change-integration/buildkite",
+ "zh/on-call/integration/change-integration/circleci",
+ "zh/on-call/integration/change-integration/coolify",
"zh/on-call/integration/change-integration/custom-event",
- "zh/on-call/integration/change-integration/heroku",
- "zh/on-call/integration/change-integration/teamcity",
- "zh/on-call/integration/change-integration/railway",
+ "zh/on-call/integration/change-integration/env0",
+ "zh/on-call/integration/change-integration/expo-eas",
+ "zh/on-call/integration/change-integration/flagsmith",
+ "zh/on-call/integration/change-integration/fluxcd",
+ "zh/on-call/integration/change-integration/gitea",
+ "zh/on-call/integration/change-integration/gitee",
"zh/on-call/integration/change-integration/github",
"zh/on-call/integration/change-integration/gitlab",
+ "zh/on-call/integration/change-integration/growthbook",
+ "zh/on-call/integration/change-integration/harness-fme",
"zh/on-call/integration/change-integration/hcp-terraform",
- "zh/on-call/integration/change-integration/argocd",
- "zh/on-call/integration/change-integration/netlify",
- "zh/on-call/integration/change-integration/vercel",
+ "zh/on-call/integration/change-integration/heroku",
+ "zh/on-call/integration/change-integration/jenkins",
"zh/on-call/integration/change-integration/jfrog-artifactory",
- "zh/on-call/integration/change-integration/buildkite",
+ "zh/on-call/integration/change-integration/jira",
"zh/on-call/integration/change-integration/launchdarkly",
- "zh/on-call/integration/change-integration/jenkins",
- "zh/on-call/integration/change-integration/circleci",
- "zh/on-call/integration/change-integration/bitbucket",
- "zh/on-call/integration/change-integration/unleash",
- "zh/on-call/integration/change-integration/gitea",
- "zh/on-call/integration/change-integration/rundeck",
- "zh/on-call/integration/change-integration/flagsmith",
- "zh/on-call/integration/change-integration/azure-devops",
- "zh/on-call/integration/change-integration/argo-rollouts",
+ "zh/on-call/integration/change-integration/nautobot",
+ "zh/on-call/integration/change-integration/netbox",
+ "zh/on-call/integration/change-integration/netlify",
"zh/on-call/integration/change-integration/octopus-deploy",
- "zh/on-call/integration/change-integration/awx",
- "zh/on-call/integration/change-integration/semaphore",
- "zh/on-call/integration/change-integration/coolify",
- "zh/on-call/integration/change-integration/scalr",
- "zh/on-call/integration/change-integration/growthbook",
- "zh/on-call/integration/change-integration/fluxcd",
"zh/on-call/integration/change-integration/pulumi",
- "zh/on-call/integration/change-integration/env0",
- "zh/on-call/integration/change-integration/expo-eas",
- "zh/on-call/integration/change-integration/harness-fme",
- "zh/on-call/integration/change-integration/gitee",
+ "zh/on-call/integration/change-integration/railway",
+ "zh/on-call/integration/change-integration/rundeck",
+ "zh/on-call/integration/change-integration/scalr",
+ "zh/on-call/integration/change-integration/semaphore",
+ "zh/on-call/integration/change-integration/teamcity",
+ "zh/on-call/integration/change-integration/unleash",
+ "zh/on-call/integration/change-integration/vercel",
"zh/on-call/integration/change-integration/yunxiao-appstack",
- "zh/on-call/integration/change-integration/zadig",
- "zh/on-call/integration/change-integration/netbox",
- "zh/on-call/integration/change-integration/nautobot",
- "zh/on-call/integration/change-integration/apollo",
- "zh/on-call/integration/change-integration/jira"
+ "zh/on-call/integration/change-integration/zadig"
]
},
{
@@ -3711,9 +3740,9 @@
{
"group": "异常上报",
"pages": [
- "zh/rum/error-tracking/erro-reporting/web",
- "zh/rum/error-tracking/erro-reporting/android",
- "zh/rum/error-tracking/erro-reporting/ios"
+ "zh/rum/error-tracking/error-reporting/web",
+ "zh/rum/error-tracking/error-reporting/android",
+ "zh/rum/error-tracking/error-reporting/ios"
]
},
"zh/rum/error-tracking/error-viewing",
@@ -3864,7 +3893,7 @@
"zh/openapi/introduction",
"zh/openapi/api-catalog",
"zh/openapi/pagination",
- "zh/openapi/go-sdk"
+ "zh/openapi/rate-limits"
]
},
{
@@ -4873,345 +4902,346 @@
"group": "Alert Integration",
"expanded": false,
"pages": [
+ "en/on-call/integration/alert-integration/overview",
"en/on-call/integration/alert-integration/alert-sources/standard-alert",
"en/on-call/integration/alert-integration/alert-sources/email",
"en/on-call/integration/alert-integration/alert-sources/http-pull",
"en/on-call/integration/alert-integration/alert-sources/db-pull",
- "en/on-call/integration/alert-integration/alert-sources/prometheus",
- "en/on-call/integration/alert-integration/alert-sources/grafana",
- "en/on-call/integration/alert-integration/alert-sources/datadog",
- "en/on-call/integration/alert-integration/alert-sources/new-relic",
- "en/on-call/integration/alert-integration/alert-sources/sumo-logic",
- "en/on-call/integration/alert-integration/alert-sources/fortisiem",
- "en/on-call/integration/alert-integration/alert-sources/ns1",
- "en/on-call/integration/alert-integration/alert-sources/site24x7",
- "en/on-call/integration/alert-integration/alert-sources/healthchecks-io",
- "en/on-call/integration/alert-integration/alert-sources/cronitor",
- "en/on-call/integration/alert-integration/alert-sources/uptimerobot",
- "en/on-call/integration/alert-integration/alert-sources/pingdom",
- "en/on-call/integration/alert-integration/alert-sources/coralogix",
- "en/on-call/integration/alert-integration/alert-sources/gitguardian",
"en/on-call/integration/alert-integration/alert-sources/aikido",
- "en/on-call/integration/alert-integration/alert-sources/cato",
- "en/on-call/integration/alert-integration/alert-sources/rollbar",
- "en/on-call/integration/alert-integration/alert-sources/trigger-dev",
- "en/on-call/integration/alert-integration/alert-sources/duplicati",
- "en/on-call/integration/alert-integration/alert-sources/robotalp",
- "en/on-call/integration/alert-integration/alert-sources/formant",
- "en/on-call/integration/alert-integration/alert-sources/powerjob",
- "en/on-call/integration/alert-integration/alert-sources/dolphinscheduler",
+ "en/on-call/integration/alert-integration/alert-sources/airbrake",
"en/on-call/integration/alert-integration/alert-sources/alertsite",
- "en/on-call/integration/alert-integration/alert-sources/robusta",
- "en/on-call/integration/alert-integration/alert-sources/pgdash",
- "en/on-call/integration/alert-integration/alert-sources/infisical",
- "en/on-call/integration/alert-integration/alert-sources/fivetran",
- "en/on-call/integration/alert-integration/alert-sources/datto-rmm",
- "en/on-call/integration/alert-integration/alert-sources/pulseway",
- "en/on-call/integration/alert-integration/alert-sources/securityscorecard",
- "en/on-call/integration/alert-integration/alert-sources/jfrog-xray",
- "en/on-call/integration/alert-integration/alert-sources/lacework",
- "en/on-call/integration/alert-integration/alert-sources/moesif",
- "en/on-call/integration/alert-integration/alert-sources/rbltracker",
- "en/on-call/integration/alert-integration/alert-sources/uptimeobserver",
- "en/on-call/integration/alert-integration/alert-sources/dash0",
- "en/on-call/integration/alert-integration/alert-sources/elastic",
- "en/on-call/integration/alert-integration/alert-sources/mongodb-atlas",
- "en/on-call/integration/alert-integration/alert-sources/checkly",
- "en/on-call/integration/alert-integration/alert-sources/prtg",
- "en/on-call/integration/alert-integration/alert-sources/netdata",
- "en/on-call/integration/alert-integration/alert-sources/stackrox",
- "en/on-call/integration/alert-integration/alert-sources/trivy-operator",
- "en/on-call/integration/alert-integration/alert-sources/honeycomb",
- "en/on-call/integration/alert-integration/alert-sources/panther",
+ "en/on-call/integration/alert-integration/alert-sources/aliyun-arms",
+ "en/on-call/integration/alert-integration/alert-sources/aliyun-cm-event",
+ "en/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics",
+ "en/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op",
+ "en/on-call/integration/alert-integration/alert-sources/aliyun-prometheus",
+ "en/on-call/integration/alert-integration/alert-sources/aliyun-sls",
+ "en/on-call/integration/alert-integration/alert-sources/amazon-inspector",
+ "en/on-call/integration/alert-integration/alert-sources/apcupsd",
+ "en/on-call/integration/alert-integration/alert-sources/apimetrics",
+ "en/on-call/integration/alert-integration/alert-sources/appdynamics",
+ "en/on-call/integration/alert-integration/alert-sources/appsignal",
+ "en/on-call/integration/alert-integration/alert-sources/argocd",
+ "en/on-call/integration/alert-integration/alert-sources/atatus",
+ "en/on-call/integration/alert-integration/alert-sources/auth0",
+ "en/on-call/integration/alert-integration/alert-sources/auvik",
+ "en/on-call/integration/alert-integration/alert-sources/aws-cloudwatch",
+ "en/on-call/integration/alert-integration/alert-sources/aws-eventbridge",
+ "en/on-call/integration/alert-integration/alert-sources/aws-health",
+ "en/on-call/integration/alert-integration/alert-sources/aws-security-hub",
"en/on-call/integration/alert-integration/alert-sources/axiom",
+ "en/on-call/integration/alert-integration/alert-sources/azure-monitor",
+ "en/on-call/integration/alert-integration/alert-sources/azure-service-health",
+ "en/on-call/integration/alert-integration/alert-sources/baidu-bcm",
+ "en/on-call/integration/alert-integration/alert-sources/bgpalerter",
+ "en/on-call/integration/alert-integration/alert-sources/bigpanda",
+ "en/on-call/integration/alert-integration/alert-sources/bitdefender",
+ "en/on-call/integration/alert-integration/alert-sources/bleemeo",
+ "en/on-call/integration/alert-integration/alert-sources/blueking",
+ "en/on-call/integration/alert-integration/alert-sources/blumira",
+ "en/on-call/integration/alert-integration/alert-sources/bugsnag",
+ "en/on-call/integration/alert-integration/alert-sources/calibre",
+ "en/on-call/integration/alert-integration/alert-sources/canarytokens",
+ "en/on-call/integration/alert-integration/alert-sources/catchpoint",
+ "en/on-call/integration/alert-integration/alert-sources/cato",
+ "en/on-call/integration/alert-integration/alert-sources/censys",
+ "en/on-call/integration/alert-integration/alert-sources/centreon",
+ "en/on-call/integration/alert-integration/alert-sources/cert-spotter",
+ "en/on-call/integration/alert-integration/alert-sources/cfengine",
+ "en/on-call/integration/alert-integration/alert-sources/check-point-smartevent",
+ "en/on-call/integration/alert-integration/alert-sources/checkly",
"en/on-call/integration/alert-integration/alert-sources/checkmk",
+ "en/on-call/integration/alert-integration/alert-sources/chronosphere",
+ "en/on-call/integration/alert-integration/alert-sources/circonus",
+ "en/on-call/integration/alert-integration/alert-sources/cloudamqp",
+ "en/on-call/integration/alert-integration/alert-sources/cloudflare",
+ "en/on-call/integration/alert-integration/alert-sources/clustercontrol",
+ "en/on-call/integration/alert-integration/alert-sources/consul",
+ "en/on-call/integration/alert-integration/alert-sources/contrast",
+ "en/on-call/integration/alert-integration/alert-sources/coralogix",
+ "en/on-call/integration/alert-integration/alert-sources/coroot",
+ "en/on-call/integration/alert-integration/alert-sources/cronicle",
+ "en/on-call/integration/alert-integration/alert-sources/cronitor",
+ "en/on-call/integration/alert-integration/alert-sources/crowdsec",
+ "en/on-call/integration/alert-integration/alert-sources/crowdstrike",
+ "en/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale",
+ "en/on-call/integration/alert-integration/alert-sources/ctyun",
+ "en/on-call/integration/alert-integration/alert-sources/cubeapm",
+ "en/on-call/integration/alert-integration/alert-sources/dash0",
+ "en/on-call/integration/alert-integration/alert-sources/datadog",
+ "en/on-call/integration/alert-integration/alert-sources/datto-rmm",
+ "en/on-call/integration/alert-integration/alert-sources/dbmarlin",
+ "en/on-call/integration/alert-integration/alert-sources/dead-mans-snitch",
+ "en/on-call/integration/alert-integration/alert-sources/dependency-track",
+ "en/on-call/integration/alert-integration/alert-sources/dingtalk-alert",
"en/on-call/integration/alert-integration/alert-sources/dkron",
- "en/on-call/integration/alert-integration/alert-sources/auvik",
+ "en/on-call/integration/alert-integration/alert-sources/dolphinscheduler",
"en/on-call/integration/alert-integration/alert-sources/domotz",
- "en/on-call/integration/alert-integration/alert-sources/ntopng",
- "en/on-call/integration/alert-integration/alert-sources/honeybadger",
- "en/on-call/integration/alert-integration/alert-sources/kener",
- "en/on-call/integration/alert-integration/alert-sources/peekaping",
- "en/on-call/integration/alert-integration/alert-sources/vigil",
- "en/on-call/integration/alert-integration/alert-sources/ofelia",
- "en/on-call/integration/alert-integration/alert-sources/dependency-track",
- "en/on-call/integration/alert-integration/alert-sources/openobserve",
- "en/on-call/integration/alert-integration/alert-sources/postman",
- "en/on-call/integration/alert-integration/alert-sources/contrast",
- "en/on-call/integration/alert-integration/alert-sources/censys",
- "en/on-call/integration/alert-integration/alert-sources/jumpcloud",
- "en/on-call/integration/alert-integration/alert-sources/zenoss",
- "en/on-call/integration/alert-integration/alert-sources/semgrep",
- "en/on-call/integration/alert-integration/alert-sources/sonarqube",
- "en/on-call/integration/alert-integration/alert-sources/level",
- "en/on-call/integration/alert-integration/alert-sources/juniper-mist",
+ "en/on-call/integration/alert-integration/alert-sources/dotcom-monitor",
+ "en/on-call/integration/alert-integration/alert-sources/duplicati",
+ "en/on-call/integration/alert-integration/alert-sources/dynatrace",
+ "en/on-call/integration/alert-integration/alert-sources/ecloud-cm",
+ "en/on-call/integration/alert-integration/alert-sources/edge-delta",
+ "en/on-call/integration/alert-integration/alert-sources/elastalert2",
+ "en/on-call/integration/alert-integration/alert-sources/elastic",
+ "en/on-call/integration/alert-integration/alert-sources/emqx",
"en/on-call/integration/alert-integration/alert-sources/extrahop",
- "en/on-call/integration/alert-integration/alert-sources/ohdear",
- "en/on-call/integration/alert-integration/alert-sources/appsignal",
+ "en/on-call/integration/alert-integration/alert-sources/fail2ban",
+ "en/on-call/integration/alert-integration/alert-sources/falco",
+ "en/on-call/integration/alert-integration/alert-sources/fastnetmon",
+ "en/on-call/integration/alert-integration/alert-sources/firebase-crashlytics",
+ "en/on-call/integration/alert-integration/alert-sources/firefly",
+ "en/on-call/integration/alert-integration/alert-sources/fivetran",
+ "en/on-call/integration/alert-integration/alert-sources/flashcat",
"en/on-call/integration/alert-integration/alert-sources/fleet",
- "en/on-call/integration/alert-integration/alert-sources/veracode-sca",
- "en/on-call/integration/alert-integration/alert-sources/dbmarlin",
- "en/on-call/integration/alert-integration/alert-sources/redash",
- "en/on-call/integration/alert-integration/alert-sources/sublime",
- "en/on-call/integration/alert-integration/alert-sources/cloudamqp",
- "en/on-call/integration/alert-integration/alert-sources/canarytokens",
- "en/on-call/integration/alert-integration/alert-sources/intersight",
- "en/on-call/integration/alert-integration/alert-sources/insightidr",
- "en/on-call/integration/alert-integration/alert-sources/upguard",
- "en/on-call/integration/alert-integration/alert-sources/tracee",
- "en/on-call/integration/alert-integration/alert-sources/airbrake",
- "en/on-call/integration/alert-integration/alert-sources/opensearch",
- "en/on-call/integration/alert-integration/alert-sources/logrocket",
- "en/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor",
- "en/on-call/integration/alert-integration/alert-sources/gitlab",
- "en/on-call/integration/alert-integration/alert-sources/hookdeck",
- "en/on-call/integration/alert-integration/alert-sources/bugsnag",
- "en/on-call/integration/alert-integration/alert-sources/raygun",
- "en/on-call/integration/alert-integration/alert-sources/librenms",
- "en/on-call/integration/alert-integration/alert-sources/last9",
- "en/on-call/integration/alert-integration/alert-sources/signoz",
- "en/on-call/integration/alert-integration/alert-sources/veeam-one",
- "en/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console",
- "en/on-call/integration/alert-integration/alert-sources/raritan-px",
- "en/on-call/integration/alert-integration/alert-sources/whatsup-gold",
"en/on-call/integration/alert-integration/alert-sources/flowmon-ads",
- "en/on-call/integration/alert-integration/alert-sources/aws-health",
- "en/on-call/integration/alert-integration/alert-sources/azure-service-health",
+ "en/on-call/integration/alert-integration/alert-sources/flowtriq",
+ "en/on-call/integration/alert-integration/alert-sources/fluxcd",
+ "en/on-call/integration/alert-integration/alert-sources/formant",
+ "en/on-call/integration/alert-integration/alert-sources/fortimonitor",
+ "en/on-call/integration/alert-integration/alert-sources/fortisiem",
+ "en/on-call/integration/alert-integration/alert-sources/gatus",
"en/on-call/integration/alert-integration/alert-sources/gcp-personalized-service-health",
- "en/on-call/integration/alert-integration/alert-sources/nut",
- "en/on-call/integration/alert-integration/alert-sources/apcupsd",
- "en/on-call/integration/alert-integration/alert-sources/centreon",
- "en/on-call/integration/alert-integration/alert-sources/opsview",
- "en/on-call/integration/alert-integration/alert-sources/microsoft-sentinel",
- "en/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud",
- "en/on-call/integration/alert-integration/alert-sources/aws-security-hub",
- "en/on-call/integration/alert-integration/alert-sources/amazon-inspector",
- "en/on-call/integration/alert-integration/alert-sources/fail2ban",
- "en/on-call/integration/alert-integration/alert-sources/suricata",
+ "en/on-call/integration/alert-integration/alert-sources/ghost-inspector",
+ "en/on-call/integration/alert-integration/alert-sources/gitguardian",
+ "en/on-call/integration/alert-integration/alert-sources/github",
+ "en/on-call/integration/alert-integration/alert-sources/gitlab",
+ "en/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring",
+ "en/on-call/integration/alert-integration/alert-sources/google-scc",
+ "en/on-call/integration/alert-integration/alert-sources/grafana",
+ "en/on-call/integration/alert-integration/alert-sources/graylog",
+ "en/on-call/integration/alert-integration/alert-sources/guance",
+ "en/on-call/integration/alert-integration/alert-sources/hackerone",
+ "en/on-call/integration/alert-integration/alert-sources/harbor",
+ "en/on-call/integration/alert-integration/alert-sources/harness",
+ "en/on-call/integration/alert-integration/alert-sources/healthchecks-io",
+ "en/on-call/integration/alert-integration/alert-sources/hertzbeat",
+ "en/on-call/integration/alert-integration/alert-sources/hetrixtools",
+ "en/on-call/integration/alert-integration/alert-sources/honeybadger",
+ "en/on-call/integration/alert-integration/alert-sources/honeycomb",
+ "en/on-call/integration/alert-integration/alert-sources/hookdeck",
+ "en/on-call/integration/alert-integration/alert-sources/hosted-graphite",
+ "en/on-call/integration/alert-integration/alert-sources/huawei-aom",
+ "en/on-call/integration/alert-integration/alert-sources/huawei-apm",
+ "en/on-call/integration/alert-integration/alert-sources/huawei-ces",
+ "en/on-call/integration/alert-integration/alert-sources/huawei-lts",
+ "en/on-call/integration/alert-integration/alert-sources/hund",
+ "en/on-call/integration/alert-integration/alert-sources/hyperdx",
+ "en/on-call/integration/alert-integration/alert-sources/hyperping",
"en/on-call/integration/alert-integration/alert-sources/ibm-qradar",
- "en/on-call/integration/alert-integration/alert-sources/opnsense",
- "en/on-call/integration/alert-integration/alert-sources/observium",
"en/on-call/integration/alert-integration/alert-sources/icinga",
- "en/on-call/integration/alert-integration/alert-sources/sensu",
- "en/on-call/integration/alert-integration/alert-sources/sysdig",
- "en/on-call/integration/alert-integration/alert-sources/circonus",
+ "en/on-call/integration/alert-integration/alert-sources/imperva",
+ "en/on-call/integration/alert-integration/alert-sources/infisical",
+ "en/on-call/integration/alert-integration/alert-sources/influxdata",
+ "en/on-call/integration/alert-integration/alert-sources/insightidr",
"en/on-call/integration/alert-integration/alert-sources/instana",
+ "en/on-call/integration/alert-integration/alert-sources/instatus",
+ "en/on-call/integration/alert-integration/alert-sources/intersight",
+ "en/on-call/integration/alert-integration/alert-sources/jdcloud",
+ "en/on-call/integration/alert-integration/alert-sources/jfrog-xray",
+ "en/on-call/integration/alert-integration/alert-sources/jiankongbao",
+ "en/on-call/integration/alert-integration/alert-sources/jumpcloud",
+ "en/on-call/integration/alert-integration/alert-sources/juniper-mist",
+ "en/on-call/integration/alert-integration/alert-sources/kapacitor",
+ "en/on-call/integration/alert-integration/alert-sources/keep",
+ "en/on-call/integration/alert-integration/alert-sources/kener",
+ "en/on-call/integration/alert-integration/alert-sources/kentik",
+ "en/on-call/integration/alert-integration/alert-sources/komodor",
+ "en/on-call/integration/alert-integration/alert-sources/kscloud-monitor",
+ "en/on-call/integration/alert-integration/alert-sources/kuvasz",
+ "en/on-call/integration/alert-integration/alert-sources/lacework",
+ "en/on-call/integration/alert-integration/alert-sources/langsmith",
+ "en/on-call/integration/alert-integration/alert-sources/lark-alert",
+ "en/on-call/integration/alert-integration/alert-sources/last9",
+ "en/on-call/integration/alert-integration/alert-sources/level",
+ "en/on-call/integration/alert-integration/alert-sources/librenms",
+ "en/on-call/integration/alert-integration/alert-sources/limacharlie",
+ "en/on-call/integration/alert-integration/alert-sources/loadster",
+ "en/on-call/integration/alert-integration/alert-sources/loggly",
"en/on-call/integration/alert-integration/alert-sources/logicmonitor",
- "en/on-call/integration/alert-integration/alert-sources/uptime-com",
- "en/on-call/integration/alert-integration/alert-sources/sematext",
- "en/on-call/integration/alert-integration/alert-sources/fortimonitor",
- "en/on-call/integration/alert-integration/alert-sources/uptrends",
- "en/on-call/integration/alert-integration/alert-sources/searchstax",
"en/on-call/integration/alert-integration/alert-sources/logpoint",
- "en/on-call/integration/alert-integration/alert-sources/hetrixtools",
- "en/on-call/integration/alert-integration/alert-sources/mackerel",
- "en/on-call/integration/alert-integration/alert-sources/thousandeyes",
- "en/on-call/integration/alert-integration/alert-sources/kentik",
- "en/on-call/integration/alert-integration/alert-sources/github",
- "en/on-call/integration/alert-integration/alert-sources/tailscale",
+ "en/on-call/integration/alert-integration/alert-sources/logrocket",
"en/on-call/integration/alert-integration/alert-sources/logz-io",
- "en/on-call/integration/alert-integration/alert-sources/split-io",
- "en/on-call/integration/alert-integration/alert-sources/firefly",
- "en/on-call/integration/alert-integration/alert-sources/hackerone",
- "en/on-call/integration/alert-integration/alert-sources/dotcom-monitor",
- "en/on-call/integration/alert-integration/alert-sources/kuvasz",
- "en/on-call/integration/alert-integration/alert-sources/thinkst-canary",
- "en/on-call/integration/alert-integration/alert-sources/falco",
- "en/on-call/integration/alert-integration/alert-sources/blumira",
- "en/on-call/integration/alert-integration/alert-sources/bitdefender",
- "en/on-call/integration/alert-integration/alert-sources/snyk",
- "en/on-call/integration/alert-integration/alert-sources/okta",
- "en/on-call/integration/alert-integration/alert-sources/statuspage",
- "en/on-call/integration/alert-integration/alert-sources/instatus",
- "en/on-call/integration/alert-integration/alert-sources/statuspal",
- "en/on-call/integration/alert-integration/alert-sources/hund",
- "en/on-call/integration/alert-integration/alert-sources/argocd",
- "en/on-call/integration/alert-integration/alert-sources/crowdstrike",
- "en/on-call/integration/alert-integration/alert-sources/fluxcd",
- "en/on-call/integration/alert-integration/alert-sources/harness",
- "en/on-call/integration/alert-integration/alert-sources/komodor",
- "en/on-call/integration/alert-integration/alert-sources/twilio",
- "en/on-call/integration/alert-integration/alert-sources/pandora-fms",
- "en/on-call/integration/alert-integration/alert-sources/openstatus",
- "en/on-call/integration/alert-integration/alert-sources/opennms",
- "en/on-call/integration/alert-integration/alert-sources/stripe",
- "en/on-call/integration/alert-integration/alert-sources/dead-mans-snitch",
- "en/on-call/integration/alert-integration/alert-sources/oci-monitoring",
- "en/on-call/integration/alert-integration/alert-sources/hyperdx",
- "en/on-call/integration/alert-integration/alert-sources/consul",
- "en/on-call/integration/alert-integration/alert-sources/firebase-crashlytics",
- "en/on-call/integration/alert-integration/alert-sources/cert-spotter",
- "en/on-call/integration/alert-integration/alert-sources/crowdsec",
- "en/on-call/integration/alert-integration/alert-sources/cfengine",
+ "en/on-call/integration/alert-integration/alert-sources/mackerel",
+ "en/on-call/integration/alert-integration/alert-sources/meraki",
+ "en/on-call/integration/alert-integration/alert-sources/metoro",
"en/on-call/integration/alert-integration/alert-sources/mezmo",
- "en/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale",
- "en/on-call/integration/alert-integration/alert-sources/bigpanda",
- "en/on-call/integration/alert-integration/alert-sources/loggly",
- "en/on-call/integration/alert-integration/alert-sources/catchpoint",
- "en/on-call/integration/alert-integration/alert-sources/check-point-smartevent",
+ "en/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud",
+ "en/on-call/integration/alert-integration/alert-sources/microsoft-sentinel",
+ "en/on-call/integration/alert-integration/alert-sources/moesif",
+ "en/on-call/integration/alert-integration/alert-sources/mongodb-atlas",
+ "en/on-call/integration/alert-integration/alert-sources/monit",
+ "en/on-call/integration/alert-integration/alert-sources/monitive",
+ "en/on-call/integration/alert-integration/alert-sources/monte-carlo",
+ "en/on-call/integration/alert-integration/alert-sources/nagios",
+ "en/on-call/integration/alert-integration/alert-sources/netbeez",
+ "en/on-call/integration/alert-integration/alert-sources/netdata",
+ "en/on-call/integration/alert-integration/alert-sources/new-relic",
+ "en/on-call/integration/alert-integration/alert-sources/nobl9",
+ "en/on-call/integration/alert-integration/alert-sources/nodeping",
+ "en/on-call/integration/alert-integration/alert-sources/ns1",
+ "en/on-call/integration/alert-integration/alert-sources/ntopng",
+ "en/on-call/integration/alert-integration/alert-sources/nut",
+ "en/on-call/integration/alert-integration/alert-sources/obkio",
+ "en/on-call/integration/alert-integration/alert-sources/observium",
+ "en/on-call/integration/alert-integration/alert-sources/oceanbase",
+ "en/on-call/integration/alert-integration/alert-sources/oci-monitoring",
+ "en/on-call/integration/alert-integration/alert-sources/odown",
+ "en/on-call/integration/alert-integration/alert-sources/ofelia",
+ "en/on-call/integration/alert-integration/alert-sources/ohdear",
+ "en/on-call/integration/alert-integration/alert-sources/okta",
+ "en/on-call/integration/alert-integration/alert-sources/open-falcon",
+ "en/on-call/integration/alert-integration/alert-sources/opennms",
+ "en/on-call/integration/alert-integration/alert-sources/openobserve",
+ "en/on-call/integration/alert-integration/alert-sources/opensearch",
+ "en/on-call/integration/alert-integration/alert-sources/openstatus",
+ "en/on-call/integration/alert-integration/alert-sources/opmanager",
+ "en/on-call/integration/alert-integration/alert-sources/opnsense",
+ "en/on-call/integration/alert-integration/alert-sources/opsgenie",
+ "en/on-call/integration/alert-integration/alert-sources/opsview",
"en/on-call/integration/alert-integration/alert-sources/ossec",
- "en/on-call/integration/alert-integration/alert-sources/zeek",
- "en/on-call/integration/alert-integration/alert-sources/chronosphere",
- "en/on-call/integration/alert-integration/alert-sources/cubeapm",
- "en/on-call/integration/alert-integration/alert-sources/red-hat-openshift",
+ "en/on-call/integration/alert-integration/alert-sources/pagerduty",
+ "en/on-call/integration/alert-integration/alert-sources/pandora-fms",
+ "en/on-call/integration/alert-integration/alert-sources/panther",
"en/on-call/integration/alert-integration/alert-sources/papertrail",
- "en/on-call/integration/alert-integration/alert-sources/zabbix",
- "en/on-call/integration/alert-integration/alert-sources/flashcat",
- "en/on-call/integration/alert-integration/alert-sources/open-falcon",
- "en/on-call/integration/alert-integration/alert-sources/uptime-kuma",
+ "en/on-call/integration/alert-integration/alert-sources/peekaping",
+ "en/on-call/integration/alert-integration/alert-sources/pgdash",
+ "en/on-call/integration/alert-integration/alert-sources/phare",
+ "en/on-call/integration/alert-integration/alert-sources/pingdom",
+ "en/on-call/integration/alert-integration/alert-sources/postman",
+ "en/on-call/integration/alert-integration/alert-sources/powerjob",
"en/on-call/integration/alert-integration/alert-sources/projectdiscovery",
- "en/on-call/integration/alert-integration/alert-sources/statuscake",
+ "en/on-call/integration/alert-integration/alert-sources/prometheus",
+ "en/on-call/integration/alert-integration/alert-sources/prtg",
"en/on-call/integration/alert-integration/alert-sources/pulsetic",
- "en/on-call/integration/alert-integration/alert-sources/edge-delta",
- "en/on-call/integration/alert-integration/alert-sources/loadster",
- "en/on-call/integration/alert-integration/alert-sources/cronicle",
- "en/on-call/integration/alert-integration/alert-sources/atatus",
- "en/on-call/integration/alert-integration/alert-sources/calibre",
- "en/on-call/integration/alert-integration/alert-sources/uptimia",
- "en/on-call/integration/alert-integration/alert-sources/clustercontrol",
- "en/on-call/integration/alert-integration/alert-sources/hertzbeat",
- "en/on-call/integration/alert-integration/alert-sources/nobl9",
+ "en/on-call/integration/alert-integration/alert-sources/pulseway",
+ "en/on-call/integration/alert-integration/alert-sources/raritan-px",
+ "en/on-call/integration/alert-integration/alert-sources/raygun",
+ "en/on-call/integration/alert-integration/alert-sources/rbltracker",
+ "en/on-call/integration/alert-integration/alert-sources/red-hat-openshift",
+ "en/on-call/integration/alert-integration/alert-sources/redash",
+ "en/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor",
+ "en/on-call/integration/alert-integration/alert-sources/rizhiyi",
+ "en/on-call/integration/alert-integration/alert-sources/robotalp",
+ "en/on-call/integration/alert-integration/alert-sources/robusta",
+ "en/on-call/integration/alert-integration/alert-sources/rollbar",
+ "en/on-call/integration/alert-integration/alert-sources/rum-alert",
+ "en/on-call/integration/alert-integration/alert-sources/searchstax",
+ "en/on-call/integration/alert-integration/alert-sources/securityscorecard",
+ "en/on-call/integration/alert-integration/alert-sources/sematext",
+ "en/on-call/integration/alert-integration/alert-sources/semgrep",
+ "en/on-call/integration/alert-integration/alert-sources/sensu",
+ "en/on-call/integration/alert-integration/alert-sources/sentry",
"en/on-call/integration/alert-integration/alert-sources/sevone",
- "en/on-call/integration/alert-integration/alert-sources/hosted-graphite",
- "en/on-call/integration/alert-integration/alert-sources/netbeez",
- "en/on-call/integration/alert-integration/alert-sources/coroot",
- "en/on-call/integration/alert-integration/alert-sources/apimetrics",
- "en/on-call/integration/alert-integration/alert-sources/gatus",
- "en/on-call/integration/alert-integration/alert-sources/metoro",
- "en/on-call/integration/alert-integration/alert-sources/odown",
- "en/on-call/integration/alert-integration/alert-sources/bleemeo",
- "en/on-call/integration/alert-integration/alert-sources/whatap",
- "en/on-call/integration/alert-integration/alert-sources/fastnetmon",
- "en/on-call/integration/alert-integration/alert-sources/updown",
- "en/on-call/integration/alert-integration/alert-sources/hyperping",
- "en/on-call/integration/alert-integration/alert-sources/statusgator",
+ "en/on-call/integration/alert-integration/alert-sources/signoz",
"en/on-call/integration/alert-integration/alert-sources/simple-observability",
- "en/on-call/integration/alert-integration/alert-sources/xitoring",
- "en/on-call/integration/alert-integration/alert-sources/phare",
- "en/on-call/integration/alert-integration/alert-sources/monitive",
- "en/on-call/integration/alert-integration/alert-sources/tideways",
- "en/on-call/integration/alert-integration/alert-sources/wormly",
- "en/on-call/integration/alert-integration/alert-sources/obkio",
- "en/on-call/integration/alert-integration/alert-sources/flowtriq",
- "en/on-call/integration/alert-integration/alert-sources/tactical-rmm",
- "en/on-call/integration/alert-integration/alert-sources/bgpalerter",
- "en/on-call/integration/alert-integration/alert-sources/imperva",
- "en/on-call/integration/alert-integration/alert-sources/wazuh",
- "en/on-call/integration/alert-integration/alert-sources/auth0",
- "en/on-call/integration/alert-integration/alert-sources/twingate",
- "en/on-call/integration/alert-integration/alert-sources/langsmith",
- "en/on-call/integration/alert-integration/alert-sources/nodeping",
- "en/on-call/integration/alert-integration/alert-sources/influxdata",
- "en/on-call/integration/alert-integration/alert-sources/kapacitor",
- "en/on-call/integration/alert-integration/alert-sources/graylog",
+ "en/on-call/integration/alert-integration/alert-sources/site24x7",
"en/on-call/integration/alert-integration/alert-sources/skywalking",
- "en/on-call/integration/alert-integration/alert-sources/elastalert2",
- "en/on-call/integration/alert-integration/alert-sources/keep",
- "en/on-call/integration/alert-integration/alert-sources/aliyun-arms",
- "en/on-call/integration/alert-integration/alert-sources/aliyun-cm-event",
- "en/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics",
- "en/on-call/integration/alert-integration/alert-sources/aliyun-sls",
- "en/on-call/integration/alert-integration/alert-sources/aliyun-prometheus",
- "en/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op",
- "en/on-call/integration/alert-integration/alert-sources/aws-cloudwatch",
- "en/on-call/integration/alert-integration/alert-sources/aws-eventbridge",
- "en/on-call/integration/alert-integration/alert-sources/azure-monitor",
- "en/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring",
- "en/on-call/integration/alert-integration/alert-sources/google-scc",
- "en/on-call/integration/alert-integration/alert-sources/tencent-cls",
- "en/on-call/integration/alert-integration/alert-sources/tencent-css",
- "en/on-call/integration/alert-integration/alert-sources/tencent-cm",
- "en/on-call/integration/alert-integration/alert-sources/tencent-eventbridge",
- "en/on-call/integration/alert-integration/alert-sources/baidu-bcm",
- "en/on-call/integration/alert-integration/alert-sources/ctyun",
- "en/on-call/integration/alert-integration/alert-sources/ecloud-cm",
- "en/on-call/integration/alert-integration/alert-sources/huawei-ces",
- "en/on-call/integration/alert-integration/alert-sources/huawei-lts",
- "en/on-call/integration/alert-integration/alert-sources/huawei-apm",
- "en/on-call/integration/alert-integration/alert-sources/huawei-aom",
- "en/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics",
- "en/on-call/integration/alert-integration/alert-sources/volcengine-cm-event",
- "en/on-call/integration/alert-integration/alert-sources/volcengine-tls",
- "en/on-call/integration/alert-integration/alert-sources/pagerduty",
- "en/on-call/integration/alert-integration/alert-sources/opsgenie",
- "en/on-call/integration/alert-integration/alert-sources/dynatrace",
- "en/on-call/integration/alert-integration/alert-sources/appdynamics",
+ "en/on-call/integration/alert-integration/alert-sources/snyk",
"en/on-call/integration/alert-integration/alert-sources/solarwinds",
"en/on-call/integration/alert-integration/alert-sources/solarwinds-orion",
+ "en/on-call/integration/alert-integration/alert-sources/sonarqube",
+ "en/on-call/integration/alert-integration/alert-sources/split-io",
"en/on-call/integration/alert-integration/alert-sources/splunk",
"en/on-call/integration/alert-integration/alert-sources/splunk-observability",
- "en/on-call/integration/alert-integration/alert-sources/sentry",
- "en/on-call/integration/alert-integration/alert-sources/opmanager",
- "en/on-call/integration/alert-integration/alert-sources/blueking",
- "en/on-call/integration/alert-integration/alert-sources/guance",
- "en/on-call/integration/alert-integration/alert-sources/jiankongbao",
- "en/on-call/integration/alert-integration/alert-sources/oceanbase",
- "en/on-call/integration/alert-integration/alert-sources/zilliz",
- "en/on-call/integration/alert-integration/alert-sources/zstack",
- "en/on-call/integration/alert-integration/alert-sources/cloudflare",
- "en/on-call/integration/alert-integration/alert-sources/meraki",
- "en/on-call/integration/alert-integration/alert-sources/monit",
- "en/on-call/integration/alert-integration/alert-sources/rum-alert",
- "en/on-call/integration/alert-integration/alert-sources/harbor",
+ "en/on-call/integration/alert-integration/alert-sources/stackrox",
+ "en/on-call/integration/alert-integration/alert-sources/statuscake",
+ "en/on-call/integration/alert-integration/alert-sources/statusgator",
+ "en/on-call/integration/alert-integration/alert-sources/statuspage",
+ "en/on-call/integration/alert-integration/alert-sources/statuspal",
+ "en/on-call/integration/alert-integration/alert-sources/stripe",
+ "en/on-call/integration/alert-integration/alert-sources/sublime",
+ "en/on-call/integration/alert-integration/alert-sources/sumo-logic",
+ "en/on-call/integration/alert-integration/alert-sources/suricata",
+ "en/on-call/integration/alert-integration/alert-sources/sysdig",
+ "en/on-call/integration/alert-integration/alert-sources/tactical-rmm",
+ "en/on-call/integration/alert-integration/alert-sources/tailscale",
+ "en/on-call/integration/alert-integration/alert-sources/tencent-cls",
+ "en/on-call/integration/alert-integration/alert-sources/tencent-cm",
+ "en/on-call/integration/alert-integration/alert-sources/tencent-css",
+ "en/on-call/integration/alert-integration/alert-sources/tencent-eventbridge",
+ "en/on-call/integration/alert-integration/alert-sources/thinkst-canary",
+ "en/on-call/integration/alert-integration/alert-sources/thousandeyes",
+ "en/on-call/integration/alert-integration/alert-sources/tideways",
+ "en/on-call/integration/alert-integration/alert-sources/tracee",
+ "en/on-call/integration/alert-integration/alert-sources/trigger-dev",
+ "en/on-call/integration/alert-integration/alert-sources/trivy-operator",
+ "en/on-call/integration/alert-integration/alert-sources/twilio",
+ "en/on-call/integration/alert-integration/alert-sources/twingate",
"en/on-call/integration/alert-integration/alert-sources/ucloud-cloudwatch",
- "en/on-call/integration/alert-integration/alert-sources/jdcloud",
- "en/on-call/integration/alert-integration/alert-sources/kscloud-monitor",
- "en/on-call/integration/alert-integration/alert-sources/volcengine-rtc",
+ "en/on-call/integration/alert-integration/alert-sources/updown",
+ "en/on-call/integration/alert-integration/alert-sources/upguard",
+ "en/on-call/integration/alert-integration/alert-sources/uptime-com",
+ "en/on-call/integration/alert-integration/alert-sources/uptime-kuma",
+ "en/on-call/integration/alert-integration/alert-sources/uptimeobserver",
+ "en/on-call/integration/alert-integration/alert-sources/uptimerobot",
+ "en/on-call/integration/alert-integration/alert-sources/uptimia",
+ "en/on-call/integration/alert-integration/alert-sources/uptrends",
+ "en/on-call/integration/alert-integration/alert-sources/veeam-one",
+ "en/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console",
+ "en/on-call/integration/alert-integration/alert-sources/veracode-sca",
+ "en/on-call/integration/alert-integration/alert-sources/vigil",
+ "en/on-call/integration/alert-integration/alert-sources/volcengine-cm-event",
+ "en/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics",
"en/on-call/integration/alert-integration/alert-sources/volcengine-dial",
- "en/on-call/integration/alert-integration/alert-sources/nagios",
- "en/on-call/integration/alert-integration/alert-sources/emqx",
- "en/on-call/integration/alert-integration/alert-sources/rizhiyi",
- "en/on-call/integration/alert-integration/alert-sources/dingtalk-alert",
- "en/on-call/integration/alert-integration/alert-sources/lark-alert",
+ "en/on-call/integration/alert-integration/alert-sources/volcengine-rtc",
+ "en/on-call/integration/alert-integration/alert-sources/volcengine-tls",
+ "en/on-call/integration/alert-integration/alert-sources/wazuh",
"en/on-call/integration/alert-integration/alert-sources/wecom-alert",
- "en/on-call/integration/alert-integration/alert-sources/ghost-inspector",
- "en/on-call/integration/alert-integration/alert-sources/monte-carlo",
- "en/on-call/integration/alert-integration/alert-sources/limacharlie"
+ "en/on-call/integration/alert-integration/alert-sources/whatap",
+ "en/on-call/integration/alert-integration/alert-sources/whatsup-gold",
+ "en/on-call/integration/alert-integration/alert-sources/wormly",
+ "en/on-call/integration/alert-integration/alert-sources/xitoring",
+ "en/on-call/integration/alert-integration/alert-sources/zabbix",
+ "en/on-call/integration/alert-integration/alert-sources/zeek",
+ "en/on-call/integration/alert-integration/alert-sources/zenoss",
+ "en/on-call/integration/alert-integration/alert-sources/zilliz",
+ "en/on-call/integration/alert-integration/alert-sources/zstack"
]
},
{
"group": "Change Integration",
"pages": [
+ "en/on-call/integration/change-integration/apollo",
+ "en/on-call/integration/change-integration/argo-rollouts",
+ "en/on-call/integration/change-integration/argocd",
+ "en/on-call/integration/change-integration/awx",
+ "en/on-call/integration/change-integration/azure-devops",
+ "en/on-call/integration/change-integration/bitbucket",
+ "en/on-call/integration/change-integration/buildkite",
+ "en/on-call/integration/change-integration/circleci",
+ "en/on-call/integration/change-integration/coolify",
"en/on-call/integration/change-integration/custom-event",
- "en/on-call/integration/change-integration/heroku",
- "en/on-call/integration/change-integration/teamcity",
- "en/on-call/integration/change-integration/railway",
+ "en/on-call/integration/change-integration/env0",
+ "en/on-call/integration/change-integration/expo-eas",
+ "en/on-call/integration/change-integration/flagsmith",
+ "en/on-call/integration/change-integration/fluxcd",
+ "en/on-call/integration/change-integration/gitea",
+ "en/on-call/integration/change-integration/gitee",
"en/on-call/integration/change-integration/github",
"en/on-call/integration/change-integration/gitlab",
+ "en/on-call/integration/change-integration/growthbook",
+ "en/on-call/integration/change-integration/harness-fme",
"en/on-call/integration/change-integration/hcp-terraform",
- "en/on-call/integration/change-integration/argocd",
- "en/on-call/integration/change-integration/netlify",
- "en/on-call/integration/change-integration/vercel",
+ "en/on-call/integration/change-integration/heroku",
+ "en/on-call/integration/change-integration/jenkins",
"en/on-call/integration/change-integration/jfrog-artifactory",
- "en/on-call/integration/change-integration/buildkite",
+ "en/on-call/integration/change-integration/jira",
"en/on-call/integration/change-integration/launchdarkly",
- "en/on-call/integration/change-integration/jenkins",
- "en/on-call/integration/change-integration/circleci",
- "en/on-call/integration/change-integration/bitbucket",
- "en/on-call/integration/change-integration/unleash",
- "en/on-call/integration/change-integration/gitea",
- "en/on-call/integration/change-integration/rundeck",
- "en/on-call/integration/change-integration/flagsmith",
- "en/on-call/integration/change-integration/azure-devops",
- "en/on-call/integration/change-integration/argo-rollouts",
+ "en/on-call/integration/change-integration/nautobot",
+ "en/on-call/integration/change-integration/netbox",
+ "en/on-call/integration/change-integration/netlify",
"en/on-call/integration/change-integration/octopus-deploy",
- "en/on-call/integration/change-integration/awx",
- "en/on-call/integration/change-integration/semaphore",
- "en/on-call/integration/change-integration/coolify",
- "en/on-call/integration/change-integration/scalr",
- "en/on-call/integration/change-integration/growthbook",
- "en/on-call/integration/change-integration/fluxcd",
"en/on-call/integration/change-integration/pulumi",
- "en/on-call/integration/change-integration/env0",
- "en/on-call/integration/change-integration/expo-eas",
- "en/on-call/integration/change-integration/harness-fme",
- "en/on-call/integration/change-integration/gitee",
+ "en/on-call/integration/change-integration/railway",
+ "en/on-call/integration/change-integration/rundeck",
+ "en/on-call/integration/change-integration/scalr",
+ "en/on-call/integration/change-integration/semaphore",
+ "en/on-call/integration/change-integration/teamcity",
+ "en/on-call/integration/change-integration/unleash",
+ "en/on-call/integration/change-integration/vercel",
"en/on-call/integration/change-integration/yunxiao-appstack",
- "en/on-call/integration/change-integration/zadig",
- "en/on-call/integration/change-integration/netbox",
- "en/on-call/integration/change-integration/nautobot",
- "en/on-call/integration/change-integration/apollo",
- "en/on-call/integration/change-integration/jira"
+ "en/on-call/integration/change-integration/zadig"
]
},
{
@@ -5394,9 +5424,9 @@
{
"group": "Error Reporting",
"pages": [
- "en/rum/error-tracking/erro-reporting/web",
- "en/rum/error-tracking/erro-reporting/android",
- "en/rum/error-tracking/erro-reporting/ios"
+ "en/rum/error-tracking/error-reporting/web",
+ "en/rum/error-tracking/error-reporting/android",
+ "en/rum/error-tracking/error-reporting/ios"
]
},
"en/rum/error-tracking/error-viewing",
@@ -5547,7 +5577,7 @@
"en/openapi/introduction",
"en/openapi/api-catalog",
"en/openapi/pagination",
- "en/openapi/go-sdk"
+ "en/openapi/rate-limits"
]
},
{
diff --git a/en/ai-sre.mdx b/en/ai-sre.mdx
index ebcb0d72..9a0a31cf 100644
--- a/en/ai-sre.mdx
+++ b/en/ai-sre.mdx
@@ -51,16 +51,7 @@ It is not a question-and-answer chatbot but a **hands-on troubleshooter**, integ
## Activation and billing
-AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed.
-
-
-
- AI SRE is billed on actual usage starting September 16, 2026, 08:00 Beijing time, settled in credits (1 credit = ¥1); usage before that date isn't charged. Metered items are model usage, sandbox online time, and web search. Activation is free, eligible accounts get gift credits each billing period, and you can also buy credit packages (1,000 / 5,000 / 20,000 credits for ¥950 / ¥4,500 / ¥17,000, valid 365 days from payment). Pay-as-you-go is off by default; an admin can turn it on and optionally set a per-period cap. Full terms: [AI SRE Credit Package Purchase Agreement](/en/compliance/ai-sre-credit-package-purchase-agreement).
-
-
- Production changes, restarts, rollbacks, and external notifications all require your confirmation before they execute.
-
-
+AI SRE must be activated in the console and is billed on actual usage in credits. Production changes, restarts, rollbacks, and external notifications all require your confirmation before they execute. For activation, billing rules, and subscription requirements, see [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Get Started
diff --git a/en/ai-sre/agents.mdx b/en/ai-sre/agents.mdx
index 42a3d889..387106be 100644
--- a/en/ai-sre/agents.mdx
+++ b/en/ai-sre/agents.mdx
@@ -5,14 +5,10 @@ keywords: ["AI SRE", "Agent", "A2A", "Agent-to-Agent", "Agent Card", "delegation
sidebarTitle: Agent
---
-
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
**Agent** is the resource category that connects AI SRE to external agent ecosystems. The currently supported type is **A2A (Agent-to-Agent)** — a standard protocol that lets different agents call one another (more agent types may be added later). A2A works in two directions:
@@ -24,55 +20,22 @@ sidebarTitle: Agent
-Delegation does not make you wait: after AI SRE hands a task to a remote agent, the conversation continues immediately, so you can keep working or delegate several tasks at once. When the remote agent finishes, its result appears in the conversation as a new message. Each A2A delegation appears in the conversation stream as a **task card** carrying an `A2A` badge, showing the remote agent name, task intent, run status (initializing / in progress / awaiting input / awaiting authorization / completed / failed (including orphaned) / interrupted / killed), and usage metrics such as tool call count, tokens, and elapsed time. Click the card to view the full delegation trace in the right-hand panel.
+Delegation does not make you wait: after AI SRE hands a task to a remote agent, the conversation continues immediately, so you can keep working or delegate several tasks at once. When the remote agent finishes, its result appears in the conversation as a new message.
+
+Each A2A delegation appears in the conversation stream as a **task card** carrying an `A2A` badge, showing the remote agent name, task intent, run status (initializing / in progress / awaiting input / awaiting authorization / completed / failed (including orphaned) / interrupted / killed), and usage metrics such as tool call count, tokens, and elapsed time. Click the card to view the full delegation trace in the right-hand panel.
-**Instructions have two levels and act as the agent-selection signal.** Before delegating, AI SRE sees a list of available agents where each entry is just `name: summary` — the summary comes from a `summary:` line at the top of the instructions (if omitted, the beginning of the body is excerpted automatically). AI SRE uses it to decide **whether and when** to delegate to this agent, so state clearly when to prefer it, what it excels at, and what it is not suited for. The body that follows the summary is not kept in the list — it is delivered to AI SRE in full only the **first time it delegates to this agent**, so you can write it as long and detailed as needed (procedures, hard rules, examples) without slowing down everyday conversations. See "[Writing Instructions](#writing-instructions)" below for the format.
+**The instructions decide whether AI SRE picks this agent.** Before delegating, AI SRE sees only one `name: summary` line per agent (the summary comes from the `summary:` line at the top of the instructions) and uses it to decide whether to delegate. The body is delivered in full only on the first delegation, so it can be long and detailed. See [Writing Instructions](#writing-instructions).
-The A2A agent list and management entry point are on the **Customize → Plugins → Agents** page (menu tab labeled **Agents**).
+The A2A agent list and management entry point are on the **Customize → Plugins → Agents** page.
-**Agents covers two distinct concepts.** This page (Agents) currently manages **A2A Agents** (external agent-to-agent calls). The other concept is the **Subagent** — a platform-built-in task executor that AI SRE dispatches on demand within a session. Subagents have no create / edit entry point; you only observe their behavior in sessions. See "[Subagent](#subagent)" below.
-
-
-## Subagent
-
----
-
-A **Subagent** is a platform **built-in** task executor. During an investigation, AI SRE can **dispatch** a self-contained subtask to a Subagent that completes it independently — dispatch always goes through the single long-running tool `agent_dispatch`, rather than exposing a separate tool per Subagent.
-
-The platform ships several **bootstrap Subagents** that work out of the box:
-
-| Name | Role |
-| --- | --- |
-| `general` | General-purpose worker with full tool access. Use it to offload work whose intermediate steps would otherwise pollute the parent's context (long reports, multi-file edits, end-to-end builds, repeated probing). Dispatch several in parallel for independent units of work |
-| `explore` | Read-only investigator restricted to `grep` / `glob` / `read`; it cannot write or execute. Returns a compact summary rather than raw search output — ideal for locating evidence inside a codebase or knowledge dump |
-
-**In the conversation**: each dispatch also appears as a **task card** in the conversation stream and shares the same status lifecycle as an A2A delegation (initializing / in progress / awaiting input / awaiting authorization / completed / failed (including orphaned) / interrupted / killed). The difference is the badge — a Subagent task card carries an `Agent` badge, whereas an A2A delegation carries an `A2A` badge. A Subagent card's reference line also leads its right-hand side with the **execution environment this dispatch runs in** (the cloud environment, or the BYOC Runner's name), so you can see where a subtask executed straight from the card — see "Dispatch target environment" below.
-
-**Runtime limits**:
-
-- **Concurrency cap**: a session runs **at most 20 Subagents concurrently** (`TaskMaxConcurrentPerSession = 20`). This caps how many run at the same instant, not how many a session dispatches over its lifetime — completing one frees a slot, so total work is unbounded. Dispatching past the cap errors (`too many active subagents (… running, limit 20)`), prompting the model to stop and wait for the running ones to finish before dispatching the rest.
-- **Nesting depth**: a dispatch chain nests **at most 3 levels deep** (`TaskMaxNestingDepth = 3`), preventing a Subagent from spawning itself indefinitely.
-
-**Dispatch target environment**: `agent_dispatch` also takes an optional `environment` argument that decides **which execution environment** the subtask runs in. Its values are:
-
-- **Omitted (the default)**: the subagent runs in the **same** environment as the current session and **shares its filesystem** — it can read your workspace's files directly. Naming the environment the session is *already* in (say, passing `cloud` from a cloud session) has the same result: an inheritance, not a second sandbox.
-- **`cloud`**: runs in a **fresh cloud environment** — an ephemeral container with its own filesystem and the account's default egress policy.
-- **A BYOC Runner's environment_id**: runs on **that Runner**. The selectable targets are **account-scope Runners** plus the Runners of the **team the session is bound to**, and online ones only; same-named Runners are tagged with their team so they can be told apart. `agent_dispatch`'s own description lists them, and each Runner's id is the value to pass. Naming an unusable Runner (offline, nonexistent, or belonging to another team) makes the dispatch fail outright with the reason — it is never silently re-routed elsewhere.
-- **Subagents only**: passing `environment` for an A2A Agent is rejected — a remote agent executes in its own environment and has no placement to choose; to move work to another environment, dispatch a Subagent.
-
-**A cross-environment dispatch cannot read the parent's files**: a child session shares the parent's sandbox / workspace only when its execution environment is **exactly the same**; dispatched to another environment, it gets **its own** sandbox or Runner scratch directory and **cannot see your (the parent's) files**. So put everything it needs **in the prompt** (file contents, paths, parameters, constraints) instead of writing "read file x in the workspace", and expect results back as **text** or through an external system (git, a ticket). See [Environments (BYOC)](/en/ai-sre/environments) for how the environments themselves differ and how to pick one.
-
-
-**Subagents currently have no user-facing create / management UI.** They are a built-in runtime capability: you can observe Subagent task cards and their sub-session traces within a session, but you cannot add, edit, or delete a Subagent the way you can an A2A Agent. This page (Agents) currently manages only A2A Agents.
+**Agents covers two distinct concepts.** This page (Agents) currently manages **A2A Agents** (external agent-to-agent calls). The other concept is the **Subagent** — a platform-built-in task executor that AI SRE dispatches on demand within a session. Subagents have no create / edit entry point; you only observe their behavior in sessions. See [Subagent](#subagent) below.
## Registering an Outbound A2A Agent
----
-
On the A2A Agents list page, click **Add A2A Agent** and fill in the form:
| Field | Type | Default | Description |
@@ -80,11 +43,11 @@ On the A2A Agents list page, click **Add A2A Agent** and fill in the form:
| Name | string | — | A2A agent identifier (e.g., `metrics-analyzer`). Required |
| Scope | Shared / Team | — | Scope: **Shared** (i.e., account level — visible account-wide) or a specific **Team** (visible and editable only to members of that team). Required — see "Scope" below |
| Execution Environment | Cloud / BYOC Runners (multiple) | All environments | Controls where this A2A agent is available. Select Cloud and one or more visible BYOC Runners; leave empty to make it available everywhere. It does not route delegated calls: an A2A call still runs in the current AI SRE session's environment. For a remote agent available only on a private network, select only the Runner(s) that can reach it |
-| Instructions | string | — | The agent-selection signal shown to AI SRE, as **a single document**: an optional `summary:` frontmatter block plus a body. The summary appears in the available-agent list; the body is delivered in full only on first delegation. Required; the whole document is at most 50 KB, and `summary` is at most 1,024 characters and must not contain `<` or `>`. See "[Writing Instructions](#writing-instructions)" below for the format |
-| Card URL | string | — | The Agent Card URL of the remote A2A agent, or just the service origin for agents that follow the default well-known location (for example, `https://agents.example.com`). If the URL includes a path, the platform reads that exact URL; if only an origin is provided, it resolves `/.well-known/agent-card.json` by A2A convention. Required. The platform only validates that the URL is well-formed (scheme is http/https, host is non-empty) — it does not classify hosts or IPs; actual network reachability and egress restrictions depend on the current AI SRE session's execution environment. The Execution Environment field above only limits where this agent is available. The remote agent must implement A2A Protocol 1.0 — see "[Protocol Version and Agent Card Requirements](#protocol-version-and-agent-card-requirements)" below |
-| Service authorization | enum | `none` | The identity AI SRE uses when calling the remote agent **as a service** (field `auth_type`): `none` / `bearer` (Bearer Token) / `api_key` (custom Header + Key). Marked **Recommended** in the form. See "[Authorization Modes](#authorization-modes)" below |
+| Instructions | string | — | The agent-selection signal shown to AI SRE, as **a single document**: an optional `summary:` frontmatter block plus a body. The summary appears in the available-agent list; the body is delivered in full only on first delegation. Required; the whole document is at most 50 KB, and `summary` is at most 1,024 characters and must not contain `<` or `>`. See [Writing Instructions](#writing-instructions) below for the format |
+| Card URL | string | — | The Agent Card URL of the remote A2A agent, or just the service origin for agents that follow the default well-known location (for example, `https://agents.example.com`). If the URL includes a path, the platform reads that exact URL; if only an origin is provided, it resolves `/.well-known/agent-card.json` by A2A convention. Required; must be an http/https URL. Whether it is reachable depends on the execution environment of the session that delegates. The remote agent must implement A2A Protocol 1.0 — see [Protocol Version and Agent Card Requirements](#protocol-version-and-agent-card-requirements) below |
+| Service authorization | enum | `none` | The identity AI SRE uses when calling the remote agent **as a service** (field `auth_type`): `none` / `bearer` (Bearer Token) / `api_key` (custom Header + Key). Marked **Recommended** in the form. See [Authorization Modes](#authorization-modes) below |
| Streaming | bool | on | Whether to communicate with the remote agent in streaming mode |
-| Member authorization | enum | `shared` (none) | The identity each member holds individually (field `auth_mode`): `shared` (none) / `per_user_secret` (Secret (Header)) / `per_user_oauth` (OAuth 2.1). See "[Authorization Modes](#authorization-modes)" below |
+| Member authorization | enum | `shared` (none) | The identity each member holds individually (field `auth_mode`): `shared` (none) / `per_user_secret` (Secret (Header)) / `per_user_oauth` (OAuth 2.1). See [Authorization Modes](#authorization-modes) below |
| Skip TLS certificate verification | bool | off | Shown only when the Card URL uses HTTPS. Enable only when the remote endpoint uses a self-signed certificate inside a controlled network; this skips certificate-chain and hostname verification |
| Allow fetching OAuth configuration over HTTP (testing only) | bool | off | Required only when **Member authorization** is set to "OAuth 2.1" and the Card URL is a non-local HTTP URL. Use only in controlled test environments; after you enable it, the AI SRE service can fetch OAuth metadata from that host |
@@ -147,7 +110,7 @@ Body: detailed instructions for the agent…
- **Hard limits**: the whole document (frontmatter + body) is at most **50 KB**; `summary` is at most **1,024 characters** and must not contain `<` or `>`; the body must be non-empty.
- If the document starts with `---`, that frontmatter block must be closed with another `---` line, or saving fails.
-The instructions used by "[Using the FlashAI Template](#using-the-flashai-template)" below are a working example — see its structure for reference.
+The instructions used by [Using the FlashAI Template](#using-the-flashai-template) below are a working example — see its structure for reference.
### Using the FlashAI Template
@@ -194,7 +157,7 @@ After FlashAI is prepared, enter the **FlashAI domain** in the panel (for exampl
https://demo.flashcat.cloud/api/fc-model/a2a/.well-known/agent-card.json
```
-The template only prefills common values. You still choose the **Scope** (Shared or Team) and configure authentication in the form. A2A agents can be installed multiple times for different scopes, so the FlashAI panel does not disappear just because one FlashAI agent already exists. Agent names must still be unique within the account; if the same FlashAI domain needs to be installed more than once, adjust the name in the form.
+The template prefills only common values; you still set the **Scope** (Shared or Team) and authentication in the form. The same FlashAI can be installed several times for different scopes, but agent names must be unique within the account, so change the name when installing it again.
Do not remove the instructions generated by the FlashAI template, especially the `summary:` line at the top — once registered, FlashAI always appears in the available-agent list, but whether AI SRE actually delegates to it hinges directly on that summary line. When the instructions are too short or too generic, AI SRE may keep reasoning locally or incorrectly delegate ordinary metrics / logs questions to FlashAI.
@@ -223,7 +186,7 @@ The "Identity resolution order" panel at the bottom of the form updates live as
- **Service authorization only**: all calls use the service authorization.
- **Member authorization only**: IM group chats use the speaking member's own authorization, turn by turn. If the remote system rejects several identities taking turns within one conversation (its identity check fails), add a service authorization.
-- **Both axes set to none**: calls carry no identity. Saving prompts for confirmation — "This Agent will call without any identity. Save anyway?". Configure a service authorization when the remote endpoint requires authentication.
+- **Both axes set to none**: calls carry no identity. Saving asks for confirmation. Configure a service authorization when the remote endpoint requires authentication.
A service authorization means any team-scope session or IM group chat in the account can call the remote system as that service identity. If the system exposes members' personal data or allows high-risk writes, enable member authorization as well.
@@ -245,16 +208,51 @@ OAuth 2.1 appears only on the **member authorization** axis. The service authori
-For security reasons, saved sensitive fields (such as `token`, `api_key`, and `client_secret`) are returned **masked** when read. When editing, leaving a sensitive field blank means "keep the current value" — not "clear it." The stored credential is only overwritten when you explicitly change it.
+Saved sensitive fields (such as tokens, API keys and client secrets) are shown **masked**. Leaving one blank when editing keeps the current value rather than clearing it.
Use HTTPS for member authorization (OAuth 2.1) discovery whenever possible. Enable "Allow fetching OAuth configuration over HTTP (testing only)" for a non-local HTTP Card URL only in controlled test environments. If an HTTPS endpoint uses a self-signed certificate, enable "Skip TLS certificate verification" only temporarily and only inside a trusted network.
-## Inbound: Letting External Agents Call AI SRE
+## Creating and Managing
----
+The full lifecycle of A2A agents is managed on the **Customize → Plugins → Agents** page.
+
+
+
+ Click **Add A2A Agent**, fill in the name, scope, instructions, Card URL, auth settings, and save. You must select a definite scope (shared or team) before submitting — the submit button remains disabled until a scope is chosen.
+
+
+ Use the toggle in the list to switch an A2A agent's enabled state. Only **enabled** agents appear in AI SRE's available-agent list and can receive delegated tasks; disabling one makes it immediately invisible to delegation.
+
+
+ Click any row in the list to open the form, where you can view and edit the name, instructions, scope, Card URL, service authorization, member authorization, and streaming. The form is **read-only** when you do not have edit permission.
+
+
+ Remove an A2A agent from the current scope. **Active sessions that delegated to it will fail.** Deletion requires confirmation.
+
+
+ Filter the list by scope (All / Shared / a specific team) or search by keywords in the name, instructions, or Card URL. Each row shows its scope (shared / team name).
+
+
+
+## Scope
+
+A2A agents share the same **two-level scope** model as other resources (skills, Knowledge, MCP, environments), divided into account level and team level. In the console UI, the account-level option is labeled "**Shared**" / "**Shared scope**" — synonymous with account level (visible account-wide):
+
+| Scope | Visibility |
+| --- | --- |
+| Account level | Visible to all members in the account |
+| Team level | Visible only to members of that team |
+
+**Edit permissions**: team-level agents can be acted on only by members of that team — organization admins must join the team first; account-level agents can be acted on only by the account owner or account admin; there is no creator-retains-rights exception. When you do not have edit permission, the corresponding row in the list is **read-only**.
+
+**Create and reassign**: to create a new team-level agent, you must belong to the target team; account-level creation is limited to the account owner or admins. When editing an existing agent, the account owner or admins can move it to any team to recover resources left behind by empty teams or departed members; regular members can move it only to teams they belong to.
+
+**Runtime visibility**: at session start, AI SRE's available-agent list shows only **account-level** resources plus resources belonging to the **team bound to the current session** (e.g., the team carried in by an incident / war room, or explicitly selected in the UI). A team's skills, MCP servers, and A2A agents are only mounted into the current session on demand after the agent reads that team's knowledge during an investigation. **The account is the only security perimeter at runtime; team is simply an ownership and editing tag.**
+
+## Inbound: Letting External Agents Call AI SRE
Expand the "**Let External Agents Call Flashduty's AI SRE**" panel at the top of the A2A Agents page to get the **Agent Card** URL for this account's AI SRE:
@@ -281,56 +279,40 @@ The Agent Card also declares Flashduty's "run options" A2A extension: callers ca
When a session **enters via an incident route** (e.g., AI SRE is triggered from an incident or war room), the platform binds the corresponding incident to the session and brings it in as context, anchoring troubleshooting to the correct incident from the start. Based on this, AI SRE can use built-in skills during the conversation to further act on the incident — reading incident details, querying the timeline, creating / viewing war rooms, linking changes, and more. For automatic war-room diagnosis on the IM side, see [IM Integration](/en/ai-sre/im).
-**Automatic incident integration** for A2A is currently supported conceptually and is under active development: automatic incident binding is not yet fully available, and bidirectional event streams across agents will be progressively completed with each release. Do not treat this as a fully available capability; rely only on features that have been explicitly enabled.
+**Automatic incident integration** for A2A is still under development: automatic incident binding is not yet fully available, and bidirectional event streams across agents will be completed over upcoming releases. Rely only on features that are actually enabled.
-## Creating and Managing
-
----
+## Subagent
-The full lifecycle of A2A agents is managed on the **Customize → Plugins → Agents** page.
+A **Subagent** is a platform **built-in** task executor. During an investigation, AI SRE can **dispatch** a self-contained subtask to a Subagent that completes it independently (via the `agent_dispatch` tool).
-
-
- Click **Add A2A Agent**, fill in the name, scope, instructions, Card URL, auth settings, and save. You must select a definite scope (shared or team) before submitting — the submit button remains disabled until a scope is chosen.
-
-
- Use the toggle in the list to switch an A2A agent's enabled state. Only **enabled** agents appear in AI SRE's available-agent list and can receive delegated tasks; disabling one makes it immediately invisible to delegation.
-
-
- Click any row in the list to open the form, where you can view and edit the name, instructions, scope, Card URL, service authorization, member authorization, and streaming. The form is **read-only** when you do not have edit permission.
-
-
- Remove an A2A agent from the current scope. **Active sessions that delegated to it will fail.** Deletion requires confirmation.
-
-
- The scope filter bar at the top of the list lets you switch between "All", "Shared", and "Specific team", making it easy to focus on relevant resources when managing many. Each row also has a label showing its scope (shared / team name). The search box to the right of the filter bar filters the list by keywords in the name, instructions, or Card URL.
-
-
+The platform ships several **bootstrap Subagents** that work out of the box:
-## Scope
+| Name | Role |
+| --- | --- |
+| `general` | General-purpose worker with full tool access. Use it to offload work whose intermediate steps would otherwise pollute the parent's context (long reports, multi-file edits, end-to-end builds, repeated probing). Dispatch several in parallel for independent units of work |
+| `explore` | Read-only investigator restricted to `grep` / `glob` / `read`; it cannot write or execute. Returns a compact summary rather than raw search output — ideal for locating evidence inside a codebase or knowledge dump |
----
+**In the conversation**: each dispatch also appears as a **task card** in the conversation stream with the same statuses as an A2A delegation, but with an `Agent` badge (A2A delegations show `A2A`). The card also shows the **execution environment** of the dispatch (the cloud environment or the BYOC Runner's name) — see "Dispatch target environment" below.
-A2A agents share the same **two-level scope** model as other resources (skills, Knowledge, MCP, environments), divided into account level and team level. In the console UI, the account-level option is labeled "**Shared**" / "**Shared scope**" — synonymous with account level (visible account-wide):
+**Runtime limits**:
-| Scope | Visibility |
-| --- | --- |
-| Account level | Visible to all members in the account |
-| Team level | Visible only to members of that team |
+- **Concurrency cap**: a session runs **at most 20 Subagents at the same time**. Total dispatches are unlimited — each completion frees a slot; at the cap, AI SRE waits for running ones to finish before dispatching the rest.
+- **Nesting depth**: a dispatch chain nests **at most 3 levels deep**, preventing a Subagent from spawning itself indefinitely.
-**Edit permissions**: team-level agents can be acted on only by members of that team — organization admins must join the team first; account-level agents can be acted on only by the account owner or account admin; there is no creator-retains-rights exception. When you do not have edit permission, the corresponding row in the list is **read-only**.
+**Dispatch target environment**: `agent_dispatch` also takes an optional `environment` argument that decides **which execution environment** the subtask runs in. Its values are:
-**Create and reassign**: to create a new team-level agent, you must belong to the target team; account-level creation is limited to the account owner or admins. When editing an existing agent, the account owner or admins can move it to any team to recover resources left behind by empty teams or departed members; regular members can move it only to teams they belong to.
+- **Omitted (the default)**: the subagent runs in the **same** environment as the current session and **shares its filesystem** — it can read your workspace's files directly. Naming the environment the session is *already* in (say, passing `cloud` from a cloud session) has the same result: an inheritance, not a second sandbox.
+- **`cloud`**: runs in a **fresh cloud environment** — an ephemeral container with its own filesystem and the account's default egress policy.
+- **A BYOC Runner's environment_id**: runs on **that Runner**. The selectable targets are **account-scope Runners** plus the Runners of the **team the session is bound to**, and online ones only; naming an unusable Runner (offline, nonexistent, or belonging to another team) makes the dispatch fail with the reason; it is never re-routed elsewhere.
+- **Subagents only**: passing `environment` for an A2A Agent is rejected — a remote agent executes in its own environment and has no placement to choose; to move work to another environment, dispatch a Subagent.
-**Runtime visibility**: at session start, AI SRE's available-agent list shows only **account-level** resources plus resources belonging to the **team bound to the current session** (e.g., the team carried in by an incident / war room, or explicitly selected in the UI). A team's skills, MCP servers, and A2A agents are only mounted into the current session on demand after the agent reads that team's knowledge during an investigation. **The account is the only security perimeter at runtime; team is simply an ownership and editing tag.**
+**A cross-environment dispatch cannot read the parent's files**: a child session shares the parent's sandbox / workspace only when its execution environment is **exactly the same**; dispatched to another environment, it gets **its own** sandbox or Runner scratch directory and **cannot see your (the parent's) files**. So put everything it needs **in the prompt** (file contents, paths, parameters, constraints) instead of writing "read file x in the workspace", and expect results back as **text** or through an external system (git, a ticket). See [Environments (BYOC)](/en/ai-sre/environments) for how the environments themselves differ and how to pick one.
## Related Pages
----
-
-
+
Observe A2A delegation task cards and their sub-session panels within a session.
diff --git a/en/ai-sre/apps.mdx b/en/ai-sre/apps.mdx
index 1049e34e..00d00c48 100644
--- a/en/ai-sre/apps.mdx
+++ b/en/ai-sre/apps.mdx
@@ -5,22 +5,16 @@ keywords: ["AI SRE", "Apps", "App", "GitHub", "GitHub App", "GitLab", "GitLab Ap
sidebarTitle: Apps
---
-
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
**Apps** is where you manage **authorized external applications**. Each external application appears as a **card** — you authorize it, manage its installations, and enable / disable or revoke it right from its card.
Apps includes **GitHub**, **GitLab**, and **Kubernetes Apps**. GitHub and GitLab authorize access to code repositories: AI SRE can read code, investigate changes / commits / PRs (MRs on GitLab), and, when asked, fix a bug or open a PR / MR or issue. A Kubernetes App connects a selected Kubernetes cluster to AI SRE and limits the agent to the configured namespaces and permission level.
## Main Scenario: Letting the Cloud Sandbox Reach Your Repositories
----
-
AI SRE sessions run in a **Flashduty cloud sandbox** by default. The sandbox is a clean, isolated, ephemeral environment that **carries none of your git credentials** — which is exactly what an App solves. Once you authorize the GitHub App or the GitLab App, the agent inside the sandbox can clone your repositories, read diffs, and open PRs / MRs, **without you handing it any password or token**; its access is limited to the repositories you granted, with only the least privilege needed to do the work. **This is what both Apps are mainly for.**
@@ -33,8 +27,6 @@ A RUM application can also record the repositories that build it (several may be
## Where to Find It
----
-
Go to **AI SRE → Customize → Plugins → Apps**. The Plugins group in the Customize sidebar lists Overview / Apps / Skill / MCP / Agents in that order, and clicking **Customize** opens **Overview** by default.
@@ -43,8 +35,6 @@ Viewing the Apps page requires the appropriate permission; without it, the entry
## Kubernetes Apps
----
-
A Kubernetes App connects an in-cluster agent to AI SRE. After installation, AI SRE can query cluster information and use the available Kubernetes tools within the namespaces and permission boundaries you configure.
### Create and install
@@ -87,7 +77,7 @@ Operations that differ between levels:
| Modify RBAC within the namespace | No | No | Yes |
| Operate cluster-scoped resources and cluster RBAC | No | No | All namespaces only |
-- **Read-only**: read access within the authorized namespaces is bound directly to Kubernetes' built-in `view` role — FlashDuty no longer maintains its own resource list. It covers Pods, logs, workloads, events, ConfigMaps, and similar resources, but never Secrets; CRDs that cluster components mark as view-readable are included as well. It also grants read-only access to cluster-level nodes, namespaces, persistentvolumes, storageclasses, and ingressclasses.
+- **Read-only**: read access within the authorized namespaces is bound directly to Kubernetes' built-in `view` role — Flashduty no longer maintains its own resource list. It covers Pods, logs, workloads, events, ConfigMaps, and similar resources, but never Secrets; CRDs that cluster components mark as view-readable are included as well. It also grants read-only access to cluster-level nodes, namespaces, persistentvolumes, storageclasses, and ingressclasses.
- **Read + limited modifications**: on top of read-only, this level may evict Pods (`pods/eviction`), scale Deployments and StatefulSets (`deployments/scale`, `statefulsets/scale`), and adjust HPA replica bounds (`horizontalpodautoscalers`). These rules can only change how many replicas a workload runs and rebuild Pods from the same configuration — they cannot change any Pod's image, startup command, environment variables, identity, or mounts. As a result, `kubectl rollout restart` and `kubectl rollout undo` are both denied (in Kubernetes both are patches to the workload); restart a workload by evicting its Pods one at a time. For rollbacks, AI SRE derives the target revision from the ReplicaSet history and gives you the complete `kubectl rollout undo --to-revision=N` command to run in your cluster.
- **Full access**: can read Secrets, modify ConfigMaps and Secrets, modify workload configurations, create or delete resources, and modify RBAC within the namespace; **All namespaces + Full access** additionally grants `cluster-admin` via a `ClusterRoleBinding`, covering cluster-scoped resources and cluster RBAC.
@@ -97,39 +87,31 @@ You can edit the cluster name, scope, and namespace access from the Kubernetes A
## The GitHub App
----
-
The following walks through **GitHub** first — authorization, installation management, and adjusting repository access; **GitLab** follows in the next section.
### Connecting a GitHub Organization
-Start the authorization from the GitHub card. The whole install completes in a popup through GitHub's official install page, and the list refreshes automatically after the callback.
+Authorization happens on GitHub's official install page, opened in a popup.
- Click **Authorize** on the GitHub card (if the App already has an installation, the button reads **More repositories**, with a + icon). The frontend opens a popup that loads GitHub's official install page.
+ Click **Authorize** on the GitHub card (**More repositories** if the App is already installed) and continue on the GitHub install page that pops up.
Choose the **organization** (or personal account) to install into, and grant a repository scope — **All repositories** or **Only select repositories**. The set of granted repositories determines which repositories AI SRE can access afterward.
- After you confirm on GitHub, the popup closes automatically, the Apps page shows **Authorized** and refreshes the installation list, and the new organization appears.
+ After you confirm on GitHub, the popup closes and the new organization appears in the installation list.
-If you are not the owner of the organization, GitHub routes the request to the organization owner through its request-to-install approval flow; the installation activates only after approval. Which organization to install into and which repositories to grant are decided entirely on GitHub's install page — Flashduty does not select on your behalf.
+If you are not an owner of the organization, GitHub sends the request to the organization owner for approval; the installation takes effect once approved.
### Managing Installations
-Each authorized organization adds one installation row under the GitHub card. Each row shows:
-
-| Element | Description |
-|---|---|
-| Organization name | The GitHub organization / account login the installation lives on |
-| Status dot | A colored dot plus a label: **Connected**, **Suspended**, **Revoked** |
-| Repository count | The number of repositories currently granted to this installation |
+Each authorized organization adds a row under the GitHub card, showing the organization name, status (**Connected**, **Suspended**, **Revoked**) and the number of repositories granted.
@@ -154,9 +136,7 @@ The organization is already connected, but you want AI SRE to reach more of its
## The GitLab App
----
-
-The **GitLab** App connects a GitLab instance — **GitLab.com**, **JihuLab** (GitLab's China distribution, SaaS at jihulab.com or a private deployment), or any other **self-managed** instance of your own. The connection method is **exactly the same for all of them**: register an OAuth application on that instance first, then authorize. Once authorized, AI SRE can read code and investigate changes / MRs, and — when you ask — file an issue or open an MR, in the repositories you authorized. Just like GitHub, **you never paste a personal token**: once Flashduty gets an OAuth grant, it provisions a dedicated bot identity for your account to do the actual work.
+The **GitLab** App connects **GitLab.com**, **JihuLab** (jihulab.com SaaS or a private deployment) or any other **self-managed** instance, the same way for all: register an OAuth application on the instance, then authorize. AI SRE can then read code and investigate changes / MRs in the authorized repositories, and file issues or open MRs when you ask. As with GitHub, **you never paste a personal token**; Flashduty provisions a dedicated bot identity for your account.
### Connecting a GitLab Instance
@@ -174,10 +154,9 @@ The **GitLab** App connects a GitLab instance — **GitLab.com**, **JihuLab** (G
The connect wizard shows a **copyable Redirect URI**. Take it to the GitLab instance you entered and create an OAuth application: a group **Owner** does this under **Group Settings → Applications**; on **GitLab.com**, if you're not the Owner of any group, a user-owned application under **User Settings → Applications** also works; an instance admin can also register one under **Admin Area → Applications**. Fill in the Redirect URI the wizard gave you, check **Confidential**, and check only the **api** scope. GitLab then issues an **Application ID** and a **Secret** — paste both back into the wizard.
- This step is the same for **every** GitLab instance — GitLab.com, JihuLab (jihulab.com SaaS or a private deployment), or any other self-managed instance: only the address changes, registering the OAuth application and pasting the Application ID / Secret works identically everywhere.
- This step shows which instance and which OAuth application it's about to authorize with; if you want to use a different application, click **Change OAuth application** to go back and register a different one. Once you confirm, the wizard opens a popup that loads GitLab's official authorization page; sign in with your GitLab account and confirm. The popup closes automatically once authorization completes, and the wizard advances to the next step.
+ Confirm the instance and OAuth application to use (click **Change OAuth application** to switch), then sign in and confirm on the GitLab authorization page that pops up.
AI SRE shows a repository picker listing the **groups where you have the Owner role** and the **projects where you have the Maintainer role**. Select the groups / projects you want AI SRE to access and save — selecting a group covers all of its projects, including ones created later.
@@ -192,7 +171,7 @@ An account can connect **only one** GitLab instance at a time (GitLab.com or one
After you save the repository selection, Flashduty provisions a dedicated bot for the account inside those groups / projects (a service account where the instance supports it, falling back to a group- or project-level access token otherwise) for AI SRE sessions to use. Either way, the bot's permissions are capped at **Developer** level — the same minimum access you'd grant it in GitLab yourself. Tokens are **rotated automatically** before they expire; there's nothing for you to manage.
-If the instance doesn't support service accounts, the bot falls back to a group- or project-level token — and a token like that can only ever bind to a single group or project, so the repository picker limits you to selecting at most **one** group or project. If you select multiple groups / projects while in multi-select mode and save, Flashduty shows "This GitLab instance doesn't support service accounts; select only one group or project and retry," and switches the picker to **single-select mode**: checking a new group or project after that automatically clears any other selection, so you need to leave just one group or project checked before saving again.
+If the instance does not support service accounts, the bot uses a group- or project-level token instead, and you can select only **one** group or project.
**One restriction on GitLab.com**: GitLab's own policy limits group- and project-level access tokens to **paid (non-free, non-trial) namespaces**. Connecting GitLab.com itself is unaffected, but if the group / project you authorize lives in a free or trial namespace, bot provisioning fails and the UI shows GitLab's own explanation ("provisioning_denied"). Upgrade that namespace to a paid plan and re-authorize to resolve it.
@@ -213,8 +192,6 @@ The GitLab card shows the connected instance's address and status.
## How AI SRE Works Inside a Repository
----
-
After authorization, you need no extra configuration. When you ask AI SRE to work on a task in a repository during a session, it works like an engineer joining the project — understand first, then change, then verify. This behavior is governed by the built-in `github` Skill and `gitlab` Skill respectively.
**Typical actions**
@@ -235,21 +212,17 @@ If the agent reports it cannot access a repository in a cloud session, it usuall
## Permissions & Scope
----
-
-**Authorize** and **revoke / disconnect** are **account-level** operations for both the GitHub App and the GitLab App. **The account is the only security boundary**; the team here is just an ownership / audit tag: any account member with the corresponding permission can authorize, revoke / disconnect, or enable / disable the whole App; when a session needs a repository, it obtains access from the account's currently active installation. Members of an account share one authorization — consistent with AI SRE's "usage = account-level, ownership = team tag" model for other resources.
+Authorizing and revoking / disconnecting the GitHub App and GitLab App are **account-level** operations: any member with the relevant permission can do them, members share one authorization, and sessions access repositories through the account's currently active installation. Teams are only an ownership tag; **the account is the only security boundary**.
The two Apps' scope models differ slightly: the **GitHub App** lets the same account install multiple organizations, each enabled / revoked independently; the **GitLab App** lets an account connect **only one** GitLab instance **at a time** — switching to a different instance requires disconnecting the current one first.
## Related Pages
----
-
Connect external tools and data sources via the Model Context Protocol.
-
+
Watch the agent clone a repo, read a diff, and open a PR / MR during a session.
diff --git a/en/ai-sre/artifacts.mdx b/en/ai-sre/artifacts.mdx
index 0b732859..336d6b36 100644
--- a/en/ai-sre/artifacts.mdx
+++ b/en/ai-sre/artifacts.mdx
@@ -5,152 +5,92 @@ keywords: ["AI SRE", "Artifacts", "present_files", "publish_artifact", "insight
sidebarTitle: Artifacts
---
-
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
An artifact is a file AI SRE produces in a session with the `present_files` tool and then publishes to the artifact gallery. There are two publish paths, and they accept different types:
- **The agent's `publish_artifact` tool**: publishes HTML / Markdown documents only (`.html` `.htm` `.md` `.markdown`) — a self-contained report or page, most typically the operational insight report generated by typing `/insight` in a session. Every other type is rejected with `unsupported_format`.
- **The "Publish to artifact gallery" button next to a `present_files` file in the console** (see [Creating an artifact](#creating-an-artifact) below): publishes the wider set of types:
-| Category | Common extensions |
-|---|---|
-| Web pages & documents | `.html` `.htm` `.md` `.markdown` `.txt` `.log` |
-| Data & config | `.csv` `.tsv` `.json` `.yaml` `.yml` `.xml` `.toml` `.ini` |
-| Images | `.png` `.jpg` `.jpeg` `.gif` `.svg` `.webp` |
-| PDF | `.pdf` |
-| Source code | `.py` `.go` `.js` `.mjs` `.ts` `.jsx` `.tsx` `.java` `.c` `.h` `.cpp` `.cs` `.rb` `.rs` `.php` `.sh` `.sql` `.kt` `.swift` `.scala` `.css` `.vue` `.svelte` `.proto` `.tf` `.hcl`, and more |
-| Archives | `.zip` `.tar` `.gz` `.tgz` |
+
+
+ | Category | Common extensions |
+ |---|---|
+ | Web pages & documents | `.html` `.htm` `.md` `.markdown` `.txt` `.log` |
+ | Data & config | `.csv` `.tsv` `.json` `.yaml` `.yml` `.xml` `.toml` `.ini` |
+ | Images | `.png` `.jpg` `.jpeg` `.gif` `.svg` `.webp` |
+ | PDF | `.pdf` |
+ | Source code | `.py` `.go` `.js` `.mjs` `.ts` `.jsx` `.tsx` `.java` `.c` `.h` `.cpp` `.cs` `.rb` `.rs` `.php` `.sh` `.sql` `.kt` `.swift` `.scala` `.css` `.vue` `.svelte` `.proto` `.tf` `.hcl`, and more |
+ | Archives | `.zip` `.tar` `.gz` `.tgz` |
+
+
Files outside the table above don't show a "Publish to artifact gallery" button in the session.
A published artifact initially inherits its source session's scope: artifacts from a personal session belong to their creator ("Personal"); artifacts from a session bound to a team belong to that team and can be shared with other account members. Users with edit permission can change the scope later.
-Entry point: **AI SRE → Artifacts** in the left navigation, route `/ai-sre/artifacts`.
+Entry point: **AI SRE → Artifacts** in the left navigation.
-The artifact gallery has no entry point for manually uploading or creating files — every artifact is produced and published by the agent using tools during a session. The console only lets you browse, search, and manage artifacts that already exist.
+You can't upload files to the artifact gallery directly: every artifact is produced and published by the agent in a session, and **New artifact** also takes you to a session to do this. The gallery is for browsing, searching, and managing published artifacts.
## List Page
----
-
-### Search and scope filter
-
-- **Search box**: fuzzy-search published artifacts by title; the query fires automatically 300ms after you stop typing.
-- **Scope**: a three-way **All / Personal / Team** switch (the same two-level scope shared with the other resources under AI SRE). Selecting "Team" expands a searchable, multi-select team picker; selecting no team means "all teams visible to me."
-
-### View toggle and sorting
+- **Search and filter**: search by title; filter by scope (**All / Personal / Team**). Choosing "Team" lets you pick specific teams; picking none means all teams visible to you.
+- **Views**: switch between card view (default) and list view at the top right; your choice is saved in the browser. List view shows the name, scope (team name, or the creator for personal artifacts), source conversation (click to jump; "Conversation deleted" if it no longer exists), created and updated times, a pin button, and actions.
+- **Sorting**: sort by created or updated time; the default is **updated time, newest first**. Whatever the sort, the artifacts you pinned always come first (most recently pinned first).
+- **Paging**: 12 / 24 / 48 per page, 24 by default.
+- **Shareable URL**: scope, search term, sorting, and page are kept in the page URL, so copying it shares or bookmarks the filtered list, and returning from a detail page lands you where you were.
-The top-right of the list page offers a **Card view / List view** toggle; your choice is persisted in the browser (card view is the default).
-
-**List view** presents artifacts in a table with these columns:
-
-| Column | Description |
-|---|---|
-| Name | Artifact title; click to open the detail page |
-| Scope | Team name for team artifacts, creator name for personal artifacts |
-| From conversation | Title of the source conversation; click to jump to it. Shows plain text "Conversation deleted" when the source conversation was deleted or has no title |
-| Created at | Artifact creation time |
-| Updated at | Artifact last-updated time |
-| Pin | An icon-only button (the column has no header); click it to pin or unpin the artifact for yourself — see [Pinning](#pinning) below |
-| Actions | Rename, download, delete, etc. |
-
-The **Created at** and **Updated at** columns support header sorting (ascending / descending toggle); sorting is executed server-side, with **Updated at descending** as the default.
-
-Whichever sort you pick, **the artifacts you pinned always come first** (most recently pinned first), and the chosen sort orders the rest.
-
-Scope, search term, sorting, page number, and page size are all reflected in the page URL (for example `?scope=team&teams=1,2&q=rebuild&page=2&size=48`), so copying the address shares or bookmarks a **filtered** list; returning from an artifact's detail page also lands back on the same filters and position instead of resetting to the default view.
-
-Page size can be **12 / 24 / 48**, defaulting to **24** (the URL's `?size=`; a value equal to the default is not written to the address). If the address is hand-edited to some other number, the nearest option is used rather than the literal value.
-
-### Artifact cards
-
-Each card shows:
-
-- A preview area rendering a **thumbnail of the artifact's own content**: HTML takes the head of the file (up to 256 KiB) and scales a desktop page laid out at 1200×630 into the box, Markdown is typeset onto that same scaled page, images show the image itself, and plain text shows its first 24 lines (up to 1400 characters). PDF and every other non-renderable kind show an empty frame. The thumbnail is a non-interactive still image — it renders inside a `sandbox=''` frame, so scripts don't run and links and buttons don't respond. It is also lazy: nothing is signed or downloaded until the card comes near the viewport (about 400px), and an empty skeleton frame shows until then;
-- The kind icon: determined by file extension and content type — images, PDF, HTML, Markdown, tables (CSV / TSV), JSON, archives, and source code each get a dedicated icon, falling back to a generic file icon when the type can't be recognized. It is a 30×30 badge straddling the divider between thumbnail and body, rather than filling the preview area;
-- The title (single line, truncated beyond that; hover to see the full title);
-- A single **Edited …** relative timestamp in the grey caption line under the title (the artifact's last update time; for an artifact never updated after creation, the update time is its creation time) — just now / N minutes ago / N hours ago / N days ago. Relative time is used at any age: an older artifact still shows "Nd ago" instead of falling back to a concrete date. Hover the timestamp for the exact time down to the minute, and note that the **Created at** / **Updated at** columns of the list view give exact times directly;
-- The same caption line also carries the scope (a small icon plus a name: team artifacts show the team name, personal artifacts show the creator's name) — cards no longer use coloured scope badges; badges appear only in the list view and on the detail page. When the artifact has a live public link, the caption line leads with a small globe glyph that has a tooltip; a pinned artifact shows a pin glyph at the end of the caption line.
-
-Clicking the card body opens the artifact's detail page. Hovering over a card reveals a "More actions" button in the top-right corner (always visible on touch devices), with an equally hover-only pin button beside it — one click pins or unpins. The public-link preview inside the share panel uses this same thumbnail.
+Cards show a content thumbnail (a static preview for HTML, Markdown, images, and plain text; an empty frame for PDFs and other types), a type icon, the title, the edited time (hover for the exact time), the scope, and whether a public link is on and whether it is pinned.
### Pinning
-Every list row and every card has a pin button — on a card it sits in the top-right corner next to "More actions" and appears on hover (always visible on touch devices); in the list it is a fixed-width column of its own, between "Updated at" and the action buttons. The first item in the "More actions" menu is the same toggle, labelled "Pin" or "Unpin" according to the current state.
-
-Pinning is **a personal preference, not an edit**:
+Click the pin button on a row or card, or choose **Pin** / **Unpin** from the **More actions** menu.
-- You can pin any artifact you can see — other people's personal artifacts and team artifacts included — with **no edit permission required** (rename, change scope, and delete do require it);
-- A pin only floats the artifact to the top of **your own** gallery. It does not change the artifact's content, title, or scope, and it does not affect the order anyone else sees;
-- Pinning and unpinning are both idempotent: re-pinning only refreshes the pin time (a later pin time sorts higher), and unpinning an artifact that was never pinned does not fail;
-- Pinning refetches the whole page. The server owns the ordering, so pinning an artifact on page 2 moves it to page 1 rather than reordering in place.
-
-The `pinned_at` field on a gallery list item is **the calling person's own** pin time (unix milliseconds); it is absent when the artifact is not pinned — so the same artifact can carry a different `pinned_at` for each member.
+Pinning is **your personal preference, not an edit**: you can pin any artifact you can see (including other people's personal artifacts and team artifacts) with **no edit permission**. It only floats the artifact to the top of your own gallery; it doesn't change the artifact or the order anyone else sees. Pinning an artifact on page 2 moves it to page 1.
### Creating an artifact
-Click **New artifact** in the upper-right corner of the page to jump to the chat page with a prefilled draft prompt:
-
-> I want to build a publishable Artifact in Flashduty AI-SRE: a self-contained web page or report, published to the artifact gallery when done. Ask me a few focused questions about the audience, content/data, interactions, and visual style, then build it and publish it.
-
-The agent first asks you about the target audience, content/data source, interactions, and visual style, then builds and publishes the artifact — there is no form to fill out directly.
+Click **New artifact** at the top right to open a chat with a prefilled draft prompt. The agent first asks about the target audience, content/data source, interactions, and visual style, then builds and publishes the artifact — there is no form to fill out.
-Separately, any file shown in a session with `present_files` also has a "Publish to artifact gallery" button next to it, letting you publish a file that session already produced directly as an artifact — a more direct path than "New artifact" when you don't need a fresh conversation.
+If a session has already produced the file, click "Publish to artifact gallery" next to it instead — it's faster than starting a new conversation.
## Card Actions
----
-
The "More actions" menu on each card offers:
| Action | Notes |
|---|---|
-| Pin / Unpin | The menu's first item, labelled "Pin" (when not pinned) or "Unpin". Pinning is a **personal preference** and skips the edit-permission check entirely — you can pin any artifact you can see, and it only changes the order of your own list without modifying the artifact (see [Pinning](#pinning) above) |
-| Copy link | Copies the full URL of the artifact's detail page, which you can share with other account members |
-| Download | Only appears when the artifact is linked to a file (`file_id` is non-empty); downloads the original file |
-| Rename | Only appears when you have edit permission on the artifact; opens a dialog to change the title |
-| Change scope | Only appears when you have edit permission; choose Personal or an accessible team. Only the artifact creator can change the scope to Personal |
-| Delete | Only appears when you have edit permission on the artifact; requires confirmation. Deleting removes the artifact from the gallery, but the source session and underlying file are unaffected |
+| Pin / Unpin | Changes only your own list order; no edit permission needed. See [Pinning](#pinning) |
+| Copy link | Copies the link to the artifact's detail page to share with other account members |
+| Download | Shown when the artifact has a linked file; downloads the original file |
+| Rename | Requires edit permission |
+| Change scope | Requires edit permission; choose Personal or an accessible team. Only the creator can change it back to Personal |
+| Delete | Requires edit permission and confirmation. Removes the artifact from the gallery only; the source session and the file itself are kept |
## Detail Page
----
-
-The detail page route is `/ai-sre/artifacts/:artifactId`. The top toolbar offers:
-
-- **Title**: if you have edit permission, click the title to edit it inline (no separate form) — press Enter to save, Esc to cancel;
-- **Creator**: shown below the title as "Artifact by [creator]";
-- **Share**: opens the share panel, where you can choose between "Account only" and "Public link" visibility — see [Share an artifact](#share-an-artifact) below;
-- **Delete**: shown only when you have edit permission; requires confirmation;
-- **More actions**: this menu appears only when at least one of the following is available —
- - **Download**: shown when the artifact is linked to a file.
- - **Change scope**: shown when you have edit permission. You can move the artifact to an accessible team; the creator can also change it back to Personal.
+The top of the detail page offers:
-Below the title there is a **source-session strip**:
+- **Title**: with edit permission, click the title to edit it — Enter saves, Esc cancels. The creator is shown below the title;
+- **Share**: choose "Account only" or "Public link" — see [Share an artifact](#share-an-artifact) below;
+- **Delete** and **Change scope** (edit permission required) and **Download** (when there is a linked file);
+- **Source session**: the edited time and "Recently updated from session 〈session name〉", which opens the source session's full conversation. It is hidden if the session was deleted or you lack access; the artifact itself stays viewable.
-- It shows the artifact's own **"Edited …"** relative timestamp (like the list cards; hover it for the exact time down to the minute);
-- When you still have access to the artifact's source session, the strip also shows a **"Recently updated from session 〈session name〉"** button — the session name is resolved from the source session via `/safari/session/get`, and clicking it opens that session's full conversation (`chat?session_id=`, messages, tool calls, artifact history). If the source session was deleted or you no longer have access, the button is hidden and the artifact itself remains fully viewable.
-
-The body renders the artifact according to its actual content type (for example, an HTML report renders inline as a page).
+The body renders according to the artifact's content type (for example, an HTML report renders inline as a page).
-On a phone the detail page degrades to a **read-only reader**: the title is no longer editable inline, the share, change-scope, and delete entries are all hidden, and the toolbar drops the back-to-list button, the file-kind icon, the scope badge, the public-link badge, the "Edited …" time, and the "Recently updated from session" entry, keeping only the title and the artifact body. When the artifact is linked to a file, **Download** remains available under "More actions". The list page and card view are unaffected.
+On a phone, the detail page is a **read-only reader**: only the title and body are shown, with no editing, sharing, scope changes, or deletion. When the artifact has a linked file, **Download** is still available under "More actions".
## Share an artifact
----
-
The **Share** button in the detail page toolbar opens the share panel. **Manage permission** at the top lists who can manage sharing for this artifact (the creator is labeled "Owner"; team artifacts also list team members). **Visibility** below offers two modes:
| Mode | Who can open it | Content |
@@ -168,13 +108,13 @@ After you choose **Public link**, the panel first shows a content preview and a
Once you generate a public link, anyone who gets the link can view this artifact, and the link can be forwarded further. Don't share secrets, personal information, or unauthorized third-party content.
-On success, the link is copied to your clipboard automatically (a "Public link generated and copied to clipboard" toast appears). The public link takes the form `https:///share/artifact/` — it's identified by the artifact's own ID and carries no token; anonymous access is served entirely by the CDN, without going through any endpoint that requires sign-in.
+The link is copied to your clipboard automatically. Public links take the form `https:///share/artifact/`; they contain no token, so anyone with the link can open it.
On private deployments, public links require the instance to be configured with a reachable share static-asset base (CDN). When it is not configured, the share panel does not offer the **Public link** option and only "Account only" sharing is available; public links generated earlier remain manageable and revocable. SaaS is not affected by this restriction.
-Visitors who open a public link see a read-only content page: next to the title, the top of the page carries the disclaimer "**Content is user-generated and unverified.**" and a "**Feedback**" entry — clicking it opens a report form (pre-filled with the current link) so anyone can report inappropriate content to Flashduty. The page also provides a "Sign in" entry that leads visitors to the console.
+Visitors see a read-only page marked "Content is user-generated and unverified." next to the title, with **Feedback** (to report inappropriate content) and **Sign in** entries.
| Action | Description |
|---|---|
@@ -188,50 +128,43 @@ Artifacts larger than **16 MiB** can't generate a public link — you'll see a n
## Update a published artifact
----
+Publishing the same file again does **not** silently overwrite a published artifact. When the agent updates an artifact, it must say which artifact it is updating and which version it based the change on. If someone changed the artifact in the meantime, the agent reads the currently published content and merges before retrying, instead of overwriting it. The link and artifact ID stay the same after an update.
-Republishing the same file does **not** silently overwrite a published artifact. When the agent updates one with `publish_artifact`, it must pass both the artifact's `artifact_id` and the `if_revision` returned by the previous publication (an opaque revision fingerprint shaped like `rev_…`):
+A few more details:
-| Case | Result envelope | Outcome |
-|---|---|---|
-| `artifact_id` and `if_revision` both match | `status: published`, with an `operation` (`created` / `updated` / `unchanged`) and a new `revision` | The artifact is updated in place (an `unchanged` operation means the content did not change); the link and artifact ID stay the same |
-| Only a file path was given (no `artifact_id`) and the content differs from the published version | `status: needs_review`, `reason: explicit_artifact_id_required` | Nothing is published |
-| `artifact_id` was given but `if_revision` was not | `status: needs_review`, `reason: revision_required` | Nothing is published |
-| `if_revision` does not match the current revision (the artifact changed after you got the revision) | `status: needs_review`, `reason: revision_conflict` | Nothing is published |
+- If the content hasn't changed, the artifact is left alone.
+- Showing the same file again in a session does **not** update the published artifact; ask the agent to publish again.
+- The agent will not revive a deleted artifact by republishing it; only clicking "Publish to artifact gallery" next to the file in a session restores a deleted artifact.
-On `needs_review`, the agent also writes a copy of the **currently published content** into the session workspace along with the current `revision`; it reads that copy, merges deliberately, and retries with the same `artifact_id` and the new `revision` instead of overwriting blindly.
+
+When the agent updates an artifact with `publish_artifact`, it must pass both the `artifact_id` and the `if_revision` returned by the previous publication (a revision fingerprint shaped like `rev_…`):
-A few more details:
+| Case | Result envelope | Outcome |
+|---|---|---|
+| `artifact_id` and `if_revision` both match | `status: published`, with an `operation` (`created` / `updated` / `unchanged`) and a new `revision` | Updated in place |
+| Only a file path was given, and the content differs from the published version | `status: needs_review`, `reason: explicit_artifact_id_required` | Nothing published |
+| `artifact_id` given without `if_revision` | `status: needs_review`, `reason: revision_required` | Nothing published |
+| `if_revision` doesn't match the current revision | `status: needs_review`, `reason: revision_conflict` | Nothing published |
-- When the content is byte-identical to the published version, the result is `operation: unchanged` and the artifact is left alone.
-- Re-presenting the same file with `present_files` does **not** update a published artifact — it only offers preview and download; publishing an update goes through `publish_artifact`.
-- If the artifact was deleted, a path-based republish fails with `artifact_deleted` instead of reviving it; only the "Publish to artifact gallery" button next to the `present_files` file in a session restores a deleted artifact.
-- Failures come back with a code: `unsupported_format` / `permission_denied` / `artifact_deleted` / `storage_unavailable` / `file_too_large` / `invalid_path`, of which `storage_unavailable` is retryable. When the commit cannot be confirmed the tool returns `status: unknown` with an `op_…` operation ID, and the agent does not create a second artifact.
+On `needs_review`, a copy of the currently published content and the current `revision` are written to the session workspace. Failures return a code: `unsupported_format` / `permission_denied` / `artifact_deleted` / `storage_unavailable` (retryable) / `file_too_large` / `invalid_path`. When the commit can't be confirmed, the tool returns `status: unknown` with an `op_…` operation ID, and the agent does not create a second artifact.
+
## Permissions
----
-
-Whether an artifact is editable (rename, change scope, delete) is determined by the `can_edit` field returned by the backend. Any one of the following grants management access:
+Any one of the following lets you rename, change the scope of, or delete an artifact:
| Condition | Notes |
|---|---|
| Creator | The owner of the session the artifact was published from |
-| Account Owner / admin | Has management access to any artifact in the account, personal or team scope |
-| Team member (team artifacts only) | When an artifact belongs to a team (`team_id > 0`), other members of that team can also manage it |
+| Account Owner / admin | Any artifact in the account, including other members' personal artifacts (unlike automation rules) |
+| Team member | Members of the team that owns a team artifact |
-Artifacts you cannot edit only expose read-only actions such as "Pin", "Copy link", and "Download" — the "Rename" and "Delete" buttons do not appear. **Pinning is not part of that check**: it is a personal preference rather than an edit, so you can pin any artifact you can see (other members' personal artifacts included), and it only changes your own list order, affecting nobody else.
-
-
-This differs from the automation rule permission model: the account Owner / admins have management access to **any** artifact, including other members' personal artifacts — there is no "no exemption for personal resources" restriction here.
-
+Without edit permission you can only pin, copy the link, and download.
## Related Pages
----
-
-
+
Learn how sessions surface files with the present_files tool — the source of every published artifact.
diff --git a/en/ai-sre/automations.mdx b/en/ai-sre/automations.mdx
index 47339646..3dd98052 100644
--- a/en/ai-sre/automations.mdx
+++ b/en/ai-sre/automations.mdx
@@ -5,14 +5,10 @@ keywords: ["AI SRE", "Automation", "inspection", "scheduled task", "cron", "HTTP
sidebarTitle: Automations
---
-
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
An automation lets AI SRE run a **hidden session** on a cadence you set. The session does not appear in the session list in the left sidebar of the console; instead it runs in the background, driven by a fixed **task prompt**, to have the agent complete its work and produce results such as routine inspections, operational insights, or incident post-mortems.
Each automation is a **rule**. A rule carries at least one trigger:
@@ -31,16 +27,14 @@ Every run produced by an automation is, at its core, still an AI SRE session —
## Creating an Automation
----
-
-The page header offers two creation entry points: an outline-style **Create via chat** button that jumps to the chat page with a prefilled prompt — "Let's create an automation task. First explain how automation tasks work. Then ask me questions to figure out what task I need to schedule and when it should run." — letting the agent work out the task content and trigger through conversation, skipping the form; and a primary-style **Create** button that opens a start panel with two entry points:
+The page header offers two ways to create: **Create via chat** opens a session with a prefilled prompt, where the agent asks questions to work out the task and when it should run, with no form to fill in; **Create** opens a start panel with two entry points:
Choose **Start from scratch** to open a blank form and manually fill in the name, task prompt, and triggers. This suits cases where you already know what you want the agent to do and want a fully custom prompt.
- Below, a set of **preset template** cards is listed (delivered by the backend per UI language: `zh-CN` for Chinese, `en-US` for English). Common ones include **Weekly On-call Review**, **Alert Governance**, **On-call Incident Analysis**, and **On-call Load Analysis**. Click any template card to prefill the form with the template's name and task prompt; tweak from there.
+ Below, a set of **preset template** cards is listed (shown in Chinese or English to match the UI language). Common ones include **Weekly On-call Review**, **Alert Governance**, **On-call Incident Analysis**, and **On-call Load Analysis**. Click any template card to prefill the form with the template's name and task prompt; tweak from there.
@@ -48,26 +42,22 @@ Either entry point leads to the same configuration form.
## Configuration Fields
----
-
The configuration form has the following fields:
| Field | Required | Notes |
|---|---|---|
| Name | Yes | The rule name, up to 255 characters. Placeholder example: `Weekly on-call insights`. |
| Scope | Yes | Use the **scope selector** to choose **Personal** (`team_id=0`) or a **Team** (`team_id>0`). Scope determines both the rule's ownership and edit permissions, and constrains the self-hosted Runners selectable in **Environment** — only account-global Runners and Runners belonging to the same team as the scope are selectable. |
-| Environment | No | Use the **environment picker** to choose the runtime environment: **Auto** (the backend picks the best available environment, the default), **Cloud Sandbox**, or a **self-hosted (BYOC) Runner**. After picking a team scope, a team Runner that does not belong to that scope is cleared automatically. |
+| Environment | No | Use the **environment picker** to choose the runtime environment: **Auto** (the system picks the best available environment, the default), **Cloud Sandbox**, or a **self-hosted (BYOC) Runner**. After picking a team scope, a team Runner that does not belong to that scope is cleared automatically. |
| Task prompt | Yes | Describe the task for AI SRE to perform, written in a rich-text editor. This prompt is exactly what is sent to the agent on each run. Placeholder: `Describe the task for Flashduty AI SRE to perform.` |
| Time zone | No | A field on the **Schedule** trigger card (see "Schedule (cron)" below): the **rule time zone** the cron expression is read in. Pick an IANA zone name (for example `Asia/Shanghai`) from a searchable dropdown; the options are ordered by their UTC offset. On create it defaults to your effective time zone (member time zone first, falling back to the account time zone); when no zone is available the field is left empty and the create request omits it. |
-For **Environment**, "Auto" has the backend pick the best available environment at each run; "Cloud Sandbox" is a platform-managed ephemeral sandbox; a self-hosted Runner runs on your own machine. See Environments for the differences and how to connect them.
+For **Environment**, "Auto" has the system pick the best available environment at each run; "Cloud Sandbox" is a platform-managed ephemeral sandbox; a self-hosted Runner runs on your own machine. See Environments for the differences and how to connect them.
## Triggers
----
-
A rule must have **at least one trigger** configured. The current console form exposes **Schedule**, **Call via API**, and **On-call incident** in the "Triggers" section, and all three can be enabled at the same time.
### Schedule (cron)
@@ -97,7 +87,7 @@ To avoid hand-writing the expression, the UI offers four modes:
| Custom | Type a 4-field or 5-field cron expression directly |
-**Time zone**: a **Schedule** run is read against the cron's **rule time zone** — pick it from the **Time zone** dropdown on the trigger card. All four modes (**Hourly / Daily / Weekly / Custom**) share that one field; there is no split between "this mode uses your local zone, that one uses UTC". Saving stores the IANA zone you picked as-is, no longer converting the hour and minute to UTC, and the cadence summary no longer carries a time zone label beside it.
+**Time zone**: **Schedule** runs use the **Time zone** chosen on the trigger card; all four modes (**Hourly / Daily / Weekly / Custom**) share this setting.
@@ -164,7 +154,7 @@ Add the **On-call incident** trigger when you want AI SRE to start automatically
Select one or more severities from `Critical`, `Warning`, and `Info`. When this trigger is enabled, at least one channel and one severity are required.
- **Merge similar incidents into one analysis** is on by default: a new incident from this rule is first compared with the incidents being analysed now (or analysed within the last 10 minutes), and one scoring at least 0.9 joins that analysis instead of starting a session of its own; with it off, every incident is analysed separately. See "Merging similar incidents into one analysis" below.
+ **Merge similar incidents into one analysis** is on by default: a new incident that is similar enough to one already being analysed joins that analysis instead of starting its own session; with it off, every incident is analysed separately. See [Merging similar incidents into one analysis](#merging-similar-incidents-into-one-analysis) for the rules.
@@ -204,15 +194,13 @@ The similarity comparison depends on the account's AIOps capability and on a Pro
## Run History
----
-
-Every rule keeps its run history. Clicking anywhere on the rule row (there is no dedicated history icon) opens the rule's detail page at `/ai-sre/automations/:ruleId`: the left column shows "Configuration" and the right column shows "Run History", side by side. The right column has its own **Run now** button at the top, so you can trigger a run directly from the detail page.
+Every rule keeps its run history. Click a rule row to open its detail page (`/ai-sre/automations/:ruleId`): the left column shows **Configuration** and the right column shows **Run History**; the **Run now** button at the top of the right column triggers a run directly.
Run history is shown as a table with these columns:
| Column | Notes |
|---|---|
-| Name | The hidden session behind this run. The backend batch-resolves each run's session title (`session_name`, the hidden session's auto-generated name); when it can't be resolved, the cell falls back to the session ID (`session_id`). A run merged into another analysis (see "Merging similar incidents into one analysis" above) has no session of its own, so this column shows the incident it is about (`# `) and names, on the line below, the analysis it joined |
+| Name | The title of the run's hidden session (`session_name`), or the session ID (`session_id`) if it can't be resolved. A run merged into another analysis has no session of its own, so this shows its incident (`#<num> <title>`) and, on the line below, the analysis it joined |
| Started at | The start time of the run |
| Duration | How long the run took |
| Triggers | The trigger type of the run, such as `Schedule`, `HTTP POST`, `On-call incident`, or `Run manually` |
@@ -239,32 +227,29 @@ Three filters are available above the table:
Run records returned by the API also include `trigger_kind`, which can be `schedule`, `manual`, `http_post`, `oncall_incident`, or `debug`. `manual` means the run was started through the run-now API, and `oncall_incident` means it was started by a matching On-call incident event. A run merged into another analysis carries no `session_id` of its own: it carries that analysis's session ID in `joined_session_id` and its session name in `joined_session_name`, and both being empty means the run has a hidden session of its own.
-Click a row to jump to the chat page of the hidden session for that run (`chat?session_id=<sessionID>`), where you can view the full messages, tool calls, and artifacts of that run. A run merged into another analysis has no session of its own, so clicking it opens the analysis that took over the incident.
+Click a row to jump to the chat page of the hidden session for that run, where you can view the full messages, tool calls, and artifacts of that run. A run merged into another analysis has no session of its own, so clicking it opens the analysis that took over the incident.
### The reason line on an unsuccessful run
-When a run's status is `failed`, `blocked`, `abandoned`, or `skipped`, the **Name** cell shows one extra line under the session name: the **reason** — clamped to one line, with the full text on hover. If the run has no session name to show, the reason takes the cell instead. The reason line sometimes carries a link beside it, which opens in a new tab.
+When a run's status is `failed`, `blocked`, `abandoned` or `skipped`, the **Name** column shows the **reason** under the session name (hover for the full text). Common reasons:
-Reasons the platform itself decides on have fixed wording:
+| Reason (`error_code`) | What to do |
+|---|---|
+| AI SRE is not enabled, or this period's credits or balance are used up; the run did not execute (`BalanceNotEnough`) | Enable or top up on the AI SRE tab of **Payment → Plan** |
+| The On-call subscription has expired or its plan does not include AI SRE; AI SRE is paused (`NoLicense`) | Renew or upgrade on the On-call tab of **Payment → Plan** |
+| The run did not finish in time and was abandoned (`task_run_stale`) | — |
+| The run was interrupted (`interrupted`) | — |
+| The run ended without a final reply (`no_final_response`) | — |
+| Joined another analysis (`similar_incident_fan_in`) | Click the row to open the analysis that took over the incident |
-| `error_code` | Reason shown | Link |
-|---|---|---|
-| `BalanceNotEnough` | AI SRE is not enabled, or this period's credits or balance are used up. This run did not execute. | Go to AI SRE billing (`/wallet/plan?product=ai-sre`) |
-| `NoLicense` | The On-call subscription has expired or its plan does not include AI SRE. AI SRE is paused. | Go to On-Call subscription (`/wallet/plan?product=oncall`) |
-| `task_run_stale` | The run did not finish in time and was abandoned. | None |
-| `interrupted` | This run was interrupted. | None |
-| `no_final_response` | The run ended without a final reply. | None |
-| `similar_incident_fan_in` | Joined “`<analysis name>`”; shows “another analysis” when the name cannot be resolved | None |
-| Any other `error_code` | The reason text recorded by the backend, shown as is; if there is none, the `error_code` itself | None |
+Other reasons show the text recorded by the system.
<Note>
-Run history is embedded in the rule's detail page, and opening the detail page itself already requires edit permission on that rule — a rule you cannot edit cannot be opened at all (it shows "Automation rule not found or access denied"), so its run history is likewise unreachable.
+Run history is shown on the rule's detail page, so viewing it requires edit permission on the rule.
</Note>
## Management and Permissions
----
-
### Enable / Disable, Edit, and Delete
Each rule offers a set of actions in the **Actions** column:
@@ -276,7 +261,7 @@ Each rule offers a set of actions in the **Actions** column:
Clicking anywhere on the rule row opens its detail page, where you can edit the configuration, delete the rule, and view its run history (see "Run History" above).
-For read-only rules you **cannot edit** (`can_edit=false`), the switch and all action buttons are disabled; opening its form shows "Read-only — you can view this automation but cannot edit it." at the top.
+Rules you **cannot edit** are view-only: you cannot toggle them or use their actions.
Above the list there are also two filters: **Scope** (All / Personal / Team, where selecting "Team" lets you multi-select specific teams) and **Status** (All statuses / Enabled / Disabled).
@@ -286,10 +271,10 @@ Automation rules share the same two-level scope model as the other resources und
| Dimension | Rule |
|---|---|
-| Ownership | **Personal rules** (`team_id=0`) belong to their creator; **team rules** (`team_id>0`) belong to that team. **Scope is fixed at creation and cannot be changed afterward**: when editing a rule, the scope selector is disabled with the hint "Scope can't be changed after creation. To use a different one, clone this automation and pick a new scope for the copy." To switch scopes, use the **Clone** button on the rule's detail page — cloning opens a prefilled create form where you pick the new scope for the copy before saving (the update API no longer accepts `team_id`, so the scope cannot be changed even by bypassing the UI). To create a team rule, the **operator themselves** must be a real member of the target team (join-to-govern); account Owners and admins have no exemption. A team rule does not stop with its creator: even after the creator has left the team, the team carries on running the rule. Only personal rules are disabled when their Owner is no longer an active account member — the system disables the rule automatically once a trigger attempt's preflight finds the Owner inactive. |
+| Ownership | **Personal rules** belong to their creator; **team rules** belong to that team. **Scope cannot be changed after creation**; to use a different scope, click **Clone** on the rule's detail page and pick a new scope for the copy. To create a team rule, the operator must be a member of that team; account Owners and admins are no exception. A team rule keeps running after its creator leaves the team; a personal rule is disabled automatically once its creator is no longer an active account member. |
| Visibility / list | The account Owner and admins see all rules; ordinary members see rules they created and rules of teams they belong to. |
| Edit / manage (team rules) | Only **current members** of the rule's owning team can act on the rule (enable / disable, edit, delete, run now); once the creator has left the team, they keep no standing privilege. The account Owner and admins have no exemption and must join the team first. |
-| Edit / manage (personal rules) | Only the creator can manage a personal rule. The account Owner and admins have **no** exemption for other members' personal rules — they cannot even view its detail page; opening one returns "access denied" outright, not just a grayed-out button. |
+| Edit / manage (personal rules) | Only the creator can view and manage a personal rule. Account Owners and admins cannot view or manage other members' personal rules. |
| HTTP POST trigger | When initiating a real run through the trigger URL, authorization is only the trigger's Bearer Token. Any external system holding that Token can trigger the rule, and the run creates a hidden session under the rule's personal or team scope. |
| On-call incident trigger | Started by a registered incident subscription, not by an HTTP POST Bearer token. The run still creates a hidden session under the rule's personal or team scope. |
@@ -303,10 +288,8 @@ The account is the only security perimeter at runtime; the team is an ownership
## Related Pages
----
-
<CardGroup cols={2}>
- <Card title="Console" icon="comments" href="/en/ai-sre/sessions">
+ <Card title="Console Chat" icon="comments" href="/en/ai-sre/sessions">
Learn how a session holds one complete conversation — every run produced by an automation is, at its core, a hidden session.
</Card>
<Card title="Environments" icon="server" href="/en/ai-sre/environments">
diff --git a/en/ai-sre/context.mdx b/en/ai-sre/context.mdx
index aa475732..2356d3b0 100644
--- a/en/ai-sre/context.mdx
+++ b/en/ai-sre/context.mdx
@@ -2,17 +2,13 @@
title: Learn about Context
description: Context is the long-lived material AI SRE carries into troubleshooting. People maintain knowledge. The system organizes memory. The console gives each its own page under Customize → Context.
keywords: ["AI SRE", "context", "knowledge", "memory", "DUTY.md"]
-sidebarTitle: Learn about Context
+sidebarTitle: "Context"
---
-<Info>
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-</Info>
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## What context is
----
-
Context is the material AI SRE can reuse across troubleshooting sessions. It has two parts, each with its own page under the **Context** group of the **AI SRE → Customize** sidebar.
- **[Knowledge](/en/ai-sre/knowledge)** is maintained by people. It describes how this environment runs: a guide named `DUTY.md`, plus runbooks, service lists, and similar files. A session reads the guide first and opens the other files when it needs them. Entry: **AI SRE → Customize → Context → Knowledge**.
@@ -22,8 +18,6 @@ Both pages have an input box at the bottom: write what to change, and the consol
## Three scopes
----
-
Both kinds of material are organized by scope, but they support different scopes.
| Scope | Memory | Knowledge |
@@ -36,8 +30,6 @@ Personal scope has no knowledge. Shared scope has no memory.
## Read next
----
-
<CardGroup cols={2}>
<Card title="Learn about Knowledge" icon="book" href="/en/ai-sre/knowledge">
How the guide, runbooks, and files are organized, and how the assistant reads them in a session.
diff --git a/en/ai-sre/environments.mdx b/en/ai-sre/environments.mdx
index b0b8904e..4ca1a5d0 100644
--- a/en/ai-sre/environments.mdx
+++ b/en/ai-sre/environments.mdx
@@ -5,14 +5,10 @@ keywords: ["AI SRE", "environment", "Environment", "Sandbox", "BYOC", "Runner",
sidebarTitle: Environments
---
-<Info>
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-</Info>
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
An **Environment** is where AI SRE agents actually execute actions. Every tool call the agent makes, including running commands, reading and writing files, running Skills, and connecting to MCP services, happens inside an Environment.
AI SRE provides two types of Environments:
@@ -36,8 +32,6 @@ The console record is called an **Environment**. The process running on your mac
## Cloud sandbox
----
-
The cloud Sandbox is a temporary execution container managed by Flashduty. It is best for quick starts, demos, and investigations that do not need access to your private network. You do not install a process or maintain a machine.
Use the cloud Sandbox when:
@@ -55,8 +49,6 @@ For lifecycle, egress boundaries, and session-selection details, see [Sandbox](/
## Cloud environment templates
----
-
A cloud environment template is a reusable, predefined configuration for the Flashduty-managed cloud Sandbox: egress policy, environment variables, and a setup script. If a session's cloud Sandbox has no template bound, it starts with the system default configuration; once a template is bound, new Sandboxes start with that template's configuration.
Go to **AI SRE → Customize → Environments → Cloud** to view, create, edit, or delete cloud environment templates.
@@ -67,7 +59,7 @@ Go to **AI SRE → Customize → Environments → Cloud** to view, create, edit,
|---|---|---|
| Name | Yes | Must be unique within the account, up to 128 characters. |
| Scope | Yes | Shared-scope templates are visible to the whole account. Team-scoped templates are visible and editable only by that team. |
-| Network access | No, defaults to "Allow all" | The dropdown shows three options — "Default allowlist," "Custom (your domain list)," and "Allow all" — but currently only **"Allow all"** can be selected. "Default allowlist" and "Custom" are shown in the UI but disabled; this is a known limitation, not yet available. In other words, creating or editing a cloud environment template today always leaves the Sandbox it's bound to with fully open egress. |
+| Network access | No, defaults to "Allow all" | Only "Allow all" can be selected for now, so the Sandbox can reach any external address; "Default allowlist" and "Custom" are not yet available |
| Environment variables | No | `.env` format (`KEY=value`, one per line, multi-line quoted values supported), up to 32 KB, with a live byte counter in the UI. |
| Setup script | No | A Bash script, up to 64 KB, with a live byte counter in the UI. |
@@ -75,7 +67,7 @@ Go to **AI SRE → Customize → Environments → Cloud** to view, create, edit,
Environment variables are visible in plaintext to everyone who uses this cloud environment template — do not put secrets or credentials here.
</Warning>
-**Platform-reserved environment variable names.** Some names are injected by the platform itself into the session's runtime environment, and a template may not set them — a template that does is **rejected at save time** (the server is the single source of truth for this list; a hint list in the UI can lag behind it):
+**Platform-reserved environment variable names.** The platform injects the following variables; templates cannot set them, and saving a template that does is rejected:
| Reserved name | Notes |
|---|---|
@@ -83,9 +75,9 @@ Environment variables are visible in plaintext to everyone who uses this cloud e
| `FLASHDUTY_DOCS_URL` | The static address of the official docs bundle; the built-in `flashduty-docs` skill downloads its copy of the docs from here. |
| `GH_TOKEN`, the `GH_TOKEN_` prefix, `GH_PROMPT_DISABLED`, the `GIT_CONFIG_` prefix | The GitHub-side token and git configuration the platform injects (an account can have more than one GitHub App installation, so names such as `GH_TOKEN_1` and `GH_TOKEN_2` are reserved too). |
| `PATH` / `HOME` | The runtime environment's base variables. |
-| `GITLAB_TOKEN`, `GITLAB_ACCESS_TOKEN`, `OAUTH_TOKEN`, `GITLAB_HOST`, `GL_HOST`, `GITLAB_URI`, `GITLAB_API_HOST`, `GITLAB_SSH_HOST`, `GITLAB_SUBFOLDER`, `CA_CERT`, `SKIP_TLS_VERIFY`, the `GLAB_` prefix | GitLab / `glab` authentication, host and TLS configuration; letting a template override any one of these is the same as letting a session bypass the bot identity the platform injects and redirect `glab`'s transport. |
+| `GITLAB_TOKEN`, `GITLAB_ACCESS_TOKEN`, `OAUTH_TOKEN`, `GITLAB_HOST`, `GL_HOST`, `GITLAB_URI`, `GITLAB_API_HOST`, `GITLAB_SSH_HOST`, `GITLAB_SUBFOLDER`, `CA_CERT`, `SKIP_TLS_VERIFY`, the `GLAB_` prefix | GitLab / `glab` authentication, host and TLS configuration, so sessions cannot bypass the bot identity the platform injects. |
-The platform injects these names **before every command**; a same-named entry in the template is discarded and the platform's value wins (this holds identically on the cloud Sandbox and on a BYOC Runner). So use the template's environment variables for business-related, non-sensitive configuration only — when a secret is needed, use MCP member authorization or the relevant App integration.
+Even if a same-named variable is set some other way, the platform's value is used when commands run (on both the cloud Sandbox and BYOC Runners). Use template environment variables only for non-sensitive business configuration; for secrets, use MCP member authorization or the relevant App integration.
The setup script runs inside a **fresh sandbox (Ubuntu 24.04, running as root)**, **before the agent starts** — typically used to `apt install` packages the agent needs.
@@ -99,8 +91,6 @@ Cloud environment templates only configure egress, environment variables, and th
## BYOC Runner
----
-
A BYOC (Bring Your Own Compute) Runner is a `flashduty-runner` process that you deploy on your own machine. It keeps a persistent WebSocket connection to AI SRE. When it receives work, it runs commands, reads and writes files, executes Skills, and connects to MCP services that are reachable from that machine.
The value of BYOC Runner comes from where execution happens:
@@ -183,7 +173,7 @@ The setup guide automatically fills in the real `TOKEN` and `URL`. The examples
</Tabs>
<Note>
-Both `connect-url` and `install_script_url` are returned by the backend; the frontend does not hardcode them. Private or air-gapped deployments can replace the install-script distribution source with an internal mirror, but the mirror must serve `install.sh`, `releases/latest`, and `releases/download/<version>/...` release assets.
+Both `connect-url` and `install_script_url` are issued dynamically by the platform rather than being fixed addresses. Private or air-gapped deployments can replace the install-script distribution source with an internal mirror, but the mirror must serve `install.sh`, `releases/latest`, and `releases/download/<version>/...` release assets.
</Note>
### Connect to a private endpoint with a self-signed certificate
@@ -295,8 +285,6 @@ Uninstall commands are also in the setup guide, and differ by installation metho
## Permission Configuration
----
-
By default, Runner uses an allow-all rule — the same trust model as running the AI model directly in your own shell:
```yaml
@@ -411,35 +399,31 @@ So the real file-access boundary is the **OS user** the Runner runs as, plus the
## Selecting an environment in a session
----
-
The environment selector at the bottom of the chat input decides where a new session executes:
| Option | Meaning |
|---|---|
| **Auto** | The default for new sessions. Tries an online BYOC Runner under the session's bound team, then an online Shared-scope (account-level) Runner, and falls back to the cloud Sandbox when neither is available. |
| **Cloud Sandbox · Default** | Forces the system-managed cloud Sandbox and ignores self-hosted Runners. |
-| **Self-hosted environment** | Lists Runners the current member can use. Offline, never-connected, or team-mismatched Runners cannot be selected; Runners in **Degraded** status **remain selectable**, and selecting one shows a "Degraded — you can continue, but responses may be slower" notice. |
+| **Self-hosted environment** | Runners you can use. Offline, never-connected or team-restricted Runners cannot be selected; **degraded** Runners can still be selected but may respond slowly. |
<Warning>
-Environment selection is locked once per session: the Environment determined when the session sends its first message is recorded and reused for all later turns. Changing the selector afterward does not change that session. To switch environments, start a new session.
+A session's environment is fixed when its first message is sent and does not change if you switch the selector later. To change environments, start a new session.
</Warning>
-When you open a historical session, the selector shows the Environment that session originally locked to, along with its current status, in read-only mode. If the bound Runner is offline or deleted, the session cannot continue sending messages; reconnect that Runner or start a new session and use the cloud Sandbox.
+When you open a past session, the selector shows its environment and status read-only. If the bound Runner is offline or deleted, the session cannot send messages; restore the Runner or start a new session.
### A child session's environment
A dispatched subagent brings its own **child session**, whose execution-environment rules differ from the root session's:
-- **It inherits the parent by default**: when `agent_dispatch` carries no `environment`, the child session **shares the parent's sandbox / workspace**, so it can read the parent's files directly — and the environment shown on the child session panel is therefore the same as the parent's.
-- **Only a cross-environment dispatch gets its own environment**: when the subtask is sent to another environment (via `agent_dispatch`'s `environment` argument — another BYOC Runner or the cloud environment, see [Agent](/en/ai-sre/agents)), the child session gets **its own** sandbox or Runner scratch directory and cannot read the parent's files.
-- **The child session panel offers no environment selector**: it only shows that child session's bound environment and its current status, in **read-only** form — the cloud environment, or the self-hosted Runner's name — reusing the same status vocabulary as the root session's read-only display (no extra marking while it is healthy; a short label and a hover explanation for offline / degraded / never connected / deleted).
+- **Shares the parent's environment by default**: the child session uses the same sandbox / workspace as the parent and can see its files.
+- **Gets its own environment when dispatched elsewhere**: when the subtask is sent to another BYOC Runner or the cloud environment (see [Agents](/en/ai-sre/agents)), the child session has its own sandbox or Runner directory and cannot see the parent's files.
+- **The child session panel shows the environment read-only**: you cannot switch environments in a child session.
- **An A2A child session shows no runtime environment**: the remote agent executes in its own environment, and the platform does not choose that location.
## Scope
----
-
Each BYOC Environment has Shared or team-level scope:
| Scope | Visibility |
@@ -459,8 +443,6 @@ The account remains the runtime security boundary, but team scope also participa
## Troubleshooting
----
-
When troubleshooting Runner issues, start with the **Status** and **Last heartbeat** columns in the self-hosted environment list.
<AccordionGroup>
@@ -484,13 +466,11 @@ Fastest split: **Offline / Pending** points to the Runner-to-AI-SRE connection;
## Related pages
----
-
<CardGroup cols={2}>
<Card title="Sandbox" icon="cloud" href="/en/ai-sre/sandbox">
Learn the cloud Sandbox lifecycle, use cases, and egress boundary.
</Card>
- <Card title="Console" icon="comments" href="/en/ai-sre/sessions">
+ <Card title="Console Chat" icon="comments" href="/en/ai-sre/sessions">
View the Environment, team, and resources invoked by the agent that are bound to a session.
</Card>
<Card title="MCP (External Tools)" icon="plug" href="/en/ai-sre/mcp">
diff --git a/en/ai-sre/im.mdx b/en/ai-sre/im.mdx
index c13319a4..bb20579a 100644
--- a/en/ai-sre/im.mdx
+++ b/en/ai-sre/im.mdx
@@ -5,14 +5,10 @@ keywords: ["AI SRE", "IM", "Slack", "Lark", "DingTalk", "WeCom", "war room", "@m
sidebarTitle: IM Platform
---
-<Info>
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-</Info>
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
Incident response usually happens right inside your IM group — alerts come in, the team discusses in the channel, and someone spins up a war room. AI SRE puts the agent directly into that collaboration chain: **you never have to switch to the console; you can summon it from IM to investigate**, and your teammates can follow every step of its analysis in real time.
AI SRE's IM integration has two trigger modes:
@@ -28,8 +24,6 @@ AI SRE's IM integration has two trigger modes:
## Supported IM Platforms
----
-
AI SRE's IM interaction covers four major platforms. Each platform supports inbound @mentions (webhook), historical message reads, and outbound replies:
| Platform | Group @mention | Direct message (DM) | Processing receipt | War room auto-diagnosis |
@@ -47,8 +41,6 @@ IM interaction requires that you have already connected the corresponding platfo
## AI SRE Settings in IM Integrations
----
-
Open the corresponding IM integration under **On-call → Integration Center → Integration List → Instant Messaging** and configure its AI SRE behavior under **Enhanced features**. The following switches are on by default:
- **Automatically start AI incident analysis**: available after you enable War Room. When the integration creates a war room, AI SRE starts one preliminary diagnosis and posts the result back to the room.
@@ -61,8 +53,6 @@ If AI SRE is not enabled for the account, these switches do not take effect. Aft
## @Mention Summon
----
-
In a connected IM group where **Allow AI SRE conversations in IM** is enabled, **@mention the bot** and type your question (for example, "@AI SRE check why the payment service's 5xx rate is spiking") — the message is forwarded to AI SRE for processing via the platform webhook:
<Steps>
@@ -104,18 +94,16 @@ AI SRE's replies in IM are delivered **only through the `reply` tool** — ordin
- **Result**: an answer to your concrete question, or an actionable interim finding.
- **Progress**: a one-or-two-sentence update while work is still going on — confirmed progress, what it is currently waiting on, a real blocker. A progress message is **not the answer**: it does not finish the turn, and the result is delivered separately as usual.
-If a turn ends naturally with the conclusion written as ordinary text instead of submitted through `reply`, the system adds one automatic **delivery-only** correction: that correction exposes `reply` alone and runs no investigative or mutating operations; if nothing has been submitted even then, the turn ends with an error — that draft never appears in the group. Non-natural endings — a cancellation, an interruption by a new message, a dispatched subagent, a wait on a subagent's reply, a truncated output — do not trigger this correction.
+If a conclusion is not submitted as a reply, the system asks AI SRE to submit it once more (submission only, with no investigation or changes); if it still is not submitted, the turn ends with an error and the draft never appears in the chat.
-This delivery contract applies only to **human-initiated IM requests**: console sessions still answer with streaming text, and war-room auto-diagnosis is an unattended background turn that also keeps native streaming output.
+This reply style applies only to **human-initiated IM requests**: console sessions still answer with streaming text, and war-room auto-diagnosis is an unattended background turn that also keeps native streaming output.
<Note>
-A single reply also has a soft reading-length budget: when it is too long, `reply` refuses it once and suggests trimming the repetition, or publishing the detailed evidence and comparisons as an artifact and sending only the key conclusions plus the artifact link into the chat. That is why a long analysis in IM usually arrives as "conclusions + artifact link" rather than one very long message — see [Artifacts](/en/ai-sre/artifacts). If you explicitly ask to have the full report pasted directly into the chat, this constraint does not apply.
+When a reply is too long, AI SRE trims it or publishes the detailed evidence as an artifact and posts only the conclusion and the artifact link (see [Artifacts](/en/ai-sre/artifacts)). This limit does not apply when you explicitly ask for the full report in the chat.
</Note>
## War Room Auto-Diagnosis
----
-
When you open a **war room** for an incident in IM and the integration keeps **Automatically start AI incident analysis** enabled, AI SRE intervenes automatically — no one needs to @mention it:
<Steps>
@@ -136,8 +124,6 @@ War room auto-diagnosis is bound to the incident context: when the investigation
## Standing Tasks and the Monitoring Card
----
-
When the agent's current turn ends but a **standing process-type task** it started is still running (e.g. a monitor watcher or a background command), AI SRE posts a monitoring card to the chat:
```
@@ -151,15 +137,15 @@ Each standing task gets one line: tasks with a deadline show the remaining minut
While any standing task is alive, the IM session's root message stays open (the incident view is not closed): later turns triggered by task notifications keep posting into the **same chat** — no re-@mention needed.
</Note>
-Notification rounds follow a silent "no message = no news" semantics: if a notification round has nothing new to deliver, AI SRE closes that round silently — **no placeholder receipt** is posted to the chat, and the monitoring card is not re-posted either. A new message appears in the chat only when there is a real new finding.
+When a notification turn has nothing new, AI SRE posts nothing; it speaks only when there is a new conclusion.
### Progress Messages During a Long Investigation
-When an investigation runs long, the chat can stay quiet for a while — interim prose is not delivered, and the monitoring card only appears once a standing task exists. So when an IM request has been **silent for about 60 seconds** with no public reply submitted, the system may add a transient reminder telling the model how long you have already been waiting, and lets the model decide whether to post a progress message:
+In long investigations, if a request has had no reply for **about 60 seconds**, AI SRE gets a reminder and decides whether to post a progress update:
-- **Reminder cadence**: two reminders for the same request are at least **3 minutes** apart, and one uninterrupted silence stretch gets **at most two reminders**. Any successfully submitted reply (result or progress) opens a new silence stretch and resets the count, but does not shorten that 3-minute minimum gap.
-- **Where the waiting time starts**: at the moment your message entered the platform's pending queue, so queueing time counts — not when the agent actually started working on it.
-- **A reminder sends nothing by itself**: it only tells the model how long you have waited; it never writes anything to the group on the model's behalf. When the wait was already explained and nothing has changed, or the model is waiting on information from you, sending nothing is the correct choice.
+- Reminders for the same request are at least **3 minutes** apart, with at most **2** per stretch of silence; any reply restarts the count.
+- Waiting time counts from when your message entered the queue, including time spent queued.
+- A reminder posts nothing by itself; AI SRE may stay quiet if nothing has changed or it is waiting for your input.
- **A progress message is not the answer**: it says "still investigating, what it is stuck on, what it checks next", does not finish the turn, and the result follows separately.
<Note>
@@ -170,23 +156,19 @@ Waiting reminders appear only on **attended IM requests**; the console, API, and
## Connections and Authorization
----
-
-When a credential is missing, the console renders inline cards (**"Authorize [resource name] to continue"**, **"Connect [vendor] to continue"** — see [Console](/en/ai-sre/sessions#when-authorization-is-required)). **IM and API channels get no card** — the agent hands the matter to you according to this session's channel, as follows:
+In the console, a missing credential shows an authorization card (see [Console conversations](/en/ai-sre/sessions#when-authorization-is-required)). **IM and API channels have no cards**, so the agent handles it this way:
| Situation | Behavior on IM / API channels |
| --- | --- |
-| Your OAuth authorization is missing (`per_user_oauth`) | The agent pastes the authorize link into the chat as a plain message (not a card); open it in a **desktop / PC browser** to complete the authorization, then reply **"已授权"** (or `authorized` in an English session) to continue. Continuing is your explicit action — a successful OAuth callback does not resume the task by itself |
-| Your secret-type credential is missing (`per_user_secret`) | There is no safe way to collect it over IM: the agent simply tells you to open **this same session in the web console** and complete it there. It never asks you to paste the secret into the chat, and never points you at a settings page instead |
-| The whole connection is missing (in the marketplace catalog, not connected in the account) | The agent gives the connect URL (a deep link into the console's plugins page) as a plain link; connect, then reply **"继续"** (or `continue`) to carry on |
+| Your OAuth authorization is missing | The agent posts the authorize link; open it in a **desktop browser**, complete authorization, then reply **"已授权"** (or `authorized` in an English session) to continue. A successful authorization does not resume the task by itself |
+| Your secret is missing | The agent asks you to open **this same session in the web console** to enter it; it never asks you to paste a secret into the chat |
+| The account has not connected the required integration | The agent posts the console link to connect it; connect, then reply **"继续"** (or `continue`) |
| A shared server's own credentials (environment variables / headers) | Not any of the above: fill them in under **Customize → Plugins → MCP** (that server), then tell the agent to retry |
On the automation channel nobody is watching and no reply will ever arrive: the agent does not wait and does not phrase anything as a question — it **records the missing connection or authorization as a blocker** in its final report and delivers whatever the evidence already supports.
## In-session Switch Commands
----
-
IM sessions have no picker UI like the console, but they support two slash commands that let you **switch bindings mid-conversation** — neither command is available for console sessions, whose environment and team bindings are set at creation and cannot be changed afterwards.
### /env — Switch Runner Environment
@@ -227,11 +209,9 @@ Knowledge bundles already mounted into this session are not removed — mounts a
## /feedback — Rate an AI SRE Reply
----
-
Once an AI SRE reply lands in a group chat, anyone in the group can rate it — not only whoever started the investigation. Send `/feedback` to the bot to rate or comment on the reply you are looking at:
-- **Entry and resolution:** `/feedback` is backed by the AI SRE side (POST /safari/session/latest-reply → POST /safari/feedback/create); it resolves "the message you are looking at" into the corresponding reply event even if you never took part in that conversation.
+- **Entry and resolution:** `/feedback` is handled by AI SRE; it resolves "the message you are looking at" into the corresponding reply event even if you never took part in that conversation.
- **Eligibility:** **not limited to session members** — any account member who can use AI SRE may rate (read-only group-chat readers included); an AI SRE answer posted into a group chat is public, and the reader who spotted the error is exactly whose opinion we want.
- **How to rate:** choose `like` / `dislike` / `none`; a comment-only submission (no rating) is allowed and does not wipe an earlier rating you gave, while an explicit `none` clears the existing rating.
- **Stored per rater:** each reply is keyed by **(reply event, rater)** — when several people rate the same reply, each gets its own row and they do not overwrite one another.
@@ -239,8 +219,6 @@ Once an AI SRE reply lands in a group chat, anyone in the group can rate it —
## Relationship to Console Sessions
----
-
Whether you start a session from IM or the console, it's **the same AI SRE**: messages are handled one at a time, with streaming output, automatic context compaction for long conversations, and optional team and environment bindings. The only difference is the entry point —
- **Console**: ask questions one at a time in the **Chat** workspace and view the full tool-call and sub-session panels; environment and team bindings are fixed at creation and cannot be changed.
@@ -250,13 +228,11 @@ For more about sessions, see [Conversations](/en/ai-sre/sessions).
## Related Pages
----
-
<CardGroup cols={2}>
<Card title="Overview" icon="gauge-high" href="/en/ai-sre/overview">
Learn about AI SRE's overall capabilities, typical use cases, and console navigation.
</Card>
- <Card title="Console" icon="comments" href="/en/ai-sre/sessions">
+ <Card title="Console Chat" icon="comments" href="/en/ai-sre/sessions">
Learn about sessions, streaming output, cancellation, and context compaction.
</Card>
<Card title="Agent" icon="satellite-dish" href="/en/ai-sre/agents">
diff --git a/en/ai-sre/init.mdx b/en/ai-sre/init.mdx
index afd8846e..9db474d8 100644
--- a/en/ai-sre/init.mdx
+++ b/en/ai-sre/init.mdx
@@ -5,26 +5,20 @@ keywords: ["AI SRE", "init", "operational map", "knowledge", "onboarding", "DUTY
sidebarTitle: Setup
---
-<Info>
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-</Info>
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
Type `/init` in the input box of any AI SRE session, and the agent switches into an **operational onboarding interviewer** that walks you through building operational knowledge from scratch — your team's "operational map." It scans your Flashduty incidents and notification channels, asks you questions, captures the service topology, runbooks, cluster access, and more that you describe into knowledge files, and helps you connect external tools (MCP) when needed.
`/init` is the **starting point** for knowledge. AI SRE's diagnostic quality depends directly on how much real knowledge it can read about your systems: the more complete and accurate your [knowledge](/en/ai-sre/knowledge) is, the faster and more reliably the agent pinpoints root causes. `/init` is the guided flow that builds that knowledge from zero — and once it's built, every session loads it automatically.
<Note>
-`/init` will **never** write or install anything without your consent. Before anything lands at each phase, it lists exactly "which files will be created/updated," and only acts after you confirm them one by one. Credentials (tokens, passwords, AK/SK) are never echoed back in plain text in the conversation — only recorded as `<recorded (length=N)>`. See [Safety and consent](#safety-and-consent).
+`/init` asks for your item-by-item confirmation before it writes or installs anything, and never echoes credentials in plain text. See [Safety and consent](#safety-and-consent).
</Note>
## When to use /init vs. plain natural language
----
-
`/init` is for **structured setup from scratch / systematic backfilling**; small, one-off edits don't need it.
| Scenario | What to use |
@@ -39,20 +33,18 @@ Type `/init` in the input box of any AI SRE session, and the agent switches into
## How to run
----
-
<Steps>
<Step title="Type /init in a session">
Type `/init` in the input box of any AI SRE session and send it. No parameters are required.
</Step>
<Step title="Confirm the scope">
- `/init` first locks the scope it will write to: **account level** (visible to all sessions in the account) or a specific **team level** (loaded only in that team's sessions). The scope is determined by whether the current session is bound to a team, and the agent confirms it with you first; a single session locks one scope and does not switch mid-way.
+ The agent first confirms the scope it will write to: the bound team's **team level** (loaded only in that team's sessions) if the session is bound to a team, otherwise **account level** (visible to all sessions in the account). One session uses one scope.
</Step>
<Step title="Follow the interview">
The agent asks questions phase by phase, topic by topic (services and topology, observability, runbooks, common failures, cluster access, and so on), turning your answers into draft knowledge files. At the end of each phase it asks whether to "continue to the next item or stop here for now."
</Step>
<Step title="Confirm each item before it writes">
- Before anything lands at each phase, the agent presents a list of "which files will be created/updated," each with a 3–5 line summary. Only after you confirm does it write to the knowledge and link the new files into the `DUTY.md` table of contents.
+ Before writing at each phase, the agent lists the files it will create or update (each with a 3–5 line summary). It writes only after you confirm, then links the new files into the `DUTY.md` table of contents.
</Step>
<Step title="Pause or rerun anytime">
You can say "skip this," "go back to step N," or "stop here" at any time. `/init` is not a one-shot run — typing `/init` again at any later point continues backfilling from the existing knowledge.
@@ -61,8 +53,6 @@ Type `/init` in the input box of any AI SRE session, and the agent switches into
## The interview
----
-
`/init` works through a fixed sequence of phases, each with clear entry and exit conditions. You can skip, go back, or stop at any time.
<AccordionGroup>
@@ -90,7 +80,7 @@ Type `/init` in the input box of any AI SRE session, and the agent switches into
| 7 | Cluster access & runtime probing | `clusters.md` (k8s) / appended to `tools.md` (MCP) |
<Note>
- In Phase 4, every datasource gap goes through the same **Monitors-first** two-step route: when the scan digest already shows Monitors usage (a datasource or alert rules), the agent names the gap's `type_ident` and hands over the console deep link `/monit/datasource?create=<type_ident>` — opening it lands in Monitors' add-datasource form with that type preselected; `type_ident` values are prometheus / loki / victorialogs / tencent_cls / sls / mysql / postgres / oracle / clickhouse / elasticsearch. Once the datasource is enabled, the built-in `monit-query` capability picks it up automatically — nothing to install. Only when there is no Monitors evidence at all does it fall back to registering the tools you already run as a direct MCP connection (see [MCP](/en/ai-sre/mcp)). `/init` itself never creates or edits a Monitors datasource.
+ In Phase 4, datasource gaps are filled through Monitors first: if the account already uses Monitors (it has datasources or alert rules), the agent gives you a link that opens the Monitors add-datasource form with the right type preselected (Prometheus, Loki, VictoriaLogs, Tencent Cloud CLS, SLS, MySQL, PostgreSQL, Oracle, ClickHouse or Elasticsearch). Once the datasource is enabled, AI SRE can query it, with nothing to install. Only when the account does not use Monitors at all does it register the tools you already run as a direct MCP connection (see [MCP](/en/ai-sre/mcp)). `/init` itself never creates or edits a Monitors datasource.
</Note>
<Note>
@@ -104,29 +94,15 @@ Type `/init` in the input box of any AI SRE session, and the agent switches into
## Safety and consent
----
-
`/init` writes knowledge, may install MCP, and touches credentials, so consent and least privilege are hard constraints:
-<AccordionGroup>
- <Accordion title="Per-item explicit consent" icon="hand">
- Any write or install requires your explicit consent. Before anything lands, each collection phase lists "which files will be created/updated" (each with a 3–5 line summary), and it only proceeds after you say yes — it never triggers a write off a vague "ok."
- </Accordion>
- <Accordion title="Credentials are never echoed" icon="key">
- When you provide sensitive information such as a token, password, or AK/SK, the agent only confirms "recorded (length=N)" and never reprints the plaintext in the conversation.
- </Accordion>
- <Accordion title="Least-privilege credentials" icon="lock">
- Whenever you need to provide or generate a credential (kubeconfig, cloud AK/SK, database account, API token), the agent asks you to configure it as **read-only / least privilege**; when the boundary is machine-verifiable, it runs a read-only boundary check before recording it.
- </Accordion>
- <Accordion title="Minimality" icon="filter">
- Not every detail belongs in the knowledge. The agent only writes content where "without it, the AI would make a worse decision during an incident" — optional, nice-to-have details aren't crammed in, keeping the knowledge from bloating.
- </Accordion>
-</AccordionGroup>
+- **Per-item explicit consent**: any write or install requires your explicit consent. Before writing, each phase lists the files it will create or update (each with a 3–5 line summary) and proceeds only after you say yes — never off a vague "ok."
+- **Credentials are never echoed**: when you provide a token, password, or AK/SK, the agent records it only as `<recorded (length=N)>` and never reprints the plaintext.
+- **Least-privilege credentials**: whenever you provide or generate a credential (kubeconfig, cloud AK/SK, database account, API token), the agent asks you to make it **read-only / least privilege**; when the boundary is machine-verifiable, it runs a read-only boundary check before recording it.
+- **Minimality**: the agent only writes content without which the AI would make worse decisions during an incident; nice-to-have details are left out so the knowledge doesn't bloat.
## What it produces
----
-
The result of `/init` is a [Knowledge](/en/ai-sre/knowledge) base that every subsequent session loads automatically:
- **`DUTY.md`** — the table-of-contents entry point for the knowledge, holding only a one-line introduction and a list of `@filename` links pointing to each topic file;
@@ -139,8 +115,6 @@ The result of `/init` is a [Knowledge](/en/ai-sre/knowledge) base that every sub
## /init and /insight: a best-practice pair
----
-
`/init` and [`/insight`](/en/ai-sre/insight) are the two ends of the operational-knowledge "build → refine" loop:
<CardGroup cols={2}>
@@ -158,8 +132,6 @@ The recommended rhythm: use `/init` to lay a solid foundation, run a few real in
## Related pages
----
-
<CardGroup cols={2}>
<Card title="Manage Knowledge" icon="book" href="/en/ai-sre/knowledge">
Where `/init`'s output lands — learn the DUTY.md structure, file constraints, and how to edit and maintain it manually.
diff --git a/en/ai-sre/insight.mdx b/en/ai-sre/insight.mdx
index 9e3f32d2..c0f19ca5 100644
--- a/en/ai-sre/insight.mdx
+++ b/en/ai-sre/insight.mdx
@@ -5,14 +5,10 @@ keywords: ["AI SRE", "insight", "operational insight", "friction report", "knowl
sidebarTitle: Usage Insights
---
-<Info>
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-</Info>
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
Type `/insight` in the input box of any AI SRE session and AI SRE will look back at **your** last 30 days of sessions to produce a single-page operational insight report. The report uses a parchment-style HTML layout and renders directly in the session as a chat card, which you can preview and download.
It is a **coach's read on the month**, not a problem list. It leads with **what's working** — where AI SRE genuinely pulled its weight this month; then covers the **frictions worth eliminating now** — the patterns that repeatedly drain your time, such as pasting the same database connection string across multiple sessions, an agent missing a runbook it should already know, or it repeatedly querying the wrong data source; and finally offers **2–3 higher-leverage next steps** — shifts in *how* you work with AI SRE that are worth trying.
@@ -21,12 +17,8 @@ It is a **coach's read on the month**, not a problem list. It leads with **what'
`/insight` is **read-only**. It only analyzes and presents; it will **not** automatically modify any knowledge, skill, or MCP configuration. Every suggestion is copyable text — whether to act on it is entirely up to you. See [How to Act on Suggestions](#how-to-act-on-suggestions).
</Note>
-`/insight` is a built-in AI SRE skill: it automatically exports your past sessions, computes quantitative metrics, analyzes the session content section by section, and renders a consolidated report. The entire process is transparent to you — all you need to do is type `/insight`.
-
## How to Generate
----
-
<Steps>
<Step title="Type /insight in a session">
Type `/insight` in the input box of any AI SRE session and send it. No parameters are required.
@@ -58,20 +50,18 @@ Understanding how the report is put together helps you see where the numbers com
<AccordionGroup>
<Accordion title="Export and filter sessions" icon="download">
- AI SRE first lists the sessions within scope for the last 30 days (up to 200 by default), covering **all four entry kinds** — web, IM, API, and automation; IM is a primary AI SRE entry point, so IM-originated sessions are analyzed alongside web. After exporting their full records, it keeps the sessions with **real signal**: **≥ 2 user-message turns OR ≥ 3 tool calls** (either one qualifies — `INSIGHT_MIN_MSGS` / `INSIGHT_MIN_CALLS`). The tool-call arm matters: it lets autonomous runs kicked off by an alert or a schedule — which may have zero human turns yet a dozen tool calls of real investigation — into the report, instead of being silently dropped by a user-turns-only filter. The quantitative overview also renders an **entry mix** line (`entry_mix`) showing where these sessions came from.
+ AI SRE first lists the sessions within scope for the last 30 days (up to 200 by default), covering all four entry kinds (web, IM, API, and automation), then keeps only sessions with **real signal**: **≥ 2 user-message turns or ≥ 3 tool calls** (either qualifies). That way, autonomous runs started by an alert or a schedule — no human turns, but real investigation — are included too.
</Accordion>
<Accordion title="Compute quantitative metrics" icon="gauge-high">
- The report's quantitative overview — session count, your turn count, tool call count, average turns, daily activity, tool and skill distribution, entry mix, and outcome distribution — is computed deterministically across all sessions by program logic, not estimated by the model, so it is reliable and always present even when no friction is found.
+ The report's quantitative overview — session count, your turn count, tool call count, average turns, daily activity, tool and skill distribution, entry mix, and outcome distribution — is computed by the program, not estimated by the model, and is shown even when no friction is found.
</Accordion>
<Accordion title="Analyze section by section, then consolidate" icon="layer-group">
- AI SRE reads the session records in sections, distilling "session topics," "wins," and "friction findings" from each, then consolidates everything: topics are aggregated into a narrative overview, the most representative wins are surfaced, and findings are deduplicated, clustered, and ranked by importance into friction cards. Every conclusion carries a **verbatim quote** as its evidence; session IDs are used internally only — to count how often a friction recurs — and are **never shown** in the report. The report contains only the distilled topics and findings — it does not copy your full raw session content verbatim.
+ AI SRE reads the session records in sections, distilling "session topics," "wins," and "friction findings" from each, then consolidates everything: topics are aggregated into a narrative overview, the most representative wins are surfaced, and findings are deduplicated, clustered, and ranked by importance into friction cards. Every conclusion carries a **verbatim quote** as evidence. The report shows no session IDs and does not copy full raw session content.
</Accordion>
</AccordionGroup>
## Report Contents
----
-
The report has **six parts** from top to bottom. Regardless of whether any friction is found, the quantitative overview is always present.
### 1. At a glance
@@ -80,18 +70,18 @@ A **2–4 sentence** coaching synthesis at the very top of the report, written *
### 2. Overview (quantitative)
-Computed deterministically by program logic, not estimated by the model; the model only transcribes the numbers into the report. Includes:
+Computed by the program, not estimated by the model. Includes:
| Metric | Description |
|---|---|
-| Sessions | Number of sessions included in this analysis (`sessions`) |
-| Your turns | Total number of messages you sent across those sessions (`your turns`) |
-| Tool calls | Total number of tool calls initiated by the agent (`tool calls`) |
-| Avg turns | Average number of turns per session (`avg turns / session`, one decimal place) |
+| Sessions | Number of sessions included in this analysis |
+| Your turns | Total number of messages you sent across those sessions |
+| Tool calls | Total number of tool calls initiated by the agent |
+| Avg turns | Average number of turns per session (one decimal place) |
| Activity | Per-day session activity bar chart, with start and end dates labeled |
| Tool distribution | Ranking of tools the agent relied on most (top ~6) |
| Skill distribution | Ranking of skills invoked during sessions; shows "No skills invoked" if none were called |
-| Entry mix | Where the sessions came from, formatted as `web (60) · IM (25) · automation (5)` (`entry_mix`) |
+| Entry mix | Where the sessions came from, formatted as `web (60) · IM (25) · automation (5)` |
| Outcome distribution | Count of completed / incomplete / errored sessions (zero values omitted) |
### 3. Narrative
@@ -109,25 +99,24 @@ Friction cards ranked **from highest to lowest importance**, up to approximately
- A **rank** and a **friction type label** (one of five types; see the next section);
- A **frequency badge** showing how many distinct sessions this friction consumed your time in (deduplicated evidence session count);
- A one-line title and a second-person explanation;
-- **Evidence**: a single **verbatim quote** from the transcript (the most telling user or agent line); session IDs are used internally only — to count recurrence — and are **not shown**;
-- **A copyable recommendation**: text you can paste directly, whose first line is the destination (`Add this to knowledge/<scope>/…`), so the target file travels with the paste.
+- **Evidence**: a single **verbatim quote** from the transcript (the most telling user or agent line);
+- **A copyable recommendation**: text you can paste directly, whose first line (`Add this to knowledge/<scope>/…`) names the target file.
### 6. Next steps
About **2–3** forward-looking, grounded suggestions. These are **strategic** (a shift in *how* you work with AI SRE, higher-leverage), distinct from the tactical, file-level fixes in the friction cards; each names the exact observation it's grounded in (a stat from the overview or a friction cluster) and maps to a real AI SRE capability.
-When the report surfaces the `expensive-automation` emergent pattern — an automation-entry session that pulls raw listings into context and counts / groups / ranks them itself instead of scripting the aggregation — the next steps include a **Tested-script automation rewrite**: ask the agent in chat to move that automation's deterministic collection and aggregation into a tested script under its knowledge folder (`knowledge/<scope>/automations/<slug>/`), leaving the task prompt as the goal, the delivery, and a pointer to that folder.
+Two common kinds of next step:
-When sessions expose a root-cause gap on the datasource side, the next steps gain another shape: a recommendation to add the matching datasource in Monitors (10 `type_ident` values: prometheus / loki / victorialogs / sls / tencent_cls / elasticsearch / mysql / postgres / oracle / clickhouse). These suggestions carry an evidence bar — the same `type_ident` gap must appear in ≥ 2 distinct sessions, or a single session must give explicit evidence. Once the datasource is added, the built-in `monit-query` capability becomes available automatically, with no skill to install; the report only suggests, never creates or enables a datasource on your behalf, and no longer suggests "install a skill from the Marketplace."
+- **Tested-script automation rewrite**: when an automation session pulls raw listings into context and has the agent count / group / rank them itself (the `expensive-automation` pattern), ask the agent in chat to move the collection and aggregation into a tested script under `knowledge/<scope>/automations/<slug>/`, leaving the task prompt with just the goal, the delivery, and a pointer to that folder.
+- **Add a datasource**: when sessions expose a root-cause gap on the datasource side (the same type in ≥ 2 sessions, or explicit evidence in one), the report suggests adding the matching datasource in Monitors (prometheus / loki / victorialogs / sls / tencent_cls / elasticsearch / mysql / postgres / oracle / clickhouse). Once added, the built-in `monit-query` capability is available automatically with no skill to install; the report never creates the datasource for you.
<Note>
-Every friction and win must be grounded in at least one real session and carry a verbatim quote as evidence — the report never fabricates sessions, facts, or runbook gaps. If no rankable friction is found, the frictions part displays an empty-state message while the rest of the report still renders — in that case, "the overview itself is the report."
+Every friction and win must be grounded in at least one real session and carry a verbatim quote as evidence — the report never fabricates sessions, facts, or runbook gaps. If no friction is found, the frictions part shows an empty-state message and the rest of the report still renders.
</Note>
## Friction Types
----
-
`/insight` recognizes exactly five friction types, each corresponding to a clear, adjustable "dial." Listed in default importance order:
| Friction type | What it looks like in sessions | Recommended destination |
@@ -144,36 +133,32 @@ Every friction and win must be grounded in at least one real session and carry a
## How to Act on Suggestions
----
-
-The report is **read-only**: it surfaces problems and provides copyable fix text, but **never** automatically applies any changes. For now, all suggestions are copy-paste style: you confirm them, then manually apply them in the corresponding resource.
+The report only provides copyable fix text; you apply it yourself in the corresponding resource.
<Steps>
<Step title="Read the report and pick what's worth doing">
Friction cards are already ranked by importance. Start with the top-ranked cards that have high frequency badge numbers — those are the patterns consuming your time most repeatedly.
</Step>
<Step title="Copy the suggested text">
- Each card's "Copyable suggestion" contains text you can paste directly, and its first line (`Add this to knowledge/<scope>/…`) is the destination — telling you which file it belongs in, and traveling with the paste.
+ Copy the card's "Copyable suggestion" text; its first line (`Add this to knowledge/<scope>/…`) names the target file.
</Step>
<Step title="Manually apply it in the corresponding resource">
Based on the friction type, paste and save in the appropriate resource: repeated context and hallucinated entities go into the knowledge's `services.md` or DUTY.md; a missing runbook means adding a new runbook to the knowledge; a wrong data source gets pinned in `observability.md` / `clusters.md`; stale knowledge means updating the outdated file directly. These are all standard edits under [Knowledge](/en/ai-sre/knowledge).
</Step>
</Steps>
-<Warning>
-`/insight` will never perform any writes on your behalf — it does not invoke any sync or install actions, and does not modify knowledge, skills, or MCP. If you later want AI SRE to "add this runbook," that is an **independent** natural-language instruction and is outside the scope of `/insight`.
-</Warning>
+<Tip>
+You can also ask AI SRE in a later message to "add this runbook" — that is a separate instruction, not something `/insight` does.
+</Tip>
<Note>
-`/insight` runs on demand, one report at a time — it does not "continuously watch" or generate reports on a schedule. The recommended approach is to run it again after accumulating a few more incident investigations, to see which frictions have been resolved and which new ones have emerged.
+`/insight` runs only when you type it; it does not generate reports on a schedule. Run it again after a few more investigations to see which frictions are gone and which are new.
</Note>
## Related Pages
----
-
<CardGroup cols={2}>
- <Card title="Console" icon="comments" href="/en/ai-sre/sessions">
+ <Card title="Console Chat" icon="comments" href="/en/ai-sre/sessions">
Learn about session creation, team binding, and war rooms — these determine the analysis scope of `/insight`.
</Card>
<Card title="Manage Knowledge" icon="book" href="/en/ai-sre/knowledge">
diff --git a/en/ai-sre/knowledge.mdx b/en/ai-sre/knowledge.mdx
index 9e48e00c..c7fff822 100644
--- a/en/ai-sre/knowledge.mdx
+++ b/en/ai-sre/knowledge.mdx
@@ -2,17 +2,13 @@
title: Learn about Knowledge
description: People maintain knowledge. It describes how this environment runs. A DUTY.md plus runbooks and service lists. A session reads the guide first and opens the other files when needed.
keywords: ["AI SRE", "knowledge", "DUTY.md", "runbook", "context"]
-sidebarTitle: Learn about Knowledge
+sidebarTitle: "Knowledge"
---
-<Info>
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-</Info>
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
Knowledge is the operational knowledge you hand to AI SRE: a `DUTY.md` file plus a collection of runbooks, FAQs, service catalogs, cluster configs, and similar files. When a session starts, the agent reads `DUTY.md` first, then opens other files as needed — bringing your team's incident-handling experience, naming conventions, and system topology into every diagnosis.
Console entry: **AI SRE → Customize → Context → Knowledge**. [Memory](/en/ai-sre/memory), in the same group, is a separate page and is managed separately.
@@ -30,8 +26,6 @@ Knowledge is one type of AI SRE resource and follows the same two-level scope mo
## DUTY.md Structure
----
-
`DUTY.md` is the **table of contents entry point** for the whole knowledge and is loaded automatically in every session. The agent reads `DUTY.md` in full, then fetches other files on demand via `@filename` references. The system attaches no file listing beside `DUTY.md`: knowledge files sit under the `knowledge/` directory of the session workspace, and the agent finds them with ls / glob / grep the way it browses a code repository, so files that `DUTY.md` does not reference can still be found.
If a scope has no `DUTY.md` yet, that scope is not silently skipped: the system tells the agent that this scope has no guide and which directory holds its files, and requires it to list that directory and read the relevant files before doing substantive work.
@@ -71,8 +65,6 @@ After reading `DUTY.md`, the agent decides which `@references` to expand based o
## Maintain it in the console
----
-
Go to **AI SRE → Customize → Context → Knowledge**. Each row of the list is one knowledge, labeled by scope ("Shared" or the team name), with its file count, `DUTY.md` status, and last edit time. The `DUTY.md` status is one of **Not created**, **Up to date**, or **Needs refresh · N changes since** (other files changed after `DUTY.md` was written). Click **Create** to add knowledge for the Shared scope or for a team you belong to; when the account and every team available to you already have one, the button is disabled.
When no knowledge exists yet, the page shows a starter instead: **Set up AI-SRE** opens a new chat that runs [`/init`](/en/ai-sre/init), and **Upload existing docs** opens a new chat with the attachment picker open.
@@ -87,13 +79,13 @@ Files still have to meet the limits above: plain text, at most 1 MiB each, and a
### Ask AI to change it
-Below the body is an input box (placeholder: "How should the AI change this knowledge? e.g. add an OOM troubleshooting runbook"). Write what to change and send it: the console opens a new chat whose input already holds a reference to this knowledge and your request; for team knowledge, the chat switches to that team. Once sent, the AI first explains in text which files it will change and how, and saves only after you agree. The page itself offers no change preview or item-by-item review.
+Type what to change in the input box below the body (for example, "add an OOM troubleshooting runbook") and send it. The console opens a new chat with a reference to this knowledge and your request (switching to the team for team knowledge). The AI first explains which files it will change and how, and saves only after you agree.
**Let AI generate it** and **Let AI update it** (below) follow the same flow: they move to a new chat with the request already written.
### When DUTY.md needs a refresh
-If other files change after `DUTY.md` was written, a notice appears above the file tree: "Changes since DUTY.md was written: N. It may need updating." With edit permission, two actions sit below it:
+If other files change after `DUTY.md` was written, a notice above the file tree says it may need updating. With edit permission, you can:
- **Let AI update it**: moves to a new chat and has the AI update the `DUTY.md` index against the current files; the change is confirmed with you first.
- **Still accurate**: confirms `DUTY.md` is still correct. The notice disappears until the next file change.
@@ -104,8 +96,6 @@ If other files change after `DUTY.md` was written, a notice appears above the fi
## How the Agent Uses Knowledge
----
-
Knowledge is not all loaded at once — it follows a **catalog-first, expand-on-demand** pattern:
<Steps>
@@ -125,13 +115,11 @@ Knowledge is not all loaded at once — it follows a **catalog-first, expand-on-
</Tip>
<Warning>
- If knowledge fails to load into the current session, a warning banner appears above the message list: "Knowledge failed to load - AI-SRE may not have access to DUTY.md and runbooks in this session.", along with a **Retry** button that re-attempts the load. Until the retry succeeds, the agent may be unable to read DUTY.md and runbooks in that session.
+ If knowledge fails to load into the current session, a warning appears above the message list, and the agent may be unable to read DUTY.md and runbooks. Click **Retry** to load it again.
</Warning>
## Scope & Visibility
----
-
Every knowledge has a scope: Shared (account-level, visible across the entire account) or team-level.
| Dimension | Shared | Team |
@@ -141,7 +129,7 @@ Every knowledge has a scope: Shared (account-level, visible across the entire ac
| Loaded in session | All sessions | Only sessions bound to that team |
| Readable at runtime | All sessions | Sessions bound to that team, plus personal sessions whose creator belongs to that team (mounting occurs on read) |
-**Edit permissions**: team knowledge can be acted on only by members of that team — organization admins must join the team first; Shared knowledge can be acted on only by the Account Owner or admins; there is no "creator retains extra rights" rule. The console grays out rows the current user cannot edit, and disables toggles and action buttons when you lack edit permission.
+**Edit permissions**: team knowledge can be edited only by members of that team (organization admins must join the team first); Shared knowledge only by the Account Owner or admins. Creators have no extra rights.
**Create and reassign**: to create new team knowledge, you must belong to the target team; Shared-scope creation is limited to the Account Owner or admins. When editing existing knowledge, the Account Owner or admins can move it to any team to recover resources left behind by empty teams or departed members; regular members can move it only to teams they belong to. Promoting existing knowledge to Shared scope (**Set to Shared**) carries the same gate as Shared-scope creation: only the Account Owner or admins can do it — a regular member cannot self-serve this even for their own team's knowledge.
@@ -155,8 +143,6 @@ This two-level scope model applies uniformly to all resources within the account
## Best Practices
----
-
<AccordionGroup>
<Accordion title="Use DUTY.md as a catalog, not as body content" icon="book">
Keep `DUTY.md` to link lists and one-line descriptions only — all substantive content goes into the sibling files it `@references`. This keeps the catalog concise and readable, and lets the agent expand only the branches relevant to the current incident, avoiding irrelevant content consuming context.
@@ -180,8 +166,6 @@ This two-level scope model applies uniformly to all resources within the account
## Related Pages
----
-
<CardGroup cols={2}>
<Card title="Skills" icon="rocket" href="/en/ai-sre/skills">
Encapsulate reusable diagnostic workflows as Skills, sharing the same scope model as Knowledge.
@@ -192,7 +176,7 @@ This two-level scope model applies uniformly to all resources within the account
<Card title="Learn about Memory" icon="brain" href="/en/ai-sre/memory">
Preferences, procedures, facts, and lessons the AI notes in conversations, managed separately from knowledge.
</Card>
- <Card title="Console" icon="comments" href="/en/ai-sre/sessions">
+ <Card title="Console Chat" icon="comments" href="/en/ai-sre/sessions">
Learn how sessions bind to teams and how knowledge is read and mounted during a session.
</Card>
</CardGroup>
diff --git a/en/ai-sre/mcp.mdx b/en/ai-sre/mcp.mdx
index cee49789..a9ead0d1 100644
--- a/en/ai-sre/mcp.mdx
+++ b/en/ai-sre/mcp.mdx
@@ -2,17 +2,13 @@
title: MCP (External Tool Connections)
description: Use the Model Context Protocol (MCP) to connect AI SRE agents to external tools and data sources — such as GitHub, Slack, Kubernetes, and observability platforms. Configure MCP servers, authentication, and scope in the console; agents will call their tools on demand during a session.
keywords: ["AI SRE", "MCP", "Model Context Protocol", "MCP server", "external tools", "OAuth", "API Key", "agent"]
-sidebarTitle: MCP
+sidebarTitle: "MCP Tools"
---
-<Info>
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-</Info>
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
**MCP** (Model Context Protocol) lets AI SRE agents connect to external tools and data sources. Each **MCP server** is a standardized endpoint that exposes a set of tools (functions) — for example, querying GitHub issues, sending Slack messages, reading Kubernetes resources, or retrieving metrics from an observability platform.
Once you configure and enable an MCP server in the console, agents will **autonomously decide** when they need an external capability during incident investigation and call the corresponding tool directly — no manual data-shuttling required.
@@ -25,8 +21,6 @@ This is **different** from the [Flashduty MCP Server](/en/developer/mcp-server)
## What Is MCP
----
-
**MCP** (Model Context Protocol) is an open protocol that describes in a uniform way "what tools a server exposes, what parameters each tool accepts, and what it returns." Think of it as the "USB port" of the AI agent world — any MCP-compliant server can be discovered and called plug-and-play by an agent, with no per-system adapter code required.
In AI SRE, MCP extends an agent's capability from "built-in tools" to "any external system":
@@ -41,61 +35,51 @@ In AI SRE, MCP extends an agent's capability from "built-in tools" to "any exter
## Installing MCP Servers from the Marketplace
----
-
Go to **Customize → Plugins → Overview** to see Flashduty's curated catalog of third-party MCP templates. The catalog is grouped into category tabs (All / Observability / Cloud & Infrastructure / Database & Middleware / Code & Collaboration / Skill), and the search box in the top-right corner filters it by name or description.
-The **Recommended** block above the catalog ("Recommended from your alert sources and common usage. Once connected, AI SRE can use them during investigations.") picks the templates that match the **alert integrations already configured** in your account (ranked by alert count over the last 30 days), then fills in the picks promoted for your current locale, showing at most 3. Installed templates, templates that need a Runner, and templates you may not install never appear here.
+The **Recommended** block above the catalog suggests up to 3 templates based on the alert integrations configured in your account (ranked by alert volume over the last 30 days). Templates that are already installed, need a Runner, or that you cannot install are not recommended.
<Steps>
<Step title="Find the template to connect">
- Each catalog row shows the template name and description; when MCP / App / Skill rows are mixed on the same screen, the row also carries a kind tag. An uninstalled row has a round **+** button on its right: clicking **+** or clicking the row itself opens the **Connect** dialog. When a template needs a self-hosted Runner and the account has no Runner available, the row's tag reads **Requires a self-hosted runner**; for a template you may not install, the row shows no **+** and is not clickable.
+ Click a template row or its **+** to open the **Connect** dialog. Templates that need a self-hosted Runner when the account has none are marked **Requires self-hosted Runner**; templates you are not allowed to install cannot be clicked.
</Step>
<Step title="Review the template and fill in the connection parameters">
- The dialog first shows the template's details: the vendor ("Official Datadog · MCP" or "Community · MCP"), a link to its official docs, its description, and a set of "**Ask things like this once connected**" example questions. Then come the connection parameters the template declares — URL / endpoint placeholders and environment variables. **Shared** fields (shared account-wide under service authorization) are labelled "Shared by the whole account."; in **Member authorization (key)** mode there is also a "**Your API token**" field (a password input) labelled "Only for your own use — other members fill in their own the first time they use it.", with a "How to get one" docs link beside it.
+ The dialog shows the template's vendor, official docs, description and example questions, followed by the connection parameters. **Shared** fields are used by the whole account; templates in member authorization (key) mode also ask for **your own API token**, which other members enter separately on first use.
</Step>
<Step title="Pick an execution environment and submit">
- Choose the **execution environment** this connection should be made from — "Connects in the session's own environment by default."; for a template that needs a self-hosted Runner, the hint reads "If 〈name〉 is only reachable on your internal network, pick a self-hosted Runner on that network." The primary button is **Connect**; for a **Member authorization (OAuth)** template it reads "**Authorize 〈name〉**" and creates the connector first, then opens the browser authorization window (OAuth discovery, Dynamic Client Registration, and token exchange all run from the chosen environment; when the authorization server does not support DCR, fc-safari falls back to a Client ID Metadata Document — see "Authentication" below).
+ Choose the **execution environment** to connect from (defaults to the session's environment). For systems reachable only from an internal network, choose a self-hosted Runner on that network. For templates in member authorization (OAuth) mode, click the **Authorize** button and finish authorization in the browser; see [Authentication](#authentication).
</Step>
<Step title="Confirm the result">
- On submit, the system creates the connector and runs one connection test against it. On success the dialog shows "**〈name〉 connected**" plus the example questions: click **Done** to close it, or click an example question to open a new chat with that question **prefilled** (it is not sent automatically). On failure it shows "**The connection test failed**" with the raw error: click **Retry** to re-run the test; for a template that needs a Runner, a non-cloud environment also offers a "Let AI SRE install it on the Runner" entry, which opens a new chat that carries no token and asks the agent to install the missing command-line tools (`npx`'s Node.js, `uvx`'s uv) on the self-hosted Runner.
+ The system creates the connector and tests the connection. On success, you can click an example question to start a chat prefilled with it. On failure, the error is shown and you can **Retry**; templates that need a Runner can also have AI SRE install missing command-line tools on the Runner (such as Node.js for `npx` or uv for `uvx`).
</Step>
</Steps>
<Note>
-The dialog creates the connector on the **first submit only**. After that its connection parameters are locked, and it shows "This connector already exists, created from the values you first submitted. To change them, edit it under Plugins → MCP." When the name collides with a connector that already exists, the dialog no longer echoes the backend error and instead shows "This account already has a connector named “〈name〉”. If that is the one you want, finish authorizing it under Plugins → MCP; otherwise an account owner or admin has to rename or delete it there first, then connect again."
+Connection parameters are fixed at the first submit; to change them later, edit the server under **Plugins → MCP**. If a connector with the same name already exists in the account, use it, or have an account owner or admin rename or delete it before connecting again.
</Note>
-Installed MCP servers record a `source_template_name` field that points back to the originating template, making it easy to trace the server's provenance later. **Marketplace-installed MCP servers are fixed to Shared scope** (account-level, `team_id` is 0) and available to all members of the account; no team owner can be chosen at install time, and the same template can only produce one instance per account.
+MCP servers installed from the marketplace record their source template and are **always Shared scope** (available to all members of the account). Each template can be installed only once per account.
<Warning>
-A template that **requires a Runner** (the `requires_runner` flag in its details) can only be used in an environment where you have deployed a BYOC Runner; cloud Sandboxes do not support it. `requires_runner` is independent of transport, and today's 50-template catalog contains both kinds: 23 **HTTP Streaming** templates that need no Runner, and 27 **stdio** templates that do — including Alibaba Cloud OpenAPI, Alibaba Cloud Observability, Nightingale (n9e), Gitee, GreptimeDB, Prometheus, Grafana (Self-Hosted), Kafka (Confluent), AWS, ClickHouse, MySQL, PostgreSQL, Alibaba Cloud RDS, Redis, and MongoDB. Those stdio templates are launched locally on each environment via `uvx` / `npx`, and a cloud Sandbox cannot launch local subprocesses; confirm your account has a working BYOC Runner configured before installing. See [Environments (BYOC)](/en/ai-sre/environments).
+Templates that **require a Runner** work only on a BYOC Runner you deploy; cloud Sandboxes do not support them. Of the 50 templates in the marketplace today, 23 are **HTTP Streaming** and need no Runner; 27 are **stdio** and need one, including Alibaba Cloud OpenAPI, Alibaba Cloud Observability, Nightingale (n9e), Gitee, GreptimeDB, Prometheus, Grafana (Self-Hosted), Kafka (Confluent), AWS, ClickHouse, MySQL, PostgreSQL, Alibaba Cloud RDS, Redis, and MongoDB. They start locally via `uvx` / `npx`, so make sure the account has a working BYOC Runner before installing. See [Environments (BYOC)](/en/ai-sre/environments).
</Warning>
### Systems only Monitors can query
-The catalog also contains a class of rows for **systems only Monitors can query** (currently Loki, VictoriaLogs, and Oracle): they appear under their category (Observability / Database), and when MCP / App / Skill rows are mixed on the same screen they carry a `Monitors` kind tag. They are **not connectors you can onboard from the marketplace** — they are entry points meaning "once you add a datasource in Monitors, AI SRE can query this system" — so they never appear in the **Recommended** block above (that block lists connectable templates).
+The catalog also lists **systems queried through Monitors** (currently Loki, VictoriaLogs and Oracle). They cannot be connected from the marketplace: once you add such a data source in Monitors, AI SRE can query it directly, without an address, token or Runner. Clicking one of these rows shows the account's data sources of that type; click **Try it in chat** if some exist, or **Add more in Monitors →** if none do (requires permission to add data sources).
-Clicking such a row (or its **+**, which opens the same panel) opens a panel with **no Connect button**, showing only:
-
-- The account's **datasources of that type** and their status, e.g. "N connected · runs through the alert engine — no URL, token or Runner needed"; with none yet it reads "No 〈type〉 datasource yet · add one in Monitors and you can query it, no Runner needed". The row's **+** appears only while the account has no datasource of that type and you have permission to add one; otherwise that slot shows "N connected" or "Added by a Monitors admin".
-- When datasources of that type exist, the primary button is **Try it in chat**: it opens a new session prefilled with a question against your datasource (it is not sent automatically).
-- With none yet, it offers **Add more in Monitors →**, opening Monitors → Datasources → Add in a new tab (the type preselected); a member without add permission only sees "A Monitors admin adds it and this updates automatically" and is not offered that action.
-
-Some MCP templates support both routes — a direct MCP connector and the Monitors one (for example Prometheus, MySQL, PostgreSQL, ClickHouse, Elasticsearch, SLS). Those rows are tagged `MCP · Monitors` and their dialog adds an "Access method" choice between the two.
+Some templates (such as Prometheus, MySQL, PostgreSQL, ClickHouse, Elasticsearch and SLS) support both a direct MCP connection and querying through Monitors. They are labeled `MCP · Monitors`, and you choose the access method when connecting.
<Note>
-Row names share a namespace with template names: if a system already has a template of the same name, only the template row is shown (the template row is the one carrying connection parameters). On a private deployment **without the Monitors module**, these rows are not listed and a template's dialog offers no Monitors route — the list API returns `monit_available: false` and the console hides the related affordances based on it.
+Row names share a namespace with template names: if a system already has a template of the same name, only the template row is shown. On a private deployment **without the Monitors module**, these rows and the Monitors access method are not shown.
</Note>
## Adding an MCP Server
----
-
Go to **Customize → Plugins → MCP**. The list page has two entries in the top-right corner:
- **Add MCP**: opens a form for defining an MCP server by hand (its fields are listed under "Basic Fields" below).
-- **Add in chat**: opens a new AI SRE session with this prompt prefilled — "I want to add an MCP server. First ask whether I want to connect my own service or install an existing one. If it is an existing one, ask which system I want to connect. If the plugin catalog has it, install it; if not, search the web and show me a few to pick from. Install the one I choose." The agent first asks whether you want to connect your own service or install an existing one; for an existing one it checks the plugin catalog first and only searches the web for candidates when the catalog has none, then completes the connection once you pick (nothing is sent automatically — you can edit the prompt first). The button appears only when there is an unambiguous scope to write into: always when you can author at account scope, otherwise when the current scope filter selects exactly one team you belong to (or you belong to exactly one team).
+- **Add in chat**: opens a session with a prefilled prompt; the agent asks whether you want to connect your own service or install an existing one, checks the plugin catalog first, and searches the web for candidates if nothing matches. The button appears only when the target scope is unambiguous (you have account-level permission, or exactly one of your teams is selected).
### Basic Fields
@@ -104,11 +88,11 @@ Go to **Customize → Plugins → MCP**. The list page has two entries in the to
| Name | string | Yes | The server name, used as the identifier when agents call it (e.g., `sqlite-explorer` in `mcp:sqlite-explorer/query`). Must start with a letter; may only contain letters, digits, `-`, and `_`; length 1–255. **Case-insensitive and unique** within an account; cannot duplicate a built-in server name. |
| Transport | enum | Yes | How the agent communicates with the server. See "Transport" below. |
| Scope | Shared / Team | Yes | The scope of this MCP server: **Shared** (visible account-wide) or a specific **Team** (visible only to members of that team). See "Scope" below. |
-| Execution Environment | Cloud / BYOC Runners (multiple) | No | Controls where this MCP server is available. Select Cloud and one or more visible BYOC Runners; leave empty to make it available everywhere. It does not route calls: an MCP call still runs in the current AI SRE session's environment. For a service available only on a private network, select only the Runner(s) that can reach it. Conversely, when this list **does not** include the session's own environment, that session cannot call it directly — but the agent still knows the server exists and which environment can run it; see "Cross-environment connectors" below. See [Environments (BYOC)](/en/ai-sre/environments). |
+| Execution Environment | Cloud / BYOC Runners (multiple) | No | Where this server is available; if none are selected, it is available everywhere. Calls are always made from the session's own environment, so for services reachable only from an internal network select only Runners that can reach them. If the session's environment is not listed, see [Cross-environment connectors](#cross-environment-connectors). See [Environments (BYOC)](/en/ai-sre/environments). |
| Description | string | Yes | Describes what this server does, for identification in the list. |
<Note>
-Each MCP server also has an **AI description**: after an agent first lists a server's tools, the system automatically generates a capability summary from the tool list and displays it in the console. This summary refreshes automatically as the tool set changes — no manual maintenance needed.
+After an agent first lists a server's tools, the system generates an **AI description** shown in the list, and keeps it updated as the tools change.
</Note>
### Transport
@@ -124,13 +108,13 @@ Each MCP server also has an **AI description**: after an agent first lists a ser
</Warning>
<Note>
-stdio server commands run on the **machine where the Runner is deployed**, not on the machine of the person who configured them. Shared configuration must be portable: do not write personal machine paths into commands or arguments (e.g., `/Users/your-name/...`, `/home/your-name/...`), and make sure the executing environment has the runtime the command needs (`uv` / `uvx` / `node` / `npx`). A missing runtime makes the server fail to connect.
+stdio commands run on the **machine where the Runner is deployed**, not on your computer. Avoid personal paths (such as `/Users/<name>/...`), and make sure the Runner has the required runtime (such as `uv` / `uvx` / `node` / `npx`) installed; otherwise the connection fails.
</Note>
There is a default timeout for both connection and tool calls: 10 seconds for connection, 60 seconds for tool invocation.
<Warning>
-Use "Skip TLS certificate verification" only when the remote HTTPS MCP server uses a self-signed certificate and the network is controlled. After you enable it, the agent execution environment skips certificate-chain and hostname verification when connecting to that server. Do not use it for untrusted public endpoints.
+Enable "Skip TLS certificate verification" only when the HTTPS server uses a self-signed certificate and the network is controlled. Never enable it for untrusted public endpoints.
</Warning>
### Authentication
@@ -141,12 +125,15 @@ MCP servers support three **authorization modes** that determine how credentials
<Tab title="Service authorization (default)">
All sessions call with the same service identity. Credentials are written directly into the server configuration — for HTTP/SSE transport, in the **Headers** (JSON) (e.g., `{ "Authorization": "Bearer xxx" }`); for stdio transport, in the **environment variables** (JSON) (e.g., `{ "API_KEY": "xxx" }`). Suitable for internal systems accessed with account-level service tokens.
- Credentials are **encrypted at rest**: on save, any entry whose key name contains `KEY`, `SECRET`, `TOKEN`, `PASSWORD`, `PASSWD`, `CREDENTIAL`, or `AUTHORIZATION` (case-insensitive) has its value encrypted before storage and returned masked on read; in addition, an entry whose key name has a whole non-alphanumeric-delimited segment equal to `PWD` or `PASS` is treated the same way — `REDIS_PWD`, `db-pass` and a bare `PWD` all qualify, while `BYPASS` and `COMPASS` (which only contain that text inside a segment) do not. Entries matching none of these rules are stored as-is, so put credentials under a recognizable key name (such as `Authorization`, `X-API-Key`, or `GITHUB_TOKEN`).
+ Values under the following key names (case-insensitive) are **encrypted at rest** and shown masked; all other entries are stored as-is, so put credentials under such key names (for example `Authorization`, `X-API-Key`, `GITHUB_TOKEN`):
+
+ - names containing `KEY`, `SECRET`, `TOKEN`, `PASSWORD`, `PASSWD`, `CREDENTIAL` or `AUTHORIZATION`;
+ - names with a segment (split on non-alphanumeric characters) that is exactly `PWD` or `PASS` (such as `REDIS_PWD`, `db-pass`; `BYPASS` and `COMPASS` do not count).
- A service authorization means any session in the account can call the system as that service identity. If it exposes members' personal data or allows high-risk writes, prefer "Member authorization (key)" or "Member authorization (OAuth)".
+ Any session in the account can call the system with this identity. For personal data or high-risk write operations, use member authorization instead.
</Tab>
<Tab title="Member authorization (key)">
- Each member provides their own key the **first time** they invoke a tool on this server. Keys are encrypted and stored at the account level, isolated per member.
+ Each member provides their own key on **first use**. Keys are encrypted and isolated per member.
Selecting this mode requires filling in a **Key Schema**:
@@ -158,47 +145,41 @@ MCP servers support three **authorization modes** that determine how credentials
Suitable for third-party SaaS where each engineer uses their own API key (e.g., a personal GitHub token).
</Tab>
<Tab title="Member authorization (OAuth)">
- Each member authorizes individually via **OAuth 2.1**. An authorization window pops up automatically the first time a tool on this server is invoked. Server discovery and client registration are performed as needed: when the authorization server advertises a registration endpoint, fc-safari uses **Dynamic Client Registration (DCR)**; when there is no registration endpoint but the server declares **Client ID Metadata Document** support, fc-safari registers no client and instead uses the `/safari/oauth/client-metadata.json` document it publishes as its `client_id`, leaving the authorization server to fetch it by that URL — nothing extra to configure on your side. Tokens are stored per member and refreshed automatically near expiry. Suitable for services that support OAuth.
+ Each member authorizes individually via **OAuth 2.1**; an authorization window pops up on first use. Dynamic Client Registration (DCR) is supported; authorization servers that support Client ID Metadata Documents instead of DCR also work without extra configuration. Tokens are stored per member and refreshed automatically before they expire. Suitable for services that support OAuth.
</Tab>
</Tabs>
<Note>
-For "Member authorization (key)" and "Member authorization (OAuth)", if credentials are missing the agent's tool call is paused and a credential entry or authorization dialog is shown to the current member; execution resumes once credentials are supplied. In service authorization mode, no credentials are requested from members.
+In member authorization modes, a tool call with missing credentials pauses and prompts the current member to enter a key or authorize, then continues.
</Note>
### MCP Server Authorization (Settings)
-Member authorization credentials — both key and OAuth — are isolated **per member**, so besides the inline "prompted on demand during a conversation" path above, you can also **manage your own authorization** for an MCP server directly **in settings** — both paths write to the **same** per-member credential.
+Member authorization credentials (key or OAuth) are isolated per member. Besides authorizing when prompted in a chat, you can manage your own authorization from the MCP list; both paths save the same credential.
-**Auth-status chip in the list**: the MCP list's **Member authorization** column shows a per-viewer auth-status chip for each MCP server, reflecting the **current viewer's** credential. The wording depends on the authorization mode — since a saved member key is never verified for validity, it deliberately avoids the word "Connected":
+**Authorization status**: the **Member authorization** column of the MCP list shows your own status:
-- **Member authorization (OAuth)**: **● Connected** (a valid credential is saved) / **○ Disconnected** (no credential provided yet).
-- **Member authorization (key)**: **● Saved** (a key is saved) / **○ Not set** (no key provided yet).
-- Shared across both modes: **⚠ Expired** (the credential has expired — OAuth token lapsed — and needs re-authorization).
+- **Member authorization (OAuth)**: **● Connected** / **○ Disconnected**.
+- **Member authorization (key)**: **● Saved** / **○ Not set**. The key is not checked for validity.
+- Both modes: **⚠ Expired** (the OAuth token has expired and needs reauthorization).
-MCP servers using service authorization have no per-member authorization step and render a dash ("—"). For a server that needs your personal credential, open the **Credential** dialog from its authorization entry in the list. It manages only your credential and never changes the server endpoint, authorization mode, or scope.
+Service authorization shows a dash ("—"). Click the authorization entry to open the **Credential** dialog; it manages only your own credential and does not change the server's configuration.
-**Actions in the Credential dialog**: the dialog offers actions based on its authorization mode and your current credential state:
+**Actions in the Credential dialog**:
-- **Member authorization (OAuth)**: first choose an **execution environment**, then click **Authorize** (when disconnected) / **Reauthorize** (when connected or expired). Choose a Cloud Sandbox or an online BYOC Runner; **Auto** is not available. OAuth discovery, Dynamic Client Registration, token exchange, and later refreshes all run from that environment (when the authorization server does not support DCR, fc-safari falls back to a Client ID Metadata Document — see "Authentication" above). On each open, the dialog prefers the last successful environment if it is still online, then an online runner bound to the connector, and finally the Cloud Sandbox. For an OAuth service reachable only on a private network, choose a BYOC Runner that can reach it. A browser popup then opens the authorization window (initiated via `/safari/credentials/oauth/initiate`, which returns an authorize URL opened in the popup).
-- **Member authorization (key)**: click **Enter Key** (when disconnected) / **Update Key** (when connected) to open the secret-entry modal, which submits to `/safari/credentials/secret`.
-- **Revoke**: when a credential exists, click **Revoke** (via `/safari/credentials/revoke`) to delete your saved credential; the status returns to Disconnected.
-
-<Note>
-OAuth authorization completes through a browser **bounce page** at `/oauth-callback`: the authorization server calls back to fc-safari, which then 302-redirects to the bounce page; the page `postMessage`s the result to the window that initiated the flow (the settings page or the chat page) and closes itself automatically. No manual token copy-pasting is required.
-</Note>
+- **Member authorization (OAuth)**: choose an **execution environment** (the cloud Sandbox or an online BYOC Runner; "Auto" is not available), then click **Authorize** or **Reauthorize** and finish in the browser window, with no tokens to copy. For OAuth services reachable only from an internal network, choose a Runner that can reach them. The last environment that authorized successfully and is still online is preselected.
+- **Member authorization (key)**: click **Enter Key** or **Update Key**.
+- **Revoke**: deletes your saved credential.
## Management & Inspection
----
-
-The MCP list displays each server's **name** (including its AI description), **scope** (Shared or team name), **transport**, an **enabled** toggle, and an **actions** column — the list only contains MCP servers you have added to the account; the built-in Flashduty MCP server is injected by the runtime and does not appear in this list, see "Inspection" below. The scope filter bar at the top lets you switch between All / Shared / Team views, and the search box to its right filters the list by keywords in the name, description, transport, or URL.
+The MCP list shows each server you added with its name and description, scope (Shared or team), transport and enabled state. You can filter by All / Shared / Team and search by name, description, transport or URL. The built-in Flashduty MCP server is not listed.
<AccordionGroup>
<Accordion title="Enable / Disable" icon="toggle-on">
Toggle the switch in the list. Only **enabled** servers are available to the agent; disabled servers are invisible to agents and cannot be called.
- A disabled connector (any status other than `enabled`) is **not reported as connected** by the connect entry point: opening its **Connect** dialog shows "**Connector disabled**" and "This connector is disabled, so AI SRE can't use it. An account owner or admin has to re-enable it under Plugins → MCP.", with an **Open Plugins → MCP** button that jumps to that connector's row. An account owner or admin re-enables it there with the **Enable** toggle. Disabled connectors also drop out of the **Enabled** strip on Plugins → Overview.
+ A disabled connector cannot be used from the **Connect** entry and does not appear in the enabled section of **Plugins → Overview**; an account owner or admin must re-enable it under **Plugins → MCP**.
</Accordion>
<Accordion title="Edit" icon="pen-to-square">
Click the edit button (or click the row) to open the form. You can modify the name, transport, description, endpoint/command, authorization mode, and scope. If you do not have edit permission, the form opens in **read-only** mode with an explanation.
@@ -210,33 +191,29 @@ The MCP list displays each server's **name** (including its AI description), **s
### Inspection: Viewing the Tools a Server Exposes
-The tools an MCP server exposes are discovered **during a session** by agents on demand — not displayed statically in the console. This is because the same MCP server may have different reachability and tool sets across different environments (Runners); connection state and tool count are per-environment properties, not global ones.
+The console does not list the tools an MCP server exposes, because the same server may be reachable with different tools in different environments.
<Tip>
To confirm which tools a given MCP server actually exposes in a particular environment, the most direct way is to ask the agent in **Chat** to list that server's tools — it will show the tools and how to use each one. See [Conversations](/en/ai-sre/sessions).
</Tip>
<Note>
-Reading Flashduty incidents, alerts, and other data is a **built-in** agent capability: the **Flashduty MCP server** is injected directly into the agent at the start of every session by the runtime, bypassing this page's MCP server list API — it does not appear in the server list above, and there is nothing to configure, enable, or view here for it. This capability is maintained by the platform and is available to every account by default.
+Reading Flashduty incidents, alerts and other data is a **built-in** agent capability (the Flashduty MCP server). It is available by default and is not configured here.
</Note>
### Cross-environment connectors
-An MCP server can be bound to execution environments **other than the current session's own**. That session cannot call it directly — execution environments do not share a network, and a tool call is always made from the session's own environment. But the agent does not conclude the connector is absent:
+An MCP server may be bound to execution environments **other than the current session's**. Because environments do not share a network, the session cannot call it directly, but the agent knows it exists:
-- **The agent knows about it from the start**: at session start the agent sees the connectors that are connected but bound to another execution environment — their names, what they do, and **which execution environments they run in**. The same connector can resolve to different names in different environments, so directory entries carry a team annotation to keep them distinguishable.
-- **A search states where it can run**: when a search matches such a connector, the result carries the environments it runs in.
-- **Asking for it by name is not answered with "not found"**: when the agent looks a connector up by name, it gets an explanation that the connector is connected but bound to another execution environment, plus how to use it — rather than being told the account has no such thing.
-- **The way to use it is to dispatch a subagent into that environment**: the agent hands the work to a subagent running in the target execution environment (`agent_dispatch`'s `environment` argument — see [Agent](/en/ai-sre/agents)), and that subagent discovers and calls the server's tools on its own side, then brings the results back into the conversation.
-- **Only environments it can actually dispatch to are listed**: the targets are **account-scope Runners** plus the Runners of the **team the current session is bound to**, and online ones (plus the bound cloud environment). Environments that are offline, never connected, deleted, or scoped to a team this session cannot dispatch to are annotated with the reason, and the agent says so plainly instead of pretending the call is possible.
-- **Only the conversation's main session sees this directory**: a dispatched subagent has no dispatch capability of its own and reports only the connectors it can call directly in its own environment; when another environment is needed, the subagent reports back to its parent.
+- The agent sees the connector's name, purpose and available environments, and asking for it by name gets an explanation rather than "not found".
+- The agent dispatches a subagent into the target environment to call it (see [Agents](/en/ai-sre/agents)) and brings the result back to the conversation.
+- Only **online** account-level Runners, Runners of the team bound to the session, and the bound cloud environment are valid targets; for others the agent explains it cannot use them right now.
+- Only the main session can dispatch this way; subagents cannot dispatch further.
Conversely, to make a connector directly usable **here**, add the current environment to that server's Execution Environment list (provided the server is reachable from this session). See [Environments (BYOC)](/en/ai-sre/environments) for how the environments themselves differ.
## Scope
----
-
MCP shares the same **two-level scope** model as other resources (Skills, Knowledge, Agents, Environments), divided into Shared scope and team scope:
| Scope | Visibility |
@@ -244,15 +221,18 @@ MCP shares the same **two-level scope** model as other resources (Skills, Knowle
| Shared | Visible to all members of the account |
| Team-level | Visible only to members of that team |
-**Edit permissions**: team-level MCP servers can be acted on only by members of that team — organization admins must join the team first; Shared-scope MCP servers can be acted on only by the account owner or admins. There is no creator-retains-rights exception. When you lack edit permission, the toggle and action buttons for that row appear as **read-only**.
+**Edit permissions**: team-level MCP servers can be edited only by members of that team (organization admins must join the team first); Shared-scope servers only by account owners or admins.
-**Create and reassign**: to create a new team-level MCP server, you must belong to the target team; Shared-scope creation is limited to the account owner or admins. **Marketplace installs are the exception**: they are fixed to Shared scope and started by the installer, and any account member can install an ordinary template (no owner/admin permission required). One class of template is the exception to that exception: when a template in a **member authorization** mode (key or OAuth) also asks for a free-form address / host parameter, the installer would effectively decide where other members' credentials are sent — so, to keep other members' credentials from flowing to a host the installer chose, installing and connecting that template is **limited to the account owner or admins**. A regular member sees no **+** on that row (and cannot click it), and opening its **Connect** dialog directly says "You don't have permission to install this. Ask your account owner or an admin." When editing an existing MCP server, the account owner or admins can move it to any team to recover resources left behind by empty teams or departed members; regular members can move it only to teams they belong to. However, **Marketplace-installed MCP servers cannot be reassigned to a team** — their scope is shown as a fixed Shared value in the edit form. A small number of legacy team-scoped Marketplace rows from earlier versions can still be changed back to Shared scope; the reverse is not allowed. **Promoting to Shared scope carries the same gate as Shared-scope creation: only the account owner or admins can do it** — a regular member is denied even for servers belonging to their own team, and the prompt now reads "ask an admin to make it shared" instead of naming the owning team.
+**Create and reassign**:
-**Runtime visibility**: At session start, the agent is offered only **Shared-scope** MCP servers and servers belonging to the **team bound to the current session**. Once the agent reads a team's knowledge during an investigation, that team's MCP servers and Skills are mounted into the session on demand. **The account is the only security boundary at runtime; the team is an ownership and editing tag only.**
+- Creating a team-level server requires membership in that team; creating a Shared-scope server is limited to account owners or admins.
+- Marketplace installs are always Shared scope and any member can install them. Exception: templates in member authorization mode that also take a free-form address can be installed only by account owners or admins, so that other members' credentials are not sent to an address chosen by the installer.
+- Account owners or admins can move a server to any team (for taking over resources of empty teams or departed members); regular members can move it only to teams they belong to.
+- Marketplace-installed servers cannot be moved to a team; a few early team-level installs can be changed back to Shared scope by an account owner or admin.
-## Related Pages
+**Runtime visibility**: at session start, the agent can use only Shared-scope MCP servers and those of the team bound to the session; servers and Skills of another team are loaded on demand after the agent reads that team's knowledge. **The account is the only security boundary at runtime; teams only determine ownership and edit permissions.**
----
+## Related Pages
<CardGroup cols={2}>
<Card title="Skills" icon="wrench" href="/en/ai-sre/skills">
@@ -264,7 +244,7 @@ MCP shares the same **two-level scope** model as other resources (Skills, Knowle
<Card title="BYOC" icon="server" href="/en/ai-sre/environments">
stdio MCP servers must run on a BYOC Runner; learn the difference between cloud Sandbox and self-hosted environments.
</Card>
- <Card title="Console" icon="comments" href="/en/ai-sre/sessions">
+ <Card title="Console Chat" icon="comments" href="/en/ai-sre/sessions">
Observe how agents inspect and invoke MCP tools during a session.
</Card>
<Card title="Flashduty MCP Server (Developer)" icon="code" href="/en/developer/mcp-server">
diff --git a/en/ai-sre/memory.mdx b/en/ai-sre/memory.mdx
index 36dcc3d4..a7f45ef2 100644
--- a/en/ai-sre/memory.mdx
+++ b/en/ai-sre/memory.mdx
@@ -2,25 +2,19 @@
title: Learn about Memory
description: Memory is the preferences, procedures, facts, and lessons the AI notes in conversations, and later conversations use them automatically. View and edit it at AI SRE → Customize → Context → Memory. Personal and team scopes stay separate.
keywords: ["AI SRE", "memory", "preference", "context", "personal", "team"]
-sidebarTitle: Learn about Memory
+sidebarTitle: "Memory"
---
-<Info>
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-</Info>
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
A new session starts from the memory files already in the current scope. If you had to re-explain your habits, where to look first for a kind of failure, or why a previous approach was abandoned, troubleshooting would begin with the same background every time. Memory keeps those points as Markdown files and later sessions reuse them.
Memory is not [knowledge](/en/ai-sre/knowledge). People maintain knowledge, and it describes how the environment runs. The system organizes memory: preferences, procedures, facts, and lessons kept from conversations. Both belong to the console's [Context](/en/ai-sre/context) group, but each has its own page: **AI SRE → Customize → Context → Memory**.
## Memory Types
----
-
Each memory file starts with a name, a one-line description, and a type. There are four types:
| Type | What it is for |
@@ -34,8 +28,6 @@ Where the file is saved follows the session. A session bound to a team writes th
## How Memory Is Created
----
-
Memory arrives in two ways:
- **You ask for it.** In the conversation, tell the assistant to remember, change, or forget something. It writes or updates the matching memory file.
@@ -45,16 +37,12 @@ Both ways write into the scope of the current session.
## How the Agent Uses Memory
----
-
When a session starts, the memory files in the current scope are ready. The assistant sees each file's name and description first, and opens the body when it needs the detail. A session bound to a team uses that team's memory. A session with no team uses your personal memory.
The four types carry different weight: procedure, fact, and lesson are past records that must be checked against the current situation before use; preference is a request you made explicitly, followed within its stated scope, and it wins when it conflicts with a Skill's or tool's default behavior.
## Scope & Isolation
----
-
Memory has only two scopes, personal and team. There is no account-level memory, and cross-account reads are rejected outright.
| Dimension | personal | team |
@@ -68,8 +56,6 @@ This isolation follows the same permission model as other AI SRE resources: team
## View and edit it in the console
----
-
Go to **AI SRE → Customize → Context → Memory**.
- **Pick a scope**: switch between **Personal** and **Team** at the top; for Team, pick one of your teams from the dropdown. There is no Shared (account-level) memory. The scope and team are kept in the page URL, so a refresh or a shared link opens the same set of memories.
@@ -85,8 +71,6 @@ With edit permission, an input box sits below the body (placeholder: "What shoul
## Related pages
----
-
<CardGroup cols={2}>
<Card title="Learn about Context" icon="layer-group" href="/en/ai-sre/context">
How memory and knowledge differ, and what personal, team, and shared scopes each contain.
diff --git a/en/ai-sre/overview.mdx b/en/ai-sre/overview.mdx
index 602c2294..75eedf22 100644
--- a/en/ai-sre/overview.mdx
+++ b/en/ai-sre/overview.mdx
@@ -11,8 +11,6 @@ sidebarTitle: Overview
## What Is AI SRE
----
-
AI SRE is Flashduty's autonomous SRE agent platform. You give the AI instructions through conversation, and it independently investigates incidents, diagnoses root causes, calls tools to run diagnostics, and captures the operational knowledge gained from each investigation for future reuse.
It is not a simple Q&A chatbot — it is a **hands-on troubleshooting worker**: it plans its own steps, reads and writes files, queries monitoring and logs, executes commands, calls external tools (MCP), and delegates subtasks when needed, ultimately delivering conclusions backed by a full investigation trail.
@@ -30,8 +28,6 @@ AI SRE is deeply integrated with Flashduty's incident response system. When Flas
## Typical Use Cases
----
-
AI SRE is more than a chat box in the console — it covers multiple collaboration entry points across the full lifecycle from incident trigger to retrospective:
<CardGroup cols={2}>
@@ -51,15 +47,13 @@ AI SRE is more than a chat box in the console — it covers multiple collaborati
## Activation and billing
----
-
AI SRE is available to accounts holding a **valid (enabled)** On-call Pro or higher subscription, with no application needed.
<AccordionGroup>
<Accordion title="Billing" icon="gift">
AI SRE is billed on actual usage starting September 16, 2026, 08:00 Beijing time, settled in credits (1 credit = ¥1); usage before that date isn't charged. Metered items are model usage, sandbox online time, and web search. Activation is free, eligible accounts get gift credits each billing period, and you can also buy credit packages (1,000 / 5,000 / 20,000 credits for ¥950 / ¥4,500 / ¥17,000, valid 365 days from payment). Pay-as-you-go is off by default; an admin can turn it on and optionally set a per-period cap. Full terms: [AI SRE Credit Package Purchase Agreement](/en/compliance/ai-sre-credit-package-purchase-agreement).
- When the gift credits, credit packages, and wallet balance are all used up, AI SRE refuses new conversation requests: the composer is disabled and a **non-dismissible** notice stays pinned above it (the text comes from the server and covers all four shapes — "not activated yet", "turned off", "this period's allowance is spent", and "the wallet is empty"), with a **Go to AI SRE billing** button that opens the billing center (`/wallet/plan?product=ai-sre`). An admin turns on pay-as-you-go, buys a credit package, or tops up the wallet there; once the state recovers, you can continue the conversation. A lapsed subscription, or a plan that doesn't include AI SRE, is a different kind of block whose banner button becomes **Go to On-Call subscription** — see [When the subscription lapses](#when-the-subscription-lapses).
+ When gift credits, credit packages and the wallet balance are all used up, AI SRE pauses new conversations and shows the reason above the composer with a **Go to AI SRE billing** button. An admin can turn on pay-as-you-go, buy a credit package or top up there, and you can then continue.
</Accordion>
<Accordion title="Human Authorization" icon="user-check">
Production changes, restarts, rollbacks, and external notifications all require your confirmation before they execute.
@@ -68,58 +62,33 @@ AI SRE is available to accounts holding a **valid (enabled)** On-call Pro or hig
### Activating and closing AI SRE
-Both directions are self-service on the same card in the console: open the billing center from the left navigation (**Payment** → **Plan**, the page titled "Your Plans") and select the **AI SRE** tab — that is `/wallet/plan?product=ai-sre`, the same destination as the **Go to AI SRE billing** entry in the credits notice. The billing center is available on SaaS only, so On-Premises deployments have no such tab.
+In the console, open **Payment → Plan** and select the **AI SRE** tab to activate or close AI SRE yourself. This is available on SaaS only and requires the **Payment Read** and wallet purchase permissions.
-Opening the page requires **Payment Read**. The **Enable AI SRE** and **Disable AI SRE** buttons additionally require wallet purchase permission (the console's own wording next to the activation entry is "Wallet purchase permission required"); without it the buttons are disabled and hovering shows "You are not authorized for this operation".
-
-| Action | Button | Cost | Result |
-|--------|--------|------|--------|
-| Enable | **Enable AI SRE** (shown while the card reads **Not enabled**) | ¥0, nothing is charged | Places a ¥0 order; once it completes, the card reads **Enabled** |
-| Disable | **Disable AI SRE** (shown while the card reads **Enabled**) | ¥0, nothing is charged and nothing is refunded | Places a ¥0 unsubscribe order; the order completes once the server confirms the service is off, and the card reads **Not enabled** again |
-
-**Disable AI SRE** first opens a confirmation dialog, "Disable AI SRE?", whose body reads "After you disable it, this account can no longer start AI SRE investigations. Purchased credit packages and gift credits are retained, and you can enable it again at any time." Once you confirm, the console polls the order status and reports one of the following:
-
-| Order outcome | Console message |
-|---------------|-----------------|
-| Completed | AI SRE disabled |
-| Still no terminal state after about a minute of polling (order still being processed) | Your request to disable AI SRE was submitted and is still being processed. Refresh in a moment to see the result. |
-| Failed | Failed to disable AI SRE. Please try again. |
-
-What disabling changes:
+| Action | Cost | Result |
+|------|------|------|
+| **Enable AI SRE** | Free | AI SRE is available right away |
+| **Disable AI SRE** | No charge and no refund | The account can no longer start new investigations; a run already in progress is not interrupted and its usage is still metered |
-- **No new investigations**: after you disable it, this account can no longer start AI SRE investigations, and a refused request gets the server's own sentence, "AI SRE is turned off for this account. Turn it back on to continue." (the credits overview reports `blocked_reason=turned_off`). A top-level run that has already started is not interrupted, and the usage it goes on to produce is still metered.
-- **Credits and packages are retained**: neither the gift credits nor the balance and validity of purchased credit packages are cleared by disabling the service, and they are usable again after you re-enable it (gift credits themselves remain usable only within the billing period they were granted for, per the Agreement). Re-enabling is simply running **Enable AI SRE** again — nothing else is required.
-- **Nothing is charged or refunded**: disabling itself costs nothing and triggers no refund; package refunds still follow the [AI SRE Credit Package Purchase Agreement](/en/compliance/ai-sre-credit-package-purchase-agreement).
-- **Arrears and a lapsed subscription do not block it**: disabling checks neither the wallet balance nor a valid On-call subscription, so an account in arrears or with a lapsed subscription can still turn the service off.
+After closing:
-<Warning>
-Disabling requires the server to confirm the service is off. If that confirmation fails, the order is not completed and the console shows "Failed to disable AI SRE. Please try again." — retry directly; nothing else has to be done first.
-</Warning>
+- Gift credits and purchased credit packages **keep** their balances and validity and are available again when you re-activate (gift credits are still valid only in the billing period they were granted for).
+- Credit package refunds follow the [AI SRE Credits Package Purchase Agreement](/en/compliance/ai-sre-credit-package-purchase-agreement).
+- You can close AI SRE even with an overdue balance or a lapsed subscription.
+- If closing fails, simply retry.
### When the subscription lapses
-Every request re-checks the account's On-call subscription, so a subscription that lapses pauses AI SRE immediately. The interface shows the server's own sentence, and distinguishes two cases whose remedies differ — don't apply the wrong one:
+AI SRE requires an **active** On-call Pro or higher subscription. When that is not the case, AI SRE pauses immediately, and the console, IM, automations and A2A calls report why:
-| Case | Notice | Remedy |
-|------|--------|--------|
-| The subscription's tier is Pro or higher, but the subscription isn't enabled (expired, or disabled for any other reason) | "This account's On-call subscription is no longer active (expired or disabled), so AI SRE is paused. It resumes automatically once the On-call subscription is renewed." | Renew the On-call subscription |
-| The account has no subscription, or its subscription is below Pro (whether or not it is enabled) | "AI SRE requires the On-call Professional plan. Upgrade the subscription to continue." | Upgrade to Pro or higher |
+| Situation | What to do |
+|------|----------|
+| A Pro or higher subscription has expired or been disabled | Renew the On-call subscription |
+| No subscription, or a plan below Pro | Upgrade to Pro or higher |
-The notice also appears in the console chat page, in IM sessions, in automation run records, and in A2A call errors; the credits overview reports the same sentence as `blocked_reason=no_license`.
-
-On the console chat page it stays pinned above the composer, and the button on its right **follows the blocking reason**:
-
-| Blocking reason | Button | Destination |
-|-----------------|--------|-------------|
-| The subscription lapsed, or the plan doesn't include AI SRE (`blocked_reason=no_license` — the two cases on this page) | **Go to On-Call subscription** | The page that sells the On-call subscription, `/wallet/plan?product=oncall` |
-| Everything else (not activated yet, turned off, this period's allowance spent, wallet empty) | **Go to AI SRE billing** | The page that sells AI SRE credits, `/wallet/plan?product=ai-sre` |
-
-A subscription block never points at AI SRE billing — that page sells AI SRE credits, which fixes nothing about the subscription. Recovery needs no re-activation: once the renewal or upgrade lands, the next request is admitted automatically.
+In the console the button next to the notice is then **Go to On-Call subscription** (for other reasons it is **Go to AI SRE billing**). After renewing or upgrading, AI SRE resumes automatically without re-activation.
## Core Capabilities
----
-
AI SRE is built around "conversational troubleshooting + knowledge accumulation + autonomous execution," with every capability configurable and manageable from the console.
<CardGroup cols={2}>
@@ -157,8 +126,6 @@ AI SRE is built around "conversational troubleshooting + knowledge accumulation
## Console Navigation
----
-
After entering AI SRE, the left sidebar has four entries (menu names match the console):
| Entry | Purpose |
@@ -182,16 +149,12 @@ Visibility of each area is determined by your access permissions in the account:
## Quick Start
----
-
For the full walkthrough from activating access to finishing your first investigation, see [Quickstart](/en/ai-sre/quickstart).
## Next Steps
----
-
<CardGroup cols={2}>
-<Card title="Console" icon="comments" href="/en/ai-sre/sessions">
+<Card title="Console Chat" icon="comments" href="/en/ai-sre/sessions">
Learn about sessions, streaming output, cancellation and context compaction, and how to launch an investigation from an incident.
</Card>
<Card title="IM Platform" icon="comment-dots" href="/en/ai-sre/im">
diff --git a/en/ai-sre/quickstart.mdx b/en/ai-sre/quickstart.mdx
index d82e2ad6..1dc1c3ba 100644
--- a/en/ai-sre/quickstart.mdx
+++ b/en/ai-sre/quickstart.mdx
@@ -11,8 +11,6 @@ sidebarTitle: Quick Start
## Key Concepts (30 Seconds)
----
-
Four things to know before you start:
| Concept | What it is |
@@ -24,8 +22,6 @@ Four things to know before you start:
## Three Entry Points
----
-
There's no single way into AI SRE — start from wherever you already are:
### Chat
@@ -42,8 +38,6 @@ Where incidents actually happen. In any Slack, Feishu, DingTalk, or WeCom group
## Your First Investigation (~5 min)
----
-
Prerequisite: at least one incident in your account. AI SRE needs no application; starting September 16, 2026, 08:00 Beijing time, activate it in the console first.
If you don't have an incident on hand right now, skip ahead to "Growing It Into Your SRE" below.
@@ -80,8 +74,6 @@ If you don't have an incident on hand right now, skip ahead to "Growing It Into
## Growing It Into Your SRE (As Needed)
----
-
Your first investigation is just the starting point. From here you can make analysis automatic, and keep sharpening its diagnoses — the latter depends on how much it knows about your systems and how much real data it can reach. All of this builds up over time, not all at once.
### Get every new incident analyzed automatically
@@ -119,8 +111,6 @@ Permission rules (limiting what the agent may do on that machine), upgrades, and
## What's Next
----
-
<CardGroup cols={2}>
<Card title="Product Overview" icon="robot" href="/en/ai-sre/overview">
What AI SRE is, its full capability set, and console navigation.
diff --git a/en/ai-sre/sandbox.mdx b/en/ai-sre/sandbox.mdx
index 00868f03..a317c4e4 100644
--- a/en/ai-sre/sandbox.mdx
+++ b/en/ai-sre/sandbox.mdx
@@ -5,14 +5,10 @@ keywords: ["AI SRE", "cloud sandbox", "Sandbox", "environment", "fallback", "egr
sidebarTitle: Sandbox
---
-<Info>
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-</Info>
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
The **cloud sandbox** is a **temporary execution environment** managed by Flashduty — an isolated, ready-to-use container. The AI SRE agent's tool calls (running commands, reading and writing files, running Skills, connecting to MCP) all happen inside it, and you **don't have to install or maintain anything**.
It is AI SRE's **default fallback**: when no usable self-hosted Runner ([BYOC Runner](/en/ai-sre/environments#byoc-runner)) is online for the current member, sessions automatically run in the cloud sandbox; you can also **pin a session to it manually**.
@@ -30,8 +26,6 @@ The cloud sandbox executes on the hosting provider's serverless platform, in **H
## When to use the cloud sandbox
----
-
The cloud sandbox is best for **investigations that don't depend on your private network**, and for getting started quickly:
- **Quick start / demos**: you haven't deployed a Runner yet and want to try AI SRE's troubleshooting first;
@@ -44,8 +38,6 @@ The cloud sandbox **cannot reach your private network**: its egress is restricte
## Using it in a session
----
-
The **environment selector** at the bottom of the chat box decides where the session executes. Two of its options relate to the cloud sandbox:
| Option | Behavior |
@@ -59,8 +51,6 @@ The environment choice is **locked once per session**: the environment determine
## Cloud sandbox vs. self-hosted Runner
----
-
| Dimension | Cloud sandbox | Self-hosted Runner ([BYOC Runner](/en/ai-sre/environments#byoc-runner)) |
|---|---|---|
| Deployment | No install, system-managed | Deploy a persistent process on your own machine |
@@ -75,13 +65,11 @@ The two aren't mutually exclusive: keep sessions on **Auto** day to day — they
## Related pages
----
-
<CardGroup cols={2}>
<Card title="BYOC Runner" icon="server" href="/en/ai-sre/environments#byoc-runner">
Deploy a persistent Runner on your own machine so investigations reach your private network.
</Card>
- <Card title="Console" icon="comments" href="/en/ai-sre/sessions">
+ <Card title="Console Chat" icon="comments" href="/en/ai-sre/sessions">
See the execution environment and status bound to a session.
</Card>
<Card title="MCP (External Tools)" icon="plug" href="/en/ai-sre/mcp">
diff --git a/en/ai-sre/sessions.mdx b/en/ai-sre/sessions.mdx
index 19ce4245..fd3e5760 100644
--- a/en/ai-sre/sessions.mdx
+++ b/en/ai-sre/sessions.mdx
@@ -1,545 +1,333 @@
---
-title: Console
+title: "Console Chat"
description: An AI SRE session holds one complete conversation between you and the agent, including messages, streaming responses, tool calls, and artifacts. This page covers creating and managing sessions, sharing, sending messages, the task panel and background tasks, previewing artifacts, session forking, context compaction, team binding, and session data export.
keywords: ["AI SRE", "session", "chat", "streaming response", "tool call", "task panel", "background tasks", "Artifacts", "Fork", "context compaction", "team binding", "export", "NDJSON"]
-sidebarTitle: Console
+sidebarTitle: "Console Chat"
---
-<Info>
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-</Info>
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
A session is one complete conversation between you and AI SRE. It holds every message you send, the agent's streaming replies, tool calls made along the way, and any artifacts the agent produces (such as code, reports, charts, or Skill archives).
-Each session is fully independent, with its own context, bound team, and environment. You switch between sessions in the left sidebar, and exchange messages, read replies, and view artifacts in the central chat area.
-
-<Note>
-Sessions are isolated from one another: context, bound team, and environment do not affect each other. Switching sessions does not interrupt a turn that is already running — AI SRE keeps writing progress to the session, so when you return you can still see the streaming output.
-</Note>
+Each session is isolated, with its own context, bound team, and environment. You switch between sessions in the left sidebar, and exchange messages, read replies, and view artifacts in the central chat area. Switching sessions does not interrupt a running turn; when you come back, the streaming output is still there.
## Creating and Managing Sessions
----
-
-The left sidebar is the single entry point for sessions. Click **New Chat** to start a fresh session. The list is sorted by most recent activity in descending order; only the most recent entries are shown initially, and older history is revealed incrementally with **Show more**.
+Click **New Chat** in the left sidebar to start a session. The list is sorted by recent activity; click **Show more** for older sessions.
-In a blank AI SRE session, four scenario suggestion cards appear above the composer: **Investigate an incident**, **Query data with natural language**, **Reduce alert noise**, and **Schedule an automated inspection**. Selecting a card only fills the composer; it does not send the prompt. You can edit it before pressing Enter.
+A new session shows four suggestion cards above the input: **Investigate an incident**, **Query data with natural language**, **Reduce alert noise** and **Schedule an automated inspection**. Clicking a card fills in a prompt you can edit before sending.
### Search and Filter
-<Steps>
- <Step title="Search chats">
- The search box at the top filters sessions by name. When there are no results, it displays **No matching chats found**.
- </Step>
- <Step title="Filter by scope / creator / status / activity">
- Click the **Filter** icon in the upper-right corner of the list to open the filter panel and combine the dimensions below. When any non-default filter is active, a small dot appears on the filter button as a reminder.
- </Step>
-</Steps>
-
-Dimensions available in the filter panel:
+The search box filters by session name. Click the **Filter** icon at the top right of the list to combine these filters (a dot on the icon means filters are active):
-| Dimension | Options | Notes |
-|---|---|---|
-| Scope | All / Personal / Team | After selecting **Team**, switch between **My teams / Selected teams** (default: **My teams**); only **Selected teams** expands the inline list where you can search and multi-select teams you belong to |
-| Creator | All / Started by me / Selected members | Narrows results by who started the session: **Started by me** shows only sessions you created; **Selected members** expands a searchable member list (up to 50 loaded at a time, with distinct empty, no-match, and load-failure states) and keeps sessions started by any of the picked members — picking none is the same as not filtering by creator. This dimension appears only when **Scope** is not **Personal** |
-| Status | Active / Archived / All | Defaults to showing only **Active** sessions; switch to **Archived** to view archived sessions |
-| Recent activity | All / 24 hours / 7 days / 30 days | Narrows results by the session's most recent activity time |
-
-The panel footer provides **Reset** (restore default filters) and **Done** (close the panel).
+| Filter | Options |
+|---|---|
+| Scope | All / Personal / Team (for Team, **My teams** or specific teams you belong to) |
+| Source | All / Started by me / Selected members (hidden when Scope is Personal) |
+| Status | Active (default) / Archived / All |
+| Recent activity | All / 24 hours / 7 days / 30 days |
### Session Visibility and Permissions
-The account is the hard access boundary for sessions: sessions are never accessible across accounts. Within the same account, personal sessions and team sessions use different rules for reading, continuing, and managing the conversation:
+Sessions are never accessible across accounts. Within an account:
-| Session type | Can read / continue the conversation | Can rename, archive, delete, or attach an incident |
+| Session type | Can read / continue | Can rename, archive, delete or link to an incident |
|---|---|---|
-| Personal session (no team bound) | Only the creator | Only the creator |
-| Team session (team bound) | Members in the same account who have the session ID | Session creator, account owner / admin, or members of the bound team |
+| Personal session (no team) | Creator only | Creator only |
+| Team session (bound to a team) | Members of the account who have the session link | Session creator, account Owner / admins, or team members |
-Pinning is a personal preference and does not modify the session itself; if you can read a session, you can pin or unpin it for yourself. Account owners and admins can manage team sessions, but they cannot read or manage another member's personal session.
+Pinning affects only your own list. Account Owners and admins can manage team sessions but cannot read other members' personal sessions.
### Sharing a Session
-The chat page header provides share controls, shown only when you have manage permission on the current session. Click the **Copy share link** button to enable sharing and copy the link to your clipboard (a "Share link copied" toast appears). The link appends a `share_token` to the current session URL, with the token in the URL fragment (after `#`). The share link is **stable**: while sharing stays enabled, copying it again yields the same link.
+If you can manage a session, click **Copy share link** in the chat header.
-| Topic | Details |
-|---|---|
-| Who can share | Members with manage permission on the session — the creator of a personal session, or the creator / account owner / admin / team members of a team session |
-| Who can open it | Members who hold the link and are signed in to the **same account**; the link does not work across accounts or for anonymous visitors |
-| What link holders see | The session opens in **read-only** mode with a "This is a read-only shared session" notice: they can inspect the full context (messages, tool calls, artifacts), and can also open a Subagent dispatch chip to view the child session's execution details (also read-only); but the composer is replaced by the notice — they cannot continue the conversation or modify the original session |
-| How to keep working | Link holders can click **Fork into a new session** to derive their own session and continue from there |
-| How to revoke | Once sharing is enabled, a **Remove share** button appears in the header; clicking it invalidates the link immediately (a "Share removed" toast appears). Re-enabling sharing later generates a new link — the old link is not restored |
-
-Sharing mainly changes the visibility of **personal sessions**: a team session is already readable by any member of the same account who has the session ID (see the table above), whereas a personal session is visible only to its creator by default — a share link is the only way for other members of the account to open it.
+- Only members signed in to the **same account** can open the link; anonymous access is not supported. The link stays the same while sharing is on.
+- People with the link see the whole session **read-only** (including subagent details) and cannot continue it; they can click **Fork into a new session** to continue in their own session.
+- Click **Remove share** to invalidate the link immediately; sharing again creates a new link.
+- Personal sessions are visible only to their creator by default, so a share link is how other members of the account can view one.
<Note>
-Incognito sessions cannot be shared.
-
-Subagent / A2A child sessions can't have sharing enabled on their own either — sharing can only be enabled on the **root session**. But once you share the root session, link holders can open a Subagent dispatch chip in the read-only view and view the corresponding child session's execution details, also read-only; child sessions are view-only and don't offer **Fork into a new session**. Revoking the root session's share also invalidates access to its child sessions.
+Incognito sessions cannot be shared. Sharing is enabled on the root session only; subagent (Subagent / A2A) sessions cannot be shared on their own.
</Note>
### Per-Session Actions
-Hover over a session row to reveal the pin and archive actions. A pinned session displays a persistent pin icon to the left of its name.
-
-| Action | Entry point | Notes |
+| Action | Where | Notes |
|---|---|---|
-| Pin / Unpin | Inline pin button on hover | Pinned sessions appear at the top of the list |
-| Archive / Unarchive | Inline archive button on hover | Archived sessions are hidden from the active list by default; switch to **Archived** in the filter to find them |
-| Rename | Click the chat title to edit in place | Press Enter or click away to confirm; press Esc to cancel; maximum 60 characters |
-| Delete | Delete button in the chat header (requires manage permission) | Deletes the session after confirmation; the conversation history cannot be recovered. Deletion also best-effort stops the session's still-running background command / monitor processes — a failed stop does not block the deletion, and no task notifications are sent for it |
+| Pin / unpin | Hover over the session row | Pinned sessions stay at the top |
+| Archive / unarchive | Hover over the session row | Find archived sessions by setting Status to **Archived** |
+| Rename | Click the chat title | Up to 60 characters |
+| Delete | Chat header (requires manage permission) | Cannot be undone; background tasks still running in the session are stopped |
-A new session does not need a manual title: after the first turn completes, the system auto-generates a title server-side from the session's content and pushes it back through the session stream as a `session.renamed` frame, which updates the sidebar and title in place. Until that finishes, a placeholder title derived from your first message is shown so the sidebar never sticks at "Untitled." You can **rename** the session at any time to override the auto-generated title (title limit: 60 characters).
-
-<Tip>
-Hovering over a session row for a moment shows a tooltip with the full session name, the associated team, and the exact timestamp — useful when the name is truncated and you need to confirm you have the right session.
-</Tip>
+A new session gets an automatic title after its first turn; you can rename it at any time.
### List Status Indicators
-Each row shows status indicators by priority: while a session is running, only the spinner is shown; otherwise the background-task badge and the unread dot can appear together; when neither applies, the relative time is shown.
-
| Indicator | Meaning |
|---|---|
-| Spinning circle | The agent in this session is running (a turn is in progress or waiting on subtask reports); takes priority over all other indicators |
-| 🔭 + count | The session has that many live background tasks (monitors / background commands) — see "Task Panel and Background Tasks" below |
-| Blue dot (unread) | The agent has produced new content you have not yet viewed; can appear alongside the 🔭 badge |
-| Relative time | When none of the above applies, the relative time of the last activity is shown (e.g. `5m`, `3h`, `3d`) |
-
-Opening a session clears its unread dot.
+| Spinning circle | The agent is running |
+| 🔭 + number | Number of background tasks running — see [Task Panel and Background Tasks](#task-panel-and-background-tasks) |
+| Blue dot | New content you have not seen; cleared when you open the session |
+| Relative time | Last activity (e.g. `5m`, `3h`) |
## Sending Messages and Streaming Responses
----
-
-Type a message in the input box at the bottom and press Enter to send. The input box supports Markdown and slash commands (type `/` to open the command menu) to trigger built-in skills and commands.
-
-When the console publishes a new version, a **version update notice** appears above the input box: "A new version of the console has been published. Refresh the page to continue." Click **Refresh** to reload the page and use the new version; clicking the close button hides the notice, and it will not repeat for the same version (the notice only appears in the full web console, not in embedded mode or on-premises deployments).
+Type a message in the input and press Enter. The input supports Markdown; type `/` for the Skill and command menu. When a new console version is released, a notice above the input asks you to refresh.
### Attachments and Context References
<AccordionGroup>
- <Accordion title="Upload attachments" icon="paperclip">
- Click the plus button at the lower left of the input box to choose files, or paste images directly. Supported formats include images, PDFs, text / Markdown / CSV / HTML, Office documents (Word / Excel / PowerPoint), and archives (`.zip` / `.rar`), up to **50 MB** per file. HTML files are read as plain text and rendered in the sandbox — any scripts inside them are not executed. Archives are **never parsed into inline text**: the agent receives only the archive's path in the sandbox, so it first inspects the declared listing (`unzip -l` / `bsdtar -tv`) and unpacks the archive in the sandbox to read the contents — a modest archive can expand into a large number of files. A single message can carry at most **9 attachments**, and the total size of all attachments in one message cannot exceed **50 MB**; the **per-file cap** and the **per-message attachment total** are two independent limits that happen to share the same 50 MB value, so don't conflate them. Both limits are validated client-side as soon as you pick the files, and exceeding either shows a corresponding message — at this point the attachments are only staged locally (pending chips) and uploaded together when the message is sent. Screenshots can be pasted directly into the chat.
-
- Extensions not listed above — such as code and config files like `.go`, `.py`, `.yaml` — are also accepted as plain text, as long as the entire file content is valid UTF-8. Empty files are the exception and are still rejected.
-
- Besides individual files, you can **upload a whole folder**: choose **Upload folder** from the plus menu to pick a local folder, or drag a folder straight into the input area. Folders are handled as follows:
+ <Accordion title="Uploading attachments" icon="paperclip">
+ Click the plus button at the bottom left of the input, or paste a screenshot.
- - **File count limit**: a single folder may contain at most **50 files**; a folder over the limit is rejected outright ("This folder exceeds the 50-file limit; please choose a smaller folder") instead of keeping only the first 50. `node_modules` directories and files / directories starting with `.` are silently ignored and don't count toward the limit.
- - **Per-file validation**: every file in the folder is still checked against the single-file rules (50 MB per file, 50 MB total, type validation). Files that fail are skipped, and after you pick a folder the input area shows a "Skipped N files" list naming each file and its skip reason (over 50 MB / over the 50 MB attachment total / not a text file / unsupported file type).
- - **Attachment counting**: the whole folder counts as **1 attachment** in a message, toward the same 9-attachment limit.
- - **Directory structure preserved**: the relative path of every file in the folder (including the top-level folder name) is preserved and staged into the sandbox. The agent sees a path-sorted file listing (an envelope with the file count and total size) rather than the file contents inlined into context; it reads individual files on demand with the read / bash / grep tools inside the sandbox.
-
- **Inline truncation of large files**: apart from archives (which are not parsed — the agent gets only their sandbox path), attachments reach the agent as extracted text. When the extracted text exceeds **64 KB**, only the first **32 KB** is inlined (cut at a valid UTF-8 boundary), and the attachment envelope carries a pointer to the full file staged in the sandbox (like `~/.flashduty/attachments/...`) — if the full content matters, ask the agent to read the file from the sandbox with the read / bash tools; nothing is lost. In addition, PDFs larger than **3 MB** are no longer passed natively to the model; they fall back to text extraction under the same truncation rule.
+ - **Supported types**: images, PDF, text / Markdown / CSV / HTML, Office documents, archives (`.zip` / `.rar`), and any UTF-8 text file (such as `.go`, `.py`, `.yaml`). Empty files are rejected.
+ - **Size and count**: up to **50 MB** per file; up to **9 attachments** per message, **50 MB** in total.
+ - **Folders**: choose **Upload folder** from the plus menu or drag a folder onto the input. A folder can hold up to **50 files** (`node_modules` and dot-files are not counted); a larger folder is rejected as a whole, and individual files that do not qualify are skipped with the reason listed. A folder counts as 1 attachment and keeps its directory structure.
+ - **How the agent reads them**: attachments are provided as text; for text over 64 KB only the beginning is provided directly, and the agent reads the full file from the sandbox when needed. Archives and folders are not expanded up front; the agent unpacks and reads them in the sandbox as needed.
</Accordion>
<Accordion title="Context references" icon="link">
- When you enter AI SRE from an incident, alert, monitor rule, monitor target, datasource, or RUM issue detail page (its **AI fix** button at the top right), the related object is embedded into the input box as a **reference capsule** — a small inline tag indicating the kind of object referenced — an incident, alert event, alert, monitor rule, host, monitor target, datasource, on-call analytics, or RUM issue — that travels with the message so the agent can start its analysis from that object directly. Click the capsule to open the referenced object in a new tab, or click its close button to remove the reference before sending.
+ When you open AI SRE from an incident, alert, alert rule, monitored object, data source or RUM issue (the **AI fix** button), that object is added to the input as a **reference capsule** and sent to the agent with your message. Click the capsule to open the object, or remove it before sending.
- **These entry points also carry a default question**, and the capsule sits at the spot the entry marks inside that sentence. Entering from a monitor target page, for instance, pre-fills "请分析这个监控对象 〈reference capsule〉:基于真实观测数据判断当前是否有问题或隐患,说明依据与影响面,并给出下一步排查或处置建议。请区分已确认事实、合理推断和待确认项;证据不足时明确说明不确定,不要过度归因"; entering from the datasource list pre-fills "调用 〈reference capsule〉 的 overview tool,校验 overview tool 是否可用"; entering from a RUM issue detail page by clicking **AI fix** pre-fills "Use the rum skill to fix this RUM issue 〈reference capsule〉: follow the issue-fix workflow to fetch the issue context, then locate the failing code in the repositories linked to the application. Only when the root cause is confirmed and you are confident in the change, create a branch and open a Draft PR that links this issue in its description; otherwise give the analysis and fix suggestions without opening a PR. Never push directly to the default branch. Distinguish confirmed facts, reasonable inferences, and items to confirm.", and that button only appears when AI SRE is enabled for the account. The prefill is only a draft — edit it, delete it, or send it as-is.
+ These entry points usually pre-fill a question as well (for example, asking the agent to separate confirmed facts from inferences); edit it as you like before sending. No question is pre-filled when several references are brought in at once.
- **A handoff carrying exactly one reference pre-fills its question**: when the merged context refs resolve to a single ref that carries the entry's default question, the input box is pre-filled with that question and the `[[ref]]` placeholder becomes the reference capsule. Clicking **AI analysis** on several incidents from the incident list, for example, pre-fills "Batch-analyze these incidents 〈reference capsule〉: first determine how they relate to each other (a shared root cause, a cascading chain, or fully independent) and group them accordingly; then give the likely root cause and impact for each group; finally give an overall remediation recommendation with priority. Fetch a single incident's details with tools only when needed, rather than expanding every incident up front. Separate confirmed facts, reasonable inferences, and open questions; state clearly when the evidence is insufficient, and never claim to have performed actions that were not performed.", with the capsule titled "Incident list (N)". A handoff carrying several references pre-fills nothing and leaves the input box as it is. A single message can carry multiple references. Besides objects carried in automatically from a related page, you can also type `@` directly in any session's input box to trigger an incident search dropdown (supporting fuzzy keyword search and a list of recent incidents); selecting one inserts the same kind of reference capsule — a standalone entry point available at any time. Typing an email address does not false-trigger it: when the `@` directly follows an email-address character (a letter, a digit, or one of `._%+-`), the picker does not open; an `@` after a space or adjacent to Chinese text still triggers it.
+ In any session, type `@` to search incidents and insert a reference. Typing an email address does not trigger the search.
</Accordion>
- <Accordion title="Knowledge and skills" icon="book">
- When a session starts, the knowledge and skills for the bound team are loaded automatically. See <a href="/en/ai-sre/knowledge">Knowledge</a> and <a href="/en/ai-sre/skills">Skills</a> for details.
+ <Accordion title="Knowledge and Skills" icon="book">
+ When a session starts, knowledge and Skills for the bound team are loaded automatically; see <a href="/en/ai-sre/knowledge">Knowledge</a> and <a href="/en/ai-sre/skills">Skills</a>.
</Accordion>
</AccordionGroup>
### Real-Time Streaming Output
-After you send a message, the agent's reply is streamed back in real time — text appears as it is generated, and tool calls and reasoning steps are rendered as they occur.
-
-The moment you send, the frontend optimistically marks the turn as "running"; the backend's running status takes over after roughly 300 ms, so the running state is not lost even if you navigate away and return.
+The agent's reply streams in real time, including text, tool calls and reasoning. The run state is kept if you switch pages and come back.
<Note>
-While a turn is running, **the Send button changes to a Stop button**. Clicking Stop immediately interrupts the current turn: the UI reflects this right away, and the interrupted turn is labeled "Interrupted" and remains visible after a page refresh.
-</Note>
-
-<Note>
-The session stream pushes progress as **frames**, and every frame may carry `is_error` and `error_code` to mark a **runtime failure**. The test is deliberately narrow: a frame only carries them once the runtime has converted a real failure into a user-facing error and stamped that marker on the persisted event row. **The platform's internal control rows (bookkeeping events such as turn settlement and automation turn outcomes) and raw provider / model error text never enter this path.** So a frame with an `error_code` can be consumed as "a runtime error the platform is exposing to the user"; conversely, the absence of these fields does not mean a frame carries no internal diagnostics. This is not the same thing as the `error` line in [Session data export](#session-data-export) below, which reports the export stream itself failing: `is_error` / `error_code` ride on ordinary event frames, while `error` is a separate line appended when the stream itself breaks.
+While a turn runs, the Send button becomes a **Stop** button. Stopping interrupts the turn immediately and marks it as interrupted.
</Note>
### Queueing Messages While Running
-The input box remains active while a turn is running: you can keep typing and send messages, which are queued and executed in order after the current turn completes. Queued messages appear in a collapsible card above the input box, with a header showing the queue count (e.g. "3 queued"); each queued message can be edited or removed individually, and when more than one message is queued, the card also offers a **Clear all** action in its top-right corner.
-
-The queue is authoritative server-side: messages you have sent but the agent (actor) has not read yet live in the server-side session queue, projected by the `pending_messages` field of the `POST /safari/session/get` response (in execution order). Before the agent starts processing one, you can **withdraw** it — the endpoint is `POST /safari/session/message/cancel`, whose request body carries `session_id` and `invocation_id` (the call ID the 202 ack / `user_message_enqueued` frame handed you when the message was sent); the response's `result` field tells you what happened:
-
-| Result | Meaning |
-|---|---|
-| `removed` | The message was removed from the queue and will **never be executed**; the server pushes a `user_message_cancelled` frame to every subscriber, and clients drop the corresponding pending bubble |
-| `consumed` | The actor had already read the message — it belongs to the running turn; the withdrawal does not take effect and that turn still executes ("too late") |
-| `forbidden` | Only the message's author may withdraw it; a call by anyone else returns `ErrAccessDenied` |
-
-Withdrawal only touches the waiting queue: an envelope the actor has already read can no longer be withdrawn (it returns `consumed`) — to interrupt a turn that is actually executing, use **Stop**. Only plain human messages can be withdrawn — question answers (`function_response`) and internal-producer envelopes (automation, child-session notifications, parent initial messages) are not included. The capability also applies to queued messages sent through API integration. The caller needs **participate permission** on the session (the same gate as sending a message or interrupting), and only the message's author can actually withdraw it — both conditions must hold for the result to be `removed`.
+You can keep sending messages while a turn runs; they queue and run in order after the current turn. Queued messages appear above the input, where you can edit, remove or **Clear all** of them. Once the agent has started on a message it can no longer be withdrawn; use Stop to interrupt.
### Environment Initialization
-The first time a session runs, an **environment initialization** card appears in the chat stream and steps through how the runtime environment (the sandbox) becomes ready: **set up a cloud container → start the runtime**; if the cloud template carries a setup script, init and reclaim runs add a third phase, **run the setup script** (resuming an existing sandbox never reruns it). The phases run serially, showing only the step currently in progress; once everything is done, the card collapses into a single result line that reflects whether this run created, resumed, or rebuilt the sandbox:
+The first time a session runs, an **environment initialization** card shows the sandbox being prepared and then collapses to one line:
-| Mode | Collapsed label | Meaning |
-|---|---|---|
-| Init | Initialized session | A brand-new cloud container was created for the session |
-| Resume | Resumed session | The previous sandbox was reused, with its files intact |
-| Reclaim | Rebuilt session | The previous sandbox had been reclaimed, so a new container was created |
+| Message | Meaning |
+|---|---|
+| Session initialized | A new cloud sandbox was created |
+| Session restored | The previous sandbox was reused; files are unchanged |
+| Session rebuilt | The previous sandbox had been reclaimed, so a new one was created |
-<Note>
-Sessions bound to a self-hosted [BYOC Runner](/en/ai-sre/environments#byoc-runner) skip the cloud phases: the init card shows a single phase — **Connecting to the self-hosted runner** (for init, resume, and reclaim alike) — which becomes **Connected to the self-hosted runner** once it succeeds, then collapses into the same result line. If connecting to the self-hosted runner fails, the card shrinks to a single-line error notice (**Failed to connect to the self-hosted runner**, with the specific reason) and offers no cloud phase-history expansion.
-</Note>
+Sessions on a self-hosted [BYOC Runner](/en/ai-sre/environments#byoc-runner) show only the step of connecting to the runner.
<Warning>
-When the previous sandbox was reclaimed after being idle, the card warns: **Previous sandbox was reclaimed after N min idle — saved files were reset**. This means anything previously written to the sandbox filesystem is gone. Persist long-lived outputs by **saving them as an Artifact or to knowledge**, rather than relying on transient sandbox files.
-</Warning>
-
-<Warning>
-If an error occurs during initialization, the card switches to a **Session setup failed** error state; click it to expand the phase history and the specific error details. You typically need to retry with a new session, or contact Flashduty support.
+When an idle sandbox is reclaimed, its files are reset. Keep anything you need by **saving it as an Artifact or to knowledge**. If initialization fails, click the card for details; starting a new session usually helps, or contact Flashduty support.
</Warning>
## Tool Calls and Artifacts
----
-
-Tools the agent invokes during a turn (reading and writing files, querying monitors, executing commands, calling MCP tools, etc.) are rendered inline in the conversation as collapsible blocks. Click one to expand and inspect its inputs and outputs; they are collapsed by default to keep the chat readable.
+Tools the agent calls (reading and writing files, querying monitoring, running commands, MCP tools, and so on) are collapsed in the conversation by default; click to see input and output.
### Todo List
-For multi-step tasks, the agent places a clickable progress badge in the chat stream (shaped like "Step X / N," with a ring progress indicator); clicking it expands into a task plan list, with each step carrying a status icon (Pending / In progress / Completed / Cancelled) and a priority tag (High / Medium / Low). If the agent ends its turn while a step is still "In progress," that step is shown as "Paused," signaling that you need to send a new message before it can proceed — it is not still running in the background.
+For tasks with three or more steps, the agent shows a progress badge (such as "Step X / N"); click it to see the task list with each step's status and priority. If the turn ends with a step unfinished, that step shows as paused and continues only after you send a new message.
-The task plan is maintained only on surfaces that actually have someone watching it: `write_todos` (the built-in tool that maintains the list) is available only in console (`web`) and IM sessions — the web panel renders the TodoList card, and the IM side renders it as a progress card. **Automation (`automation`) and API (`api`) sessions do not get the tool**: the agent cannot call `write_todos` there and receives no "keep your todo list current" nudge, so multi-step work runs directly without producing a progress list (an automation run can still be opened in the console to see the full messages and tool calls, but there is no checklist). Dispatched child sessions (Subagent / A2A) are excluded as well — todo state is per-session, and a child writing todos would clobber the parent's list.
-
-A list is only created when the task genuinely is multi-step: **three or more distinct steps** (previously judged as "2+ tool calls," now tightened). Single-step lookups and pure conversation with no investigation behind it produce no list. Session entry kinds are described under "Session entry kind" above.
+Todo lists are available in console and IM sessions only, not in automation, API or subagent sessions.
### Agent Questions
-While troubleshooting, the agent may need you to clarify something, in which case it inserts an interactive question card into the chat stream: single-select (picking an option automatically advances to the next question), multi-select (after checking options you must click **Confirm** / **Next** to proceed), or free-text input (press Enter to submit). The **✕** button in the top-right corner of the card skips the whole question (not shown for required questions); a multi-question batch also shows a "Question i of N" pager, which you can navigate with the ←→ keys or by clicking, and returning to an already-answered question preserves your previous selection. Keyboard shortcuts: ↑↓ to move between options, Enter to confirm, Esc to skip.
+When the agent needs clarification, it adds a question card — single choice, multiple choice or free text. You can use the keyboard (↑↓ to choose, Enter to confirm, Esc to skip); optional questions can be skipped with **✕**.
-**A parked question is auto-skipped by a new message**: when the model is parked on a question card waiting for your answer, sending a new message marks the parked question as skipped — the server writes a `function_response` (`reason=user_replied_with_message`, one entry per question in a batch) **without driving the model**; your new message runs immediately as the next turn, and the model in that turn sees "question skipped + what you said" instead of being blocked by the parked question. Conversely, **a late answer never resumes that question branch**: submitting an answer to a question that already has a user-side response (auto-skipped, or answered from another device) converts the answer into a plain message (rendered as the answer text — e.g. "(skipped)") that joins the next turn — the same question is never resumed twice.
+If you send a new message instead of answering, the question is treated as skipped and your message runs immediately. Answering a question that was already skipped or answered elsewhere sends your answer as a regular message.
### When Authorization Is Required
-When a tool or MCP call is blocked because it lacks credentials or has not completed OAuth authorization, an **"Authorize [resource name] to continue"** card appears inline in the chat stream, in one of two forms:
+When a tool or MCP call needs a credential or OAuth authorization, an **"Authorize [resource name] to continue"** card appears:
-- **Secret-based**: clicking the card's button opens an input field; paste your API key / token and save it, and the task resumes automatically. If a help link is configured, the card also shows "How do I get a key?"
-- **OAuth-based**: click **Authorize** to complete third-party authorization in the popup window. Once authorized, the card's button changes to **Continue task** — you must click it manually to actually resume the blocked tool call.
+- **Secret-based**: click the button, paste the API key or token and save; the task continues automatically.
+- **OAuth-based**: click **Authorize**, complete the third-party authorization, then click **Continue task**. If the authorization link expires, start the task again.
<Note>
-OAuth authorization links expire. After expiry, the card shows "Authorization link expired, please retrigger the task" — you need to start a new task to get a fresh authorization link.
-</Note>
-
-<Note>
-Channel differences: only the console (`web`) renders this card. IM and API channels get no card — the agent pastes the OAuth authorize link into its reply as plain text, and you open it in a desktop browser, complete the authorization, then reply "authorized" or "已授权" to continue (continuing is your explicit action, not an automatic OAuth callback side effect); for a secret-type credential there is no safe way to collect it over IM, so the agent tells you to open **this same session in the web console** and **never** asks you to paste the secret into the chat. On the automation channel nobody is watching, so the agent does not wait — it records the missing authorization as a blocker and delivers what it can. See [IM Platforms](/en/ai-sre/im#connections-and-authorization).
+Only the console shows the authorization card. In IM and API sessions the agent posts the OAuth link; finish authorizing in a browser and reply that you have authorized. Secrets must be entered in **this same session in the web console** — **never** paste a secret into the chat. Automation sessions do not wait and list the missing authorization as a blocker. See [IM Platforms](/en/ai-sre/im#connections-and-authorization).
</Note>
### When a Connection Is Required
-When the agent searches for a capability to fulfil your request (`tool_search`), that search matches no tool at all, and the query happens to name a vendor that **exists in the marketplace catalog but your account has not connected**, a **"Connect [vendor] to continue"** card appears inline in the chat stream: the vendor's icon and name on the left, a **Connect** button on the right, and nothing else.
-
-This means you **don't have to go hunting in the plugins marketplace first**: name the vendor right in the conversation (for example, "connect Datadog for me") and you reach the connection step from there. If the catalog has no connector for that vendor at all, the agent just says so instead of showing a card.
+When you ask the agent to use a vendor that is in the plugin marketplace but not yet connected to your account (for example "connect Datadog for me"), a **"Connect [vendor] to continue"** card appears, so you do not have to look for it in the marketplace first.
-Clicking **Connect** opens that vendor's connect dialog (the same one as in the plugins marketplace: enter credentials, complete authorization and the connection test). Once the connection succeeds, the card flips in place:
-
-| Phase | Card state |
-|---|---|
-| Not connected | Title **"Connect [vendor] to continue"**, the vendor's description underneath, button **Connect** |
-| Connected | Title **"[vendor] connected"**, subtitle "Click Continue task and AI SRE will pick up where it left off", button **Continue task** |
+1. Click **Connect** and fill in credentials and run the connection test in the dialog.
+2. Once connected, the card shows **"[vendor] connected"**; click **Continue task** and the agent resumes the original task.
-Clicking **Continue task** makes the console send "连接已完成,请继续之前的任务。" to the agent on your behalf so it resumes the original task — **closing the connect dialog does not resume the turn by itself**; resuming is always an explicit click from you. After a page reload the card still shows as connected: the console re-derives that from the template's own install state in the account, not from temporary browser state.
-
-In the following cases **no card** appears and the agent just says so in one sentence:
-
-- The account already has a connector for that vendor (in any team, in any environment): the agent says it is connected (or that it must be enabled or its credentials re-entered).
-- Only an account Owner or admin may connect that vendor: the agent says an admin has to do it.
-- The vendor's template requires a self-hosted Runner and this session has no Runner available.
-- The search matched a connected tool — a connect card only appears for "zero matches + the query names an unconnected marketplace template".
+No card appears — the agent explains instead — when the vendor is already connected (it may need enabling or new credentials), only an Owner or admin can connect it, it needs a self-hosted runner and the session has none, or the marketplace has no connector for it.
<Note>
-Channel differences: only the console (`web`) renders this card. IM and API channels get no card — the agent gives the connect URL as a plain link and asks you to reply "继续" or "continue" once connected, then carries on; on the automation channel nobody is watching, so the agent does not wait — it records the missing connection as a blocker and delivers what it can. The full per-channel behavior is in [IM Platforms](/en/ai-sre/im#connections-and-authorization).
+Only the console shows the connection card. In IM and API sessions the agent posts a link; connect and reply "continue". Automation sessions do not wait and list the missing connection as a blocker. See [IM Platforms](/en/ai-sre/im#connections-and-authorization).
</Note>
### Subagents
-When the agent delegates a subtask, a clickable **dispatch reference line** appears in the conversation: a status ring, a type badge (Agent / A2A), the subtask's name and current intent, and right-aligned **target execution environment**, status and elapsed time; once finished it adds the tool-call count / token usage / total duration, and on failure a red reason line appears underneath. The environment segment states the location only — the **cloud environment**, or the BYOC Runner's name (just "self-hosted" when no name resolves) — and carries **no status dot**; an A2A delegation (the remote agent executes on its own side) and legacy tasks with no environment binding show no such segment. The reference line is a compact single row and carries **no stop button** — stopping lives in the task panel's detail header (see "Task Panel and Background Tasks" below). Clicking the line opens a subagent session panel on the right, side by side with the main conversation — the main chat area shrinks accordingly rather than being covered by a modal. The panel can be expanded to fill the main area, or collapsed back to the side-by-side layout.
+When the agent delegates work, a subagent line appears in the conversation with its type (Agent / A2A), name, execution environment, status and duration, and afterwards its tool calls, token usage and any failure reason. Click it to open the subagent session side by side; it can be expanded to full screen.
-Besides running, completed, failed, and interrupted, a subtask can also sit in one of two "needs you" states:
+A subagent may also need you:
-- **Awaiting authorization**: an action area unfolds beneath the reference line — click **Authorize** to open the OAuth popup; once authorization completes, the button becomes **Continue task**, and clicking it lets the main agent resume the same task in place instead of starting a new one.
-- **Awaiting input**: the subtask has asked you a question and is parked waiting for an answer; the question text is read on the task's row in the task panel, not inline on the reference line.
+- **Awaiting authorization**: click **Authorize**, then **Continue task**; the subagent resumes the original task.
+- **Awaiting input**: read and answer the subagent's question in the task panel.
-An orphaned subtask (its executor is gone) renders as **Failed**; a task terminated by the platform shows as **Killed**.
+Stop subagents from the task panel. A subagent whose executor was lost shows as **Failed**; one terminated by the platform shows as **Killed**.
### Task Panel and Background Tasks
-Beyond subagents, the agent can push time-consuming work into the background. Tasks dispatched within a session come in three kinds:
-
-| Kind | Dispatched by | Notes |
-|---|---|---|
-| agent | Subagent / A2A subagent dispatch | Has its own child session — see "Subagents" above |
-| shell | The `bash` tool with `run_in_background` | A long one-shot command (build, batch job, data pull); only its completion needs reporting |
-| monitor | The `monitor` tool | A standing watcher task: watches a condition until it hits or reaches its deadline, and the script's output flows back to the agent as event batches; a one-shot delayed action (e.g. "check again in half an hour") is done with a monitor plus `sleep` |
-
-A unified **Tasks** panel on the right side of the session tracks every task of the session, grouped into **Needs you / Running / Finished**. There are three entry points:
-
-- **The tasks button in the chat header**: carries a count badge for "needs you + running" tasks, capped at `9+`; the badge is red when any task needs you (awaiting authorization / awaiting input), and blue when tasks are only running.
-- **The generation status row while a turn is running**: shows the live task count (e.g. "3 tasks · 1 agent needs you"); clicking it opens the same task panel.
-- **The tool row that started a monitor / background bash**: the tool row in the conversation that started a `monitor` or a background command (`bash` with `run_in_background`) — when it is the only tool in its group, that group's header — is itself that task's handle in the transcript: its trailing external-link icon marks it clickable, the tooltip reads **Open task detail**, and clicking it opens that task's detail panel directly. Such rows no longer expand into raw Input/Output (a background bash row used to show only the command, with no status or output). In a read-only shared session the detail opens in read-only mode as well.
-
-Task details differ by kind: clicking an **agent** task opens the child session's execution transcript (see above); clicking a **shell / monitor** task opens its own event-timeline detail, which includes the status (a running task also shows how many seconds ago its last liveness probe landed — probing happens roughly every 30 seconds), run duration, event count, output bytes, the monitor's deadline (standing tasks with no deadline show "Persistent"), the exit code, the full command, and the event timeline in order. **The stop button lives in the detail header** — **Stop task** for shell / monitor tasks and **Stop Subagent** for subagents — and interrupts only that task, without affecting the main session.
+Besides subagents, the agent can run long commands in the background (builds, bulk data pulls) or start monitors that watch a condition until it is met or a deadline passes.
-How this surfaces in the conversation stream:
+Click the **Tasks** button in the chat header to see all tasks in the session, grouped as **Needs you / Running / Finished**. The number on the button counts tasks that need you or are running, and turns red when something needs you. You can also click the line in the conversation that started a task to open its details.
-- A tool line that starts a background command reads **Started background command**; when a turn mixes foreground and background commands, the collapsed tool group counts each category separately (e.g. `Ran 1 command, started 1 background command`).
-- Each time a monitor's condition hits, a 🔭 system line is inlined into the conversation: the first line shows the monitor's description plus a first-line summary of that output batch, and clicking it expands the full batch in place.
-- When a task ends, a terminal line appears with the end state and a result summary, plus the exit code and a note when the task envelope carries them.
-- The `monitor` tool line itself does not expand into input / output — clicking it opens the corresponding task's detail panel, where the bookkeeping it returns (task ID, output file, deadline, and so on) is presented more completely.
+- **Subagent** details show the subagent's transcript.
+- **Background command and monitor** details show status, run time, deadline, exit code, the full command and an event timeline.
+- **Stop task** or **Stop Subagent** in the detail header stops only that task, not the main session.
-Two status indicators related to background tasks:
-
-- **The 🔭 badge on a session list row** means the session has live background tasks (`standing_tasks`; the number is the count). When the session is running, the spinner takes priority.
-- **A session's "running" indicator reflects only agent turns and subagent tasks**: standing monitors / background commands do not keep a session "running" — a session with only standing tasks alive shows as idle.
+Each time a monitor's condition fires, a 🔭 line appears in the conversation; click to expand the output. When a task ends, its final status and result summary are shown. A session with only monitors or background commands left counts as idle and shows 🔭 with the task count in the list.
### Artifacts Preview
-Files the agent produces are available as artifacts with an inline preview. Click an artifact to open the preview panel on the right, which renders the content by type:
+Click a file the agent produced to preview it on the right:
| Type | Preview |
|---|---|
-| Code (multiple languages) | Syntax highlighting + line numbers |
-| Markdown | Rendered view by default; toggle to **Source** |
-| HTML | Rendered view by default (iframe sandbox); toggle to **Source** |
-| Image | Displayed directly; a retryable error message is shown if loading fails |
-| PDF | Rendered in the browser's built-in PDF viewer |
-| Skill archive (`.skill`) | Left-side file tree + right-side content; the whole package can be downloaded, and you can **Save Skill** to your account with one click |
-
-The preview panel provides **Copy**, **Download**, and **Close** actions.
-
-<Tip>
-Report-type artifacts (such as operational insight reports) can be generated as HTML containing Mermaid diagrams and charts, viewable directly in the rendered view. For operational insight capabilities, see <a href="/en/ai-sre/insight">Operational Insight Reports</a>.
-</Tip>
+| Code | Syntax highlighting and line numbers |
+| Markdown / HTML | Rendered view, with a **Source** toggle |
+| Images, PDF | Shown directly |
+| Skill package (`.skill`) | File tree and contents; download it or **Save Skill** to your account |
-All published artifacts can also be viewed and managed in one place on the **Artifacts** page in the left navigation (list, search, filter by personal / team scope, card / list view toggle, sort by created / modified time, rename, download, and delete) — see <a href="/en/ai-sre/artifacts">Artifacts</a>.
+Previews support **Copy** and **Download**. All artifacts can also be managed on the **Artifacts** page in the left navigation — see <a href="/en/ai-sre/artifacts">Artifacts</a>.
### Status Page Update Drafts
-The agent can call the `statuspage_draft` tool to **draft** an announcement for your public status page — a new incident or maintenance event, or an update appended to an existing event. Drafts are saved server-side and rendered in the conversation as a **status page update draft card**; but a draft is **never published automatically**: publishing a status page reaches subscribers immediately and cannot be recalled, so that step is always left to a human — review each item in the status page publish form in the console, then click publish.
+The agent can **draft** an announcement for a public status page: a new incident or maintenance event, or an update to an existing one. Drafts are **never published automatically** — you review and publish them in the console, because publishing notifies subscribers immediately and cannot be undone.
-#### What's on the draft card
+The draft card shows exactly what would be published: title, status or schedule, the Markdown message, affected components and their status, and the target status page and event type. If the message uses formatting the status page does not support (such as headings, code blocks, quotes or images), the card lists it, because it would be lost on publishing.
-The card reuses the visuals, field order, and component status icons of the console's corresponding cards (IncidentCard / MaintenanceCard), so what reviewers see is exactly what will be published:
-
-| Content | Description |
-|---|---|
-| Title | For a new event, the form's `name` field (backend `title`, up to 255 characters); for an appended update, the title of the event it attaches to — the append-update form has no title field, so this serves as identification only (shows "Untitled status page update" when not provided) |
-| Status / scheduled time | New maintenance shows "Scheduled for 〈start〉 → 〈end〉" (shows "No schedule set" when unset); otherwise the status text — incidents: Investigating / Identified / Monitoring / Resolved; appended maintenance updates: Scheduled / Ongoing / Completed |
-| Body | The `message` field is **fully rendered** as Markdown — this is what customers will read; reviewers must see the whole picture, and it must not appear as plain text |
-| Affected components | One chip per component: component status icon + name (hover shows "name · status") |
-| Target & type | Bottom left shows "Will publish to 〈status page〉" (appended updates show "Update · 〈event title〉"); the right side labels the type: Incident / Maintenance |
-| Warning banner | If the draft message contains Markdown the status page editor doesn't support and that would be **silently dropped** when loaded into the form (headings, code blocks, block quotes, images, strikethrough, inline code), the card lists each one in a warning banner — already detected by the tool at draft time |
-
-#### Card states
-
-| State | Behavior |
-|---|---|
-| Drafting | Skeleton screen, with "Drafting status page update…" at the bottom |
-| Tool error | "Failed to generate draft" + the specific reason; you can ask the AI to try again, or create it manually on the status page |
-| Incomplete draft | "Incomplete draft" + the same hint (the tool returned a result but no usable draft object) |
-| Ready to review | Button is **Review →**: opens the corresponding status page form in the console in a new tab, with the draft content pre-filled (URL convention below) |
-| Published | Button becomes a disabled **Published**; the bottom target becomes a link to the **published change** (`/status-page/{page_id}?menu=incidents\|maintenance&incident\|maintenance={change_id}`), so you can look back at what the draft eventually became |
-| Draft expired / not found | Button becomes a disabled **Draft expired**, with "Draft expired or not found — ask the AI to draft a new one" — treated the same when the console query returns ResourceNotFound or a network error |
-
-Whether it has been published is a fact the card cannot observe on its own (publishing happens in the console, in another tab), so the card queries `GET /status-page/draft/info?draft_id=...` by draft ID, which returns `status: pending | published`. While the draft is still pending, it refreshes every time the window regains focus ("review here, publish there, come back" is the normal path); `published` and "draft not found" are both terminal states, and the result is cached for the lifetime of the current page. Read-only shared sessions don't render the review button, and the draft status query is skipped as well.
-
-#### Handoff URL for review
-
-The draft itself lives server-side (fc-statuspage's draft storage); only the `draft_id` crosses over to the console: the form pulls the body from `/status-page/draft/info` by ID. The URLs combine into four variants by "new / append" × "incident / maintenance":
-
-| Scenario | URL |
-|---|---|
-| New incident | `/status-page/{page_id}?menu=incidents&incident=new&draft={draft_id}` |
-| New maintenance | `/status-page/{page_id}?menu=maintenance&maintenance=new&draft={draft_id}` |
-| Append incident update | `/status-page/{page_id}?menu=incidents&incident={change_id}&action=add-update&draft={draft_id}` |
-| Append maintenance update | `/status-page/{page_id}?menu=maintenance&maintenance={change_id}&action=add-update&draft={draft_id}` |
-
-`action=add-update` makes the detail page auto-expand the append-update form; without it, the route only opens the event itself and the draft is never read. `?draft=` carries only the draft ID — the draft is server-side state, not a chunk of JSON in the URL.
-
-#### Tool specifics
-
-| Field | Description |
-|---|---|
-| `page_id` / `page_name` | Target status page (required) and its display name (used on the card) |
-| `type` | `incident` (incident) / `maintenance` (maintenance) |
-| `change_id` | Omitted = new event; set = append an update to that event. Before drafting, the tool first checks `fduty status-page list` and `fduty status-page change-active-list` — if the target already has an active event, it should append rather than open another one (a second event reads to customers as another separate outage) |
-| `title` / `message` | Title for a new event (≤255 characters) and the body (required, Markdown; the status page editor keeps only bold, italic, links, bulleted / numbered lists, tables, and `---` dividers) |
-| `status` | New incident: `investigating` / `identified` / `monitoring` / `resolved`; new maintenance: omit (whether it advances on schedule is decided by the publish form's toggle); appended maintenance update: `scheduled` / `ongoing` / `completed` |
-| `affected_components` | Affected components (`component_id` + `status`, optionally with display name `name`); incident component status: `operational` / `degraded` / `partial_outage` / `full_outage`, maintenance component status: `operational` / `under_maintenance` |
-| `start_at_seconds` / `end_at_seconds` | Only for a new maintenance: planned window start and end, unix **seconds** (milliseconds and ISO strings are treated as invalid) |
+Click **Review →** to open the status page publishing form in a new tab with the draft filled in. After publishing, the button becomes **Published** and links to the published event; if the draft has expired or is missing, ask the agent to draft it again.
<Note>
-Channel differences: the console (`web`) and automation channels render the card above; IM and API channels don't render cards — instead the agent puts a "[Review & publish](〈the same handoff URL〉)" link at the **start of the reply**, then summarizes the draft points in a sentence or two (IM message truncation doesn't parse Markdown, so the link comes first to be safe). If saving the draft failed (no `review_url`), it falls back to a text summary and points you to the status page in the console to verify manually.
+IM and API sessions show no card; the agent puts a "Review and publish" link at the **start of the reply** and summarizes the draft. If saving the draft failed, the agent summarizes it in text and asks you to check it in the console.
</Note>
### Message Actions
-Hover over a message to reveal action buttons:
+Hover over a message to:
| Action | Applies to | Notes |
|---|---|---|
-| Copy | User message / artifact | Copies the message or file content to the clipboard |
-| Retry | User message | Restarts a turn using that message |
-| Edit | User message | Fills the message back into the input box for editing; if a turn is currently running it is interrupted first, attachments cannot be added while editing, and the Send button label changes to **Send rewind** |
-| Fork | Agent reply from a completed turn | Creates a new session from the completed turn that produced that reply, so you can continue down a different investigation path |
+| Copy | User messages / artifacts | Copy the content |
+| Retry | User messages | Run a new turn with this message |
+| Edit | User messages | Change and resend it — see below |
+| Fork | Replies of completed turns | Start a new session from here to try another approach |
<Note>
-Editing a historical message is, under the hood, a **rewind** operation: once submitted, the conversation regenerates from that message onward, and any content after that message is replaced. Confirm before submitting. If the turn that produced the target message is still running or stopping, the rewind is rejected (`rewind target invocation is still active`) — wait for that turn to settle before submitting. A rewind is also rejected while the session is busy with another operation (compacting its context, for example), in which case you get "The session is busy with another operation. Please try again in a moment." — that is not a permanent failure; just resubmit after a moment. When a rewind takes effect, the background processes and dispatched subagents spawned by the wiped turns are stopped along with it, and their task rows are removed from the task panel.
+Editing an earlier message **rewinds** the session: everything after it is replaced, and related background tasks and subagents are stopped. You cannot edit while that turn is still running or while the session is busy (for example, compacting); try again shortly.
</Note>
### Forking a session
-After a turn has fully completed, a **Fork** button appears beside the agent reply. Click it to open the **Fork new conversation** dialog. It pre-fills the source session's scope and environment as suggestions, but every fork requires an explicit target scope and environment. Choose Personal or an accessible team, then choose **Auto**, a cloud Sandbox, or an online BYOC Runner. Click **Confirm** to create — and automatically open — a new session forked from the completed turn that produced that reply.
-
-Forking is useful when you want to try another path from the same investigation context. The new session keeps the conversation and tool-call history up to the selected turn, but it never inherits the source environment binding on the server. Available environments are filtered by the target scope. If you are not a member of the source team, the dialog changes to Personal; if the source environment is deleted, offline, never connected, or outside the target scope, it changes to **Auto**. Later turns from the source session are not included. The forked session includes a "Forked from conversation" divider; click it to return to the source position in the original session.
+After a turn completes, click **Fork** next to the reply, choose the new session's scope (personal or a team you can access) and runtime environment, and confirm to create and open it.
-<Note>
-You can fork only from a **completed** turn in a top-level session. If the source session is still running, the selected turn has not settled, or the target is a Subagent child session, AI SRE rejects the fork.
-</Note>
-
-If the forked portion of the conversation dispatched any Subagent or A2A tasks, those dispatch chips are copied over to the new session along with their respective child sessions — opening one still shows the execution details, and it never points at an original task you don't have access to. **Dispatches that had already completed or failed in the source session keep their real status** (completed / failed), copied together with their result; only **dispatches still in progress at fork time** show as "Interrupted" — the new session has no executor picking them up, so they cannot continue running. If you need to rerun one, just start a fresh dispatch in the new session.
-
-Forking clears temporary state that only belongs to an in-progress run, such as active-turn caches, pending mount state, frontend state that has not been persisted, and current-turn counters. Persisted history, tool calls, and reusable compaction state are retained; team and environment binding are written to the new session based on your choice in the fork dialog. The forked session has its own context, so later messages, compaction, and run results do not write back to the source session.
+- The new session contains the conversation and tool calls up to that turn; from then on the two sessions are independent.
+- If the source team or environment is not available to you, the new session uses personal scope or **Auto** instead.
+- Completed or failed subagents are copied with their results; subagents still running at fork time show as interrupted and can be started again.
+- You can fork only from completed turns of a main session, not from subagent sessions.
### Session Feedback
-The chat header has a pair of session-level feedback buttons, **Helpful** / **Not helpful** (thumbs up / down), for rating the quality of the whole session.
-
-Clicking **Not helpful** opens a feedback card where you can select preset reasons and add a note:
-
-| Preset reason | Meaning |
-|---|---|
-| Wrong diagnosis / root cause | The diagnosis or identified root cause is incorrect |
-| Didn't find the root cause | The real root cause was never located |
-| Remediation unavailable | The suggested remediation cannot be applied |
-| Off-topic | The reply drifted away from your question |
-
-The card also has a free-text box to add specifics (optional). On submit, the feedback is persisted via `POST /safari/feedback/create`; when you reopen the session, the earlier rating is automatically refilled onto the header buttons.
+Use **Helpful** or **Not helpful** in the chat header to rate the whole session. With **Not helpful** you can pick reasons (wrong diagnosis / root cause, did not find the problem, unusable remediation, off-topic) and add a comment.
## Context Compaction
----
-
-As a conversation grows longer, the session context approaches the model's context-window limit. AI SRE automatically compacts older conversation history — summarizing it into a digest while preserving recent content — to free up context space without losing critical information.
-
-Every compaction boundary summary also appends a deterministic **folded-resources manifest**: it lists the resources folded out of context this round and how to get them back — skills re-read via `skill(name)`, MCP server tool definitions re-discovered via `tool_search`, and A2A agent usage notes re-delivered automatically on the next dispatch or message. Post-compaction turns can recover those definitions on demand without keeping them in context.
-
-Compaction is triggered in four ways:
+As a conversation grows, AI SRE automatically summarizes older history while keeping recent content and key conclusions, so the conversation carries on. Content folded out of context, such as Skills or MCP tool definitions, is reloaded by the agent when needed.
-| Trigger | Timing |
+| Trigger | When |
|---|---|
-| Automatic (before a turn) | Before a turn starts, when context usage exceeds the threshold |
-| Automatic (mid-turn) | During a turn, if context continues to grow and crosses the threshold again |
-| Automatic (event count) | Once the conversation reaches about **500 events**, even if token usage is still below the threshold |
-| Manual | You explicitly trigger compaction with the `/compact` command |
+| Automatic | When context usage passes the threshold (before or during a turn), or when the session reaches about **500 events** |
+| Manual | Type `/compact` |
-The **event-count trigger** is a safety net: in a session made of many short turns, the token estimate can stay below the threshold for a long time while the number of events (messages, tool calls, and so on) keeps growing. Compaction fires once the count reaches about 500, so the history window cannot freeze against the model's per-load row cap. If you see compaction happen while the Context percentage is well below the threshold, this is why.
-
-### What You Will See
-
-- **Compaction in progress**: A status line reading "Compacting conversation context…" appears in the chat stream, showing elapsed time and progress; it disappears automatically when compaction finishes.
-- **Compaction complete**: The conversation remains coherent with no action needed from you. The most direct indicator is the **Context** usage percentage in the chat header dropping — it reflects the current utilization of the context window, and hovering over it shows exact token usage.
-- **No compaction needed**: When compaction is unnecessary (for example, the conversation history is too short, or it is already in a compacted state), a manual trigger returns an appropriate message such as "Context does not need compaction" or "Conversation history is too short to compact."
-
-<Note>
-Compaction is transparent to you: what you perceive is a continuous conversation. The agent retains a summary of the compacted content in the background, so subsequent turns can still build on earlier key conclusions.
-</Note>
+Progress is shown while compacting; afterwards the **Context** percentage in the chat header drops (hover for token usage). If compaction happens while usage is far below the threshold, the event limit was reached.
## Choosing a Runtime Environment
----
-
-When creating a session, the input area has a separate **environment** selector alongside the team selector, which determines where the agent's tool, Skill, and MCP calls actually execute. The selector has three sections:
+When creating a session, choose the **runtime environment** in the input area to decide where the agent's tools, Skills and MCP run:
| Option | Description |
|---|---|
-| Auto (default) | The backend automatically picks an available environment; falls back to the cloud sandbox if none is available |
-| Cloud environment | Uses a Flashduty-managed cloud sandbox (the default template, or a cloud environment template already created for the account / team) |
-| A specific BYOC runner | Pick one of the online self-hosted runners in your account, so the investigation reaches your private network |
+| Auto (default) | The system picks an available environment, falling back to the cloud sandbox |
+| Cloud environment | A Flashduty-hosted cloud sandbox (the default template or one you created) |
+| BYOC Runner | An online self-hosted runner, so troubleshooting runs inside your network |
-Self-hosted runners are shown by their current status: runners that are offline or have never connected appear dimmed in the list and cannot be selected; if a selected runner goes offline afterward, sending messages is also blocked with a corresponding notice.
-
-The environment choice is fixed once the first message is sent and the session is created. To switch afterward, see the in-place switching capability for IM sessions under "Session entry kind" below, or fork a new session.
+Offline runners cannot be selected, and if the selected runner goes offline you cannot send messages. The environment is fixed once the session is created; to change it, fork a new session (IM sessions can switch in place).
## Binding a Team
----
+When creating a session you can **bind a team**; the session then loads that team's knowledge, Skills and MCP. Your choice is remembered. In a personal session without a team, the agent can load knowledge from your teams when needed; a team session uses only shared content and that team's content.
-When you create a session you can **bind a team** to it. Once bound, the session automatically loads that team's knowledge, skills, and MCP servers at startup, giving the agent the team's domain context and capabilities from the very beginning. When no team is bound, the session runs in account scope.
+<Note>
+Automatic team binding for incidents and war rooms is still being improved.
+</Note>
-<Steps>
- <Step title="Select a team">
- Use the team selector in the new-session input area to choose the team to bind. Your last selection is remembered, so you do not have to repeat it each time.
- </Step>
- <Step title="Automatic team context loading">
- As soon as the session starts, the knowledge / skill / MCP metadata for "account scope + bound team" is loaded and the agent is ready to use.
- </Step>
- <Step title="Personal sessions mount team knowledge on demand">
- In a personal session not bound to a team, the agent can read the knowledge of teams the session creator belongs to on demand, mounting that team's knowledge and capabilities as persistent context in the current session — a mount remains active for the lifetime of the session. A session bound to a team uses only the Shared knowledge and that team's knowledge, and cannot mount other teams'.
- </Step>
-</Steps>
+## Session source
-The bound team stays with the session: reopening the same session restores the original team binding, and the session's team is also shown in the sidebar tooltip.
+Each session records where it came from, which affects some behavior:
-<Warning>
-Automatic linking between incidents / war rooms and teams is still evolving. You can currently bind a team to a session explicitly; automatic binding in incident scenarios will continue to improve in future updates.
-</Warning>
+| Source | Notes |
+|---|---|
+| Console | Runtime environment and team are fixed at creation |
+| IM platforms (Feishu / DingTalk / WeCom / Slack) | Switch environment and team in the conversation with `/env` and `/scope` |
+| API | Programmatic integrations. When creating a session with `POST /safari/session/create` you can pass `entry_kind` (`web` / `im` / `api` / `automation`, default `web`); it cannot be changed later |
+| Automation | Triggered by automation rules |
-For the rules governing team scope for resources (account scope vs. team scope, visibility, and edit permissions), see the "Scope" section on each resource page.
+## Reply language
-## Session entry kind
+The **reply language** is set when the session is created and used for the whole session.
----
+| Source | Reply language |
+|---|---|
+| Console | The console UI language at creation; changing the UI language later does not affect existing sessions |
+| IM / API / Automation | The account's default notification language |
-Every session is created with an **entry kind** (`entry_kind`) that identifies which surface produced it. The value is persisted to the database and returned in the create response.
+## Integrating sessions through the API
-| Value | Source | Notes |
-|---|---|---|
-| `web` | Console | Default; unknown or missing values are automatically normalized to `web` |
-| `im` | IM platform (Feishu / DingTalk / WeCom / Slack) | Set automatically by the IM path; enables **in-place switching** for the session (see below) |
-| `api` | External API call | For programmatic integration scenarios |
-| `automation` | Automated workflow | Sessions triggered by automation tasks |
+This section is for developers integrating AI SRE sessions through the [Open API](/en/api-reference/ai-sre/sessions/session-read-info).
-When calling `POST /safari/session/create`, you may include `entry_kind` in the request body (optional; defaults to `web`). The `entry_kind` cannot be changed after the session is created.
+### Withdrawing a queued message
-<Note>
-Sessions with `entry_kind=im` support **in-place environment and team switching** — the IM `/env` and `/scope` commands can rebind the session to a different execution environment (a BYOC runner or the cloud sandbox) or team scope without discarding the conversation. Console sessions (`web`) have their environment and team fixed at creation time and do not support in-place switching.
-</Note>
-
-## Reply language
+The `pending_messages` field in the `POST /safari/session/get` response lists queued messages the agent has not read yet, in execution order. Before the agent reads one, its author can withdraw it with `POST /safari/session/message/cancel`, passing `session_id` and `invocation_id` (the invocation ID returned when the message was sent). The `result` field means:
----
+| Result | Meaning |
+|---|---|
+| `removed` | Removed from the queue and will never run; clients receive a `user_message_cancelled` frame |
+| `consumed` | The agent already read it, so withdrawing has no effect; use Stop to interrupt |
+| `forbidden` | The caller is not the message author |
-Every session determines a **reply language** at creation time. The agent replies in that language for the entire session and never switches midway; reopening the session later continues in the same language.
+Only regular human messages can be withdrawn, not question answers or messages produced internally. The caller needs permission to chat in the session.
-| Entry kind | Where the reply language comes from |
-|---|---|
-| Console (`web`) | Follows the console UI language when the session is created; it is fixed at creation, so switching the UI language afterward does not affect existing sessions |
-| IM / API / automation (`im` / `api` / `automation`) | These entries carry no UI-language signal, so they default to the account's notification language |
+### Error markers in stream frames
-## Session data export
+Frames in the session stream may carry `is_error` and `error_code`, marking a runtime error the platform surfaces to the user. A frame without them may still contain diagnostics; they also differ from the `error` line that marks a broken export stream below.
----
+### Session data export
`POST /safari/session/export` streams all events from a session as **NDJSON** (`application/x-ndjson`), one JSON object per line. This is intended for auditing, archiving, offline analysis, or feeding session data into external systems.
-### Request fields
+#### Request fields
| Field | Type | Required | Description |
|---|---|---|---|
| `session_id` | string | Yes | ID of the session to export |
| `include_subagents` | bool | No | When `true`, recursively includes the event streams of all subagent child sessions; defaults to `false` |
-### Response format
+#### Response format
The response `Content-Type` is `application/x-ndjson`. The **first line is always** a `session_meta` envelope containing the session's metadata; subsequent lines are session events. When `include_subagents=true`, each `subagent_dispatch` line is immediately followed by the complete event stream of the child session, which also begins with its own `session_meta` line.
@@ -554,7 +342,8 @@ The response `Content-Type` is `application/x-ndjson`. The **first line is alway
{"type":"final_answer","seq":5,"session_id":"s_...","content":"...","usage":{"input_tokens":0,"output_tokens":0,"cache_read":0,"cache_creation":0},"ts":"2026-09-08T08:05:00Z"} // turn-final answer
```
-#### Line types
+<AccordionGroup>
+<Accordion title="Line types">
The export stream contains only the line types below (the `type` field); no other types occur:
@@ -571,26 +360,28 @@ The export stream contains only the line types below (the `type` field); no othe
| `session_fork` | The "Forked from conversation" divider row | `content` |
| `error` | Appended at the end of the stream when an error occurs after streaming started, or inlined when a child session is unavailable under `include_subagents` | `content` (error text; consumers must inspect this line to tell whether the stream completed — see the Warning below) |
-#### Fields and behavioral conventions
+</Accordion>
+<Accordion title="Fields and behavioral conventions">
- **`seq`**: a monotonic counter over **lines emitted**, starting at 1 (reset per child session; never reset across pages). When one DB event yields several lines (see below), the lines are numbered consecutively in part order. `session_meta` lines carry no `seq`.
-- **`call_id` (the pairing key)**: the ADK `function_call` / `function_response` id (both sides of a call share the same `id`). A single model response can bundle several tool calls into **one DB event** (e.g. 2 `agent_dispatch` calls + 1 `bash` call in the same event); the export emits one line per part, in the original part order, and `call_id` lets a consumer re-pair a response line with its call line without relying on emission order.
+- **`call_id` (the pairing key)**: the `function_call` / `function_response` id (both sides of a call share the same `id`). A single model response can bundle several tool calls into **one DB event** (e.g. 2 `agent_dispatch` calls + 1 `bash` call in the same event); the export emits one line per part, in the original part order, and `call_id` lets a consumer re-pair a response line with its call line without relying on emission order.
- **`usage` (token counts)**: per-event totals (`input_tokens` / `output_tokens` / `cache_read` / `cache_creation`), emitted as `0` rather than omitted when absent. It is **stamped on the first line of the event only** — the lines of a batched dispatch share one usage figure, so a consumer that sums per line is not over-counted N times.
-- **No model identifier**: the export deliberately carries **no serving model identifier** — neither `session_meta` nor `llm_call` lines have a `model` field. The export is a customer-downloadable artifact, and the model identifier combined with the per-call token counts is enough to reconstruct the underlying usage cost, so it stays server-side only (`t_session.chat_model`); no customer-facing export or query returns it (`/safari/session/get` does not expose it either), so scripts that parsed `model` from the export must be adjusted.
+- **No model identifier**: the export deliberately carries **no serving model identifier** — neither `session_meta` nor `llm_call` lines have a `model` field. The export is a customer-downloadable artifact, and the model identifier combined with the per-call token counts is enough to reconstruct the underlying usage cost, so neither the export nor the query APIs (including `/safari/session/get`) return it.
- **Timing**: `ts` is the event's write time (RFC 3339). `llm_call` and `tool_call` lines use it as an approximation of the **end time** (`ended_at`); start times and durations (`started_at` / `duration_ms`) are not provided (empty / 0).
- **`include_subagents=true`**: each `subagent_dispatch` line is immediately followed by the child session's complete export stream, recursively (every dispatch line of a batch is inlined, not just the first); the child's `seq` restarts at 1 and its `session_meta` carries `parent_session_id`. If a child session is missing or fails to export, the parent stream is not interrupted — an inlined `error` line is emitted and the stream continues.
- Some bookkeeping rows produce no export line (e.g. OAuth-authorized markers), so the line count can be lower than the session's event count.
+</Accordion>
+</AccordionGroup>
+
<Warning>
If an error occurs after streaming has already begun, the server cannot switch to a standard JSON error envelope. Instead, a JSON-encoded error object is appended as the final line of the stream. Consumers must inspect this last line to determine whether the stream completed successfully.
</Warning>
-**Permissions**: the export endpoint uses the same access gate as sending messages (`CanChatSession`), meaning the caller must have message-send permission on the session — read-only access is not sufficient. Personal sessions can be exported only by their creator; team sessions can be exported by same-account members who can access the session.
+**Permissions**: the export endpoint uses the same access gate as sending messages, meaning the caller must have message-send permission on the session — read-only access is not sufficient. Personal sessions can be exported only by their creator; team sessions can be exported by same-account members who can access the session.
## Related Pages
----
-
<CardGroup cols={2}>
<Card title="Overview" icon="robot" href="/en/ai-sre/overview">
Learn about AI SRE's positioning, capabilities, and use cases.
diff --git a/en/ai-sre/skills.mdx b/en/ai-sre/skills.mdx
index 29930de0..2650ff68 100644
--- a/en/ai-sre/skills.mdx
+++ b/en/ai-sre/skills.mdx
@@ -5,14 +5,10 @@ keywords: ["AI SRE", "Skill", "SKILL.md", "Marketplace", "skill-creator", "agent
sidebarTitle: Skills
---
-<Info>
- AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it must be activated in the console before use and is billed on actual usage; see [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-</Info>
+> AI SRE must be activated in the console, is available on On-call Pro or higher, and is billed on actual usage. See [Activation and billing](/en/ai-sre/overview#activation-and-billing).
## Overview
----
-
A Skill is a **reusable capability bundle**. Every skill consists of two parts:
- A **SKILL.md** instruction document that tells the agent "when to use it, how to use it, and what steps to follow";
@@ -34,7 +30,7 @@ If you just want to **mention** `/skill-name` in a message (for example, asking
The difference between Skills and MCP: MCP provides **connectivity to external tools**; Skills provide **the methodology for orchestrating those tools to complete a category of tasks**. They work together — a skill declares in SKILL.md which tools it needs, including built-in tools and MCP tools in the form `mcp:server/tool`.
</Tip>
-### SKILL.md Format
+## SKILL.md Format
`SKILL.md` consists of two parts — YAML frontmatter (metadata) and a body (human-readable instructions for the agent) — separated by `---`:
@@ -82,28 +78,29 @@ Tools can be specified in two ways:
- **Built-in tools**: write the tool name directly. Available built-in tools include `read`, `write`, `edit`, `bash`, `grep`, `glob`, `skill`, `mcp`, `todo`, `time`, `webfetch`, `web_search`, and others.
- **MCP tools**: write them as `mcp:server/tool` (e.g., `mcp:my-server/query`). At upload time, only the existence of the MCP server is validated; the specific tool name is verified when the MCP is loaded during a session.
-<Note>
-The AI SRE runtime bundles a few skills that are available without installation. `flashduty` is one such reference: it uses the `fduty` CLI to cover the entire Flashduty API, allowing the agent to investigate incidents, read AI insights, query alerts, correlate changes, and more — use it as a template when writing your own skills. Another bundled skill is `github`, which the agent self-selects from `<available_skills>` to let AI SRE work directly inside a GitHub repository — explore code, investigate PRs and commits, and open a PR or issue on request; it requires the GitHub App (cloud) or the runner host's `gh` (BYOC). A third bundled skill is `gitlab`, symmetric with `github` in capability: the agent self-selects it to work directly inside a GitLab repository — explore code, trace MRs and issues, and open an MR or issue on request; it requires the GitLab App (cloud) or the runner host's `glab` (BYOC). See [Apps](/en/ai-sre/apps).
+## Built-in Skills
-There is also `flashduty-docs`: it downloads Flashduty's **official documentation** (both the Chinese and English page sets, the glossary and the Open API specs) into the runtime environment and answers questions about **how the product itself works** by searching it by topic — features, settings, limits, plans, compatibility, SDK behaviour and performance impact, API fields and errors — across On-call, RUM, Monitors, AI SRE, Status Page, the platform and Open API. Its answers cite public docs.flashduty.com links and are drawn from the docs alone; where the docs do not cover something it says so plainly. It only reads documentation and does not replace hands-on work (actual RUM instrumentation belongs to `rum`), and the docs bundle's address is injected by the platform, so there is nothing to configure.
-</Note>
+The AI SRE runtime bundles these skills; no installation needed:
-<Note>
-Those are examples, not the whole set: the runtime also bundles `init`, `insight`, `artifact-design`, `alert-governance`, `monit-query` and more, and the set grows between releases. What the agent actually sees in a session is `<available_skills>`; to find out which bundled skills a given session has, just ask the agent.
-</Note>
+| Skill | What it does | Requirements |
+| --- | --- | --- |
+| `flashduty` | Covers the entire Flashduty API through the `fduty` CLI: investigate incidents, read AI insights, query alerts, correlate changes, and more. A good reference when writing your own skills | — |
+| `github` | Works inside a GitHub repository: explore code, investigate PRs and commits, open a PR or issue on request | The GitHub App (cloud) or the runner host's `gh` (BYOC); see [Apps](/en/ai-sre/apps) |
+| `gitlab` | The GitLab counterpart of `github`: explore code, trace MRs and issues, open an MR or issue on request | The GitLab App (cloud) or the runner host's `glab` (BYOC) |
+| `flashduty-docs` | Searches Flashduty's official docs (Chinese and English pages, glossary, Open API specs) to answer how the product works — features, settings, limits, plans, compatibility, SDK behaviour, API fields and errors — citing docs.flashduty.com links. Answers from the docs only and says so when they don't cover something. Doesn't replace hands-on work (RUM instrumentation belongs to `rum`) | Nothing to configure |
-## Install from Marketplace
+There are more — `init`, `insight`, `artifact-design`, `alert-governance`, `monit-query` and others — and the set grows between releases. To see which skills a given session has, just ask the agent.
----
+## Install from Marketplace
-The skill catalog is part of the plugin catalog on **Customize → Plugins → Overview**: skill templates are listed alongside MCP templates and the built-in Apps, grouped by category, with skills in their own **Skill** category (they also appear under the "All" tab, tagged `Skill`). The search box above the catalog filters by name or description, the tabs narrow the list to one category, and "See all N" next to a category heading expands that category; the search term and the selected tab live in the page URL, so leaving and coming back lands you where you were.
+The skill Marketplace is part of the plugin catalog on **Customize → Plugins → Overview**, under the **Skill** category; search by name or description.
<Steps>
<Step title="Find the template">
On **Customize → Plugins → Overview**, find the template under the **Skill** category; each row shows the template name and description.
</Step>
<Step title="Confirm the install">
- An uninstalled row has a round **+** button on its right; clicking **+** or the row itself opens the `Install skill "<name>"` confirmation dialog: "Installs to the account — available to all members." Marketplace installs are always **shared scope** (shared = account level), with no owner selection. Click **Install** to actually call the install endpoint — this copies the template content into your account as a regular skill entry and marks its source template (shown on the list as a `From Marketplace — <template name> v<version>` tooltip). A successful install reports `"<name>" installed`.
+ Click a template row or its **+**, then confirm to install. Marketplace installs are always **shared scope** (available to all members of the account); the template is copied into your account as a regular skill, labeled with its source template and version.
</Step>
<Step title="Manage what is installed">
An installed row no longer shows **+**; it shows **Enabled**. Managing and updating it happens on the **Customize → Plugins → Skill** list — see "Management and Inspection" and "Automatic and Manual Updates" below.
@@ -137,8 +134,6 @@ Updating a modified skill **overwrites your local changes with the latest Market
## Custom Skills
----
-
In addition to installing from the Marketplace, you can upload your own skill packages. On the skill list page, click **Upload Skill** and fill in the form:
| Field | Type | Required | Description |
@@ -154,26 +149,19 @@ All metadata other than the skill name (description, version, tags, author, tool
### Overwrite upload (Replace)
-When you want to replace an existing skill with a new version, the upload endpoint supports two overwrite modes. The UI presents a "Replace" confirmation dialog at the appropriate moment:
-
-| Mode | Trigger | Behavior |
-| --- | --- | --- |
-| **Replace by name** | Upload with `replace=true` and no `skill_id` | Matches an existing skill in the account by the `name` field in the new archive's `SKILL.md` and overwrites its content. The SkillID remains the same, so all existing references (e.g., `/<skill-name>` triggers) continue to work. |
-| **Replace by ID** | Upload with `replace=true` and a `skill_id` | Ignores the `name` field in the zip and directly targets the skill with the specified ID. Use this when you want to overwrite a specific record even if the skill has been renamed. |
+By default, uploading an archive whose name matches an existing skill is rejected. To replace an existing skill with a new version, choose "Replace" in its detail panel, or confirm the "Replace" dialog that appears when you upload a skill with the same name. The SkillID stays the same, so references such as `/<skill-name>` keep working; a replace never creates a new skill.
-Both modes return the updated skill object on success. If the target skill does not exist, a 404 error is returned — neither mode silently creates a new skill. **Without the `replace` parameter (the default), a name collision is rejected outright**; the upload endpoint never implicitly overwrites an existing skill.
+Via the API, upload with `replace=true` to match and overwrite by the `name` in `SKILL.md`; add a `skill_id` to overwrite by ID instead (useful after a rename). A missing target returns 404.
### Add in conversation (skill-creator)
Besides uploading a zip, you can **create and refine skills right inside an AI SRE session**. `skill-creator` is a Flashduty-provided Marketplace skill, pre-installed into your account by default, that exists specifically to "build skills." Trigger it with `/skill-creator` in any session, or just describe what you want in natural language:
-**Add in conversation** at the top right of the skill list page opens a new session with a pre-filled brief: "I want to add a Skill. First ask me whether I'm authoring it myself or installing an existing one from the web. For an existing one, search a few candidates for me to pick from, and install the one I choose." In other words the agent first asks whether you want to **author a new one** or **install an existing one**; for an existing one it checks the plugin catalog / Marketplace first, searches the web only when the catalog has nothing, and installs what you pick. The prompt is only pre-filled, never sent automatically. The button appears only when you have a scope you can author into: always when you can author at account scope, otherwise when the current scope filter selects exactly one team you belong to (or you belong to only one team).
-
- **Create from scratch**: say "help me create a skill for troubleshooting X," or after an investigation, "turn that workflow into a skill." skill-creator clarifies your intent, drafts the `SKILL.md`, optionally sets up test cases and iterates on them, and saves the result as a skill in your account once you're happy.
-- **Find an existing one online**: when you enter through "Add in conversation" and choose to install an existing skill, the agent checks the plugin catalog first and searches the web only when the catalog has nothing; once you pick one it completes the install, which becomes a regular skill entry.
+- **Install an existing one**: click **Add in conversation** at the top right of the skill list page and choose to install an existing skill. The agent checks the plugin catalog first, then searches the web if nothing matches; once you pick one, it completes the install. (The button appears only when the target scope is unambiguous — you have account-level permission, or exactly one of your teams is selected.)
- **Rewrite & optimize**: click **"Edit in Chat"** in a skill's detail panel to have skill-creator rewrite that skill; it can also tune the `description` to improve triggering accuracy.
-Once the draft is ready, the agent saves it as a skill with one click. If the name conflicts with an existing skill, a "Replace" confirmation dialog appears — under the hood this invokes the replace-by-name mode (`replace=true`, no `skill_id`).
+Once the draft is ready, the agent saves it as a skill with one click. If the name conflicts with an existing skill, a "Replace" confirmation dialog appears.
<Warning>
Skill archive size limits: archives saved by the agent in-conversation are capped at **10 MB**; archives uploaded via the web form or file upload in a session are capped at **100 MB**.
@@ -181,9 +169,7 @@ Skill archive size limits: archives saved by the agent in-conversation are cappe
## Management and Inspection
----
-
-The skill list displays each skill's **name** (with source template badge, **Update available** marker, and **Local runner only** badge), **scope** (shared or team), **version**, **enabled** toggle, and an **actions** column. Skills that declare `venues: [byoc]` carry a **Local runner only** badge whose tooltip reads "Available only in sessions bound to a local runner; unavailable in cloud sandbox sessions"; Marketplace template cards show the same badge, so you know a template needs a self-hosted Runner before you install it. The toolbar above the list provides a scope filter (All / Account / Team) and a search box that filters the list by keywords in the name, description, or author.
+The skill list shows each skill's name, scope (shared or team), version and enabled state, with labels for the source template, **Update available** and **Local runner only**. Skills that declare `venues: [byoc]` are labeled **Local runner only**: they work only in sessions bound to a local runner, not in cloud sandbox sessions. Marketplace templates carry the same label so you can tell before installing. You can filter by scope (All / Account / Team) and search by name, description or author.
<AccordionGroup>
<Accordion title="Enable / Disable" icon="toggle-on">
@@ -209,9 +195,9 @@ Click any row in the list to open the skill's **detail panel**:
- **Left side**: the file tree of the skill package (`SKILL.md`, `README.md`, etc. are prioritized as the default preview file).
- **Right side**: content preview of the selected file, with the skill description shown at the top.
-- **Header area**: skill name (short reference in the form `skill-xxxxxx`), scope label (shared / team name), source template version badge (hover to see "From Marketplace — template name `v<version>`"), **Update available** marker, author, `version`, and the full SkillID.
+- **Header area**: skill name and short reference (such as `skill-xxxxxx`), scope, source template version, **Update available** marker, author, `version` and the full SkillID.
- **Actions**: try in chat (injects `/<skill-name>` into a new session), update to latest version, edit in chat, replace, download, uninstall.
-- **Try asking**: if the skill declares `examples` in the `SKILL.md` frontmatter, a **Try asking** toggle appears below the header area of the detail panel, **collapsed by default** — the sample questions are not laid out until you click it; expanding it lists up to 2 sample questions, and clicking one opens a new session with that skill plus the question pre-filled (never sent automatically). The bottom of the expanded area carries the hint "Clicking a question opens a new chat with it filled in. Review it, then send."
+- **Try asking**: if the skill declares `examples` in the `SKILL.md` frontmatter, you can expand up to 2 sample questions; clicking one opens a new chat prefilled with the skill and question, ready for you to review and send.
<Tip>
When a skill package is **too large to preview**, the detail panel displays the file size and suggests using "Download" instead.
@@ -219,8 +205,6 @@ When a skill package is **too large to preview**, the detail panel displays the
## Scope
----
-
Skills share the same **two-level scope** model with other resources (Knowledge, MCP, Agents, environments), divided into account level and team level:
| Scope | Visibility |
@@ -230,18 +214,21 @@ Skills share the same **two-level scope** model with other resources (Knowledge,
**Edit permissions**: team-level skills can be acted on only by members of that team — organization admins must join the team first; account-level skills can be acted on only by the account owner or an account administrator. There is no "creator retains rights" exception. Rows you cannot edit appear as **read-only** in the list.
-**Create and reassign**: to upload a new team-level skill, you must belong to the target team; account-level upload is limited to the account owner or admins. **Marketplace installs are the exception**: they are always shared scope (account level), any account member can install one (no owner/admin permission required), and no team can be chosen at install time. When editing an existing skill, the account owner or admins can move it to any team to recover resources left behind by empty teams or departed members; regular members can move it only to teams they belong to. However, **Marketplace-installed skills cannot be reassigned to a team** — their scope is shown as a fixed account value in the edit form. A small number of legacy team-scoped Marketplace skills from earlier versions can be promoted to account scope via **Set to Shared** in the detail panel. **Set to Shared carries the same gate as account-level upload: only the account owner or admins can do it** — a regular member cannot self-serve the promotion even for their own team's skill, and the denied action prompts them to ask an admin to make it shared.
+**Create and reassign**:
-**Runtime visibility**: at session start, only **shared-scope (account-level)** skills and skills belonging to the **team bound to the current session** are loaded into the session. Skills and MCP servers from other teams are mounted into the current session on demand only after the agent reads that team's knowledge during an investigation. **The account is the sole security boundary at runtime, and using a team-level skill is bound by the same visibility rules — a team is no longer just an ownership and editing tag on this surface.**
+- Uploading a team-level skill requires membership in the target team; uploading an account-level skill is limited to the account owner or admins.
+- **Marketplace installs are the exception**: always shared scope, any member can install one, no team can be chosen at install time, and the skill cannot be reassigned to a team later.
+- When editing an existing skill, the account owner or admins can move it to any team (to recover resources left by empty teams or departed members); regular members can move it only to teams they belong to.
+- A few legacy team-scoped Marketplace skills can be promoted to account scope with **Set to Shared** in the detail panel — **account owner or admins only**.
+
+**Runtime visibility**: at session start, only **shared-scope (account-level)** skills and skills belonging to the **team bound to the current session** are loaded into the session. Skills and MCP servers from other teams are mounted into the current session on demand only after the agent reads that team's knowledge during an investigation. **The account is the sole security boundary at runtime, and using a team-level skill is bound by the same visibility rules — a team is not just an ownership and editing tag here.**
<Note>
-The `/` autocomplete dropdown in the chat input only shows **shared-scope skills** plus team-level skills for **teams you belong to** — and that visibility is the resolution boundary, not just menu cosmetics. Manually typed slash commands pass through the exact same per-row scope gate ("resolve == visible"), so a team-level skill outside the current session's reach is never parsed or executed. Concretely: in a team session, invoking another team's command is rejected with a message explaining why; in a personal session, the command resolves (mounting the team on demand) only for members of the team that owns the skill — a non-member's input is refused exactly as if the command did not exist.
+The `/` autocomplete in the chat input lists only shared-scope skills and skills of teams you belong to, and typed slash commands follow the same scope. In a team session, invoking another team's skill is rejected with the reason; in a personal session, only members of the owning team can invoke it (the team is mounted on demand).
</Note>
## Related Pages
----
-
<CardGroup cols={2}>
<Card title="Manage Knowledge" icon="book" href="/en/ai-sre/knowledge">
Use DUTY.md and knowledge to provide the agent with team context and troubleshooting experience.
@@ -252,7 +239,7 @@ The `/` autocomplete dropdown in the chat input only shows **shared-scope skills
<Card title="Agent" icon="satellite-dish" href="/en/ai-sre/agents">
Extend AI SRE's collaboration and task-delegation capabilities with Agents.
</Card>
- <Card title="Console" icon="comments" href="/en/ai-sre/sessions">
+ <Card title="Console Chat" icon="comments" href="/en/ai-sre/sessions">
Explicitly trigger a skill in a session with `/<skill-name>`, or let the agent invoke it autonomously.
</Card>
<Card title="Overview" icon="gauge-high" href="/en/ai-sre/overview">
diff --git a/en/compliance/service-sla.mdx b/en/compliance/service-sla.mdx
index 18bb92d6..96654144 100644
--- a/en/compliance/service-sla.mdx
+++ b/en/compliance/service-sla.mdx
@@ -10,7 +10,6 @@ This Service Level Agreement (hereinafter referred to as "SLA") stipulates the s
Please note that unless otherwise agreed, this agreement does not apply to Flashduty's beta, invitation-only, free features and versions, nor does it apply to Flashduty's on-premises version.
## How We Ensure SLA
----
1. **Multi-Active in Same City**: Infrastructure is built on multiple data centers, with stateful components all running in multi-active mode within the same city;
2. **Asynchronous Processing**: After an alert is reported, it immediately enters an asynchronous process with retry mechanisms, reducing the risk of alert loss;
@@ -19,7 +18,6 @@ Please note that unless otherwise agreed, this agreement does not apply to Flash
5. **Continuous Monitoring**: Comprehensive collection of system metrics, regular stress testing to identify system issues proactively or in advance.
## Our SLA Commitment
----
- **Feature Availability (Error Rate)**: Core features are available 99.9% of the time
- **Delivery Timeliness (Delay Rate)**: 99.9% of alerts are delivered within 5 minutes of triggering
@@ -58,7 +56,6 @@ Service unavailability due to the following reasons will not be counted as servi
- Force majeure events.
## How to Apply for Compensation
----
### Compensation Standards
@@ -75,7 +72,6 @@ You can submit compensation applications for Flashduty services that didn't meet
Compensation applications must be submitted within two (2) months after the end of the month when Flashduty failed to meet service availability commitments.
## Additional Notes
----
Flashcat Cloud reserves the right to modify these SLA terms.
diff --git a/en/compliance/terms-of-service.mdx b/en/compliance/terms-of-service.mdx
index 0b922e95..6878f4f3 100644
--- a/en/compliance/terms-of-service.mdx
+++ b/en/compliance/terms-of-service.mdx
@@ -8,7 +8,6 @@ Last Updated: 2023-02-10
Welcome to sign this "Flashcat Cloud Product Service Agreement" (hereinafter referred to as "this Agreement") with Beijing Flashcat Cloud Technology Co.,Ltd. (hereinafter referred to as "Flashcat Cloud") and use Flashcat Cloud services!
## **General Terms**
----
1.1. You confirm that before using this service, you have fully read, understood, and accepted all contents of this agreement and other related agreements and rules (especially the content marked in bold and/or underlined). Once you select "Agree" on this website (specific wording detailed on the registration page) and complete the purchase process or choose to use this service in any other way, you agree to comply with all terms under the aforementioned agreements and/or rules and are willing to be bound by them.
@@ -19,7 +18,6 @@ Welcome to sign this "Flashcat Cloud Product Service Agreement" (hereinafter ref
1.4. Flashcat Cloud only provides technical services and technical support related to Flashcat Cloud services, and is a neutral information storage space and related technical service provider. The websites, applications, and any products, services, and related content that you own, upload, store, or manage and operate in any form through Flashcat Cloud are developed and operated by you, and you bear full responsibility. Flashcat Cloud assumes no responsibility for any such products, services, and related content.
## **Standard Service Terms**
----
### **1. Contracting Parties and Agreement Scope**
diff --git a/en/compliance/user-agreement.mdx b/en/compliance/user-agreement.mdx
index 99e11841..777d9632 100644
--- a/en/compliance/user-agreement.mdx
+++ b/en/compliance/user-agreement.mdx
@@ -11,7 +11,6 @@ This "Flashduty User Agreement" (hereinafter referred to as "this Agreement") is
Please carefully read and fully understand each clause of this Agreement, as well as any separate agreements or rules (hereinafter referred to as "other relevant agreements and rules") that should apply and be followed when activating or using certain Flashcat Cloud Services, especially the terms highlighted in bold or underlined text.
## **1 General Terms**
----
1.1 You confirm that before using the Services, you have fully read, understood, and accepted all contents of this Agreement and other relevant agreements and rules (especially the content marked in bold and/or underlined). Once you select "Agree" on this website (specific wording detailed on the registration page) and complete the registration process or choose to use the Services in any other way, you agree to comply with all terms under the aforementioned agreements and/or rules and are willing to be bound by them.
@@ -22,7 +21,6 @@ Please carefully read and fully understand each clause of this Agreement, as wel
1.4 Flashcat Cloud only provides technical services and technical support related to Flashcat Cloud Services, and is a neutral provider of information storage space and related technical services. Any products, services, and related content that you own, upload, store, or manage and operate in any form through Flashcat Cloud are developed and operated by you, and you shall bear full responsibility. Flashcat Cloud does not assume any responsibility for any such products, services, and related content.
## **2 User Service Account**
----
### **2.1 Account Registration**
@@ -64,7 +62,6 @@ If you are a minor or a person with limited capacity for civil conduct, you do n
2.4.3 You have the right to actively cancel your account by sending an email to [support@flashcat.cloud](mailto:support@flashcat.cloud) to request account cancellation.
## **3 Service Rules**
----
3.1 Instructions sent by you to Flashcat Cloud in the following ways are irrevocable or irreversible instructions issued by you personally, and you shall bear any results and responsibilities arising from Flashcat Cloud executing such instructions:
@@ -112,7 +109,6 @@ If you are a minor or a person with limited capacity for civil conduct, you do n
3.10.5 If you believe content generated by AI Features is illegal, incorrect, or infringes your lawful rights, you may complain or report via the in-product feedback entry or by emailing [contact-us@flashcat.cloud](mailto:contact-us@flashcat.cloud), and Flashcat Cloud will review and act promptly.
## **4 Your Rights and Obligations**
----
4.1 Flashcat Cloud will provide you with network technical and information services, and will provide Flashcat Cloud's technical support, customer consultation, and other services when providing services to you. The content of such services is detailed on the relevant pages of this website.
@@ -167,7 +163,6 @@ If you violate the above promises, Flashcat Cloud can not only take measures suc
4.6 You acknowledge and recognize that installing and using pirated software and other unauthorized software that violates this Service Agreement is not allowed on Flashcat Cloud services. At the same time, you should take all necessary and appropriate security protection measures for your computer information system according to national regulations, including but not limited to installing computer information system security special products permitted by the state.
## **5 Flashcat Cloud's Rights and Obligations**
----
5.1 According to your service selection and payment situation, Flashcat Cloud will provide you with qualified network technical and information services.
@@ -195,7 +190,6 @@ If you violate the above promises, Flashcat Cloud can not only take measures suc
If circumstances occur where your account funds are frozen according to the above provisions, Flashcat Cloud will notify you through one or multiple methods such as email, in-site messages, SMS, or phone calls. You can appeal according to the corresponding procedures. If you appeal according to the requirements of Article 3.8 of this Agreement and pass Flashcat Cloud's review, Flashcat Cloud will immediately lift the fund freezing measures; if you fail to appeal within the specified time, or your appeal fails to pass Flashcat Cloud's review, you acknowledge that Flashcat Cloud has the right to freeze such funds long-term, or return the relevant frozen funds to the original recharge source account through the original route, including but not limited to bank accounts, WeChat accounts, Alipay accounts, etc.
## **6 Personal Information Protection**
----
6.1 Flashcat Cloud collects, uses, stores, shares, and protects your personal information in accordance with the [Privacy Policy](/en/compliance/privacy-policy). The Privacy Policy sets out the categories of information we collect, the purposes for which we use it, whom we share it with, cross-border transfers, retention periods, device permission and third-party SDK disclosures, and the rights you have over your personal information.
@@ -204,7 +198,6 @@ If circumstances occur where your account funds are frozen according to the abov
6.3 For your responsibility in safeguarding your account and password, see Article 2.3 of this Agreement.
## **7 System Interruption or Failure**
----
When the following circumstances occur, the Flashcat Cloud service system may not operate normally, thus causing you to be unable to use the services and producing corresponding consequences, for which Flashcat Cloud shall not bear any responsibility:
@@ -218,7 +211,6 @@ When the following circumstances occur, the Flashcat Cloud service system may no
- 8. Other circumstances not due to Flashcat Cloud's fault, beyond Flashcat Cloud's control or reasonable foresight.
## **8 Scope of Responsibility and Limitation of Liability**
----
8.1 Flashcat Cloud only assumes responsibility within the scope of responsibility stated in this Agreement.
@@ -231,14 +223,12 @@ When the following circumstances occur, the Flashcat Cloud service system may no
8.5 In any case, unless otherwise stipulated in this Agreement or separately agreed between Flashcat Cloud and you regarding a specific product and/or service, you agree that the total compensation liability borne by Flashcat Cloud under the terms of this Agreement and other relevant agreements and rules shall not exceed the total service fee charged to you for that particular service.
## **9 Intellectual Property**
----
9.1 Except for third-party products or services, all content on this website, including but not limited to all content of related products or services, as well as images, logos, files, information, architecture, page design, etc., are legally owned by Flashcat Cloud or Flashcat Cloud affiliated companies for their intellectual property rights, including but not limited to copyright, trademark rights, patent rights, trade secrets, etc. For any behavior infringing upon Flashcat Cloud's intellectual property rights, Flashcat Cloud has the right to require legal responsibility according to relevant applicable laws and the provisions of this Agreement.
9.2 Without written permission from Flashcat Cloud or Flashcat Cloud affiliated companies, no one may use, modify, copy, distribute, spread, publish or publicly display any part of the products, services, software, programs, information, etc. on this website in any way or for any reason, or bundle them with other products for use or sale, or use them through hyperlinks or transmission or for any other commercial purposes.
## **10 Confidentiality**
----
10.1 Under this Agreement, for any information received by either party ("Receiving Party") from the other party ("Disclosing Party"), if marked or can be reasonably considered as confidential or proprietary information of the Disclosing Party (including but not limited to technical, commercial related information, hereinafter referred to as "Confidential Information"), the Receiving Party shall keep it confidential, and without written consent from the Disclosing Party, shall not use it for any purpose outside this Agreement. The Receiving Party shall handle the Disclosing Party's Confidential Information with the same degree of care as it uses to protect its own confidential information (and not less than reasonable prudent duty).
@@ -254,7 +244,6 @@ When the following circumstances occur, the Flashcat Cloud service system may no
10.4 Both parties' confidentiality obligations remain valid during the effective period of this Agreement and after its expiration, until the relevant information no longer has confidential significance.
## **11 Complete Agreement**
----
11.1 This Agreement consists of these Agreement terms and various rules displayed on this website. If there are different understandings of the meanings of words used in this Agreement and various rules displayed on this website, the terms of this Agreement shall prevail.
@@ -265,14 +254,12 @@ When the following circumstances occur, the Flashcat Cloud service system may no
11.4 If part of the content of this Agreement is determined to be invalid or unenforceable by a court with jurisdiction, it does not affect the validity or enforceability of other content.
## **12 Notice Delivery**
----
12.1 You understand and recognize that after reasonable judgment, Flashcat Cloud can send notices to you through webpage announcements, emails, SMS, or regular mail delivery, etc., and Flashcat Cloud can presume that the contact information you provide to this website is complete, accurate, and currently valid; the above notices are deemed delivered to the recipient on the date of sending.
12.2 Unless otherwise agreed in the terms of this Agreement or explicitly specified in a special agreement signed between Flashcat Cloud and you, any notice you send to Flashcat Cloud must be delivered through Flashcat Cloud's officially announced communication address, fax number, email address, and other contact information.
## **13 Applicable Law and Dispute Resolution**
----
13.1 The signing place of this Agreement is Haidian District, Beijing.
diff --git a/en/developer/cli.mdx b/en/developer/cli.mdx
index 6c3c6dbc..1958f03a 100644
--- a/en/developer/cli.mdx
+++ b/en/developer/cli.mdx
@@ -54,7 +54,7 @@ A copy installed under another command name uses that name in help output, error
flashduty login
```
-When prompted, paste your APP Key. To obtain one, sign in to the [Flashduty console](https://console.flashcat.cloud) and copy your APP Key from **Profile > Personal Info**.
+When prompted, paste your APP Key. To obtain one, sign in to the [Flashduty console](https://console.flashcat.cloud) and copy your APP Key from **Profile → Personal Info**.
### Credential resolution order
@@ -892,7 +892,7 @@ Table view with no column truncation — useful for copy-paste or wide terminals
</Tab>
</Tabs>
-#### Generated-command output bound
+### Generated-command output bound
Generated commands (the ones covering the OpenAPI through the code generator, such as `safari session-list`, `monit datasource-list`, `safari a2a-agent-list`) apply a 16 KiB bound to **list-shaped** responses in `json`/`toon` mode. The reduction has three tiers, plus a machine-readable marker:
diff --git a/en/developer/go-sdk.mdx b/en/developer/go-sdk.mdx
index 52cac98b..019432e4 100644
--- a/en/developer/go-sdk.mdx
+++ b/en/developer/go-sdk.mdx
@@ -7,8 +7,6 @@ keywords: ["Go SDK", "go-flashduty", "Open API", "Golang", "client"]
## Overview
----
-
`go-flashduty` is the official open-source Go client for Flashduty, covering every REST endpoint of the Flashduty Open API. It follows the same design as [go-github](https://github.com/google/go-github) — service groups, typed requests and responses, a composable transport layer — and stays strictly 1:1 with the OpenAPI spec: each method maps to exactly one HTTP call, returns `(*T, *Response, error)`, and performs no implicit cross-endpoint aggregation or enrichment.
The SDK provides typed API operations generated from the Flashduty OpenAPI spec, covered by unit tests, and end-to-end verified against the live API.
@@ -30,8 +28,6 @@ The module path is `github.com/flashcatcloud/go-flashduty`, the package name is
## Installation
----
-
<Steps>
<Step title="Requires Go 1.24+">
Make sure your local Go toolchain is at least 1.24.
@@ -50,8 +46,6 @@ import flashduty "github.com/flashcatcloud/go-flashduty"
## Quick start
----
-
Here is a minimal runnable example: construct the client, list incidents in the "Triggered" state, and handle the returned triple `(data, *Response, error)`.
```go
@@ -100,8 +94,6 @@ Every call returns three values:
## Create a client
----
-
`NewClient` takes an `app_key` plus zero or more `Option`s. An empty `app_key` returns an error directly. The default Base URL is `https://api.flashcat.cloud`, the default HTTP timeout is 30 seconds, and the default User-Agent is `go-flashduty`.
```go
@@ -146,8 +138,6 @@ Access tokens are issued by the Flashduty OAuth authorization server, whose addr
## Services and methods
----
-
Endpoints are grouped by service and hang off the client: the call convention is uniformly `client.<Service>.<Method>(ctx, req)`, returning `(*T, *Response, error)`. For example, `client.Incidents.List(ctx, req)` or `client.Sessions.Info(ctx, req)`.
| Service field | Description |
@@ -190,20 +180,40 @@ Endpoints are grouped by service and hang off the client: the call convention is
| `client.SessionReplay` | RUM session replay |
| `client.Sourcemaps` | RUM sourcemaps |
+<Note>
+All identifiers, service field names, and method names match the generated code. For exactly which methods each service has and their request and response types, rely on `services_gen.go` and the per-service files, plus the [Open API reference](/en/openapi/introduction).
+</Note>
+
+The following services have behavior that needs extra explanation:
+
+### Status page drafts
+
`client.StatusPages.DraftCreate` (`POST /status-page/draft/create`) stores a status page event draft for a human to review and publish from the console; it is never directly visible to the public: `draft` is arbitrary JSON stored verbatim, up to 64 KB serialized, with `page_id`, `type` (`incident` or `maintenance`), `name`, and `message` validated; `change_id` (> 0 appends an update to an existing event), `status`, and `affected_components` are optional, and for a new maintenance you can set `start_time` / `end_time` (Unix seconds) for the window. The request-level `source` is an opaque marker of the drafting origin (up to 64 characters, e.g. `ai_sre:sess_xxx`); the response returns a `draft_id` matching `draft_[A-Za-z0-9]{22}`, which the console review link carries.
+### Knowledge
+
`client.Knowledge` covers the 9 operations under `/safari/knowledge/*`: on the knowledge side `PackReadGet` (get the account knowledge), `PackReadList` (list knowledge), `PackWriteEnsure` (ensure the knowledge exists), `PackWriteUpdate` (change its scope), and `PackWriteDelete` (delete it); on the file side `FileReadGet`, `FileReadList`, `FileWritePut` (upload/overwrite), and `FileWriteDelete`. Exported types include `KnowledgePackItem`, `KnowledgeFileItem`, `KnowledgeWarning`, and the various `Knowledge*Request` / `Knowledge*Response` structs.
+### AI SRE artifacts
+
`client.Artifacts` (AI SRE artifacts) covers the 11 operations under `/safari/artifact/*`: on the gallery read side `ReadGet` (get a single published artifact by ID), `ReadList` (list artifacts visible to the caller, with title substring search and `scope` (`all` / `personal` / `team`) plus `team_ids` filtering), and `ReadGetFileState` (probe up to 50 presented-file IDs (`pf_` prefix) in one call for ones that already have a live published artifact); on the file side `ReadSign` (issue short-lived download/preview URLs for a presented file, valid 5 minutes, `expires_in` is fixed at 300) and `ReadStream` (download or preview the file's bytes with a signed token — the success body is a file, not a JSON envelope, with the raw bytes on `Response.Raw`); on the write side `WritePublish` (publish a session-produced file to the gallery), `WriteUpdate` (rename the artifact or transfer it between personal and team scope), and `WriteDelete` (detach it from the gallery; the source file stays with its session); public sharing `WriteShareEnable` (turn on anonymous public sharing and return the public link — anyone with the link can view it, no login required), `WriteShareRevoke` (turn sharing off; the link stops resolving immediately), and `WriteShareSync` (refresh the public snapshot with the latest content — when `share_enabled` is true and `share_file_id` differs from `file_id`, the snapshot is stale and calling this refreshes it). Exported types include `PublishedArtifactItem`, `ArtifactShareState`, `SignedUrLs`, and the various `Artifact*Request` / `Artifact*Response` structs.
+### Member email notifications
+
`client.Members.MemberNotify` (`POST /member/notify`, `memberNotify`) sends an email to account members on behalf of the caller, and is callable only with a credential minted for an AI SRE session — any other credential, a plain `app_key` included, is rejected with `AccessDenied` (check it with `IsAccessDenied` / `ErrorCodeOf`). Request fields: `subject` (required, 1–200 characters) and `html` (required, the entire email body the recipients see, up to 102,400 bytes), while `person_ids` is optional (at most 20, no duplicates; omitted or empty sends to the caller only). `script`, `meta`, `link`, and `base` tags and `on*` event handlers are silently stripped from `html` before sending; a `style`, `svg`, `iframe`, `object`, `embed`, `form`, `input`, or `button` tag, an `img` without an `https` `src`, or a link outside `http`/`https`/`mailto` instead fails the call with `InvalidParameter` before anything is queued, naming each offending construct. Delivery is asynchronous, so `accepted` only means the email was queued; the response's `recipients[]` returns one entry per recipient (`person_id` plus `status`), where `status` is `accepted` or `skipped`, and a skipped entry carries a `reason` of `not_member`, `no_email`, `email_disabled`, `duplicate`, `rate_limited` (at most 20 emails per recipient per hour), or `send_failed`. The response carries only two fields, `recipients[]` and an optional `agent_instructions`, and never echoes the sanitized email HTML back; `agent_instructions` is returned when the submitted `html` does not follow the default email layout (no `max-width:600px` wrapper table) and holds guidance addressed to the calling AI SRE agent on how to conform — advisory only, so a layout the caller deliberately chose needs no change.
+### Diagnostic queries
+
`client.Diagnostics.QueryData` runs a synchronous query via `POST /monit/query/data` and returns a stable `query_result.v1` structured result (`result.kind` is one of `frames`, `records`, or `samples`). This API requires monit-edge v0.65.0 or later. For log-pattern and metric-trend analysis, use `client.DataSources.ToolsInvoke` with `prometheus.metric_trends`, `loki.log_patterns`, or `victorialogs.log_patterns`.
`client.Diagnostics.QueryExplore` (`POST /monit/query/explore`, `monit-read-query-explore`) runs an explore query against a configured data source and returns the data source's native `explore_result.v1` shape: `ExploreData.format` is always `explore_result.v1`; `result.kind` is `frames` (columnar tables or time series, see `ExploreFrame` / `ExploreField`), `samples` (instant values with labels, `ExploreSample`), or `logs` (log entries as `ExploreLogEntry`, at most 1,000, with `has_more` set when truncated and `applied_limit` reporting the effective cap); and `execution.effective_step_seconds` echoes the step actually used after applying `max_data_points` and `min_step_seconds`. Request fields: `datasource_id` (from `/monit/datasource/list`, and it must belong to the authenticated account), `expr` (a query expression in the data source's native language — PromQL, LogsQL, SQL, and so on), `args` (macro substitutions keyed by variable name, used for Grafana-style variables; required in the request, so pass an empty `map[string]string{}` when you have none — a nil Go map serializes to `null`, which does not satisfy the schema), and `execution` (`QueryExploreExecution`: `kind` is `instant`, `range`, or `window`; `to_ms` is required for all three; `range` additionally requires `from_ms` and `max_data_points`, `window` additionally requires `from_ms`; `min_step_seconds` is accepted only for `range`). How it differs from `QueryData`: reach for `QueryExplore` when you need the data source's native result shape (raw logs included) and `QueryData` when you need the stable `query_result.v1` contract. This API requires the **data source view** (`monit`) permission and monit-edge v0.68.0 or later in supported deployments.
+### RUM remote config and repositories
+
Beyond application management, `client.Applications` (RUM applications) covers the five **RUM remote configuration** methods: `RemoteConfigReadGet` (`POST /rum/application/remote-config/get`, read the live configuration and its `version`), `RemoteConfigReadHistoryList` (`/rum/application/remote-config/history/list`, page through published history versions), `RemoteConfigReadPreview` (`/rum/application/remote-config/preview`, evaluate a draft configuration against a simulated client's `env` / `app_version` / `sdk` and return the matching rule index `hit_rule_index` plus the `values` finally delivered, without publishing), `RemoteConfigWriteUpdate` (`/rum/application/remote-config/update`, publish a complete new configuration), and `RemoteConfigWriteHistoryRevert` (`/rum/application/remote-config/history/revert`, republish a history version's content as a new version). Main types: `RemoteConfig` (`enabled`, `activation`, `default`, `rules`, `custom`, `refresh_on_foreground`), `RemoteConfigValues` (the four SDK knobs a configuration can set), `RemoteConfigRule` (`match` conditions plus the `set` values), `RemoteConfigHistoryItem` (with `version`, `reason`, `content_hash`, and `updated_by`), and the `GetRemoteConfigRequest` / `ListRemoteConfigHistoryRequest` / `PreviewRemoteConfigRequest` / `UpdateRemoteConfigRequest` / `RevertRemoteConfigRequest` structs with their matching `*Response` types. The application's own `WriteCreate` / `WriteUpdate` / `ReadInfo` / `ReadInfos` / `ReadList` also carry `repositories` (`[]RUMApplicationRepository`, a body-only field rather than a top-level flag): it links the application to the source code repositories that build it — ordered, first entry is the primary repository, at most 10 entries, each one a `Repo` (GitHub repository in `owner/name` form, required) plus an optional `Subdir` (the directory holding the application inside the repository, relative to the repository root — `.` is the repository root, an empty value is saved as `.`). Passing it on create establishes the links; on update the field is presence-based — passing it replaces the whole list, an empty array clears the links, and omitting it leaves them unchanged; `ReadInfo` / `ReadInfos` / `ReadList` echo it back on `RUMApplicationItem`. Linking grants no access by itself: AI sessions can only read repositories granted to the account's GitHub App installations. This field is currently available through the API and SDK only; the console's application management page does not expose repository links.
+### Data source tool invocation
+
`client.DataSources.ToolsInvoke` (`POST /monit/datasource/tools/invoke`, `monit-datasource-tools-invoke`) executes one deterministic tool against a configured datasource: `tool` is a single tool name prefixed by the datasource type (e.g. `mysql.overview`), and `params` is the tool-specific JSON parameters (omitted means `{}`; an explicit `null` is invalid). Alongside diagnostic tools, the entry supports `<type>.query` query tools (`prometheus`, `mysql`, `postgres`, `oracle`, `clickhouse`, `elasticsearch`, `loki`, `victorialogs`, `sls`, `tencent_cls`); the `/monit/query/data` entry stays unchanged. It requires all currently online routable Edge sessions in the cluster to support the v0.71.0 base invoke protocol (individual tools may require a newer implementation), and there is no tool catalog, no automatic replay, and no fallback to legacy diagnose. The request body limit is 128 KiB, the complete success response limit is 10 MiB, and the tool timeout is at most 25 seconds; the response is a `DatasourceToolResult` (`data` is tool-specific JSON, never null, `summary` is optional, and a `truncated` object with `reason` indicates truncation).
To call a `<type>.query` tool, build the request with `NewDatasourceQueryInvokeRequest(datasourceID, tool, params)` and pass the matching typed struct for that tool: `PrometheusQueryParams`, `MySQLQueryParams`, `PostgresQueryParams`, `OracleQueryParams`, `ClickHouseQueryParams`, `ElasticsearchQueryParams`, `LokiQueryParams`, `VictoriaLogsQueryParams`, `SLSQueryParams`, or `TencentCLSQueryParams`. All of them pair `expr` with an `execution` (`DatasourceQueryExecution`: `kind` is `instant`, `range`, or `window`, and `from_ms` / `to_ms` are Unix-millisecond `*int64` values; `range` additionally requires `max_data_points` and accepts `min_step_seconds` to raise the computed step). Optional fields are pointers — a nil pointer omits the key and lets the server apply its default. Query-tool `params` may not be empty: `NewDatasourceQueryInvokeRequest(..., nil)` returns an error, unlike the general "omitted means `{}`" rule. The execution mode is constrained by datasource type: Prometheus and Loki use `instant` or `range` (`instant` carries only `to_ms`); the SQL types (MySQL, Postgres, Oracle, ClickHouse, and the SQL-flavored Elasticsearch) plus SLS and Tencent CLS use `window`; VictoriaLogs uses `window` for raw logs and `instant` / `range` for stats queries. `limit` and `direction` on Loki, VictoriaLogs, SLS, and Tencent CLS bound raw-log retrieval only, and `SLSQueryParams` also requires `project` / `logstore` while `TencentCLSQueryParams` requires `region` / `topic_id` / `syntax`.
@@ -223,20 +233,18 @@ if err != nil {
out, _, err := client.DataSources.ToolsInvoke(ctx, req)
```
+### Prometheus label values
+
`client.DataSources.ReadPrometheusLabelValues(ctx, dataSourceID, labelName)` (`GET /monit/prometheus/api/v1/label/{label_name}/values`, `monit-prometheus-read-label-values`) lists every value of one label on a Prometheus-compatible data source through the monitoring proxy: the label name goes in the URL path (the SDK escapes it), and the target data source is selected by the `X-DSID` request header — the SDK sets it from the `dataSourceID` argument (a `0` ID or an empty `labelName` errors immediately), with the ID taken from `/monit/datasource/list` and required to be a Prometheus-compatible data source of the current account. It is the only method whose success body is not the Flashduty `{request_id, data}` envelope: the response decodes straight into `PrometheusLabelValuesResponse` (`data` carries the label-value strings when `status` is `success`; `errorType` and `error` are present when it is `error`). Failures before the data source is reached (`X-DSID` missing or invalid, data source absent, or not a Prometheus type) come back as `text/plain`, while the data source's own failures use its own JSON error shape; the SDK treats both alike and carries the raw body as-is on `*ErrorResponse.Message`. Supported deployments require monit-edge v0.35.0 or later.
+### Data source configuration
+
For `client.DataSources`, the `payload` selects a type-specific configuration block by `type_ident`. Fifteen `type_ident` values are allowed: `prometheus`, `loki`, `mysql`, `oracle`, `postgres`, `clickhouse`, `elasticsearch`, `sls`, `tencent_cls`, `victorialogs`, plus the new diagnostic-only types `redis_node`, `redis_sentinel`, `mongodb_mongod`, `mongodb_mongos`, and `kafka` — diagnostic-only types always have `alerting_enabled` false (which does not block non-alerting queries or tools) and reject true. Connection address rules: Redis/MongoDB diagnostic types take a single `host:port` (bracket IPv6), with no URI, userinfo, or query; `kafka` takes 1–32 unique comma-separated `host:port` bootstrap addresses (at most 4096 characters after normalization, and the payload has no broker list); for `mongodb_mongod` / `mongodb_mongos` the configuration block's `auth_source` defaults to `admin`, username and password must be configured together, and client certificates are unsupported; the Redis node configuration's `database` defaults to 0. Sensitive fields such as the diagnostic types' `password` and Kafka's `tls_key` support `${env:NAME}` references: literal values are omitted from responses (only `${env:...}` references are echoed back), omitting the fields on update preserves the stored values, and explicitly sending an empty string clears them.
`enabled` and `alerting_enabled` are independent: `enabled` (whether business execution is enabled) defaults to true on create; `alerting_enabled` (whether alert evaluation is allowed; alerting also requires `enabled` true and an alerting-capable type) defaults to true for alerting types and false for diagnostic-only types on create. On update, omitting either preserves the current value and an explicit `null` is invalid; disabling (`enabled` false) is rejected with a conflict when enabled rules reference the datasource. Also note that `payload` is always `null` in `/monit/datasource/list` responses (the list query does not read the payload column); it is populated in create/update/info responses.
-<Note>
-All identifiers, service field names, and method names match the generated code. For exactly which methods each service has and their request and response types, rely on `services_gen.go` and the per-service files, plus the [Open API reference](/en/openapi/introduction).
-</Note>
-
## Response timestamps
----
-
Time fields in responses are no longer bare integers but self-describing `Timestamp` (Unix seconds) or `TimestampMilli` (milliseconds) types (types shared by requests and responses are the exception — see the warning below). They serialize to RFC3339 strings in the local time zone, so JSON, logs, and LLM-facing output are directly readable; the raw epoch is still one method call away.
- **Serialization (outbound)**: a non-zero value serializes to a quoted RFC3339 string (`TimestampMilli` uses RFC3339Nano to preserve millisecond precision). A zero value serializes to the bare integer `0` — an "unset" sentinel rather than a 1970 date, and dropped by `json:",omitempty"`.
@@ -277,8 +285,6 @@ zero := inc.StartTime.IsZero() // whether it's the unset sentinel
## Pagination
----
-
All list endpoints share `ListOptions`, which you embed in the request struct. Zero values are omitted and never override server defaults (the backend defaults to `p=1`, `limit=20`).
| Field | Type | Wire field | Description |
@@ -315,11 +321,9 @@ for page := 0; page < 100; page++ {
## Error handling
----
-
An unsuccessful call returned by the Flashduty API — whether the envelope carries an error or the HTTP status is non-2xx — returns `*ErrorResponse`. It has `Code`, `Message`, an optional `Reason`, and `RequestID` fields; when troubleshooting, give `RequestID` to the support team to pinpoint the request. `Reason` carries the server-supplied optional cause (the envelope's `DutyError` has the same field, JSON `reason`,omitempty); when non-empty it is also appended to the end of the error string, as `, reason X`.
-When the API returns 429, the error is promoted to `*RateLimitError`: it embeds `*ErrorResponse` (so `errors.As` for `*ErrorResponse` still matches) and additionally carries a `RetryAfter` hint.
+When the API returns 429, the error is promoted to `*RateLimitError`: it embeds `*ErrorResponse` (so `errors.As` for `*ErrorResponse` still matches) and additionally carries a `RetryAfter` hint. `Code` values match the Open API [error code list](/en/openapi/introduction#error-code-list).
<Note>
For **generated endpoints**, if you receive a non-2xx response with a non-JSON body, the SDK returns a plain `error`, not `*ErrorResponse`. This indicates that a gateway, load balancer, proxy, or other intermediary produced the response, usually because the request exceeded an intermediary timeout. Retry the request or split a long-running batch into smaller batches, and do not assume that `errors.As(err, &apiErr)` matches this error.
@@ -366,8 +370,6 @@ case flashduty.ErrorCodeAccessDenied, flashduty.ErrorCodeUnauthorized:
## Retry
----
-
The core client has **no** built-in automatic retry. Compose the optional `retry` subpackage through the transport layer — a safe-by-default retrying `http.RoundTripper`.
Features of `github.com/flashcatcloud/go-flashduty/retry`:
@@ -400,8 +402,6 @@ The `retry` subpackage is pure `net/http` and deliberately does not import the p
## Streaming export
----
-
`client.Sessions.Export` exports the full event transcript of an AI SRE session, returning an `io.ReadCloser` (an NDJSON stream, `application/x-ndjson`) rather than a JSON envelope. The first line is always a `session_meta` envelope, and each subsequent line is a session event; when `req.IncludeSubagents` is true, each `subagent_dispatch` line is followed by the subagent's own full event stream.
Because the response body can be large, read it line by line and write directly to a file — do **not** buffer the whole transcript into memory. The returned `io.ReadCloser` is the live HTTP response body, held by the caller and which you **must** `Close` (a `defer` close is correct). Pair it with `NewExportScanner` to scan line by line and `DecodeExportLine` to decode a line into an `ExportLine`:
diff --git a/en/developer/mcp-server.mdx b/en/developer/mcp-server.mdx
index bff49425..2b610d11 100644
--- a/en/developer/mcp-server.mdx
+++ b/en/developer/mcp-server.mdx
@@ -1,6 +1,6 @@
---
title: MCP Server
-sidebarTitle: MCP Server
+sidebarTitle: "Flashduty MCP Server"
description: "Connect the Flashduty API to AI tools via the MCP protocol for intelligent incident management and automation in clients like Cursor and Claude."
keywords: ["MCP", "Model Context Protocol", "AI", "Claude", "Cursor", "Flashduty", "incident management"]
---
@@ -13,8 +13,6 @@ Flashduty MCP Server is a [Model Context Protocol (MCP)](https://modelcontextpro
## Use cases
----
-
<CardGroup cols={2}>
<Card title="Automate incident workflows" icon="robot">
Hand incident creation, acknowledgment, and closure in Flashduty over to AI orchestration, wired into your operations workflow.
@@ -32,8 +30,6 @@ Flashduty MCP Server is a [Model Context Protocol (MCP)](https://modelcontextpro
## Deployment
----
-
Flashduty MCP Server offers three deployment modes; choose based on your MCP client's capabilities and your runtime environment.
<Tabs>
@@ -131,8 +127,6 @@ Flashduty MCP Server offers three deployment modes; choose based on your MCP cli
## Authentication and transport
----
-
| Item | Description |
| --- | --- |
| Auth (local) | Provide the Flashduty APP Key via the `FLASHDUTY_APP_KEY` environment variable or the `--app-key` command-line flag. |
@@ -161,8 +155,6 @@ In each metadata response, `resource` is the request origin plus the matching pa
## Configuration
----
-
Flashduty MCP Server supports toolset trimming, read-only mode, output format, and other settings to suit different scenarios. Local deployments are configured via environment variables or command-line flags; the remote service is configured dynamically by appending query parameters to the URL.
### Environment variables
@@ -241,8 +233,6 @@ The server supports outputting tool results in [TOON (Token-Oriented Object Nota
## Toolsets and tools
----
-
The server provides **8 toolsets and 23 tools** in total, all enabled by default. The table below summarizes each toolset:
| Toolset | Tools | Description |
@@ -366,8 +356,6 @@ The tools in each toolset are as follows:
## Related resources
----
-
<CardGroup cols={2}>
<Card title="go-flashduty SDK" icon="code" href="/en/developer/go-sdk">
The Go SDK that MCP Server depends on, covering the entire Flashduty Open API.
diff --git a/en/home.mdx b/en/home.mdx
index d4924b36..7205aa76 100644
--- a/en/home.mdx
+++ b/en/home.mdx
@@ -1,201 +1,124 @@
---
title: Flashduty
-description: A unified observability platform covering On-call alert management, RUM user experience monitoring, and Monitors unified monitoring
+description: Official Flashduty documentation covering AI SRE autonomous troubleshooting, On-call alert response, RUM user experience monitoring, and the Monitors alert engine
sidebarTitle: Overview
---
-<video
- controls
- autoPlay
- muted
- playsInline
- preload="metadata"
- className="w-full aspect-video rounded-xl"
- src="https://static.flashcat.cloud/flashduty-docs/videos/film-en-5d6bdc8d.mp4"
- poster="https://static.flashcat.cloud/videos/flashduty/flashduty-film-v9-en.jpg"
- aria-label="Flashduty product overview video"
-></video>
+Flashduty is a unified observability platform for DevOps, SRE, and operations teams, covering everything from monitoring and alerting to incident response. Pick a task below to get started, or search the docs from the top bar (Ctrl K).
-## Product Suite
+## Start here
-Flashduty is a unified observability platform designed for DevOps, SRE, and operations teams, providing end-to-end solutions from monitoring and alerting to incident response.
-
-<CardGroup cols={2}>
- <Card title="AI SRE" icon="robot" href="./ai-sre">
- Autonomous troubleshooting Agent
+<CardGroup cols={3}>
+ <Card title="Connect your first alert" icon="bell" href="/en/on-call/quickstart/quickstart">
+ Go from alert ingestion to a phone notification end to end
</Card>
- <Card title="On-call" icon="bell" href="./on-call/quickstart/quickstart">
- Accelerate alert response
+ <Card title="Set up schedules and escalation" icon="calendar" href="/en/on-call/configuration/schedule">
+ Create on-call schedules, then route incidents to the on-call person with escalation rules
</Card>
- <Card title="RUM" icon="chart-line" href="./rum/quickstart/quickstart">
- Real user experience monitoring
+ <Card title="Find an alert integration" icon="plug" href="/en/on-call/integration/alert-integration/overview">
+ Look up the setup guide for your monitoring tool or cloud platform
</Card>
- <Card title="Monitors" icon="desktop" href="./monitors/quickstart/quickstart">
- Unified monitoring platform
+ <Card title="Start AI troubleshooting" icon="robot" href="/en/ai-sre/quickstart">
+ Run your first AI SRE investigation
+ </Card>
+ <Card title="Integrate the RUM SDK" icon="chart-line" href="/en/rum/quickstart/quickstart">
+ Add real user monitoring to web, mobile, or mini program apps
+ </Card>
+ <Card title="Create an alert rule" icon="desktop" href="/en/monitors/quickstart/quickstart">
+ Deploy monitedge and create your first Monitors alert rule
</Card>
</CardGroup>
----
+## Products
-## AI SRE Autonomous Troubleshooting
+### AI SRE: autonomous troubleshooting agent
-A conversational, autonomous SRE Agent: issue instructions in natural language, and the AI investigates incidents, finds root causes, calls tools, and accumulates reusable operational knowledge. Integrated deeply with Flashduty incident response and IM collaboration.
+Issue instructions in natural language, and the AI investigates incidents, finds root causes, calls tools, and accumulates reusable operational knowledge. It works with Flashduty incident response and IM collaboration.
-<AccordionGroup>
- <Accordion title="Core capabilities" icon="star">
- - **Chat to troubleshoot**: the Agent plans, calls tools, and streams its investigation and conclusion
- - **Integrated with incident response**: spin up a session from an incident or war room with full context
- - **Knowledge that compounds**: DUTY.md-rooted knowledge holds long-lived operational context
- - **Extensible tooling**: Skills, MCP, A2A Agents, and self-hosted Runners
- </Accordion>
+- **Chat to troubleshoot**: the Agent plans, calls tools, and streams its investigation and conclusion
+- **Integrated with incident response**: spin up a session from an incident or war room with full context
+- **Knowledge that compounds**: DUTY.md-rooted knowledge holds long-lived operational context
+- **Extensible tooling**: Skills, MCP, A2A Agents, and self-hosted Runners
- <Accordion title="Use cases" icon="bullseye">
- - Start an investigation from the console or an IM group, visible to the whole team
- - Automatic initial diagnosis posted back to the incident war room
- - Use /insight to review the last 30 days and quantify operational friction
- - Build reusable runbooks and troubleshooting flows
- </Accordion>
-</AccordionGroup>
+AI SRE is available to accounts on an On-call Pro or higher subscription and is billed on actual usage. See the [billing terms](/en/compliance/ai-sre-credit-package-purchase-agreement).
-<Note>
-AI SRE is available to accounts on an On-call Pro or higher subscription, with no application needed. Starting September 16, 2026, 08:00 Beijing time, it's billed on actual usage. See the [AI SRE introduction](./ai-sre) and [billing terms](./compliance/ai-sre-credit-package-purchase-agreement).
-</Note>
+[Introduction](/en/ai-sre) · [Product overview](/en/ai-sre/overview) · [Quickstart](/en/ai-sre/quickstart)
-<CardGroup cols={2}>
- <Card title="Product overview" icon="rocket" href="./ai-sre/overview">
- Learn the full capability map and console navigation
- </Card>
- <Card title="Get started" icon="comments" href="./ai-sre/sessions">
- Create a session and start conversational troubleshooting
- </Card>
-</CardGroup>
+### On-call: alert response
----
+Reduce noise, schedule, assign, escalate, and notify so teams can respond to production incidents quickly.
-## On-call Alert Management
-
-A unified intelligent alert response platform: reduce noise, schedule, assign, escalate, and notify to help teams respond to and handle production incidents quickly.
-
-<AccordionGroup>
- <Accordion title="Core Capabilities" icon="star">
- - **Intelligent noise reduction**: Alert grouping, inhibition, and deduplication to reduce 90% of alert noise
- - **Flexible assignment**: Multi-level escalation, dynamic routing, and rotation scheduling
- - **Multi-channel notifications**: Feishu/Lark, Dingtalk, WeCom, Slack, phone calls, SMS
- - **Rich integrations**: Native support for 267 alert sources
- </Accordion>
-
- <Accordion title="Use Cases" icon="bullseye">
- - Build 7x24 on-call systems to ensure service availability
- - Aggregate alerts from multiple sources into a unified incident management portal
- - Establish escalation mechanisms to ensure timely response
- - Analyze alert data to continuously improve monitoring quality
- </Accordion>
-</AccordionGroup>
+- **Noise reduction**: alert grouping, inhibition, and deduplication cut repeated notifications
+- **Flexible assignment**: multi-level escalation, dynamic routing, and rotation scheduling
+- **Multi-channel notifications**: Feishu/Lark, DingTalk, WeCom, Slack, Microsoft Teams, phone calls, SMS, and email
+- **Rich integrations**: 290+ alert integrations covering mainstream monitoring tools and cloud platforms
-<CardGroup cols={2}>
- <Card title="Quick Start" icon="rocket" href="./on-call/quickstart/quickstart">
- Complete your first alert integration in 5 minutes
- </Card>
- <Card title="Product Comparison" icon="scale-balanced" href="./on-call/comparison/vs-pagerduty">
- In-depth comparisons with PagerDuty and Opsgenie
- </Card>
-</CardGroup>
+[Introduction](/en/on-call) · [Getting started](/en/on-call/quickstart/quickstart) · [Compare with PagerDuty / Opsgenie](/en/on-call/comparison/vs-pagerduty)
----
+### RUM: real user monitoring
-## RUM User Experience Monitoring
-
-Real User Monitoring helps you understand how real users experience your application and quickly identify and resolve frontend issues.
-
-<AccordionGroup>
- <Accordion title="Core Capabilities" icon="star">
- - **Performance monitoring**: Full-chain tracking of page loads, resource loads, and API calls
- - **Error tracking**: Automatic collection and grouping of JS errors and network errors
- - **Session replay**: Reproduce user operation paths to quickly replicate issues
- - **Custom metrics**: Report business-specific metrics to meet personalized needs
- </Accordion>
-
- <Accordion title="Use Cases" icon="bullseye">
- - Monitor core web vitals (LCP, FID, CLS) for web applications
- - Track and analyze frontend errors to improve application stability
- - Analyze user behavior paths to optimize product experience
- - Correlate with backend traces for full-stack observability
- </Accordion>
-</AccordionGroup>
+Understand how real users experience your application and quickly find and fix frontend issues.
-<CardGroup cols={2}>
- <Card title="Quick Start" icon="rocket" href="./rum/quickstart/quickstart">
- Integrate SDK to start monitoring
- </Card>
- <Card title="Performance Analysis" icon="gauge-high" href="./rum/performance/overview">
- Learn about performance metrics and analysis methods
- </Card>
-</CardGroup>
+- **Performance monitoring**: full-chain tracking of page loads, resource loads, and API calls
+- **Error tracking**: automatic collection and grouping of JS errors and network errors
+- **Session replay**: reproduce user paths to replicate issues quickly
+- **Custom metrics**: report business-specific metrics
----
+[Introduction](/en/rum) · [Getting started](/en/rum/quickstart/quickstart) · [Performance monitoring](/en/rum/performance/overview)
-## Monitors Management
+### Monitors: alert engine
Onboard data sources scattered across network zones and manage alert rules centrally; rules are evaluated locally by the alert engine deployed next to your data, and the events they produce flow into On-call.
-<AccordionGroup>
- <Accordion title="Core Capabilities" icon="star">
- - **Multiple data source types**: Prometheus, VictoriaLogs, Loki, Elasticsearch, SLS, and Tencent Cloud CLS for metrics and logs, plus MySQL, PostgreSQL, Oracle, ClickHouse, Redis, Kafka, and MongoDB for databases and middleware
- - **Local evaluation next to your data**: `monitedge` runs inside your private network, syncs rules from SaaS and queries data sources locally, so data never leaves your network; engine instances in the same cluster shard the rules automatically
- - **Three evaluation modes**: threshold, no-data, and any-data, with consecutive or cumulative hit counting and per-level recovery semantics
- - **Unified management views**: manage rules in a folder tree, with overview, active alerts, Query Workbench, Entity Tree and dashboards, plus rule import/export and change audit
- </Accordion>
-
- <Accordion title="Use Cases" icon="bullseye">
- - Monitoring is spread across multiple clouds and data centers, and you want to onboard sources and manage alert rules in one place
- - Data sources live in a private network without public access, and alert evaluation should stay local
- - Manage Prometheus, log, database, and middleware alerting under one workflow
- - Let rule-generated alerts flow straight into Flashduty grouping, escalation, and routing
- </Accordion>
-</AccordionGroup>
+- **Multiple data source types**: Prometheus, VictoriaLogs, Loki, Elasticsearch, SLS, and Tencent Cloud CLS for metrics and logs, plus MySQL, PostgreSQL, Oracle, ClickHouse, Redis, Kafka, and MongoDB for databases and middleware
+- **Local evaluation next to your data**: `monitedge` runs inside your private network, syncs rules from SaaS and queries data sources locally, so data never leaves your network; engine instances in the same cluster shard the rules automatically
+- **Three evaluation modes**: threshold, no-data, and any-data, with consecutive or cumulative hit counting and per-level recovery semantics
+- **Unified management views**: manage rules in a folder tree, with overview, active alerts, Query Workbench, Entity Tree and dashboards, plus rule import/export and change audit
-<CardGroup cols={2}>
- <Card title="Quick Start" icon="rocket" href="./monitors/quickstart/quickstart">
- Create your first monitoring task
- </Card>
- <Card title="FAQ" icon="circle-question" href="./monitors/faq/faq">
- Answers to common questions
- </Card>
-</CardGroup>
+[Introduction](/en/monitors) · [Getting started](/en/monitors/quickstart/quickstart) · [FAQ](/en/monitors/faq/faq)
----
+## Product video
+
+<video
+ controls
+ muted
+ playsInline
+ preload="metadata"
+ className="w-full aspect-video rounded-xl"
+ src="https://static.flashcat.cloud/flashduty-docs/videos/film-en-5d6bdc8d.mp4"
+ poster="https://static.flashcat.cloud/videos/flashduty/flashduty-film-v9-en.jpg"
+ aria-label="Flashduty product overview video"
+></video>
## Developers
-Integrate Flashduty through Open API and Webhooks for automation and custom development.
+Integrate Flashduty through the Open API, CLI, SDKs, and Webhooks for automation and custom development.
<CardGroup cols={3}>
- <Card title="Quick Start" icon="rocket" href="/en/openapi/introduction">
+ <Card title="Open API quick start" icon="rocket" href="/en/openapi/introduction">
Authentication, request specs, error handling
</Card>
- <Card title="API Catalog" icon="list" href="/en/openapi/api-catalog">
- All 354 endpoints organized by module
+ <Card title="API catalog" icon="list" href="/en/openapi/api-catalog">
+ All endpoints, organized by module
</Card>
- <Card title="About Pagination" icon="file-lines" href="/en/openapi/pagination">
- Traditional and cursor pagination
+ <Card title="Developer tools" icon="code" href="/en/developer/overview">
+ CLI, Go SDK, MCP Server, and Terraform Provider
</Card>
</CardGroup>
----
-
-## Contact Us
+## Contact us
<CardGroup cols={2}>
<Card title="Technical Support" icon="headset">
Scan to add our WeCom for one-on-one technical support
- <img src="https://docs-cdn.flashcat.cloud/images/png/447591.png" alt="Technical Support WeCom" width="100" />
+ <img src="https://docs-cdn.flashcat.cloud/images/png/447591.png" alt="Technical support WeCom QR code" width="100" />
</Card>
<Card title="Business Inquiries" icon="handshake">
Scan to add our business manager on WeCom
- <img src="https://docs-cdn.flashcat.cloud/images/png/447590.png" alt="Business Manager WeCom" width="100" />
+ <img src="https://docs-cdn.flashcat.cloud/images/png/447590.png" alt="Business manager WeCom QR code" width="100" />
</Card>
<Card title="Console Feedback" icon="comment" href="https://console.flashcat.cloud">
- Sign in to the console and submit feedback in the bottom left corner
+ Sign in to the console and submit feedback from the bottom left corner
</Card>
<Card title="Email" icon="envelope" href="mailto:support@flashcat.cloud">
support@flashcat.cloud
diff --git a/en/monitors.mdx b/en/monitors.mdx
index 215d53d9..52bbe77c 100644
--- a/en/monitors.mdx
+++ b/en/monitors.mdx
@@ -98,6 +98,13 @@ Monitors supports cluster deployment to ensure high availability of the alert en
</Card>
</CardGroup>
+## Use Cases
+
+- Monitoring is spread across multiple clouds and data centers, and you want to onboard sources and manage alert rules in one place
+- Data sources live in a private network without public access, and alert evaluation should stay local
+- Manage Prometheus, log, database, and middleware alerting under one workflow
+- Let rule-generated alerts flow straight into Flashduty grouping, escalation, and routing
+
## Quick Start
<CardGroup cols={2}>
diff --git a/en/monitors/alert-rules/clickhouse.mdx b/en/monitors/alert-rules/clickhouse.mdx
index 80ca7071..02896f47 100644
--- a/en/monitors/alert-rules/clickhouse.mdx
+++ b/en/monitors/alert-rules/clickhouse.mdx
@@ -13,29 +13,29 @@ Monitors supports using standard SQL syntax to query ClickHouse and trigger aler
| **Field Processing** | All field names are automatically converted to lowercase; please use lowercase letters when configuring |
| **Type Conversion** | Recommended to use `toString()`, `toFloat64()` and other functions to convert complex types |
-## 1. Threshold Evaluation Mode
+## Threshold Evaluation Mode
This mode is suitable for scenarios requiring threshold comparison on aggregated values.
### Configuration
1. **Query Statement**: Write SQL aggregate query, returning value columns and (optional) label columns.
- - Example: Count error log quantity by service in the last 5 minutes.
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE timestamp > now() - INTERVAL 5 MINUTE AND level = 'error'
- GROUP BY service_name
- ```
+ - Example: Count error log quantity by service in the last 5 minutes.
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE timestamp > now() - INTERVAL 5 MINUTE AND level = 'error'
+ GROUP BY service_name
+ ```
2. **Field Mapping**:
- - **Value fields**: Select `error_cnt` for threshold evaluation.
- - **Label fields**: Select `service_name` to identify the alert object. After you select label fields, other non-value fields are carried with the alert as additional information.
- - See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for the complete behavior.
+ - **Value fields**: Select `error_cnt` for threshold evaluation.
+ - **Label fields**: Select `service_name` to identify the alert object. After you select label fields, other non-value fields are carried with the alert as additional information.
+ - See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for the complete behavior.
3. **Threshold Conditions**:
- - Use `$A.field_name` to reference values.
- - Example: `Critical: $A.error_cnt > 50`, `Warning: $A.error_cnt > 10`.
+ - Use `$A.field_name` to reference values.
+ - Example: `Critical: $A.error_cnt > 50`, `Warning: $A.error_cnt > 10`.
### How It Works
@@ -50,23 +50,23 @@ Monitors distinguishes alert objects by their label fields and evaluates thresho
| **Recovery Query** | Independent SQL for recovery evaluation, supports `${label_name}` variables |
| **Manual Close** | Keep the alert active until it is closed manually |
-## 2. Data Exists Mode
+## Data Exists Mode
This mode is suitable for scenarios where filter logic is written directly in SQL.
### Configuration
1. **Query Statement**: Use `HAVING` clause in SQL to directly filter out anomalous data.
- - Example: Directly query services with error count exceeding 50.
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE timestamp > now() - INTERVAL 5 MINUTE AND level = 'error'
- GROUP BY service_name
- HAVING count(*) > 50
- ```
+ - Example: Directly query services with error count exceeding 50.
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE timestamp > now() - INTERVAL 5 MINUTE AND level = 'error'
+ GROUP BY service_name
+ HAVING count(*) > 50
+ ```
2. **Evaluation Rules**: As long as SQL query returns data, triggers alert.
### Pros and Cons Analysis
@@ -82,20 +82,20 @@ This mode is suitable for scenarios where filter logic is written directly in SQ
- **Recovery Query**: Supports configuring additional query statements to assist in determining recovery status
- **Manual Close**: Keep the alert active until it is closed manually
-## 3. No Data Mode
+## No Data Mode
This mode is used to monitor scenarios where "data is expected but actually missing".
### Configuration
1. **Query Statement**: Write a SQL query that is expected to continuously return data.
- - Example: Query heartbeat reports from all probes.
- ```sql
- SELECT probe_id, max(timestamp) as last_seen
- FROM probe_heartbeat
- WHERE timestamp > now() - INTERVAL 5 MINUTE
- GROUP BY probe_id
- ```
+ - Example: Query heartbeat reports from all probes.
+ ```sql
+ SELECT probe_id, max(timestamp) as last_seen
+ FROM probe_heartbeat
+ WHERE timestamp > now() - INTERVAL 5 MINUTE
+ GROUP BY probe_id
+ ```
2. **Evaluation Rules**: If a `probe_id` appeared in previous cycles but cannot be found in current and N consecutive cycles, triggers "No Data" alert.
### Recovery Logic
@@ -108,7 +108,7 @@ A no-data alert's **recovery mode** is configured inside the "Alert if previousl
| **End when data reappears or the timeout expires** | The alert ends when the data reappears or the automatic close timeout is reached. The timeout is in seconds with a minimum of 1. Available only when the "Alert if previously found data is now missing" mode is enabled |
| **Manual close only** | The alert stays active until you close it manually |
-## 4. Best Practices
+## Best Practices
<AccordionGroup>
<Accordion title="Type Conversion">
diff --git a/en/monitors/alert-rules/elasticsearch.mdx b/en/monitors/alert-rules/elasticsearch.mdx
index 520e57ba..1260227b 100644
--- a/en/monitors/alert-rules/elasticsearch.mdx
+++ b/en/monitors/alert-rules/elasticsearch.mdx
@@ -20,28 +20,28 @@ Due to SQL feature dependency, only **ElasticSearch 6.3** and above versions are
Use explicit, stable column aliases in SQL and match their casing exactly in field mappings. This prevents mappings from breaking when query fields change.
</Tip>
-## 1. Threshold Evaluation Mode
+## Threshold Evaluation Mode
This mode is suitable for scenarios requiring threshold comparison on aggregated values, such as monitoring "error log count in the last 5 minutes".
### Configuration
1. **Query Statement**: Write SQL aggregate query, returning value columns and (optional) grouping columns.
- - Example: Count error log quantity by service in the last 5 minutes.
- ```sql
- SELECT service_name, count(*) AS error_cnt
- FROM "app-logs-*"
- WHERE "@timestamp" > now() - INTERVAL 5 MINUTES AND log_level = 'ERROR'
- GROUP BY service_name
- ```
+ - Example: Count error log quantity by service in the last 5 minutes.
+ ```sql
+ SELECT service_name, count(*) AS error_cnt
+ FROM "app-logs-*"
+ WHERE "@timestamp" > now() - INTERVAL 5 MINUTES AND log_level = 'ERROR'
+ GROUP BY service_name
+ ```
2. **Field Mapping**:
- - **Label fields**: Select `service_name` to identify the alert object. After you select label fields, other non-value fields are carried with the alert as additional information.
- - **Value fields**: Select `error_cnt` for threshold evaluation.
- - If Label fields is empty, every returned field except the value fields becomes a label. See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for the complete behavior.
+ - **Label fields**: Select `service_name` to identify the alert object. After you select label fields, other non-value fields are carried with the alert as additional information.
+ - **Value fields**: Select `error_cnt` for threshold evaluation.
+ - If Label fields is empty, every returned field except the value fields becomes a label. See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for the complete behavior.
3. **Threshold Conditions**:
- - Use `$A.field_name` to reference values.
- - Example: `Critical: $A.error_cnt > 50`, `Warning: $A.error_cnt > 10`.
- - Shorthand: If only one value field is configured, you can directly use `$A`, like `$A > 50`.
+ - Use `$A.field_name` to reference values.
+ - Example: `Critical: $A.error_cnt > 50`, `Warning: $A.error_cnt > 10`.
+ - Shorthand: If only one value field is configured, you can directly use `$A`, like `$A > 50`.
### How It Works
@@ -74,24 +74,24 @@ WHERE "@timestamp" > now() - INTERVAL 5 MINUTES
The engine will replace variables with actual values before executing the query. If data is found, recovery is determined.
</Accordion>
-## 2. Data Exists Mode
+## Data Exists Mode
This mode is suitable for scenarios where filter logic is written directly in SQL, or when you only care about "whether data is returned".
### Configuration
1. **Query Statement**: Use `HAVING` clause in SQL to directly filter out anomalous data.
- - Example: Directly query services with error count exceeding 50.
- ```sql
- SELECT service_name, count(*) AS error_cnt
- FROM "app-logs-*"
- WHERE "@timestamp" > now() - INTERVAL 5 MINUTES AND log_level = 'ERROR'
- GROUP BY service_name
- HAVING count(*) > 50
- ```
+ - Example: Directly query services with error count exceeding 50.
+ ```sql
+ SELECT service_name, count(*) AS error_cnt
+ FROM "app-logs-*"
+ WHERE "@timestamp" > now() - INTERVAL 5 MINUTES AND log_level = 'ERROR'
+ GROUP BY service_name
+ HAVING count(*) > 50
+ ```
2. **Field Mapping**:
- - Label fields and value fields are **optional** in this mode. If both are empty, Monitors treats every returned field as a label.
- - To identify alerts with only stable fields and keep other columns as troubleshooting context, explicitly select Label fields. See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields).
+ - Label fields and value fields are **optional** in this mode. If both are empty, Monitors treats every returned field as a label.
+ - To identify alerts with only stable fields and keep other columns as troubleshooting context, explicitly select Label fields. See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields).
### Recovery Logic
@@ -109,24 +109,24 @@ This mode is suitable for scenarios where filter logic is written directly in SQ
| **Pros** | Leverages ES cluster's computing power for filtering, reducing network transmission with better performance |
| **Cons** | Cannot differentiate multi-level alerts (like Info/Warning); SQL can only return data satisfying specific conditions |
-## 3. No Data Mode
+## No Data Mode
This mode is used to monitor scenarios where "data is expected but actually missing", commonly used to monitor log collection pipeline interruption or periodic task non-execution.
### Configuration
1. **Query Statement**: Write a SQL query that is expected to continuously return data.
- - Example: Query log reporting heartbeat from all hosts.
- ```sql
- SELECT host_name
- FROM "heartbeat-logs-*"
- WHERE "@timestamp" > now() - INTERVAL 5 MINUTES
- GROUP BY host_name
- ```
+ - Example: Query log reporting heartbeat from all hosts.
+ ```sql
+ SELECT host_name
+ FROM "heartbeat-logs-*"
+ WHERE "@timestamp" > now() - INTERVAL 5 MINUTES
+ GROUP BY host_name
+ ```
2. **Evaluation Rules**:
- - The engine periodically executes this SQL.
- - If a `host_name` appeared in previous cycles but no longer appears in current cycle (and N consecutive cycles) query results, triggers "No Data" alert.
- - Note: This is opposite to Data Exists mode. Data Exists means "alert when data found", No Data means "alert when data not found".
+ - The engine periodically executes this SQL.
+ - If a `host_name` appeared in previous cycles but no longer appears in current cycle (and N consecutive cycles) query results, triggers "No Data" alert.
+ - Note: This is opposite to Data Exists mode. Data Exists means "alert when data found", No Data means "alert when data not found".
### Recovery Logic
@@ -138,7 +138,7 @@ A no-data alert's **recovery mode** is configured inside the "Alert if previousl
| **End when data reappears or the timeout expires** | The alert ends when the data reappears or the automatic close timeout is reached. The timeout is in seconds with a minimum of 1. Available only when the "Alert if previously found data is now missing" mode is enabled |
| **Manual close only** | The alert stays active until you close it manually |
-## 4. Use Case
+## Use Case
Log alerting often encounters this requirement: count ERROR logs in the last 5 minutes, alert if exceeding threshold, and display the most recent ERROR log as a sample in the alert message. Configuration approach:
diff --git a/en/monitors/alert-rules/loki.mdx b/en/monitors/alert-rules/loki.mdx
index fe8b635f..66ac651e 100644
--- a/en/monitors/alert-rules/loki.mdx
+++ b/en/monitors/alert-rules/loki.mdx
@@ -18,7 +18,7 @@ Loki's query language LogQL is divided into two types:
When writing LogQL, the query input autocompletes label names and label values from the data source, helping you locate log streams quickly.
</Tip>
-## 1. Threshold Evaluation Mode
+## Threshold Evaluation Mode
This mode is suitable for scenarios requiring multi-level threshold evaluation on log aggregate values (e.g., Info/Warning/Critical).
@@ -48,7 +48,7 @@ The engine executes LogQL query and gets time series data with labels (Vector).
| **Recovery Query** | Supports independent LogQL for recovery evaluation |
| **Manual Close** | Keep the alert active until it is closed manually |
-## 2. Data Exists Mode
+## Data Exists Mode
This mode is suitable for users who prefer writing filter conditions directly in LogQL, or scenarios that only care about "whether anomalous data exists". Recommended for log anomaly detection alerts.
@@ -77,7 +77,7 @@ count_over_time({job="ingress"} |= "error-code-500" [5m]) / count_over_time({job
- **Recovery Query**: Supports configuring additional query statements to assist in determining recovery status
- **Manual Close**: Keep the alert active until it is closed manually
-## 3. No Data Mode
+## No Data Mode
This mode is used to monitor whether log reporting pipeline is interrupted, or whether logs that should be continuously generated have stopped.
@@ -108,7 +108,7 @@ A no-data alert's **recovery mode** is configured inside the "Alert if previousl
- Monitor whether Promtail/Fluentd and other collection Agents have stopped working
- Monitor whether critical business logs (like order creation logs) are abnormally interrupted
-## 4. Using a raw log query as the primary query
+## Using a raw log query as the primary query
To alert whenever matching log rows exist, select **Raw log** and use **Data exists** mode. Suppose the query returns `job`, `service`, `__time__`, and `__log__`:
@@ -122,11 +122,11 @@ Do not use frequently changing fields such as `__time__`, `__log__`, or a trace
See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for default behavior, threshold references, and multi-query matching requirements.
-## 5. Getting raw logs through a related query
+## Getting raw logs through a related query
Original logs can be obtained through related queries during alerts. But typically not recommended to get too many; just get 1 as a log sample to include in alert message.
-
+
Related query results can be rendered in "Notes Description", example:
diff --git a/en/monitors/alert-rules/mysql.mdx b/en/monitors/alert-rules/mysql.mdx
index 18a21e43..3d5d9a0e 100644
--- a/en/monitors/alert-rules/mysql.mdx
+++ b/en/monitors/alert-rules/mysql.mdx
@@ -13,29 +13,29 @@ Monitors supports using standard SQL syntax to query MySQL and trigger alerts ba
| **Field Processing** | All field names are automatically converted to lowercase; please use lowercase letters when configuring |
| **Time Processing** | Recommended to use `now()`, `unix_timestamp()` and other functions for time filtering |
-## 1. Threshold Evaluation Mode
+## Threshold Evaluation Mode
This mode is suitable for scenarios requiring threshold comparison on aggregated values.
### Configuration
1. **Query Statement**: Write SQL aggregate query, returning value columns and (optional) label columns.
- - Example: Count error log quantity by service in the last 5 minutes (assuming there's a log table).
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE log_time > now() - INTERVAL 5 MINUTE AND level = 'error'
- GROUP BY service_name
- ```
+ - Example: Count error log quantity by service in the last 5 minutes (assuming there's a log table).
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE log_time > now() - INTERVAL 5 MINUTE AND level = 'error'
+ GROUP BY service_name
+ ```
2. **Field Mapping**:
- - **Value fields**: Select `error_cnt` for threshold evaluation.
- - **Label fields**: Select `service_name` to identify the alert object. After you select label fields, other non-value fields are carried with the alert as additional information.
- - See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for the complete behavior.
+ - **Value fields**: Select `error_cnt` for threshold evaluation.
+ - **Label fields**: Select `service_name` to identify the alert object. After you select label fields, other non-value fields are carried with the alert as additional information.
+ - See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for the complete behavior.
3. **Threshold Conditions**:
- - Use `$A.field_name` to reference values.
- - Example: `Critical: $A.error_cnt > 50`, `Warning: $A.error_cnt > 10`.
+ - Use `$A.field_name` to reference values.
+ - Example: `Critical: $A.error_cnt > 50`, `Warning: $A.error_cnt > 10`.
### How It Works
@@ -50,23 +50,23 @@ Monitors distinguishes alert objects by their label fields and evaluates thresho
| **Recovery Query** | Independent SQL for recovery evaluation, supports `${label_name}` variables |
| **Manual Close** | Keep the alert active until it is closed manually |
-## 2. Data Exists Mode
+## Data Exists Mode
This mode is suitable for scenarios where filter logic is written directly in SQL.
### Configuration
1. **Query Statement**: Use `HAVING` clause in SQL to directly filter out anomalous data.
- - Example: Directly query services with error count exceeding 50.
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE log_time > now() - INTERVAL 5 MINUTE AND level = 'error'
- GROUP BY service_name
- HAVING count(*) > 50
- ```
+ - Example: Directly query services with error count exceeding 50.
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE log_time > now() - INTERVAL 5 MINUTE AND level = 'error'
+ GROUP BY service_name
+ HAVING count(*) > 50
+ ```
2. **Evaluation Rules**: As long as SQL query returns data (Result Set is not empty), triggers alert.
### Pros and Cons Analysis
@@ -82,20 +82,20 @@ This mode is suitable for scenarios where filter logic is written directly in SQ
- **Recovery Query**: Supports configuring additional query statements to assist in determining recovery status
- **Manual Close**: Keep the alert active until it is closed manually
-## 3. No Data Mode
+## No Data Mode
This mode is used to monitor scenarios where "data is expected but actually missing".
### Configuration
1. **Query Statement**: Write a SQL query that is expected to continuously return data.
- - Example: Query heartbeat reports from all probes.
- ```sql
- SELECT probe_id, max(check_time) as last_seen
- FROM probe_heartbeat
- WHERE check_time > now() - INTERVAL 5 MINUTE
- GROUP BY probe_id
- ```
+ - Example: Query heartbeat reports from all probes.
+ ```sql
+ SELECT probe_id, max(check_time) as last_seen
+ FROM probe_heartbeat
+ WHERE check_time > now() - INTERVAL 5 MINUTE
+ GROUP BY probe_id
+ ```
2. **Evaluation Rules**: If a `probe_id` appeared in previous cycles but cannot be found in current and N consecutive cycles, triggers "No Data" alert.
### Recovery Logic
@@ -108,7 +108,7 @@ A no-data alert's **recovery mode** is configured inside the "Alert if previousl
| **End when data reappears or the timeout expires** | The alert ends when the data reappears or the automatic close timeout is reached. The timeout is in seconds with a minimum of 1. Available only when the "Alert if previously found data is now missing" mode is enabled |
| **Manual close only** | The alert stays active until you close it manually |
-## 4. Best Practices
+## Best Practices
<AccordionGroup>
<Accordion title="Index Optimization">
diff --git a/en/monitors/alert-rules/oracle.mdx b/en/monitors/alert-rules/oracle.mdx
index e4405fea..fa6a61b1 100644
--- a/en/monitors/alert-rules/oracle.mdx
+++ b/en/monitors/alert-rules/oracle.mdx
@@ -13,29 +13,29 @@ Monitors supports using standard SQL syntax to query Oracle and trigger alerts b
| **Field Processing** | All field names are automatically converted to lowercase; please use lowercase letters when configuring |
| **Time Processing** | Recommended to use `SYSDATE`, `SYSTIMESTAMP` and other functions for time filtering |
-## 1. Threshold Evaluation Mode
+## Threshold Evaluation Mode
This mode is suitable for scenarios requiring threshold comparison on aggregated values.
### Configuration
1. **Query Statement**: Write SQL aggregate query, returning value columns and (optional) label columns.
- - Example: Count error log quantity by service in the last 5 minutes.
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE log_time > SYSDATE - INTERVAL '5' MINUTE AND level = 'error'
- GROUP BY service_name
- ```
+ - Example: Count error log quantity by service in the last 5 minutes.
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE log_time > SYSDATE - INTERVAL '5' MINUTE AND level = 'error'
+ GROUP BY service_name
+ ```
2. **Field Mapping**:
- - **Value fields**: Select `error_cnt` for threshold evaluation.
- - **Label fields**: Select `service_name` to identify the alert object. After you select label fields, other non-value fields are carried with the alert as additional information.
- - See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for the complete behavior.
+ - **Value fields**: Select `error_cnt` for threshold evaluation.
+ - **Label fields**: Select `service_name` to identify the alert object. After you select label fields, other non-value fields are carried with the alert as additional information.
+ - See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for the complete behavior.
3. **Threshold Conditions**:
- - Use `$A.field_name` to reference values.
- - Example: `Critical: $A.error_cnt > 50`, `Warning: $A.error_cnt > 10`.
+ - Use `$A.field_name` to reference values.
+ - Example: `Critical: $A.error_cnt > 50`, `Warning: $A.error_cnt > 10`.
### How It Works
@@ -50,23 +50,23 @@ Monitors distinguishes alert objects by their label fields and evaluates thresho
| **Recovery Query** | Independent SQL for recovery evaluation, supports `${label_name}` variables |
| **Manual Close** | Keep the alert active until it is closed manually |
-## 2. Data Exists Mode
+## Data Exists Mode
This mode is suitable for scenarios where filter logic is written directly in SQL.
### Configuration
1. **Query Statement**: Use `HAVING` clause in SQL to directly filter out anomalous data.
- - Example: Directly query services with error count exceeding 50.
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE log_time > SYSDATE - INTERVAL '5' MINUTE AND level = 'error'
- GROUP BY service_name
- HAVING count(*) > 50
- ```
+ - Example: Directly query services with error count exceeding 50.
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE log_time > SYSDATE - INTERVAL '5' MINUTE AND level = 'error'
+ GROUP BY service_name
+ HAVING count(*) > 50
+ ```
2. **Evaluation Rules**: As long as SQL query returns data, triggers alert.
### Pros and Cons Analysis
@@ -82,20 +82,20 @@ This mode is suitable for scenarios where filter logic is written directly in SQ
- **Recovery Query**: Supports configuring additional query statements to assist in determining recovery status
- **Manual Close**: Keep the alert active until it is closed manually
-## 3. No Data Mode
+## No Data Mode
This mode is used to monitor scenarios where "data is expected but actually missing".
### Configuration
1. **Query Statement**: Write a SQL query that is expected to continuously return data.
- - Example: Query heartbeat reports from all probes.
- ```sql
- SELECT probe_id, max(check_time) as last_seen
- FROM probe_heartbeat
- WHERE check_time > SYSDATE - INTERVAL '5' MINUTE
- GROUP BY probe_id
- ```
+ - Example: Query heartbeat reports from all probes.
+ ```sql
+ SELECT probe_id, max(check_time) as last_seen
+ FROM probe_heartbeat
+ WHERE check_time > SYSDATE - INTERVAL '5' MINUTE
+ GROUP BY probe_id
+ ```
2. **Evaluation Rules**: If a `probe_id` appeared in previous cycles but cannot be found in current and N consecutive cycles, triggers "No Data" alert.
### Recovery Logic
@@ -108,7 +108,7 @@ A no-data alert's **recovery mode** is configured inside the "Alert if previousl
| **End when data reappears or the timeout expires** | The alert ends when the data reappears or the automatic close timeout is reached. The timeout is in seconds with a minimum of 1. Available only when the "Alert if previously found data is now missing" mode is enabled |
| **Manual close only** | The alert stays active until you close it manually |
-## 4. Best Practices
+## Best Practices
<AccordionGroup>
<Accordion title="Index Optimization">
diff --git a/en/monitors/alert-rules/postgres.mdx b/en/monitors/alert-rules/postgres.mdx
index ecd7b1c5..7a1281ec 100644
--- a/en/monitors/alert-rules/postgres.mdx
+++ b/en/monitors/alert-rules/postgres.mdx
@@ -13,29 +13,29 @@ Monitors supports using standard SQL syntax to query PostgreSQL and trigger aler
| **Field Processing** | All field names are automatically converted to lowercase; please use lowercase letters when configuring |
| **Time Processing** | Recommended to use `NOW()`, `CURRENT_TIMESTAMP` and other functions for time filtering |
-## 1. Threshold Evaluation Mode
+## Threshold Evaluation Mode
This mode is suitable for scenarios requiring threshold comparison on aggregated values.
### Configuration
1. **Query Statement**: Write SQL aggregate query, returning value columns and (optional) label columns.
- - Example: Count error log quantity by service in the last 5 minutes.
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE log_time > NOW() - INTERVAL '5 minutes' AND level = 'error'
- GROUP BY service_name
- ```
+ - Example: Count error log quantity by service in the last 5 minutes.
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE log_time > NOW() - INTERVAL '5 minutes' AND level = 'error'
+ GROUP BY service_name
+ ```
2. **Field Mapping**:
- - **Value fields**: Select `error_cnt` for threshold evaluation.
- - **Label fields**: Select `service_name` to identify the alert object. After you select label fields, other non-value fields are carried with the alert as additional information.
- - See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for the complete behavior.
+ - **Value fields**: Select `error_cnt` for threshold evaluation.
+ - **Label fields**: Select `service_name` to identify the alert object. After you select label fields, other non-value fields are carried with the alert as additional information.
+ - See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for the complete behavior.
3. **Threshold Conditions**:
- - Use `$A.field_name` to reference values.
- - Example: `Critical: $A.error_cnt > 50`, `Warning: $A.error_cnt > 10`.
+ - Use `$A.field_name` to reference values.
+ - Example: `Critical: $A.error_cnt > 50`, `Warning: $A.error_cnt > 10`.
### How It Works
@@ -50,23 +50,23 @@ Monitors distinguishes alert objects by their label fields and evaluates thresho
| **Recovery Query** | Independent SQL for recovery evaluation, supports `${label_name}` variables |
| **Manual Close** | Keep the alert active until it is closed manually |
-## 2. Data Exists Mode
+## Data Exists Mode
This mode is suitable for scenarios where filter logic is written directly in SQL.
### Configuration
1. **Query Statement**: Use `HAVING` clause in SQL to directly filter out anomalous data.
- - Example: Directly query services with error count exceeding 50.
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE log_time > NOW() - INTERVAL '5 minutes' AND level = 'error'
- GROUP BY service_name
- HAVING count(*) > 50
- ```
+ - Example: Directly query services with error count exceeding 50.
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE log_time > NOW() - INTERVAL '5 minutes' AND level = 'error'
+ GROUP BY service_name
+ HAVING count(*) > 50
+ ```
2. **Evaluation Rules**: As long as SQL query returns data, triggers alert.
### Pros and Cons Analysis
@@ -82,20 +82,20 @@ This mode is suitable for scenarios where filter logic is written directly in SQ
- **Recovery Query**: Supports configuring additional query statements to assist in determining recovery status
- **Manual Close**: Keep the alert active until it is closed manually
-## 3. No Data Mode
+## No Data Mode
This mode is used to monitor scenarios where "data is expected but actually missing".
### Configuration
1. **Query Statement**: Write a SQL query that is expected to continuously return data.
- - Example: Query heartbeat reports from all probes.
- ```sql
- SELECT probe_id, max(check_time) as last_seen
- FROM probe_heartbeat
- WHERE check_time > NOW() - INTERVAL '5 minutes'
- GROUP BY probe_id
- ```
+ - Example: Query heartbeat reports from all probes.
+ ```sql
+ SELECT probe_id, max(check_time) as last_seen
+ FROM probe_heartbeat
+ WHERE check_time > NOW() - INTERVAL '5 minutes'
+ GROUP BY probe_id
+ ```
2. **Evaluation Rules**: If a `probe_id` appeared in previous cycles but cannot be found in current and N consecutive cycles, triggers "No Data" alert.
### Recovery Logic
@@ -108,7 +108,7 @@ A no-data alert's **recovery mode** is configured inside the "Alert if previousl
| **End when data reappears or the timeout expires** | The alert ends when the data reappears or the automatic close timeout is reached. The timeout is in seconds with a minimum of 1. Available only when the "Alert if previously found data is now missing" mode is enabled |
| **Manual close only** | The alert stays active until you close it manually |
-## 4. Best Practices
+## Best Practices
<AccordionGroup>
<Accordion title="Index Optimization">
diff --git a/en/monitors/alert-rules/prometheus.mdx b/en/monitors/alert-rules/prometheus.mdx
index b0a773ba..436cfd32 100644
--- a/en/monitors/alert-rules/prometheus.mdx
+++ b/en/monitors/alert-rules/prometheus.mdx
@@ -21,7 +21,7 @@ Used for monitoring data reporting interruption scenarios
</Card>
</CardGroup>
-## 1. Threshold Evaluation Mode
+## Threshold Evaluation Mode
This mode is suitable for scenarios requiring multi-level alerts on the same metric (e.g., Info/Warning/Critical) or needing precise recovery values.
@@ -69,7 +69,7 @@ Supports multiple recovery strategies:
Recovery query statements support embedded variables (format `${label_name}`), which are automatically replaced with corresponding label values from the alert event, enabling precise detection for specific alert objects.
</Note>
-## 2. Data Exists Mode
+## Data Exists Mode
This mode behaves consistently with Prometheus native alerting rules. Suitable for users who prefer defining thresholds directly in PromQL, or scenarios requiring high-performance processing of large numbers of Series.
@@ -101,7 +101,7 @@ This mode behaves consistently with Prometheus native alerting rules. Suitable f
</Tab>
</Tabs>
-## 3. No Data Mode
+## No Data Mode
This mode is specifically for monitoring whether monitored objects are alive or whether data reporting pipelines are normal.
@@ -178,7 +178,7 @@ The validator tries to parse the expression as PromQL first, then as MetricsQL;
- **Length limit**: A single query statement is limited to 64KB; exceeding this limit also prevents saving.
<Note>
-Save-time validation is a conservative syntax-level check only. Passing the check does not guarantee that the backend Prometheus/VictoriaMetrics instance can execute the statement.
+Save-time validation is a conservative syntax-level check only. Passing the check does not guarantee that the data source (the Prometheus/VictoriaMetrics instance) can execute the statement.
</Note>
### Labels and Variables
diff --git a/en/monitors/alert-rules/query-result-fields.mdx b/en/monitors/alert-rules/query-result-fields.mdx
index 75f90150..3cbc489c 100644
--- a/en/monitors/alert-rules/query-result-fields.mdx
+++ b/en/monitors/alert-rules/query-result-fields.mdx
@@ -155,7 +155,7 @@ A data source can impose a stricter limit. For example, raw log queries for SLS,
When a query exceeds its effective limit, it fails with `too many rows`. Monitors does not return a partial result or evaluate alerts with truncated data.
-The query preview table on the rule editor page paginates in the frontend: 100 rows per page by default, with options of 100 / 200 / 500, and the paginator is hidden when the results fit in a single page. This pagination affects display only and is independent of the Edge `--alerter.previewMaxRows` limit — a query that exceeds the Edge limit still fails with `too many rows`.
+The query preview table on the rule editor page is paginated: 100 rows per page by default, with options of 100 / 200 / 500, and the paginator is hidden when the results fit in a single page. This pagination affects display only and is independent of the Edge `--alerter.previewMaxRows` limit — a query that exceeds the Edge limit still fails with `too many rows`.
<Warning>
Increasing the Edge row limit does not disable safeguards for response bytes, field size, or total result values. High-cardinality Prometheus queries and large SQL results can still fail on another resource limit.
diff --git a/en/monitors/alert-rules/sls.mdx b/en/monitors/alert-rules/sls.mdx
index f1a54296..40d119fc 100644
--- a/en/monitors/alert-rules/sls.mdx
+++ b/en/monitors/alert-rules/sls.mdx
@@ -14,29 +14,29 @@ Monitors retrieves data through SLS SQL query interface (GetLogsV3) and triggers
| **Time Range** | Controlled by API parameters; no need to write `WHERE __time__ > ...` in SQL |
| **Field Processing** | `__source__` and `__time__` fields are ignored by default |
-## 1. Threshold Evaluation Mode
+## Threshold Evaluation Mode
This mode is suitable for scenarios requiring threshold comparison on aggregated values.
### Configuration
1. **Query Statement**: Write SLS SQL aggregate query.
- - Example: Count error log quantity by host in the last 15 minutes.
- ```sql
- * | SELECT host, count(*) as error_cnt WHERE level = 'ERROR' GROUP BY host
- ```
+ - Example: Count error log quantity by host in the last 15 minutes.
+ ```sql
+ * | SELECT host, count(*) as error_cnt WHERE level = 'ERROR' GROUP BY host
+ ```
2. **Query Parameters**:
- - `sls.project`: (Required) Project name.
- - `sls.logstore`: (Required) Logstore name.
- - `sls.timespan.value`: (Optional) Time span value, default is 15.
- - `sls.timespan.unit`: (Optional) Time span unit, supports `s` (seconds), `m` (minutes), `h` (hours), `d` (days). Default is `m`.
+ - `sls.project`: (Required) Project name.
+ - `sls.logstore`: (Required) Logstore name.
+ - `sls.timespan.value`: (Optional) Time span value, default is 15.
+ - `sls.timespan.unit`: (Optional) Time span unit, supports `s` (seconds), `m` (minutes), `h` (hours), `d` (days). Default is `m`.
3. **Field Mapping**:
- - **Value fields**: Select `error_cnt` for threshold evaluation.
- - **Label fields**: Select `host` to identify the alert object. After you select label fields, other non-value fields are carried with the alert as additional information.
- - See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for the complete behavior.
+ - **Value fields**: Select `error_cnt` for threshold evaluation.
+ - **Label fields**: Select `host` to identify the alert object. After you select label fields, other non-value fields are carried with the alert as additional information.
+ - See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for the complete behavior.
4. **Threshold Conditions**:
- - Use `$A.field_name` to reference values.
- - Example: `Critical: $A.error_cnt > 50`, `Warning: $A.error_cnt > 10`.
+ - Use `$A.field_name` to reference values.
+ - Example: `Critical: $A.error_cnt > 50`, `Warning: $A.error_cnt > 10`.
### How It Works
@@ -51,17 +51,17 @@ Monitors runs the SLS query for the configured time range, distinguishes alert o
| **Recovery Query** | Independent SQL for recovery evaluation, supports `${label_name}` variables |
| **Manual Close** | Keep the alert active until it is closed manually |
-## 2. Data Exists Mode
+## Data Exists Mode
This mode is suitable for scenarios where filter logic is written directly in SQL.
### Configuration
1. **Query Statement**: Use `HAVING` clause to filter anomalous data.
- - Example: Query hosts with error count exceeding 50.
- ```sql
- * | SELECT host, count(*) as error_cnt WHERE level = 'ERROR' GROUP BY host HAVING error_cnt > 50
- ```
+ - Example: Query hosts with error count exceeding 50.
+ ```sql
+ * | SELECT host, count(*) as error_cnt WHERE level = 'ERROR' GROUP BY host HAVING error_cnt > 50
+ ```
2. **Query Parameters**: Same as above, need to configure `sls.project` and `sls.logstore`.
3. **Evaluation Rules**: As long as query returns data, triggers alert.
@@ -78,39 +78,29 @@ This mode is suitable for scenarios where filter logic is written directly in SQ
- **Recovery Query**: Supports configuring additional query statements
- **Manual Close**: Keep the alert active until it is closed manually
-## 3. No Data Mode
+## No Data Mode
This mode is used to monitor scenarios where "data is expected but actually missing".
-SLS is a cloud log service data source and does not support per-series no-data detection. It keeps only one condition, **Alert when all queries return no data**:
-
-- The UI shows a single condition card, "Alert when all queries return no data", backed by the `alert_on_empty_result` and `alert_on_empty_result_severity` fields.
-- The per-series card, "Alert if previously found data is now missing", is not rendered for SLS rules, so its config field `check_nodata.enabled` cannot be set at all.
-- Tencent Cloud CLS also disables this condition, and enforces it in the backend (submitting `check_nodata.enabled` is rejected with a 400); SLS is currently disabled by the frontend, without a backend guard.
+SLS does not support per-series no-data detection. Only "**Alert when all queries return no data**" is available; "Alert if previously found data is now missing" is not supported.
### Configuration
1. **Query Statement**: Write a query that is expected to continuously return data.
- - Example: Query log reporting heartbeat from all hosts.
- ```sql
- * | SELECT host, max(__time__) as last_seen GROUP BY host
- ```
+ - Example: Query log reporting heartbeat from all hosts.
+ ```sql
+ * | SELECT host, max(__time__) as last_seen GROUP BY host
+ ```
2. **Evaluation Rules**: The alert fires when all queries return empty results for N consecutive checks. N comes from the **Trigger condition** shared by the tab.
### Existing Rules with Per-Series Detection Enabled
-For an existing SLS rule that has per-series no-data detection enabled, opening its edit page turns that condition off automatically (`check_nodata.enabled` is loaded as off) and shows a toast:
-
-<Warning>
-This datasource type does not support "Alert if previously found data is now missing"; the check has been turned off automatically and takes effect on save
-</Warning>
-
-The rule detail page is read-only and does not show this toast. The condition is turned off inside the edit page: as long as you do not open the edit page, the rule's config does not change; once you open it and save, the off state is written back to the rule. The automatic turn-off applies to this condition only, so at save time:
+If an existing SLS rule has per-series no-data detection enabled, opening its edit page turns that condition off automatically; the change takes effect when you save. The rule does not change unless you open the edit page.
-- If the rule still has other enabled conditions (threshold evaluation, data exists), the "at least one must be enabled" validation does not block this downgrade, and per-series detection stops working with that save — which is exactly why the toast above is shown.
-- If this was the rule's only condition, the save is blocked by the "Threshold evaluation, Data missing, Data exists at least one must be enabled" validation, and you must change the configuration explicitly before it can be saved.
+- If the rule has other enabled conditions (threshold evaluation, data exists), you can save directly.
+- If this was its only condition, enable at least one condition before saving.
-After opening such a rule, switch its no-data detection to "Alert when all queries return no data", make sure at least one alert condition is enabled, and then save.
+Switch to "Alert when all queries return no data" and make sure at least one condition is enabled before saving.
### Recovery Logic
@@ -122,7 +112,7 @@ The **recovery mode** of "Alert when all queries return no data" is not configur
The former recovery-mode dropdown (`End automatically when data reappears` / `End when data reappears or the timeout expires` / `Manual close only`) exists only inside the per-series card, so it is unavailable for SLS. The only configurable items shared by the conditions on the no-data tab are the trigger and recovery settings (`Trigger mode`, `Trigger condition`, `Recovery condition`).
-## 4. Advanced Configuration
+## Advanced Configuration
<AccordionGroup>
<Accordion title="Power SQL">
diff --git a/en/monitors/alert-rules/tencent-cls.mdx b/en/monitors/alert-rules/tencent-cls.mdx
index 5dcd5503..e05dba4c 100644
--- a/en/monitors/alert-rules/tencent-cls.mdx
+++ b/en/monitors/alert-rules/tencent-cls.mdx
@@ -10,7 +10,7 @@ Monitors retrieves data through the Tencent Cloud Log Service (CLS) search and a
| Config Item | Description |
|--------|------|
| **Query Resource** | Each query must specify `tencent_cls.region` (region) and `tencent_cls.topic_id` (log topic); logsets are used only for filtering in the UI and are neither saved nor executed |
-| **Query Mode** | `raw` log search returns log lines; `analysis` SQL analysis returns aggregated rows. The backend executes exactly what is stored and never infers it from the expression |
+| **Query Mode** | `raw` log search returns log lines; `analysis` SQL analysis returns aggregated rows. The rule runs in the selected mode; it is never inferred from the query |
| **Search Syntax** | Raw log search uses the syntax set by `tencent_cls.syntax`: `CQL` or `Lucene` |
| **Time Range** | Controlled by parameters; no need to write time filters in the query statement |
| **Execution Identifier** | Only the log topic ID is used at execution time; the topic name is for display only |
@@ -50,7 +50,7 @@ Searches logs with CQL or Lucene syntax and returns matching log lines. Each ret
Aggregates logs with SQL and returns aggregated rows, suitable for threshold and data-exists evaluation.
- The time window is capped at **24 hours**.
-- `tencent_cls.limit` is not allowed; including it is rejected by the backend.
+- `tencent_cls.limit` is not allowed; including it is rejected.
## Time Range
@@ -60,23 +60,22 @@ The default query window is the last 15 minutes (`tencent_cls.timespan.value=15`
### Single Data Source Binding
-Tencent CLS rules can bind exactly **one data source** and do not support name patterns. When creating a rule, the data source picker is single-select and the name-pattern input is hidden. An invalid configuration is rejected on save with "This data source type can bind only one data source" or "This data source type does not support name patterns. Clear them and pick one data source."
+Tencent CLS rules can bind exactly **one data source** and do not support name patterns.
### Topic Index Requirement
-A log topic must have indexing enabled for search and SQL analysis to return results. Topics without indexing are tagged "Index not enabled" in the topic list; after you select such a topic, the editor warns: "This topic has no index configured, so neither search nor SQL analysis will return results. Configure an index in the Tencent Cloud console first." Queries against such topics keep returning empty results.
+A log topic must have indexing enabled, otherwise search and SQL analysis return no results. Topics without indexing are marked in the topic list; configure an index in the Tencent Cloud console first.
### Topic ID Execution
-The topic picker supports searching by name or pasting a topic ID directly. Only the topic ID is saved into the rule and used at execution time; the logset filter is display-only and never saved. When editing an existing rule whose topic has been deleted, the UI reports "Topic does not exist or has been deleted" and you need to pick a topic again.
+You can search topics by name or paste a topic ID. Rules save and run against the topic ID only (the logset filter is just for finding topics and is not saved). If the topic has been deleted, pick a topic again when editing the rule.
## No Data Detection
Tencent CLS does not support per-series no-data detection:
-- Only one condition card is supported: "**Alert when all queries return no data**".
-- The "Alert if previously found data is now missing" option is not available — enabling it submits `check_nodata.enabled`, which the backend rejects with a 400 — so the card does not appear in the UI.
-- The **recovery mode** is not configurable: there are no options, and the engine fixes it to "Recovers automatically once any query returns data again", shown as read-only text in the UI. "Manual close only" does not exist here — the recovery-mode dropdown (`End automatically when data reappears` / `End when data reappears or the timeout expires` / `Manual close only`) is rendered only inside the per-series card, which never appears for CLS rules, so none of the three is selectable.
+- Only "**Alert when all queries return no data**" is available; "Alert if previously found data is now missing" is not supported (not even through the API).
+- Recovery is fixed to **recovering automatically once any query returns data again**; it cannot be configured, and manual-close-only is not available.
## Recovery Queries and Related Queries
diff --git a/en/monitors/alert-rules/victorialogs.mdx b/en/monitors/alert-rules/victorialogs.mdx
index f6858533..e17784ef 100644
--- a/en/monitors/alert-rules/victorialogs.mdx
+++ b/en/monitors/alert-rules/victorialogs.mdx
@@ -5,7 +5,7 @@ description: "Configure alert rules for VictoriaLogs data sources"
Monitors queries VictoriaLogs via HTTP, supporting querying raw logs and statistical analysis, and performing threshold evaluation and data exists/missing checks based on results.
-## 1. Prerequisites
+## Prerequisites
### Query Modes
@@ -39,7 +39,7 @@ Query statement must include `_time` filter condition (like `_time:5m`), otherwi
VictoriaLogs data source most recommends using "Data Exists Mode", best suited for log scenarios.
</Tip>
-## 2. Threshold Evaluation Mode
+## Threshold Evaluation Mode
Both **Query Raw** and **Do Stats** query modes can be used. Examples below explain each.
@@ -89,7 +89,7 @@ Different threshold different level configuration examples:
| **Recovery Query** | Independent query for recovery evaluation, supports `${label_name}` variables |
| **Manual Close** | Keep the alert active until it is closed manually |
-## 3. Data Exists Mode
+## Data Exists Mode
<Note>
This is the **most recommended VictoriaLogs alert configuration method**, because log scenarios are better suited for "alert when anomalous data exists" mode.
@@ -115,7 +115,7 @@ If Label fields is empty, every returned field except the value fields becomes a
See [Query Result Field Mapping](/en/monitors/alert-rules/query-result-fields) for details.
-## 4. No Data Mode
+## No Data Mode
No Data mode is used to monitor "logs that should be continuously generated are no longer appearing", common scenarios:
@@ -142,11 +142,11 @@ A no-data alert's **recovery mode** is configured inside the "Alert if previousl
| **End when data reappears or the timeout expires** | The alert ends when the data reappears or the automatic close timeout is reached. The timeout is in seconds with a minimum of 1. Available only when the "Alert if previously found data is now missing" mode is enabled |
| **Manual close only** | The alert stays active until you close it manually |
-## 5. Getting Original Logs During Alert
+## Getting Original Logs During Alert
Alert query conditions typically use "Do Stats" mode, which doesn't return original logs. Monitors supports configuring "Related Query" in alert rules to additionally query original logs when alert triggers.
-
+
"Related Query" results can be rendered in "Notes Description", example:
diff --git a/en/monitors/dashboards/dashboards.mdx b/en/monitors/dashboards/dashboards.mdx
index a87d62cf..f3c4a675 100644
--- a/en/monitors/dashboards/dashboards.mdx
+++ b/en/monitors/dashboards/dashboards.mdx
@@ -6,315 +6,255 @@ keywords: ["dashboard", "panel", "template variables", "comparison", "version hi
A dashboard turns queries into charts: it is made of tabs, sections and panels, and each panel binds one data source with a set of queries, evaluated live for the current time range and variable selections every time it opens. It is the right place to pin down the few charts you keep opening for routine inspection and incident review, instead of rewriting the queries in the [Query Workbench](/en/monitors/explore/explore) every time.
-## Overview and entry points
+## Where to find it
-- **Menu entry**: **Visualization → Dashboards** in the left menu (frontend route `/monit/dashboards`). Both the menu item and the page routes are gated on the "Datasource Visit" permission, so anyone who can see data sources can see the dashboard entry.
-- **From the Query Workbench**: a query that has produced a result can be saved straight to a dashboard through **Save to dashboard**, see [Create and save a dashboard](#create-and-save-a-dashboard).
+- **Menu**: **Visualization → Dashboards** in the left menu. Members who can view data sources see this entry.
+- **From the Query Workbench**: save a query that returns results straight to a dashboard — see [Create and save a dashboard](#create-and-save-a-dashboard).
-Access to a dashboard is decided by the **folder** it lives in, not by the dashboard itself: reads inherit the folder read permission, while write operations require the "Dashboard Manage" permission plus read access to the folder. See [Permissions](#permissions).
+Whether you can view or edit a dashboard depends on its **folder** — see [Permissions](#permissions).
## List and folders
-**Menu entry**: Visualization → Dashboards
+The left side is the folder tree shared with alert rules; the right side lists the dashboards in the current folder. Folders are created, renamed, moved and deleted on the tree — see [Folder management](/en/monitors/folders/folders).
-The left side is the folder tree shared with alert rules (the same `/monit/folder/list` API), and the right side lists the dashboards in the selected folder. Creating, renaming, moving and deleting folders all happen on that tree, and are governed by folder permissions — see [Folder management](/en/monitors/folders/folders).
-
-| Column | Description |
-|--------|-------------|
-| **Title** | Dashboard name; click to open the viewer |
-| **Updated by** | The user who last saved this dashboard |
-| **Updated at** | Time of the last save |
-| **Actions** | Shown with the "Dashboard Manage" permission: edit, delete, and the **More** menu (Move to another folder / Clone in this folder / Clone to another folder) |
-
-- **The search box only searches the current folder**, never across folders. Input is debounced by 300 ms, and the folder, search term and page number are all reflected in the URL (`folder_id`, `q`), so a list link can be shared and survives a refresh. Clicking the breadcrumb in the viewer returns you to the list with the same conditions you left it in.
-- **Paging** defaults to 20 rows per page.
-- An empty folder shows "No dashboards in this folder yet", and users with manage permission can create one straight from that empty state.
+- Search covers the **current folder** only.
+- The folder, search term and page are kept in the page address, so links can be shared and returning from a dashboard restores the list.
+- Each row's **More** menu offers: move to another folder, clone to this folder, clone to another folder. A clone is a new dashboard whose title gets a "copy" suffix and **does not carry version history**; moving or cloning into another folder requires read access to that folder.
## Create and save a dashboard
-**Create**: **New dashboard** at the top right of the list page (manage permission required), which opens `/monit/dashboards/new?edit=1`. A new dashboard starts with the title "Untitled dashboard", a default time range of the last hour, auto-refresh off, a single tab titled `Overview`, and no panels.
-
-**Save from the Query Workbench**: the workbench's **Save to dashboard** button turns the current query into a panel. In the dialog you can choose:
-
-| Option | Description |
-|--------|-------------|
-| **New dashboard** | Pick a folder and type a dashboard title; the dashboard is really created in that folder first, then opened in edit mode |
-| **Existing dashboard** | Pick a folder, then pick one of the dashboards in it; the dashboard opens in edit mode with this panel appended to the bottom of its first tab — **nothing is written until you save** |
-| **Panel title** | Panel name; empty means "Untitled panel" |
-| **Visualization** | Recommended from the last successful result (logs → Logs, sampled time series → Time series, otherwise → Table), and changeable |
-
-Prometheus runs both a range and an instant query in the workbench (Both); when the panel is saved it is stored as `Range` with the notice "Query type Both was saved as Range" — dashboards do not accept Both.
+**Create**: click **New dashboard** at the top right of the list (requires the Dashboard management permission). A new dashboard defaults to "Last 1 hour" and starts with one empty `Overview` tab.
-**Edit mode** works on a whole-dashboard draft kept in the browser:
+**Save from the Query Workbench**: click **Save to dashboard** in the workbench, choose a new or an existing dashboard, enter a chart title and pick a chart type (one is suggested from the query result; you can change it). When saving to an existing dashboard the panel is appended to the bottom of the first tab and takes effect only when you save.
-- The header lets you change the folder (new dashboards only) and the title; on the right are the time range, undo / redo (`⌘Z` / `⌘⇧Z`), cancel and save.
-- Every change (adding a panel, dragging the layout, editing variables or configuration) goes into the draft, one undo step per action, and is **lost when you refresh** (there is no server-side draft); leaving the page with unsaved changes is intercepted with "The draft is not saved. Leave anyway?".
-- **Save**: the title is required, and a new dashboard also requires a folder. The dialog takes an optional **version message** (up to 1024 characters) and states "The full definition will be submitted as a new revision (current vN)". The whole definition is submitted and a successful save creates a new revision; when the server finds nothing changed it reports "No changes". For an existing dashboard with no changes the save button is disabled.
-- **Use the current time range as the dashboard default**: when the range you browsed with is one of the relative presets (15m / 30m / 1h / 3h / 6h / 12h / 24h / 7d) and differs from the stored default, the save dialog offers the checkbox "Set current time range (…) as dashboard default".
-- **Concurrent edits**: if someone saved while you were editing, the save fails with "Dashboard was updated by someone else" and three options: **Save as copy…** (pick a folder and save a second copy), **Discard draft and load latest** (drop your draft and return to the viewer), or **Keep editing** (keep the draft — it is never merged automatically).
-- **Validation failure**: a "Save failed: definition validation errors" dialog lists each offending JSON Pointer path with its reason.
+<Note>
+Dashboards do not support Prometheus's Both query mode. A workbench query that runs as Both is saved to the panel as Range.
+</Note>
-**The remaining list actions**:
+**Editing and saving**:
-| Action | Description |
-|--------|-------------|
-| **Clone in this folder / Clone to another folder** | Builds a second dashboard from the full definition (new ID, title suffixed with "(copy)") and **does not carry history** |
-| **Move to another folder** | Changes the folder; the destination must be readable |
-| **Edit** | Opens the dashboard in edit mode |
-| **Delete** | See [Delete and trash](#delete-and-trash) |
+- Every change while editing is a draft you can undo / redo (`⌘Z` / `⌘⇧Z`). The draft lives only in the current browser page and is **lost on refresh**; you are warned before leaving the page.
+- When saving you can add a **version message** (optional, up to 1024 characters). Every save creates a new version.
+- If the relative time range you were previewing differs from the default, you can tick an option to make it the dashboard's default time range.
+- If someone else saved while you were editing, the save fails and you can save a copy, discard your draft and load the latest version, or keep editing. Drafts are never merged automatically.
## Tabs, sections and panel layout
-- **Tabs** are the top-level divisions of a dashboard: one by default, at most 10. Double-click a tab title to rename it; deleting a tab asks for confirmation first and reports "Contains N sections and M panels."
-- **Sections** sit inside a tab, like Grafana rows: the title row is always visible and the section can be collapsed. **A collapsed section loads no data**, and its header reads "(N panels · collapsed, not loading)". A tab holds at most 10 sections.
-- **Panels** are laid out on a 24-column grid. A new panel is `12×8` and lands at the bottom of its container; on the canvas you can drag, resize, duplicate (the copy is inserted below the original) and delete them.
-- A tab holds at most 30 panels and a whole dashboard at most 100.
-- A panel can carry a description next to its title: by default it is tucked into the ⓘ tooltip, and the panel option **Use as subtitle** moves it below the title. Descriptions render Markdown like text panels do, without images or raw HTML.
-- An empty canvas points you at "Start with your first chart / Pick a datasource, write a query, and refine with live preview", with **Add panel** and **New section** buttons.
+- **Tabs** are the top-level divisions of a dashboard. Double-click a title to rename it.
+- **Sections** live inside a tab and can be collapsed. **Collapsed sections do not load data**, which makes them a good place for charts you rarely need.
+- **Panels** sit on a 24-column grid and can be dragged, resized, duplicated and deleted.
+- A panel description appears in the ⓘ tooltip next to the title by default, or as a subtitle below it; descriptions do not support images or HTML.
+- Only panels in the current tab and in expanded sections load, with panels in view first.
-Panels are **lazy-loaded**: only the panels of the active tab and of expanded sections are scheduled, at most 4 queries are in flight at once, and panels inside the viewport go first. While refreshing, the previous chart stays on screen at half opacity; only the very first load shows a skeleton.
+For limits, see [Quotas and limits](#quotas-and-limits).
## Panel types and queries
-The panel editor shows a preview on the left and configuration on the right, grouped like Grafana: panel / legend / graph styles / standard options / thresholds / drill-down. **Visualization** offers seven types:
+The panel editor shows a preview on the left and configuration on the right. Available chart types:
-| Visualization | Description | Selectable |
-|---------------|-------------|-----------|
-| **Time series** | Trends over time; compare multiple series | Yes |
-| **Table** | Rows and columns of details; good for instant queries | Yes |
-| **Stat** | One key number with threshold coloring | Yes |
-| **Text** | Markdown notes, without a data source or queries | Yes |
-| **Bar** | Compare values across categories | Greyed out, marked "Coming in a later release" |
-| **Gauge** | Where a value sits within a range | Greyed out, marked "Coming in a later release" |
-| **Logs** | Stream of log lines | Greyed out, marked "Coming in a later release" |
+| Chart type | Best for |
+|---------|------|
+| **Time series** | Trends over time, with multiple series for comparison |
+| **Table** | Rows and columns of detail, good for instant query results |
+| **Stat** | One key number, with threshold colouring |
+| **Text** | Markdown notes; needs no data source or query |
-Bar, gauge and logs are supported by the backend contract but have no renderer in the console yet, so they cannot be selected in the type picker. If you saved a Logs panel through the workbench's "Save to dashboard", the viewer shows "This visualization (logs) will be supported in a later release".
+Bar, gauge and logs chart types will be supported in a later release.
-The **datasource** dropdown only lists the types a dashboard can query at runtime — **prometheus, mysql, loki** (the same set as Dashboard Runtime; diagnostic-only data source types never appear) — and a panel can reference either a **fixed datasource** or a **datasource variable** (switch the variable to move every panel that uses it to another datasource).
+**Data source**: Prometheus, MySQL and Loki are supported. Pick a fixed data source or a **data source variable**, so switching the variable switches the whole dashboard.
-The **query type** follows from the data source and the visualization and is not chosen by hand: MySQL data sources run a time-window query (`window`), tables take an instant snapshot (`instant`), and time series and stats take a range (`range`).
+**Query mode** is chosen automatically from the data source and chart type: tables use instant values, time series and stat use ranges, and MySQL queries a time window.
| Setting | Description |
-|---------|-------------|
-| **Query expression** | Prometheus and Loki panels support `${variable}` templates (the braces are optional — `$variable` works too) as well as built-in time variables such as `$__interval`, see [Built-in time variables](#built-in-time-variables); MySQL panels support no variable interpolation; PromQL data sources prompt for a PromQL query, other types prompt by type |
-| **Multiple queries** | Queries are labelled `A`~`Z`; only time series support more than one. Switching to any other visualization forces you to pick which one to keep, and the rest are removed |
-| **Series name** | Shown for time series only. Sets the display name used by the legend, tooltip and data links; `{{instance}}` is replaced with that series' `instance` label value, and leaving it empty shows all labels. If both the legend and the tooltip are hidden, the editor tells you the setting is invisible |
-| **Min step** | Shown for Prometheus range queries only. A lower bound for the query step, 15s by default (matching Prometheus' default scrape interval); it is dropped when you switch to a data source or query type that does not accept it |
-| **Value fields** | Which fields a stat panel shows as values (several are shown side by side, names are case-sensitive); a Prometheus result has only `value`, so a Prometheus stat is fixed to it |
-| **Unit / decimals / thresholds** | Threshold direction "Higher is worse / Lower is worse", with warning and critical levels colored as text or as background |
-| **Table column configuration** | Tables configure unit, thresholds and coloring per numeric column; a Prometheus table has only the `value` column to configure. Coloring can be "None / Text / Background", and a background-colored column can be **applied to the entire row** |
-| **Value mappings** | Turn numbers into text and color (e.g. show 0 as "Offline" in red). The first matching mapping from the top wins, and its color overrides threshold colors |
-| **Drill-down** | Panel links and data links, see [Click-to-filter and drill-down links](#click-to-filter-and-drill-down-links) |
+|--------|------|
+| **Query expression** | Prometheus / Loki panels can reference template variables as `$name` or `${name}` and use [built-in time variables](#built-in-time-variables). MySQL panels do not support variables |
+| **Multiple queries** | Only time series supports multiple queries (`A`–`Z`). When switching to another chart type you choose which one to keep |
+| **Series name** | The display name of each series in a time series, e.g. `{{instance}}` becomes the `instance` label value; empty shows all labels |
+| **Min step** | The lower bound of the step for Prometheus range queries, 15s by default |
+| **Value fields** | The fields a stat panel shows; case-sensitive |
+| **Unit / decimals / thresholds** | Thresholds can be "higher is worse" or "lower is worse", with warning / critical levels coloured as text or background |
+| **Table columns** | Unit, thresholds and colouring for numeric columns; background colouring can apply to the whole row |
+| **Value mappings** | Show values as text and colour (e.g. 0 as "Offline" in red). The first matching mapping wins and overrides threshold colours |
+| **Drill-down** | Panel links and data links — see [Click-to-filter and drill-down links](#click-to-filter-and-drill-down-links) |
+
+After changing a query, press Enter (or `⌘/Ctrl + Enter`) to run the preview; changing the data source, chart type or time reruns it automatically, and display settings (unit, thresholds, etc.) apply instantly. **Saving does not require a successful preview.**
### Panel-level query options
-**Query options** sit next to the datasource and apply to **every query on the panel** (A / B share them):
+These options apply to **all queries** of the panel:
| Option | Description |
-|--------|-------------|
-| **Max data points** | Maximum points per series, which sets the query step (time range ÷ max data points). Leave it empty to derive it from the panel width; the placeholder shows the value currently in effect |
-| **Relative time** | This panel always queries the last N and ignores the dashboard time range — e.g. `5m` always shows the last 5 minutes |
-| **Time shift** | Shifts the whole query range back by N, e.g. `1d` to compare with the same time yesterday |
-| **Compare** | Period-over-period comparison, see [Period-over-period comparison](#period-over-period-comparison) |
-
-Durations are always written as a number plus a unit (`s` / `m` / `h` / `d` / `w`), such as `5m`, `1h`, `1d`; an invalid value turns the input red with "Use a duration like 5m, 1h or 1d". A panel with a relative time or a time shift is marked next to its title in blue with the range it actually queries (e.g. "Last 5 minutes · timeshift -1d"), so viewers can tell it does not follow the dashboard time range.
+|------|------|
+| **Max data points** | The maximum points per series, which sets the query step. Empty means it is calculated from the panel width |
+| **Relative time** | Always query the most recent period instead of following the dashboard's time range, e.g. `5m` |
+| **Time shift** | Shift the query window back, e.g. `1d` to compare with the same period yesterday |
+| **Comparison** | Period-over-period — see [Period-over-period comparison](#period-over-period-comparison) |
-Previewing happens live inside the panel editor: editing the query itself runs it on Enter (or `⌘/Ctrl + Enter`), while changing the datasource, visualization or time re-runs it automatically; display settings (unit, thresholds, alias and so on) apply immediately without re-querying. **Saving does not require a successful preview.** On a new dashboard with no folder selected yet, the preview area shows "Select a folder before previewing".
+Durations are "number + unit" (`s` / `m` / `h` / `d` / `w`), e.g. `5m`, `1h`, `1d`. Panels with a relative time or time shift show the actual queried time next to the title, so viewers know they do not follow the global time.
### Built-in time variables
-A panel query expression can reference built-in time variables directly; they render the seconds computed from that panel's own execution window and step, so `$__range` spares you from maintaining a hand-written variable for how long the window is.
+You can use these variables directly in a panel's query expression; they are calculated from that panel's time window and step:
-| Variable | What it renders |
-|----------|-----------------|
-| `$__interval` | The panel's query step in seconds, such as `30s`; the step follows from the time range and the **Max data points**, bounded by the **Min step** |
-| `$__rate_interval` | The larger of `step + 15s` and `60s` (15s is the assumed scrape interval) — the value to hand straight to `rate()` |
-| `$__range` | The length of the panel's execution window in seconds, e.g. `86400s` for a 24-hour window |
-| `$__auto` | In a Loki instant query, the duration of the whole window in the largest unit that divides it — `1h`, `5m`, `90s` or `90500ms`; in a Loki range query it is the step in seconds, like `$__interval` |
+| Variable | Meaning |
+|------|-----------|
+| `$__interval` | The query step, e.g. `30s`, calculated from the time range and max data points and never below the min step |
+| `$__rate_interval` | The larger of `step + 15s` and `60s`, ready to use in `rate()` |
+| `$__range` | The length of the time window, e.g. `86400s` for 24 hours |
+| `$__auto` | In Loki instant queries, the whole window length (e.g. `1h`, `5m`); in Loki range queries, the same as `$__interval` |
-The reference syntax matches variables: both `${__interval}` and `$__interval` are accepted (the braces are optional), but a built-in takes no formatter — `${__interval:raw}` and the like are rejected.
+Where they are available:
-Which ones you can use follows from the datasource and the query type; every combination outside the table below (MySQL included) is unavailable, and such a definition fails validation on save — the dialog lists the offending JSON Pointer and the reason — while the panel itself queries nothing at run time:
-
-| Datasource · query type | Available built-in time variables |
-|-------------------------|-----------------------------------|
+| Data source · query mode | Variables |
+|------------------|------------------|
| Prometheus · range | `$__interval`, `$__rate_interval`, `$__range` |
| Loki · range | `$__auto`, `$__interval`, `$__range` |
| Loki · instant | `$__auto`, `$__range` |
-Built-in time variables exist only in a **panel query expression**: neither a template variable's candidate query nor a panel query's `args` can resolve them, and the definition is rejected on save.
+<Note>
+Built-in time variables work only in **panel query expressions** — not in template variable candidate queries — and do not accept format suffixes such as `:raw`. They are not available for MySQL panels. Using them anywhere else prevents the dashboard from being saved.
+</Note>
## Template variables
-The variable bar sits above the canvas and uses the same filter control as the rest of the product: each variable is a permanent filter field, single- or multi-select according to its configuration. In edit mode the bar has a **Manage variables** button at the end, opening a drawer where every variable can be added, edited or deleted.
+The variable bar sits above the canvas; each variable is a filter. While editing, click **Manage variables** at the end of the bar to add, change or delete variables.
-There are three **variable kinds**:
+| Type | Values come from | Settings |
+|------|---------|--------|
+| **Datasource** | A specific data source | Data source type (Prometheus / MySQL / Loki), default data source |
+| **Custom** | A hand-written list | One option per line, `text=value` or a bare value |
+| **Query** | A data source query | Data source (fixed or a data source variable) + query + when to refresh options |
-| Kind | Where values come from | Settings |
-|------|------------------------|----------|
-| **Datasource** | One concrete data source | Datasource type (only prometheus / mysql / loki) and default datasource |
-| **Custom** | A hand-written candidate list | Options (one per line, `text=value` or a bare value) |
-| **Query** | Candidates fetched by querying a data source | Datasource (fixed or a datasource variable) + query definition + when to refresh candidates |
+**Candidate queries for Query variables**:
-A **Query variable's candidate query** has three flavours by data source type: Prometheus needs `label` (required) and `metric` (optional) plus any number of **label filters** using `= / != / =~ / !~`; SQL data sources take an expression and a value field; Loki takes an expression and a field, where the field must be a stream label name (`^[A-Za-z_][A-Za-z0-9_]*$` — dotted or JSON field names do not work), and the candidates are that label's values on the streams the expression selects **within the dashboard's time range**, with an empty expression meaning every stream; the expression may reference dashboard variables but not built-in time variables (those exist only in panel query expressions, see [Built-in time variables](#built-in-time-variables)). **Preview candidates** in the drawer fetches candidates once with the current configuration to confirm the datasource and query are right, and shows the failure reason next to the variable when they are not.
+- **Prometheus**: `label` (required) and `metric` (optional), plus `= / != / =~ / !~` label filters.
+- **SQL data sources**: an expression and a value field.
+- **Loki**: an expression and a field. The field must be a stream label name (dotted or JSON field names do not work); options are that label's values on the selected streams within the dashboard's time range. An empty expression means all streams.
-**Names and references**: a variable name must match `^[A-Za-z_][A-Za-z0-9_]{0,63}$` and must not start with `__` (that prefix is reserved for built-in time variables), and a name already in use is rejected. Renaming is an atomic frontend refactor — every `${oldName}` reference (query expressions, query args, datasource variable references and the variable's own candidate query) is rewritten, and the editor warns "N references will be rewritten" before doing it. A variable that is still referenced cannot be deleted: "Variable x is referenced in N places; remove the references first." A dashboard holds at most 20 variables.
+Expressions may reference other dashboard variables but not built-in time variables. Click **Preview candidates** to check the query.
-**Selection mode and the 「All」 option**:
+**Naming and references**:
-- **Single**: must hold one concrete value, defaulting to the first candidate when the dashboard opens.
-- **Multi**: may be left empty, and **empty means everything**; the control then shows the placeholder "All". "All" is not a candidate — it is the state of having no concrete selection, so candidates added later are not implied by it, and there is no "select all" button.
-- **Clearing means All**: a variable that allows "All" has its own clear affordance (the × on the tag, or "clear" in the dropdown), and clearing writes an explicit All rather than falling back to the default. A variable that does not allow "All" has no clear affordance and must always keep a concrete value.
-- When a dashboard opens, a variable with no value in the URL first takes its default; with no default it falls back to the first candidate (or to All for a variable that allows it), and that selection is written back to the URL.
-- **Values outside the candidate list** (carried in by a URL or by an alert entry point) still run normally: the control shows them as "value (not in candidates)" with a warning, and does not block the query.
+- Names start with a letter or underscore, contain only letters, digits and underscores, are at most 64 characters, must not start with `__`, and must be unique.
+- Renaming a variable updates every place that references it.
+- A variable that is still referenced cannot be deleted; remove the references first.
-The URL is the single source of truth for variable selections: a single value is written as `var-<name>=value`, several values as repeated parameters, and All as `var-<name>=$__all` — the same parameters a dashboard URL uses, so a link can be shared with its variable selections attached.
+**Single, multi and "All"**:
+
+- A **single-select** variable always has one value; it defaults to the first option.
+- A **multi-select** variable can be left empty, and **empty means "All"**. "All" means no filtering, not "every current option".
+- Variables that allow "All" can be cleared; others must keep a value.
+- When the page address has no value, the variable uses its default, or else the first option ("All" if allowed).
+- A value passed in through a link applies even if it is not among the options; the control marks it as such.
+
+Variable selections are written to the page address, so they travel with shared links.
## Time range and auto-refresh
-- The **time range** comes from the URL's `from` / `to`, either absolute milliseconds or a `now-*` relative expression; with no URL parameters the stored **default time range** applies (the last hour for a new dashboard, and one of eight presets — 15m / 30m / 1h / 3h / 6h / 12h / 24h / 7d — when saved, always ending at "now").
-- **Auto-refresh**: the interval stored on the dashboard is one of Off / 30s / 1m / 5m; the viewer's refresh picker offers finer steps (Off / 10s / 30s / 1m / 5m / 15m / 30m / 1h). Picking one writes the `refresh` URL parameter and refreshes immediately rather than waiting a full interval. Relative ranges roll forward with "now" on each refresh, and the refresh button on the left runs a manual refresh at any time, spinning while queries are still running.
-- **Display time zone**: the bottom of the time picker's dialog holds a time zone row — the current zone (city plus abbreviation) and its UTC offset on the left, and a **Change time zone** button on the right that opens a searchable city list (search by city name, abbreviation or IANA name), grouped by continent, whose first group **Common** holds the three special entries in the table below. It applies to dashboards only (viewer, edit mode, panel editor and panel fullscreen) and decides how the time picker displays and parses times, the time series x-axis and tooltip times, and the time range label; what actually renders in the zone is absolute instants, while a relative range (such as the last hour) is a duration and does not shift with the zone. When the display zone differs from your personal effective zone, the time picker carries that zone's abbreviation as a reminder.
+- **Time range**: the dashboard's saved default is used. The defaults you can save are 15m / 30m / 1h / 3h / 6h / 12h / 24h / 7d.
+- **Auto-refresh**: a dashboard can save off / 30s / 1m / 5m; while viewing you can pick more intervals (10s to 1h). Choosing one refreshes immediately.
+- **Display time zone**: click **Change time zone** at the bottom of the time picker to choose a city time zone or one of the three shortcuts below. It only affects dashboards and is remembered in this browser. Relative ranges (such as "Last 1 hour") are durations and are not shifted by time zone.
-| Common entry | Meaning |
-|--------------|---------|
-| **Default** | Follow your personal effective time zone |
-| **Browser time** | Follow the current browser's time zone |
+| Shortcut | Meaning |
+|--------|------|
+| **Default** | Your effective time zone from personal settings |
+| **Browser time** | The browser's current time zone |
| **Coordinated Universal Time** | Always UTC |
-The choice is stored in this browser (the localStorage key `monit.dashboards.timeZone`) and reused when you come back; picking **Default** clears that record and returns to your personal effective zone.
-
## Period-over-period comparison
-The **Compare** entry in a panel's **query options** makes the same query run a second time over the period one cycle earlier — "1d before" or "1w before" — and merges both results into the same panel.
+In a time series or stat panel, set **Query options → Comparison** to "1 day ago" or "1 week ago". The same query runs again for the previous period and both results appear in one chart:
-- **Supported panels**: only **time series** and **stat** panels have this option; every other visualization has neither the setting nor an extra request.
-- **Available periods**: only "1d before" and "1w before", plus "No comparison"; arbitrary durations are not offered.
-- **Time series**: the comparison run is drawn as a **dashed line in the same color**, and the legend spells out the period, e.g. `series name (1d ago)`.
-- **Stat**: shows the percentage change against the comparison period, e.g. "▲ 12.3% vs 1d ago" (flat values get no arrow, so 0% is not read as a rise); no percentage is shown when the comparison value is 0 or missing.
-- **Failure handling**: if the comparison query fails you only lose the comparison line — the current results still render, and the panel's overall state still reflects the current run.
+- **Time series**: the comparison series is a dashed line in the same colour, with the period in the legend, e.g. "series (1 day ago)".
+- **Stat**: shows the percentage change against the comparison period, e.g. "▲ 12.3% vs 1 day ago". No percentage is shown when the comparison value is 0 or missing.
+- If the comparison query fails, only the comparison line is missing; the current results are unaffected.
## Cross-panel cursor linking
-Every **time series** panel in a dashboard shares one cursor synchronisation group: moving the mouse over any of them draws the same **vertical line and points** on the others, which makes it easy to line up several metrics at the same instant.
-
-- Only mouse move and mouse leave are synchronised, not press and release (otherwise a drag-zoom would zoom every panel), and the **Y axis is not synchronised** — only the vertical line is drawn.
-- The tooltip stays on the panel under the mouse; a linked cursor does not raise one.
-- **Panels with a relative time or a time shift do not take part** — their time axis differs from the dashboard's, so linking by timestamp would point at the wrong instant.
-- The editor's preview canvas and the panel fullscreen view do not link; only the time series in the dashboard grid do.
+Moving the mouse over any time series shows a vertical line at the same moment on the dashboard's other time series, so you can line up several metrics. Panels with a relative time or time shift do not take part.
## Click-to-filter and drill-down links
-**Click-to-filter**: clicking data in a chart (a point on a time series, a stat, a numeric or label cell in a table) opens an overlay. If the clicked data carries a **label — or table column — whose name matches a dashboard variable**, the overlay offers "Filter by `k = v`", which sets that variable to that value and re-queries the whole dashboard.
-
-- The variables that can be set this way are all variables **except datasource variables** (a datasource variable is a single-choice datasource selector and does not take part).
-- When a time series point carries a timestamp, the overlay header shows the series name (with a copy button), the point's time and its value formatted with the panel's unit.
-- Label cells in tables only offer filtering, never drill-down: a drill-down link expands the labels of the whole row or series, so handing it a single label would build a broken URL.
-
-**Drill-down links (data links)**: with data links configured, clicking data can open an `http(s)://` URL or a site-relative `/` URL, carrying the clicked value, labels and time. The rules are:
+**Click-to-filter**: when you click data in a chart (a point, a stat, a table cell) whose label or column name matches a dashboard variable, you can choose "Filter by `k = v`" to set that variable and refresh the whole dashboard. Data source variables are not used for filtering.
-- A time series panel can enable **One click** on one link (clicking data opens it straight away, with no menu; at most one link per panel). A stat or table panel opens the only available link directly and pops a menu when there are several.
-- Links are expanded **at click time**: dashboard variables and the time range come from the current view context, while point-related placeholders come from the point that was clicked. Inserted values are URL-encoded, and `${xxx:raw}` splices a value in verbatim when it belongs inside a path.
-- Available placeholders: `${__value.raw}` (the point's value), `${__value.time}` (the point's time in ms), `${__series.name}` (series name), `${__field.labels.<label>}` (a label value), `${__from}` / `${__to}` (the current range in ms), `${__url_time_range}` (`from=…&to=…` time parameters), `${__all_variables}` (all dashboard variables as URL parameters), plus any dashboard variable name.
+**Data links**: with data links configured, clicking a data point opens an external address (`http(s)://`) or an in-product address (starting with `/`), optionally carrying the clicked value, labels and time:
-**Panel links** sit next to the panel title: a single one opens directly, several open a menu, and they open in a new tab by default. They expand the same way as above, minus the point placeholders.
+- A time series can mark one link as **open on click** (at most one per panel). Stat and table panels open the link directly when there is one, and show a menu when there are several.
+- Inserted values are URL-encoded automatically; use `${xxx:raw}` to insert a value into a path as is.
+- Placeholders: `${__value.raw}` (value), `${__value.time}` (time, ms), `${__series.name}` (series name), `${__field.labels.<label>}` (label value), `${__from}` / `${__to}` (time range bounds, ms), `${__url_time_range}` (time range parameters), `${__all_variables}` (all variable parameters), and any dashboard variable name.
-## Sharing and URL state
+**Panel links**: shown next to the panel title and opened in a new tab by default; they accept the placeholders above except those tied to a data point.
-A dashboard keeps all of its state in the URL, so "sharing" is just sending the address. The viewer's URL parameters are:
+## Sharing
-| Parameter | Description |
-|-----------|-------------|
-| `from` / `to` | Time range, in absolute milliseconds or as a `now-*` relative expression |
-| `var-<name>` | Variable selection; several values are repeated parameters, and All is `$__all` |
-| `target` | Jumps to a tab, section or panel, scrolling to it and highlighting it briefly; if the target no longer exists the page says "The linked content no longer exists; showing the first tab instead" |
-| `view` | Panel fullscreen; the value is the panel ID |
-| `refresh` | Auto-refresh interval |
-| `edit` | `1` opens edit mode (manage permission required, otherwise you are sent back to the list) |
-
-**Copy panel link** inside the panel fullscreen dialog writes both `target` and `view`, so the copied address opens directly on that one panel in fullscreen.
+A dashboard keeps its time range, variable selections, fullscreen panel and auto-refresh in the page address, so copying the address shares your current view. In a fullscreen panel, **Copy panel link** opens straight to that panel in fullscreen.
<Note>
-Dashboards have **no** anonymous or public sharing: every API validates folder and datasource permissions behind an authenticated session, and a URL only shows the same content to someone who can read the folder and the datasources. When a dashboard is missing or not accessible, the page says "Dashboard not found or not accessible".
+Dashboards **cannot** be shared publicly or anonymously. Anyone opening a link must sign in and have access to the dashboard's folder and the panels' data sources.
</Note>
## Fullscreen and query details
-Hovering a panel title bar reveals its action icons: **Edit** (manage permission required; opens edit mode with that panel's editor already open), **Fullscreen**, and **Retry** (once the panel has results).
+Hover over a panel title to **Edit** (requires management permission), go **Fullscreen**, or **Retry**.
-- **Fullscreen** is driven by the `view=<panel ID>` URL parameter, so it can be shared, survives a refresh and exits with the back button. A text panel in fullscreen only shows its content, with no time picker and no download.
-- Inside fullscreen you can **change the time range for that one panel** (session state, not written to the URL, and without touching the main grid); only that panel re-queries.
-- Fullscreen also offers **Copy panel link** and **Download data CSV** (named after the panel title).
-- The **Query details** table at the bottom lists the panel's queries one by one — `Ref`, expression (as saved), `request ID`, state — and each row has an **Open in query workbench** icon that jumps to the [Query Workbench](/en/monitors/explore/explore) with the expanded variables and the current time (or the time you changed inside fullscreen) for isolated debugging.
-- Keyboard shortcuts: with the pointer over a panel (or while it is fullscreen), `v` toggles fullscreen and `e` enters edit mode (manage permission required). Shortcuts are ignored while an input has focus.
+- In fullscreen you can change that panel's time range without affecting the others.
+- In fullscreen you can **Copy panel link** or **Download data CSV**.
+- **Query details** lists each query's expression and status; **Open in query workbench** takes the current variables and time to the [Query Workbench](/en/monitors/explore/explore) for debugging.
+- Shortcuts: press `v` on a panel to toggle fullscreen and `e` to edit.
## Version history and restore
-**⋮ → Version history** at the top right of the viewer. The list is ordered by version descending, with columns **Version / Time / Updated by / Message**; the current version carries a "Current" badge, and the two newest versions are selected by default.
-
-- **Compare versions**: select two versions and click **Compare**. The comparison view lets you pick the version on each side (the left one can only be older than the right one) and shows the difference between the two stored definitions as a **JSON diff**; different key order is not a difference, and two identical versions report "No changes".
-- **Restore**: click **Restore vN** in the comparison view and confirm ("Restoring creates a new version with that content (current vM stays in history and can be restored back)"). A restore is implemented as a save of the old definition, so it **creates yet another new version**, with the message "Restored from vN".
-- **Retention**: each dashboard keeps only the most recent **20** versions, and older ones are pruned on save — so you can only restore a version that is still in the history.
+Click **⋮ → Version history** at the top right of the dashboard:
-This is the same interaction as the alert rule [change log · version comparison](/en/monitors/quickstart/quickstart).
+- **Compare**: tick two versions and click **Compare** to see the JSON diff of their definitions.
+- **Restore**: on the compare page, click **Restore vN**. Restoring **creates a new version** from the old content; the current version stays in history.
+- Each dashboard keeps its latest **20** versions.
## Delete and trash
-Deleting a dashboard from its list row (after confirmation) moves it to the trash, and the confirmation dialog states `"title" will be moved to trash and purged after 30 days.` A background job runs hourly and physically deletes trash older than 30 days, together with its revision history.
+Deleted dashboards go to the trash and are permanently deleted, with their version history, after **30 days**.
-- Opening a deleted dashboard directly reports "This dashboard has been deleted".
-- The console currently has **no** trash list page and no restore entry point; the backend exposes trash listing and restore APIs, and a restore can be told which folder to use, which becomes mandatory once the original folder no longer exists (otherwise it answers that a restore folder is required).
-- Deleting requires read access to the dashboard's folder plus the manage permission, and the request carries the current revision, so it cannot delete a version someone else just saved.
+The console has no trash page yet. To restore a dashboard, use the Open API to list the trash (`/monit/dashboard/trash/list`) and restore (`/monit/dashboard/restore`); if the original folder no longer exists, specify a target folder.
## Permissions
-| Capability | Required permission |
-|------------|--------------------|
-| Seeing the Dashboards menu, opening the list and the viewer | "Datasource Visit", plus read access to the folder |
-| Creating, editing, moving, deleting, cloning and restoring versions | "Dashboard Manage" (`monitDashboard:manage`), plus read access to the folder in question |
-| Running a panel (querying its datasources) | Read-only (readonly) permission on every datasource the panel references |
-
-A few implementation facts explain the behaviour above:
+| Action | Required |
+|------|-----------|
+| View dashboards | The Data source view permission, and read access to the folder |
+| Create, edit, move, delete, clone, restore versions | The Dashboard management permission, and read access to the folder (and any target folder) |
+| See data in a panel | Query permission on the panel's data sources |
-- **Reads have no permission point of their own**: the backend gates dashboard reads on folder read permission (a Folder Read filter), so the frontend route visibility follows the Query Workbench precedent and hangs off "Datasource Visit".
-- **The folder decides visibility**: the account owner and Admins can read every folder, while for other members the visible scope follows the teams bound along the folder chain (if the folder or any ancestor has a bound team, the member must belong to that team; if nothing on the chain is bound, every member can read it). When a folder is outside that scope, read APIs answer "Dashboard not found" without revealing whether it exists, and write APIs answer with a permission error. The evaluation rules are in [Folder management](/en/monitors/folders/folders).
-- **Two gates on writes**: both the manage permission and read access to the target folder — moving or cloning a dashboard into another folder requires read access to that destination too.
-- **Panel queries follow datasource authorisation**: at run time only the datasources you may query are resolved, so a panel whose datasource is missing, disabled or outside your permission shows "No permission for this datasource" instead of leaking datasource details. Datasource authorisation is documented in [Data source management](/en/monitors/data-sources/data-sources).
-- **Public sharing**: not supported. There is no anonymous access switch or endpoint, and a URL only means something inside an authenticated session that passes the folder and datasource checks (see [Sharing and URL state](#sharing-and-url-state)).
+- Folder read access is determined by the teams bound to the folder; the owner account and Admins can read every folder. See [Folder management](/en/monitors/folders/folders).
+- A panel whose data source you cannot query (or that is disabled or missing) shows a "no data source permission" message. See [Data sources](/en/monitors/data-sources/data-sources) for data source authorization.
## Export JSON
-**⋮ → Export JSON** in the viewer downloads the current definition as a JSON file named after the dashboard title (or `dashboard` when there is none). The file contains `schema_version`, `dashboard_id` and the full `definition`, which is useful for backups or for committing to a repository to compare changes. The console has **no** matching import entry point.
+Click **⋮ → Export JSON** to download the current version's full definition for backups or version control. Importing is not available in the console yet.
-## Panel states and common errors
+## Panel states and common issues
-Each panel reports its own run state; the common ones are:
+| What the panel shows | Cause and fix |
+|------------|------|
+| No data | The query succeeded but returned nothing for this time range |
+| **Partially failed** | Some queries failed; hover to see why. Successful parts still render |
+| Result does not match the chart | The result shape does not suit the chart type (e.g. a table received time series data); change the chart type or the query |
+| Unresolved variable | A variable the panel needs has no value yet; make a selection in the variable bar |
+| No data source permission | See [Permissions](#permissions) |
+| Query timeout / result too large | Narrow the time range or simplify the query |
+| Query failed | Read the error and click **Retry** to rerun the panel |
-| State / notice | Meaning |
-|----------------|---------|
-| "Query succeeded, but no data in this range" | The query succeeded and the time range holds no data |
-| **Partial failure** badge | Only some of the panel's queries succeeded; hover to see each failed `Ref` and its reason, while the successful ones keep rendering |
-| "Result does not match the panel configuration" | The result shape does not match what this visualization requires (for example a table fed a pure time-series frame); the panel never silently switches renderers |
-| "Variable x is unresolved / Make a selection above first" | A variable the panel depends on has no valid value yet, so the panel **sends no request** until you make the selection in the variable bar |
-| "No permission for this datasource" | You may not query the panel's datasource (or it is disabled / missing) |
-| "Query timed out" | The runtime query exceeded its deadline |
-| "Result exceeds the size limit; narrow the time range or simplify the query" | The result was too large and needs a narrower range or a simpler query |
-| "Query failed" + Retry | Any other error is shown with the message the server returned, and **Retry** re-runs just that panel |
-
-One more behaviour: if someone saves the dashboard while you are viewing it, the page detects that its revision is stale and **silently reloads the latest definition**, with no manual refresh needed.
+If someone saves the dashboard while you are viewing it, the page loads the latest version automatically.
## Quotas and limits
| Limit | Maximum |
-|-------|---------|
+|--------|------|
| Tabs per dashboard | 10 |
| Sections per tab | 10 |
| Panels per tab | 30 |
| Panels per dashboard | 100 |
| Variables per dashboard | 20 |
-| Data links on a table (including link columns) | 5 |
-| Retained revisions | 20 |
+| Data links per table (including link columns) | 5 |
+| Versions kept | 20 |
| Trash retention | 30 days |
-| Single definition (the JSON submitted on save) | 1 MiB |
-
-Hitting the panel, tab or variable limits surfaces "Panel limit reached", "Tab limit reached" or simply disables the add button; an oversized definition makes the save fail with a size-limit error.
+| Dashboard definition size | 1 MiB |
diff --git a/en/monitors/data-sources/data-sources.mdx b/en/monitors/data-sources/data-sources.mdx
index 49347742..5c64886d 100644
--- a/en/monitors/data-sources/data-sources.mdx
+++ b/en/monitors/data-sources/data-sources.mdx
@@ -30,154 +30,95 @@ Monitors supports the following 15 data source types:
| **MongoDB Mongos** (`mongodb_mongos`) | MongoDB sharded cluster router, diagnostic-only |
| **Kafka** (`kafka`) | Apache Kafka cluster, diagnostic-only |
-Of these, the 5 **diagnostic-only types** — Redis Node, Redis Sentinel, MongoDB (mongod/mongos) and Kafka — are used for database and middleware diagnostics and cannot evaluate alerts: `alerting_enabled` cannot be enabled (always `false`), so they cannot participate in alert rule queries and evaluation. They cannot enter the query workbench either — they are used from AI SRE through diagnostic tools only (see the "Data source row actions: query and AI analysis" section below). Connection address requirements are covered in [Data source type configuration](#data-source-type-configuration).
+Of these, the 5 **diagnostic-only types** — Redis Node, Redis Sentinel, MongoDB (mongod/mongos) and Kafka — cannot be used in alert rules or queried in the Query Workbench; they are only used by AI SRE to diagnose databases and middleware (see [Query and AI analysis](#data-source-row-actions-query-and-ai-analysis)).
## Data source list
-The data source list shows only the data sources you are allowed to query, with the following information:
+The list shows only the data sources you are allowed to query, with these columns:
-- **Name**: The identifier for the data source; when the row carries a team authorization, the name is followed by **Managing team** and **Query-allowed team** tags (see [Authorization tags in the Name column](#authorization-tags-in-the-name-column))
-- **Type**: Data source type with icon
-- **Connection URL**: The access address of the data source
-- **Associated Alert Engine**: The bound alert engine cluster name, with engine online status indicator
-- **Enable datasource**: An inline switch controlling whether the data source takes part in business queries and diagnostics — this column is where you enable or disable a data source in the console
-- **Notes**: Supplementary description
+- **Name**: data sources with team authorization show a green **Managing team** tag and grey **Query-allowed team** tags after the name. If a team has been deleted, the tag reads **Deleted team** and that authorization no longer applies; the creator or an admin can fix it.
+- **Type**, **Connection URL**, **Notes**
+- **Associated Alert Engine**: the engine cluster that runs queries, with its online status
+- **Enable datasource**: turns the data source on or off — see [Enable and alert evaluation](#enable-and-alert-evaluation)
-The list is filtered by query permission: when you have no query (readonly) permission on a data source, the whole row is absent from the response — you can neither see it nor find it with the search box — so the list may hold fewer rows than the account actually has. The owner account, the Admin role, the creator, and members of the managing team or the readonly teams always see it. See the "Data source permissions (team authorization)" section below for the authorization model.
-
-You can filter data sources by name, type, connection address, or note using the search box. The list auto-refreshes every 5 seconds to reflect real-time engine connection status.
-
-### Authorization tags in the Name column
-
-The Name column states the authorization role of each data source, so a glance is enough to tell which ones have an owner:
-
-- A row with `manage_team_id` carries a green **Managing team** tag showing the team name.
-- Every team in `readonly_team_ids` gets its own grey **Query-allowed team** tag, also showing the team name.
-- Hovering a tag names the role it stands for (managing team or query-allowed team).
-- Rows with neither field set carry no tag at all — the whole tenant being able to query and manage is the norm and needs no label.
-- Team names are fetched asynchronously: while the managing team's name is still in flight the row shows a placeholder skeleton, so it never flashes a wrong "Deleted team", and a name that still cannot be resolved once the lookup settles renders as **Deleted team** — that authorization no longer matches anything (after a team is deleted, the creator or an administrator can take over and fix it; see "Validation and normalization" above).
-
-### Enable datasource
-
-The **Enable datasource** column on the right of the list is the console entry point for enabling and disabling a data source; a toggle takes effect immediately. The tooltip icon beside the column header explains what disabling does:
-
-| State | Meaning |
-|-------|---------|
-| **On** | The data source takes part in business queries and data source diagnostics as usual. |
-| **Off** | No queries, diagnostics or alert evaluations run against it, but the configuration — connection parameters, credentials, associated alert engine — is kept in full and it can be re-enabled at any time; disabling does not change `alerting_enabled`. |
-
-- **Permission**: whether this column is operable is decided by the data source edit permission (`MonitDatasourceUpdate`); without it the switch is disabled and the column is read-only. The switch itself calls the data source detail and update endpoints, which add an instance-level `manage` check on top: even with `MonitDatasourceUpdate`, if you are not the creator, not the owner account or an Admin, and not a member of the datasource's managing team, the toggle is rejected by the backend (`only the managing team can manage this datasource`). See the "Data source permissions (team authorization)" section below for the decision rules.
-- **New data sources are enabled by default**: they are always created with `enabled=true`, and the create/edit drawer has no such switch; to disable a data source, switch it off in the list after creating it.
-- **List badge**: the Name column no longer shows a separate "disabled" badge — the switch alone carries the enabled/disabled state. A "Not used for alerting" badge on the Name column means `alerting_enabled=false`, and it appears only when the data source is enabled and its type supports alert evaluation: a disabled data source carries no badge (the switch already expresses that state), and neither do the 5 diagnostic-only types (alert evaluation is simply not applicable to them).
+You can search by name, type, connection URL or remarks. The list refreshes engine status every 5 seconds.
## Data source permissions (team authorization)
-A data source can restrict two kinds of operation by team: **query and reference** (readonly) and **management** (manage). With no authorization configured the behaviour is exactly the default — the whole tenant can read and write; existing data sources have both authorization fields set to `NULL` and need no action.
-
-| Field | Value | Meaning |
-|-------|-------|---------|
-| `manage_team_id` | A team ID, nullable | The single managing team of this data source. `NULL` means management is unrestricted |
-| `readonly_team_ids` | An array of team IDs, nullable | The teams allowed to query and reference this data source. `NULL` means query and reference are unrestricted |
-| `creator_id` | A member ID, nullable | The creator, written automatically on creation; when an existing row has `NULL`, management is decided by the managing team and administrators only |
-
-There are exactly three legal authorization configurations:
-
-| Configuration | Who can query / reference | Who can manage |
-|---------------|---------------------------|----------------|
-| Neither field configured (`NULL`) | The whole tenant | The whole tenant |
-| Only `manage_team_id` | The whole tenant | The creator, the owner account, the Admin role, and members of the managing team |
-| Both `manage_team_id` and `readonly_team_ids` | The creator, the owner account, the Admin role, and members of the managing and readonly teams | The creator, the owner account, the Admin role, and members of the managing team |
-
-`manage` always implies `readonly`: whoever can manage can also query. The team set comes from the current user's team membership; if that lookup fails the context fails closed to an empty team set rather than opening up permissions.
-
-**Validation and normalization**:
-
-- `readonly_team_ids` non-empty while `manage_team_id` is empty is rejected (HTTP 400, with an error naming the dependency between the two fields) — a data source with restricted query access must have an explicit responsible team.
-- Updates are validated against the merged final state of "old value + input", so clearing `manage_team_id` while `readonly_team_ids` stays non-empty is rejected too.
-- Values are normalized before writing: `manage_team_id` of `0` becomes `NULL`; `readonly_team_ids` is deduplicated, stripped of `0`, sorted, and an empty set becomes `NULL`. Teams are not checked for existence — dangling IDs simply stop matching (after a team is deleted, the creator or an administrator can take over and fix it).
+By default every member can query and manage every data source. To restrict that, set these fields when creating or editing a data source:
-### What authorization changes
+| Field | Effect |
+|----------|----------|
+| **Managing team** (single) | Only members of this team can edit, delete, enable or disable the data source |
+| **Query-allowed teams** (multiple) | Only these teams (plus the managing team) can query the data source or reference it in alert rules and dashboards |
-- **List**: only data sources you are allowed to query are returned. A data source you may not query is absent from the response entirely; each row carries a `my_perm` field whose value is `manage` or `readonly`, plus the authorization fields (`manage_team_id`, `readonly_team_ids`, `creator_id`). The frontend only consumes these decisions; it never computes them.
-- **Management operations**: the data source detail (which returns connection credentials), edit, delete and the enable toggle all require `manage`, otherwise the request is rejected with an access-denied error (`only the managing team can manage this datasource`). For rows you lack `manage` on, the console offers a read-only view instead (see "Edit and delete"): it renders from the list row with every credential masked and does not change this server-side gate.
-- **Query and reference**: instant queries, data exploration, dashboard panel queries, datasource tool calls, and referencing the data source in an alert rule all require `readonly`; without it the request is refused explicitly, without exposing data source details.
-- **Saving alert rules**: saving a rule requires the author to hold `readonly` on every data source the rule references, including data sources matched by a name pattern at save time; otherwise the save is rejected and names the data source that may not be referenced. The only exemption is a pure disable (a field update that only sets `enabled` to `false`). Once saved, rules are executed under the system identity, so later changes to member permissions do not affect them.
-- **Audit**: changes to the authorization fields are written as a `datasource_auth_update` audit record.
+Leave a field empty for no restriction. There are three valid combinations:
-### How to configure it
+| Configuration | Who can query and reference | Who can manage |
+|------|--------------|----------|
+| Neither set | All members | All members |
+| Managing team only | All members | Creator, owner account, Admins, managing team members |
+| Both set | Creator, owner account, Admins, managing and query-allowed team members | Creator, owner account, Admins, managing team members |
-The create and edit drawers each hold a team input per field, which takes effect once you save and leaves the scope unrestricted when left empty:
+- If you set query-allowed teams, you **must also set a managing team**.
+- Except for the owner account and Admins, you can only pick a managing team you belong to.
+- Anyone who can manage can also query. Authorization is per team only; to authorize an individual, create a small team for them.
+- Authorization changes are recorded in the audit log.
-| Form field | Field name | Selection | Effect |
-|------------|------------|-----------|--------|
-| **Managing team** | `manage_team_id` | Single select | Members of the managing team can edit, delete, enable or disable this data source. Leave empty to let everyone manage it; the creator and admins can always manage it |
-| **Query-allowed teams** | `readonly_team_ids` | Multi select | Restricts which teams can query and reference this data source. Leave empty to let everyone query it; the managing team can always query it |
+Once authorization is set:
-Both values travel with the data source create and update requests (`POST /monit/datasource/create`, `POST /monit/datasource/update`): you can set them while creating a data source, and changing the authorization fields of an existing data source is a management operation that requires `manage` on that data source. They are normalized before submission: clearing `manage_team_id` becomes an explicit `null`, and `readonly_team_ids` deduplicated to an empty list also becomes `null`. In an update request a missing key keeps the current value while `null` clears it, so **clearing the selection is what revokes that authorization**. You can also submit both fields straight through the API instead of using the console.
-
-Two constraints on the console side:
-
-- **A managing team is required once query-allowed teams are set**: if you pick query-allowed teams without a managing team, the form reports "A managing team is required when query-allowed teams are set" under **Managing team** before submitting, rather than letting the backend answer with a 400.
-- **You can only point the managing team at a team you belong to**: except for the owner account and the Admin role, the **Managing team** candidates are limited to the current user's own teams — pointing the managing team at a team you are not in costs you management of that data source the moment you save (the creator has a fallback, an ordinary managing-team member does not). A team you are not a member of that is already selected still shows its name normally.
-
-<Note>
-Authorization is granted at team granularity only; per-member authorization is not supported. To authorize an individual member, create a small team for them.
-</Note>
+- Members without query permission do not see the data source in the list and cannot use it in the Query Workbench, dashboards or data source tools.
+- Members with query permission only can view the configuration read-only, with credentials hidden.
+- **When saving an alert rule**, you need query permission on every data source it references (including those matched by a name pattern at save time). Disabling a rule is exempt. Once saved, a rule keeps running regardless of later permission changes.
## Create a data source
<Steps>
-<Step title="Select data source type">
-Click the **New** button and select the data source type (e.g., Prometheus, MySQL) at the top of the form.
+<Step title="Select the data source type">
+Click **New** and choose the data source type (such as Prometheus or MySQL) at the top of the form.
</Step>
<Step title="Fill in basic information">
-| Config Item | Description |
-|-------------|-------------|
-| **Name** | Unique identifier for the data source; alert rules can reference data sources via wildcard by name or exact match by ID (see below) |
-| **Notes** | Optional supplementary description |
-| **Associated Alert Engine** | Select the engine cluster responsible for querying this data source; typically choose a cluster in the same datacenter |
+| Setting | Description |
+|--------|------|
+| **Name** | A unique name; alert rules can bind data sources by name pattern or exact match (see below) |
+| **Notes** | Optional notes |
+| **Associated Alert Engine** | The engine cluster that queries this data source, usually one in the same data centre |
</Step>
<Step title="Configure connection parameters">
-Fill in the connection parameters specific to the data source type. See the sections below for details.
+Fill in the connection parameters for the type — see [Data source type configuration](#data-source-type-configuration).
</Step>
<Step title="Save">
-Click **OK** to complete creation.
+Click **OK**. New data sources are enabled by default.
</Step>
</Steps>
### Two ways to bind data sources in alert rules
-Alert rules support two methods for binding data sources. Both can be used together, and at least one must be specified. The rule applies to all data sources matched by either method (union).
+An alert rule binds data sources in at least one of these ways; you can use both, and the rule applies to the union of their matches.
-| Binding Mode | Field | Matching Logic | Use Case |
-|--------------|-------|----------------|----------|
-| **Wildcard by name** | `Data Sources (Wildcard)` | Matches by name with wildcards. `*` matches all data sources; `Prom*` matches names with the Prom prefix | Dynamically match a group of data sources, e.g., data sources sharing a common naming prefix |
-| **Exact match by ID** | `Data Sources (Exact Match)` | Associates by data source ID; select specific data sources from a dropdown list | Precisely bind specific data sources, unaffected by data source renames |
+| Binding | Matching | When to use |
+|----------|----------|----------|
+| **Wildcard by name** | Wildcard match on the name: `*` matches all data sources, `Prom*` matches names starting with Prom | Dynamically match a group of consistently named data sources |
+| **Exact match by ID** | Pick specific data sources from the list | Bind particular data sources, unaffected by renames |
<Warning>
-Wildcard by name stores name strings — if a data source is renamed, existing wildcard rules may no longer match. Exact match by ID stores the data source ID and is unaffected by renames. If stability is a priority, prefer exact match.
+After a data source is renamed, existing name patterns may no longer match it. For rules that must stay stable, prefer exact match.
</Warning>
-<Note>
-Saving a rule also requires the author to hold query (readonly) rights on every data source the rule references — both the ones picked by **exact match** and the ones matched by a **name pattern** at save time. If any of them fails the requirement, the save is rejected with a message that the data source may not be referenced. The only exception is a pure disable: a batch field update that only sets `enabled` to `false` is always allowed. See the "Data source permissions (team authorization)" section below.
-</Note>
-
-## Enabled and alert evaluation switches
+## Enable and alert evaluation
-Data sources have two independent switches, controlling business execution and alert evaluation respectively:
+A data source has two independent switches:
-| Switch | Field | Meaning |
-|--------|-------|---------|
-| **Enabled** | `enabled` | Whether business execution is enabled. When disabled, the data source rejects business queries and datasource tools, but `alerting_enabled` is unchanged |
-| **Use for alerting** | `alerting_enabled` | Whether the data source may participate in alert rule queries and evaluation; once off, the Name column in the list shows a "Not used for alerting" badge. Alert evaluation also requires `enabled=true` and an alerting-capable type; `false` does not block non-alerting queries and datasource tools |
+| Switch | Where | When off |
+|------|------|------|
+| **Enable datasource** | The switch in the data source list | The data source runs no queries, diagnostics or alerts, but its configuration is kept and you can turn it back on at any time |
+| **Use for alerting** | The create / edit form | The data source is excluded from alert rule evaluation (the list shows "Not used for alerting"); other queries are unaffected |
-- **Console entry point**: the `enabled` switch is the **Enable datasource** column in the data source list (see [Enable datasource](#enable-datasource)); the create/edit drawer has no such switch. `alerting_enabled` is set in the create/edit drawer.
-- **Create defaults**: `enabled` defaults to `true`; `alerting_enabled` defaults to `true` for alerting-capable types and `false` for diagnostic-only types.
-- **Update behavior**: omitting either field preserves the current value; an explicit `null` is invalid.
-- **Diagnostic-only types** (`redis_node`, `redis_sentinel`, `mongodb_mongod`, `mongodb_mongos`, `kafka`) reject `alerting_enabled=true`.
-- **Conflict protection**: when enabled alert rules reference the data source, disabling `alerting_enabled` is rejected with a conflict (HTTP 409); handle the referencing rules first. In addition, alert evaluation in practice requires the data source to be `enabled=true`.
+- New data sources are enabled; types that support alerting are used for alerting by default, and diagnostic-only types cannot be.
+- Disabling a data source requires manage permission on it.
+- While enabled alert rules still reference a data source, you cannot turn off its "Use for alerting"; deal with those rules first.
## Data source type configuration
@@ -340,26 +281,26 @@ Tencent Cloud CLS requires all Edge instances in the alert engine cluster to run
| **unsupported** | The alert engine is too old to support Tencent Cloud CLS |
| **unavailable** | No registered alert engine was found |
-The same gate applies on the alert rule page: a cluster can degrade later due to a rollback or a newly joined old instance, in which case saving a rule is rejected by the backend even though the data source already exists.
+The same gate applies on the alert rule page: a cluster can degrade later due to a rollback or a newly joined old instance, in which case saving a rule fails even though the data source already exists.
#### Connection Test
After saving the data source, you can use **Connection Test** to verify the connection:
-1. The test is unavailable for a new data source — save it first ("Save the data source before testing the connection").
+1. Save the data source before testing the connection.
2. Pick a region to test against. The data source itself does not store a region, so you pick one at test time.
-3. Click **Test**. The request is routed to a single Edge instance in the selected region, and the result is tagged **Current execution instance only** — it does not mean the whole cluster was verified.
-4. On failure, the result surfaces the raw Tencent Cloud error code and RequestId, which you can use for troubleshooting.
+3. Click **Test**. The test runs on one alert engine instance only, so it does not mean the whole cluster was verified.
+4. On failure, the Tencent Cloud error code and RequestId are shown for troubleshooting.
Results are **Connection is healthy**, **Connected with warnings**, or **Connection failed**.
#### Region Selection
-The region picker, shared by rule queries and the connection test, offers a list of commonly used regions: Guangzhou (ap-guangzhou), Shanghai (ap-shanghai), Beijing (ap-beijing), Nanjing (ap-nanjing), Chengdu (ap-chengdu), Chongqing (ap-chongqing), Hong Kong (ap-hongkong), Singapore (ap-singapore), Bangkok (ap-bangkok), Jakarta (ap-jakarta), Seoul (ap-seoul), Tokyo (ap-tokyo), Silicon Valley (na-siliconvalley), Ashburn (na-ashburn), Frankfurt (eu-frankfurt), Sao Paulo (sa-saopaulo), and Riyadh (me-saudi-arabia). The list is a suggestion, not a whitelist — Tencent Cloud opens new regions from time to time, so you can also type any region code matching `[a-z0-9-]`; Tencent Cloud decides whether it works.
+The region picker, shared by rule queries and the connection test, offers a list of commonly used regions: Guangzhou (ap-guangzhou), Shanghai (ap-shanghai), Beijing (ap-beijing), Nanjing (ap-nanjing), Chengdu (ap-chengdu), Chongqing (ap-chongqing), Hong Kong (ap-hongkong), Singapore (ap-singapore), Bangkok (ap-bangkok), Jakarta (ap-jakarta), Seoul (ap-seoul), Tokyo (ap-tokyo), Silicon Valley (na-siliconvalley), Ashburn (na-ashburn), Frankfurt (eu-frankfurt), Sao Paulo (sa-saopaulo), and Riyadh (me-saudi-arabia). You can also type a region code that is not in the list (such as `ap-xxx`).
#### Rule Binding Constraint
-Alert rules of the Tencent CLS type can bind exactly one data source and do not support name patterns. When creating a rule, the data source picker is single-select and the name-pattern input is hidden; an invalid configuration is rejected on save with "This data source type can bind only one data source" or "This data source type does not support name patterns. Clear them and pick one data source." See [Tencent CLS alert rules](/en/monitors/alert-rules/tencent-cls).
+Alert rules of the Tencent CLS type can bind exactly one data source and do not support name patterns. See [Tencent CLS alert rules](/en/monitors/alert-rules/tencent-cls).
### Redis Node / Redis Sentinel
@@ -385,7 +326,7 @@ Alert rules of the Tencent CLS type can bind exactly one data source and do not
| **Timeout (milliseconds)** | Connection timeout; range 1000–10000 | `3000` |
| **TLS** | Whether TLS is enabled | Disabled |
| **CA certificate** | PEM CA certificates or an `${env:NAME}` reference | - |
-| **Minimum / Maximum TLS version** | The form offers TLS 1.0, 1.1, 1.2 and 1.3 with nothing preselected (both selects are clearable); the server requires a minimum of at least 1.2, so choosing 1.0 or 1.1 is rejected on save; the maximum must not be below the minimum | Empty means 1.2 / no constraint |
+| **Minimum / Maximum TLS version** | The minimum cannot be lower than TLS 1.2, and the maximum cannot be lower than the minimum | Empty means 1.2 / no constraint |
| **Server name** | SNI / certificate hostname for the TLS handshake; defaults to the hostname in the connection address | - |
| **Skip server certificate verification** | Skip server certificate verification when TLS is enabled | No |
@@ -404,13 +345,13 @@ MongoDB does not support client certificate authentication (mTLS).
| **TLS** | Whether TLS is enabled | Disabled |
| **CA certificate** | PEM CA certificates or an `${env:NAME}` reference | - |
| **Client certificate / key** | PEM format; must be configured as a pair; the literal key is not echoed after saving; supports `${env:NAME}` references | - |
-| **Minimum / Maximum TLS version** | The form offers TLS 1.0, 1.1, 1.2 and 1.3 with nothing preselected (both selects are clearable); the server requires a minimum of at least 1.2, so choosing 1.0 or 1.1 is rejected on save; the maximum must not be below the minimum | Empty means 1.2 / no constraint |
+| **Minimum / Maximum TLS version** | The minimum cannot be lower than TLS 1.2, and the maximum cannot be lower than the minimum | Empty means 1.2 / no constraint |
| **Server name** | SNI / certificate hostname for the TLS handshake; defaults to the hostname in the connection address | - |
| **Skip server certificate verification** | Skip server certificate verification when TLS is enabled | No |
### Credential save semantics
-As with Tencent CLS, these 5 diagnostic types treat passwords (and the Kafka client private key) as write-only fields: after saving, neither the list nor the detail returns the literal value. Values saved as `${env:}` references are not secrets and are shown as-is. When updating, omitting the field preserves the saved value; sending an explicit empty string clears it.
+As with Tencent CLS, passwords (and the Kafka client private key) for these 5 diagnostic types are not shown again after saving; values entered as `${env:}` references are shown as-is. Leaving the field empty when editing keeps the saved value.
## Reference credentials locally in Edge
@@ -436,40 +377,22 @@ Environment variable references are not supported in the data-source **address**
## Data source row actions: query and AI analysis
-The operations column of the data source list holds a single primary action button, which branches by data source type:
+Each row's primary action depends on the data source type:
-| Data source type | Primary action | What it does |
+| Data source type | Primary action | Use it to |
|------------------|----------------|--------------|
-| Queryable types: Prometheus, Elasticsearch, Loki, ClickHouse, MySQL, Oracle, PostgreSQL, Aliyun SLS, Tencent CLS, VictoriaLogs | **Query** | Opens the [query workbench](/en/monitors/explore/explore) with this data source attached and an empty query; running one query there verifies the connection and previews results |
-| Diagnostic-only types: `redis_node`, `redis_sentinel`, `mongodb_mongod`, `mongodb_mongos`, `kafka` | **AI analysis** | Opens the AI SRE panel docked on the current page, with this data source passed as a context reference |
-
-### How diagnostic-only types verify their connection
+| Queryable types: Prometheus, Elasticsearch, Loki, ClickHouse, MySQL, Oracle, PostgreSQL, Aliyun SLS, Tencent CLS, VictoriaLogs | **Query** | Open the [Query Workbench](/en/monitors/explore/explore) with this data source selected; running one query verifies the connection |
+| Diagnostic-only types: Redis Node, Redis Sentinel, MongoDB, Kafka | **AI analysis** | Open the AI SRE panel with this data source as context. This is also how you check that such a data source is reachable |
-Diagnostic-only types cannot enter the query workbench, so the list offers no **Query** entry for them and there is no generic connection test button (the Tencent CLS form has its own connection test — see **Connection Test** in the Tencent CLS section above). To confirm such a data source is reachable, use the row's **AI analysis** to hand it to AI SRE and let a diagnostic tool connect once, for example `redis_node.overview`, `redis_sentinel.overview`, `mongodb_mongod.overview` or `kafka.overview`.
-
-### When "AI analysis" appears
-
-- It appears only for types that **cannot enter the query workbench** (the 5 diagnostic-only types listed above); queryable types show **Query** instead, never both.
-- The account must have AI SRE enabled, otherwise the row offers edit and delete only, with no primary action at all.
-- It requires the AI SRE chat permission (`AiSreChatVisit`): without it the button is visible but disabled.
+**AI analysis** requires AI SRE to be enabled on the account and the AI SRE chat permission.
## Edit and delete
- **Edit**: Click the **Edit** button in the data source list to modify the configuration and save.
-- **View**: for a row where you hold readonly permission only, hovering that same edit entry reads **View** and opens a read-only drawer titled **View data source**.
+- **View**: with query permission only, you can view the configuration read-only, with credentials hidden.
- **Delete**: Click the **Delete** button in the data source list and confirm to delete the data source.
-Editing, deleting and toggling all go through the data source `manage` check first: you must be the creator of the data source, the owner account or an Admin, or a member of its managing team; otherwise the request is rejected (`only the managing team can manage this datasource`). The edit drawer loads the data source detail, and the detail returns connection credentials — which is why viewing the credentials, editing, deleting and enabling all sit behind the same gate. See the "Data source permissions (team authorization)" section for the decision rules.
-
-The edit entry itself carries no row-level gate, but it still requires the account permission to edit data sources (`MonitDatasourceUpdate`): without it the entry is disabled as well.
-
-### What the read-only view shows
-
-When you hold readonly permission only on a data source, the console does not drop the entry — it downgrades it to read-only:
-
-- The drawer is titled **View data source**, the whole form is non-editable, and the data source type picker plus the Tencent Cloud CLS connection test are disabled along with it.
-- The basic fields come from the list row; the connection settings render in their usual form layout, but every string field shows `******` (switch, numeric and enum fields are left empty). The read-only view deliberately never calls the data source detail endpoint (that endpoint is gated on `manage`), so real credentials are never sent to the browser.
-- The **OK** button is disabled and the submit path applies the same hard stop; the **Delete** button and the **Enable datasource** switch become disabled controls whose hover card lists who can operate instead (organization admin, creator, managing team).
+Editing, deleting and enabling or disabling require the permission to edit data sources, and you must be the data source's creator, the owner account, an Admin, or a member of its managing team — see [Data source permissions](#data-source-permissions-team-authorization).
<Warning>
Before deleting a data source, ensure no alert rules reference it, otherwise the related alert rules will not execute properly.
diff --git a/en/monitors/engine/engine-lost-alert.mdx b/en/monitors/engine/engine-lost-alert.mdx
index 6337c890..3ed0ccda 100644
--- a/en/monitors/engine/engine-lost-alert.mdx
+++ b/en/monitors/engine/engine-lost-alert.mdx
@@ -14,19 +14,7 @@ For an engine cluster composed of multiple instances, as long as at least one in
## Alert rule list
-The list displays all configured engine disconnection alert rules, with support for keyword search and customizable display columns.
-
-| Column | Description |
-|--------|-------------|
-| **Rule Name** | Name of the alert rule |
-| **Severity** | Critical (red), Warning (orange), Info (yellow) |
-| **Include Pattern** | Engine cluster name patterns to monitor; supports wildcard `*` |
-| **Exclude Pattern** | Engine cluster name patterns to exclude from monitoring |
-| **Lost Duration (seconds)** | Triggers an alert after the engine cluster has no heartbeat for this duration |
-| **Channel** | The channel where alert events are delivered |
-| **Trigger Count** | Maximum number of alert events to generate during disconnection |
-| **Trigger Interval (seconds)** | Time interval between repeated alert event generation |
-| **Enabled** | Enable/disable toggle for the rule |
+The list shows the configured rules and their main parameters (see [Create an alert rule](#create-an-alert-rule) for what each means). You can search by keyword, customize the displayed columns, and enable or disable a rule with its switch.
## Create an alert rule
@@ -75,6 +63,4 @@ Select the channel where alert events should be delivered. Alert events are proc
## Edit and delete
-- **Edit**: Click the **Edit** button in the list to modify rule configuration. Only the rule creator, primary account, or admin roles can edit.
-- **Delete**: Click the **Delete** button in the list. Only the rule creator, primary account, or admin roles can delete.
-- **Enable/Disable**: Quickly toggle the rule status using the switch in the list.
+Click **Edit** or **Delete** in the list to modify or delete a rule. Only the rule creator, the primary account, or admin roles can edit or delete rules.
diff --git a/en/monitors/engine/engine.mdx b/en/monitors/engine/engine.mdx
index db9993bb..cec68562 100644
--- a/en/monitors/engine/engine.mdx
+++ b/en/monitors/engine/engine.mdx
@@ -126,7 +126,7 @@ The `monitedge` binary is configured via command-line flags. The following flags
| Flag | Default | Description |
|------|---------|-------------|
-| `alerter.serverURL` | `https://api.flashcat.cloud` | FlashDuty SaaS endpoint address |
+| `alerter.serverURL` | `https://api.flashcat.cloud` | Flashduty SaaS endpoint address |
| `alerter.serverAPIKey` | — (required) | API Key used to authenticate with the SaaS |
| `alerter.serverTimeout` | `30s` | Per-request timeout for a single push attempt |
| `alerter.alertRuleDeliveryWorkers` | `64` | Number of delivery workers for ordinary alert rule events. Events are partitioned to per-worker queues by alert key, so events of the same alert are always delivered serially by the same worker |
diff --git a/en/monitors/entity-tree/entity-tree.mdx b/en/monitors/entity-tree/entity-tree.mdx
index 91ebd4fb..0294af63 100644
--- a/en/monitors/entity-tree/entity-tree.mdx
+++ b/en/monitors/entity-tree/entity-tree.mdx
@@ -59,7 +59,7 @@ If the alert engine version is incompatible, the page prompts you to upgrade and
### 1. Request access
-Go to **Monitors > Entity Tree**. If Entity Tree is not enabled for the account, click **Request access**. The page shows the submission time while the request is pending. You can start configuring Entity Tree after approval.
+Go to **Monitors → Entity Tree**. If Entity Tree is not enabled for the account, click **Request access**. The page shows the submission time while the request is pending. You can start configuring Entity Tree after approval.
### 2. Create an entity definition
diff --git a/en/monitors/explore/explore.mdx b/en/monitors/explore/explore.mdx
index 49d172a7..d174ef50 100644
--- a/en/monitors/explore/explore.mdx
+++ b/en/monitors/explore/explore.mdx
@@ -9,7 +9,7 @@ The Query Workbench (Explore) is an ad-hoc query interface in Flashduty Monitors
## Access
- **From the data source list**: Go to **Monitors → Data Sources** and click the "Query Workbench" entry on the target data source row.
-- **Direct URL**: Navigate to `/monit/explore` and select a data source in the page.
+- **Directly**: open the Query Workbench and select a data source on the page.
- **From incident/alert labels**: In the label area of incident or alert detail, the "Explore" icon on query-type label rows opens the workbench with the alert's triggering query and time window pre-filled.
## Query Types
@@ -29,7 +29,7 @@ Different data sources support different query types, switched above the editor:
| SLS / CLS | — | No query type selector; vendor-classified logs/tables |
| MySQL / PostgreSQL / Oracle / ClickHouse / ES | — | SQL/query expression executed directly |
-> Before a query is routed to Edge for execution, it goes through a syntax check: Prometheus data source expressions must pass a PromQL/MetricsQL syntax validation — invalid expressions are rejected upfront with the parser error detail and are never sent for execution. Other data source types are not affected by this check.
+> Prometheus queries are syntax-checked as PromQL / MetricsQL first; an invalid expression returns the error detail without running.
## Result Display
@@ -38,13 +38,13 @@ The result area auto-layouts based on data source and query type:
- **Prometheus**: Split pane — line chart (Graph) on top, raw samples (Raw) below, with a draggable splitter.
- **Other data sources**: Single result pane showing log view, table view, or samples view depending on the query type.
-The samples view and table view paginate in the browser instead of rendering all rows at once: the samples view shows 20 rows per page; the table view defaults to 100 rows per page with options of 100 / 200 / 500. The paginator is hidden when the results fit in a single page.
+The samples view shows 20 rows per page; the table view shows 100 rows per page by default, or 200 or 500.
### Graph Features
- **Drag-to-zoom**: Drag-select a time range on the chart to zoom in.
-- **Legend facet filtering**: The legend area supports filtering by label-value dimension and searching by keyword, grouped by metric name; a keyword search box appears once there are more than 10 series, the legend is capped at 45% of the panel height, and the rows beyond that scroll.
-- **Tooltip**: Hovering shows the value and label of the single series nearest the cursor at that time point; move the cursor along the time axis to step through the others. To compare several series at once, use the legend filters or switch to the raw data.
+- **Legend facet filtering**: filter by label value and group by metric name; with more than 10 series you can also search by keyword.
+- **Tooltip**: shows the value and labels of the series nearest the cursor. To compare several series at once, use the legend filters or the raw data.
### Log Time Distribution
@@ -56,15 +56,14 @@ When the query type includes logs, a log time distribution chart appears above t
### Log View
-Log-type query results are displayed row by row; each row contains the timestamp, body, and a field summary. If a batch of results contains fields whose value is identical in every row (common fields, such as Loki's stream labels), these fields are shown in the summary on every row by default, but they take up width on each row repeatedly.
+Logs are shown row by row, each with the timestamp, body and a field summary.
-- The **Common Fields** button on the toolbar lists the fields that are identical across every row in the current batch, with their values; after checking **Hide Inline** in the popover, these common fields are collapsed out of the inline summary, and each row keeps only the content that differs (with a "+N fields" hint displayed)
-- **Hide Inline** is off by default (common fields are shown by default); the toggle is session state, not persisted — refreshing the page restores the default
-- Clicking a row expands its details; the details always show all fields of that row, unaffected by the **Hide Inline** toggle
+- Click **Common Fields** on the toolbar to see fields that are identical in every row of the batch (such as Loki stream labels); tick **Hide Inline** to stop repeating them on each row. Refreshing the page shows them again.
+- Click a row to expand all of its fields.
### Query Failure Hints
-When a query fails, the result area shows a hint matched to the failure reason (such as query timeout, result row limit exceeded, or Edge version too low). Among these, a data-source-level authorization denial (HTTP 403, error code `AccessDenied`) shows a dedicated hint — "You don't have access to this data source. Please contact the team responsible for the data source or an administrator." — instead of the generic "Query failed, please try again later." For team-based data source authorization rules, see [Data source permissions (team authorization)](/en/monitors/data-sources/data-sources#data-source-permissions-team-authorization).
+When a query fails, the result area explains why, such as a timeout, too many result rows, or an outdated alert engine version. If you cannot query the data source, see [Data source permissions](#data-source-permissions).
## Query Parameters
@@ -83,54 +82,44 @@ In addition to the query expression, some data sources support private parameter
### Built-in Time Variables
-Prometheus and Loki queries support built-in time variables: before the query runs, each variable is rendered into a concrete duration from that query's own time window and step, so the query follows the time range you select on the page without hard-coding any time. Write a variable with a leading `$`, or in the `${...}` form.
+Prometheus and Loki range queries can use built-in time variables so the query follows the time range you select instead of hard-coding it. Write them as `$__interval` or `${__interval}`.
-| Variable | Rendered value |
+| Variable | Meaning |
|----------|----------------|
-| `$__interval` | The step of this query in seconds, for example `30s`; it is the same step that is sent to Edge — the larger of the value the backend derives from the data point count and **Min step** |
-| `$__rate_interval` | The step plus 15 seconds, and never below 60 seconds, for example `60s`; 15 seconds is the scrape interval `$__rate_interval` assumes |
-| `$__range` | The length of this query's time window in seconds, with a minimum of 1 second, for example `3600s` |
-| `$__auto` | In a Loki range query, the step (for example `30s`); in a Loki instant query it would be the whole time window in the largest unit that divides it (for example `1h`), but instant queries carry no start time, so it is not usable (see below) |
+| `$__interval` | The query step, e.g. `30s`, never below **Min step** |
+| `$__rate_interval` | The step plus 15 seconds, at least 60 seconds; ready for `rate()` |
+| `$__range` | The length of the time window, e.g. `3600s` |
+| `$__auto` | In Loki range queries, the same as the step |
-Availability depends on both the data source and the query type:
-
-| Query | Available built-in time variables |
+| Query | Available variables |
|-------|----------------------------------|
-| Prometheus range (**Graph only**, and the graph half of **Graph + Raw**) | `$__interval`, `$__rate_interval`, `$__range` |
-| Prometheus instant (**Raw only**, and the raw half of **Graph + Raw**) | none |
+| Prometheus range (**Graph only**) | `$__interval`, `$__rate_interval`, `$__range` |
| Loki range | `$__auto`, `$__interval`, `$__range` |
-| Loki instant | none |
+| Prometheus / Loki instant queries | none |
-- No built-in time variable works in an instant query: a Prometheus instant query accepts no range variable, and a Loki instant query carries no start time, so window-length variables such as `$__auto` and `$__range` cannot be rendered. If you write one, the result area shows "The query or its parameters are invalid. Check them and retry." with the backend reason below it (for example `built-in variable "__rate_interval" is not available in prometheus instant queries`, `built-in variable "__range" requires from_ms`).
-- Prometheus's default **Graph + Raw** query type sends one range query and one instant query that share the same statement: `$__rate_interval` renders on the graph half and fails on the raw half. To use `$__rate_interval` in this query type, switch the query type to **Graph only**.
-- Built-in time variables share their names with the dashboard built-in time variables and are computed by the same rendering logic from this query's time window and step. Apart from the variable names in the table above, any other `$` text — including `${name}` and regex capture-group references such as `$1` — is sent to the data source verbatim and is not substituted, because the workbench has no dashboard variables.
+- Using these variables in an instant query returns an error.
+- Prometheus's default **Graph + Raw** runs a range and an instant query together, so `$__rate_interval` fails in its instant half. Switch to **Graph only** to use it.
+- These variables mean the same as their namesakes in [dashboards](/en/monitors/dashboards/dashboards#built-in-time-variables). The workbench has no dashboard variables, so any other `$` text is sent to the data source as is.
## AI Query Assistant
-The query editor input has a rainbow **Write with AI** button in its top-right corner that fades in on hover or focus (select a data source first). Clicking it opens the **Query Assistant** panel, which can see the current data source, query type, private parameters, and time window, plus how the query will actually run (instant / range / range+instant / window; Prometheus's default **Graph + Raw** mode runs one range query and one instant query, which is `range+instant`), and generates or rewrites the query statement accordingly.
+With a data source selected, click **Write with AI** at the top right of the query input. The Query Assistant uses the current data source, query type, parameters and time range to generate or rewrite the query.
-- The result is applied automatically and as a whole: statement, private parameters, and query type are written back together. If the data source chosen by the assistant differs from the current one, the workbench switches to it first, clears the current results, and remembers it as the default data source for your next visit.
-- When the result is delivered, the query runs once automatically and its results appear below. The **Apply** button on the result card re-applies that version without running it; press Enter or click **Run query** to execute it manually afterwards.
-- Applying overwrites the statement currently in the editor and merges the assistant’s private parameters into the existing ones (parameters it does not return keep their current values), so review the result before continuing or sharing.
+- The assistant fills in the statement, parameters and query type together and runs the query once. If it chooses a different data source, the workbench switches to it.
+- Click **Apply** on a result card to put that version back into the editor (without running it).
## Query History
-Each successful query is automatically saved to query history, which stores only the query expression — not the time range or results. History is isolated per data source, stored in the browser locally, and retains up to 200 entries. When the limit is exceeded, the oldest entry is evicted. Oversized query expressions are not saved to history but the query itself still succeeds. You can delete individual entries or clear all history for the current data source from the history panel.
+Successful queries are saved to query history (expressions only). History is kept per data source in this browser, up to 200 entries each; you can delete entries or clear it.
## Sharing and URL State
-The workbench encodes the current data source, query expression, time range, and query type into URL parameters. Copy the browser address bar to share the current query state — opening the link restores it automatically. If the data source in the link doesn't exist, is disabled, or the user lacks permissions, the page prompts and does not auto-execute.
-
-## Data Source Permissions and Denials
-
-The workbench's data source options include only data sources you have query (readonly) permission on; a data source you may not query never appears as a candidate and its contents cannot be read (see "Data source permissions (team authorization)" in [Data source management](/en/monitors/data-sources/data-sources) for the authorization model).
-
-When a query is stopped by data source authorization on the server (HTTP 403, error code `AccessDenied` — for instance when permissions changed after the page was opened), the workbench does not fall back to the generic query-failure hint but states:
+The current data source, query, time range and query type are kept in the page address, so copying it shares your query. If the link's data source does not exist, is disabled, or you lack access, the query does not run automatically.
-> No access to this data source. Contact the data source's managing team or an administrator.
+## Data Source Permissions
-The result area also shows the raw backend message and the RequestId of that request for troubleshooting. To restore access, ask the data source's managing team or an administrator to adjust that data source's **Managing team** and **Query-allowed teams** on the data source management page.
+Only data sources you can query appear in the list. If a query reports that you have no access to the data source (for example because permissions changed after you opened the page), ask the data source's managing team or an administrator to adjust its **Managing team** and **Query-allowed teams** — see [Data source permissions (team authorization)](/en/monitors/data-sources/data-sources#data-source-permissions-team-authorization).
## Edge Version Requirements
-The Query Workbench relies on monit-edge to execute queries. If the Edge version in the data source's cluster is too low or versions are mixed, the page shows an upgrade prompt and disables querying. All Edge instances in the cluster must be upgraded to the required version before use.
+Queries run on the data source's alert engine (Edge). If the cluster's Edge version is too low or versions are mixed, the page asks you to upgrade; once every Edge in the cluster is upgraded you can query.
diff --git a/en/monitors/faq/faq.mdx b/en/monitors/faq/faq.mdx
index 7fb6f59c..189908b0 100644
--- a/en/monitors/faq/faq.mdx
+++ b/en/monitors/faq/faq.mdx
@@ -5,7 +5,7 @@ description: "Monitors frequently asked questions"
---
<AccordionGroup>
-<Accordion title="Alert rule execution is not as expected, how to debug?">
+<Accordion id="debug-rule" title="Alert rule execution is not as expected, how to debug?">
On the alert rules list page, there is a **Debug Log Switch** that you can enable. Afterwards, the alert engine process `monitedge` will output detailed execution logs for that rule, making it easier to troubleshoot.
`monitedge` outputs logs to standard output (`stdout`). The viewing method depends on the deployment method:
@@ -21,33 +21,39 @@ On the alert rules list page, there is a **Debug Log Switch** that you can enabl
</Note>
</Accordion>
-<Accordion title="What information does the overview dashboard display?">
+<Accordion id="overview-dashboard" title="What information does the overview dashboard display?">
**Menu Entry**: Overview
The overview page provides a global view of alert rules, consisting of the following cards:
| Card | Description |
|------|-------------|
-| **Alert rule total trend** | An area chart showing how the total number of alert rules changes over time. The x-axis represents dates and the y-axis represents rule count, helping you track overall growth or reduction trends |
-| **Alert rules by channel** | A pie chart showing the distribution of alert rules across channels. The top 10 channels are displayed by default; the remainder are aggregated as "Others." You can click to expand and view all details |
-| **System event list** | Displays system events generated by the alert engine (such as engine disconnection, configuration anomalies, etc.), with pagination and delete support, helping you promptly discover and address infrastructure-level issues |
+| **Alert rule total trend** | Total number of alert rules over time (area chart) |
+| **Alert rules by channel** | Alert rules per channel (pie chart). Shows the top 10 by default, with the rest grouped as "Others"; click to expand |
+| **System event list** | System events from the alert engine (such as engine disconnection or configuration anomalies); paginated, and you can delete them |
<Tip>
The overview page checks whether you have installed an alert engine. If not, a prompt guides you to the alert engine page to complete installation.
</Tip>
</Accordion>
-<Accordion title="How do I quickly clone an alert rule?">
+<Accordion id="clone-rule" title="How do I quickly clone an alert rule?">
On the alert rule edit or detail page, you can find the **Clone** action button. Clicking it creates a new rule based on the current rule's configuration, with all settings copied over (except the name), making it easy to quickly create similar alert rules.
</Accordion>
-<Accordion title="How do I preview query results for an alert rule?">
+<Accordion id="preview-query" title="How do I preview query results for an alert rule?">
When creating or editing an alert rule, after configuring the query conditions, you can click the **Query Preview** button. The system immediately executes a query and displays the results, helping you verify whether the query expression is correct and whether the returned data meets expectations, without waiting for the next detection cycle.
-If the backend returns an unrecognized result format, the preview shows a hint that the frontend and backend versions may be out of sync and to contact the administrator. When debug arguments (debug JSON) for SLS / VictoriaLogs / Loki are invalid or contain nested structures, the preview aborts the query with an error ("Invalid JSON format" / "Nested structures are not supported") instead of silently ignoring them. If the data source returns an authorization denial (HTTP 403, error code `AccessDenied`), the preview shows a fixed hint: "You don't have access to this data source. Please contact the team responsible for the data source or an administrator." Check the data source's authorization configuration in [Data source permissions (team authorization)](/en/monitors/data-sources/data-sources#data-source-permissions-team-authorization).
+If the preview fails, common causes are:
+
+| Message | Cause and fix |
+| --- | --- |
+| Unrecognized result format | The frontend and backend versions may be out of sync; contact your administrator |
+| Invalid JSON format / Nested structures are not supported | The debug arguments (debug JSON) for SLS / VictoriaLogs / Loki are invalid or nested; fix them and retry |
+| No access to this data source | The data source denied authorization (HTTP 403). Check its authorization in [Data source permissions (team authorization)](/en/monitors/data-sources/data-sources#data-source-permissions-team-authorization), or contact the team that owns it |
</Accordion>
-<Accordion title="What format does the alert rule notes description support?">
+<Accordion id="notes-format" title="What format does the alert rule notes description support?">
The notes description supports Markdown format. You can use headings, lists, links, code blocks, and other Markdown syntax to organize content. It also supports variable references, embedding dynamic information such as alert event label values and query results into the notes, making it convenient for responders to quickly understand the alert context.
</Accordion>
</AccordionGroup>
diff --git a/en/monitors/quickstart/quickstart.mdx b/en/monitors/quickstart/quickstart.mdx
index b5e9880c..051ad625 100644
--- a/en/monitors/quickstart/quickstart.mdx
+++ b/en/monitors/quickstart/quickstart.mdx
@@ -66,7 +66,7 @@ For an engine cluster composed of multiple instances, as long as at least one in
There may be many alert rules. Monitors provides a tree-structured grouping for categorized management. Each alert rule must belong to a group. You can create groups first, then create alert rules under the groups.
-The create/edit alert rule page is a single-page form divided into five numbered sections — **Basic Configuration**, **Data Sources and Queries**, **Alert Conditions**, **Detection Frequency & Effective Time**, and **Event Configuration** — arranged top to bottom, so you fill them in by scrolling a single page; there is no step wizard.
+The create / edit alert rule page is a single form with five sections, top to bottom: **Basic Configuration**, **Data Sources and Queries**, **Alert Conditions**, **Detection Frequency & Effective Time**, and **Event Configuration**.
### Basic Configuration
@@ -74,7 +74,7 @@ The create/edit alert rule page is a single-page form divided into five numbered
| Config Item | Description |
|--------|------|
-| **Group** | Shows the group the rule belongs to as a breadcrumb path (e.g., "Default / Database Alerts"). When the group is unavailable (deleted, or you don't have permission for it), the panel turns red and shows "This group is unavailable. Return to the alerting rule list and select it again." — go back to the alert rules list and select a group again |
+| **Group** | The group path of the rule (e.g., "Default / Database Alerts"). If the group has been deleted or you cannot access it, go back to the rule list and pick a group again |
| **Rule Name** | Name of the alert rule; does not support variable references (fixed names facilitate filtering and grouping operations). It must be unique within its group; imports, edits, and moves fail if the target group already contains that name |
| **Additional Labels** | Similar to `labels` in Prometheus; attached to all alert events for filtering, routing, and inhibition |
@@ -86,64 +86,55 @@ Section 2 has two parts: **Data Sources** decides which data sources the rule ap
-To the right of the sub-heading there is a hint icon explaining the scope of the binding, plus a **Go to Data Source Management** entry — it opens in a new tab so unsaved edits in the current form are not lost.
+First choose a **data source type**. Only types that already have data sources are listed; if you have none yet, click **Go to Data Source Management** (it opens in a new tab, so your form is kept) to create one.
-First choose a **data source type**. Only types that **already have at least one configured data source** are listed here — types with none don't appear, so you can't end up picking a type with no data sources to query. When you're editing an existing rule, its current type always stays visible, even if all the data sources under that type have since been deleted.
+Then choose which data sources the rule applies to — one rule can cover many:
-If the list is empty (showing "No data sources available"), your account hasn't configured any data sources yet — click **Go to Data Source Management** to create one first. If only the selected type has none, the page shows "The current data source type has no available data sources. Create one or switch type." If the type list fails to load, a **Reload** button appears.
+- **Wildcard by name**: matches by name and defaults to `*` (every data source of the type) for a new rule. `*` matches any string (e.g. `db-*`), `?` matches one character, `[0-9]` or `[a-z]` match a range, and `[!0-9]` matches characters outside it. Renaming a data source affects matching.
+- **Exact match by ID**: pick specific data sources from the list; unaffected by renames.
-After choosing a type, Monitors supports a single rule applying to multiple data sources with two binding methods:
-
-- **Wildcard by name**: Match data sources by name using wildcards. `*` matches a string of any length (`*` matches all data sources; `db-*` matches all data sources starting with `db-`), and `?` matches any single character. Character classes are also supported, e.g. `db-[0-9]` matches `db-0` through `db-9` and `svc-[a-z]` matches `svc-a` through `svc-z` (character ranges compare by Unicode code point), while `[!0-9]` matches any non-digit character. Stores name strings, so renaming a data source affects matching.
-- **Exact match by ID**: Select specific data sources from a dropdown by ID. Unaffected by data source renames.
-
-Both methods can be used together, and at least one must be specified. The rule applies to all data sources matched by either method.
-
-When you create a rule — and each time you switch the **data source type** card afterwards — **Wildcard by name** is pre-filled with `*`, so by default the rule applies to every data source of that type. The one exception is Tencent CLS: it can only bind a single data source by exact match, the form never offers a pattern value for it, and saving requires exactly one selection. In the pattern selector `*` is mutually exclusive with the other entries: choosing `*` clears the rest, and choosing anything other than `*` drops the `*`. If both methods are left empty, saving fails with "Name pattern and exact match cannot both be empty".
+Use at least one method, or both; the rule applies to the union of their matches. Tencent CLS is the exception: it binds exactly one data source by exact match.
<Tip>
If you need stable rule bindings that are unaffected by data source renames, prefer exact match. See [Data Source Management](/en/monitors/data-sources/data-sources) for details.
</Tip>
<Note>
-**Saving a rule also requires query rights on the data sources it references.** Except for the account subject and Admin, creating a rule, editing a rule, and batch field updates (including batch edits of custom fields and additional labels) all require the author to have query (readonly) rights on every data source the rule references — both the data sources picked explicitly under **Exact match by ID** and those matched by **Wildcard by name** at the moment of saving — so a wildcard rule can fail to save because of a data source you never picked explicitly. If any referenced data source is not permitted, create/edit fails outright with `no permission to reference datasource "<name>"`; in a batch field update that rule is reported as its own failure while the others still update (the toast reads e.g. "2 / 10 rules failed to update. First error: ...").
-
-**Pure disable is the only exempt operation**: merely disabling a rule (the enable switch in the list, or batch disable — both boil down to "only `enabled` changes") is not checked against data source rights, so a member who lost data source access can still turn a rule off; re-enabling it or changing any other field is checked as usual. For how data source access itself is granted (who can query, who can manage), see [Data Source Management](/en/monitors/data-sources/data-sources).
+To save a rule you need query permission on every data source it references, including those matched by a wildcard at save time (the owner account and Admins excepted). A wildcard rule can therefore fail to save because it matches a data source you cannot query. Disabling a rule is exempt. See [Data Source Management](/en/monitors/data-sources/data-sources#data-source-permissions-team-authorization) for data source authorization.
</Note>
#### Query Statements
-Under the **Query Statements** sub-heading you configure the query type and the statements themselves. To the right of the sub-heading is the **Usage guide** entry, which opens a drawer titled "Query Statements" with the guide to writing statements. For how value fields, label fields, and additional information are mapped from tabular query results, see [Query result field mapping](/en/monitors/alert-rules/query-result-fields).
+Configure the query type and statements. Click **Usage guide** for help writing them. For how value fields, label fields, and additional information are mapped from tabular query results, see [Query result field mapping](/en/monitors/alert-rules/query-result-fields).
#### AI Query Assistant
-Every query statement input has a rainbow **Write with AI** button in its top-right corner. It fades in on hover or focus, and appears once a data source type is selected. Clicking it opens the **Query Assistant** panel, which reads the current rule context — the data source, query type, configured alert thresholds, and the other query statements — to generate or rewrite the current query.
+Once a data source type is selected, click **Write with AI** at the top right of a query input. The Query Assistant uses the rule's data source, query type, thresholds and other queries to generate or rewrite the statement.
-- The generated statement is written back into the input together with data source private parameters (such as the SLS project/logstore, Tencent CLS region/topic, or the Loki and VictoriaLogs result limit), and the field is re-validated immediately, so the required-field error clears along with it. The **Apply** button on the result card re-applies that version of the statement at any time.
-- The entry is available on the main query, the recovery queries for threshold and data-exists modes, related queries, the query preview dialog, and the entity tree's rule PromQL and entity-category discovery PromQL. In the entity tree, the assistant only writes back the statement and never switches the data source.
-- Applying a statement changes the current form only; the rule is not saved automatically. Confirm that the statement matches the alert thresholds before saving.
+- The statement and related parameters (such as the SLS project / logstore or Tencent CLS region / topic) are filled into the form; click **Apply** on a result card to fill it in again.
+- The assistant is available for main queries, recovery queries, related queries, the query preview, and PromQL in the entity tree.
+- Applying does not save the rule; check that the statement matches the thresholds before saving.
### Alert Conditions
-Section 3 offers three check modes, presented as tabs: **Threshold evaluation**, **Missing data**, and **Data exists**. The enable switches are not on the tab titles but on the right of each enabling card inside the tab: on **Threshold evaluation** it is the "When higher-level threshold triggers, lower-level thresholds are skipped" card, and on **Data exists** it is the "Alert when data is found" card; **Missing data** has two cards you can enable independently — "Alert when all queries return no data" and "Alert if previously found data is now missing" — so that tab has two switches. The tabs still mark their state: once any condition in a tab is enabled, a check mark appears after the tab title.
+Alert Conditions offers three check modes, one per tab; enable each with the switch on the card title inside the tab. Enabled tabs show a check mark.
+
-| Tab | What it evaluates |
|-----|-------------------|
-| **Threshold evaluation** | Set a threshold expression per level; once a condition is met for the required number of checks, an alert of that level fires. When a higher-level threshold triggers, lower-level thresholds are skipped. With this tab enabled, at least one of Critical, Warning, and Info must be filled in |
-| **Missing data** | Evaluates "alert if previously found data is now missing" or "alert when all queries return no data"; the two cards can be enabled independently |
+| **Threshold evaluation** | Set a threshold expression per level; once a condition is met for the required number of checks, an alert of that level fires. Once a higher level fires, lower levels are skipped. Fill in at least one of Critical, Warning and Info |
+| **Missing data** | Alerts when "previously found data is now missing" or "all queries return no data"; the two conditions can be enabled separately |
| **Data exists** | Any returned data counts as a match; once the trigger count is reached, an alert of the configured level fires |
-The settings are grouped into cards: except on the **Missing data** tab, each tab has an **Alert fired** card and an **Alert recovered** card; the **Missing data** tab merges both into a single **Trigger & recovery conditions** card that applies to all enabled conditions above. The rows inside these cards are:
+Each tab has an **Alert fired** card and an **Alert recovered** card (**Missing data** combines them into one **Trigger & recovery conditions** card). Key fields:
| Field | Description |
|-------|-------------|
| **Trigger mode** | `Consecutive` or `Cumulative`; see the next section |
-| **Trigger condition** | The sentence matching the trigger mode. On the **Threshold evaluation** tab, the level expression rows (`Critical` / `Warning` / `Info`) sit above the trigger mode and are the trigger condition itself |
-| **Alert level** | `Critical`, `Warning`, or `Info`; defaults to `Critical`. The **Threshold evaluation** tab has no such row — the level comes from whichever expression row matched; on the **Data exists** and **Missing data** tabs it is set per condition |
-| **Recovery mode** | Sits in the **Alert recovered** card; on the **Missing data** tab it is set per condition — see the end of this section |
-| **Recovery condition** | **N consecutive normal checks to recover**, defaults to 1. At 1, a single check that meets the recovery condition produces a recovery event; above 1, several consecutive normal checks are required |
+| **Alert level** | `Critical`, `Warning`, or `Info`; defaults to `Critical`. For threshold evaluation, the level comes from the expression that matched |
+| **Recovery mode** | See [Alert recovery](#alert-recovery) below |
+| **Recovery condition** | Recover after N consecutive normal checks; defaults to 1 |
#### Trigger mode: consecutive vs cumulative
@@ -152,12 +143,10 @@ The settings are grouped into cards: except on the **Missing data** tab, each ta
| **Consecutive** (default) | Alerts after the set number of consecutive matches | `alert after N consecutive checks all match` — the rule alerts only after N consecutive checks meet the condition, where N is the **Matches** count, default 3 |
| **Cumulative** | Alerts when enough of the last checks match, even if not consecutive | `alert once N of the last M checks match` — the rule alerts when N of the last M checks meet the condition, where M is the **Checks** count, defaulting to `max(Matches, 5)` when you switch to cumulative |
-- Under **Cumulative**, the match count cannot exceed the check count, and the check count cannot be lower than the match count. Neither can exceed 10000; going over is reported as a validation error rather than being silently clamped to the maximum
-- The two modes are mutually exclusive: after switching back to **Consecutive**, the check count is no longer submitted with the rule (the server tells the modes apart by whether that field is present), so the "N of the last M checks" semantics cannot linger
-- The underlying rule fields: match count `alerting_check_times`, check count `alerting_window_size`, recovery condition `recovery_check_times`
+- Under Cumulative, the match count cannot exceed the check count, and neither can exceed 10000
<Note>
-**Cumulative matching requires alert engine ≥ `v0.69.0`.** When you select **Cumulative**, a "Supported in v0.69.0+" badge appears next to the option. Older engines fall back to consecutive matches, which may delay or miss alerts, but never fires earlier than the new semantics.
+**Cumulative matching requires alert engine `v0.69.0` or later.** Older engines evaluate it as consecutive matching, so alerts may be delayed or missed.
</Note>
#### Alert recovery
@@ -172,18 +161,14 @@ The available recovery modes depend on the check mode:
### Detection Frequency and Effective Time
-This section is always visible: there is no one-line summary and no expand/collapse control — the detection frequency, query time offset, rule timezone, and effective time fields are laid out directly in the section.
-
-When you click save, if a field fails validation the page scrolls to and highlights the first invalid field: if the error is inside a tab of **Alert Conditions**, that tab is activated first, and if it is inside **Custom Fields & Related Queries** in **Event Configuration**, that area is expanded first.
-
| Config Item | Description |
|--------|------|
-| **Detection Frequency** | Usually periodic detection; also supports `cron` expressions (down to seconds) and the `@every` shorthand. A new rule defaults to `@every 15s`; the dropdown presets are `@every 15s`, `@every 30s`, `@every 45s`, `@every 60s`, `@every 120s`, `@every 150s`, `@every 180s`, and `@every 300s`, and you can type any other valid expression |
+| **Detection Frequency** | Usually periodic detection; also supports `cron` expressions (down to seconds) and the `@every` shorthand. Defaults to `@every 15s`; pick a preset from the dropdown or type your own |
| **Query Time Offset** | Sets the query time offset (in seconds) to handle data source ingestion lag. For example, setting it to 60 shifts the query window back by 60 seconds, ensuring data has been fully written before querying. Only applies to Prometheus, Loki, VictoriaLogs, SLS, and Tencent CLS data sources |
| **Rule Timezone** | The timezone in which the rule executes. It controls how `cron` schedules and **Effective Time** windows are interpreted. Defaults to `Asia/Shanghai`. Must be a valid IANA timezone name such as `Asia/Shanghai`, `UTC`, `Europe/London`, or `America/New_York` |
-| **Effective Time** | Time period when the alert rule is effective; alerts will not trigger outside this period. Time windows are evaluated in the **Rule Timezone** above. It is a list of addable and removable time windows: each row is a **weekday** multi-select (any of Monday through Sunday) plus a **start time** and an **end time** (both `HH:mm`), and all three are required. A new rule starts with one row covering all 7 days, `00:00`–`23:59`, that is, all day. The **Add active period** button adds a row and the delete button at the end of each row removes one (both are unavailable when viewing rule details) |
+| **Effective Time** | Time period when the alert rule is effective; alerts will not trigger outside this period. Time windows are evaluated in the **Rule Timezone** above. You can add several windows, each made of weekdays (multi-select) and a start / end time (`HH:mm`). Defaults to all day, every day |
<Warning>
**Timezone rules**:
@@ -195,16 +180,16 @@ When you click save, if a field fails validation the page scrolls to and highlig
- `cron` expressions must be **6-field second-level expressions**, in the order seconds, minutes, hours, day of month, month, day of week. 5-field forms (for example `*/5 * * * *`) are rejected; add the seconds field (for example `0 */5 * * * *`).
- The `@every` shorthand is supported, for example `@every 30s` for a check every 30 seconds. The duration must be a **whole number of seconds of at least 1 second**; combined durations such as `@every 1m30s` are accepted, while `@every 0s`, `@every 1500ms`, or any sub-second or non-whole-second value is rejected.
-- The detection frequency is validated when editing an existing rule as well; historically saved invalid expressions must be fixed before the rule can be saved.
+- When editing an older rule, a detection frequency that does not follow these rules must be fixed before saving.
</Warning>
<Note>
-Saving a rule also validates its runtime configuration: the repeat notification **maximum count** (`repeat_total`) and **repeat interval** (`repeat_interval`), as well as the **alerting check times** and **recovery check times** of every check mode (Threshold, Data exists, No data), must all be ≥ 1. A rule that fails validation is not scheduled, and the alert engine reports the failure as an `alert-rule-schedule-invalid` problem. Fix the rule configuration according to the error message.
+The repeat notification maximum count and interval, and the match and recovery counts of every check mode, must all be at least 1; otherwise the rule does not run.
</Note>
### Event Configuration
-Section 5 contains, in order, **Custom Fields & Related Queries** (collapsed by default, with Expand / Collapse on the right; while collapsed the summary line shows how many custom fields and related queries are configured, or a hint line when there are none), the notes description, and the repeat notification settings.
+Event Configuration covers **Custom Fields & Related Queries** (collapsed by default), the notes description, and repeat notification settings.
| Config Item | Description |
|--------|------|
@@ -252,7 +237,7 @@ When the state is `Waiting for first run` or `Status stale`, the page explains w
Query the rule's historical execution records by time range (last 15 minutes, 1 hour, 4 hours, or 1 day; up to 24 hours back). Each record carries an execution summary badge: `Execution failed`, `Event produced`, `Alert recovered`, or `Periodic sample`. Expanding a record shows the log ingestion time, Edge instance and cluster, runtime phase, consecutive failures, active instance counts per check mode, events produced, and the error summary.
<Note>
-Execution history depends on server-side VictoriaLogs queries: if the server has not configured a query endpoint or the query service is unavailable, the panel shows "Execution history temporarily unavailable". Records only capture key execution summaries (errors, events, recoveries, and periodic samples) — not every evaluation is guaranteed to produce a record. When more than 200 records match, only the latest 200 are shown; narrow the time range to see more.
+Execution history only records key execution summaries (errors, events, recoveries, and periodic samples) — not every evaluation is guaranteed to produce a record. When more than 200 records match, only the latest 200 are shown; narrow the time range to see more.
</Note>
## Batch operations
@@ -274,7 +259,7 @@ After selecting multiple rules, click **Batch Update** to uniformly modify the f
| **Detection Frequency** | Uniformly adjust the detection period |
| **Rule Timezone** | Uniformly switch the IANA timezone of the alert rule |
| **Effective Time** | Uniformly configure effective time periods |
-| **Query Time Offset** | Uniformly set the query time offset. Batch update is available only when the data sources of all selected rules support query time offset (Prometheus, Loki, VictoriaLogs, SLS, and Tencent CLS); otherwise this option is disabled |
+| **Query Time Offset** | Uniformly set the query time offset. Available only when all selected rules use data sources that support it (Prometheus, Loki, VictoriaLogs, SLS, Tencent CLS) |
| **Custom Fields** | Uniformly configure annotations; supports both incremental modification and full replacement |
| **Channel** | Uniformly specify the channel for alert delivery |
| **Repeat Notification Config** | Uniformly set repeat notification interval and count |
@@ -286,14 +271,14 @@ When batch updating **Additional Labels** and **Custom Fields**, a dedicated met
| Update Mode | Description |
|-------------|-------------|
-| **Incremental modification** (default) | Add one or more modification operations (`Set` / `Delete`), each specifying a key and a value. Candidate keys and values are aggregated from the selected rules' existing content (autocomplete, with hit counts per candidate), with a live impact preview such as "Set key=value: X added, Y updated, Z unchanged" or "Delete key: affects N rules, others unchanged". When more than 500 rules are selected, candidate values are not loaded, but you can still type them manually. Note that Custom Fields keys must not start with `$`. Keys are trimmed of surrounding whitespace; if a key is empty after trimming or collides with another operation's key (for example `env` and `" env"` together), the whole batch fails validation with an error |
+| **Incremental modification** (default) | Add "Set" or "Delete" operations, each with a key and value. Keys and values autocomplete from the selected rules, with a preview of how many rules each operation affects. Custom field keys must not start with `$`, and keys in one batch must be unique |
| **Full replacement** | Completely replaces the field on each rule with the content below, deleting any other content on each rule that is not filled in here |
<Warning>
Modifying additional labels may affect alert routing, grouping, or noise reduction. Proceed with caution.
</Warning>
-When a batch update fails, the toast reports the number of failed rules and the first error reason (for example, "2 / 10 rules failed to update. First error: ..."), so you can troubleshoot rule by rule.
+If some rules fail to update, you see the number of failures and the first reason; the other rules are still updated.
### Batch move
@@ -322,7 +307,7 @@ After uploading the file, you can configure:
### Pre-import check results
-After parsing the file, the system shows a pre-import check table listing, rule by rule, the import name, status (`Ready to import` / `Skipped` / `Invalid`), and explanation. Check the rules you want to import (all importable rules are selected by default), then click "Import N rules" at the bottom to submit.
+After parsing the file, the system shows a pre-import check table listing, rule by rule, the import name, status (`Ready to import` / `Skipped` / `Invalid`), and explanation. Select the rules to import (all importable rules are selected by default) and submit.
<Note>
Nightingale rules are imported disabled and must be checked for data source matching and conversion warnings before you enable them manually. Common conversion notes include: Doris data sources mapped to MySQL, only the highest-severity alert condition kept, level inhibition / query correlation / notification target configs not preserved, recovery semantics approximated with Flashduty rule capabilities, `Local` timezone converted to `Asia/Shanghai`, all-day effective time converted to `00:00-23:59`, and durations converted at a 15-second interval when the evaluation interval is missing.
@@ -330,7 +315,7 @@ Nightingale rules are imported disabled and must be checked for data source matc
### Import results
-After submission, the system reports the import result: counts of imported, skipped, and invalid rules. When everything succeeds, it shows a success message; if nothing was imported, the dialog stays open so you can review why rules were skipped or invalid and select again.
+After submission, the system reports the import result: counts of imported, skipped, and invalid rules. If nothing was imported, review the reasons in the dialog and select again.
## Export alert rules
diff --git a/en/on-call.mdx b/en/on-call.mdx
index 5bdf0cfa..0145bb15 100644
--- a/en/on-call.mdx
+++ b/en/on-call.mdx
@@ -25,7 +25,7 @@ On-call is Flashduty's core product, serving thousands of enterprises and proces
Feishu/Lark, Dingtalk, WeCom, Slack, Microsoft Teams, phone calls, SMS, email
</Card>
<Card title="Rich Integrations" icon="plug">
- Native support for 100+ monitoring tools and cloud platforms, complete setup in 5 minutes
+ 290+ alert integrations covering mainstream monitoring tools and cloud platforms
</Card>
</CardGroup>
@@ -68,6 +68,13 @@ The Flashduty On-call workflow is intuitive:
</Accordion>
</AccordionGroup>
+## Use Cases
+
+- Build 7x24 on-call systems to ensure service availability
+- Aggregate alerts from multiple sources into a unified incident management portal
+- Establish escalation mechanisms to ensure timely response
+- Analyze alert data to continuously improve monitoring quality
+
## Quick Start
<CardGroup cols={2}>
@@ -77,7 +84,7 @@ The Flashduty On-call workflow is intuitive:
<Card title="Create a Channel" icon="folder-plus" href="/en/on-call/channel/create-edit">
Learn how to create and configure channels to manage team incident response
</Card>
- <Card title="Notification Delivery" icon="sitemap" href="/en/on-call/channel/escalation-rule">
+ <Card title="Escalation Rules" icon="sitemap" href="/en/on-call/channel/escalation-rule">
Set up alert notification rules, escalation paths, and responders
</Card>
<Card title="On-call Scheduling" icon="calendar" href="/en/on-call/configuration/schedule">
diff --git a/en/on-call/advanced/war-room.mdx b/en/on-call/advanced/war-room.mdx
index 3ed1aee3..136114af 100644
--- a/en/on-call/advanced/war-room.mdx
+++ b/en/on-call/advanced/war-room.mdx
@@ -115,17 +115,17 @@ If the IM integration used by the war room is later disabled or deleted, **Add s
</Warning>
<Info>
-**Platform-created war room chats cannot be used as standing notification targets.** Every chat carries an origin mark: `origin=system` means the platform created it (today, that is only war rooms), distinguishing it from human-created chats. Accordingly, the group-chat pickers in escalation rules' **IM app groups** (Feishu/DingTalk, Slack, and Microsoft Teams group chats) and in schedule handoff notifications' **group chat channels** (Feishu/DingTalk and Slack) automatically exclude war rooms — the Feishu/DingTalk and Slack pickers even read "Select … group chat (war rooms excluded)". A war room is born with an incident and dies with it: configuring one as a standing notification target points the configuration at a group that is bound to disappear. If a saved chat ID no longer resolves (war room dissolved, bot removed from the group, group deleted), the picker shows that target as **Chat unavailable**, with a remove button to clear it.
+**War room chats cannot be used as standing notification targets.** War rooms are created and closed with their incidents, so the **IM app groups** picker in escalation rules and the **group chat channels** picker in schedule handoff notifications do not list them. If a saved chat no longer exists (war room dissolved, bot removed, or group deleted), it shows as **Chat unavailable** and can be removed.
</Info>
### Mobile App
-The Flashduty App supports the full war room lifecycle, sharing the same war room capabilities as the console and IM apps. Key mobile behaviors:
+The Flashduty App supports the full war room lifecycle, consistent with the console and IM apps:
-- **Capability gating**: The mobile war room requires an On-call Pro or higher subscription and at least one IM integration with war room enabled; when the plan requirement is not met, neither the overview entry nor war-room actions are shown
-- **Overview entry card**: When the incident has a war room, the incident overview page shows a **War room** entry card. Tapping it opens the IM chat directly when the integration supports deep links; if the link cannot be opened or the integration does not provide a share link, a dialog shows the group name (one-tap copy) so you can search for the group name in your IM app to join
-- **Create war room**: The entry lives in **More Actions** in the bottom action bar of the incident details page. It is hidden when the incident already has a war room or is closed; when the incident has no responders, it is disabled with the toast "This incident has no responders, so a war room cannot be created" (the group is created by the backend based on the responders)
-- **Add stakeholders to war room / Dissolve war room**: Also in **More Actions**. Both remain available after the incident is closed (for review), and dissolving requires confirmation; they do, however, require the war room's IM integration to still be available. Once that integration is disabled or deleted, the two entries disappear from **More Actions** and an administrator must unlink the war room from the incident details page in the console; the **War room** entry card on the overview page stays, and tapping it shows "The integration is disabled or deleted. Ask an administrator to unlink the war room from the incident details on desktop. The original group chat will not be dissolved."
+- **Requirements**: same as the console: On-call Pro or higher, and at least one IM integration with war room enabled
+- **Opening the war room**: the **War room** card on the incident overview page opens the IM chat directly; if it cannot, it shows the group name for you to copy and search
+- **Create war room**: in **More Actions** at the bottom of the incident details page. Hidden when the incident already has a war room or is closed; unavailable when the incident has no responders (the group is created from the responders)
+- **Add stakeholders to war room / Dissolve war room**: also in **More Actions**, and still available after the incident is closed (for review); dissolving asks for confirmation. If the war room's IM integration is disabled or deleted, both disappear and an administrator must unlink the war room from the incident details page in the console (the original group chat is not dissolved)
<Check>
By deeply integrating emergency processes with instant messaging tools, Flashduty War Room brings you an **automated**, **visual**, and **traceable** incident collaboration experience.
@@ -145,6 +145,31 @@ Key incident operations (acknowledgment, closure, snooze, comments, etc.) are sy
- In messages for follow-up operations, `Action` is replaced with `Follow-up`
- When the operator cannot be resolved to a specific member, the message shows **System** as the operator
+## AI SRE
+
+War rooms integrate deeply with **AI SRE**: when a war room opens, AI SRE automatically runs a first round of diagnosis and posts its findings back to the group; you can also **@ AI SRE** in the chat to follow up or start a new investigation. See the [AI SRE introduction](/en/ai-sre) and [IM platforms](/en/ai-sre/im).
+
+### AI SRE in the War Room
+
+<CardGroup cols={2}>
+ <Card title="Automatic first diagnosis" icon="robot">
+ When a war room opens, AI SRE analyzes the incident and posts a first round of findings — before anyone has started investigating
+ </Card>
+ <Card title="Follow up in chat" icon="comment-dots">
+ @ AI SRE in the group to start or continue an investigation; the agent replies in the thread, visible to the whole team
+ </Card>
+ <Card title="Context-aware investigation" icon="chart-line">
+ Reply to an alert or incident card and the agent resolves the referenced incident automatically — no manual context-pasting
+ </Card>
+ <Card title="Incident review" icon="file-lines">
+ Generate structured post-mortems from the incident timeline and investigation evidence
+ </Card>
+</CardGroup>
+
+<Info>
+To build a more comprehensive context of the incident's full lifecycle, AI-generated post-mortem reads war room chat history. Ensure your IM integration has been granted the necessary permissions — see [Feishu/Lark](/en/on-call/integration/instant-messaging/lark) or [Slack](/en/on-call/integration/instant-messaging/slack) integration guides for details.
+</Info>
+
## FAQ
<AccordionGroup>
@@ -203,27 +228,3 @@ Key incident operations (acknowledgment, closure, snooze, comments, etc.) are sy
</Accordion>
</AccordionGroup>
-## AI SRE
-
-War rooms integrate deeply with **AI SRE**: when a war room opens, AI SRE automatically runs a first round of diagnosis and posts its findings back to the group; you can also **@ AI SRE** in the chat to follow up or start a new investigation. See the [AI SRE introduction](/en/ai-sre) and [IM platforms](/en/ai-sre/im).
-
-### AI SRE in the War Room
-
-<CardGroup cols={2}>
- <Card title="Automatic first diagnosis" icon="robot">
- When a war room opens, AI SRE analyzes the incident and posts a first round of findings — before anyone has started investigating
- </Card>
- <Card title="Follow up in chat" icon="comment-dots">
- @ AI SRE in the group to start or continue an investigation; the agent replies in the thread, visible to the whole team
- </Card>
- <Card title="Context-aware investigation" icon="chart-line">
- Reply to an alert or incident card and the agent resolves the referenced incident automatically — no manual context-pasting
- </Card>
- <Card title="Incident review" icon="file-lines">
- Generate structured post-mortems from the incident timeline and investigation evidence
- </Card>
-</CardGroup>
-
-<Info>
-To build a more comprehensive context of the incident's full lifecycle, AI-generated post-mortem reads war room chat history. Ensure your IM integration has been granted the necessary permissions — see [Feishu/Lark](/en/on-call/integration/instant-messaging/lark) or [Slack](/en/on-call/integration/instant-messaging/slack) integration guides for details.
-</Info>
diff --git a/en/on-call/analytics/insights.mdx b/en/on-call/analytics/insights.mdx
index 233b4076..5b255b8a 100644
--- a/en/on-call/analytics/insights.mdx
+++ b/en/on-call/analytics/insights.mdx
@@ -6,7 +6,7 @@ description: "Use insights for data analysis, with statistics and analysis of in
<Tip>**Plan requirement**: This feature requires an On-call Standard or higher subscription. [Learn more](https://flashcat.cloud/flashduty/price/)</Tip>
<Note>
-**The dashboard can be empty while your subscription is expired**: once your On-call subscription expires or is disabled, alert ingestion has stopped and the dashboard produces no new analytics data, so the default time window is naturally empty — this is not data loss. A non-dismissable banner stays at the top of the page stating that the subscription has expired, that alert ingestion has stopped so no new analytics data is produced, and that historical data is unaffected and can still be viewed and exported. Historical data stays viewable and exportable, and everything resumes automatically after renewal. For the account-level explanation, see [What happens when your subscription expires](/en/platform/pricing#what-happens-when-your-subscription-expires).
+**The dashboard can be empty while your subscription is expired**: once the subscription expires or is disabled, alert ingestion stops and no new statistics are produced, so the default time window may be empty. This is not data loss: historical data can still be viewed and exported, and everything resumes after renewal. See [What happens when your subscription expires](/en/platform/pricing#what-happens-when-your-subscription-expires).
</Note>
## Key Features
@@ -40,8 +40,8 @@ When customizing filter conditions, the system remembers your selections. Even a
| Channel | Select channel names to query, supports multiple selection. Dashboard data updates based on selected channels |
| Severity | Select severity levels to query, supports multiple selection. Dashboard data updates based on selected severity levels |
| Time Range | Select time range to query. Supports this week, last two weeks, this month, last month, and custom time ranges, querying up to the last **2 years (720 days)** of data (the exact limit depends on your plan) |
-| Data Interval | Supports day, week, and month dimensions. Defaults to hourly queries, but when time range exceeds 31 days, daily preview is not available. Day/week/month bucketing follows the viewer's effective time zone (personal time zone preferred, falling back to the organization's) |
-| Time Zone | Dashboard times, day/week/month aggregation, and queries are all displayed and counted in the viewer's effective time zone (personal time zone preferred, falling back to the organization's). The filter bar shows the current effective time zone on the right, with the tooltip "Times are shown and bucketed in your local timezone." |
+| Data Interval | Hourly by default; day, week or month also available. Daily view is not available for time ranges over 31 days |
+| Time Zone | Times and day/week/month statistics use your time zone (personal time zone first, otherwise the organization's), shown on the right of the filter bar |
| Sorting | Team, channel, and individual dimension dashboards support ascending and descending order. Defaults to showing TOP 10 data; expand to show more |
## Time Period Segmentation
diff --git a/en/on-call/channel/escalation-rule.mdx b/en/on-call/channel/escalation-rule.mdx
index 09dce253..0d8f9504 100644
--- a/en/on-call/channel/escalation-rule.mdx
+++ b/en/on-call/channel/escalation-rule.mdx
@@ -20,20 +20,7 @@ src="https://download.flashcat.cloud/flashduty/video/escalate-rule.mp4"
An escalation rule contains six core elements. The system matches rules from top to bottom, **stopping after the first successful match**.
-You can enable or disable individual escalation rules. Disabled rules are skipped during matching and will not trigger notifications. You can also copy an escalation rule to the current channel or another channel to quickly reuse existing configurations.
-
-### Copy an Escalation Rule
-
-Each escalation rule card shows a **Copy** icon on hover. Clicking it opens the copy dialog (the same component used for copying silence rules), which contains:
-
-| Field | Description |
-| :--- | :--- |
-| **Rule name** | Required; pre-filled with "Copy " plus the original name, **39 characters max** (the backend limit is 40) — overlong input is truncated in the field |
-| **Channel** | Choose **This channel** or **Another channel**. Copying to another channel requires picking the target from a dropdown that excludes the source rule's channel; non-admin users only see channels they manage |
-| **Description** | Optional; pre-filled with the original description, **500 characters max** — overlong input is truncated in the field |
-
-- The copy reuses the source rule's full configuration (trigger conditions, notification targets, notification methods, delay window, notification template, and escalation levels), but the **priority (list matching order) is not copied** — reposition the new rule in the list after copying
-- Copying to the current channel makes the new rule appear in the list immediately; copying to another channel shows the **Copy succeeded** result dialog with the target channel, rule name, description, and creator. Click **Go to view** to open the target channel and locate the new rule
+You can enable or disable individual escalation rules. Disabled rules are skipped during matching and will not trigger notifications. You can also copy an escalation rule to the current channel or another channel to quickly reuse existing configurations; see [Copy an Escalation Rule](#copy-an-escalation-rule).
### 1. Trigger Conditions
@@ -150,6 +137,18 @@ The minimum escalation timeout is 1 minute.
- **Add or remove levels**: you can add or remove levels freely; a rule must keep at least 1 level
- **Reorder**: you can move a level up or down, or insert a new level between any two existing levels
+## Copy an Escalation Rule
+
+Click the **Copy** icon on an escalation rule card to set the new rule's name, target channel and description:
+
+| Field | Description |
+| :--- | :--- |
+| **Rule name** | Required; defaults to "Copy \<original name\>", **39 characters max** |
+| **Channel** | This channel or another channel (non-admins can choose only channels they manage) |
+| **Description** | Optional; defaults to the original description, **500 characters max** |
+
+The copy keeps the source rule's full configuration (trigger conditions, notification targets, notification methods, delay window, notification template and escalation levels), but **not its position in the list**; move the new rule to the right position after copying. After copying to another channel, click **Go to view** to open the new rule.
+
## Best Practices
<AccordionGroup>
diff --git a/en/on-call/channel/integrate-data.mdx b/en/on-call/channel/integrate-data.mdx
index 1b46e148..4dc93611 100644
--- a/en/on-call/channel/integrate-data.mdx
+++ b/en/on-call/channel/integrate-data.mdx
@@ -47,7 +47,7 @@ Integration created within a channel, alerts automatically enter that channel.
</Frame>
<Note>
-A dedicated integration belongs to the channel it was created in: **editing, enabling/disabling, and deleting** it requires the "Channels Manage" or "Integrations Manage" functional permission together with the data permission for that channel — only **account admins, the channel creator, or the channel's managing team** can operate. Other members see these buttons disabled, with the reason on hover.
+A dedicated integration belongs to the channel it was created in. **Editing, enabling/disabling, and deleting** it requires the "Channels Manage" or "Integrations Manage" permission, and you must be an account admin, the channel creator, or a member of the channel's managing team.
</Note>
### Shared Integration
@@ -98,7 +98,7 @@ Clicking the **All** chip opens a full-screen catalog:
- The number next to the title is how many integrations the catalog covers, and the search box at the top searches all of them.
- The category rail on the left lists every category with its entry count; clicking one scrolls the right side to that category (and clears the search).
-- The right side lays out cards by category (logo, name, and a two-line blurb); hovering a card reveals **Add**, which opens the new-integration page for that system.
+- The right side lists systems by category; click **Add** to open the new-integration page for that system.
At the bottom the catalog keeps a "Can't find your system?" fallback area with two ways out: connect it with a generic integration, or request an integration.
@@ -240,7 +240,7 @@ Exceeding any of these limits returns a `429` status code — please wait and re
</Accordion>
<Accordion title="What happens to integrations after the subscription expires?" icon="circle-question">
- After the subscription expires, every integration (dedicated and shared) stops receiving alert events, a persistent subscription-expired banner appears at the top of the Integration Center, and the cards for adding a new integration are disabled (hover for the reason). Configured integrations are not deleted, and ingestion resumes automatically after renewal — no reconfiguration needed.
+ After the subscription expires, every integration (dedicated and shared) stops receiving alert events, and new integrations cannot be added. Configured integrations are not deleted, and ingestion resumes automatically after renewal, with no reconfiguration needed.
</Accordion>
</AccordionGroup>
diff --git a/en/on-call/channel/noise-reduction.mdx b/en/on-call/channel/noise-reduction.mdx
index 32337770..b60b3fdd 100644
--- a/en/on-call/channel/noise-reduction.mdx
+++ b/en/on-call/channel/noise-reduction.mdx
@@ -176,7 +176,7 @@ Flashduty On-call provides two grouping modes:
### Configuration Limits
-To protect grouping performance and stability, the following fields have hard backend caps:
+To protect grouping performance and stability, the following fields have hard system caps:
| Grouping mode | Limit | Cap | Description |
| :--- | :--- | :--- | :--- |
@@ -317,7 +317,7 @@ Quickly create temporary silence rules based on existing incidents.
</Frame>
-When creating a quick silence, the drawer shows "N labels identified, M labels automatically excluded" and lists each excluded label with its reason: system format rules are marked as **JSON / Numeric / Too long / Datetime**, account rules as **Globally excluded** or the owning integration name. From the drawer you can click **Manage exclusion rules** or **View exclusion rules** to open the account configuration (only the main account or Account.Admin can modify it; other members can view it read-only). The matching conditions are generated automatically from the source incident's labels — conditions that are too precise may cause similar alerts to escape silencing, so review the list carefully before creating.
+When creating a quick silence, the drawer lists labels that were excluded automatically, with the reason: their format (JSON, numeric, too long, datetime) or an account exclusion rule. Only the main account or account admins can change account exclusion rules. The matching conditions are generated from the source incident's labels; conditions that are too precise may let similar alerts escape silencing, so review them before creating.
<Note>
When repeatedly using quick silence on the same incident, it edits the original rule rather than creating a new one.
@@ -325,18 +325,16 @@ When creating a quick silence, the drawer shows "N labels identified, M labels a
### Copy a Silence Rule
-Every rule card in the silence rule list (except rules created by **Quick Silence**) shows a **Copy** icon on hover. Clicking it opens the copy dialog, where you can set the new rule's name and description and choose the target channel:
+Click the **Copy** icon on a silence rule card (not available for rules created by **Quick Silence**) to set the new rule's name, description and target channel:
| Configuration | Description |
| :--- | :--- |
-| **Rule name** | Required; pre-filled with "Copy " plus the original name (e.g. `Copy Database Maintenance`), **39 characters max** — overlong input is truncated in the field |
-| **Description** | Pre-filled with the original description, **500 characters max** — overlong input is truncated in the field |
-| **Channel** | Choose **This channel** (the current one) or **Another channel**. Copying to another channel requires picking the target from a dropdown that excludes the source rule's channel; non-admin users only see channels they manage |
+| **Rule name** | Required; defaults to "Copy \<original name\>", **39 characters max** |
+| **Description** | Defaults to the original description, **500 characters max** |
+| **Channel** | This channel or another channel (non-admins can choose only channels they manage) |
-The result is **a new, independent rule**: it reuses the source rule's silence conditions, silence behavior (Drop directly / Retain and mark), auto-delete-on-expiration setting, and schedule (one-time or recurring), but it does not carry over identity fields such as `rule_id` or `from_incident_id`, nor the quick-silence link to the source incident.
+The copy is **a new, independent rule** that keeps the source rule's silence conditions, silence behavior, auto-delete setting and schedule, but is no longer linked to the source incident. After copying to another channel, click **Go to view** to open the new rule.
-- **Copying to the current channel**: on success, the new rule appears in the list immediately and a "Copied" toast is shown.
-- **Copying to another channel**: on success, a **Copy succeeded** dialog appears showing the target channel, rule name, description, and creator. Click **Go to view** to open the target channel and jump straight to the new rule's detail page.
<Note>
**Quick silence** rules cannot be copied: a quick-silence rule is bound to its source incident (repeating the action on the same incident edits the original rule), so its card has no **Copy** action.
diff --git a/en/on-call/comparison/vs-opsgenie.mdx b/en/on-call/comparison/vs-opsgenie.mdx
index f52d7a54..51f41900 100644
--- a/en/on-call/comparison/vs-opsgenie.mdx
+++ b/en/on-call/comparison/vs-opsgenie.mdx
@@ -6,8 +6,6 @@ keywords: ["Opsgenie", "Opsgenie alternative", "Opsgenie sunset", "Opsgenie migr
## Introduction
----
-
Atlassian has given Opsgenie a definite end: **new sales stopped on June 4, 2025**; existing customers can keep using it until **support ends on April 5, 2027**, after which Opsgenie access shuts off and customer data that has not been moved out will be deleted (see the [Atlassian Opsgenie Licensing FAQ](https://www.atlassian.com/licensing/opsgenie)).
<Note>
@@ -33,8 +31,6 @@ The feature and pricing information on this page is current **as of September 20
## Sunset Timeline and the Official Migration Path
----
-
### Key Dates
| Date | Event | Impact |
@@ -57,8 +53,6 @@ For organizations already standardized on Jira, Confluence, and JSM, this is the
## Product Feature Comparison
----
-
### On-call
On-call solves "getting the alert to the right person": reduce noise first, then notify according to scheduling and escalation policies.
@@ -137,7 +131,7 @@ Response solves "closing the loop quickly once the right person is found": a sin
| Core Capability | Flashduty | Opsgenie |
| --- | --- | --- |
-| **Alert Integration** | 267 integration sources with full coverage of China-region cloud and monitoring ecosystems (Alibaba Cloud, Tencent Cloud, Huawei Cloud, etc.), compatible with the PagerDuty protocol | 200+ integrations with a mature overseas ecosystem |
+| **Alert Integration** | 290+ integration sources with full coverage of China-region cloud and monitoring ecosystems (Alibaba Cloud, Tencent Cloud, Huawei Cloud, etc.), compatible with the PagerDuty protocol | 200+ integrations with a mature overseas ecosystem |
| **Heartbeat Monitoring** | Monitoring-side heartbeats are covered by the [Monitors engine-lost alert](/en/monitors/engine/engine-lost-alert); On-call has no standalone cron-job heartbeat capability | ✅ Heartbeats are a mature Opsgenie capability — evaluate alternatives for cron/scheduled-job monitoring before migrating |
| **Alert Pipelines & Label Enrichment** | Routing, filtering, severity reset, regex extraction, and [data mapping](/en/on-call/integration/alert-integration/label-enhancement) (import CMDB tables to dynamically generate labels) | Alert Policies cover basic filtering and field modification |
| **Insights & Reporting** | MTTA/MTTR, personnel workload, frequency analysis, and **time period analysis** (work/rest/sleep) | Basic reporting |
@@ -148,8 +142,6 @@ Response solves "closing the loop quickly once the right person is found": a sin
## Pricing Comparison
----
-
| Dimension | Flashduty | Opsgenie / JSM Path |
| --- | --- | --- |
| **Billing Model** | License fee + excess communication fees | Per-user seats; after migrating to JSM, billed by the JSM plan |
@@ -176,8 +168,6 @@ Opsgenie's seat price is modest, but it is a sunset product — the meaningful c
## Migration Path Comparison
----
-
### Path One: Migrate into Jira Service Management (Stay in Atlassian)
Best for organizations already standardized on the Atlassian suite. The official in-app tool syncs most configuration into the selected JSM plan, but note:
@@ -216,8 +206,6 @@ Whichever path you choose, **complete the migration and export the data you need
## How to Choose
----
-
<CardGroup cols={2}>
<Card title="Choose Flashduty if" icon="star">
- You need a durable on-call / incident-response home outside Atlassian's merge path
@@ -241,8 +229,6 @@ Still comparing other vendors? See the in-depth [Flashduty vs PagerDuty comparis
## Summary
----
-
Opsgenie was an excellent alerting and on-call product, but its lifecycle is now on a countdown. For existing users, April 5, 2027 is a firm planning boundary: **migration is not a question of whether, but of where to**.
- If your organization already runs on the Atlassian suite, JSM is the official, lowest-friction path;
diff --git a/en/on-call/comparison/vs-pagerduty.mdx b/en/on-call/comparison/vs-pagerduty.mdx
index 1b34ce66..6a1c6682 100644
--- a/en/on-call/comparison/vs-pagerduty.mdx
+++ b/en/on-call/comparison/vs-pagerduty.mdx
@@ -6,8 +6,6 @@ keywords: ["product comparison", "PagerDuty", "feature comparison", "pricing com
## Introduction
----
-
In the rapidly evolving digital era, enterprises increasingly rely on **monitoring and incident management tools**—these are essential foundations for ensuring business continuity and service stability. However, as monitoring systems scale, the flood of **alerts and event notifications** presents unprecedented operational challenges for IT teams.
<Note>
@@ -37,8 +35,6 @@ When your organization encounters the following situations, it's time to conside
## Procurement Guide Overview
----
-
This guide provides **comprehensive On-call tool procurement recommendations**. We'll analyze the points IT managers should focus on when seeking efficient collaborative incident management solutions for development and operations teams, across three core dimensions: **Product Features**, **Service Quality**, and **Pricing Strategy**.
We'll also provide detailed comparison analysis between **Flashduty** and **PagerDuty**, two leading On-call vendors, to help you make an informed choice.
@@ -51,8 +47,6 @@ The feature and pricing information on this page is current **as of July 2026**;
## Product Feature Comparison
----
-
Product features are compared module by module, following Flashduty's current product structure: **On-call** (noise reduction, scheduling, escalation, notifications), **Response** (war room collaboration and incident resolution), **Status Pages** (external status communication), **AI SRE** (autonomous troubleshooting agent), and the **platform foundation** that underpins them (integrations, alert pipelines, insights, security, and the open developer ecosystem). This breakdown roughly maps to PagerDuty's own product lines, making it easy to compare block by block.
### On-call
@@ -177,7 +171,7 @@ Platform is the shared foundation underneath the four products above: how data g
| Core Capability | Flashduty | PagerDuty | Notes |
| --- | --- | --- | --- |
-| **Alert Integration** | 267 integration sources with full coverage of China-region cloud and monitoring ecosystems (Alibaba Cloud, Tencent Cloud, Huawei Cloud, JD Cloud, Kingsoft Cloud, UCloud, etc.), **compatible with the PagerDuty protocol** | 750+ integrations with broad overseas ecosystem coverage | PagerDuty offers more integrations overall; Flashduty covers the China-region tech stack more completely, and existing PagerDuty integration configs can switch over directly |
+| **Alert Integration** | 290+ integration sources with full coverage of China-region cloud and monitoring ecosystems (Alibaba Cloud, Tencent Cloud, Huawei Cloud, JD Cloud, Kingsoft Cloud, UCloud, etc.), **compatible with the PagerDuty protocol** | 750+ integrations with broad overseas ecosystem coverage | PagerDuty offers more integrations overall; Flashduty covers the China-region tech stack more completely, and existing PagerDuty integration configs can switch over directly |
| **Pull-based Ingestion** | [HTTP Pull](/en/on-call/integration/alert-integration/alert-sources/http-pull) periodically polls an endpoint; [DB Pull](/en/on-call/integration/alert-integration/alert-sources/db-pull) queries MySQL/PostgreSQL/ClickHouse directly to generate alerts from incremental changes | Push-based integration is the primary model | Legacy systems with no Webhook push capability can still integrate with Flashduty |
| **Two-way Ticket Sync** | [Jira](/en/on-call/integration/webhooks/jira-sync) (status mapping is configurable; field mapping supports incident ID / incident URL), [ServiceNow](/en/on-call/integration/webhooks/servicenow-sync), [ServiceDesk Plus](/en/on-call/integration/webhooks/servicedesk-plus-sync) | Jira, ServiceNow, etc. | Both support |
| **Change Event Integration** | ✅ Supports change event ingestion, dynamic routing, and label enrichment | ✅ Change Events | Both support |
@@ -239,8 +233,6 @@ Before reaching the team, alerts pass through routing, filtering, and transforma
## Pricing Comparison
----
-
Pricing is a critical factor in enterprise decisions—you need to choose the most cost-effective option that meets your requirements.
| Dimension | Flashduty | PagerDuty |
@@ -296,8 +288,6 @@ Take a 100-person engineering team where 15 people are routinely involved in inc
## Service Quality Comparison
----
-
Quality service support is essential for successful product implementation.
| Service Item | Flashduty | PagerDuty |
@@ -317,8 +307,6 @@ Quality service support is essential for successful product implementation.
## Migrating from PagerDuty / Opsgenie
----
-
<CardGroup cols={2}>
<Card title="Migrating from PagerDuty" icon="arrow-right-arrow-left">
Flashduty is **compatible with the PagerDuty protocol**—existing alert integration configs can switch over with essentially no rework. A dedicated service group provides one-on-one expert support throughout the migration.
@@ -332,8 +320,6 @@ Quality service support is essential for successful product implementation.
## Summary and Recommendations
----
-
### Core Advantages Comparison
<CardGroup cols={2}>
diff --git a/en/on-call/configuration/custom-forms.mdx b/en/on-call/configuration/custom-forms.mdx
index bc7fd0f2..a684c02a 100644
--- a/en/on-call/configuration/custom-forms.mdx
+++ b/en/on-call/configuration/custom-forms.mdx
@@ -47,21 +47,17 @@ These forms also work in the Flashduty App: creating, acknowledging, and closing
If an action has no configured form elements, or no element is visible for the current incident and user, Flashduty runs the normal create, acknowledge, or close flow without asking for additional input.
</Note>
-## Union interaction for batch operations
+## Batch Acknowledge or Close
-When you select **multiple** incidents in the incident list and batch **acknowledge** or batch **close** them, the system first splits the selection into two groups by form applicability, then handles each group separately:
+When you **acknowledge** or **close** several incidents at once from the incident list:
-- **Incidents that don't need the form**: the action has no configured form elements, or no element is visible for the current incident/user. Clicking **Acknowledge / Close** **executes immediately** and deselects them from the selection, then the form for the remaining incidents is shown
-- **Incidents that need the form**: a **union form** is shown — you fill it once and the values are written to every listed incident in a single request (all-or-nothing; on failure the dialog stays open so you can retry)
+- **Incidents that need no form** (no form elements are configured for the action, or the incident/user meets no element's display condition) are processed immediately and removed from the selection.
+- **The remaining incidents** get one **union form**: an element appears if it is visible for any incident and is required if it is required for any incident. You fill it in once and it is written to every incident in a single request that succeeds or fails as a whole; on failure the dialog stays open so you can retry.
-The union form's fields are the union of all incidents awaiting the form: an element appears if any incident can see it and is required if any incident requires it.
-
-**Overview in mixed scenarios**: when the selection contains both no-form and form incidents, the dialog starts with an overview — "N incidents acknowledged / M incidents pending acknowledgment" ("closed / pending closure" for the close action) — noting that "the incidents below require the form before acknowledgment and the form values are written to each of them". If every selected incident needs the form, the dialog goes straight to the form with no overview.
-
-**Abandon warning**: if you close the dialog without submitting (Cancel or the top-right close) after some incidents have already been executed, a warning appears — "N acknowledged, M remaining not filled in and not processed" ("closed" for the close action) — so you don't assume the whole batch was completed.
+When both kinds are selected, the top of the dialog shows how many incidents were already processed and how many are pending; if every incident needs the form, the form opens directly. If you close the dialog without submitting, you are told that the remaining incidents were left unprocessed, so you don't assume the whole batch is done.
<Note>
- **Fallback when the form cannot be resolved**: for single-incident acknowledge/close, the existing semantics hold — a resolution failure raises the error and is not silently bypassed; for batch acknowledge/close, a resolution failure does not block the action and the whole batch is executed as if no form existed (consistent with the backend's degradation for form-less batch requests).
+If the form fails to parse, a single acknowledge / close shows an error; a batch acknowledge / close is not blocked and runs the whole batch as if no form were needed.
</Note>
## Recommendations
diff --git a/en/on-call/configuration/filter-conditions.mdx b/en/on-call/configuration/filter-conditions.mdx
index 8b5809c2..8be649be 100644
--- a/en/on-call/configuration/filter-conditions.mdx
+++ b/en/on-call/configuration/filter-conditions.mdx
@@ -5,8 +5,6 @@ description: Filter specific alerts or incidents through condition matching, use
## Where Are Filter Conditions Used?
----
-
Filter conditions apply to the following scenarios:
| Scenario | Description |
@@ -21,13 +19,9 @@ Filter conditions apply to the following scenarios:
## How to Configure Filter Conditions?
----
-
### Rule Design
-Flashduty On-call abstracts the entire filter condition system, aiming for minimal configuration while meeting most scenario requirements.
-
-The overall judgment logic consists of multiple condition groups:
+A filter consists of one or more condition groups:
- **Conditions within a group**: `AND` relationship—each condition must match for the group to match
- **Between groups**: `OR` relationship—any group matching means overall match
@@ -65,10 +59,6 @@ Both take integration instance IDs as values; in the UI you pick integrations fr
Historically, `alert_severity` (alert severity) and `incident_severity` (incident severity) were used as two separate fields. They are now unified as `severity`. When loading legacy rules, the system automatically migrates both keys to `severity` — you don't need to edit anything manually; simply saving the rule will persist the new key.
</Note>
-<Tip>
-Target values in conditions are all strings, supporting **exact**, **regex**, **wildcard**, **IP range**, and **numeric comparison** matching methods.
-</Tip>
-
As shown above, we have two condition groups, each with two conditions, and conditions have multiple match values. The expression is:
@@ -81,6 +71,8 @@ or
### Matching Methods
+Target values are always strings; the format decides the matching method: **regex**, **wildcard**, **IP range**, or **numeric comparison**, and anything else is an **exact** match.
+
<Tabs>
<Tab title="Regex Matching">
When a value string has `/` as prefix and suffix, the entire value is recognized as **regex**.
@@ -113,7 +105,7 @@ or
When a value has `cidr` as prefix, the entire value is recognized as **IP range**.
**Example**:
- - `labels.host`: `cidr:10.0.0.206/24` — matches when ip label is within "10.0.0.206/24" range
+ - `labels.host`: `cidr:10.0.0.206/24` — matches when the host label is within "10.0.0.206/24" range
<Warning>
This filter condition doesn't apply in: incident list filtering by labels, alert list filtering by labels, and alert inhibit rule filtering for active alerts.
@@ -145,8 +137,6 @@ or
## FAQ
----
-
<AccordionGroup>
<Accordion title="Why doesn't the system suggest available labels?">
Flashduty On-call receives large volumes of data. To ensure system stability, the system only searches the most recent 500 alert events from the past 24 hours for label deduplication. Therefore, extracted labels may change dynamically, or no labels may be extracted if there's no new data in the past 24 hours.
diff --git a/en/on-call/configuration/notifications.mdx b/en/on-call/configuration/notifications.mdx
index d5ad98ab..f62bdec6 100644
--- a/en/on-call/configuration/notifications.mdx
+++ b/en/on-call/configuration/notifications.mdx
@@ -4,8 +4,6 @@ description: Comprehensive guide to Flashduty On-call supported notification cha
---
## Overview
----
-
### Supported Channel Matrix
Flashduty On-call provides a comprehensive notification matrix covering mobile App, traditional communication, and mainstream instant messaging (IM) tools.
@@ -23,8 +21,6 @@ Flashduty On-call provides a comprehensive notification matrix covering mobile A
## Core Notification Channel Configuration
----
-
### Flashduty App
The Flashduty App is the most efficient mobile work tool for On-call engineers. Wherever you are, you can fully control the incident handling process just like at your computer.
@@ -119,8 +115,6 @@ The Flashduty App is the most efficient mobile work tool for On-call engineers.
## Instant Messaging (IM) Integration
----
-
Integrating Flashduty On-call with your team's daily IM tools (like Feishu/Lark, Dingtalk) allows receiving and handling incidents in familiar collaboration environments, greatly improving On-call efficiency.
### App Integration (Recommended)
@@ -364,8 +358,6 @@ Verify the following:
## General Configuration
----
-
<AccordionGroup>
<Accordion title="How to customize notification content?" icon="paint-brush">
Flashduty On-call allows you to customize personalized notification messages for different channels.
@@ -397,8 +389,6 @@ Flashduty On-call allows you to customize personalized notification messages for
## Related Topics
----
-
<CardGroup cols={2}>
<Card title="Escalation Rules" icon="sitemap" href="/en/on-call/channel/escalation-rule">
Configure alert notification rules and escalation paths
diff --git a/en/on-call/configuration/personal-settings.mdx b/en/on-call/configuration/personal-settings.mdx
index dacdf140..7646abf7 100644
--- a/en/on-call/configuration/personal-settings.mdx
+++ b/en/on-call/configuration/personal-settings.mdx
@@ -10,16 +10,12 @@ description: Set personal contact information, notification preferences, and API
## Accessing Personal Center
----
-
Hover over the user icon in the lower left corner and select **Personal Information**. Related personal settings (**Notification Preferences**, APP Key, Flashduty APP) live in the same menu; for organization-level settings, go to **Platform Management → Organization → Organization Information**.
## Personal Information
----
-
Personal settings are accessed via the user icon in the lower left corner → **Personal Information**. The page shows an **account profile card** at the top and a **Login & Security** section below.
### Account Profile Card
@@ -61,8 +57,6 @@ The organization time zone is maintained by the subject account or an Account.Ad
## Notification Preferences
----
-
The Notification Preferences page configures notification channels **per notification scene**: **Incident Dispatch**, **Collaboration & Follow-up**, **Schedule Shift**, and **Internal Status Page**.
Supported channels per scene:
@@ -140,8 +134,6 @@ Status-page notifications are pushed only through IM apps; subscription emails a
## APP Key
----
-
APP Keys are used for API request authentication.
| Limit | Description |
@@ -159,8 +151,6 @@ When creating or editing an APP Key, choose its mode under **Permission Scope**.
## Flashduty APP
----
-
### Download the app
| Platform | Download Method |
@@ -197,8 +187,6 @@ The Flashduty APP supports free push notifications for alerts, ensuring critical
## FAQ
----
-
<AccordionGroup>
<Accordion title="I set personal notification preferences, why didn't notifications trigger?">
1. Check if the channel has escalation rules configured. Without escalation rules, incidents won't trigger notifications
@@ -210,8 +198,6 @@ The Flashduty APP supports free push notifications for alerts, ensuring critical
## Related Topics
----
-
<CardGroup cols={2}>
<Card title="Escalation Rules" icon="sitemap" href="/en/on-call/channel/escalation-rule">
Set notification channel to "Follow Personal Preferences"
diff --git a/en/on-call/configuration/schedule.mdx b/en/on-call/configuration/schedule.mdx
index 9cdb026b..1b37909c 100644
--- a/en/on-call/configuration/schedule.mdx
+++ b/en/on-call/configuration/schedule.mdx
@@ -10,15 +10,11 @@ Flashduty On-call provides highly flexible scheduling capabilities, supporting d
{/*
## Video Introduction
----
-
<Video src="https://download.flashcat.cloud/flashduty/video/schedule.mp4"></Video>
*/}
## Core Concepts
----
-
Understanding these concepts before configuration will help you better plan your schedules:
| Concept | Description |
@@ -35,8 +31,6 @@ Understanding these concepts before configuration will help you better plan your
## Configuration Process
----
-
<Steps>
<Step title="Create a Schedule">
Go to **Schedule Management**, click "Create Schedule"
@@ -96,8 +90,6 @@ Understanding these concepts before configuration will help you better plan your
## Delete a schedule
----
-
You can delete a schedule from the schedule list or the schedule detail page. The system asks for confirmation before deletion.
<Warning>
@@ -106,8 +98,6 @@ If a schedule is referenced by escalation rules, the delete button is disabled.
## On-call roles
----
-
On-call roles distinguish responders with different responsibilities within the same schedule (e.g., "primary" and "backup") and are an account-level resource:
- **Shared across the account**: Roles take effect at the account level and are shared by all schedules
@@ -120,8 +110,6 @@ By default, each account has only one on-call role, so you don't need to choose
## Override and time off
----
-
When on-call personnel need time off or have a temporary conflict, **don't modify permanent rules** — use the "Override" feature instead. An override is an independent rule type that **fully preempts** the normal on-call rules within its effective window. Once the window ends, the original rules resume automatically.
### Two ways to create an override
@@ -155,8 +143,6 @@ We recommend having a brief sync meeting between outgoing and incoming on-call p
## Date mask and continuous rotation
----
-
### Date mask
Date mask controls which days of the week an on-call rule takes effect. By selecting different day combinations, you can flexibly implement differentiated scheduling between weekdays and weekends.
@@ -186,8 +172,6 @@ Consider enabling continuous rotation in the following scenarios:
## Common scheduling scenarios
----
-
<Tabs>
<Tab title="24/7 Simple Rotation">
**Requirement**: Ops team has A, B, C—each person on-call for one week, handoff Monday at 10:00 AM.
@@ -234,8 +218,6 @@ Consider enabling continuous rotation in the following scenarios:
## View schedule details
----
-
Click a schedule name to enter the detail page, where you can view the scheduling calendar and manage on-call rules. The upper right corner provides these options:
- **View switcher**: Toggle between "Week", "Two Weeks", and "Calendar" (month view)
@@ -245,8 +227,6 @@ Click any time slot in the calendar to view the current responders or create an
## View My Schedule
----
-
The **Schedules** list page embeds a **My Schedule** section at the top, summarizing your on-call assignments in a week view: the left column lists the schedules in which you have shifts this week, and the calendar on the right shows your on-call time slots in each schedule.
Click the left and right arrows next to the section title to browse previous or upcoming weeks, and click the dot button in the middle to quickly jump back to the current week.
@@ -255,8 +235,6 @@ Shift times are rendered in your effective time zone; when a schedule's time zon
## Related Topics
----
-
<CardGroup cols={2}>
<Card title="Escalation Rules" icon="sitemap" href="/en/on-call/channel/escalation-rule">
Configure alert notification rules and escalation paths
diff --git a/en/on-call/configuration/service-calendar.mdx b/en/on-call/configuration/service-calendar.mdx
index d3aafec9..bb25fead 100644
--- a/en/on-call/configuration/service-calendar.mdx
+++ b/en/on-call/configuration/service-calendar.mdx
@@ -9,16 +9,12 @@ description: Service calendars define workdays and rest days, working with escal
{/*
## Video Introduction
----
-
<Video src="https://download.flashcat.cloud/flashduty/video/calendar.mp4"></Video>
*/}
## Use Cases
----
-
| Scenario | Description |
| --- | --- |
| **Escalation Rules** | Assign to different on-call personnel based on workdays/rest days |
@@ -26,8 +22,6 @@ description: Service calendars define workdays and rest days, working with escal
## Creating a Calendar
----
-
Go to **Configuration → Service Calendar** and click **Add Calendar**.
| Configuration | Description |
@@ -48,8 +42,6 @@ New calendars default to all workdays. After creation, open the calendar detail
## Editing a Calendar
----
-
| Action | Description |
| --- | --- |
| **Modify Basic Info** | Calendar name, description, management team |
@@ -65,8 +57,6 @@ Deleting a calendar is irreversible. Please confirm no escalation rules or silen
## FAQ
----
-
<AccordionGroup>
<Accordion title="What's the difference between a service calendar and a schedule?">
They serve different purposes:
@@ -80,8 +70,6 @@ Deleting a calendar is irreversible. Please confirm no escalation rules or silen
## Related Topics
----
-
<CardGroup cols={2}>
<Card title="Escalation Rules" icon="sitemap" href="/en/on-call/channel/escalation-rule">
Reference service calendars in escalation rules
diff --git a/en/on-call/configuration/templates.mdx b/en/on-call/configuration/templates.mdx
index f462509e..0242baa5 100644
--- a/en/on-call/configuration/templates.mdx
+++ b/en/on-call/configuration/templates.mdx
@@ -164,166 +164,6 @@ Complete variable list for incident objects:
</Accordion>
</AccordionGroup>
-## FAQ
-
-<AccordionGroup>
-<Accordion title="How do I know what Labels are available?">
-- Manually created incidents have no labels
-- Auto-created incidents have labels, same as the first merged alert's labels
-
-Go to **Incident List** → view incident details to see all label information.
-</Accordion>
-
-<Accordion title="Configured custom template but default template was used instead?">
-When creating custom templates, the system uses mock data to check syntax. Mock data covers limited scenarios; rendering may fail at runtime, and system falls back to default template.
-
-<Tip>
-Recommend checking if variable exists before referencing:
-
-```go
-// ❌ Wrong: Read label directly
-{{.Labels.resource}}
-
-// ✅ Recommended: Check then read
-{{if .Labels.resource}}{{.Labels.resource}}{{end}}
-```
-</Tip>
-</Accordion>
-
-<Accordion title="Incident title has character escaping (like >)?">
-Use `toHtml` function to handle:
-
-```go
-// Escape HTML characters
-{{toHtml .Title}}
-
-// Render with first non-empty value
-{{toHtml .Title .TitleEnglish}}
-```
-</Accordion>
-
-<Accordion title="How to convert time format?">
-```go
-// date function: Convert timestamp to readable format
-{{date "2006-01-02 15:04:05" .StartTime}}
-
-// ago function: Convert time difference to readable format (e.g., "5 minutes ago")
-{{ago .StartTime}}
-```
-</Accordion>
-
-<Accordion title="How to reference external variable inside for loop?">
-Add `$` before external variable:
-
-```go
-{{range .Responders}}
- {{if eq $.Progress "Triggered"}}
- 【Pending】{{.Email}}
- {{end}}
-{{end}}
-```
-</Accordion>
-
-<Accordion title="How to extract field value with . (like obj.instance)?">
-Use `index` function:
-
-```go
-{{index .Labels "obj.instance"}}
-```
-</Accordion>
-
-<Accordion title="How to extract labels from associated alerts and deduplicate?">
-```go
-// alertLabels: Get deduplicated array
-{{alertLabels . "resource"}}
-
-// joinAlertLabels: Deduplicate and join with delimiter as string
-{{joinAlertLabels . "resource" ", "}}
-```
-</Accordion>
-
-<Accordion title="How to iterate and print Labels?">
-```go
-// Complete iteration
-{{range $k, $v := .Labels}}
- {{$k}} : {{toHtml $v}}
-{{end}}
-
-// Exclude single label
-{{range $k, $v := .Labels}}
- {{if ne $k "resource"}}
- {{$k}} : {{toHtml $v}}
- {{end}}
-{{end}}
-
-// Exclude multiple labels
-{{range $k, $v := .Labels}}
- {{if not (in $k "resource" "body_text")}}
- {{$k}} : {{toHtml $v}}
- {{end}}
-{{end}}
-```
-</Accordion>
-
-<Accordion title="How to extract info from JSON field?">
-Use `jsonGet` function to extract values by path from valid JSON. Syntax reference at [gjson.dev](https://gjson.dev/).
-
-```go
-// Extract detail_url field from rule_note label
-{{jsonGet .Labels.rule_note "detail_url"}}
-
-// Extract name field of first element in JSON array
-{{jsonGet .Labels.slice "0.name"}}
-
-// Iterate array, match instanceId field where userId==7777
-{{jsonGet .Labels.rule_note "#(userId==7777)#.instanceId"}}
-```
-</Accordion>
-
-<Accordion title="How to get image URL?">
-**imageSrcToURL**: Convert image_key or URL to accessible address (for Dingtalk/Slack App)
-
-```go
-{{ $root := . }}
-{{ range $i, $v := .Images }}
- {{ $imageURL := imageSrcToURL $root $v.Src }}
- {{ if $imageURL }}{{ end }}
-{{ end }}
-```
-
-**transferImage**: Upload image to third-party platform (for Feishu/Lark App)
-
-```go
-{{ $root := . }}
-{{ range $i, $v := .Images }}
- {{ $transferURL := transferImage $root $v.Src }}
- {{ if $transferURL }}{{ end }}
-{{ end }}
-```
-
-<Note>
-Image size cannot exceed 10 MB, supports JPG, PNG, WEBP, GIF, BMP formats.
-</Note>
-</Accordion>
-
-<Accordion title="How to use logical operations?">
-| Function | Description | Example |
-| :--- | :--- | :--- |
-| `and` | Logical AND | `{{if and (eq .A "x") (eq .B "y")}}` |
-| `or` | Logical OR | `{{if or (eq .A "x") (eq .A "y")}}` |
-| `not` | Logical NOT | `{{if not (eq .A "x")}}` |
-| `eq` | Equal | `{{if eq .A "x"}}` |
-| `ne` | Not equal | `{{if ne .A "x"}}` |
-| `gt` / `ge` | Greater than / Greater or equal | `{{if gt .AlertCnt 1}}` |
-| `lt` / `le` | Less than / Less or equal | `{{if lt .AlertCnt 10}}` |
-</Accordion>
-
-<Accordion title="How to find more functions?">
-- Function list: [functions.go](https://github.com/flashcatcloud/sprig/blob/master/functions.go#L97)
-- Usage examples: Check corresponding `_test.go` files, e.g., [date_test.go](https://github.com/flashcatcloud/sprig/blob/master/date_test.go)
-</Accordion>
-</AccordionGroup>
-
## Channel Templates
Different notification channels support different template formats and limitations.
@@ -365,21 +205,21 @@ Requires [Feishu/Lark integration](/en/on-call/integration/instant-messaging/lar
### Card Fields and Bottom Action Buttons
-When editing a Feishu/Lark app template, the **Additional info** tab next to the **Content** tab provides a card-fields switch panel ("These fields are rendered by the system. Use the switches to show or hide them at the bottom of the message."), which controls whether 7 system fields — channel, snooze deadline, severity, aggregated alert count, responders, the details button, and AI analysis — are rendered at the bottom of the card.
-
-**Create war room** can be configured on Feishu/Lark app, Dingtalk app, and Slack app templates (backed respectively by the `feishu_app_war_room_enabled`, `dingtalk_app_war_room_enabled`, and `slack_app_war_room_enabled` fields, **off** by default; save the template to apply the change). The switch itself is labelled **Create war room**, and the panel describes it as "Once enabled, a dedicated Create War Room button is shown at the bottom of the card when the group-creation conditions are met."
+The **Additional info** tab next to **Content** controls which system content appears at the bottom of the card. Switches available per channel:
-- **On**: when the incident is not closed, has no war room yet, and has responders, the card for that channel shows a dedicated **👥 Create War Room** button at the bottom; clicking it starts group creation
-- **Off**: no such button is shown
+| Switch | Feishu/Lark app | Dingtalk app | Slack app | Microsoft Teams | WeCom app |
+| --- | --- | --- | --- | --- | --- |
+| Channel, snooze deadline, severity, aggregated alert count, responders, details button | ✓ | ✓ | ✓ | ✓ | ✓ |
+| AI analysis | ✓ | ✓ | ✓ | — | — |
+| Create war room | ✓ | ✓ | ✓ | — | — |
+| Keep custom actions after incident closure | ✓ | ✓ | ✓ | ✓ | — |
-**Keep custom actions after incident closure** is offered on Feishu/Lark app, Dingtalk app, Slack app, and Microsoft Teams templates; the WeCom app template does not offer it (the panel does not render the switch for that channel). It is backed by the `incident_card_closed_action_apps` field — an array of the channel keys for which the capability is enabled (e.g. `["feishu_app"]`), **off** by default (an empty array means off); save the template to apply the change.
+- **Create war room** (off by default): when on, and the incident is not closed, has no war room yet and has responders, the card shows a **👥 Create War Room** button at the bottom; click it to create the group.
+- **Keep custom actions after incident closure** (off by default): when on, configured custom actions can still be run from the message card for 3 days after the incident is closed; when off, or after 3 days, run them from the incident details page.
-- **On** (panel description: "Enabled. Configured custom actions can be run from the message card for 3 days after the incident is closed. After that, run them from the incident details."): configured custom actions can still be run directly from the message card for 3 days after the incident is closed; after that, run them from the incident details page
-- **Off** (panel description: "Disabled. Custom actions are hidden from the message card after the incident is closed. You can still run them from the incident details."): the message card no longer shows the custom actions entry once the incident is closed; they can still be run from the incident details page
+Save the template for switch changes to take effect.
-Together with the 7 card-field switches above, the **Additional info** panel holds **9 switches** on Feishu/Lark app, Dingtalk app, and Slack app templates, **7** on Microsoft Teams, and **6** on WeCom app (see the channel template tabs below).
-
-The card's bottom action area has changed as well: **More Actions** (that placeholder is its label) is now a dropdown select menu holding custom actions, snooze durations, and unacknowledge — the war room button is no longer one of its entries.
+On Feishu/Lark app cards, **More Actions** at the bottom is a dropdown menu with custom actions, snooze durations, and unacknowledge; the **👥 Create War Room** button is shown separately, not in that menu.
</Tab>
<Tab title="Dingtalk App">
@@ -402,7 +242,7 @@ Requires [Dingtalk integration](/en/on-call/integration/instant-messaging/dingta
<img src="https://download.flashcat.cloud/flashduty/changelog/20230720/dingtalk_app_render.png" alt="Dingtalk App Notification" />
</Frame>
-As with the Feishu/Lark app, the **Additional info** tab next to the **Content** tab provides a card-fields switch panel ("These fields are rendered by the system. Use the switches to show or hide them at the bottom of the message."), controlling whether 7 system fields — channel, snooze deadline, severity, aggregated alert count, responders, the details button, and AI analysis — are rendered at the bottom of the card; the Dingtalk app template also offers the **Create war room** switch (backed by the `dingtalk_app_war_room_enabled` field, **off** by default; save the template to apply the change) and the **Keep custom actions after incident closure** switch (recorded in the `incident_card_closed_action_apps` channel-key array, **off** by default), so the **Additional info** panel holds **9 switches**.
+For the switches on the **Additional info** tab, see [Card Fields and Bottom Action Buttons](#card-fields-and-bottom-action-buttons).
</Tab>
<Tab title="WeCom App">
@@ -428,7 +268,7 @@ WeCom limits card length, template render area max **8 lines**, excess will be h
<img src="https://download.flashcat.cloud/flashduty/changelog/20230720/wecom_app_render.png" alt="WeCom App Notification" />
</Frame>
-As with the Feishu/Lark app, the **Additional info** tab next to the **Content** tab provides a card-fields switch panel ("These fields are rendered by the system. Use the switches to show or hide them at the bottom of the message."), controlling whether 6 system fields — channel, snooze deadline, severity, aggregated alert count, responders, and the details button — are rendered at the bottom of the card. The WeCom app template does not offer the **AI Analysis**, **Create war room**, or **Keep custom actions after incident closure** switches, so its **Additional info** panel holds **6 switches**.
+For the switches on the **Additional info** tab, see [Card Fields and Bottom Action Buttons](#card-fields-and-bottom-action-buttons).
</Tab>
<Tab title="Slack App">
@@ -459,7 +299,7 @@ When displaying images, separate images from other content with `---`, format st
<img src="https://download.flashcat.cloud/flashduty/integration/slack/slack_app_message.png" alt="Slack App Notification" />
</Frame>
-As with the Feishu/Lark app, the **Additional info** tab next to the **Content** tab provides a card-fields switch panel ("These fields are rendered by the system. Use the switches to show or hide them at the bottom of the message."), controlling whether 7 system fields — channel, snooze deadline, severity, aggregated alert count, responders, the details button, and AI analysis — are rendered at the bottom of the card; the Slack app template also offers the **Create war room** switch (backed by the `slack_app_war_room_enabled` field, **off** by default; save the template to apply the change) and the **Keep custom actions after incident closure** switch (recorded in the `incident_card_closed_action_apps` channel-key array, **off** by default), so the **Additional info** panel holds **9 switches**.
+For the switches on the **Additional info** tab, see [Card Fields and Bottom Action Buttons](#card-fields-and-bottom-action-buttons).
</Tab>
<Tab title="Microsoft Teams">
@@ -478,7 +318,7 @@ Requires [Teams integration](/en/on-call/integration/instant-messaging/microsoft
<img src="https://download.flashcat.cloud/flashduty/integration/microsoft-teams/teams_app_message.png" alt="Teams App Notification" />
</Frame>
-As with the Feishu/Lark app, the **Additional info** tab next to the **Content** tab provides a card-fields switch panel ("These fields are rendered by the system. Use the switches to show or hide them at the bottom of the message."), controlling whether 6 system fields — channel, snooze deadline, severity, aggregated alert count, responders, and the details button — are rendered at the bottom of the card, plus a **Keep custom actions after incident closure** switch (recorded in the `incident_card_closed_action_apps` channel-key array, **off** by default), so its **Additional info** panel holds **7 switches**. The Microsoft Teams template does not offer the **AI Analysis** or **Create war room** switches.
+For the switches on the **Additional info** tab, see [Card Fields and Bottom Action Buttons](#card-fields-and-bottom-action-buttons).
</Tab>
</Tabs>
@@ -722,6 +562,166 @@ Supports full HTML format. Default template provides professional email layout i
</Tab>
</Tabs>
+## FAQ
+
+<AccordionGroup>
+<Accordion title="How do I know what Labels are available?">
+- Manually created incidents have no labels
+- Auto-created incidents have labels, same as the first merged alert's labels
+
+Go to **Incident List** → view incident details to see all label information.
+</Accordion>
+
+<Accordion title="Configured custom template but default template was used instead?">
+When creating custom templates, the system uses mock data to check syntax. Mock data covers limited scenarios; rendering may fail at runtime, and system falls back to default template.
+
+<Tip>
+Recommend checking if variable exists before referencing:
+
+```go
+// ❌ Wrong: Read label directly
+{{.Labels.resource}}
+
+// ✅ Recommended: Check then read
+{{if .Labels.resource}}{{.Labels.resource}}{{end}}
+```
+</Tip>
+</Accordion>
+
+<Accordion title="Incident title has character escaping (like >)?">
+Use `toHtml` function to handle:
+
+```go
+// Escape HTML characters
+{{toHtml .Title}}
+
+// Render with first non-empty value
+{{toHtml .Title .TitleEnglish}}
+```
+</Accordion>
+
+<Accordion title="How to convert time format?">
+```go
+// date function: Convert timestamp to readable format
+{{date "2006-01-02 15:04:05" .StartTime}}
+
+// ago function: Convert time difference to readable format (e.g., "5 minutes ago")
+{{ago .StartTime}}
+```
+</Accordion>
+
+<Accordion title="How to reference external variable inside for loop?">
+Add `$` before external variable:
+
+```go
+{{range .Responders}}
+ {{if eq $.Progress "Triggered"}}
+ 【Pending】{{.Email}}
+ {{end}}
+{{end}}
+```
+</Accordion>
+
+<Accordion title="How to extract field value with . (like obj.instance)?">
+Use `index` function:
+
+```go
+{{index .Labels "obj.instance"}}
+```
+</Accordion>
+
+<Accordion title="How to extract labels from associated alerts and deduplicate?">
+```go
+// alertLabels: Get deduplicated array
+{{alertLabels . "resource"}}
+
+// joinAlertLabels: Deduplicate and join with delimiter as string
+{{joinAlertLabels . "resource" ", "}}
+```
+</Accordion>
+
+<Accordion title="How to iterate and print Labels?">
+```go
+// Complete iteration
+{{range $k, $v := .Labels}}
+ {{$k}} : {{toHtml $v}}
+{{end}}
+
+// Exclude single label
+{{range $k, $v := .Labels}}
+ {{if ne $k "resource"}}
+ {{$k}} : {{toHtml $v}}
+ {{end}}
+{{end}}
+
+// Exclude multiple labels
+{{range $k, $v := .Labels}}
+ {{if not (in $k "resource" "body_text")}}
+ {{$k}} : {{toHtml $v}}
+ {{end}}
+{{end}}
+```
+</Accordion>
+
+<Accordion title="How to extract info from JSON field?">
+Use `jsonGet` function to extract values by path from valid JSON. Syntax reference at [gjson.dev](https://gjson.dev/).
+
+```go
+// Extract detail_url field from rule_note label
+{{jsonGet .Labels.rule_note "detail_url"}}
+
+// Extract name field of first element in JSON array
+{{jsonGet .Labels.slice "0.name"}}
+
+// Iterate array, match instanceId field where userId==7777
+{{jsonGet .Labels.rule_note "#(userId==7777)#.instanceId"}}
+```
+</Accordion>
+
+<Accordion title="How to get image URL?">
+**imageSrcToURL**: Convert image_key or URL to accessible address (for Dingtalk/Slack App)
+
+```go
+{{ $root := . }}
+{{ range $i, $v := .Images }}
+ {{ $imageURL := imageSrcToURL $root $v.Src }}
+ {{ if $imageURL }}{{ end }}
+{{ end }}
+```
+
+**transferImage**: Upload image to third-party platform (for Feishu/Lark App)
+
+```go
+{{ $root := . }}
+{{ range $i, $v := .Images }}
+ {{ $transferURL := transferImage $root $v.Src }}
+ {{ if $transferURL }}{{ end }}
+{{ end }}
+```
+
+<Note>
+Image size cannot exceed 10 MB, supports JPG, PNG, WEBP, GIF, BMP formats.
+</Note>
+</Accordion>
+
+<Accordion title="How to use logical operations?">
+| Function | Description | Example |
+| :--- | :--- | :--- |
+| `and` | Logical AND | `{{if and (eq .A "x") (eq .B "y")}}` |
+| `or` | Logical OR | `{{if or (eq .A "x") (eq .A "y")}}` |
+| `not` | Logical NOT | `{{if not (eq .A "x")}}` |
+| `eq` | Equal | `{{if eq .A "x"}}` |
+| `ne` | Not equal | `{{if ne .A "x"}}` |
+| `gt` / `ge` | Greater than / Greater or equal | `{{if gt .AlertCnt 1}}` |
+| `lt` / `le` | Less than / Less or equal | `{{if lt .AlertCnt 10}}` |
+</Accordion>
+
+<Accordion title="How to find more functions?">
+- Function list: [functions.go](https://github.com/flashcatcloud/sprig/blob/master/functions.go#L97)
+- Usage examples: Check corresponding `_test.go` files, e.g., [date_test.go](https://github.com/flashcatcloud/sprig/blob/master/date_test.go)
+</Accordion>
+</AccordionGroup>
+
## Related Topics
<CardGroup cols={2}>
diff --git a/en/on-call/incident/alert-management.mdx b/en/on-call/incident/alert-management.mdx
index 5925e3f8..ce930f57 100644
--- a/en/on-call/incident/alert-management.mdx
+++ b/en/on-call/incident/alert-management.mdx
@@ -59,11 +59,11 @@ Click the view settings button at the top of the list to adjust the following op
| Option | Description |
| :--- | :--- |
-| **Detail Display** | Choose to open alert details as a **Page** or in a **Side Panel** when clicking an alert |
+| **Detail Display** | Choose to open alert details as a **Page** or in a **Side Panel** when clicking an alert; the side panel lets you browse without leaving the list |
| **Auto Refresh** | Options: Off / 5 seconds / 10 seconds / 20 seconds / 30 seconds / 1 minute / 2 minutes / 3 minutes / 5 minutes / 10 minutes, defaulting to 10 seconds |
| **Display Attributes** | Toggle visibility of columns such as recovery status, incident progress, associated events, associated incident, trigger time, integration source, and channel |
-View settings are retained per view and persist long-term in the current browser.
+View settings are saved per view in the current browser.
### Batch Operations
@@ -91,7 +91,7 @@ In aggregate view, the system matches at most **100** records for grouping displ
## Alert Details
-Click an alert title to enter the alert details page. The top of the page is a **HeaderInfo bar** that shows the alert title, severity tag, alert ID (hover to copy the full ID), recovery status (Recovered / Not Recovered), and the progress tag of the incident it belongs to. If the alert has ever been silenced or inhibited, the corresponding icon is displayed before the title. The right side of the header provides a **Merge** action button to merge the current alert into an incident.
+Click an alert title to enter the alert details page. The header bar at the top shows the alert title, severity tag, alert ID (hover to copy the full ID), recovery status (Recovered / Not Recovered), and the progress tag of the incident it belongs to. If the alert has ever been silenced or inhibited, the corresponding icon is displayed before the title. The right side of the header provides a **Merge** action button to merge the current alert into an incident.
The details page body is split into two tabs:
@@ -100,17 +100,13 @@ The details page body is split into two tabs:
| **Alert Overview** | The left side shows the alert description, labels, and **related events preview** (up to 5 entries, with a link to the *Associated Events* tab for the full list); the right side shows attributes (channel, trigger time), images, alert source, associated incident, and Links |
| **Associated Events** | Shows the list of all raw events associated with this alert |
-The active tab is controlled by the URL parameter `tab`: appending `?tab=events` to the alert details URL (e.g. `/alert/detail/{id}?tab=events`) opens the **Associated Events** tab directly, and tab switches are synced to the address bar. The **View full event history** entry in the "showing only the latest N alert events" hint on the incident details page uses this mechanism.
+Append `?tab=events` to the alert details URL (e.g. `/alert/detail/{id}?tab=events`) to open the **Associated Events** tab directly; switching tabs updates the address bar. The **View full event history** link on the incident details page opens alerts this way.
The **Alert Source** is clickable so you can quickly trace where an alert came from:
- **Alerts from the Monit integration**: Display the name of the rule that produced the alert. Click to jump to that alert rule — Entity Tree rules open the rule editing view directly in Entity Tree, while standalone rules open the rule details page. When older data lacks rule labels, it falls back to showing the integration name and links to the integration details
- **Alerts from other integrations**: Display the integration name and type tag (shared or dedicated); click to jump to the corresponding integration details page
-<Tip>
-You can also choose to view details in the **Side Panel** mode from the alert list view settings, allowing you to quickly browse alert information without navigating to a new page.
-</Tip>
-
### Alert Lifecycle Records
The entire process from trigger to close is fully recorded by the system. Common record types include:
diff --git a/en/on-call/incident/custom-actions.mdx b/en/on-call/incident/custom-actions.mdx
index e88dd31b..661be2d3 100644
--- a/en/on-call/incident/custom-actions.mdx
+++ b/en/on-call/incident/custom-actions.mdx
@@ -1,5 +1,6 @@
---
title: "Custom Actions"
+sidebarTitle: "Incident Custom Actions"
description: "Learn about custom action use cases and configuration methods"
---
@@ -26,7 +27,7 @@ When confirmed that incidents affect production services, trigger external Statu
<Steps>
<Step title="Enter Integration Center">
-Login to console, go to **Integration Center => Webhook**.
+Login to console, go to **Integration Center → Webhook**.
</Step>
<Step title="Add Integration">
diff --git a/en/on-call/incident/handle-update-incident.mdx b/en/on-call/incident/handle-update-incident.mdx
index c7ac7285..5d4b3d4c 100644
--- a/en/on-call/incident/handle-update-incident.mdx
+++ b/en/on-call/incident/handle-update-incident.mdx
@@ -65,12 +65,12 @@ You have three ways to acknowledge a newly triggered incident.
<Tab title="Acknowledge via Console">
- **Single Acknowledge**: Click incident details in console, click **Acknowledge** button to complete
- **Batch Operation**: In console incident list, select multiple triggered incidents, click **Acknowledge** button for batch acknowledgment
-- **AI Analysis**: After selecting multiple incidents, click the **AI Analysis** button to batch-send the selected incidents as context to the AI SRE Agent for analysis. This button requires the AI SRE module to be enabled and the `AiSreChatVisit` permission; if all selected incidents belong to the same team, the session defaults to that team's scope.
+- **AI Analysis**: After selecting multiple incidents, click the **AI Analysis** button to batch-send the selected incidents as context to the AI SRE Agent for analysis. This requires AI SRE to be activated and permission to use AI SRE chat; if all selected incidents belong to the same team, the session defaults to that team's scope.
</Tab>
<Tab title="Acknowledge via IM App">
-- **App Messages**: App message main card provides an **Acknowledge** button, click the card to complete acknowledgment. If clicking the card has no effect, you may not have completed login account linking in the app or other reasons. See [Feishu/Lark Integration Guide](/en/on-call/integration/instant-messaging/lark) for details
-- **Bot Messages**: Most bot channels push messages in Markdown format. You can modify notification templates to add an **Acknowledge** redirect link for jumping to console to acknowledge. See default templates for details
+- **App Messages**: Click **Acknowledge** on the message card. If nothing happens, you have most likely not linked your Flashduty account in the app yet. See [Feishu/Lark Integration Guide](/en/on-call/integration/instant-messaging/lark) for details
+- **Bot Messages**: Most bot channels push messages in Markdown format. You can add an **Acknowledge** link in the [notification template](/en/on-call/configuration/templates) that opens the console to acknowledge.
</Tab>
<Tab title="Acknowledge via Voice Call">
@@ -135,7 +135,7 @@ Open the incident detail in the [Flashduty App](/en/on-call/quickstart/mobile-ap
## Close Incident
-You have multiple ways to close an incident.
+You can close an incident in any status. Closing sets its progress to **Closed**, and its alerts stop merging new events. If an alert hasn't recovered in the original monitoring system, later events will trigger new alerts and incidents in Flashduty On-call.
<Tabs>
<Tab title="Close via Console">
@@ -144,7 +144,7 @@ You have multiple ways to close an incident.
</Tab>
<Tab title="Close via IM App">
-App message main card provides a **Close** button, click the card to complete closure. If clicking the card has no effect, you may not have completed login account linking in the app or other reasons. See [Feishu/Lark Integration Guide](/en/on-call/integration/instant-messaging/lark) for details.
+Click **Close** on the message card. If nothing happens, you have most likely not linked your Flashduty account in the app yet. See [Feishu/Lark Integration Guide](/en/on-call/integration/instant-messaging/lark) for details.
</Tab>
<Tab title="Close via Flashduty App">
@@ -158,9 +158,7 @@ If an authorized account member has configured a close custom form and the curre
### Reopen Incident
-Manually closing an incident changes progress to **Closed**. You can click **Close** in any status. Once manually closed, associated alerts stop merging new events. If alerts haven't recovered in the original monitoring system, new notification events may occur, triggering new alerts and incidents in Flashduty On-call.
-
-You can reopen accidentally closed incidents. Follow these steps:
+If you closed an incident by mistake, reopen it:
<Steps>
<Step title="Initiate reopen">
@@ -208,7 +206,7 @@ You can manually merge between incidents, or between incidents and alerts. Mergi
| Merge Alert to Incident | Alerts may be grouped into incidents by grouping rules, but you may want to adjust alert-incident associations. Go to alert details, click **Merge Into**, migrate the alert to target incident |
<Note>
-The essence of merging is: changing alert-incident associations. If all alerts of an incident merge into others, that incident closes directly, and you only need to handle the target incident. Timeline completely records your modification process.
+Merging changes which incident an alert belongs to. If all alerts of an incident are merged into others, that incident closes automatically and you only need to handle the target incident. The timeline records every merge.
</Note>
## FAQ
diff --git a/en/on-call/incident/search-view-incident.mdx b/en/on-call/incident/search-view-incident.mdx
index 8d4be9e3..aaeb1872 100644
--- a/en/on-call/incident/search-view-incident.mdx
+++ b/en/on-call/incident/search-view-incident.mdx
@@ -5,7 +5,7 @@ description: "Learn how to use the incident list and details page, including agg
## Incident List
-Flashduty On-call provides two entry points to view the incident list. One is within a channel, the other is under the Incident Management menu. The difference is that under Incident Management, you can see incidents from multiple channels, even all incidents across the entire account.
+The incident list has two entry points: the list inside a channel shows only that channel's incidents, while the list under the **Incident Management** menu spans channels, up to every incident in the account.
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/988781efcb13781c33c986b6f19ef1f9.png" alt="Incident List Interface" />
@@ -13,7 +13,7 @@ Flashduty On-call provides two entry points to view the incident list. One is wi
| # | Feature | Description |
| :---: | :--- | :--- |
-| 1 | Assignment toggle | A three-state control at the head of the filter bar: **All** / **Assigned to Me** (incidents where I am a responder) / **My Teams** (incidents in channels I belong to). It is mutually exclusive with the **Responders** and **Channels** filters in More Filters: manually selecting either one resets the toggle to **All** (manual selection takes precedence and is kept); the toggle only applies once those manual filters are cleared |
+| 1 | Assignment toggle | A three-state control at the head of the filter bar: **All** / **Assigned to Me** (I am a responder) / **My Teams** (in channels I belong to). Selecting **Responders** or **Channels** under **More Filters** resets the toggle to **All** and the manual filter wins; the toggle applies again once both filters are cleared |
| 2 | Time Filter | Supports relative time and custom range filtering |
| 3 | Severity | Filter incidents by severity |
| 4 | Processing Progress | Filter incidents by progress, defaults to **All** |
@@ -38,7 +38,7 @@ To improve performance, when search conditions match more than **1000** incident
### Using Aggregate View
-Aggregate view provides a different perspective for viewing incidents, where you can define different aggregation dimensions. The essence of aggregation dimensions is real-time Group By, such as viewing grouped by severity.
+Aggregate view groups incidents in real time by the dimensions you define (a live Group By), for example by severity.
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/c0b5d9a41a35c47f928da0d44e96f2aa.png" alt="Aggregate View" />
@@ -57,14 +57,14 @@ To improve performance, in aggregate view, the system matches at most **100** re
### Using More Filters
-Flashduty On-call provides filtering capabilities across various dimensions with ample flexibility. Typical scenarios include:
+**More Filters** lets you combine many dimensions. Common uses:
- Search for incidents triggered by the "Host Down" alert policy based on `check` label
- Search for incidents marked as "false positive" based on the false alarm field
- Set **Unfinished actions / follow-ups** to **Yes** to surface incidents that still have open work to wrap up
<Tip>
-Flexibility often means lower performance, and Flashduty On-call is no exception, despite our many performance optimizations. We always recommend narrowing your query time range and using conditions like **Assigned to Me** and **Processing Progress** to reduce query scope.
+For faster queries, narrow the time range and use conditions such as **Assigned to Me** and **Processing Progress** to reduce the scope.
</Tip>
### Saving Filter Views
@@ -73,6 +73,7 @@ Flexibility often means lower performance, and Flashduty On-call is no exception
The **Saving Filter Views** feature is temporarily offline. The filter bar currently offers no entry point for saving, applying, or managing filter views. It will be restored in a future release — stay tuned.
</Warning>
+<Accordion title="How it works once restored">
You can save the current filter conditions on the filter bar as a named **filter view** and reapply it with one click later — ideal for frequently used search combinations:
- **Save a view**: After configuring your filter conditions, save them as a named view; names must be unique, and each user can save at most **10** views
@@ -82,6 +83,7 @@ You can save the current filter conditions on the filter bar as a named **filter
<Note>
Filter views are saved per user and are only visible to you. A view saves all filter conditions except the **time range** — when you apply a view, the time range keeps your current selection.
</Note>
+</Accordion>
### Row content
@@ -122,7 +124,7 @@ Click the **Settings** button in the upper right corner of the incident list to
## Incident Details
-Incident details is the main entry point for investigating incidents, displaying all available information. Especially on the incident overview page, Flashduty On-call centrally displays the information you need most.
+Incident details is the main entry point for investigating an incident and shows everything known about it; the default **Incident Overview** tab gathers what you need most often.
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/390e0ab50c4747c881e6ed03c86b9742.png" alt="Incident Details Interface" />
@@ -138,18 +140,49 @@ Incident details is the main entry point for investigating incidents, displaying
### Label Deep Links
-Incident labels are displayed in the **Details** area of the details page. When an incident is aggregated from alerts produced by a monitoring integration (`monit.alert`) or a RUM integration (`rum.alert`), certain label values are rendered as deep links, letting you jump straight to the rule or issue that generated the alert:
+Incident labels appear in the **Details** area of the details page. For incidents aggregated from Monitors or RUM alerts, some labels show a link:
-| Integration Type | Label Key | Link Behavior |
+| Alert source | Label | Link |
| :--- | :--- | :--- |
-| `rum.alert` | `issue_id` | A **View Issue** link is rendered next to the label value, jumping to the corresponding issue in RUM error tracking |
-| `monit.alert` | `rule_id` | A **View Rule** link is rendered next to the label value, jumping to the standalone alert rule that generated the alert |
-| `monit.alert` | `__alert_rule_id` | A **View Rule** link is rendered next to the label value, jumping to the standalone alert rule that generated the alert. New data prefers this label; historical data falls back to `rule_id` |
-| `monit.alert` | `__entity_alert_rule_id` | A **View Rule** link is rendered next to the label value, jumping to the edit view of the corresponding alert rule in the entity tree |
+| RUM | `issue_id` | **View Issue**: opens the RUM issue |
+| Monitors alert rule | `__alert_rule_id` (`rule_id` for older data) | **View Rule**: opens the alert rule that generated the alert |
+| Monitors entity tree | `__entity_alert_rule_id` | **View Rule**: opens the alert rule in the entity tree |
+
+If a label value is invalid or the needed context is missing, it is shown as plain text. Labels on the alert details page support the same links.
+
+If a label carries the query from when the alert fired (such as PromQL or a log expression), an **Explore** icon appears on the right of the label. Clicking it opens the Query Workbench in a new tab with that query and a time window around the alert's start time; with several queries, pick one from the list.
+
+### AI Summary
-Jumping to an entity-tree rule requires contextual labels such as `__entity_alert_account_id`, `__entity_alert_entity_definition_id`, `__entity_alert_data_source_id`, and `__entity_alert_policy_scope_group_id` for locating; when any required label is missing or invalid, the label value is shown as plain text. Standalone alert rules (`rule_id` / `__alert_rule_id`) likewise require a positive integer value (e.g. `123`); when the value is empty, `0`, or non-numeric, the label is shown as plain text to avoid generating an invalid link. This deep-link capability also applies to the label area of the alert details page.
+<Tip>
+**Plan requirement**: This feature requires an On-call Pro or higher subscription. [Learn more](https://flashcat.cloud/flashduty/price/)
+</Tip>
-Additionally, when a label carries query-type information (such as the PromQL / log expression that was active when the alert triggered), an **Explore** icon appears on the right side of the label row. Clicking it opens the Query Workbench in a new tab, pre-filled with the alert's triggering query and a time window set around the alert's start time. A single query links directly; multiple queries (primary + related) display a popover list for selection.
+Click the **AI Summary** button in the details area to generate a structured summary from the incident's associated alerts (up to 20):
+
+- **Summary**: A one-sentence description of what happened
+- **Impacts**: Key affected resources such as services, systems, environments, and instances
+- **Actions**: Immediately actionable investigation and remediation steps (up to 3)
+
+AI Summary is always generated with the DeepSeek V4 Pro (`deepseek-v4-pro`) model; the console does not offer a model selector. The generated summary supports real-time streaming output, can be regenerated, and can be saved as the incident description.
+
+<Tip>
+AI Summary is only available for incidents automatically triggered by alerts. Manually created incidents do not support this feature.
+</Tip>
+
+### Comprehensive Info Panel
+
+The comprehensive info panel on the right side of the incident details page consolidates auxiliary information around the incident. From top to bottom:
+
+| Section | Description |
+| :--- | :--- |
+| **Attributes** | Basic attributes such as channel, incident trigger time, and alert count |
+| **Images** | Displayed when alerts associated with the incident include image information reported via API. Click a thumbnail to preview, and hover to view the Alt description and source link |
+| **Key Timestamps** | A timeline view of key timestamps in the incident lifecycle, including **trigger time**, **first acknowledgment time**, **close time**, and reopen events, so you can quickly grasp incident progress |
+| **Responders** | Lists all responders (individuals or on-call personnel) assigned to the incident along with their acknowledgment status |
+| **Related Links** | Shortcut links preconfigured in the owning channel (such as dashboards, runbooks, knowledge bases). Parameters are dynamically rendered from the current incident's labels or fields, enabling one-click navigation to related systems. Link templates are maintained in channel settings |
+| **Custom Fields** | Displays and allows editing of the incident's custom field values; unset fields are shown as `-` |
+| **External Tickets** | If you have configured ticket integrations such as Jira, ServiceNow, or ServiceDesk Plus, external tickets created from this incident appear here and can be clicked to open in the external system |
### Detail Tabs
@@ -165,30 +198,6 @@ The incident details page contains 7 tabs; some appear only under certain condit
| **Post-Mortem** | A built-in post-mortem editor that lets you create, edit, AI-generate, and publish a post-mortem report without leaving the details page | Subject to subscription tier; always visible when enabled |
| **Past Incidents** | Shows historical incidents similar to the current one, so you can draw on prior handling experience | Always visible |
-### Action Item and Follow-Up Events
-
-Every operation on [action items and follow-ups](/en/on-call/incident/work-items) is written to the timeline as an iconized record, displayed alongside comments, acknowledgments, and other events. The supported event types are:
-
-| Event Type | Timeline Record |
-| :--- | :--- |
-| `i_wi_created` | Created action / Created follow-up |
-| `i_wi_updated` | Updated action / Updated follow-up |
-| `i_wi_assignees` | Updated action assignees / Updated follow-up assignees |
-| `i_wi_completed` | Completed action / Completed follow-up |
-| `i_wi_converted` | Converted action to follow-up |
-| `i_wi_bound` | Linked follow-up to the post-mortem |
-| `i_wi_auto_converted` | Converted N unfinished actions to follow-ups: title, title… (a batch conversion on incident close; one record summarizes all items) |
-| `i_wi_deleted` | Deleted action / Deleted follow-up |
-
-### AI SRE Action Records
-
-Actions that AI SRE performed on behalf of a member — for example when an [automation rule](/en/ai-sre/automations) finishes a run and writes its conclusion back to the incident — are recorded on the timeline under a **joint signature**: the byline reads `{{name}} and AI SRE`, and both names carry equal weight because AI SRE acts with that member's identity and permissions. Such records are flagged `via: ai_sre` on the backend.
-
-- **Signature hover card**: hovering the **AI SRE** part of the byline opens a hover card that states "Acting as `{{name}}` with their permissions" and offers a **Continue conversation** button, which opens that session in the AI SRE panel
-- **Always-visible entry**: every AI-performed action row also carries a persistent **Continue conversation** entry with a ↗ icon, so you can jump straight into the session without hovering; one incident can contain several AI sessions, so the entry sits on each row rather than being a single incident-level entry
-
-Both entries require the AI SRE module to be enabled and the current member to hold the `AiSreChatVisit` permission. When the session is a personal session (visible only to its creator) or has expired, the always-visible entry is not rendered and the hover card shows "This session is visible only to its creator or has expired" instead; when the row has no associated session, the hover card shows "This action is not linked to a session".
-
### Timeline Comments
The top of the Timeline tab provides a Markdown comment box that supports:
@@ -204,7 +213,7 @@ The top of the Timeline tab provides a Markdown comment box that supports:
</Note>
<Tip>
-Posting a comment requires update permission on the incident. On the Timeline tab, the comment input box is always visible to all members, but only members with incident update permission see the **Send** button. On the incident overview page's "Recent Timeline" section, the **Leave Comment** button and the comment input box it opens are likewise visible only to members with update permission.
+Posting a comment requires update permission on the incident; members without it do not see the send controls.
</Tip>
### Comment Types
@@ -233,41 +242,28 @@ The operations and limits above (name up to **40** characters, 6 preset colors p
- Renaming, recoloring, deleting, and reordering must be done in the console
</Note>
-### War Room Operations
+### Action Item and Follow-Up Events
-If a war room has been created for the incident (requires enabling [War Room](/en/on-call/advanced/war-room) in IM integration), the **More** menu on the action bar reveals two additional war-room management actions:
+Every operation on [action items and follow-ups](/en/on-call/incident/work-items) is written to the timeline as an iconized record, alongside comments, acknowledgments, and other events: create, update, change assignees, complete, delete, convert an action to a follow-up, and link a follow-up to the post-mortem. Unfinished actions converted automatically when the incident closes are summarized in one record.
-| Action | Description |
+<Accordion title="Event type reference">
+| Event Type | Timeline Record |
| :--- | :--- |
-| **Invite Followers to War Room** | Pull additional members into the existing IM war room group for multi-party collaboration |
-| **Close War Room** | End the current war room and close the IM group. If collaboration is needed again later, you can create a new war room |
-
-<Note>
-War-room management actions are only visible when a war room already exists for the current incident; the create action is still initiated by the **Create War Room** button on the action bar.
-</Note>
-
-If the IM integration used by the war room is later disabled or deleted, **Invite Followers to War Room** and **Close War Room** both disappear (the original chat can no longer be operated on). The **View War Room** dialog then reads "The original integration is disabled or deleted. An administrator can unlink this war room without dissolving the group chat. Before creating another room, make sure the original group has been handled." and, for account owners/admins with incident update permission, offers a **Confirm unlink** button. That action only removes the link between the incident and the original group — it does **not** dissolve the chat — and the timeline records it as "Requested war room unlink".
-
-In the Flashduty App (mobile), war room behavior matches the console: the incident overview page shows a **War room** entry card (IM integrations with deep-link support open the chat directly; otherwise a dialog shows the group name to search for); **Create war room** lives in **More Actions** at the bottom, hidden when the incident already has a war room or is closed, and disabled with a toast when the incident has no responders; **Add stakeholders to war room** and **Dissolve war room** remain available after the incident is closed, but they do depend on the war room's IM integration being available — once it is disabled or deleted, both entries disappear from **More Actions**, while the overview entry card stays and shows "The integration is disabled or deleted. Ask an administrator to unlink the war room from the incident details on desktop. The original group chat will not be dissolved." on tap.
-
-### Post-Mortem
-
-The incident details page has a built-in post-mortem editor, allowing you to complete the entire post-mortem workflow without leaving the page. The action area includes a shortcut button that navigates directly to the **Post-Mortem** tab.
+| `i_wi_created` | Created action / Created follow-up |
+| `i_wi_updated` | Updated action / Updated follow-up |
+| `i_wi_assignees` | Updated action assignees / Updated follow-up assignees |
+| `i_wi_completed` | Completed action / Completed follow-up |
+| `i_wi_converted` | Converted action to follow-up |
+| `i_wi_bound` | Linked follow-up to the post-mortem |
+| `i_wi_auto_converted` | Converted N unfinished actions to follow-ups: title, title… (a batch conversion on incident close; one record summarizes all items) |
+| `i_wi_deleted` | Deleted action / Deleted follow-up |
+</Accordion>
-In the Post-Mortem tab, you can perform the following actions:
+### AI SRE Action Records
-| Action | Description |
-| :--- | :--- |
-| **Create** | Click the create button to start writing a post-mortem report |
-| **AI Generate** | Use AI to auto-generate initial post-mortem content, which you can then refine |
-| **Edit Title** | Modify the post-mortem report title to accurately reflect the incident |
-| **Edit Content** | Write and modify post-mortem content using the rich text editor |
-| **Publish** | Publish the post-mortem report to make it visible to the team |
-| **Re-edit** | Published post-mortem reports can be re-opened for editing |
-| **Delete** | Remove post-mortem reports that are no longer needed |
-| **Export Markdown** | Export the post-mortem report as Markdown for sharing or archiving on other platforms |
+Actions that AI SRE performed on behalf of a member (for example when an [automation rule](/en/ai-sre/automations) finishes a run and writes its conclusion back to the incident) are recorded on the timeline under the joint signature **`{{name}} and AI SRE`**, because AI SRE acts with that member's identity and permissions.
-See [Post-Mortem](/en/on-call/post-mortem/create-edit-post-mortem) for details.
+Each such row has a **Continue conversation** entry that opens the original session in the AI SRE panel (one incident can have several sessions). This requires AI SRE to be enabled for the account and permission to use AI SRE chat; personal sessions (visible only to their creator) and expired sessions cannot be continued.
### Change History
@@ -288,37 +284,28 @@ The change event list displays the following information:
You can adjust the query scope through the filter at the top, including time range and change source. Expand any row to view a timeline visualization of that change event, allowing comparison with the incident trigger time.
-### AI Summary
+### Post-Mortem
-The incident details page supports one-click AI summary generation to help you quickly understand the full picture of an incident. Click the **AI Summary** button in the details area, and the system will automatically generate a structured summary based on the incident's associated alerts (up to 20), including:
+The incident details page has a built-in post-mortem editor, and a shortcut button in the action area jumps straight to the **Post-Mortem** tab. There you can create a post-mortem, AI-generate a first draft, edit the title and rich-text content, publish, re-edit after publishing, delete, and export as Markdown.
-<Tip>
-**Plan requirement**: This feature requires an On-call Pro or higher subscription. [Learn more](https://flashcat.cloud/flashduty/price/)
-</Tip>
+See [Post-Mortem](/en/on-call/post-mortem/create-edit-post-mortem) for details.
-- **Summary**: A one-sentence description of what happened
-- **Impacts**: Key affected resources such as services, systems, environments, and instances
-- **Actions**: Immediately actionable investigation and remediation steps (up to 3)
+### War Room Operations
-AI Summary is always generated with the DeepSeek V4 Pro (`deepseek-v4-pro`) model; the console does not offer a model selector. The generated summary supports real-time streaming output, can be regenerated, and can be saved as the incident description.
+If a war room has been created for the incident (requires enabling [War Room](/en/on-call/advanced/war-room) in IM integration), the **More** menu on the action bar reveals two additional war-room management actions:
-<Tip>
-AI Summary is only available for incidents automatically triggered by alerts. Manually created incidents do not support this feature.
-</Tip>
+| Action | Description |
+| :--- | :--- |
+| **Invite Followers to War Room** | Pull additional members into the existing IM war room group for multi-party collaboration |
+| **Close War Room** | End the current war room and close the IM group. If collaboration is needed again later, you can create a new war room |
-### Comprehensive Info Panel
+<Note>
+War-room management actions are only visible when a war room already exists for the current incident; the create action is still initiated by the **Create War Room** button on the action bar.
+</Note>
-The comprehensive info panel on the right side of the incident details page consolidates auxiliary information around the incident. From top to bottom:
+If the war room's IM integration is disabled or deleted, **Invite Followers to War Room** and **Close War Room** are no longer shown. Account owners or admins with incident update permission can click **Confirm unlink** in **View War Room**: this only removes the link between the incident and the original group, does **not** dissolve the chat, and is recorded on the timeline.
-| Section | Description |
-| :--- | :--- |
-| **Attributes** | Basic attributes such as channel, incident trigger time, and alert count |
-| **Images** | Displayed when alerts associated with the incident include image information reported via API. Click a thumbnail to preview, and hover to view the Alt description and source link |
-| **Key Timestamps** | A timeline view of key timestamps in the incident lifecycle, including **trigger time**, **first acknowledgment time**, **close time**, and reopen events, so you can quickly grasp incident progress |
-| **Responders** | Lists all responders (individuals or on-call personnel) assigned to the incident along with their acknowledgment status |
-| **Related Links** | Shortcut links preconfigured in the owning channel (such as dashboards, runbooks, knowledge bases). Parameters are dynamically rendered from the current incident's labels or fields, enabling one-click navigation to related systems. Link templates are maintained in channel settings |
-| **Custom Fields** | Displays and allows editing of the incident's custom field values; unset fields are shown as `-` |
-| **External Tickets** | If you have configured ticket integrations such as Jira, ServiceNow, or ServiceDesk Plus, external tickets created from this incident appear here and can be clicked to open in the external system |
+War room actions in the Flashduty App (mobile) match the console; see [War Room · Mobile App](/en/on-call/advanced/war-room#mobile-app).
## FAQ
diff --git a/en/on-call/incident/work-items.mdx b/en/on-call/incident/work-items.mdx
index 34e262dd..94e304b7 100644
--- a/en/on-call/incident/work-items.mdx
+++ b/en/on-call/incident/work-items.mdx
@@ -85,8 +85,8 @@ In addition, reading and writing action items are constrained by the incident's
Once an incident is closed, the Actions card becomes read-only while the Follow-ups card unlocks for editing:
-- **Actions**: You cannot create, edit, or delete action items, nor change their status (the UI hides the add button and action entries, and the backend also rejects creating action items for closed incidents). At the moment of closing, the system already converted unfinished action items into follow-ups, so this card normally keeps only items that were completed or marked as won't do
-- **Follow-ups**: You can add, edit, complete, or delete follow-ups directly under the incident without creating a post-mortem report first; if the incident already has one, the backend back-fills the post-mortem link on newly created follow-ups
+- **Actions**: You cannot create, edit, or delete action items, nor change their status (the UI hides the add button and action entries, and creating action items for closed incidents through the API is rejected as well). At the moment of closing, the system already converted unfinished action items into follow-ups, so this card normally keeps only items that were completed or marked as won't do
+- **Follow-ups**: You can add, edit, complete, or delete follow-ups directly under the incident without creating a post-mortem report first; if the incident already has one, the post-mortem link is filled in automatically on newly created follow-ups
- There is no need to clear unfinished action items before closing an incident; if you want a piece of work to stay an action item, mark it **Completed** or **Won't do** before closing, otherwise it will be converted into a follow-up on close
## Further Reading
diff --git a/en/on-call/integration/alert-integration/alert-pipelines.mdx b/en/on-call/integration/alert-integration/alert-pipelines.mdx
index ea7a849b..81b65530 100644
--- a/en/on-call/integration/alert-integration/alert-pipelines.mdx
+++ b/en/on-call/integration/alert-integration/alert-pipelines.mdx
@@ -50,7 +50,7 @@ Pipeline sits between **Label Enhancement** and **Route Distribution**. Its exec
## Configuration Entry
-Go to **Integration Center** => Select created integration => **Alert Processing** tab.
+Go to **Integration Center** → Select created integration → **Alert Processing** tab.
<Frame>
<img src="https://download.flashcat.cloud/flashduty/doc/en/fd/pipeline-2.png" alt="Alert processing configuration entry" />
diff --git a/en/on-call/integration/alert-integration/alert-sources/aikido.mdx b/en/on-call/integration/alert-integration/alert-sources/aikido.mdx
index b40e3c4f..a3c57735 100644
--- a/en/on-call/integration/alert-integration/alert-sources/aikido.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/aikido.mdx
@@ -1,5 +1,6 @@
---
title: "Aikido Security alert integration"
+sidebarTitle: "Aikido Security"
description: "Send Aikido issue creation, severity change, and closure events to Flashduty On-call through a webhook."
keywords: ["alert integration", "Aikido", "Aikido Security", "webhook", "vulnerability", "issue_id"]
---
@@ -9,7 +10,6 @@ Use an Aikido Security webhook to send security issues to Flashduty On-call. Eac
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure in Aikido
----
<Steps>
<Step title="Create the webhook">
@@ -65,12 +64,10 @@ Let Aikido raise a new issue and confirm the alert reaches Flashduty. Then close
</Steps>
## Alert Key
----
Flashduty uses `payload.issue_id` as the Alert Key. Aikido's documentation defines it as the ID of the issue, and every event for the same issue carries it. Changes to severity, status, or event type do not change the Alert Key. An issue event without `payload.issue_id` is rejected, because later updates and recovery could not be matched to the alert.
## Status and severity
----
| Aikido `event_type` | Flashduty handling |
| :--- | :--- |
@@ -94,7 +91,6 @@ Flashduty uses `payload.issue_id` as the Alert Key. Aikido's documentation defin
The Aikido payload has no title field, so the alert title looks like `Aikido open_source issue #123 (critical)`. The issue type (`open_source`, `leaked_secret`, `cloud`, `iac`, `sast`, `surface_monitoring`, `malware`), `severity_score`, and `workspace_id` are stored as alert labels.
## Troubleshooting
----
- **Aikido gets a non-200 response and retries**: Aikido retries 5 times on a non-200 response or a timeout. Confirm the push URL is complete and includes `integration_key`
- **Flashduty returns a parameter error**: confirm the body is valid JSON and issue events carry `payload.issue_id`
diff --git a/en/on-call/integration/alert-integration/alert-sources/airbrake.mdx b/en/on-call/integration/alert-integration/alert-sources/airbrake.mdx
index b8b1d117..62a9c335 100644
--- a/en/on-call/integration/alert-integration/alert-sources/airbrake.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/airbrake.mdx
@@ -1,5 +1,6 @@
---
title: "Airbrake alert integration"
+sidebarTitle: "Airbrake"
description: "Send error notifications from an Airbrake project to Flashduty On-call through a webhook."
keywords: ["alert integration", "Airbrake", "webhook", "error monitoring", "exception monitoring"]
---
@@ -9,7 +10,6 @@ Use the Webhook integration of an Airbrake project to send error notifications t
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Airbrake
----
<Steps>
<Step title="Add a Webhook integration">
@@ -60,17 +59,14 @@ Airbrake's documentation does not describe a test notification body, so Flashdut
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from `error.id` (the Airbrake error ID) in the webhook body. Every notification for the same error uses the same Alert Key, and changes to the error message, occurrence count, environment, or last occurrence time do not change it. A notification without `error.id` is rejected.
## Severity
----
The Airbrake webhook carries no severity. Every notification is a Warning trigger.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -84,7 +80,6 @@ The Airbrake webhook carries no severity. Every notification is a Warning trigge
| `url` | Link to the error in Airbrake (`airbrake_error_url`) |
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: confirm the URL is complete and includes `integration_key`
- **Alerts do not recover**: Airbrake sends no recovery notification; turn on the channel's auto-close or close alerts manually
diff --git a/en/on-call/integration/alert-integration/alert-sources/alertsite.mdx b/en/on-call/integration/alert-integration/alert-sources/alertsite.mdx
index 9e54feb3..041e0c43 100644
--- a/en/on-call/integration/alert-integration/alert-sources/alertsite.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/alertsite.mdx
@@ -1,5 +1,6 @@
---
title: "SmartBear AlertSite alert integration"
+sidebarTitle: "SmartBear AlertSite"
description: "Send SmartBear AlertSite availability and performance alerts to Flashduty On-call through JSON alerts."
keywords: ["alert integration", "AlertSite", "SmartBear", "synthetic monitoring", "uptime", "webhook"]
---
@@ -9,7 +10,6 @@ Use AlertSite JSON alerts (POST JSON request to web server) to send monitor avai
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure AlertSite
----
<Steps>
<Step title="Create a JSON alert recipient">
@@ -68,14 +67,12 @@ Use the default JSON alert template. This integration reads the field names of t
</Warning>
## Alert Key
----
Flashduty computes the Alert Key from the alert type (availability or performance) and `device_id`. The AlertSite docs note that monitor names can change and recommend `device_id` as the identifier. The error and clear alerts of a monitor carry the same `device_id`, so they land on the same alert.
Availability alerts (`error` / `clear`) and performance alerts (`perf_warning` / `perf_error` / `perf_clear`) are keyed separately: a performance clear does not close an availability alert that is still failing. Changes to the monitor name, failing location, failing step, status code, time, or response time do not change the Alert Key. Flashduty rejects a request without `device_id`, because the later recovery could not be matched.
## Status and severity
----
| AlertSite `notify_type` | Flashduty status | Flashduty severity |
| :--- | :--- | :--- |
@@ -89,14 +86,12 @@ Availability alerts (`error` / `clear`) and performance alerts (`perf_warning` /
An empty or other `notify_type` is rejected, so a request whose state cannot be determined never lands in the wrong alert lifecycle.
## Alert content
----
- **Title**: the monitor name `device_name`
- **Description**: status text, failing location, URL, HTTP status, failing step, check time; the status of each location for rotated locations (`rotated_locations`); the response time and threshold of each location for performance alerts (`locations`)
- **Labels**: `device_id`, `device_type`, `custid`, `notify_type`, `alert_type` (`availability` or `performance`), `status_code` (the AlertSite status code, `0` means OK), `status_text`, `location`, `location_num`, `http_status`, `check` (monitor name), `resource` (the monitored URL), and `source` (always `alertsite`)
## Troubleshooting
----
- **AlertSite delivery fails**: make sure **Recipient** holds the full push URL, including `https://` and `integration_key`
- **Flashduty returns a parameter error**: make sure the default template is used and the request has `notify_type` and `device_id`
diff --git a/en/on-call/integration/alert-integration/alert-sources/aliyun-arms.mdx b/en/on-call/integration/alert-integration/alert-sources/aliyun-arms.mdx
index fce1e1ed..93c5b7ec 100644
--- a/en/on-call/integration/alert-integration/alert-sources/aliyun-arms.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/aliyun-arms.mdx
@@ -1,5 +1,6 @@
---
title: "Alibaba Cloud ARMS Integration"
+sidebarTitle: "Alibaba Cloud ARMS"
description: "Sync Alibaba Cloud ARMS monitoring alerts to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,42 +9,42 @@ Sync Alibaba Cloud ARMS monitoring alerts to Flashduty via webhook for automated
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alerts to different channels. It's simpler and recommended.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Alibaba Cloud ARMS** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alerts** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alerts** to enter the integration selection page
2. Select **Alibaba Cloud ARMS** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
-## In Alibaba Cloud ARMS
----
+## In Alibaba Cloud ARMS
**Step 1: Configure Notification Target**
<div class="md-block">
@@ -69,7 +70,6 @@ Choose this method when you need to route alerts to different channels based on
</div>
## Status Mapping
----
<div class="md-block">
Alibaba Cloud ARMS monitoring to Flashduty alert severity mapping:
diff --git a/en/on-call/integration/alert-integration/alert-sources/aliyun-cm-event.mdx b/en/on-call/integration/alert-integration/alert-sources/aliyun-cm-event.mdx
index db160711..aac2eba0 100644
--- a/en/on-call/integration/alert-integration/alert-sources/aliyun-cm-event.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/aliyun-cm-event.mdx
@@ -1,5 +1,6 @@
---
title: "Alibaba Cloud Monitor CM Event Integration"
+sidebarTitle: "Alibaba Cloud Monitor CM Event"
description: "Sync Alibaba Cloud Monitor event center alerts to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,48 +9,48 @@ Sync Alibaba Cloud Monitor event center alerts to Flashduty via webhook for auto
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler method when you don't need to route alerts to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Alibaba Cloud CM Event** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alerts** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alerts** to enter the integration selection page
2. Select **Alibaba Cloud CM Event** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Alibaba Cloud Monitor CM Event
----
**Step 1: Add Push Channel**
<div class="md-block">
1. Log in to your Alibaba Cloud Console and select Cloud Monitor
-2. Go to **Event Center -> Event Subscription** page, switch to the **Push Channels** tab, click Create Push Channel button to start editing
+2. Go to **Event Center → Event Subscription** page, switch to the **Push Channels** tab, click Create Push Channel button to start editing
3. As shown, select **POST** as the **Request Method**, and fill in the integration push URL in the **Address** field
4. Click Confirm button to submit the update
@@ -62,7 +63,7 @@ Choose this method when you need to route alerts to different channels based on
<div class="md-block">
1. Log in to your Alibaba Cloud Console and select Cloud Monitor
-2. Go to **Event Center -> Event Subscription** page, switch to the **Subscription Policies** tab, click Create Subscription Policy button to start editing
+2. Go to **Event Center → Event Subscription** page, switch to the **Subscription Policies** tab, click Create Subscription Policy button to start editing
3. Fill in the subscription name, select event type and scope, and configure the push channel as the Flashduty channel created earlier at the bottom
4. Click Confirm button to submit the update
5. The image below shows subscription results for both threshold and system event types
@@ -72,7 +73,6 @@ Choose this method when you need to route alerts to different channels based on
</div>
## Status Mapping
----
<div class="md-block">
Alibaba Cloud Monitor event alert to Flashduty severity level mapping:
diff --git a/en/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics.mdx b/en/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics.mdx
index 25c67ad9..3813abda 100644
--- a/en/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics.mdx
@@ -1,5 +1,6 @@
---
title: "Alibaba Cloud Monitor CM Metrics Integration"
+sidebarTitle: "Alibaba Cloud Monitor CM Metrics"
description: "Sync Alibaba Cloud Monitor alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,42 +9,42 @@ Sync Alibaba Cloud Monitor alert events to Flashduty via webhook for automated a
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Alibaba Cloud CM Metrics** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Alibaba Cloud CM Metrics** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Alibaba Cloud Monitor
----
Choose one of the following two methods:
**Method 1: Rule-based Configuration**
@@ -51,11 +52,11 @@ Choose one of the following two methods:
<div class="md-block">
1. Log in to your Alibaba Cloud Console and select Cloud Monitor
-2. Go to Alert Service -> Alert Rules page, select a rule, and click the Modify button to edit the rule content
+2. Go to Alert Service → Alert Rules page, select a rule, and click the Modify button to edit the rule content
3. As shown in the image, under Advanced Settings, enter the integration push URL as the callback address
4. Click Confirm to submit the update
-<img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/metric-1.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/metric-1.png" alt="drawing" width="500"/>
5. Repeat these steps for all alert rules you want to sync
6. Return to the integration list; if the latest event time is displayed, the configuration is successful and events are being received
@@ -68,11 +69,11 @@ Choose one of the following two methods:
<div class="md-block">
1. Log in to your Alibaba Cloud Console and select Cloud Monitor
-2. Go to Alert Service -> Alert Contacts page and select a contact to modify
+2. Go to Alert Service → Alert Contacts page and select a contact to modify
3. As shown in the image, enter the integration push URL under Webhook
4. Click Confirm to submit the update
-<img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/metric-2.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/metric-2.png" alt="drawing" width="500"/>
5. Repeat these steps for all contacts you want to sync events for
6. Return to the integration list; if the latest event time is displayed, the configuration is successful and events are being received
@@ -81,7 +82,6 @@ Choose one of the following two methods:
</div>
## Status Mapping
----
<div class="md-block">
Severity level mapping from Alibaba Cloud Monitor to Flashduty:
diff --git a/en/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op.mdx b/en/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op.mdx
index c865c0f3..2c5b9dc2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op.mdx
@@ -1,5 +1,6 @@
---
title: "Alibaba Cloud DataWorks Integration"
+sidebarTitle: "Alibaba Cloud DataWorks"
description: "Sync alert events from Alibaba Cloud DataWorks Intelligent Monitoring (Operation Center) to Flashduty On-call through a custom webhook, with automated alert noise reduction"
keywords: ["alert integration", "Alibaba Cloud DataWorks", "DataWorks Intelligent Monitoring", "Operation Center", "monitoring alerts", "data ingestion"]
---
@@ -8,7 +9,6 @@ keywords: ["alert integration", "Alibaba Cloud DataWorks", "DataWorks Intelligen
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following two ways.
### Use an exclusive integration
@@ -16,7 +16,7 @@ You can obtain an integration push URL in either of the following two ways.
Choose this option when you do not need to route alert events to different collaboration spaces. It is simpler.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Collaboration Spaces**, and open a space's detail page
2. Select the **Integrated Data** tab, click **Add an integration**, and open the add-integration page
@@ -32,9 +32,9 @@ Choose this option when you do not need to route alert events to different colla
Choose this option when you need to route alerts to different collaboration spaces based on the alert payload.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console and select **Integration Center => Alert Events** to open the integration selection page
+ 1. Go to the Flashduty console and select **Integration Center → Alert Events** to open the integration selection page
2. Select the **Alibaba Cloud DataWorks Operation Center** integration:
- **Integration name**: define a name for this integration
3. Configure the default route and select the corresponding collaboration space (after creation, you can go to `Routing` to configure more routing rules)
@@ -46,7 +46,6 @@ Choose this option when you need to route alerts to different collaboration spac
</div>
## In Alibaba Cloud DataWorks
----
**Step 1: Create a custom webhook**
<div className="md-block">
@@ -70,7 +69,6 @@ Choose this option when you need to route alerts to different collaboration spac
</div>
## Supported alert types
----
<div className="md-block">
DataWorks Intelligent Monitoring wraps every custom webhook message in a `message` field, distinguished by `message.title`. This integration supports the following three alert families:
@@ -86,7 +84,6 @@ The connectivity test message (`message.content`) is used only to verify the pus
</div>
## Severity mapping
----
<div className="md-block">
Mapping from custom alert `remind_type` to Flashduty severity:
@@ -122,7 +119,6 @@ Mapping from event alert `event_type`:
</div>
## Alert Key and alert merging
----
<div className="md-block">
DataWorks Intelligent Monitoring webhooks are **one-shot events**: the official protocol defines alert notifications only, with **no recovery** or update semantics, and it provides no vendor-level deduplication ID or fingerprint field. Therefore this integration never automatically recovers (closes) any alert; every event is delivered in a triggered state.
@@ -132,7 +128,6 @@ Every webhook delivery receives a fresh random UUID as its Alert Key, so each pu
</div>
## Field label mapping
----
<div className="md-block">
Key fields from the push message are preserved as labels on the alert event and can be used for routing, silencing, and template rendering:
@@ -156,7 +151,6 @@ Key fields from the push message are preserved as labels on the alert event and
</div>
## FAQ
----
<div className="md-block">
**Why are alerts never automatically recovered?**
diff --git a/en/on-call/integration/alert-integration/alert-sources/aliyun-prometheus.mdx b/en/on-call/integration/alert-integration/alert-sources/aliyun-prometheus.mdx
index 550f941e..b09098e3 100644
--- a/en/on-call/integration/alert-integration/alert-sources/aliyun-prometheus.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/aliyun-prometheus.mdx
@@ -1,5 +1,6 @@
---
title: "Alibaba Cloud Prometheus integration"
+sidebarTitle: "Alibaba Cloud Prometheus"
description: "Sync Alibaba Cloud Prometheus monitoring alert events to Flashduty On-call via webhook for automated alert noise reduction"
keywords: ["alert integration", "Alibaba Cloud Prometheus integration", "monitoring alerts", "data ingestion"]
---
@@ -7,7 +8,6 @@ keywords: ["alert integration", "Alibaba Cloud Prometheus integration", "monitor
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL through either of these two methods:
### Using private integration
@@ -15,7 +15,7 @@ You can obtain an integration push URL through either of these two methods:
Choose this method when you don't need to route alert events to different channels — it's simpler.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
@@ -30,9 +30,9 @@ Choose this method when you don't need to route alert events to different channe
Choose this method when you need to route alerts to different channels based on the alert event payload.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center => Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Alibaba Cloud Monitor Prometheus** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after creation, go to `Route` to configure more routing rules)
@@ -43,7 +43,6 @@ Choose this method when you need to route alerts to different channels based on
</div>
## In Alibaba Cloud
----
<Steps>
<Step title="Create a custom webhook">
@@ -74,7 +73,6 @@ Go back to the Flashduty console integration list page. If the latest event time
</Steps>
## Severity mapping
----
<div className="md-block">
Alibaba Cloud Prometheus to Flashduty severity mapping:
diff --git a/en/on-call/integration/alert-integration/alert-sources/aliyun-sls.mdx b/en/on-call/integration/alert-integration/alert-sources/aliyun-sls.mdx
index d09acace..fd270cb8 100644
--- a/en/on-call/integration/alert-integration/alert-sources/aliyun-sls.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/aliyun-sls.mdx
@@ -1,5 +1,6 @@
---
title: "Alibaba Cloud SLS Integration"
+sidebarTitle: "Alibaba Cloud SLS"
description: "Sync Alibaba Cloud Log Service (SLS) monitoring alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,42 +9,42 @@ Sync Alibaba Cloud Log Service (SLS) monitoring alert events to Flashduty via we
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alerts to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Alibaba Cloud SLS** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alerts** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alerts** to enter the integration selection page
2. Select **Alibaba Cloud SLS** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Alibaba Cloud SLS
----
**Step 1: Configure Webhook**
<div class="md-block">
@@ -51,11 +52,11 @@ Choose this option when you need to route alerts to different channels based on
1. Log in to your Alibaba Cloud Console, select Log Service (SLS), and choose a Project
2. Navigate to `Alert`->`Alert Management`->`Webhook Integration` page, click the `Create` button to start editing
-<img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/sls-1.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/sls-1.png" alt="drawing" width="500"/>
3. As shown, select "Generic Webhook" for `Type`, choose POST for `Request Method`, and enter the integration push URL (obtained after saving) for `Request URL`
-<img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/sls-2.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/sls-2.png" alt="drawing" width="500"/>
4. Click the `Confirm` button to save
@@ -68,11 +69,11 @@ Choose this option when you need to route alerts to different channels based on
1. Switch to the `Content Template` page and click the `Add` button to start editing
2. Enter the `Webhook-Custom` configuration, select "Send Individually" for `Send Method`, and copy the following content for `Send Content`:
-```
-{{ alert | to_json}}
-```
+ ```
+ {{ alert | to_json}}
+ ```
-<img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/sls-3.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/sls-3.png" alt="drawing" width="500"/>
3. Click the `Confirm` button to save
@@ -86,7 +87,7 @@ Choose this option when you need to route alerts to different channels based on
2. Enter the `First Action List` configuration and click to add an `Action Group` node
3. Select "Generic Webhook" for `Channel`, use previously created objects for `Select Webhook` and `Content Template`, and choose "Any" for `Send Period`
-<img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/sls-4.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/sls-4.png" alt="drawing" width="500"/>
4. Click `Finish` to complete the first action list creation
5. Click the `Confirm` button to save
@@ -101,7 +102,7 @@ Choose this option when you need to route alerts to different channels based on
2. Enter the `Alert Rule` editing page, `Alert Policy`
3. Select "Normal Mode" for `Alert Policy` and use the previously created object for `Action Policy`
-<img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/sls-5.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/aliyun/sls-5.png" alt="drawing" width="500"/>
4. Click the `Confirm` button to save
5. Repeat these steps for all other rules to push all alerts to Flashduty
@@ -109,7 +110,6 @@ Choose this option when you need to route alerts to different channels based on
</div>
## Status Mapping
----
<div class="md-block">
Alibaba Cloud SLS monitoring to Flashduty alert severity mapping:
@@ -125,7 +125,6 @@ Alibaba Cloud SLS monitoring to Flashduty alert severity mapping:
</div>
## Alibaba Cloud ActionTrail
----
<div class="md-block">
ActionTrail's "event alert" feature is provided by Log Service (SLS), not a separate push channel: first create a trail that delivers events to a Logstore, then configure an SLS alert on that Logstore. The notification channel reuses the webhook integration steps above — no separate integration is needed for ActionTrail.
diff --git a/en/on-call/integration/alert-integration/alert-sources/amazon-inspector.mdx b/en/on-call/integration/alert-integration/alert-sources/amazon-inspector.mdx
index a81373fb..6d3dea28 100644
--- a/en/on-call/integration/alert-integration/alert-sources/amazon-inspector.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/amazon-inspector.mdx
@@ -1,5 +1,6 @@
---
title: "Amazon Inspector Alert Integration"
+sidebarTitle: "Amazon Inspector"
description: "Send Amazon Inspector vulnerability and network reachability findings to Flashduty's AWS EventBridge integration through an EventBridge rule; alerts recover when a finding is closed or suppressed."
keywords: ["alert integration", "Amazon Inspector", "Inspector2", "vulnerability scanning", "EventBridge", "AWS"]
---
@@ -9,7 +10,6 @@ Amazon Inspector sends an **Inspector2 Finding** event to Amazon EventBridge whe
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the AWS EventBridge integration type** in both, not Amazon Inspector.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the AWS Ev
</div>
## Configure in AWS
----
Inspector emits events to the default event bus of each Region where it is enabled, so create the rule in every such Region.
@@ -67,7 +66,6 @@ Do not add `"status": ["ACTIVE"]` to the pattern. The notification example in th
Other Inspector events (`Inspector2 Scan`, `Inspector2 Coverage`, `Inspector2 AutoEnable`) are not findings and should not be forwarded to Flashduty; the `detail-type` above already excludes them.
## Field mapping
----
The mapping below is how Flashduty processes these AWS EventBridge events:
@@ -83,7 +81,6 @@ The mapping below is how Flashduty processes these AWS EventBridge events:
| Event `source`, `region`, `account`, `detail-type`, `detail`, `resources` | Labels `source`, `region`, `account`, `check`, `detail`, `resources` |
## Recovery and deduplication
----
- Inspector sends another event for the same `findingArn` when a vulnerability is fixed or a finding changes state. When `status` is `CLOSED` (fixed) or `SUPPRESSED`, Flashduty closes the alert.
- If the account is an Inspector delegated administrator, findings of member accounts are also delivered to it; use the label `aws_account_id` to tell the source account.
@@ -91,7 +88,6 @@ The mapping below is how Flashduty processes these AWS EventBridge events:
- The `detail` of code vulnerability findings contains file paths and detector names, which end up in the alert through the `detail` label.
## Troubleshooting
----
- **The API destination call fails**: confirm the endpoint is the full push URL including `integration_key` and that `HTTP method` is `POST`
- **Alerts do not recover**: check whether the rule's event pattern filters on `status`, and whether the target has an Input transformer (the full event must be sent)
diff --git a/en/on-call/integration/alert-integration/alert-sources/apcupsd.mdx b/en/on-call/integration/alert-integration/alert-sources/apcupsd.mdx
index ae31e583..0850d314 100644
--- a/en/on-call/integration/alert-integration/alert-sources/apcupsd.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/apcupsd.mdx
@@ -1,5 +1,6 @@
---
title: "apcupsd Alert Integration"
+sidebarTitle: "apcupsd"
description: "Push APC UPS on-battery, battery-failure and communication-loss events to the Flashduty Standard Alert Event integration through apcupsd event scripts; recovery events close the alerts."
keywords: ["alert integration", "apcupsd", "APC UPS", "UPS", "power outage", "apccontrol", "standard alert event"]
---
@@ -9,7 +10,6 @@ When apcupsd detects a UPS state change it calls `apccontrol`, which runs the ex
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the Standard Alert Event integration type** in both, not apcupsd.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the Standa
</div>
## Configure in apcupsd
----
### Step 1: Create the push script
@@ -114,7 +113,6 @@ Run the event scripts by hand on the host, first a trigger and then a recovery:
In Flashduty you should first see the alert `UPS myups: on battery` and then see it recover. Running `onbattery` by hand also runs whatever else the event file already contains; to test only the push, run `/etc/apcupsd/flashduty-notify.sh onbattery myups` directly.
## Recovery and deduplication
----
- `onbattery`, the failure events (`failing`, `timeout`, `loadlimit`, `runlimit`), `offbattery` and `mainsback` share the Alert Key `apcupsd:<UPS name>:power`: `onbattery` triggers the alert, a following failure event raises it to Critical, and it recovers when utility power returns
- `commfailure` and `commok`, and `battdetach` and `battattach`, are paired
@@ -122,7 +120,6 @@ In Flashduty you should first see the alert `UPS myups: on battery` and then see
- Alerts of several UPS units do not affect each other: the Alert Key contains the UPS name (the name configured in `apcupsd.conf`)
## Troubleshooting
----
- **No alert arrives**: confirm the file named after the event exists in `/etc/apcupsd` and is executable, and that `URL` in `flashduty-notify.sh` is correct; run the event file by hand and check the output
- **The alert does not recover**: confirm the recovery events (`offbattery`, `mainsback`, `commok`, `battattach`) are hooked too
diff --git a/en/on-call/integration/alert-integration/alert-sources/apimetrics.mdx b/en/on-call/integration/alert-integration/alert-sources/apimetrics.mdx
index 3c425cde..1ae3a79c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/apimetrics.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/apimetrics.mdx
@@ -1,5 +1,6 @@
---
title: "APIContext (APImetrics) alert integration"
+sidebarTitle: "APIContext (APImetrics)"
description: "Send failed, warning, slow and recovered API call results from the APIContext (formerly APImetrics) Performance Results Webhook to Flashduty On-call."
keywords: ["alert integration", "APIContext", "APImetrics", "API monitoring", "webhook", "call_id", "result_class"]
---
@@ -9,7 +10,6 @@ Use the APIContext (formerly APImetrics) Performance Results Webhook to send API
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure APIContext
----
<Steps>
<Step title="Add a Generic webhook">
@@ -65,7 +64,6 @@ With **Pass** on, every successful call sends a request to Flashduty. A `PASS` w
</Steps>
## Payload
----
APIContext sends JSON with an HTTP POST, one request per call result; no template is needed. Flashduty uses these fields:
@@ -86,14 +84,12 @@ APIContext sends JSON with an HTTP POST, one request per call result; no templat
The alert title is "call name: result", for example `Orders API: HTTP_SERVER_ERROR`.
## Alert Key
----
The Alert Key is computed from `call_id`, so each API call has one alert. The APIContext documentation describes `call_id` as a static ID that is the same every time the call is made, so the failure and the recovery of one call land on the same alert, whichever probe location reports them. With the default schedule each run executes from one random location, so a `PASS` from any location closes the call's alert and the next failure reopens it. `location_id` is kept as a label and in the description.
Changing the call name, result detail, response time or HTTP status code does not change the Alert Key. When a request has no `call_id`, Flashduty returns a parameter error because it cannot reliably match a recovery to its alert. A request with no `call_id`, `result_id` and `result_class` (such as an empty object) is treated as a test request: it returns success and creates no alert.
## Status and severity
----
| `result_class` | Flashduty status or severity |
| :--- | :--- |
@@ -106,7 +102,6 @@ Changing the call name, result detail, response time or HTTP status code does no
`SLOW` means the call succeeded but responded slowly. Flashduty records it as Warning and does not close an existing failure alert. To change a severity, rewrite it with a rule under the channel's **Configuration**.
## FAQ
----
<AccordionGroup>
<Accordion title="The alert does not recover automatically?">
@@ -129,7 +124,6 @@ No. The Alert Key of a call does not change, so repeated failure results merge i
</AccordionGroup>
## Troubleshooting
----
- **APIContext does not receive a success response**: confirm the URL is the full push URL and includes `integration_key`
- **Flashduty returns a parameter error**: the request body has no `call_id`. Confirm that you use the Generic webhook rather than an OpenTelemetry or other export type
diff --git a/en/on-call/integration/alert-integration/alert-sources/appdynamics.mdx b/en/on-call/integration/alert-integration/alert-sources/appdynamics.mdx
index a0007de4..4a7ce047 100644
--- a/en/on-call/integration/alert-integration/alert-sources/appdynamics.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/appdynamics.mdx
@@ -1,5 +1,6 @@
---
title: "AppDynamics Alert Integration"
+sidebarTitle: "AppDynamics"
description: "Sync AppDynamics alerts to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,58 +9,57 @@ Sync AppDynamics alerts to Flashduty via webhook for automated alert noise reduc
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alerts to different channels. It's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**, and enter the integration page
3. Choose **AppDynamics** integration and click **Save** to generate a card
4. Click the generated card to view the **Push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alerts**, and enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alerts**, and enter the integration selection page
2. Select **AppDynamics** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In AppDynamics
----
<div class="md-block">
-## I. AppDynamics Alert Push Configuration
### Step 1: Configure Flashduty Alert Channel
1. Log in to your AppDynamics console
2. Find `Alert Respond`, select `HTTP Request Templates`, and click `New` to create an alert channel
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-1.png" />
3. In the template configuration, enter **Flashduty** as the `Name`
4. In the `Request URL` section, select **POST** as the `Method`, and enter the integration push URL in `Raw URL` (enter the integration name on this page, and the URL will be generated after saving)
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-2.png" />
5. In the `Payload` section, select `application/json` as `MIME Type` and `UTF-8` as `Payload Encoding`
6. Paste the following content in the `Payload` text box:
@@ -118,7 +118,7 @@ If you need to configure `Custom Templating Variables`, you can refer to the fol
7. In the `Response Handling Criteria` section, set the `Failure Criteria` status code to 400 and the `Success Criteria` status code to 201
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-4.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-4.png" />
8. Click `Save` to complete
@@ -127,7 +127,7 @@ If you need to configure `Custom Templating Variables`, you can refer to the fol
1. Select `Actions` in the left navigation bar, choose the application type you want to create for, and click `Create`
2. In the `Create Action` popup, select `Make an HTTP Request` and click `OK`
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-6.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-6.png" />
3. In the `Create HTTP Action` popup, enter a Name, select **Flashduty** created in `Step 1` as the `HTTP Request Template`, and click `SAVE`
@@ -139,13 +139,13 @@ If you need to configure `Custom Templating Variables`, you can refer to the fol
2. Create or edit existing policies (configure alert rules as needed, alert rule configuration is omitted here)
3. In the `Actions` section of the policy configuration page, click add and select the Action created in `Step 2`
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-8.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-8.png" />
4. After completing other configurations, click `Save` to finish
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/appsignal.mdx b/en/on-call/integration/alert-integration/alert-sources/appsignal.mdx
index 0be8db83..4bcb4b45 100644
--- a/en/on-call/integration/alert-integration/alert-sources/appsignal.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/appsignal.mdx
@@ -1,5 +1,6 @@
---
title: "AppSignal alert integration"
+sidebarTitle: "AppSignal"
description: "Send AppSignal exception incidents, performance incidents, and anomaly detection alerts to Flashduty On-call through a webhook notifier."
keywords: ["alert integration", "AppSignal", "webhook", "APM", "anomaly detection", "error monitoring"]
---
@@ -13,7 +14,6 @@ Use the AppSignal Webhook notifier to send exception incidents, performance inci
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -34,7 +34,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## In AppSignal
----
<Steps>
<Step title="Add a Webhook notifier">
@@ -69,7 +68,6 @@ The AppSignal documentation does not describe a test button for the Webhook noti
</Steps>
## Events and recovery
----
| AppSignal payload | When it is sent | Effect in Flashduty |
| :--- | :--- | :--- |
@@ -82,7 +80,6 @@ The AppSignal documentation does not describe a test button for the Webhook noti
AppSignal notifies webhooks only on two anomaly detection transitions, opened and resolved. The warming up and cooldown phases send nothing.
## Alert Key
----
Flashduty builds the Alert Key from the object the event is about, so every delivery for one object shares one Alert Key:
@@ -94,17 +91,14 @@ Flashduty builds the Alert Key from the object the event is about, so every deli
Exception and performance incidents share one incident numbering. The Alert Key is computed from the object type and the fields above, so changes to the trigger name, current value, time, exception message, or revision do not change it. A delivery missing one of these fields is rejected, and the error names the field.
## Severity
----
AppSignal payloads carry no severity, so every alert is Warning in Flashduty, and a recovery moves it to recovered. To distinguish severity, use labels in the integration's routing or alert processing rules.
## Incidents do not recover
----
AppSignal sends no recovery for exception and performance incidents. In the channel that receives this integration, turn on the [auto-resolve timeout](/en/on-call/channel/create-edit). 24 hours is a reasonable start; adjust it to how quickly your team handles exceptions. A repeat occurrence of the same incident updates the same alert; once the alert is closed, the next occurrence creates a new one.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -123,7 +117,6 @@ AppSignal sends no recovery for exception and performance incidents. In the chan
| `url` | Link to the alert or incident in AppSignal |
## Troubleshooting
----
- **Flashduty returns an invalid parameter error**: confirm the URL is complete and includes `integration_key`
- **Nothing arrives**: confirm the Webhook notifier is selected on the trigger (alerts) or in the app's notification settings (incidents), and that the payload types are selected
diff --git a/en/on-call/integration/alert-integration/alert-sources/argocd.mdx b/en/on-call/integration/alert-integration/alert-sources/argocd.mdx
index 8412f226..29238203 100644
--- a/en/on-call/integration/alert-integration/alert-sources/argocd.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/argocd.mdx
@@ -1,5 +1,6 @@
---
title: "Argo CD alert integration"
+sidebarTitle: "Argo CD"
description: "Send Argo CD application sync failures and health degradation to Flashduty On-call through an Argo CD Notifications webhook service. Alerts close automatically when a sync succeeds or the application is healthy again."
keywords: ["alert integration", "Argo CD", "ArgoCD", "GitOps", "Notifications", "webhook", "Kubernetes"]
---
@@ -12,7 +13,6 @@ Argo CD pushes alerts through its built-in **Notifications** (`argocd-notificati
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -33,7 +33,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Argo CD
----
The steps below need Kubernetes permission to edit ConfigMaps in the Argo CD namespace (`argocd` by default) and to edit annotations on Applications or AppProjects. The Argo CD cluster must be able to reach the domain of the push URL.
@@ -160,7 +159,6 @@ Make a subscribed application fail to sync (for example, set a Deployment's imag
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from `event_type` and the application's `app_uid` (`app.metadata.uid`). Kubernetes gives every object a UID that is unique over the whole lifetime of the cluster, so:
@@ -173,7 +171,6 @@ Changes to the application name, project, revision, sync status, or error messag
Flashduty rejects a request that lacks `event_type` or `app_uid`, a sync message without `phase`, or a health message without `health_status`.
## Alert lifecycle
----
| `event_type` | Status field | Value | Flashduty action |
| :--- | :--- | :--- | :--- |
@@ -189,7 +186,6 @@ Status values are case-insensitive. Any other value is rejected.
If an application is deleted while its alert is open, Argo CD sends no recovery message. Close the alert by hand, or turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit) (24 hours suggested).
## Severity
----
| Alert | Severity |
| :--- | :--- |
@@ -199,7 +195,6 @@ If an application is deleted while its alert is open, Argo CD sends no recovery
To use one severity for every alert, append `&severity=Critical` (or `Warning`, `Info`) to the push URL. A recovery event keeps the severity of the original alert.
## Alert content
----
- **Title**: `Argo CD application <app-name> sync <phase>` or `Argo CD application <app-name> health <health_status>`
- **Description**: for a sync failure, the Argo CD sync result message (`operationState.message`); for health degraded, `Health status: Degraded`
@@ -208,7 +203,6 @@ To use one severity for every alert, append `&severity=Critical` (or `Warning`,
Empty fields are not written as labels.
## Troubleshooting
----
- **No alert arrives**: check the `argocd-notifications-controller` logs (`kubectl logs -n argocd deploy/argocd-notifications-controller`) and confirm that the application has the `notifications.argoproj.io/subscribe.on-flashduty.flashduty` annotation, or that `subscriptions` includes `on-flashduty`
- **The logs show `failed with error code 400`**: make sure the templates match this page and every value goes through `toJson`. The response body names the missing or unsupported field
diff --git a/en/on-call/integration/alert-integration/alert-sources/atatus.mdx b/en/on-call/integration/alert-integration/alert-sources/atatus.mdx
index 52bd94d6..81ba28e2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/atatus.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/atatus.mdx
@@ -1,5 +1,6 @@
---
title: "Atatus Alert Integration"
+sidebarTitle: "Atatus"
description: "Sync Atatus incident open and close notifications to Flashduty On-call through a Webhook notification channel."
keywords: ["alert integration", "Atatus", "APM", "Webhook", "Notification Channel", "Alert Policy", "incident_id"]
---
@@ -9,7 +10,6 @@ Sync Atatus incidents to Flashduty On-call through an Atatus Webhook notificatio
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Atatus
----
<Steps>
<Step title="Create a Webhook notification channel">
@@ -57,7 +56,6 @@ Trigger an alert rule and confirm Flashduty receives an active alert. After the
</Steps>
## Payload
----
Atatus POSTs these fields as `application/json`. Flashduty parses them directly, with no template to configure:
@@ -77,14 +75,12 @@ Atatus POSTs these fields as `application/json`. Flashduty parses them directly,
Other fields, including `target_name`, `acknowledge_url`, `account_id`, `alert_url` and `timestamp`, are not stored.
## Alert Key
----
Flashduty uses `incident_id` as the Alert Key. The open and close notifications of one Atatus incident carry the same `incident_id`, so they land on the same alert. What counts as one incident is set by the policy's **Incident preference** (by policy, by rule, or by rule and target), and Flashduty follows it.
A request without `incident_id` is rejected with a parameter error, because its close notification could not be matched to the original alert.
## Status and severity
----
| Atatus field | Flashduty status or severity |
| :--- | :--- |
@@ -96,7 +92,6 @@ A request without `incident_id` is rejected with a parameter error, because its
A request whose `status` is empty or any other value is rejected, so a request of unknown state never lands in the wrong lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="Does acknowledging an incident in Atatus affect the Flashduty alert?">
@@ -113,7 +108,6 @@ The channel test only checks that the URL is reachable and opens a separate Info
</AccordionGroup>
## Troubleshooting
----
- **Atatus fails to deliver**: confirm the URL is the full push URL and includes `integration_key`
- **Flashduty returns a parameter error**: confirm the request has `incident_id` and that `status` is `Opened`, `Closed` or `Acknowledged`
diff --git a/en/on-call/integration/alert-integration/alert-sources/auth0.mdx b/en/on-call/integration/alert-integration/alert-sources/auth0.mdx
index e5eca44b..602accf4 100644
--- a/en/on-call/integration/alert-integration/alert-sources/auth0.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/auth0.mdx
@@ -1,5 +1,6 @@
---
title: "Auth0 alert integration"
+sidebarTitle: "Auth0"
description: "Send attack protection, leaked password and failed login tenant logs to Flashduty On-call through an Auth0 custom webhook log stream."
keywords: ["alert integration", "Auth0", "log stream", "identity", "security alerts", "leaked password"]
---
@@ -9,7 +10,6 @@ Auth0 log streams deliver tenant logs in near real time to a custom webhook. Set
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Auth0
----
<Steps>
<Step title="Create the log stream">
@@ -39,12 +38,12 @@ You can get the integration push URL in either of the following ways.
2. Click **Create Log Stream**, select **Custom Webhook**, and enter a name
3. Fill in the following settings:
-| Setting | Value |
-| :--- | :--- |
-| Payload URL | The Flashduty push URL |
-| Content Type | `application/json` |
-| Content Format | JSON Lines, JSON Array, or JSON Object; all three are supported |
-| Authorization Token | Leave empty. Flashduty authenticates with the `integration_key` in the URL |
+ | Setting | Value |
+ | :--- | :--- |
+ | Payload URL | The Flashduty push URL |
+ | Content Type | `application/json` |
+ | Content Format | JSON Lines, JSON Array, or JSON Object; all three are supported |
+ | Authorization Token | Leave empty. Flashduty authenticates with the `integration_key` in the URL |
4. Under **Filter by Log Event Category**, select only the error and warning categories to reduce volume. Leaving it unfiltered also works, because Flashduty ignores success logs
5. Click **Save**
@@ -65,19 +64,16 @@ Auth0 log streams have no "send test notification" button.
</Steps>
## Events and recovery
----
Auth0 sends each tenant log once and never sends an update or a recovery. Each log has a unique `log_id`, which Flashduty uses as the Alert Key. A retried delivery of the same log does not create a duplicate alert, and different logs each create their own Flashduty alert. Alerts do not recover automatically.
Turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit) (24 hours suggested), or close alerts by hand after handling them. When the same source IP triggers many logs, configure a noise-reduction rule on the channel to merge them into one incident.
## Alert Key
----
The Alert Key is computed from the log's `log_id`. An alertable log without `log_id` is rejected with an invalid-parameter error.
## Severity
----
Severity follows the log type code (`type`); logs with any other type code are ignored:
@@ -92,7 +88,6 @@ Severity follows the log type code (`type`); logs with any other type code are i
For the full list of type codes, see [Auth0 log event type codes](https://auth0.com/docs/deploy-monitor/logs/log-event-type-codes).
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -109,7 +104,6 @@ For the full list of type codes, see [Auth0 log event type codes](https://auth0.
The alert description comes from the log's `description` and `details.error.message`. Flashduty does not read the user's email, the User-Agent, or other fields.
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: confirm Content Type is `application/json` and check the `integration_key` in the Payload URL
- **No alert arrives**: confirm the log type is in the table above, the Health tab shows Active, and the stream's event category filter does not exclude that type
diff --git a/en/on-call/integration/alert-integration/alert-sources/auvik.mdx b/en/on-call/integration/alert-integration/alert-sources/auvik.mdx
index c1e66b25..1a215e34 100644
--- a/en/on-call/integration/alert-integration/alert-sources/auvik.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/auvik.mdx
@@ -1,5 +1,6 @@
---
title: "Auvik alert integration"
+sidebarTitle: "Auvik"
description: "Send Auvik network monitoring alert triggered and cleared notifications to Flashduty On-call through a Webhook integration."
keywords: ["alert integration", "Auvik", "webhook", "network monitoring", "MSP"]
---
@@ -9,7 +10,6 @@ Use the Webhook integration of Auvik to send alerts on devices, interfaces, netw
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Auvik
----
Webhook integrations can be managed only from the MSP global view in Auvik, and you need the matching administrative permission. The webhook URL must use HTTPS, which the Flashduty push URL does.
@@ -70,12 +69,10 @@ Auvik requires standard English characters in organization names. Webhook alerts
</Note>
## Alert Key
----
Flashduty uses `correlationId` from the notification as the Alert Key. Auvik documents it as the unique API identifier of the alert trigger. The triggered and cleared notifications of one alert carry the same `correlationId` but different `alertId` values, so Flashduty does not use `alertId`. Changes to the alert name, severity, description, or time do not change the Alert Key. A notification that has a status but no `correlationId` is rejected.
## Status and severity
----
Flashduty derives the status from `alertStatusString` (or `alertStatus` when the string is missing) and the severity from `alertSeverity` (or `alertSeverityString` when the number is missing):
@@ -94,7 +91,6 @@ Flashduty derives the status from `alertStatusString` (or `alertStatus` when the
A missing or unrecognized severity is treated as Warning.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -108,7 +104,6 @@ A missing or unrecognized severity is treated as Warning.
| `url` | Link to the alert in Auvik |
## Troubleshooting
----
- **Test Connection fails**: Confirm the webhook URL is complete, includes `integration_key`, and uses HTTPS
- **No alerts arrive**: Confirm the notification channel is associated with the alerts and uses this Webhook integration as its contact method
diff --git a/en/on-call/integration/alert-integration/alert-sources/aws-cloudwatch.mdx b/en/on-call/integration/alert-integration/alert-sources/aws-cloudwatch.mdx
index 34c2e4a0..f0c286b2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/aws-cloudwatch.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/aws-cloudwatch.mdx
@@ -1,5 +1,6 @@
---
title: "AWS CloudWatch Integration"
+sidebarTitle: "AWS CloudWatch"
description: "Sync CloudWatch alarms, Cost Anomaly Detection, Amazon Managed Service for Prometheus and AWS Budgets notifications to Flashduty On-call through Amazon SNS"
---
@@ -8,42 +9,42 @@ This integration receives the HTTPS subscription of an Amazon SNS topic. The tri
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels. It's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **AWS CloudWatch** integration, click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **AWS CloudWatch** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## Configure in AWS
----
<div class="md-block">
1. Log in to the AWS console and open `Simple Notification Service`
@@ -52,13 +53,13 @@ Choose this method when you need to route alerts to different channels based on
4. Select `Flashduty` for `Topic ARN`, `HTTPS` for `Protocol`, and enter the integration push URL as `Endpoint`
5. Click `Create subscription`
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/aws-cloudwatch-subscribe.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/aws-cloudwatch-subscribe.png" />
6. Return to the `Subscriptions` page. The status `Confirmed` means Flashduty has confirmed the subscription
7. Open the `CloudWatch` console, go to `All alarms`, and create or edit an alarm
8. In the `Notification` step, select the SNS topic `Flashduty` for all three states: `In alarm`, `OK` and `Insufficient data`. Without `OK`, the alert does not recover automatically
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/aws-cloudwatch-alram.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/aws-cloudwatch-alram.png" />
9. Return to the integration list. A latest event time means events are arriving
@@ -69,7 +70,6 @@ The subscription works with **Raw message delivery** on or off. With raw deliver
</Note>
## Other AWS services that publish to SNS
----
Send the notifications of these services to the same `Flashduty` topic. No other setup is needed.
@@ -98,7 +98,6 @@ In the budget **Alert** settings, choose **Amazon SNS Alerts** and enter the ARN
Each unrecognized message (plain text or other JSON) creates one Warning alert. The Alert Key is the SNS `MessageId`, so an SNS retry of the same message does not create a second alert. The title is the SNS `Subject`, or the first line of the message when there is no subject. These alerts do not recover automatically.
## Alert Key
----
| Message | Alert Key | Recovers when |
| :--- | :--- | :--- |
@@ -110,7 +109,6 @@ Each unrecognized message (plain text or other JSON) creates one Warning alert.
`ALARM`, `INSUFFICIENT_DATA` and `OK` of a CloudWatch alarm share one Alert Key; changes to the alarm name, threshold, reason or description do not split the alert. A CloudWatch alarm message without `AlarmArn` is rejected.
## Status and severity
----
<div class="md-block">
CloudWatch alarms have no severity. `ALARM` and `INSUFFICIENT_DATA` map to Warning by default, and `OK` recovers the alert.
@@ -124,7 +122,6 @@ Order service CPU too high flashduty_severity: critical
</div>
## Labels
----
- Single-metric alarms: `trigger_metric_name`, `trigger_namespace`, `trigger_dimensions_<dimension name>` and more. When the dimensions include `InstanceId`, it is written to `resource`
- Metric math and anomaly detection alarms: each query writes `trigger_expression_<query ID>`, `trigger_metric_<query ID>` (`namespace/metric name`) and `trigger_dimensions_<dimension name>`. `metric` and `check` come from the query that returns data
@@ -132,7 +129,6 @@ Order service CPU too high flashduty_severity: critical
- All alarms: `alarm_arn`, `aws_account_id`, `region`, `new_state_value`, `old_state_value`
## Troubleshooting
----
- **Subscription stays in `Pending confirmation`**: Make sure the endpoint is the full push URL including `integration_key`, then run **Request confirmation** on the subscription in the SNS console
- **Flashduty returns a SubscribeURL error**: Flashduty only visits subscription confirmation URLs on `sns.<region>.amazonaws.com`, `sns.<region>.amazonaws.com.cn` and `sns.<region>.amazonaws.eu`. Make sure the subscription request comes from Amazon SNS
diff --git a/en/on-call/integration/alert-integration/alert-sources/aws-eventbridge.mdx b/en/on-call/integration/alert-integration/alert-sources/aws-eventbridge.mdx
index eac543ad..3277d448 100644
--- a/en/on-call/integration/alert-integration/alert-sources/aws-eventbridge.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/aws-eventbridge.mdx
@@ -1,5 +1,6 @@
---
title: "AWS EventBridge Alert Events"
+sidebarTitle: "AWS EventBridge"
description: "Sync CloudWatch alarm, GuardDuty, Security Hub, AWS Health, Inspector, Config and DevOps Guru events to Flashduty On-call through EventBridge, with automatic merging and recovery"
---
@@ -8,42 +9,42 @@ This integration receives Amazon EventBridge events, either pushed directly by a
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **AWS EventBridge** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event payload.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **AWS EventBridge** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## Configure in AWS EventBridge
----
Use either of the following delivery methods.
@@ -56,7 +57,7 @@ Use either of the following delivery methods.
2. Select `Integration=>API destinations` from the left navigation bar
3. Click `Connections`, then click `Create connection`
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/aws-eb-3.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/aws-eb-3.png" />
4. In the `Connection details` section, enter `Flashduty` for `Connection name`
5. In the `Authorization` section, select `Other` for `Destination type`
@@ -70,7 +71,7 @@ Use either of the following delivery methods.
1. Return to the `API destinations` interface and click `Create API destination`
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/aws-eb-5.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/aws-eb-5.png" />
2. Fill in the information in the `API destination detail` editing interface, enter `Flashduty` for `Name`
3. Enter the integration push URL for `API destination endpoint`
@@ -101,7 +102,6 @@ Use either of the following delivery methods.
Flashduty only visits subscription confirmation URLs on `sns.<region>.amazonaws.com`, `sns.<region>.amazonaws.com.cn` and `sns.<region>.amazonaws.eu`.
## Event rule
----
Use an event pattern in the rule, for example:
@@ -131,7 +131,6 @@ Do not filter out recovery states in the rule, or alerts cannot recover automati
AWS Health sends events to the Region where they occur; events of global services arrive in `us-east-1`. Create the rule in every Region you care about.
## Alert Key and recovery
----
| Source | `detail-type` | Alert Key | Recovers when |
| :--- | :--- | :--- | :--- |
@@ -150,7 +149,6 @@ AWS Health sends events to the Region where they occur; events of global service
- GuardDuty sends no event when a finding is archived, so close the alert manually
## Severity
----
EventBridge events have no common severity field, so every event triggers as Warning, as it always has. The source's own severity is kept in a label, and an [alert pipeline](/en/on-call/integration/alert-integration/alert-pipelines) can rewrite the severity based on it:
@@ -166,7 +164,6 @@ EventBridge events have no common severity field, so every event triggers as War
For CloudWatch alarms, set the severity with `flashduty_severity: critical` (`critical`, `warning` or `info`) in the **Alarm description**, the same way as in the [AWS CloudWatch integration](/en/on-call/integration/alert-integration/alert-sources/aws-cloudwatch).
## Title and labels
----
- The alert title is `source::detail-type`, for example `aws.guardduty::GuardDuty Finding`
- Every event carries the labels `source`, `region`, `account`, `check` (`detail-type`), `detail` (the event `detail` as JSON) and `resources`
@@ -174,7 +171,6 @@ For CloudWatch alarms, set the severity with `flashduty_severity: critical` (`cr
- Sources with dedicated handling also add source fields such as `finding_id`, `finding_arn`, `event_arn`, `config_rule_name` and `insight_id`; `resource` is the affected resource (DevOps Guru insights have none)
## Troubleshooting
----
- **API destination invocations fail**: Make sure the endpoint is the full push URL including `integration_key` and `HTTP method` is `POST`
- **SNS subscription stays in `Pending confirmation`**: Make sure the subscription points to this integration's push URL, then run **Request confirmation** in the SNS console
diff --git a/en/on-call/integration/alert-integration/alert-sources/aws-health.mdx b/en/on-call/integration/alert-integration/alert-sources/aws-health.mdx
index 3f21c793..4bc1d864 100644
--- a/en/on-call/integration/alert-integration/alert-sources/aws-health.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/aws-health.mdx
@@ -1,5 +1,6 @@
---
title: "AWS Health Alert Integration"
+sidebarTitle: "AWS Health"
description: "Receive AWS Health events through an Amazon EventBridge rule using the Flashduty AWS EventBridge integration; alerts recover automatically when the event closes."
keywords: ["alert integration", "AWS Health", "AWS Health Dashboard", "EventBridge", "service health", "scheduled change"]
---
@@ -9,7 +10,6 @@ AWS Health sends the service events that affect your account (operational issues
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the AWS EventBridge integration type** in both, not AWS Health.
@@ -30,31 +30,30 @@ Get an integration push URL in either of the two ways below. **Choose the AWS Ev
</div>
## Configure in AWS
----
AWS Health events are forwarded by an EventBridge rule whose target is an API destination that points to the Flashduty push URL (an SNS topic target also works). The steps for both target types are in the [AWS EventBridge integration](/en/on-call/integration/alert-integration/alert-sources/aws-eventbridge); for AWS Health you only need the event pattern below.
1. Create a rule in EventBridge with this event pattern:
-```json
-{
- "source": ["aws.health"],
- "detail-type": ["AWS Health Event"]
-}
-```
+ ```json
+ {
+ "source": ["aws.health"],
+ "detail-type": ["AWS Health Event"]
+ }
+ ```
2. To narrow the scope, add filters under `detail`. For example, only `issue` events for Amazon EC2:
-```json
-{
- "source": ["aws.health"],
- "detail-type": ["AWS Health Event"],
- "detail": {
- "eventTypeCategory": ["issue"],
- "service": ["EC2"]
- }
-}
-```
+ ```json
+ {
+ "source": ["aws.health"],
+ "detail-type": ["AWS Health Event"],
+ "detail": {
+ "eventTypeCategory": ["issue"],
+ "service": ["EC2"]
+ }
+ }
+ ```
3. Choose the API destination that points to the Flashduty push URL as the rule target and save the rule
4. While creating the rule, you can pick the AWS Health sample events in the **Test event pattern** panel of the EventBridge console to confirm the pattern matches
@@ -66,14 +65,12 @@ Do not filter out `statusCode` in the event pattern, for example by matching onl
</Warning>
## Regions and backup rules
----
- Create a rule in every Region you want to receive events from. Global events (for example IAM-related events) are delivered to US East (N. Virginia), `us-east-1`
- In the standard AWS partition, events are also sent to the backup Region US West (Oregon). If you create rules in both the primary and the backup Region, the same event arrives twice; both copies have the same `eventArn` and affected account, so Flashduty merges them into one alert through the same Alert Key
- To keep only the primary Region's events, add the filter `"backupEvent": ["false"]` (`detail.backupEvent`) to the backup Region rule
## Field mapping
----
| AWS Health field | Flashduty |
| :--- | :--- |
@@ -88,12 +85,10 @@ Do not filter out `statusCode` in the event pattern, for example by matching onl
| `region`, `account`, `resources`, `detail` | Labels `region`, `account`, `resources`, `detail` (`detail` holds the event detail as JSON) |
## Severity
----
EventBridge events carry no common severity field, so every AWS Health event triggers as Warning. To differentiate, rewrite the severity by the `event_type_category` label in [Alert processing](/en/on-call/integration/alert-integration/alert-pipelines), for example `issue` to Critical and `scheduledChange` kept at Warning or lowered to Info.
## Recovery and deduplication
----
- AWS Health sends an update with `statusCode` set to `closed` when the event ends, and Flashduty recovers the alert with the same Alert Key
- Scheduled changes (`scheduledChange`) are sent with status `upcoming` before they start, so Flashduty triggers alerts ahead of time. If you only care about ongoing incidents, restrict `eventTypeCategory` to `issue` in the event pattern
@@ -101,7 +96,6 @@ EventBridge events carry no common severity field, so every AWS Health event tri
- Events without `detail.eventArn` are rejected (HTTP 400)
## Troubleshooting
----
- **The rule does not fire**: check the event pattern; public events can take up to an hour after the rule is created; make sure rules exist in the event's Region and in `us-east-1` for global events
- **The alert does not recover**: confirm the event pattern does not filter out the `closed` status and that the target has no Input transformer (the full event must be sent)
diff --git a/en/on-call/integration/alert-integration/alert-sources/aws-security-hub.mdx b/en/on-call/integration/alert-integration/alert-sources/aws-security-hub.mdx
index 16848384..cd0b1887 100644
--- a/en/on-call/integration/alert-integration/alert-sources/aws-security-hub.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/aws-security-hub.mdx
@@ -1,5 +1,6 @@
---
title: "AWS Security Hub Alert Integration"
+sidebarTitle: "AWS Security Hub"
description: "Send AWS Security Hub findings to Flashduty's AWS EventBridge integration through an EventBridge rule; findings merge per finding and recover when their workflow status changes."
keywords: ["alert integration", "AWS Security Hub", "Security Hub", "ASFF", "EventBridge", "cloud security", "AWS"]
---
@@ -9,7 +10,6 @@ AWS Security Hub sends each finding to Amazon EventBridge as a **Security Hub Fi
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the AWS EventBridge integration type** in both, not AWS Security Hub.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the AWS Ev
</div>
## Configure in AWS
----
1. Follow "Option 1: API destination" in the [AWS EventBridge integration](/en/on-call/integration/alert-integration/alert-sources/aws-eventbridge) to create the Connection and API destination, using the Flashduty push URL as the endpoint. "Option 2: SNS topic" also works
2. In the EventBridge console, create a rule and choose **Rule with an event pattern** for **Rule type**
@@ -67,7 +66,6 @@ Do not filter on `Workflow.Status`, `RecordState`, `Compliance.Status` or `Sever
Create the rule in every Region where Security Hub is enabled. **Security Hub Findings - Custom Action** events, sent by custom actions, also carry findings and are handled the same way; add that `detail-type` to the rule if you use them.
## Field mapping
----
The `detail.findings` array of a **Security Hub Findings - Imported** event holds a single finding. The mapping below is how Flashduty processes these AWS EventBridge events:
@@ -82,14 +80,12 @@ The `detail.findings` array of a **Security Hub Findings - Imported** event hold
| Event `source`, `region`, `account`, `detail-type`, `detail` | Labels `source`, `region`, `account`, `check`, `detail` |
## Recovery and deduplication
----
- Changing a finding's workflow status to **Resolved** or **Suppressed** in Security Hub, or archiving the finding, produces a new **Security Hub Findings - Imported** event, and Flashduty closes the alert with the same Alert Key.
- When an event contains several findings, each finding becomes its own alert.
- If an event lacks `Id` or `ProductArn`, Flashduty returns HTTP 400.
## Troubleshooting
----
- **The API destination call fails**: confirm the endpoint is the full push URL including `integration_key` and that `HTTP method` is `POST`
- **Alerts do not recover**: check whether the rule's event pattern filters on `Workflow.Status` or `RecordState`, and whether the target has an Input transformer (the full event must be sent)
diff --git a/en/on-call/integration/alert-integration/alert-sources/axiom.mdx b/en/on-call/integration/alert-integration/alert-sources/axiom.mdx
index 76d68e13..6bc084d4 100644
--- a/en/on-call/integration/alert-integration/alert-sources/axiom.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/axiom.mdx
@@ -1,5 +1,6 @@
---
title: "Axiom alert integration"
+sidebarTitle: "Axiom"
description: "Use an Axiom custom webhook notifier to send monitor triggers and recoveries to Flashduty On-call."
keywords: ["alert integration", "Axiom", "Monitor", "Notifier", "Webhook"]
---
@@ -9,7 +10,6 @@ Use an Axiom custom webhook notifier to send monitor alerts to Flashduty On-call
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Axiom
----
<Steps>
<Step title="Create a custom webhook notifier">
@@ -96,7 +95,6 @@ Make a threshold monitor's condition actually hold (for example, lower the thres
</Steps>
## Alert Key
----
Flashduty builds the Alert Key from `event.monitorID`. When the notification carries groups (`event.groupKeys` is not empty), the group names and values are part of the Alert Key too. Axiom's documentation defines `.MonitorID` as the unique identifier of the monitor the notification belongs to; with **Notify by group** on, each group triggers separately and the notification carries that group's values.
@@ -105,7 +103,6 @@ Flashduty builds the Alert Key from `event.monitorID`. When the notification car
- Changes to the monitor name, description, current value, or times do not change the Alert Key
## Status and severity
----
Axiom notifications carry no severity, so Flashduty sets every Axiom alert to Critical. To use another severity, adjust it by the `check` or `monitor_id` label with an [Alert Pipeline](/en/on-call/integration/alert-integration/alert-pipelines).
@@ -116,7 +113,6 @@ Axiom notifications carry no severity, so Flashduty sets every Axiom alert to Cr
| Empty or any other value | Rejects the request |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -133,7 +129,6 @@ Axiom notifications carry no severity, so Flashduty sets every Axiom alert to Cr
The alert description is the notification's `event.body`: for a threshold monitor, the current value compared with the threshold; for a match monitor, the matched event.
## Troubleshooting
----
- **Flashduty returns a parameter error**: confirm the body is still the default template above and `monitorID` and `action` are not empty
- **The alert does not recover**: match monitors send no recovery, so turn on auto-close. A threshold monitor sends `Closed` only when a later run no longer crosses the threshold
diff --git a/en/on-call/integration/alert-integration/alert-sources/azure-monitor.mdx b/en/on-call/integration/alert-integration/alert-sources/azure-monitor.mdx
index e5f0d8f4..82b3ad2d 100644
--- a/en/on-call/integration/alert-integration/alert-sources/azure-monitor.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/azure-monitor.mdx
@@ -1,5 +1,6 @@
---
title: "Azure Monitor Integration"
+sidebarTitle: "Azure Monitor"
description: "Sync Azure Monitor alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,42 +9,42 @@ Sync Azure Monitor alert events to Flashduty via webhook for automated alert noi
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels. It's simpler and recommended.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Azure Monitor** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Azure Monitor** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Azure Monitor
----
**Step 1: Configure webhook**
<div class="md-block">
@@ -63,7 +64,7 @@ Flashduty also parses Azure's noncommon payloads when the common alert schema is
1. Go to `Alerts -> Alert rules` page, click Create or select an existing policy to edit;
2. As shown below, select the created Action group on the `Actions` page;
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/azure-mon/alert_rule.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/azure-mon/alert_rule.png" />
3. Save and wait for alerts to trigger.
@@ -72,7 +73,6 @@ Metric alerts, log search alerts, Prometheus alerts, Application Insights smart
</div>
## Service Health
----
<div class="md-block">
1. In the Azure Portal, go to `Service Health -> Health alerts` and click `Create service health alert`;
@@ -86,7 +86,6 @@ The Service Health sample sent by `Test action group` is at the `Resolved` stage
</div>
## Resource Health
----
<div class="md-block">
1. In the Azure Portal, go to `Service Health -> Resource health` and click `Add resource health alert`;
@@ -98,7 +97,6 @@ Each resource maps to one Flashduty alert, with the Alert Key derived from the r
</div>
## Defender for Cloud security alerts
----
<div class="md-block">
Defender for Cloud writes its security alerts to the `Security` category of the activity log. In `Alerts -> Alert rules`, create an alert rule whose condition is an activity log signal with category `Security`, and select the Action group created above.
@@ -108,7 +106,6 @@ With the common alert schema, the alert title is "alert rule name on resource na
</div>
## Other activity log alerts
----
<div class="md-block">
Administrative, Policy, Autoscale, and Recommendation activity log alerts are one-shot events: each notification creates one Flashduty alert that does not recover automatically. With the common alert schema, the alert title is "alert rule name on resource name" and the operation goes into the `operation_name` label. Without it, the payload has no rule name, so the title is "operation on resource", for example `Microsoft.Compute/virtualMachines/restart/action on test-VM`.
@@ -116,7 +113,6 @@ Administrative, Policy, Autoscale, and Recommendation activity log alerts are on
</div>
## Alert Key and recovery
----
<div class="md-block">
| Alert type | Alert Key source | Recovers when |
@@ -133,7 +129,6 @@ Dimensions of metric and log alerts (for example `ApiName` or `Computer`), the m
</div>
## Status mapping
----
<div class="md-block">
Azure Monitor to Flashduty alert severity mapping:
@@ -151,7 +146,6 @@ Noncommon metric alerts and Log Alerts V1 express severity as `0` to `4`, mapped
</div>
## FAQ
----
<div class="md-block">
- **Azure reports a failed webhook call (400)**: check whether the log search alert uses a custom JSON payload. Enable the common alert schema and retry.
diff --git a/en/on-call/integration/alert-integration/alert-sources/azure-service-health.mdx b/en/on-call/integration/alert-integration/alert-sources/azure-service-health.mdx
index 3cea2f72..4646b741 100644
--- a/en/on-call/integration/alert-integration/alert-sources/azure-service-health.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/azure-service-health.mdx
@@ -1,5 +1,6 @@
---
title: "Azure Service Health Alert Integration"
+sidebarTitle: "Azure Service Health"
description: "Receive Azure service events through a Service Health alert rule and an action group webhook using the Flashduty Azure Monitor integration; alerts recover automatically when the event is resolved."
keywords: ["alert integration", "Azure Service Health", "action group", "webhook", "Azure Monitor"]
---
@@ -9,7 +10,6 @@ Azure writes service issues, planned maintenance, health advisories and security
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the Azure Monitor integration type** in both, not Azure Service Health.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the Azure
</div>
## Configure in Azure
----
### Step 1: Create an action group with a webhook
@@ -51,7 +50,6 @@ Azure requires that the action group used by a Service Health alert has its regi
5. Click **Advanced options**, select the action group from Step 1 on the **Actions** tab, and create the rule
## Field mapping
----
| Service Health field | Flashduty |
| :--- | :--- |
@@ -64,7 +62,6 @@ Azure requires that the action group used by a Service Health alert has its regi
| Subscription ID + `trackingId` | Label `service_health_url`, which links to the event's Service Health page |
## Title and description
----
| | Common alert schema on | Off (legacy `Microsoft.Insights/activityLogs`) |
| :--- | :--- | :--- |
@@ -75,14 +72,12 @@ Azure requires that the action group used by a Service Health alert has its regi
With the common schema, the event title and text stay in the JSON of the `alertContext` label. If you want the event title directly in notifications, use the legacy payload (leave the common alert schema off).
## Recovery and deduplication
----
- Azure sends several notifications for one Tracking ID as the event progresses, and Flashduty merges them through the Alert Key; the alert recovers when the event reaches a resolved stage
- Legacy notifications without `properties.trackingId` are rejected (HTTP 400); with the common schema, a notification without a Tracking ID becomes its own alert and does not recover automatically
- Planned maintenance recovers in the `Complete` or `Canceled` stage; until then, the alert stays triggered
## Troubleshooting
----
- **The action group does not fire**: confirm the action group's region is **Global** and that the alert rule's **Actions** tab has this action group selected
- **The alert does not recover**: confirm the alert rule is still enabled and wait for Azure to send the notification for the resolved stage
diff --git a/en/on-call/integration/alert-integration/alert-sources/baidu-bcm.mdx b/en/on-call/integration/alert-integration/alert-sources/baidu-bcm.mdx
index 6fc87a23..d511b324 100644
--- a/en/on-call/integration/alert-integration/alert-sources/baidu-bcm.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/baidu-bcm.mdx
@@ -1,5 +1,6 @@
---
title: "Baidu Cloud BCM Integration"
+sidebarTitle: "Baidu Cloud BCM"
description: "Sync Baidu Cloud BCM alerts to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,42 +9,42 @@ Sync Baidu Cloud BCM alerts to Flashduty via webhook for automated alert noise r
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alerts to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Baidu Cloud BCM** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alerts** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alerts** to enter the integration selection page
2. Select **Baidu Cloud BCM** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Baidu Cloud BCM
----
<div class="md-block">
1. Log in to your Baidu Cloud Console, search for the `Cloud Monitor` product, and enter its console
@@ -51,14 +52,13 @@ Choose this option when you need to route alerts to different channels based on
3. Go to the `Alert Management-Alert Policy` page, choose to edit an existing policy or create a new one
4. In the alert policy, fill in the integration push URL in the `Callback URL` field (enter the integration name on the current page, and the URL will be generated after saving)
-<img src="https://download.flashcat.cloud/flashduty/doc/en/baidu/bcm-1.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/baidu/bcm-1.png" alt="drawing" width="500"/>
5. Done
</div>
## Status Mapping
----
<div class="md-block">
Severity level mapping from Baidu Cloud Monitor to Flashduty:
diff --git a/en/on-call/integration/alert-integration/alert-sources/bgpalerter.mdx b/en/on-call/integration/alert-integration/alert-sources/bgpalerter.mdx
index 9916f773..f89bce0c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/bgpalerter.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/bgpalerter.mdx
@@ -1,5 +1,6 @@
---
title: "BGPalerter alert integration"
+sidebarTitle: "BGPalerter"
description: "Send BGP hijacks, prefix visibility loss, RPKI-invalid announcements, and other BGPalerter events to Flashduty On-call through the reportHTTP report module."
keywords: ["alert integration", "BGPalerter", "BGP", "BGP hijack", "RPKI", "prefix monitoring", "webhook"]
---
@@ -11,7 +12,6 @@ BGPalerter sends each event once and never sends a recovery notification. Close
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure BGPalerter
----
BGPalerter has no fixed webhook format: the request body comes from the `reportHTTP` template in `config.yml`. Flashduty parses only the JSON that the template below produces, so use it as is.
@@ -87,7 +86,6 @@ BGPalerter has no "send test notification" button. Running `bgpalerter -t` (in D
</Steps>
## Events and recovery
----
Each channel in `channels` is one kind of event:
@@ -106,7 +104,6 @@ Each channel in `channels` is one kind of event:
BGPalerter sends no recovery notification, so Flashduty never closes these alerts automatically. Turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit) (24 hours suggested). Hijack events usually need a human check, so you can also close them by hand once handled.
## Alert Key
----
Flashduty computes the Alert Key from the routing facts of the event: the channel (`channel`), the monitored prefix (`prefix`), the monitored AS (`asn`), the new origin AS (`neworigin`), and the prefix actually announced (`newprefix`). BGPalerter itself groups hijack events by origin AS and prefix.
@@ -118,7 +115,6 @@ Flashduty computes the Alert Key from the routing facts of the event: the channe
A request without `channel`, or without any of prefix, AS, and summary, is rejected with an error.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -136,7 +132,6 @@ A request without `channel`, or without any of prefix, AS, and summary, is rejec
The alert title is BGPalerter's event summary, and the description is the prefix description.
## Troubleshooting
----
- **Flashduty receives no alerts**: check that `hooks.default` is the full HTTPS push URL with `integration_key`. BGPalerter only writes a failed post to its own log and does not retry
- **BGPalerter logs a JSON parse error**: check the prefix descriptions in `prefixes.yml` for double quotes or line breaks
diff --git a/en/on-call/integration/alert-integration/alert-sources/bigpanda.mdx b/en/on-call/integration/alert-integration/alert-sources/bigpanda.mdx
index 1638fb9c..92656323 100644
--- a/en/on-call/integration/alert-integration/alert-sources/bigpanda.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/bigpanda.mdx
@@ -1,5 +1,6 @@
---
title: "BigPanda alert integration"
+sidebarTitle: "BigPanda"
description: "Send the incidents BigPanda creates by correlating alerts to Flashduty On-call through BigPanda's Notifications Webhook v2 integration."
keywords: ["alert integration", "BigPanda", "AIOps", "Notifications Webhook v2", "AutoShare", "incident.id"]
---
@@ -11,7 +12,6 @@ Notifications Webhook v2 can currently only be created and updated through BigPa
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -20,7 +20,7 @@ You can obtain an integration push URL in either of the following ways.
Choose this method when you do not need to route alerts to different channels.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View dedicated integration setup steps">
1. In the Flashduty console, select **Channel** and open a channel
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**
@@ -35,7 +35,7 @@ Choose this method when you do not need to route alerts to different channels.
Choose this method when you need to route alerts to different channels based on the payload.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View shared integration setup steps">
1. In the Flashduty console, select **Integration Center → Alert Events**
2. Select **BigPanda** and enter an integration name
@@ -48,14 +48,12 @@ Choose this method when you need to route alerts to different channels based on
</div>
## Prerequisites
----
- **Permissions**: calling the Notifications Webhook v2 API needs the **Integrations** permission; creating an AutoShare rule needs the **Notifications** permission (view, add, edit, and delete AutoShare rules).
- **Authentication**: the Notifications Webhook v2 API currently only accepts credentials from a **User Account** — a Service Account cannot call it.
- This integration does not parse a fixed BigPanda schema. It parses the JSON template you paste into the request body in step one below — keep the field names exactly as given.
## Configure BigPanda
----
<Steps>
<Step title="Create the Notifications Webhook v2 integration">
@@ -120,14 +118,12 @@ Trigger a real alert in that environment (or wait for the next real one) and con
</Steps>
## Alert Key
----
Flashduty uses the request body's `incident_id` (from BigPanda's template variable `{{incident.id}}`) directly as the Alert Key. BigPanda's documentation defines `incident.id` as the incident's system-generated unique identifier; an incident's creation, updates, and closure all share the same `incident.id`.
Changes to `status`, `environment`, `host`, `check`, `description`, or `url` do not change the Alert Key.
## Status and severity
----
| BigPanda `incident.status` | Flashduty status | Flashduty severity |
| :--- | :--- | :--- |
@@ -139,7 +135,6 @@ Changes to `status`, `environment`, `host`, `check`, `description`, or `url` do
`incident.status` is the most severe status among the incident's correlated alerts. `unknown` means BigPanda could not determine health from the correlated alerts; the incident is still open, so it is treated as Warning. An empty or unrecognized `status` is rejected.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -153,7 +148,6 @@ Changes to `status`, `environment`, `host`, `check`, `description`, or `url` do
The alert title uses `check` first; when the template's `{{primaryAlert.tags.check}}` is empty, it falls back to `description`.
## FAQ
----
<AccordionGroup>
<Accordion title="I created the integration but never received any request.">
diff --git a/en/on-call/integration/alert-integration/alert-sources/bitdefender.mdx b/en/on-call/integration/alert-integration/alert-sources/bitdefender.mdx
index 857b6b25..f013a357 100644
--- a/en/on-call/integration/alert-integration/alert-sources/bitdefender.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/bitdefender.mdx
@@ -1,5 +1,6 @@
---
title: "Bitdefender GravityZone alert integration"
+sidebarTitle: "Bitdefender GravityZone"
description: "Send malware, ransomware, network attack and incident detections from Bitdefender GravityZone to Flashduty On-call through the Event Push Service."
keywords: ["alert integration", "Bitdefender", "GravityZone", "Event Push Service", "EDR", "security"]
---
@@ -9,7 +10,6 @@ The GravityZone Event Push Service posts detection events to a URL as JSON-RPC 2
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the push URL in either of the following ways.
</div>
## In GravityZone
----
The Event Push Service is configured only through the GravityZone public API; the console has no screen for it.
@@ -99,12 +98,10 @@ Flashduty opens a separate Info alert titled `Bitdefender GravityZone test notif
</Steps>
## Turn on auto-close
----
Detection events are one-shot, and GravityZone never pushes a recovery. In the channel that receives them, turn on [auto-close](/en/on-call/channel/create-edit) with a suggested duration of 24 hours, counted from **Incident trigger**. While an alert is open, a repeat detection of the same threat merges into it; a detection after it closes creates a new alert.
## Supported event types
----
Only the detection events in the table create alerts. Status and inventory events (such as `modules`, `sva`, `registration`, `task-status`, `install`, `uninstall`, `uc` and `adcloud`) are ignored: Flashduty returns success and does nothing, so do not subscribe to them.
@@ -126,19 +123,16 @@ Only the detection events in the table create alerts. Status and inventory event
GravityZone publishes no severity scale for detection events, so these levels are a mapping made from the event fields. To change them, configure routing or alert processing rules on labels in the channel.
## Alert Key
----
GravityZone detection events have no event ID, so Flashduty builds the Alert Key from the parts of an event that do not change: `module`, `companyId`, the endpoint ID (`computer_id`, or `endpointId` for Sandbox Analyzer), and the threat identity of that event type. Antimalware uses the malware type, name and file path; Antiphishing uses the phishing type and URL; Ransomware Mitigation uses the attack type and attack source. Changes to the action taken, counters, times, hashes, host name and IP do not change the Alert Key.
Incidents use `incident_id`. `new-incident` and `new-extended-incident` share one Alert Key, so version updates of one incident merge into one alert. Events without an endpoint ID or `incident_id` are rejected.
## Batches
----
One `addEvents` request can carry several events. Flashduty creates one alert per event and processes them sorted by Alert Key. It handles at most 100 events per request; the rest create no alerts and the response returns an error. If one event is malformed, the others are still created and the response names the malformed event's position and the reason.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -153,12 +147,10 @@ One `addEvents` request can carry several events. Flashduty creates one alert pe
User names, mail senders and recipients, mail subjects and incident nodes (`nodes`) are never written to labels or the description.
## About signatures
----
GravityZone sends `md5(api_key, md5(request body))` in the `Event-Push-Service-Md5` header, and you can set an `authorization` header in `serviceSettings`. Flashduty verifies neither. The `integration_key` in the push URL is the only credential, so keep it safe.
## Troubleshooting
----
- **`setPushEventSettings` returns an error**: confirm the API key has Event Push Service API selected and that `serviceType` is `jsonRPC`
- **Flashduty receives nothing**: confirm the push URL is a publicly reachable HTTPS address that supports TLS 1.2 or later; GravityZone treats anything other than a 2xx response as a failure
diff --git a/en/on-call/integration/alert-integration/alert-sources/bleemeo.mdx b/en/on-call/integration/alert-integration/alert-sources/bleemeo.mdx
index dad23b20..69ba59af 100644
--- a/en/on-call/integration/alert-integration/alert-sources/bleemeo.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/bleemeo.mdx
@@ -1,5 +1,6 @@
---
title: "Bleemeo alert integration"
+sidebarTitle: "Bleemeo"
description: "Send Bleemeo metric status changes, both alerts and recoveries, to Flashduty On-call through a webhook integration."
keywords: ["alert integration", "Bleemeo", "monitoring", "webhook", "status change"]
---
@@ -9,7 +10,6 @@ Use a Bleemeo webhook integration to send metric status changes to Flashduty On-
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Bleemeo
----
<Steps>
<Step title="Add a webhook notification target">
@@ -56,7 +55,6 @@ Push a metric past its threshold (for example, temporarily lower a CPU usage thr
</Steps>
## Payload
----
Bleemeo POSTs a JSON notification. Flashduty parses it directly, with no template to configure:
@@ -70,14 +68,12 @@ Bleemeo POSTs a JSON notification. Flashduty parses it directly, with no templat
| `status_text` | Status text | Label `status_text` |
## Alert Key
----
Flashduty uses `metric` as the Alert Key. The alert and recovery notifications of one metric carry the same `metric`, so they land on the same alert, while different metrics produce different alerts. The top-level `id` is not part of the Alert Key, and changes to the title, value, or time do not change it.
If `metric` is missing, Flashduty returns a parameter error, because a recovery cannot be reliably matched to its alert.
## Status and severity
----
| Bleemeo `status` | Flashduty status or severity |
| :--- | :--- |
@@ -89,7 +85,6 @@ If `metric` is missing, Flashduty returns a parameter error, because a recovery
A request with an empty or any other `status` is rejected, so a request whose state is unclear never enters the wrong alert lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="Which Bleemeo plan includes webhooks?">
@@ -112,7 +107,6 @@ No. `3` (Unknown) is handled as Warning, and only `0` (OK) closes the alert.
</AccordionGroup>
## Troubleshooting
----
- **The test notification opens an Info alert**: the test sent after saving a target has no metric and is recognised by its fixed body (status `10`, title `Test`); it opens its own Info alert that never recovers, so close it manually
diff --git a/en/on-call/integration/alert-integration/alert-sources/blueking.mdx b/en/on-call/integration/alert-integration/alert-sources/blueking.mdx
index dc3ce403..d6f7cd94 100644
--- a/en/on-call/integration/alert-integration/alert-sources/blueking.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/blueking.mdx
@@ -1,5 +1,6 @@
---
title: "Tencent BlueKing Integration"
+sidebarTitle: "Tencent BlueKing"
description: "Sync Tencent BlueKing monitoring events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,47 +9,47 @@ Sync Tencent BlueKing monitoring events to Flashduty via webhook for automated a
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alerts to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Tencent BlueKing** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're Done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to Flashduty console, select **Integration Center=>Alerts** to enter the integration selection page
+ 1. Go to Flashduty console, select **Integration Center → Alerts** to enter the integration selection page
2. Select **Tencent BlueKing** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Tencent BlueKing
----
The following content has been verified on `BlueKing V6/7 versions`. V5 and below versions are no longer officially supported, and upgrading is recommended.
BlueKing alert policies can trigger `Action Plans`, which can integrate with external systems for complex functionalities. First, create an Action Plan and configure the Flashduty callback URL, then edit the alert policy to associate actions with this plan, enabling automatic alert changes to be pushed to Flashduty. Here are the specific steps:
-#### Step 1: Create Action Plan
+### Step 1: Create Action Plan
<div class="md-block">
@@ -56,25 +57,25 @@ BlueKing alert policies can trigger `Action Plans`, which can integrate with ext
2. Go to `Configuration-Action Plans` page, click the `Add Plan` button to start creating an action plan;
3. Enter the name as `Send To Flashduty`, select `HTTP Callback` as the plan type, choose `POST` as the push method, and fill in the integration push URL (obtained after saving the integration), as shown below:
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/tencent-bk/create_package.jpg" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/tencent-bk/create_package.jpg" />
4. Switch to `Body`, select `JSON` type, copy and paste the following information (when an actual alert occurs, BlueKing will render the variable content as the payload to push to the target callback URL):
-```
-{{alarm.callback_message}}
-```
+ ```
+ {{alarm.callback_message}}
+ ```
5. Save the plan to complete creation.
</div>
-#### Step 2: Edit Alert Policy
+### Step 2: Edit Alert Policy
<div class="md-block">
1. Go to `Configuration-Alert Policies` page, select an existing policy to edit or create a new one;
2. Scroll down to the `Alert Processing` section, select the `Send To Flashduty` action plan for all three scenarios, and disable `Defense Rules`, as shown below:
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/tencent-bk/update_alert_rule.jpg" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/tencent-bk/update_alert_rule.jpg" />
3. Submit and save to complete;
4. Repeat these steps for other alerts you want to push to Flashduty.
@@ -82,7 +83,6 @@ BlueKing alert policies can trigger `Action Plans`, which can integrate with ext
</div>
## Status Mapping
----
<div class="md-block">
Alert severity mapping between BlueKing and Flashduty:
diff --git a/en/on-call/integration/alert-integration/alert-sources/blumira.mdx b/en/on-call/integration/alert-integration/alert-sources/blumira.mdx
index 342d6db9..72369d00 100644
--- a/en/on-call/integration/alert-integration/alert-sources/blumira.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/blumira.mdx
@@ -1,5 +1,6 @@
---
title: "Blumira alert integration"
+sidebarTitle: "Blumira"
description: "Send Blumira finding created and resolved events to Flashduty On-call through a Blumira webhook."
keywords: ["alert integration", "Blumira", "webhook", "security alerts", "finding", "SIEM"]
---
@@ -9,7 +10,6 @@ Use a Blumira webhook to send security findings to Flashduty On-call. Each Blumi
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Blumira
----
<Steps>
<Step title="Create the webhook">
@@ -74,19 +73,16 @@ Wait for a real Blumira finding and confirm Flashduty receives the active alert.
</Steps>
## About signatures
----
Blumira signs each delivery in the `X-Blumira-Signature` header (format `t=<timestamp>,v1=<HMAC-SHA256>`). Flashduty does not verify this signature and does not need the signing secret. The `integration_key` in the push URL is the only credential, so keep it private.
## Alert Key
----
Flashduty uses `data.finding_id` as the Alert Key. The `finding.created` and `finding.status.changed` examples in Blumira's documentation carry the same `finding_id`, so the trigger, status updates, and recovery land on one alert.
Changes to the title, priority, status, or time do not change the Alert Key. A request without `data.finding_id` is rejected with a parameter error.
## Status and severity
----
| Blumira event | Flashduty behavior |
| :--- | :--- |
@@ -108,7 +104,6 @@ Flashduty treats only `resolved` as recovery. Blumira's documentation shows no o
Alert labels include the finding ID, short ID, type, category, priority, source country, and link. Owner and actor names and emails are not written to the alert.
## Troubleshooting
----
- **Blumira reports failed deliveries or auto-disabled the webhook**: check that the push URL is complete and includes `integration_key`. Blumira disables a webhook after sustained failures; fix the cause and re-enable it under **Edit**
- **No alerts arrive**: confirm the webhook is enabled and the event filters include `finding.created`
diff --git a/en/on-call/integration/alert-integration/alert-sources/bugsnag.mdx b/en/on-call/integration/alert-integration/alert-sources/bugsnag.mdx
index 29720a90..1b5a35b3 100644
--- a/en/on-call/integration/alert-integration/alert-sources/bugsnag.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/bugsnag.mdx
@@ -1,5 +1,6 @@
---
title: "BugSnag alert integration"
+sidebarTitle: "BugSnag"
description: "Send error events from a BugSnag project to Flashduty On-call through the Webhook data forwarding integration."
keywords: ["alert integration", "BugSnag", "webhook", "error monitoring", "data forwarding"]
---
@@ -9,7 +10,6 @@ Use the Webhook (data forwarding) integration of a BugSnag project to send error
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure BugSnag
----
The Webhook integration is configured per project and requires administrative privileges on the project. Configure it once for each project you want to connect.
@@ -82,14 +81,12 @@ The filters below the triggers, such as release stage and handled state, reduce
</Steps>
## Alert Key
----
Flashduty uses the BugSnag error ID (`error.errorId`) as the Alert Key. BugSnag groups repeated occurrences of the same exception into one error, and every occurrence, frequency notification, reopen, and state change of that error carries the same `errorId`, so they merge into one alert, which the error's state change recovers.
The per-occurrence event ID (`error.id`), error message, release stage, and severity do not change the Alert Key. Error events without `errorId` are rejected.
## Status and severity
----
Flashduty sets the alert severity from the error's severity (`error.severity`):
@@ -109,7 +106,6 @@ The trigger type sets the status:
| `errorStateManualChange` with state `reopened`, `snoozeCancelled`, or `unignored` | Trigger |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -128,7 +124,6 @@ The trigger type sets the status:
| `url` | Link to the error in BugSnag |
## Troubleshooting
----
- **Flashduty returns a parameter error**: Confirm that the URL is complete and includes `integration_key`
- **No alert after clicking Test**: This is expected. The test request does not create an alert; verify with a real error
diff --git a/en/on-call/integration/alert-integration/alert-sources/calibre.mdx b/en/on-call/integration/alert-integration/alert-sources/calibre.mdx
index 0fdc51e4..1ffbf056 100644
--- a/en/on-call/integration/alert-integration/alert-sources/calibre.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/calibre.mdx
@@ -1,5 +1,6 @@
---
title: "Calibre alert integration"
+sidebarTitle: "Calibre"
description: "Send Calibre performance budget at-risk, exceeded and met notifications to Flashduty On-call through a site webhook."
keywords: ["alert integration", "Calibre", "performance budget", "Budget", "webhook", "Core Web Vitals"]
---
@@ -9,7 +10,6 @@ Use a Calibre site webhook to send performance budget status changes to Flashdut
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Calibre
----
<Steps>
<Step title="Add a webhook">
@@ -60,7 +59,6 @@ Calibre webhooks have no test button. You can also set a shared secret under **S
</Note>
## Payload
----
The main fields of a budget notification are parsed directly, with no template to configure:
@@ -77,14 +75,12 @@ The main fields of a budget notification are parsed directly, with no template t
| `budgets` | Status and measured value per test profile and page | Written to the alert description |
## Alert Key
----
Flashduty builds the Alert Key from the site identifier `site_id` and the budget ID `id`. At-risk, exceeded and met notifications for the same budget carry the same Alert Key and land on one alert; different budgets or sites produce different alerts. Changing the budget name, status or measured value does not change the Alert Key.
If `id` or `site_id` is missing, Flashduty returns a parameter error because a met notification could not be tied to its alert reliably.
## Status and severity
----
| Calibre `status` | Flashduty state or severity |
| :--- | :--- |
@@ -95,7 +91,6 @@ If `id` or `site_id` is missing, Flashduty returns a parameter error because a m
A budget notification with an empty or any other `status` is rejected, so a request whose state cannot be determined never enters the wrong alert lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="No budget notifications arrive?">
@@ -112,7 +107,6 @@ No. A snapshot notification only reports a completed test run. Flashduty returns
</AccordionGroup>
## Troubleshooting
----
- **Calibre fails to deliver**: confirm the payload URL is the full push URL and includes `integration_key`
- **Flashduty returns a parameter error**: confirm the request is a budget notification with non-empty `id`, `site_id` and `status`
diff --git a/en/on-call/integration/alert-integration/alert-sources/canarytokens.mdx b/en/on-call/integration/alert-integration/alert-sources/canarytokens.mdx
index 28bf9d11..d62a6fe0 100644
--- a/en/on-call/integration/alert-integration/alert-sources/canarytokens.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/canarytokens.mdx
@@ -1,5 +1,6 @@
---
title: "Canarytokens alert integration"
+sidebarTitle: "Canarytokens"
description: "Send alerts from Canarytokens (canarytokens.org or self-hosted) to Flashduty On-call through a webhook when a honeytoken is touched."
keywords: ["alert integration", "Canarytokens", "webhook", "honeytoken", "canary", "intrusion detection", "security"]
---
@@ -9,7 +10,6 @@ Canarytokens, by Thinkst, creates decoys such as web bugs, DNS names, Word, Exce
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the push URL in either of the following ways.
</div>
## In Canarytokens
----
<Steps>
<Step title="Set the webhook URL on the token">
@@ -60,7 +59,6 @@ Canarytokens alerts are one-shot and are never recovered. In the channel that re
</Steps>
## Event types
----
Canarytokens posts one JSON object per event and never posts a recovery.
@@ -71,17 +69,14 @@ Canarytokens posts one JSON object per event and never posts a recovery.
| The test request sent when the webhook is saved | Creates a separate Info alert that never recovers |
## Alert Key
----
Flashduty computes the Alert Key from `token`, the token's fixed identifier. A token touched from different source IPs or through different channels keeps one Alert Key, and changes to the memo, source IP or time do not change it. A request without `token` is rejected. An exposure notice uses `token` plus `key_id`, so it never merges into the token's hit alert.
## Status and severity
----
A honeytoken has no legitimate visitors, so any touch may be an intrusion and hit alerts are always Critical. Exposure notices are Warning and the test request is Info. To grade tokens differently, adjust severity with a channel route or alert processing rule on a label such as `token_type`.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -97,12 +92,10 @@ A honeytoken has no legitimate visitors, so any touch may be an intrusion and hi
The `manage_url` in the payload carries the auth parameter that controls the token. Flashduty neither reads nor stores it. Use the Canarytokens management page to see the token's details and hit history.
## About signatures
----
The Canarytokens webhook has no signature and sends no dedicated header, so Flashduty does not verify one. The `integration_key` in the push URL is the only credential; keep it private.
## Troubleshooting
----
- **Flashduty receives nothing**: make sure the webhook URL is publicly reachable and not a private address. Canarytokens times out after 2 seconds and does not retry
- **The token's webhook was disabled**: Canarytokens disables a webhook after 5 consecutive errors. Fix the push URL and save the webhook again, and confirm the push URL is complete and includes `integration_key`
diff --git a/en/on-call/integration/alert-integration/alert-sources/catchpoint.mdx b/en/on-call/integration/alert-integration/alert-sources/catchpoint.mdx
index f49f930f..f15218c0 100644
--- a/en/on-call/integration/alert-integration/alert-sources/catchpoint.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/catchpoint.mdx
@@ -1,5 +1,6 @@
---
title: "Catchpoint alert integration"
+sidebarTitle: "Catchpoint"
description: "Send Catchpoint test alert, escalation, and recovery events to Flashduty On-call through a custom Alert Webhook template."
keywords: ["alert integration", "Catchpoint", "Alert Webhook", "template", "TestId"]
---
@@ -11,14 +12,12 @@ Catchpoint's [default JSON Alert Webhook format](https://docs.catchpoint.com/doc
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **Catchpoint** alert integration and copy its complete Push URL.
</div>
## Configure Catchpoint
----
<Steps>
<Step title="Create an Alert Webhook">
@@ -82,7 +81,6 @@ Let a test actually trigger a Warning or Critical alert, and confirm Flashduty r
</Steps>
## Alert Key
----
Flashduty derives the Alert Key from `test_id`, `alert_group_item_id`, and `alert_initial_trigger_epoch` combined.
@@ -91,7 +89,6 @@ Catchpoint's own [PagerDuty Events API v2 integration template](https://docs.cat
Changes to the title, description, severity, number of triggered nodes, or threshold never change the Alert Key.
## Status and alert severity
----
Catchpoint's `notification_level_id` has 4 documented values:
@@ -105,7 +102,6 @@ Catchpoint's `notification_level_id` has 4 documented values:
A request with an empty or unsupported `notification_level_id` is rejected. The Improved notification does not say which level the alert recovered from, so Flashduty shows it at Critical severity; the actual state is the recovery (Ok) status.
## Troubleshooting
----
- **Flashduty returns a parameter error**: confirm **Format** is set to **Template** and the template is valid JSON; confirm `test_id`, `alert_group_item_id`, and `alert_initial_trigger_epoch` are still in the template and their macros were not removed or swapped for another macro
- **No alert is created**: confirm the endpoint is selected under **API Endpoints** in the **Alerts** settings of the Test/Folder/Product, or that **Apply to All Alerts** is enabled on the endpoint
diff --git a/en/on-call/integration/alert-integration/alert-sources/cato.mdx b/en/on-call/integration/alert-integration/alert-sources/cato.mdx
index 0042798a..c93569d6 100644
--- a/en/on-call/integration/alert-integration/alert-sources/cato.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/cato.mdx
@@ -1,5 +1,6 @@
---
title: "Cato Networks Alert Integration"
+sidebarTitle: "Cato Networks"
description: "Send Site Operations stories and other alerts from the Cato Management Application (CMA) to Flashduty On-call through a custom-body webhook."
keywords: ["alert integration", "Cato Networks", "Cato", "SASE", "webhook", "Site Operations"]
---
@@ -9,7 +10,6 @@ Cato Networks webhooks have no fixed request body; you write the body in CMA. Th
<div className="hide">
## In Flashduty On-call
----
Get the push URL in either of the following ways.
@@ -30,14 +30,13 @@ Get the push URL in either of the following ways.
</div>
## In Cato
----
You need permission to manage Subscriptions in CMA.
<Steps>
<Step title="Create the webhook">
-1. In CMA, go to **Account > Subscriptions**, open the **Webhooks** tab, and click **New Webhook**
+1. In CMA, go to **Account → Subscriptions**, open the **Webhooks** tab, and click **New Webhook**
2. Enter a name and enable it
3. Choose **POST** (Create) as the request method and paste the full Flashduty push URL, which includes `integration_key`
4. No authentication is needed; `integration_key` is already in the URL
@@ -71,7 +70,7 @@ Field definitions: [Understanding the JSON Fields for Alert Integrations](https:
<Step title="Subscribe and verify">
-1. Under **Account > Subscriptions**, add this webhook as a delivery target for the alert types you want (Site Operations stories and so on)
+1. Under **Account → Subscriptions**, add this webhook as a delivery target for the alert types you want (Site Operations stories and so on)
2. Click **Test** on the webhook page. The Cato documentation does not show the test request body, and Flashduty handles it as a normal alert: without `storyId` and `correlationId` it returns a parameter error, otherwise it opens a separate alert that you close manually after the check
3. Trigger a real event (for example, disconnect the Socket of a test site), confirm Flashduty receives an active alert, then confirm it recovers when the story resolves
@@ -83,12 +82,10 @@ Field definitions: [Understanding the JSON Fields for Alert Integrations](https:
</Warning>
## Alert Key
----
Flashduty uses `storyId` as the Alert Key, and `correlationId` when `storyId` is empty. Cato defines `storyId` as "Unique identifier for the Site Operations story" and `correlationId` as "Unique identifier used to correlate related events, messages, or operations". Changes to title, level or time never change the Alert Key. A request with neither field is rejected with the field name.
## Status and severity
----
An alert recovers when `storyStatus` is `RESOLVED` or `endDate` is not empty; other states such as `OPEN` and `IN_PROGRESS` trigger or update it. Severity comes from `level`:
@@ -101,7 +98,6 @@ An alert recovers when `storyStatus` is `RESOLVED` or `endDate` is not empty; ot
| Empty or other | Warning |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -116,7 +112,6 @@ An alert recovers when `storyStatus` is `RESOLVED` or `endDate` is not empty; ot
| `isp` | `ISPName` |
## Troubleshooting
----
- **Cato test fails**: confirm the URL is complete, includes `integration_key`, and the method is POST
- **Flashduty returns a parameter error**: confirm the body is valid JSON and contains `storyId` or `correlationId`. If a title or subject contains double quotes, Cato's substitution may break the JSON; remove the `title` or `subject` field from the template
diff --git a/en/on-call/integration/alert-integration/alert-sources/censys.mdx b/en/on-call/integration/alert-integration/alert-sources/censys.mdx
index b4684953..487cf4a4 100644
--- a/en/on-call/integration/alert-integration/alert-sources/censys.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/censys.mdx
@@ -1,5 +1,6 @@
---
title: "Censys alert integration"
+sidebarTitle: "Censys"
description: "Send new risks found by Censys ASM to Flashduty On-call through a webhook."
keywords: ["alert integration", "Censys", "Censys ASM", "webhook", "attack surface management", "risk"]
---
@@ -9,7 +10,6 @@ Use the Webhook Connection of Censys Attack Surface Management (ASM) to send new
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## In Censys ASM
----
Webhook Connection is available only at the Advanced and Enterprise access levels of Censys ASM. If your firewall or gateway restricts source IPs, allow the Censys egress addresses `52.5.142.59`, `34.226.132.221`, and `52.54.43.157`.
@@ -67,14 +66,12 @@ The Censys webhook documentation describes no test button. When ASM finds a new
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from `event.data.risk_id` (the risk type ID) and `event.data.impacted_asset` (the affected asset, such as `Host: 1.1.1.1`). Censys defines a risk instance as one risk type on one asset, but does not state that `risk_id` and `impacted_asset` stay unchanged across deliveries. The same risk type on the same asset gets the same Alert Key, so repeated deliveries merge into one alert; the same risk type on different assets, or different risk types on one asset, produce separate alerts.
Changes to the risk name, description, severity, first and last seen times, or the event ID do not change the Alert Key. An event without `risk_id` or `impacted_asset` is rejected. An event whose `event.type` is not `risk_instance_opened` creates no alert; Flashduty acknowledges it and returns success.
## Status and severity
----
Every event is a trigger. Flashduty sets the severity from `risk_severity`:
@@ -86,7 +83,6 @@ Every event is a trigger. Flashduty sets the severity from `risk_severity`:
| Empty or other | Warning |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -103,7 +99,6 @@ Every event is a trigger. Flashduty sets the severity from `risk_severity`:
The alert title is the risk description (`risk_description`, or the risk name when empty) followed by the affected asset.
## Troubleshooting
----
- **Webhook Connection is missing**: check that the Censys ASM access level is Advanced or Enterprise
- **The integration does not work**: Censys requires the receiver to accept the top-level `event` field; the Flashduty push URL needs no extra handling
diff --git a/en/on-call/integration/alert-integration/alert-sources/centreon.mdx b/en/on-call/integration/alert-integration/alert-sources/centreon.mdx
index b19c2719..9521918b 100644
--- a/en/on-call/integration/alert-integration/alert-sources/centreon.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/centreon.mdx
@@ -1,5 +1,6 @@
---
title: "Centreon Alert Integration"
+sidebarTitle: "Centreon"
description: "Push Centreon host and service alerts to the Flashduty PagerDuty Compatible integration through Centreon's PagerDuty Events stream connector; recovery states close the alerts automatically."
keywords: ["alert integration", "Centreon", "stream connector", "PagerDuty", "Broker", "infrastructure monitoring"]
---
@@ -9,7 +10,6 @@ Centreon ships a PagerDuty Events stream connector (`pagerduty-events-apiv2.lua`
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the PagerDuty Compatible integration type** in both, not Centreon.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the PagerD
</div>
## Configure in Centreon
----
### Step 1: Install the stream connector
@@ -50,19 +49,19 @@ apt install centreon-stream-connector-pagerduty
2. On the **Output** tab, select **Generic - Stream connector** and click **Add** to add an output
3. Fill in the fields as follows:
-| Field | Value |
-| :--- | :--- |
-| Name | `Flashduty` |
-| Path | `/usr/share/centreon-broker/lua/pagerduty-events-apiv2.lua` |
-| Filter category | `Neb` |
+ | Field | Value |
+ | :--- | :--- |
+ | Name | `Flashduty` |
+ | Path | `/usr/share/centreon-broker/lua/pagerduty-events-apiv2.lua` |
+ | Filter category | `Neb` |
4. Click **+Add a new entry** below the **Filter category** table to add these parameters:
-| Type | Name | Value |
-| :--- | :--- | :--- |
-| string | `pdy_routing_key` | The `integration_key` value from the push URL above (mandatory parameter) |
-| string | `http_server_url` | The full push URL (including `integration_key`) |
-| string | `pdy_centreon_url` | The address of your Centreon server (optional, used for the link in the alert) |
+ | Type | Name | Value |
+ | :--- | :--- | :--- |
+ | string | `pdy_routing_key` | The `integration_key` value from the push URL above (mandatory parameter) |
+ | string | `http_server_url` | The full push URL (including `integration_key`) |
+ | string | `pdy_centreon_url` | The address of your Centreon server (optional, used for the link in the alert) |
5. Deploy the configuration and restart `centengine` on all pollers:
@@ -83,7 +82,6 @@ curl -X POST -H 'content-type: application/json' '<push URL>' -d '{"dedup_key":"
Flashduty should return HTTP 202 and an alert should appear; send it again with `event_action` set to `resolve` and the alert recovers.
## Field mapping
----
How the fields sent by the Centreon connector (see the connector source) map to Flashduty:
@@ -107,14 +105,12 @@ Severity set by the connector for each Centreon state:
| Service UNKNOWN | `error` | Critical |
## Recovery and deduplication
----
- A host or service always uses the same Alert Key, so a change from WARNING to CRITICAL updates the same alert and a return to OK or UP recovers it
- With the connector library's default parameters only HARD states are sent, and objects that are acknowledged or in scheduled downtime are not sent; to change this, adjust `hard_only`, `acknowledged` and `in_downtime` in the connector parameters
- To push only some objects, use the connector's filter parameters such as `accepted_hostgroups`, `accepted_servicegroups` and `accepted_pollers`
## Troubleshooting
----
- **Flashduty receives no alert**: check `/var/log/centreon-broker/pagerduty-events.log` (the default log file; `log_level` goes up to 3); confirm `http_server_url` is the full push URL and `pdy_routing_key` is set
- **The connector log shows a failed POST**: the connector only treats HTTP 202 as success, and Flashduty answers PagerDuty Events API v2 requests with 202; for other status codes, check that `integration_key` is correct
diff --git a/en/on-call/integration/alert-integration/alert-sources/cert-spotter.mdx b/en/on-call/integration/alert-integration/alert-sources/cert-spotter.mdx
index 7ace2c11..769c4158 100644
--- a/en/on-call/integration/alert-integration/alert-sources/cert-spotter.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/cert-spotter.mdx
@@ -1,5 +1,6 @@
---
title: "Cert Spotter alert integration"
+sidebarTitle: "Cert Spotter"
description: "Sync unknown certificates detected by Cert Spotter to Flashduty On-call through a webhook."
keywords: ["alert integration", "Cert Spotter", "SSLMate", "Certificate Transparency", "unauthorized certificate", "webhook"]
---
@@ -9,7 +10,6 @@ Cert Spotter is SSLMate's certificate monitoring service. It continuously watche
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Cert Spotter
----
Webhook notifications are available on the Cert Spotter Startup plan and above. The Hobbyist plan only sends email.
@@ -59,7 +58,6 @@ Cert Spotter has no button that sends a test delivery. Issue a new certificate f
</Steps>
## Payload
----
| Cert Spotter event | Result in Flashduty |
| :--- | :--- |
@@ -69,19 +67,16 @@ Cert Spotter has no button that sends a test delivery. Issue a new certificate f
Cert Spotter sends expiration reminders and installation problems only by email and Slack, not by webhook, so they do not reach this integration.
## Alert Key
----
Flashduty uses the ID of the certificate issuance (`id` in the webhook) as the Alert Key. A network problem can deliver the same request more than once; the duplicate carries the same `id` and merges into the same alert. Different certificates create different alerts.
Deliveries without `id` are rejected.
## Severity
----
Cert Spotter sends no severity, so every unknown certificate triggers a **Warning** alert. Whether the certificate has been revoked is recorded in the `revoked` label and does not change the severity.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -99,7 +94,6 @@ Cert Spotter sends no severity, so every unknown certificate triggers a **Warnin
The alert title is `Unknown certificate for <first monitored name>`, followed by `(+N more)` when the certificate covers several names.
## FAQ
----
<AccordionGroup>
diff --git a/en/on-call/integration/alert-integration/alert-sources/cfengine.mdx b/en/on-call/integration/alert-integration/alert-sources/cfengine.mdx
index a66ac260..48409462 100644
--- a/en/on-call/integration/alert-integration/alert-sources/cfengine.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/cfengine.mdx
@@ -1,5 +1,6 @@
---
title: "CFEngine alert integration"
+sidebarTitle: "CFEngine"
description: "Send CFEngine Enterprise alerts to Flashduty On-call through a Mission Portal custom action script. Alerts close automatically when the CFEngine alert clears."
keywords: ["alert integration", "CFEngine", "Mission Portal", "Custom action"]
---
@@ -11,7 +12,6 @@ The CFEngine Enterprise Mission Portal has no webhook notification method, but a
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure CFEngine
----
The steps below are based on CFEngine Enterprise 3.27. Uploading custom action scripts and associating them with alerts requires the admin role in Mission Portal. The script only needs `bash` and `curl` on the hub.
@@ -97,7 +96,6 @@ CFEngine has no "send test notification" button. To verify a real alert, make th
</Steps>
## Alert Key
----
Flashduty uses the CFEngine alert ID `ALERT_ID` as the Alert Key. The CFEngine documentation describes it as the alert's unique ID. The trigger, reminder, and clear deliveries of one alert carry the same `ALERT_ID`, so they land on the same Flashduty alert. Changes to the alert name, severity, failed host count, or timestamps do not change the Alert Key.
@@ -106,7 +104,6 @@ Flashduty uses the CFEngine alert ID `ALERT_ID` as the Alert Key. The CFEngine d
Flashduty rejects a request that has no `ALERT_ID`, or whose `ALERT_STATUS` is not `fail` or `success`.
## Alert lifecycle
----
One CFEngine alert covers all the hosts it is defined for. Flashduty creates one alert for it and records the failed host count in the description and labels.
@@ -117,7 +114,6 @@ One CFEngine alert covers all the hosts it is defined for. Flashduty creates one
| Alert cleared | `success` | Recover the alert |
## Alert severity
----
The severity comes from the severity selected when the alert was created, `ALERT_SEVERITY`:
@@ -131,7 +127,6 @@ The severity comes from the severity selected when the alert was created, `ALERT
A recovery event keeps the alert's severity.
## Alert content
----
- **Title**: the alert name `ALERT_NAME`
- **Description**: the condition description `ALERT_CONDITION_DESCRIPTION`, followed by `Triggered on <failed hosts> of <total hosts> hosts.`
@@ -140,7 +135,6 @@ A recovery event keeps the alert's severity.
Timestamp parameters (`ALERT_LAST_CHECK`, `ALERT_LAST_EVENT_TIME`, `ALERT_LAST_STATUS_CHANGE`), `ALERT_STATUS`, and the condition description are not written to labels, and neither are empty parameters. Each alert holds at most 50 labels; if there are more, the ones beyond the limit in name order are dropped.
## Troubleshooting
----
- **The script reports HTTP 4xx**: confirm that `FLASHDUTY_URL` is the full push URL and includes `integration_key`
- **The script cannot be selected in Mission Portal**: confirm that the current user has the admin role and that the script is saved under **Custom notification scripts**
diff --git a/en/on-call/integration/alert-integration/alert-sources/check-point-smartevent.mdx b/en/on-call/integration/alert-integration/alert-sources/check-point-smartevent.mdx
index 477aa5b5..c30858bb 100644
--- a/en/on-call/integration/alert-integration/alert-sources/check-point-smartevent.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/check-point-smartevent.mdx
@@ -1,5 +1,6 @@
---
title: "Check Point SmartEvent Alert Integration"
+sidebarTitle: "Check Point SmartEvent"
description: "Check Point SmartEvent automatic reactions can send email. Use the Flashduty Email integration to bring SmartEvent events into Flashduty."
keywords: ["alert integration", "Check Point", "SmartEvent", "email", "security events"]
---
@@ -9,7 +10,6 @@ SmartEvent automatic reactions offer Mail, SNMP Trap, Block Source, Block Event
<div className="hide">
## In Flashduty On-call
----
You can get the integration email address in either of two ways. **Choose the Email integration type in both cases**, not Check Point.
@@ -29,12 +29,10 @@ You can get the integration email address in either of two ways. **Choose the Em
</div>
## Confirm the push mode in Flashduty
----
SmartEvent sends one mail per event and no recovery mail, and the subject carries the event number (see [Mail subject format](#mail-subject-format)), so every mail is an independent event. Set the Email integration's push mode to the one that always triggers a new alert (the create page may preselect a different mode, so check it): each mail creates a new alert whose title is the mail subject and whose description is the mail body. No trigger or close rules are needed.
## In Check Point SmartConsole
----
Paths follow the Check Point R81.10 administration guide.
@@ -47,12 +45,10 @@ Paths follow the Check Point R81.10 administration guide.
7. Save, reference the automatic reaction in the event definitions you want notifications for, and install the policy
## Mail subject format
----
The default **Subject** of the Mail reaction is `[EventNumber] - [Severity] - [Name]`: event number, severity and event name. Flashduty uses the mail subject as the alert title.
## Limitations
----
- **No recovery**: SmartEvent sends no recovery mail. Enable [auto-resolve timeout](/en/on-call/channel/create-edit) on the channel that receives this integration (24 hours suggested), or close alerts manually in Flashduty.
- **No deduplication**: the subject contains the event number, so each event creates its own alert.
diff --git a/en/on-call/integration/alert-integration/alert-sources/checkly.mdx b/en/on-call/integration/alert-integration/alert-sources/checkly.mdx
index bcbd931f..ee38a87d 100644
--- a/en/on-call/integration/alert-integration/alert-sources/checkly.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/checkly.mdx
@@ -1,5 +1,6 @@
---
title: "Checkly alert integration"
+sidebarTitle: "Checkly"
description: "Send Checkly failure, degradation, recovery, and SSL certificate alerts to Flashduty On-call through a Webhook Alert Channel."
keywords: ["alert integration", "Checkly", "webhook", "synthetic monitoring", "API monitoring"]
---
@@ -9,14 +10,12 @@ Use a Checkly Webhook Alert Channel to send check-state changes to Flashduty On-
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **Checkly** alert integration and copy its complete Push URL.
</div>
## Configure Checkly
----
<Steps>
<Step title="Create a Webhook Alert Channel">
@@ -81,7 +80,6 @@ A Checkly test notification or webhook HTTP 200 proves connectivity only. Use re
</Steps>
## Alert Key
----
Normal check-state notifications use the trimmed `check_id` (Checkly variable `CHECK_ID`) as the Alert Key. Titles, errors, run locations, response times, result IDs, and alert-state changes do not affect it.
@@ -92,7 +90,6 @@ If `check_id` is missing or empty, Flashduty accepts the request and generates a
`ALERT_SSL` is an independent one-shot Warning event. It always receives a new random UUID, even when the payload includes `check_id`, and does not update or recover the Check's normal state alert.
## Status and severity
----
| Checkly `ALERT_TYPE` | Flashduty status | Flashduty severity |
| :--- | :--- | :--- |
@@ -106,7 +103,6 @@ If `check_id` is missing or empty, Flashduty accepts the request and generates a
An empty or unknown `alert_type` returns an invalid-parameter response. Recovery is determined only by `alert_type`, not by the title or error text.
## Labels and description
----
Flashduty creates these labels:
@@ -134,7 +130,6 @@ The request body, labels, and description all have hard limits, handled as follo
A label value that is empty after trimming is not written to the alert.
## Delivery and troubleshooting
----
Checkly retries a failed webhook delivery up to five times at approximately 20-second intervals. Use Checkly's Alert Notification Log to inspect the final delivery result.
diff --git a/en/on-call/integration/alert-integration/alert-sources/checkmk.mdx b/en/on-call/integration/alert-integration/alert-sources/checkmk.mdx
index 933451ec..e1fc9c5f 100644
--- a/en/on-call/integration/alert-integration/alert-sources/checkmk.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/checkmk.mdx
@@ -1,5 +1,6 @@
---
title: "Checkmk alert integration"
+sidebarTitle: "Checkmk"
description: "Send Checkmk host and service notifications to Flashduty On-call through a notification script. Alerts close automatically when the problem recovers."
keywords: ["alert integration", "Checkmk", "Check_MK", "notification script", "Nagios"]
---
@@ -9,7 +10,6 @@ Checkmk has no generic webhook notification method. This integration provides a
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Checkmk
----
The steps below are based on Checkmk 2.5. Menu names may differ slightly in other 2.x versions. The script only needs the Python 3 that ships with Checkmk; nothing else has to be installed.
@@ -113,7 +112,6 @@ You can also send a test from **Test notifications** under **Setup → Events
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from the host name `HOSTNAME` and the service name `SERVICEDESC`. Host notifications use an empty service name. Problem and recovery notifications for the same host or service carry the same host and service names, so they land on the same alert. When the state rises to a higher severity (for example a service going from WARN to CRIT), Flashduty opens a new alert at the higher severity and keeps the earlier alert open; the recovery notification closes both.
@@ -122,7 +120,6 @@ Changes to the state, plugin output, notification number, time, host address, si
Flashduty rejects a request that lacks `HOSTNAME`, `WHAT`, the current state, or `NOTIFICATIONTYPE`, and a service notification that lacks `SERVICEDESC`.
## Alert lifecycle
----
Checkmk sends a recovery notification only after it has sent a problem notification. Acknowledgement, downtime, flapping, and custom notifications are also sent when the problem notification was suppressed (for example while a service flaps). An alert opened from them would never get a recovery notification to close it. So only problem notifications open alerts, and Flashduty handles each notification type `NOTIFICATIONTYPE` as follows:
@@ -139,7 +136,6 @@ While a service flaps, Checkmk sends no state change notifications: a return to
Ignored notifications get a success response, so Checkmk does not retry them.
## Severity
----
Severity comes from the current state: `SERVICESTATE` for service notifications and `HOSTSTATE` for host notifications.
@@ -155,7 +151,6 @@ Severity comes from the current state: `SERVICESTATE` for service notifications
A recovery event takes the severity of the hard state before recovery (`PREVIOUSSERVICEHARDSTATE` or `PREVIOUSHOSTHARDSTATE`).
## Alert content
----
- **Title**: `<service name> on <host name>` for service notifications, `Host <host name>` for host notifications
- **Description**: the plugin output `SERVICEOUTPUT` or `HOSTOUTPUT`, followed by the long output when present
@@ -164,7 +159,6 @@ A recovery event takes the severity of the hard state before recovery (`PREVIOUS
Each alert carries at most 50 labels. When there are more, labels beyond the limit are dropped in name order. Contact details such as contact names and email addresses are not written to labels.
## Troubleshooting
----
- **Flashduty is not listed as a method in Checkmk**: make sure the script is in the site's `local/share/check_mk/notifications/` directory, is named `flashduty`, is executable, and has `# Flashduty` on its second line
- **No notification is sent**: check the site's `var/log/notify.log` to confirm the rule matched the event and that the user under **Recipient** has not disabled notifications
diff --git a/en/on-call/integration/alert-integration/alert-sources/chronosphere.mdx b/en/on-call/integration/alert-integration/alert-sources/chronosphere.mdx
index 4cf9fd55..1909517a 100644
--- a/en/on-call/integration/alert-integration/alert-sources/chronosphere.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/chronosphere.mdx
@@ -1,5 +1,6 @@
---
title: "Chronosphere Alert Integration"
+sidebarTitle: "Chronosphere"
description: "Receive Chronosphere alerts through Chronosphere's webhook notifier using a Flashduty Prometheus integration; with resolved notifications on, alerts close automatically."
keywords: ["alert integration", "Chronosphere", "webhook", "Prometheus", "Alertmanager", "observability"]
---
@@ -9,7 +10,6 @@ Chronosphere's webhook notifier sends an HTTP POST to the URL you enter. The bod
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the Prometheus integration type** in both, not Chronosphere.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the Promet
</div>
## Configure in Chronosphere
----
<Steps>
<Step title="Create a webhook notifier">
@@ -59,7 +58,6 @@ Trigger an alert from a monitor and confirm Flashduty receives an active alert;
</Steps>
## Field mapping
----
| Chronosphere field | Flashduty |
| :--- | :--- |
@@ -75,7 +73,6 @@ Trigger an alert from a monitor and confirm Flashduty receives an active alert;
One notification can carry several alerts, and Flashduty handles each one separately (up to 100 per request).
## Recovery and deduplication
----
- When Chronosphere sends a notification with `status` set to `resolved`, Flashduty closes the alert with the same `fingerprint`.
- If the notifier does not send resolved notifications, Flashduty never receives a recovery request and the alert stays active. In that case enable [auto-resolve timeout](/en/on-call/channel/create-edit) on the channel.
@@ -83,7 +80,6 @@ One notification can carry several alerts, and Flashduty handles each one separa
- Chronosphere's documentation does not say whether the webhook notifier has a test send. After the first setup, verify with a real alert that both the trigger and the recovery show up in Flashduty.
## Troubleshooting
----
- **Flashduty returns `Invalid parameters`**: the push URL is incomplete and lacks `integration_key`, or the integration type is not Prometheus
- **Alerts do not recover**: confirm the notifier has **Notify when resolved** selected (`send_resolved` is `true` in Terraform, `skip_resolved` is `false` in Chronoctl) and that the resolved notification's `fingerprint` matches the trigger
diff --git a/en/on-call/integration/alert-integration/alert-sources/circonus.mdx b/en/on-call/integration/alert-integration/alert-sources/circonus.mdx
index b301dd48..db5a7905 100644
--- a/en/on-call/integration/alert-integration/alert-sources/circonus.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/circonus.mdx
@@ -1,5 +1,6 @@
---
title: "Circonus alert integration"
+sidebarTitle: "Circonus"
description: "Send alert and recovery notifications from Circonus rulesets to Flashduty On-call through a contact group webhook."
keywords: ["alert integration", "Circonus", "webhook", "contact group", "alert_id"]
---
@@ -9,7 +10,6 @@ Use the webhook contact method of a Circonus contact group to send alerts raised
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Circonus
----
<Steps>
<Step title="Add a webhook to a contact group">
@@ -63,14 +62,12 @@ Let a rule fire and confirm Flashduty shows an active alert, then let the metric
</Steps>
## Alert Key
----
Flashduty uses the `alert_id` of each alert as the Alert Key. The Circonus alert link has the form `...fault-detection?alert_id=<id>`, and a recovery notification carries all fields of the original alert plus `clear_value` and `clear_time`, so the trigger and the recovery share one `alert_id`.
The `alerts` array of one request can hold several alerts; each becomes its own Flashduty event. Changes to the rule, metric, severity, value, or time never change the Alert Key. A request whose alert has no `alert_id` is rejected, because a later recovery could not be matched.
## Status and severity
----
Circonus severities run from 1 to 5, where 1 is the most severe.
@@ -84,7 +81,6 @@ Circonus severities run from 1 to 5, where 1 is the most severe.
A notification with `clear_time` or `clear_value` is treated as a recovery and keeps the original severity. A body with no `alerts`, or an empty `alerts` array, returns success and creates no alert.
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: check that the URL ends with `&format=json` and that every alert has a non-empty `alert_id`
- **The alert does not recover**: check that the contact group is assigned to that severity of the rule and that Circonus has cleared the alert; the recovery must carry the same `alert_id` as the trigger
diff --git a/en/on-call/integration/alert-integration/alert-sources/cloudamqp.mdx b/en/on-call/integration/alert-integration/alert-sources/cloudamqp.mdx
index e4502985..18b2d1b1 100644
--- a/en/on-call/integration/alert-integration/alert-sources/cloudamqp.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/cloudamqp.mdx
@@ -1,5 +1,6 @@
---
title: "CloudAMQP alert integration"
+sidebarTitle: "CloudAMQP"
description: "Send CloudAMQP instance alarms (queue depth, consumers, CPU, memory, disk, connections, and more) to Flashduty On-call through a webhook recipient."
keywords: ["alert integration", "CloudAMQP", "webhook", "RabbitMQ", "LavinMQ", "message queue"]
---
@@ -9,7 +10,6 @@ Use a webhook recipient of CloudAMQP alarms to send instance alarms to Flashduty
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the push URL in either of the following ways.
</div>
## In CloudAMQP
----
<Steps>
<Step title="Add a webhook recipient">
@@ -59,7 +58,6 @@ To get repeated reminders, set a **Reminder interval** on the alarm (minimum 30
</Steps>
## Event types
----
CloudAMQP pushes one alarm subject per request, as JSON.
@@ -72,17 +70,14 @@ CloudAMQP pushes one alarm subject per request, as JSON.
CloudAMQP retries when the webhook returns a non-2xx status. Duplicate pushes carry the same Alert Key and merge into one alert.
## Alert Key
----
Flashduty computes the Alert Key from `dedup_key`. It combines the alarm type and its subject (for a queue alarm, `queue::<vhost>/<queue>`), and the trigger, reminder, and resolve pushes of one subject carry the same value. Changes to the threshold, time threshold, current value, or subject text do not change the Alert Key. A request without `dedup_key` is rejected.
## Status and severity
----
CloudAMQP pushes carry no severity, so every alarm type is Warning in Flashduty, and `resolved: true` recovers the alert. To distinguish severity, use a label such as `alarm_type` in the channel's routing or alert processing rules.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -96,7 +91,6 @@ CloudAMQP pushes carry no severity, so every alarm type is Warning in Flashduty,
| `data_*` | Fields of the `data` object, such as `data_value`, `data_name`, `data_type` |
## Troubleshooting
----
- **Flashduty receives nothing**: confirm the webhook recipient is added to the alarm's Recipients, and check the recipient's status column in the alarms list for errors
- **Invalid parameter error**: confirm the URL is complete and includes `integration_key`
diff --git a/en/on-call/integration/alert-integration/alert-sources/cloudflare.mdx b/en/on-call/integration/alert-integration/alert-sources/cloudflare.mdx
index c88560e6..23bd3f3e 100644
--- a/en/on-call/integration/alert-integration/alert-sources/cloudflare.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/cloudflare.mdx
@@ -1,5 +1,6 @@
---
title: "Cloudflare Alert Events"
+sidebarTitle: "Cloudflare"
description: "Sync Cloudflaret alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,47 +9,47 @@ Sync Cloudflare alert events to Flashduty via webhook for automated alert noise
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels - it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Cloudflare** integration and click **Save** to generate a card
4. Click the generated card to view the **Push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event payload.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Cloudflare** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Cloudflare
----
<div class="md-block">
-## 一、Create Notification Object
+### Create Notification Object
1. Log in to the `Cloudflare dashboard` and select your account.
2. Go to `Notifications` > `Destinations`.
3. In the `Webhooks` card, select Create.
@@ -59,7 +60,7 @@ After configuring the Webhook channel, you can use it in notification policies.
</div>
-## 二、Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/clustercontrol.mdx b/en/on-call/integration/alert-integration/alert-sources/clustercontrol.mdx
index 2acd4271..53638f23 100644
--- a/en/on-call/integration/alert-integration/alert-sources/clustercontrol.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/clustercontrol.mdx
@@ -1,5 +1,6 @@
---
title: "ClusterControl alert integration"
+sidebarTitle: "ClusterControl"
description: "Send Severalnines ClusterControl alarm and recovery notifications to Flashduty On-call through the Notification Services webhook."
keywords: ["alert integration", "ClusterControl", "Severalnines", "Notification Services", "webhook", "database operations", "cmon-events"]
---
@@ -9,7 +10,6 @@ Use **Notification Services → Webhook** in Severalnines ClusterControl to send
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In ClusterControl
----
<Steps>
<Step title="Add a webhook integration">
@@ -62,7 +61,6 @@ ClusterControl only notifies for alarms raised after the integration is created;
</Warning>
## Payload
----
ClusterControl POSTs the following JSON fields. Flashduty parses them directly, with no template to configure:
@@ -80,7 +78,6 @@ ClusterControl POSTs the following JSON fields. Flashduty parses them directly,
The alert title is `title`; when empty, it is `ClusterControl alarm <id>`.
## Alert Key
----
Flashduty uses the alarm `id` as the Alert Key. The ClusterControl documentation states that when an alarm ends it sends another event with the same alarm ID and `status` set to `ENDED`, so the created, changed and ended notifications land on the same Flashduty alert, and different `id` values produce different alerts. Changing the title, host or severity does not change the Alert Key.
@@ -89,7 +86,6 @@ The documented payload has no cluster ID (ClusterControl 2.1.0 also sends `contr
When a request has no `id`, Flashduty returns a parameter error, because a recovery could not be matched to its alert reliably.
## Status and severity
----
| ClusterControl field | Flashduty status or severity |
| :--- | :--- |
@@ -101,7 +97,6 @@ When a request has no `id`, Flashduty returns a parameter error, because a recov
A request whose `status` is empty or any other value is rejected, so a request with an unknown state never enters the wrong alert lifecycle. ClusterControl forwards only `CREATED` and `ENDED` by default; `CHANGED` must be enabled with the `allowed_events` parameter of `cmon-events`.
## FAQ
----
<AccordionGroup>
<Accordion title="Test credentials reports a failure in ClusterControl?">
@@ -124,7 +119,6 @@ In ClusterControl, a muted alarm type sends no notification until it is unmuted.
</AccordionGroup>
## Troubleshooting
----
- **Flashduty receives no alert**: confirm the URL is the complete push URL (including `integration_key`), that the `cmon-events` process is running, and that notifications are enabled for the cluster and events
- **Flashduty returns a parameter error**: confirm the body is ClusterControl's JSON and that `id` and `status` are not empty
diff --git a/en/on-call/integration/alert-integration/alert-sources/consul.mdx b/en/on-call/integration/alert-integration/alert-sources/consul.mdx
index 716e72b4..ea8c5a84 100644
--- a/en/on-call/integration/alert-integration/alert-sources/consul.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/consul.mdx
@@ -1,5 +1,6 @@
---
title: "HashiCorp Consul alert integration"
+sidebarTitle: "HashiCorp Consul"
description: "Send HashiCorp Consul health check failures and recoveries to Flashduty On-call through a checks watch with an HTTP handler on a Consul agent."
keywords: ["alert integration", "Consul", "HashiCorp Consul", "watch", "health check", "http_handler_config"]
---
@@ -11,7 +12,6 @@ This integration works with both Consul Community Edition and Consul Enterprise.
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -20,7 +20,7 @@ You can obtain an integration push URL in either of the following ways.
Choose this method when you do not need to route alerts to different channels.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View dedicated integration setup steps">
1. In the Flashduty console, select **Channel** and open a channel
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**
@@ -35,7 +35,7 @@ Choose this method when you do not need to route alerts to different channels.
Choose this method when you need to route alerts to different channels based on the payload.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View shared integration setup steps">
1. In the Flashduty console, select **Integration Center → Alert Events**
2. Select **HashiCorp Consul** and enter an integration name
@@ -48,7 +48,6 @@ Choose this method when you need to route alerts to different channels based on
</div>
## How it works
----
Whenever any watched health check changes (its status or its output), a Consul watch of type `checks` POSTs the current state of **all** watched checks to the push URL as one JSON array. Flashduty turns each check in the array into one event:
@@ -59,14 +58,12 @@ Whenever any watched health check changes (its status or its output), a Consul w
The watch sends the current state once as soon as it is loaded, so checks that are already `warning` or `critical` raise alerts right away.
## Prerequisites
----
- **Network**: the Consul agent that runs the watch must be able to reach the Flashduty push URL (for example `https://api.flashcat.cloud`).
- **Permissions**: you need to be able to edit that agent's configuration directory (for example `/etc/consul.d`) and run `consul reload`.
- **ACL**: when ACLs are enabled, the token the watch uses needs read access to all nodes and services, as described below.
## In Consul
----
<Steps>
<Step title="Choose the agent that runs the watch">
@@ -149,7 +146,6 @@ When ACLs are enabled, add `-H "X-Consul-Token: <ACL token>"` to each command.
</Steps>
## Alert Key
----
Flashduty builds the Alert Key from `Partition`, `Node`, and `CheckID`.
@@ -162,7 +158,6 @@ Changes to a check's status, name, output, or notes do not change its Alert Key.
A watch only returns the checks of its own datacenter, and the payload does not include the datacenter name. If several datacenters share one integration and have nodes with the same name, checks with the same ID on those nodes merge into one alert. We recommend one integration per datacenter.
## Status and severity
----
| Consul `Status` | Flashduty status | Flashduty severity |
| :--- | :--- | :--- |
@@ -173,7 +168,6 @@ A watch only returns the checks of its own datacenter, and the payload does not
When a check moves between `warning` and `critical`, Flashduty keeps one alert per severity: `warning` turning `critical` creates a new Critical alert, and `passing` recovers both.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -190,7 +184,6 @@ When a check moves between `warning` and `critical`, Flashduty keeps one alert p
The alert title is `<check name> on <node name>`, and the alert description is the check's `Output` and `Notes`.
## FAQ
----
<AccordionGroup>
<Accordion title="A check or node was removed and its alert did not recover. What should I do?">
diff --git a/en/on-call/integration/alert-integration/alert-sources/contrast.mdx b/en/on-call/integration/alert-integration/alert-sources/contrast.mdx
index be5738ad..54de49c2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/contrast.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/contrast.mdx
@@ -1,5 +1,6 @@
---
title: "Contrast Security Alert Integration"
+sidebarTitle: "Contrast Security"
description: "Sync Contrast Security new-vulnerability, vulnerability-closed, and server-offline events to Flashduty On-call through a generic webhook."
keywords: ["alert integration", "Contrast Security", "webhook", "vulnerability", "application security", "IAST"]
---
@@ -11,7 +12,6 @@ Contrast's generic webhook has no fixed payload; the body is the template you en
<div className="hide">
## In Flashduty On-call
----
Get the push URL in either of the following ways.
@@ -32,7 +32,6 @@ Get the push URL in either of the following ways.
</div>
## In Contrast Security
----
<Steps>
<Step title="Add a generic webhook">
@@ -67,7 +66,6 @@ Click **Add**. Contrast disconnects a webhook after 5 consecutive attempts witho
</Steps>
## Events and Alert Key
----
| Contrast event | `event_type` | Effect in Flashduty | Alert Key field |
| :--- | :--- | :--- | :--- |
@@ -81,7 +79,6 @@ Changes to severity, status, title, or application do not change the Alert Key.
Server-offline alerts and the events in the last row have no recovery event. Configure **Auto-close after timeout** (for example 24 hours) on the integration or channel, or close them manually.
## Severity mapping
----
Mapped from `$Severity`:
@@ -95,7 +92,6 @@ Mapped from `$Severity`:
When a vulnerability is closed the alert recovers and keeps the severity carried by the closing event.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -110,7 +106,6 @@ When a vulnerability is closed the alert recovers and keeps the severity carried
| `organization` / `organization_id` | Organization name and ID |
## Troubleshooting
----
- **Contrast reports the webhook as disconnected**: Flashduty returned a non-2XX response. Check that the URL contains `integration_key` and that the Payload is the template above and valid JSON, then test and save again in Contrast
- **The alert does not recover**: confirm the vulnerability moved to a closed status in Contrast. Other status changes (such as Confirmed or Suspicious) send no event
diff --git a/en/on-call/integration/alert-integration/alert-sources/coralogix.mdx b/en/on-call/integration/alert-integration/alert-sources/coralogix.mdx
index 9c71c8f6..ee7a805f 100644
--- a/en/on-call/integration/alert-integration/alert-sources/coralogix.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/coralogix.mdx
@@ -1,5 +1,6 @@
---
title: "Coralogix alert integration"
+sidebarTitle: "Coralogix"
description: "Send Coralogix alert trigger and recovery notifications to Flashduty On-call through a Notification Center Generic HTTPS connector."
keywords: ["alert integration", "Coralogix", "Notification Center", "Generic HTTPS", "groupingKey"]
---
@@ -9,7 +10,6 @@ Use a Coralogix Notification Center Generic HTTPS connector to send alerts to Fl
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Coralogix
----
These steps require Notification Center admin permissions (create connectors, presets, and routers, and edit alert definition labels).
@@ -101,7 +100,6 @@ Let the alert actually trigger and confirm that Flashduty receives an active ale
</Steps>
## Alert Key
----
Flashduty uses `alert.groupingKey` as the Alert Key. Coralogix defines `groupingKey` as the deduplication key in its alert notification schema, and its official Opsgenie and Jira Service Management setups use `groupingKey` to close the matching alert on `Resolved`.
@@ -110,7 +108,6 @@ With **Separate cases**, each Group by combination is notified separately with i
Changes to the title, description, priority, or group values do not change the Alert Key.
## Status and severity
----
Flashduty uses `status` to tell triggers from recoveries, and `priority` (`alert.highestPriority`, or the alert definition priority when empty) to set the severity.
@@ -126,7 +123,6 @@ Flashduty uses `status` to tell triggers from recoveries, and `priority` (`alert
When `status` is `Resolved`, Flashduty recovers the original alert and keeps its last severity. An empty or any other `status` is rejected.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -142,7 +138,6 @@ When `status` is `Resolved`, Flashduty recovers the original alert and keeps its
An alert can have at most 50 labels. Requests that exceed this limit are rejected.
## Troubleshooting
----
- **Coralogix reports a delivery failure**: Confirm that the connector URL is the complete push URL and includes `integration_key`
- **Flashduty returns a parameter error**: Confirm that the preset Body matches the template above, renders valid JSON, and that `grouping_key` and `status` are not empty
diff --git a/en/on-call/integration/alert-integration/alert-sources/coroot.mdx b/en/on-call/integration/alert-integration/alert-sources/coroot.mdx
index 76d472d3..ec4519dc 100644
--- a/en/on-call/integration/alert-integration/alert-sources/coroot.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/coroot.mdx
@@ -1,5 +1,6 @@
---
title: "Coroot Alert Integration"
+sidebarTitle: "Coroot"
description: "Sync Coroot alert and SLO incident open and resolve notifications to Flashduty On-call through a Webhook integration."
keywords: ["alert integration", "Coroot", "Webhook", "Incident", "Alert", "observability"]
---
@@ -9,7 +10,6 @@ Sync the alerts (alerting rules) and SLO incidents of a Coroot project to Flashd
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Coroot
----
<Steps>
<Step title="Create a Webhook integration">
@@ -76,7 +75,6 @@ Coroot only sends webhooks for categories that have notifications enabled.
</Steps>
## Alert Key
----
Flashduty uses the ID carried in the `url` field of the Coroot notification as the Alert Key:
@@ -88,7 +86,6 @@ Flashduty uses the ID carried in the `url` field of the Coroot notification as t
Coroot generates a unique ID when it creates an alert or incident, and the open and resolve notifications use the same one. If the same rule fires again on the same application, Coroot creates a new ID, so it is a new Flashduty alert. Changes to severity, rule name, summary or the domain in `url` never change the Alert Key.
## Status and severity
----
Coroot sends a notification only when an alert or incident opens or resolves; a severity change in between is not notified.
@@ -104,7 +101,6 @@ Coroot sends a notification only when an alert or incident opens or resolves; a
- An unrecognized `status` is treated as Warning, so that Coroot is not made to pause later notifications by an error response
## Labels
----
| Label | Meaning |
| :--- | :--- |
@@ -117,7 +113,6 @@ Coroot sends a notification only when an alert or incident opens or resolves; a
| Custom fields | Custom fields configured on the integration |
## Troubleshooting
----
<AccordionGroup>
<Accordion title="Coroot logs show failed to send alert ... 400">
diff --git a/en/on-call/integration/alert-integration/alert-sources/cronicle.mdx b/en/on-call/integration/alert-integration/alert-sources/cronicle.mdx
index 59a7479a..7eee15b2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/cronicle.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/cronicle.mdx
@@ -1,5 +1,6 @@
---
title: "Cronicle alert integration"
+sidebarTitle: "Cronicle"
description: "Send Cronicle job failures and launch failures to Flashduty On-call through the event web hook, and recover automatically on the next successful run."
keywords: ["alert integration", "Cronicle", "job scheduler", "cron", "webhook"]
---
@@ -9,7 +10,6 @@ Use the Cronicle event web hook to send job failures and launch failures to Flas
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Cronicle
----
<Steps>
<Step title="Enter the web hook URL">
@@ -61,7 +60,6 @@ An alert closes only when the next job of the same event succeeds. Events that a
</Steps>
## Payload
----
Cronicle POSTs the following fields as JSON. Flashduty parses them directly, with no template to configure:
@@ -80,12 +78,10 @@ Cronicle POSTs the following fields as JSON. Flashduty parses them directly, wit
The body also contains the event parameters (`params`) and the web hook URL (`web_hook`). Flashduty neither reads nor stores these two fields.
## Alert Key
----
Flashduty uses `event` (the event ID) as the Alert Key. Every job of the same event carries the same `event`, and only the job ID `id` changes per run, so failures, launch failures, and the later success of one event land on the same alert. Changing the event title, the exit code, or the server that ran the job does not change the Alert Key.
## Status and severity
----
Cronicle notifications carry no severity, so a failed scheduled job is treated as Critical:
@@ -99,7 +95,6 @@ Cronicle notifications carry no severity, so a failed scheduled job is treated a
The Cronicle web hook has no test button. To check connectivity, run an event once.
## FAQ
----
<AccordionGroup>
<Accordion title="If a job has retries configured, do I get a notification for every failed attempt?">
@@ -122,7 +117,6 @@ The Web Hook URL can be set on a single event or on a category, so fill it in on
</AccordionGroup>
## Troubleshooting
----
- **Cronicle does not send anything**: confirm the Web Hook URL is the complete push URL including `integration_key`, and set `debug_level` to 9 to see `Web Hook Error` and `Web Hook Response` entries in the Cronicle log
- **Flashduty returns a parameter error**: confirm the body contains `action` and `event`, and that `job_complete` notifications contain `code`
diff --git a/en/on-call/integration/alert-integration/alert-sources/cronitor.mdx b/en/on-call/integration/alert-integration/alert-sources/cronitor.mdx
index c6542a09..1aa17114 100644
--- a/en/on-call/integration/alert-integration/alert-sources/cronitor.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/cronitor.mdx
@@ -1,5 +1,6 @@
---
title: "Cronitor alert integration"
+sidebarTitle: "Cronitor"
description: "Send Cronitor monitor alert and recovery notifications to Flashduty On-call through a webhook."
keywords: ["alert integration", "Cronitor", "cron", "heartbeat monitoring", "webhook"]
---
@@ -11,7 +12,6 @@ According to the Cronitor pricing page, webhook alerts are included in the free
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Cronitor
----
<Steps>
<Step title="Create a webhook integration">
@@ -70,7 +69,6 @@ Cronitor recommends testing alerts with a heartbeat monitor:
</Steps>
## Payload fields
----
Cronitor sends the following fields as JSON:
@@ -90,7 +88,6 @@ Cronitor sends the following fields as JSON:
The alert title is the issue name; when it is empty, the monitor name, then the monitor key. Every alert also carries the label `source=cronitor`.
## Alert Key
----
Flashduty builds the Alert Key from the monitor key (`id`) and the environment (`environment`):
@@ -103,7 +100,6 @@ The monitor key is the same for every outage. After an alert recovers, the next
Changing the monitor key, or deleting the monitor and creating it again, produces a new Alert Key that is no longer linked to the old alert.
## Status and severity
----
Cronitor webhooks carry no severity. Flashduty maps them as follows:
@@ -115,7 +111,6 @@ Cronitor webhooks carry no severity. Flashduty maps them as follows:
`type` is matched case-insensitively. Requests without `id`, or with an empty or any other `type`, are rejected.
## FAQ
----
<AccordionGroup>
<Accordion title="Does a monitor that keeps failing send repeated notifications?">
@@ -134,7 +129,6 @@ Resolving an issue by hand in Cronitor sends no recovery notification. A failure
</AccordionGroup>
## Troubleshooting
----
- **Flashduty returns an invalid parameter error**: make sure the push URL is complete (including `integration_key`) and the body has the `id` and `type` fields
- **No notifications arrive**: make sure the webhook is selected in the monitor's notification list, and the list's environments include the alert's environment
diff --git a/en/on-call/integration/alert-integration/alert-sources/crowdsec.mdx b/en/on-call/integration/alert-integration/alert-sources/crowdsec.mdx
index 4b69fe9f..b062eafb 100644
--- a/en/on-call/integration/alert-integration/alert-sources/crowdsec.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/crowdsec.mdx
@@ -1,5 +1,6 @@
---
title: "CrowdSec alert integration"
+sidebarTitle: "CrowdSec"
description: "Sync attack sources detected by the CrowdSec Security Engine to Flashduty On-call through its HTTP notification plugin."
keywords: ["alert integration", "CrowdSec", "Security Engine", "intrusion prevention", "IPS", "HTTP notification plugin", "webhook"]
---
@@ -9,7 +10,6 @@ The CrowdSec Security Engine is an open-source, self-hosted intrusion detection
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure CrowdSec
----
Do the following on the machine that runs the CrowdSec Local API (LAPI). The HTTP notification plugin ships with CrowdSec, so nothing extra needs to be installed.
@@ -98,24 +97,20 @@ An Info alert titled `test alert` appears in Flashduty. It does not recover on i
</Steps>
## What is pushed
----
Each request carries a JSON array with one CrowdSec alert per element; with `group_wait` or `group_threshold`, CrowdSec holds alerts until the next flush, so delivery can lag the detection by up to `group_wait`, and a request may hold several alerts. Flashduty creates one alert per array element. The event details (`events`) and the raw logs in `meta` are not sent to Flashduty.
## Alert Key
----
Flashduty uses the `uuid` that CrowdSec generates for each alert as the Alert Key. A retried request carries the same `uuid` and merges into the same alert; when the same source IP triggers again later, the new alert has a new `uuid` and creates a new Flashduty alert.
For older releases that send no `uuid`, Flashduty derives the Alert Key from the scenario, source scope, source value and `start_at`. The request is rejected when those fields are missing.
## Severity
----
CrowdSec provides no severity, so every alert triggers at **Warning**, including alerts in simulation mode (`simulated`). The test alert from `cscli notifications test` is **Info** and uses its own Alert Key, so it never merges with a real alert.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -136,7 +131,6 @@ CrowdSec provides no severity, so every alert triggers at **Warning**, including
The alert title is `<scenario> from <source value>` and the description is the CrowdSec `message`.
## FAQ
----
<AccordionGroup>
diff --git a/en/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale.mdx b/en/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale.mdx
index ca16240d..23f6ca4a 100644
--- a/en/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale.mdx
@@ -1,5 +1,6 @@
---
title: "CrowdStrike Falcon LogScale alert integration"
+sidebarTitle: "CrowdStrike Falcon LogScale"
description: "Send Trigger hits from Falcon LogScale (formerly Humio) to Flashduty On-call through the Trigger's Webhook Action."
keywords: ["alert integration", "CrowdStrike", "Falcon LogScale", "Humio", "Webhook Action", "Trigger"]
---
@@ -12,7 +13,6 @@ Falcon LogScale (formerly Humio) describes an always-running query as a **Trigge
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -33,7 +33,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Falcon LogScale
----
<Steps>
<Step title="Create a Webhook Action">
@@ -75,7 +74,6 @@ LogScale triggers only fire; they never send anything that means "resolved", so
</Steps>
## Payload
----
Flashduty parses the request body against LogScale's own default Message Body Template, sent as `application/json`:
@@ -115,7 +113,6 @@ Flashduty parses the request body against LogScale's own default Message Body Te
Don't rename or move the fields above in the default template. The template can carry more variables, but Flashduty only reads the fields in this table and ignores the rest.
## Alert Key
----
Flashduty uses `alert.id` (what the LogScale docs define as the Trigger ID) as the Alert Key directly:
@@ -124,12 +121,10 @@ Flashduty uses `alert.id` (what the LogScale docs define as the Trigger ID) as t
- A request without `alert.id` is rejected
## Status and severity
----
LogScale's default template carries no severity field, so every alert opens as Warning.
## FAQ
----
<AccordionGroup>
<Accordion title="Why don't these alerts recover on their own?">
@@ -152,7 +147,6 @@ No. Flashduty identifies the integration by the `integration_key` in the push UR
</AccordionGroup>
## Troubleshooting
----
- **"Problem invoking test action" when clicking Test action**: usually means `{id}` and other template variables had no real value at test time, so Flashduty rejected the empty `alert.id`. Trigger a real match with your query to verify instead
- **No alert in Flashduty**: check that the action's URL is complete (including `integration_key`) and that the action is attached to a trigger
diff --git a/en/on-call/integration/alert-integration/alert-sources/crowdstrike.mdx b/en/on-call/integration/alert-integration/alert-sources/crowdstrike.mdx
index b8183da8..f1967efc 100644
--- a/en/on-call/integration/alert-integration/alert-sources/crowdstrike.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/crowdstrike.mdx
@@ -1,5 +1,6 @@
---
title: "CrowdStrike Falcon alert integration"
+sidebarTitle: "CrowdStrike Falcon"
description: "Send EPP and NG-SIEM detections to Flashduty On-call through the Cloud HTTP Request action of a CrowdStrike Falcon Fusion SOAR workflow."
keywords: ["alert integration", "CrowdStrike", "Falcon", "Fusion SOAR", "EDR", "NG-SIEM", "webhook"]
---
@@ -9,7 +10,6 @@ CrowdStrike Falcon has no built-in generic alert webhook: detection notification
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure CrowdStrike Falcon
----
The steps below need permission to create and release (publish) Fusion SOAR workflows in the Falcon console. The NG-SIEM Detection trigger needs the Next-Gen SIEM module; the EPP Detection trigger needs Falcon Insight/Prevent endpoint detection. The Falcon cloud must be able to reach the domain of the push URL.
@@ -85,7 +84,6 @@ To also ingest endpoint protection (EPP) detections, repeat the previous step fo
</Steps>
## Alert Key
----
Flashduty uses the `detection_id` field of the request body as the Alert Key. It maps to the Falcon Fusion trigger variable `${data['Trigger.Detection.DetectionID']}` — CrowdStrike's own Fusion workflow authoring reference calls this path "release-verified" (checked to exist at release time), and both the NG-SIEM and EPP detection triggers return it in the same composite-ID format for the same detection.
@@ -97,7 +95,6 @@ Flashduty rejects a request that is missing `detection_id`, or whose `severity`
Falcon Fusion has no "detection closed" trigger that carries the detection ID, so this integration is one-shot: Flashduty does not close an alert when the detection is closed in Falcon. **Turn on [auto-close](/en/on-call/channel/create-edit) for the channel (24 hours is a reasonable default for security detections).** A repeat of the same detection inside that window refreshes the same alert.
## Severity mapping
----
| CrowdStrike `severity` (SeverityDisplayName) | Flashduty level |
| :--- | :--- |
@@ -109,7 +106,6 @@ Falcon Fusion has no "detection closed" trigger that carries the detection ID, s
| (empty) | **Warning** |
## Alert content
----
- **Title**: `name` (the detection name), falling back to `CrowdStrike detection` when empty
- **Labels**: `detection_id`, `product` (`NGSIEM` or `EPP`), `severity_raw` (the raw `severity` value); the NG-SIEM template also sends `source_url`; the EPP template also sends `resource`/`host` (`hostname`), `process_sha256`, `ioc_value`, `ioc_type`
@@ -117,7 +113,6 @@ Falcon Fusion has no "detection closed" trigger that carries the detection ID, s
Empty fields are not written as labels.
## Troubleshooting
----
- **The workflow shows no error, but Flashduty never receives an alert**: confirm the workflow was **Released**, not just saved as a draft — a draft workflow never runs
- **The HTTP Action fails with a 400 in the logs**: check that the body field names match the templates above exactly; the response names the missing or unsupported field (for example `detection_id is required`)
diff --git a/en/on-call/integration/alert-integration/alert-sources/ctyun.mdx b/en/on-call/integration/alert-integration/alert-sources/ctyun.mdx
index 29fa7690..131a68fa 100644
--- a/en/on-call/integration/alert-integration/alert-sources/ctyun.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/ctyun.mdx
@@ -1,5 +1,6 @@
---
title: "StateCloud Alert Events"
+sidebarTitle: "StateCloud"
description: "Sync StateCloud alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -11,46 +12,45 @@ For resource monitoring events from StateCloud [secondary nodes](#secondary-node
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Dedicated Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Select **StateCloud** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **StateCloud** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In StateCloud
----
<div class="md-block">
-## I. StateCloud Alert Push Configuration
1. Log in to your `StateCloud` console, search for the `Cloud Eye` product, and enter its console
2. In `Alarm Service`, select `Alarm Contact/Group` and create corresponding alert contact/group
@@ -62,7 +62,7 @@ Choose this option when you need to route alerts to different channels based on
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
@@ -72,7 +72,7 @@ Choose this option when you need to route alerts to different channels based on
| Warning | Warning | warning |
| Normal | Info | info |
-## III. StateCloud Secondary Node List<span id="secondary-nodes"></span>
+## StateCloud Secondary Node List<span id="secondary-nodes"></span>
| Region | Cities |
| ---------- | -------- |
diff --git a/en/on-call/integration/alert-integration/alert-sources/cubeapm.mdx b/en/on-call/integration/alert-integration/alert-sources/cubeapm.mdx
index 184ce35d..f35bd5b9 100644
--- a/en/on-call/integration/alert-integration/alert-sources/cubeapm.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/cubeapm.mdx
@@ -1,5 +1,6 @@
---
title: "CubeAPM Alert Integration"
+sidebarTitle: "CubeAPM"
description: "Receive CubeAPM alerts through CubeAPM's webhook receiver using a Flashduty Prometheus integration; alerts close automatically when they resolve."
keywords: ["alert integration", "CubeAPM", "webhook", "Prometheus", "Alertmanager", "observability"]
---
@@ -9,7 +10,6 @@ CubeAPM can send alert notifications by HTTP POST to any webhook URL. The defaul
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the Prometheus integration type** in both, not CubeAPM.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the Promet
</div>
## Configure in CubeAPM
----
<Steps>
<Step title="Create a webhook receiver">
@@ -49,7 +48,6 @@ Let a CubeAPM alert rule fire and confirm Flashduty receives an active alert; af
</Steps>
## Field mapping
----
| CubeAPM field | Flashduty |
| :--- | :--- |
@@ -65,13 +63,11 @@ Let a CubeAPM alert rule fire and confirm Flashduty receives an active alert; af
One notification can carry several alerts, and Flashduty handles each one separately (up to 100 per request).
## Recovery and deduplication
----
- When CubeAPM sends a notification whose `status` is not `firing` (for example `resolved`), Flashduty closes the alert with the same `fingerprint`. CubeAPM's own PagerDuty and Zenduty examples likewise map any non-`firing` status to a resolve.
- The CubeAPM documentation does not say whether the webhook has a test-send function. After the first setup, verify with a real alert that both trigger and recovery appear in Flashduty.
## Troubleshooting
----
- **Flashduty returns `Invalid parameters`**: the push URL is incomplete, `integration_key` is missing, or the integration type is not Prometheus
- **Alerts do not resolve**: confirm that every alert in a customized Payload has `status` and `fingerprint`, and that the recovery notification carries the same `fingerprint` as the trigger
diff --git a/en/on-call/integration/alert-integration/alert-sources/dash0.mdx b/en/on-call/integration/alert-integration/alert-sources/dash0.mdx
index 2605c5b5..646d1601 100644
--- a/en/on-call/integration/alert-integration/alert-sources/dash0.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/dash0.mdx
@@ -1,5 +1,6 @@
---
title: "Dash0 alert integration"
+sidebarTitle: "Dash0"
description: "Send Dash0 check rule alert and recovery events to Flashduty On-call through a webhook notification channel."
keywords: ["alert integration", "Dash0", "check rule", "webhook", "issueIdentifier"]
---
@@ -9,14 +10,12 @@ Use a Dash0 webhook notification channel to send check rule alerts to Flashduty
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **Dash0** alert integration and copy its complete Push URL.
</div>
## Configure Dash0
----
<Steps>
<Step title="Create a webhook notification channel">
@@ -42,14 +41,12 @@ Let a check rule cross its threshold and confirm Flashduty receives an active al
</Steps>
## Alert Key
----
Flashduty uses `data.issue.issueIdentifier` as the Alert Key. Dash0 documents it as the "identifier for the combination of CheckRule and Resource, should remain stable over different issue instances", so trigger and recovery carry the same value.
`data.issue.id` identifies a single issue instance and `data.issue.checkrules[].id` identifies the check rule. Both are kept as labels only and are not part of the Alert Key. Changes to the title, status, description, start time, or check rule version do not change the Alert Key. An alert-type request without `issueIdentifier` is rejected, because later recovery could not be matched.
## Event types and severity
----
| Dash0 `type` | Flashduty handling |
| :--- | :--- |
@@ -68,7 +65,6 @@ Flashduty uses `data.issue.issueIdentifier` as the Alert Key. Dash0 documents it
Dash0 does not publish the exact meaning of `alert.closed` and `alert.superseded`. Flashduty handles them conservatively: `closed` is treated as the issue having ended, and `superseded` is assumed to be followed by a new `alert.ongoing` for the same identifier, so it does not change alert state.
## Troubleshooting
----
- **Dash0 gets a non-2xx response**: confirm the Push URL is complete and includes `integration_key`
- **Flashduty returns an invalid-parameter error**: confirm the body is valid JSON and `data.issue.issueIdentifier` is not empty
diff --git a/en/on-call/integration/alert-integration/alert-sources/datadog.mdx b/en/on-call/integration/alert-integration/alert-sources/datadog.mdx
index 0bec748a..15039e18 100644
--- a/en/on-call/integration/alert-integration/alert-sources/datadog.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/datadog.mdx
@@ -1,5 +1,6 @@
---
title: "Datadog alert integration"
+sidebarTitle: "Datadog"
description: "Send Datadog Monitor alerts to Flashduty On-call through webhooks and correlate firing, update, and recovery events correctly."
keywords: ["alert integration", "Datadog", "webhook", "Monitor", "alert recovery"]
---
@@ -9,7 +10,6 @@ Use a Datadog webhook to send Monitor alerts to Flashduty On-call. Flashduty pri
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
### Use a dedicated integration
@@ -17,7 +17,7 @@ You can obtain an integration push URL in either of the following ways.
Choose this method when you do not need to route alerts to different channels.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View dedicated integration setup steps">
1. In the Flashduty console, select **Channel** and open a channel
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**
@@ -32,7 +32,7 @@ Choose this method when you do not need to route alerts to different channels.
Choose this method when you need to route alerts to different channels based on the payload.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View shared integration setup steps">
1. In the Flashduty console, select **Integration Center → Alert Events**
2. Select **Datadog** and enter an integration name
@@ -45,7 +45,6 @@ Choose this method when you need to route alerts to different channels based on
</div>
## Configure a webhook in Datadog
----
<Steps>
<Step title="Create the webhook">
@@ -123,7 +122,6 @@ A Datadog test notification can verify webhook connectivity, but only a real fir
</Steps>
## Add custom labels
----
The default payload includes common environment, service, team, and region labels. To send additional Datadog variables, add a `custom_labels` object at the top level of the payload:
@@ -152,7 +150,6 @@ Do not encode multiple custom labels in a comma-separated string. Label values c
</Warning>
## Alert Key
----
Flashduty primarily uses `$ALERT_CYCLE_KEY` as the Alert Key. Datadog defines this value as the ID that links events from the time an alert triggers until it resolves, so repeat notifications and recovery events update the same Flashduty alert.
@@ -161,7 +158,6 @@ If `alert_cycle_key` is missing or empty, Flashduty generates a random Alert Key
`$ID`, `$ALERT_ID`, `$AGGREG_KEY`, the title, severity, timestamps, and custom labels do not participate in Alert Key generation.
## Status and Severity
----
Recovery is determined only from `$ALERT_TRANSITION` and is independent of severity mapping.
@@ -177,7 +173,6 @@ Recovery is determined only from `$ALERT_TRANSITION` and is independent of sever
To change the severity, remap it with an [Alert Processing Pipeline](/en/on-call/integration/alert-integration/alert-pipelines).
## Troubleshooting
----
- **Datadog does not send a request**: Confirm that the Monitor notification message contains the correct `@webhook-<name>` recipient
- **Flashduty returns an invalid parameter error**: Confirm that the payload is valid JSON and contains a non-empty `alert_transition` value
diff --git a/en/on-call/integration/alert-integration/alert-sources/datto-rmm.mdx b/en/on-call/integration/alert-integration/alert-sources/datto-rmm.mdx
index 2cd1f612..dea8e925 100644
--- a/en/on-call/integration/alert-integration/alert-sources/datto-rmm.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/datto-rmm.mdx
@@ -1,5 +1,6 @@
---
title: "Datto RMM alert integration"
+sidebarTitle: "Datto RMM"
description: "Send Datto RMM device alert and auto-resolve events to Flashduty On-call through a webhook."
keywords: ["alert integration", "Datto RMM", "webhook", "alert_uid", "RMM"]
---
@@ -11,14 +12,12 @@ Datto RMM sends a request body that you write yourself, so paste the JSON templa
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **Datto RMM** alert integration and copy its complete Push URL.
</div>
## Configure Datto RMM
----
You can configure the webhook on a single monitor's response settings or globally. **Turning on Global Webhooks automatically disables the webhooks set on individual monitors**, so use one or the other.
@@ -93,12 +92,10 @@ Click **Test Webhook** (**Test Alert Webhook** for global webhooks) to confirm D
</Steps>
## Alert Key
----
Flashduty uses `alert_uid` (the Datto RMM variable `[alert_uid]`, documented as "The alert ID") as the Alert Key. The alert-raised and alert-resolved payloads use the same variable, so they refer to the same alert. Changes to device, site, alert type, message, or severity do not change the Alert Key.
## Status and severity
----
| `event` | Flashduty status |
| :--- | :--- |
@@ -113,12 +110,10 @@ Flashduty uses `alert_uid` (the Datto RMM variable `[alert_uid]`, documented as
| Empty or other | Warning |
## About recovery
----
Datto RMM sends the resolved payload only when an alert resolves **automatically**; resolving an alert manually in the console sends nothing. Turn on [auto-close after timeout](/en/on-call/channel/create-edit) in the channel that receives these alerts, with a suggested duration of 24 hours, so manually resolved alerts do not stay open.
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: Check that the payload is valid JSON, `alert_uid` is not empty, and `event` is `triggered` or `resolved`
- **The alert does not recover**: Check that **When alert is resolved (optional)** is on and uses the `resolved` template; manually resolved alerts send no recovery
diff --git a/en/on-call/integration/alert-integration/alert-sources/db-pull.mdx b/en/on-call/integration/alert-integration/alert-sources/db-pull.mdx
index 8b4cf8e3..f8586f00 100644
--- a/en/on-call/integration/alert-integration/alert-sources/db-pull.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/db-pull.mdx
@@ -1,5 +1,6 @@
---
title: "Database Pull Alert Integration (DB Pull)"
+sidebarTitle: "Database Pull (DB Pull)"
description: "Flashduty periodically queries a MySQL, PostgreSQL, or ClickHouse database and converts matching rows into standard alert events. Use this when alert data is already written to a relational database and the system cannot push alerts outward."
keywords: ["Alert Integration", "DB Pull", "Database", "MySQL", "PostgreSQL", "ClickHouse", "Polling", "Data Ingestion"]
---
@@ -13,7 +14,6 @@ DB Pull is the right choice when **alert data is already stored in a relational
<div className="hide">
## Setup Steps
----
### In Flashduty
@@ -33,7 +33,7 @@ When you don't need to route alert events to different channels, this method is
When you need to route alert events to different channels based on the alert payload, choose this method.
-1. Enter the Flashduty console, select **Integration Center => Alert Events** to enter the integration selection page.
+1. Enter the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page.
2. Select the **DB Pull** integration and fill in the **Integration Name**.
3. Configure the **Default Route** and select the corresponding channel (after the integration is created, go to **Route** to add finer-grained routing rules).
4. Fill in the form as described in the "Configuration" section below and click **Save**.
@@ -42,7 +42,6 @@ When you need to route alert events to different channels based on the alert pay
</div>
## Configuration
----
### Database Driver
@@ -149,14 +148,12 @@ Example configuration:
```
## Default Route
----
-When creating a "Shared Integration" (under **Integration Center => Alert Events**), you must configure a default route — otherwise newly pulled events will be dropped. After creation, you can add finer-grained rules under **Route**.
+When creating a "Shared Integration" (under **Integration Center → Alert Events**), you must configure a default route — otherwise newly pulled events will be dropped. After creation, you can add finer-grained rules under **Route**.
A "Dedicated Integration" (created under **Configuration → Integrations → Private integration** in a specific channel) is automatically bound to that channel and does not require a separate default route.
## Notes
----
- **Database account permissions**: Create a dedicated read-only account for DB Pull with only `SELECT` privilege on the target table. Do not grant write access.
- **Network reachability**: The Flashduty service must be able to reach `host:port` over the public internet or a dedicated line. Private subnets (`10.x.x.x`, `192.168.x.x`, `172.16–31.x.x`) and loopback addresses are rejected by the system.
diff --git a/en/on-call/integration/alert-integration/alert-sources/dbmarlin.mdx b/en/on-call/integration/alert-integration/alert-sources/dbmarlin.mdx
index 07670ec1..d6245abf 100644
--- a/en/on-call/integration/alert-integration/alert-sources/dbmarlin.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/dbmarlin.mdx
@@ -1,5 +1,6 @@
---
title: "DBmarlin alert integration"
+sidebarTitle: "DBmarlin"
description: "Send DBmarlin instance and host alert start and end events to Flashduty On-call through its Webhook integration."
keywords: ["alert integration", "DBmarlin", "database monitoring", "webhook"]
---
@@ -11,14 +12,12 @@ DBmarlin's webhook has no fixed format: you write the request body in the **Cont
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **DBmarlin** alert integration and copy its complete Push URL.
</div>
## Configure DBmarlin
----
The Webhook integration requires DBmarlin v5.11 or later, and the webhook you create is marked **Default** and enabled, which is what sends alerts.
@@ -95,7 +94,6 @@ Save and enable the integration. Under **Settings → Alert Rules**, create a ru
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from the rule ID (`ruleid`) plus the instance name (`instance`) or host name (`node`); instance alerts and host alerts never share a key. The "started" and "ended" notifications of one rule on the same instance or host share one Alert Key; changes to `from`, `to`, values, and the rule name do not change it.
@@ -103,7 +101,6 @@ Flashduty computes the Alert Key from the rule ID (`ruleid`) plus the instance n
- When the same rule fires again, it uses the same Alert Key
## Status and severity
----
| DBmarlin `startedended` | Flashduty status or severity |
| :--- | :--- |
@@ -113,12 +110,10 @@ Flashduty computes the Alert Key from the rule ID (`ruleid`) plus the instance n
The webhook body carries no severity, so every alert is treated as Warning. DBmarlin sends `startedended` in upper case (`STARTED`, `ENDED`); Flashduty ignores the case, treats a value starting with `end` as the end and any other value as a start.
## Recovery and auto-close
----
DBmarlin sends an "ended" notification when an alert ends, and Flashduty uses it to recover the alert. To keep a lost notification from leaving an alert open, configure **auto-close after timeout** on the channel or integration, longer than your rules can stay active.
## Troubleshooting
----
- **DBmarlin logs `status code 400`**: confirm the template is valid JSON and contains `ruleid`, plus `instance` (instance alerts) or `node` (host alerts)
- **`404` or `401`**: confirm the Webhook URL is complete and contains `integration_key`
diff --git a/en/on-call/integration/alert-integration/alert-sources/dead-mans-snitch.mdx b/en/on-call/integration/alert-integration/alert-sources/dead-mans-snitch.mdx
index 98a8a0e7..07e91402 100644
--- a/en/on-call/integration/alert-integration/alert-sources/dead-mans-snitch.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/dead-mans-snitch.mdx
@@ -1,5 +1,6 @@
---
title: "Dead Man's Snitch alert integration"
+sidebarTitle: "Dead Man's Snitch"
description: "Send Dead Man's Snitch missing, errored, and recovery notifications to Flashduty On-call through a webhook."
keywords: ["alert integration", "Dead Man's Snitch", "cron", "heartbeat monitoring", "webhook"]
---
@@ -11,7 +12,6 @@ According to the Dead Man's Snitch pricing page, integrations are available from
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Dead Man's Snitch
----
<Steps>
<Step title="Add a webhook integration">
@@ -67,7 +66,6 @@ If your plan includes Error Notices, you can also report a non-zero exit status
</Steps>
## Payload fields
----
Dead Man's Snitch sends the following fields as JSON:
@@ -84,7 +82,6 @@ Dead Man's Snitch sends the following fields as JSON:
The alert title is the snitch name followed by its state, for example `Nightly Backup is missing`. When the name is empty, `Snitch` is used. Every alert also carries the label `source=dead-mans-snitch`.
## Alert Key
----
The token is the check-in credential of the snitch: anyone who holds it can check in to the snitch. Flashduty therefore never shows the token in alerts and uses the MD5 hash of the token as the Alert Key:
@@ -94,7 +91,6 @@ The token is the check-in credential of the snitch: anyone who holds it can chec
The token stays the same for the whole life of a snitch. After an alert recovers, the next time the same snitch goes missing a new alert is created; the recovered alert is not reopened. Deleting a snitch and creating it again produces a new token that is no longer linked to the old alert.
## Status and severity
----
Dead Man's Snitch webhooks carry no severity. Flashduty maps them as follows:
@@ -108,7 +104,6 @@ Dead Man's Snitch webhooks carry no severity. Flashduty maps them as follows:
`type` is case-insensitive. Requests without `data.snitch.token`, or with an empty or other `type`, are rejected.
## FAQ
----
<AccordionGroup>
<Accordion title="Does a snitch that stays missing send repeated notifications?">
@@ -131,7 +126,6 @@ The first check-in of a new snitch also sends `snitch.reporting`. There is no ac
</AccordionGroup>
## Troubleshooting
----
- **Flashduty returns a parameter error**: make sure the push URL is complete (it includes `integration_key`) and the request body contains `type` and `data.snitch.token`
- **No notifications arrive**: make sure your plan includes integrations. If the webhook has tag filters, make sure the snitch carries one of those tags
diff --git a/en/on-call/integration/alert-integration/alert-sources/dependency-track.mdx b/en/on-call/integration/alert-integration/alert-sources/dependency-track.mdx
index 4ba429ff..24761818 100644
--- a/en/on-call/integration/alert-integration/alert-sources/dependency-track.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/dependency-track.mdx
@@ -1,5 +1,6 @@
---
title: "Dependency-Track Alert Integration"
+sidebarTitle: "Dependency-Track"
description: "Sync new vulnerabilities, newly vulnerable dependencies and policy violations found by Dependency-Track to Flashduty On-call through an Outbound Webhook."
keywords: ["alert integration", "Dependency-Track", "Webhook", "SBOM", "vulnerability", "policy violation", "software supply chain"]
---
@@ -17,7 +18,6 @@ Dependency-Track notifies once when it finds a problem and sends nothing when th
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -38,7 +38,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Dependency-Track
----
<Steps>
<Step title="Create a notification rule">
@@ -76,7 +75,6 @@ Selecting other groups (for example BOM_CONSUMED or PROJECT_AUDIT_CHANGE) does n
</Steps>
## Alert Key
----
Flashduty builds the Alert Key from the `uuid` values in the notification, joined with an invisible separator and hashed with MD5:
@@ -93,7 +91,6 @@ Flashduty builds the Alert Key from the `uuid` values in the notification, joine
- When the `uuid` of the project, component, vulnerability or policy violation is missing, Flashduty returns 400 and names the missing field
## Status and severity
----
NEW_VULNERABILITY uses `subject.vulnerability.severity`; NEW_VULNERABLE_DEPENDENCY uses the most severe of its vulnerabilities:
@@ -112,21 +109,18 @@ POLICY_VIOLATION carries no vulnerability, so the policy's violation state decid
| `INFO` or any other value | Info |
## Alerts do not recover automatically
----
Dependency-Track notifies once per problem and has no "vulnerability fixed" or "violation cleared" notification, so every alert stays open until it is closed. In the channel that receives this integration, turn on [auto-close after timeout](/en/on-call/channel/create-edit) and set it to how quickly your team handles vulnerabilities, for example 7 days.
A repeated notification for the same problem (for example the same vulnerability found again after a re-analysis) merges into the alert that is still open; if that alert was closed, a new alert is created.
## Alert content
----
- **Title**: `Dependency-Track: <vulnerability ID> in <component> (<project>)` for NEW_VULNERABILITY; `Dependency-Track: vulnerable dependency <component> in <project> (<N> vulnerabilities)` for NEW_VULNERABLE_DEPENDENCY; `Dependency-Track: policy violation <policy name> on <component> (<project>)` for POLICY_VIOLATION
- **Description**: the notification content, the project and component, and each vulnerability's source, severity, CVSS scores, aliases and recommendation (at most 10 vulnerabilities for a vulnerable dependency, most severe first); for a policy violation, the policy, violation type and condition
- **Labels**: `source=dependency_track`, `group`, `project_uuid`, `project_name`, `project_version`, `component_uuid`, `component_group`, `component_name`, `component_version`, `component_purl`, `vuln_id`, `vuln_source`, `vuln_uuid`, `vuln_severity`, `vuln_count`, `vuln_ids`, `policy_name`, `violation_type`, `violation_state`, `violation_uuid`
## Troubleshooting
----
<AccordionGroup>
<Accordion title="The rule is saved but Flashduty receives no request">
diff --git a/en/on-call/integration/alert-integration/alert-sources/dingtalk-alert.mdx b/en/on-call/integration/alert-integration/alert-sources/dingtalk-alert.mdx
index 242289a5..41939b35 100644
--- a/en/on-call/integration/alert-integration/alert-sources/dingtalk-alert.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/dingtalk-alert.mdx
@@ -1,5 +1,6 @@
---
title: "DingTalk Bot Compatible Integration"
+sidebarTitle: "DingTalk Bot Compatible"
description: "Flashduty generates a webhook address in the format of a DingTalk custom robot. Point a tool that already sends alerts to a DingTalk custom robot at this address to bring alert triggers and recoveries into Flashduty."
keywords: ["alert integration", "DingTalk Bot Compatible", "DingTalk custom robot", "webhook"]
---
@@ -9,7 +10,6 @@ Generate a unique Dingtalk robot address in Flashduty, and synchronize the occur
<div class="hide">
## Operation Steps
----
### Create DingTalk Bot Compatible Integration
@@ -19,24 +19,25 @@ You can obtain a DingTalk Bot Compatible integration address through either of t
Choose this method when you don't need to route alert events to different channels. It's simpler and recommended.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **DingTalk Bot Compatible** integration and click **Save** to generate a card
4. Click the generated card to view the **DingTalk Bot Compatible Integration URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
#### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center => Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **DingTalk Bot Compatible** integration:
- **Integration Name**: Define a name for the current integration
- **Message Type**: Select Dingtalk alert message type, currently only Text and Markdown are supported
@@ -45,7 +46,8 @@ Choose this method when you need to route alerts to different channels based on
4. Configure the default route and select the corresponding channel (after integration creation, you can go to `Routes` to configure more routing rules)
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
### Customize DingTalk Bot Compatible Integration
@@ -76,12 +78,10 @@ By default, the system always creates new alerts for each message, but you can s
- When Dingtalk message type is Text, Flashduty will generate a default alert title "Dingtalk Alert"
## Severity Mapping
----
Currently, all alerts pushed to Flashduty through the DingTalk Bot Compatible integration are set to Warning severity. However, you can customize the severity using the [alert pipeline](/en/on-call/integration/alert-integration/alert-pipelines).
## Alibaba Cloud Message Center
----
<div class="md-block">
The "Robot Reception" feature in Alibaba Cloud's account Message Center can push account, product, and security notices to a custom webhook. Its data format can reuse the Dingtalk robot protocol, so it connects directly to the DingTalk Bot Compatible integration on this page.
diff --git a/en/on-call/integration/alert-integration/alert-sources/dkron.mdx b/en/on-call/integration/alert-integration/alert-sources/dkron.mdx
index 961edcdb..35a53a36 100644
--- a/en/on-call/integration/alert-integration/alert-sources/dkron.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/dkron.mdx
@@ -1,5 +1,6 @@
---
title: "Dkron alert integration"
+sidebarTitle: "Dkron"
description: "Send Dkron job failure and recovery events to Flashduty On-call through a webhook notification."
keywords: ["alert integration", "Dkron", "cron", "scheduled jobs", "webhook"]
---
@@ -9,7 +10,6 @@ Dkron can send a webhook notification after every job execution. Point it at a F
<div className="hide">
## In Flashduty On-call
----
You can get the Push URL in either of two ways.
@@ -30,7 +30,6 @@ You can get the Push URL in either of two ways.
</div>
## Configure Dkron
----
Dkron has no fixed webhook body. It renders the Go template you set in `webhook-payload` and posts the result. Flashduty parses only the fields the template below produces, so use it as is. The webhook is a server-wide Dkron setting that applies to every job. It is sent once per finished job execution (after retries are used up), by the leader node, for both successes and failures.
@@ -70,12 +69,10 @@ Create a job that fails, for example with the command `false`, and run it manual
</Steps>
## Alert Key
----
Flashduty uses the job name, `job_name` (Dkron's `JobName`), as the Alert Key. The job name identifies a job in Dkron, and every execution result of that job, success or failure, carries the same name, so a failure and the success after it land on the same alert. Changes to the node, the start and end times, or the outcome do not change the Alert Key.
## Status and severity
----
| Dkron execution result | Flashduty status or severity |
| :--- | :--- |
@@ -85,7 +82,6 @@ Flashduty uses the job name, `job_name` (Dkron's `JobName`), as the Alert Key. T
Dkron has no severity, so every failed job is Critical. A request whose `success` is empty or is neither `true` nor `false` is rejected, so a request with an unknown state never lands in the wrong alert lifecycle.
## Alert labels
----
| Label | Source |
| :--- | :--- |
@@ -95,7 +91,6 @@ Dkron has no severity, so every failed job is Critical. A request whose `success
| `started_at`, `finished_at` | Start and end time of the execution |
## Troubleshooting
----
- **Flashduty receives nothing**: Dkron only logs webhook send errors and does not retry. Confirm the server can reach `api.flashcat.cloud` and that the Push URL is complete and includes `integration_key`
- **Dkron logs `notifier: error parsing template`**: the `webhook-payload` template has a syntax error. Compare the quotes and braces with the template above
diff --git a/en/on-call/integration/alert-integration/alert-sources/dolphinscheduler.mdx b/en/on-call/integration/alert-integration/alert-sources/dolphinscheduler.mdx
index 87725bec..8b7934d5 100644
--- a/en/on-call/integration/alert-integration/alert-sources/dolphinscheduler.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/dolphinscheduler.mdx
@@ -1,5 +1,6 @@
---
title: "Apache DolphinScheduler Alert Integration"
+sidebarTitle: "Apache DolphinScheduler"
description: "Send workflow instance failure, success, and timeout notifications from DolphinScheduler's HTTP alert plugin to Flashduty On-call."
keywords: ["alert integration", "DolphinScheduler", "workflow", "Webhook", "job scheduling"]
---
@@ -11,7 +12,6 @@ This integration was verified against DolphinScheduler 3.4.3. You must fill in *
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of two ways. Pick one.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of two ways. Pick one.
</div>
## In DolphinScheduler
----
<Steps>
<Step title="Create an HTTP alarm instance">
@@ -41,14 +40,14 @@ You can get the integration push URL in either of two ways. Pick one.
2. For **Select plugin** choose `Http`, and enter an **Alarm instance name**
3. Fill in the plugin parameters:
-| Parameter | Value |
-| :--- | :--- |
-| URL | The full Flashduty push URL, including `integration_key` |
-| Request Type | `POST` |
-| Headers | Leave empty |
-| Body | `{"content":"${msg}"}` |
-| Content Type | `application/json` |
-| Timeout(s) | Default 120 |
+ | Parameter | Value |
+ | :--- | :--- |
+ | URL | The full Flashduty push URL, including `integration_key` |
+ | Request Type | `POST` |
+ | Headers | Leave empty |
+ | Body | `{"content":"${msg}"}` |
+ | Content Type | `application/json` |
+ | Timeout(s) | Default 120 |
4. Save. The DolphinScheduler server must be able to reach Flashduty on the public internet.
@@ -82,7 +81,6 @@ In **Alarm Instance Manage**, open the alarm instance for editing, click **Test
</Steps>
## Recovery and auto-close
----
DolphinScheduler sends a notification according to the state the workflow instance ends in:
@@ -99,7 +97,6 @@ Workflow and task timeout alerts are sent once and never recover. If nobody re-r
Sub-workflow states are not notified on their own.
## Alert types
----
The `content` array of one request can hold several alert objects. Each object becomes one Flashduty alert.
@@ -111,7 +108,6 @@ The `content` array of one request can hold several alert objects. Each object b
If the alarm group also receives alerts that carry no workflow information (for example a service-down alert), Flashduty rejects them with an invalid-parameter error. To keep failed sends out of DolphinScheduler, create a separate alarm group for this integration.
## Alert Key
----
| Alert type | Alert Key |
| :--- | :--- |
@@ -122,7 +118,6 @@ If the alarm group also receives alerts that carry no workflow information (for
Changes to the workflow instance name, state, run count, or times do not change the Alert Key. A failure and the later success of the same instance share one Alert Key, so the success recovers the failure. An alert object without `projectCode` or `workflowInstanceId` makes the whole request be rejected.
## Status and severity
----
| Source | Status | Severity |
| :--- | :--- | :--- |
@@ -131,7 +126,6 @@ Changes to the workflow instance name, state, run count, or times do not change
| Timeout | Triggered | Warning |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -149,7 +143,6 @@ Changes to the workflow instance name, state, run count, or times do not change
| `task_code` / `task_name` | Task code and name (task timeout) |
## Troubleshooting
----
- **Flashduty receives no events**: confirm the workflow was started with an alarm group and a notification strategy other than **None**, that the alarm group contains the alarm instance, and that the push URL is complete and includes `integration_key`. **Test Send** in the alarm instance's create or edit dialog checks the network path
- **Flashduty returns an invalid-parameter error**: usually **Body** is not `{"content":"${msg}"}`, or an alert without workflow information (for example service-down) was received
diff --git a/en/on-call/integration/alert-integration/alert-sources/domotz.mdx b/en/on-call/integration/alert-integration/alert-sources/domotz.mdx
index 559b2007..c5c45a34 100644
--- a/en/on-call/integration/alert-integration/alert-sources/domotz.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/domotz.mdx
@@ -1,5 +1,6 @@
---
title: "Domotz alert integration"
+sidebarTitle: "Domotz"
description: "Send Domotz Alert Rule notifications for device and collector status, TCP services, latency, and more to Flashduty On-call through a webhook contact channel."
keywords: ["alert integration", "Domotz", "webhook", "network monitoring", "MSP"]
---
@@ -11,7 +12,6 @@ Alert profiles bound through the Domotz Public API deliver named events instead
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure in Domotz
----
You need permission in the Domotz portal to create contact channels and Alert Rules.
@@ -71,12 +70,10 @@ Heartbeat lost, SNMP, IP change, configuration change, security issue, and WAN/L
</Warning>
## Alert Key
----
For an Alert Rule notification (`monitoring_profile_state_changed`), Flashduty builds the Alert Key from the event name and `alert_id`. The Problem and the Resolved notification of one occurrence carry the same `alert_id`, so the alert closes when the state becomes Resolved. The next occurrence gets a new `alert_id` and opens a new alert. A notification without `alert_id`, or with a state other than Problem or Resolved, is rejected.
## State and severity
----
| Alert Rule severity | Flashduty severity |
| :--- | :--- |
@@ -87,7 +84,6 @@ For an Alert Rule notification (`monitoring_profile_state_changed`), Flashduty b
`data.state.current` decides the state: `Problem` triggers the alert and `Resolved` recovers it.
## Events from Public API alert profiles
----
Alert profiles bound through the alert-profile endpoints of the Domotz Public API deliver the events below. Flashduty builds the Alert Key from the event name, `agent_id` (collector ID), and `device_id` (device ID), plus the port for TCP services. The fields are joined with a non-printing separator and hashed with MD5. These identifiers come from the webhook event schemas in the Domotz Public API definition. Changes to device name, state value, or time do not change the Alert Key.
@@ -110,7 +106,6 @@ Alert profiles bound through the alert-profile endpoints of the Domotz Public AP
One `device_tcp` notification can list several ports. Flashduty creates one event per port, in ascending port order, and processes at most 50. Device discovery, feature discovery, and MIB discovery are accepted but create no alert. A state value outside the table returns a parameter error.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -125,7 +120,6 @@ One `device_tcp` notification can list several ports. Flashduty creates one even
| `trigger_name` | SNMP trigger name |
## Troubleshooting
----
- **No alerts arrive**: confirm the Alert Rule is applied to a device or collector (**Applied To** is not `-`) and lists this webhook channel under **Notification Channels**
- **An alert does not recover**: only the events with a recovery condition in the table recover on their own; rely on auto-close for the rest
diff --git a/en/on-call/integration/alert-integration/alert-sources/dotcom-monitor.mdx b/en/on-call/integration/alert-integration/alert-sources/dotcom-monitor.mdx
index 42adcf29..3c3e9fe3 100644
--- a/en/on-call/integration/alert-integration/alert-sources/dotcom-monitor.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/dotcom-monitor.mdx
@@ -1,5 +1,6 @@
---
title: "Dotcom-Monitor alert integration"
+sidebarTitle: "Dotcom-Monitor"
description: "Send Dotcom-Monitor website, API and server monitoring alerts to Flashduty On-call through an HTTP Webhook and a JSON alert template. Alerts close automatically when the device recovers."
keywords: ["alert integration", "Dotcom-Monitor", "webhook", "website monitoring", "synthetic monitoring", "UserView", "WebView"]
---
@@ -9,7 +10,6 @@ Dotcom-Monitor is a cloud service for website, API and server monitoring. Its **
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Dotcom-Monitor
----
<Steps>
<Step title="Create an alert template">
@@ -76,7 +75,6 @@ Make a monitoring device fail (for example, point its target at a page that does
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from the device name (`device_name`). Both the alert and the recovery notification of Dotcom-Monitor refer to the same monitoring device, so they land on the same Flashduty alert.
@@ -87,7 +85,6 @@ Flashduty computes the Alert Key from the device name (`device_name`). Both the
Requests without `device_name` are rejected.
## Alert lifecycle
----
Flashduty handles messages by the `notification_type` field, case-insensitively:
@@ -99,12 +96,10 @@ Flashduty handles messages by the `notification_type` field, case-insensitively:
Any other value, including `TEST`, is rejected with a parameter error. Dotcom-Monitor's variables reference lists a `TEST` type but does not say whether the test send uses it, so Flashduty has no separate handling for it; verify with a real device state change. Repeated notifications received while the device stays in error merge into the same alert.
## Severity
----
Dotcom-Monitor messages carry no severity field. A device error means the monitored target is unavailable, so it is fixed at **Critical**. A recovery event keeps the severity of the original alert.
## Alert content
----
- **Title**: the device name
- **Description**: error type, error code, error reason and the failing target URL
@@ -113,7 +108,6 @@ Dotcom-Monitor messages carry no severity field. A device error means the monito
Dotcom-Monitor HTML-encodes the text it substitutes into the template; Flashduty decodes it before use.
## Troubleshooting
----
- **A test notification returns a parameter error**: a request whose `notification_type` is `TEST` is not accepted and creates no alert. This does not mean the setup is wrong; verify with a real device state change
- **Request rejected with a missing `device_name` or an unsupported `notification_type`**: check that the field names in the alert template match the template above and that Data Type is Raw JSON
diff --git a/en/on-call/integration/alert-integration/alert-sources/duplicati.mdx b/en/on-call/integration/alert-integration/alert-sources/duplicati.mdx
index 6d3b0846..88530f2f 100644
--- a/en/on-call/integration/alert-integration/alert-sources/duplicati.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/duplicati.mdx
@@ -1,5 +1,6 @@
---
title: "Duplicati alert integration"
+sidebarTitle: "Duplicati"
description: "Send Duplicati backup failures, warnings, and recoveries to Flashduty On-call through its HTTP JSON notification."
keywords: ["alert integration", "Duplicati", "backup", "webhook", "send-http-json-urls"]
---
@@ -9,7 +10,6 @@ After every backup run, Duplicati can send a JSON report to a URL you choose. Se
<div className="hide">
## In Flashduty On-call
----
You can get the integration Push URL in either of the following two ways.
@@ -30,7 +30,6 @@ You can get the integration Push URL in either of the following two ways.
</div>
## Configure Duplicati
----
The `--send-http-json-urls` option is available in Duplicati 2.0.9.106 and later. This integration was verified with 2.4.0.0.
@@ -66,7 +65,6 @@ Duplicati has no "send test notification" button, so verification needs real bac
</Steps>
## Alert Key
----
Flashduty builds the Alert Key from `Extra.machine-id` and `Extra.backup-id` in the Duplicati report. The Duplicati documentation defines `%machine-id%` as the unique random identifier assigned to the machine and `%backup-id%` as the identifier assigned to the backup. We verified on a real Duplicati 2.4.0.0 that both fields stay the same when one backup job fails and then succeeds.
@@ -78,7 +76,6 @@ Flashduty builds the Alert Key from `Extra.machine-id` and `Extra.backup-id` in
If you delete a job and create it again, it gets a new `backup-id`; close any open alert of the old job manually.
## Status and severity
----
| Duplicati `Data.ParsedResult` | Flashduty status or severity |
| :--- | :--- |
@@ -90,7 +87,6 @@ If you delete a job and create it again, it gets a new `backup-id`; close any op
An empty or any other value, including `Unknown`, is rejected. Duplicati only sends a report when a backup runs: if a job is disabled or stops running, its open alert does not recover and must be closed manually.
## Troubleshooting
----
- **Flashduty receives no events**: confirm the option is `send-http-json-urls` and the Push URL is complete with `integration_key`
- **Flashduty returns a parameter error**: confirm you did not use `--send-http-url` or the form format; the report must be JSON and contain `Extra.backup-id`
diff --git a/en/on-call/integration/alert-integration/alert-sources/dynatrace.mdx b/en/on-call/integration/alert-integration/alert-sources/dynatrace.mdx
index 10a12b8f..7b7ef8b3 100644
--- a/en/on-call/integration/alert-integration/alert-sources/dynatrace.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/dynatrace.mdx
@@ -1,5 +1,6 @@
---
title: "Dynatrace Alert Events"
+sidebarTitle: "Dynatrace"
description: "Sync Dynatrace alert events to Flashduty via webhook to achieve automated alert noise reduction."
---
@@ -8,89 +9,87 @@ Sync Dynatrace alert events to Flashduty via webhook to achieve automated alert
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Select **Dynatrace** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Dynatrace** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Dynatrace
----
<div class="md-block">
-## I. Dynatrace Alert Push Configuration
1. Log in to your Dynatrace console
2. Select `Apps` in the left navigation bar and find `Settings` in the `Manage` area
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-1.png" />
3. Find `Integration` and select `Problem notifications`
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-2.png" />
4. Click `Add notification`
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-3.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-3.png" />
5. Under `Notification type`, select `Custom Integration`
6. Fill in `Display name` with `Flashduty`
7. In `Webhook URL`, enter the integration push URL (generated after saving the integration name on the current page)
8. Keep `Call webhook if problem is closed` enabled
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-4.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-4.png" />
9. Under `Custom payload`, enter the following content:
-```
-{
- "State":"{State}",
- "PID":"{PID}",
- "ProblemTitle":"{ProblemTitle}",
- "ProblemImpact":"{ProblemImpact}",
- "ProblemDetails":"{ProblemDetailsText}",
- "ProblemURL":"{ProblemURL}",
- "ProblemSeverity":"{ProblemSeverity}",
- "ImpactedEntityNames":"{ImpactedEntityNames}",
- "Tags":"{Tags}"
-}
-```
-
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-5.png" />
+ ```
+ {
+ "State":"{State}",
+ "PID":"{PID}",
+ "ProblemTitle":"{ProblemTitle}",
+ "ProblemImpact":"{ProblemImpact}",
+ "ProblemDetails":"{ProblemDetailsText}",
+ "ProblemURL":"{ProblemURL}",
+ "ProblemSeverity":"{ProblemSeverity}",
+ "ImpactedEntityNames":"{ImpactedEntityNames}",
+ "Tags":"{Tags}"
+ }
+ ```
+
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-5.png" />
10. Click `Save changes` to complete the setup
-## II. Status Mapping
-
+## Status Mapping
|Dynatrace|Flashduty|Status|
|---|---|---|
diff --git a/en/on-call/integration/alert-integration/alert-sources/ecloud-cm.mdx b/en/on-call/integration/alert-integration/alert-sources/ecloud-cm.mdx
index cd685fda..115c7cd6 100644
--- a/en/on-call/integration/alert-integration/alert-sources/ecloud-cm.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/ecloud-cm.mdx
@@ -1,5 +1,6 @@
---
title: "China Mobile Cloud (ecloud) Cloud Monitor integration"
+sidebarTitle: "China Mobile Cloud (ecloud) Cloud Monitor"
description: "Sync China Mobile Cloud Cloud Monitor alerts to Flashduty On-call through the custom webhook of an alarm contact. Alerts close automatically when they recover."
keywords: ["alert integration", "China Mobile Cloud", "ecloud", "Cloud Monitor", "移动云", "Webhook"]
---
@@ -9,7 +10,6 @@ Push China Mobile Cloud (ecloud) Cloud Monitor alerts to Flashduty On-call throu
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## In China Mobile Cloud
----
<Steps>
<Step title="Create an alarm contact with a webhook address">
@@ -62,7 +61,6 @@ When an alarm rule in the policy triggers or recovers, China Mobile Cloud pushes
</Steps>
## Alert Key
----
Every push from China Mobile Cloud carries an alarm ID (`alarmId`). According to China Mobile Cloud, `alarmId` stays the same for alarms that the same rule keeps raising on the same resource. Flashduty computes the Alert Key from `alarmId`, so:
@@ -73,7 +71,6 @@ Every push from China Mobile Cloud carries an alarm ID (`alarmId`). According to
Requests without `alarmId` are rejected.
## Status and severity
----
The alert recovers when `recover` is `true`. Any other value is treated as a trigger. The severity comes from the alarm level (`alarmLevel`):
@@ -88,7 +85,6 @@ The alert recovers when `recover` is `true`. Any other value is treated as a tri
A recovered alert keeps the severity it had before recovery.
## Alert content and labels
----
The alert title combines the resource name (`resourceName`) and the metric name (`metricName`), for example `ECS-45273803 CPU利用率`. The alert description is the alarm content (`content`) pushed by China Mobile Cloud, which includes the trigger value and trigger time.
@@ -111,7 +107,6 @@ The alert title combines the resource name (`resourceName`) and the metric name
| `notify_time` | Time of this alarm notification (`notifyTime`) |
## Troubleshooting
----
- **Flashduty receives no alerts**: Confirm that the alarm policy notifies the alarm contact that has the webhook address, and that the address is complete and includes `integration_key`
- **Flashduty returns a parameter error**: Confirm that the pushed content includes `alarmId`
diff --git a/en/on-call/integration/alert-integration/alert-sources/edge-delta.mdx b/en/on-call/integration/alert-integration/alert-sources/edge-delta.mdx
index 19eecd38..22fdbb52 100644
--- a/en/on-call/integration/alert-integration/alert-sources/edge-delta.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/edge-delta.mdx
@@ -1,5 +1,6 @@
---
title: "Edge Delta alert integration"
+sidebarTitle: "Edge Delta"
description: "Send Edge Delta monitor alert, warning and recovery notifications to Flashduty On-call through an Edge Delta webhook integration."
keywords: ["alert integration", "Edge Delta", "observability", "webhook", "monitor"]
---
@@ -9,7 +10,6 @@ An Edge Delta webhook integration has no fixed request body: you write the paylo
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Edge Delta
----
<Steps>
<Step title="Create one webhook integration per state">
@@ -90,7 +89,6 @@ Click **Test Notifications** in the monitor's notification section to send a tes
</Steps>
## Payload
----
| Field | Meaning | In Flashduty |
| :--- | :--- | :--- |
@@ -104,7 +102,6 @@ Click **Test Notifications** in the monitor's notification section to send a tes
| `time` | `$EVENT_DATE`, the event time | Added to the description |
## Alert Key
----
Flashduty builds the Alert Key from `monitor` and `group`. The alert, warning and recovery requests of one monitor (and one group) carry the same `monitor` and `group`, so they land on the same alert; different groups stay separate. A monitor without group by sends `*` as `group`, so the whole monitor maps to one alert; a monitor with group by sends `<tag>:<value>` (for example `ed.tag:docker-logs`). `value`, `metric` and the time are not part of the Alert Key.
@@ -113,7 +110,6 @@ The Edge Delta documentation does not provide a stable ID for monitor events, so
</Note>
## Status and severity
----
| `status` | Flashduty status or severity |
| :--- | :--- |
@@ -124,7 +120,6 @@ The Edge Delta documentation does not provide a stable ID for monitor events, so
If `monitor` or `status` is missing, or `status` is not one of the values above, Flashduty returns a parameter error.
## FAQ
----
<AccordionGroup>
<Accordion title="Why must monitor be typed instead of using a variable?">
@@ -141,7 +136,6 @@ If the monitor has a renotification period, Edge Delta sends the alert request a
</AccordionGroup>
## Troubleshooting
----
- **The monitor shows `Receiver webhook-flashduty-warning does not exist`**: every `@webhook-...` handle in the notification must match an existing integration; create it or remove its block
- **Edge Delta does not push**: confirm the monitor's Notifications reference `@webhook-<integration name>` inside the matching `{{#is_alert}}` or similar block
diff --git a/en/on-call/integration/alert-integration/alert-sources/elastalert2.mdx b/en/on-call/integration/alert-integration/alert-sources/elastalert2.mdx
index f6022bbf..da9a4d42 100644
--- a/en/on-call/integration/alert-integration/alert-sources/elastalert2.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/elastalert2.mdx
@@ -1,5 +1,6 @@
---
title: "ElastAlert2 Alert Integration Guide"
+sidebarTitle: "ElastAlert2"
description: "Push alert events to Flashduty through ElastAlert2's Provider to achieve automated alert noise reduction."
---
@@ -8,43 +9,43 @@ Push ElastAlert2 alerts to Flashduty via webhook, to achieve automatic alert noi
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Dedicated Integration
Choose this method when you don't need to route alert events to different channels. It's simpler and recommended.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **ElastAlert 2** integration and click **Save** to generate a card
4. Click the generated card to view the **Integration Key**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **ElastAlert 2** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **Integration Key** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In ElastAlert 2
----
### Configure ElastAlert 2 Alerts
Follow the [ElastAlert Flashduty](https://elastalert2.readthedocs.io/en/latest/alerts.html#flashduty) push configuration document
diff --git a/en/on-call/integration/alert-integration/alert-sources/elastic.mdx b/en/on-call/integration/alert-integration/alert-sources/elastic.mdx
index e3ab785b..00065002 100644
--- a/en/on-call/integration/alert-integration/alert-sources/elastic.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/elastic.mdx
@@ -1,5 +1,6 @@
---
title: "Elastic alert integration"
+sidebarTitle: "Elastic"
description: "Send Elastic (Kibana Alerting) rule alerts and recoveries to Flashduty On-call through the Kibana Webhook connector."
keywords: ["alert integration", "Elastic", "Kibana", "Kibana Alerting", "webhook", "Elastic Observability", "Elastic Security"]
---
@@ -11,7 +12,6 @@ This integration works with Elastic Cloud, Elastic Cloud Serverless, and self-ma
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -20,7 +20,7 @@ You can obtain an integration push URL in either of the following ways.
Choose this method when you do not need to route alerts to different channels.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View dedicated integration setup steps">
1. In the Flashduty console, select **Channel** and open a channel
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**
@@ -35,7 +35,7 @@ Choose this method when you do not need to route alerts to different channels.
Choose this method when you need to route alerts to different channels based on the payload.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View shared integration setup steps">
1. In the Flashduty console, select **Integration Center → Alert Events**
2. Select **Elastic** and enter an integration name
@@ -48,14 +48,12 @@ Choose this method when you need to route alerts to different channels based on
</div>
## Prerequisites
----
- **Subscription**: the Kibana Webhook and PagerDuty connectors require an Elastic Gold subscription or higher (Basic does not include them); a 30-day trial license also works. See [Elastic subscriptions](https://www.elastic.co/subscriptions).
- **Network**: Kibana must be able to reach the Flashduty push URL. If your self-managed Kibana sets [`xpack.actions.allowedHosts`](https://www.elastic.co/docs/reference/kibana/configuration-reference/alerting-settings#action-settings) in `kibana.yml`, add the push URL's host name (for example `api.flashcat.cloud`) to that list, otherwise the connector refuses to send.
- **Permissions**: you need Kibana privileges to create connectors and edit rules. See [Alerting security](https://www.elastic.co/docs/explore-analyze/alerting/alerts/alerting-setup#alerting-security).
## In Kibana
----
<Steps>
<Step title="Create a Webhook connector">
@@ -99,7 +97,6 @@ Let the rule actually match its condition and confirm that Flashduty receives an
</Steps>
## Action template
----
Paste the following JSON into the **Body** of every action:
@@ -147,7 +144,6 @@ To turn fields from the rule context into Flashduty labels (for routing or noise
Custom and built-in labels together are limited to 50. Keys may contain only letters, digits, and underscores and must not start with a digit. A built-in label overrides a custom label with the same key.
## Alert Key
----
Flashduty builds the Alert Key from `rule_id` and `alert_id`.
@@ -160,7 +156,6 @@ Flashduty builds the Alert Key from `rule_id` and `alert_id`.
Changes to the rule name, tags, severity, description, or action group do not change the Alert Key. For example, when a Metric threshold rule's group moves from `Warning` to `Alert`, both notifications carry the same Alert Key.
## Status and severity
----
| Condition | Flashduty status or severity |
| :--- | :--- |
@@ -175,7 +170,6 @@ Changes to the rule name, tags, severity, description, or action group do not ch
Security detection rules do not send Recovered notifications. Each detection alert becomes a separate Flashduty alert that you close manually or through auto-close in Flashduty.
## Use the PagerDuty connector (optional)
----
If your rules already use the Kibana PagerDuty connector, you can point it at the Flashduty [PagerDuty Compatible integration](/en/on-call/integration/alert-integration/alert-sources/pagerduty) without rewriting the actions. Alerts sent this way arrive through Flashduty's PagerDuty Compatible integration, not the Elastic integration on this page.
@@ -185,7 +179,6 @@ If your rules already use the Kibana PagerDuty connector, you can point it at th
4. Keep the **DedupKey** that Kibana pre-fills, `{{rule.id}}:{{alert.id}}`, on both actions and do not clear it, so the resolve event closes the matching alert. With an empty DedupKey on the Trigger action, Kibana sends no `dedup_key`, Flashduty generates a random Alert Key for each trigger, and the resolve event cannot close it
## Troubleshooting
----
- **Kibana reports `target url "..." is not added to the Kibana config xpack.actions.allowedHosts`**: add the Flashduty push URL's host name to `xpack.actions.allowedHosts`
- **Flashduty returns an error starting with `alert_id is required`**: the action's **Action frequency** is Summary of alerts; change it to For each alert
diff --git a/en/on-call/integration/alert-integration/alert-sources/email.mdx b/en/on-call/integration/alert-integration/alert-sources/email.mdx
index d43d7090..0d6038c5 100644
--- a/en/on-call/integration/alert-integration/alert-sources/email.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/email.mdx
@@ -1,5 +1,6 @@
---
title: "Email Integration"
+sidebarTitle: "Email"
description: "Generate a unique email address in Flashduty to synchronize alert triggers and recoveries through email"
---
@@ -8,7 +9,6 @@ Generate a unique email address in Flashduty to synchronize alert triggers and r
<div class="hide">
## Steps
----
### Create Email Integration
@@ -18,24 +18,25 @@ You can obtain an email address through either of these two methods:
Choose this simpler option when you don't need to route alerts to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**, and enter the integration page
3. Choose **Email** integration, click **Save** to generate a card
4. Click the generated card to view the **Email Address**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
#### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alerts**, and enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alerts**, and enter the integration selection page
2. Select **Email** integration:
- **Integration Name**: Define a name for the current integration
- **Email Address**: Set an easy-to-remember prefix for the email, which must be unique within your account
@@ -44,7 +45,8 @@ Choose this option when you need to route alerts to different channels based on
4. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
### Customize Email Integration
@@ -87,15 +89,15 @@ In the integration card (edit and preview), the **Silence Detection** (Heartbeat
1. The system will reject emails larger than 5MB
2. If the email text content exceeds 128KB, the system will truncate it and add a label in the incident details:
-```
-body_cut = true
-```
+ ```
+ body_cut = true
+ ```
3. If the email contains attachments, the system will discard them and add a label in the incident details:
-```
-attachment_stripped = true
-```
+ ```
+ attachment_stripped = true
+ ```
4. For new alerts triggered by email, **the title is the email subject, and the description is the email content**
@@ -104,6 +106,5 @@ attachment_stripped = true
## Severity Mapping
----
Currently, all alerts pushed to Flashduty through the email integration are set to Warning severity. However, you can customize the severity using the [alert pipeline](/en/on-call/integration/alert-integration/alert-pipelines).
diff --git a/en/on-call/integration/alert-integration/alert-sources/emqx.mdx b/en/on-call/integration/alert-integration/alert-sources/emqx.mdx
index da7c71ee..c7bfa8aa 100644
--- a/en/on-call/integration/alert-integration/alert-sources/emqx.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/emqx.mdx
@@ -1,5 +1,6 @@
---
title: "EMQX Alert Integration"
+sidebarTitle: "EMQX"
description: "Push EMQX alert events to Flashduty via Webhook for automated alert noise reduction"
keywords: ["alert integration", "EMQX", "MQTT", "monitoring alert", "data ingestion"]
---
@@ -7,7 +8,6 @@ keywords: ["alert integration", "EMQX", "MQTT", "monitoring alert", "data ingest
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
@@ -15,35 +15,36 @@ You can obtain an integration push URL through either of these two methods:
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Select **EMQX** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **EMQX** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In EMQX
----
EMQX Cloud (hosted service) and self-hosted EMQX are integrated differently. Choose the steps that match your deployment.
@@ -130,7 +131,6 @@ Use the same request body template as Step 1, but set `event_status` to `Ok`, so
</div>
## Severity Mapping
----
<div class="md-block">
@@ -147,7 +147,6 @@ Use the same request body template as Step 1, but set `event_status` to `Ok`, so
</div>
## FAQ
----
<details>
<summary>Why am I not receiving alerts in Flashduty?</summary>
diff --git a/en/on-call/integration/alert-integration/alert-sources/extrahop.mdx b/en/on-call/integration/alert-integration/alert-sources/extrahop.mdx
index 7f5ae28f..790b4f2d 100644
--- a/en/on-call/integration/alert-integration/alert-sources/extrahop.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/extrahop.mdx
@@ -1,5 +1,6 @@
---
title: "ExtraHop alert integration"
+sidebarTitle: "ExtraHop"
description: "Send ExtraHop Reveal(x) security and performance detections to Flashduty On-call through a detection notification rule's Custom Webhook."
keywords: ["alert integration", "ExtraHop", "Reveal(x)", "RevealX", "NDR", "NPM", "network detection", "webhook"]
---
@@ -11,7 +12,6 @@ ExtraHop's documentation does not describe a notification when a detection is cl
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure ExtraHop
----
You need NDR or NPM module access with full write privileges or higher. Webhooks are sent over TCP 443 (HTTPS), so ExtraHop must be able to reach the Flashduty push URL.
@@ -80,19 +79,16 @@ If you select **Send once per detection**, ExtraHop requires a custom payload. A
</Steps>
## Alert Key
----
Flashduty uses `id` (ExtraHop defines it as "The unique identifier for the detection") as the Alert Key. Every update of one detection carries the same `id` and merges into one alert. Changes to the title, description, risk score, and time do not change the Alert Key. Requests without `id` are rejected.
## Detections and recovery
----
ExtraHop detection notifications cover creation and updates only. The documentation does not describe a notification when a detection is closed or resolved. Every notification Flashduty receives is a trigger, and none recovers an alert automatically.
Turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit), 24 hours recommended, or close the alert by hand once the detection is handled.
## Severity
----
Severity comes from `risk_score`, using the same bands as the ExtraHop console colors:
@@ -104,7 +100,6 @@ Severity comes from `risk_score`, using the same bands as the ExtraHop console c
| Missing, 0, or non-numeric (performance detections have no risk score) | Warning |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -122,7 +117,6 @@ Severity comes from `risk_score`, using the same bands as the ExtraHop console c
The alert title is `title`, falling back to `type` and then `ExtraHop detection <id>`. The description is the detection description followed by the link to the detection.
## Troubleshooting
----
- **Flashduty returns a parameter error**: check that the URL is complete and includes `integration_key`, and that the payload contains `id`
- **Alerts never close**: ExtraHop sends no recovery notification. Turn on the channel's auto-resolve timeout or close alerts by hand
diff --git a/en/on-call/integration/alert-integration/alert-sources/fail2ban.mdx b/en/on-call/integration/alert-integration/alert-sources/fail2ban.mdx
index f5509fe9..5e311ce2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/fail2ban.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/fail2ban.mdx
@@ -1,5 +1,6 @@
---
title: "Fail2ban alert integration"
+sidebarTitle: "Fail2ban"
description: "Add a custom Fail2ban action that uses curl to push ban and unban events to Flashduty's standard alert event integration; unbanning closes the alert automatically."
keywords: ["alert integration", "Fail2ban", "intrusion prevention", "IP ban", "curl", "standard alert event"]
---
@@ -9,7 +10,6 @@ Fail2ban has no built-in webhook notification, but an action is just a shell com
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of the two ways below. **In both cases choose Standard Alert Event as the integration type**, not Fail2ban.
@@ -30,7 +30,6 @@ You can get the push URL in either of the two ways below. **In both cases choose
</div>
## Configure in Fail2ban
----
Run these steps on the host where Fail2ban runs, as root.
@@ -91,7 +90,6 @@ fail2ban-client set sshd unbanip 192.0.2.10
</Steps>
## Field mapping
----
| Fail2ban | Flashduty |
| :--- | :--- |
@@ -103,7 +101,6 @@ fail2ban-client set sshd unbanip 192.0.2.10
| `labels` | Labels `jail`, `ip`, `failures`, `bantime` |
## Recovery and deduplication
----
- Fail2ban runs `actionunban` when the ban time expires, and Flashduty closes the alert with the same `alert_key`.
- With a permanent ban (`bantime = -1`) the IP is never unbanned, so the alert does not close by itself. Enable [auto-resolve timeout](/en/on-call/channel/create-edit) on the channel that receives this integration, or close the alert manually once handled.
@@ -111,7 +108,6 @@ fail2ban-client set sshd unbanip 192.0.2.10
- `norestored = 1` stops Fail2ban from notifying for bans restored from its database after a restart, which would otherwise produce a burst of duplicate alerts.
## Troubleshooting
----
- **Flashduty receives nothing**: confirm `fail2ban-client reload` was run; call the push URL with `curl` from the same host to check the response and that api.flashcat.cloud is reachable
- **`InvalidParameter` is returned**: the push URL is missing `integration_key`, or the JSON was broken by quoting; make sure there are no stray line breaks in `[Definition]`
diff --git a/en/on-call/integration/alert-integration/alert-sources/falco.mdx b/en/on-call/integration/alert-integration/alert-sources/falco.mdx
index 4f5fc676..0feae027 100644
--- a/en/on-call/integration/alert-integration/alert-sources/falco.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/falco.mdx
@@ -1,5 +1,6 @@
---
title: "Falco alert integration"
+sidebarTitle: "Falco"
description: "Send Falco runtime security detections to Flashduty On-call through the Falcosidekick webhook output or Falco's built-in http_output."
keywords: ["alert integration", "Falco", "Falcosidekick", "webhook", "runtime security"]
---
@@ -9,7 +10,6 @@ Use the Falcosidekick webhook output (or Falco's built-in `http_output`) to send
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Falco
----
Pushing through Falcosidekick is recommended because `minimumpriority` filters low-priority events at the source. Without Falcosidekick, Falco can push directly.
@@ -78,7 +77,6 @@ The push URL contains `integration_key`. Paste it in full, including the paramet
</Warning>
## Verify
----
Send a request to the Falcosidekick `/test` endpoint (it listens on port 2801 by default):
@@ -91,7 +89,6 @@ Flashduty opens a new alert titled `Test rule` with Info severity. The test aler
Then trigger a real rule on a monitored host or container (for example, open an interactive shell in a container to fire `Terminal shell in container`) and confirm the alert appears in Flashduty.
## Alert Key
----
Each Falco event is an independent detection with no lifecycle, so each event becomes its own alert:
@@ -101,7 +98,6 @@ Each Falco event is an independent detection with no lifecycle, so each event be
A request without `rule` is rejected, because Flashduty cannot tell which rule fired.
## Severity
----
| Falco `priority` | Flashduty severity |
| :--- | :--- |
@@ -111,17 +107,14 @@ A request without `rule` is rejected, because Flashduty cannot tell which rule f
| Empty or unknown | Warning |
## Labels
----
The title is the rule name (`rule`) and the description is `output`. These fields become labels: `rule`, `priority`, `hostname` (also used as `resource`), `falco_source`, `falco_uuid`, and `tags` (comma-separated). Every field in `output_fields` also becomes a label, with `.` in the key replaced by `_`, for example `container.id` becomes `container_id` and `k8s.pod.name` becomes `k8s_pod_name`. At most 50 labels are kept.
## Recovery
----
Falco sends no recovery event, so alerts do not resolve on their own. Turn on the [auto-resolve timeout](/en/on-call/channel/create-edit) for the channel that receives Falco alerts (24 hours suggested; adjust it to how quickly you need to respond), or close alerts by hand after handling them.
## Troubleshooting
----
- **Falcosidekick logs a webhook error**: check that the address is complete, includes `integration_key`, and that `api.flashcat.cloud` is reachable from where Falcosidekick runs
- **Flashduty returns a parameter error**: make sure Falco has `json_output: true` and the body is valid JSON containing `rule`
diff --git a/en/on-call/integration/alert-integration/alert-sources/fastnetmon.mdx b/en/on-call/integration/alert-integration/alert-sources/fastnetmon.mdx
index d15df6d7..acef0019 100644
--- a/en/on-call/integration/alert-integration/alert-sources/fastnetmon.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/fastnetmon.mdx
@@ -1,5 +1,6 @@
---
title: "FastNetMon alert integration"
+sidebarTitle: "FastNetMon"
description: "Send FastNetMon Advanced DDoS ban and unban notifications to Flashduty On-call through a web callback."
keywords: ["alert integration", "FastNetMon", "DDoS", "web callback", "ban", "unban", "BGP blackhole", "Flow Spec"]
---
@@ -9,7 +10,6 @@ Use the FastNetMon Advanced web callback to send DDoS ban (`ban`, `partial_block
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of two ways.
@@ -30,7 +30,6 @@ You can get the push URL in either of two ways.
</div>
## In FastNetMon
----
<Steps>
<Step title="Enable the web callback">
@@ -69,7 +68,6 @@ Trigger an attack detection (for example, send test traffic above the ban thresh
</Steps>
## Payload
----
| Field | Meaning | In Flashduty |
| :--- | :--- | :--- |
@@ -85,7 +83,6 @@ Trigger an attack detection (for example, send test traffic above the ban thresh
Packet samples (`packet_dump`) and Flow Spec rules in ban notifications are not stored on the alert.
## Alert Key
----
The Alert Key identifies the attacked object: `ip` for host scope, `hostgroup_name` for host group scope. The ban, status updates and unban for one IP land on the same alert; different IPs or host groups are different alerts. Changes to severity, traffic data or `attack_uuid` do not change the Alert Key.
@@ -96,7 +93,6 @@ If a blackhole ban and a Flow Spec partial block are active on the same IP, they
A request without `ip` (or without `hostgroup_name` in host group scope) is rejected with a parameter error, because the unban could not be matched to its alert reliably. A request with any other `action` or `alert_scope` is rejected too.
## Status and severity
----
| FastNetMon `attack_severity` | Flashduty severity |
| :--- | :--- |
@@ -108,7 +104,6 @@ A request without `ip` (or without `hostgroup_name` in host group scope) is reje
The official samples only show `middle`; the other values follow common naming. On unban the alert recovers and keeps the severity of the last attack notification.
## FAQ
----
<AccordionGroup>
<Accordion title="Does FastNetMon have a test button?">
@@ -131,7 +126,6 @@ This integration targets the JSON format that FastNetMon Advanced uses for web c
</AccordionGroup>
## Troubleshooting
----
- **No alerts arrive**: on the FastNetMon server, confirm `web_callback_enabled` is on, `fcli commit` was run, and the server can reach the Flashduty push URL
- **Flashduty returns a parameter error**: confirm the request is a FastNetMon JSON notification and that `ip` (host scope) or `hostgroup_name` (host group scope) is not empty
diff --git a/en/on-call/integration/alert-integration/alert-sources/firebase-crashlytics.mdx b/en/on-call/integration/alert-integration/alert-sources/firebase-crashlytics.mdx
index c8bd1b36..3d3e6ab6 100644
--- a/en/on-call/integration/alert-integration/alert-sources/firebase-crashlytics.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/firebase-crashlytics.mdx
@@ -1,5 +1,6 @@
---
title: "Firebase Crashlytics alert integration"
+sidebarTitle: "Firebase Crashlytics"
description: "Send new fatal, regression, and velocity alerts from Firebase Crashlytics to Flashduty On-call through a small Cloud Function."
keywords: ["alert integration", "Firebase", "Crashlytics", "Cloud Functions", "Eventarc", "crash", "mobile app"]
---
@@ -19,7 +20,6 @@ Firebase also sends a **stability digest** (`onStabilityDigestPublished`), a dai
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -40,7 +40,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Firebase
----
Crashlytics alert functions run on Cloud Functions (2nd gen). The Firebase project must be on the **Blaze (pay as you go)** plan to deploy them, even if actual usage stays inside the free tier — a billing account still has to be attached.
@@ -155,7 +154,6 @@ Crashlytics sends no "resolved" notification for any of these events, so alerts
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from the event type `alert_type`, the app ID `app_id`, and Crashlytics' issue ID `issue_id` (the official `Issue.id`). One Cloud Function deployment (one push URL) can forward events for every app in the project (see "Scope to one app" above), and Firebase does not document `issue_id` as unique across apps, so `app_id` is folded in too — this keeps two apps from merging into one alert if they happen to get the same issue ID. As a result:
@@ -167,7 +165,6 @@ Flashduty computes the Alert Key from the event type `alert_type`, the app ID `a
If a request is missing `issue_id`, Flashduty rejects it.
## Severity
----
Crashlytics alert events carry no severity. Flashduty sets it by event type:
@@ -182,7 +179,6 @@ Crashlytics alert events carry no severity. Flashduty sets it by event type:
To override this with a fixed severity, append `&severity=Critical` (or `Warning`, `Info`) to the push URL.
## Alert content
----
The alert title is `Firebase Crashlytics <event type>: <issue_title>`, for example `Firebase Crashlytics new fatal issue: java.lang.NullPointerException`. The description includes the issue subtitle (the class and method where the crash happened) and the app version; a regression alert also includes the time the issue was previously marked resolved, and a velocity alert also includes the crash session count, crash percentage, and the version where the issue first appeared.
@@ -198,7 +194,6 @@ The alert title is `Firebase Crashlytics <event type>: <issue_title>`, for examp
| `crash_count` / `crash_percentage` / `first_version` | Velocity alerts only: crash session count, crash percentage, and the version where the issue first appeared |
## Troubleshooting
----
- **Function deployment fails or reports a permission error**: Make sure the Firebase project is on the Blaze plan and the account deploying it has permission to deploy Cloud Functions on that project
- **A crash happened but no alert arrives**: Crashlytics can take a few minutes to process a crash log and trigger the alert function; check `firebase functions:log` to see whether the function ran and whether `fetch` threw an error
diff --git a/en/on-call/integration/alert-integration/alert-sources/firefly.mdx b/en/on-call/integration/alert-integration/alert-sources/firefly.mdx
index 612a9dab..8194230f 100644
--- a/en/on-call/integration/alert-integration/alert-sources/firefly.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/firefly.mdx
@@ -1,5 +1,6 @@
---
title: "Firefly alert integration"
+sidebarTitle: "Firefly"
description: "Send configuration drift, unmanaged resource, ghost resource, and insight events detected by Firefly to Flashduty On-call through a webhook."
keywords: ["alert integration", "Firefly", "webhook", "configuration drift", "drift", "IaC", "unmanaged resource"]
---
@@ -9,7 +10,6 @@ Use Firefly's Webhook notification integration to send the events Firefly detect
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Firefly
----
<Steps>
<Step title="Add a Webhook integration">
@@ -77,7 +76,6 @@ Firefly does not document the content of the test notification. If it carries no
</Steps>
## Alert Key
----
Each resource (one entry in `samples`) produces one alert. The Alert Key is computed from the event type `notificationType` and the resource's `FRN`; when `FRN` is empty, the resource's `ARN` is used instead. As a result:
@@ -88,7 +86,6 @@ Each resource (one entry in `samples`) produces one alert. The Alert Key is comp
If a resource has neither `FRN` nor `ARN`, Flashduty rejects the whole delivery.
## Status and severity
----
Firefly's Webhook notifications carry no severity. Flashduty sets the severity by event type, and every event is a trigger:
@@ -98,7 +95,6 @@ Firefly's Webhook notifications carry no severity. Flashduty sets the severity b
| `UnmanagedResource` | Info |
## Title, description, and labels
----
The alert title is `Firefly <event type>: <resource name> (<resource type>)`, for example `Firefly drift detected: web-1 (aws_instance)`. The description of a `Drift` alert lists each drifted attribute on its own line with its IaC value and its live cloud value.
@@ -119,7 +115,6 @@ The alert title is `Firefly <event type>: <resource name> (<resource type>)`, fo
The actor information in Firefly's delivery (`ownerData.userIdentity`) is not written to labels.
## Troubleshooting
----
- **Firefly reports an invalid webhook URL when creating the integration**: Make sure the URL is complete, includes `integration_key`, and **Add custom credentials** is unchecked
- **Flashduty returns an invalid parameter error**: Make sure the `integration_key` in the push URL belongs to a Firefly integration
diff --git a/en/on-call/integration/alert-integration/alert-sources/fivetran.mdx b/en/on-call/integration/alert-integration/alert-sources/fivetran.mdx
index 59ff56c4..62867260 100644
--- a/en/on-call/integration/alert-integration/alert-sources/fivetran.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/fivetran.mdx
@@ -1,5 +1,6 @@
---
title: "Fivetran alert integration"
+sidebarTitle: "Fivetran"
description: "Send failed syncs, failed connection tests, and their recoveries from Fivetran to Flashduty On-call through a webhook."
keywords: ["alert integration", "Fivetran", "data pipeline", "sync failure", "webhook"]
---
@@ -9,7 +10,6 @@ Use Fivetran webhooks to send sync results and connection test results of a conn
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## In Fivetran
----
Fivetran webhooks are created through the [Webhook REST API](https://fivetran.com/docs/developer-resources/webhooks), authenticated with a Fivetran API key and secret using Basic authentication. A webhook is either account-level (covers every connection in the account) or group-level (covers the connections in one group).
@@ -82,14 +81,12 @@ Fivetran's **Test a Webhook** call (`POST /v1/webhooks/{webhookId}/test` with bo
</Steps>
## Alert Key
----
Flashduty uses the connection ID (`connector_id` in the webhook) plus the event family (sync or connection test) as the Alert Key. Fivetran documents `connector_id` as "the ID of the connection for which the webhooks are sent", and every sync and connection test of one connection carries the same value. Sync and connection test use separate Alert Keys, so a successful sync does not close a connection test alert that is still unresolved.
Changes in the per-sync `sync_id`, the failure reason, or the time do not change the Alert Key. A sync or connection test event without `connector_id` is rejected.
## Status and severity
----
| Event | `data.status` | Status | Flashduty severity |
| :--- | :--- | :--- | :--- |
@@ -107,7 +104,6 @@ For an ignored delivery, Flashduty returns success without creating an alert or
Each `sync_end` is an independent delivery with no progress updates: a triggered alert stays active until the next `SUCCESSFUL` sync of the same connection. If the connection is paused or deleted, the triggered alert does not recover on its own. Close it manually in Flashduty, or configure automatic closing after a timeout for the channel.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -125,7 +121,6 @@ Each `sync_end` is an independent delivery with no progress updates: a triggered
The alert description comes from the failure reason (`data.reason`) or the connection test message (`data.message`).
## Troubleshooting
----
- **Fivetran returns 400 when creating the webhook**: make sure the URL is HTTPS and reachable by Fivetran. Fivetran sends a test request on both creation and activation, and it must return 2xx. Flashduty answers that test request with 200 and opens a separate Info alert as described above
- **An alert does not recover**: make sure the webhook subscribes to `sync_end` and `connection_successful`. An expected reschedule and `CANCELED` do not produce a recovery
diff --git a/en/on-call/integration/alert-integration/alert-sources/flashcat.mdx b/en/on-call/integration/alert-integration/alert-sources/flashcat.mdx
index 152db1b5..a494ba60 100644
--- a/en/on-call/integration/alert-integration/alert-sources/flashcat.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/flashcat.mdx
@@ -1,5 +1,6 @@
---
title: "Nightingale/Flashcat Integration"
+sidebarTitle: "Nightingale/Flashcat"
description: "Push alert events from Nightingale (n9e) or Flashcat to Flashduty via webhook. When an alert is triggered, send a trigger event to Flashduty; when an alert recovers, send a recovery event to Flashduty"
---
@@ -12,20 +13,17 @@ In the Nightingale/Flashcat v8.0.0-beta.7+ version, you can configure the collab
<div class="hide">
## Prerequisites
----
### In Nightingale
-- You must have permission to modify **System Settings=>Global Notifications** or **Alert Management=>Alert Rules**.
+- You must have permission to modify **System Settings → Global Notifications** or **Alert Management → Alert Rules**.
- Your Nightingale server must be able to access the domain api.flashcat.cloud to push alerts to the external network.
## Supported Versions
----
This guide is compatible with **Nightingale V5 and V6** versions.
## Setup Steps
----
### In Flashduty
@@ -35,8 +33,8 @@ You can obtain an integration push URL through either of these two methods:
Choose this method when you don't need to route alert events to different channels - it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Enter the Flashduty console, select **Channels**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**, and enter the add integration page
@@ -44,16 +42,17 @@ Choose this method when you don't need to route alert events to different channe
4. Click the generated card to view the **push URL**, copy it for later use
5. (Optional) Click the generated card, click the **Edit** button, select **Console URL**, enter the Nightingale console URL (domain part only), and Flashduty will generate a Nightingale details link for new alerts
-</details>
+</Accordion>
+</AccordionGroup>
#### Using Shared Integration
Choose this method when you need to route alert events to different channels based on the alert Payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Enter the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Enter the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Nightingale/Flashcat** integration:
- **Integration Name**: Define a name for the current integration
- **Console URL**: (Optional) Enter the Nightingale console URL (domain part only), and Flashduty will generate a Nightingale details link for new alerts
@@ -61,7 +60,8 @@ Choose this method when you need to route alert events to different channels bas
4. Click **Save** and copy the newly generated **push URL** for later use
5. Complete
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Nightingale/Flashcat
@@ -72,7 +72,7 @@ In the new version, although you can configure the collaboration space directly
#### Step 1: Add Notification Media
-1. Log in to your n9e console, select Alerting > Media types and click **Add**
+1. Log in to your n9e console, select Alerting → Media types and click **Add**
2. Fill in the media name and identifier, select **Flashduty** type, and enter the integration push URL in the `URL` section
3. Click **Save** and complete
@@ -80,7 +80,7 @@ In the new version, although you can configure the collaboration space directly
#### Step 2: Configure Notification Rules
-1. Log in to your n9e console, select Alerting > Rules and click **Add** or edit the existing alert rules
+1. Log in to your n9e console, select Alerting → Rules and click **Add** or edit the existing alert rules
2. Configure the basic information as needed
3. Select the `Flashduty` notification media added in the previous step
4. Select the collaboration space (the collaboration space must be created in [Flashduty](https://console.flashcat.cloud/channel) in advance), and select other options as needed
@@ -90,7 +90,7 @@ In the new version, although you can configure the collaboration space directly
#### Step 3: Select Notification Rules in Alert Rules
-1. Log in to your n9e console, select Alerting > Alert Rules and click **Add** or edit the existing alert rules
+1. Log in to your n9e console, select Alerting → Alert Rules and click **Add** or edit the existing alert rules
2. Select the `Flashduty` notification rule added in the previous step, and select other options as needed
3. Click **Save** and complete
@@ -108,11 +108,11 @@ Choose one of the following two methods:
Select multiple alert rules and configure webhook in batch.
-1. Log in to your n9e console, select Alert Management > Alert Rules to enter the alert rules list page
+1. Log in to your n9e console, select Alert Management → Alert Rules to enter the alert rules list page
2. Select the alert rules you want to import in batch, choose batch update alert rules in the upper right corner
3. In the popup, select the "Callback URL" field and enter the integration push URL in the new input box, as shown below:
-<img src="https://download.flashcat.cloud/flashduty/doc/en/fc/fc-1.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/fc/fc-1.png" alt="drawing" width="500"/>
4. Return to the integration list, if the latest event time is displayed, the configuration is successful and events are being received
5. Complete
@@ -130,7 +130,7 @@ Nightingale supports configuring global webhook URLs in both the interface and c
2. Go to `System Settings-Notification Settings-Callback URL` page
3. As shown below, enable a new webhook, fill in the integration push URL in the `URL` section
-<img src="https://download.flashcat.cloud/flashduty/doc/en/fc/fc-2.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/fc/fc-2.png" alt="drawing" width="500"/>
4. Complete
@@ -161,8 +161,6 @@ Nightingale supports configuring global webhook URLs in both the interface and c
## Silence Detection
----
-
In the integration card (edit and preview), the **Silence Detection** (Heartbeat) setting is available below the alert push settings: if no valid event arrives within the configured interval, the system generates a Warning alert.
| Setting | Description |
@@ -172,7 +170,6 @@ In the integration card (edit and preview), the **Silence Detection** (Heartbeat
| **Auto-recover on new event** | Switch, on by default. When the next valid event arrives, the alert raised by silence detection is recovered automatically |
## Severity Mapping
----
Nightingale/Flashcat to Flashduty alert severity mapping:
@@ -183,7 +180,6 @@ Nightingale/Flashcat to Flashduty alert severity mapping:
| 3 | Info | Info |
## FAQ
----
<details>
<summary>Why am I not receiving alerts in Flashduty?</summary>
@@ -195,7 +191,7 @@ Nightingale/Flashcat to Flashduty alert severity mapping:
#### In Nightingale/Flashcat
- 1. First confirm if Nightingale has generated new alerts: Go to **Alert Management=>Alert History**, check if new alerts were generated after configuring the webhook, note that new alerts must be in **Triggered** status. If no new alerts were generated, please wait for new alerts to trigger and verify again.
+ 1. First confirm if Nightingale has generated new alerts: Go to **Alert Management → Alert History**, check if new alerts were generated after configuring the webhook, note that new alerts must be in **Triggered** status. If no new alerts were generated, please wait for new alerts to trigger and verify again.
2. After finding the alert, go to alert details and check the **Callback URL** section. Verify if the actual callback URL exactly matches the integration push URL. If they don't match, modify the **Alert Rules** and verify again.
3. If they match, you need to log into the Nightingale server and confirm it can access the external domain api.flashcat.cloud. If not, you first need to enable external network access for the server, or specifically enable access for Flashduty's domain.
4. If the network is fine, you need to continue investigating the server and look for related error logs.
diff --git a/en/on-call/integration/alert-integration/alert-sources/fleet.mdx b/en/on-call/integration/alert-integration/alert-sources/fleet.mdx
index 0f060161..14d45f7b 100644
--- a/en/on-call/integration/alert-integration/alert-sources/fleet.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/fleet.mdx
@@ -1,5 +1,6 @@
---
title: "Fleet alert integration"
+sidebarTitle: "Fleet"
description: "Send failing policy checks and newly detected vulnerabilities (CVEs) from Fleet automation webhooks to Flashduty On-call."
keywords: ["alert integration", "Fleet", "osquery", "endpoint management", "policy", "vulnerability", "webhook"]
---
@@ -14,7 +15,6 @@ Fleet sends these webhooks once, when the event happens, and never sends a recov
<div className="hide">
## In Flashduty On-call
----
Get the integration push URL in either of the following ways.
@@ -35,7 +35,6 @@ Get the integration push URL in either of the following ways.
</div>
## In Fleet
----
Enable the webhooks under **Manage automations** in the Fleet admin UI, or set them through GitOps or the configuration file, as shown below. Use the full Flashduty push URL, including `integration_key`, as `destination_url` for both webhooks.
@@ -87,7 +86,6 @@ Hosts run policies at the interval set by `FLEET_OSQUERY_POLICY_UPDATE_INTERVAL`
</Steps>
## Events and recovery
----
| Fleet delivery | Effect in Flashduty |
| :--- | :--- |
@@ -100,7 +98,6 @@ One delivery can carry many hosts. Flashduty handles them in host ID order and p
Fleet does not notify Flashduty when a host is fixed. Turn on [auto-close](/en/on-call/channel/create-edit) for the integration's channel, with a suggested window of 24 hours to 7 days depending on how long you take to handle failing policies. When the same policy fails again on the same host (for example after the policy is reset in Fleet), it merges into the same alert.
## Alert Key
----
- Failing policy: computed from the policy ID (`policy.id`) and the host ID (`hosts[].id`)
- Vulnerability: computed from the CVE ID and the host ID
@@ -108,7 +105,6 @@ Fleet does not notify Flashduty when a host is fixed. Turn on [auto-close](/en/o
Both IDs are Fleet database IDs and stay constant within one Fleet instance. Changes to the policy name, host name, or failing-host counts do not change the Alert Key. A delivery without the policy ID, CVE ID, or host ID is rejected, and the error names the missing field.
## Severity
----
| Source | Condition | Flashduty severity |
| :--- | :--- | :--- |
@@ -122,7 +118,6 @@ Both IDs are Fleet database IDs and stay constant within one Fleet instance. Cha
The policy `critical` option requires a Fleet Premium license; free Fleet rejects it with `option critical requires a premium license`. On free Fleet, every policy alert therefore arrives as Warning.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -136,7 +131,6 @@ The policy `critical` option requires a Fleet Premium license; free Fleet reject
The policy query, author details, and software installation paths in the payload are not stored as labels.
## Troubleshooting
----
- **Flashduty returns a parameter error**: the message names the missing field. If it says only failing policy and vulnerability webhooks are supported, check whether a host status or activity webhook points at this URL
- **No alert arrives**: the policy webhook fires only when a policy changes from passing to failing; a host that keeps failing is not sent again. Hosts run policies every `FLEET_OSQUERY_POLICY_UPDATE_INTERVAL` (default 1 hour), and Fleet posts only after a result changes
diff --git a/en/on-call/integration/alert-integration/alert-sources/flowmon-ads.mdx b/en/on-call/integration/alert-integration/alert-sources/flowmon-ads.mdx
index 2a43d704..6097f6d9 100644
--- a/en/on-call/integration/alert-integration/alert-sources/flowmon-ads.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/flowmon-ads.mdx
@@ -1,5 +1,6 @@
---
title: "Flowmon ADS alert integration"
+sidebarTitle: "Flowmon ADS"
description: "Flowmon ADS sends detected network anomaly events as email reports; use a Flashduty email integration to turn each event into an alert."
keywords: ["alert integration", "Flowmon ADS", "Flowmon", "Progress", "email", "network anomaly detection", "NDR"]
---
@@ -9,7 +10,6 @@ When Flowmon ADS (Anomaly Detection System) detects a network anomaly event, it
<div className="hide">
## In Flashduty On-call
----
Get the integration email address in either of the two ways below. **In both cases choose the Email integration type**, not Flowmon ADS.
@@ -30,7 +30,6 @@ Get the integration email address in either of the two ways below. **In both cas
</div>
## Configure Flowmon ADS
----
1. In Flowmon ADS, open **Email notifications** under **Event Response** and create an email report. Each email report is bound to exactly one perspective
2. Click **Add new email** and add the Flashduty email integration address as a recipient
@@ -55,12 +54,10 @@ The body of a per-event email contains these fields:
| `Ports involved` | Port numbers related to the event, may be empty |
## Push mode in Flashduty
----
Keep the email integration's default push mode, which creates a new alert for every email: the alert title is the email title and the description is the email body, which contains the fields above. Flowmon ADS sends one email per event and events don't need to be merged, so no rules are needed.
## Limitations
----
- **No recovery email**: Flowmon ADS events are one-time notifications and no recovery email is sent, so alerts do not close on their own. Turn on the [auto-resolve timeout](/en/on-call/channel/create-edit) in the channel that receives this integration; 24 hours is a reasonable start.
- **Severity**: in Flashduty these alerts show the Email integration type, and their severity is always Warning; the event priority is in the `Severity` field of the body. You can adjust it with [alert pipelines](/en/on-call/integration/alert-integration/alert-pipelines).
diff --git a/en/on-call/integration/alert-integration/alert-sources/flowtriq.mdx b/en/on-call/integration/alert-integration/alert-sources/flowtriq.mdx
index c0721768..05fc250f 100644
--- a/en/on-call/integration/alert-integration/alert-sources/flowtriq.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/flowtriq.mdx
@@ -1,5 +1,6 @@
---
title: "Flowtriq alert integration"
+sidebarTitle: "Flowtriq"
description: "Send DDoS attack events detected by Flowtriq to Flashduty On-call through a Webhook alert channel."
keywords: ["alert integration", "Flowtriq", "webhook", "DDoS", "DDoS detection", "attack alerts"]
---
@@ -9,7 +10,6 @@ Use a Flowtriq Webhook alert channel to send DDoS attack events to Flashduty On-
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Flowtriq
----
<Steps>
<Step title="Add a Webhook alert channel">
@@ -58,7 +57,6 @@ Trigger attack detection on a monitored node. Confirm that Flashduty receives an
Flowtriq retries a failed delivery up to 3 times (after 10 seconds, 60 seconds, and 5 minutes). Each request times out after 10 seconds, and a non-2xx status code counts as a failure.
## Events and recovery
----
Flowtriq posts to the webhook on every incident event. The event type is in `event_type`:
@@ -72,12 +70,10 @@ Flowtriq posts to the webhook on every incident event. The event type is in `eve
Other event types, including any Flowtriq adds later, create no alert; Flashduty returns success for them.
## Alert Key
----
Flashduty builds the Alert Key from the incident identity: `incident.uuid` when present, otherwise `incident.id`. Webhook deliveries currently carry the numeric `incident.id` and no `uuid`. The start and end events of one attack share one Alert Key, so the end event recovers the matching alert. An event with neither field is rejected. Changes to the title, severity, or peak traffic do not change the Alert Key.
## Severity mapping
----
| `incident.severity` | Flashduty severity |
| :--- | :--- |
@@ -89,7 +85,6 @@ Flashduty builds the Alert Key from the incident identity: `incident.uuid` when
A recovery event keeps the last severity from the attack.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -105,7 +100,6 @@ A recovery event keeps the last severity from the attack.
The alert description comes from Flowtriq's AI summary (`ai_summary`). The `attack_start` delivery carries no summary, so the description is empty at that point.
## Troubleshooting
----
- **Flowtriq shows a failed delivery**: confirm the URL is complete, includes `integration_key`, and uses HTTPS. Failed deliveries are listed in the notification log on the incident detail page in Flowtriq
- **The alert did not recover**: confirm the Flowtriq channel sent an `attack_end` event. Recovery relies on the start and end events carrying the same `incident.id`; if an alert stays open for a long time, close it manually in Flashduty
diff --git a/en/on-call/integration/alert-integration/alert-sources/fluxcd.mdx b/en/on-call/integration/alert-integration/alert-sources/fluxcd.mdx
index 7b43ee5e..ecf79e60 100644
--- a/en/on-call/integration/alert-integration/alert-sources/fluxcd.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/fluxcd.mdx
@@ -1,5 +1,6 @@
---
title: "Flux CD alert integration"
+sidebarTitle: "Flux CD"
description: "Send Flux object reconciliation failures to Flashduty On-call through a Flux notification-controller generic Provider, and close the alert automatically once reconciliation succeeds again."
keywords: ["alert integration", "Flux CD", "Flux", "GitOps", "notification-controller", "Kustomization", "HelmRelease", "Kubernetes"]
---
@@ -9,7 +10,6 @@ Flux's notification-controller pushes events out through two kinds of objects: a
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Flux
----
You need `kubectl` permissions to create a Secret and the Flux `Provider` and `Alert` objects in the cluster. The examples use the `notification.toolkit.fluxcd.io/v1beta3` API and the `flux-system` namespace; the Provider, Alert, and Secret must be in the same namespace. The cluster must be able to reach the domain of the Flashduty push URL.
@@ -113,7 +112,6 @@ Flux has no button that sends a test message. Use a temporary Kustomization inst
</Steps>
## Alert Key
----
Flashduty uses `involvedObject.uid`, the Kubernetes UID of the Flux object, as the Alert Key. Flux's own `pagerduty` Provider uses the same UID as the deduplication key for both trigger and resolve. All failure events of one Flux object land on the same Flashduty alert; changes to the failure reason (`reason`), message, or revision do not change the Alert Key.
@@ -123,7 +121,6 @@ Flashduty uses `involvedObject.uid`, the Kubernetes UID of the Flux object, as t
Flashduty rejects a request without `involvedObject.uid`.
## Alert lifecycle
----
Flashduty handles each event by its `severity` and `reason` fields:
@@ -140,12 +137,10 @@ By default, Flux pushes an event for the same object with the same `message` and
**When only `error` events are forwarded**: if the Alert's `eventSeverity` is `error`, or its `exclusionList` filters out success events, Flashduty receives no recovery events and alerts never close on their own. In that case, turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit) with **Incident trigger** as the timing start. A timeout of 12 hours is a reasonable default: if the object is still failing, the next failed reconciliation triggers the alert again.
## Severity
----
Flux failure events have a single level, `error`, so all alerts default to **Critical**. For a different severity, append `&severity=Warning` (or `Info`) to the push URL. A recovery event keeps the severity of the original alert.
## Alert content
----
- **Title**: `<Kind> <namespace>/<name>: <reason>`, for example `Kustomization apps/webapp: ValidationFailed`
- **Description**: the event `message`
@@ -154,7 +149,6 @@ Flux failure events have a single level, `error`, so all alerts default to **Cri
In `metadata` key names, characters other than `a-z`, `A-Z`, `0-9`, and `_` are replaced with `_` (for example, `kustomize.toolkit.fluxcd.io/revision` sent by older Flux versions becomes `kustomize_toolkit_fluxcd_io_revision`). A key with the same name as a built-in label does not overwrite it. Empty values are not written as labels.
## Troubleshooting
----
- **No alerts arrive**: run `kubectl -n flux-system logs deploy/notification-controller` and look for errors such as `failed to dispatch notification`; run `kubectl -n flux-system get events --field-selector involvedObject.kind=Alert` to see warnings recorded on the Alert
- **Alerts arrive for only some objects**: check that the object's `kind` is listed in `eventSources`, and that the object is in the Alert's namespace or the entry sets `namespace`
diff --git a/en/on-call/integration/alert-integration/alert-sources/formant.mdx b/en/on-call/integration/alert-integration/alert-sources/formant.mdx
index ccec7d5e..f5490723 100644
--- a/en/on-call/integration/alert-integration/alert-sources/formant.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/formant.mdx
@@ -1,5 +1,6 @@
---
title: "Formant alert integration"
+sidebarTitle: "Formant"
description: "Send Formant robot and device events to Flashduty On-call through event webhook forwarding."
keywords: ["alert integration", "Formant", "robotics", "device monitoring", "webhook", "events"]
---
@@ -11,7 +12,6 @@ A Formant event is sent once and has no recovery notification, so the alert in F
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Formant
----
<Steps>
<Step title="Create a webhook">
@@ -61,19 +60,16 @@ Make a forwarded event trigger once (for example, take a device offline or push
</Steps>
## Recovery and auto-close
----
Formant events cannot be changed after they trigger, and the webhook is sent once per event. The request body has no field that marks an event as ended or recovered, so the alert in Flashduty does not recover on its own.
Each Formant event is a separate Flashduty alert. Close it by hand, or turn on [auto-close](/en/on-call/channel/create-edit) in the channel that receives this integration. We suggest 2 hours; adjust to how quickly your team handles device problems.
## Alert Key
----
The Alert Key is the Formant event ID (`payload.id`). A repeated delivery of the same event merges into the same alert; different events, even from the same event trigger and device, are different alerts. If a request has no event ID, Flashduty generates a random Alert Key, and that alert is not merged either.
## Status and severity
----
The alert status equals its severity; it does not recover.
@@ -86,7 +82,6 @@ The alert status equals its severity; it does not recover.
| Missing or any other value | Warning |
## Alert content
----
- **Title**: the event `message`; if missing, `Formant event on <stream name>`; if that is missing too, `Formant event`
- **Description**: device ID, stream, datapoint value, event time and the event link in Formant
@@ -103,7 +98,6 @@ The alert status equals its severity; it does not recover.
| Device tags | Each key and value in the event `tags`; characters such as `.` and `-` in keys become `_`, and a tag never overrides the labels above |
## Troubleshooting
----
- **Flashduty receives nothing**: check that the event's **Actions** tab has the webhook selected under **Webhook forwarding**, and that the webhook URL is the full push URL including `integration_key`
- **Flashduty returns a parameter error**: the body is not JSON or has no `payload` object. Use Formant's built-in webhook forwarding and do not rewrite the body
diff --git a/en/on-call/integration/alert-integration/alert-sources/fortimonitor.mdx b/en/on-call/integration/alert-integration/alert-sources/fortimonitor.mdx
index edabced4..f26031ff 100644
--- a/en/on-call/integration/alert-integration/alert-sources/fortimonitor.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/fortimonitor.mdx
@@ -1,5 +1,6 @@
---
title: "FortiMonitor alert integration"
+sidebarTitle: "FortiMonitor"
description: "Send FortiMonitor incident and clear notifications to Flashduty On-call through a webhook."
keywords: ["alert integration", "FortiMonitor", "Panopta", "Fortinet", "webhook", "Alert Timeline", "outage_id"]
---
@@ -9,7 +10,6 @@ Use the FortiMonitor (formerly Panopta) webhook integration to send incident and
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure FortiMonitor
----
<Steps>
<Step title="Create a webhook integration">
@@ -43,18 +42,18 @@ You can get the integration push URL in either of the following ways.
6. Set **Authentication Method** to **None**
7. Set **Payload Type** to **Form Variables** and add the variables below, one per row. Variable names are case-sensitive; the values are FortiMonitor macros:
-| Variable name | Value |
-| :--- | :--- |
-| `trigger` | `$trigger` |
-| `outage_id` | `$outage_id` |
-| `severity` | `$severity` |
-| `name` | `$name` |
-| `fqdn` | `$fqdn` |
-| `server_id` | `$server_id` |
-| `items` | `$items` |
-| `reasons` | `$reasons` |
-| `duration` | `$duration` |
-| `tags` | `$tags` |
+ | Variable name | Value |
+ | :--- | :--- |
+ | `trigger` | `$trigger` |
+ | `outage_id` | `$outage_id` |
+ | `severity` | `$severity` |
+ | `name` | `$name` |
+ | `fqdn` | `$fqdn` |
+ | `server_id` | `$server_id` |
+ | `items` | `$items` |
+ | `reasons` | `$reasons` |
+ | `duration` | `$duration` |
+ | `tags` | `$tags` |
8. Click **Save**
@@ -92,7 +91,6 @@ FortiMonitor sends webhook requests from fixed IP addresses: `104.197.35.194/32`
</Warning>
## Payload
----
FortiMonitor POSTs the following form fields, one request per incident and event:
@@ -112,14 +110,12 @@ FortiMonitor POSTs the following form fields, one request per incident and event
The alert title is `<instance name>: <affected metrics>`. If the instance name is empty, the FQDN is used; if both are empty, the title is `FortiMonitor incident <outage_id>`.
## Alert Key
----
Flashduty uses `outage_id` (the FortiMonitor incident ID) as the Alert Key. The incident, escalation, and clear notifications of one incident carry the same `outage_id`, so they land on the same alert. When the same metric on the same instance fails again after recovering, FortiMonitor opens a new incident ID and Flashduty opens a new alert. Changing the instance name, reason, or severity does not change the Alert Key.
If a request has no `outage_id`, or still contains the unexpanded `$outage_id`, Flashduty returns a parameter error, because the clear notification could not be linked to the original alert.
## Status and severity
----
| FortiMonitor `trigger` | Flashduty behavior |
| :--- | :--- |
@@ -136,7 +132,6 @@ If a request has no `outage_id`, or still contains the unexpanded `$outage_id`,
Requests with an empty or unknown `trigger` are rejected.
## FAQ
----
<AccordionGroup>
<Accordion title="Does an Alert Timeline with several events create several alerts?">
@@ -159,7 +154,6 @@ The Alert Timeline sends a notification only after the incident has lasted until
</AccordionGroup>
## Troubleshooting
----
- **Delivery fails**: make sure the Postback URL is the complete push URL and includes `integration_key`. If inbound traffic is restricted, allow the FortiMonitor webhook IP addresses
- **Flashduty returns a parameter error**: make sure Payload Type is Form Variables, the variable names match the table above, and `trigger` and `outage_id` are set to `$trigger` and `$outage_id`
diff --git a/en/on-call/integration/alert-integration/alert-sources/fortisiem.mdx b/en/on-call/integration/alert-integration/alert-sources/fortisiem.mdx
index 0eae561c..030ecea8 100644
--- a/en/on-call/integration/alert-integration/alert-sources/fortisiem.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/fortisiem.mdx
@@ -1,5 +1,6 @@
---
title: "FortiSIEM alert integration"
+sidebarTitle: "FortiSIEM"
description: "Send FortiSIEM incident trigger, update, and clear notifications to Flashduty On-call through Incident HTTP Notification."
keywords: ["alert integration", "FortiSIEM", "Fortinet", "SIEM", "Incident HTTP Notification", "incidentId"]
---
@@ -9,7 +10,6 @@ When a rule triggers an incident, FortiSIEM's Incident HTTP Notification POSTs a
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In FortiSIEM
----
<Steps>
<Step title="Fill in Incident HTTP Notification">
@@ -56,14 +55,12 @@ Let a rule trigger a real incident and confirm Flashduty receives an active aler
</Steps>
## Alert Key
----
Flashduty uses the `incidentId` attribute of the `incident` element as the Alert Key. The FortiSIEM documentation defines it as "Unique ID of the incident in FortiSIEM", and describes `status` as "New, Update or Clear"; one `incidentId` is expected across the notifications of one incident. The XML schema comes from the FortiSIEM 6.7.0 Integration API guide; check the first real delivery on your 7.x version against the field list below. Changes to the rule name, severity, repeat count, time, or incident details do not change the Alert Key.
Flashduty rejects a request without `incidentId` (HTTP 400), because later updates and recovery could not be matched reliably.
## Status and severity
----
The `status` attribute:
@@ -84,7 +81,6 @@ The `severity` attribute accepts `HIGH`, `MEDIUM`, `LOW`, or the matching 0-10 s
| Empty or unrecognized | Warning |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -97,7 +93,6 @@ The `severity` attribute accepts `HIGH`, `MEDIUM`, `LOW`, or the matching 0-10 s
`deviceDetails`, which carries user names and emails, is not written to labels.
## Troubleshooting
----
- **FortiSIEM reports a failed push**: confirm **HTTP(S) Server URL** starts with `https://`, includes the full `integration_key`, and that the FortiSIEM network can reach `api.flashcat.cloud`
- **Flashduty returns an invalid-parameter error**: confirm the body is FortiSIEM incident XML (root element `incident`) with an `incidentId` attribute
diff --git a/en/on-call/integration/alert-integration/alert-sources/gatus.mdx b/en/on-call/integration/alert-integration/alert-sources/gatus.mdx
index 18283a95..afec8fbd 100644
--- a/en/on-call/integration/alert-integration/alert-sources/gatus.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/gatus.mdx
@@ -1,5 +1,6 @@
---
title: "Gatus alert integration"
+sidebarTitle: "Gatus"
description: "Send Gatus endpoint trigger and recovery events to Flashduty On-call through the custom alerting provider."
keywords: ["alert integration", "Gatus", "health check", "webhook", "custom provider"]
---
@@ -11,14 +12,12 @@ Gatus has no fixed webhook format: you write the request body in its configurati
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **Gatus** alert integration and copy its complete Push URL.
</div>
## Configure Gatus
----
<Steps>
<Step title="Configure the custom provider">
@@ -81,7 +80,6 @@ Restart or reload Gatus so the configuration takes effect. Make an endpoint cond
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from the endpoint's `group` and `name`. Gatus identifies an endpoint by `<group>_<name>` and provides no separate ID per alert, so the trigger, reminders, and recovery of one endpoint share one Alert Key. An endpoint without a group uses `name` alone.
@@ -90,7 +88,6 @@ Flashduty computes the Alert Key from the endpoint's `group` and `name`. Gatus i
- Changes to `url`, `description`, or `errors` do not change the Alert Key
## Status and severity
----
| Gatus `[ALERT_TRIGGERED_OR_RESOLVED]` | Flashduty status or severity |
| :--- | :--- |
@@ -100,7 +97,6 @@ Flashduty computes the Alert Key from the endpoint's `group` and `name`. Gatus i
Gatus alerts have no severity field, so a failing endpoint health check is treated as Critical. Empty or other status values are rejected.
## Troubleshooting
----
- **Gatus logs `status code 400`**: confirm `method` is `POST`, the body is valid JSON, and `name` and `status` are not empty. Gatus escapes only double quotes in `[RESULT_ERRORS]`; a double quote, backslash, or line break in an endpoint name, group, or description breaks the JSON, so avoid those characters
- **Gatus logs `status code 404` or `401`**: confirm the Push URL is complete and contains `integration_key`
diff --git a/en/on-call/integration/alert-integration/alert-sources/gcp-personalized-service-health.mdx b/en/on-call/integration/alert-integration/alert-sources/gcp-personalized-service-health.mdx
index 3e9b4594..77411ce8 100644
--- a/en/on-call/integration/alert-integration/alert-sources/gcp-personalized-service-health.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/gcp-personalized-service-health.mdx
@@ -1,5 +1,6 @@
---
title: "Google Cloud Personalized Service Health Alert Integration"
+sidebarTitle: "Google Cloud Personalized Service Health"
description: "Receive Personalized Service Health events through a Cloud Monitoring log-based alerting policy and a webhook notification channel using the Flashduty Google Cloud Monitoring integration, with an auto-resolve timeout to close alerts."
keywords: ["alert integration", "Google Cloud", "Personalized Service Health", "Service Health", "Cloud Monitoring", "log-based alert", "webhook"]
---
@@ -9,7 +10,6 @@ Personalized Service Health writes the Google Cloud events that affect your proj
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the Google Cloud Monitoring integration type** in both, not Personalized Service Health.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the Google
</div>
## Configure in Google Cloud
----
### Step 1: Prepare
@@ -101,14 +100,12 @@ gcloud logging write --payload-type=json LOG_NAME '{ "category": "INCIDENT", "re
Use the Service Health log name for `LOG_NAME`; the Google documentation uses the format `projects/PROJECT_ID/logs/servicehealth.googleapis.com%2Factivity`.
## Enable the auto-resolve timeout
----
For log-based alerting policies, Cloud Monitoring only sends a notification when an incident opens, not when it closes (the API documents the notification prompt of log-based policies as always `OPENED`), so Flashduty receives no recovery notification. Enable the [auto-resolve timeout](/en/on-call/channel/create-edit) on the channel that receives these alerts, choose **Incident trigger** as the window timing start, and start with 24 hours, adjusted to the usual duration of the events you care about.
The `autoClose` setting in the alerting policy only decides when the incident closes in Cloud Monitoring (7 days by default for log-based alerts); it does not notify Flashduty.
## Field mapping
----
| Cloud Monitoring field | Flashduty |
| :--- | :--- |
@@ -123,7 +120,6 @@ The `autoClose` setting in the alerting policy only decides when the incident cl
| `incident.policy_user_labels` | Each key becomes a label |
## Troubleshooting
----
- **No alert arrives**: confirm in **Monitoring** → **Incidents** that the incident opened; check whether the log filter matches, and note that notifications are rate limited (the Google documentation gives 20 alerts per policy per day per project as an example)
- **The alert does not recover**: log-based alerts send no closure notification, so enable the channel's auto-resolve timeout
diff --git a/en/on-call/integration/alert-integration/alert-sources/ghost-inspector.mdx b/en/on-call/integration/alert-integration/alert-sources/ghost-inspector.mdx
index 0b3cf6ab..e6f801a9 100644
--- a/en/on-call/integration/alert-integration/alert-sources/ghost-inspector.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/ghost-inspector.mdx
@@ -1,5 +1,6 @@
---
title: "Ghost Inspector alert integration"
+sidebarTitle: "Ghost Inspector"
description: "Send Ghost Inspector test failures and recoveries to Flashduty On-call through a webhook."
keywords: ["alert integration", "Ghost Inspector", "webhook", "test automation", "end-to-end testing"]
---
@@ -9,7 +10,6 @@ Use a Ghost Inspector webhook to send test run results to Flashduty On-call. Eac
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Ghost Inspector
----
Ghost Inspector's notification settings have three levels — organization, suite, and test — and each level inherits from the one above by default, though you can override it at any level. Pick whichever level matches how broadly you want the webhook applied; setting it at the organization or suite level covers every test underneath at once.
@@ -55,12 +54,10 @@ Ghost Inspector has no separate "send test notification" button: every test run,
</Steps>
## Alert key
----
Flashduty keys the alert on the test's `test._id`, the `data.test._id` field in the webhook body. Ghost Inspector sends the same `test._id` on every run of that test — unlike `data._id`, the id of that individual run's result, which is different every time — so a failing run and the later passing run of the same test reliably map to one alert. Changes to the test name, browser, region, or start/end URL do not change the alert key.
## Status and severity
----
Ghost Inspector has no severity levels, only a pass/fail result:
@@ -72,7 +69,6 @@ Ghost Inspector has no severity levels, only a pass/fail result:
A request missing the `passing` field is rejected, so Flashduty never treats an indeterminate result as a failure.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -86,7 +82,6 @@ A request missing the `passing` field is rejected, so Flashduty never treats an
| `passing` | Whether this run passed |
## Troubleshooting
----
- **Flashduty returns a parameter error**: confirm the push URL includes `integration_key`, and the payload includes `data.test._id` and `data.passing`
- **The alert never recovers**: confirm the recovery came from the same test, and that the level you configured the webhook at (test, suite, or organization) actually covers it
diff --git a/en/on-call/integration/alert-integration/alert-sources/gitguardian.mdx b/en/on-call/integration/alert-integration/alert-sources/gitguardian.mdx
index fd6704ae..79651b0c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/gitguardian.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/gitguardian.mdx
@@ -1,5 +1,6 @@
---
title: "GitGuardian alert integration"
+sidebarTitle: "GitGuardian"
description: "Send triggered, updated, and closed secret-leak incidents from GitGuardian to Flashduty On-call through a Custom webhook."
keywords: ["alert integration", "GitGuardian", "secret leak", "incident", "webhook", "secrets detection"]
---
@@ -9,7 +10,6 @@ Use the Custom webhook destination of GitGuardian to send secret-leak incidents
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure GitGuardian
----
You need permission to manage integrations in the GitGuardian workspace.
@@ -81,14 +80,12 @@ Trigger a new incident in the workspace and confirm that Flashduty receives an a
</Steps>
## Alert Key
----
Flashduty uses the incident `id` (`incident.id` in the webhook) as the Alert Key. In GitGuardian's published webhook examples, the New incident, New occurrence, Resolved, Ignored, and Reopened events of the same incident carry the same `incident.id`.
Changes to severity, validity, occurrence count, or detector name do not change the Alert Key. Incident events without `incident.id` are rejected.
## Status and severity
----
The alert status follows `action`: `incident_resolved` and `incident_ignored` recover the alert, and every other event in the table above triggers it. A validity, severity, or risk score change on an incident that is already resolved or ignored is ignored and does not re-open the alert. A reopened incident triggers a new alert with the same Alert Key.
@@ -104,7 +101,6 @@ The severity follows `incident.severity`:
`unknown` means GitGuardian has not rated the incident yet, so Flashduty treats it as Warning.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -121,7 +117,6 @@ The severity follows `incident.severity`:
| `repository` / `filepath` / `occurrence_url` | Repository, file path, and link of the new occurrence in `new_occurrence` events |
## Troubleshooting
----
- **No alert was created**: confirm the matching event is selected and that the webhook's filtering rules do not exclude the incident. GitGuardian states that webhook delivery is best effort and not guaranteed
- **The alert did not recover**: confirm **Resolved** and **Ignored** are selected under **Incident status change**
diff --git a/en/on-call/integration/alert-integration/alert-sources/github.mdx b/en/on-call/integration/alert-integration/alert-sources/github.mdx
index c4217b11..0639197c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/github.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/github.mdx
@@ -1,5 +1,6 @@
---
title: "GitHub alert integration"
+sidebarTitle: "GitHub"
description: "Send GitHub Dependabot, code scanning, and secret scanning alerts and failed Actions workflows to Flashduty On-call through a repository or organization webhook, and recover them once fixed."
keywords: ["alert integration", "GitHub", "Dependabot", "code scanning", "secret scanning", "GitHub Actions", "webhook"]
---
@@ -14,7 +15,6 @@ Change events such as deployments and code pushes are not part of this integrati
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -35,7 +35,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure GitHub
----
A webhook can be created on a single repository or on an organization (covering every repository in it). A repository webhook requires admin access to the repository; an organization webhook requires the organization owner role.
@@ -83,7 +82,6 @@ GitHub does not retry failed deliveries automatically. Use **Redeliver** in **Re
</Steps>
## Events and alert status
----
GitHub puts the event type in the `X-GitHub-Event` request header and the action in the `action` field of the body. Flashduty handles them as follows:
@@ -97,7 +95,6 @@ GitHub puts the event type in the `X-GitHub-Event` request header and the action
`ping` and other event types (such as a `push` selected by mistake) also get a success response without creating an alert.
## Alert Key
----
- **Security alerts**: the Alert Key is built from the event type, the repository ID (`repository.id`), and the alert number (`alert.number`). The alert number is unique per repository and alert type, and GitHub uses it to address the alert in its API (for example, `/repos/{owner}/{repo}/dependabot/alerts/{alert_number}`). The Alert Key stays the same from creation through fix, dismissal, and reopening, and renaming the repository does not change it.
- **Actions failures**: the Alert Key is built from the repository ID, the workflow ID (`workflow_run.workflow_id`), the ID of the repository the run came from (`workflow_run.head_repository.id`), and the branch (`workflow_run.head_branch`). Later runs of the same workflow on the same branch, including **Re-run**, merge into this alert, and any successful run recovers it. Each branch and each workflow gets its own alert; a pull request from a fork never merges with a branch of the same name in your repository. A run without branch information gets its own alert keyed by the run ID (`workflow_run.id`), which recovers only when a **Re-run** of that run succeeds.
@@ -105,7 +102,6 @@ GitHub puts the event type in the `X-GitHub-Event` request header and the action
Events without `repository.id`, `alert.number`, `workflow_run.id`, or `workflow_run.workflow_id` are rejected.
## When alerts do not recover
----
In these cases no successful run follows, so the alert does not recover on its own:
@@ -116,7 +112,6 @@ In these cases no successful run follows, so the alert does not recover on its o
We recommend turning on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit) with **Incident trigger** as the **Window timing start** and a **Timeout duration** of 24 hours. A failed workflow is normally fixed within a working day. Security alerts recover when they are fixed, dismissed, or closed in GitHub, so a channel that only receives security alerts can leave the timeout off.
## Severity
----
| Event | GitHub field | GitHub value | Flashduty severity |
| :--- | :--- | :--- | :--- |
@@ -134,7 +129,6 @@ We recommend turning on the channel's [auto-resolve timeout](/en/on-call/channel
A recovery event keeps the alert's existing severity.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -151,7 +145,6 @@ A recovery event keeps the alert's existing severity.
| `run_id` / `run_number` / `run_attempt` / `run_url` / `head_sha` | Workflow run ID, number, attempt, link, and commit |
## Troubleshooting
----
- **Recent Deliveries shows a failure**: open the delivery's **Response**. If it is not `200`, make sure the push URL is complete and includes `integration_key`. GitHub waits at most 10 seconds for a response
- **Ping succeeds but no alert arrives**: make sure the four events above are selected and the repository has the matching security features enabled. Cancelled or skipped workflow runs never create alerts, and a successful run only recovers an existing one
diff --git a/en/on-call/integration/alert-integration/alert-sources/gitlab.mdx b/en/on-call/integration/alert-integration/alert-sources/gitlab.mdx
index a191fdb5..b743d2c1 100644
--- a/en/on-call/integration/alert-integration/alert-sources/gitlab.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/gitlab.mdx
@@ -1,5 +1,6 @@
---
title: "GitLab alert integration"
+sidebarTitle: "GitLab"
description: "Sync failed GitLab pipelines, failed deployments and security vulnerabilities to Flashduty On-call through a webhook, and recover them once fixed."
keywords: ["alert integration", "GitLab", "webhook", "CI/CD", "pipeline", "deployment", "vulnerability"]
---
@@ -9,7 +10,6 @@ Use a GitLab project or group webhook to sync failed pipelines, failed deploymen
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure GitLab
----
GitLab.com, GitLab Self-Managed and GitLab Dedicated all support webhooks. Project webhooks are available on every tier and require the Maintainer or Owner role on the project. Group webhooks require Premium or Ultimate and the Owner role on the group, and send events from every project in the group and its subgroups.
@@ -71,7 +70,6 @@ For **Push events** (the default **Test** option) and other events unrelated to
</Steps>
## Alert Key
----
Flashduty builds the Alert Key from the business object, so the trigger and recovery events of one object share one Alert Key:
@@ -84,7 +82,6 @@ Flashduty builds the Alert Key from the business object, so the trigger and reco
The Alert Key combines the object type with the fields above, so a branch never merges with a tag or an environment of the same name. Renaming or moving the project does not change the Alert Key. A failed or successful event missing these fields is rejected.
## Status and severity
----
| Event | Status | Flashduty severity |
| :--- | :--- | :--- |
@@ -97,7 +94,6 @@ The Alert Key combines the object type with the fields above, so a branch never
| Pipeline `success`, deployment `success`, vulnerability `resolved` / `dismissed` | Recover | - |
## When alerts do not recover automatically
----
These objects never receive a later successful event, so their alerts do not recover automatically:
@@ -108,7 +104,6 @@ These objects never receive a later successful event, so their alerts do not rec
Turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit), set **Window timing start** to **Incident trigger**, and set the timeout to 24 hours. Pipeline and deployment failures are usually fixed within a working day. Vulnerability alerts recover when the vulnerability is resolved or dismissed, so a channel that only receives vulnerability alerts can leave the timeout off.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -130,7 +125,6 @@ Turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit), s
Pipeline variables (`variables`) and user emails never become labels.
## Troubleshooting
----
- **The webhook shows Temporarily disabled or Disabled**: GitLab temporarily disables a webhook after 4 consecutive failed deliveries and permanently disables it after 40. Check that the push URL is complete and includes `integration_key`, then click **Test** to send a test request and re-enable the webhook
- **A rejected deployment raised an alert**: when a deployment to a protected environment is rejected, GitLab sends `rejected` and then, after dropping the deployment job, `failed` for the same deployment. Flashduty treats it as a failed deployment; close the alert by hand or let the next successful deployment recover it
diff --git a/en/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring.mdx b/en/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring.mdx
index fa64c25c..7291b0ac 100644
--- a/en/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring.mdx
@@ -1,5 +1,6 @@
---
title: "Google Cloud Monitoring Alert Events"
+sidebarTitle: "Google Cloud Monitoring"
description: "Sync Google Cloud Monitoring, Error Reporting, Security Command Center, and Cloud Billing budget alerts to Flashduty through a webhook or a Pub/Sub push subscription"
---
@@ -8,42 +9,42 @@ Sync Google Cloud Monitoring, Error Reporting, Security Command Center, and Clou
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Google Cloud Monitoring** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center => Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Google Cloud Monitoring** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Google Cloud
----
<div class="md-block">
@@ -58,13 +59,15 @@ The push URL of one **GCP Cloud Monitoring** integration accepts all of the foll
Below, **push URL** means the integration push URL you copied earlier, in the form `https://api.flashcat.cloud/event/push/alert/google-cm?integration_key=<integration key>`.
-## I. Cloud Monitoring: webhook notification channel
+<span id="webhook-channel"></span>
+
+## Cloud Monitoring: webhook notification channel
### Step 1: Configure alert channel
1. Log in to the Google Cloud Console, search for the `Monitoring` product, and enter its console
2. Find `Alerting` in the left menu and click `EDIT NOTIFICATION CHANNELS` to create a channel
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/google-cm-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/google-cm-1.png" />
3. Find `Webhooks` on the Notification channels page and click `ADD NEW`
4. Enter the integration push URL in the `Endpoint URL` field (the URL will be generated after saving the integration name on the current page)
@@ -86,20 +89,20 @@ Below, **push URL** means the integration push URL you copied earlier, in the fo
Metric alerts, uptime checks, log-based alerts, and PromQL alerts (Managed Service for Prometheus) are all sent by alerting policies and are configured the same way.
-## II. Cloud Monitoring: Pub/Sub notification channel
+## Cloud Monitoring: Pub/Sub notification channel
If your organization requires alerts to go through Pub/Sub, use a Pub/Sub notification channel. The Alert Key is the same as for the webhook channel (`incident_id`), so the two channels are interchangeable.
-1. Create the topic and push subscription as described in **Section VI. Create a Pub/Sub push subscription**.
+1. Create the topic and push subscription as described in [Create a Pub/Sub push subscription](#pubsub-subscription).
2. In `Alerting` → `EDIT NOTIFICATION CHANNELS`, click `ADD NEW` in the `Pub/Sub` section and enter the topic name.
3. As prompted, grant `service-<project number>@gcp-sa-monitoring-notification.iam.gserviceaccount.com` the `Pub/Sub Publisher` role on the topic.
4. Select this Pub/Sub channel in the alerting policy's `Notification channels` and check `Notify on incident closure`.
-## III. Error Reporting
+## Error Reporting
Error Reporting sends notifications through Cloud Monitoring webhook notification channels (schema version 1.0). It supports webhooks only, not Pub/Sub.
-1. Create a webhook notification channel as in **Section I, Step 1** (you can reuse the same **Flashduty** channel).
+1. Create a webhook notification channel as in step 1 of [Cloud Monitoring: webhook notification channel](#webhook-channel) (you can reuse the same **Flashduty** channel).
2. Open the `Error Reporting` page and click `Configure notifications`.
3. Select the **Flashduty** channel under `Notification channels` and save.
@@ -109,11 +112,11 @@ Error Reporting sends a notification when an error cannot be grouped with existi
- Error Reporting sends no "resolved" notification, so the alert never recovers by itself. Close it in Flashduty.
- Alerts have Warning severity. To use another severity, append `&severity=Critical` (or `Info`) to the push URL.
-## IV. Security Command Center
+## Security Command Center
Security Command Center (SCC) can only continuously export findings to Pub/Sub. A push subscription forwards them to Flashduty.
-1. Create the topic and push subscription as described in **Section VI. Create a Pub/Sub push subscription**.
+1. Create the topic and push subscription as described in [Create a Pub/Sub push subscription](#pubsub-subscription).
2. Grant the SCC service account the `Pub/Sub Publisher` role on the topic, then create a continuous export (NotificationConfig), for example:
```bash
@@ -132,11 +135,11 @@ Do not add `state="ACTIVE"` to the filter. SCC only publishes finding updates th
- The alert recovers when the finding's `state` becomes `INACTIVE` (remediated, resource deleted, or set by hand) or its `mute` becomes `MUTED`. It triggers again when the finding becomes `ACTIVE` or `UNMUTED`.
- Threat findings (for example, from Event Threat Detection) never become INACTIVE automatically. Change their state or mute them in SCC.
-## V. Cloud Billing budgets
+## Cloud Billing budgets
Budget alerts are available only as programmatic notifications through Pub/Sub.
-1. Create the topic and push subscription as described in **Section VI. Create a Pub/Sub push subscription**.
+1. Create the topic and push subscription as described in [Create a Pub/Sub push subscription](#pubsub-subscription).
2. Go to `Billing` → `Budgets & alerts`, create or edit a budget, and set threshold rules (actual and/or forecasted cost).
3. Under `Manage notifications`, check `Connect a Pub/Sub topic to this budget`, select the topic above, and save.
@@ -147,7 +150,9 @@ Cloud Billing publishes the budget's current status to the topic several times a
- The Alert Key combines the billing account, budget, budget period, cost type, and the highest threshold exceeded. Repeated messages for the same threshold merge into one alert. Crossing a higher threshold creates a new alert.
- Budget alerts never recover automatically. When a new budget period starts, alerts are tracked for the new period. Close alerts from the previous period by hand.
-## VI. Create a Pub/Sub push subscription
+<span id="pubsub-subscription"></span>
+
+## Create a Pub/Sub push subscription
Sections II, IV, and V share these steps. One push subscription can carry several sources.
diff --git a/en/on-call/integration/alert-integration/alert-sources/google-scc.mdx b/en/on-call/integration/alert-integration/alert-sources/google-scc.mdx
index bf106e8d..2e610b23 100644
--- a/en/on-call/integration/alert-integration/alert-sources/google-scc.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/google-scc.mdx
@@ -1,5 +1,6 @@
---
title: "Google Security Command Center alert integration"
+sidebarTitle: "Google Security Command Center"
description: "Send Google Security Command Center finding notifications to Flashduty On-call through a Pub/Sub push subscription."
keywords: ["alert integration", "Google Security Command Center", "SCC", "Pub/Sub", "finding"]
---
@@ -9,14 +10,12 @@ Google Security Command Center (SCC) publishes new and updated findings to a Pub
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **Google Security Command Center** alert integration and copy its complete Push URL.
</div>
## Configure Google Cloud
----
You need an organization with Security Command Center enabled and a project to hold the Pub/Sub topic. Creating a notification config requires Security Center Admin (`roles/securitycenter.admin`) on the organization and Project IAM Admin (`roles/resourcemanager.projectIamAdmin`) on the project that holds the topic.
@@ -74,14 +73,12 @@ Pub/Sub push subscriptions have no test button. Make SCC produce a finding that
</Steps>
## Alert Key
----
Flashduty uses `finding.name` as the Alert Key, in the form `organizations/{organization ID}/sources/{source ID}/findings/{finding ID}`. In the SCC Finding resource, `name` is the finding's relative resource name, and the notifications for a finding's creation, updates and change to `INACTIVE` all carry the same value.
Changes to the title, severity, state, category or event time do not change the Alert Key. A request without `finding.name` is rejected, because later updates and the recovery could not be matched to the alert.
## Status and severity
----
| SCC field | Flashduty status or severity |
| :--- | :--- |
@@ -98,7 +95,6 @@ The alert title is `category: resource display name` (for example `OPEN_FIREWALL
Flashduty also writes these labels: `category`, `resource_name`, `resource_type`, `project`, `location`, `service`, `finding_name`, `finding_state`, `finding_severity`, `finding_class`, `finding_source`, `notification_config_name`, `external_uri`. `securityMarks` is not read.
## Troubleshooting
----
- **Pub/Sub keeps redelivering the same message**: Flashduty returns a 4xx for requests it cannot parse, and Pub/Sub retries with backoff. Check that the push endpoint contains `integration_key` and that payload unwrapping is off. Configure a dead-letter topic on the subscription to avoid endless retries
- **Flashduty returns an invalid-parameter error**: the message names the missing field, for example `finding.name is required` means the notification has no finding
diff --git a/en/on-call/integration/alert-integration/alert-sources/grafana.mdx b/en/on-call/integration/alert-integration/alert-sources/grafana.mdx
index 08f977a3..2e9b9331 100644
--- a/en/on-call/integration/alert-integration/alert-sources/grafana.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/grafana.mdx
@@ -1,5 +1,6 @@
---
title: "Grafana Integration"
+sidebarTitle: "Grafana"
description: "Sync Grafana alert events to Flashduty via webhook to achieve automated alert noise reduction."
---
@@ -8,53 +9,53 @@ Sync Grafana alert events to Flashduty via webhook to achieve automated alert no
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels. It's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Grafana** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Grafana** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
-## In Grafana
----
+## In Grafana
Grafana V4~V8 versions enable Legacy Alerting by default, while V9 and later versions enable Grafana Alerting by default. For feature distinctions and activation methods, please refer to the [official documentation](https://grafana.com/docs/grafana/v8.4/alerting/unified-alerting/opt-in/#opt-in-to-grafana-alerting). Follow these steps based on your deployed version.
### Legacy Alerting
<div class="md-block">
-1. Open your Grafana console and navigate to Alerting > Notification channels
+1. Open your Grafana console and navigate to Alerting → Notification channels
2. Click Add Channel to open the channel configuration dialog
3. Configure the name, select webhook as Type, enter the integration push URL in the Url field, and select POST as Method, as shown below:
-<img src="https://download.flashcat.cloud/grafana-legacy-alerting.png" alt="drawing" width="600"/>
+ <img src="https://download.flashcat.cloud/grafana-legacy-alerting.png" alt="drawing" width="600"/>
4. Save and return to the integration list. After an alert occurs, if the latest event time is displayed, the configuration is successful and events are being received
5. Complete
@@ -65,25 +66,24 @@ Grafana V4~V8 versions enable Legacy Alerting by default, while V9 and later ver
<div class="md-block">
-1. Open your Grafana console and navigate to Alerting > Contact points
+1. Open your Grafana console and navigate to Alerting → Contact points
2. Click New contact point to open the configuration dialog
3. Configure the name, select webhook as Type, enter the integration push URL in the Url field, and select POST as Method, as shown below:
-<img src="https://download.flashcat.cloud/grafana-contact-point.png" alt="drawing" width="600"/>
+ <img src="https://download.flashcat.cloud/grafana-contact-point.png" alt="drawing" width="600"/>
4. Open the Notification policies page, edit or add a policy as needed, and select the contact point created in the previous step as the delivery channel, as shown below:
-<img src="https://download.flashcat.cloud/grafana-notification-policy.png" alt="drawing" width="600"/>
+ <img src="https://download.flashcat.cloud/grafana-notification-policy.png" alt="drawing" width="600"/>
5. Save and return to the integration list. After an alert occurs, if the latest event time is displayed, the configuration is successful and events are being received
6. The default alert severity is warning. To customize it, you can configure the severity label in the alert details page (refer to the status mapping below), as shown in the following image:
-<img src="https://download.flashcat.cloud/grafana-alert-rule.png" alt="drawing" width="600"/>
+ <img src="https://download.flashcat.cloud/grafana-alert-rule.png" alt="drawing" width="600"/>
7. Complete
## Status Mapping
----
Legacy Alerting to Flashduty severity mapping:
diff --git a/en/on-call/integration/alert-integration/alert-sources/graylog.mdx b/en/on-call/integration/alert-integration/alert-sources/graylog.mdx
index a38673b0..afb5ec93 100644
--- a/en/on-call/integration/alert-integration/alert-sources/graylog.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/graylog.mdx
@@ -1,5 +1,6 @@
---
title: "Graylog Alert Events"
+sidebarTitle: "Graylog"
description: "Sync Graylog alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,45 +9,44 @@ Sync Graylog alert events to Flashduty via webhook for automated alert noise red
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Graylog** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Graylog** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Graylog
----
<div class="md-block">
-## I. Graylog Alert Push Configuration
### Step 1: Configure Alert Channel
1. Log in to the Graylog console
@@ -55,15 +55,15 @@ Choose this option when you need to route alerts to different channels based on
4. Enter Title and Description
5. Select **HTTP Notification** as Notification Type, as shown below
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-2.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-2.png" />
6. Enter the Flashduty URL you obtained (URL whitelist required for first-time use)
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-3.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-3.png" />
7. Click Save to whitelist the URL
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-1.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-1.png" />
8. After saving, submit Create
@@ -80,7 +80,7 @@ Choose this option when you need to route alerts to different channels based on
<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-4.png" />
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/guance.mdx b/en/on-call/integration/alert-integration/alert-sources/guance.mdx
index 989aab49..71066cb0 100644
--- a/en/on-call/integration/alert-integration/alert-sources/guance.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/guance.mdx
@@ -1,5 +1,6 @@
---
title: "Guance Alert Events"
+sidebarTitle: "Guance"
description: "Sync Guance alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,46 +9,45 @@ Sync Guance monitoring alert events to Flashduty via webhook for automated alert
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Dedicated Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Select **Guance** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Guance** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Guance
----
<div class="md-block">
-## I. Alert Push Configuration
### Step 1: Create Notification Object
1. Log in to your `Guance` console, select `Notification Targets` under `Monitoring`
@@ -68,7 +68,7 @@ Choose this option when you need to route alerts to different channels based on
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/hackerone.mdx b/en/on-call/integration/alert-integration/alert-sources/hackerone.mdx
index bb69951f..6a747c57 100644
--- a/en/on-call/integration/alert-integration/alert-sources/hackerone.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/hackerone.mdx
@@ -1,5 +1,6 @@
---
title: "HackerOne alert integration"
+sidebarTitle: "HackerOne"
description: "Send submitted, triaged, and closed vulnerability report events from a HackerOne program to Flashduty On-call through a webhook."
keywords: ["alert integration", "HackerOne", "vulnerability report", "webhook", "bug bounty"]
---
@@ -9,7 +10,6 @@ Use the webhook of a HackerOne program to send vulnerability reports to Flashdut
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure HackerOne
----
Webhooks are configured per program and inherit the permissions of the user who creates them: that user must be able to see the program's reports and change its settings.
@@ -79,14 +78,12 @@ When editing the webhook, you can click **Test request** to send an example requ
</Steps>
## Alert Key
----
Flashduty uses the report ID (`data.report.id` in the webhook) as the Alert Key. Every HackerOne delivery carries the full report, and the same report has the same `data.report.id` when it is submitted, triaged, closed, or reopened. It is also the number in the report URL `https://hackerone.com/reports/<id>`.
Changes to the title, state, or severity do not change the Alert Key. Deliveries that contain a report without `data.report.id` are rejected.
## Status and severity
----
The report's current state (`data.report.attributes.state`), not the event name, sets the alert status:
@@ -111,7 +108,6 @@ The report severity (`data.report.relationships.severity.data.attributes.rating`
When triage changes a report's severity, the alert is updated with the new severity.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -126,7 +122,6 @@ When triage changes a report's severity, the alert is updated with the new sever
The alert description is the report's vulnerability information (`vulnerability_information`), truncated beyond 8 KB.
## Troubleshooting
----
- **HackerOne shows a failed delivery**: Open the failed request under **Recent deliveries** on the webhook edit page and check Flashduty's reply on the **Response** tab. Make sure the **Payload URL** is complete and includes `integration_key`
- **The alert does not recover**: Make sure `report_resolved` and all four `report_closed_as_*` events are checked. Close alerts manually in Flashduty for reports that were closed while those events were not selected
diff --git a/en/on-call/integration/alert-integration/alert-sources/harbor.mdx b/en/on-call/integration/alert-integration/alert-sources/harbor.mdx
index c7b8f0b3..80eb9704 100644
--- a/en/on-call/integration/alert-integration/alert-sources/harbor.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/harbor.mdx
@@ -1,5 +1,6 @@
---
title: "Harbor Alert Integration"
+sidebarTitle: "Harbor"
description: "Sync Harbor alert events to Flashduty via webhook for automated alert noise reduction"
keywords: ["Harbor", "alert integration", "webhook", "container registry"]
---
@@ -18,7 +19,7 @@ You can obtain an integration push URL through either of these two methods:
Choose this method when you don't need to route alert events to different channels - it's simpler.
-<Accordion title="Expand">
+<Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Harbor** integration and click **Save** to generate a card
@@ -29,8 +30,8 @@ Choose this method when you don't need to route alert events to different channe
Choose this method when you need to route alerts to different channels based on the alert event payload.
-<Accordion title="Expand">
-1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+<Accordion title="View shared integration setup steps">
+1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Harbor** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
diff --git a/en/on-call/integration/alert-integration/alert-sources/harness.mdx b/en/on-call/integration/alert-integration/alert-sources/harness.mdx
index 7a7ab6f0..6f837092 100644
--- a/en/on-call/integration/alert-integration/alert-sources/harness.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/harness.mdx
@@ -1,5 +1,6 @@
---
title: "Harness alert integration"
+sidebarTitle: "Harness"
description: "Sync failed Harness pipelines, stages and triggers to Flashduty On-call through the Webhook method of a pipeline notification, and recover them on the next successful run."
keywords: ["alert integration", "Harness", "webhook", "CI/CD", "pipeline", "deployment"]
---
@@ -9,7 +10,6 @@ Use the Webhook method of a Harness pipeline notification rule to sync failed Ha
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Harness
----
Every Harness SaaS edition supports notification rules on a pipeline. You need the **Create/Edit** permission on the pipeline. The steps below configure one pipeline. If centralised notifications are enabled on your account, you can also configure many pipelines at once under **Account Settings → Notification Rules**; choose the events and the notification method the same way.
@@ -80,7 +79,6 @@ Run the pipeline so that it fails (for example, run `exit 1` in a Shell Script s
</Steps>
## Alert Key
----
Flashduty builds the Alert Key from the pipeline and stage, so the failure and success events of one object share one Alert Key:
@@ -95,7 +93,6 @@ Changes to the display names of pipelines, stages and triggers, to the execution
If both pipeline and stage events are selected, one failure raises two alerts: one for the pipeline and one for the failed stage. Select the events of one level only if you need just one.
## Status and severity
----
| Event | Status | Flashduty severity |
| :--- | :--- | :--- |
@@ -105,7 +102,6 @@ If both pipeline and stage events are selected, one failure raises two alerts: o
| `PipelineSuccess`, `StageSuccess` | Recover | - |
## When alerts do not recover automatically
----
In these cases no later success event arrives for the same object, so the alert does not recover automatically:
@@ -116,7 +112,6 @@ In these cases no later success event arrives for the same object, so the alert
Turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit), set **Window timing start** to **Incident trigger**, and set the timeout to 12 hours. Pipeline failures are usually fixed on the same day, and alerts that never recover close when the timeout expires.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -134,7 +129,6 @@ Turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit), s
User emails never become labels.
## Troubleshooting
----
- **No alerts arrive**: Check that the notification rule is enabled, that **Notification Method** is **Webhook**, and that the push URL is complete and includes `integration_key`. With delegate connectivity, check that the delegate can reach the Flashduty push URL
- **Alerts don't recover**: Check that **Pipeline Success** (or **Stage Success**) is selected and that the same pipeline has since run successfully
diff --git a/en/on-call/integration/alert-integration/alert-sources/healthchecks-io.mdx b/en/on-call/integration/alert-integration/alert-sources/healthchecks-io.mdx
index b0499fe4..57349ab2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/healthchecks-io.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/healthchecks-io.mdx
@@ -1,5 +1,6 @@
---
title: "Healthchecks.io alert integration"
+sidebarTitle: "Healthchecks.io"
description: "Send Healthchecks.io check down and up notifications to Flashduty On-call through a webhook."
keywords: ["alert integration", "Healthchecks.io", "cron", "heartbeat monitoring", "webhook"]
---
@@ -11,7 +12,6 @@ Self-hosted Healthchecks needs v3.5 or later, because the template below uses th
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Healthchecks.io
----
<Steps>
<Step title="Add a webhook integration">
@@ -94,7 +93,6 @@ To verify the full flow, make a check go down (for example, call `https://hc-pin
</Steps>
## Payload fields
----
| Field | Placeholder | Description | Use in Flashduty |
| :--- | :--- | :--- | :--- |
@@ -110,14 +108,12 @@ To verify the full flow, make a check go down (for example, call `https://hc-pin
The alert title is the check name. When the name is empty, Flashduty uses the slug, then `Healthchecks.io check <code>`. Every alert also carries the label `source=healthchecks-io`.
## Alert Key
----
Flashduty uses `$CODE` (`code`, the check UUID) as the Alert Key. The down and up notifications of a check carry the same UUID, so they land on the same alert. Different checks create different alerts even if they share a name. Renaming a check or changing its slug or tags does not change the Alert Key.
A check that is deleted and created again gets a new UUID and is no longer linked to the old alert.
## Status and severity
----
Healthchecks.io notifications have no severity. Flashduty maps them as follows:
@@ -129,7 +125,6 @@ Healthchecks.io notifications have no severity. Flashduty maps them as follows:
An empty or any other `status` is rejected.
## FAQ
----
<AccordionGroup>
<Accordion title="Does a check that stays down send repeated notifications?">
@@ -152,7 +147,6 @@ Yes. Each Healthchecks.io request times out after 30 seconds. On a connection fa
</AccordionGroup>
## Troubleshooting
----
- **Flashduty returns an invalid parameter error**: Confirm the method is POST, the request body is the JSON above, and `code` and `status` are unchanged
- **JSON parsing fails**: Check whether a tag contains a double quote or backslash. `$TAGS` is inserted as is, and these characters make the body invalid JSON. Change the tag, or remove the `tags` line from the template
diff --git a/en/on-call/integration/alert-integration/alert-sources/hertzbeat.mdx b/en/on-call/integration/alert-integration/alert-sources/hertzbeat.mdx
index b043c5ee..c7ff597e 100644
--- a/en/on-call/integration/alert-integration/alert-sources/hertzbeat.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/hertzbeat.mdx
@@ -1,5 +1,6 @@
---
title: "Apache HertzBeat Alert Integration"
+sidebarTitle: "Apache HertzBeat"
description: "Send Apache HertzBeat alerts and recoveries to Flashduty On-call through a Webhook notice receiver."
keywords: ["alert integration", "Apache HertzBeat", "HertzBeat", "webhook", "notice receiver", "monitoring", "alert rules"]
---
@@ -9,7 +10,6 @@ Use the Webhook type of a notice receiver under **Alerting → Notification →
<div className="hide">
## In Flashduty On-call
----
Get the push URL in either of two ways.
@@ -30,7 +30,6 @@ Get the push URL in either of two ways.
</div>
## Configure HertzBeat
----
<Steps>
<Step title="Add a notice receiver">
@@ -60,7 +59,6 @@ Flashduty parses only the default Webhook template that ships with HertzBeat. If
</Warning>
## Payload
----
HertzBeat POSTs the default template as JSON. One request can carry several alerts in `alerts`, and Flashduty handles each one:
@@ -78,14 +76,12 @@ HertzBeat POSTs the default template as JSON. One request can carry several aler
`commonLabels` and `commonAnnotations` are not read.
## Alert Key
----
The HertzBeat payload carries no alert ID. Flashduty builds the Alert Key from `alertname`, `instance` and `defineid` in `alerts[].labels`. In real HertzBeat 1.9.0 deliveries these three values were identical on trigger, repeated notification while firing, and recovery, so all three land on one Flashduty alert. Changing the severity, content or monitor name does not change the Alert Key.
A request without `labels.alertname` is rejected with a parameter error, because a recovery could not be tied to its alert. A missing `instance` or `defineid` counts as empty.
## Status and severity
----
| HertzBeat field | Flashduty status or severity |
| :--- | :--- |
@@ -98,7 +94,6 @@ A request without `labels.alertname` is rejected with a parameter error, because
A request with any other `status`, or an empty `alerts`, is rejected. In the default template `commonLabels.severity` is rewritten to decorated text (such as "Critical"), so it is not used for severity.
## FAQ
----
<AccordionGroup>
<Accordion title="What does Flashduty show after I click Send test message?">
@@ -121,7 +116,6 @@ Flashduty recovers an alert only when HertzBeat sends `resolved`. On HertzBeat 1
</AccordionGroup>
## Troubleshooting
----
- **Flashduty receives no alerts**: confirm the URL is the full push URL (with `integration_key`), a notice policy exists, and the alert matches it
- **Flashduty returns a parameter error**: confirm the body is the default HertzBeat template JSON, `status` is `firing` or `resolved`, and every alert has `labels.alertname`
diff --git a/en/on-call/integration/alert-integration/alert-sources/hetrixtools.mdx b/en/on-call/integration/alert-integration/alert-sources/hetrixtools.mdx
index 1895490d..39031db1 100644
--- a/en/on-call/integration/alert-integration/alert-sources/hetrixtools.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/hetrixtools.mdx
@@ -1,5 +1,6 @@
---
title: "HetrixTools alert integration"
+sidebarTitle: "HetrixTools"
description: "Send HetrixTools uptime monitoring, server resource usage, and blacklist monitoring notifications to Flashduty On-call through a contact list webhook."
keywords: ["alert integration", "HetrixTools", "webhook", "uptime monitoring", "blacklist monitoring"]
---
@@ -13,7 +14,6 @@ Use the webhook of a HetrixTools contact list to send monitoring notifications t
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -34,7 +34,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure HetrixTools
----
<Steps>
<Step title="Create a contact list">
@@ -70,14 +69,12 @@ Blacklist Monitoring notifications are not sent in real time: HetrixTools batche
</Tip>
## Alert Key
----
**Uptime Monitoring**: Flashduty computes the Alert Key from `monitor_id`, the HetrixTools monitor ID. The `offline` and `online` notifications of a monitor carry the same `monitor_id`, so they land on the same alert. Repeat notifications while the monitor stays offline merge into that alert as well. Changes to the monitor name, target, category, timestamp, or failing locations do not change the Alert Key. A request without `monitor_id` is rejected, because its recovery could not be matched.
**Server Monitoring Resource Usage and Blacklist Monitoring**: HetrixTools sends no recovery message for these notifications, so Flashduty creates a separate alert for each notification (and for each IP or domain in a blacklist notification). Close these alerts manually once handled.
## Status and severity
----
Uptime Monitoring notifications are handled by `monitor_status`:
@@ -99,7 +96,6 @@ Resource usage severity comes from `resource_usage.resource_type`:
Blacklist severity comes from `blacklisted_now`: greater than 0 (still listed) is Warning, and 0 (removed from every blacklist) is Info.
## Alert content
----
**Uptime Monitoring**
@@ -120,7 +116,6 @@ Blacklist severity comes from `blacklisted_now`: greater than 0 (still listed) i
- **Labels**: `check` (monitor label), `resource` (IP or domain), `source`, `notification` (always `blacklist`), `blacklisted_before`, `blacklisted_now`, `blacklisted_on` (comma-separated), `report_link`
## Troubleshooting
----
- **HetrixTools reports a failed delivery**: make sure the webhook is the full push URL, including `integration_key`
- **Flashduty returns a parameter error**: uptime and resource usage notifications need `monitor_id`, and an uptime notification's `monitor_status` must be `offline` or `online`; every item of a blacklist notification needs `monitor`
diff --git a/en/on-call/integration/alert-integration/alert-sources/honeybadger.mdx b/en/on-call/integration/alert-integration/alert-sources/honeybadger.mdx
index 785a66c1..8ea15c29 100644
--- a/en/on-call/integration/alert-integration/alert-sources/honeybadger.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/honeybadger.mdx
@@ -1,5 +1,6 @@
---
title: "Honeybadger alert integration"
+sidebarTitle: "Honeybadger"
description: "Send error, uptime check, and check-in events from a Honeybadger project to Flashduty On-call through a webhook."
keywords: ["alert integration", "Honeybadger", "webhook", "error monitoring", "uptime monitoring", "check-in"]
---
@@ -9,7 +10,6 @@ Use the Webhook integration of a Honeybadger project to send error (fault), upti
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Honeybadger
----
The Webhook integration is configured per project and is available only on Honeybadger's Team, Business, and Enterprise plans. You need administrative privileges on the project.
@@ -78,7 +77,6 @@ The **Test this integration** button on the integration settings page sends an `
</Steps>
## Alert Key
----
Flashduty builds the Alert Key from the object the event is about, so the trigger and recovery events of the same object share one Alert Key:
@@ -93,7 +91,6 @@ Flashduty builds the Alert Key from the object the event is about, so the trigge
The Alert Key combines the object type with the ID in the table, so an `up` event for a site does not recover that site's certificate alert, and an error ID never merges with an equal project ID. Changes to the error message, environment, occurrence count, site name, and similar fields do not change the Alert Key. Events without the required ID are rejected.
## Status and severity
----
Honeybadger events carry no severity, so Flashduty sets the status and severity from the event name:
@@ -107,7 +104,6 @@ Honeybadger events carry no severity, so Flashduty sets the status and severity
`cert_will_expire` and `volume_spike` have no recovery event. Close these alerts manually in Flashduty after handling them.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -130,7 +126,6 @@ Honeybadger events carry no severity, so Flashduty sets the status and severity
| `url` | Link to the error, check, or check-in page in Honeybadger |
## Troubleshooting
----
- **Webhook is not in the integration list**: Confirm that the account is on the Team plan or higher and that you are a project administrator
- **Flashduty returns a parameter error**: Confirm that the URL is complete and includes `integration_key`
diff --git a/en/on-call/integration/alert-integration/alert-sources/honeycomb.mdx b/en/on-call/integration/alert-integration/alert-sources/honeycomb.mdx
index 7962b476..265a25d4 100644
--- a/en/on-call/integration/alert-integration/alert-sources/honeycomb.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/honeycomb.mdx
@@ -1,5 +1,6 @@
---
title: "Honeycomb alert integration"
+sidebarTitle: "Honeycomb"
description: "Send Honeycomb Trigger and SLO burn alert trigger and recovery notifications to Flashduty On-call through a webhook recipient with custom payload templates."
keywords: ["alert integration", "Honeycomb", "Trigger", "SLO", "Burn Alert", "Webhook"]
---
@@ -9,7 +10,6 @@ Use a Honeycomb webhook recipient to send Trigger alerts and SLO burn alerts to
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Honeycomb
----
These steps require a Honeycomb account that can edit integrations in **Team Settings**. Triggers are available on every plan; SLOs and burn alerts require the Pro or Enterprise plan.
@@ -156,7 +155,6 @@ To verify the full flow, let the Trigger condition actually fire and confirm tha
</Steps>
## Alert Key
----
Flashduty uses `instance_id` (`.Alert.InstanceID`) as the Alert Key. Honeycomb's template variable reference defines it as the unique identifier of one Trigger or burn alert firing, useful for deduplicating and correlating alerts. Honeycomb's official incident.io template also uses it as the `deduplication_key` and resolves the matching alert on `OK`.
@@ -167,7 +165,6 @@ Flashduty uses `instance_id` (`.Alert.InstanceID`) as the Alert Key. Honeycomb's
With **Group resolution alerts**, Flashduty also merges notifications by `instance_id` and recovers the alert when a notification with `status` `OK` arrives. The alert description lists the groups currently over the threshold.
## Status and severity
----
Flashduty uses `status` to tell triggers from recoveries, and the `severity` variable to set the severity.
@@ -181,7 +178,6 @@ Flashduty uses `status` to tell triggers from recoveries, and the `severity` var
When `status` is `OK`, Flashduty recovers the original alert and keeps its last severity. An empty or any other `status` is rejected.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -199,7 +195,6 @@ When `status` is `OK`, Flashduty recovers the original alert and keeps its last
| `slo_id`, `slo_url` | ID and link of the related SLO (burn alerts only) |
## Troubleshooting
----
- **The Flashduty recipient is not selectable in Honeycomb**: Confirm that the matching alert type is enabled on the **Payload** tab and has a template
- **Flashduty returns a parameter error**: Confirm that the template matches the one above and that `instance_id` and `status` are not empty. Honeycomb does not retry 4xx responses
diff --git a/en/on-call/integration/alert-integration/alert-sources/hookdeck.mdx b/en/on-call/integration/alert-integration/alert-sources/hookdeck.mdx
index 41a4a17b..9dbe7bfa 100644
--- a/en/on-call/integration/alert-integration/alert-sources/hookdeck.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/hookdeck.mdx
@@ -1,5 +1,6 @@
---
title: "Hookdeck alert integration"
+sidebarTitle: "Hookdeck"
description: "Send Hookdeck issues (failed deliveries, rejected requests, transformation errors, queue backpressure) to Flashduty On-call through the project's webhook notifications. Alerts recover when the issue is resolved."
keywords: ["alert integration", "Hookdeck", "issue", "webhook notifications", "delivery failure"]
---
@@ -9,7 +10,6 @@ Hookdeck opens an issue when a delivery fails, a source rejects a request, a tra
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Hookdeck
----
Hookdeck sends webhook notifications to a source in your project, and a connection forwards them to a destination. So first create a connection that forwards notifications to Flashduty, then turn on webhook notifications in the project settings.
@@ -69,11 +68,11 @@ If you select only `issue.opened`, Flashduty never hears that an issue was resol
1. Create a test connection whose destination URL is `https://mock.hookdeck.com?status=500` (a Hookdeck mock endpoint that always returns HTTP 500), then send a request to the connection's source URL (shown when you open the source in Hookdeck):
-```bash
-curl -X POST '<source URL>' \
- -H 'Content-Type: application/json' \
- -d '{"type":"flashduty.test"}'
-```
+ ```bash
+ curl -X POST '<source URL>' \
+ -H 'Content-Type: application/json' \
+ -d '{"type":"flashduty.test"}'
+ ```
2. Once a new delivery issue appears on the Hookdeck **Issues** page, confirm that Flashduty receives a Critical alert
3. On the Issues page, change the issue's status to **Resolved** and confirm that the alert recovers
@@ -83,14 +82,12 @@ curl -X POST '<source URL>' \
</Steps>
## Alert Key
----
Flashduty uses the Hookdeck issue ID (`issue.id`, such as `iss_...`) as the Alert Key. An issue keeps the same ID when it is opened, acknowledged, resolved, and reopened, so status update notifications apply to the alert created when the issue opened.
Changes to the issue's error code, response status, first and last seen times, or connection name do not change the Alert Key. Requests without `issue.id` are rejected.
## Status and severity
----
The severity comes from the issue type (`issue.type`):
@@ -114,7 +111,6 @@ The status comes from `issue.status`:
Other status values are rejected with a parameter error. Only the `issue.opened` and `issue.updated` topics create alerts; other topics (such as `event.successful`) are accepted and ignored.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -134,7 +130,6 @@ Other status values are rejected with a parameter error. Only the `issue.opened`
The failed request included in the notification (headers and body) is not written to labels.
## Troubleshooting
----
- **No alerts arrive**: Check that webhook notifications are on and point to the right source, and that the `flashduty` connection is not paused. In Hookdeck, open that connection's events and confirm that Flashduty returned 200
- **The alert does not recover**: Check that `issue.updated` is selected under Webhook topics, and mark the issue Resolved or Ignored in Hookdeck. Dismissing an issue does not change its status
diff --git a/en/on-call/integration/alert-integration/alert-sources/hosted-graphite.mdx b/en/on-call/integration/alert-integration/alert-sources/hosted-graphite.mdx
index 6cb8eed3..5ea5642f 100644
--- a/en/on-call/integration/alert-integration/alert-sources/hosted-graphite.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/hosted-graphite.mdx
@@ -1,5 +1,6 @@
---
title: "Hosted Graphite alert integration"
+sidebarTitle: "Hosted Graphite"
description: "Send threshold alert triggers and recoveries from Hosted Graphite to Flashduty On-call through the alert Webhook notification channel."
keywords: ["alert integration", "Hosted Graphite", "Graphite", "Webhook", "Notification Channel", "metric alerts"]
---
@@ -9,7 +10,6 @@ Use a Hosted Graphite Webhook notification channel to send metric alert triggers
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Hosted Graphite
----
<Steps>
<Step title="Create a Webhook notification channel">
@@ -57,7 +56,6 @@ Hosted Graphite notifications carry no alert ID, so Flashduty tells alerts apart
</Warning>
## Payload
----
Hosted Graphite POSTs these fields as `application/json`. Flashduty parses them directly; no template is needed.
@@ -73,14 +71,12 @@ Hosted Graphite POSTs these fields as `application/json`. Flashduty parses them
| `timestamp`, `backoff_minutes` | Send time, backoff setting | Not stored |
## Alert Key
----
Flashduty computes the Alert Key as the MD5 of the alert name and metric name joined by a delimiter. The trigger and recovery of one alert on one metric carry the same name and metric, so they land on the same Flashduty alert; alerts with a different name or metric stay separate. Changing the condition or the current value does not change the Alert Key.
Hosted Graphite provides no alert ID, so this combination is inferred: two alerts with the same name and metric merge. If `name` is missing, Flashduty returns a parameter error.
## Status and severity
----
Hosted Graphite notifications carry no severity, so Flashduty treats every alert as Warning.
@@ -92,7 +88,6 @@ Hosted Graphite notifications carry no severity, so Flashduty treats every alert
Requests with an empty or unknown `status` are rejected so they cannot corrupt an alert lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="Do Hosted Graphite retries create duplicate alerts?">
@@ -109,7 +104,6 @@ No test button was observed for the Webhook channel. Verify by pushing a metric
</AccordionGroup>
## Troubleshooting
----
- **Hosted Graphite fails to deliver**: check that the URL is the full push URL including `integration_key`
- **Flashduty returns a parameter error**: check that the body is JSON, `name` is not empty, and `status` is `alerting` or `recovered`
diff --git a/en/on-call/integration/alert-integration/alert-sources/http-pull.mdx b/en/on-call/integration/alert-integration/alert-sources/http-pull.mdx
index 13ae2d64..916a600e 100644
--- a/en/on-call/integration/alert-integration/alert-sources/http-pull.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/http-pull.mdx
@@ -1,5 +1,6 @@
---
title: "HTTP Pull Alert Integration"
+sidebarTitle: "HTTP Pull"
description: "Flashduty periodically polls an external HTTP endpoint and ingests the returned alert events. Use this for systems that cannot push alerts, or when you prefer to decouple ingestion from the source."
keywords: ["Alert Integration", "HTTP Pull", "Polling", "Cursor Pagination", "Data Ingestion"]
---
@@ -13,7 +14,6 @@ HTTP Pull is the right choice when your source **cannot send webhooks**, **is qu
<div className="hide">
## Setup Steps
----
### In Flashduty
@@ -33,7 +33,7 @@ When you don't need to route alert events to different channels, this method is
When you need to route alert events to different channels based on the alert payload, choose this method.
-1. Enter the Flashduty console, select **Integration Center => Alert Events** to enter the integration selection page.
+1. Enter the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page.
2. Select the **HTTP Pull** integration and fill in the **Integration Name**.
3. Configure the **Default Route** and select the corresponding channel (after the integration is created, go to **Route** to add finer-grained routing rules).
4. Fill in the form as described in the "Configuration" section below and click **Save**.
@@ -42,7 +42,6 @@ When you need to route alert events to different channels based on the alert pay
</div>
## Configuration
----
### HTTP Request
@@ -95,14 +94,12 @@ When pagination is enabled, the response must additionally expose a field for th
```
## Default Route
----
-When creating a "Shared Integration" (under **Integration Center => Alert Events**), you must configure a default route — otherwise newly pulled events will be dropped. After creation, you can add finer-grained rules under **Route**.
+When creating a "Shared Integration" (under **Integration Center → Alert Events**), you must configure a default route — otherwise newly pulled events will be dropped. After creation, you can add finer-grained rules under **Route**.
A "Dedicated Integration" (created under **Configuration → Integrations → Private integration** in a specific channel) is automatically bound to that channel and does not need a separate default route.
## Template Variables
----
The URL and request body support Go template syntax. There is currently **one** built-in variable:
diff --git a/en/on-call/integration/alert-integration/alert-sources/huawei-aom.mdx b/en/on-call/integration/alert-integration/alert-sources/huawei-aom.mdx
index 80e58ae9..d74aba82 100644
--- a/en/on-call/integration/alert-integration/alert-sources/huawei-aom.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/huawei-aom.mdx
@@ -1,5 +1,6 @@
---
title: "Huawei Cloud AOM alert integration"
+sidebarTitle: "Huawei Cloud AOM"
description: "Send Huawei Cloud AOM alerts to Flashduty On-call through SMN notifications or AOM webhook data subscriptions"
keywords: ["alert integration", "Huawei Cloud AOM", "SMN", "webhook", "data ingestion"]
---
@@ -21,7 +22,7 @@ Use either of the following methods to obtain an integration push URL.
Use this method when you do not need to route alerts to different channels.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View dedicated integration setup steps">
1. In the Flashduty console, select **Channels** and open the target channel.
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**.
3. Select **Huawei Cloud AOM** and click **Save**.
@@ -34,8 +35,8 @@ Use this method when you do not need to route alerts to different channels.
Use this method when you need to route alerts to different channels based on their payload.
<AccordionGroup>
- <Accordion title="Expand">
- 1. In the Flashduty console, select **Integration Center > Alert events**.
+ <Accordion title="View shared integration setup steps">
+ 1. In the Flashduty console, select **Integration Center → Alert events**.
2. Select **Huawei Cloud AOM** and enter an integration name.
3. Configure the default route and select a channel. You can add more routing rules under **Routes** after creating the integration.
4. Click **Save** and copy the generated **push URL**.
@@ -58,7 +59,7 @@ Use this method when you need to route alerts to different channels based on the
<Steps>
<Step title="Create an SMN topic">
1. Sign in to the Huawei Cloud console and open **Simple Message Notification (SMN)**.
-2. Select **Topic Management > Topics** and click **Create Topic**.
+2. Select **Topic Management → Topics** and click **Create Topic**.
3. Set the topic name to **Flashduty** and save it.
<Frame>
@@ -81,7 +82,7 @@ Use this method when you need to route alerts to different channels based on the
### Configure an AOM message template
-In the AOM 2.0 console, go to **Alarm Center > Alarm Notifications > Message Templates**. In some console versions, the path is **Alarms > Alarm Action Rules > Message Templates**.
+In the AOM 2.0 console, go to **Alarm Center → Alarm Notifications → Message Templates**. In some console versions, the path is **Alarms → Alarm Action Rules → Message Templates**.
When creating the template, select **HTTP/HTTPS** as the notification method. Flashduty supports the following content formats:
@@ -151,7 +152,7 @@ When creating the template, select **HTTP/HTTPS** as the notification method. Fl
<Steps>
<Step title="Associate the SMN topic and message template">
-1. In the AOM 2.0 console, go to **Alarm Center > Alarm Notifications**.
+1. In the AOM 2.0 console, go to **Alarm Center → Alarm Notifications**.
2. Under **Notification Rule Management**, create an alarm notification rule.
3. Select the **Flashduty** SMN topic and the AOM message template created earlier.
</Step>
@@ -171,7 +172,7 @@ When creating the template, select **HTTP/HTTPS** as the notification method. Fl
AOM webhook data subscription is not generally available. If the webhook alarm subscription option is not available in your console, submit a Huawei Cloud service ticket or use SMN instead.
</Warning>
-If Huawei Cloud has enabled this feature for your account, go to **Settings > Global Settings > Data Subscription** in the AOM 2.0 console. Create a webhook alarm subscription and set its destination to the same Flashduty AOM integration push URL.
+If Huawei Cloud has enabled this feature for your account, go to **Settings → Global Settings → Data Subscription** in the AOM 2.0 console. Create a webhook alarm subscription and set its destination to the same Flashduty AOM integration push URL.
The webhook request must use the official AOM structured event format:
diff --git a/en/on-call/integration/alert-integration/alert-sources/huawei-apm.mdx b/en/on-call/integration/alert-integration/alert-sources/huawei-apm.mdx
index 03af18b1..f0b87aef 100644
--- a/en/on-call/integration/alert-integration/alert-sources/huawei-apm.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/huawei-apm.mdx
@@ -1,5 +1,6 @@
---
title: "Huawei Cloud APM Alerts"
+sidebarTitle: "Huawei Cloud APM"
description: "Sync Huawei Cloud APM alerts to Flashduty through webhook to achieve automatic alert noise reduction"
---
@@ -8,46 +9,45 @@ Sync Huawei Cloud APM alerts to Flashduty through webhook, to achieve automatic
<div class="hide">
## In Flashduty
----
You can get an integration push URL through the following 2 methods, choose one of them.
### Use dedicated integration
When you don't need to route alerts to different channels, choose this method, it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to Flashduty console, select **Channels**, enter the details page of a channel
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Select **Huawei Cloud APM** integration, click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use. Done.
-</details>
+</Accordion>
+</AccordionGroup>
### Use shared integration
When you need to route alerts to different channels based on alert payload information, this method is preferred.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to Flashduty console, select **Integration Center=>Alerts** to enter the integration selection page
+ 1. Go to Flashduty console, select **Integration Center → Alerts** to enter the integration selection page
2. Select **Huawei Cloud APM** integration:
- **Integration Name**: Define a name for the current integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done.
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Huawei Cloud
----
<div class="md-block">
-## I. Huawei Cloud APM Alert Push Configuration
### Create Flashduty Alert Channel
@@ -55,15 +55,15 @@ When you need to route alerts to different channels based on alert payload infor
2. Select `Topic Management=>Topics` from the left navigation bar
3. Click `Create Topic`, enter `Flashduty` as the topic name in the edit page and confirm
-<img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-1.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-1.png" alt="drawing" width="500"/>
4. Return to the topic list and click `Add Subscription` in the newly created Flashduty topic
-<img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-2.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-2.png" alt="drawing" width="500"/>
5. In the edit page, select `HTTPS` as the protocol, enter the **push URL** as the subscription endpoint and confirm
-<img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-3.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-3.png" alt="drawing" width="500"/>
6. After adding, check if the subscription status shows **Confirmed** in the subscription list
@@ -91,7 +91,7 @@ When you need to route alerts to different channels based on alert payload infor
**Note:** The current integration configuration only supports application monitoring alerts, and does not fully support front-end monitoring, link tracking, and App monitoring alerts.
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/huawei-ces.mdx b/en/on-call/integration/alert-integration/alert-sources/huawei-ces.mdx
index 4419112b..ca955e35 100644
--- a/en/on-call/integration/alert-integration/alert-sources/huawei-ces.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/huawei-ces.mdx
@@ -1,5 +1,6 @@
---
title: "Huawei Cloud CES Integration"
+sidebarTitle: "Huawei Cloud CES"
description: "Sync Huawei Cloud CES alerts to Flashduty via webhook to achieve automated alert noise reduction"
---
@@ -8,42 +9,42 @@ Sync Huawei Cloud CES alerts to Flashduty via webhook to achieve automated alert
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alerts to different channels. It's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Huawei Cloud CES** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alerts** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alerts** to enter the integration selection page
2. Select **Huawei Cloud CES** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Huawei Cloud CES
----
<div class="md-block">
1. Log in to your Huawei Cloud console, search for `Cloud Eye Service` product, and enter its console
@@ -51,20 +52,20 @@ Choose this method when you need to route alerts to different channels based on
3. Select `HTTPS` as protocol, enter `flashduty` as name, and fill in the integration URL (enter integration name on current page, URL will be generated after saving)
4. Click `OK` button to complete notification object creation
-<img src="https://download.flashcat.cloud/flashduty/doc/en/hw/hw-1.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/hw/hw-1.png" alt="drawing" width="500"/>
5. Go to `Alarm-Alarm Notifications-Notification Groups` page, click `Create Notification Group` button
6. Enter `Flashduty` as group name, check the `flashduty` notification object created earlier
7. Click `OK` button to complete notification group creation
-<img src="https://download.flashcat.cloud/flashduty/doc/en/hw/hw-2.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/hw/hw-2.png" alt="drawing" width="500"/>
-Note: When creating a notification group, Huawei Cloud will send a request to Flashduty to verify the push URL. Check the notification group's object list - alerts will only be pushed normally when the notification object status is `Confirmed`
+ Note: When creating a notification group, Huawei Cloud will send a request to Flashduty to verify the push URL. Check the notification group's object list - alerts will only be pushed normally when the notification object status is `Confirmed`
8. Go to `Alarm-Alarm Rules` page, edit existing alarm rules or create new ones to open the `Alarm Rule Details` page
9. Select `Flashduty` as the notification group, check both `Alarm Triggered` and `Cleared` conditions. Click `OK` button to save changes
-<img src="https://download.flashcat.cloud/flashduty/doc/en/hw/hw-3.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/hw/hw-3.png" alt="drawing" width="500"/>
10. Return to Flashduty console's integration list page. If the latest event time is displayed, the configuration is successful and events are being received
11. Done
@@ -72,7 +73,6 @@ Note: When creating a notification group, Huawei Cloud will send a request to Fl
</div>
## Status Mapping
----
<div class="md-block">
Huawei Cloud CES to Flashduty alert severity mapping:
diff --git a/en/on-call/integration/alert-integration/alert-sources/huawei-lts.mdx b/en/on-call/integration/alert-integration/alert-sources/huawei-lts.mdx
index ccf21cd4..d6f4fdae 100644
--- a/en/on-call/integration/alert-integration/alert-sources/huawei-lts.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/huawei-lts.mdx
@@ -1,5 +1,6 @@
---
title: "Huawei Cloud LTS Alert Events"
+sidebarTitle: "Huawei Cloud LTS"
description: "Sync Huawei Cloud Log Tank Service (LTS) alert events to Flashduty via webhook for automated alert noise reduction."
---
@@ -8,61 +9,60 @@ Sync Huawei Cloud Log Tank Service (LTS) alert events to Flashduty via webhook f
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Huawei Cloud LTS** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're Done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Huawei Cloud LTS** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Huawei Cloud
----
<div class="md-block">
-## I. Huawei Cloud LTS Alert Push Configuration
### Step 1: Create Flashduty Alert Channel
1. Log in to your Huawei Cloud Console, search for `SMN` (Simple Message Notification) service and enter its console
2. Select `Topic Management=>Topics` from the left navigation bar
3. Click `Create Topic`, enter `Flashduty` as the topic name in the edit page and confirm
-<img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-1.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-1.png" alt="drawing" width="500"/>
4. Return to the topic list and click `Add Subscription` in the newly created Flashduty topic
-<img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-2.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-2.png" alt="drawing" width="500"/>
5. In the edit page, select `HTTPS` as the protocol, enter the **push URL** as the subscription endpoint and confirm
-<img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-3.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-3.png" alt="drawing" width="500"/>
6. After adding, check if the subscription status shows **Confirmed** in the subscription list
@@ -73,13 +73,13 @@ Choose this option when you need to route alerts to different channels based on
1. Log in to your Huawei Cloud Console, search for `LTS` (Log Tank Service) and enter its console
2. Select `Log Alert=>Alert Action Rules=>Message Templates` from the left navigation bar and click `Create`
-<img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-5.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-5.png" alt="drawing" width="500"/>
3. In the template edit page, enter **Flashduty** as the name, select `English` as the message header language
4. Select `HTTP/HTTPS` as notification type and `JSON` as data type
5. Click `Confirm` to save
-<img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-6.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/hw/lts-6.png" alt="drawing" width="500"/>
6. Return to the `Alert Action Rules` list and click `Create`
7. Enter **Flashduty** as the rule name, select the previously created **Flashduty** topic and template
@@ -99,7 +99,7 @@ Choose this option when you need to route alerts to different channels based on
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/hund.mdx b/en/on-call/integration/alert-integration/alert-sources/hund.mdx
index 288e2a73..31460dee 100644
--- a/en/on-call/integration/alert-integration/alert-sources/hund.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/hund.mdx
@@ -1,5 +1,6 @@
---
title: "Hund alert integration"
+sidebarTitle: "Hund"
description: "Use Hund status page webhooks to send status page issues and component availability changes to Flashduty On-call."
keywords: ["alert integration", "Hund", "status page", "webhook", "component status"]
---
@@ -12,7 +13,6 @@ Use Hund status page outgoing webhooks (version 2) to send changes on your statu
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -33,7 +33,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Hund
----
<Steps>
<Step title="Enable the Webhooks notifier">
@@ -67,7 +66,6 @@ You can also verify with a real event: create an issue on the status page and an
</Steps>
## Payload
----
Hund sends JSON. `event.kind` is the notification type:
@@ -108,7 +106,6 @@ Fields used for component status (`degraded`, `restored`):
Every alert also carries the labels `source=hund` and `event` (the notification type).
## Alert Key
----
- Issues: the issue ID. Every notification from creation through updates to resolution lands on the same alert
- Components: the component ID. Hund creates a new status object on every state change (one ID for degraded, another for restored), so component alerts are keyed on the component itself, and `degraded` through `restored` for one component lands on the same alert
@@ -116,7 +113,6 @@ Every alert also carries the labels `source=hund` and `event` (the notification
Issue alerts and component alerts are independent. An issue can affect several components, which may each have their own alert; use the channel's [alert grouping](/en/on-call/channel/noise-reduction) to merge them into one incident. Changing an issue title or a component name does not change the Alert Key.
## Status and severity
----
| Hund notification | Flashduty status or severity |
| :--- | :--- |
@@ -132,7 +128,6 @@ Issue alerts and component alerts are independent. An issue can affect several c
An update that carries a `state_override` takes precedence; otherwise the issue's own value is used.
## FAQ
----
<AccordionGroup>
<Accordion title="Issue updates do not reach Flashduty. Why?">
@@ -155,7 +150,6 @@ There is one issue alert, keyed by the issue ID. Each component's `degraded` and
</AccordionGroup>
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: the payload has no `event.eventable.id` (issues) or `event.contexts.component.id` (component status)
- **An issue alert does not recover**: confirm the issue is marked resolved or ended in Hund and that the subscription includes the matching notification
diff --git a/en/on-call/integration/alert-integration/alert-sources/hyperdx.mdx b/en/on-call/integration/alert-integration/alert-sources/hyperdx.mdx
index 9b029e69..60e27d6c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/hyperdx.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/hyperdx.mdx
@@ -1,5 +1,6 @@
---
title: "HyperDX alert integration"
+sidebarTitle: "HyperDX"
description: "Send HyperDX (ClickStack) search alert and chart alert trigger and recovery notifications to Flashduty On-call through a Generic webhook with a fixed body template."
keywords: ["alert integration", "HyperDX", "ClickStack", "ClickHouse", "Webhook"]
---
@@ -9,7 +10,6 @@ Use a Generic webhook in HyperDX (the UI layer of ClickStack) to send search ale
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure HyperDX
----
Both open-source HyperDX and managed ClickStack in ClickHouse Cloud support Generic webhooks. A self-hosted HyperDX must be able to reach the public domain of the Flashduty push URL.
@@ -43,18 +42,18 @@ Both open-source HyperDX and managed ClickStack in ClickHouse Cloud support Gene
4. Leave **Webhook Headers** empty. HyperDX sends `Content-Type: application/json` by default
5. Paste the following template into **Webhook Body**
-```json
-{
- "event_id": "{{eventId}}",
- "state": "{{state}}",
- "severity": "Warning",
- "title": "{{title}}",
- "body": "{{body}}",
- "link": "{{link}}",
- "alert_id": "{{alertId}}",
- "group": "{{groupKey}}"
-}
-```
+ ```json
+ {
+ "event_id": "{{eventId}}",
+ "state": "{{state}}",
+ "severity": "Warning",
+ "title": "{{title}}",
+ "body": "{{body}}",
+ "link": "{{link}}",
+ "alert_id": "{{alertId}}",
+ "group": "{{groupKey}}"
+ }
+ ```
6. Click **Test Webhook** to confirm the push URL is reachable, then click **Add Webhook** to save
@@ -94,7 +93,6 @@ To verify the full flow, make the alert condition actually match and confirm an
</Steps>
## Alert Key
----
Flashduty uses `event_id` (`{{eventId}}`) as the Alert Key directly. HyperDX's webhook template variable documentation states that `{{eventId}}` stays the same for one alert, group and webhook from trigger to recovery, and HyperDX's own incident.io template uses it as the deduplication key.
@@ -104,7 +102,6 @@ Flashduty uses `event_id` (`{{eventId}}`) as the Alert Key directly. HyperDX's w
- Changing the alert's **grouped by**, or deleting and recreating the webhook, produces a new `event_id`. Flashduty alerts triggered before the change receive no recovery and must be closed manually
## Status and severity
----
Flashduty uses `state` to decide between trigger and recovery, and `severity` to set the alert severity.
@@ -124,7 +121,6 @@ Flashduty uses `state` to decide between trigger and recovery, and `severity` to
`severity` is case-insensitive. HyperDX sends a recovery notification only when it previously sent a trigger notification for the alert. While an alert is silenced, HyperDX sends neither trigger nor recovery notifications.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -137,7 +133,6 @@ Flashduty uses `state` to decide between trigger and recovery, and `severity` to
The alert title comes from `{{title}}` with the 🚨 and ✅ prefixes added by HyperDX removed. The alert description comes from `{{body}}`.
## Troubleshooting
----
- **Flashduty returns a parameter error**: Make sure the webhook body matches the template above, `event_id` and `state` are not empty, and string variables keep their surrounding double quotes
- **Test Webhook succeeds but no alert appears**: This is expected. Test data does not create alerts
diff --git a/en/on-call/integration/alert-integration/alert-sources/hyperping.mdx b/en/on-call/integration/alert-integration/alert-sources/hyperping.mdx
index 925685b0..eafdbc9c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/hyperping.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/hyperping.mdx
@@ -1,5 +1,6 @@
---
title: "Hyperping alert integration"
+sidebarTitle: "Hyperping"
description: "Send Hyperping monitor down and recovery notifications to Flashduty On-call through the Webhooks integration."
keywords: ["alert integration", "Hyperping", "Uptime", "webhook", "check.down", "check.up"]
---
@@ -9,7 +10,6 @@ Use Hyperping's Webhooks integration to send monitor down (`check.down`) and rec
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Hyperping
----
<Steps>
<Step title="Connect the Webhooks integration">
@@ -53,7 +52,6 @@ Hyperping recommends testing with a monitor that returns an error, such as a pag
The Webhook card on the Integrations page is marked Pro and needs the Pro plan or higher; during the free trial, clicking it redirects to the Billing page. If you cannot open the configuration, upgrade your plan first.
## Payload
----
Hyperping POSTs JSON. Flashduty parses it directly, with no template to configure:
@@ -69,14 +67,12 @@ Hyperping POSTs JSON. Flashduty parses it directly, with no template to configur
The alert title is the monitored URL; when the URL is empty it is `Hyperping monitor <monitor ID>`.
## Alert Key
----
The Alert Key is `check.monitorUuid`. In the Hyperping documentation, the `check.down` and `check.up` samples carry the same `monitorUuid`, so a monitor's down and recovery notifications land on one alert, and different monitors produce different alerts. Changing the URL, status code, time, or check location does not change the Alert Key.
If a request has no `check.monitorUuid`, Flashduty returns a parameter error, because the recovery could not be tied to its alert reliably. A notification whose `event` is neither `check.down` nor `check.up` (for example an event type Hyperping adds later) is ignored and acknowledged, and creates no alert.
## Status and severity
----
Hyperping notifications carry no severity, so a down is treated as Critical.
@@ -88,7 +84,6 @@ Hyperping notifications carry no severity, so a down is treated as Critical.
A request whose `event` is empty or any other value is rejected, so that a request of unknown state never enters the wrong alert lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="Does the webhook test button create an alert?">
@@ -105,7 +100,6 @@ No. Notifications for the same monitor carry the same `monitorUuid` and merge in
</AccordionGroup>
## Troubleshooting
----
- **Hyperping shows a failed delivery**: confirm the webhook URL is the full push URL and includes `integration_key`
- **Flashduty returns a parameter error**: confirm the request is a Hyperping JSON notification and that `event` and `check.monitorUuid` are not empty
diff --git a/en/on-call/integration/alert-integration/alert-sources/ibm-qradar.mdx b/en/on-call/integration/alert-integration/alert-sources/ibm-qradar.mdx
index 8c49fd87..02522216 100644
--- a/en/on-call/integration/alert-integration/alert-sources/ibm-qradar.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/ibm-qradar.mdx
@@ -1,5 +1,6 @@
---
title: "IBM QRadar alert integration"
+sidebarTitle: "IBM QRadar"
description: "IBM QRadar rule responses can send email. Use Flashduty's email integration to receive QRadar alerts by rules."
keywords: ["alert integration", "IBM QRadar", "QRadar", "SIEM", "email", "security alerts"]
---
@@ -9,7 +10,6 @@ An IBM QRadar rule can run an email response, and the subject and body of that e
<div className="hide">
## In Flashduty On-call
----
Get the integration email address in either of the two ways below. **In both cases choose the Email integration type**, not IBM QRadar.
@@ -30,7 +30,6 @@ Get the integration email address in either of the two ways below. **In both cas
</div>
## Configure in QRadar
----
A rule's email response uses the event or flow templates in `alert-config.xml`. QRadar's documentation describes how to edit them: [Configuring event and flow custom email notifications](https://www.ibm.com/docs/en/qsip/7.4.0?topic=notifications-configuring-event-flow-custom-email). Below is the minimal change that makes the email fit a Flashduty rule.
@@ -93,7 +92,6 @@ In the response of each QRadar rule that should notify, enable the email notific
</Steps>
## Configure the push rule in Flashduty
----
QRadar rule emails have no recovery email; one email corresponds to one rule firing. One trigger rule is therefore enough, and the Alert Key is extracted from the email title as "rule name + source IP".
@@ -111,7 +109,6 @@ Regex: /^\[QRadar\] (.+)$/
The default rule discards mail so that emails without the `[QRadar]` prefix (for example system notifications) do not create alerts.
## Recovery and deduplication
----
- A QRadar rule response does not send another email when the condition clears, so Flashduty never closes these alerts on its own. Enable the [auto-resolve timeout](/en/on-call/channel/create-edit) on the channel that receives this integration (24 hours suggested), or close alerts manually once handled.
- When the same rule fires again for the same source IP, the title and Alert Key are the same, so Flashduty updates the existing alert. To distinguish by destination IP or user, add the matching parameter (such as `${DestinationIP}` or `${UserName}`) to `<subject>`.
@@ -119,7 +116,6 @@ The default rule discards mail so that emails without the `[QRadar]` prefix (for
- An email body over 128 KB is truncated and attachments are dropped; see the [email integration](/en/on-call/integration/alert-integration/alert-sources/email).
## Troubleshooting
----
- **No alerts arrive**: confirm **Deploy Full Configuration** was run, the rule's email response uses the new template, and the QRadar mail server can deliver to the Flashduty email address
- **Every alert is discarded**: the email title does not start with `[QRadar] `, which means the rule is not using the new template; check the title of a received email
diff --git a/en/on-call/integration/alert-integration/alert-sources/icinga.mdx b/en/on-call/integration/alert-integration/alert-sources/icinga.mdx
index b4eeb109..bc4216e3 100644
--- a/en/on-call/integration/alert-integration/alert-sources/icinga.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/icinga.mdx
@@ -1,5 +1,6 @@
---
title: "Icinga 2 alert integration"
+sidebarTitle: "Icinga 2"
description: "Send Icinga 2 host and service notifications to Flashduty On-call through a notification command. Alerts close automatically when the problem recovers."
keywords: ["alert integration", "Icinga", "Icinga 2", "NotificationCommand", "notification command", "Nagios"]
---
@@ -9,7 +10,6 @@ Icinga 2 has no built-in webhook notification method. This integration provides
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Icinga 2
----
The configuration below works with Icinga 2.11 and later. The notification command only needs `curl`, installed on the Icinga 2 node that runs notifications, and that node must be able to reach the Flashduty push URL.
@@ -131,7 +130,6 @@ You can also choose **Send custom notification** on the service page to check co
<Warning>Icinga 2 runs the notification command once for each user of a notification. If `users` or `user_groups` contains several users, the same notification is pushed several times. These pushes land on the same alert but create duplicate events. So configure only the `flashduty` user for the Flashduty notifications.</Warning>
## Alert Key
----
Flashduty computes the Alert Key from the host name `host_name` and the service name `service_name`. Host notifications use an empty service name. Icinga 2 names a service object `host name!service name`, and a service name is unique within its host, so problem and recovery notifications for the same host or service land on the same alert.
@@ -140,7 +138,6 @@ Changes to the state, plugin output, display names, host address, or groups do n
Flashduty rejects a request that lacks `host_name` or `notification_type`, a host notification that lacks `host_state`, and a service notification that lacks `service_state`.
## Alert lifecycle
----
Icinga 2 sends a recovery notification only after it has sent a problem notification. An alert opened from an acknowledgement, downtime, flapping, or custom notification might never get a recovery notification to close it. So only problem notifications open alerts, and Flashduty handles each notification type `notification_type` as follows:
@@ -157,7 +154,6 @@ While a problem lasts, Icinga 2 resends the `PROBLEM` notification every 30 minu
The `apply Notification` rules above set no `types` or `states`, so Icinga 2 sends every notification type. When a downtime is removed, Icinga 2 sends the type `DOWNTIMECANCELLED`. Ignored notifications get a success response.
## Severity
----
Severity comes from the current state: `service_state` for service notifications and `host_state` for host notifications.
@@ -173,14 +169,12 @@ Severity comes from the current state: `service_state` for service notifications
A recovery event takes its severity from the state before the recovery (`service_last_state` or `host_last_state`).
## Alert content
----
- **Title**: `<service display name> on <host display name>` for service notifications, `Host <host display name>` for host notifications. Object names are used when no display name is set
- **Description**: the plugin output `service_output` or `host_output`
- **Labels**: `host`, `resource` (host name), `service`, `check` (service name, service notifications only), `notification_type`, `state`, `host_display_name`, `host_address`, `host_groups`, `service_display_name` and `service_groups` (service notifications only). Multiple groups are joined with commas
## Troubleshooting
----
- **No notification is sent**: check the object's notification history in Icinga Web, confirm the `flashduty` notification objects exist (run `icinga2 daemon -C --dump-objects` to write the object cache, then `icinga2 object list --type Notification --name '*flashduty'`), and confirm notifications are not disabled on the host or service
- **The Icinga 2 log shows `exit code 22`**: `curl` got an HTTP 4xx/5xx response. Confirm that `vars.flashduty_push_url` is the full push URL and includes `integration_key`
diff --git a/en/on-call/integration/alert-integration/alert-sources/image-upload.mdx b/en/on-call/integration/alert-integration/alert-sources/image-upload.mdx
index f289d102..3deac634 100644
--- a/en/on-call/integration/alert-integration/alert-sources/image-upload.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/image-upload.mdx
@@ -4,7 +4,7 @@ description: "Upload an image via the image upload API to obtain an image_key, t
keywords: ["image upload", "image_key", "standard alert", "alert image", "integration_key", "Flashduty"]
---
-## 1. Overview
+## Overview
When reporting an alert, you can attach images via the `images` field of a [Standard Alert](/en/on-call/integration/alert-integration/alert-sources/standard-alert) to display alert-related screenshots in the frontend and in Feishu/DingTalk app notifications. The `src` of each image in `images` accepts two kinds of values:
@@ -21,7 +21,7 @@ When an image has no public URL, call the image upload API first to upload it an
Image upload and standard alert reporting share the same integration key (`integration_key`). Use the push key you obtained from a [Standard Alert](/en/on-call/integration/alert-integration/alert-sources/standard-alert) (or any other) integration — no separate provisioning is required.
</Note>
-## 2. API Specification
+## API Specification
### Request Method
@@ -111,7 +111,7 @@ To keep the service stable, image upload is rate-limited per account:
Exceeding the limit returns `RequestTooFrequently` (HTTP 429).
-## 3. Example
+## Example
Request:
@@ -131,7 +131,7 @@ Success response:
}
```
-## 4. Referencing the Image in an Alert
+## Referencing the Image in an Alert
Once you have the `image_key`, put it into the `src` field of an image in the `images` array when reporting a [Standard Alert](/en/on-call/integration/alert-integration/alert-sources/standard-alert):
@@ -158,7 +158,7 @@ For the full field definitions of the `images` array and the `image` struct, see
- An uploaded image is stored temporarily at first and is promoted to long-term storage only after it is referenced by an alert. Use the `image_key` in an alert report promptly after uploading.
</Note>
-## 5. FAQ
+## FAQ
1. **What happens if I upload the same image twice?**
diff --git a/en/on-call/integration/alert-integration/alert-sources/imperva.mdx b/en/on-call/integration/alert-integration/alert-sources/imperva.mdx
index 344afd8e..5ece534b 100644
--- a/en/on-call/integration/alert-integration/alert-sources/imperva.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/imperva.mdx
@@ -1,5 +1,6 @@
---
title: "Imperva alert integration"
+sidebarTitle: "Imperva"
description: "Send Imperva DDoS attack start and stop, BGP connection down and up, and connection performance events to Flashduty On-call through a Webhook Connection."
keywords: ["alert integration", "Imperva", "Thales", "DDoS", "BGP", "webhook", "network protection"]
---
@@ -9,7 +10,6 @@ The Imperva (Thales) Cloud Application and Network Security console has Webhook
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Imperva
----
<Steps>
<Step title="Add a Webhook Connection">
@@ -61,7 +60,6 @@ Click **Test Webhook** on the connection. Flashduty creates an Info alert titled
Imperva's webhook payload has a fixed format and cannot be templated. Imperva may deliver the same event more than once; Flashduty merges repeats under the same Alert Key, so no duplicate alerts appear.
## Events and recovery
----
| Notification subtype | Start event | End event | Flashduty severity |
| :--- | :--- | :--- | :--- |
@@ -80,7 +78,6 @@ Imperva's webhook payload has a fixed format and cannot be templated. Imperva ma
- Other notification types (account, site, billing, subscription, policy changes, range status changes) create no alert; Flashduty acknowledges them and returns success
## Alert Key
----
The Alert Key is computed from the event family, the Imperva account ID, and the object identity. Start and end events read the same fields:
@@ -95,7 +92,6 @@ The Alert Key is computed from the event family, the Imperva account ID, and the
The title, event time, account name in the payload, and the webhook ID do not take part. A request without `event_type`, or without the object identity of its family, is rejected with an error that names the missing field.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -111,7 +107,6 @@ The title, event time, account name in the payload, and the webhook ID do not ta
The alert title comes from `event_title` and the description from `event_details.event_body`.
## Troubleshooting
----
- **Test Webhook fails**: Imperva requires the receiver to answer 200 or 201. Check that the push URL is complete, the `integration_key` is valid, and the integration type is Imperva
- **No alerts arrive**: check that the notification policy's Recipients use this Webhook Connection and that the event type is in the table above. Event types outside the table create no alert
diff --git a/en/on-call/integration/alert-integration/alert-sources/infisical.mdx b/en/on-call/integration/alert-integration/alert-sources/infisical.mdx
index b30ca3ee..9b760931 100644
--- a/en/on-call/integration/alert-integration/alert-sources/infisical.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/infisical.mdx
@@ -1,5 +1,6 @@
---
title: "Infisical alert integration"
+sidebarTitle: "Infisical"
description: "Send Infisical secret rotation failures and honey token triggers to Flashduty On-call through a project webhook."
keywords: ["alert integration", "Infisical", "secrets management", "secret rotation", "honey token", "webhook"]
---
@@ -11,7 +12,6 @@ Secret modifications (`secrets.modified`), change requests, and access requests
<div className="hide">
## In Flashduty On-call
----
You can get the integration Push URL in either of the following two ways.
@@ -32,7 +32,6 @@ You can get the integration Push URL in either of the following two ways.
</div>
## Configure Infisical
----
<Steps>
<Step title="Create a webhook">
@@ -61,7 +60,6 @@ In the channel that receives these alerts, turn on [auto-close timeout](/en/on-c
</Steps>
## Alert Key
----
The Infisical request body has no alert ID, so Flashduty uses the monitored object itself as the Alert Key:
@@ -71,7 +69,6 @@ The Infisical request body has no alert ID, so Flashduty uses the monitored obje
Repeated failures of one rotation (including manual runs and retries), or one honey token triggered several times from different IPs, merge into the same alert. A change in the error message, project name, source IP, or timestamp does not change the Alert Key. A request missing `project.projectId`, `project.environment`, `project.rotationName`, or `honeyToken.name` is rejected.
## Status and severity
----
| Infisical event | Flashduty severity | Notes |
| :--- | :--- | :--- |
@@ -83,7 +80,6 @@ Repeated failures of one rotation (including manual runs and retries), or one ho
Neither alert has a recovery event.
## Troubleshooting
----
- **Infisical reports a failed webhook**: check that the Push URL is complete and includes `integration_key`, and that the webhook **Type** is **General** (the Slack and Microsoft Teams types send their own message formats)
- **No alert after a rotation failure**: check that the webhook's **Environment** matches the rotation's environment, that **Secret Path** matches the rotation's folder (for example `/**`), and that **Secret Rotation Failed** is selected
diff --git a/en/on-call/integration/alert-integration/alert-sources/influxdata.mdx b/en/on-call/integration/alert-integration/alert-sources/influxdata.mdx
index 775914c9..9daf95f76 100644
--- a/en/on-call/integration/alert-integration/alert-sources/influxdata.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/influxdata.mdx
@@ -1,5 +1,6 @@
---
title: "InfluxData Alert Integration"
+sidebarTitle: "InfluxData"
description: "Integrate InfluxData alerts with Flashduty On-call through a webhook for automated routing, deduplication, and noise reduction."
keywords: ["alert integration", "InfluxData", "webhook", "alert routing", "noise reduction"]
---
@@ -9,48 +10,48 @@ Sync Influxdata alert events to Flashduty via webhook to achieve automated alert
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Influxdata** integration, click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event payload.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Influxdata** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Influxdata
----
Supports Influxdata versions 1.x ~ 2.x, with different configurations for each version as detailed below.
- [Version 2.x](#v2)
- [Version 1.x](#v1)
-## I. Influxdata Configuration
+## Influxdata Configuration
<span id="v2"></span>
@@ -69,7 +70,7 @@ Supports Influxdata versions 1.x ~ 2.x, with different configurations for each v
3. Configure `About` and `Conditions` as needed.
4. Select `Flashduty` created in Step 1 for `Message`.
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/influxdb-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/influxdb-2.png" />
5. Done.
@@ -82,7 +83,7 @@ Supports Influxdata versions 1.x ~ 2.x, with different configurations for each v
2. Click on the alert rule you want to synchronize events for, enter the `Alert Rule Builder` page to start editing the rule
3. In the `Alert Handlers` section, select `Add Another Handler`, choose `post` type, and enter the integration push URL in `HTTP endpoint` as shown below:
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/influxdb-alert-rule.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/influxdb-alert-rule.png" />
4. Click the `Save Rule` button to save. Wait for event triggering. If the latest event time is displayed in the integration list, the configuration is successful and events are being received
5. Done
@@ -93,7 +94,7 @@ Supports Influxdata versions 1.x ~ 2.x, with different configurations for each v
The `post` handler in Chronograf is Kapacitor's `post` event handler. When using Kapacitor directly, add `.post('<push URL>')` to the `alert()` node of the TICKscript, or use a topic handler (`kind: post`, with the push URL in `options.url`). For the full steps, see [Kapacitor Alert Integration](/en/on-call/integration/alert-integration/alert-sources/kapacitor).
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/insightidr.mdx b/en/on-call/integration/alert-integration/alert-sources/insightidr.mdx
index 78b5f0cd..bb6bb0da 100644
--- a/en/on-call/integration/alert-integration/alert-sources/insightidr.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/insightidr.mdx
@@ -1,5 +1,6 @@
---
title: "Rapid7 InsightIDR alert integration"
+sidebarTitle: "Rapid7 InsightIDR"
description: "Send investigations generated by Rapid7 InsightIDR to Flashduty On-call through a Universal Webhook data exporter."
keywords: ["alert integration", "Rapid7", "InsightIDR", "Universal Webhook", "SIEM", "security investigation"]
---
@@ -11,7 +12,6 @@ InsightIDR only sends "investigation created". It does not send updates or closu
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the push URL in either of the following ways.
</div>
## In Rapid7 InsightIDR
----
<Steps>
<Step title="Add a Universal Webhook data exporter">
@@ -57,7 +56,6 @@ After that, every investigation InsightIDR generates is pushed as one alert.
</Steps>
## Event types
----
| `X-Rapid7-Event` | Effect in Flashduty |
| :--- | :--- |
@@ -66,17 +64,14 @@ After that, every investigation InsightIDR generates is pushed as one alert.
| Any other value | The request is rejected with a parameter error |
## Alert Key
----
Flashduty uses `investigationId`, the fixed ID InsightIDR assigns to each investigation, as the Alert Key. Changes to the title, description, or time do not change it. A request without `investigationId` is rejected.
## Status and severity
----
The InsightIDR payload carries no severity, so every investigation is treated as Warning. To separate levels, adjust them in the integration's **Alert processing** by title or label.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -89,12 +84,10 @@ The InsightIDR payload carries no severity, so every investigation is treated as
User emails and AD distinguished names (`distinguishedName`) are not written to labels.
## About signatures
----
InsightIDR signs the request body with the Secret (`X-Rapid7-Signature`). Flashduty does not verify it, so the `integration_key` in the push URL is the only credential; keep it private. You can also add custom headers on the exporter; Flashduty does not require them.
## Troubleshooting
----
- **Flashduty receives nothing**: the collector is hosted by you. Confirm it can reach the internet and that the URL is complete and includes `integration_key`
- **Parameter error**: a missing `investigationId` means the request is not an investigation; an unsupported event means `X-Rapid7-Event` is neither `idr_investigation_created` nor `test`
diff --git a/en/on-call/integration/alert-integration/alert-sources/instana.mdx b/en/on-call/integration/alert-integration/alert-sources/instana.mdx
index 8621dba7..66d6526c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/instana.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/instana.mdx
@@ -1,5 +1,6 @@
---
title: "IBM Instana alert integration"
+sidebarTitle: "IBM Instana"
description: "Send IBM Instana issues, incidents, and changes to Flashduty On-call through a Generic webhook alert channel."
keywords: ["alert integration", "Instana", "IBM Instana", "webhook", "Generic webhook", "alert channel"]
---
@@ -9,7 +10,6 @@ Use an IBM Instana Generic webhook alert channel to send Instana issues, inciden
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Instana
----
You need permission to configure alert channels and alerts in Instana. First create an alert channel that points to Flashduty, then select that channel in your alert configurations.
@@ -52,15 +51,15 @@ You need permission to configure alert channels and alerts in Instana. First cre
1. Click **Settings** → **Alerts** → **New alert** and enter an alert name
2. In the **Events** drop-down, select **Alert on event type(s)**, then turn on the event types to send:
-| Instana event type | What is sent | Effect in Flashduty |
-| :--- | :--- | :--- |
-| Incidents | `type` is `incident`, with state `OPEN` / `CLOSED` | Triggers when opened, recovers when closed |
-| Critical issues / Warning issues | `type` is `issue`, with state `OPEN` / `CLOSED` | Triggers when opened, recovers when closed |
-| Monitoring issues | `type` is `monitoringIssue`, with state `OPEN` / `CLOSED` | Triggers when opened, recovers when closed |
-| Changes | `type` is `change`, no state | Each delivery creates an Info alert that does not recover automatically |
-| Online / Offline | `type` is `presence`, no state | Each delivery creates an Info alert that does not recover automatically |
+ | Instana event type | What is sent | Effect in Flashduty |
+ | :--- | :--- | :--- |
+ | Incidents | `type` is `incident`, with state `OPEN` / `CLOSED` | Triggers when opened, recovers when closed |
+ | Critical issues / Warning issues | `type` is `issue`, with state `OPEN` / `CLOSED` | Triggers when opened, recovers when closed |
+ | Monitoring issues | `type` is `monitoringIssue`, with state `OPEN` / `CLOSED` | Triggers when opened, recovers when closed |
+ | Changes | `type` is `change`, no state | Each delivery creates an Info alert that does not recover automatically |
+ | Online / Offline | `type` is `presence`, no state | Each delivery creates an Info alert that does not recover automatically |
-Changes and online/offline events are frequent and do not recover automatically. In most cases, turning on **Incidents**, **Critical issues**, and **Warning issues** is enough.
+ Changes and online/offline events are frequent and do not recover automatically. In most cases, turning on **Incidents**, **Critical issues**, and **Warning issues** is enough.
3. Under **Scope**, choose the required **Apply on** range: an application perspective, a Dynamic Focus query (Selected entities only), or All available entities
4. Under **Alerting**, click **Add alert channels** and select the channel you created in the previous step
@@ -75,11 +74,11 @@ Smart Alerts for applications, websites, and synthetic tests select their alert
1. Trigger an Instana issue and confirm that Flashduty receives an active alert. On a host running the Instana agent, you can send a critical event with a duration through the agent's Event SDK:
-```bash
-curl -X POST http://localhost:42699/com.instana.plugin.generic.event \
- -H 'Content-Type: application/json' \
- -d '{"title":"Flashduty test","text":"Flashduty test","severity":10,"duration":300000}'
-```
+ ```bash
+ curl -X POST http://localhost:42699/com.instana.plugin.generic.event \
+ -H 'Content-Type: application/json' \
+ -d '{"title":"Flashduty test","text":"Flashduty test","severity":10,"duration":300000}'
+ ```
2. Wait for the issue to close in Instana (after 5 minutes in this example) and confirm that the alert recovers
@@ -89,14 +88,12 @@ An issue raised right after you save the alert configuration may not be delivere
</Steps>
## Alert Key
----
Flashduty uses the Instana issue ID (`issue.id`) as the Alert Key. An issue or incident carries the same `issue.id` when it opens and when it closes, so the close notification recovers the alert created when it opened.
Changes to the issue title, severity, start time, or tags do not change the Alert Key. Requests without `issue.id` are rejected.
## Status and severity
----
Flashduty sets the alert severity from the issue's severity (`issue.severity`):
@@ -117,7 +114,6 @@ Flashduty sets the alert severity from the issue's severity (`issue.severity`):
Any other state value is rejected with a parameter error.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -138,7 +134,6 @@ Any other state value is rejected with a parameter error.
Instana fills fields that do not apply with `not available`. Those fields do not become labels.
## Troubleshooting
----
- **Test channel reports that the domain is not allowed**: Instana SaaS may restrict the domains alert channels can send to. Contact IBM Instana support to allow the domain of the Flashduty push URL
- **Flashduty returns a parameter error**: Make sure the URL is complete and includes `integration_key`
diff --git a/en/on-call/integration/alert-integration/alert-sources/instatus.mdx b/en/on-call/integration/alert-integration/alert-sources/instatus.mdx
index 85a5ac4f..3f47f6e2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/instatus.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/instatus.mdx
@@ -1,5 +1,6 @@
---
title: "Instatus alert integration"
+sidebarTitle: "Instatus"
description: "Subscribe to an Instatus status page by webhook and send Instatus incidents and component outages to Flashduty On-call."
keywords: ["alert integration", "Instatus", "status page", "third-party service status", "webhook"]
---
@@ -9,7 +10,6 @@ Use an Instatus webhook subscriber to send changes on a status page to Flashduty
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Add a webhook subscriber in Instatus
----
<Steps>
<Step title="Open the webhook subscribers">
@@ -67,7 +66,6 @@ If you publish an incident or update without notifying subscribers, Instatus sen
</Steps>
## Payload
----
Instatus sends one JSON payload each time an incident is added or updated, a component changes status, or a maintenance is added or updated. Flashduty handles the first two:
@@ -98,7 +96,6 @@ Instatus sends one JSON payload each time an incident is added or updated, a com
Component alert titles look like `Website: major outage`. Every alert also carries the label `source=instatus`, plus `page_url` and `page_status`. The unsubscribe link in the payload (`meta.unsubscribe`) contains a subscription credential, so Flashduty does not write it to the alert.
## Alert Key
----
Flashduty builds the Alert Key per payload kind:
@@ -110,7 +107,6 @@ Incident alerts and component alerts are independent. One outage usually produce
Renaming an incident or component, or changing the impact, does not change the Alert Key. When the severity rises (for example a component going from `PARTIALOUTAGE` to `MAJOROUTAGE`), Flashduty opens a new alert at the higher severity and keeps the earlier alert open; the recovery delivery closes both. After an alert recovers, a new outage of the same component opens a new alert.
## Status and severity
----
**Component status**
@@ -144,7 +140,6 @@ An incident with no affected component falls back to the same mapping applied to
Scheduled maintenance (`maintenance` payloads with the status `NOTSTARTEDYET`, `INPROGRESS`, or `COMPLETED`) is planned change. Flashduty returns success and creates no alert.
## FAQ
----
<AccordionGroup>
<Accordion title="Does the alert recover while the incident is MONITORING?">
@@ -173,7 +168,6 @@ In Instatus, open the subscriber under **Subscribers → Webhook** and click **U
</AccordionGroup>
## Troubleshooting
----
- **No alerts in Flashduty**: check that subscribers were notified when the incident or update was published. Scheduled maintenance and `UNDERMAINTENANCE` never create alerts
- **Flashduty returns an invalid parameter error**: check that the push URL is complete (includes `integration_key`) and that the subscriber uses the default payload format. Payloads without `page.id`, an incident ID, or a component ID are rejected
diff --git a/en/on-call/integration/alert-integration/alert-sources/intersight.mdx b/en/on-call/integration/alert-integration/alert-sources/intersight.mdx
index 3f4b41f2..9834b5e9 100644
--- a/en/on-call/integration/alert-integration/alert-sources/intersight.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/intersight.mdx
@@ -1,5 +1,6 @@
---
title: "Cisco Intersight alert integration"
+sidebarTitle: "Cisco Intersight"
description: "Send alarms from Cisco Intersight servers, storage, and hyperconverged systems to Flashduty On-call through a webhook subscription."
keywords: ["alert integration", "Cisco Intersight", "Intersight", "webhook", "UCS", "HyperFlex", "infrastructure"]
---
@@ -9,7 +10,6 @@ Cisco Intersight is Cisco's cloud platform for managing UCS, HyperFlex, and othe
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the push URL in either of the following ways.
</div>
## In Cisco Intersight
----
<Steps>
<Step title="Create the webhook">
@@ -58,7 +57,6 @@ Subscribe only to `cond.Alarm`. Flashduty rejects pushes for other object types,
</Steps>
## Event types
----
| Push | Effect in Flashduty |
| :--- | :--- |
@@ -67,12 +65,10 @@ Subscribe only to `cond.Alarm`. Flashduty rejects pushes for other object types,
| Request without an alarm (`Operation` `None`, `Event` null) | Creates a separate Info alert that never recovers |
## Alert Key
----
Flashduty uses the alarm's `Moid`, the fixed identifier Intersight assigns to each alarm, as the Alert Key. Creation, updates, and the clear of one alarm share the same Alert Key. Changes to the name, description, severity, or time do not change it, and a request without a `Moid` is rejected.
## Status and severity
----
| Intersight `Severity` | Flashduty severity |
| :--- | :--- |
@@ -82,7 +78,6 @@ Flashduty uses the alarm's `Moid`, the fixed identifier Intersight assigns to ea
| Cleared | Recovery (severity from `OrigSeverity`, Info if it has no valid value) |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -96,12 +91,10 @@ Flashduty uses the alarm's `Moid`, the fixed identifier Intersight assigns to ea
| `create_time` / `last_transition` | Alarm creation time and time of the last severity change |
## About signatures
----
Intersight signs requests with HMAC using the Secret you set (`Authorization` and `Digest` headers). Flashduty does not verify signatures, so the `integration_key` in the push URL is the only credential. Keep it private.
## Troubleshooting
----
- **Flashduty receives nothing**: confirm the webhook URL is complete and includes `integration_key`, and that Intersight can reach the public internet
- **Parameter error returned**: an object type error means the subscription covers an object other than `cond.Alarm`; a missing `Moid` means the push is not an alarm object
diff --git a/en/on-call/integration/alert-integration/alert-sources/jdcloud.mdx b/en/on-call/integration/alert-integration/alert-sources/jdcloud.mdx
index 957dedd4..27d230f3 100644
--- a/en/on-call/integration/alert-integration/alert-sources/jdcloud.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/jdcloud.mdx
@@ -1,5 +1,6 @@
---
title: "JD Cloud monitoring integration"
+sidebarTitle: "JD Cloud monitoring"
description: "Sync JD Cloud monitoring alert events to Flashduty On-call via webhook for automated alert noise reduction"
keywords: ["alert integration", "JD Cloud monitoring integration", "monitoring alerts", "data ingestion"]
---
@@ -7,7 +8,6 @@ keywords: ["alert integration", "JD Cloud monitoring integration", "monitoring a
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL through either of these two methods:
### Using private integration
@@ -15,7 +15,7 @@ You can obtain an integration push URL through either of these two methods:
Choose this method when you don't need to route alert events to different channels — it's simpler.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
@@ -30,9 +30,9 @@ Choose this method when you don't need to route alert events to different channe
Choose this method when you need to route alerts to different channels based on the alert event payload.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center => Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **JD Cloud Monitoring** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after creation, go to `Route` to configure more routing rules)
@@ -43,7 +43,6 @@ Choose this method when you need to route alerts to different channels based on
</div>
## In JD Cloud
----
<Steps>
<Step title="Create notification template">
@@ -53,29 +52,29 @@ Choose this method when you need to route alerts to different channels based on
3. Check **Alert Callback** and enter the integration push URL in the `URL` field
4. Enter the following template content in the `POST` input box:
-```json
-{
- "resource_id": "${resourceId}",
- "request_id": "${requestId}",
- "metric": "${metric}",
- "current_value": "${currentValue}",
- "times": "${times}",
- "tags": "${tags}",
- "alert_time": "${alertTime}",
- "region": "${region}",
- "threshold": "${threshold}",
- "service_code": "${serviceCode}",
- "as_group_id": "${asGroupId}",
- "unhealthy_instance": "${unhealthyInstance}",
- "rule_policy_id": "${rulePolicyId}",
- "service_code_en": "${serviceCodeEN}",
- "service_code_cn": "${serviceCodeCN}",
- "level": "${level}",
- "resource_name": "${resourceName}",
- "ip_address": "${ipAddress}",
- "status": "${status}"
-}
-```
+ ```json
+ {
+ "resource_id": "${resourceId}",
+ "request_id": "${requestId}",
+ "metric": "${metric}",
+ "current_value": "${currentValue}",
+ "times": "${times}",
+ "tags": "${tags}",
+ "alert_time": "${alertTime}",
+ "region": "${region}",
+ "threshold": "${threshold}",
+ "service_code": "${serviceCode}",
+ "as_group_id": "${asGroupId}",
+ "unhealthy_instance": "${unhealthyInstance}",
+ "rule_policy_id": "${rulePolicyId}",
+ "service_code_en": "${serviceCodeEN}",
+ "service_code_cn": "${serviceCodeCN}",
+ "level": "${level}",
+ "resource_name": "${resourceName}",
+ "ip_address": "${ipAddress}",
+ "status": "${status}"
+ }
+ ```
5. Configure other options as needed and click **Save**
@@ -97,7 +96,6 @@ Go back to the Flashduty console integration list page. If the latest event time
</Steps>
## Severity mapping
----
<div className="md-block">
JD Cloud Monitoring to Flashduty severity mapping:
diff --git a/en/on-call/integration/alert-integration/alert-sources/jfrog-xray.mdx b/en/on-call/integration/alert-integration/alert-sources/jfrog-xray.mdx
index aff34b0c..c75d1651 100644
--- a/en/on-call/integration/alert-integration/alert-sources/jfrog-xray.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/jfrog-xray.mdx
@@ -1,5 +1,6 @@
---
title: "JFrog Xray alert integration"
+sidebarTitle: "JFrog Xray"
description: "Send the security, license and operational risk violations found by JFrog Xray watches to Flashduty On-call through an Xray webhook."
keywords: ["alert integration", "JFrog", "Xray", "webhook", "vulnerability", "license", "policy violation", "software supply chain"]
---
@@ -11,7 +12,6 @@ Xray sends a webhook only when a scan finds violations and sends nothing when an
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure JFrog Xray
----
<Steps>
<Step title="Create a webhook">
@@ -67,14 +66,12 @@ The Xray webhook page has no test button. Upload a component with a known vulner
</Steps>
## Recovery and auto-close
----
The Xray violation webhook is sent only when a scan finds violations. The request body has no field that marks a violation as fixed or ignored, so the alert in Flashduty does not recover on its own.
Each delivery is a separate Flashduty alert. Close it by hand, or turn on [auto-close](/en/on-call/channel/create-edit) in the channel that receives this integration, set to how quickly your team handles vulnerabilities, for example 7 days.
## Alert Key
----
Xray creates an `alert_id` for each scan of a watch. When one scan matches several policy rules (for example a security policy and a license policy on the same watch), Xray sends one webhook per rule, all with the same `alert_id`. So Flashduty builds the Alert Key from `alert_id`, the watch name `watch_name`, the policy name `policy_name` and the rule name `policy_rule` (joined with an invisible separator, then MD5):
@@ -84,7 +81,6 @@ Xray creates an `alert_id` for each scan of a watch. When one scan matches sever
- If the body has no `watch_name`, Flashduty returns 400 and names the missing field
## Status and severity
----
The alert status equals its severity; it does not recover. The severity comes from the highest severity in the body, `top_severity`; if it is missing or not one of the values below, the most severe issue decides.
@@ -95,7 +91,6 @@ The alert status equals its severity; it does not recover. The severity comes fr
| `Low`, `Information`, `Unknown`, missing or any other value | Info |
## Alert content
----
One webhook holds every issue (`issues`) that the scan found under that rule.
@@ -114,7 +109,6 @@ One webhook holds every issue (`issues`) that the scan found under that rule.
| `artifacts` | Impacted components, most severe first, up to 20 |
## Troubleshooting
----
- **Flashduty receives nothing**: check that the policy rule's **Then** section has **Trigger webhook** selected with this webhook, that the policy is assigned to a watch, and that the watch is active. Xray sends a webhook only for newly found violations; saving a rule does not resend violations that already exist. **Apply on Existing Content** in the row actions of the watch does not resend them either. Upload a new vulnerable component to a watched repository to verify
- **Flashduty returns a parameter error**: the body is not JSON, or it has no `watch_name`. Send the Xray violation webhook directly, not through a relay that rewrites the body
diff --git a/en/on-call/integration/alert-integration/alert-sources/jiankongbao.mdx b/en/on-call/integration/alert-integration/alert-sources/jiankongbao.mdx
index f44e6716..67851dc8 100644
--- a/en/on-call/integration/alert-integration/alert-sources/jiankongbao.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/jiankongbao.mdx
@@ -1,5 +1,6 @@
---
title: "Jiankongbao Alert Events"
+sidebarTitle: "Jiankongbao"
description: "Sync Jiankongbao alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,64 +9,64 @@ Sync Jiankongbao alert events to Flashduty via webhook for automated alert noise
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Jiankongbao** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're Done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Jiankongbao** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Jiankongbao
----
This integration also covers Cloudwise Jiankongbao (including Jiankongbao 6) URL callback notifications.
<div class="md-block">
-## I. Jiankongbao Alert Push Configuration
+## Jiankongbao Alert Push Configuration
### Step 1: Configure Alert Channel
1. Log in to the Jiankongbao console
2. Click Personal Configuration in the upper right corner
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-1.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-1.png" />
3. Click Webhooks Settings in the left navigation bar, then click Add and select URL Callback
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-2.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-2.png" />
4. Enter Flashduty as the custom name, and input the copied integration push URL
5. Select **POST** as the callback method and **JSON** as the data format
6. Check **Enable URL Callback**, configure other options as needed, refer to the image below
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-3.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-3.png" />
7. Click Save
@@ -74,12 +75,12 @@ This integration also covers Cloudwise Jiankongbao (including Jiankongbao 6) URL
2. Other alert configurations are omitted here
3. Under Webhook notification, select the Flashduty channel
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-4.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-4.png" />
4. Save the monitoring task to complete
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/jumpcloud.mdx b/en/on-call/integration/alert-integration/alert-sources/jumpcloud.mdx
index 7f7b26b8..69a44243 100644
--- a/en/on-call/integration/alert-integration/alert-sources/jumpcloud.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/jumpcloud.mdx
@@ -1,5 +1,6 @@
---
title: "JumpCloud Alert Integration"
+sidebarTitle: "JumpCloud"
description: "Send JumpCloud Insights alerts to Flashduty On-call through a webhook notification channel."
keywords: ["alert integration", "JumpCloud", "webhook", "Insights", "identity security", "MDM"]
---
@@ -9,7 +10,6 @@ Send alerts raised by JumpCloud Insights rules to Flashduty On-call through a Ju
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure JumpCloud
----
<Steps>
<Step title="Create a webhook notification channel">
@@ -62,14 +61,12 @@ The channel page's **Test Webhook** button only shows a simulated request and re
</Steps>
## Alert Key
----
Flashduty builds the Alert Key from `alert_id`, the ID of the JumpCloud alert. JumpCloud sends the same `alert_id` on every status change of one alert (Open, Acknowledged, Resolved, Auto-Resolved), so the trigger and the recovery land on the same Flashduty alert. Changes to the title, priority, description or update time do not change the Alert Key. A request without `alert_id` is rejected.
JumpCloud documents that a new event after the threshold is reached updates the existing alert; those updates all fold into the same Flashduty alert.
## Status and severity
----
| JumpCloud `status` | Flashduty status |
| :--- | :--- |
@@ -86,7 +83,6 @@ JumpCloud documents that a new event after the threshold is reached updates the
A recovery keeps the severity of the last payload.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -103,7 +99,6 @@ A recovery keeps the severity of the last payload.
The alert title comes from `alert_title` and the description from `description`.
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: check that the URL is complete and includes `integration_key`, and that the request body is JSON
- **An alert does not recover**: check that Alert Resolution is on in the rule and that the channel is enabled
diff --git a/en/on-call/integration/alert-integration/alert-sources/juniper-mist.mdx b/en/on-call/integration/alert-integration/alert-sources/juniper-mist.mdx
index 31095edb..0c78ebf2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/juniper-mist.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/juniper-mist.mdx
@@ -1,5 +1,6 @@
---
title: "Juniper Mist alert integration"
+sidebarTitle: "Juniper Mist"
description: "Send Juniper Mist alarm triggers and recoveries to Flashduty On-call through a webhook."
keywords: ["alert integration", "Juniper Mist", "Mist", "Marvis", "wireless network", "webhook", "alarms"]
---
@@ -9,7 +10,6 @@ Use webhooks in Juniper Mist to send alarms from the `alarms` topic to Flashduty
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Juniper Mist
----
<Steps>
<Step title="Create a webhook">
@@ -76,7 +75,6 @@ The webhook only sends alarm types that are enabled. Enable the types you need i
</Steps>
## Alert Key
----
One delivery can carry several alarm events (the `events` array). Flashduty handles each event on its own.
@@ -93,7 +91,6 @@ The paired types are: AP, switch, and WAN Edge offline and reconnect (`device_do
Several critical-port alarms on the same switch or gateway share one Alert Key, and so do the two nodes of an HA cluster.
## Status and severity
----
| Event | Status |
| :--- | :--- |
@@ -115,7 +112,6 @@ Severity comes from `severity`:
A recovery event keeps its own severity.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -132,7 +128,6 @@ A recovery event keeps its own severity.
The alert title is `type: device or hostname`, for example `device down: d420b02000fa`. The description comes from `reasons`, `text`, `suggestion`, and `count`.
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: confirm the URL is complete and includes `integration_key`, and that the body is a Mist `alarms` topic payload
- **An alert does not recover**: confirm the matching recovery type is enabled in Mist too (for example, if AP offline is enabled, also enable AP reconnected). Check each type's default enablement in `alarm_defs`
diff --git a/en/on-call/integration/alert-integration/alert-sources/kapacitor.mdx b/en/on-call/integration/alert-integration/alert-sources/kapacitor.mdx
index 22218d09..1cd8a8d1 100644
--- a/en/on-call/integration/alert-integration/alert-sources/kapacitor.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/kapacitor.mdx
@@ -1,5 +1,6 @@
---
title: "Kapacitor Alert Integration"
+sidebarTitle: "Kapacitor"
description: "Receive Kapacitor alerts through Kapacitor's post event handler using a Flashduty InfluxData integration; alerts close automatically when they recover."
keywords: ["alert integration", "Kapacitor", "InfluxData", "TICKscript", "post event handler", "time series alerting"]
---
@@ -9,7 +10,6 @@ Kapacitor's [post event handler](https://docs.influxdata.com/kapacitor/v1/refere
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the InfluxData integration type** in both.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the Influx
</div>
## Configure in Kapacitor
----
Use any one of the three ways below. Always enter the full push URL, including `?integration_key=...`.
@@ -90,7 +89,6 @@ Then run `kapacitor define-topic-handler flashduty.yaml` and use `.topic('cpu-al
Adding a `post` handler in the Chronograf 1.x Alert Rule Builder uses this same Kapacitor handler; see the [InfluxData integration](/en/on-call/integration/alert-integration/alert-sources/influxdata) for those steps.
## Field mapping
----
| Kapacitor field | Flashduty |
| :--- | :--- |
@@ -105,14 +103,12 @@ Adding a `post` handler in the Chronograf 1.x Alert Rule Builder uses this same
For any other `level`, Flashduty rejects the event with `level ... is not supported`.
## Recovery and deduplication
----
- When the level returns to `OK`, Kapacitor sends an event with `level` `OK`, and Flashduty closes the alert with the same `id`. Do not use `.noRecoveries()` on `alert()`, or Kapacitor sends no recovery events.
- The default `id` is `{{ .Name }}:{{ .Group }}` (measurement name and group). If you set a custom `.id()`, make sure the trigger and the recovery of one object use the same value.
- To see Flashduty's error in the Kapacitor log, add `.captureResponse()` to `.post()` (`capture-response: true` for a topic handler); the response is logged when the status is not 2xx.
## Troubleshooting
----
- **Flashduty returns `Invalid parameters`**: the push URL is incomplete, `integration_key` is missing, or the integration type is not InfluxData
- **`level ... is not supported`**: the `level` in the body is not `CRITICAL`, `WARNING`, `INFO` or `OK`; make sure the original Kapacitor alert data is sent, not a forwarded or rewritten body
diff --git a/en/on-call/integration/alert-integration/alert-sources/keep.mdx b/en/on-call/integration/alert-integration/alert-sources/keep.mdx
index 4afc7abe..69330458 100644
--- a/en/on-call/integration/alert-integration/alert-sources/keep.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/keep.mdx
@@ -1,5 +1,6 @@
---
title: "Keep Alert Integration Guide"
+sidebarTitle: "Keep"
description: "Push alert events to Flashduty through Keep's Provider to achieve automated alert noise reduction."
---
@@ -11,40 +12,41 @@ Push alert events to Flashduty through Keep's Flashduty Provider to achieve auto
You can obtain an integration key through either of these 2 methods:
-#### Using Dedicated Integration
+### Using Dedicated Integration
Choose this method when you don't need to route alert events to different channels - it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Enter the Flashduty console, select **Channel**, and go to a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Keep** integration, click **Save** to generate a card
4. Click the generated card to view the **Integration Key**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
-#### Using Shared Integration
+### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Enter the Flashduty console, select **Integration Center=>Alert Events** to access the integration selection page
+ 1. Enter the Flashduty console, select **Integration Center → Alert Events** to access the integration selection page
2. Select **Keep** integration:
- **Integration Name**: Define a name for this integration
3. Configure default routing and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **Integration Key** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Keep
----
### Field Definitions
@@ -54,7 +56,7 @@ Field|Required|Type|Definition
| event_status | Yes | string | Alert status. Enumerated values (`First letter capitalized`): *Critical*: Critical, *Warning*: Warning, *Info*: Info, *Ok*: Recovery. When set to Ok, it indicates automatic recovery of the alert
| alert_key | No | string | Alert identifier, used for updating or automatically recovering existing alerts. You can customize this value, but it cannot exceed `255` characters. You can also rely on system-generated values, which will be returned in the response. This value must exist if you're reporting a recovery event
| description | No | string | Alert description, maximum `2048` characters, will be truncated if exceeded
-| labels | No | map | Alert label collection, where key is the label name and value is the label value. 1. Both label key and value are case-sensitive strings. 2. Label keys should not exceed `128` characters and follow Prometheus label naming conventions. Values should not exceed `8192` bytes (8 KB) and are truncated if exceeded; the cut backs off to a UTF-8 character boundary. 3. Maximum `50` labels allowed. See [Standard Alert Best Practices](/en/on-call/integration/alert-integration/alert-sources/standard-alert#iv-best-practices). Example: "resource": "171.26.23.22", "check": "api latency > 500ms"
+| labels | No | map | Alert label collection, where key is the label name and value is the label value. 1. Both label key and value are case-sensitive strings. 2. Label keys should not exceed `128` characters and follow Prometheus label naming conventions. Values should not exceed `8192` bytes (8 KB) and are truncated if exceeded; the cut backs off to a UTF-8 character boundary. 3. Maximum `50` labels allowed. See [Standard Alert Best Practices](/en/on-call/integration/alert-integration/alert-sources/standard-alert#best-practices). Example: "resource": "171.26.23.22", "check": "api latency > 500ms"
diff --git a/en/on-call/integration/alert-integration/alert-sources/kener.mdx b/en/on-call/integration/alert-integration/alert-sources/kener.mdx
index e93294d9..9d529e19 100644
--- a/en/on-call/integration/alert-integration/alert-sources/kener.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/kener.mdx
@@ -1,5 +1,6 @@
---
title: "Kener alert integration"
+sidebarTitle: "Kener"
description: "Send Kener monitor alerts for downtime, latency, and uptime to Flashduty On-call through a webhook trigger."
keywords: ["alert integration", "Kener", "webhook", "status page", "monitoring", "self-hosted"]
---
@@ -11,7 +12,6 @@ Kener's webhook body is a template you write in the trigger. This page provides
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Kener
----
You need Kener 4.x and an account that can manage triggers and alert configurations in the admin console. The Kener server must be able to reach the Flashduty push URL.
@@ -44,22 +43,22 @@ You need Kener 4.x and an account that can manage triggers and alert configurati
3. Leave **Headers** empty. Flashduty authenticates with the `integration_key` in the URL
4. Replace **Webhook Body** with the following template:
-```json
-{
- "alert_id": {{alert_id}},
- "alert_name": "{{alert_name}}",
- "alert_for": "{{alert_for}}",
- "alert_value": "{{alert_value}}",
- "alert_status": "{{alert_status}}",
- "alert_severity": "{{alert_severity}}",
- "alert_cta_url": "{{alert_cta_url}}",
- "alert_incident_id": {{#alert_incident_id}}{{alert_incident_id}}{{/alert_incident_id}}{{^alert_incident_id}}null{{/alert_incident_id}},
- "alert_failure_threshold": {{alert_failure_threshold}},
- "alert_success_threshold": {{alert_success_threshold}},
- "is_resolved": {{is_resolved}},
- "is_triggered": {{is_triggered}}
-}
-```
+ ```json
+ {
+ "alert_id": {{alert_id}},
+ "alert_name": "{{alert_name}}",
+ "alert_for": "{{alert_for}}",
+ "alert_value": "{{alert_value}}",
+ "alert_status": "{{alert_status}}",
+ "alert_severity": "{{alert_severity}}",
+ "alert_cta_url": "{{alert_cta_url}}",
+ "alert_incident_id": {{#alert_incident_id}}{{alert_incident_id}}{{/alert_incident_id}}{{^alert_incident_id}}null{{/alert_incident_id}},
+ "alert_failure_threshold": {{alert_failure_threshold}},
+ "alert_success_threshold": {{alert_success_threshold}},
+ "is_resolved": {{is_resolved}},
+ "is_triggered": {{is_triggered}}
+ }
+ ```
5. Save the trigger
@@ -87,14 +86,12 @@ Kener renders the template without JSON escaping. The built-in default template
</Steps>
## Alert Key
----
Flashduty uses the Kener `alert_id` as the Alert Key. Kener creates an alert record when a monitor reaches the failure threshold and updates the same record when it recovers, so the trigger and the recovery carry the same `alert_id`. If the same monitor goes down again, Kener creates a new `alert_id`, which is a new alert in Flashduty.
Changes to the monitor name, severity, status, or value do not change the Alert Key. A request without `alert_id` is rejected. `alert_id` is unique only within one Kener instance, so connect only one Kener instance to each Flashduty integration.
## Status and severity
----
| `alert_status` | Flashduty status |
| :--- | :--- |
@@ -110,7 +107,6 @@ Changes to the monitor name, severity, status, or value do not change the Alert
The alert title combines the monitor identifier, the alert type, and the value, for example `my-api STATUS: DOWN`.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -124,7 +120,6 @@ The alert title combines the monitor identifier, the alert type, and the value,
| `alert_url` | Link to the monitor page in Kener |
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: Confirm the URL is complete and includes `integration_key`, and that the trigger uses the template on this page. The response names the missing field
- **The Kener trigger test fails**: The test result shows the HTTP status code or network error. Confirm the Kener server can reach the Flashduty push URL
diff --git a/en/on-call/integration/alert-integration/alert-sources/kentik.mdx b/en/on-call/integration/alert-integration/alert-sources/kentik.mdx
index c6651faa..733a29d5 100644
--- a/en/on-call/integration/alert-integration/alert-sources/kentik.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/kentik.mdx
@@ -1,5 +1,6 @@
---
title: "Kentik alert integration"
+sidebarTitle: "Kentik"
description: "Send Kentik alert policy and Synthetics alerts to Flashduty On-call through a Custom Webhook notification channel, and recover them automatically when the alert clears."
keywords: ["alert integration", "Kentik", "Custom Webhook", "notification channel", "Synthetics"]
---
@@ -9,7 +10,6 @@ Use a Kentik Custom Webhook notification channel to send alerts to Flashduty On-
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Kentik
----
Creating a notification channel requires the Administrator role in Kentik; Members can only view channels.
@@ -41,39 +40,39 @@ Creating a notification channel requires the Administrator role in Kentik; Membe
2. Click **Add Notification Channel** and set **Type** to **Webhook** (listed as Custom Webhook). Do not choose the **JSON** type: Flashduty parses the output of the template below
3. Fill in the fields as follows:
-| Field | Value |
-| :--- | :--- |
-| **Name** | A recognizable name, such as `Flashduty` |
-| **Status** | On |
-| **URL** | The full Flashduty integration push URL, including `integration_key` |
-| **Custom Headers** | Leave empty |
-| **Custom Template** | Click **Go to Notification Template Setup** and paste the template below into **TEMPLATE** on the **Template & Preview** tab, without renaming any field |
-| **Uglify JSON** | Keep the default |
-
-```go-template
-{
- "CompanyID": "{{ .CompanyID }}",
- "Events": [
- {{- range $index, $event := .Events -}}
- {{- join $index }}
- {
- "Type": {{ .Type | toJSON }},
- "AlarmID": "{{ with .Details.GetValue "AlarmID" }}{{ . }}{{ end }}",
- "IsActive": {{ .IsActive | toJSON }},
- "Importance": {{ .Importance | toJSON }},
- "Description": {{ .Description | toJSON }},
- "CurrentState": {{ .CurrentState | toJSON }},
- "PreviousState": {{ .PreviousState | toJSON }},
- "StartTime": {{ .StartTime | toJSON }},
- "EndTime": {{ .EndTime | toJSON }},
- "Details": {{ .Details.General.ToMap | toJSON }},
- "Dimensions": {{ (.Details.WithTag "dimension").ToMap | toJSON }},
- "Links": {{ (.Details.WithTag "url").ToMap | toJSON }}
- }
- {{- end }}
- ]
-}
-```
+ | Field | Value |
+ | :--- | :--- |
+ | **Name** | A recognizable name, such as `Flashduty` |
+ | **Status** | On |
+ | **URL** | The full Flashduty integration push URL, including `integration_key` |
+ | **Custom Headers** | Leave empty |
+ | **Custom Template** | Click **Go to Notification Template Setup** and paste the template below into **TEMPLATE** on the **Template & Preview** tab, without renaming any field |
+ | **Uglify JSON** | Keep the default |
+
+ ```go-template
+ {
+ "CompanyID": "{{ .CompanyID }}",
+ "Events": [
+ {{- range $index, $event := .Events -}}
+ {{- join $index }}
+ {
+ "Type": {{ .Type | toJSON }},
+ "AlarmID": "{{ with .Details.GetValue "AlarmID" }}{{ . }}{{ end }}",
+ "IsActive": {{ .IsActive | toJSON }},
+ "Importance": {{ .Importance | toJSON }},
+ "Description": {{ .Description | toJSON }},
+ "CurrentState": {{ .CurrentState | toJSON }},
+ "PreviousState": {{ .PreviousState | toJSON }},
+ "StartTime": {{ .StartTime | toJSON }},
+ "EndTime": {{ .EndTime | toJSON }},
+ "Details": {{ .Details.General.ToMap | toJSON }},
+ "Dimensions": {{ (.Details.WithTag "dimension").ToMap | toJSON }},
+ "Links": {{ (.Details.WithTag "url").ToMap | toJSON }}
+ }
+ {{- end }}
+ ]
+ }
+ ```
4. Click **Save**
@@ -97,7 +96,6 @@ Do not use this channel for mitigation methods or Insights notifications: these
</Steps>
## Alert Key
----
Flashduty uses the Kentik alert ID (`AlarmID`, shown as **Alert ID** in Kentik) as the Alert Key. Every state-change notification of one Kentik alert, from Active to Cleared, carries the same alert ID, so they merge into one alert, and the clear notification closes it.
@@ -107,7 +105,6 @@ Flashduty uses the Kentik alert ID (`AlarmID`, shown as **Alert ID** in Kentik)
- When one notification carries several events, each event maps to its own alert. A notification with no events is accepted but creates no alert
## Status and severity
----
The status comes from `IsActive`:
@@ -129,7 +126,6 @@ The severity comes from the event importance (`Importance`, 0 to 7). For alert p
| Other or empty | - | Info |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -145,7 +141,6 @@ The severity comes from the event importance (`Importance`, 0 to 7). For alert p
The alert title is the Kentik event description (`Description`), such as `Alarm for DDoS Protect Policy Active`.
## Troubleshooting
----
- **Flashduty returns a parameter error**: make sure the URL is complete and includes `integration_key`, the channel type is **Custom Webhook**, and the template matches the one above
- **`AlarmID is required`**: the channel is used for mitigation or Insights notifications, or the template was changed. Use the channel only for alert policies and Synthetics tests
diff --git a/en/on-call/integration/alert-integration/alert-sources/komodor.mdx b/en/on-call/integration/alert-integration/alert-sources/komodor.mdx
index e1cf5da1..72b2a278 100644
--- a/en/on-call/integration/alert-integration/alert-sources/komodor.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/komodor.mdx
@@ -1,5 +1,6 @@
---
title: "Komodor alert integration"
+sidebarTitle: "Komodor"
description: "Send Kubernetes workload, node, PVC, and Job issues and their recoveries from Komodor Realtime Health Monitors to Flashduty On-call through a webhook notification."
keywords: ["alert integration", "Komodor", "Kubernetes", "Realtime Health Monitors", "webhook"]
---
@@ -9,7 +10,6 @@ Use the webhook notification channel of Komodor Realtime Health Monitors to send
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -18,7 +18,7 @@ You can obtain an integration push URL in either of the following ways.
Choose this method when you do not need to route alerts to different channels.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View dedicated integration setup steps">
1. In the Flashduty console, select **Channel** and open a channel
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**
@@ -33,7 +33,7 @@ Choose this method when you do not need to route alerts to different channels.
Choose this method when you need to route alerts to different channels based on the payload.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View shared integration setup steps">
1. In the Flashduty console, select **Integration Center → Alert Events**
2. Select **Komodor** and enter an integration name
@@ -46,13 +46,11 @@ Choose this method when you need to route alerts to different channels based on
</div>
## Prerequisites
----
- The Komodor Agent is installed in your Kubernetes cluster, and the cluster appears in the Komodor console.
- Your account can edit Komodor **Health Policies**.
## In Komodor
----
<Steps>
<Step title="Open a monitor">
@@ -89,7 +87,6 @@ Deploy monitor notifications describe a rollout (successful or failed), not a he
</Note>
## Alert Key
----
Flashduty builds the Alert Key from the `monitorType`, `cluster`, `namespace`, and `resourceName` fields. For one kind of issue on one resource, the `open` and `closed` messages carry the same four values, so they merge into one alert and the `closed` message recovers it.
@@ -98,7 +95,6 @@ Flashduty builds the Alert Key from the `monitorType`, `cluster`, `namespace`, a
- Node issues have no namespace; an empty `namespace` still produces a valid Alert Key.
## Status and severity
----
Komodor webhook notifications carry no severity field, so Flashduty uses Critical for every issue.
@@ -110,7 +106,6 @@ Komodor webhook notifications carry no severity field, so Flashduty uses Critica
If `status` has any other value, or `monitorType`, `cluster`, or `resourceName` is missing, Flashduty returns an error and Komodor records a failed delivery.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -126,7 +121,6 @@ If `status` has any other value, or `monitorType`, `cluster`, or `resourceName`
The alert title is `<monitor type> issue on <resource name> (<cluster>/<namespace>)`, and the description contains the issue details and the Komodor link.
## FAQ
----
<AccordionGroup>
<Accordion title="Are Komodor Agentic Operation Platform notification sinks supported?">
diff --git a/en/on-call/integration/alert-integration/alert-sources/kscloud-monitor.mdx b/en/on-call/integration/alert-integration/alert-sources/kscloud-monitor.mdx
index 598cfba6..d01fe393 100644
--- a/en/on-call/integration/alert-integration/alert-sources/kscloud-monitor.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/kscloud-monitor.mdx
@@ -1,5 +1,6 @@
---
title: "Kingsoft Cloud monitoring integration"
+sidebarTitle: "Kingsoft Cloud monitoring"
description: "Sync Kingsoft Cloud monitoring alerts to Flashduty On-call via webhook for automated alert noise reduction"
keywords: ["alert integration", "Kingsoft Cloud monitoring", "monitoring alerts", "data ingestion"]
---
@@ -9,7 +10,6 @@ Sync metric and event alerts from Kingsoft Cloud Monitoring to Flashduty On-call
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL through either of the following methods.
### Use a dedicated integration
@@ -17,7 +17,7 @@ You can obtain an integration push URL through either of the following methods.
Choose this method when you do not need to route alerts to different channels.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View dedicated integration setup steps">
1. In the Flashduty console, select **Channel** and open a channel
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**
@@ -32,7 +32,7 @@ Choose this method when you do not need to route alerts to different channels.
Choose this method when you need to route alerts to different channels based on the event payload.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View shared integration setup steps">
1. In the Flashduty console, select **Integration Center → Alert Events**
2. Select **Kingsoft Cloud Monitoring** and enter an integration name
@@ -44,7 +44,6 @@ Choose this method when you need to route alerts to different channels based on
</div>
## In Kingsoft Cloud
----
<Steps>
<Step title="Configure the alert callback">
@@ -64,7 +63,6 @@ Return to the integration list in the Flashduty console. If the integration card
</Steps>
## Status and severity
----
Metric alerts support both firing and recovery notifications. Event alerts only send firing events and do not have corresponding recovery events.
diff --git a/en/on-call/integration/alert-integration/alert-sources/kuvasz.mdx b/en/on-call/integration/alert-integration/alert-sources/kuvasz.mdx
index fac22c76..13eebf81 100644
--- a/en/on-call/integration/alert-integration/alert-sources/kuvasz.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/kuvasz.mdx
@@ -1,5 +1,6 @@
---
title: "Kuvasz alert integration"
+sidebarTitle: "Kuvasz"
description: "Send Kuvasz website, port, DNS, container and SSL certificate monitoring alerts to Flashduty On-call through the Kuvasz webhook integration. Alerts close automatically when the monitor recovers."
keywords: ["alert integration", "Kuvasz", "webhook", "website monitoring", "SSL certificate monitoring", "open source monitoring"]
---
@@ -9,7 +10,6 @@ Kuvasz is an open-source, self-hosted uptime and SSL certificate monitor. Its **
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Kuvasz
----
Kuvasz integrations are configured only in the YAML configuration file, and you must restart the Kuvasz container after changing it.
@@ -68,7 +67,6 @@ Make a monitor fail (for example, create an HTTP monitor that points to a URL re
</Steps>
## Alert Key
----
Flashduty uses the monitor type plus `monitorId` as the Alert Key. Each Kuvasz monitor has a fixed numeric ID, and the down (`*_DOWN`) and up (`*_UP`) messages of one monitor carry the same `monitorId`, so they land on the same Flashduty alert.
@@ -79,7 +77,6 @@ Flashduty uses the monitor type plus `monitorId` as the Alert Key. Each Kuvasz m
Flashduty rejects requests that have no `monitorId`.
## Alert lifecycle
----
Flashduty handles messages by the `type` field:
@@ -96,19 +93,16 @@ Flashduty handles messages by the `type` field:
Other types are ignored as well. `DNS_RECORDS_CHANGED` has no recovery message, so turn on [auto-close after timeout](/en/on-call/channel/create-edit) for the channel, start the timer from **Incident triggered**, and set about 24 hours.
## Severity
----
Kuvasz messages carry no severity. Down events and `SSL_INVALID` mean the service is unavailable and are fixed at **Critical**; `SSL_WILL_EXPIRE` and `DNS_RECORDS_CHANGED` are fixed at **Warning**. A recovery event keeps the original alert's severity.
## Alert content
----
- **Title**: the monitor name
- **Description**: the event text Kuvasz generates (`eventDetails`)
- **Labels**: `check` (monitor name), `monitor_id`, `monitor_type`, `monitor_name`, `monitor_urn`, `monitor_detail` (relative path of the monitor's details page), `event_type` (Kuvasz `type`), and `source` (always `kuvasz`)
## Troubleshooting
----
- **The test event created no alert**: this is expected; test events only verify connectivity
- **4xx or an invalid `integration_key` error**: check that `url` is the full push URL and the integration is not disabled
diff --git a/en/on-call/integration/alert-integration/alert-sources/label-mapping-api.mdx b/en/on-call/integration/alert-integration/alert-sources/label-mapping-api.mdx
index 301f062f..076d745c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/label-mapping-api.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/label-mapping-api.mdx
@@ -4,7 +4,7 @@ description: "Configure Label Mapping API to automatically call your external AP
keywords: ["Label Mapping", "API", "Alert Enrichment", "CMDB", "Label Enhancement", "External Data Source"]
---
-## I. Overview
+## Overview
The Label Mapping API allows you to build custom external services to enrich alert labels. The workflow is as follows:
@@ -16,7 +16,7 @@ The Label Mapping API allows you to build custom external services to enrich ale
<span id="ApiSpec"></span>
-## II. API Specification
+## API Specification
### Request Method
@@ -131,7 +131,7 @@ POST, Content-Type:"application/json"
<span id="ServiceConfig"></span>
-## III. Configure Mapping Service
+## Configure Mapping Service
When configuring label mapping in Flashduty, you need to first create a mapping service, then reference that service in your label enrichment rules.
@@ -161,7 +161,7 @@ When configuring label enrichment rules, you only need to focus on the following
<span id="HeaderBlacklist"></span>
-## IV. Header Security Constraints
+## Header Security Constraints
To prevent security bypasses, request smuggling, IP spoofing, and cache poisoning, the following Headers are **prohibited** when customizing API request headers. The system gateway will automatically filter or reject requests containing these Headers.
@@ -182,7 +182,7 @@ To prevent security bypasses, request smuggling, IP spoofing, and cache poisonin
2. **Length Limits**: The Key or Value length of a single Header should not exceed 1024 bytes
3. **Format Validation**: Header Values must not contain line breaks (`\r`, `\n`) to prevent Header injection attacks
-## V. Best Practices
+## Best Practices
1. **Performance First:** This API is on the critical path of alert processing and must ensure low latency. Queries to external data sources should be as fast as possible, and implementing caching is recommended.
@@ -192,7 +192,7 @@ To prevent security bypasses, request smuggling, IP spoofing, and cache poisonin
4. **Security:** The API must be protected through authentication and authorization mechanisms. Using custom Headers (e.g., `X-Custom-Auth`) for passing authentication information is recommended.
-## VI. FAQ
+## FAQ
1. **Is there a response timeout for the service?**
diff --git a/en/on-call/integration/alert-integration/alert-sources/lacework.mdx b/en/on-call/integration/alert-integration/alert-sources/lacework.mdx
index 42ea7ed5..b3fa70d7 100644
--- a/en/on-call/integration/alert-integration/alert-sources/lacework.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/lacework.mdx
@@ -1,5 +1,6 @@
---
title: "Lacework FortiCNAPP alert integration"
+sidebarTitle: "Lacework FortiCNAPP"
description: "Send cloud security alerts from FortiCNAPP (formerly Lacework) to Flashduty On-call through a custom webhook alert channel."
keywords: ["alert integration", "Lacework", "FortiCNAPP", "Fortinet", "webhook", "CNAPP", "cloud security alerts"]
---
@@ -9,7 +10,6 @@ Use a Lacework FortiCNAPP custom webhook alert channel to send compliance change
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,13 +30,12 @@ You can get the integration push URL in either of the following ways.
</div>
## In FortiCNAPP
----
<Steps>
<Step title="Create the webhook alert channel">
1. Log in to the FortiCNAPP console as a user with administrative privileges
-2. Go to **Settings > Notifications > Channels** and click **+ Add new**
+2. Go to **Settings → Notifications → Channels** and click **+ Add new**
3. Select **Webhook** and click **Next**
4. Enter a channel name, for example `Flashduty`
5. In **Webhook URL**, paste the full Flashduty push URL (it must be `https`; keep `integration_key` in the query string)
@@ -48,7 +47,7 @@ FortiCNAPP sends an HTTP `POST` with a fixed JSON body, so no template is needed
<Step title="Create an alert rule">
-In **Settings > Notifications > Alert rules**, click **+ Add New**, select the channel from the previous step, and choose the alert severities, resource groups and alert categories you need. Only alerts that match an alert rule are sent to Flashduty.
+In **Settings → Notifications → Alert rules**, click **+ Add New**, select the channel from the previous step, and choose the alert severities, resource groups and alert categories you need. Only alerts that match an alert rule are sent to Flashduty.
</Step>
@@ -66,14 +65,12 @@ Run **Test Integration** on the channel in the channel list (where available), o
</Steps>
## Alert Key
----
Flashduty builds the Alert Key from `lacework_account` and `event_id` in the request body. The FortiCNAPP documentation describes `event_id` as "The FortiCNAPP ID for the event". Repeated deliveries of one event (for example one notification per resource when the channel groups issues by resources) land on the same Flashduty alert, and each event opens its own alert.
Changes to the title, severity, description or time do not change the Alert Key. A request without `event_id` opens an alert of its own. A request with none of `event_id`, `event_title` and `event_description` is rejected with a parameter error.
## Status and severity
----
The FortiCNAPP webhook has no status field, so every request is a trigger event. `event_severity` ranges from 1 to 5, with 1 the highest.
@@ -87,7 +84,6 @@ The FortiCNAPP webhook has no status field, so every request is a trigger event.
The alert title is `event_title` and the description is `event_description`. Alert labels include the Lacework account (`lacework_account`), event source (`event_source`), event type (`event_type`), event ID, raw severity, recommendation ID (`rec_id`, compliance events only), event time and event link.
## Troubleshooting
----
- **No alert arrives**: check that an alert rule uses the channel and that its severities, resource groups and alert categories cover the alert; a disabled channel delivers nothing
- **The channel cannot be saved**: the webhook URL must be `https` and include the full `integration_key` query parameter
diff --git a/en/on-call/integration/alert-integration/alert-sources/langsmith.mdx b/en/on-call/integration/alert-integration/alert-sources/langsmith.mdx
index edef70dd..aaa2edc1 100644
--- a/en/on-call/integration/alert-integration/alert-sources/langsmith.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/langsmith.mdx
@@ -1,5 +1,6 @@
---
title: "LangSmith alert integration"
+sidebarTitle: "LangSmith"
description: "Send LangSmith threshold alerts on error count, latency, cost and feedback score to Flashduty On-call through an alert rule webhook."
keywords: ["alert integration", "LangSmith", "LangChain", "webhook", "alert_rule_id", "LLM observability"]
---
@@ -11,7 +12,6 @@ LangSmith's documentation describes no "resolved" notification: once the metric
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of two ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of two ways.
</div>
## Configure in LangSmith
----
<Steps>
<Step title="Create an alert rule with a webhook">
@@ -60,7 +59,6 @@ A LangSmith webhook has no recovery notification: after the metric falls back, n
</Steps>
## Payload
----
LangSmith POSTs these fields as `application/json`, and Flashduty parses them directly:
@@ -82,19 +80,16 @@ LangSmith POSTs these fields as `application/json`, and Flashduty parses them di
The alert title is the rule name; if it is empty, `LangSmith alert <alert_rule_id>` is used.
## Alert Key
----
Flashduty uses `alert_rule_id` as the Alert Key. LangSmith documents it as the UUID identifying the alert, and every firing of one rule carries the same `alert_rule_id`, so repeated notifications while the metric stays above the threshold merge into one alert and different rules stay separate. Changing the rule name, threshold or metric value does not change the Alert Key.
A request without `alert_rule_id`, or with the all-zero UUID that LangSmith uses for test notifications, is treated as a test notification: Flashduty returns success and creates no alert.
## Status and severity
----
LangSmith notifications carry no severity, so Flashduty treats every one as Warning. A threshold breach does not mean the service is down, so the default is not Critical.
## FAQ
----
<AccordionGroup>
<Accordion title="Why does the alert never recover on its own?">
diff --git a/en/on-call/integration/alert-integration/alert-sources/lark-alert.mdx b/en/on-call/integration/alert-integration/alert-sources/lark-alert.mdx
index 3cd4c4fa..dbc0291a 100644
--- a/en/on-call/integration/alert-integration/alert-sources/lark-alert.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/lark-alert.mdx
@@ -1,5 +1,6 @@
---
title: "Lark Bot Compatible Integration"
+sidebarTitle: "Lark Bot Compatible"
description: "Flashduty generates a webhook address in the format of a Lark (Feishu) custom bot. Point a tool that already sends alerts to a Lark (Feishu) custom bot at this address to bring alert triggers and recoveries into Flashduty."
keywords: ["alert integration", "Lark Bot Compatible", "Lark custom robot", "webhook"]
---
@@ -9,7 +10,6 @@ Generate a unique Feishu robot address in Flashduty, and synchronize the occurre
<div class="hide">
## Operation Steps
----
### Create Lark Bot Compatible Integration
@@ -19,24 +19,25 @@ You can obtain a Lark Bot Compatible integration address through either of these
Choose this method when you don't need to route alert events to different channels. It's simpler and recommended.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Lark Bot Compatible** integration and click **Save** to generate a card
4. Click the generated card to view the **Lark Bot Compatible Integration URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
#### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center => Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Lark Bot Compatible** integration:
- **Integration Name**: Define a name for the current integration
- **Message Type**: Select Feishu alert message type, currently only Text and Post (rich text) are supported
@@ -45,7 +46,8 @@ Choose this method when you need to route alerts to different channels based on
4. Configure the default route and select the corresponding channel (after integration creation, you can go to `Routes` to configure more routing rules)
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
### Customize Lark Bot Compatible Integration
@@ -76,12 +78,10 @@ By default, the system always creates new alerts for each message, but you can s
- When Feishu message type is Text, Flashduty will generate a default alert title "Feishu Alert"
## Severity Mapping
----
Currently, all alerts pushed to Flashduty through the Feishu(lark) integration are set to Warning severity. However, you can customize the severity using the [alert pipeline](/en/on-call/integration/alert-integration/alert-pipelines).
## Alibaba Cloud Message Center
----
<div class="md-block">
The "Robot Reception" feature in Alibaba Cloud's account Message Center can push account, product, and security notices to a custom webhook. Its data format can reuse the Feishu robot protocol, so it connects directly to the Lark Bot Compatible integration on this page.
diff --git a/en/on-call/integration/alert-integration/alert-sources/last9.mdx b/en/on-call/integration/alert-integration/alert-sources/last9.mdx
index 333b66ac..b27670d6 100644
--- a/en/on-call/integration/alert-integration/alert-sources/last9.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/last9.mdx
@@ -1,5 +1,6 @@
---
title: "Last9 Alert Integration"
+sidebarTitle: "Last9"
description: "Receive Last9 alerts through Last9's webhook notification channel using a Flashduty PagerDuty Compatible integration; resolve notifications close the alert automatically."
keywords: ["alert integration", "Last9", "webhook", "PagerDuty", "observability"]
---
@@ -9,7 +10,6 @@ Last9's webhook notification channel sends PagerDuty Events API v2 JSON to the U
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the PagerDuty Compatible integration type** in both, not Last9.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the PagerD
</div>
## Configure in Last9
----
1. In Last9, go to **Notification Channels** and click **Add Channel** → **Webhook**
2. Enter the full push URL copied above as the webhook URL, including `?integration_key=...`
@@ -39,7 +38,6 @@ Get an integration push URL in either of the two ways below. **Choose the PagerD
Last9 detects URLs for Microsoft Teams, Flock, Google Chat, Telegram, Jira and Zenduty and switches to their own formats. A Flashduty push URL is not one of them, so Last9 sends the generic format described here.
## Field mapping
----
| Last9 field | Flashduty |
| :--- | :--- |
@@ -53,7 +51,6 @@ Last9 detects URLs for Microsoft Teams, Flock, Google Chat, Telegram, Jira and Z
| `links`, `images` | Labels keyed by the link text (or `link_N`, `img_N`) |
## Recovery and deduplication
----
- When Last9 sends a notification with `event_action` set to `resolve`, Flashduty closes the alert with the same `dedup_key`.
- `severity` must be one of `critical`, `error`, `warning`, `info`; Flashduty rejects other values.
@@ -61,7 +58,6 @@ Last9 detects URLs for Microsoft Teams, Flock, Google Chat, Telegram, Jira and Z
- Last9's documentation does not describe test-button behavior. After the first setup, verify with a real alert that both the trigger and the recovery show up in Flashduty.
## Troubleshooting
----
- **Flashduty returns `Invalid parameters`**: the push URL is incomplete and lacks `integration_key`, or the integration type is not PagerDuty Compatible
- **Alerts do not recover**: confirm Last9 sent a `resolve` notification and that its `dedup_key` matches the trigger
diff --git a/en/on-call/integration/alert-integration/alert-sources/level.mdx b/en/on-call/integration/alert-integration/alert-sources/level.mdx
index 5c2b644a..28d9b049 100644
--- a/en/on-call/integration/alert-integration/alert-sources/level.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/level.mdx
@@ -1,5 +1,6 @@
---
title: "Level alert integration"
+sidebarTitle: "Level"
description: "Send Level device alert triggers and resolutions to Flashduty On-call through a webhook."
keywords: ["alert integration", "Level", "level.io", "RMM", "webhook", "device alerts"]
---
@@ -9,7 +10,6 @@ Use webhooks in Level (level.io) to send device alerts to Flashduty On-call. Lev
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Level
----
<Steps>
<Step title="Add a webhook">
@@ -55,12 +54,10 @@ Level's documentation does not say whether the webhook has a test button or what
</Steps>
## Alert Key
----
Flashduty uses `data.id` (the Level alert ID) as the Alert Key, so `alert_active` and `alert_resolved` for the same alert share one Alert Key. Changes to the alert name, description, severity, or device hostname do not change it. Level's `event_id` identifies an event and stays the same across retries and manual re-runs; Flashduty does not use it as the Alert Key. Requests without `data.id` are rejected.
## Status and severity
----
| Event type | Status |
| :--- | :--- |
@@ -82,7 +79,6 @@ Severity comes from `data.severity`:
A recovery event keeps the alert's existing severity.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -98,7 +94,6 @@ A recovery event keeps the alert's existing severity.
The alert title is `hostname: alert name`, and the description comes from `data.description` and `data.payload`.
## Troubleshooting
----
- **Flashduty returns a parameter error**: check that the URL is complete and includes `integration_key`, and that the request body is in Level's webhook format
- **Alerts do not recover**: check that the webhook has `alert_resolved` selected
diff --git a/en/on-call/integration/alert-integration/alert-sources/librenms.mdx b/en/on-call/integration/alert-integration/alert-sources/librenms.mdx
index e49dafce..1f901da1 100644
--- a/en/on-call/integration/alert-integration/alert-sources/librenms.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/librenms.mdx
@@ -1,5 +1,6 @@
---
title: "LibreNMS alert integration"
+sidebarTitle: "LibreNMS"
description: "Send LibreNMS device alerts to Flashduty On-call through the LibreNMS API alert transport. Alerts close automatically when the alert rule recovers."
keywords: ["alert integration", "LibreNMS", "API transport", "network monitoring", "SNMP"]
---
@@ -9,7 +10,6 @@ LibreNMS pushes alerts through an alert transport of type **API**: every time an
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure LibreNMS
----
The steps below need LibreNMS 25.7.0 or later: the body template escapes text fields with the `json_encode` filter, which is available from 25.7.0.
@@ -106,7 +105,6 @@ Then make a rule really trigger (for example, make a monitored device unreachabl
</Steps>
## Alert Key
----
Flashduty uses `alert_id` as the Alert Key. `alert_id` is the row ID in the LibreNMS `alerts` table, which holds exactly one row per device and alert rule, and every trigger, change, and recovery notification carries the same value. The LibreNMS PagerDuty transport uses it as its dedup key too. So notifications for the same rule on the same device land on one alert, and a new trigger after recovery opens a new alert.
@@ -115,7 +113,6 @@ Changes to the severity, rule name, host name, or alert message do not change th
Flashduty rejects requests without `alert_id` or `state`.
## Alert lifecycle
----
Flashduty handles notifications by the `state` field:
@@ -133,7 +130,6 @@ Rules that use an Operation (LibreNMS 26.4.0 and later) send only trigger, ackno
When **Acknowledgement alerts** is on for a rule, LibreNMS sends a notification with `state` `2` when the alert is acknowledged. Acknowledgements neither open nor close a Flashduty alert, and ignored notifications get a success response.
## Severity
----
The severity comes from the **Severity** of the alert rule:
@@ -147,7 +143,6 @@ The severity comes from the **Severity** of the alert rule:
Recovery notifications carry the same rule severity, and the recovery event keeps it.
## Alert content
----
- **Title**: `<rule name> on <host name>`. When the rule name is empty, `LibreNMS rule <rule_id>` is used instead
- **Description**: the alert message `msg` rendered from the LibreNMS alert template. The default template includes the title, severity, time, and faulty items
@@ -156,7 +151,6 @@ Recovery notifications carry the same rule severity, and the recovery event keep
Empty fields are not written as labels.
## Troubleshooting
----
- **The test fails with `Transport delivery failed with 401` and `integration_key is required`**: put `integration_key` in **Options**, not in the **API URL**
- **The test fails with `Transport delivery failed with 400`**: if the response shows `{{ $name|json_encode }}` unrendered, LibreNMS is older than 25.7.0 and does not know the `json_encode` filter; upgrade it. Otherwise make sure the fields with `|json_encode` have no extra quotes and that **Send as form** is unchecked
diff --git a/en/on-call/integration/alert-integration/alert-sources/limacharlie.mdx b/en/on-call/integration/alert-integration/alert-sources/limacharlie.mdx
index 5cfe092f..2625f3a8 100644
--- a/en/on-call/integration/alert-integration/alert-sources/limacharlie.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/limacharlie.mdx
@@ -1,5 +1,6 @@
---
title: "LimaCharlie alert integration"
+sidebarTitle: "LimaCharlie"
description: "Send detections from LimaCharlie Detection & Response (D&R) rules to Flashduty On-call through a webhook output."
keywords: ["alert integration", "LimaCharlie", "EDR", "D&R", "detection", "webhook", "detect_id"]
---
@@ -11,7 +12,6 @@ LimaCharlie sends a detection once, when the rule matches, and sends no recovery
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure LimaCharlie
----
<Steps>
<Step title="Add a webhook output">
@@ -63,14 +62,12 @@ For an end-to-end check, let a D&R rule match once and confirm the alert arrives
</Steps>
## Alert Key
----
Flashduty uses the detection's `detect_id` as the Alert Key. The LimaCharlie documentation defines it as the unique detection identifier. A resent detection keeps its `detect_id` and merges into the same alert, and different detections become separate alerts.
`cat` (the detection name), `priority`, and timestamps are not part of the Alert Key. A request that has `cat` but no `detect_id` is rejected with a parameter error.
## Severity
----
LimaCharlie provides only an optional integer `priority` (0 to 10) with no defined levels. The Flashduty mapping is:
@@ -82,7 +79,6 @@ LimaCharlie provides only an optional integer `priority` (0 to 10) with no defin
| 0, missing, or not a number | Warning |
## Field mapping
----
| Flashduty | LimaCharlie field |
| :--- | :--- |
@@ -93,12 +89,10 @@ LimaCharlie provides only an optional integer `priority` (0 to 10) with no defin
The matched event (`detect`) and the extracted IOCs (`detect_data`) are not copied into labels.
## Alerts do not recover
----
A detection is a one-shot event and LimaCharlie sends no recovery. In the channel that receives this integration, turn on the [auto-resolve timeout](/en/on-call/channel/create-edit). 24 hours is a reasonable start; adjust it to how quickly your team handles detections.
## Troubleshooting
----
<AccordionGroup>
<Accordion title="LimaCharlie reports a failed or temporarily disabled output">
diff --git a/en/on-call/integration/alert-integration/alert-sources/loadster.mdx b/en/on-call/integration/alert-integration/alert-sources/loadster.mdx
index 283c79be..0a8cc80f 100644
--- a/en/on-call/integration/alert-integration/alert-sources/loadster.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/loadster.mdx
@@ -1,5 +1,6 @@
---
title: "Loadster alert integration"
+sidebarTitle: "Loadster"
description: "Send Loadster monitor failure and recovery notifications to Flashduty On-call through the Loadster webhook integration."
keywords: ["alert integration", "Loadster", "synthetic monitoring", "uptime", "webhook"]
---
@@ -9,7 +10,6 @@ Use the Loadster webhook integration to send monitor failure (**Monitor Fails**)
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Loadster
----
<Steps>
<Step title="Enable webhooks">
@@ -60,7 +59,6 @@ Make a monitor fail (for example, point an HTTP Request Monitor at a URL that re
</Steps>
## Payload
----
Loadster POSTs the following fields as JSON. Flashduty parses them directly, so no template is needed:
@@ -76,12 +74,10 @@ Loadster POSTs the following fields as JSON. Flashduty parses them directly, so
When the monitor name is empty, the alert title is `Loadster monitor <monitor.id>`.
## Alert Key
----
Flashduty uses `monitor.id` as the Alert Key. The failure and recovery notifications of one monitor carry the same `monitor.id`, so they land on the same alert. Renaming the monitor does not change the Alert Key. The top-level `id` of the request is a new UUID for every notification and is not part of the Alert Key.
## Status and severity
----
Loadster notifications carry no severity, so Flashduty maps them as follows:
@@ -93,7 +89,6 @@ Loadster notifications carry no severity, so Flashduty maps them as follows:
Notifications without `monitor.id` (for example, load test started and finished notifications) are acknowledged and ignored without creating an alert. The Loadster webhook has no test button.
## FAQ
----
<AccordionGroup>
<Accordion title="Do I get repeated notifications while a monitor keeps failing?">
@@ -110,7 +105,6 @@ The Loadster webhook applies to the whole account. To separate monitors, use rou
</AccordionGroup>
## Troubleshooting
----
- **Loadster does not push**: confirm webhooks are enabled and saved under **Account → Integrations → Webhooks**, and that both URLs are the complete push URL containing `integration_key`
- **Flashduty returns a parameter error**: confirm the request body contains `monitor.id` and `cycle.status`
diff --git a/en/on-call/integration/alert-integration/alert-sources/loggly.mdx b/en/on-call/integration/alert-integration/alert-sources/loggly.mdx
index 5ac70e74..acb136f5 100644
--- a/en/on-call/integration/alert-integration/alert-sources/loggly.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/loggly.mdx
@@ -1,5 +1,6 @@
---
title: "Loggly alert integration"
+sidebarTitle: "Loggly"
description: "Sync log alerts from Loggly (a SolarWinds product) to Flashduty On-call through HTTP Endpoints."
keywords: ["alert integration", "Loggly", "SolarWinds", "HTTP Endpoints", "log alert", "webhook"]
---
@@ -13,7 +14,6 @@ Loggly's alert feature is available only on paid plans (Standard, Pro); the free
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -34,7 +34,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Loggly
----
<Steps>
<Step title="Create or edit an alert">
@@ -89,7 +88,6 @@ Loggly's HTTP Endpoints has no separate test-delivery button. Make the saved sea
</Steps>
## Alert Key
----
Flashduty keys the alert on the Loggly account subdomain (`owner_subdomain`) combined with the alert-definition ID. The alert-definition ID is parsed from `edit_alert_link` (the alert's edit-page URL) — the number after `/alerts/edit/`, for example `8188` in `.../alerts/edit/8188`.
@@ -98,12 +96,10 @@ A request is rejected if `edit_alert_link` is missing, or is not shaped like `/a
Repeated notifications from the same alert definition while its condition holds merge into one Flashduty alert instead of opening a new one each time; changes to the alert name, hit count, time window, or query do not affect the Alert Key.
## Severity
----
Loggly's HTTP Endpoints notification carries no severity field, so every alert triggers at **Warning**. A saved search crossing its hit-count threshold is not on its own an outage signal; raise the severity with an alert rule in Flashduty if a given saved search warrants it.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -118,7 +114,6 @@ Loggly's HTTP Endpoints notification carries no severity field, so every alert t
| `num_hits` | Number of log lines matched in this check window |
## FAQ
----
<AccordionGroup>
diff --git a/en/on-call/integration/alert-integration/alert-sources/logicmonitor.mdx b/en/on-call/integration/alert-integration/alert-sources/logicmonitor.mdx
index 5eae67e4..7c32b5ed 100644
--- a/en/on-call/integration/alert-integration/alert-sources/logicmonitor.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/logicmonitor.mdx
@@ -1,5 +1,6 @@
---
title: "LogicMonitor alert integration"
+sidebarTitle: "LogicMonitor"
description: "Send LogicMonitor alerts to Flashduty On-call through a LogicMonitor Custom HTTP Delivery integration. Alerts close automatically when they clear in LogicMonitor."
keywords: ["alert integration", "LogicMonitor", "Custom HTTP Delivery", "webhook", "infrastructure monitoring"]
---
@@ -9,7 +10,6 @@ LogicMonitor pushes alerts through a **Custom HTTP Delivery** integration: every
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure LogicMonitor
----
The steps below need a LogicMonitor user who can manage **Integrations**, **Escalation Chains**, and **Alert Rules**.
@@ -112,7 +111,6 @@ Make a datapoint cross its alert threshold (for example, temporarily lower the t
</Steps>
## Alert Key
----
Flashduty uses `alert_id` (`##ALERTID##`, for example `LMD12345`) as the Alert Key. The LogicMonitor docs state that all alerts on one resource (or website), LogicModule, instance, and datapoint combination share the same alert ID, so the raise, severity change, and clear notifications land on one Flashduty alert. A new alert after a clear opens a new Flashduty alert.
@@ -121,7 +119,6 @@ Changes to the severity, value, threshold, or alert message do not change the Al
Flashduty rejects requests without `alert_id` or `alert_status`, or where either field is still the unreplaced `##ALERTID##` or `##ALERTSTATUS##`.
## Alert lifecycle
----
Flashduty handles each notification by its `alert_status` field (`##ALERTSTATUS##`):
@@ -136,7 +133,6 @@ Flashduty handles each notification by its `alert_status` field (`##ALERTSTATUS#
If you select **Acknowledged** in the integration, LogicMonitor sends an `ack` notification when an alert is acknowledged. An acknowledgement neither opens nor closes a Flashduty alert, and ignored notifications return success.
## Severity
----
The severity comes from the `level` field (`##LEVEL##`), case-insensitive:
@@ -150,7 +146,6 @@ The severity comes from the `level` field (`##LEVEL##`), case-insensitive:
The clear notification carries the level of the alert that cleared, and the recovery event keeps that severity.
## Alert content
----
- **Title**: `<DataSource> <datapoint> on <resource>`, where the resource is the host name, or the website name for website alerts. Without a DataSource and datapoint, the title is the resource name; with none of them, it is `LogicMonitor alert <alert_id>`
- **Description**: the alert message rendered by `##MESSAGE##`, as configured in the LogicModule
@@ -159,7 +154,6 @@ The clear notification carries the level of the alert that cleared, and the reco
Empty fields are not written as labels. When a field does not apply to the alert type (for example, website alerts have no datapoint), LogicMonitor may leave a placeholder such as `##DATAPOINT##` as-is; Flashduty treats it as empty.
## Troubleshooting
----
- **Test Alert Delivery fails**: make sure **URL** is the full push URL including the `integration_key` parameter, and that **HTTP Method** is `HTTP Post`
- **Flashduty says the body is not valid JSON**: make sure **Alert Data** uses **Raw** with the **JSON** format, and that every `##TOKEN##` in the template is inside double quotes
diff --git a/en/on-call/integration/alert-integration/alert-sources/logpoint.mdx b/en/on-call/integration/alert-integration/alert-sources/logpoint.mdx
index e0dbec1f..9496dff1 100644
--- a/en/on-call/integration/alert-integration/alert-sources/logpoint.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/logpoint.mdx
@@ -1,5 +1,6 @@
---
title: "Logpoint alert integration"
+sidebarTitle: "Logpoint"
description: "Send triggered Logpoint (Guardsix) alert rules to Flashduty On-call through the HTTP Notification."
keywords: ["alert integration", "Logpoint", "Guardsix", "SIEM", "HTTP Notification", "alertrule_id"]
---
@@ -11,14 +12,12 @@ Logpoint sends a notification only when the rule triggers and sends nothing when
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **Logpoint** alert integration and copy its complete Push URL.
</div>
## Configure Logpoint
----
The Logpoint HTTP Notification has no fixed payload; the body comes from the Jinja template you enter. Flashduty parses only the template below.
@@ -69,12 +68,10 @@ Trigger the alert rule (or wait for it to match) and confirm Flashduty receives
</Steps>
## Alert Key
----
Flashduty uses `alertrule_id` (`{{alertrule_id}}`) as the Alert Key. The Logpoint documentation defines it as the ID of the alert. When the same rule triggers again it merges into the alert that is still open. `incident_id` changes on every trigger, so it is kept only as a label. Changes to the rule name, risk level or number of matching logs do not change the Alert Key.
## Status and severity
----
Flashduty maps severity from `risk_level` (`{{risk_level}}`):
@@ -88,12 +85,10 @@ Flashduty maps severity from `risk_level` (`{{risk_level}}`):
The Logpoint documentation does not list every `risk_level` value; its examples use `medium` and `high`, and `critical` and `low` are inferred from the risk options in the rule editor.
## Alerts do not recover
----
Logpoint sends no recovery notification. In the channel that receives this integration, turn on the [auto-resolve timeout](/en/on-call/channel/create-edit). 24 hours is a reasonable start; adjust it to how quickly your team handles alerts.
## Troubleshooting
----
- **Logpoint sends no request**: confirm Notification Trigger is **Automatic** and the rule is enabled and actually matching
- **Flashduty returns a parameter error**: confirm the Body is valid JSON and keeps `alertrule_id`; double quotes in a log source or rule name break the JSON
diff --git a/en/on-call/integration/alert-integration/alert-sources/logrocket.mdx b/en/on-call/integration/alert-integration/alert-sources/logrocket.mdx
index 7728f7d3..52e4c46a 100644
--- a/en/on-call/integration/alert-integration/alert-sources/logrocket.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/logrocket.mdx
@@ -1,5 +1,6 @@
---
title: "LogRocket alert integration"
+sidebarTitle: "LogRocket"
description: "Send LogRocket Timeseries chart alerts to Flashduty On-call through a webhook."
keywords: ["alert integration", "LogRocket", "webhook", "frontend monitoring", "Timeseries"]
---
@@ -9,7 +10,6 @@ Use the Webhook alert type of a LogRocket Timeseries chart to send metric alerts
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure LogRocket
----
<Steps>
<Step title="Add a Webhook alert to a Timeseries chart">
@@ -54,12 +53,10 @@ Push the metric past the threshold and confirm Flashduty receives an active aler
The Issues Alerts webhook (new severe issues) uses a different message format and carries no alert ID, so it cannot be tied to a recovery. Flashduty acknowledges it and creates no alert.
## Alert Key
----
The Alert Key is the `alert_id` LogRocket sends. LogRocket documents that this ID stays the same across multiple triggerings and resolutions of the same alert, so the trigger and recovery events share one Alert Key. Editing the alert's threshold, interval, or chart location does not change it. Requests without `alert_id` are rejected.
## Status and severity
----
| LogRocket `status` | Flashduty status | Flashduty severity |
| :--- | :--- | :--- |
@@ -69,7 +66,6 @@ The Alert Key is the `alert_id` LogRocket sends. LogRocket documents that this I
The LogRocket webhook carries no severity, and a metric crossing a threshold is not the same as an outage, so every alert is Warning. Any other `status` value is rejected.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -86,7 +82,6 @@ The LogRocket webhook carries no severity, and a metric crossing a threshold is
The alert title and description come from `reason`, which LogRocket fills with the alert name you entered. Without `reason` the title is `LogRocket alert <alert_id>`.
## Troubleshooting
----
- **Flashduty returns an invalid parameter error**: check that the URL is complete and includes `integration_key`, and that the request comes from a Timeseries chart alert rather than Issues Alerts
- **The alert does not recover**: check that the resolved notification is sent to the same URL and that its `alert_id` matches the one sent on trigger
diff --git a/en/on-call/integration/alert-integration/alert-sources/logz-io.mdx b/en/on-call/integration/alert-integration/alert-sources/logz-io.mdx
index ff36504f..ec8bab92 100644
--- a/en/on-call/integration/alert-integration/alert-sources/logz-io.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/logz-io.mdx
@@ -1,5 +1,6 @@
---
title: "Logz.io alert integration"
+sidebarTitle: "Logz.io"
description: "Send Logz.io log alert triggers to Flashduty On-call through a Custom Endpoint."
keywords: ["alert integration", "Logz.io", "Custom Endpoint", "webhook", "alert_definition_id"]
---
@@ -11,7 +12,6 @@ A Logz.io Custom Endpoint only fires while the alert condition is met — there
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Logz.io
----
<Steps>
<Step title="Create a Custom Endpoint">
@@ -87,7 +86,6 @@ A Logz.io Custom Endpoint has no recovery event: once the alert condition return
</Steps>
## Alert Key
----
Flashduty uses `alert_definition_id` as the Alert Key. Logz.io's own documentation describes it as the "Unique alert ID" (the alert definition's ID), as opposed to `alert_event_id`, the "Unique ID of the triggered alert instance" — which changes on every notification. So repeated firings of the same alert definition (including the repeat after the wait period ends, and escalation notifications across severity thresholds) land on the same Flashduty alert, while different alert definitions stay separate.
@@ -96,7 +94,6 @@ Logz.io's Custom Endpoint variables do not expose the value of a group-by field.
Changes to the title, description, severity, or timeframe never change the Alert Key. A request without `alert_definition_id` is rejected.
## Severity
----
| Logz.io `alert_severity` | Flashduty severity |
| :--- | :--- |
@@ -109,14 +106,12 @@ Changes to the title, description, severity, or timeframe never change the Alert
`alert_severity` corresponds to the severity threshold (`severityThresholdTiers`) configured on the Logz.io alert; the value is matched case-insensitively. An empty or unlisted value is rejected. Because the Custom Endpoint never sends a recovery event, the alert status always equals the severity above — there is no "recovered" state.
## Alert content
----
- **Title**: `alert_title`; falls back to `Logz.io alert` when empty
- **Description**: `alert_description`
- **Labels**: `check` (the title), `source` (fixed to `logz_io`), `alert_definition_id`, `alert_event_id`, `account_id`, `account_name`, `alert_tags`, `alert_timeframe_start`, `alert_timeframe_end`, `alert_app_url`, `vendor_severity` (the raw `alert_severity` value)
## Troubleshooting
----
- **Flashduty returns a parameter error**: make sure the message body is valid JSON, `alert_definition_id` and `alert_severity` are not empty, and the `Content-Type: application/json` header is set
- **A real alert never arrives (the test always shows failed, which is expected)**: make sure the alert's **Notification endpoints** include this Custom Endpoint, and that the alert condition actually triggered
diff --git a/en/on-call/integration/alert-integration/alert-sources/mackerel.mdx b/en/on-call/integration/alert-integration/alert-sources/mackerel.mdx
index 7066bdd2..10de3e2c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/mackerel.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/mackerel.mdx
@@ -1,5 +1,6 @@
---
title: "Mackerel alert integration"
+sidebarTitle: "Mackerel"
description: "Send Mackerel alerts to Flashduty On-call through a Webhook notification channel; alerts recover automatically when they close."
keywords: ["alert integration", "Mackerel", "webhook", "server monitoring", "external monitoring"]
---
@@ -9,7 +10,6 @@ Use a Mackerel Webhook notification channel to send Mackerel alerts to Flashduty
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Mackerel
----
<Steps>
<Step title="Add a Webhook notification channel">
@@ -60,14 +59,12 @@ A new channel is added to the default notification group, which receives every n
</Steps>
## Alert Key
----
Flashduty uses the Mackerel alert's `alert.id` as the Alert Key. A Mackerel alert keeps the same ID from the moment it opens, through status changes, until it closes, so these notifications merge into one Flashduty alert.
When the same monitor fires again after its alert closed, Mackerel creates a new alert ID and Flashduty creates a new alert. Changes to the monitor name, message, metric value, or host status do not change the Alert Key. Alert notifications without `alert.id` are rejected.
## Status and severity
----
| Mackerel `alert.status` | `alert.isOpen` | Status | Flashduty severity |
| :--- | :--- | :--- | :--- |
@@ -80,7 +77,6 @@ When the same monitor fires again after its alert closed, Mackerel creates a new
Mackerel ranks Unknown at the same level as Critical, so Flashduty maps it to Critical. Closing an alert manually, deleting its monitor, retiring its host, or deleting its service all close the alert (`alert.isOpen` is `false`), and Flashduty recovers the alert.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -101,7 +97,6 @@ Mackerel ranks Unknown at the same level as Critical, so Flashduty maps it to Cr
The alert `message` and the monitor `memo` are written to the alert description.
## Troubleshooting
----
- **Flashduty returns a parameter error**: Make sure the URL is complete and includes `integration_key`
- **No alerts arrive**: Make sure the channel subscribes to the alert (`alert`) event, the channel's notification group includes the monitor, the host status is `working` (Mackerel does not send alert notifications for hosts in `standby`, `maintenance`, or `poweroff`), and the monitor's notifications are not muted
diff --git a/en/on-call/integration/alert-integration/alert-sources/meraki.mdx b/en/on-call/integration/alert-integration/alert-sources/meraki.mdx
index 1c34b67d..2da96b6b 100644
--- a/en/on-call/integration/alert-integration/alert-sources/meraki.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/meraki.mdx
@@ -1,5 +1,6 @@
---
title: "Meraki Alert Events"
+sidebarTitle: "Meraki"
description: "Sync Meraki alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,46 +9,45 @@ Sync Meraki alert events to Flashduty via webhook for automated alert noise redu
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Meraki** integration, click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event payload.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Meraki** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Meraki
----
<div class="md-block">
-## I. Meraki Alert Push Configuration
1. Log in to your `Meraki` console and select the device you want to configure alerts for
2. On the `Alerts` page, configure `Cellular gateway` and other sections as needed
@@ -59,7 +59,7 @@ Choose this option when you need to route alerts to different channels based on
<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/meraki-5.png" />
-## II. Status Mapping
+## Status Mapping
| Meraki | Flashduty | Status |
| ---------- | -------- | ---- |
diff --git a/en/on-call/integration/alert-integration/alert-sources/metoro.mdx b/en/on-call/integration/alert-integration/alert-sources/metoro.mdx
index 00335079..3f677d2a 100644
--- a/en/on-call/integration/alert-integration/alert-sources/metoro.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/metoro.mdx
@@ -1,5 +1,6 @@
---
title: "Metoro alert integration"
+sidebarTitle: "Metoro"
description: "Send Metoro alert trigger and recovery events to Flashduty On-call through a webhook destination."
keywords: ["alert integration", "Metoro", "Kubernetes", "webhook", "observability"]
---
@@ -11,14 +12,12 @@ You write the Metoro webhook body yourself in **Body Template**, and Metoro subs
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **Metoro** alert integration and copy its complete Push URL.
</div>
## Configure Metoro
----
<Steps>
<Step title="Add a webhook">
@@ -65,7 +64,6 @@ Metoro has no separate test button. Let an alert that uses this webhook fire for
</Steps>
## Alert Key
----
Flashduty uses `alert_fire_uuid` (Metoro's `$alert_fire_uuid`, the UUID of one fire instance) as the Alert Key. Metoro's own Rootly integration guide pairs firing and resolved notifications on this same field (identifier `$.metoro_alert_fire_uuid`, state field `resolved`), and states that for alerts with a group by, each group value has its own `$alert_fire_uuid` while `$alert_uuid` is the same for all of them.
@@ -74,7 +72,6 @@ Flashduty uses `alert_fire_uuid` (Metoro's `$alert_fire_uuid`, the UUID of one f
- Changes to `description`, `value`, and similar fields don't change the Alert Key
## Status and severity
----
| Metoro `$alert_state` | Flashduty status or severity |
| :--- | :--- |
@@ -84,7 +81,6 @@ Flashduty uses `alert_fire_uuid` (Metoro's `$alert_fire_uuid`, the UUID of one f
Metoro alerts have no severity field, so every alert is treated as Warning. An empty or other state value is rejected. To distinguish severity, adjust it with rules in the Flashduty channel.
## Troubleshooting
----
- **Metoro reports a webhook failure (400)**: confirm the Body Template is valid JSON and that `alert_fire_uuid` and `state` are not empty. Metoro escapes variables automatically for JSON requests, so don't add escaping yourself
- **404 or 401**: confirm the Push URL is complete and includes `integration_key`
diff --git a/en/on-call/integration/alert-integration/alert-sources/mezmo.mdx b/en/on-call/integration/alert-integration/alert-sources/mezmo.mdx
index 7dc194f9..746f5a39 100644
--- a/en/on-call/integration/alert-integration/alert-sources/mezmo.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/mezmo.mdx
@@ -1,5 +1,6 @@
---
title: "Mezmo alert integration"
+sidebarTitle: "Mezmo"
description: "Sync matches from a Mezmo (formerly LogDNA) log view to Flashduty On-call through a Webhook Alert."
keywords: ["alert integration", "Mezmo", "LogDNA", "log alert", "webhook", "View", "Alert"]
---
@@ -13,7 +14,6 @@ Mezmo's own docs say `autoresolve` "only applies to PagerDuty" — the Webhook c
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -34,7 +34,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Mezmo
----
<Steps>
<Step title="Create or open a View">
@@ -89,12 +88,10 @@ Click the **Test** link at the top of the Alert panel and confirm Flashduty retu
</Steps>
## Alert Key
----
Mezmo's Webhook Alert request body has no alert id, View id, or dedup key — none of the [12 documented body tokens](https://docs.mezmo.com/docs/webhook-alert-integration#body-tokens) (`name`, `matches`, `lines`, `level`, `url`, `query`, `app`, `host`, `tag`, `line`, `line_objects`, `first_line_object`) is an identifier. The View name and the query it runs are the check's identity across repeated matches — the docs define `query` as "the query of the View to which this alert is attached" — so Flashduty keys on `MD5(view_name, query)`: repeated matches of the same View and query merge into the same alert (the first matched line, match count, level, and other fields changing does not change this key); a different View, or the same View with an edited query, opens its own alert.
## Severity
----
Mezmo's own docs describe `{{ level }}` only as "Severity level (info, warn, error, etc)" — the first matched log line's level — without a full enumeration. Flashduty maps it using the table below; any value not listed, including an empty one (the log line had no parsed level), is treated as **Warning**:
@@ -106,7 +103,6 @@ Mezmo's own docs describe `{{ level }}` only as "Severity level (info, warn, err
| Empty or any other unrecognized value | Warning |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -122,7 +118,6 @@ Mezmo's own docs describe `{{ level }}` only as "Severity level (info, warn, err
The alert title is the View name; the description leads with the raw text of the first matched log line (`{{ line }}`), followed by the query.
## FAQ
----
<AccordionGroup>
diff --git a/en/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud.mdx b/en/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud.mdx
index c8dccac6..06b9284d 100644
--- a/en/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud.mdx
@@ -1,5 +1,6 @@
---
title: "Microsoft Defender for Cloud Alert Integration"
+sidebarTitle: "Microsoft Defender for Cloud"
description: "Run a Logic App from Defender for Cloud workflow automation and use its HTTP action to push security alerts to Flashduty's standard alert event integration."
keywords: ["alert integration", "Microsoft Defender for Cloud", "Azure Security Center", "Logic App", "workflow automation", "cloud security", "standard alert event"]
---
@@ -11,7 +12,6 @@ If the same tenant already sends Defender for Cloud alerts to Microsoft Sentinel
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the Standard Alert Event integration type** in both, not Microsoft Defender for Cloud.
@@ -32,7 +32,6 @@ Get an integration push URL in either of the two ways below. **Choose the Standa
</div>
## Configure in Microsoft Defender for Cloud
----
You need the **Security admin** role or **Owner** on the resource group; creating and editing Logic Apps needs **Logic App Contributor**.
@@ -54,7 +53,6 @@ You need the **Security admin** role or **Owner** on the resource group; creatin
You can also open a single security alert and click **Trigger logic app** to run the Logic App for that alert manually.
## HTTP action
----
Fields of the HTTP action:
@@ -107,7 +105,6 @@ In the designer, the same values map to these dynamic contents (outputs of the *
| Labels `product_name`, `vendor_name` | Product Name, Vendor Name | `ProductName`, `VendorName` |
## Field mapping
----
| Defender for Cloud field | Flashduty |
| :--- | :--- |
@@ -119,12 +116,10 @@ In the designer, the same values map to these dynamic contents (outputs of the *
| Alert Uri | Label `alert_url`, which opens the alert details in the Azure portal |
## Recovery and deduplication
----
Defender for Cloud workflow automation runs the Logic App only when an alert is created or triggered and sends nothing when the alert is dismissed, so alerts from this integration do not recover automatically. Enable [auto-resolve timeout](/en/on-call/channel/create-edit) on the channel that receives this integration, with a suggested window of 3 days or the time your team usually takes to handle alerts; you can also close alerts manually in Flashduty.
## Troubleshooting
----
- **Flashduty returns `InvalidParameter`**: check that `event_status` is one of the capitalized `Critical`, `Warning`, `Info`, and that `title_rule` is not empty
- **The Logic App is missing from the workflow automation list**: the list shows only Consumption Logic Apps that use a Defender for Cloud connector; click **Refresh** after creating it
diff --git a/en/on-call/integration/alert-integration/alert-sources/microsoft-sentinel.mdx b/en/on-call/integration/alert-integration/alert-sources/microsoft-sentinel.mdx
index 0cef2c21..44245921 100644
--- a/en/on-call/integration/alert-integration/alert-sources/microsoft-sentinel.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/microsoft-sentinel.mdx
@@ -1,5 +1,6 @@
---
title: "Microsoft Sentinel Alert Integration"
+sidebarTitle: "Microsoft Sentinel"
description: "Run a Logic App from a Microsoft Sentinel automation rule and use its HTTP action to push incidents to Flashduty's standard alert event integration; closing the incident recovers the alert."
keywords: ["alert integration", "Microsoft Sentinel", "Azure Sentinel", "Logic App", "SIEM", "automation rule", "standard alert event"]
---
@@ -11,7 +12,6 @@ Sentinel incidents also include alerts from Microsoft security products such as
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the Standard Alert Event integration type** in both, not Microsoft Sentinel.
@@ -32,7 +32,6 @@ Get an integration push URL in either of the two ways below. **Choose the Standa
</div>
## Configure in Microsoft Sentinel
----
There are two parts: create a Logic App that starts with the **Microsoft Sentinel incident** trigger (called a playbook in Sentinel), then create automation rules that run it.
@@ -54,7 +53,6 @@ In Microsoft Sentinel, go to **Configuration** → **Automation** (in the Defend
If the playbook appears grayed out in the list, Sentinel has no permission on its resource group: click **Manage playbook permissions**, select the resource group and click **Apply** (this needs the **Owner** role on the resource group).
## HTTP action
----
Fields of the HTTP action:
@@ -105,7 +103,6 @@ In the designer, the same values map to these dynamic contents (outputs of the M
| Labels `workspace`, `resource_group` | Workspace Name, Resource Group Name | `workspaceInfo.WorkspaceName`, `workspaceInfo.ResourceGroupName` |
## Field mapping
----
| Sentinel field | Flashduty |
| :--- | :--- |
@@ -117,7 +114,6 @@ In the designer, the same values map to these dynamic contents (outputs of the M
| Incident URL and others | Labels of the same name; `incident_url` opens the incident from the alert details |
## Recovery and deduplication
----
- When the incident is closed (**Status** becomes `Closed`), the Logic App sends an event with `event_status` set to `Ok`, and Flashduty closes the alert with the same Alert Key.
- Sentinel also fires **When incident is updated** when alerts, comments or tags are added. The update rule above runs only on status or severity changes; if you remove those conditions, every update is pushed, and repeated events with the same Alert Key merge into the original alert.
@@ -125,7 +121,6 @@ In the designer, the same values map to these dynamic contents (outputs of the M
- An incident that groups several Sentinel alerts is pushed as one Flashduty alert; the title and description come from the incident itself.
## Troubleshooting
----
- **Flashduty returns `InvalidParameter`**: check that `event_status` is one of the four capitalized values and that `title_rule` is not empty
- **The HTTP action returns a 4xx about authentication or routing**: the push URL lacks `integration_key`, or it is not the push URL of a Standard Alert Event integration
diff --git a/en/on-call/integration/alert-integration/alert-sources/moesif.mdx b/en/on-call/integration/alert-integration/alert-sources/moesif.mdx
index 0c8493e1..640b0a3f 100644
--- a/en/on-call/integration/alert-integration/alert-sources/moesif.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/moesif.mdx
@@ -1,5 +1,6 @@
---
title: "Moesif alert integration"
+sidebarTitle: "Moesif"
description: "Send Moesif API monitoring alerts to Flashduty On-call through a Moesif webhook notification channel."
keywords: ["alert integration", "Moesif", "API monitoring", "API analytics", "webhook"]
---
@@ -11,7 +12,6 @@ Moesif notifies only when an alert triggers and has no recovery notification, so
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Moesif
----
<Steps>
<Step title="Create a webhook notification channel">
@@ -65,26 +64,22 @@ The **Notification Throttle** of a channel or rule and **Silencing alerts** stop
</Note>
## Recovery and auto-close
----
Moesif notifies only when a rule triggers. The request body has no alert ID and no field that marks a recovery, so the alert in Flashduty does not recover on its own.
Each Moesif notification is a separate Flashduty alert. Close it by hand, or turn on [auto-close](/en/on-call/channel/create-edit) in the channel that receives this integration. We suggest twice the rule's evaluation period, for example 30 minutes for a 15-minute rule.
## Alert Key
----
The request has no field that identifies the same alert across notifications, so Flashduty generates a random Alert Key for each notification. Different notifications never merge into one alert.
## Status and severity
----
Moesif alerts carry no severity. The alert in Flashduty is always **Warning**; its status equals its severity and it does not recover.
A notification whose `type` is not `alert` (for example another kind of notification sent to the same channel) is ignored and creates no alert.
## Alert content
----
- **Title**: the alert rule name `name`. When the notification has a single group value, it is appended, for example `Latency per user: user-1`. Without a rule name the title is `Moesif alert`
- **Description**: the rule condition `metric`, then each group value with its current value and, for dynamic alerts, its direction; up to 20 are listed
@@ -100,7 +95,6 @@ A notification whose `type` is not `alert` (for example another kind of notifica
| `feature_count` | Number of group values, when the notification has more than one |
## Troubleshooting
----
- **Flashduty receives nothing**: check that the rule is on and selects the channel in **Send To**, and that the channel's Webhook URL is the full push URL including `integration_key`. In Moesif **Alert History**, check that the rule triggered and was not suppressed by a throttle or silencing
- **Flashduty returns a parameter error**: the body is not JSON, or has neither `name` nor `metric_values`. Use Moesif's built-in webhook channel and do not rewrite the body
diff --git a/en/on-call/integration/alert-integration/alert-sources/mongodb-atlas.mdx b/en/on-call/integration/alert-integration/alert-sources/mongodb-atlas.mdx
index 93c3cf46..5698c986 100644
--- a/en/on-call/integration/alert-integration/alert-sources/mongodb-atlas.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/mongodb-atlas.mdx
@@ -1,5 +1,6 @@
---
title: "MongoDB Atlas alert integration"
+sidebarTitle: "MongoDB Atlas"
description: "Send MongoDB Atlas project alerts to Flashduty On-call through a webhook. Alerts recover automatically when Atlas closes them."
keywords: ["alert integration", "MongoDB", "MongoDB Atlas", "Atlas", "webhook"]
---
@@ -9,7 +10,6 @@ Use the webhook integration of a MongoDB Atlas project to send Atlas alerts to F
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure MongoDB Atlas
----
Configuring the webhook integration requires the `Project Owner` role on the project or the `Organization Owner` role. Editing alert settings requires `Project Owner` or `Project Alerts Manager`.
@@ -74,14 +73,12 @@ Atlas requires the webhook URL to be reachable from the internet and to return 2
</Tip>
## Alert Key
----
Flashduty uses the alert `id` in the request body as the Alert Key. The Atlas documentation defines `id` as the unique identifier of the alert. The open, update, acknowledge, close, and cancel notifications of one alert carry the same `id`, so they land on the same Flashduty alert.
Changes to `status`, `currentValue`, `humanReadable`, or the timestamps do not change the Alert Key. Flashduty rejects a request without `id`, because it could not be matched to its recovery.
## Status and severity
----
Atlas sets the alert state in the `X-MMS-Event` request header:
@@ -112,7 +109,6 @@ Atlas evaluates host conditions on each node of a replica set, and each node's a
An informational alert is a point-in-time event. Each notification carries a new `id`, and Atlas never sends a close notification for it. These alerts do not recover automatically in Flashduty: close them by hand, or turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit).
## Alert content
----
- **Title**: `metricName`, or `eventTypeName` when it is empty, followed by ` on <resource>` when a resource is known, for example `CONNECTIONS on Cluster0`
- **Description**: `humanReadable`, which contains the project name, organization name, and alert details
@@ -121,7 +117,6 @@ An informational alert is a point-in-time event. Each notification carries a new
The acknowledging user `acknowledgingUsername` and the acknowledgement comment are not written to labels.
## Troubleshooting
----
- **The Atlas Activity Feed shows failed deliveries**: check that **Webhook URL** is the full push URL including `integration_key`
- **Flashduty returns a parameter error**: check that no **Webhook Body Template** is set and that the body contains `id`
diff --git a/en/on-call/integration/alert-integration/alert-sources/monit.mdx b/en/on-call/integration/alert-integration/alert-sources/monit.mdx
index 4f27a8ee..c0424061 100644
--- a/en/on-call/integration/alert-integration/alert-sources/monit.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/monit.mdx
@@ -1,5 +1,6 @@
---
title: "Monit Alert Integration"
+sidebarTitle: "Monit"
description: "Flashduty Monit alert integration, Monit service reports alerts through this integration"
---
@@ -13,6 +14,6 @@ You cannot modify or delete this integration. However, you can manage the label
Go to the `Monit` - `Alert Rules` - `Rule Details` page to configure monitoring metrics and threshold conditions, and enable alerts. You can choose to deliver alerts to multiple channels. Alert notification rules follow the escalation rules under the channel, and you can set responders for the team to assign to responders when alerts occur.
-
+
In some cases, you may want to route alerts generated by the same alert rule to different channels based on conditions. In this case, you can choose to deliver alerts directly to the integration rather than to the channels, and set routing rules under the current integration.
diff --git a/en/on-call/integration/alert-integration/alert-sources/monitive.mdx b/en/on-call/integration/alert-integration/alert-sources/monitive.mdx
index d5353d0c..5abac120 100644
--- a/en/on-call/integration/alert-integration/alert-sources/monitive.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/monitive.mdx
@@ -1,5 +1,6 @@
---
title: "Monitive alert integration"
+sidebarTitle: "Monitive"
description: "Send Monitive (uptimemonitoring.com) down, flapping, and recovery notifications to Flashduty On-call through a monitor webhook."
keywords: ["alert integration", "Monitive", "uptimemonitoring.com", "Uptime", "webhook", "monitor_id"]
---
@@ -9,7 +10,6 @@ Use a Monitive (uptimemonitoring.com) monitor webhook to send down (`monitor.dow
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Monitive
----
Monitive webhooks are set per monitor, and each monitor has one webhook slot. Set the webhook on every monitor you want to send to Flashduty.
@@ -65,7 +64,6 @@ Every Monitive delivery carries an `X-UptimeMonitoring-Signature` (HMAC-SHA256)
</Note>
## Payload
----
Monitive POSTs the following fields as `application/json`. Flashduty parses them directly; no template is needed:
@@ -82,14 +80,12 @@ Monitive POSTs the following fields as `application/json`. Flashduty parses them
The alert title is the monitor name; if it is empty, the monitored URL is used, then `Monitive monitor <monitor_id>`.
## Alert Key
----
Flashduty uses `monitor_id` as the Alert Key. Down, flapping, and recovery notifications of one monitor carry the same `monitor_id`, so they land on the same alert; different monitors produce different alerts even when their names and URLs match. Renaming the monitor or changing its URL or reason does not change the Alert Key. `delivery_id` differs for every state change, so it is not part of the Alert Key.
A request without `monitor_id` is rejected with a parameter error, because its recovery could not be matched to the original alert. A request whose `event` is none of the three values is acknowledged and ignored without creating an alert.
## Status and severity
----
Monitive notifications carry no severity. A down monitor is an outage signal and maps to Critical; flapping maps to Warning.
@@ -100,7 +96,6 @@ Monitive notifications carry no severity. A down monitor is an outage signal and
| `monitor.up` | Recovery, keeping the alert's last severity |
## FAQ
----
<AccordionGroup>
<Accordion title="When does a flapping alert recover?">
@@ -123,7 +118,6 @@ Webhooks are included in the free plan, with one webhook per monitor and up to 5
</AccordionGroup>
## Troubleshooting
----
- **Flashduty receives no alert**: query `GET /api/v1/webhook-deliveries?monitor_id=<id>` in Monitive and check the delivery status and response code
- **Flashduty returns a parameter error**: confirm the body is Monitive's JSON and `monitor_id` is not empty
diff --git a/en/on-call/integration/alert-integration/alert-sources/monte-carlo.mdx b/en/on-call/integration/alert-integration/alert-sources/monte-carlo.mdx
index 9b2a3bf7..2b484107 100644
--- a/en/on-call/integration/alert-integration/alert-sources/monte-carlo.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/monte-carlo.mdx
@@ -1,5 +1,6 @@
---
title: "Monte Carlo alert integration"
+sidebarTitle: "Monte Carlo"
description: "Send anomaly events from the Monte Carlo data observability platform to Flashduty On-call through a webhook."
keywords: ["alert integration", "Monte Carlo", "data observability", "webhook", "incident_id"]
---
@@ -9,7 +10,6 @@ Use Monte Carlo's Webhook notification channel to send custom-rule breaches and
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Monte Carlo
----
<Steps>
<Step title="Create a webhook audience">
@@ -61,12 +60,10 @@ Monte Carlo's official docs don't publish a webhook connectivity test button, an
</Steps>
## Alert Key
----
Flashduty uses `payload.incident_id` as the Alert Key. Both example payloads in Monte Carlo's official docs (custom rule breach, volume anomaly) carry this field, and `payload.url` in the same payload is always `https://getmontecarlo.com/incidents/<incident_id>` — the address Monte Carlo's own console uses to locate that incident — which is how the docs imply this field stays the same throughout the incident's lifecycle. A request missing `incident_id` is rejected.
## Status and severity
----
Alert status is decided by `payload.alert_feedback`: it recovers when the value is `fixed`, `expected`, `no_action_needed`, or `false_positive`, and stays active for every other value (`investigating`, `no_status`, `work_in_progress`, and so on).
@@ -81,7 +78,6 @@ Alert severity is decided by `payload.declared_alert_severity`, which only appea
| Empty or never declared (the default) | Warning |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -100,7 +96,6 @@ Alert severity is decided by `payload.declared_alert_severity`, which only appea
Monte Carlo's official docs describe the audience owner field as an email address; Flashduty does not write email addresses into labels, for privacy.
## Troubleshooting
----
- **Monte Carlo reports the webhook call failed**: confirm the push URL is complete and includes `integration_key`
- **Flashduty returns a parameter error**: confirm the audience is configured as a Webhook channel, and that Monte Carlo isn't sending a custom payload — Flashduty only parses the official fixed format
diff --git a/en/on-call/integration/alert-integration/alert-sources/nagios.mdx b/en/on-call/integration/alert-integration/alert-sources/nagios.mdx
index c30da774..0f6f98c9 100644
--- a/en/on-call/integration/alert-integration/alert-sources/nagios.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/nagios.mdx
@@ -1,5 +1,6 @@
---
title: "Nagios Alert Events"
+sidebarTitle: "Nagios"
description: "Sync Nagios alert events to Flashduty via webhook for automated alert noise reduction"
keywords: ["alert integration", "Nagios alert events", "monitoring alerts", "data ingestion"]
---
@@ -7,42 +8,42 @@ keywords: ["alert integration", "Nagios alert events", "monitoring alerts", "dat
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels - it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Nagios** integration and click **Save** to generate a card
4. Click the generated card to view the **Push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event payload.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Nagios** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Nagios
----
<div class="md-block">
@@ -184,23 +185,23 @@ define contactgroup {
1. Verify the Nagios configuration file:
-- **Debian/Ubuntu systems**:
+ - **Debian/Ubuntu systems**:
-```bash
-/usr/sbin/nagios3 -v /etc/nagios3/nagios.cfg
-```
+ ```bash
+ /usr/sbin/nagios3 -v /etc/nagios3/nagios.cfg
+ ```
-- **RHEL/CentOS systems**:
+ - **RHEL/CentOS systems**:
-```bash
-/usr/sbin/nagios -v /etc/nagios/nagios.cfg
-```
+ ```bash
+ /usr/sbin/nagios -v /etc/nagios/nagios.cfg
+ ```
-- **Source installation**:
+ - **Source installation**:
-```bash
-/usr/local/nagios/bin/nagios -v /usr/local/nagios/etc/nagios.cfg
-```
+ ```bash
+ /usr/local/nagios/bin/nagios -v /usr/local/nagios/etc/nagios.cfg
+ ```
2. If verification passes, restart the Nagios service:
@@ -217,7 +218,6 @@ systemctl restart nagios
</div>
## Status Mapping
----
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/netbeez.mdx b/en/on-call/integration/alert-integration/alert-sources/netbeez.mdx
index 1efa7119..9f3fc541 100644
--- a/en/on-call/integration/alert-integration/alert-sources/netbeez.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/netbeez.mdx
@@ -1,5 +1,6 @@
---
title: "NetBeez alert integration"
+sidebarTitle: "NetBeez"
description: "Send NetBeez network monitoring alert and incident notifications to Flashduty On-call through a webhook."
keywords: ["alert integration", "NetBeez", "network monitoring", "webhook", "alert_dedup_id", "incident_id"]
---
@@ -9,7 +10,6 @@ Use the NetBeez webhook integration to send network monitoring alerts and incide
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure NetBeez
----
<Steps>
<Step title="Enable the webhook integration">
@@ -60,7 +59,6 @@ Make a Target or Agent fail (for example, temporarily disable an Agent), confirm
</Steps>
## Payload fields
----
NetBeez POSTs `application/json` with a single `data` field: an object for a single notification, an array for an aggregate notification. Flashduty parses it directly, so no template is needed.
@@ -81,7 +79,6 @@ NetBeez POSTs `application/json` with a single `data` field: an object for a sin
The alert title is "object name: message". The object name is the first non-empty of `target`, `wifi_profile`, `agent` and `destination`.
## Alert Key
----
- Alert notifications use `alert_dedup_id`. NetBeez documents that the open and cleared notifications of one alert share it, so grouping by it is enough.
- Incident notifications use the object type, the object ID and `incident_ts`. `incident_ts` is always the incident start time and is the same in the open and cleared notifications. NetBeez also suggests correlating incidents by `incident_id`, but the cleared example in its documentation carries a different `incident_id` from the open one, so Flashduty does not depend on it and keeps `incident_id` only as a label.
@@ -90,7 +87,6 @@ The alert title is "object name: message". The object name is the first non-empt
If an alert notification has no `alert_dedup_id`, or an incident notification has no object ID or `incident_ts`, Flashduty returns a parameter error because the cleared notification could not be matched to its alert reliably.
## Status and severity
----
| NetBeez notification | Flashduty status or severity |
| :--- | :--- |
@@ -103,7 +99,6 @@ If an alert notification has no `alert_dedup_id`, or an incident notification ha
NetBeez documents only that open alerts have a `severity` of at most 5 with names such as `alert` and `critical`, and does not publish a full table, so only 1 and 2 map to Critical. To change a severity, rewrite it with a rule under the channel's **Configuration**.
## FAQ
----
<AccordionGroup>
<Accordion title="What happens when an aggregate notification contains both open and cleared events?">
@@ -126,7 +121,6 @@ No. NetBeez retries on non-2xx responses, the Alert Key of an event does not cha
</AccordionGroup>
## Troubleshooting
----
- **NetBeez fails to deliver**: confirm the webhook URL is the full push URL and includes `integration_key`
- **Flashduty returns a parameter error**: confirm the body has `data`, alerts carry `alert_dedup_id`, and incidents carry an object ID and `incident_ts`
diff --git a/en/on-call/integration/alert-integration/alert-sources/netdata.mdx b/en/on-call/integration/alert-integration/alert-sources/netdata.mdx
index 711e8eff..8fe7195a 100644
--- a/en/on-call/integration/alert-integration/alert-sources/netdata.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/netdata.mdx
@@ -1,5 +1,6 @@
---
title: "Netdata alert integration"
+sidebarTitle: "Netdata"
description: "Send Netdata alert raises, escalations, and recoveries to Flashduty On-call through the Netdata Agent custom notification (custom_sender)."
keywords: ["alert integration", "Netdata", "Netdata Agent", "health_alarm_notify.conf", "custom_sender", "webhook"]
---
@@ -11,7 +12,6 @@ This integration works with the open-source Netdata Agent, including Docker depl
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -20,7 +20,7 @@ You can obtain an integration push URL in either of the following ways.
Choose this method when you do not need to route alerts to different channels.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View dedicated integration setup steps">
1. In the Flashduty console, select **Channel** and open a channel
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**
@@ -35,7 +35,7 @@ Choose this method when you do not need to route alerts to different channels.
Choose this method when you need to route alerts to different channels based on the payload.
<AccordionGroup>
- <Accordion title="Expand">
+ <Accordion title="View shared integration setup steps">
1. In the Flashduty console, select **Integration Center → Alert Events**
2. Select **Netdata** and enter an integration name
@@ -48,14 +48,12 @@ Choose this method when you need to route alerts to different channels based on
</div>
## Prerequisites
----
- **Network**: the host running the Netdata Agent must be able to reach the Flashduty push URL (for example `https://api.flashcat.cloud`).
- **curl**: the notification script sends requests with `curl`. The official Netdata packages and Docker image already include it.
- **Permissions**: you need to be able to edit files in the Netdata configuration directory (usually `/etc/netdata`).
## In Netdata
----
<Steps>
<Step title="Open the notification configuration file">
@@ -148,7 +146,6 @@ The test command sends WARNING, CRITICAL, and CLEAR notifications in turn. When
</Steps>
## Alert Key
----
Flashduty builds the Alert Key from the `host`, `chart`, and `alarm` fields.
@@ -161,7 +158,6 @@ Changes to the alert status, value, description, or duration do not change the A
The `alarm_id` in Netdata notifications is unique only within one Agent (the test command, for example, sends `alarm_id` `1` on every Agent), so Flashduty does not use it.
## Status and severity
----
Netdata sends notifications only for the WARNING, CRITICAL, and CLEAR states.
@@ -176,7 +172,6 @@ When an alert rises from WARNING to CRITICAL, Flashduty opens a new Critical ale
Netdata sends CLEAR only when an alert changes from WARNING or CRITICAL to CLEAR.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -193,7 +188,6 @@ Netdata sends CLEAR only when an alert changes from WARNING or CRITICAL to CLEAR
The alert title is `<host>: <summary>`. Older Netdata versions that do not send `summary` use the alert name instead.
## FAQ
----
<AccordionGroup>
<Accordion title="Is the Netdata Cloud webhook notification supported?">
diff --git a/en/on-call/integration/alert-integration/alert-sources/new-relic.mdx b/en/on-call/integration/alert-integration/alert-sources/new-relic.mdx
index 2d5e8967..1302855b 100644
--- a/en/on-call/integration/alert-integration/alert-sources/new-relic.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/new-relic.mdx
@@ -1,5 +1,6 @@
---
title: "New Relic alert integration"
+sidebarTitle: "New Relic"
description: "Send New Relic Issues to Flashduty On-call through Workflow webhooks and correlate activation, update, and closure notifications."
keywords: ["alert integration", "New Relic", "Workflow", "webhook", "Issue"]
---
@@ -9,14 +10,12 @@ Use a New Relic Workflow webhook to send Issues to Flashduty On-call. One New Re
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **New Relic** alert integration and copy its complete Push URL.
</div>
## Configure New Relic
----
<Steps>
<Step title="Create a webhook destination">
@@ -68,14 +67,12 @@ Open a real Issue and confirm an active Flashduty alert. Change its priority or
</Steps>
## Alert Key and Issue merges
----
Flashduty uses `issue_id` (`issueId`) directly as the Alert Key. Titles, priorities, policies, conditions, entities, and `incident_ids` do not affect it. `incident_ids` is the list of Alert Events aggregated into the Issue and is stored only as context.
For `trigger_event=MERGE_REQUEST`, Flashduty updates the surviving Issue identified by the payload's `issue_id`. This version does not invoke Flashduty's internal alert merge operation or infer and close a source Issue.
## Status and severity
----
| New Relic value | Flashduty status or severity |
| :--- | :--- |
@@ -89,7 +86,6 @@ For `trigger_event=MERGE_REQUEST`, Flashduty updates the surviving Issue identif
New Relic warning thresholds create `HIGH` priority Alert Events, so `HIGH` maps to Flashduty Warning. Use an [Alert Processing Pipeline](/en/on-call/integration/alert-integration/alert-pipelines) for a different mapping.
## Add custom labels
----
Add a top-level `custom_labels` object to send more Workflow variables:
@@ -110,3 +106,11 @@ Add a top-level `custom_labels` object to send more Workflow variables:
`custom_labels` accepts at most 50 entries. Use snake_case keys. Strings, numbers, booleans, arrays, and objects are accepted; arrays and objects are stored as JSON strings. Empty values are discarded, built-in labels win collisions, and the final event may contain at most 50 labels. Never send secrets.
For the complete variable list, see [New Relic Workflow variables](https://docs.newrelic.com/docs/alerts/get-notified/custom-variables-alert-event-workflows/).
+
+## Troubleshooting
+
+- **Only test notifications arrive, real alerts don't**: make sure the Workflow is enabled and its filter matches real issues
+- **Flashduty returns a parameter error**: make sure the payload is valid JSON and contains a non-empty `issue_id` and a supported `state`
+- **Alerts don't recover**: make sure the Destination has **Closed** enabled and the close payload carries the same `issue_id` as the activation
+- **Severity or merge changes aren't updated**: enable **Priority changed** and **Other updates**
+- **Some lists are empty**: different conditions and issue types provide different context; Flashduty ignores empty labels
diff --git a/en/on-call/integration/alert-integration/alert-sources/nobl9.mdx b/en/on-call/integration/alert-integration/alert-sources/nobl9.mdx
index 678bf86c..56851714 100644
--- a/en/on-call/integration/alert-integration/alert-sources/nobl9.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/nobl9.mdx
@@ -1,5 +1,6 @@
---
title: "Nobl9 Alert Integration"
+sidebarTitle: "Nobl9"
description: "Sync alerts fired by Nobl9 SLO alert policies to Flashduty On-call through the Nobl9 Webhook alert method."
keywords: ["alert integration", "Nobl9", "SLO", "Alert Method", "Webhook", "alert_id"]
---
@@ -9,7 +10,6 @@ Use the Nobl9 Webhook alert method to sync alerts fired by SLO alert policies to
<div className="hide">
## In Flashduty On-call
----
Get the integration push URL in either of two ways.
@@ -30,7 +30,6 @@ Get the integration push URL in either of two ways.
</div>
## Configure in Nobl9
----
<Steps>
<Step title="Create the Webhook alert method">
@@ -77,7 +76,6 @@ Use the template above. Nobl9's default fields do not include `alert_id`, and Fl
</Warning>
## Payload
----
| Field | Meaning | In Flashduty |
| :--- | :--- | :--- |
@@ -89,12 +87,10 @@ Use the template above. Nobl9's default fields do not include `alert_id`, and Fl
| `alert_policy_conditions_text`, `slo_details_link` | Trigger conditions, SLO details link | Description |
## Alert Key
----
Flashduty uses `alert_id` (Nobl9 docs: "Unique identifier of the alert") as the Alert Key. Repeated deliveries for the same Nobl9 alert merge into one Flashduty alert.
## Severity
----
| Nobl9 `severity` | Flashduty severity |
| :--- | :--- |
@@ -104,7 +100,6 @@ Flashduty uses `alert_id` (Nobl9 docs: "Unique identifier of the alert") as the
| Other or empty | Warning |
## FAQ
----
<AccordionGroup>
<Accordion title="Do alerts recover automatically?">
@@ -115,7 +110,6 @@ No. The Nobl9 Webhook documentation has no recovery notification. Enable auto-cl
</AccordionGroup>
## Troubleshooting
----
- **Nobl9 test fails**: a test request without `alert_id` is rejected, which is expected; otherwise confirm the URL is the full push URL starting with `https://` and includes `integration_key`
- **Flashduty returns a parameter error**: confirm the template contains `"alert_id": "$alert_id"`
diff --git a/en/on-call/integration/alert-integration/alert-sources/nodeping.mdx b/en/on-call/integration/alert-integration/alert-sources/nodeping.mdx
index a7043fd4..5aadeed0 100644
--- a/en/on-call/integration/alert-integration/alert-sources/nodeping.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/nodeping.mdx
@@ -1,5 +1,6 @@
---
title: "NodePing alert integration"
+sidebarTitle: "NodePing"
description: "Send NodePing check down and up notifications to Flashduty On-call through a webhook contact method."
keywords: ["alert integration", "NodePing", "Uptime", "webhook", "Contact", "uuid"]
---
@@ -9,7 +10,6 @@ Use a webhook contact method on a NodePing contact to send check down (`down`) a
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure NodePing
----
<Steps>
<Step title="Add a webhook contact method">
@@ -65,7 +64,6 @@ Keep the request method at **GET** and do not add custom Query Strings or a Body
</Warning>
## Payload
----
NodePing sends a GET request with the following fields appended to the push URL's query string. Flashduty parses them directly, with no template to configure:
@@ -86,14 +84,12 @@ NodePing sends a GET request with the following fields appended to the push URL'
The alert title is the check name. If the name is empty, Flashduty uses the check target, then `NodePing check <uuid>`.
## Alert Key
----
Flashduty uses the check `uuid` as the Alert Key. Down and up notifications for the same check carry the same `uuid`, so they land on the same alert. Different checks produce different alerts even when their names and targets are the same. Changing the check name, target, or result code does not change the Alert Key.
`_id` identifies a single check result and changes on every notification, so it is not used to correlate alerts. A request without `uuid` is rejected with a parameter error, because its recovery could not be matched to the original alert reliably.
## Status and severity
----
NodePing notifications have no severity, so Flashduty treats them all as Critical.
@@ -106,7 +102,6 @@ NodePing notifications have no severity, so Flashduty treats them all as Critica
`first` means monitoring has started and this webhook is registered as a notification target. It does not describe an outage, so Flashduty only returns success. Requests whose `event` is empty or has any other value are rejected, so that a request with an unknown state never enters the wrong alert lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="Why GET instead of POST with a JSON template like other integrations?">
@@ -129,7 +124,6 @@ Confirm that the check is enabled, the webhook contact method is not muted, and
</AccordionGroup>
## Troubleshooting
----
- **NodePing fails to deliver**: Confirm that the URL is the complete push URL including `integration_key`, and that the request method is GET
- **Flashduty returns a parameter error**: Confirm that no custom Query Strings or Body are set, and that `uuid` and `event` are present
diff --git a/en/on-call/integration/alert-integration/alert-sources/ns1.mdx b/en/on-call/integration/alert-integration/alert-sources/ns1.mdx
index fc1bf66a..7376e77c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/ns1.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/ns1.mdx
@@ -1,5 +1,6 @@
---
title: "NS1 Connect alert integration"
+sidebarTitle: "NS1 Connect"
description: "Send IBM NS1 Connect monitoring job down and up events to Flashduty On-call through a webhook notifier."
keywords: ["alert integration", "NS1", "IBM NS1 Connect", "webhook", "notifier", "monitoring job"]
---
@@ -9,14 +10,12 @@ Use an NS1 Connect webhook notifier to send monitoring job `down` and `up` state
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **NS1** alert integration and copy its complete Push URL.
</div>
## Configure NS1 Connect
----
<Steps>
<Step title="Create a webhook notifier">
@@ -49,7 +48,6 @@ Make the monitored endpoint genuinely unreachable and confirm Flashduty receives
</Steps>
## Alert Key
----
Flashduty uses the monitoring job ID, `job_document.id`, as the Alert Key. NS1's official example of the `down` body carries the full `job_document`, whose `id` is the job ID. The down, repeated, and up notifications of one job share it.
@@ -62,7 +60,6 @@ NS1's official documentation shows the full `down` body only; its `up` example i
</Note>
## State and severity
----
NS1 sends no severity.
@@ -75,12 +72,10 @@ NS1 sends no severity.
`state` is case-insensitive.
## Labels
----
Flashduty keeps the labels `check` (job name), `resource` (`host`, `url`, or `domain` from `config`), `job_id`, `job_type`, `region`, `state`, and `notify_list` for troubleshooting and routing on the alert page.
## Troubleshooting
----
- **The alert does not recover**: confirm **Notify failback** is enabled on the monitoring job. If you cannot enable it, turn on [auto-close timeout](/en/on-call/channel/create-edit) for the channel with a duration of 1 hour and the timer starting at incident trigger
- **NS1 reports a webhook failure**: confirm the Push URL is complete and includes `integration_key`
diff --git a/en/on-call/integration/alert-integration/alert-sources/ntopng.mdx b/en/on-call/integration/alert-integration/alert-sources/ntopng.mdx
index 3d2f50ec..ffd20e38 100644
--- a/en/on-call/integration/alert-integration/alert-sources/ntopng.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/ntopng.mdx
@@ -1,5 +1,6 @@
---
title: "ntopng alert integration"
+sidebarTitle: "ntopng"
description: "Send ntopng host, interface, and flow alert engage and release events to Flashduty On-call through a webhook endpoint."
keywords: ["alert integration", "ntopng", "webhook", "endpoint", "recipient", "traffic monitoring"]
---
@@ -9,7 +10,6 @@ Use an ntopng Webhook endpoint to send ntopng alerts to Flashduty On-call. For h
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **ntopng** alert integration and copy its complete Push URL.
@@ -30,7 +30,6 @@ Create either a dedicated or shared **ntopng** alert integration and copy its co
</div>
## In ntopng
----
<Steps>
<Step title="Create a Webhook endpoint">
@@ -61,7 +60,6 @@ Trigger a host alert (for example, let a host breach one of ntopng's threshold c
</Steps>
## Alert Key
----
The `engage` and `release` messages for one alert carry the same interface ID (`ifid`), entity type (`entity_id`), entity value (`entity_val`), alert type (`alert_id`), and subtype (`subtype`). Flashduty builds the Alert Key from these five fields. ntopng itself tells engaged alerts apart by entity value, alert type, and subtype. The score (`score`), timestamps, host name, and check period change between messages and are not part of the Alert Key.
@@ -70,7 +68,6 @@ A flow alert has `action` set to `store` and each one becomes its own alert. Whe
If an `engage` or `release` message lacks `alert_id`, `entity_id`, or `entity_val`, Flashduty returns a parameter error that names the field.
## Severity
----
ntopng derives severity from `score`; Flashduty maps it as follows. A missing or non-numeric `score` is treated as Info.
@@ -81,7 +78,6 @@ ntopng derives severity from `score`; Flashduty maps it as follows. A missing or
| Below 50 | None, Info, Notice | Info |
## Recovery and testing
----
- **`release`**: closes the alert with the same Alert Key and keeps the severity it had before the release.
- **`store` (flow alerts) and any alert without a release message**: does not recover on its own. Turn on [auto-close](/en/on-call/channel/create-edit) in the integration or channel, with a suggested duration of 24 hours.
@@ -90,7 +86,6 @@ ntopng derives severity from `score`; Flashduty maps it as follows. A missing or
A request carries at most 10 alerts (ntopng's per-request limit). Flashduty creates one event per alert and keeps the order of the request.
## Troubleshooting
----
- **ntopng reports a delivery failure**: confirm the webhook URL is complete, includes `integration_key`, and that the ntopng server can reach `api.flashcat.cloud`. ntopng retries a failed delivery 3 times
- **Flashduty returns a parameter error**: check that the body is JSON and that every `engage` and `release` alert has `alert_id`, `entity_id`, and `entity_val`
diff --git a/en/on-call/integration/alert-integration/alert-sources/nut.mdx b/en/on-call/integration/alert-integration/alert-sources/nut.mdx
index 70a17aac..5b3e6b47 100644
--- a/en/on-call/integration/alert-integration/alert-sources/nut.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/nut.mdx
@@ -1,5 +1,6 @@
---
title: "NUT (Network UPS Tools) Alert Integration"
+sidebarTitle: "NUT (Network UPS Tools)"
description: "Push UPS on-battery, low-battery and communication-loss events to the Flashduty Standard Alert Event integration through a upsmon NOTIFYCMD script; recovery events close the alerts."
keywords: ["alert integration", "NUT", "Network UPS Tools", "upsmon", "UPS", "power outage", "standard alert event"]
---
@@ -9,7 +10,6 @@ The NUT (Network UPS Tools) `upsmon` daemon can run the script set by `NOTIFYCMD
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the Standard Alert Event integration type** in both, not NUT.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the Standa
</div>
## Configure in NUT
----
### Step 1: Create the notification script
@@ -120,7 +119,6 @@ NOTIFYTYPE=ONLINE UPSNAME=ups@localhost /usr/local/bin/nut-flashduty.sh "UPS ups
In Flashduty you should first see the alert `UPS ups@localhost: on battery` and then see it recover.
## Recovery and deduplication
----
- `ONBATT`, `LOWBATT` and `ONLINE` share the Alert Key `nut:<UPS name>:power`: `ONBATT` triggers the alert, a following `LOWBATT` raises it to Critical, and `ONLINE` recovers it
- `COMMBAD`, `NOCOMM` and `COMMOK` share `comm`; `ALARM` and `NOTALARM`, `OVER` and `NOTOVER`, and `BYPASS` and `NOTBYPASS` are also paired
@@ -128,7 +126,6 @@ In Flashduty you should first see the alert `UPS ups@localhost: on battery` and
- Alerts of several UPS units do not affect each other: the Alert Key contains `UPSNAME`
## Troubleshooting
----
- **No alert arrives**: confirm the `NOTIFYFLAG` of the event type in `upsmon.conf` includes `EXEC` and that `upsmon -c reload` was run
- **The script works by hand but no alert arrives when upsmon triggers it**: `NOTIFYCMD` must be the full path of the script and the user `upsmon` runs as must be able to execute it; `curl -fsS` prints failures to stderr, which `upsmon` may not record, so run the script by hand to see them
diff --git a/en/on-call/integration/alert-integration/alert-sources/obkio.mdx b/en/on-call/integration/alert-integration/alert-sources/obkio.mdx
index 4d0329f6..a740cdb1 100644
--- a/en/on-call/integration/alert-integration/alert-sources/obkio.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/obkio.mdx
@@ -1,5 +1,6 @@
---
title: "Obkio alert integration"
+sidebarTitle: "Obkio"
description: "Send network monitoring alerts from Obkio to Flashduty On-call through a webhook notification."
keywords: ["alert integration", "Obkio", "network monitoring", "webhook", "latency", "packet loss"]
---
@@ -9,7 +10,6 @@ Use the organization-level webhook notification of Obkio to send network monitor
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## In Obkio
----
The webhook is configured at the organization level and requires permission to change the organization's advanced parameters.
@@ -63,14 +62,12 @@ The Obkio documentation describes no test delivery. Flashduty only handles deliv
</Steps>
## Alert Key
----
Flashduty uses `data.alert_id` from the webhook as the Alert Key. Obkio's example lists `alert_id` (the alert) separately from `notification_id` (this notification); the notification ID differs on every delivery, so it is not part of the Alert Key. The Obkio documentation does not say whether `alert_id` stays the same across notifications for one alert. If it changes, each notification becomes its own alert and auto-close cleans them up.
Changes to the event type, severity, or description never change the Alert Key. A delivery without `data.alert_id` is rejected.
## Status and severity
----
Flashduty sets the severity from `data.severity` (the Obkio levels, see [Notifications](https://obkio.com/docs/notifications/)):
@@ -86,7 +83,6 @@ Flashduty sets the severity from `data.severity` (the Obkio levels, see [Notific
The Obkio documentation does not say whether the `ok` level is ever sent. If it is, the alert with that `alert_id` recovers.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -101,7 +97,6 @@ The Obkio documentation does not say whether the `ok` level is ever sent. If it
The title comes from `event_description`, such as `High latency: 118.32 ms`.
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: the message names the missing field (`data.alert_id`). Check that Webhook Type is `Obkio`
- **Obkio keeps retrying**: confirm the URL is complete and includes `integration_key`; Obkio stops retrying once it gets a 2xx response
diff --git a/en/on-call/integration/alert-integration/alert-sources/observium.mdx b/en/on-call/integration/alert-integration/alert-sources/observium.mdx
index a1c49163..f47cfdc3 100644
--- a/en/on-call/integration/alert-integration/alert-sources/observium.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/observium.mdx
@@ -1,5 +1,6 @@
---
title: "Observium alert integration"
+sidebarTitle: "Observium"
description: "Send Observium alert checker and syslog alerts to Flashduty On-call through the Observium Webhook JSON transport. Alerts close automatically when the alert checker recovers."
keywords: ["alert integration", "Observium", "Webhook JSON", "network monitoring", "SNMP"]
---
@@ -9,7 +10,6 @@ Observium pushes alerts through a contact of type **Webhook JSON**: every time a
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Observium
----
The **Webhook JSON** transport ships with the Observium Community Edition; no subscription is needed. Screen names below follow Observium CE 26.1.
@@ -125,7 +124,6 @@ Then make a checker fire for real (for example, make a monitored device unreacha
</Steps>
## Alert Key
----
Flashduty uses `ALERT_ID` as the Alert Key for alert checker alerts. `ALERT_ID` is the row ID in the Observium `alert_table` table, which holds exactly one row per alert checker and entity, and every alert, reminder, and recovery notification carries the same value. So notifications for the same checker on the same entity land on one alert, and a new failure after recovery opens a new alert.
@@ -136,7 +134,6 @@ For syslog alerts, `ALERT_ID` is the syslog rule ID and no recovery is ever sent
Flashduty rejects requests without `ALERT_STATE` or `ALERT_ID`, or whose `ALERT_STATE` is not a value in the table below.
## Alert lifecycle
----
Flashduty handles notifications by the `ALERT_STATE` field:
@@ -150,7 +147,6 @@ Flashduty handles notifications by the `ALERT_STATE` field:
`ALERT_STATE` carries Observium's fixed state names and is not affected by `$config['alerts']['status_name']`. Custom names appear in `ALERT_STATE_NAME`, which Flashduty does not read.
## Severity
----
The severity comes from `ALERT_SEVERITY`:
@@ -164,7 +160,6 @@ The severity comes from `ALERT_SEVERITY`:
For alert checkers the severity is the checker's **Severity** (`Critical` or `Warning`); for syslog alerts it is the syslog priority of the log line. Recovery notifications carry the same checker severity, and the recovery event keeps it.
## Alert content
----
- **Title**: `<checker message> on <entity name>`. When the entity is not the device itself (for example a port or a sensor), `(<host name>)` is appended. When the checker message is empty, `Observium alert <ALERT_ID>` is used instead
- **Description**: `CONDITIONS` (the failed conditions), `METRICS` (current metric values), and `DURATION`, one per line
@@ -173,7 +168,6 @@ For alert checkers the severity is the checker's **Severity** (`Critical` or `Wa
Empty fields and `%TAG%` placeholders left unreplaced by the template (such as `ENTITY_*` in syslog notifications) are not written to labels.
## Troubleshooting
----
- **Observium records notifications as failed and Flashduty receives duplicate events**: the contact's **Transport** is **Webhook**. Change it to **Webhook JSON**
- **Flashduty returns 400 with `ALERT_STATE is required` or `ALERT_ID is required`**: the contact's JSON template lacks that field. Restore the default template
diff --git a/en/on-call/integration/alert-integration/alert-sources/oceanbase.mdx b/en/on-call/integration/alert-integration/alert-sources/oceanbase.mdx
index dac8d8ae..a57dd762 100644
--- a/en/on-call/integration/alert-integration/alert-sources/oceanbase.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/oceanbase.mdx
@@ -1,5 +1,6 @@
---
title: "OceanBase Alert Events"
+sidebarTitle: "OceanBase"
description: "Synchronize OceanBase alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,46 +9,45 @@ Sync OceanBase alert events to Flashduty via webhook for automated alert noise r
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels. It's simpler and recommended.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **OceanBase** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **OceanBase** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In OceanBase
----
<div class="md-block">
-## I. OceanBase Alert Push Configuration
### Step 1: Configure Alert Channel
1. Log in to your OceanBase console and select Alert Center
@@ -55,7 +55,7 @@ Choose this method when you need to route alerts to different channels based on
3. Select **Custom Script** as the channel type
4. Configure the basic settings as shown below:
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/oceanbase-1.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/oceanbase-1.png" />
5. Copy the following script content into the channel configuration, and **please add the integration_key value from your Flashduty push URL to the integration_key parameter in the script**
@@ -158,10 +158,10 @@ OCP Alert Notification - Single Alert
### Step 2: Configure Alert Push
-1. Create a new push configuration at: **Alert Center=>Alert Push=>New Push Configuration**
+1. Create a new push configuration at: **Alert Center → Alert Push → New Push Configuration**
2. Configure push type and specified objects as needed
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/oceanbase-2.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/oceanbase-2.png" />
3. Select **English** for push language
4. Select **Flashduty** for alert channel
@@ -171,7 +171,7 @@ OCP Alert Notification - Single Alert
<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/oceanbase-3.png" />
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/oci-monitoring.mdx b/en/on-call/integration/alert-integration/alert-sources/oci-monitoring.mdx
index 9065c322..2bf9fd88 100644
--- a/en/on-call/integration/alert-integration/alert-sources/oci-monitoring.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/oci-monitoring.mdx
@@ -1,5 +1,6 @@
---
title: "OCI Monitoring alert integration"
+sidebarTitle: "OCI Monitoring"
description: "Send Oracle Cloud Infrastructure Monitoring alarm triggers and recoveries to Flashduty On-call through an OCI Notifications HTTPS subscription."
keywords: ["alert integration", "Oracle Cloud", "OCI", "Monitoring", "Alarm", "Notifications", "dedupeKey"]
---
@@ -9,7 +10,6 @@ Use an HTTPS (Custom URL) subscription on an OCI Notifications topic to send Ora
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -34,7 +34,6 @@ OCI HTTPS subscription URLs cannot contain query parameters, so this integration
</Note>
## Configure OCI
----
<Steps>
<Step title="Create a topic">
@@ -75,14 +74,12 @@ OCI HTTPS subscription URLs cannot contain query parameters, so this integration
</Steps>
## Alert Key
----
Flashduty uses the `dedupeKey` of the alarm message as the Alert Key. OCI defines `dedupeKey` as the unique identifier of the alarm (grouped message) or of the metric stream in the alarm (split message), and says to use it to group messages that belong to the same alarm. The `OK_TO_FIRING`, `REPEAT`, `FIRING_TO_OK`, and `RESET` messages of one alarm carry the same `dedupeKey`, so they update the same Flashduty alert.
Changes to the title, body, severity, time, or metric values do not change the Alert Key. An alarm message without a `dedupeKey` is rejected.
## Status and severity
----
| OCI `type` | Flashduty status |
| :--- | :--- |
@@ -101,7 +98,6 @@ Changes to the title, body, severity, time, or metric values do not change the A
A recovery keeps the alert's severity. An empty or unknown `severity` is treated as Warning; an unknown `type` is rejected.
## Alert labels
----
Flashduty writes the following fields to alert labels for routing and troubleshooting:
@@ -112,7 +108,6 @@ Flashduty writes the following fields to alert labels for routing and troublesho
The alarm `body` and `alarmSummary` go into the alert description.
## Troubleshooting
----
- **The subscription stays Pending**: Check that the URL is the complete push URL, with the integration key in the path and no query parameters. Then delete the subscription and create it again with the correct URL. A confirmation link is valid for 3 days; after it expires, recreate the subscription as well
- **Flashduty returns a ConfirmationURL error**: Flashduty only visits https confirmation links on Oracle Cloud domains such as `oraclecloud.com`. Make sure the request comes from OCI Notifications
diff --git a/en/on-call/integration/alert-integration/alert-sources/odown.mdx b/en/on-call/integration/alert-integration/alert-sources/odown.mdx
index 8c629846..e631bf2e 100644
--- a/en/on-call/integration/alert-integration/alert-sources/odown.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/odown.mdx
@@ -1,5 +1,6 @@
---
title: "Odown alert integration"
+sidebarTitle: "Odown"
description: "Send Odown check down, recovery, and SSL certificate expiry notifications to Flashduty On-call through a webhook channel."
keywords: ["alert integration", "Odown", "Uptime", "webhook", "SSL", "ALERT_FAILURE", "ALERT_RECOVERY"]
---
@@ -9,7 +10,6 @@ Use an Odown webhook channel to send check down (`ALERT_FAILURE`), recovery (`AL
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Odown
----
<Steps>
<Step title="Add a webhook channel">
@@ -57,7 +56,6 @@ Let a check actually fail (for example, point it at an unreachable address tempo
</Steps>
## Payload
----
Odown POSTs each event as JSON. Flashduty parses it directly, so no template is needed:
@@ -78,7 +76,6 @@ Odown POSTs each event as JSON. Flashduty parses it directly, so no template is
The alert title is the check name, or the monitored URL when the name is empty. SSL expiry alert titles start with `SSL certificate expiring:`.
## Alert Key
----
- Down and recovery: Flashduty uses `check.id` as the Alert Key. `ALERT_FAILURE` and `ALERT_RECOVERY` for the same check carry the same `check.id`, so they land on one alert, while different checks produce different alerts. Renaming a check or a change in status code or run location does not change the Alert Key.
- SSL expiry: the Alert Key is `check.id` plus `:ssl_expiry`. It is separate from the check's down alert, so a recovery does not close the certificate alert, and repeated expiry notices for one check merge into one alert.
@@ -86,7 +83,6 @@ The alert title is the check name, or the monitored URL when the name is empty.
A request without `check.id` is rejected with a parameter error, because a recovery could not be matched to its alert.
## Status and severity
----
Odown notifications carry no severity.
@@ -99,12 +95,10 @@ Odown notifications carry no severity.
A request with an empty or unknown `event` is rejected, so a request whose state is unclear never lands in the wrong alert lifecycle.
## Turn on the auto-resolve timeout for one-shot alerts
----
An SSL expiry notice has no matching close notification, so these alerts do not recover automatically in Flashduty. Turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit) and set it to 7 days, or close the alert by hand after you renew the certificate.
## FAQ
----
<AccordionGroup>
<Accordion title="Does the webhook test button create an alert?">
@@ -121,7 +115,6 @@ No. Notifications for one check carry the same `check.id` and merge into one ale
</AccordionGroup>
## Troubleshooting
----
- **Odown reports a failed delivery**: check that the webhook URL is the complete push URL and includes `integration_key`
- **Flashduty returns a parameter error**: check that the request is an Odown JSON notification with non-empty `check.id` and `event`
diff --git a/en/on-call/integration/alert-integration/alert-sources/ofelia.mdx b/en/on-call/integration/alert-integration/alert-sources/ofelia.mdx
index 3fc31dca..f32869cc 100644
--- a/en/on-call/integration/alert-integration/alert-sources/ofelia.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/ofelia.mdx
@@ -1,5 +1,6 @@
---
title: "Ofelia alert integration"
+sidebarTitle: "Ofelia"
description: "Send failure and recovery events from Ofelia scheduled jobs to Flashduty On-call through a webhook."
keywords: ["alert integration", "Ofelia", "cron", "Docker", "webhook", "scheduled jobs"]
---
@@ -11,7 +12,6 @@ This page covers the webhook feature of [netresearch/ofelia](https://github.com/
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Ofelia
----
Ofelia talks to the Docker API even when it only runs `job-local` jobs, so the Ofelia container must mount `/var/run/docker.sock`; without it Ofelia exits at startup. With `docker run`, add `-v /var/run/docker.sock:/var/run/docker.sock:ro`.
@@ -101,7 +100,6 @@ Make a job fail once (for example, temporarily change its command to `false`) an
</Steps>
## Alert Key
----
Flashduty builds the Alert Key from `host.hostname` and `job.name`, joined by a separator that cannot appear in either, then hashed with MD5. In our verification, failed and successful runs of the same job carried the same hostname and job name. `execution.id` differs on every run, so it is not part of the Alert Key.
@@ -111,7 +109,6 @@ Flashduty builds the Alert Key from `host.hostname` and `job.name`, joined by a
- If `job.name` is missing, Flashduty returns 400 rather than writing a failure and its recovery to the wrong alert
## Status and severity
----
| Ofelia `execution.status` | Flashduty handling |
| :--- | :--- |
@@ -124,7 +121,6 @@ A job skipped by `no-overlap` means the previous run is still going, so the job'
Repeated failures update the same alert. If a job stops running altogether (deleted or disabled), its alert does not recover. Close it manually, or turn on [auto-close after timeout](/en/on-call/channel/create-edit) for the channel.
## Alert content
----
- **Title**: `Ofelia job "<job name>" failed`, or `Ofelia job "<job name>" succeeded` on recovery
- **Description**: `execution.error`, followed by `execution.stderr` on a new line
@@ -133,7 +129,6 @@ Repeated failures update the same alert. If a job stops running altogether (dele
The job command and stdout never reach labels or the description, because a command can carry credentials.
## Troubleshooting
----
- **Flashduty receives nothing**: confirm the job has `webhooks = flashduty` and look for `Webhook error` in the Ofelia log. Ofelia retries a failed webhook 3 times by default, 5 seconds apart
- **Failures arrive but never recover**: confirm the webhook has `trigger = always` and that the hostname did not change between runs
diff --git a/en/on-call/integration/alert-integration/alert-sources/ohdear.mdx b/en/on-call/integration/alert-integration/alert-sources/ohdear.mdx
index 26123e69..9d369a50 100644
--- a/en/on-call/integration/alert-integration/alert-sources/ohdear.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/ohdear.mdx
@@ -1,5 +1,6 @@
---
title: "Oh Dear alert integration"
+sidebarTitle: "Oh Dear"
description: "Send uptime, performance, certificate, DNS, and scheduled task events from Oh Dear to Flashduty On-call through the team webhook."
keywords: ["alert integration", "Oh Dear", "webhook", "uptime monitoring", "certificate monitoring", "scheduled task monitoring"]
---
@@ -9,7 +10,6 @@ Use the webhook in your Oh Dear team settings to send uptime, performance, broke
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Oh Dear
----
The Oh Dear webhook is configured per team, and events from every monitor in the team go to the same URL.
@@ -56,7 +55,6 @@ Oh Dear treats only HTTP 200 as delivered. Any other status, including a 301 or
</Steps>
## How events map to alerts
----
Oh Dear pushes every event, and you cannot filter event types on the Oh Dear side. Flashduty handles them as follows:
@@ -84,7 +82,6 @@ Monitor added (`monitorAddedNotification`) and any event type Oh Dear adds later
</Warning>
## Alert Key
----
- Checks with a recovery event: the Alert Key is computed from `run.check_id` (the ID of one kind of check under a monitor in Oh Dear). The trigger and recovery events of one check share an Alert Key, and different monitors, or different checks of the same monitor, never merge
- Events without a recovery event: the Alert Key is computed from the event's `uuid`. Oh Dear keeps the same `uuid` when it retries an event, so a retry does not create a duplicate alert, while each new event creates its own alert
@@ -92,7 +89,6 @@ Monitor added (`monitorAddedNotification`) and any event type Oh Dear adds later
Changes to the monitor name, URL, time, or run ID do not change the Alert Key. A push without `run.check_id` (checks with a recovery event) or without `uuid` (events without one) is rejected.
## Status and severity
----
Oh Dear events carry no severity, so Flashduty decides by event:
@@ -105,7 +101,6 @@ Oh Dear events carry no severity, so Flashduty decides by event:
An uptime `...UptimeCheckRecovered` event with `run.result` set to `warning` means partial connectivity (the primary checker failed, the secondary succeeded, and the site still counts as online). Flashduty treats it as a recovery too.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -118,7 +113,6 @@ An uptime `...UptimeCheckRecovered` event with `run.result` set to `warning` mea
| `url` | Link to the matching report in Oh Dear |
## Troubleshooting
----
- **No alerts arrive**: check that `integration_key` in the URL is correct, and look at the request's response status in Oh Dear's webhook log
- **An alert does not recover**: check that Oh Dear has sent the matching recovery event. Certificate expiry, DNS record changes, and scheduled task events have none and must be closed manually
diff --git a/en/on-call/integration/alert-integration/alert-sources/okta.mdx b/en/on-call/integration/alert-integration/alert-sources/okta.mdx
index 046a2a7e..c95998d6 100644
--- a/en/on-call/integration/alert-integration/alert-sources/okta.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/okta.mdx
@@ -1,5 +1,6 @@
---
title: "Okta alert integration"
+sidebarTitle: "Okta"
description: "Sync account lockouts, breached credentials, and user-reported suspicious activity from Okta Event Hooks to Flashduty On-call."
keywords: ["alert integration", "Okta", "Event Hooks", "account lockout", "identity security"]
---
@@ -14,7 +15,6 @@ Only super administrators can create and configure event hooks, and each Okta or
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -35,7 +35,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Okta
----
<Steps>
<Step title="Create an event hook">
@@ -87,14 +86,12 @@ Preview sends real events from your org's System Log, and Flashduty cannot tell
</Steps>
## Configure auto-resolve timeout
----
Breached credential and suspicious activity alerts have no recovery notification and never close on their own. In the channel that receives these alerts, turn on the [auto-resolve timeout](/en/on-call/channel/create-edit), set **Window timing start** to **Incident trigger**, and set the timeout to 24 hours: responders get one working day to confirm and reset the credential, and unhandled incidents do not stay open indefinitely.
Account lockout alerts are closed by unlock events and do not depend on this setting.
## Payload fields
----
The `data.events` array in one delivery may carry several events. Flashduty processes them one by one in order of each event's `published` time. Each event is an Okta System Log record, and Flashduty uses the following fields:
@@ -112,7 +109,6 @@ The `data.events` array in one delivery may carry several events. Flashduty proc
The alert title has the form `<event name>: <user display name>`, for example `Okta account locked: Jane Doe`. Every alert also carries the label `source=okta`.
## Alert Key
----
Flashduty builds the Alert Key from the event category and the user ID:
@@ -122,7 +118,6 @@ Flashduty builds the Alert Key from the event category and the user ID:
- A new breached credential or suspicious activity event for a user whose alert is still open merges into that alert
## Status and severity
----
The `severity` that Okta records does not reflect urgency (an account lockout is recorded as `DEBUG`, for example), so Flashduty maps severity by event type:
@@ -135,7 +130,6 @@ The `severity` that Okta records does not reflect urgency (an account lockout is
| Other event types | Ignored; no alert |
## FAQ
----
<AccordionGroup>
<Accordion title="Why is security.threat.detected (ThreatInsight) not supported?">
@@ -158,7 +152,6 @@ Okta times out after 3 seconds and retries at most once on a 5xx response or a t
</AccordionGroup>
## Troubleshooting
----
- **Verify fails**: make sure the URL is the full push URL, including `integration_key`
- **Flashduty returns an invalid parameter error**: an event that should create an alert has no user (neither `target` nor `actor` contains an object of type `User`). This usually happens with sample data in Preview
diff --git a/en/on-call/integration/alert-integration/alert-sources/open-falcon.mdx b/en/on-call/integration/alert-integration/alert-sources/open-falcon.mdx
index 8f785ba5..68732cef 100644
--- a/en/on-call/integration/alert-integration/alert-sources/open-falcon.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/open-falcon.mdx
@@ -1,5 +1,6 @@
---
title: "Open Falcon Integration"
+sidebarTitle: "Open Falcon"
description: "Sync Open-Falcon alert events to Flashduty via webhook to achieve automated alert noise reduction"
---
@@ -8,42 +9,42 @@ Sync Open-Falcon alert events to Flashduty via webhook to achieve automated aler
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Falcon** integration, click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use. Done.
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Falcon** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
-## In Falcon
----
+## In Falcon
Configure webhooks for each alert rule.
<div class="md-block">
@@ -53,10 +54,10 @@ Configure webhooks for each alert rule.
3. Click the Save button to save the alert rule
4. Repeat steps 2 and 3 for all alert rule templates that need to send events
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/open-falcon-tmpls.png" />
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/saas-open-falcon-rule.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/open-falcon-tmpls.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/saas-open-falcon-rule.png" />
-Similarly, you can configure the same push URL for Expressions alert rules.
+ Similarly, you can configure the same push URL for Expressions alert rules.
5. Return to the integration list, if the latest event time is displayed, the configuration is successful and events are being received
6. Done
@@ -64,7 +65,6 @@ Similarly, you can configure the same push URL for Expressions alert rules.
</div>
## Status Mapping
----
<div class="md-block">
Open-Falcon to Flashduty alert severity mapping:
diff --git a/en/on-call/integration/alert-integration/alert-sources/opennms.mdx b/en/on-call/integration/alert-integration/alert-sources/opennms.mdx
index d82f32e3..8ec4101c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/opennms.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/opennms.mdx
@@ -1,5 +1,6 @@
---
title: "OpenNMS alert integration"
+sidebarTitle: "OpenNMS"
description: "Send OpenNMS Horizon node, interface, and service outage notices to Flashduty On-call through a webhook notification command. Alerts close automatically when the outage is resolved."
keywords: ["alert integration", "OpenNMS", "OpenNMS Horizon", "webhook", "notification command", "notificationCommands.xml", "network monitoring"]
---
@@ -9,7 +10,6 @@ OpenNMS Horizon uses notices to tell operators about events in the network. This
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure OpenNMS
----
This integration uses the OpenNMS webhook notification strategy `WebhookNotificationStrategy`, which requires **OpenNMS Horizon 36.0.3 or later**. Earlier versions do not have this strategy, so upgrade first. Below, `$OPENNMS_HOME` is the OpenNMS installation directory, `/opt/opennms` in the official container image. The OpenNMS server must be able to reach the Flashduty push URL.
@@ -149,7 +148,6 @@ OpenNMS has no button to test a notification command on its own.
</Steps>
## Alert Key
----
Flashduty uses the OpenNMS notice ID `notice_id` (`${noticeid}`) as the Alert Key. The notice ID stays the same when an escalation step resends the notice and when OpenNMS sends the resolution notice after a recovery event auto-acknowledges it, so all of these land on the same alert.
@@ -160,7 +158,6 @@ Notice IDs are unique only within one OpenNMS instance. Use a separate integrati
Flashduty rejects a request that lacks `notice_id`, and OpenNMS logs the failed push in `notifd.log`.
## Alert lifecycle
----
OpenNMS configures auto-acknowledgement (`auto-acknowledge`) for outage events in `notifd-configuration.xml`: when the recovery event arrives, OpenNMS acknowledges the matching outage notice and sends the original notice again to its original recipients, with `RESOLVED: ` in front of the subject and text. Flashduty checks whether the subject starts with `RESOLVED:`:
@@ -183,7 +180,6 @@ To push other notices that have no auto-acknowledgement (for example, threshold
When the event's alarm is cleared by its clearing event, OpenNMS acknowledges the notice and sends the resolution notice. After the change, reload Notifd as in the first step. For notices that still get no resolution notice, turn on the [auto-resolve timeout](/en/on-call/channel/create-edit) in the channel that receives this integration's alerts, set **Window timing start** to **Incident trigger**, and set the timeout to 24 hours.
## Severity
----
Severity comes from `severity` in the request, which is the OpenNMS event severity that `%severity%` resolves to in the optional step:
@@ -201,14 +197,12 @@ Severity comes from `severity` in the request, which is the OpenNMS event severi
In a resolution notice, `severity` is the numeric severity id OpenNMS stores (for example `5` for `Minor` and `6` for `Major`). Flashduty converts ids 1–7 back to severity names, so the recovery event keeps the severity the alert was triggered with.
## Alert content
----
- **Title**: the notice subject `subject` without the `RESOLVED: ` prefix; `OpenNMS notice #<notice ID>` when the subject is empty
- **Description**: the notice text `message` without the `RESOLVED: ` prefix
- **Labels**: `notice_id`, `event_id`, `event_uei`, `node_id`, `interface`, `service`, `severity` (the severity name; the numeric id in a resolution notice is converted to its name). Labels with empty values are not added
## Troubleshooting
----
The log messages below are in `$OPENNMS_HOME/logs/notifd.log`.
diff --git a/en/on-call/integration/alert-integration/alert-sources/openobserve.mdx b/en/on-call/integration/alert-integration/alert-sources/openobserve.mdx
index 8fe2570f..1bfc4bbb 100644
--- a/en/on-call/integration/alert-integration/alert-sources/openobserve.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/openobserve.mdx
@@ -1,5 +1,6 @@
---
title: "OpenObserve alert integration"
+sidebarTitle: "OpenObserve"
description: "Send OpenObserve alerts to Flashduty On-call through a webhook template on an alert destination."
keywords: ["alert integration", "OpenObserve", "webhook", "log alerts", "observability"]
---
@@ -9,7 +10,6 @@ An OpenObserve webhook destination has no fixed request body: the body is the te
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure OpenObserve
----
You need permission to manage alert templates and destinations.
@@ -84,14 +83,12 @@ The template must contain `org_name`, `stream_name`, and `alert_name`; Flashduty
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from `org_name`, `stream_type`, `stream_name`, and `alert_name`, so the trigger, repeated triggers, and recovery of one OpenObserve alert share an Alert Key. Changes to the level, result count, threshold, trigger time, or `episode_id` do not change it; an empty `stream_type` counts as an empty value. A request without `org_name`, `stream_name`, or `alert_name` is rejected.
Renaming an OpenObserve alert, stream, or organization produces a new Alert Key.
## Status and severity
----
| `alert_level` | Flashduty severity |
| :--- | :--- |
@@ -101,12 +98,10 @@ Renaming an OpenObserve alert, stream, or organization produces a new Alert Key.
An `alert_status` of `resolved` recovers the alert; any other value triggers it. Before OpenObserve 1.1, `{alert_status}`, `{alert_level}`, and `{episode_id}` are not substituted and arrive as the literal template text. Flashduty treats them as empty, so the alert triggers as Warning.
## Recovery
----
Flashduty receives a recovery request, and closes the alert automatically, only with OpenObserve 1.1 or later and recovery notifications enabled on the alert. Otherwise every firing is an independent one-shot notification with no recovery request. For these alerts, set **auto-close after timeout** on the Flashduty integration or channel with a suitable duration, or the alert stays active.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -123,7 +118,6 @@ Flashduty receives a recovery request, and closes the alert automatically, only
The template does not contain `{rows}`, so Flashduty does not receive the log rows the query returned.
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: Check that the URL is complete and includes `integration_key`, that the template contains `org_name`, `stream_name`, and `alert_name`, and that the template is valid JSON
- **The alert does not recover**: Check that OpenObserve is 1.1 or later and that the alert has recovery notifications enabled; otherwise configure auto-close after timeout
diff --git a/en/on-call/integration/alert-integration/alert-sources/opensearch.mdx b/en/on-call/integration/alert-integration/alert-sources/opensearch.mdx
index c5ec7cf7..603ec201 100644
--- a/en/on-call/integration/alert-integration/alert-sources/opensearch.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/opensearch.mdx
@@ -1,5 +1,6 @@
---
title: "OpenSearch alert integration"
+sidebarTitle: "OpenSearch"
description: "Send trigger notifications from OpenSearch monitors to Flashduty On-call through a custom webhook notification channel of the Alerting plugin."
keywords: ["alert integration", "OpenSearch", "Alerting", "Notifications", "webhook", "log monitoring"]
---
@@ -11,7 +12,6 @@ Each trigger of each monitor maps to one Flashduty alert: while the trigger cond
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure OpenSearch
----
The Alerting and Notifications plugins must be installed (OpenSearch ships with both), and you need permission to create notification channels and monitors.
@@ -57,19 +56,19 @@ If the cluster sets `opensearch.notifications.core.http.host_deny_list`, make su
3. Under the trigger, click **Add action** and select the channel you just created as the **Notification channel**
4. Paste the whole template below into **Message**, without changing the quotation marks or field names:
-```text
-{
- "monitor_id": "{{ctx.monitor._id}}",
- "monitor_name": "{{ctx.monitor.name}}",
- "trigger_id": "{{ctx.trigger.id}}",
- "trigger_name": "{{ctx.trigger.name}}",
- "severity": "{{ctx.trigger.severity}}",
- "period_start": "{{ctx.periodStart}}",
- "period_end": "{{ctx.periodEnd}}",
- "hit_count": "{{ctx.results.0.hits.total.value}}",
- "error": "{{ctx.error}}"
-}
-```
+ ```text
+ {
+ "monitor_id": "{{ctx.monitor._id}}",
+ "monitor_name": "{{ctx.monitor.name}}",
+ "trigger_id": "{{ctx.trigger.id}}",
+ "trigger_name": "{{ctx.trigger.name}}",
+ "severity": "{{ctx.trigger.severity}}",
+ "period_start": "{{ctx.periodStart}}",
+ "period_end": "{{ctx.periodEnd}}",
+ "hit_count": "{{ctx.results.0.hits.total.value}}",
+ "error": "{{ctx.error}}"
+ }
+ ```
5. Save the monitor
@@ -95,14 +94,12 @@ Triggers of per query and per cluster metrics monitors run their actions only wh
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from the monitor ID and the trigger ID, which are `monitor_id` and `trigger_id` in the template. Every notification from the same trigger of the same monitor uses the same Alert Key and merges into one alert; different triggers and different monitors each get their own alert. Changes to the monitor name, trigger name, severity, hit count, or time period do not change the Alert Key. A notification with an empty `monitor_id` or `trigger_id` is rejected with an invalid-parameter error.
The template does not use `ctx.alert.id`: when a trigger runs its action for the first time, OpenSearch has not created the alert yet, so the variable is empty.
## Status and severity
----
The trigger's **Severity level** ranges from 1 (highest) to 5 (lowest). Flashduty maps it as follows:
@@ -116,7 +113,6 @@ The trigger's **Severity level** ranges from 1 (highest) to 5 (lowest). Flashdut
Every notification is a trigger. Flashduty never recovers an alert because of an OpenSearch notification; recovery comes from auto-close, or you can close the alert manually in Flashduty.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -129,7 +125,6 @@ Every notification is a trigger. Flashduty never recovers an alert because of an
| `error` | Error message when the trigger could not get results or evaluate its condition |
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: make sure Message holds the complete template with values for both `monitor_id` and `trigger_id`, and that the URL is complete and includes `integration_key`
- **The notification fails in OpenSearch**: click **Send test message** on the channel in **Notifications → Channels** to see the error. Common causes are a cluster that cannot reach `api.flashcat.cloud` or a domain listed in `host_deny_list`
diff --git a/en/on-call/integration/alert-integration/alert-sources/openstatus.mdx b/en/on-call/integration/alert-integration/alert-sources/openstatus.mdx
index af0e063e..15af4e2b 100644
--- a/en/on-call/integration/alert-integration/alert-sources/openstatus.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/openstatus.mdx
@@ -1,5 +1,6 @@
---
title: "OpenStatus alert integration"
+sidebarTitle: "OpenStatus"
description: "Send OpenStatus monitor errors, degradations, and recoveries to Flashduty On-call through a Webhook notification channel."
keywords: ["alert integration", "OpenStatus", "webhook", "synthetic monitoring", "uptime monitoring"]
---
@@ -9,7 +10,6 @@ Use an OpenStatus Webhook notification channel to send monitor alerts to Flashdu
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure OpenStatus
----
<Steps>
<Step title="Create a Webhook notification channel">
@@ -65,7 +64,6 @@ OpenStatus sends an `error` notification only after at least half of the monitor
</Tip>
## Alert Key
----
Flashduty computes the Alert Key from `monitor.id` (the OpenStatus monitor ID). The `error`, `degraded`, and `recovered` notifications for a monitor carry the same `monitor.id`, so they land on the same alert: when the monitor goes from error to degraded, the alert is updated to Warning, and it closes when the monitor recovers.
@@ -76,7 +74,6 @@ Changes to the monitor name, URL, status code, latency, error message, or check
</Note>
## Status and severity
----
| OpenStatus `status` | Flashduty handling | Severity |
| :--- | :--- | :--- |
@@ -88,14 +85,12 @@ Changes to the monitor name, URL, status code, latency, error message, or check
An empty or any other `status` is rejected so that a request whose state cannot be determined never lands in the wrong alert lifecycle.
## Alert content
----
- **Title**: the monitor name `monitor.name`, or `OpenStatus monitor <monitor.id>` when it is empty
- **Description**: `errorMessage`
- **Labels**: `check` (monitor name), `resource` (monitor URL `monitor.url`), `source` (always `openstatus`), `monitor_id`, `status`, `status_code`, `latency_ms`
## Troubleshooting
----
- **Send Test fails**: make sure **Webhook URL** is the full push URL and includes `integration_key`
- **Flashduty returns a parameter error**: make sure the request has `monitor.id` and `status`. This integration accepts only the JSON format of the OpenStatus Webhook channel
diff --git a/en/on-call/integration/alert-integration/alert-sources/opmanager.mdx b/en/on-call/integration/alert-integration/alert-sources/opmanager.mdx
index 077b4815..04852029 100644
--- a/en/on-call/integration/alert-integration/alert-sources/opmanager.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/opmanager.mdx
@@ -1,5 +1,6 @@
---
title: "OpManager Alert Events"
+sidebarTitle: "OpManager"
description: "Sync OpManager alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,50 +9,49 @@ Sync OpManager alert events to Flashduty via webhook for automated alert noise r
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alerts to different channels - it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Select **OpManager** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **OpManager** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In OpManager
----
<div class="md-block">
-## I. OpManager Alert Push Configuration
1. Log in to your `OpManager` console, select `Settings => Notification Profiles` from the navigation menu
2. On the `Notifications` page, click `Add` and select `Invoke a Webhook` to add a configuration profile
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/opm-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/opm-1.png" />
3. Begin configuring specific content on the Webhook editing page
4. In `Hook URL`, select `POST` as the request method and fill in the **integration push URL** as the `URL`
@@ -106,11 +106,11 @@ Choose this method when you need to route alerts to different channels based on
7. Keep the `Request Headers` as default
8. Fill in any value between 1-300 for `Time Out` and click next
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/opm-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/opm-2.png" />
9. On the `Choose the criteria` configuration page, check `Notify when the alarm is cleared` and configure other options as needed
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/opm-3.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/opm-3.png" />
10. Select the devices you want to apply this configuration to, move them to the selected devices window using the right arrow, then click next
11. Configure Time Window/Delayed Trigger/Recurring Trigger as needed, then click next
@@ -118,7 +118,7 @@ Choose this method when you need to route alerts to different channels based on
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/opnsense.mdx b/en/on-call/integration/alert-integration/alert-sources/opnsense.mdx
index b91d3a28..2b14e25c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/opnsense.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/opnsense.mdx
@@ -1,5 +1,6 @@
---
title: "OPNsense alert integration"
+sidebarTitle: "OPNsense"
description: "OPNsense's Monit module sends service alerts by email; use a Flashduty email integration with rules to trigger and close OPNsense alerts."
keywords: ["alert integration", "OPNsense", "Monit", "firewall", "email"]
---
@@ -9,7 +10,6 @@ OPNsense monitors services with the **Monit** module (**Services → Monit**) an
<div className="hide">
## In Flashduty On-call
----
Get the integration email address in either of the two ways below. **In both cases choose the Email integration type**, not OPNsense.
@@ -30,20 +30,18 @@ Get the integration email address in either of the two ways below. **In both cas
</div>
## Configure OPNsense
----
1. **SMTP**: go to **Services → Monit → Settings**, enable Monit under **General Settings**, and enter the SMTP server address, port and credentials
2. **Recipient**: under **Alert Settings**, add an alert and set **Recipient** to the Flashduty email integration address
3. **Mail format**: in **Mail format** of that alert, enter the line below. The default subject has no host name and no fixed separator between service and event, so the rules could not extract a stable Alert Key from it; with this fixed format the rules can process every email
-```
-Subject: [$HOST] [$SERVICE] $EVENT
-```
+ ```
+ Subject: [$HOST] [$SERVICE] $EVENT
+ ```
4. **Recovery notifications**: Monit sends a recovery email in the same format when a service recovers. Leave **Not on** off so that every event, including recovery, is emailed
## Configure push rules in Flashduty
----
In the title `[$HOST] [$SERVICE] $EVENT`, `$HOST` and `$SERVICE` are the same in the failure email and the recovery email; only `$EVENT` differs. The rules use the first two parts as the Alert Key, so a recovery email closes the matching alert.
@@ -68,7 +66,6 @@ Regex: /^\[(.+?)\] \[(.+?)\] /
The close rule comes before the trigger rule. The Alert Key is the host name plus the service name, so repeated failures of the same service on the same host merge into one alert. The default rule discards mail that was not sent in the format above (for example from other alerts that have no **Mail format** set) so it does not create alerts that can never close on their own.
## Events in the email title
----
`$EVENT` is Monit's description of the event. Failures and recoveries come in pairs:
@@ -81,7 +78,6 @@ The close rule comes before the trigger rule. The Alert Key is the host name plu
| nonexist | `Does not exist` | `Exists` |
## Limitations
----
- **Type and severity**: in Flashduty these alerts show the Email integration type, and their severity is always Warning. You can adjust it with [alert pipelines](/en/on-call/integration/alert-integration/alert-pipelines) based on the title.
- **Other events**: Monit events not in the table above are handled as trigger alerts. If an event type has no matching recovery email, turn on the [auto-resolve timeout](/en/on-call/channel/create-edit) in the channel that receives this integration; 24 hours is a reasonable start.
diff --git a/en/on-call/integration/alert-integration/alert-sources/opsgenie.mdx b/en/on-call/integration/alert-integration/alert-sources/opsgenie.mdx
index 2b1cb913..4b688f5b 100644
--- a/en/on-call/integration/alert-integration/alert-sources/opsgenie.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/opsgenie.mdx
@@ -1,5 +1,6 @@
---
title: "Opsgenie Compatible Alert Integration"
+sidebarTitle: "Opsgenie Compatible"
description: "Push alerts to Flashduty On-call with the Opsgenie Alert API protocol. Tools that already send to Opsgenie only need a new API URL."
keywords: ["alert integration", "Opsgenie", "Alert API", "Alertmanager", "Grafana", "migration"]
---
@@ -9,7 +10,6 @@ Flashduty implements alert creation and closing from the Opsgenie Alert API, wit
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of two ways.
@@ -30,7 +30,6 @@ You can get the push URL in either of two ways.
</div>
## Push URL
----
The push URL has this format, with `integration_key` as part of the path:
@@ -51,7 +50,6 @@ Supported endpoints:
A successful request returns HTTP 202 and `{"result": "Request will be processed", "took": 0, "requestId": "..."}`, the same as Opsgenie.
## Configure in Prometheus Alertmanager
----
Add `opsgenie_configs` to a receiver in `alertmanager.yml` and set `api_url` to the push URL:
@@ -75,7 +73,6 @@ receivers:
- The Update Message and Update Description requests sent with `update_alerts: true` are accepted and ignored; the title and description update with the next Create request
## Configure in Grafana
----
<Steps>
<Step title="Create an OpsGenie contact point">
@@ -112,7 +109,6 @@ Grafana sends alert labels in `tags` as `key:value`, and Flashduty turns them ba
The contact point's **Test** button uses a new alias on every press, so each press opens a separate Warning alert in Flashduty that never recovers on its own. Close it by hand.
## Other tools
----
Any tool that lets you change the Opsgenie API URL and closes alerts by alias works with this integration: replace the API URL with the push URL (with or without `v2/alerts`, depending on how the tool appends paths), and send Close requests with `identifierType=alias`.
@@ -123,14 +119,12 @@ Not supported:
- **Aliases that contain `/`**: the alias is part of the URL path, so such requests match no endpoint
## Alert Key
----
The request's `alias` is the Alert Key. Opsgenie defines alias as the "client-defined identifier of the alert, that is also the key element of Alert De-Duplication" ([Alert API](https://docs.opsgenie.com/docs/alert-api#create-alert)). Create requests with the same alias merge into one alert, and a Close request recovers that alert by alias. Alertmanager and Grafana both use a hash of the alert group as the alias, which stays the same from trigger to recovery.
Without `alias`, every Create request opens a new alert that no Close request can recover.
## Field mapping
----
| Opsgenie field | In Flashduty |
| :--- | :--- |
@@ -146,7 +140,6 @@ Without `alias`, every Create request opens a new alert that no Close request ca
`responders`, `visibleTo`, `actions`, `user` and `note` are ignored; assignment and notifications follow the Flashduty channel's settings.
## Severity
----
| Opsgenie `priority` | Flashduty severity |
| :--- | :--- |
@@ -157,7 +150,6 @@ Without `alias`, every Create request opens a new alert that no Close request ca
Any other value returns 422. Recovery comes from the Close request, not from `priority`.
## Troubleshooting
----
- **404**: the Alertmanager `api_url` is missing the trailing `/`, or the Grafana Alert API URL is missing `/v2/alerts`
- **401**: the `integration_key` in the push URL is wrong, or the integration is disabled
diff --git a/en/on-call/integration/alert-integration/alert-sources/opsview.mdx b/en/on-call/integration/alert-integration/alert-sources/opsview.mdx
index bd067382..d3f5e5ba 100644
--- a/en/on-call/integration/alert-integration/alert-sources/opsview.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/opsview.mdx
@@ -1,5 +1,6 @@
---
title: "Opsview Alert Integration"
+sidebarTitle: "Opsview"
description: "Push Opsview host and service alerts to the Flashduty Standard Alert Event integration through a custom notification method script; recovery notifications close the alerts."
keywords: ["alert integration", "Opsview", "ITRS Opsview", "notification method", "custom notification", "standard alert event"]
---
@@ -9,7 +10,6 @@ Opsview supports custom notification methods: when it notifies, it runs the scri
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the Standard Alert Event integration type** in both, not Opsview.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the Standa
</div>
## Configure in Opsview
----
### Step 1: Create the notification script
@@ -136,14 +135,12 @@ Opsview notifications are driven by each user's Notification Profile, so every u
You can also create a shared profile under Shared Notification Profiles and assign it to several users.
## Recovery and deduplication
----
- A host or service always uses the same Alert Key, so repeated problem notifications (for example from Opsview's re-notification interval) only update the same alert, and the `RECOVERY` notification recovers it
- When a service goes from WARNING to CRITICAL, the severity is updated on the same alert
- Acknowledgement (`ACKNOWLEDGEMENT`), flapping (`FLAPPING*`) and downtime (`DOWNTIME*`) notifications are ignored by the script and produce no event in Flashduty
## Troubleshooting
----
- **No alert arrives**: confirm the Notification Profile selects `Flashduty` and **Apply Changes** was run; check in Opsview's **Notifications View** whether the notification was sent; test the script on its own with `test_notifications`
- **The test works but real alerts are not pushed**: in a real notification the script reads the environment variables Opsview passes; add `{ date; echo "Called with $@"; env; echo; } >> /tmp/env.txt` to the top of the script (the debugging method given in the Opsview documentation) to see what it actually receives
diff --git a/en/on-call/integration/alert-integration/alert-sources/ossec.mdx b/en/on-call/integration/alert-integration/alert-sources/ossec.mdx
index 9bcdd65a..4a19121c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/ossec.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/ossec.mdx
@@ -1,5 +1,6 @@
---
title: "OSSEC Alert Integration"
+sidebarTitle: "OSSEC"
description: "OSSEC sends alert notifications by email. Use the Flashduty Email integration to bring OSSEC alerts into Flashduty On-call."
keywords: ["alert integration", "OSSEC", "OSSEC HIDS", "HIDS", "intrusion detection", "email", "security alerts"]
---
@@ -9,7 +10,6 @@ The OSSEC server (ossec-maild) can send alerts by email to the recipients you co
<div className="hide">
## In Flashduty On-call
----
You can get the integration email address in either of the two ways below. **Choose Email as the integration type** in both cases, not OSSEC.
@@ -30,7 +30,6 @@ You can get the integration email address in either of the two ways below. **Cho
</div>
## Configure the push mode in Flashduty
----
OSSEC sends one email when an alert is generated and never sends a recovery email, so no "close alert" rule is needed. Set **Push Mode** to **Trigger or Update Alert Based on Email Subject**: emails with the same title (same host, same log source, same level, same rule description) are merged into the one open alert, and emails with different titles each create a separate alert.
@@ -39,7 +38,6 @@ The title format is described in [Email subject format](#email-subject-format).
OSSEC does not send recovery notifications. Enable [auto-resolve timeout](/en/on-call/channel/create-edit) on the channel that receives this integration, with a suggested window of 24 hours, or close alerts manually once handled.
## Configure OSSEC
----
All configuration below is done in `/var/ossec/etc/ossec.conf` on the OSSEC server. Agents need no configuration because alerts are generated only on the server.
@@ -110,7 +108,6 @@ By default OSSEC batches alerts that arrive close together into a single email,
</Steps>
## Email subject format
----
OSSEC emails use the full subject by default (internal option `maild.full_subject=0`, the default value):
@@ -129,7 +126,6 @@ The location is "(agent name) agent IP", or the server name for alerts from the
The email body starts with `OSSEC HIDS Notification.`, followed by the alert time, `Received From` (the alert source), `Rule: <rule ID> fired (level <level>) -> "<rule description>"`, the source IP / user when present, and the triggering log excerpt (`Portion of the log(s)`). In Flashduty, the alert title is the email subject and the description is the email body.
## Limitations
----
- **No recovery**: an OSSEC alert is a one-time event. Alerts in Flashduty do not resolve automatically; rely on [auto-resolve timeout](/en/on-call/channel/create-edit) or close them manually.
- **Severity**: the Email integration sets every alert to Warning. The subject carries the OSSEC level (`Level N`), so you can adjust severity by level with an [Alert Pipeline](/en/on-call/integration/alert-integration/alert-pipelines).
diff --git a/en/on-call/integration/alert-integration/alert-sources/pagerduty.mdx b/en/on-call/integration/alert-integration/alert-sources/pagerduty.mdx
index e454952d..4ae1ac36 100644
--- a/en/on-call/integration/alert-integration/alert-sources/pagerduty.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/pagerduty.mdx
@@ -1,5 +1,6 @@
---
title: "PagerDuty Compatible Integration"
+sidebarTitle: "PagerDuty Compatible"
description: "Flashduty implements the PagerDuty Events API v1/v2. Tools that already send to PagerDuty send alerts to Flashduty after you change the push URL."
keywords: ["alert integration", "PagerDuty", "PagerDuty Compatible", "Events API v2", "routing_key"]
---
@@ -11,42 +12,42 @@ Similarly, for alert systems that already support pushing events to PagerDuty (s
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **PagerDuty Compatible** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **PagerDuty Compatible** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In your alerting system
----
### Request URL
```
@@ -97,17 +98,17 @@ Using [ElastAlert2](https://github.com/jertel/elastalert2) as an example:
1. Step 1: Obtain Push URL
-Enter integration name on the current page and save. Reopen integration details and copy the push URL, such as:
+ Enter integration name on the current page and save. Reopen integration details and copy the push URL, such as:
-```
-{api_host}/event/push/alert/pagerduty?integration_key=xxx
-```
+ ```
+ {api_host}/event/push/alert/pagerduty?integration_key=xxx
+ ```
2. Step 2: Modify Push URL
-Modify the corresponding source code of your deployed ElastAlert instance, [view diff](https://github.com/jertel/elastalert2/commit/e815a62a6b1eecef6e1fef13afd99d905b67fc34):
+ Modify the corresponding source code of your deployed ElastAlert instance, [view diff](https://github.com/jertel/elastalert2/commit/e815a62a6b1eecef6e1fef13afd99d905b67fc34):
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/pagerduty-replace-endpoint.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/pagerduty-replace-endpoint.png" />
3. Step 3: Report Alert Events
diff --git a/en/on-call/integration/alert-integration/alert-sources/pandora-fms.mdx b/en/on-call/integration/alert-integration/alert-sources/pandora-fms.mdx
index f262f6bb..a0d988c2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/pandora-fms.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/pandora-fms.mdx
@@ -1,5 +1,6 @@
---
title: "Pandora FMS alert integration"
+sidebarTitle: "Pandora FMS"
description: "Send Pandora FMS module alert triggers and recoveries to Flashduty On-call through a custom alert command."
keywords: ["alert integration", "Pandora FMS", "Alert command", "Alert recovery", "_id_alert_", "curl"]
---
@@ -9,7 +10,6 @@ Use a custom Pandora FMS alert command to send module alert triggers and recover
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Pandora FMS
----
Pandora FMS alert actions run a command on the Pandora FMS server. The steps below create an alert command that pushes with `curl`, create an action that uses the command, and then add the action to module alerts.
@@ -45,16 +44,16 @@ The Pandora FMS server that executes alerts needs `curl` installed and HTTPS acc
2. Set **Name** to `Flashduty`
3. Set **Command** to the command below. Keep it on one line and do not rename the fields:
-```text
-curl -sS -m 10 "_field1_" --data-urlencode "event=_field2_" --data-urlencode "id_alert=_id_alert_" --data-urlencode "alert_name=_alert_name_" --data-urlencode "alert_priority=_alert_priority_" --data-urlencode "alert_times_fired=_alert_times_fired_" --data-urlencode "agent=_agent_" --data-urlencode "id_agent=_id_agent_" --data-urlencode "address=_address_" --data-urlencode "agent_group=_agentgroup_" --data-urlencode "module=_module_" --data-urlencode "id_module=_id_module_" --data-urlencode "module_description=_moduledescription_" --data-urlencode "module_status=_modulestatus_" --data-urlencode "data=_data_" --data-urlencode "timestamp=_timestamp_"
-```
+ ```text
+ curl -sS -m 10 "_field1_" --data-urlencode "event=_field2_" --data-urlencode "id_alert=_id_alert_" --data-urlencode "alert_name=_alert_name_" --data-urlencode "alert_priority=_alert_priority_" --data-urlencode "alert_times_fired=_alert_times_fired_" --data-urlencode "agent=_agent_" --data-urlencode "id_agent=_id_agent_" --data-urlencode "address=_address_" --data-urlencode "agent_group=_agentgroup_" --data-urlencode "module=_module_" --data-urlencode "id_module=_id_module_" --data-urlencode "module_description=_moduledescription_" --data-urlencode "module_status=_modulestatus_" --data-urlencode "data=_data_" --data-urlencode "timestamp=_timestamp_"
+ ```
4. Fill in the field descriptions and values as follows:
-| Field | Description | Values |
-| :--- | :--- | :--- |
-| **Field 1** | `Flashduty push URL` | Leave empty |
-| **Field 2** | `Event` | `alert_fired,Alert fired;alert_recovered,Alert recovered` |
+ | Field | Description | Values |
+ | :--- | :--- | :--- |
+ | **Field 1** | `Flashduty push URL` | Leave empty |
+ | **Field 2** | `Event` | `alert_fired,Alert fired;alert_recovered,Alert recovered` |
5. Click **Create** to save
@@ -68,10 +67,10 @@ Every macro sits inside double quotes. Pandora FMS shell-quotes the value when i
2. Set **Name** to `Flashduty`, set **Group** to the groups that should use the action (**All** for every group), and set **Command** to the `Flashduty` command from the previous step
3. Fill in the fields as follows. Fill in both the **Triggering** and **Recovery** columns:
-| Field | Triggering | Recovery |
-| :--- | :--- | :--- |
-| **Field 1** (Flashduty push URL) | The full push URL of the Flashduty integration | The full push URL of the Flashduty integration |
-| **Field 2** (Event) | `Alert fired` (`alert_fired`) | `Alert recovered` (`alert_recovered`) |
+ | Field | Triggering | Recovery |
+ | :--- | :--- | :--- |
+ | **Field 1** (Flashduty push URL) | The full push URL of the Flashduty integration | The full push URL of the Flashduty integration |
+ | **Field 2** (Event) | `Alert fired` (`alert_fired`) | `Alert recovered` (`alert_recovered`) |
4. Click **Create** to save
@@ -105,7 +104,6 @@ The action's **Field 2** must be `alert_recovered` in the **Recovery** column. I
</Warning>
## Pushed content
----
The command POSTs the following fields as an `application/x-www-form-urlencoded` form:
@@ -130,7 +128,6 @@ The command POSTs the following fields as an `application/x-www-form-urlencoded`
The alert title is `<template name>: <agent> / <module>`. When some fields are missing the rest are used, and when all are empty the title is `Pandora FMS alert <id_alert>`.
## Alert Key
----
Flashduty uses `id_alert` (the Pandora FMS macro `_id_alert_`) as the Alert Key. The Pandora FMS documentation describes this macro as "Alert identifier, useful for correlating the alert in third-party tools": it is the ID of the module alert created when a template is assigned to a module. The trigger, repeated firings, and recovery of one module alert carry the same ID, so they land on the same Flashduty alert. One template assigned to two modules makes two module alerts with different IDs, which produce different Flashduty alerts. Changing the template name, priority, agent alias, or data does not change the Alert Key.
@@ -139,7 +136,6 @@ Module alert IDs are unique only within one Pandora FMS installation. Use a sepa
Only module alerts carry `_id_alert_`. Event alerts, log alerts, and correlated alerts have no module alert ID and Flashduty rejects them as a parameter error, so do not add the `Flashduty` action to them.
## Status and severity
----
`event` decides whether the alert triggers or recovers, and `alert_priority` (the alert template's **Priority**) decides the severity:
@@ -155,7 +151,6 @@ Only module alerts carry `_id_alert_`. Event alerts, log alerts, and correlated
When `event` is `alert_recovered` the alert recovers, and its severity still comes from the template priority. Requests with an empty or any other `event` are rejected, so a request whose state cannot be determined never enters the wrong alert lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="Why does the action need an Event field?">
@@ -184,7 +179,6 @@ Check, in order: the alert template has **Alert recovery** enabled; the action's
</AccordionGroup>
## Troubleshooting
----
- **Pandora FMS does not push**: run `curl -sS <push URL>` on the Pandora FMS server to confirm the network path, and make sure the action's **Group** covers the agent's group
- **Flashduty returns a parameter error**: make sure the command is pasted in full on one line, the action's **Field 2** is `alert_fired` and `alert_recovered` in the two columns, and the action is only added to module alerts
diff --git a/en/on-call/integration/alert-integration/alert-sources/panther.mdx b/en/on-call/integration/alert-integration/alert-sources/panther.mdx
index 5d6e18ac..aeb29fe3 100644
--- a/en/on-call/integration/alert-integration/alert-sources/panther.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/panther.mdx
@@ -1,5 +1,6 @@
---
title: "Panther alert integration"
+sidebarTitle: "Panther"
description: "Send Panther detection alerts to Flashduty On-call through a Panther Custom Webhook alert destination."
keywords: ["alert integration", "Panther", "webhook", "SIEM", "security alerts", "detection"]
---
@@ -9,7 +10,6 @@ Use a Panther Custom Webhook alert destination to send alerts from rules, polici
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Panther
----
<Steps>
<Step title="Create the Custom Webhook destination">
@@ -69,14 +68,12 @@ Wait for a detection to match (or re-dispatch an alert from its details page in
</Steps>
## Alert Key
----
Flashduty uses the `alertId` field of the body as the Alert Key. Panther describes it as "Identifier of the alert in Panther Backend". Manually re-sending the same Panther alert from its details page lands on the same Flashduty alert.
Changes to the title, severity or description do not change the Alert Key. A request without `alertId` returns a parameter error.
## Status and severity
----
The Panther Custom Webhook has no status field, so every delivery is a trigger event.
@@ -90,7 +87,6 @@ The Panther Custom Webhook has no status field, so every delivery is a trigger e
Alert labels carry the detection name, detection ID (`id`), alert ID, alert type, raw severity, alert link and `tags`. `alertContext` is defined by the detection author and may hold raw log fields, so it is not copied into the alert; `runbook` is not copied either.
## Troubleshooting
----
- **Panther shows a delivery failure**: confirm the push URL is complete and includes `integration_key`; Panther retries up to 10 times when Flashduty returns a non-`2XX` response
- **No alert arrives**: confirm the destination's **Severity Levels**, **Default Alert Types** and **Log Types** cover the alert, and check the detection's destination routing
diff --git a/en/on-call/integration/alert-integration/alert-sources/papertrail.mdx b/en/on-call/integration/alert-integration/alert-sources/papertrail.mdx
index 17d1b4cb..d54b55db 100644
--- a/en/on-call/integration/alert-integration/alert-sources/papertrail.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/papertrail.mdx
@@ -1,5 +1,6 @@
---
title: "Papertrail alert integration"
+sidebarTitle: "Papertrail"
description: "Sync log lines matched by a Papertrail saved search to Flashduty On-call through a webhook."
keywords: ["alert integration", "Papertrail", "SolarWinds", "saved search", "webhook", "log alert"]
---
@@ -13,7 +14,6 @@ Papertrail (SolarWinds' log aggregation service) uses a **saved search** to desc
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -34,7 +34,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Papertrail
----
<Steps>
<Step title="Create a saved search and attach an alert">
@@ -67,7 +66,6 @@ Papertrail's own documentation mentions no test-delivery button for webhooks. Le
</Steps>
## Payload
----
Flashduty parses the request in Papertrail's own fixed format: the body is `application/x-www-form-urlencoded` with a single form field `payload`, whose value is a JSON hash:
@@ -108,7 +106,6 @@ Flashduty parses the request in Papertrail's own fixed format: the body is `appl
| `counts[]` ("Send only counts" mode) | Per-source counts with no individual log lines or IDs | Not supported. Flashduty rejects the request; turn this setting off in Papertrail |
## Alert Key
----
Flashduty uses `saved_search.id` alone as the Alert Key. It is the saved search's stable identifier, unchanged across every delivery for that search, so repeated matches for the same saved search keep merging into the same alert, treated as the same problem still happening. Different saved searches produce different Alert Keys and open separate alerts.
@@ -117,12 +114,10 @@ Flashduty uses `saved_search.id` alone as the Alert Key. It is the saved search'
Deliveries missing `saved_search.id` are rejected.
## Severity
----
A Papertrail saved-search alert has no severity field, so every match triggers a **Warning** alert. The `severity` on each individual log line (such as `Info` or `Error`) is that line's own syslog level, and one delivery can mix several values; it does not represent the alert's urgency, and only shows up in the log lines quoted in the alert description.
## FAQ
----
<AccordionGroup>
diff --git a/en/on-call/integration/alert-integration/alert-sources/peekaping.mdx b/en/on-call/integration/alert-integration/alert-sources/peekaping.mdx
index 451849af..f5f6f2a9 100644
--- a/en/on-call/integration/alert-integration/alert-sources/peekaping.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/peekaping.mdx
@@ -1,5 +1,6 @@
---
title: "Peekaping Alert Integration"
+sidebarTitle: "Peekaping"
description: "Sync Peekaping monitor down and recovery events to Flashduty On-call through a Webhook notification channel."
keywords: ["alert integration", "Peekaping", "Webhook", "uptime monitoring", "monitoring", "self-hosted"]
---
@@ -9,7 +10,6 @@ Peekaping is an open-source, self-hosted monitoring system. With a Peekaping Web
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Peekaping
----
You need Peekaping 0.0.46 or later and an account that can manage notification channels and monitors. The Peekaping server must be able to reach the Flashduty push URL.
@@ -60,14 +59,12 @@ You need Peekaping 0.0.46 or later and an account that can manage notification c
</Steps>
## Alert Key
----
Flashduty uses `monitor.id` from the request as the Alert Key. A monitor sends the same `monitor.id` when it goes down and when it recovers, so the recovery closes the matching alert. `heartbeat.id` differs on every heartbeat and is not part of the Alert Key.
Changes to the monitor name, status message, or time do not change the Alert Key. A request without `monitor.id` is rejected. `monitor.id` is unique only within one Peekaping instance, so point one Flashduty integration at a single Peekaping instance.
## Status and severity
----
| `heartbeat.status` | Meaning | Flashduty handling |
| :--- | :--- | :--- |
@@ -79,7 +76,6 @@ Changes to the monitor name, status message, or time do not change the Alert Key
Peekaping has no severity of its own, so every down event maps to Critical. The alert title is the monitor name and the description is the heartbeat message (for example `TCP connection failed: ...`).
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -91,7 +87,6 @@ Peekaping has no severity of its own, so every down event maps to Critical. The
The monitor `config` (which holds hosts and credentials) and `push_token` never reach labels or the description.
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: confirm the URL is complete and includes `integration_key`, and that the channel's **Request Body** is `application/json`; the response names the missing field
- **The Peekaping test fails**: confirm the Peekaping server can reach the Flashduty push URL, and check the Peekaping log for the HTTP status code
diff --git a/en/on-call/integration/alert-integration/alert-sources/pgdash.mdx b/en/on-call/integration/alert-integration/alert-sources/pgdash.mdx
index 776fcf04..cf5a66e7 100644
--- a/en/on-call/integration/alert-integration/alert-sources/pgdash.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/pgdash.mdx
@@ -1,5 +1,6 @@
---
title: "pgDash alert integration"
+sidebarTitle: "pgDash"
description: "Send pgDash PostgreSQL monitoring alerts to Flashduty On-call through webhooks."
keywords: ["alert integration", "pgDash", "PostgreSQL", "database monitoring", "webhook"]
---
@@ -9,7 +10,6 @@ Use pgDash webhook notifications to send PostgreSQL monitoring alerts to Flashdu
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure pgDash
----
The setup is the same for pgDash SaaS and self-hosted pgDash. Webhooks require pgDash 2.4.11 or later.
@@ -60,7 +59,6 @@ Enter this push URL only on the **Alerts** page. Notifications from the **Change
</Warning>
## Alert lifecycle
----
pgDash webhooks are edge-triggered: a notification is sent only when the alert status of a server changes, and each notification carries every current alert item of that server (the `alerts` array). When all alerts clear, pgDash sends one notification with an empty `alerts` array.
@@ -76,7 +74,6 @@ Renaming a server in pgDash produces a new Alert Key. Close alerts under the old
</Tip>
## Severity
----
| pgDash alert items | Flashduty severity |
| :--- | :--- |
@@ -85,14 +82,12 @@ Renaming a server in pgDash produces a new Alert Key. Close alerts under the old
| `alerts` is empty | Recovered |
## Alert content
----
- **Title**: `server name: rule description`, taken from the first `crit` item (or the first item if none is critical). `(+N more)` is appended when there are several items
- **Description**: the pgmetrics report time (UTC) and, for each alert item, its type, rule description, current value, object name, and link. Query-level alerts include the SQL text (truncated to 500 characters). Up to 50 items are listed
- **Labels**: `server`, `check` (rule description of the item used in the title), `resource` (that item's object name), `link` (that item's pgDash link), `alert_count` (number of current alert items), `source` (always `pgdash`)
## Troubleshooting
----
- **pgDash sends nothing**: pgDash notifies only when the alert status changes and does not repeat an unchanged state. Check that an alert rule has fired and that the webhook is set on the **Alerts** page, not the **Change Alerts** page
- **Delivery times out**: pgDash expects a response within 3 seconds and retries at most 3 times on timeout. For self-hosted pgDash, make sure the pgDash server can reach the push URL
diff --git a/en/on-call/integration/alert-integration/alert-sources/phare.mdx b/en/on-call/integration/alert-integration/alert-sources/phare.mdx
index 22809427..91731e30 100644
--- a/en/on-call/integration/alert-integration/alert-sources/phare.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/phare.mdx
@@ -1,5 +1,6 @@
---
title: "Phare Uptime alert integration"
+sidebarTitle: "Phare Uptime"
description: "Send Phare Uptime incident created and recovered events to Flashduty On-call through an outgoing webhook."
keywords: ["alert integration", "Phare", "Phare Uptime", "outgoing webhook", "incident", "uptime"]
---
@@ -9,14 +10,12 @@ Use a Phare outgoing webhook to send Uptime incidents to Flashduty On-call. Crea
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **Phare** alert integration and copy its complete Push URL.
</div>
## Configure Phare
----
A Phare webhook body is written by you from placeholders, so the template below is the one to paste. Flashduty parses exactly this template.
@@ -87,12 +86,10 @@ Make a monitored target actually fail and confirm Flashduty receives an active a
</Steps>
## Alert Key
----
Flashduty uses `incident.id` as the Alert Key. Phare's created, propagated, partially recovered, and recovered events all expose the same incident entity, and `{{ incident.id }}` is that incident's number, so every notification for one incident gets the same Alert Key. Changes to the title, description, state, impact, or affected monitors do not change it.
## Status and severity
----
The event type comes from the `X-Phare-Request-Event` header:
@@ -115,7 +112,6 @@ Severity comes from `incident.impact`:
An incident is created when a monitor check fails, so an unknown impact is treated as Critical. A recovery event keeps the severity that `impact` maps to and sets the status to recovered.
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: confirm the template is valid JSON, `incident.id` is not empty, and the request carries `X-Phare-Request-Event` or an `event` field
- **The alert does not recover**: confirm an **Incident recovered** rule exists and uses the same template
diff --git a/en/on-call/integration/alert-integration/alert-sources/pingdom.mdx b/en/on-call/integration/alert-integration/alert-sources/pingdom.mdx
index d0d9226c..ee962539 100644
--- a/en/on-call/integration/alert-integration/alert-sources/pingdom.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/pingdom.mdx
@@ -1,5 +1,6 @@
---
title: "Pingdom alert integration"
+sidebarTitle: "Pingdom"
description: "Send Pingdom uptime check and transaction check state changes to Flashduty On-call through a webhook."
keywords: ["alert integration", "Pingdom", "SolarWinds", "uptime", "transaction", "webhook"]
---
@@ -9,7 +10,6 @@ Use Pingdom state change webhooks to send uptime check and transaction check ale
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Pingdom
----
<Steps>
<Step title="Create a webhook integration">
@@ -68,14 +67,12 @@ When the SolarWinds APM Integrated Experience is enabled, Pingdom menus may be i
</Tip>
## Alert Key
----
Flashduty computes the Alert Key from the check family (uptime or transaction) and `check_id`. The failure and recovery webhooks of one check carry the same `check_id`, so they land on the same alert. Uptime checks and transaction checks are separate check lists in Pingdom; including the family keeps them apart even when their numeric IDs are equal.
Changes to the check name, `importance_level`, state, timestamps, error description, or probe locations do not change the Alert Key. A request without `check_id` is rejected, because its recovery could not be matched.
## Status and severity
----
| Pingdom `current_state` | Flashduty status |
| :--- | :--- |
@@ -97,7 +94,6 @@ Severity comes from the check's `importance_level`:
A recovery keeps the alert's original severity.
## Alert content
----
- **Title**: the check name, `check_name`
- **Description**: `long_description`, or `description` when it is empty
@@ -106,7 +102,6 @@ A recovery keeps the alert's original severity.
Request headers and authentication settings in `check_params` are not stored as labels.
## Troubleshooting
----
- **Pingdom receives a non-2xx response**: verify that the URL is the full Push URL and includes `integration_key`
- **Flashduty reports an invalid parameter**: verify that the request has `check_id` and `current_state`
diff --git a/en/on-call/integration/alert-integration/alert-sources/postman.mdx b/en/on-call/integration/alert-integration/alert-sources/postman.mdx
index a128cce6..ff580236 100644
--- a/en/on-call/integration/alert-integration/alert-sources/postman.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/postman.mdx
@@ -1,5 +1,6 @@
---
title: "Postman Alert Integration"
+sidebarTitle: "Postman"
description: "Send Postman Monitor run results to Flashduty On-call through a Postman custom webhook."
keywords: ["alert integration", "Postman", "Monitor", "webhook", "API monitoring", "API testing"]
---
@@ -9,7 +10,6 @@ Use the Postman webhook integration "Post monitoring results" to send the result
<div className="hide">
## In Flashduty On-call
----
Get the push URL in either of the following ways.
@@ -30,7 +30,6 @@ Get the push URL in either of the following ways.
</div>
## In Postman
----
<Steps>
<Step title="Add the webhook integration">
@@ -43,7 +42,7 @@ Get the push URL in either of the following ways.
- **Notify for all completed monitor runs** (choose this one): every run is sent. A failing run triggers the alert and a passing run recovers it
- **Notify for 3 failures and then first success**: Postman describes this only by the option name and does not say which runs are sent, so a passing run may not be delivered when you need it, the alert may never recover, and it triggers later
-The Postman payload has no status field and Flashduty recovers an alert from a passing run, so recovery works reliably only with **Notify for all completed monitor runs**.
+ The Postman payload has no status field and Flashduty recovers an alert from a passing run, so recovery works reliably only with **Notify for all completed monitor runs**.
6. Click **Add Integration**
Add one webhook integration per Monitor.
@@ -62,12 +61,10 @@ The Postman documentation does not describe a test delivery for this webhook.
</Steps>
## Alert Key
----
Flashduty uses `monitor_uid` (the Monitor's unique ID) as the Alert Key, so failure and recovery deliveries for the same Monitor share one key. Changing the Monitor name, test counts or latency does not change it. A request without `monitor_uid` is rejected.
## Status and severity
----
The Postman payload has no status field, so Flashduty reads the run result from the counts in `metrics`:
@@ -80,7 +77,6 @@ The Postman payload has no status field, so Flashduty reads the run result from
A request without the `metrics` object, or with `errorCount` or `failedTestCount` missing or not a non-negative integer, is rejected and is never treated as a passing run. A passing run for a Monitor with no active alert creates no new alert.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -96,7 +92,6 @@ A request without the `metrics` object, or with `errorCount` or `failedTestCount
The user who triggered the run (`user_id`, `user_name`) is not written to labels.
## Troubleshooting
----
- **Flashduty returns an invalid parameter error**: check that the URL is complete and includes `integration_key`
- **The alert does not recover**: confirm that the Monitor later has a run with every test passing and no request errors. make sure the notification mode is **Notify for all completed monitor runs**
diff --git a/en/on-call/integration/alert-integration/alert-sources/powerjob.mdx b/en/on-call/integration/alert-integration/alert-sources/powerjob.mdx
index 7538d237..9f2a6e94 100644
--- a/en/on-call/integration/alert-integration/alert-sources/powerjob.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/powerjob.mdx
@@ -1,5 +1,6 @@
---
title: "PowerJob alert integration"
+sidebarTitle: "PowerJob"
description: "Send failed job instances and failed workflow instances from PowerJob to Flashduty On-call through a user WebHook alarm."
keywords: ["alert integration", "PowerJob", "scheduled jobs", "workflow", "webhook", "job scheduling"]
---
@@ -11,7 +12,6 @@ PowerJob alarms only on failure and sends nothing when a run succeeds, so the al
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the push URL in either of the following ways.
</div>
## In PowerJob
----
PowerJob sends alarms to users: first set a WebHook address on a user, then select that user on the job or workflow. This integration is verified against PowerJob 5.1.7.
@@ -63,14 +62,12 @@ PowerJob has no test button. Make a job fail, for example with the built-in `Sta
</Steps>
## Alerts do not recover
----
PowerJob sends no recovery notification, and it does not alarm when a job later succeeds. In the channel that receives this integration, turn on [auto-close](/en/on-call/channel/create-edit). We suggest 12 hours; adjust to how quickly your team handles failed jobs.
Each failed run is a separate alert. A job that is scheduled often (for example every minute) and keeps failing creates many alerts; use Flashduty alert grouping to reduce the noise.
## Job failures and workflow failures
----
The integration tells the two alarms apart by their content:
@@ -82,7 +79,6 @@ If a job inside a workflow fails and that job also has notified users, PowerJob
The alert description contains the execution `result` reported by PowerJob (cut at 1000 bytes). Job parameters, instance parameters, and the processor info (for example the body of a shell script) may hold secrets, so Flashduty does not read those fields.
## Alert Key
----
| Alarm type | Alert Key |
| :--- | :--- |
@@ -94,12 +90,10 @@ Every run has a new instance ID, so each failure is a new alert and the same run
Instance IDs are long integers above 2^53; Flashduty keeps every digit of the original text.
## Status and severity
----
PowerJob alarms carry no severity field and are sent only on failure, so every alert is in the triggered state with Critical severity.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -114,7 +108,6 @@ PowerJob alarms carry no severity field and are sent only on failure, so every a
| `task_tracker_address` | Address of the TaskTracker that ran the job (job failure) |
## Troubleshooting
----
- **Flashduty receives no event**: confirm the failed job or workflow has notified users selected and that user has a WebHook; confirm the PowerJob server can reach Flashduty and that the push URL is complete with `integration_key`. When delivery fails, PowerJob only logs `[WebHookAlarmService] invoke webhook ... failed` on the server and does not retry
- **Flashduty returns an invalid-parameter error**: the request lacks the fields listed under Alert Key, or it is not a PowerJob JSON alarm
diff --git a/en/on-call/integration/alert-integration/alert-sources/projectdiscovery.mdx b/en/on-call/integration/alert-integration/alert-sources/projectdiscovery.mdx
index 54b46b50..fb2c18e9 100644
--- a/en/on-call/integration/alert-integration/alert-sources/projectdiscovery.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/projectdiscovery.mdx
@@ -1,5 +1,6 @@
---
title: "ProjectDiscovery Cloud alert integration"
+sidebarTitle: "ProjectDiscovery Cloud"
description: "Send new vulnerabilities found by rescans, and failed scans and asset discoveries, from ProjectDiscovery Cloud webhook alerting to Flashduty On-call."
keywords: ["alert integration", "ProjectDiscovery", "Nuclei", "vulnerability scanning", "asset discovery", "webhook", "scan_id"]
---
@@ -11,7 +12,6 @@ ProjectDiscovery sends no "fixed" or "resolved" notification, so these alerts do
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In ProjectDiscovery Cloud
----
<Steps>
<Step title="Add a webhook alerting configuration">
@@ -62,7 +61,6 @@ Clicking **Verify** when you create the webhook sends `{"type":"verify","message
</Note>
## Payload
----
ProjectDiscovery POSTs notifications as `application/json`, and Flashduty parses them directly with no template. Scan notifications carry `scan_name` and `scan_id`; asset discovery notifications carry `enumeration_name` and `enumeration_id`.
@@ -81,14 +79,12 @@ ProjectDiscovery POSTs notifications as `application/json`, and Flashduty parses
Alert title: `<name>: new vulnerabilities` for new vulnerabilities, `<name> failed` for failures.
## Alert Key
----
Flashduty uses `scan_id` (`enumeration_id` for asset discovery) as the Alert Key. ProjectDiscovery documents it as the unique identifier of the execution. Notifications with the same ID merge into one alert, and different scans or discoveries create different alerts. Changing the name, counts or time does not change the Alert Key.
If a new-vulnerability or failure notification has no matching ID, Flashduty returns a parameter error naming the missing field.
## Status and severity
----
| ProjectDiscovery event | Flashduty severity |
| :--- | :--- |
@@ -101,17 +97,14 @@ If a new-vulnerability or failure notification has no matching ID, Flashduty ret
For `new_vuln`, the highest severity in `rescan_vulns_list` decides; when the list is empty, the highest bucket of `severity_breakdown` with a count above 0 is used. A failed scan is a coverage gap rather than an outage, so it is a Warning.
## Auto-close
----
ProjectDiscovery sends no recovery notification, so these alerts stay active. Turn on [auto-close](/en/on-call/channel/create-edit) in the channel that receives them, with a suggested duration of 24 hours; adjust it to your scan frequency.
## About signatures
----
The ProjectDiscovery webhook supports an optional custom authentication header. Flashduty does not verify it and relies on the `integration_key` in the push URL, so keep the push URL secret.
## FAQ
----
<AccordionGroup>
<Accordion title="Why does a finished scan not create an alert?">
@@ -134,7 +127,6 @@ ProjectDiscovery sends `new_vuln` only for rescans, so the results of a first sc
</AccordionGroup>
## Troubleshooting
----
- **ProjectDiscovery reports a failed delivery**: check that the Webhook URL is the full HTTPS push URL including `integration_key`
- **Flashduty returns a parameter error**: check that the body is a ProjectDiscovery JSON notification and that `new_vuln` and `failed_stopped` carry `scan_id` or `enumeration_id`
diff --git a/en/on-call/integration/alert-integration/alert-sources/prometheus.mdx b/en/on-call/integration/alert-integration/alert-sources/prometheus.mdx
index 7f0b6b28..aa48d1da 100644
--- a/en/on-call/integration/alert-integration/alert-sources/prometheus.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/prometheus.mdx
@@ -1,5 +1,6 @@
---
title: "Prometheus Integration Guide"
+sidebarTitle: "Prometheus"
description: "Push Prometheus alert events to Flashduty through AlertManager using webhooks. When an alert is triggered, it sends a trigger event to Flashduty, and when the alert recovers, it sends a recovery event."
---
@@ -8,7 +9,6 @@ Push Prometheus alert events to Flashduty through AlertManager using webhooks. W
<div class="hide">
## Requirements
----
### In AlertManager
@@ -16,12 +16,10 @@ Push Prometheus alert events to Flashduty through AlertManager using webhooks. W
- Your AlertManager server must be able to access api.flashcat.cloud domain to push alerts to the internet.
## Supported Versions
----
This guide is compatible with **Alertmanager 0.16.0 and above**.
## Setup Steps
----
### In Flashduty
@@ -31,31 +29,33 @@ You can obtain an integration push URL through either of these two methods:
Choose this method when you don't need to route alert events to different channels. It's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**, and enter the integration page
3. Select **Prometheus** integration, click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
#### Using Shared Integration
Choose this method when you need to route alert events to different channels based on the alert payload.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Prometheus** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
### In AlertManager
@@ -159,7 +159,6 @@ VMP's `alertname` label is the alert rule's UUID, so the default alert title is
</Tip>
## Severity Mapping
----
The system extracts `severity`, `priority`, and `level` from alert event labels in that order. The corresponding value will be used as Prometheus's own alert severity. If none are found, it reads VMP's `internal_label_alert_level` label: `P0` maps to Critical, `P1` to Warning, and `P2` to Info. If that is also missing, the system sets the Prometheus alert severity to `Warning`.
@@ -177,7 +176,6 @@ Prometheus to Flashduty severity mapping:
| ok | Ok | Ok |
## FAQ
----
<details>
<summary>Why am I not receiving alerts in Flashduty?</summary>
diff --git a/en/on-call/integration/alert-integration/alert-sources/prtg.mdx b/en/on-call/integration/alert-integration/alert-sources/prtg.mdx
index 40ebadc2..c6829fcc 100644
--- a/en/on-call/integration/alert-integration/alert-sources/prtg.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/prtg.mdx
@@ -1,5 +1,6 @@
---
title: "PRTG alert integration"
+sidebarTitle: "PRTG"
description: "Send PRTG Network Monitor sensor alerts and recoveries to Flashduty On-call through Execute HTTP Action notification templates."
keywords: ["alert integration", "PRTG", "Paessler", "PRTG Network Monitor", "PRTG Hosted Monitor", "Execute HTTP Action", "notification template", "sensorid"]
---
@@ -9,7 +10,6 @@ Use the **Execute HTTP Action** of PRTG notification templates to send sensor st
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure PRTG
----
PRTG needs two notification templates: one sent when a sensor enters an alert state (`event=trigger`) and one sent when it leaves that state (`event=resolve`). Both templates use the same push URL and the same fields; only the leading `event` differs.
@@ -41,19 +40,19 @@ PRTG needs two notification templates: one sent when a sensor enters an alert st
2. Enter `Flashduty alert` as the **Template Name**
3. Select **Execute HTTP Action** and fill it in as follows:
-| Setting | Value |
-| :--- | :--- |
-| **URL** | The complete Flashduty push URL |
-| **SNI Handling** | **Send SNI** |
-| **SNI Name** | The host name in the push URL, for example `api.flashcat.cloud` |
-| **HTTP Method** | **POST** |
-| **Payload** | The alert template below, kept on one line |
+ | Setting | Value |
+ | :--- | :--- |
+ | **URL** | The complete Flashduty push URL |
+ | **SNI Handling** | **Send SNI** |
+ | **SNI Name** | The host name in the push URL, for example `api.flashcat.cloud` |
+ | **HTTP Method** | **POST** |
+ | **Payload** | The alert template below, kept on one line |
-Alert template:
+ Alert template:
-```text
-event=trigger&sensorid=%sensorid&laststatus=%laststatus&sensor=%sensor&device=%device&deviceid=%deviceid&group=%group&probe=%probe&host=%host&priority=%priority&linksensor=%linksensor&tags=%tags&sitename=%sitename&lastvalue=%lastvalue&message=%message
-```
+ ```text
+ event=trigger&sensorid=%sensorid&laststatus=%laststatus&sensor=%sensor&device=%device&deviceid=%deviceid&group=%group&probe=%probe&host=%host&priority=%priority&linksensor=%linksensor&tags=%tags&sitename=%sitename&lastvalue=%lastvalue&message=%message
+ ```
4. Click **Create**
@@ -76,11 +75,11 @@ You can send a test notification for a template from the **Notification Template
1. Open the object to connect (the Root group, a group, a device, or a sensor), go to the **Notification Triggers** tab, and select **Add State Trigger**
2. Fill it in as follows:
-| Setting | Value |
-| :--- | :--- |
-| **When sensor status is** | **Down**, **for at least** `60` **seconds** |
-| **perform** | `Flashduty alert` |
-| **When sensor status is no longer Down, perform** | `Flashduty recovery` |
+ | Setting | Value |
+ | :--- | :--- |
+ | **When sensor status is** | **Down**, **for at least** `60` **seconds** |
+ | **perform** | `Flashduty alert` |
+ | **When sensor status is no longer Down, perform** | `Flashduty recovery` |
3. Save the trigger. Child groups, devices, and sensors inherit it
@@ -100,7 +99,6 @@ Put a sensor into the Down state for real (for example, briefly cut the network
</Warning>
## Payload fields
----
PRTG posts the template fields as an `application/x-www-form-urlencoded` form. Each field is named after the PRTG placeholder that fills it:
@@ -125,14 +123,12 @@ PRTG posts the template fields as an `application/x-www-form-urlencoded` form. E
The alert title is `<device name>: <sensor name>`. If the device name is empty, Flashduty uses the sensor name alone; if both are empty, it uses `PRTG sensor <sensorid>`.
## Alert Key
----
Flashduty uses `sensorid` as the Alert Key. Alert, escalation, and recovery notifications for the same sensor carry the same sensor ID, so they land on the same alert. Two sensors with the same name on one device have different IDs and produce different alerts. Changing the sensor name, device name, status, or message does not change the Alert Key.
Sensor IDs are unique only within one PRTG server. Use a separate Flashduty integration for each PRTG server, so that sensors with the same ID on different servers do not merge into one alert.
## Status and severity
----
`event` decides whether the alert triggers or recovers, and `laststatus` decides the severity:
@@ -147,7 +143,6 @@ Sensor IDs are unique only within one PRTG server. Use a separate Flashduty inte
Requests with an empty or any other `event` are rejected, so a request whose state cannot be determined never enters the wrong alert lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="Why are two notification templates needed?">
@@ -182,7 +177,6 @@ PRTG sends placeholders it does not know as literal text. `%laststatus` needs PR
</AccordionGroup>
## Troubleshooting
----
- **PRTG fails to send**: check that the URL is the complete push URL including `integration_key`, and that HTTP Method is POST
- **Flashduty returns a parameter error**: check that the Payload contains the whole template on one line, including `event` and `sensorid`
diff --git a/en/on-call/integration/alert-integration/alert-sources/pulsetic.mdx b/en/on-call/integration/alert-integration/alert-sources/pulsetic.mdx
index e5078fdd..32bda10d 100644
--- a/en/on-call/integration/alert-integration/alert-sources/pulsetic.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/pulsetic.mdx
@@ -1,5 +1,6 @@
---
title: "Pulsetic alert integration"
+sidebarTitle: "Pulsetic"
description: "Send Pulsetic website down, recovery and SSL certificate expiry alerts to Flashduty On-call through a monitor webhook."
keywords: ["alert integration", "Pulsetic", "Uptime", "website monitoring", "webhook", "monitor_offline", "monitor_online"]
---
@@ -9,7 +10,6 @@ Use the webhook notification of a Pulsetic monitor to send down (`monitor_offlin
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Pulsetic
----
<Steps>
<Step title="Open the monitor's webhook settings">
@@ -61,7 +60,6 @@ Let a monitor go down for real (for example, point it to a URL that returns 5xx)
</Steps>
## Payload
----
Pulsetic POSTs the following fields as JSON. Flashduty parses them directly, with no template to configure:
@@ -80,7 +78,6 @@ Pulsetic POSTs the following fields as JSON. Flashduty parses them directly, wit
The alert title is the monitor name. When the name is empty, the monitored URL is used.
## Alert Key
----
Flashduty uses `monitor.id` as the Alert Key for down and recovery alerts. The down, repeated down and recovery notifications of one monitor carry the same `monitor.id`, so they land on the same alert. Renaming the monitor or changing its URL or tags does not change the Alert Key.
@@ -89,7 +86,6 @@ SSL certificate expiry notifications get their own Alert Key built from `alert_t
When `monitor.id` is missing, Flashduty returns a parameter error because the recovery cannot be matched to the original alert.
## Status and severity
----
Pulsetic notifications carry no severity. Flashduty maps them as follows:
@@ -102,7 +98,6 @@ Pulsetic notifications carry no severity. Flashduty maps them as follows:
Any other `alert_type` (for example, a type Pulsetic adds later) is acknowledged and ignored without creating an alert.
## FAQ
----
<AccordionGroup>
<Accordion title="Does the SSL expiry alert close on its own?">
@@ -125,7 +120,6 @@ Pulsetic probes at the check interval set on the monitor, and you can set how lo
</AccordionGroup>
## Troubleshooting
----
- **Pulsetic does not push**: confirm the monitor's Alerts → Webhook is saved and the Webhook URL is the complete push URL including `integration_key`
- **Flashduty returns a parameter error**: confirm the request body contains `alert_type` and `monitor.id`
diff --git a/en/on-call/integration/alert-integration/alert-sources/pulseway.mdx b/en/on-call/integration/alert-integration/alert-sources/pulseway.mdx
index 4ae71247..06572f5c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/pulseway.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/pulseway.mdx
@@ -1,5 +1,6 @@
---
title: "Pulseway alert integration"
+sidebarTitle: "Pulseway"
description: "Sync Pulseway RMM device notifications to Flashduty On-call through Pulseway notification webhooks."
keywords: ["alert integration", "Pulseway", "RMM", "remote monitoring", "notification webhook", "webhook"]
---
@@ -9,7 +10,6 @@ Pulseway is a remote monitoring and management (RMM) platform for IT teams and M
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Pulseway
----
Pulseway notification webhooks are created through the REST API. One webhook covers every device in the selected organizations, and nothing is installed on the devices.
@@ -85,12 +84,10 @@ On a monitored test device, trigger a notification at one of the selected priori
</Steps>
## Alert Key
----
Flashduty uses the notification `Id` as the Alert Key, so each notification opens its own alert. While a problem persists, Pulseway notifies again with a new `Id`, which opens a new alert; the channel can group these alerts into one incident by rule. A device coming back online is a separate notification in Pulseway and does not close the earlier alert.
## Alert severity
----
| Pulseway `Priority` | Flashduty severity |
| :--- | :--- |
@@ -103,7 +100,6 @@ Flashduty uses the notification `Id` as the Alert Key, so each notification open
Priority matching is case-insensitive.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -117,7 +113,6 @@ Priority matching is case-insensitive.
The alert title is the notification `Title` and the description is the notification `Message`.
## FAQ
----
<AccordionGroup>
diff --git a/en/on-call/integration/alert-integration/alert-sources/raritan-px.mdx b/en/on-call/integration/alert-integration/alert-sources/raritan-px.mdx
index 73110a87..d3950ec1 100644
--- a/en/on-call/integration/alert-integration/alert-sources/raritan-px.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/raritan-px.mdx
@@ -1,5 +1,6 @@
---
title: "Raritan PX PDU alert integration"
+sidebarTitle: "Raritan PX PDU"
description: "Raritan PX-Series PDUs send email notifications through event rules; use a Flashduty email integration with rules to trigger and close PDU alerts."
keywords: ["alert integration", "Raritan", "Raritan PX", "PX3", "PDU", "email", "environment monitoring"]
---
@@ -9,7 +10,6 @@ Raritan PX-Series PDUs send email through the **Send email** action of an event
<div className="hide">
## In Flashduty On-call
----
Get the integration email address in either of the two ways below. **In both cases choose the Email integration type**, not Raritan.
@@ -30,7 +30,6 @@ Get the integration email address in either of the two ways below. **In both cas
</div>
## Configure push rules in Flashduty
----
The subject format below puts the device name, the event rule name and an assertion flag in the title. The flag `1` means the event condition became true and `0` means it cleared. The rules extract the device name and event rule name as the Alert Key. Trigger and resolve emails yield the same key, so a resolve email closes the matching alert.
@@ -55,7 +54,6 @@ Regex: /^Raritan PX \| (.+) \| (.+) \| 1$/
The close rule comes before the trigger rule. The default rule discards emails that do not follow the subject format, such as default emails sent by other event rules, so they don't create alerts that can never close on their own.
## Configure Raritan PX
----
The paths below come from the Raritan PX-Series PDU user guide (firmware 4.3.11) and are used in the PDU web interface.
@@ -63,21 +61,20 @@ The paths below come from the Raritan PX-Series PDU user guide (firmware 4.3.11)
2. **Create the action**: go to **Device Settings** → **Event Rules**, create an action, choose **Send email** in **Action**, and enter the Flashduty email integration address in **Recipient email addresses**
3. **Email subject**: select **Custom subject** and enter:
-```
-Raritan PX | [DEVICENAME] | [EVENTRULENAME] | [ISASSERTED]
-```
+ ```
+ Raritan PX | [DEVICENAME] | [EVENTRULENAME] | [ISASSERTED]
+ ```
-`[DEVICENAME]` (the device the event occurred on), `[EVENTRULENAME]` (the name of the matching event rule) and `[ISASSERTED]` (1 when the event condition became true, 0 when it became false) are placeholders listed in the user guide; they are replaced with actual values when the email is sent. A rendered subject looks like:
+ `[DEVICENAME]` (the device the event occurred on), `[EVENTRULENAME]` (the name of the matching event rule) and `[ISASSERTED]` (1 when the event condition became true, 0 when it became false) are placeholders listed in the user guide; they are replaced with actual values when the email is sent. A rendered subject looks like:
-```
-Raritan PX | PX3-rack12 | Rack12 temperature high | 1
-```
+ ```
+ Raritan PX | PX3-rack12 | Rack12 temperature high | 1
+ ```
4. **Create the event rule**: go to **Device Settings** → **Event Rules**, create a rule, select the event to watch (for example **Above upper critical threshold** of a temperature sensor), set **Trigger condition** to **Both** so the action runs when the event occurs and when it clears, and select the Send email action from step 2 in **Available actions**
5. **Email body**: the rules read only the email title; the default or a custom message both work
## Limitations
----
- **Unique event rule names**: the Alert Key is built from the device name and the event rule name, so events that share one rule name merge into one alert. Create a separate event rule with its own name for each event you want to monitor.
- **Trigger condition**: with **Asserted** only, the PDU sends trigger emails but no resolve emails, and alerts do not close automatically.
diff --git a/en/on-call/integration/alert-integration/alert-sources/raygun.mdx b/en/on-call/integration/alert-integration/alert-sources/raygun.mdx
index 344b9dea..2b6d7974 100644
--- a/en/on-call/integration/alert-integration/alert-sources/raygun.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/raygun.mdx
@@ -1,5 +1,6 @@
---
title: "Raygun alert integration"
+sidebarTitle: "Raygun"
description: "Send error notifications and status changes from a Raygun Crash Reporting application to Flashduty On-call through a webhook."
keywords: ["alert integration", "Raygun", "webhook", "error monitoring", "Crash Reporting"]
---
@@ -9,7 +10,6 @@ Use the Webhook integration of a Raygun Crash Reporting application to send erro
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Raygun
----
The Webhook integration is configured per application and is available only on Raygun's Team plan or higher. Configure each application separately; several applications can use the same push URL.
@@ -75,14 +74,12 @@ Use the application-level **Integrations → Webhooks**. The plan-level webhooks
</Note>
## Alert Key
----
Flashduty groups alerts by Raygun error group: the new, reoccurred, follow-up, and resolved notifications of the same error group land on the same alert.
The Alert Key is built from `error.url` in the event, the link to the error group page in Raygun. Only the path of the link is used; the scheme, host, trailing slash, and query string are ignored. Changes to the error message, occurrence count, affected user count, and tags do not change the Alert Key. Events without `error.url` are rejected.
## Status and severity
----
Raygun errors carry no severity, so Flashduty uses Warning for all of them:
@@ -92,7 +89,6 @@ Raygun errors carry no severity, so Flashduty uses Warning for all of them:
| `StatusChanged` with `status` `resolved` or `archived` (case-insensitive) | Recover | - |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -108,7 +104,6 @@ Raygun errors carry no severity, so Flashduty uses Warning for all of them:
Affected user identifiers, custom data (`customData`), and the name of the person who made a change are not written to labels.
## Troubleshooting
----
- **Webhooks is missing from the integration list**: Make sure the account is on the Team plan or higher, or on a trial
- **Flashduty returns a parameter error**: Make sure the URL is complete and includes `integration_key`, and that you configured the application-level webhook rather than a webhook in Alerting
diff --git a/en/on-call/integration/alert-integration/alert-sources/rbltracker.mdx b/en/on-call/integration/alert-integration/alert-sources/rbltracker.mdx
index 00d5b38b..6bbd06e7 100644
--- a/en/on-call/integration/alert-integration/alert-sources/rbltracker.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/rbltracker.mdx
@@ -1,5 +1,6 @@
---
title: "RBLTracker alert integration"
+sidebarTitle: "RBLTracker"
description: "Send RBLTracker (Generator Labs) blocklist listings, certificate expiry and errors, and monitoring agent timeouts to Flashduty On-call through a webhook."
keywords: ["alert integration", "RBLTracker", "Generator Labs", "blocklist", "RBL", "certificate monitoring", "webhook"]
---
@@ -15,7 +16,6 @@ Events that come in trigger and resolve pairs map to one Flashduty alert: the tr
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -36,7 +36,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure RBLTracker
----
<Steps>
<Step title="Add a webhook">
@@ -80,7 +79,6 @@ To verify the full lifecycle, add a test host that you know is listed, confirm t
</Steps>
## Alert Key
----
Flashduty uses the SID of the object in the RBLTracker event as the Alert Key, with a prefix per event category:
@@ -98,7 +96,6 @@ In the official RBLTracker API reference, `rbl.host.listed` and `rbl.host.delist
Changes to the host name, the number of blocklists, the check SID (`check_sid`), or the event SID (`event_sid`) never change the Alert Key. An event without the matching SID is rejected.
## Status and severity
----
The event type sets the alert status; the table above shows which events recover. RBLTracker does not send a severity, so Flashduty sets it by event type:
@@ -113,12 +110,10 @@ The event type sets the alert status; the table above shows which events recover
| `agent.timeout` | Warning | The agent stopped checking in, so monitoring has a blind spot |
## Auto-close for one-shot events
----
`cert.changed` is a single notification, and RBLTracker never sends a matching resolve event. Each certificate replacement on a monitor creates its own alert, and these alerts do not recover on their own. Turn on the [auto-close timeout](/en/on-call/channel/create-edit) for the channel and set it to **24 hours**.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -140,14 +135,12 @@ The event type sets the alert status; the table above shows which events recover
| `instances` | Identifiers of the agent instances that timed out |
## Delivery and retries
----
RBLTracker sends `application/json` POST requests, and a 2xx response from Flashduty counts as delivered. A failed delivery (non-2xx, timeout, or connection error) is retried after 30 seconds and again after 2 minutes with the same event SID, so retries do not create duplicate alerts. After 10, 20, and 30 consecutive failures RBLTracker pauses the webhook for 1 hour, 6 hours, and 1 day; after 40 it disables the webhook and you must re-enable it under **Development → Webhooks**.
Every delivery carries an `X-Webhook-Signature` header. Flashduty authenticates requests with the `integration_key` in the push URL and does not verify that header.
## Troubleshooting
----
- **RBLTracker shows a failed delivery**: confirm the URL is complete and includes `integration_key`, and check the response code in the **Send Test** result
- **Flashduty returns an invalid parameter error**: the body must be an RBLTracker JSON delivery; events without `host.sid`, `monitor.sid`, or `agent.sid` are rejected
diff --git a/en/on-call/integration/alert-integration/alert-sources/red-hat-openshift.mdx b/en/on-call/integration/alert-integration/alert-sources/red-hat-openshift.mdx
index 3a9c4876..d47c0b52 100644
--- a/en/on-call/integration/alert-integration/alert-sources/red-hat-openshift.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/red-hat-openshift.mdx
@@ -1,5 +1,6 @@
---
title: "Red Hat OpenShift Alert Integration"
+sidebarTitle: "Red Hat OpenShift"
description: "Receive OpenShift cluster alerts through the webhook receiver of OpenShift monitoring's built-in Alertmanager using a Flashduty Prometheus integration; alerts close automatically when they resolve."
keywords: ["alert integration", "Red Hat OpenShift", "OpenShift", "Alertmanager", "webhook", "Prometheus", "Kubernetes"]
---
@@ -9,7 +10,6 @@ The OpenShift Container Platform monitoring stack ships its own Alertmanager (`a
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the Prometheus integration type** in both, not Red Hat OpenShift.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the Promet
</div>
## Configure in OpenShift
----
The OpenShift documentation offers two ways to configure a receiver; use either one. Both require the `cluster-admin` role.
@@ -57,24 +56,24 @@ The OpenShift documentation offers two ways to configure a receiver; use either
2. Add a receiver and a route to `alertmanager.yaml`. The example adds a `flashduty` receiver to the default configuration and routes alerts whose `severity` is `critical` or `warning` to it. `send_resolved` defaults to `true` in the Alertmanager webhook configuration; it is written out to make sure resolved notifications stay on:
-```yaml
-receivers:
-- name: default
-- name: watchdog
-- name: flashduty
- webhook_configs:
- - url: https://api.flashcat.cloud/event/push/alert/prometheus?integration_key=<integration key>
- send_resolved: true
-route:
- routes:
- - matchers:
- - "alertname=Watchdog"
- repeat_interval: 2m
- receiver: watchdog
- - matchers:
- - "severity=~critical|warning"
- receiver: flashduty
-```
+ ```yaml
+ receivers:
+ - name: default
+ - name: watchdog
+ - name: flashduty
+ webhook_configs:
+ - url: https://api.flashcat.cloud/event/push/alert/prometheus?integration_key=<integration key>
+ send_resolved: true
+ route:
+ routes:
+ - matchers:
+ - "alertname=Watchdog"
+ repeat_interval: 2m
+ receiver: watchdog
+ - matchers:
+ - "severity=~critical|warning"
+ receiver: flashduty
+ ```
Replace `<integration key>` with your Flashduty integration key. Keep the new route after the `Watchdog` route: Watchdog is an alert that fires continuously, and the OpenShift documentation describes it as a check on the notification path, not a fault alert to forward to Flashduty.
@@ -94,7 +93,6 @@ Trigger a cluster alert (the OpenShift documentation points to the Red Hat Custo
</Steps>
## Field mapping
----
| OpenShift Alertmanager field | Flashduty |
| :--- | :--- |
@@ -109,14 +107,12 @@ Trigger a cluster alert (the OpenShift documentation points to the Red Hat Custo
One notification can carry several alerts, and Flashduty handles each one separately (up to 100 per request).
## Recovery and deduplication
----
- `send_resolved` defaults to `true` for the Alertmanager webhook receiver. On recovery it sends a notification with `status` set to `resolved`, and Flashduty closes the alert with the same `fingerprint`.
- If you turn resolved notifications off under **Show advanced configuration** (or set `send_resolved: false` in YAML), Flashduty receives no recovery requests; enable [auto-resolve timeout](/en/on-call/channel/create-edit) on the channel.
- Alertmanager repeats notifications for alerts that are still firing, per `repeat_interval`; Flashduty deduplicates by `fingerprint`, so no duplicate alerts are created.
## Troubleshooting
----
- **Flashduty returns `Invalid parameters`**: the push URL is incomplete, `integration_key` is missing, or the integration type is not Prometheus
- **Alerts do not resolve**: confirm the receiver does not set `send_resolved: false`
diff --git a/en/on-call/integration/alert-integration/alert-sources/redash.mdx b/en/on-call/integration/alert-integration/alert-sources/redash.mdx
index 6ae00323..8186b319 100644
--- a/en/on-call/integration/alert-integration/alert-sources/redash.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/redash.mdx
@@ -1,5 +1,6 @@
---
title: "Redash alert integration"
+sidebarTitle: "Redash"
description: "Send alert state changes from Redash to Flashduty On-call through the Webhook alert destination."
keywords: ["alert integration", "Redash", "webhook", "query alerts", "data analytics"]
---
@@ -9,7 +10,6 @@ Use the Webhook alert destination of Redash to send query alert state changes to
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Redash
----
You need Redash administrator privileges to create an alert destination, and the Redash server must be able to reach the Flashduty push URL.
@@ -66,14 +65,12 @@ The Redash Webhook destination has no test button.
</Steps>
## Alert Key
----
Flashduty uses the Redash alert ID (`alert.id`) as the Alert Key. The trigger, repeated notifications, and recovery of one Redash alert share one Alert Key. Changes to the alert name, condition, threshold, or state do not change it. A request without `alert.id` is rejected.
Connect only one Redash instance to each Flashduty integration: alert IDs repeat across instances, so create a separate integration for each.
## State and severity
----
Redash notifications carry no severity, so Flashduty acts on the alert state:
@@ -86,7 +83,6 @@ Redash notifications carry no severity, so Flashduty acts on the alert state:
`unknown` means the query has no data to evaluate. Redash notifies only when the state changes, or when a triggered alert passes its repeat interval; an alert whose first evaluation is `OK` sends no notification.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -98,7 +94,6 @@ Redash notifications carry no severity, so Flashduty acts on the alert state:
| `alert_url` / `query_url` | Links to the alert and the query in Redash |
## Troubleshooting
----
- **Flashduty receives no alert**: confirm the alert has the Webhook destination, is not muted, and its query is published and runs on a refresh schedule (on a self-hosted Redash the worker must consume the `periodic` and `scheduled_queries` queues, which the default configuration does). Redash times the request out after 5 seconds and does not retry; failures appear only in the Redash log
- **Flashduty returns an invalid-parameter error**: confirm the URL is complete and includes `integration_key`
diff --git a/en/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor.mdx b/en/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor.mdx
index 39d82017..744f4880 100644
--- a/en/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor.mdx
@@ -1,5 +1,6 @@
---
title: "Redgate SQL Monitor alert integration"
+sidebarTitle: "Redgate SQL Monitor"
description: "Send Redgate Monitor (formerly SQL Monitor) alerts to Flashduty On-call through a webhook, with automatic recovery when an alert ends."
keywords: ["alert integration", "Redgate", "SQL Monitor", "Redgate Monitor", "SQL Server", "webhook"]
---
@@ -9,7 +10,6 @@ Use the webhook notifications of Redgate Monitor (formerly Redgate SQL Monitor)
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Redgate Monitor
----
Webhook notifications are configured in the Redgate Monitor web console, apply to every alert raised by that Base Monitor, and require administrator permissions. The machine that runs the Base Monitor service must be able to reach the Flashduty push URL.
@@ -65,12 +64,10 @@ If the Base Monitor reaches the internet through a proxy, configure the proxy on
</Note>
## Alert Key
----
A Redgate Monitor alert ID (`id`) is unique only within a single Base Monitor, so Flashduty computes the Alert Key from both the Base Monitor identifier (`baseMonitorGuid`) and the alert ID (`id`). The Raised, Escalated, DeEscalated, and Ended messages of one alert share the same Alert Key, and alerts from several Base Monitors that push to the same integration never merge. Changes to the alert name, severity, description, or timestamps do not change the Alert Key. Messages without `id` or `baseMonitorGuid` are rejected.
## Status and severity
----
| `statusChange` | Meaning | Flashduty status |
| :--- | :--- | :--- |
@@ -88,7 +85,6 @@ A Redgate Monitor alert ID (`id`) is unique only within a single Base Monitor, s
An `Ended` message carries `severity` `None`, so Flashduty uses `previousSeverity` (the severity before the alert ended) as the severity of the recovery event. An empty or unrecognized severity is treated as Warning. Messages whose `messageType` is not `AlertNotification` do not create alerts; Flashduty returns success for them.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -109,7 +105,6 @@ An `Ended` message carries `severity` `None`, so Flashduty uses `previousSeverit
The alert description is Redgate Monitor's description of the alert type. For a custom metric with a secondary query, it also includes the detail text that query returns (`alertDetailText`).
## Troubleshooting
----
- **The test message fails**: Confirm that the Base Monitor machine can reach the Flashduty push URL, and configure the proxy as described above if one is required
- **Flashduty returns a parameter error**: Confirm that the URL is complete and includes `integration_key`, and that the default message format is selected
diff --git a/en/on-call/integration/alert-integration/alert-sources/rizhiyi.mdx b/en/on-call/integration/alert-integration/alert-sources/rizhiyi.mdx
index 019c39c1..52550fd6 100644
--- a/en/on-call/integration/alert-integration/alert-sources/rizhiyi.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/rizhiyi.mdx
@@ -1,5 +1,6 @@
---
title: "Logease Alert Integration"
+sidebarTitle: "Logease"
description: "Push Logease (rizhiyi) alert events to Flashduty through a custom alarm plugin for automated alert noise reduction"
keywords: ["alert integration", "Logease", "rizhiyi", "log monitoring", "data ingestion"]
---
@@ -7,7 +8,6 @@ keywords: ["alert integration", "Logease", "rizhiyi", "log monitoring", "data in
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
@@ -15,35 +15,36 @@ You can obtain an integration push URL through either of these two methods:
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Select **Logease** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Logease** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Logease
----
Logease alerts can be delivered via email, syslog, alert forwarding, or custom alarm plugins. The JSON structure pushed by **alert forwarding** is a fixed Logease format that does not match the event format required by Flashduty. Therefore, use a **custom alarm plugin** (a Python script) to convert alerts into the standard format before pushing them to Flashduty.
@@ -134,7 +135,6 @@ The events pushed by the plugin must follow the Flashduty standard alert event f
</Note>
## Severity Mapping
----
<div class="md-block">
@@ -152,7 +152,6 @@ The mapping from Logease alert levels to Flashduty severities is defined by `LEV
</div>
## FAQ
----
<details>
<summary>Why am I not receiving alerts in Flashduty?</summary>
diff --git a/en/on-call/integration/alert-integration/alert-sources/robotalp.mdx b/en/on-call/integration/alert-integration/alert-sources/robotalp.mdx
index 144280a9..3bec6a65 100644
--- a/en/on-call/integration/alert-integration/alert-sources/robotalp.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/robotalp.mdx
@@ -1,5 +1,6 @@
---
title: "Robotalp alert integration"
+sidebarTitle: "Robotalp"
description: "Send Robotalp monitor downtimes and recoveries to Flashduty On-call through its Custom Webhook."
keywords: ["alert integration", "Robotalp", "uptime monitoring", "webhook"]
---
@@ -9,7 +10,6 @@ Robotalp is an uptime monitoring service. When a monitor goes down or recovers,
<div className="hide">
## In Flashduty On-call
----
You can get the integration Push URL in either of the following two ways.
@@ -30,7 +30,6 @@ You can get the integration Push URL in either of the following two ways.
</div>
## Configure Robotalp
----
<Steps>
<Step title="Add a Custom Webhook integration">
@@ -67,7 +66,6 @@ The check interval is set on the monitor; with a 1-minute interval, the down and
</Steps>
## Alert Key
----
Flashduty uses `incident_id` from the request body as the Alert Key. Robotalp sends the same `incident_id` on the down notification and the recovery notification of one downtime. We verified this on a real Robotalp account: a monitor went down and then recovered, and both deliveries carried the same `incident_id`.
@@ -76,7 +74,6 @@ Flashduty uses `incident_id` from the request body as the Alert Key. Robotalp se
- Requests without `incident_id` are rejected, because their recovery could not be matched reliably
## Status and severity
----
The Robotalp request body has no severity field, only `status`.
@@ -88,7 +85,6 @@ The Robotalp request body has no severity field, only `status`.
Any other value is rejected. A recovery carries `resolved_at` and `downtime_seconds`; Flashduty stores them as labels together with the failure reason `result_message`.
## Troubleshooting
----
- **Flashduty receives nothing**: confirm the webhook is enabled under the monitor's **Notification Preferences** and that the Push URL is complete, including `integration_key`
- **The alert does not recover**: confirm **Custom payload** does not override `incident_id` or `status`. If the monitor is paused or deleted, Robotalp sends no recovery, so close the alert by hand; you can also turn on auto-close in the channel as a fallback
diff --git a/en/on-call/integration/alert-integration/alert-sources/robusta.mdx b/en/on-call/integration/alert-integration/alert-sources/robusta.mdx
index c8a8dd3d..0b23dcf2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/robusta.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/robusta.mdx
@@ -1,5 +1,6 @@
---
title: "Robusta alert integration"
+sidebarTitle: "Robusta"
description: "Send Robusta alerts from your Kubernetes clusters to Flashduty On-call through the Robusta webhook sink."
keywords: ["alert integration", "Robusta", "Kubernetes", "K8s", "Prometheus", "webhook"]
---
@@ -9,7 +10,6 @@ Use the Robusta webhook sink (`webhook_sink`) to send Robusta findings to Flashd
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Robusta
----
<Steps>
<Step title="Add a webhook sink">
@@ -74,7 +73,6 @@ If your Prometheus alerts do not go through Robusta, Alertmanager can also push
</Tip>
## Alert Key
----
Flashduty computes the Alert Key from `cluster_name` and `fingerprint`.
@@ -84,7 +82,6 @@ Flashduty computes the Alert Key from `cluster_name` and `fingerprint`.
Changes to the title, description, severity, timestamps, or finding ID do not change the Alert Key. Flashduty rejects a request without `fingerprint`, because later notifications could not be matched to it.
## Status and severity
----
Flashduty marks the alert as recovered when the request has a non-empty `ends_at` or the title starts with `[RESOLVED] `. Robusta sends such notifications only for Prometheus alerts that Alertmanager has resolved, so make sure the Robusta receiver in Alertmanager has `send_resolved: true` (the Prometheus bundled with Robusta has it on by default).
@@ -98,14 +95,12 @@ Flashduty marks the alert as recovered when the request has a non-empty `ends_at
When Robusta forwards a Prometheus alert, it converts the alert's `severity` label: `critical`, `high`, `medium`, and `error` become `HIGH`; `warning` and `low` become `LOW`; `info` and any other value become `INFO`; `debug` becomes `DEBUG`. A resolution keeps the last severity.
## Alert content
----
- **Title**: `title`, with the `[RESOLVED] ` prefix removed from resolutions
- **Description**: `description`, the links in `links` (such as the Prometheus graph), and the resolution time `ends_at`
- **Labels**: `cluster`, `fingerprint`, `aggregation_key` (alert name or problem type), `finding_source` (such as `PROMETHEUS` or `KUBERNETES_API_SERVER`), `finding_type`, `severity` (the original Robusta severity), `resource` (`kind/namespace/name`), `kind`, `namespace`, `node`, `container`, `source` (always `robusta`), plus the resource labels and Prometheus alert labels from `subject.labels` (such as `alertname` and `pod`)
## Troubleshooting
----
- **Flashduty returns request body is not Robusta JSON**: the `webhook_sink` does not set `format: json`
- **Flashduty returns fingerprint is required**: make sure `slack_webhook` is off and `size_limit` is not set too small
diff --git a/en/on-call/integration/alert-integration/alert-sources/rollbar.mdx b/en/on-call/integration/alert-integration/alert-sources/rollbar.mdx
index 967af46c..39ec6ff2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/rollbar.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/rollbar.mdx
@@ -1,5 +1,6 @@
---
title: "Rollbar alert integration"
+sidebarTitle: "Rollbar"
description: "Send new, reactivated, and resolved item events from a Rollbar project to Flashduty On-call through a webhook."
keywords: ["alert integration", "Rollbar", "item", "webhook", "error monitoring"]
---
@@ -9,7 +10,6 @@ Use the Webhook notification channel of a Rollbar project to send error items to
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Rollbar
----
Webhooks are configured per project. You need permission to change the project's notification settings in Rollbar.
@@ -76,14 +75,12 @@ Raise a new error in an application that uses a Rollbar SDK and confirm that Fla
</Steps>
## Alert Key
----
Flashduty uses the item `id` (`data.item.id` in the webhook) as the Alert Key. In Rollbar's official webhook examples, the `new_item`, `item_velocity`, `exp_repeat_item`, and `resolved_item` events for the same item carry the same `id`. It is also the ID that the Rollbar API uses to look up an item.
The number in an item URL (such as `.../items/40`) is the project-level `counter` and is kept only as a label. Changes to the title, level, environment, or occurrence count do not change the Alert Key. Item events without `data.item.id` are rejected.
## Status and severity
----
The event name sets the alert status: `resolved_item` recovers the alert, and every other item event triggers it. The item level (`data.item.level`) sets the severity:
@@ -99,7 +96,6 @@ The event name sets the alert status: `resolved_item` recovers the alert, and ev
New Rollbar items default to `error`. To be notified at Critical for a class of errors, change the item level to `critical` in Rollbar or set the level in your SDK.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -117,7 +113,6 @@ New Rollbar items default to `error`. To be notified at Critical for a class of
| `window` / `threshold` | Time window and threshold of `item_velocity` |
## Troubleshooting
----
- **Rollbar shows failed deliveries**: Confirm that the URL is complete and includes `integration_key`, and check each attempt under the rule's **History**. Rollbar retries failed deliveries and automatically disables rules that keep failing; re-enable the rule on the Webhook settings page after fixing the cause
- **Flashduty returns a parameter error**: Confirm that the rule's payload format is JSON
diff --git a/en/on-call/integration/alert-integration/alert-sources/rum-alert.mdx b/en/on-call/integration/alert-integration/alert-sources/rum-alert.mdx
index 08f192f9..9c6d250b 100644
--- a/en/on-call/integration/alert-integration/alert-sources/rum-alert.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/rum-alert.mdx
@@ -1,5 +1,6 @@
---
title: "RUM Alert Integration"
+sidebarTitle: "RUM"
description: "Flashduty RUM alert integration, RUM service reports alerts through this integration"
---
@@ -13,6 +14,6 @@ You cannot modify or delete this integration. However, you can manage the label
Go to the `RUM` - `Application Details` - `Alert Settings` page to enable alerts. You can choose to deliver alerts to multiple channels. Alert notification rules follow the escalation rules under the channel, and you can set responders for the team to assign to responders when alerts occur.
-
+
-For more information, please refer to [RUM Issue Alerting](https://docs.flashduty.com/en/flashduty/rum/issue-alerting?nav=01JCQ7A4N4WRWNXW8EWEHXCMF5).
+For more information, please refer to [RUM Issue Alerting](/en/rum/error-tracking/issue-alerts).
diff --git a/en/on-call/integration/alert-integration/alert-sources/searchstax.mdx b/en/on-call/integration/alert-integration/alert-sources/searchstax.mdx
index 9210fabd..dbab6210 100644
--- a/en/on-call/integration/alert-integration/alert-sources/searchstax.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/searchstax.mdx
@@ -1,5 +1,6 @@
---
title: "SearchStax alert integration"
+sidebarTitle: "SearchStax"
description: "Send SearchStax Managed Search metric alerts to Flashduty On-call through a webhook. Flashduty alerts close automatically when the SearchStax alert closes."
keywords: ["alert integration", "SearchStax", "Managed Search", "Solr", "webhook", "search service"]
---
@@ -9,7 +10,6 @@ SearchStax Managed Search lets you define the webhook body: the webhook's **Payl
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure SearchStax
----
Managing webhooks and alerts requires the Account Owner, Admin, or Technical Contact role in SearchStax.
@@ -84,7 +83,6 @@ Push a metric over its threshold (for example, give a test alert a very low thre
</Steps>
## Alert Key
----
Flashduty uses `alert_id` (`$ALERT_ID`) as the Alert Key. SearchStax describes it as the internal alert number. Trigger and resolve use the same webhook template, so `OPEN` and `CLOSED` messages land on the same Flashduty alert.
@@ -93,7 +91,6 @@ A SearchStax alert is a deployment-level rule: a rule whose `host` is `*` watche
Changes to the alert title, metric value, or time do not change the Alert Key. Flashduty rejects a request that lacks `alert_id` or `alert_status`, or whose value is still an unrendered `$...` variable.
## Alert lifecycle
----
Flashduty handles a message by its `alert_status` field (`$ALERT_STATUS`, case-insensitive):
@@ -105,12 +102,10 @@ Flashduty handles a message by its `alert_status` field (`$ALERT_STATUS`, case-i
Any other value is rejected.
## Severity
----
SearchStax alerts carry no severity, so every alert defaults to **Warning**. To use another level, append `&severity=Critical` (or `Info`) to the push URL. A recovery keeps the severity of the original alert.
## Alert content
----
- **Title**: the alert name (`$ALERT_TITLE`); `SearchStax alert <alert_id>` when missing
- **Description**: `metric current-value operator threshold`, for example `os.SystemCpuLoad 0.01 > 10.0`
@@ -119,7 +114,6 @@ SearchStax alerts carry no severity, so every alert defaults to **Warning**. To
Fields with an empty value are not written as labels.
## Troubleshooting
----
- **Flashduty says the body is not valid JSON**: check that the Payload matches the template and that form encoding is off
- **No alert arrives**: check that the alert's webhook droplist selects this webhook and that the webhook is not **Paused**. Tick **Ignore SSL Validation** only if the target uses a self-signed certificate
diff --git a/en/on-call/integration/alert-integration/alert-sources/securityscorecard.mdx b/en/on-call/integration/alert-integration/alert-sources/securityscorecard.mdx
index f1ddb386..3a014fcd 100644
--- a/en/on-call/integration/alert-integration/alert-sources/securityscorecard.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/securityscorecard.mdx
@@ -1,5 +1,6 @@
---
title: "SecurityScorecard alert integration"
+sidebarTitle: "SecurityScorecard"
description: "Send SecurityScorecard score changes, new issues and breach events to Flashduty On-call with the Rule Builder Send a web request action."
keywords: ["alert integration", "SecurityScorecard", "security rating", "Rule Builder", "webhook", "execution_id"]
---
@@ -11,7 +12,6 @@ SecurityScorecard sends an event once, when it happens, and sends no recovery no
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure SecurityScorecard
----
Rule Builder requires a paid SecurityScorecard plan, and each user can create up to 25 rules.
@@ -65,14 +64,12 @@ Rule Builder has no button that sends a test request. SecurityScorecard evaluate
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from `execution_id`, `scorecard_id` and `trigger.type`. The SecurityScorecard article [Rule Builder: Webhooks](https://support.securityscorecard.com/hc/en-us/articles/360058429271-Rule-Builder-Webhooks) defines `execution_id` as the unique identifier of one rule execution, and it stays the same when a failed request is retried. A retry of the same execution therefore merges into the same alert, and every other rule execution becomes its own alert.
When a request has no `execution_id`, Flashduty generates a random Alert Key and every request becomes a new alert. A request without `trigger.type` returns a parameter error.
## Severity
----
| Event (`trigger.type`) | Condition | Flashduty severity |
| :--- | :--- | :--- |
@@ -83,7 +80,6 @@ When a request has no `execution_id`, Flashduty generates a random Alert Key and
| Score change (`grade_drop`) and any other event type | | Warning |
## Field mapping
----
| Flashduty | SecurityScorecard field |
| :--- | :--- |
@@ -94,12 +90,10 @@ When a request has no `execution_id`, Flashduty generates a random Alert Key and
The `retries` and `webhooks` (responses of earlier webhooks in the rule) fields are not copied to the alert. SecurityScorecard marks this request body as beta; if the structure of the issue or breach details changes, Flashduty ignores the parts it cannot parse and still creates the alert.
## Alerts do not recover
----
Score changes, new issues and breaches are one-shot events, and SecurityScorecard sends no recovery notification. Turn on [auto-resolve timeout](/en/on-call/channel/create-edit) in the channel that receives this integration. 24 hours is a reasonable start; adjust it to how long your team takes to handle security rating events.
## Troubleshooting
----
<AccordionGroup>
<Accordion title="The rule ran but no alert arrives">
diff --git a/en/on-call/integration/alert-integration/alert-sources/sematext.mdx b/en/on-call/integration/alert-integration/alert-sources/sematext.mdx
index fc3fae09..504426bc 100644
--- a/en/on-call/integration/alert-integration/alert-sources/sematext.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/sematext.mdx
@@ -1,5 +1,6 @@
---
title: "Sematext alert integration"
+sidebarTitle: "Sematext"
description: "Send metric, log, Heartbeat, Experience and Synthetics alerts from Sematext Cloud to Flashduty On-call through a Custom notification hook."
keywords: ["alert integration", "Sematext", "webhook", "Notification Hook", "monitoring"]
---
@@ -9,7 +10,6 @@ Use a Custom notification hook in Sematext Cloud to send alert rule notification
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Sematext
----
<Steps>
<Step title="Create a Custom notification hook">
@@ -42,29 +41,29 @@ You can obtain an integration push URL in either of the following ways.
5. Set **Send data as** to **Json** and **HTTP method** to **Post**
6. Click **Add parameter** and add each parameter in the table below. The left column is the parameter name and the right column is its value; Sematext replaces the `$` variables when it sends the notification
-| Parameter name | Value |
-| :--- | :--- |
-| `backToNormal` | `$backToNormal` |
-| `priority` | `$priority` |
-| `ruleType` | `$ruleType` |
-| `description` | `$description` |
-| `applicationId` | `$applicationId` |
-| `createTimestamp` | `$createTimestamp` |
-| `troubleshootUrl` | `$troubleshootUrl` |
-
-When you are done, the request body in **Preview** should be:
-
-```json
-{
- "backToNormal": "$backToNormal",
- "priority": "$priority",
- "ruleType": "$ruleType",
- "description": "$description",
- "applicationId": "$applicationId",
- "createTimestamp": "$createTimestamp",
- "troubleshootUrl": "$troubleshootUrl"
-}
-```
+ | Parameter name | Value |
+ | :--- | :--- |
+ | `backToNormal` | `$backToNormal` |
+ | `priority` | `$priority` |
+ | `ruleType` | `$ruleType` |
+ | `description` | `$description` |
+ | `applicationId` | `$applicationId` |
+ | `createTimestamp` | `$createTimestamp` |
+ | `troubleshootUrl` | `$troubleshootUrl` |
+
+ When you are done, the request body in **Preview** should be:
+
+ ```json
+ {
+ "backToNormal": "$backToNormal",
+ "priority": "$priority",
+ "ruleType": "$ruleType",
+ "description": "$description",
+ "applicationId": "$applicationId",
+ "createTimestamp": "$createTimestamp",
+ "troubleshootUrl": "$troubleshootUrl"
+ }
+ ```
7. Click **Send Test Notification** and confirm that the request succeeds, then click **Save Notification Hook**
@@ -101,7 +100,6 @@ The request sent by **Send Test Notification** does not belong to any alert rule
</Note>
## Alert Key
----
Sematext adds the alert rule ID (`ruleId`) and rule name (`alertName`) to every alert notification. When the rule uses Group by, it also adds the group tag values that fired the alert (`filters`, for example `{os.host=web-01}`). You do not need to configure these fields in the hook.
@@ -114,7 +112,6 @@ The Alert Key is computed from `ruleId` and all group tags in `filters`; the ord
Requests that carry `alertName` but no `ruleId` are rejected.
## Status and severity
----
The alert recovers when `backToNormal` is `true`; any other value is treated as a trigger. The severity comes from the alert rule priority (`$priority`):
@@ -129,7 +126,6 @@ The alert recovers when `backToNormal` is `true`; any other value is treated as
Matching ignores case.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -144,7 +140,6 @@ Matching ignores case.
| `create_timestamp` | Creation time of the alert notification, as a Unix timestamp in milliseconds |
## Troubleshooting
----
- **Flashduty returns a parameter error**: Make sure the URL is complete and includes `integration_key`, and that **Send data as** is set to **Json**
- **The alert does not recover**: Make sure **Alert me when the value goes back to non-alert level** is on in the rule's **Notifications** tab, that the hook has the `backToNormal` parameter with the value `$backToNormal`, and that the group is still sending data
diff --git a/en/on-call/integration/alert-integration/alert-sources/semgrep.mdx b/en/on-call/integration/alert-integration/alert-sources/semgrep.mdx
index b17b8219..fb176566 100644
--- a/en/on-call/integration/alert-integration/alert-sources/semgrep.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/semgrep.mdx
@@ -1,5 +1,6 @@
---
title: "Semgrep alert integration"
+sidebarTitle: "Semgrep"
description: "Send new Semgrep AppSec Platform findings and supply chain incidents to Flashduty On-call through a webhook."
keywords: ["alert integration", "Semgrep", "webhook", "SAST", "SCA", "code security", "supply chain security"]
---
@@ -9,7 +10,6 @@ Use the Semgrep AppSec Platform webhook integration to send newly detected code
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of two ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of two ways.
</div>
## In Semgrep
----
You need admin access to Semgrep AppSec Platform.
@@ -62,7 +61,6 @@ To receive supply chain incidents, turn on the **Early notification for Supply C
</Steps>
## Payloads and recovery
----
Semgrep sends three kinds of objects, and one request can carry several:
@@ -75,7 +73,6 @@ Semgrep sends three kinds of objects, and one request can carry several:
Semgrep sends a finding only the first time it is detected and never sends update or fixed notifications, so Flashduty alerts do not recover automatically. Turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit) (7 days suggested), or close alerts by hand after the issue is fixed.
## Alert Key
----
| Object | Field used |
| :--- | :--- |
@@ -85,7 +82,6 @@ Semgrep sends a finding only the first time it is detected and never sends updat
The Alert Key is computed from the object type and the ID above, so a repeated delivery of the same finding merges, and a finding ID never merges with an incident ID that has the same number. Changes to the rule name or severity do not change the Alert Key. An object without its ID causes the whole request to be rejected.
## Severity
----
A finding's `severity` is a number derived from the rule severity:
@@ -101,7 +97,6 @@ A finding's `severity` is a number derived from the rule severity:
Supply chain incidents that affect your projects are always Critical.
## Labels
----
Findings:
@@ -128,7 +123,6 @@ Supply chain incidents:
Every alert carries `source=semgrep` and `event_type` (`finding` or `supply_chain_incident`). The alert description is the rule's `message`; code snippets are not sent.
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: check that the webhook URL is complete and includes `integration_key`; the error is also returned when a finding lacks `numeric_id` or an incident lacks `incident_id`
- **No alerts arrive**: check that the policy has a **Call a webhook** action; Semgrep notifies only the first time a finding is detected, so existing findings are not re-sent
diff --git a/en/on-call/integration/alert-integration/alert-sources/sensu.mdx b/en/on-call/integration/alert-integration/alert-sources/sensu.mdx
index 770d4364..26c020e9 100644
--- a/en/on-call/integration/alert-integration/alert-sources/sensu.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/sensu.mdx
@@ -1,5 +1,6 @@
---
title: "Sensu Go alert integration"
+sidebarTitle: "Sensu Go"
description: "Send Sensu Go check events to Flashduty On-call through a pipe handler. Alerts close automatically when the check recovers."
keywords: ["alert integration", "Sensu", "Sensu Go", "pipe handler", "handler", "pipeline"]
---
@@ -9,7 +10,6 @@ Sensu Go has no built-in HTTP handler. This integration uses a pipe handler: the
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Sensu Go
----
The steps below are based on Sensu Go 6.x and use `sensuctl`. You need permission to create handlers and pipelines and to edit checks in the target namespace.
@@ -144,7 +143,6 @@ You can also create events by hand for a proxy entity through the Sensu events A
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from the entity's namespace `entity.metadata.namespace`, the entity name `entity.metadata.name`, and the check name `check.metadata.name`. Trigger, repeat, and resolution events for the same check on the same entity carry the same three fields, so they land on the same alert. Events from proxy checks (`proxy_entity_name`) use the proxy entity as their entity, so each proxy entity gets its own alert.
@@ -153,7 +151,6 @@ Changes to the status, check output, `occurrences`, time, event ID, or silenced
Flashduty rejects a request that lacks `entity` or `check` (for example a metrics-only event), or lacks the namespace, entity name, check name, or `check.status`. `curl` then exits with a non-zero code, and the Sensu backend log records the handler failure.
## Alert lifecycle
----
| Sensu event | Flashduty action |
| :--- | :--- |
@@ -164,7 +161,6 @@ Flashduty rejects a request that lacks `entity` or `check` (for example a metric
With the `is_incident` filter, every execution of a check that stays non-zero is posted once, and these events merge into the same alert.
## Severity
----
| `check.status` | Sensu meaning | Flashduty severity |
| :--- | :--- | :--- |
@@ -176,7 +172,6 @@ With the `is_incident` filter, every execution of a check that stays non-zero is
A resolution event takes the severity of the most recent non-zero status in `check.history`.
## Alert content
----
- **Title**: `<entity name>: <check name>`
- **Description**: the check output `check.output`, followed by the namespace, status code, `check.state`, and `occurrences`
@@ -185,7 +180,6 @@ A resolution event takes the severity of the most recent non-zero status in `che
The check command, secrets, and the entity's `redact` field are not written to labels.
## Troubleshooting
----
- **Flashduty receives no alert**: search the backend log for runs of the `flashduty` handler (`journalctl -u sensu-backend`), make sure the check's `pipelines` include `flashduty`, and make sure the event status is non-zero
- **The handler reports `curl: not found`**: `curl` is not installed on the backend machine or container
diff --git a/en/on-call/integration/alert-integration/alert-sources/sentry.mdx b/en/on-call/integration/alert-integration/alert-sources/sentry.mdx
index af5811ea..0f5e3ab2 100644
--- a/en/on-call/integration/alert-integration/alert-sources/sentry.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/sentry.mdx
@@ -1,5 +1,6 @@
---
title: "Sentry Alert Events"
+sidebarTitle: "Sentry"
description: "Sync Sentry alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,60 +9,60 @@ Sync Sentry alert events to Flashduty via webhook for automated alert noise redu
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Select **Sentry** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Sentry** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Sentry
----
<div class="md-block">
-## I. Prerequisites
+### Prerequisites
Sentry provides two types of alert mechanisms: Issue Alerts and Metric Alerts. While Issue Alerts support notifications through WebHooks in Integrations, Metric Alerts are limited to using Internal Integration for alert notifications. Notably, Internal Integration works with both Metric Alerts and Issue Alerts. Given the versatility of Internal Integration, we've chosen to standardize on this approach rather than relying on WebHooks separately, thus simplifying alert notification configuration.
-## II. Sentry Alert Push Configuration
+### Sentry Alert Push Configuration
-### Step 1: Add Flashduty Custom Integrations
+#### Step 1: Add Flashduty Custom Integrations
1. Log in to the Sentry management console
-2. In the left navigation bar, locate **Settings => Custom Integrations**
+2. In the left navigation bar, locate **Settings → Custom Integrations**
3. Click Create New Integration and select **Internal Integration**
4. On the editing page, **enter Flashduty for Name and paste the integration push URL into WebhookURL**
5. Enable **Alert Rule Action**, configure as shown below:
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-1.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-1.png" />
-5. In PERMISSIONS configuration, set **Read permission for Issue & Event**
+ 5. In PERMISSIONS configuration, set **Read permission for Issue & Event**
6. In WEBHOOKS configuration, check **issue**, **do not check error and comment**
7. After configuration, click Save Changes to complete the setup
@@ -72,27 +73,27 @@ Sentry provides two types of alert mechanisms: Issue Alerts and Metric Alerts. W
2. Other issue events such as create, assigned, archived, and unresolved are not supported
3. If error and comment are also checked, Flashduty will not receive or process these types of events
-### Step 2: Use Flashduty Integration in Alerts
-1. In the left navigation bar, locate **Alerts => Create Alert**
+#### Step 2: Use Flashduty Integration in Alerts
+1. In the left navigation bar, locate **Alerts → Create Alert**
2. Select the type of Alert to create, such as Issue
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-3.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-3.png" />
3. Configure trigger conditions as needed
4. Under **THEN perform these actions**, **Add action** and select **Send a notification via**
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-4.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-4.png" />
5. Select **Flashduty** added above as the notification channel
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-5.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-5.png" />
6. Configure other options as needed and click **Save Rule** to complete
</div>
-## III. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/sevone.mdx b/en/on-call/integration/alert-integration/alert-sources/sevone.mdx
index 9e731c33..4014ecdc 100644
--- a/en/on-call/integration/alert-integration/alert-sources/sevone.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/sevone.mdx
@@ -1,5 +1,6 @@
---
title: "IBM SevOne NPM alert integration"
+sidebarTitle: "IBM SevOne NPM"
description: "Send IBM SevOne NPM policy alert triggers and clears to Flashduty On-call through a Webhook Definition."
keywords: ["alert integration", "IBM SevOne", "SevOne NPM", "Webhook Definition", "Policy", "alertId"]
---
@@ -9,7 +10,6 @@ Use IBM SevOne NPM 8.x Webhook Definition Manager to send policy alert triggers
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure SevOne NPM
----
Create two Webhook Definitions: one sent when an alert triggers, one sent when it clears.
@@ -43,9 +42,9 @@ Create two Webhook Definitions: one sent when an alert triggers, one sent when i
4. Set **Request Method** to **POST** and **Content Type** to **application/json**
5. Paste this template into **Body**:
-```json
-{"event":"trigger","alert_id":"$alertId","severity":"$alertState","message":"$alertMessage","alert_type":"$alertType","occurrences":"$occurrences","device_id":"$deviceId","device_name":"$deviceName","device_ip":"$deviceIp","device_group":"$groupName","policy_id":"$policyId","policy_name":"$policyName","threshold_name":"$thresholdName","object_name":"$objectName","plugin":"$pluginName","cluster":"$clusterName"}
-```
+ ```json
+ {"event":"trigger","alert_id":"$alertId","severity":"$alertState","message":"$alertMessage","alert_type":"$alertType","occurrences":"$occurrences","device_id":"$deviceId","device_name":"$deviceName","device_ip":"$deviceIp","device_group":"$groupName","policy_id":"$policyId","policy_name":"$policyName","threshold_name":"$thresholdName","object_name":"$objectName","plugin":"$pluginName","cluster":"$clusterName"}
+ ```
6. Click **Test Definition** to check that the request can be sent, then click **Save**
@@ -83,7 +82,6 @@ Let a policy trigger and confirm Flashduty shows an active alert. Then let it cl
</Warning>
## Payload
----
Each field is the substitution of one SevOne variable (see IBM's [Webhook Definition Manager](https://www.ibm.com/docs/en/SSUWLY_8.0/nms/Webhook_Definition_Manager.html)):
@@ -105,14 +103,12 @@ Each field is the substitution of one SevOne variable (see IBM's [Webhook Defini
SevOne outputs `n/a` for a variable a policy type does not support (for example `$pluginName` on flow policies). Flashduty ignores `n/a`.
## Alert Key
----
Flashduty uses `alert_id` (`$alertId`, described by IBM as "The id of the triggered alert") as the Alert Key. Repeated triggers and the clear of one SevOne alert carry the same `alert_id`, so they land on one Flashduty alert. Changing the policy name, severity or message does not change the Alert Key.
If `alert_id` is empty, `n/a`, or still the unsubstituted `$alertId`, Flashduty returns a parameter error.
## Status and severity
----
`$alertState` is the policy severity. A clear event keeps the alert's severity and sets the status to recovered.
@@ -124,7 +120,6 @@ If `alert_id` is empty, `n/a`, or still the unsubstituted `$alertId`, Flashduty
| Empty or other | Warning |
## FAQ
----
<AccordionGroup>
<Accordion title="Does Test Definition create an alert in Flashduty?">
@@ -153,7 +148,6 @@ The templates on this page are for the Policy type. Trap definitions use a diffe
</AccordionGroup>
## Troubleshooting
----
- **SevOne cannot deliver**: check that Destination URL is the complete push URL; for a self-signed TLS certificate, check **Allow insecure webhook connection**, and use a certificate with a SAN rather than only a Common Name
- **Flashduty returns a parameter error**: check that Content Type is application/json, `event` is `trigger` or `clear`, and `alert_id` has a value
diff --git a/en/on-call/integration/alert-integration/alert-sources/signoz.mdx b/en/on-call/integration/alert-integration/alert-sources/signoz.mdx
index 6f07f504..04be8181 100644
--- a/en/on-call/integration/alert-integration/alert-sources/signoz.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/signoz.mdx
@@ -1,5 +1,6 @@
---
title: "SigNoz Alert Integration"
+sidebarTitle: "SigNoz"
description: "Receive SigNoz alerts through SigNoz's webhook notification channel using a Flashduty Prometheus integration; resolve notifications close the alert automatically."
keywords: ["alert integration", "SigNoz", "webhook", "Prometheus", "Alertmanager", "observability"]
---
@@ -9,7 +10,6 @@ SigNoz's webhook notification channel sends Prometheus Alertmanager JSON (`statu
<div className="hide">
## In Flashduty On-call
----
Get an integration push URL in either of the two ways below. **Choose the Prometheus integration type** in both, not SigNoz.
@@ -30,7 +30,6 @@ Get an integration push URL in either of the two ways below. **Choose the Promet
</div>
## Configure in SigNoz
----
1. In SigNoz, go to **Settings** → **Notification Channels** (also reachable from the **Notification Channels** tab on the **Alerts** page) and click **New Channel**
2. Enter a channel name, select **Webhook** as the type, and enter the full push URL copied above as the endpoint URL, including `?integration_key=...`
@@ -38,7 +37,6 @@ Get an integration push URL in either of the two ways below. **Choose the Promet
4. Save, then select the channel in the threshold row (**send to**) of your SigNoz alert rules
## Field mapping
----
| SigNoz field | Flashduty |
| :--- | :--- |
@@ -53,7 +51,6 @@ Get an integration push URL in either of the two ways below. **Choose the Promet
SigNoz groups notifications by rule (`ruleId`); one notification can carry several alerts, and Flashduty handles each one separately (up to 100 per request). A firing rule normally arrives within a minute.
## Recovery and deduplication
----
- When SigNoz sends a notification with `status` set to `resolved`, Flashduty closes the alert with the same `fingerprint`.
- In current SigNoz rules the `severity` label is taken from the threshold row name (for example a threshold named `critical` or `warning`), which is also written to the `threshold.name` label. If you use a value that is not built in, such as `error`, configure a custom severity mapping on the Prometheus integration; otherwise it is treated as Warning.
@@ -61,7 +58,6 @@ SigNoz groups notifications by rule (`ruleId`); one notification can carry sever
- The channel's **Test** button sends a `firing` test alert titled `Test Alert (<channel name>)` with `severity` `critical`. It opens a Critical alert in Flashduty and is never followed by a resolved notification, so close that alert manually.
## Troubleshooting
----
- **Flashduty returns `Invalid parameters`**: the push URL is incomplete and lacks `integration_key`, or the integration type is not Prometheus
- **Alerts do not recover**: confirm **Send resolved alerts** is on for the SigNoz channel and that the resolved notification's `fingerprint` matches the trigger
diff --git a/en/on-call/integration/alert-integration/alert-sources/simple-observability.mdx b/en/on-call/integration/alert-integration/alert-sources/simple-observability.mdx
index ce732109..6584fb9b 100644
--- a/en/on-call/integration/alert-integration/alert-sources/simple-observability.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/simple-observability.mdx
@@ -1,5 +1,6 @@
---
title: "Simple Observability alert integration"
+sidebarTitle: "Simple Observability"
description: "Send Simple Observability rule, server, job, and endpoint alerts and their recoveries to Flashduty On-call through a webhook channel."
keywords: ["alert integration", "Simple Observability", "webhook", "server monitoring", "endpoint monitoring", "cron job monitoring"]
---
@@ -9,7 +10,6 @@ Use a Simple Observability webhook channel to send alerts and recoveries for ale
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Simple Observability
----
<Steps>
<Step title="Add a webhook channel">
@@ -61,7 +60,6 @@ Simple Observability requires your endpoint to return a 2xx status code; otherwi
</Warning>
## Payload
----
The webhook POSTs JSON, which Flashduty parses directly without a template. `event_type` decides which kind of object the alert is about:
@@ -88,7 +86,6 @@ How the other fields appear in Flashduty:
| Job `server`, `schedule` | Labels `job_server`, `job_schedule` |
## Alert Key
----
Flashduty uses the object type plus the object ID as the Alert Key, for example `endpoint:<data.endpoint.id>`. The trigger and recovery notifications for one rule, server, endpoint, or job land on the same alert. Different objects produce different alerts, and objects of different types never affect each other even if their IDs match. Changing the name, severity, description, or time does not change the Alert Key.
@@ -99,7 +96,6 @@ The Simple Observability documentation shows only the trigger example for each t
</Note>
## Status and severity
----
| Simple Observability `severity` | Flashduty severity |
| :--- | :--- |
@@ -111,7 +107,6 @@ The Simple Observability documentation shows only the trigger example for each t
Rule and job alerts carry a null `severity`, so they are treated as Warning. A recovery notification (`RESOLVED`, `SERVER_UP`, `ENDPOINT_UP`, `SUCCESS`) closes the alert with the same Alert Key.
## FAQ
----
<AccordionGroup>
<Accordion title="Is a notification sent for every successful job run?">
@@ -134,7 +129,6 @@ A rule alert produces one Flashduty alert per rule ID. The matching hosts and va
</AccordionGroup>
## Troubleshooting
----
- **Simple Observability reports an error**: confirm the webhook URL is the full push URL and includes `integration_key`
- **Flashduty returns a parameter error**: the message names the missing object ID or the unsupported `event_type` or `status`
diff --git a/en/on-call/integration/alert-integration/alert-sources/site24x7.mdx b/en/on-call/integration/alert-integration/alert-sources/site24x7.mdx
index 25c1f09b..37ae5a51 100644
--- a/en/on-call/integration/alert-integration/alert-sources/site24x7.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/site24x7.mdx
@@ -1,5 +1,6 @@
---
title: "Site24x7 alert integration"
+sidebarTitle: "Site24x7"
description: "Send Site24x7 monitor status changes to Flashduty On-call through a webhook. Alerts recover automatically when the monitor returns to Up."
keywords: ["alert integration", "Site24x7", "webhook", "Incident Parameters", "MONITOR_ID"]
---
@@ -9,7 +10,6 @@ Use the Site24x7 Webhooks third-party integration to send monitor status changes
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Site24x7
----
<Steps>
<Step title="Add a Webhooks integration">
@@ -76,14 +75,12 @@ The test alert is a `DOWN` notification for a fixed sample monitor (`MONITOR_ID`
</Steps>
## Alert Key
----
Flashduty uses the Site24x7 monitor ID as the Alert Key. It takes `MONITOR_ID` first and, when that is missing, extracts the ID from `MONITOR_DASHBOARD_LINK` (for example `.../home/monitors/<monitor ID>/Summary`). The Down, Trouble, Critical, and Up notifications of one monitor all carry the same monitor ID, so they are grouped into the same alert and the Up notification recovers it.
Changes to `STATUS`, the monitor name, the incident reason, the failed locations, or the time do not change the Alert Key.
## Status and severity mapping
----
| Site24x7 `STATUS` | Flashduty status or severity |
| :--- | :--- |
@@ -96,7 +93,6 @@ Changes to `STATUS`, the monitor name, the incident reason, the failed locations
Requests with an empty `STATUS` are rejected.
## Alert labels
----
Flashduty writes the following incident parameters to alert labels for filtering and troubleshooting:
@@ -118,7 +114,6 @@ Flashduty writes the following incident parameters to alert labels for filtering
The alert title comes from `MONITORNAME` and the alert description from `INCIDENT_REASON`.
## Troubleshooting
----
- **Site24x7 reports an integration failure**: Make sure the Hook URL is complete, includes `integration_key`, and uses POST
- **Flashduty returns a parameter error**: Make sure **Post as JSON** and **Send Incident Parameters** are both selected and the request body contains `MONITOR_ID` and `STATUS`
diff --git a/en/on-call/integration/alert-integration/alert-sources/skywalking.mdx b/en/on-call/integration/alert-integration/alert-sources/skywalking.mdx
index b95b504c..c352d9fb 100644
--- a/en/on-call/integration/alert-integration/alert-sources/skywalking.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/skywalking.mdx
@@ -1,5 +1,6 @@
---
title: "Skywalking Alert Events"
+sidebarTitle: "Skywalking"
description: "Sync Skywalking alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,45 +9,45 @@ Sync Skywalking alert events to Flashduty via webhook for automated alert noise
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels. It's simpler and recommended.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Skywalking** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Skywalking** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Skywalking
----
<div class="md-block">
-## I. Modify Skywalking Service Configuration File
+### Modify Skywalking Service Configuration File
1. Log in to the Skywalking server
2. Locate the Skywalking configuration file ./config/alarm-settings.yml
@@ -85,7 +86,7 @@ hooks:
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/snyk.mdx b/en/on-call/integration/alert-integration/alert-sources/snyk.mdx
index e2243cba..b60c399c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/snyk.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/snyk.mdx
@@ -1,5 +1,6 @@
---
title: "Snyk alert integration"
+sidebarTitle: "Snyk"
description: "Send Snyk open source and container issues, new and removed, to Flashduty On-call through a Snyk webhook."
keywords: ["alert integration", "Snyk", "webhook", "vulnerability", "security alerts", "SCA"]
---
@@ -11,7 +12,6 @@ Snyk webhooks currently cover Open Source and Container scans. The Webhooks API
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Snyk
----
Snyk webhooks can only be created through the API; the Snyk web console has no entry for them.
@@ -81,19 +80,16 @@ Wait for (or trigger) a project retest and confirm that a new issue opens an ale
</Steps>
## About the signature
----
Snyk signs each request in the `X-Hub-Signature` header (`sha256=<hex HMAC digest>`, keyed with the `secret` you set when creating the webhook). Flashduty does not verify it, so `secret` can be any random string. The `integration_key` in the push URL is the only credential; keep it private.
## Alert Key
----
Flashduty builds the Alert Key from the **project ID (`project.id`) plus the issue ID (`id`)**: one alert per issue per project. Issues in `newIssues` and `removedIssues` share the same shape and `id`, so an issue appearing and disappearing land on the same alert.
Changes to the project name, branch, or severity do not change the Alert Key. An issue that repeats for several dependency paths of one project produces a single alert. The same issue in two projects is two alerts.
## Status and severity
----
| Source | Flashduty behavior |
| :--- | :--- |
@@ -117,7 +113,6 @@ One request processes at most the first 100 issues of `newIssues` and of `remove
Alert labels include the project ID and name, project type, branch, organization, issue ID, package name and versions, CVE, CWE, CVSS score, and the fixed-in version. The importing user's name and email are not written to the alert.
## Troubleshooting
----
- **The create call returns an error**: check that `url` is HTTPS, the token has access to the organization, the organization is in a region where Snyk webhooks are available, and the plan includes API access (the Free plan returns `not entitled for api access`)
- **No alerts arrive**: Snyk sends an event only when a project is retested and it is not sent when a project is first imported. Make sure the project's scan type is Open Source or Container
diff --git a/en/on-call/integration/alert-integration/alert-sources/solarwinds-orion.mdx b/en/on-call/integration/alert-integration/alert-sources/solarwinds-orion.mdx
index 76c4230c..4280b9c1 100644
--- a/en/on-call/integration/alert-integration/alert-sources/solarwinds-orion.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/solarwinds-orion.mdx
@@ -1,5 +1,6 @@
---
title: "SolarWinds Platform (Orion) alert integration"
+sidebarTitle: "SolarWinds Platform (Orion)"
description: "Send SolarWinds Platform (Orion) alerts to Flashduty On-call through the alert's HTTP request actions. Alerts close automatically when they reset in SolarWinds."
keywords: ["alert integration", "SolarWinds", "Orion", "SolarWinds Platform", "NPM", "SAM", "network monitoring"]
---
@@ -11,7 +12,6 @@ SolarWinds Platform (formerly Orion Platform, self-hosted, including products su
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure SolarWinds Platform
----
The steps below need a SolarWinds Platform account with **Allow Alert Management Rights**. The SolarWinds server must be able to reach the domain of the Flashduty push URL over HTTPS (port 443).
@@ -118,7 +117,6 @@ You can also let the alert trigger for real (for example by lowering a threshold
</Steps>
## Alert Key
----
Flashduty uses `alert_object_id` (`${N=Alerting;M=AlertObjectID}`) as the Alert Key. SolarWinds assigns one fixed AlertObjectID to each alert definition and triggered object pair (for example "Node is down" on one switch). The trigger, repeated notifications, and the reset on that object all carry the same ID, so they land on one Flashduty alert; if the alert triggers again after a reset, a new Flashduty alert opens. When the same alert definition triggers on different objects, each object has its own AlertObjectID and gets its own alert.
@@ -127,7 +125,6 @@ Changes to the alert name, severity, object name, or alert message do not change
Flashduty rejects a request that is missing `action` or `alert_object_id`, or whose `alert_object_id` is still the unrendered `${N=Alerting;M=AlertObjectID}`.
## Alert lifecycle
----
Flashduty handles each notification by its `action` field (case-insensitive):
@@ -139,7 +136,6 @@ Flashduty handles each notification by its `action` field (case-insensitive):
Acknowledging an alert in SolarWinds does not run any action, so the Flashduty alert does not change.
## Severity
----
The severity comes from the alert definition's **Severity of Alert** (`${N=Alerting;M=Severity}`), case-insensitive:
@@ -155,7 +151,6 @@ The severity comes from the alert definition's **Severity of Alert** (`${N=Alert
The reset notification carries the alert definition's severity, and the recovery event keeps it.
## Alert content
----
- **Title**: `<alert name> on <object name>`. Without an object name, only the alert name is used; if both are missing, the title is `SolarWinds alert <alert_object_id>`
- **Description**: the alert message rendered from `${N=Alerting;M=AlertMessage}`, that is, the **Message displayed when this alert is triggered** in the alert's **Trigger Actions**
@@ -164,7 +159,6 @@ The reset notification carries the alert definition's severity, and the recovery
SolarWinds does not JSON-escape variable values. When an object name, alert message, or other value contains a double quote, a backslash, or a line break, Flashduty still reads it as-is from the template fields. Empty fields are not written as labels. When a variable does not apply to the object type, SolarWinds may leave the `${...}` variable as-is, and Flashduty treats it as empty.
## Troubleshooting
----
- **Simulate reports "Failed to execute HTTP request"**: make sure **URL** is the full push URL including the `integration_key` parameter, and that the SolarWinds server can reach it (proxy, firewall)
- **Flashduty reports that the body is not valid JSON**: the body is not the template on this page. Make sure the template was pasted completely, with the braces, each field's `"field_name": "`, and the closing `"` of each value in place
diff --git a/en/on-call/integration/alert-integration/alert-sources/solarwinds.mdx b/en/on-call/integration/alert-integration/alert-sources/solarwinds.mdx
index fc9de117..eacaab2a 100644
--- a/en/on-call/integration/alert-integration/alert-sources/solarwinds.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/solarwinds.mdx
@@ -1,5 +1,6 @@
---
title: "SolarWinds Alert Events"
+sidebarTitle: "SolarWinds"
description: "Sync SolarWinds alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,46 +9,45 @@ Sync SolarWinds alert events to Flashduty via webhook for automated alert noise
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **SolarWinds** integration, click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event payload.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **SolarWinds** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In SolarWinds
----
<div class="md-block">
-## I. SolarWinds Alert Push Configuration
### Step 1: Configure Flashduty Alert Channel
@@ -60,7 +60,7 @@ Choose this option when you need to route alerts to different channels based on
1. Log in to your SolarWinds console
2. Find `Settings` in the left navigation bar, select `Notification Services` and click `Webhook` to enter the new alert channel page
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/sw-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/sw-1.png" />
3. Click `CREATE CONFIGURATION` to create the corresponding alert channel
4. Select **POST** for `Method`, name it according to the prerequisites, e.g., Anomaly_Flashduty
@@ -70,7 +70,7 @@ Choose this option when you need to route alerts to different channels based on
8. Leave `HTTP POST Body` unchanged, use the system-generated default
9. Click `CREATE` to save after configuration
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/sw-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/sw-2.png" />
10. Repeat the above steps to create other types of Webhook channels as needed
@@ -82,13 +82,13 @@ Choose this option when you need to route alerts to different channels based on
4. Select the Anomaly_Flashduty channel created in Step 1 for `Configuration`
5. Keep `Send an additional notification when the Alert is cleared` enabled
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/sw-4.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/sw-4.png" />
6. Click `Save` after completing other configurations
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/sonarqube.mdx b/en/on-call/integration/alert-integration/alert-sources/sonarqube.mdx
index 04f9a71d..c278e296 100644
--- a/en/on-call/integration/alert-integration/alert-sources/sonarqube.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/sonarqube.mdx
@@ -1,5 +1,6 @@
---
title: "SonarQube alert integration"
+sidebarTitle: "SonarQube"
description: "Send SonarQube Server and SonarQube Cloud quality gate results to Flashduty On-call through a webhook."
keywords: ["alert integration", "SonarQube", "SonarQube Cloud", "webhook", "quality gate", "code quality"]
---
@@ -9,7 +10,6 @@ Use a SonarQube webhook to send the quality gate result of every code analysis t
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the push URL in either of the following ways.
</div>
## In SonarQube
----
<Steps>
<Step title="Create the webhook">
@@ -63,7 +62,6 @@ SonarQube has no test button for webhooks. On SonarQube Server, the **Last deliv
</Steps>
## Alert Key
----
The Alert Key is computed from the project key (`project.key`), the branch type (`branch.type`, such as `BRANCH` or `PULL_REQUEST`), and the branch name (`branch.name`). As a result:
@@ -75,7 +73,6 @@ The Alert Key is computed from the project key (`project.key`), the branch type
A request without `project.key` is rejected.
## Status and severity
----
SonarQube webhooks carry no severity, and a failed quality gate is a code quality signal rather than an outage, so every alert is Warning. Adjust it with routing or alert management in Flashduty if needed.
@@ -90,7 +87,6 @@ These deliveries are ignored, and Flashduty returns success: failed or cancelled
Every passing analysis sends an `OK`; it is used only to recover the active alert of the same project and branch.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -105,7 +101,6 @@ Every passing analysis sends an `OK`; it is used only to recover the active aler
The alert description lists each failed condition with its metric, current value, and threshold.
## Troubleshooting
----
- **Flashduty returns an invalid parameter error**: check that the URL is complete and includes `integration_key`
- **No alert arrives**: confirm the analysis produced a quality gate result. On SonarQube Server, check the status code under **Last delivery** on the Webhooks page; SonarQube Cloud needs a paid plan
diff --git a/en/on-call/integration/alert-integration/alert-sources/split-io.mdx b/en/on-call/integration/alert-integration/alert-sources/split-io.mdx
index 2a660134..9bcf11dc 100644
--- a/en/on-call/integration/alert-integration/alert-sources/split-io.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/split-io.mdx
@@ -1,5 +1,6 @@
---
title: "Split alert integration"
+sidebarTitle: "Split"
description: "Sync Split (Harness FME) metric degradation alerts to Flashduty On-call through the Metric Alert webhook."
keywords: ["alert integration", "Split", "Harness FME", "feature flags", "metric alerts", "webhook"]
---
@@ -9,7 +10,6 @@ Split is now part of Harness, under the name Harness Feature Management & Experi
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Harness FME
----
<Steps>
<Step title="Check permissions">
@@ -70,7 +69,6 @@ FME sends a delivery only when an alert fires. Nothing is sent when the alert is
</Steps>
## Payload
----
Each FME delivery is one JSON object whose `type` is `METRIC_ALERT`. Flashduty uses these fields:
@@ -93,7 +91,6 @@ Each FME delivery is one JSON object whose `type` is `METRIC_ALERT`. Flashduty u
The alert title is `<feature flag or experiment name> degraded <metric name> in <environment name>`. Every alert also carries the label `source=split-io`.
## Alert Key
----
Flashduty builds the Alert Key from the feature flag or experiment ID, the environment ID and the metric ID:
@@ -105,7 +102,6 @@ Flashduty builds the Alert Key from the feature flag or experiment ID, the envir
Renaming the feature flag, metric, environment or alert policy does not change the Alert Key.
## Severity
----
| `data.alertType` | Flashduty severity |
| :--- | :--- |
@@ -121,7 +117,6 @@ These deliveries return success and create no alert:
A `METRIC_ALERT` delivery without `source.id`, `data.environment.id` or `data.metric.id` is rejected.
## FAQ
----
<AccordionGroup>
<Accordion title="Why did the Flashduty alert not close after the FME alert auto-resolved?">
@@ -144,7 +139,6 @@ FME can also email alerts to any address. The webhook sends structured fields, w
</AccordionGroup>
## Troubleshooting
----
- **Flashduty returns a parameter error**: make sure the push URL is complete (including `integration_key`)
- **FME shows an alert but Flashduty does not**: make sure the webhook includes that environment and that alert type; improvements (`DESIRED`) create no alert
diff --git a/en/on-call/integration/alert-integration/alert-sources/splunk-observability.mdx b/en/on-call/integration/alert-integration/alert-sources/splunk-observability.mdx
index 55f83f89..33bdef00 100644
--- a/en/on-call/integration/alert-integration/alert-sources/splunk-observability.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/splunk-observability.mdx
@@ -1,5 +1,6 @@
---
title: "Splunk Observability Cloud alert integration"
+sidebarTitle: "Splunk Observability Cloud"
description: "Send Splunk Observability Cloud (formerly SignalFx) detector alerts to Flashduty On-call through a webhook."
keywords: ["alert integration", "Splunk Observability Cloud", "SignalFx", "detector", "webhook"]
---
@@ -13,7 +14,6 @@ This integration receives detector alerts from Splunk Observability Cloud (forme
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -34,7 +34,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Splunk Observability Cloud
----
<Steps>
<Step title="Create a Webhook integration">
@@ -79,14 +78,12 @@ If you change the template on the **Customize message** page, keep the `incident
</Warning>
## Alert Key
----
Flashduty uses `incidentId` as the Alert Key. Splunk documents that the trigger and clear notifications of one alert carry the same `incidentId`, so both land on the same Flashduty alert.
Changes to the rule name, severity, status, timestamps, message text, or dimension values do not change the Alert Key.
## Status and severity
----
Flashduty reads `statusExtended`, and `status` when `statusExtended` is empty:
@@ -115,7 +112,6 @@ Severity comes from the rule's `severity`:
A recovery keeps the alert's original severity.
## Alert content
----
- **Title**: the rule name `rule`, or the detector name `detector` when `rule` is empty
- **Description**: `messageBody`, or `description` when `messageBody` is empty
@@ -127,7 +123,6 @@ A recovery keeps the alert's original severity.
`orgId`, `imageUrl`, and `inputs` are not written to labels.
## Troubleshooting
----
- **Splunk reports a failed notification**: confirm that the URL is the complete push URL and includes `integration_key`. Splunk retries a notification that does not get a `200` response for up to 24 hours
- **Flashduty returns a parameter error**: confirm that the template still contains `incidentId` and `statusExtended`
diff --git a/en/on-call/integration/alert-integration/alert-sources/splunk.mdx b/en/on-call/integration/alert-integration/alert-sources/splunk.mdx
index 70bc3c20..046df50f 100644
--- a/en/on-call/integration/alert-integration/alert-sources/splunk.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/splunk.mdx
@@ -1,5 +1,6 @@
---
title: "Splunk Alert Events"
+sidebarTitle: "Splunk"
description: "Sync Splunk alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,57 +9,56 @@ Sync Splunk alert events to Flashduty via webhook for automated alert noise redu
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels. It's simpler and recommended.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Splunk** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're Done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Splunk** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Splunk
----
<div class="md-block">
-## I. Splunk Alert Push Configuration
1. Log in to your Splunk console
2. In the `Search and Report` application, search for keywords you want to monitor, such as "error"
3. In the upper right corner's save menu, select `Alerts` to configure the search keywords as monitoring items
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/splunk-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/splunk-1.png" />
4. In the configuration popup, enter relevant information. Configure the `set up` and `Triggering conditions` sections according to your needs
5. In the `Trigger Action` section, click `Add Action` and select `Webhook`
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/splunk-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/splunk-2.png" />
6. In the `Webhook` section, enter the integration push URL in the `URL` field (the URL will be generated after saving the integration name on the current page) and save to complete the alert configuration
@@ -66,7 +66,7 @@ Choose this method when you need to route alerts to different channels based on
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
Since Splunk alert events don't differentiate severity levels, all alert events pushed from Splunk to Flashduty will have a Warning status and won't include recovery events.
diff --git a/en/on-call/integration/alert-integration/alert-sources/stackrox.mdx b/en/on-call/integration/alert-integration/alert-sources/stackrox.mdx
index a2750295..3f4e059c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/stackrox.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/stackrox.mdx
@@ -1,5 +1,6 @@
---
title: "StackRox Alert Integration"
+sidebarTitle: "StackRox"
description: "Send StackRox (Red Hat Advanced Cluster Security for Kubernetes) policy violation alerts to Flashduty On-call through a Generic Webhook."
keywords: ["alert integration", "StackRox", "Red Hat ACS", "RHACS", "Kubernetes", "container security", "webhook"]
---
@@ -9,7 +10,6 @@ Send policy violation alerts from StackRox (Red Hat Advanced Cluster Security fo
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure StackRox
----
You need permission in RHACS to create notifier integrations and edit policies. Central must be able to reach the Flashduty push URL over HTTPS.
@@ -71,14 +70,12 @@ The **Test** button on the Generic Webhook integration sends a test alert with I
</Steps>
## Alert Key
----
Flashduty uses the StackRox alert ID (`alert.id` in the request body) as the Alert Key. The StackRox documentation states that each alert is sent once: a new notification is sent when a violation first occurs in a deployment, or when it occurs again after a previous runtime alert for that policy in that deployment was resolved. Every notification is therefore a separate alert with its own Alert Key. If StackRox sends the same alert again, the deliveries merge into one Flashduty alert.
Changes to the policy name, severity, violation details, or time do not change the Alert Key. Requests without `alert.id` are rejected.
## Status and severity
----
Flashduty maps the policy severity (`alert.policy.severity`) to the alert severity:
@@ -93,7 +90,6 @@ Flashduty maps the policy severity (`alert.policy.severity`) to the alert severi
To page on `HIGH_SEVERITY` policies as Critical, adjust the severity in Flashduty with a route or alert processing rule that matches the `policy_severity` label.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -110,7 +106,6 @@ To page on `HIGH_SEVERITY` policies as Critical, adjust the severity in Flashdut
Violation details (`alert.violations[].message`) go into the alert description.
## Troubleshooting
----
- **Central reports a delivery failure**: confirm the Endpoint is complete and includes `integration_key`, and that Central's network can reach Flashduty
- **Test succeeds but no alert appears**: Test sends `testalert`, which never creates an alert. Confirm the policy has the notifier enabled and cause a real violation
diff --git a/en/on-call/integration/alert-integration/alert-sources/standard-alert.mdx b/en/on-call/integration/alert-integration/alert-sources/standard-alert.mdx
index 5c1b9b47..594cfaaf 100644
--- a/en/on-call/integration/alert-integration/alert-sources/standard-alert.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/standard-alert.mdx
@@ -1,5 +1,6 @@
---
title: "Standard Alert Event Integration Guide"
+sidebarTitle: "Standard Alert Event"
description: "Push alert events from your own system to Flashduty through standard protocols to achieve automated alert noise reduction."
---
@@ -10,7 +11,6 @@ Flashduty has already adapted webhook protocols for most common alert systems. F
:::
## Steps
----
### In Flashduty
@@ -20,34 +20,35 @@ You can obtain an integration push URL through either of the following two metho
When you don't need to route alert events to different collaboration spaces, this method is preferred as it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Enter the Flashduty console, select **Collaboration Space**, and enter the details page of a space
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration**, and enter the add integration page
3. Select **Standard Alert Event** integration, click **Save** to generate a card
4. Click the generated card to view the **Push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
#### Using Shared Integration
When you need to route alert events to different collaboration spaces based on the alert event's Payload information, this method is preferred.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Enter the Flashduty console, select **Integration Center => Alert Events** to enter the integration selection page
+ 1. Enter the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Standard Alert Event** integration:
- **Integration Name**: Define a name for the current integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
-## I. Request Description
----
+## Request Description
### Request Method
@@ -75,7 +76,7 @@ Field|Required|Type|Description
Field|Required|Type|Description
:-:|:-:|:-:|:---
-| title_rule | Yes | string | Alert title, no more than `512` characters, will be truncated if exceeded. Supports dynamic title generation based on alert content, see [Customizing Incidents](https://docs.flashduty.com/zh/on-call/integration/alert-integration/alert-pipelines) for generation rules.
+| title_rule | Yes | string | Alert title, no more than `512` characters, will be truncated if exceeded. Supports dynamic title generation based on alert content, see [Customizing Incidents](/en/on-call/integration/alert-integration/alert-pipelines) for generation rules.
| event_status | Yes | string | Alert status. Enumerated values (case-sensitive): *Critical*, *Warning*, *Info*, *Ok*. When specified as Ok, it means automatic recovery of the alert.
| alert_key | No | string | Alert identifier, used to update or automatically recover existing alerts. You can customize this value, but it cannot exceed `255` characters. You can also rely on system auto-generation, this value will be returned in the response. If you're reporting a recovery event, this value must exist.
| description | No | string | Alert description, no more than `2048` characters, will be truncated if exceeded.
@@ -131,8 +132,7 @@ Code:
| NoLicense | 400 | Account has insufficient subscription licenses, please upgrade or purchase subscription in the cost center |
| InternalError | 500 | Internal or unknown error |
-### II. Request Example
----
+### Request Example
Request:
@@ -175,8 +175,7 @@ Failed Response:
}
```
-## III. Field Mapping and Value Mapping
----
+## Field Mapping and Value Mapping
If your system's JSON format cannot directly match the standard Payload structure above, you can configure **field mapping (field_mapping)** and **value mapping (value_mapping)** in the integration settings to let Flashduty automatically convert any JSON format into standard alert events.
@@ -276,8 +275,7 @@ In the integration detail page (edit and preview), the **Silence Detection** (He
| **Detection Interval (minutes)** | A Warning alert is generated if no valid event arrives within this interval. Must be an integer between 10 minutes and 48 hours (default 10 minutes) |
| **Auto-recover on new event** | Switch, on by default. When the next valid event arrives, the alert raised by silence detection is recovered automatically |
-## IV. Best Practices <span id="best-practices"></span>
----
+## Best Practices <span id="best-practices"></span>
1. Send events to Flashduty when alert status changes
2. When an alert recovers, send an event with status Ok to close the alert. Otherwise, the alert will remain open. If your alert system doesn't have recovery events, we recommend manually sending recovery events
@@ -286,8 +284,7 @@ In the integration detail page (edit and preview), the **Silence Detection** (He
- Alert ownership information, like team, owner
- Alert category information, like class (api, db, net)
-## V. FAQ
----
+## FAQ
<details>
<summary>Why haven't I received alerts in Flashduty?</summary>
diff --git a/en/on-call/integration/alert-integration/alert-sources/statuscake.mdx b/en/on-call/integration/alert-integration/alert-sources/statuscake.mdx
index e437cb05..0f7d5192 100644
--- a/en/on-call/integration/alert-integration/alert-sources/statuscake.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/statuscake.mdx
@@ -1,5 +1,6 @@
---
title: "StatusCake alert integration"
+sidebarTitle: "StatusCake"
description: "Send StatusCake uptime test down and up notifications to Flashduty On-call through a notification group webhook."
keywords: ["alert integration", "StatusCake", "Uptime", "Notification Group", "Contact Group", "webhook", "TestID"]
---
@@ -9,7 +10,6 @@ Use a StatusCake notification group (formerly contact group) webhook to send upt
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure StatusCake
----
<Steps>
<Step title="Create a notification group">
@@ -66,7 +65,6 @@ Webhook Method must be **POST**. With GET, StatusCake only requests the URL with
</Warning>
## Payload fields
----
StatusCake posts the following fields as an `application/x-www-form-urlencoded` form. Flashduty parses them directly; no template is needed.
@@ -85,14 +83,12 @@ StatusCake posts the following fields as an `application/x-www-form-urlencoded`
The alert title is the test name. If the name is empty, Flashduty uses the tested address, then `StatusCake test <TestID>`.
## Alert Key
----
Flashduty uses `TestID` as the Alert Key. Down, repeated down, and up notifications for the same test carry the same `TestID`, so they land on the same alert. Two different tests produce different alerts even if they share a name and address. Changing the test name, status code, or tags does not change the Alert Key.
Flashduty returns a parameter error when `TestID` is missing, because the recovery notification could not otherwise be matched to the original alert.
## Status and severity
----
StatusCake notifications carry no severity, so Flashduty treats every alert as Critical.
@@ -104,7 +100,6 @@ StatusCake notifications carry no severity, so Flashduty treats every alert as C
Requests with an empty or any other `Status` are rejected, so a request whose state cannot be determined never enters the wrong alert lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="Do repeat alerts create more Flashduty alerts?">
@@ -127,7 +122,6 @@ The notification group test only proves that the URL is reachable. Check that th
</AccordionGroup>
## Troubleshooting
----
- **StatusCake fails to deliver**: Make sure the Webhook URL is the complete push URL and includes `integration_key`
- **Flashduty returns a parameter error**: Make sure Webhook Method is POST and that `TestID` and `Status` are not empty
diff --git a/en/on-call/integration/alert-integration/alert-sources/statusgator.mdx b/en/on-call/integration/alert-integration/alert-sources/statusgator.mdx
index d6ce59c8..632211bd 100644
--- a/en/on-call/integration/alert-integration/alert-sources/statusgator.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/statusgator.mdx
@@ -1,5 +1,6 @@
---
title: "StatusGator alert integration"
+sidebarTitle: "StatusGator"
description: "Send StatusGator monitor status changes and early warning signals for third-party services to Flashduty On-call through the Webhook integration."
keywords: ["alert integration", "StatusGator", "status page monitoring", "webhook", "StatusChange", "EarlyWarningSignal"]
---
@@ -9,7 +10,6 @@ Use StatusGator's Webhook integration (webhook version 3.0) to send monitor stat
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In StatusGator
----
<Steps>
<Step title="Add the Webhook integration">
@@ -53,7 +52,6 @@ After saving, click **Test integrations** on the Webhook integration page, choos
The Webhook integration is available on all Business and Education plans, including Free. If StatusGator does not get a 200 response five times in a row, it disables the webhook. Fix the URL on the **Integrations** page to re-enable it.
## Payload
----
StatusGator POSTs JSON. The body is fixed and cannot be customized. Flashduty parses it directly, so no template is needed:
@@ -73,7 +71,6 @@ StatusGator POSTs JSON. The body is fixed and cannot be customized. Flashduty pa
The alert title is `<monitor name>: <message>`. When `message` is empty it is `<monitor name> is <status>`.
## Alert Key
----
`StatusChange` uses `monitor.id` as the Alert Key. The StatusGator body has no event or incident ID, so the monitor is the only stable business object: the down, warn and up notifications of one monitor land on one alert, and different monitors produce different alerts. Changing the message, components, name or time does not change the Alert Key.
@@ -82,7 +79,6 @@ The alert title is `<monitor name>: <message>`. When `message` is empty it is `<
If `monitor.id` is missing, Flashduty returns a parameter error, because a recovery could not be reliably matched to its alert.
## Status and severity
----
| StatusGator `status` | Flashduty status or severity |
| :--- | :--- |
@@ -95,12 +91,10 @@ If `monitor.id` is missing, Flashduty returns a parameter error, because a recov
Requests whose `type` or `status` is empty or unknown are rejected, so a request that cannot be classified never lands in the wrong alert lifecycle.
## Early warnings do not recover
----
`EarlyWarningSignal` is a one-shot notification. StatusGator sends no matching recovery event and Flashduty does not close it when the service recovers. Enable [auto-close on timeout](/en/on-call/channel/create-edit) for the channel, with **1 hour** recommended.
## FAQ
----
<AccordionGroup>
<Accordion title="Does the test notification create an alert?">
@@ -123,7 +117,6 @@ Yes. Non-connection failures are retried up to 20 times over about 24 days, with
</AccordionGroup>
## Troubleshooting
----
- **StatusGator shows failed deliveries or disabled the webhook**: confirm the Webhook URL is the full push URL and includes `integration_key`
- **Flashduty returns a parameter error**: confirm the request is a version 3.0 JSON notification and that `type`, `monitor.id` and `status` meet the requirements above
diff --git a/en/on-call/integration/alert-integration/alert-sources/statuspage.mdx b/en/on-call/integration/alert-integration/alert-sources/statuspage.mdx
index 64e6797f..e7d95c58 100644
--- a/en/on-call/integration/alert-integration/alert-sources/statuspage.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/statuspage.mdx
@@ -1,5 +1,6 @@
---
title: "Atlassian Statuspage alert integration"
+sidebarTitle: "Atlassian Statuspage"
description: "Subscribe to any Atlassian Statuspage status page by webhook and send component outages and Statuspage incidents to Flashduty On-call."
keywords: ["alert integration", "Statuspage", "Atlassian", "status page", "third-party service status", "webhook"]
---
@@ -11,7 +12,6 @@ Subscribers need no Statuspage account and pay nothing. The Webhook option appea
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Subscribe on a Statuspage status page
----
<Steps>
<Step title="Open the subscribe menu">
@@ -69,7 +68,6 @@ If your team runs a Statuspage page, you can use it to verify: change a componen
</Steps>
## Payload
----
Statuspage posts one JSON body each time a component changes status and each time an incident is updated. There are two kinds:
@@ -101,7 +99,6 @@ The alert title looks like `API Requests: major outage`.
Every alert also carries the label `source=statuspage`. The unsubscribe link in the payload (`meta.unsubscribe`) contains the subscription credential, and Flashduty never writes it into the alert.
## Alert Key
----
Flashduty builds the Alert Key per payload kind:
@@ -113,7 +110,6 @@ Component alerts and incident alerts are independent. One upstream outage usuall
Renaming a component or incident, or changing the impact, does not change the Alert Key. When the severity rises (for example an incident's impact changing from `none` to `critical`), Flashduty opens a new alert at the higher severity and keeps the earlier alert open; the recovery delivery closes both. After an alert recovers, a new outage of the same component opens a new alert.
## Status and severity
----
**Component status**
@@ -145,7 +141,6 @@ The alert severity comes from the impact (`impact`), and the alert status from t
Scheduled maintenance (status `scheduled`, `in_progress`, `verifying`, or `completed`, or impact `maintenance`) is planned change: Flashduty returns success and creates no alert.
## FAQ
----
<AccordionGroup>
<Accordion title="Does the alert recover while an incident is in monitoring?">
@@ -168,7 +163,6 @@ The Statuspage unsubscribe link appears only in the payload, and Flashduty does
</AccordionGroup>
## Troubleshooting
----
- **The status page has no webhook subscribe option**: the page owner has not enabled webhook subscriptions, so this integration cannot subscribe to it
- **Flashduty returns an invalid parameter error**: make sure the push URL is complete (including `integration_key`). Payloads without `page.id`, a component ID, or an incident ID are rejected
diff --git a/en/on-call/integration/alert-integration/alert-sources/statuspal.mdx b/en/on-call/integration/alert-integration/alert-sources/statuspal.mdx
index d14da99b..08e4fdac 100644
--- a/en/on-call/integration/alert-integration/alert-sources/statuspal.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/statuspal.mdx
@@ -1,5 +1,6 @@
---
title: "Statuspal alert integration"
+sidebarTitle: "Statuspal"
description: "Use Statuspal webhooks to send status page incidents and Statuspal-monitored services going down or up to Flashduty On-call."
keywords: ["alert integration", "Statuspal", "status page", "webhook", "service monitoring"]
---
@@ -12,7 +13,6 @@ Use Statuspal outbound webhooks to send changes on your status page to Flashduty
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -33,7 +33,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Statuspal
----
<Steps>
<Step title="Create a webhook">
@@ -69,7 +68,6 @@ Service monitoring: about 5 minutes after a service goes down, Statuspal sends `
</Steps>
## Payload
----
Statuspal pushes JSON. The `event` field is the event type, and `data.object` is the Statuspal incident or service:
@@ -97,7 +95,6 @@ Statuspal pushes JSON. The `event` field is the event type, and `data.object` is
Service alert titles look like `API is down`. Every alert also carries the labels `source=statuspal` and `event` (the event type pushed).
## Alert Key
----
- Incident: the incident ID. Every push for one Statuspal incident, from creation through updates to its end, lands on the same alert
- Service: the service ID. The `down` and `up` pushes for one service land on the same alert, and repeated `down` pushes merge into it
@@ -105,7 +102,6 @@ Service alert titles look like `API is down`. Every alert also carries the label
Incident alerts and service alerts are independent. With **Automatically create incident** enabled on the service, Statuspal creates an incident when the service goes down (`incident.created`, titled like `Service API seems to be down`). It is a separate Warning alert and is not ended when the service recovers; it recovers only after you resolve the incident in Statuspal (`incident.updated` with `ends_at` set). A service going down therefore produces a service alert and an incident alert; use the channel's [alert grouping](/en/on-call/channel/noise-reduction) to group them into one Flashduty incident. Renaming an incident or a service does not change the Alert Key.
## Status and severity
----
Statuspal payloads carry no incident type (major, minor) or severity, so every incident alert is Warning.
@@ -122,7 +118,6 @@ Statuspal payloads carry no incident type (major, minor) or severity, so every i
A maintenance has an end time from the moment it is created, so Flashduty treats its pushes as recoveries. There is no matching triggered alert, so no alert is created.
## FAQ
----
<AccordionGroup>
<Accordion title="Does the alert recover while the incident is in Monitoring?">
@@ -145,7 +140,6 @@ No. This event is sent only for services with Statuspal's built-in monitoring en
</AccordionGroup>
## Troubleshooting
----
- **Send test request shows an error**: make sure the push URL is complete (including `integration_key`) and the integration still exists
- **Flashduty returns an invalid parameter error**: the payload has no `data.object.id`, or `monitored_status` is neither `up` nor `down`
diff --git a/en/on-call/integration/alert-integration/alert-sources/stripe.mdx b/en/on-call/integration/alert-integration/alert-sources/stripe.mdx
index 99141628..3afbe980 100644
--- a/en/on-call/integration/alert-integration/alert-sources/stripe.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/stripe.mdx
@@ -1,5 +1,6 @@
---
title: "Stripe alert integration"
+sidebarTitle: "Stripe"
description: "Send Stripe dispute, failed payout, and early fraud warning events to Flashduty On-call through a webhook, and recover dispute alerts when Stripe closes the dispute."
keywords: ["alert integration", "Stripe", "dispute", "chargeback", "failed payout", "early fraud warning", "Radar", "webhook"]
---
@@ -15,7 +16,6 @@ Every Stripe account can create webhook endpoints, up to 16 per account.
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -36,7 +36,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Stripe
----
<Steps>
<Step title="Create an event destination">
@@ -100,7 +99,6 @@ A dispute usually takes 2 to 3 months from creation to closure, and the auto-res
</Steps>
## Payload
----
Stripe sends one event (an Event object) per request, with the affected object in `data.object`:
@@ -124,7 +122,6 @@ Stripe sends one event (an Event object) per request, with the affected object i
Every alert also carries the label `source=stripe`. Example titles: `Stripe dispute needs response: fraudulent`, `Stripe inquiry under review: general`, `Stripe payout failed: account_closed`, `Stripe early fraud warning: made_with_stolen_card`.
## Alert Key
----
Flashduty uses `data.object.id` (the ID of the dispute, payout, or warning itself) as the Alert Key, not the event ID:
@@ -134,7 +131,6 @@ Flashduty uses `data.object.id` (the ID of the dispute, payout, or warning itsel
- Stripe retries failed deliveries (for up to 3 days in live mode) and occasionally sends two events for one change; these events merge into the original alert instead of creating duplicates
## Status and severity
----
| Stripe event or status | Flashduty status or severity |
| :--- | :--- |
@@ -149,7 +145,6 @@ Flashduty uses `data.object.id` (the ID of the dispute, payout, or warning itsel
A request is rejected if an event that creates an alert has no `data.object.id`.
## FAQ
----
<AccordionGroup>
<Accordion title="Why did a dispute not create an alert?">
@@ -172,7 +167,6 @@ No. Flashduty identifies the integration by the `integration_key` in the push UR
</AccordionGroup>
## Troubleshooting
----
- **Stripe shows failed deliveries (4xx)**: make sure the push URL is complete (it includes `integration_key`) and the event payload style is Snapshot
- **Deliveries succeed but no alert appears**: make sure the event type is in the table above; other event types create no alert
diff --git a/en/on-call/integration/alert-integration/alert-sources/sublime.mdx b/en/on-call/integration/alert-integration/alert-sources/sublime.mdx
index f86540f4..e722e754 100644
--- a/en/on-call/integration/alert-integration/alert-sources/sublime.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/sublime.mdx
@@ -1,5 +1,6 @@
---
title: "Sublime Security alert integration"
+sidebarTitle: "Sublime Security"
description: "Send email messages flagged by Sublime Security to Flashduty On-call through a webhook Action, one alert per message group."
keywords: ["alert integration", "Sublime Security", "Sublime", "email security", "phishing", "webhook"]
---
@@ -11,7 +12,6 @@ Sublime pushes only when a message is flagged and sends no resolve notification,
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of two ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of two ways.
</div>
## In Sublime Security
----
<Steps>
<Step title="Create a webhook Action">
@@ -59,7 +58,6 @@ Add the Action to the detection rules or automations you want to be notified abo
</Steps>
## Events and recovery
----
| Sublime `type` | Meaning | Effect in Flashduty |
| :--- | :--- | :--- |
@@ -70,12 +68,10 @@ Add the Action to the detection rules or automations you want to be notified abo
Sublime sends no resolve notification. Enable [auto-close on timeout](/en/on-call/channel/create-edit) for the channel, with 7 days suggested, or close alerts by hand once the message is handled.
## Alert Key
----
The Alert Key is `data.message.canonical_id`, or `data.message.id` when it is absent. Sublime documents `canonical_id` as the identifier of the message group a message belongs to, shared when the same message is delivered to several mailboxes. Changes to identifiers, classification, rule names or severity do not change the Alert Key. A push with neither field is rejected, and the error names the field.
## Severity
----
Flashduty uses the highest severity among `flagged_rules`:
@@ -87,7 +83,6 @@ Flashduty uses the highest severity among `flagged_rules`:
| No rules or an unknown value | Warning |
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -105,12 +100,10 @@ Flashduty uses the highest severity among `flagged_rules`:
The push carries no subject or body; use `message_id` to look the message up in Sublime. Flashduty does not store the user email in `actor`.
## Signature header
----
Sublime sends an `X-Sublime-Signature` header on every delivery, in the format `t=<Unix timestamp>,v0=<HMAC signature>`. The Flashduty push URL authenticates with `integration_key` and does not verify this header, so no extra setup is needed.
## Troubleshooting
----
- **No alerts arrive**: confirm the Action is attached to a rule and check the Action's message group scope
- **Flashduty returns a parameter error**: the push has neither `data.message.canonical_id` nor `data.message.id`, which happens for a manual trigger with no message selected
diff --git a/en/on-call/integration/alert-integration/alert-sources/sumo-logic.mdx b/en/on-call/integration/alert-integration/alert-sources/sumo-logic.mdx
index ad598e92..abbcb319 100644
--- a/en/on-call/integration/alert-integration/alert-sources/sumo-logic.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/sumo-logic.mdx
@@ -1,5 +1,6 @@
---
title: "Sumo Logic alert integration"
+sidebarTitle: "Sumo Logic"
description: "Send Sumo Logic Monitor alert and recovery events to Flashduty On-call through a webhook."
keywords: ["alert integration", "Sumo Logic", "Monitor", "webhook", "AlertResponseId"]
---
@@ -9,14 +10,12 @@ Use a Sumo Logic webhook to send Monitor alerts to Flashduty On-call. Each Sumo
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **Sumo Logic** alert integration and copy its complete Push URL.
</div>
## Configure Sumo Logic
----
<Steps>
<Step title="Create a webhook connection">
@@ -72,14 +71,12 @@ Make the Monitor cross its threshold and confirm an active Flashduty alert. Then
</Steps>
## Alert Key
----
Flashduty uses `AlertResponseId` directly as the Alert Key. Sumo Logic defines it as the unique identifier of the triggered alert. A real Monitor test also confirmed that a `Critical` trigger and its `ResolvedCritical` recovery carry the same `AlertResponseId`.
`Id` identifies the Monitor. A grouped Monitor can produce independent alerts, so the Monitor ID is stored only as context and is not used by itself as the Alert Key. Changes to the title, severity, time range, trigger value, or `AlertGroup` do not change the Alert Key.
## Status and severity
----
| Sumo Logic `TriggerType` | Flashduty status or severity |
| :--- | :--- |
@@ -94,7 +91,6 @@ Flashduty uses `AlertResponseId` directly as the Alert Key. Sumo Logic defines i
An empty or unknown `TriggerType` is rejected so that an ambiguous request cannot enter the wrong alert lifecycle.
## Troubleshooting
----
- **Sumo Logic receives a non-2xx response**: verify that the full Push URL includes `integration_key`
- **Flashduty reports an invalid parameter**: verify valid JSON and non-empty `alert_response_id` and `trigger_type` fields
diff --git a/en/on-call/integration/alert-integration/alert-sources/suricata.mdx b/en/on-call/integration/alert-integration/alert-sources/suricata.mdx
index f5e7143c..b1f3b88b 100644
--- a/en/on-call/integration/alert-integration/alert-sources/suricata.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/suricata.mdx
@@ -1,5 +1,6 @@
---
title: "Suricata alert integration"
+sidebarTitle: "Suricata"
description: "Suricata has no webhook output. Collect its eve.json log with Wazuh and receive Suricata alerts through Flashduty's Wazuh integration."
keywords: ["alert integration", "Suricata", "IDS", "intrusion detection", "Wazuh", "eve.json", "network security"]
---
@@ -9,7 +10,6 @@ Suricata only writes events to its EVE JSON log and cannot send HTTP requests it
<div className="hide">
## In Flashduty On-call
----
Get the integration push URL in either of the two ways below. **In both cases choose Wazuh as the integration type**, not Suricata.
@@ -30,7 +30,6 @@ Get the integration push URL in either of the two ways below. **In both cases ch
</div>
## Data flow
----
1. Suricata writes events as JSON to `/var/log/suricata/eve.json`
2. The Wazuh agent on the same host reads that file
@@ -40,7 +39,6 @@ Get the integration push URL in either of the two ways below. **In both cases ch
Rule `86601` matches only Suricata alert events. Other event types in the same `eve.json` (`http`, `dns`, `tls`) map to level-0 rules and raise no alert.
## Collect Suricata logs on the Wazuh agent
----
In the Wazuh agent's `/var/ossec/etc/ossec.conf` on the host that runs Suricata, add:
@@ -60,7 +58,6 @@ sudo systemctl restart wazuh-agent
Make sure Suricata has EVE JSON output enabled and that the file path matches the `location` above.
## Push to Flashduty from the Wazuh manager
----
In `/var/ossec/etc/ossec.conf` on the manager, add a `shuffle` integration that forwards only the Suricata alert rule, and replace `hook_url` with the Flashduty push URL:
@@ -86,7 +83,6 @@ systemctl restart wazuh-manager
For Docker deployments, restart the manager container. The [Wazuh integration](/en/on-call/integration/alert-integration/alert-sources/wazuh) page covers the full setup, field mapping and troubleshooting.
## Trigger and verify
----
The Wazuh Suricata example triggers Suricata by sending ICMP from another host to the monitored host:
@@ -97,19 +93,16 @@ ping -c 20 <IP of the host running Suricata>
Whether this fires depends on Suricata having a rule loaded that matches ICMP. Once it fires, you can filter with `rule.groups:suricata` in the Wazuh console, and an alert titled `Suricata: Alert - <signature>` should appear in Flashduty. If nothing arrives, check `/var/ossec/logs/integrations.log` and `/var/ossec/logs/ossec.log` on the manager.
## Events and recovery
----
Suricata and Wazuh raise an alert once per event and never send a recovery. Every Wazuh alert has a unique ID, which Flashduty uses as the Alert Key, so each Suricata alert opens its own Flashduty alert and none closes automatically.
Enable the [auto-resolve timeout](/en/on-call/channel/create-edit) on the channel that receives this integration (24 hours suggested). When the same signature fires repeatedly, configure a noise-reduction rule on the channel to merge them into one incident.
## Severity
----
Rule `86601` is level 3, which Flashduty maps to Info by Wazuh rule level (0-6 Info, 7-11 Warning, 12-15 Critical). Flashduty does not read Suricata's own `alert.severity`; to distinguish severity, adjust it with an [alert processing pipeline](/en/on-call/integration/alert-integration/alert-pipelines) using the signature in the title or the `rule_id` label.
## Notes
----
- Suricata events carry source and destination IPs and possibly payload content. Flashduty neither reads nor stores the raw log (`full_log`), but `shuffle` sends the whole Wazuh alert to `hook_url`, so forward only the rules that need a human response.
- To forward only certain signatures or categories, write custom Wazuh rules for them with a higher level, then filter with `<rule_id>` or `<level>`.
diff --git a/en/on-call/integration/alert-integration/alert-sources/sysdig.mdx b/en/on-call/integration/alert-integration/alert-sources/sysdig.mdx
index 0a77722a..f1e4a0a7 100644
--- a/en/on-call/integration/alert-integration/alert-sources/sysdig.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/sysdig.mdx
@@ -1,5 +1,6 @@
---
title: "Sysdig alert integration"
+sidebarTitle: "Sysdig"
description: "Send Sysdig Monitor alerts to Flashduty On-call through a Webhook notification channel, and recover them automatically when the alert resolves."
keywords: ["alert integration", "Sysdig", "Sysdig Monitor", "webhook", "notification channel"]
---
@@ -9,7 +10,6 @@ Use a Sysdig Monitor Webhook notification channel to send alert events to Flashd
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Sysdig Monitor
----
Creating a notification channel requires administrator privileges in Sysdig Monitor.
@@ -41,16 +40,16 @@ Creating a notification channel requires administrator privileges in Sysdig Moni
2. Click **Add Notification Channel** and select **Webhook**. Do not select **Custom Webhook**: Flashduty parses the fixed format of the Webhook channel
3. Fill in the fields as follows:
-| Field | Value |
-| :--- | :--- |
-| **URL** | The full Flashduty push URL, including `integration_key` |
-| **Channel Name** | A recognizable name, such as `Flashduty` |
-| **Enabled** | On |
-| **Notify when Resolved** | On. If it is off, Sysdig sends no resolve notifications and alerts in Flashduty do not recover automatically |
-| **Notify when Acknowledged** | Off is recommended. Flashduty does not sync Sysdig acknowledgements |
-| **Test notification** | When on, Sysdig sends a test notification on save to check that the URL is reachable |
-| **Shared With** | **All Teams** or the current team, as needed |
-| **Custom headers** / **Custom data** | Leave empty |
+ | Field | Value |
+ | :--- | :--- |
+ | **URL** | The full Flashduty push URL, including `integration_key` |
+ | **Channel Name** | A recognizable name, such as `Flashduty` |
+ | **Enabled** | On |
+ | **Notify when Resolved** | On. If it is off, Sysdig sends no resolve notifications and alerts in Flashduty do not recover automatically |
+ | **Notify when Acknowledged** | Off is recommended. Flashduty does not sync Sysdig acknowledgements |
+ | **Test notification** | When on, Sysdig sends a test notification on save to check that the URL is reachable |
+ | **Shared With** | **All Teams** or the current team, as needed |
+ | **Custom headers** / **Custom data** | Leave empty |
4. Click **Save**
@@ -75,7 +74,6 @@ Creating a notification channel requires administrator privileges in Sysdig Moni
</Steps>
## Alert Key
----
Flashduty uses the Sysdig event ID (`event.id`) as the Alert Key. Sysdig creates one event each time an alert fires, and the first notification, renotifications, and the resolve notification of that event all carry the same event ID, so they merge into one alert, which the resolve notification recovers.
@@ -84,7 +82,6 @@ Flashduty uses the Sysdig event ID (`event.id`) as the Alert Key. Sysdig creates
- Changes to the alert name, severity, metric value, and time do not change the Alert Key. Requests without `event.id` are rejected
## Status and severity
----
`state` sets the status:
@@ -106,7 +103,6 @@ The alert rule's severity (`alert.severity`, 0 to 7) sets the alert severity. If
A recovered alert keeps the severity of its last trigger.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -124,7 +120,6 @@ A recovered alert keeps the severity of its last trigger.
The alert description is the Sysdig notification body (`alert.body`), which includes the metric value, segment, and trigger time.
## Troubleshooting
----
- **Flashduty returns a parameter error**: make sure the URL is complete and includes `integration_key`, and that the channel type is **Webhook**, not **Custom Webhook**
- **No alert after saving the channel**: this is expected. The test notification does not create an alert; use a real alert to verify
diff --git a/en/on-call/integration/alert-integration/alert-sources/tactical-rmm.mdx b/en/on-call/integration/alert-integration/alert-sources/tactical-rmm.mdx
index d7c6f544..90715d68 100644
--- a/en/on-call/integration/alert-integration/alert-sources/tactical-rmm.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/tactical-rmm.mdx
@@ -1,5 +1,6 @@
---
title: "Tactical RMM alert integration"
+sidebarTitle: "Tactical RMM"
description: "Send Tactical RMM agent-overdue, check, and task failure alerts to Flashduty On-call through a webhook (URL Action) in an alert template."
keywords: ["alert integration", "Tactical RMM", "webhook", "RMM", "MSP", "remote monitoring and management"]
---
@@ -11,7 +12,6 @@ Tactical RMM has no fixed webhook payload; you write the request body yourself.
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the push URL in either of the following ways.
</div>
## Configure Tactical RMM
----
Create two webhooks, one for failure and one for recovery, then attach both to an alert template. Both webhooks use the Flashduty push URL, and the request bodies differ only in `status`.
@@ -43,9 +42,9 @@ Create two webhooks, one for failure and one for recovery, then attach both to a
2. Set **URL Pattern** to the full Flashduty push URL, including `integration_key`, and set the request method to **POST**
3. Set **Request Headers** to:
-```json
-{ "Content-Type": "application/json" }
-```
+ ```json
+ { "Content-Type": "application/json" }
+ ```
4. Set **Request Body** to:
@@ -91,7 +90,6 @@ Tactical RMM runs webhooks for Error alerts (such as an overdue agent) and Warni
</Steps>
## Event types
----
| Request body | Effect in Flashduty |
| :--- | :--- |
@@ -100,14 +98,12 @@ Tactical RMM runs webhooks for Error alerts (such as an overdue agent) and Warni
| Test button (`alert_id` and `alert_type` are still the unrendered `{{alert.id}}` and `{{alert.alert_type}}`) | Creates a separate Info alert that does not recover |
## Alert Key
----
Flashduty computes the Alert Key from `alert_id` (`{{alert.id}}`, the number of the alert record in Tactical RMM). The failure and recovery webhooks render from the same record, so the number is the same. If the same subject fails again after recovery, Tactical RMM creates a new alert record, so it is a new alert in Flashduty. Changes to severity, message, or hostname do not change the Alert Key, and requests without `alert_id` are rejected.
Use one Flashduty integration per Tactical RMM instance. Alert numbers from different instances can collide.
## Status and severity
----
| Tactical RMM `severity` | Flashduty severity |
| :--- | :--- |
@@ -119,7 +115,6 @@ Use one Flashduty integration per Tactical RMM instance. Alert numbers from diff
When `status` is `resolved` the alert recovers and keeps its last severity.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -131,7 +126,6 @@ When `status` is `resolved` the alert recovers and keeps its last severity.
| `client` / `site` | Client and site the agent belongs to |
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: the message names the field. Common causes are a request body without `alert_id`, or an `alert_type` other than `availability`, `check`, `task`, or `custom` (for example, when a test target was selected on the Test button)
- **The alert does not recover**: confirm the recovery webhook exists, is set as the **Resolved Web Hook** of the alert template, and sends `"status": "resolved"`. The action result is visible in the alert details in Tactical RMM
diff --git a/en/on-call/integration/alert-integration/alert-sources/tailscale.mdx b/en/on-call/integration/alert-integration/alert-sources/tailscale.mdx
index b915455c..766f46fe 100644
--- a/en/on-call/integration/alert-integration/alert-sources/tailscale.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/tailscale.mdx
@@ -1,5 +1,6 @@
---
title: "Tailscale alert integration"
+sidebarTitle: "Tailscale"
description: "Send Tailscale node key expiry, pending device approval, and subnet router or exit node misconfiguration events to Flashduty On-call through a webhook."
keywords: ["alert integration", "Tailscale", "tailnet", "node key expiry", "device approval", "webhook"]
---
@@ -11,7 +12,6 @@ According to the Tailscale documentation, webhooks are available on all plans, i
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Tailscale
----
<Steps>
<Step title="Add a webhook endpoint">
@@ -85,7 +84,6 @@ Node key expiry and IP forwarding misconfiguration have no recovery event: after
</Steps>
## Payload
----
Each Tailscale delivery is a JSON array that can carry several events. Flashduty handles every event that creates an alert separately:
@@ -103,7 +101,6 @@ Each Tailscale delivery is a JSON array that can carry several events. Flashduty
Every alert also has the label `source=tailscale` and a `check` label (`key_expiry`, `approval`, `signature`, `user_approval`, `exit_node_ip_forwarding`, or `subnet_ip_forwarding`). When `message` is empty, the title is `Tailscale <event type>: <device or user>`.
## Alert Key
----
Flashduty builds the Alert Key from the object (the device's `nodeID` or the user's `user`) and the check (`check`):
@@ -115,7 +112,6 @@ Flashduty builds the Alert Key from the object (the device's `nodeID` or the use
Renaming a device or the tailnet does not change the Alert Key.
## Status and severity
----
| Tailscale event | Flashduty status or severity |
| :--- | :--- |
@@ -134,7 +130,6 @@ Renaming a device or the tailnet does not change the Alert Key.
If a device event that creates an alert has no `data.nodeID`, or a user event has no `data.user`, the whole request is rejected.
## FAQ
----
<AccordionGroup>
<Accordion title="Why did the alert not recover after I renewed the node key?">
@@ -151,7 +146,6 @@ No. Flashduty identifies the integration by the `integration_key` in the push UR
</AccordionGroup>
## Troubleshooting
----
- **Flashduty returns a parameter error**: make sure **Destination** is **None** and the push URL is complete (it includes `integration_key`)
- **The test event succeeds but no alert appears**: the `test` event creates no alert; make sure the endpoint subscribes to the events in the table above
diff --git a/en/on-call/integration/alert-integration/alert-sources/tencent-cls.mdx b/en/on-call/integration/alert-integration/alert-sources/tencent-cls.mdx
index b6ec1347..c42de0a3 100644
--- a/en/on-call/integration/alert-integration/alert-sources/tencent-cls.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/tencent-cls.mdx
@@ -1,5 +1,6 @@
---
title: "Tencent Cloud CLS Integration"
+sidebarTitle: "Tencent Cloud CLS"
description: "Sync Tencent Cloud Log Service (CLS) monitoring alerts to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,42 +9,42 @@ Sync Tencent Cloud Log Service (CLS) monitoring alerts to Flashduty via webhook
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alerts to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Tencent Cloud CLS** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alerts** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alerts** to enter the integration selection page
2. Select **Tencent Cloud CLS** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Tencent Cloud CLS
----
**Step 1: Configure Notification Channel Group**
@@ -52,7 +53,7 @@ Choose this option when you need to route alerts to different channels based on
1. Log in to your Tencent Cloud Console, select CLS service, and go to Monitoring Alerts - Notification Channel Groups
2. Click `Create` to start
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/integration/tencent-cls/tencent-cls-notify.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/integration/tencent-cls/tencent-cls-notify.png" />
3. As shown, enter a specific channel group name in `Name`, select "Custom API Callback" for `Channel Type`, fill in the integration push URL in `Callback URL`, and select POST for `Request Method`
@@ -67,7 +68,7 @@ Choose this option when you need to route alerts to different channels based on
1. Log in to your Tencent Cloud Console, select CLS service, and go to Monitoring Alerts - Alert Policies
2. Click `Create` to start
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/integration/tencent-cls/tencent-cls-alert.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/integration/tencent-cls/tencent-cls-alert.png" />
3. As shown, enter a specific alert name in `Alert Name`, select the specific log topic
@@ -126,7 +127,6 @@ Choose this option when you need to route alerts to different channels based on
</div>
## Status Mapping
----
<div class="md-block">
Tencent Cloud CLS monitoring alert level mapping to Flashduty:
diff --git a/en/on-call/integration/alert-integration/alert-sources/tencent-cm.mdx b/en/on-call/integration/alert-integration/alert-sources/tencent-cm.mdx
index da1edc43..6824c1b5 100644
--- a/en/on-call/integration/alert-integration/alert-sources/tencent-cm.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/tencent-cm.mdx
@@ -1,5 +1,6 @@
---
title: "Tencent Cloud Monitor CM Integration"
+sidebarTitle: "Tencent Cloud Monitor CM"
description: "Sync Tencent Cloud Monitor CM alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,54 +9,54 @@ Sync Tencent Cloud Monitor CM alert events to Flashduty via webhook for automate
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Select **Tencent Cloud Monitor CM** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use. Done.
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Tencent Cloud Monitor CM** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Tencent Cloud Monitor CM
----
<div class="md-block">
1. Log in to your Tencent Cloud Console and select Cloud Monitor
-2. Go to Alert Management -> Notification Templates page, click the New button to start editing a notification template
+2. Go to Alert Management → Notification Templates page, click the New button to start editing a notification template
3. Fill in the callback URL with the integration push URL, and select English as the notification language
4. Click the Save button to save the template
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/saas-tecent-cm-template.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/saas-tecent-cm-template.png" />
-5. Go to Alert Configuration -> Alert Policies page, select the alert policies for which you want to send events, enter details, and add the newly created notification template
+5. Go to Alert Configuration → Alert Policies page, select the alert policies for which you want to send events, enter details, and add the newly created notification template
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/tecent-cm-rule.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/tecent-cm-rule.png" />
6. Return to the integration list, if the latest event time is displayed, the configuration is successful and events are being received
7. Done
@@ -63,7 +64,6 @@ Choose this option when you need to route alerts to different channels based on
</div>
## Status Mapping
----
<div class="md-block">
When `alarmLevel` is present, Flashduty maps the alert severity as follows:
diff --git a/en/on-call/integration/alert-integration/alert-sources/tencent-css.mdx b/en/on-call/integration/alert-integration/alert-sources/tencent-css.mdx
index f3dd30ea..1beab858 100644
--- a/en/on-call/integration/alert-integration/alert-sources/tencent-css.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/tencent-css.mdx
@@ -1,5 +1,6 @@
---
title: "Tencent Cloud Live alert integration"
+sidebarTitle: "Tencent Cloud Live"
description: "Send Tencent Cloud Live (CSS) stream interruptions to Flashduty On-call through live callbacks. Alerts close automatically when the stream is pushed again or the broadcaster stops normally."
keywords: ["alert integration", "Tencent Cloud Live", "CSS", "live callback", "stream push callback", "stream interruption callback"]
---
@@ -11,7 +12,6 @@ This integration handles only **stream push callbacks** and **stream interruptio
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,14 +32,13 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Tencent Cloud Live
----
Callbacks are configured in a callback template. The template takes effect only after it is bound to a push domain.
<Steps>
<Step title="Create a callback template">
-1. Sign in to the [CSS console](https://console.cloud.tencent.com/live) and select **功能配置 (Feature Configuration) > 直播回调 (Live Callback)**
+1. Sign in to the [CSS console](https://console.cloud.tencent.com/live) and select **功能配置 (Feature Configuration) → 直播回调 (Live Callback)**
2. Click **创建模板 (Create Template)** and enter a **模板名称 (Template Name)**
3. You can leave **回调密钥 (Callback Key)** empty or keep an existing value. Flashduty identifies the integration by the `integration_key` in the push URL and does not verify the `sign` field in callbacks
4. Under **回调类型 (Callback Type)**, enter the Flashduty push URL in both **推流回调 (Stream Push Callback)** and **断流回调 (Stream Interruption Callback)**. Fill in both: with only the interruption callback, alerts do not close when the push resumes
@@ -72,7 +71,6 @@ CSS has no "send test callback" button. Push a test stream to the push domain wi
</Steps>
## Alert Key
----
Flashduty computes the Alert Key from the account APPID `appid`, the push domain `app`, the push path `appname`, and the stream name `stream_id`. Stream push and stream interruption callbacks for the same stream carry the same four fields, so they land on the same alert.
@@ -81,7 +79,6 @@ Changes to the error code, error message, push node, pusher IP, push duration, o
If a stream push or stream interruption callback lacks `appid`, `app`, `appname`, or `stream_id`, or a callback has no `event_type`, Flashduty rejects the request with an error, and CSS retries it according to its callback retry rules.
## Alert lifecycle
----
| CSS callback | Flashduty action |
| :--- | :--- |
@@ -99,12 +96,10 @@ If a stream is interrupted abnormally and never pushed again (for example, the d
</Warning>
## Alert severity
----
Callbacks have no severity field. Every alert triggered by an abnormal interruption is **Critical**. `errcode` gives the reason for the interruption and is written to the labels and description. For its meaning, see the error code table in the CSS documentation.
## Alert content
----
- **Title**: for an abnormal interruption, `Live stream interrupted: <push domain>/<push path>/<stream name>`
- **Description**: the error message `errmsg`, followed by the error code, push node IP, pusher IP, and push duration (milliseconds)
@@ -113,7 +108,6 @@ Callbacks have no severity field. Every alert triggered by an abnormal interrupt
The callback's `stream_param` (push URL parameters, which may include the push authentication `txSecret`), `sign`, and `t` are not written to labels.
## Troubleshooting
----
- **Flashduty receives no callbacks**: make sure the callback template is bound to the domain you actually push to, and that 5 to 10 minutes have passed since binding. Make sure the stream push and stream interruption callbacks contain the full push URL, including `integration_key`
- **An alert was created when the broadcaster stopped**: `errcode` is `1` only when the pusher stops pushing on purpose. When the pusher is ended forcibly (for example, the process exits or the network drops), the interruption callback usually carries an `errcode` other than `1`, and Flashduty triggers an alert for an abnormal interruption. The alert's `errcode` and `errmsg` labels show the reason CSS reported
diff --git a/en/on-call/integration/alert-integration/alert-sources/tencent-eventbridge.mdx b/en/on-call/integration/alert-integration/alert-sources/tencent-eventbridge.mdx
index 8fcdc5c3..54a85c3b 100644
--- a/en/on-call/integration/alert-integration/alert-sources/tencent-eventbridge.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/tencent-eventbridge.mdx
@@ -1,5 +1,6 @@
---
title: "Tencent Cloud EventBridge"
+sidebarTitle: "Tencent Cloud EventBridge"
description: "Sync Tencent Cloud EventBridge events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,73 +9,73 @@ Sync Tencent Cloud EventBridge events to Flashduty via webhook for automated ale
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alerts to different channels. It's simpler and recommended.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Tencent Cloud EventBridge** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're Done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center => Alerts** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alerts** to enter the integration selection page
2. Select **Tencent Cloud EventBridge** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Tencent Cloud EventBridge
----
<div class="md-block">
1. Log in to your Tencent Cloud Console and select EventBridge service
2. Go to the Event Rules page, click the New button to start editing rules
3. Enter the name as Flashduty, as shown below:
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-new-rule.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-new-rule.png" />
4. For event matching, you can either select specific events through the form mode or customize by entering the following JSON content to match all events:
-```
-{
- "source": [
- {
- "suffix": ".cloud.tencent"
- }
- ]
-}
-```
+ ```
+ {
+ "source": [
+ {
+ "suffix": ".cloud.tencent"
+ }
+ ]
+ }
+ ```
-As shown below:
+ As shown below:
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-match-rule.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-match-rule.png" />
5. Next, configure the event target by selecting "Message Push", "General Notification Template", "English", "API Callback", and "Custom webhook". Enter the integration push URL in the webhook address field
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-target-webhook.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-target-webhook.png" />
6. Click the Save button, return to the Event Set page, select an event set, and click Send Event to test
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-test-send.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-test-send.png" />
7. Return to the integration list. If the latest event time is displayed, the configuration is successful and events are being received
8. Done
@@ -82,7 +83,6 @@ As shown below:
</div>
## Status Mapping
----
<div class="md-block">
All Tencent Cloud EventBridge events correspond to "warning" severity level alerts in Flashduty.
diff --git a/en/on-call/integration/alert-integration/alert-sources/thinkst-canary.mdx b/en/on-call/integration/alert-integration/alert-sources/thinkst-canary.mdx
index a5b2d79b..ef0cb573 100644
--- a/en/on-call/integration/alert-integration/alert-sources/thinkst-canary.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/thinkst-canary.mdx
@@ -1,5 +1,6 @@
---
title: "Thinkst Canary Alert Integration"
+sidebarTitle: "Thinkst Canary"
description: "Send Thinkst Canary honeypot and Canarytoken incidents to Flashduty On-call through the console's generic webhook. Each incident creates one alert."
keywords: ["alert integration", "Thinkst Canary", "Canarytoken", "webhook", "honeypot", "intrusion detection"]
---
@@ -9,7 +10,6 @@ Thinkst Canary provides honeypot devices and Canarytokens. When someone touches
<div className="hide">
## In Flashduty On-call
----
Get the push URL in either of these ways.
@@ -30,7 +30,6 @@ Get the push URL in either of these ways.
</div>
## Configure Thinkst Canary
----
<Steps>
<Step title="Add a generic webhook">
@@ -53,22 +52,18 @@ The console can also post audit-trail events (`{"type":"console-audit"}`, such a
</Steps>
## Alert Key
----
Flashduty uses the incident's `IncidentHash` as the Alert Key. Canary device incidents and Canarytoken incidents both carry it, and deliveries with the same hash merge into one alert. A request without `IncidentHash` is rejected, except the test incident.
## Alert lifecycle
----
Canary only sends the incident itself; there is no recovery message. Enable [auto-close](/en/on-call/channel/create-edit) on the channel, start the timer from **Incident triggered**, and use 24 hours as a starting point, adjusted to your response process.
## Severity
----
Canary messages have no severity field. `AlertType` `CanaryIncident` (device) or `CanarytokenIncident` (token) maps to **Critical**, because any touch of a decoy is an intrusion signal. Any other value maps to **Warning**. To change this, rewrite severity with an alert processing rule on the `alert_type` or `log_type` label.
## Alert content
----
- **Title**: incident type (`Description`)
- **Description**: incident summary (`Intro`)
@@ -77,12 +72,10 @@ Canary messages have no severity field. `AlertType` `CanaryIncident` (device) or
`AdditionalDetails` (request details that may include usernames) and the Canarytoken value are not written to the alert.
## About signatures
----
The Canary generic webhook documentation does not describe request signing. Flashduty identifies the integration by the `integration_key` in the push URL.
## Troubleshooting
----
- **No alerts arrive**: confirm the webhook URL is the full push URL, the integration is enabled, and the console can reach a public address
- **Only an Info alert appears**: that is the test incident sent when saving the webhook; real incidents arrive when a device or token is triggered
diff --git a/en/on-call/integration/alert-integration/alert-sources/thousandeyes.mdx b/en/on-call/integration/alert-integration/alert-sources/thousandeyes.mdx
index b366c3c0..ba8c7d37 100644
--- a/en/on-call/integration/alert-integration/alert-sources/thousandeyes.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/thousandeyes.mdx
@@ -1,5 +1,6 @@
---
title: "ThousandEyes alert integration"
+sidebarTitle: "ThousandEyes"
description: "Send Cisco ThousandEyes alerts to Flashduty On-call through a classic webhook, and recover them automatically when the alert clears."
keywords: ["alert integration", "ThousandEyes", "Cisco ThousandEyes", "webhook", "classic webhook"]
---
@@ -9,7 +10,6 @@ Use a Cisco ThousandEyes classic webhook (the webhook you configure in an alert
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure ThousandEyes
----
Editing alert rules and webhooks requires permission to manage alert rules in ThousandEyes. Webhook alert notifications are not available in the ThousandEyes for Government instance.
@@ -42,11 +41,11 @@ Editing alert rules and webhooks requires permission to manage alert rules in Th
3. In the **Webhooks** section, click **Configure Webhooks** (**Edit webhooks** if webhooks already exist), then click **Add New Webhook**
4. Fill in the fields as follows:
-| Field | Value |
-| :--- | :--- |
-| **Name** | A recognizable name, such as `Flashduty` |
-| **URL** | The full push URL of the Flashduty integration, including `integration_key`. Paste the URL as is, not URL-encoded. ThousandEyes does not follow HTTP redirects, so use the final URL you copied |
-| **Auth Type** | Select **None**. Flashduty authenticates the request by the `integration_key` in the URL |
+ | Field | Value |
+ | :--- | :--- |
+ | **Name** | A recognizable name, such as `Flashduty` |
+ | **URL** | The full push URL of the Flashduty integration, including `integration_key`. Paste the URL as is, not URL-encoded. ThousandEyes does not follow HTTP redirects, so use the final URL you copied |
+ | **Auth Type** | Select **None**. Flashduty authenticates the request by the `integration_key` in the URL |
5. Click **Test**. **Webhook test completed successfully** means the URL is reachable
6. Save the webhook
@@ -75,7 +74,6 @@ Use this alert-rule webhook, which ThousandEyes calls a classic webhook. Do not
</Steps>
## Alert Key
----
Flashduty uses the ThousandEyes alert ID (`alert.alertId`) as the Alert Key. ThousandEyes assigns a unique `alertId` to each generated alert, and the trigger and clear notifications of one alert carry the same `alertId`, so the clear notification recovers the matching Flashduty alert.
@@ -84,7 +82,6 @@ Flashduty uses the ThousandEyes alert ID (`alert.alertId`) as the Alert Key. Tho
- The `eventId` differs on every delivery and is not part of the Alert Key. Changes to the rule name, severity, metric values, or time do not change the Alert Key either. Requests without `alert.alertId` are rejected
## Status and severity
----
The status is determined by `eventType`:
@@ -107,7 +104,6 @@ The severity is determined by the alert rule severity (`alert.severity`):
Alert rules created with **Add New Alert Rule** in ThousandEyes default to the **Info** severity, and such alerts are Info in Flashduty; the built-in Default Alert Rules default to **Minor**. For a higher severity, change the alert rule's **Severity** in ThousandEyes. A recovered alert keeps the severity it had when it triggered.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -126,7 +122,6 @@ Alert rules created with **Add New Alert Rule** in ThousandEyes default to the *
The alert title is "alert rule name: test name", or "alert rule name: agent name" for agent notifications. The alert description contains the alert condition and each agent's metrics when the alert triggered.
## Troubleshooting
----
- **Flashduty returns a parameter error**: make sure the URL is complete, not encoded, and includes `integration_key`, and that you use the classic webhook in the alert rule rather than a custom webhook
- **No alert after clicking Test**: this is expected. The test event does not create an alert; verify with a real alert
diff --git a/en/on-call/integration/alert-integration/alert-sources/tideways.mdx b/en/on-call/integration/alert-integration/alert-sources/tideways.mdx
index c7b30e73..bfdacbbf 100644
--- a/en/on-call/integration/alert-integration/alert-sources/tideways.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/tideways.mdx
@@ -1,5 +1,6 @@
---
title: "Tideways alert integration"
+sidebarTitle: "Tideways"
description: "Send Tideways response time, error rate, missing data, exception, and slow SQL notifications to Flashduty On-call through a webhook."
keywords: ["alert integration", "Tideways", "PHP", "APM", "webhook"]
---
@@ -9,7 +10,6 @@ Use the organization-level Webhook integration in Tideways to send performance a
<div className="hide">
## In Flashduty On-call
----
Get the push URL in either of the following ways.
@@ -30,7 +30,6 @@ Get the push URL in either of the following ways.
</div>
## Configure Tideways
----
You need admin permission on the organization. The Tideways webhook only accepts HTTPS URLs and sends no signature or custom headers. Flashduty identifies the integration by the `integration_key` in the push URL, so keep the URL private.
@@ -71,7 +70,6 @@ The **Preview** button on the integration page sends one `response_time` notific
</Steps>
## Alert Key
----
For response time, failure rate, and transaction response time incidents, the Alert Key is computed from the incident ID (`notification.incident_id`) together with the notification type, organization, and application. The Tideways documentation states that `status` is `opened`, `ongoing`, or `closed` depending on the incident phase; `incidient_id` is a misspelled legacy copy of `incident_id` with the same value, and Flashduty reads it when `incident_id` is missing. Incident notifications missing both are rejected, and so is an unknown `status`.
@@ -83,7 +81,6 @@ Other types use their own object:
Changes to the value, time, threshold, or occurrence count never change the Alert Key. An error group notification with status `resolved`, `not_error`, or `ignored` recovers the alert of that group. The exception rule only notifies for new, reappeared, reopened, and unacknowledged errors, so in practice a resolved group produces no notification; a reopened group merges into its existing alert.
## Status and severity
----
Tideways notifications carry no severity, so Flashduty sets it by type:
@@ -97,14 +94,12 @@ Tideways notifications carry no severity, so Flashduty sets it by type:
When `status` is `closed`, or an error group is `resolved`, `not_error`, or `ignored`, the alert recovers, and the recovery event keeps the last severity.
## When alerts do not recover
----
Transaction failure rate and missing data notifications are sent once, and Tideways sends no matching recovery, so these alerts do not recover automatically. Exception and slow SQL alerts also stay active after the error group is resolved or ignored in Tideways, because Tideways sends no notification for that.
Turn on [auto-close](/en/on-call/channel/create-edit) for the channel, with the timer starting from **Incident triggered** and a suggested duration of 24 hours. Missing data and new exceptions are normally handled within a working day. If the channel only receives response time and failure rate notifications, you can leave it off.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -117,7 +112,6 @@ Turn on [auto-close](/en/on-call/channel/create-edit) for the channel, with the
| `error_group_id` / `exception_type` / `source_location` / `occurrences` | Error group ID, exception type, source location, and total occurrences; exceptions and slow SQL only |
## Troubleshooting
----
- **Tideways shows a delivery failure**: confirm the URL uses HTTPS and includes `integration_key`. Tideways does not retry, and a response with status 400 or higher is only recorded in the integration's error log
- **Flashduty returns an invalid-parameter error**: the message names the missing field (for example `notification.incident_id`) or the unsupported `type`
diff --git a/en/on-call/integration/alert-integration/alert-sources/tracee.mdx b/en/on-call/integration/alert-integration/alert-sources/tracee.mdx
index e2efb1f4..453e36fd 100644
--- a/en/on-call/integration/alert-integration/alert-sources/tracee.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/tracee.mdx
@@ -1,5 +1,6 @@
---
title: "Aqua Tracee alert integration"
+sidebarTitle: "Aqua Tracee"
description: "Send runtime security detections from Tracee to Flashduty On-call through its webhook output destination."
keywords: ["alert integration", "Aqua Tracee", "Tracee", "eBPF", "runtime security", "webhook"]
---
@@ -9,7 +10,6 @@ Use Tracee's webhook output destination to send runtime security detections to F
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Tracee
----
<Steps>
<Step title="Add a webhook output destination">
@@ -109,7 +108,6 @@ Confirm that an active alert appears in Flashduty with `threat.name` as the titl
</Steps>
## Alert Key
----
Tracee events have no unique ID. Flashduty builds the Alert Key from the rule identity plus where the event ran (the MD5 of `"tracee"`, the rule identity and the location, separated by NUL):
@@ -123,7 +121,6 @@ Events outside a container are told apart by process ID only. Tracee events carr
</Note>
## Severity
----
In the default JSON, `threat.severity` is a number (`INFO`=0 to `CRITICAL`=4):
@@ -135,12 +132,10 @@ In the default JSON, `threat.severity` is a number (`INFO`=0 to `CRITICAL`=4):
| Empty or unknown | Warning |
## Labels
----
Flashduty sets these labels when they have a value: `rule_id`, `signature_id`, `event_name`, `category`, `threat_severity`, `mitre_tactic`, `mitre_technique_id`, `mitre_technique`, `container_id`, `container_name`, `image`, `pod`, `namespace`, `process`, `executable`, `pid`, `host_pid`, `policies`, `detected_from`. The event's `data` array (file paths, command arguments and so on) is never copied into labels.
## Troubleshooting
----
- **Tracee logs `Error sending webhook, http status`**: confirm the URL is complete and includes `integration_key`
- **No alerts arrive**: confirm the event carries a `threat` field; ordinary events create no alert, and the stream's `events` must include the detection event
diff --git a/en/on-call/integration/alert-integration/alert-sources/trigger-dev.mdx b/en/on-call/integration/alert-integration/alert-sources/trigger-dev.mdx
index e1c7aefe..1bbdbc61 100644
--- a/en/on-call/integration/alert-integration/alert-sources/trigger-dev.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/trigger-dev.mdx
@@ -1,5 +1,6 @@
---
title: "Trigger.dev alert integration"
+sidebarTitle: "Trigger.dev"
description: "Send failed task runs, error groups, and deployment failures from Trigger.dev to Flashduty On-call through the webhook alert channel."
keywords: ["alert integration", "Trigger.dev", "webhook", "background jobs", "deployment failure"]
---
@@ -13,7 +14,6 @@ Use the webhook alert channel of Trigger.dev to send failed task runs, error gro
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of the following ways.
@@ -34,7 +34,6 @@ You can get the push URL in either of the following ways.
</div>
## In Trigger.dev
----
Webhook channels are created per project and environment. On Trigger.dev cloud, the free plan includes 1 alert channel (webhook, email, and Slack combined). Once the plan's quota is used, upgrade or delete an existing channel.
@@ -67,14 +66,12 @@ The Trigger.dev alert channel has no test button. Trigger a task run that fails
Trigger.dev generates a signing secret for each webhook channel and sends the signature in the `x-trigger-signature-hmacsha256` header. Flashduty does not verify this signature; access is controlled by the `integration_key` in the push URL.
## Failed runs and error groups do not recover
----
These two alert types have no recovery notification. In the channel that receives this integration, turn on [auto-close](/en/on-call/channel/create-edit). We suggest 12 hours for failed runs and 24 hours for error groups; adjust to how quickly your team handles failed tasks. Each failed run is a separate alert. When an error group is pushed again after being marked resolved (or after its ignore condition is breached), it updates the same alert; if that alert was closed, a new alert is created.
Trigger.dev sends an error group alert only when its status changes: a group that is Unresolved is not pushed again. To be told about every failed run, use the run failure alert.
## Alert Key
----
| Event type | Alert Key |
| :--- | :--- |
@@ -85,7 +82,6 @@ Trigger.dev sends an error group alert only when its status changes: a group tha
The top-level `id` of the request is a per-delivery ID and is not part of the Alert Key. A deployment's `deployment.id` is different for every deployment, so failures and successes are tied together by environment: a successful deployment recovers the deployment failure alert of the same environment. Changes to the title, error message, occurrence count, or `classification` never change the Alert Key. Events missing these fields are rejected, and so is a `type` outside the table above.
## Status and severity
----
| Event type | Status | Flashduty severity |
| :--- | :--- | :--- |
@@ -97,7 +93,6 @@ The top-level `id` of the request is a per-delivery ID and is not part of the Al
Trigger.dev alerts carry no severity, so every failure event is treated as Critical.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -114,7 +109,6 @@ Trigger.dev alerts carry no severity, so every failure event is treated as Criti
| `organization` / `project` / `project_ref` | Organization name, project name, and project reference |
## Troubleshooting
----
- **Flashduty receives no events**: a run failure alert is sent only after the task's retries are exhausted. Make sure the channel was created in the environment where the failure happened and has the matching alert type selected. Trigger.dev requires a webhook URL that is reachable from the public internet
- **Flashduty returns an invalid parameter error**: make sure the request body contains `type` and `object` (in real deliveries `webhookVersion` is `v1` for run and deployment events and `2025-01-01` for error group events) and that only the supported alert types above are selected. The legacy webhook channel posts a body without `type` and `object`, which is not supported; delete it and create the channel again
diff --git a/en/on-call/integration/alert-integration/alert-sources/trivy-operator.mdx b/en/on-call/integration/alert-integration/alert-sources/trivy-operator.mdx
index 92691f2a..5ffaab63 100644
--- a/en/on-call/integration/alert-integration/alert-sources/trivy-operator.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/trivy-operator.mdx
@@ -1,5 +1,6 @@
---
title: "Trivy Operator Alert Integration"
+sidebarTitle: "Trivy Operator"
description: "Send vulnerability, exposed secret and config audit reports from Aqua Trivy Operator to Flashduty On-call through its webhook broadcast."
keywords: ["alert integration", "Trivy Operator", "Aqua Security", "Trivy", "Kubernetes", "vulnerability scanning", "container security", "webhook"]
---
@@ -9,7 +10,6 @@ Trivy Operator, Aqua Security's open-source Kubernetes scanner, stores scan resu
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Trivy Operator
----
You need permission to change the Trivy Operator deployment, and the operator must be able to reach the Flashduty push URL over HTTPS.
@@ -66,14 +65,12 @@ Trivy Operator has no test button. After the operator finishes a scan, check Fla
</Steps>
## Alert Key
----
Flashduty uses the UID of the report object (`metadata.uid` in the request body) as the Alert Key. The operator re-sends the same object when a report changes, the UID stays the same, and the pushes merge into one alert. Different workloads, containers and report types have different UIDs and do not affect each other. When a workload is recreated or a report object is deleted and generated again, it gets a new UID and opens a new alert.
Changes to the report name, image tag, scanner version or summary counts do not change the Alert Key. Requests without `metadata.uid` are rejected. A request body larger than 4 MiB is rejected with a parameter error; the description lists at most the 10 most severe findings, so a large report does not enlarge the alert.
## Status and severity
----
Flashduty maps severity from the counts in `report.summary`:
@@ -89,7 +86,6 @@ When the same report object is pushed again with all counts at 0, its alert reco
Reports without a severity summary (SBOM and compliance reports) and deleted-report messages are acknowledged without creating an alert.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -107,7 +103,6 @@ Reports without a severity summary (SBOM and compliance reports) and deleted-rep
The description holds the summary counts and the 10 most severe findings. For exposed secrets only the rule ID and file path are listed, never the matched text. View the full report with `kubectl get vulnerabilityreports -n <namespace> -o yaml`.
## Troubleshooting
----
- **No alerts arrive**: confirm `operator.webhookBroadcastURL` took effect (check `OPERATOR_WEBHOOK_BROADCAST_URL` on the operator pod) and that the operator log shows no push errors. The operator does not check the response status and does not retry a failed request
- **An alert does not recover**: the operator sends no "resolved" notification. An alert recovers only when the report is scanned again with an all-zero summary, so turn on channel auto-close for the rest
diff --git a/en/on-call/integration/alert-integration/alert-sources/twilio.mdx b/en/on-call/integration/alert-integration/alert-sources/twilio.mdx
index 7c0001a3..64379efc 100644
--- a/en/on-call/integration/alert-integration/alert-sources/twilio.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/twilio.mdx
@@ -1,5 +1,6 @@
---
title: "Twilio alert integration"
+sidebarTitle: "Twilio"
description: "Send Error-level events from the Twilio Debugger to Flashduty On-call through the Error webhook. Events with the same error code on the same account merge into one alert."
keywords: ["alert integration", "Twilio", "Debugger", "Error webhook", "error code", "webhook"]
---
@@ -14,7 +15,6 @@ The Error webhook is available in every Twilio region (US1, IE, and AU).
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -35,7 +35,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Twilio
----
<Steps>
<Step title="Set the Error webhook">
@@ -65,7 +64,6 @@ Debugger events are one-time log entries. Twilio sends nothing when an error sto
</Steps>
## Payload
----
Twilio sends one Debugger event per request. The body is `application/x-www-form-urlencoded`, and `Payload` is JSON:
@@ -86,7 +84,6 @@ Twilio sends one Debugger event per request. The body is `application/x-www-form
Every alert also carries the label `source=twilio`, and its description links to the error code in the Twilio error dictionary (`https://www.twilio.com/docs/errors/<error code>`). Example title: `Twilio error 11200: An attempt to retrieve content from https://app.example.com/voice returned the HTTP status code 404`.
## Alert Key
----
Flashduty computes the Alert Key from `AccountSid` and `Payload.error_code`, not from the event ID `Sid`:
@@ -95,7 +92,6 @@ Flashduty computes the Alert Key from `AccountSid` and `Payload.error_code`, not
- This matches how Twilio [Alarms](https://www.twilio.com/docs/usage/troubleshooting/alarms) count errors per account and per error code
## Status and severity
----
| Twilio event level | Flashduty status or severity |
| :--- | :--- |
@@ -105,7 +101,6 @@ Flashduty computes the Alert Key from `AccountSid` and `Payload.error_code`, not
An Error event is rejected if it lacks `AccountSid` or `Payload.error_code`, or if `Payload` is not valid JSON.
## FAQ
----
<AccordionGroup>
<Accordion title="Why don't Warning events create alerts?">
@@ -128,7 +123,6 @@ No. Flashduty identifies the integration by the `integration_key` in the push UR
</AccordionGroup>
## Troubleshooting
----
- **Errors appear in the Twilio Debugger but not in Flashduty**: make sure the URL under **Monitor** → **Error webhook** is complete (including `integration_key`) and that the event level is Error
- **Requests are rejected (4xx)**: make sure the push URL belongs to a Twilio integration, not another integration
diff --git a/en/on-call/integration/alert-integration/alert-sources/twingate.mdx b/en/on-call/integration/alert-integration/alert-sources/twingate.mdx
index 8ceb6eac..4704e046 100644
--- a/en/on-call/integration/alert-integration/alert-sources/twingate.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/twingate.mdx
@@ -1,5 +1,6 @@
---
title: "Twingate alert integration"
+sidebarTitle: "Twingate"
description: "Send Twingate connector offline, events sync and integration errors, and key expiration notifications to Flashduty On-call through notification webhooks. Alerts close automatically when a recoverable notification arrives."
keywords: ["alert integration", "Twingate", "zero trust", "Connector", "webhook"]
---
@@ -9,7 +10,6 @@ Twingate Admin Console notifications can be delivered to a webhook. This integra
<div className="hide">
## In Flashduty On-call
----
Get the push URL in either of the following ways.
@@ -30,7 +30,6 @@ Get the push URL in either of the following ways.
</div>
## Configure Twingate
----
<Steps>
<Step title="Add a webhook">
@@ -51,7 +50,6 @@ Click **Test Payload** next to a notification and Twingate sends a sample notifi
<Note>Twingate notification webhooks carry no signature header and need no secret. The `integration_key` in the push URL acts as the credential; do not publish it.</Note>
## Alert Key
----
Twingate notifications carry no alert ID, so Flashduty builds the Alert Key from the tenant (`tenant`) and the notification group:
@@ -71,7 +69,6 @@ Changes to the message, timestamp, `days_remaining`, or `table` never change the
These notifications create no alert and Flashduty returns success: `CLIENT_UPDATE_RECOMMENDED`, `CLIENT_UPDATE_REQUIRED`, `CONNECTOR_UPGRADE_AVAILABLE`.
## Severity
----
Twingate notifications have no severity field, so Flashduty sets it from the type:
@@ -84,19 +81,16 @@ Twingate notifications have no severity field, so Flashduty sets it from the typ
A recovery notification keeps the severity of the notification it closes.
## Alert content
----
- **Title**: the notification `message`; `Twingate <type>` when absent
- **Description**: the access request `reason` and the key-value pairs of every `table` row (at most 20 rows; fields whose name contains key, token, or secret are left out)
- **Labels**: `tenant`, `type`, `check` (notification group), `integration`, `sync_type`, `platform`, `days_remaining`, `request_id`, `user_name`, `resource_name`, `approval_mode`, `request_type`
## Notifications that do not recover
----
Key and token expiration, Google Workspace sync errors, and access requests are one-shot: Twingate sends no recovery. Turn on [auto-close](/en/on-call/channel/create-edit) for the channel, with 24 hours as a suggested duration. Repeated notifications for the same object merge into one alert.
## Troubleshooting
----
- **Twingate reports a webhook error**: the receiver must accept POST with JSON. Confirm you entered the full push URL including `integration_key`
- **The alert did not close after the connector came back**: confirm the Connectors online notification is selected. Flashduty matches the online notification by remote network plus connector name; after a connector is renamed, close the alert under the old name manually
diff --git a/en/on-call/integration/alert-integration/alert-sources/ucloud-cloudwatch.mdx b/en/on-call/integration/alert-integration/alert-sources/ucloud-cloudwatch.mdx
index 6ce04bc8..db971b1c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/ucloud-cloudwatch.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/ucloud-cloudwatch.mdx
@@ -1,50 +1,51 @@
---
title: "UCloud CloudWatch Alert Integration"
+sidebarTitle: "UCloud CloudWatch"
description: "Sync UCloud CloudWatch alert events to Flashduty via webhook for automated alert noise reduction"
keywords: ["UCloud", "CloudWatch", "alert integration", "webhook", "cloud monitoring"]
---
-Sync Ucloud CloudWatch alert events to Flashduty via webhook for automated alert noise reduction.
+Sync UCloud CloudWatch alert events to Flashduty via webhook for automated alert noise reduction.
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels - it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
- 3. Choose **Ucloud CloudWatch** integration and click **Save** to generate a card
+ 3. Choose **UCloud CloudWatch** integration and click **Save** to generate a card
4. Click the generated card to view the **Push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event payload.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
- 2. Select **Ucloud CloudWatch** integration:
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
+ 2. Select **UCloud CloudWatch** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
-## In Ucloud
----
+## In UCloud
### Step 1: Configure Notice Template
@@ -56,7 +57,7 @@ Choose this method when you need to route alerts to different channels based on
6. Configure other options as needed.
7. Click `Submit` to complete the configuration.
-
+
### Step 2: Configure Alert Policy
1. Login to your Ucloud console, search for `CloudWatch` product, and enter the corresponding product console.
@@ -67,5 +68,4 @@ Choose this method when you need to route alerts to different channels based on
## Severity Mapping
----
-Currently, all Ucloud CloudWatch alert events pushed to Flashduty have a severity of Warning. You can customize the severity through [Alert Processing Pipeline](https://docs.flashduty.com/en/on-call/integration/alert-integration/alert-pipelines).
+Currently, all UCloud CloudWatch alert events pushed to Flashduty have a severity of Warning. You can customize the severity through [Alert Processing Pipeline](/en/on-call/integration/alert-integration/alert-pipelines).
diff --git a/en/on-call/integration/alert-integration/alert-sources/updown.mdx b/en/on-call/integration/alert-integration/alert-sources/updown.mdx
index 1cbb5afc..39745aec 100644
--- a/en/on-call/integration/alert-integration/alert-sources/updown.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/updown.mdx
@@ -1,5 +1,6 @@
---
title: "updown.io alert integration"
+sidebarTitle: "updown.io"
description: "Send updown.io down, recovery, SSL certificate, and performance drop notifications to Flashduty On-call through a webhook."
keywords: ["alert integration", "updown.io", "Updown", "Uptime", "webhook", "SSL", "check.down", "check.up"]
---
@@ -9,7 +10,6 @@ Use an updown.io webhook to send check down (`check.down`), recovery (`check.up`
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure updown.io
----
<Steps>
<Step title="Add a webhook URL">
@@ -51,7 +50,6 @@ Make a check actually go down (for example, create one that points to an unreach
</Steps>
## Payload
----
updown.io POSTs a JSON array of events (one request can carry several). Flashduty parses it directly, with no template to configure:
@@ -72,7 +70,6 @@ updown.io POSTs a JSON array of events (one request can carry several). Flashdut
Event types that updown.io adds later are ignored and acknowledged, and create no alert.
## Alert Key
----
- Down and recovery: the Alert Key is `check.token`. `check.down` and `check.up` of one check carry the same `check.token`, so they land on one alert; different checks produce different alerts. Renaming the check or a change in status code or error text does not change the Alert Key.
- Invalid certificate: `check.token` plus `:ssl_invalid`, recovered by `check.ssl_valid`.
@@ -82,7 +79,6 @@ Event types that updown.io adds later are ignored and acknowledged, and create n
Each event family has its own Alert Key, so a check recovering does not close its certificate or performance alert. An event without `check.token` cannot be matched to its recovery, so Flashduty skips it and still processes the other valid events in the same request; a parameter error is returned only when no event in the request is valid.
## Status and severity
----
updown.io notifications carry no severity.
@@ -97,12 +93,10 @@ updown.io notifications carry no severity.
| `check.performance_drop` | Warning |
## One-shot alerts need auto-resolve
----
A performance drop (`check.performance_drop`) has no matching close notification, so these alerts do not recover automatically. Turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit) and set it to 6 hours, or close the alert by hand.
## FAQ
----
<AccordionGroup>
<Accordion title="Does the test webhook create an alert?">
@@ -119,7 +113,6 @@ No. Notices for one check carry the same `check.token` and merge into one alert.
</AccordionGroup>
## Troubleshooting
----
- **updown.io reports a failed delivery**: confirm the webhook URL is the complete push URL and includes `integration_key`
- **Flashduty returns a parameter error**: confirm the body is an updown.io JSON array and its events have a non-empty `check.token` (events without one are skipped; an error is returned only when none is valid)
diff --git a/en/on-call/integration/alert-integration/alert-sources/upguard.mdx b/en/on-call/integration/alert-integration/alert-sources/upguard.mdx
index 69dd7e85..b4b97a4b 100644
--- a/en/on-call/integration/alert-integration/alert-sources/upguard.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/upguard.mdx
@@ -1,5 +1,6 @@
---
title: "UpGuard Alert Integration"
+sidebarTitle: "UpGuard"
description: "Send UpGuard risk notifications, such as security score drops and new data leaks, to Flashduty On-call through a webhook integration."
keywords: ["alert integration", "UpGuard", "webhook", "security score", "data leak", "vendor risk", "attack surface"]
---
@@ -9,7 +10,6 @@ UpGuard is a third-party risk and attack surface management platform. Create a w
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the push URL in either of the following ways.
</div>
## Configure in UpGuard
----
<Steps>
<Step title="Add a webhook integration">
@@ -81,24 +80,20 @@ Turn on [auto-close](/en/on-call/channel/create-edit) in the channel that receiv
</Steps>
## Event types
----
| Payload | Effect in Flashduty |
| :--- | :--- |
| A notification from any trigger | Opens one alert with severity Warning |
## Alert Key
----
Flashduty uses `notification.id` as the Alert Key: notifications with different ids open different alerts, and a redelivery with the same id merges into the same alert. A request without `notification.id` is rejected. UpGuard's documentation does not state the scope of that id's uniqueness, so before going live, confirm with the test message and one real trigger that two notifications carry different `id` values.
## Status and severity
----
UpGuard notifications carry no severity, so every notification opens as Warning. To tell them apart, adjust the severity in the channel's alert processing rules using the `notification_type` label.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -112,14 +107,12 @@ UpGuard notifications carry no severity, so every notification opens as Warning.
The alert title is the `description` (for example `The score for 'Example Company' dropped below 600 with a score of 599`), or the notification type when it is empty.
## Notes
----
- UpGuard notifications can carry breach and identity data. Keep the template to the fields listed above and do not add credentials or personal data
- UpGuard sends requests from a fixed set of IP addresses, listed in [webhook-ips.json](https://cdn.cyber-risk.upguard.com/webhook-ips.json). Allow them if an IP allowlist sits in front of Flashduty
- If `description` contains a double quote, the rendered JSON is invalid and the request is rejected as a parameter error
## Troubleshooting
----
- **Flashduty receives nothing**: confirm the webhook destination is complete, includes `integration_key`, and the integration is enabled
- **Parameter error**: a missing `notification.id` means the template dropped `id`; an invalid JSON message means a string field is not quoted
diff --git a/en/on-call/integration/alert-integration/alert-sources/uptime-com.mdx b/en/on-call/integration/alert-integration/alert-sources/uptime-com.mdx
index cebec1be..714aeeb1 100644
--- a/en/on-call/integration/alert-integration/alert-sources/uptime-com.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/uptime-com.mdx
@@ -1,5 +1,6 @@
---
title: "Uptime.com alert integration"
+sidebarTitle: "Uptime.com"
description: "Send Uptime.com check downtime and recovery to Flashduty On-call through the Custom Postback URL (Webhook)."
keywords: ["alert integration", "Uptime.com", "Custom Postback URL", "webhook", "uptime monitoring"]
---
@@ -9,7 +10,6 @@ Use the Uptime.com Custom Postback URL (Webhook) to send check alerts to Flashdu
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Uptime.com
----
<Steps>
<Step title="Create a Custom Postback URL integration">
@@ -68,14 +67,12 @@ When a check fails, Uptime.com uses the check's **Sensitivity** (how many probe
</Tip>
## Alert Key
----
Flashduty computes the Alert Key from `data.service.id`, the Uptime.com check ID. The `alert_raised` and `alert_cleared` messages of a check carry the same `data.service.id`, so they land on the same alert. Repeat notifications during an ongoing outage merge into that alert as well.
`data.alert.id` identifies a detection record from one probe location and changes on recovery, so it is not part of the Alert Key. Changes to the check name, tags, state, output, timestamps, or failing locations do not change the Alert Key. A request without `data.service.id` is rejected, because its recovery could not be matched.
## Status and severity
----
| Uptime.com `event` | Flashduty handling |
| :--- | :--- |
@@ -96,7 +93,6 @@ Severity comes from `data.alert.state`:
Recovery events keep the original alert severity.
## Alert content
----
- **Title**: the check's `display_name`, or `name` when it is empty
- **Description**: `data.alert.output`, or `data.alert.short_output` when it is empty
@@ -105,7 +101,6 @@ Recovery events keep the original alert severity.
The push URL and custom headers in `data.integration` are never written to labels.
## Troubleshooting
----
- **The integration shows an error or Uptime.com fails to deliver**: confirm that the URL is the full push URL and includes `integration_key`
- **Flashduty returns a parameter error**: confirm that the request contains `event` and `data.service.id`. This integration accepts only the Custom Postback URL JSON format
diff --git a/en/on-call/integration/alert-integration/alert-sources/uptime-kuma.mdx b/en/on-call/integration/alert-integration/alert-sources/uptime-kuma.mdx
index db3707d4..253ff903 100644
--- a/en/on-call/integration/alert-integration/alert-sources/uptime-kuma.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/uptime-kuma.mdx
@@ -1,5 +1,6 @@
---
title: "Uptime Kuma Integration"
+sidebarTitle: "Uptime Kuma"
description: "Sync Uptime Kuma alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,43 +9,43 @@ Sync Uptime Kuma alert events to Flashduty via webhook for automated alert noise
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this simpler option when you don't need to route alert events to different channels.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Select **Uptime Kuma** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this option when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Uptime Kuma** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Uptime Kuma
----
**Step 1: Set up Notification Channel**
@@ -70,7 +71,6 @@ Choose this option when you need to route alerts to different channels based on
</div>
## Status Mapping
----
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/uptimeobserver.mdx b/en/on-call/integration/alert-integration/alert-sources/uptimeobserver.mdx
index 4c5cf455..1b691993 100644
--- a/en/on-call/integration/alert-integration/alert-sources/uptimeobserver.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/uptimeobserver.mdx
@@ -1,5 +1,6 @@
---
title: "UptimeObserver alert integration"
+sidebarTitle: "UptimeObserver"
description: "Send UptimeObserver incident and resolution webhooks to Flashduty On-call."
keywords: ["alert integration", "UptimeObserver", "webhook", "uptime monitoring", "incident_id"]
---
@@ -9,14 +10,12 @@ Use UptimeObserver webhooks to send monitor incidents to Flashduty On-call. Each
<div className="hide">
## In Flashduty On-call
----
Create either a dedicated or shared **UptimeObserver** alert integration and copy its complete Push URL.
</div>
## Configure UptimeObserver
----
UptimeObserver has no fixed webhook payload; the body comes from the template you enter. Flashduty parses only the two templates below, so create two webhooks: one for incidents and one for resolutions.
@@ -79,14 +78,12 @@ Make the monitored endpoint genuinely unreachable and confirm Flashduty shows an
</Steps>
## Alert Key
----
Flashduty uses `incident_id` (`__INCIDENT_ID__`) as the Alert Key. UptimeObserver documents it as the numeric incident identifier and uses it in both its incident and resolution example templates. The documentation does not state outright that the two webhooks carry the same value for one incident, so this is inferred; verify it with a real outage when you first set up the integration.
`monitor_id` is stored only as a label. Changes to the monitor name, root cause, or `incident_status` do not change the Alert Key. The next outage of the same monitor is a new incident and therefore a new alert.
## Status and severity
----
| `event_type` | Flashduty status or severity |
| :--- | :--- |
@@ -96,7 +93,6 @@ Flashduty uses `incident_id` (`__INCIDENT_ID__`) as the Alert Key. UptimeObserve
An empty or unknown `event_type` is rejected. An empty object `{}` returns 200 and creates no alert.
## Troubleshooting
----
- **UptimeObserver reports a non-2xx response**: confirm the URL is complete and includes `integration_key`
- **Flashduty returns an invalid-parameter error**: confirm the body is valid JSON. UptimeObserver substitutes `__INCIDENT_ROOT_CAUSE__` and the monitor name as raw text, so a double quote in either can break the JSON; remove the `root_cause` field or avoid quotes in monitor names
diff --git a/en/on-call/integration/alert-integration/alert-sources/uptimerobot.mdx b/en/on-call/integration/alert-integration/alert-sources/uptimerobot.mdx
index c5ed8fc2..b9a216c7 100644
--- a/en/on-call/integration/alert-integration/alert-sources/uptimerobot.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/uptimerobot.mdx
@@ -1,5 +1,6 @@
---
title: "UptimeRobot alert integration"
+sidebarTitle: "UptimeRobot"
description: "Send UptimeRobot Monitor down and up notifications to Flashduty On-call through a webhook."
keywords: ["alert integration", "UptimeRobot", "Monitor", "webhook", "uptime monitoring"]
---
@@ -13,7 +14,6 @@ UptimeRobot offers webhook integrations only on the Team plan and higher paid pl
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -34,7 +34,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure UptimeRobot
----
<Steps>
<Step title="Add a webhook integration">
@@ -100,14 +99,12 @@ On the Monitor details page, click **Test Notification** and select the webhook.
</Steps>
## Alert Key
----
Flashduty uses `*monitorID*` (the `monitor_id` field) as the Alert Key. UptimeRobot includes the same Monitor ID in both Down and Up notifications, so a Monitor's outage, repeated reminders, and recovery land on one alert, and different Monitors produce different alerts.
Changes to the Monitor name, URL, alert details, HTTP status code, or timestamps do not change the Alert Key. A Monitor that is deleted and recreated gets a new Monitor ID and is no longer linked to its old alerts.
## Status and severity
----
| UptimeRobot `*alertType*` | Meaning | Flashduty status or severity |
| :--- | :--- | :--- |
@@ -120,13 +117,11 @@ An empty or other `alert_type` is rejected so that an ambiguous request cannot e
SSL certificate and domain expiry reminders have no matching recovery notification. Each reminder creates a separate Warning alert that does not recover automatically, so close it manually once handled.
## Delivery
----
- UptimeRobot sends Down and Up notifications once. It does not retry after a timeout, a connection error, or a non-2xx response. If an Up notification is lost, the matching alert stays active until you close it manually
- Recurring notifications configured on a Monitor resend the Down notification with the same Monitor ID, and Flashduty merges them into the existing alert
## Troubleshooting
----
- **Flashduty reports an invalid parameter**: verify that **Send as JSON (application/json)** is checked, the POST value is valid JSON, and `monitor_id` and `alert_type` are unchanged
- **JSON parsing fails**: check whether the Monitor name or alert details contain double quotes or backslashes, which can make the rendered POST value invalid JSON
diff --git a/en/on-call/integration/alert-integration/alert-sources/uptimia.mdx b/en/on-call/integration/alert-integration/alert-sources/uptimia.mdx
index 3588652a..862db216 100644
--- a/en/on-call/integration/alert-integration/alert-sources/uptimia.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/uptimia.mdx
@@ -1,5 +1,6 @@
---
title: "Uptimia alert integration"
+sidebarTitle: "Uptimia"
description: "Send Uptimia monitor down and up notifications to Flashduty On-call through a webhook contact."
keywords: ["alert integration", "Uptimia", "Uptime", "webhook", "monitoring", "downtime"]
---
@@ -9,7 +10,6 @@ Use an Uptimia webhook integration to send monitor down (`down`) and recovery (`
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Uptimia
----
<Steps>
<Step title="Create a webhook integration">
@@ -60,7 +59,6 @@ The request sent by **Actions → Test** in Uptimia's integration list (`monitor
</Note>
## Payload
----
Uptimia POSTs a fixed set of 11 fields as `application/json`. Flashduty parses them directly, with no template to configure:
@@ -81,14 +79,12 @@ Uptimia POSTs a fixed set of 11 fields as `application/json`. Flashduty parses t
When alert groups are enabled, Uptimia adds a `group` object on top of the same 11 fields (the fields describe the first failed monitor in the group). Flashduty processes the 11 fields and stores `group.id` and `group.size` as labels `group_id` and `group_size`.
## Alert Key
----
Flashduty uses `monitor_type` together with `id` as the Alert Key. Uptimia numbers `id` separately within each monitor type, so it must be paired with `monitor_type`; the payload has no incident ID. Down, severity change, repeated notification, and recovery for one monitor carry the same two fields and land on the same alert. Renaming the monitor or changing its note, severity, or times does not change the Alert Key.
If `monitor_type` or `id` is missing, Flashduty returns a parameter error, because a recovery could not be matched reliably to its alert.
## Status and severity
----
| Uptimia fields | Flashduty status or severity |
| :--- | :--- |
@@ -100,7 +96,6 @@ If `monitor_type` or `id` is missing, Flashduty returns a parameter error, becau
Requests whose `monitor_status` is empty or any other value are rejected, so a request with an unknown state never enters the wrong alert lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="Do duplicate deliveries create several Flashduty alerts?">
@@ -123,7 +118,6 @@ That message only means Uptimia sent the request. Check that the Webhook URL is
</AccordionGroup>
## Troubleshooting
----
- **Uptimia reports a failed delivery**: confirm the Webhook URL is the full push URL. Flashduty returns 2xx on success
- **Flashduty returns a parameter error**: confirm the body contains `monitor_type` and `id`, and that `monitor_status` is `down` or `up`
diff --git a/en/on-call/integration/alert-integration/alert-sources/uptrends.mdx b/en/on-call/integration/alert-integration/alert-sources/uptrends.mdx
index ce1c0b32..e6bf81f0 100644
--- a/en/on-call/integration/alert-integration/alert-sources/uptrends.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/uptrends.mdx
@@ -1,5 +1,6 @@
---
title: "Uptrends alert integration"
+sidebarTitle: "Uptrends"
description: "Send Uptrends monitoring alerts to Flashduty On-call through an Uptrends custom integration. Alerts close automatically when the monitor recovers."
keywords: ["alert integration", "Uptrends", "custom integration", "webhook", "website monitoring", "synthetic monitoring"]
---
@@ -9,7 +10,6 @@ Uptrends pushes alerts through a **custom integration** (Uptrends integration):
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Uptrends
----
The steps below need an Uptrends user who can manage **Integrations** and **Alert definitions**.
@@ -103,7 +102,6 @@ Make a monitor fail (for example, temporarily point an HTTPS monitor to a path t
</Steps>
## Alert Key
----
Flashduty uses `incident_key` (`{{@incident.key}}`) as the Alert Key. Uptrends documents that the error alert and the Ok alert of one incident share the same incident key and that each new incident gets a new key, so the error, reminder, and recovery messages all land on the same Flashduty alert. A new failure after the monitor recovers opens a new alert.
@@ -112,7 +110,6 @@ Changes to the monitor name, error description, checkpoint, or alert definition
Flashduty rejects a request that lacks `incident_key` or `alert_type`, or in which either field is still an unrendered `{{@...}}` variable.
## Alert lifecycle
----
Flashduty handles each message by its `alert_type` field (`{{@alert.type}}`, case-insensitive):
@@ -125,12 +122,10 @@ Flashduty handles each message by its `alert_type` field (`{{@alert.type}}`, cas
Any other value is rejected.
## Severity
----
Uptrends alerts carry no severity, so every alert is **Critical** by default. For another severity, append `&severity=Warning` (or `Info`) to the push URL. A recovery event keeps the severity of the original alert.
## Alert content
----
- **Title**: the monitor name, or `Uptrends incident <incident_key>` when the monitor name is missing
- **Description**: the error description (`{{@alert.description}}`), which includes the failing step number for multi-step monitors
@@ -139,7 +134,6 @@ Uptrends alerts carry no severity, so every alert is **Critical** by default. Fo
Empty fields are not written as labels.
## Troubleshooting
----
- **The test alert fails**: Make sure **ApiUrl** is the full push URL, including the `integration_key` parameter, and that **Method** is `POST`
- **Flashduty reports that the body is not valid JSON**: Make sure the request body matches the template and the text fields use `@JsonEncode`
diff --git a/en/on-call/integration/alert-integration/alert-sources/veeam-one.mdx b/en/on-call/integration/alert-integration/alert-sources/veeam-one.mdx
index 6c5b6c18..811b1830 100644
--- a/en/on-call/integration/alert-integration/alert-sources/veeam-one.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/veeam-one.mdx
@@ -1,5 +1,6 @@
---
title: "Veeam ONE alert integration"
+sidebarTitle: "Veeam ONE"
description: "Veeam ONE sends alarm notifications by email; use a Flashduty email integration with rules to trigger and close Veeam ONE alerts."
keywords: ["alert integration", "Veeam ONE", "Veeam", "email", "backup monitoring"]
---
@@ -9,7 +10,6 @@ Veeam ONE sends alarm notifications only by email (plus SNMP, syslog and scripts
<div className="hide">
## In Flashduty On-call
----
Get the integration email address in either of the two ways below. **In both cases choose the Email integration type**, not Veeam ONE.
@@ -30,7 +30,6 @@ Get the integration email address in either of the two ways below. **In both cas
</div>
## Configure push rules in Flashduty
----
Veeam ONE emails carry no alarm ID. An alarm is identified by its alarm name plus the object, and the rules extract these two parts from the email title as the Alert Key. Trigger and resolve emails yield the same key, so a resolve email closes the matching alert.
@@ -71,7 +70,6 @@ The close rules come before the trigger rules. Rules 1 and 3 match subject templ
The default rule discards unmatched mail so that summary emails (see [Limitations](#limitations)) don't create alerts that can never close on their own. If you changed the subject template and don't want to lose any email, set the default rule to **create new alert** instead; alerts created that way from the email title do not resolve automatically.
## Configure Veeam ONE
----
The paths below are for Veeam ONE v13, all in the Veeam ONE Client.
@@ -82,7 +80,6 @@ The paths below are for Veeam ONE v13, all in the Veeam ONE Client.
5. **Email format**: HTML or Plain Text both work; the rules read only the email title
## Email title format
----
The title of a Mission Critical email comes from **Email subject template** under **Notification Policy** → **Mission Critical** → **Edit template**. The default has two forms depending on the version:
@@ -102,7 +99,6 @@ Values of `%STATUS%`:
If you change the subject template, update the regexes in the rules to match. You can also set the subject explicitly to template A in **Edit template**; then only rules 1 and 3 are needed.
## Limitations
----
- **Manual resolve**: resolving an alarm manually in Veeam ONE sends a summary email (title `Alarm resolve notification`) that can list several alarms. The rules cannot close them one by one, so the email is discarded by the default rule. Close these alerts manually in Flashduty, or turn on the [auto-resolve timeout](/en/on-call/channel/create-edit) in the channel that receives this integration; 24 hours is a reasonable start.
- **Acknowledge and summary emails**: acknowledgements (`Alarm acknowledgement notification`) and the Other policy's summaries (`Alarm summary notification`) are also summary emails and are discarded by the default rule.
diff --git a/en/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console.mdx b/en/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console.mdx
index b4820c02..9661d0b7 100644
--- a/en/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console.mdx
@@ -1,5 +1,6 @@
---
title: "Veeam Service Provider Console alert integration"
+sidebarTitle: "Veeam Service Provider Console"
description: "Veeam Service Provider Console sends alarm notifications by email; use a Flashduty email integration with rules to trigger VSPC alerts."
keywords: ["alert integration", "Veeam Service Provider Console", "VSPC", "Veeam", "email", "backup monitoring"]
---
@@ -9,7 +10,6 @@ Veeam Service Provider Console (VSPC) sends alarm notifications by email. The Fl
<div className="hide">
## In Flashduty On-call
----
Get the integration email address in either of the two ways below. **In both cases choose the Email integration type**, not Veeam Service Provider Console.
@@ -30,7 +30,6 @@ Get the integration email address in either of the two ways below. **In both cas
</div>
## Configure push rules in Flashduty
----
VSPC emails carry no alarm ID. The subject format below puts the company, location and alarm name in the title, and the rule extracts these three parts as the Alert Key. Emails with the same company, location and alarm name merge into one alert. The alarm status is not part of the Alert Key, so when an alarm changes from Warning to Error the existing alert is updated instead of a new one being created.
@@ -48,7 +47,6 @@ Regex: /^VSPC (?:Error|Warning) \| (.+) \| (.+) \| (.+)$/
The default rule discards unmatched mail so that emails with the Information status don't create alerts.
## Configure Veeam Service Provider Console
----
The paths below come from the VSPC documentation and require administrator rights.
@@ -56,21 +54,20 @@ The paths below come from the VSPC documentation and require administrator right
2. **Notification frequency**: in the **Alarms** section, set the frequency slider to **Emails on every event**. **Summary emails only** sends a daily digest, which the rules cannot process one alarm at a time
3. **Subject**: in the **Alarms** section, set **Subject** to:
-```
-VSPC %alarmStatus% | %company% | %location% | %alarmName%
-```
+ ```
+ VSPC %alarmStatus% | %company% | %location% | %alarmName%
+ ```
-`%alarmStatus%`, `%company%`, `%location%` and `%alarmName%` are the variables VSPC supports in alarm notification subjects. A rendered subject looks like:
+ `%alarmStatus%`, `%company%`, `%location%` and `%alarmName%` are the variables VSPC supports in alarm notification subjects. A rendered subject looks like:
-```
-VSPC Error | Contoso | London | Backup job failed
-```
+ ```
+ VSPC Error | Contoso | London | Backup job failed
+ ```
4. **Recipients**: by default VSPC sends alarm emails to location administrators and company administrators. To send them to Flashduty, go to **Configuration** → **Templates** → **Predefined Alarms** tab, select an alarm and click **Edit**, click **Add** at the **Actions** step, choose **Send email notification** in **Action**, enter the Flashduty email integration address in **Value**, and set the condition to **Errors and warnings**
5. **Email format**: the rules read only the email title; the body format does not affect matching
## Limitations
----
- **No resolve email**: by default VSPC sends email when a new alarm is raised or when an existing alarm changes to Error or Warning, so the rules cannot close alerts automatically. Turn on the [auto-resolve timeout](/en/on-call/channel/create-edit) in the channel that receives this integration; 24 hours is a reasonable start. You can also close alerts manually in Flashduty.
- **Object merging**: the subject variables do not include an object name, so alarms with the same name on different objects under the same company and location merge into one Flashduty alert.
diff --git a/en/on-call/integration/alert-integration/alert-sources/veracode-sca.mdx b/en/on-call/integration/alert-integration/alert-sources/veracode-sca.mdx
index 8580d094..6bda48c6 100644
--- a/en/on-call/integration/alert-integration/alert-sources/veracode-sca.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/veracode-sca.mdx
@@ -1,5 +1,6 @@
---
title: "Veracode SCA alert integration"
+sidebarTitle: "Veracode SCA"
description: "Send vulnerability issues found by Veracode SCA (agent-based scanning) to Flashduty On-call through a project webhook, and recover them when the issue is resolved."
keywords: ["alert integration", "Veracode", "SCA", "software composition analysis", "vulnerability", "webhook"]
---
@@ -13,7 +14,6 @@ Use the Veracode SCA (agent-based scanning) project webhook to send open-source
<div className="hide">
## In Flashduty On-call
----
Get the integration push URL in either of the following ways.
@@ -34,7 +34,6 @@ Get the integration push URL in either of the following ways.
</div>
## In Veracode
----
Webhooks are configured per project. You need the Security Lead, Workspace Administrator, or Workspace Editor role.
@@ -68,7 +67,6 @@ The Veracode documentation does not describe a test button for webhooks. When a
</Steps>
## Events and recovery
----
| Veracode event | `issues[].status` | Effect in Flashduty |
| :--- | :--- | :--- |
@@ -81,12 +79,10 @@ The Veracode documentation does not describe a test button for webhooks. When a
One delivery can carry several issues. Flashduty processes them in issue id order, at most 200 issues per delivery; the rest are ignored.
## Alert Key
----
The Alert Key is computed from the project id (`project.id`) and the issue id (`issues[].id`). In the Veracode documentation examples, the same issue has the same id in the discovered and changed events, so the recovery lands on the same alert. Changes to the vulnerability title, score, or project name do not change the Alert Key. A delivery without `project.id`, `issues[].id`, or `issues[].status` is rejected, and the error names the missing field.
## Severity
----
The Veracode payload carries no severity, so Flashduty maps the vulnerability's CVSS score, using the CVSS v3 score and falling back to the CVSS v2 score:
@@ -100,7 +96,6 @@ The Veracode payload carries no severity, so Flashduty maps the vulnerability's
On recovery the status becomes Ok and the severity stays at the last severity.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -118,7 +113,6 @@ On recovery the status becomes Ok and the severity stays at the last severity.
Flashduty does not keep the organization and user information in the payload.
## Troubleshooting
----
- **Veracode fails to save the webhook**: confirm the push URL is reachable from the internet and includes `integration_key`
- **Flashduty returns an invalid-parameter error**: the message names the missing field or the unsupported event
diff --git a/en/on-call/integration/alert-integration/alert-sources/vigil.mdx b/en/on-call/integration/alert-integration/alert-sources/vigil.mdx
index 42993523..127de010 100644
--- a/en/on-call/integration/alert-integration/alert-sources/vigil.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/vigil.mdx
@@ -1,5 +1,6 @@
---
title: "Vigil Alert Integration"
+sidebarTitle: "Vigil"
description: "Sync Vigil status page changes (dead, sick, healthy) to Flashduty On-call through the Vigil webhook notifier."
keywords: ["alert integration", "Vigil", "Webhook", "status page", "monitoring", "self-hosted"]
---
@@ -11,7 +12,6 @@ Vigil's webhook body has a fixed format, so no template is needed.
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -32,7 +32,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Vigil
----
You need Vigil 1.29.x and access to edit Vigil's configuration file (`config.cfg`). The server running Vigil must be able to reach the Flashduty push URL.
@@ -72,7 +71,6 @@ If `startup_notification = true` is set under `[notify]`, Vigil sends a `startup
</Steps>
## Alert Key
----
Flashduty uses the status page URL `page.url` as the Alert Key. Vigil notifications describe only the aggregate status of the whole status page and carry no per-alert ID, so one Vigil status page maps to one Flashduty alert: it is created or updated when the status becomes `dead` or `sick`, and recovered when it becomes `healthy`.
@@ -82,7 +80,6 @@ Flashduty uses the status page URL `page.url` as the Alert Key. Vigil notificati
- `page.url` comes from `page_url` under `[branding]` in `config.cfg` and is unique only within one Vigil instance. Do not give several Vigil instances the same `page_url`, and send only one Vigil instance to each Flashduty integration
## Status and severity
----
| Notification `type` | Flashduty handling |
| :--- | :--- |
@@ -103,7 +100,6 @@ Any other `status` is rejected. Vigil's notification time has only hours, minute
The alert title looks like `Vigil: Example Status is dead`, built from the status page title (or the page URL when the title is empty) and the status. The description lists the failing nodes in alphabetical order, in the format `service ID:node ID:probe URL`.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -115,7 +111,6 @@ The alert title looks like `Vigil: Example Status is dead`, built from the statu
| `replicas` | Failing nodes, sorted alphabetically and joined with commas |
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: confirm `hook_url` is complete and includes `integration_key`; the response names the missing field or the unsupported status
- **No alert received**: confirm Vigil was restarted, `hook_url` under `[notify.webhook]` is correct, and the overall status Vigil computes actually became `dead` or `sick`; Vigil sends notifications only on status changes and when the reminder interval elapses
diff --git a/en/on-call/integration/alert-integration/alert-sources/volcengine-cm-event.mdx b/en/on-call/integration/alert-integration/alert-sources/volcengine-cm-event.mdx
index fce92a8c..dbc29448 100644
--- a/en/on-call/integration/alert-integration/alert-sources/volcengine-cm-event.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/volcengine-cm-event.mdx
@@ -1,5 +1,6 @@
---
title: "Volcengine Cloud Monitor Event Center Alert Events"
+sidebarTitle: "Volcengine Cloud Monitor Event Center"
description: "Sync Volcengine Cloud Monitor Event Center alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,53 +9,52 @@ Sync Volcengine Cloud Monitor Event Center alert events to Flashduty via webhook
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels - it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Volcengine CM Event** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
- 2. Select **Volcengine CM Metrics** integration:
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
+ 2. Select **Volcengine CM Event** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Volcengine
----
<div class="md-block">
-## I. Volcengine Cloud Monitor Event Center Alert Push Configuration
### Step 1: Create Flashduty Alert Channel
1. Log in to your Volcengine console, search for `Cloud Monitor` product, and enter the corresponding product console
2. Select `Notification Groups=>Callback` from the left navigation bar
3. Click `Create Callback URL`
-<img src="https://download.flashcat.cloud/flashduty/doc/en/volcengine/event-1.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/volcengine/event-1.png" alt="drawing" width="500"/>
4. Fill in the information on the edit page, enter `Flashduty_Event` as the callback URL name
5. Select `General Callback URL` as the callback URL type
@@ -74,7 +74,7 @@ Choose this method when you need to route alerts to different channels based on
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics.mdx b/en/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics.mdx
index 1a0549c9..657bff3d 100644
--- a/en/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics.mdx
@@ -1,5 +1,6 @@
---
title: "Volcengine Cloud Monitor Alert Events"
+sidebarTitle: "Volcengine Cloud Monitor"
description: "Sync Volcengine Cloud Monitor alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,53 +9,52 @@ Sync Volcengine Cloud Monitor alert events to Flashduty via webhook for automate
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels - it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Select **Volcengine CM Metrics** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Volcengine CM Metrics** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Volcengine
----
<div class="md-block">
-## I. Volcengine Cloud Monitor Alert Push Configuration
### Step 1: Create Flashduty Alert Channel
1. Log in to your Volcengine console, search for `Cloud Monitor` product, and enter the corresponding product console
2. Select `Notification Groups=>Callback` from the left navigation bar
3. Click `Create Callback URL`
-<img src="https://download.flashcat.cloud/flashduty/doc/en/volcengine/event-1.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/volcengine/event-1.png" alt="drawing" width="500"/>
4. Fill in the information on the edit page, enter `Flashduty_Metric` as the callback URL name
5. Select `General Callback URL` as the callback URL type
@@ -76,7 +76,7 @@ Choose this method when you need to route alerts to different channels based on
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/volcengine-dial.mdx b/en/on-call/integration/alert-integration/alert-sources/volcengine-dial.mdx
index b80fb0a1..99069a9c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/volcengine-dial.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/volcengine-dial.mdx
@@ -1,5 +1,6 @@
---
title: "Volcengine Cloud-Detect Alert Events"
+sidebarTitle: "Volcengine Cloud-Detect"
description: "Sync Volcengine Cloud-Detect alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,47 +9,45 @@ Sync Volcengine Cloud-Detect alert events to Flashduty via webhook for automated
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels - it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Volcengine Detect** integration and click **Save** to generate a card
4. Click the generated card to view the **Push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event payload.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Volcengine Detect** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Volcengine
----
<div class="md-block">
-## 一、Create Notification Object
-
### Step 1: Create Notification Object
1. Login to your `Volcengine` console, find `Alert Manager` in the `Notify Object` menu
2. Click `System Integration`, click `Create System Integration` or edit the existing endpoint
@@ -67,7 +66,7 @@ Choose this method when you need to route alerts to different channels based on
</div>
-## 二、Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/volcengine-rtc.mdx b/en/on-call/integration/alert-integration/alert-sources/volcengine-rtc.mdx
index a9f09732..fd6c9501 100644
--- a/en/on-call/integration/alert-integration/alert-sources/volcengine-rtc.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/volcengine-rtc.mdx
@@ -1,5 +1,6 @@
---
title: "Volcengine RTC Alert Integration"
+sidebarTitle: "Volcengine RTC"
description: "Sync Volcengine RTC alert events to Flashduty via webhook for automated alert noise reduction"
keywords: ["Volcengine", "RTC", "alert integration", "webhook", "real-time communication"]
---
@@ -9,42 +10,42 @@ Sync Volcengine RTC alert events to Flashduty via webhook for automated alert no
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels - it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Volcengine RTC** integration and click **Save** to generate a card
4. Click the generated card to view the **Push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event payload.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Volcengine RTC** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Volcengine
----
### Configure Alert Rules
@@ -54,7 +55,7 @@ Choose this method when you need to route alerts to different channels based on
4. Configure other options as needed.
5. Click `Confirm` to complete the configuration.
-
+
## Status Mapping
diff --git a/en/on-call/integration/alert-integration/alert-sources/volcengine-tls.mdx b/en/on-call/integration/alert-integration/alert-sources/volcengine-tls.mdx
index 904599cd..75511045 100644
--- a/en/on-call/integration/alert-integration/alert-sources/volcengine-tls.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/volcengine-tls.mdx
@@ -1,5 +1,6 @@
---
title: "Volcengine Log Service (TLS) Alert Events"
+sidebarTitle: "Volcengine Log Service (TLS)"
description: "Sync Volcengine Log Service (TLS) alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,53 +9,52 @@ Sync Volcengine Log Service (TLS) alert events to Flashduty via webhook for auto
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels - it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Volcengine TLS** integration and click **Save** to generate a card
4. Click the generated card to view the **Push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event payload.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Volcengine TLS** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Volcengine
----
<div class="md-block">
-## I. Volcengine Log Service (TLS) Alert Push Configuration
### Step 1: Create Flashduty Alert Channel
1. Log in to your Volcengine console, search for `TLS` Log Service product, and enter the corresponding product console
2. Select `Alert=>Notification Management` from the left navigation bar
3. Choose `Webhook Alert Integration` and click `Create Webhook Alert Integration`
-<img src="https://download.flashcat.cloud/flashduty/doc/en/volcengine/tls-1.png" alt="drawing" width="500"/>
+ <img src="https://download.flashcat.cloud/flashduty/doc/en/volcengine/tls-1.png" alt="drawing" width="500"/>
4. Fill in the information in the pop-up editor, enter `Flashduty` as the name
5. Select `Custom Webhook` as type and `POST` as request method
@@ -70,28 +70,28 @@ Choose this method when you need to route alerts to different channels based on
3. Fill in the relevant information, enter `Flashduty` as the template name
4. Other channel content can be empty. In the `Custom Webhook` notification content, enter the following template:
-```
-{
- "AccountID":"{{AccountID}}",
- "ProjectName":"{{ProjectName}}",
- "AlarmTopicName":"{{AlarmTopicName}}",
- "Region":"{{Region}}",
- "Alarm":"{{Alarm}}",
- "AlarmID":"{{AlarmID}}",
- "Duration":"{{Duration}}",
- "Condition":"{{Condition}}",
- "HappenThreshold":"{{HappenThreshold}}",
- "Topics":"{{Topics|join:','}}",
- "NotifyTimeUnix":"{{NotifyTimeUnix}}",
- "NotifyType":"{{NotifyType}}",
- "Severity":"{{Severity}}",
- "ConsecutiveAlertNums":"{{ConsecutiveAlertNums}}",
- "TriggerParams":{{toJson(TriggerParams)|safe}},
- "ExecuteQuery":{{toJson(ExecuteQuery)|safe}},
- "DetailUrl":"{{DetailUrl}}",
- "FireResultsCount":"{{FireResultsCount}}"
-}
-```
+ ```
+ {
+ "AccountID":"{{AccountID}}",
+ "ProjectName":"{{ProjectName}}",
+ "AlarmTopicName":"{{AlarmTopicName}}",
+ "Region":"{{Region}}",
+ "Alarm":"{{Alarm}}",
+ "AlarmID":"{{AlarmID}}",
+ "Duration":"{{Duration}}",
+ "Condition":"{{Condition}}",
+ "HappenThreshold":"{{HappenThreshold}}",
+ "Topics":"{{Topics|join:','}}",
+ "NotifyTimeUnix":"{{NotifyTimeUnix}}",
+ "NotifyType":"{{NotifyType}}",
+ "Severity":"{{Severity}}",
+ "ConsecutiveAlertNums":"{{ConsecutiveAlertNums}}",
+ "TriggerParams":{{toJson(TriggerParams)|safe}},
+ "ExecuteQuery":{{toJson(ExecuteQuery)|safe}},
+ "DetailUrl":"{{DetailUrl}}",
+ "FireResultsCount":"{{FireResultsCount}}"
+ }
+ ```
5. Click `Confirm` to complete the content template creation
<img src="https://download.flashcat.cloud/flashduty/doc/en/volcengine/tls-3.png" alt="drawing" width="500"/>
@@ -120,7 +120,7 @@ Choose this method when you need to route alerts to different channels based on
<img src="https://download.flashcat.cloud/flashduty/doc/en/volcengine/tls-5.png" alt="drawing" width="500"/>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/wazuh.mdx b/en/on-call/integration/alert-integration/alert-sources/wazuh.mdx
index 3e9ff1aa..34e3c104 100644
--- a/en/on-call/integration/alert-integration/alert-sources/wazuh.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/wazuh.mdx
@@ -1,5 +1,6 @@
---
title: "Wazuh alert integration"
+sidebarTitle: "Wazuh"
description: "Send Wazuh alerts to Flashduty On-call through the manager's built-in Shuffle integration."
keywords: ["alert integration", "Wazuh", "SIEM", "XDR", "security alerts", "Shuffle", "integratord"]
---
@@ -9,7 +10,6 @@ The Wazuh manager's Integrator module (integratord) has a built-in `shuffle` int
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Wazuh
----
The Integrator module runs only on the Wazuh manager. The configuration file is `/var/ossec/etc/ossec.conf`, and you need root access on the manager.
@@ -77,19 +76,16 @@ Wazuh has no "send test notification" feature. The shuffle script skips alerts f
</Steps>
## Events and recovery
----
Wazuh pushes each alert once and never sends an update or a recovery notification. Every Wazuh alert has a unique alert ID, which Flashduty uses as the Alert Key: a redelivery of the same alert merges, different alerts each open their own Flashduty alert, and none resolves automatically.
Turn on the channel's [auto-resolve timeout](/en/on-call/channel/create-edit) (24 hours suggested), or close alerts by hand after handling them. When the same rule fires repeatedly on the same host, configure a noise-reduction rule on the channel to merge them into one incident.
## Alert Key
----
The Alert Key is computed from the Wazuh alert's `id` field (for example `1790000101.123456`). A request without `id` is rejected with an invalid-parameter error. This includes requests in the Slack integration format: Flashduty supports only the `shuffle` integration.
## Severity mapping
----
Flashduty maps `all_fields.rule.level` (the Wazuh rule level, 0-15):
@@ -102,7 +98,6 @@ Flashduty maps `all_fields.rule.level` (the Wazuh rule level, 0-15):
When `all_fields.rule.level` is missing, the shuffle script's `severity` field is used: `3` (rule level 8 and above) is Warning, and `1` and `2` are Info. When both are missing, the severity is Warning.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -120,7 +115,6 @@ When `all_fields.rule.level` is missing, the shuffle script's `severity` field i
Flashduty neither reads nor stores the raw log (`text` and `full_log`). The shuffle script still sends the whole alert to `hook_url`, and it can contain usernames, IP addresses, file paths and command lines. Filter with `<level>`, `<rule_id>` and `<group>`, and avoid forwarding raw authentication logs.
## Troubleshooting
----
- **Flashduty returns an invalid-parameter error**: make sure you use the `shuffle` integration with `<alert_format>` set to `json`, and check the `integration_key` in `hook_url`
- **No alerts arrive**: confirm the manager was restarted, the alert level is at or above `<level>`, the rule is not in the skip list above, and check `integrations.log`
diff --git a/en/on-call/integration/alert-integration/alert-sources/wecom-alert.mdx b/en/on-call/integration/alert-integration/alert-sources/wecom-alert.mdx
index c1f8c11e..170d1bcb 100644
--- a/en/on-call/integration/alert-integration/alert-sources/wecom-alert.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/wecom-alert.mdx
@@ -1,5 +1,6 @@
---
title: "WeCom Bot Compatible Integration"
+sidebarTitle: "WeCom Bot Compatible"
description: "Flashduty generates a webhook address in the format of a WeCom group robot. Point a tool that already sends alerts to a WeCom group robot at this address to bring alert triggers and recoveries into Flashduty."
keywords: ["alert integration", "WeCom Bot Compatible", "WeCom custom robot", "webhook"]
---
@@ -9,7 +10,6 @@ Generate a unique Wecom robot address in Flashduty, and synchronize the occurren
<div class="hide">
## Operation Steps
----
### Create WeCom Bot Compatible Integration
@@ -19,24 +19,25 @@ You can obtain a WeCom Bot Compatible integration address through either of thes
Choose this method when you don't need to route alert events to different channels. It's simpler and recommended.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **WeCom Bot Compatible** integration and click **Save** to generate a card
4. Click the generated card to view the **WeCom Bot Compatible Integration URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
#### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center => Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **WeCom Bot Compatible** integration:
- **Integration Name**: Define a name for the current integration
- **Message Type**: Select Wecom alert message type, currently only Text and Post (rich text) are supported
@@ -45,7 +46,8 @@ Choose this method when you need to route alerts to different channels based on
4. Configure the default route and select the corresponding channel (after integration creation, you can go to `Routes` to configure more routing rules)
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
### Customize WeCom Bot Compatible Integration
@@ -89,6 +91,5 @@ In the integration card (edit and preview), the **Silence Detection** (Heartbeat
- Flashduty will generate a default alert title: "Wecom robot Alert , If you need to change the title, you can customize it using the [alert pipeline](/en/on-call/integration/alert-integration/alert-pipelines)"
## Severity Mapping
----
Currently, all alerts pushed to Flashduty through the WeCom Bot Compatible integration are set to Warning severity. However, you can customize the severity using the [alert pipeline](/en/on-call/integration/alert-integration/alert-pipelines).
\ No newline at end of file
diff --git a/en/on-call/integration/alert-integration/alert-sources/whatap.mdx b/en/on-call/integration/alert-integration/alert-sources/whatap.mdx
index a384835d..b1a2c12c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/whatap.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/whatap.mdx
@@ -1,5 +1,6 @@
---
title: "WhaTap Alert Integration"
+sidebarTitle: "WhaTap"
description: "Sync WhaTap event alerts and recoveries to Flashduty On-call through a 3rd party plugin (Webhook JSON)."
keywords: ["alert integration", "WhaTap", "monitoring", "webhook", "event alerts"]
---
@@ -9,7 +10,6 @@ Use the Webhook JSON type of a WhaTap 3rd party plugin to sync the event alerts
<div className="hide">
## In Flashduty On-call
----
You can get the push URL in either of two ways.
@@ -30,7 +30,6 @@ You can get the push URL in either of two ways.
</div>
## Configure in WhaTap
----
<Steps>
<Step title="Add a Webhook JSON plugin">
@@ -57,7 +56,6 @@ Push a metric past its threshold (for example, lower a CPU threshold temporarily
</Steps>
## Payload
----
WhaTap POSTs `application/json`; every value is a string. Flashduty parses it directly, no template is needed:
@@ -76,14 +74,12 @@ WhaTap POSTs `application/json`; every value is a string. Flashduty parses it di
Numeric values may carry thousands separators (for example `55,223.0`). Flashduty keeps them as text labels and does not parse them.
## Alert Key
----
The Alert Key is `uuid`. The fire and recovery notifications of one WhaTap event carry the same `uuid`, so they land on one Flashduty alert. When the level of the same object and rule changes (for example a Critical event recovers and a Warning event fires), WhaTap creates a new event with a new `uuid`, which is a separate alert in Flashduty. Changes to title, level, value or time do not change the Alert Key.
A request without `uuid` is rejected with a parameter error, because its recovery could not be matched to the original alert.
## Status and severity
----
Flashduty reads `status` first and `level` second, because a WhaTap recovery always carries level `Info`.
@@ -98,7 +94,6 @@ Flashduty reads `status` first and `level` second, because a WhaTap recovery alw
A request whose `status` is neither `on` nor `off` is rejected, so a request of unknown state is never written into a wrong alert lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="Do I get repeated alerts while the condition persists?">
@@ -115,7 +110,6 @@ Refer to the current WhaTap plan description. 3rd party plugins are available du
</AccordionGroup>
## Troubleshooting
----
- **The test created an Info alert**: the notification sent by **Test alert** has no `uuid`. Flashduty recognizes it by all of its fixed content (`oid` `123456789`, `oname` `sample-name`, title `[Test] Alert reception test`, message `This is a test of WhaTap alert message`, level `Info`, status `on`, and empty metric, `okind` and `onode` fields) and opens a separate Info alert that never recovers; close it manually. Any other request without `uuid` is still rejected
- **WhaTap reports a failed push**: confirm the Webhook URL is the full push URL and includes `integration_key`
diff --git a/en/on-call/integration/alert-integration/alert-sources/whatsup-gold.mdx b/en/on-call/integration/alert-integration/alert-sources/whatsup-gold.mdx
index 41cb9415..8dbd08bc 100644
--- a/en/on-call/integration/alert-integration/alert-sources/whatsup-gold.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/whatsup-gold.mdx
@@ -1,5 +1,6 @@
---
title: "WhatsUp Gold alert integration"
+sidebarTitle: "WhatsUp Gold"
description: "WhatsUp Gold sends device down and up notifications through its e-mail action; use a Flashduty email integration with rules to trigger and close WhatsUp Gold alerts."
keywords: ["alert integration", "WhatsUp Gold", "Progress", "WUG", "email", "network monitoring"]
---
@@ -9,7 +10,6 @@ WhatsUp Gold sends device state notifications through the E-mail action in an ac
<div className="hide">
## In Flashduty On-call
----
Get the integration email address in either of the two ways below. **In both cases choose the Email integration type**, not WhatsUp Gold.
@@ -30,7 +30,6 @@ Get the integration email address in either of the two ways below. **In both cas
</div>
## Configure WhatsUp Gold
----
WhatsUp Gold emails carry no alert ID, so the subject below includes the device display name and Flashduty extracts it as the Alert Key. The down and up emails differ only in the prefix, so both yield the same key and the up email closes the matching alert.
@@ -52,7 +51,6 @@ Percent variables are case sensitive and must not contain spaces. `%Device.Displ
To get one alert per monitor instead of per device, bind the action policy to a specific active monitor and append `- %ActiveMonitor.Name` to the subject of both actions. `%ActiveMonitor.Name` only has a value when the action is associated directly with an active monitor; it cannot be used in a device-level action policy.
## Configure push rules in Flashduty
----
1. Set **Push mode** to **Trigger or close alert based on rules**
2. Add the two rules below in this order. Each rule's condition is **Email title** **Match** the given regex, and the Alert Key is extracted from the **Email title**
@@ -77,7 +75,6 @@ The close rule comes before the trigger rule. Both regexes extract what follows
The default rule discards unmatched mail so that other WhatsUp Gold emails, such as ones from other E-mail actions you created, don't create alerts that can never close on their own.
## Limitations
----
- **Recovery needs an up action**: Flashduty receives recovery emails only if the action policy has an action on the Up state change. Without one, turn on the [auto-resolve timeout](/en/on-call/channel/create-edit) in the channel that receives this integration; 24 hours is a reasonable start.
- **Repeated notifications**: with **Repeat action** checked in the policy, the down email is resent at the interval. The titles are identical, so they merge into one alert.
diff --git a/en/on-call/integration/alert-integration/alert-sources/wormly.mdx b/en/on-call/integration/alert-integration/alert-sources/wormly.mdx
index d5a6a3a3..4d79107c 100644
--- a/en/on-call/integration/alert-integration/alert-sources/wormly.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/wormly.mdx
@@ -1,5 +1,6 @@
---
title: "Wormly alert integration"
+sidebarTitle: "Wormly"
description: "Send Wormly host failure, escalation, and recovery notifications to Flashduty On-call through a contact webhook channel."
keywords: ["alert integration", "Wormly", "Uptime", "webhook", "Alert Group", "hostid"]
---
@@ -9,7 +10,6 @@ Use the webhook channel of a Wormly contact to send host failure and recovery no
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## In Wormly
----
<Steps>
<Step title="Create a webhook contact">
@@ -61,7 +60,6 @@ Wormly requires the receiving endpoint to be on a different server than the one
</Note>
## Payload
----
Wormly sends one JSON object per notification. Flashduty parses it directly, with no template to configure:
@@ -78,14 +76,12 @@ Wormly sends one JSON object per notification. Flashduty parses it directly, wit
The alert title is the host name, or `Wormly host <hostid>` when the name is empty. The request can be a JSON body, or a urlencoded or multipart form that carries the JSON in the `wormlyalert` field.
## Alert Key
----
Flashduty uses `hostid` as the Alert Key. Wormly documents it as the unique ID of the host that triggered the alert. Failure, repeated escalation, and recovery notifications for one host carry the same `hostid`, so they land on the same alert. Different hosts produce different alerts even when they share a name. Changing the host name, escalation level, or sensors does not change the Alert Key.
If `hostid` is missing, Flashduty returns a parameter error because a recovery could not be matched to its alert.
## Status and severity
----
Wormly notifications carry no severity. `alertlevel` is an escalation step, not a severity, so Flashduty treats every failure as Critical.
@@ -97,7 +93,6 @@ Wormly notifications carry no severity. `alertlevel` is an escalation step, not
Requests whose `isrecovery` is missing or is neither `0` nor `1` are rejected, so a request of unknown state never enters the wrong alert lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="Does a continuing failure create multiple Flashduty alerts?">
@@ -120,7 +115,6 @@ No. Flashduty only parses the JSON format. Choose a JSON webhook type in Wormly.
</AccordionGroup>
## Troubleshooting
----
- **Wormly reports a failed push**: confirm the URL is the full push URL and includes `integration_key`
- **Flashduty returns a parameter error**: confirm the webhook type is JSON and that `hostid` and `isrecovery` are present in the request
diff --git a/en/on-call/integration/alert-integration/alert-sources/xitoring.mdx b/en/on-call/integration/alert-integration/alert-sources/xitoring.mdx
index fc593fda..66dc3aa9 100644
--- a/en/on-call/integration/alert-integration/alert-sources/xitoring.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/xitoring.mdx
@@ -1,5 +1,6 @@
---
title: "Xitoring alert integration"
+sidebarTitle: "Xitoring"
description: "Send Xitoring down and up notifications to Flashduty On-call through a notification role webhook."
keywords: ["alert integration", "Xitoring", "Notification Role", "webhook", "Uptime", "server monitoring"]
---
@@ -9,7 +10,6 @@ Use a Xitoring notification role webhook to send check and server metric down an
<div className="hide">
## In Flashduty On-call
----
You can get the integration push URL in either of the following ways.
@@ -30,7 +30,6 @@ You can get the integration push URL in either of the following ways.
</div>
## Configure Xitoring
----
<Steps>
<Step title="Create a notification role">
@@ -59,7 +58,6 @@ Make a check actually go down (for example, point it at an unreachable address)
</Steps>
## Payload fields
----
Xitoring POSTs these fields as `application/x-www-form-urlencoded`. Flashduty parses them directly, with no template to configure:
@@ -79,14 +77,12 @@ Xitoring POSTs these fields as `application/x-www-form-urlencoded`. Flashduty pa
| `incident_time` | Incident time | Not stored |
## Alert Key
----
Xitoring documents `id` as the incident ID but does not say whether the recovery notification reuses it. So Flashduty does not use `id`. It joins the resource fields that every notification carries (`server_id`, `check_id`, `type`, `name`) with a delimiter and takes the MD5 as the Alert Key. The down, repeated down, and recovery notifications of one check or metric trigger get the same Alert Key and land on one alert; different checks, servers, or triggers get different alerts. Changing the name, group, metric value, `id`, or time does not change the Alert Key.
When both `server_id` and `check_id` are empty, or `type` is empty, Flashduty returns a parameter error because the recovery could not be matched to its alert reliably.
## Status and severity
----
Xitoring notifications carry no severity, so Flashduty decides by check type:
@@ -103,7 +99,6 @@ Xitoring notifications carry no severity, so Flashduty decides by check type:
Requests whose `status` is empty or any other value are rejected, so a request that cannot be classified never lands in the wrong alert lifecycle.
## FAQ
----
<AccordionGroup>
<Accordion title="Does the test notification create an alert?">
@@ -126,7 +121,6 @@ Two outages of the same check or trigger use the same Alert Key. After the earli
</AccordionGroup>
## Troubleshooting
----
- **Xitoring fails to deliver**: confirm the webhook URL is the full push URL and includes `integration_key`
- **Flashduty returns a parameter error**: confirm `status` is `0` or `1`, `type` is not empty, and at least one of `server_id` and `check_id` is not empty
diff --git a/en/on-call/integration/alert-integration/alert-sources/zabbix.mdx b/en/on-call/integration/alert-integration/alert-sources/zabbix.mdx
index 35202007..1256d32d 100644
--- a/en/on-call/integration/alert-integration/alert-sources/zabbix.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/zabbix.mdx
@@ -1,5 +1,6 @@
---
title: "Zabbix Integration"
+sidebarTitle: "Zabbix"
description: "Synchronize Zabbix alert events to Flashduty via webhook (supports Zabbix 3.x ~ 6.x versions, with different configuration requirements) to achieve automated alert noise reduction"
---
@@ -9,45 +10,43 @@ Synchronize Zabbix alert events to Flashduty via webhook (supports Zabbix 3.x ~
## In Flashduty
----
-
You can obtain an integration push URL through either of these two methods:
### Using Private Integration
Choose this method when you don't need to route alert events to different channels - it's simpler.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a specific channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Zabbix** integration, click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on alert event payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center => Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Zabbix** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Zabbix
----
-
- [7.x version](#v7)
- [5.x~6.x version](#v5)
- [3.x~4.x version](#v4)
@@ -62,10 +61,10 @@ Choose this method when you need to route alerts to different channels based on
1. Media type is a transport channel used for sending notifications and alerts in Zabbix. Enter the terminal and download the complete configuration using the following command:
-```
-wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/zbx_mediatype_flashcat_v7.yml
+ ```
+ wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/zbx_mediatype_flashcat_v7.yml
-```
+ ```
2. Log in to the Zabbix console, select `Alert > Media Types`, click the Import button in the top right corner, enter the editing page, select the configuration file downloaded above, and click Import to complete the import
3. Return to the Media Types page to see the imported media type. Click the name to enter the editing page, complete the URL, zabbix_url, and HTTPProxy content:
@@ -84,11 +83,11 @@ The media type must be associated with a user to send events. The user must have
1. Log in to the Zabbix console, select `Users > Users`, select Admin user, select media, select Add to enter the editing window:
-- Type: Select the Flashduty media type created above
-- Send To: Fill in Flashduty
-- Keep other configurations unchanged using default settings
+ - Type: Select the Flashduty media type created above
+ - Send To: Fill in Flashduty
+ - Keep other configurations unchanged using default settings
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/zabbix-3.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/zabbix-3.png" />
2. Click Add button to exit the add media window
3. Click Update button to exit the edit user page
@@ -99,7 +98,7 @@ Sending notifications is one of the operations executed by actions in Zabbix. Th
1. Click `Create action` to enter the action editing page
-- Name: Fill in "Send To Flashduty"
+ - Name: Fill in "Send To Flashduty"
2. Select `Operations`, add notification sending configurations for three scenarios respectively:
@@ -120,7 +119,7 @@ Log in to the Zabbix console, select `Monitoring > Problems` to view the latest
1. Click Actions, you can see the message notification results in the popup
2. Find the Flashduty corresponding log, if the Status is `Sent`, it means the notification was successful. Otherwise, troubleshoot according to the prompts
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/zabbix-6.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/zabbix-6.png" />
3. Return to the integration list, if the latest event time is displayed, it means the configuration is successful and events are being received
4. Done
@@ -133,13 +132,13 @@ Log in to the Zabbix console, select `Monitoring > Problems` to view the latest
1. Media type is a transport channel used for sending notifications and alerts in Zabbix. Enter the terminal and download the complete configuration using the following command:
-```
-// 5.x version XML configuration:
-wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/zbx_mediatype_flashcat_v5.xml
+ ```
+ // 5.x version XML configuration:
+ wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/zbx_mediatype_flashcat_v5.xml
-// 6.x version YAML configuration:
-wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/zbx_mediatype_flashcat_v6.yml
-```
+ // 6.x version YAML configuration:
+ wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/zbx_mediatype_flashcat_v6.yml
+ ```
2. Log in to the Zabbix console, select `Administration > Media Types`, click the Import button in the top right corner, enter the editing page, select the configuration file downloaded above, and click Import to complete the import
3. Return to the Media Types page to see the imported media type. Click the name to enter the editing page, complete the URL, zabbix_url, and HTTPProxy content:
@@ -158,9 +157,9 @@ The media type must be associated with a user to send events. The user must have
1. Log in to the Zabbix console, select `Administration > Users`, select Admin user, select media, select Add to enter the editing window:
-- Type: Select the Flashduty media type created above
-- Send To: Fill in N/A
-- Keep other configurations unchanged using default settings
+ - Type: Select the Flashduty media type created above
+ - Send To: Fill in N/A
+ - Keep other configurations unchanged using default settings
<img alt="drawing" width="600" src="https://download.flashcat.cloud/user.png" />
@@ -173,7 +172,7 @@ Sending notifications is one of the operations executed by actions in Zabbix. Th
1. Click `Create action` to enter the action editing page
-- Name: Fill in "Send To Flashduty"
+ - Name: Fill in "Send To Flashduty"
2. Select `Operations`, add notification sending configurations for three scenarios respectively:
@@ -194,7 +193,7 @@ Log in to the Zabbix console, select `Monitoring > Problems` to view the latest
1. Click Actions, you can see the message notification results in the popup
2. Find the Flashduty corresponding log, if the Status is `Sent`, it means the notification was successful. Otherwise, troubleshoot according to the prompts
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/problem.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/problem.png" />
3. Return to the integration list, if the latest event time is displayed, it means the configuration is successful and events are being received
4. Done
@@ -208,11 +207,11 @@ Log in to the Zabbix console, select `Monitoring > Problems` to view the latest
1. Log in to the Zabbix console, select `Administration > Media Types`, click `Create media type` button in the top right corner to enter the editing page
2. On the editing page, select `Script` for Type, fill in the following content for Parameter in order (do not adjust the order, leave empty if no value, the script gets parameter values in sequence):
-- `{ALERT.SUBJECT}`: Alert title, keep as first parameter
-- `{ALERT.MESSAGE}`: Alert message, keep as second parameter
-- `Flashduty webhook push URL`, simply copy the integration push URL, keep as third parameter
-- `Zabbix console address`, copy directly (if your page is configured with tomcat/nginx forwarding path, please include it), used to generate alert detail page links. Leave empty if none, keep as fourth parameter
-- `HTTPProxy`: If your Zabbix Server cannot directly access Flashduty services, you can set this parameter to a proxy address. Leave empty if none, keep as fifth parameter
+ - `{ALERT.SUBJECT}`: Alert title, keep as first parameter
+ - `{ALERT.MESSAGE}`: Alert message, keep as second parameter
+ - `Flashduty webhook push URL`, simply copy the integration push URL, keep as third parameter
+ - `Zabbix console address`, copy directly (if your page is configured with tomcat/nginx forwarding path, please include it), used to generate alert detail page links. Leave empty if none, keep as fourth parameter
+ - `HTTPProxy`: If your Zabbix Server cannot directly access Flashduty services, you can set this parameter to a proxy address. Leave empty if none, keep as fifth parameter
<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/zabbix/v4_create_fd_media_type.jpg"/>
@@ -220,16 +219,16 @@ Log in to the Zabbix console, select `Monitoring > Problems` to view the latest
4. Click Update to save the configuration
5. Log in to the Zabbix server host, execute the following commands:
-```
-#1. Enter alert script loading directory (specific address configured in Zabbix Server configuration file `AlertScriptsPath` variable, usually `/usr/lib/zabbix/alertscripts`)
-cd /usr/lib/zabbix/alertscripts
+ ```
+ #1. Enter alert script loading directory (specific address configured in Zabbix Server configuration file `AlertScriptsPath` variable, usually `/usr/lib/zabbix/alertscripts`)
+ cd /usr/lib/zabbix/alertscripts
-#2. Download script
-wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/send-to-flashduty.sh
+ #2. Download script
+ wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/send-to-flashduty.sh
-#3. Change script to executable status
-chmod +x send-to-flashduty.sh
-```
+ #3. Change script to executable status
+ chmod +x send-to-flashduty.sh
+ ```
6. Note that `the script uses curl and jq commands`, ensure that the Zabbix server process can find and execute these two commands, if not you need to install them as needed
@@ -281,7 +280,7 @@ Sending notifications is one of the operations executed by actions in Zabbix. Th
#### Step 4: Send Events to Flashduty
-Log in to the Zabbix console, select Monitoring > Problems to view the latest alert list.
+Log in to the Zabbix console, select Monitoring → Problems to view the latest alert list.
1. Click Actions, you can see the message notification results in the popup
2. Find the Flashduty corresponding log, if the Status is Sent, it means the notification was successful. Otherwise, troubleshoot according to the prompts
@@ -291,7 +290,7 @@ Log in to the Zabbix console, select Monitoring > Problems to view the latest al
3. Return to the integration list, if the latest event time is displayed, it means the configuration is successful and events are being received
4. Done
-## II. Status Mapping
+## Status Mapping
Zabbix to Flashduty alert severity mapping:
diff --git a/en/on-call/integration/alert-integration/alert-sources/zeek.mdx b/en/on-call/integration/alert-integration/alert-sources/zeek.mdx
index 94baf508..9fadd46f 100644
--- a/en/on-call/integration/alert-integration/alert-sources/zeek.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/zeek.mdx
@@ -1,5 +1,6 @@
---
title: "Zeek alert integration"
+sidebarTitle: "Zeek"
description: "Zeek's Notice framework can send notices by email; use a Flashduty email integration to bring Zeek notices into Flashduty."
keywords: ["alert integration", "Zeek", "Bro", "Notice", "email", "network security monitoring", "NDR"]
---
@@ -9,7 +10,6 @@ Zeek records detections as notices through its Notice framework, and the `Notice
<div className="hide">
## In Flashduty On-call
----
Get the integration email address in either of the two ways below. **In both cases choose the Email integration type**, not Zeek.
@@ -30,7 +30,6 @@ Get the integration email address in either of the two ways below. **In both cas
</div>
## Configure the push mode in Flashduty
----
Zeek notice emails only trigger; there is no resolve email, so no rules are needed to close alerts. Set the email integration's push mode to the one that always triggers a new alert (the create page may preselect a different mode, so check it), which creates a new alert for every email.
@@ -41,7 +40,6 @@ Zeek notice emails only trigger; there is no resolve email, so no rules are need
Zeek already suppresses repeats of the same notice for `suppress_for` (1 hour by default), so merging in Flashduty is usually unnecessary. To merge notices of the same type into one alert, switch the push mode to **Trigger or Update Alert Based on Email Subject**. The title holds only the notice type, so notices of the same type from different hosts merge together.
## Configure Zeek
----
### Recipient and mailer (ZeekControl)
@@ -83,7 +81,6 @@ hook Notice::policy(n: Notice::Info)
Redeploy Zeek (`zeekctl deploy`) for the change to take effect.
## Email format
----
A single-notice email (`Notice::ACTION_EMAIL`) has the title `Notice::mail_subject_prefix` (`[Zeek]` by default), a space, then the notice type. The body is made of the parts below:
@@ -103,7 +100,6 @@ Connection uid: CXWv6p3arKYeMETxOg
- Content that scripts add through `email_body_sections` is appended at the end of the body
## Limitations
----
- **Trigger only, no resolve**: Zeek never sends a resolve email. Turn on the [auto-resolve timeout](/en/on-call/channel/create-edit) in the channel that receives this integration; 24 hours is a reasonable start. Otherwise alerts must be closed manually.
- **Summary emails**: `Notice::ACTION_ALARM` does not send one email per notice. It bundles the `notice_alarm` log on a schedule (`MailAlarmsInterval` in ZeekControl, 86400 seconds by default) into one summary email titled like `[Zeek] Log Contents: ...`, which holds several notices and creates a single alert. Use `Notice::ACTION_EMAIL` when you need one alert per notice.
diff --git a/en/on-call/integration/alert-integration/alert-sources/zenoss.mdx b/en/on-call/integration/alert-integration/alert-sources/zenoss.mdx
index 2b651954..fce8b436 100644
--- a/en/on-call/integration/alert-integration/alert-sources/zenoss.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/zenoss.mdx
@@ -1,5 +1,6 @@
---
title: "Zenoss alert integration"
+sidebarTitle: "Zenoss"
description: "Send events from Zenoss Cloud (Virtana Service Observability) to Flashduty On-call through a webhook destination."
keywords: ["alert integration", "Zenoss", "Virtana", "Service Observability", "webhook", "infrastructure monitoring"]
---
@@ -9,7 +10,6 @@ Use a webhook destination in Zenoss Cloud (now Virtana Service Observability) to
<div className="hide">
## In Flashduty On-call
----
You can obtain an integration push URL in either of the following ways.
@@ -30,14 +30,13 @@ You can obtain an integration push URL in either of the following ways.
</div>
## Configure Zenoss
----
Zenoss sends notifications through a **destination**, a **trigger**, and a **rule**. Creating a rule requires the Manager role.
<Steps>
<Step title="Add a webhook destination">
-1. Go to **ADMIN > Actions**, open the **DESTINATIONS** tab, and click **ADD DESTINATION**
+1. Go to **ADMIN → Actions**, open the **DESTINATIONS** tab, and click **ADD DESTINATION**
2. Select the **Webhook** destination type and enter a **Destination name**
3. Paste the full Flashduty push URL into **URL**; it must include `integration_key`
4. Leave **Headers** empty and keep **Custom Payload** off: Flashduty parses the default Zenoss message, and a custom JSON body cannot be recognized
@@ -73,14 +72,12 @@ The **TEST** button on the destination page sends a test message. The Zenoss doc
</Steps>
## Alert Key
----
Flashduty builds the Alert Key from the event ID (`context.Context.Event.id` in the message). Zenoss identifies an event by its name plus dimensions and documents the event ID as the key for retrieving that event, so repeat notifications, updates, and the close of one event are expected to carry the same ID and share one Alert Key. Zenoss does not state this for the close notification in so many words: before going live, close one test event and confirm its alert recovers instead of a new alert opening. Changes to severity, summary, status, or time do not change the Alert Key.
The top-level `id` of the message is the notification ID, different on every delivery, and is not used. A message without an event ID is rejected.
## Status and severity
----
| Zenoss status (`status`) | Flashduty status |
| :--- | :--- |
@@ -98,7 +95,6 @@ The top-level `id` of the message is the notification ID, different on every del
A notification that carries no event (for example from a non-event trigger) creates no alert; Flashduty returns success.
## Labels
----
| Label | Source |
| :--- | :--- |
@@ -112,7 +108,6 @@ A notification that carries no event (for example from a non-event trigger) crea
The event summary (`summary`) becomes the alert description.
## Troubleshooting
----
- **Flashduty returns a parameter error**: Confirm that the URL is complete and includes `integration_key`, and that the destination does not use Custom Payload
- **The alert does not recover**: Confirm that **Send updates** is on in the rule and that the trigger does not exclude Closed events
diff --git a/en/on-call/integration/alert-integration/alert-sources/zilliz.mdx b/en/on-call/integration/alert-integration/alert-sources/zilliz.mdx
index 3a97ef1d..b48ffc49 100644
--- a/en/on-call/integration/alert-integration/alert-sources/zilliz.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/zilliz.mdx
@@ -1,5 +1,6 @@
---
title: "Zilliz Alert Events"
+sidebarTitle: "Zilliz"
description: "Sync Zilliz alert events to Flashduty via webhook for automated alert noise reduction"
---
@@ -8,46 +9,45 @@ Sync Zilliz alert events to Flashduty via webhook for automated alert noise redu
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Dedicated Integration
Choose this method when you don't need to route alert events to different channels. It's simpler and recommended.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **Zilliz** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **Zilliz** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In Zilliz
----
<div class="md-block">
-## I. Alert Push Configuration
1. Log in to your `Zilliz` console, create or modify an `Alert` in `Project Alerts`
2. In the `Send to` section of the `Alert` editing page, select `Webhook` and fill in the <span class='integration_url'>push URL</span> from your alert integration
@@ -58,7 +58,7 @@ Choose this method when you need to route alerts to different channels based on
</div>
-## II. Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/alert-sources/zstack.mdx b/en/on-call/integration/alert-integration/alert-sources/zstack.mdx
index 6ac4c940..b3b2f4a4 100644
--- a/en/on-call/integration/alert-integration/alert-sources/zstack.mdx
+++ b/en/on-call/integration/alert-integration/alert-sources/zstack.mdx
@@ -1,5 +1,6 @@
---
title: "zstack integration"
+sidebarTitle: "zstack"
description: "Push ZStack alerts to Flashduty via webhook, to achieve automatic alert noise reduction."
---
@@ -8,48 +9,46 @@ Push ZStack alerts to Flashduty via webhook, to achieve automatic alert noise re
<div class="hide">
## In Flashduty
----
You can obtain an integration push URL through either of these two methods:
### Using Dedicated Integration
Choose this method when you don't need to route alert events to different channels. It's simpler and recommended.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View dedicated integration setup steps">
1. Go to the Flashduty console, select **Channel**, and enter a channel's details page
2. Select **Configuration** → **Integrations** → **Private integration**, then click **Add an integration** to enter the integration page
3. Choose **ZStack** integration and click **Save** to generate a card
4. Click the generated card to view the **push URL**, copy it for later use, and you're done
-</details>
+</Accordion>
+</AccordionGroup>
### Using Shared Integration
Choose this method when you need to route alerts to different channels based on the alert event's payload information.
-<details>
- <summary>Expand</summary>
+<AccordionGroup>
+ <Accordion title="View shared integration setup steps">
- 1. Go to the Flashduty console, select **Integration Center=>Alert Events** to enter the integration selection page
+ 1. Go to the Flashduty console, select **Integration Center → Alert Events** to enter the integration selection page
2. Select **ZStack** integration:
- **Integration Name**: Define a name for this integration
3. Configure the default route and select the corresponding channel (after the integration is created, you can go to `Route` to configure more routing rules)
4. Click **Save** and copy the newly generated **push URL** for later use
5. Done
-</details>
+</Accordion>
+</AccordionGroup>
</div>
## In ZStack
----
<div class="md-block">
-## 一、Create Notification Object
-
### Step 1: Create Notification Object
1. Login to your `ZStack` console, find `Cloud Monitoring` in the `Platform O&M` menu
2. Click `Endpoint`, click `Create Endpoint` or edit the existing endpoint
@@ -72,7 +71,7 @@ Choose this method when you need to route alerts to different channels based on
</div>
-## 二、Status Mapping
+## Status Mapping
<div class="md-block">
diff --git a/en/on-call/integration/alert-integration/label-enhancement.mdx b/en/on-call/integration/alert-integration/label-enhancement.mdx
index d57ff972..3e1416b2 100644
--- a/en/on-call/integration/alert-integration/label-enhancement.mdx
+++ b/en/on-call/integration/alert-integration/label-enhancement.mdx
@@ -17,22 +17,14 @@ keywords: ["label enhancement", "auto labels", "data extraction", "field mapping
*/}
## Core Uses
-Labels are used throughout Flashduty On-call's alert processing workflow:
-
-| Scenario | Use |
-| :--- | :--- |
-| **Incident Filtering** | Quickly filter by labels in incident list |
-| **Route Distribution** | Route alerts to different channels based on labels |
-| **Assignment Notification** | Match different escalation rules by labels |
-| **Alert Grouping** | Group similar alerts by label dimensions |
-| **Silence/Inhibition** | Match alerts to silence or inhibit by labels |
+Labels drive the whole alert workflow: filtering the incident list, routing alerts to channels, matching escalation rules, grouping alerts, and matching silence and inhibition rules. Label enhancement lets these steps use information the source data doesn't provide directly.
## Configure Label Enhancement
Go to Integration Details → **Label Enhancement** → **Add Rule**.
<Note>
-**An empty rule list disables label enhancement**: Label enhancement rules can be saved as an empty list. After you delete all rules and save, the integration no longer performs any label enhancement, matching the integration's initial state; this applies to both alert events and change events. After you delete the last rule, the edit page shows the **No label rules** empty state — click **Add label rule** to configure rules again.
+To turn off label enhancement for an integration, delete all rules and save (applies to both alert and change events). The edit page then shows **No label rules**; click **Add label rule** to configure rules again.
</Note>
### Enhancement Types
@@ -48,6 +40,15 @@ Go to Integration Details → **Label Enhancement** → **Add Rule**.
<img src="https://docs-cdn.flashcat.cloud/images/png/c833e4ac159c9abaea755bad701d95ac.png" alt="Label enhancement types" />
</Frame>
+#### Mapping Methods
+
+When source label values vary or aren't meaningful on their own, map them to new labels and values. When adding a mapping rule, choose **Schema** or **API**:
+
+| Mapping Type | Description | Use Case |
+| :--- | :--- | :--- |
+| **Schema (Mapping Table)** | Static mapping via predefined CSV mapping table | Mapping relationships are relatively fixed with limited data |
+| **API (API Mapping)** | Dynamic mapping by calling external API service | Need to query external systems (e.g., mapping api) for real-time data |
+
### Configuration Options
| Option | Description |
@@ -131,18 +132,7 @@ Condition fields are validated when a rule is saved: fields outside this vocabul
</Steps>
</Tab>
-<Tab title="Label Mapping">
-**Scenario**: When source alert label values are variable and not intuitively meaningful, use mapping to map source labels to newly defined labels and values.
-
-Label mapping supports two mapping methods, selected via an inline radio toggle when adding a mapping rule -- choose **Schema** or **API**:
-
-| Mapping Type | Description | Use Case |
-| :--- | :--- | :--- |
-| **Schema (Mapping Table)** | Static mapping via predefined CSV mapping table | Mapping relationships are relatively fixed with limited data |
-| **API (API Mapping)** | Dynamic mapping by calling external API service | Need to query external systems (e.g., mapping api) for real-time data |
-
-<Tabs>
-<Tab title="Schema Mapping">
+<Tab title="Mapping: Schema">
**Example**: Source alerts only have resource type IDs, want to show corresponding resource type names.
<Steps>
@@ -159,11 +149,11 @@ Prepare a CSV format mapping table file to map resource type IDs in alerts to ac
</Step>
<Step title="Create Mapping Table">
-1. Go to `Configuration` → `Mappings` → `Schema` → `Create mapping schema`
+1. Go to **Configuration** → **Mappings** → **Schema** → **Create mapping schema**
2. Fill in basic info like name, description, management team, etc.
3. In `Mapping Table Data`, upload the prepared CSV file (if quantity is small, you can edit and add in mapping details page after creation)
4. Select `Source Label` (e.g., `ID`), select `Target Label` (e.g., `Type`)
-5. Click `Create` to complete mapping table creation
+5. Click **Create** to complete mapping table creation
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/95bc8cdf3d3dcb60a52d11cdad4c386b.png" alt="Create mapping table" />
@@ -192,22 +182,22 @@ Prepare a CSV format mapping table file to map resource type IDs in alerts to ac
</Steps>
</Tab>
-<Tab title="API Mapping">
+<Tab title="Mapping: API">
**Example**: Need to query responsible team, service tier, and other dynamic data from mapping api system based on host information in alerts.
<Steps>
<Step title="Create Mapping Service">
-1. Go to `Configuration` → `Mappings` → `API` → `Create API`
+1. Go to **Configuration** → **Mappings** → **API** → **Create API**
2. Fill in service configuration:
-| Configuration | Description | Example |
-| :--- | :--- | :--- |
-| Service Name | Readable name for the service | Mapping api Asset Query Service |
-| Description | Service purpose description | Query asset info by host IP |
-| Request URL | API request address | `https://mapping-api.example.com/v1/enrich-event` |
-| Headers | HTTP request header configuration | `X-Auth-Token: your-token` |
-| Timeout | Request timeout, 1-3 seconds, default 2 seconds | 1 |
-| Retry Count | Retry count on failure, 0-1 times, default 0 times | 1 |
+ | Configuration | Description | Example |
+ | :--- | :--- | :--- |
+ | Service Name | Readable name for the service | Mapping api Asset Query Service |
+ | Description | Service purpose description | Query asset info by host IP |
+ | Request URL | API request address | `https://mapping-api.example.com/v1/enrich-event` |
+ | Headers | HTTP request header configuration | `X-Auth-Token: your-token` |
+ | Timeout | Request timeout, 1-3 seconds, default 2 seconds | 1 |
+ | Retry Count | Retry count on failure, 0-1 times, default 0 times | 1 |
<Tip>
If the API uses HTTPS with an untrusted certificate, you can enable the `Skip Certificate Verification` option.
@@ -227,8 +217,6 @@ When an alert is triggered, Flashduty automatically calls the configured API ser
</Steps>
</Tab>
</Tabs>
-</Tab>
-</Tabs>
## Mapping Data Management
diff --git a/en/on-call/integration/alert-integration/overview.mdx b/en/on-call/integration/alert-integration/overview.mdx
new file mode 100644
index 00000000..0080ce1f
--- /dev/null
+++ b/en/on-call/integration/alert-integration/overview.mdx
@@ -0,0 +1,128 @@
+---
+title: "Alert integrations overview"
+sidebarTitle: "Overview"
+description: "Find the setup guide for a monitoring tool, cloud platform, or other alert source, and learn the generic ingestion methods"
+---
+
+Flashduty On-call receives alerts that external systems push or that Flashduty pulls through alert integrations. The generic methods that do not depend on a specific tool come first, followed by every alert integration sorted by name. You can also search for a tool name with Ctrl K.
+
+## Before you start
+
+Every integration can be connected as a **dedicated integration** (alerts go straight into one channel) or a **shared integration** (alerts are routed to channels by routing rules). See [Integrate Data](/en/on-call/channel/integrate-data) and [Routing Rules](/en/on-call/integration/alert-integration/routing-rules).
+
+## Generic ingestion methods
+
+<CardGroup cols={2}>
+ <Card title="Standard Alert Event" href="/en/on-call/integration/alert-integration/alert-sources/standard-alert">
+ Push alerts in the Flashduty standard format, for in-house systems or tools without a dedicated integration
+ </Card>
+ <Card title="Email" href="/en/on-call/integration/alert-integration/alert-sources/email">
+ Generate a dedicated email address and sync alert triggers and recoveries by email
+ </Card>
+ <Card title="HTTP Pull" href="/en/on-call/integration/alert-integration/alert-sources/http-pull">
+ Let Flashduty periodically pull alerts from an HTTP endpoint
+ </Card>
+ <Card title="Database Pull (DB Pull)" href="/en/on-call/integration/alert-integration/alert-sources/db-pull">
+ Let Flashduty periodically query alert records from a database
+ </Card>
+</CardGroup>
+
+## All alert integrations (sorted by name)
+
+290 alert integration guides are currently available.
+
+### A
+
+[Aikido Security](/en/on-call/integration/alert-integration/alert-sources/aikido) · [Airbrake](/en/on-call/integration/alert-integration/alert-sources/airbrake) · [SmartBear AlertSite](/en/on-call/integration/alert-integration/alert-sources/alertsite) · [Alibaba Cloud ARMS](/en/on-call/integration/alert-integration/alert-sources/aliyun-arms) · [Alibaba Cloud Monitor CM Event](/en/on-call/integration/alert-integration/alert-sources/aliyun-cm-event) · [Alibaba Cloud Monitor CM Metrics](/en/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics) · [Alibaba Cloud DataWorks](/en/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op) · [Alibaba Cloud Prometheus](/en/on-call/integration/alert-integration/alert-sources/aliyun-prometheus) · [Alibaba Cloud SLS](/en/on-call/integration/alert-integration/alert-sources/aliyun-sls) · [Amazon Inspector](/en/on-call/integration/alert-integration/alert-sources/amazon-inspector) · [apcupsd](/en/on-call/integration/alert-integration/alert-sources/apcupsd) · [APIContext (APImetrics)](/en/on-call/integration/alert-integration/alert-sources/apimetrics) · [AppDynamics](/en/on-call/integration/alert-integration/alert-sources/appdynamics) · [AppSignal](/en/on-call/integration/alert-integration/alert-sources/appsignal) · [Argo CD](/en/on-call/integration/alert-integration/alert-sources/argocd) · [Atatus](/en/on-call/integration/alert-integration/alert-sources/atatus) · [Auth0](/en/on-call/integration/alert-integration/alert-sources/auth0) · [Auvik](/en/on-call/integration/alert-integration/alert-sources/auvik) · [AWS CloudWatch](/en/on-call/integration/alert-integration/alert-sources/aws-cloudwatch) · [AWS EventBridge](/en/on-call/integration/alert-integration/alert-sources/aws-eventbridge) · [AWS Health](/en/on-call/integration/alert-integration/alert-sources/aws-health) · [AWS Security Hub](/en/on-call/integration/alert-integration/alert-sources/aws-security-hub) · [Axiom](/en/on-call/integration/alert-integration/alert-sources/axiom) · [Azure Monitor](/en/on-call/integration/alert-integration/alert-sources/azure-monitor) · [Azure Service Health](/en/on-call/integration/alert-integration/alert-sources/azure-service-health)
+
+### B
+
+[Baidu Cloud BCM](/en/on-call/integration/alert-integration/alert-sources/baidu-bcm) · [BGPalerter](/en/on-call/integration/alert-integration/alert-sources/bgpalerter) · [BigPanda](/en/on-call/integration/alert-integration/alert-sources/bigpanda) · [Bitdefender GravityZone](/en/on-call/integration/alert-integration/alert-sources/bitdefender) · [Bleemeo](/en/on-call/integration/alert-integration/alert-sources/bleemeo) · [Tencent BlueKing](/en/on-call/integration/alert-integration/alert-sources/blueking) · [Blumira](/en/on-call/integration/alert-integration/alert-sources/blumira) · [BugSnag](/en/on-call/integration/alert-integration/alert-sources/bugsnag)
+
+### C
+
+[Calibre](/en/on-call/integration/alert-integration/alert-sources/calibre) · [Canarytokens](/en/on-call/integration/alert-integration/alert-sources/canarytokens) · [Catchpoint](/en/on-call/integration/alert-integration/alert-sources/catchpoint) · [Cato Networks](/en/on-call/integration/alert-integration/alert-sources/cato) · [Censys](/en/on-call/integration/alert-integration/alert-sources/censys) · [Centreon](/en/on-call/integration/alert-integration/alert-sources/centreon) · [Cert Spotter](/en/on-call/integration/alert-integration/alert-sources/cert-spotter) · [CFEngine](/en/on-call/integration/alert-integration/alert-sources/cfengine) · [Check Point SmartEvent](/en/on-call/integration/alert-integration/alert-sources/check-point-smartevent) · [Checkly](/en/on-call/integration/alert-integration/alert-sources/checkly) · [Checkmk](/en/on-call/integration/alert-integration/alert-sources/checkmk) · [Chronosphere](/en/on-call/integration/alert-integration/alert-sources/chronosphere) · [Circonus](/en/on-call/integration/alert-integration/alert-sources/circonus) · [CloudAMQP](/en/on-call/integration/alert-integration/alert-sources/cloudamqp) · [Cloudflare](/en/on-call/integration/alert-integration/alert-sources/cloudflare) · [ClusterControl](/en/on-call/integration/alert-integration/alert-sources/clustercontrol) · [HashiCorp Consul](/en/on-call/integration/alert-integration/alert-sources/consul) · [Contrast Security](/en/on-call/integration/alert-integration/alert-sources/contrast) · [Coralogix](/en/on-call/integration/alert-integration/alert-sources/coralogix) · [Coroot](/en/on-call/integration/alert-integration/alert-sources/coroot) · [Cronicle](/en/on-call/integration/alert-integration/alert-sources/cronicle) · [Cronitor](/en/on-call/integration/alert-integration/alert-sources/cronitor) · [CrowdSec](/en/on-call/integration/alert-integration/alert-sources/crowdsec) · [CrowdStrike Falcon](/en/on-call/integration/alert-integration/alert-sources/crowdstrike) · [CrowdStrike Falcon LogScale](/en/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale) · [StateCloud](/en/on-call/integration/alert-integration/alert-sources/ctyun) · [CubeAPM](/en/on-call/integration/alert-integration/alert-sources/cubeapm)
+
+### D
+
+[Dash0](/en/on-call/integration/alert-integration/alert-sources/dash0) · [Datadog](/en/on-call/integration/alert-integration/alert-sources/datadog) · [Datto RMM](/en/on-call/integration/alert-integration/alert-sources/datto-rmm) · [DBmarlin](/en/on-call/integration/alert-integration/alert-sources/dbmarlin) · [Dead Man's Snitch](/en/on-call/integration/alert-integration/alert-sources/dead-mans-snitch) · [Dependency-Track](/en/on-call/integration/alert-integration/alert-sources/dependency-track) · [DingTalk Bot Compatible](/en/on-call/integration/alert-integration/alert-sources/dingtalk-alert) · [Dkron](/en/on-call/integration/alert-integration/alert-sources/dkron) · [Apache DolphinScheduler](/en/on-call/integration/alert-integration/alert-sources/dolphinscheduler) · [Domotz](/en/on-call/integration/alert-integration/alert-sources/domotz) · [Dotcom-Monitor](/en/on-call/integration/alert-integration/alert-sources/dotcom-monitor) · [Duplicati](/en/on-call/integration/alert-integration/alert-sources/duplicati) · [Dynatrace](/en/on-call/integration/alert-integration/alert-sources/dynatrace)
+
+### E
+
+[China Mobile Cloud (ecloud) Cloud Monitor](/en/on-call/integration/alert-integration/alert-sources/ecloud-cm) · [Edge Delta](/en/on-call/integration/alert-integration/alert-sources/edge-delta) · [ElastAlert2](/en/on-call/integration/alert-integration/alert-sources/elastalert2) · [Elastic](/en/on-call/integration/alert-integration/alert-sources/elastic) · [EMQX](/en/on-call/integration/alert-integration/alert-sources/emqx) · [ExtraHop](/en/on-call/integration/alert-integration/alert-sources/extrahop)
+
+### F
+
+[Fail2ban](/en/on-call/integration/alert-integration/alert-sources/fail2ban) · [Falco](/en/on-call/integration/alert-integration/alert-sources/falco) · [FastNetMon](/en/on-call/integration/alert-integration/alert-sources/fastnetmon) · [Firebase Crashlytics](/en/on-call/integration/alert-integration/alert-sources/firebase-crashlytics) · [Firefly](/en/on-call/integration/alert-integration/alert-sources/firefly) · [Fivetran](/en/on-call/integration/alert-integration/alert-sources/fivetran) · [Nightingale/Flashcat](/en/on-call/integration/alert-integration/alert-sources/flashcat) · [Fleet](/en/on-call/integration/alert-integration/alert-sources/fleet) · [Flowmon ADS](/en/on-call/integration/alert-integration/alert-sources/flowmon-ads) · [Flowtriq](/en/on-call/integration/alert-integration/alert-sources/flowtriq) · [Flux CD](/en/on-call/integration/alert-integration/alert-sources/fluxcd) · [Formant](/en/on-call/integration/alert-integration/alert-sources/formant) · [FortiMonitor](/en/on-call/integration/alert-integration/alert-sources/fortimonitor) · [FortiSIEM](/en/on-call/integration/alert-integration/alert-sources/fortisiem)
+
+### G
+
+[Gatus](/en/on-call/integration/alert-integration/alert-sources/gatus) · [Google Cloud Personalized Service Health](/en/on-call/integration/alert-integration/alert-sources/gcp-personalized-service-health) · [Ghost Inspector](/en/on-call/integration/alert-integration/alert-sources/ghost-inspector) · [GitGuardian](/en/on-call/integration/alert-integration/alert-sources/gitguardian) · [GitHub](/en/on-call/integration/alert-integration/alert-sources/github) · [GitLab](/en/on-call/integration/alert-integration/alert-sources/gitlab) · [Google Cloud Monitoring](/en/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring) · [Google Security Command Center](/en/on-call/integration/alert-integration/alert-sources/google-scc) · [Grafana](/en/on-call/integration/alert-integration/alert-sources/grafana) · [Graylog](/en/on-call/integration/alert-integration/alert-sources/graylog) · [Guance](/en/on-call/integration/alert-integration/alert-sources/guance)
+
+### H
+
+[HackerOne](/en/on-call/integration/alert-integration/alert-sources/hackerone) · [Harbor](/en/on-call/integration/alert-integration/alert-sources/harbor) · [Harness](/en/on-call/integration/alert-integration/alert-sources/harness) · [Healthchecks.io](/en/on-call/integration/alert-integration/alert-sources/healthchecks-io) · [Apache HertzBeat](/en/on-call/integration/alert-integration/alert-sources/hertzbeat) · [HetrixTools](/en/on-call/integration/alert-integration/alert-sources/hetrixtools) · [Honeybadger](/en/on-call/integration/alert-integration/alert-sources/honeybadger) · [Honeycomb](/en/on-call/integration/alert-integration/alert-sources/honeycomb) · [Hookdeck](/en/on-call/integration/alert-integration/alert-sources/hookdeck) · [Hosted Graphite](/en/on-call/integration/alert-integration/alert-sources/hosted-graphite) · [Huawei Cloud AOM](/en/on-call/integration/alert-integration/alert-sources/huawei-aom) · [Huawei Cloud APM](/en/on-call/integration/alert-integration/alert-sources/huawei-apm) · [Huawei Cloud CES](/en/on-call/integration/alert-integration/alert-sources/huawei-ces) · [Huawei Cloud LTS](/en/on-call/integration/alert-integration/alert-sources/huawei-lts) · [Hund](/en/on-call/integration/alert-integration/alert-sources/hund) · [HyperDX](/en/on-call/integration/alert-integration/alert-sources/hyperdx) · [Hyperping](/en/on-call/integration/alert-integration/alert-sources/hyperping)
+
+### I
+
+[IBM QRadar](/en/on-call/integration/alert-integration/alert-sources/ibm-qradar) · [Icinga 2](/en/on-call/integration/alert-integration/alert-sources/icinga) · [Imperva](/en/on-call/integration/alert-integration/alert-sources/imperva) · [Infisical](/en/on-call/integration/alert-integration/alert-sources/infisical) · [InfluxData](/en/on-call/integration/alert-integration/alert-sources/influxdata) · [Rapid7 InsightIDR](/en/on-call/integration/alert-integration/alert-sources/insightidr) · [IBM Instana](/en/on-call/integration/alert-integration/alert-sources/instana) · [Instatus](/en/on-call/integration/alert-integration/alert-sources/instatus) · [Cisco Intersight](/en/on-call/integration/alert-integration/alert-sources/intersight)
+
+### J
+
+[JD Cloud monitoring](/en/on-call/integration/alert-integration/alert-sources/jdcloud) · [JFrog Xray](/en/on-call/integration/alert-integration/alert-sources/jfrog-xray) · [Jiankongbao](/en/on-call/integration/alert-integration/alert-sources/jiankongbao) · [JumpCloud](/en/on-call/integration/alert-integration/alert-sources/jumpcloud) · [Juniper Mist](/en/on-call/integration/alert-integration/alert-sources/juniper-mist)
+
+### K
+
+[Kapacitor](/en/on-call/integration/alert-integration/alert-sources/kapacitor) · [Keep](/en/on-call/integration/alert-integration/alert-sources/keep) · [Kener](/en/on-call/integration/alert-integration/alert-sources/kener) · [Kentik](/en/on-call/integration/alert-integration/alert-sources/kentik) · [Komodor](/en/on-call/integration/alert-integration/alert-sources/komodor) · [Kingsoft Cloud monitoring](/en/on-call/integration/alert-integration/alert-sources/kscloud-monitor) · [Kuvasz](/en/on-call/integration/alert-integration/alert-sources/kuvasz)
+
+### L
+
+[Lacework FortiCNAPP](/en/on-call/integration/alert-integration/alert-sources/lacework) · [LangSmith](/en/on-call/integration/alert-integration/alert-sources/langsmith) · [Lark Bot Compatible](/en/on-call/integration/alert-integration/alert-sources/lark-alert) · [Last9](/en/on-call/integration/alert-integration/alert-sources/last9) · [Level](/en/on-call/integration/alert-integration/alert-sources/level) · [LibreNMS](/en/on-call/integration/alert-integration/alert-sources/librenms) · [LimaCharlie](/en/on-call/integration/alert-integration/alert-sources/limacharlie) · [Loadster](/en/on-call/integration/alert-integration/alert-sources/loadster) · [Loggly](/en/on-call/integration/alert-integration/alert-sources/loggly) · [LogicMonitor](/en/on-call/integration/alert-integration/alert-sources/logicmonitor) · [Logpoint](/en/on-call/integration/alert-integration/alert-sources/logpoint) · [LogRocket](/en/on-call/integration/alert-integration/alert-sources/logrocket) · [Logz.io](/en/on-call/integration/alert-integration/alert-sources/logz-io)
+
+### M
+
+[Mackerel](/en/on-call/integration/alert-integration/alert-sources/mackerel) · [Meraki](/en/on-call/integration/alert-integration/alert-sources/meraki) · [Metoro](/en/on-call/integration/alert-integration/alert-sources/metoro) · [Mezmo](/en/on-call/integration/alert-integration/alert-sources/mezmo) · [Microsoft Defender for Cloud](/en/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud) · [Microsoft Sentinel](/en/on-call/integration/alert-integration/alert-sources/microsoft-sentinel) · [Moesif](/en/on-call/integration/alert-integration/alert-sources/moesif) · [MongoDB Atlas](/en/on-call/integration/alert-integration/alert-sources/mongodb-atlas) · [Monit](/en/on-call/integration/alert-integration/alert-sources/monit) · [Monitive](/en/on-call/integration/alert-integration/alert-sources/monitive) · [Monte Carlo](/en/on-call/integration/alert-integration/alert-sources/monte-carlo)
+
+### N
+
+[Nagios](/en/on-call/integration/alert-integration/alert-sources/nagios) · [NetBeez](/en/on-call/integration/alert-integration/alert-sources/netbeez) · [Netdata](/en/on-call/integration/alert-integration/alert-sources/netdata) · [New Relic](/en/on-call/integration/alert-integration/alert-sources/new-relic) · [Nobl9](/en/on-call/integration/alert-integration/alert-sources/nobl9) · [NodePing](/en/on-call/integration/alert-integration/alert-sources/nodeping) · [NS1 Connect](/en/on-call/integration/alert-integration/alert-sources/ns1) · [ntopng](/en/on-call/integration/alert-integration/alert-sources/ntopng) · [NUT (Network UPS Tools)](/en/on-call/integration/alert-integration/alert-sources/nut)
+
+### O
+
+[Obkio](/en/on-call/integration/alert-integration/alert-sources/obkio) · [Observium](/en/on-call/integration/alert-integration/alert-sources/observium) · [OceanBase](/en/on-call/integration/alert-integration/alert-sources/oceanbase) · [OCI Monitoring](/en/on-call/integration/alert-integration/alert-sources/oci-monitoring) · [Odown](/en/on-call/integration/alert-integration/alert-sources/odown) · [Ofelia](/en/on-call/integration/alert-integration/alert-sources/ofelia) · [Oh Dear](/en/on-call/integration/alert-integration/alert-sources/ohdear) · [Okta](/en/on-call/integration/alert-integration/alert-sources/okta) · [Open Falcon](/en/on-call/integration/alert-integration/alert-sources/open-falcon) · [OpenNMS](/en/on-call/integration/alert-integration/alert-sources/opennms) · [OpenObserve](/en/on-call/integration/alert-integration/alert-sources/openobserve) · [OpenSearch](/en/on-call/integration/alert-integration/alert-sources/opensearch) · [OpenStatus](/en/on-call/integration/alert-integration/alert-sources/openstatus) · [OpManager](/en/on-call/integration/alert-integration/alert-sources/opmanager) · [OPNsense](/en/on-call/integration/alert-integration/alert-sources/opnsense) · [Opsgenie Compatible](/en/on-call/integration/alert-integration/alert-sources/opsgenie) · [Opsview](/en/on-call/integration/alert-integration/alert-sources/opsview) · [OSSEC](/en/on-call/integration/alert-integration/alert-sources/ossec)
+
+### P
+
+[PagerDuty Compatible](/en/on-call/integration/alert-integration/alert-sources/pagerduty) · [Pandora FMS](/en/on-call/integration/alert-integration/alert-sources/pandora-fms) · [Panther](/en/on-call/integration/alert-integration/alert-sources/panther) · [Papertrail](/en/on-call/integration/alert-integration/alert-sources/papertrail) · [Peekaping](/en/on-call/integration/alert-integration/alert-sources/peekaping) · [pgDash](/en/on-call/integration/alert-integration/alert-sources/pgdash) · [Phare Uptime](/en/on-call/integration/alert-integration/alert-sources/phare) · [Pingdom](/en/on-call/integration/alert-integration/alert-sources/pingdom) · [Postman](/en/on-call/integration/alert-integration/alert-sources/postman) · [PowerJob](/en/on-call/integration/alert-integration/alert-sources/powerjob) · [ProjectDiscovery Cloud](/en/on-call/integration/alert-integration/alert-sources/projectdiscovery) · [Prometheus](/en/on-call/integration/alert-integration/alert-sources/prometheus) · [PRTG](/en/on-call/integration/alert-integration/alert-sources/prtg) · [Pulsetic](/en/on-call/integration/alert-integration/alert-sources/pulsetic) · [Pulseway](/en/on-call/integration/alert-integration/alert-sources/pulseway)
+
+### R
+
+[Raritan PX PDU](/en/on-call/integration/alert-integration/alert-sources/raritan-px) · [Raygun](/en/on-call/integration/alert-integration/alert-sources/raygun) · [RBLTracker](/en/on-call/integration/alert-integration/alert-sources/rbltracker) · [Red Hat OpenShift](/en/on-call/integration/alert-integration/alert-sources/red-hat-openshift) · [Redash](/en/on-call/integration/alert-integration/alert-sources/redash) · [Redgate SQL Monitor](/en/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor) · [Logease](/en/on-call/integration/alert-integration/alert-sources/rizhiyi) · [Robotalp](/en/on-call/integration/alert-integration/alert-sources/robotalp) · [Robusta](/en/on-call/integration/alert-integration/alert-sources/robusta) · [Rollbar](/en/on-call/integration/alert-integration/alert-sources/rollbar) · [RUM](/en/on-call/integration/alert-integration/alert-sources/rum-alert)
+
+### S
+
+[SearchStax](/en/on-call/integration/alert-integration/alert-sources/searchstax) · [SecurityScorecard](/en/on-call/integration/alert-integration/alert-sources/securityscorecard) · [Sematext](/en/on-call/integration/alert-integration/alert-sources/sematext) · [Semgrep](/en/on-call/integration/alert-integration/alert-sources/semgrep) · [Sensu Go](/en/on-call/integration/alert-integration/alert-sources/sensu) · [Sentry](/en/on-call/integration/alert-integration/alert-sources/sentry) · [IBM SevOne NPM](/en/on-call/integration/alert-integration/alert-sources/sevone) · [SigNoz](/en/on-call/integration/alert-integration/alert-sources/signoz) · [Simple Observability](/en/on-call/integration/alert-integration/alert-sources/simple-observability) · [Site24x7](/en/on-call/integration/alert-integration/alert-sources/site24x7) · [Skywalking](/en/on-call/integration/alert-integration/alert-sources/skywalking) · [Snyk](/en/on-call/integration/alert-integration/alert-sources/snyk) · [SolarWinds](/en/on-call/integration/alert-integration/alert-sources/solarwinds) · [SolarWinds Platform (Orion)](/en/on-call/integration/alert-integration/alert-sources/solarwinds-orion) · [SonarQube](/en/on-call/integration/alert-integration/alert-sources/sonarqube) · [Split](/en/on-call/integration/alert-integration/alert-sources/split-io) · [Splunk](/en/on-call/integration/alert-integration/alert-sources/splunk) · [Splunk Observability Cloud](/en/on-call/integration/alert-integration/alert-sources/splunk-observability) · [StackRox](/en/on-call/integration/alert-integration/alert-sources/stackrox) · [StatusCake](/en/on-call/integration/alert-integration/alert-sources/statuscake) · [StatusGator](/en/on-call/integration/alert-integration/alert-sources/statusgator) · [Atlassian Statuspage](/en/on-call/integration/alert-integration/alert-sources/statuspage) · [Statuspal](/en/on-call/integration/alert-integration/alert-sources/statuspal) · [Stripe](/en/on-call/integration/alert-integration/alert-sources/stripe) · [Sublime Security](/en/on-call/integration/alert-integration/alert-sources/sublime) · [Sumo Logic](/en/on-call/integration/alert-integration/alert-sources/sumo-logic) · [Suricata](/en/on-call/integration/alert-integration/alert-sources/suricata) · [Sysdig](/en/on-call/integration/alert-integration/alert-sources/sysdig)
+
+### T
+
+[Tactical RMM](/en/on-call/integration/alert-integration/alert-sources/tactical-rmm) · [Tailscale](/en/on-call/integration/alert-integration/alert-sources/tailscale) · [Tencent Cloud CLS](/en/on-call/integration/alert-integration/alert-sources/tencent-cls) · [Tencent Cloud Monitor CM](/en/on-call/integration/alert-integration/alert-sources/tencent-cm) · [Tencent Cloud Live](/en/on-call/integration/alert-integration/alert-sources/tencent-css) · [Tencent Cloud EventBridge](/en/on-call/integration/alert-integration/alert-sources/tencent-eventbridge) · [Thinkst Canary](/en/on-call/integration/alert-integration/alert-sources/thinkst-canary) · [ThousandEyes](/en/on-call/integration/alert-integration/alert-sources/thousandeyes) · [Tideways](/en/on-call/integration/alert-integration/alert-sources/tideways) · [Aqua Tracee](/en/on-call/integration/alert-integration/alert-sources/tracee) · [Trigger.dev](/en/on-call/integration/alert-integration/alert-sources/trigger-dev) · [Trivy Operator](/en/on-call/integration/alert-integration/alert-sources/trivy-operator) · [Twilio](/en/on-call/integration/alert-integration/alert-sources/twilio) · [Twingate](/en/on-call/integration/alert-integration/alert-sources/twingate)
+
+### U
+
+[UCloud CloudWatch](/en/on-call/integration/alert-integration/alert-sources/ucloud-cloudwatch) · [updown.io](/en/on-call/integration/alert-integration/alert-sources/updown) · [UpGuard](/en/on-call/integration/alert-integration/alert-sources/upguard) · [Uptime.com](/en/on-call/integration/alert-integration/alert-sources/uptime-com) · [Uptime Kuma](/en/on-call/integration/alert-integration/alert-sources/uptime-kuma) · [UptimeObserver](/en/on-call/integration/alert-integration/alert-sources/uptimeobserver) · [UptimeRobot](/en/on-call/integration/alert-integration/alert-sources/uptimerobot) · [Uptimia](/en/on-call/integration/alert-integration/alert-sources/uptimia) · [Uptrends](/en/on-call/integration/alert-integration/alert-sources/uptrends)
+
+### V
+
+[Veeam ONE](/en/on-call/integration/alert-integration/alert-sources/veeam-one) · [Veeam Service Provider Console](/en/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console) · [Veracode SCA](/en/on-call/integration/alert-integration/alert-sources/veracode-sca) · [Vigil](/en/on-call/integration/alert-integration/alert-sources/vigil) · [Volcengine Cloud Monitor Event Center](/en/on-call/integration/alert-integration/alert-sources/volcengine-cm-event) · [Volcengine Cloud Monitor](/en/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics) · [Volcengine Cloud-Detect](/en/on-call/integration/alert-integration/alert-sources/volcengine-dial) · [Volcengine RTC](/en/on-call/integration/alert-integration/alert-sources/volcengine-rtc) · [Volcengine Log Service (TLS)](/en/on-call/integration/alert-integration/alert-sources/volcengine-tls)
+
+### W
+
+[Wazuh](/en/on-call/integration/alert-integration/alert-sources/wazuh) · [WeCom Bot Compatible](/en/on-call/integration/alert-integration/alert-sources/wecom-alert) · [WhaTap](/en/on-call/integration/alert-integration/alert-sources/whatap) · [WhatsUp Gold](/en/on-call/integration/alert-integration/alert-sources/whatsup-gold) · [Wormly](/en/on-call/integration/alert-integration/alert-sources/wormly)
+
+### X
+
+[Xitoring](/en/on-call/integration/alert-integration/alert-sources/xitoring)
+
+### Z
+
+[Zabbix](/en/on-call/integration/alert-integration/alert-sources/zabbix) · [Zeek](/en/on-call/integration/alert-integration/alert-sources/zeek) · [Zenoss](/en/on-call/integration/alert-integration/alert-sources/zenoss) · [Zilliz](/en/on-call/integration/alert-integration/alert-sources/zilliz) · [zstack](/en/on-call/integration/alert-integration/alert-sources/zstack)
diff --git a/en/on-call/integration/change-integration/apollo.mdx b/en/on-call/integration/change-integration/apollo.mdx
index 88c2b1f9..dd2a9346 100644
--- a/en/on-call/integration/change-integration/apollo.mdx
+++ b/en/on-call/integration/change-integration/apollo.mdx
@@ -1,5 +1,6 @@
---
title: "Apollo config center change integration"
+sidebarTitle: "Apollo config center"
description: "Sync every Apollo config release, rollback, gray release, and full release to Flashduty On-call through the Apollo Portal release webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Apollo", "Ctrip Apollo", "config center", "config release", "Webhook"]
---
@@ -15,7 +16,6 @@ Apollo sends a webhook only after the operation is done and has no start event,
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Apollo** and enter an integration name
@@ -25,7 +25,6 @@ Apollo sends a webhook only after the operation is done and has no start event,
</div>
## Configure Apollo
----
Apollo supports the config release webhook since version 1.8.0. The settings live in the `ApolloPortalDB.ServerConfig` table. You can also edit them on the Apollo Portal page **Administrator Tools → System Parameters**; a change takes effect in about a minute.
@@ -64,7 +63,6 @@ Apollo has no test delivery: publish a config in any environment that has the we
</Steps>
## What one change is
----
One change is one Apollo release operation. Its change key (`change_key`) is `<environment>/<release history ID>`, for example `PRO/1234`.
@@ -75,7 +73,6 @@ The `releaseId` in the payload is not used as the key. When you roll back, Apoll
Two releases of the same namespace are two changes, and so are a release and a later rollback.
## Status mapping
----
The `operation` Apollo sends decides the kind of change; the status is Done, except for abandoned releases (see the note below the table):
@@ -91,7 +88,6 @@ When `isReleaseAbandoned` in the payload is `true` (the release the delivery des
Any `operation` value other than the four above returns InvalidParameter and creates no change.
## Change content
----
| Field | Content |
|---|---|
@@ -118,7 +114,6 @@ Labels can be used for routing and for filtering the change list:
| `emergency` | `true` for an emergency release |
## FAQ
----
<AccordionGroup>
<Accordion title="Why can't I see the config values?">
diff --git a/en/on-call/integration/change-integration/argo-rollouts.mdx b/en/on-call/integration/change-integration/argo-rollouts.mdx
index 4d13ff3d..0d98f97c 100644
--- a/en/on-call/integration/change-integration/argo-rollouts.mdx
+++ b/en/on-call/integration/change-integration/argo-rollouts.mdx
@@ -1,5 +1,6 @@
---
title: "Argo Rollouts change integration"
+sidebarTitle: "Argo Rollouts"
description: "Sync Argo Rollouts releases to Flashduty On-call through the built-in Argo Rollouts Notifications webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Argo Rollouts", "Rollout", "canary", "blue-green", "progressive delivery", "Notifications", "Webhook", "deployment events"]
---
@@ -13,7 +14,6 @@ Both the canary and blue-green strategies are recorded. Analysis run failures, p
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Argo Rollouts** and enter an integration name
@@ -23,7 +23,6 @@ Both the canary and blue-green strategies are recorded. Analysis run failures, p
</div>
## Configure Argo Rollouts
----
The steps below need Kubernetes permission to edit ConfigMaps in the Argo Rollouts controller namespace (`argo-rollouts` by default) and to edit annotations on Rollouts. The Argo Rollouts controller must be able to reach the domain of the push URL.
@@ -189,7 +188,6 @@ Argo Rollouts has no way to send a test message. Change the image of a subscribe
</Steps>
## What one change is
----
One change is one release revision of one Rollout. The change key (change_key) is `<rollout_uid>/<revision>`:
@@ -201,7 +199,6 @@ So the start, completion, and abort of one revision update the same change; two
Flashduty rejects a request that lacks `event`, `rollout_uid`, `revision`, or `event_time`.
## Status mapping
----
| Trigger | Event (`event`) | Meaning | Flashduty change status |
|---|---|---|---|
@@ -217,7 +214,6 @@ Done and Failed are end states; Flashduty records the change's end time. `event`
- After an abort, if you run `kubectl argo rollouts retry` and the rollout eventually completes, the same change is updated from Failed to Done
## Change content
----
- **Title**: `<namespace>/<rollout name>: rollout revision <revision> (<images>)`; images of several containers are comma-separated, and the parenthesized part is omitted when there are none
- **Link**: Argo Rollouts has no web page for a single release, so changes have no link
@@ -235,7 +231,6 @@ Labels can be used for routing and for filtering the change list:
| `event` | Latest event: `updated`, `completed`, `skip_steps`, or `aborted` |
## FAQ
----
<AccordionGroup>
<Accordion title="Why are no changes received?">
diff --git a/en/on-call/integration/change-integration/argocd.mdx b/en/on-call/integration/change-integration/argocd.mdx
index 4fd9bf6d..974218e1 100644
--- a/en/on-call/integration/change-integration/argocd.mdx
+++ b/en/on-call/integration/change-integration/argocd.mdx
@@ -1,5 +1,6 @@
---
title: "Argo CD change integration"
+sidebarTitle: "Argo CD"
description: "Sync Argo CD application sync operations to Flashduty On-call through an Argo CD Notifications webhook service, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Argo CD", "ArgoCD", "GitOps", "Sync", "Notifications", "Webhook", "deployment events"]
---
@@ -13,7 +14,6 @@ Automated syncs, manual syncs from the UI or CLI, and rollbacks are all sync ope
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Argo CD** and enter an integration name
@@ -23,7 +23,6 @@ Automated syncs, manual syncs from the UI or CLI, and rollbacks are all sync ope
</div>
## Configure Argo CD
----
The steps below need Kubernetes permission to edit ConfigMaps in the Argo CD namespace (`argocd` by default) and to edit annotations on Applications or AppProjects. The Argo CD cluster must be able to reach the domain of the push URL.
@@ -137,7 +136,6 @@ Sync a subscribed application (click **Sync** in the UI, or run `argocd app sync
</Steps>
## What one change is
----
One change is one sync operation of one application. Its change key (change_key) is `<app_uid>/<started_at>`:
@@ -149,7 +147,6 @@ So the start, the failed retries, and the final result of one sync update the sa
Flashduty rejects a request that lacks `app_uid` or `started_at`, or whose times are not in RFC 3339 format.
## Status mapping
----
| Argo CD sync phase (`phase`) | Flashduty change status |
|---|---|
@@ -165,7 +162,6 @@ Sync phases are case-sensitive, and other values are rejected. The following del
The recorded time is `started_at` when a sync starts and `finished_at` when it ends. While Argo CD retries a failed sync automatically, the phase stays `Running`, so the change is not marked Failed early.
## Change content
----
- **Title**: `<app name>: sync <revision> to <destination namespace>`. A Git commit shows its first 7 characters; other values, such as a Helm chart version, are shown as is. The revision or destination namespace part is omitted when empty
- **Link**: `<argocdUrl>/applications/<app name>`, only when `context.argocdUrl` is configured
@@ -188,7 +184,6 @@ Labels can be used for routing and for filtering the change list:
Empty fields are not written as labels.
## FAQ
----
<AccordionGroup>
<Accordion title="Why are no changes received?">
diff --git a/en/on-call/integration/change-integration/awx.mdx b/en/on-call/integration/change-integration/awx.mdx
index efd865b0..cf668c4b 100644
--- a/en/on-call/integration/change-integration/awx.mdx
+++ b/en/on-call/integration/change-integration/awx.mdx
@@ -1,5 +1,6 @@
---
title: "AWX / Ansible Automation Platform change integration"
+sidebarTitle: "AWX / Ansible Automation Platform"
description: "Sync every run of your AWX or Ansible Automation Platform job templates and workflows to Flashduty On-call through a webhook notification, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "AWX", "Ansible", "Ansible Automation Platform", "webhook notification", "job template", "automation"]
---
@@ -13,7 +14,6 @@ AWX cannot tell whether a template changes production, so enable the notificatio
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **AWX / Ansible Automation Platform** and enter an integration name
@@ -23,7 +23,6 @@ AWX cannot tell whether a template changes production, so enable the notificatio
</div>
## Configure AWX
----
<Steps>
<Step title="Create a webhook notification template">
@@ -55,7 +54,6 @@ Save, then launch the job template; the change appears in the Flashduty change l
</Steps>
## What one change is
----
Each run of a job template or workflow job is one change. The change key (change_key) is AWX's job ID (`id`), for example `4711`.
@@ -65,7 +63,6 @@ Each run of a job template or workflow job is one change. The change key (change
- Job IDs are unique within one AWX instance. Create a separate integration per instance, otherwise the same job ID on two instances is merged into one change
## Status mapping
----
| Notification | Job status (`status`) | Flashduty change status |
|---|---|---|
@@ -80,7 +77,6 @@ Done, Failed, and Canceled are end states; Flashduty records the change's end ti
With a custom message body, `new` maps to Planned, and `pending` and `waiting` map to Ready; the default body never sends these three.
## Change content
----
| Field | Content |
|---|---|
@@ -104,7 +100,6 @@ Labels can be used for routing and for filtering the change list:
Extra variables (`extra_vars`), credentials, and per-host results may contain sensitive data and are not recorded.
## FAQ
----
<AccordionGroup>
<Accordion title="Why don't I see any changes?">
diff --git a/en/on-call/integration/change-integration/azure-devops.mdx b/en/on-call/integration/change-integration/azure-devops.mdx
index e550e446..92ac43f2 100644
--- a/en/on-call/integration/change-integration/azure-devops.mdx
+++ b/en/on-call/integration/change-integration/azure-devops.mdx
@@ -1,5 +1,6 @@
---
title: "Azure DevOps change integration"
+sidebarTitle: "Azure DevOps"
description: "Sync Azure DevOps pipeline runs and classic release stage deployments to Flashduty On-call through Service Hooks, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Azure DevOps", "Pipelines", "Release", "Service Hooks", "Webhook"]
---
@@ -14,7 +15,6 @@ Use Azure DevOps Service Hooks (Web Hooks) to sync two kinds of objects to Flash
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Azure DevOps** and enter an integration name
@@ -24,7 +24,6 @@ Use Azure DevOps Service Hooks (Web Hooks) to sync two kinds of objects to Flash
</div>
## In Azure DevOps
----
<Steps>
<Step title="Create a service hooks subscription">
@@ -64,7 +63,6 @@ Use **Filters** to limit a subscription to a pipeline, release definition, or st
**Test** sends a sample delivery; Flashduty answers success and records no change.
## What one change is
----
| Azure DevOps object | Change identity (change_key) | Notes |
|---|---|---|
@@ -74,7 +72,6 @@ Use **Filters** to limit a subscription to a pipeline, release definition, or st
<Note>Azure DevOps run ids are unique only within an organization. Create a separate Flashduty integration for each Azure DevOps organization.</Note>
## Status mapping
----
**Pipeline runs** (Run state changed)
@@ -105,7 +102,6 @@ These deliveries return success and record nothing:
- The **Test** delivery of Service Hooks
## Change content
----
| Field | Content |
|---|---|
@@ -126,7 +122,6 @@ Labels can be used for routing and for filtering the change list:
Run events carry no project name, so pipeline runs have no `project` label.
## FAQ
----
<AccordionGroup>
<Accordion title="Does a repeated delivery create a duplicate record?">
diff --git a/en/on-call/integration/change-integration/bitbucket.mdx b/en/on-call/integration/change-integration/bitbucket.mdx
index a7eac835..deb1efa6 100644
--- a/en/on-call/integration/change-integration/bitbucket.mdx
+++ b/en/on-call/integration/change-integration/bitbucket.mdx
@@ -1,5 +1,6 @@
---
title: "Bitbucket change integration"
+sidebarTitle: "Bitbucket"
description: "Sync commit build statuses from Bitbucket Cloud (Pipelines and third-party CI) to Flashduty On-call through a repository webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Bitbucket", "Bitbucket Pipelines", "build status", "deployment", "Webhook", "CI/CD"]
---
@@ -13,7 +14,6 @@ Bitbucket has no separate deployment event, so build statuses are the source of
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Bitbucket** and enter an integration name
@@ -23,7 +23,6 @@ Bitbucket has no separate deployment event, so build statuses are the source of
</div>
## Configure Bitbucket
----
<Steps>
<Step title="Add a webhook">
@@ -50,7 +49,6 @@ In the repository, go to **Repository settings → Webhooks** and click **Add we
</Steps>
## What one change is
----
A Bitbucket build status has no id of its own; it is addressed by repository, commit, and status key (the API path `/commit/<hash>/statuses/build/<key>`). The Flashduty change identifier (change_key) is `<repository uuid>/<commit hash>/<status key>`, so the created and updated events of one build status update the same change.
@@ -59,7 +57,6 @@ A Bitbucket build status has no id of its own; it is addressed by repository, co
- If a third-party CI reuses one key on the same commit (for example when re-running), Bitbucket overwrites the status. In Flashduty the same change returns to in progress and is updated with the new final state when it ends
## Status mapping
----
Flashduty derives the status from `commit_status.state` in the payload:
@@ -75,7 +72,6 @@ Done, Failed, and Canceled are end states, and Flashduty records the change end
These deliveries return success but create no change: `repo:push`, pull request, comment, and other events that are not build statuses, and statuses whose type is not `build`.
## Change content
----
| Field | Content |
|---|---|
@@ -94,7 +90,6 @@ The payload carries no branch, so there is no branch label. Labels can be used f
| `state` | The latest Bitbucket build state |
## FAQ
----
<AccordionGroup>
<Accordion title="Why are no build changes arriving?">
diff --git a/en/on-call/integration/change-integration/buildkite.mdx b/en/on-call/integration/change-integration/buildkite.mdx
index a44fd0b5..0b299ed5 100644
--- a/en/on-call/integration/change-integration/buildkite.mdx
+++ b/en/on-call/integration/change-integration/buildkite.mdx
@@ -1,5 +1,6 @@
---
title: "Buildkite change integration"
+sidebarTitle: "Buildkite"
description: "Sync Buildkite pipeline builds to Flashduty On-call through a Buildkite webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Buildkite", "build", "deployment", "Webhook", "CI/CD"]
---
@@ -13,7 +14,6 @@ We recommend sending only deployment pipelines: select those pipelines in the we
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Buildkite** and enter an integration name
@@ -23,7 +23,6 @@ We recommend sending only deployment pipelines: select those pipelines in the we
</div>
## Configure Buildkite
----
<Steps>
<Step title="Add a webhook notification service">
@@ -51,12 +50,10 @@ In your Buildkite organization, go to **Settings → Notification Services** and
</Steps>
## What one change is
----
One build is one change. Its change identifier (change_key) is the build's `build.id`, a UUID unique across Buildkite. Every `build.*` event of the same build updates the same change; two builds of the same pipeline and branch are two changes, and a rebuild creates a new build and a new change.
## Status mapping
----
Flashduty takes the status from `build.state` in the delivery:
@@ -74,7 +71,6 @@ Done, Failed, and Canceled are end states; Flashduty records the change's end ti
These deliveries return success but create no change: `ping` and other non-build events such as `job.*`, `agent.*`, and `cluster_token.*`.
## Change content
----
| Field | Content |
|---|---|
@@ -97,7 +93,6 @@ Use labels for routing and for filtering the change list:
| `state` | The latest Buildkite build state; `blocked` while waiting on a block step |
## FAQ
----
<AccordionGroup>
<Accordion title="Why are no build changes arriving?">
diff --git a/en/on-call/integration/change-integration/circleci.mdx b/en/on-call/integration/change-integration/circleci.mdx
index 9fed1c03..71e32376 100644
--- a/en/on-call/integration/change-integration/circleci.mdx
+++ b/en/on-call/integration/change-integration/circleci.mdx
@@ -1,5 +1,6 @@
---
title: "CircleCI change integration"
+sidebarTitle: "CircleCI"
description: "Sync CircleCI workflow results to Flashduty On-call through a CircleCI outbound webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "CircleCI", "workflow", "CI/CD", "Webhook"]
---
@@ -13,7 +14,6 @@ CircleCI sends the `workflow-completed` event only when a workflow ends and has
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **CircleCI** and enter an integration name
@@ -23,7 +23,6 @@ CircleCI sends the `workflow-completed` event only when a workflow ends and has
</div>
## Configure CircleCI
----
<Steps>
<Step title="Open the project's Webhooks settings">
@@ -55,14 +54,12 @@ Click **Test Ping Event**. Flashduty returns success and records no change. Then
</Steps>
## What one change is
----
| CircleCI object | Change key (change_key) | Notes |
|---|---|---|
| Workflow | `workflow.id` | Each workflow of a pipeline run has its own ID and becomes one Flashduty change; two runs on the same project and branch are two changes |
## Status mapping
----
| CircleCI `workflow.status` | Flashduty change status |
|---|---|
@@ -79,7 +76,6 @@ These deliveries return success and record nothing:
- any other event type
## Change content
----
| Field | Content |
|---|---|
@@ -105,7 +101,6 @@ Labels for routing and filtering the change list:
| `circleci_state` | The raw CircleCI workflow status |
## FAQ
----
<AccordionGroup>
<Accordion title="Why is there no running state for a workflow?">
diff --git a/en/on-call/integration/change-integration/coolify.mdx b/en/on-call/integration/change-integration/coolify.mdx
index 9e92bc8f..03b4e8c4 100644
--- a/en/on-call/integration/change-integration/coolify.mdx
+++ b/en/on-call/integration/change-integration/coolify.mdx
@@ -1,5 +1,6 @@
---
title: "Coolify change integration"
+sidebarTitle: "Coolify"
description: "Sync Coolify application deployment results to Flashduty On-call through Coolify's webhook notification channel, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Coolify", "deployment", "PaaS", "Webhook"]
---
@@ -13,7 +14,6 @@ Coolify sends a notification only when a deployment ends and has no start event,
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Coolify** and enter an integration name
@@ -23,7 +23,6 @@ Coolify sends a notification only when a deployment ends and has no start event,
</div>
## Configure Coolify
----
<Steps>
<Step title="Open the webhook notification channel">
@@ -52,7 +51,6 @@ Click the test notification button. Flashduty returns success and records no cha
</Steps>
## What one change is
----
| Coolify object | Change key (change_key) | Notes |
|---|---|---|
@@ -61,7 +59,6 @@ Click the test notification button. Flashduty returns success and records no cha
For a multi-server deployment, Coolify sends one notification after all servers finish: the main deployment's UUID when all succeed, or the UUID of the first deployment that did not succeed.
## Status mapping
----
| Coolify `event` | Flashduty change status |
|---|---|
@@ -75,7 +72,6 @@ These deliveries return success and record nothing:
- backup, scheduled task, Docker cleanup, server and container events
## Change content
----
| Field | Content |
|---|---|
@@ -99,7 +95,6 @@ Labels can be used for routing and for filtering the change list:
| `coolify_event` | The raw Coolify event name |
## FAQ
----
<AccordionGroup>
<Accordion title="Why is there no in-progress state for a deployment?">
diff --git a/en/on-call/integration/change-integration/custom-event.mdx b/en/on-call/integration/change-integration/custom-event.mdx
index 0896d868..bb8e8cb2 100644
--- a/en/on-call/integration/change-integration/custom-event.mdx
+++ b/en/on-call/integration/change-integration/custom-event.mdx
@@ -1,5 +1,6 @@
---
title: "Custom Change Events"
+sidebarTitle: "Custom"
description: "Push change events from your own systems to Flashduty On-call via standard protocol. Most incidents are caused by changes, and linking changes with alert events helps quickly identify incident root causes"
---
@@ -13,7 +14,7 @@ Flashduty On-call has adapted webhook protocols for some common ticketing and de
<Steps>
<Step title="Enter Integration Center">
-Go to Flashduty console, select **Integration Center => Change Events** to enter the integration selection page.
+Go to Flashduty console, select **Integration Center → Change Events** to enter the integration selection page.
</Step>
<Step title="Create Integration">
diff --git a/en/on-call/integration/change-integration/env0.mdx b/en/on-call/integration/change-integration/env0.mdx
index 85aa477b..213ccd00 100644
--- a/en/on-call/integration/change-integration/env0.mdx
+++ b/en/on-call/integration/change-integration/env0.mdx
@@ -1,5 +1,6 @@
---
title: "env0 change integration"
+sidebarTitle: "env0"
description: "Sync environment deploys and destroys from an env0 webhook notification target to Flashduty On-call as change events correlated with alerts and incidents."
keywords: ["change integration", "env0", "env zero", "Deployment", "Destroy", "Terraform", "Webhook"]
---
@@ -11,7 +12,6 @@ Use an env0 webhook notification target to sync environment deploys and destroys
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **env0** and enter an integration name
@@ -21,7 +21,6 @@ Use an env0 webhook notification target to sync environment deploys and destroys
</div>
## In env0
----
<Steps>
<Step title="Add a webhook notification target">
@@ -53,7 +52,6 @@ Click **Save**. Configure each project separately. Other events (drift, budget,
env0 does not retry a failed webhook delivery, and its delivery timeout is 10 seconds.
## What one change is
----
| env0 object | Change key (change_key) | Notes |
|---|---|---|
@@ -62,7 +60,6 @@ env0 does not retry a failed webhook delivery, and its delivery timeout is 10 se
The key is not the environment ID: one environment has many runs, each with its own deployment log.
## Status mapping
----
| env0 event | Flashduty change status |
|---|---|
@@ -78,7 +75,6 @@ Done, Failed and Canceled are end states; Flashduty records the change's end tim
These deliveries return success and create no change: `com.env0.webhook.test`, `com.env0.pr_plan.failed`, `com.env0.environment.*`, `com.env0.drift.*`, `com.env0.budget.exceeded`, and any other event type that is not a deploy or destroy run.
## Change content
----
| Field | Value |
|---|---|
@@ -99,7 +95,6 @@ Labels are available for routing and for filtering the change list:
| `actor` | Name of the user who started the run; absent for scheduled or automatic runs |
## FAQ
----
<AccordionGroup>
<Accordion title="Does a repeated delivery create a duplicate record?">
diff --git a/en/on-call/integration/change-integration/expo-eas.mdx b/en/on-call/integration/change-integration/expo-eas.mdx
index a57a6a76..0e1aaf69 100644
--- a/en/on-call/integration/change-integration/expo-eas.mdx
+++ b/en/on-call/integration/change-integration/expo-eas.mdx
@@ -1,5 +1,6 @@
---
title: "Expo EAS change integration"
+sidebarTitle: "Expo EAS"
description: "Sync Expo EAS Build and EAS Submit results to Flashduty On-call through EAS webhooks, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Expo", "EAS", "EAS Build", "EAS Submit", "Webhook"]
---
@@ -13,7 +14,6 @@ EAS sends a webhook only when a build or submission ends and has no start event,
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Expo EAS** and enter an integration name
@@ -23,7 +23,6 @@ EAS sends a webhook only when a build or submission ends and has no start event,
</div>
## Configure Expo EAS
----
<Steps>
<Step title="Create a webhook for builds">
@@ -60,7 +59,6 @@ Webhooks are configured per project: create them in each project you want to syn
</Steps>
## What one change is
----
| EAS object | Change key (change_key) | Notes |
|---|---|---|
@@ -68,7 +66,6 @@ Webhooks are configured per project: create them in each project you want to syn
| Submission | `submission:<id>` | `id` is the submission ID (UUID). A build and a submission never merge, even with the same ID |
## Status mapping
----
| EAS `status` | Flashduty change status |
|---|---|
@@ -79,7 +76,6 @@ Webhooks are configured per project: create them in each project you want to syn
The EAS documentation lists only these three end states. Any other value makes the delivery return InvalidParameter and records no change.
## Change content
----
| Field | Content |
|---|---|
@@ -107,7 +103,6 @@ Labels for routing and filtering the change list:
| `expo_state` | The raw EAS `status` |
## FAQ
----
<AccordionGroup>
<Accordion title="Why is there no running state for a build?">
diff --git a/en/on-call/integration/change-integration/flagsmith.mdx b/en/on-call/integration/change-integration/flagsmith.mdx
index 43697096..d7a86b1f 100644
--- a/en/on-call/integration/change-integration/flagsmith.mdx
+++ b/en/on-call/integration/change-integration/flagsmith.mdx
@@ -1,5 +1,6 @@
---
title: "Flagsmith change integration"
+sidebarTitle: "Flagsmith"
description: "Sync Flagsmith feature flag and segment changes to Flashduty On-call through a Flagsmith audit log webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Flagsmith", "Feature Flag", "feature flag", "audit log", "Webhook"]
---
@@ -13,7 +14,6 @@ Flagsmith sends changes that have already taken effect, so each change is record
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Flagsmith** and enter an integration name
@@ -23,7 +23,6 @@ Flagsmith sends changes that have already taken effect, so each change is record
</div>
## Configure Flagsmith
----
<Steps>
<Step title="Create an organisation webhook">
@@ -47,7 +46,6 @@ You need organisation administrator permission. Use the organisation audit webho
Flagsmith sends the audit log of every project in the organisation to this URL. After saving, make a change to any flag and it appears in the Flashduty change list. The **Test your webhook** button in the webhook dialog gets a success response from Flashduty and records no change.
## What one change is
----
| Flagsmith object | Change key (change_key) | Notes |
|---|---|---|
@@ -56,7 +54,6 @@ Flagsmith sends the audit log of every project in the organisation to this URL.
Audit log entry `data.id` increments within one Flagsmith instance. Create one integration per Flagsmith instance: if several instances share an integration, the same `id` from different instances is treated as the same change.
## Status mapping
----
| Flagsmith audit log entry (`related_object_type`) | Flashduty change status |
|---|---|
@@ -71,7 +68,6 @@ These deliveries return success but record no change:
- Flagsmith's test request
## Change content
----
| Field | Content |
|---|---|
@@ -90,7 +86,6 @@ Labels can be used for routing and for filtering the change list:
| `audit_log_id` | Audit log entry ID |
## FAQ
----
<AccordionGroup>
<Accordion title="Does a Flagsmith retry record a duplicate?">
diff --git a/en/on-call/integration/change-integration/fluxcd.mdx b/en/on-call/integration/change-integration/fluxcd.mdx
index 66a7714e..7b1d626a 100644
--- a/en/on-call/integration/change-integration/fluxcd.mdx
+++ b/en/on-call/integration/change-integration/fluxcd.mdx
@@ -1,5 +1,6 @@
---
title: "Flux CD change integration"
+sidebarTitle: "Flux CD"
description: "Sync every revision that Kustomizations and HelmReleases apply to Flashduty On-call through the Flux notification-controller generic Provider, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Flux CD", "Flux", "GitOps", "Kustomization", "HelmRelease", "notification-controller", "Provider", "Alert", "deployment events"]
---
@@ -16,7 +17,6 @@ Events of other kinds (GitRepository, HelmChart, ImageUpdateAutomation, and so o
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Flux CD** and enter an integration name
@@ -26,7 +26,6 @@ Events of other kinds (GitRepository, HelmChart, ImageUpdateAutomation, and so o
</div>
## Configure Flux
----
The steps below need Kubernetes permission to create Providers, Alerts, and Secrets in the `flux-system` namespace (or the namespace where you keep notification config). The notification-controller must be able to reach the domain of the push URL.
@@ -97,7 +96,6 @@ kubectl -n flux-system describe alert flashduty-change
</Steps>
## What one change is
----
One change is one revision applied by one Flux object. Its change key (change_key) is `<object UID>/<revision>`:
@@ -114,7 +112,6 @@ Flux events carry no operation ID, so in two cases an existing change is updated
Flashduty rejects an event without `involvedObject.uid`.
## Status mapping
----
**Kustomization**
@@ -134,7 +131,6 @@ Flashduty rejects an event without `involvedObject.uid`.
Done and Failed are end states, and Flashduty records the change's end time. These events return success but are not recorded: `severity` `trace`; the Kustomization reasons `DependencyNotReady` and `HealthCheckCanceled`; the HelmRelease reasons `PendingRelease` (a stuck release unlocked), `DriftCorrected`, `DriftCorrectionFailed` (drift repair), and `HealthCheckCanceled`; and every event without a revision. Any other `reason` or `severity` is rejected.
## Change content
----
- **Title**: `<namespace>/<object name>: apply <revision> (<kind>)`, for example `apps/webapp: apply main@sha1:731f7ea (Kustomization)`; a HelmRelease uninstall reads `uninstall`. Git commit IDs are shortened to 7 characters in the title
- **Link**: Flux events carry no web address, so changes have no link
@@ -158,7 +154,6 @@ Labels can be used for routing and for filtering the change list:
Every event of one revision should carry the same routing labels: use the same `eventMetadata` in all Alerts, or later events may land in another channel and start a second change there.
## FAQ
----
<AccordionGroup>
<Accordion title="Why don't I see any changes?">
diff --git a/en/on-call/integration/change-integration/gitea.mdx b/en/on-call/integration/change-integration/gitea.mdx
index 414ea3ab..fad3714d 100644
--- a/en/on-call/integration/change-integration/gitea.mdx
+++ b/en/on-call/integration/change-integration/gitea.mdx
@@ -1,5 +1,6 @@
---
title: "Gitea change integration"
+sidebarTitle: "Gitea"
description: "Sync Gitea Actions workflow runs and releases to Flashduty On-call through a Gitea webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Gitea", "Gitea Actions", "workflow", "Release", "Webhook", "deployment events"]
---
@@ -15,7 +16,6 @@ This page covers Gitea. Forgejo names its Actions events differently and sends a
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Gitea** and enter an integration name
@@ -25,7 +25,6 @@ This page covers Gitea. Forgejo names its Actions events differently and sends a
</div>
## Configure Gitea
----
<Steps>
<Step title="Open webhook settings">
@@ -59,7 +58,6 @@ You need admin permission on the repository or organization. The repository must
Gitea's **Test Push Event** sends a fake `push` event; Flashduty returns success and records no change.
## What one change is
----
| Gitea object | Change key (change_key) | Notes |
|---|---|---|
@@ -67,7 +65,6 @@ Gitea's **Test Push Event** sends a fake `push` event; Flashduty returns success
| Release | `release:<release.id>` | Publishing and deleting the same release update the same change |
## Status mapping
----
| Gitea event | Gitea state | Flashduty change status |
|---|---|---|
@@ -85,7 +82,6 @@ Done, Failed and Canceled are end statuses; Flashduty records the change's end t
These deliveries return success and record nothing: every other Gitea event type (including `workflow_job` and the `push` sent by the test button), the release `updated` action, draft releases, and a queued run (the `requested` event with state `queued`, `pending` or `requested`; the change starts when the run starts).
## Change content
----
| Field | Workflow run | Release |
|---|---|---|
@@ -110,7 +106,6 @@ Labels can be used for routing and for filtering the change list:
| `prerelease` | — | `true` for a prerelease |
## FAQ
----
<AccordionGroup>
<Accordion title="Why did I not receive workflow changes?">
diff --git a/en/on-call/integration/change-integration/gitee.mdx b/en/on-call/integration/change-integration/gitee.mdx
index 72252dfc..0d8da14b 100644
--- a/en/on-call/integration/change-integration/gitee.mdx
+++ b/en/on-call/integration/change-integration/gitee.mdx
@@ -1,5 +1,6 @@
---
title: "Gitee change integration"
+sidebarTitle: "Gitee"
description: "Sync branch pushes, tag pushes and merged pull requests to Flashduty On-call through a Gitee WebHook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Gitee", "WebHook", "Push", "Tag", "Pull Request", "merge"]
---
@@ -13,7 +14,6 @@ A Gitee WebHook cannot filter pushes by branch, so with **Push** selected every
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Gitee** and enter an integration name
@@ -23,7 +23,6 @@ A Gitee WebHook cannot filter pushes by branch, so with **Push** selected every
</div>
## Configure Gitee
----
<Steps>
<Step title="Add a WebHook">
@@ -55,7 +54,6 @@ Do not select **Issue** or **Comment**; they do not create changes. After saving
Merging a pull request creates a commit on the target branch. With both **Push** and **Pull Request** selected, one merge can create two changes: the push to the target branch and the pull request merge. If you only need one of them, select only that hook.
## What one change is
----
| Gitee object | Change key (change_key) | Notes |
|---|---|---|
@@ -66,7 +64,6 @@ Merging a pull request creates a commit on the target branch. With both **Push**
The same commit pushed to two branches is two changes.
## Status mapping
----
| Gitee hook | Condition | Flashduty change status |
|---|---|---|
@@ -79,7 +76,6 @@ Done is an end state, so Flashduty records the change's end time.
These deliveries return success and create no change: Issue and comment hooks, pushes that delete a branch or tag, pull request hooks whose `action` is not `merge` (`open`, `update`, `approved`, `close`, `tested`, and so on), and unrecognized hook types.
## Change content
----
| Field | Branch push | Tag push | Pull request merge |
|---|---|---|---|
@@ -102,7 +98,6 @@ Labels are available for routing and for filtering the change list:
| `pull_request_id` / `pull_request_number` | `id` / `number` of the pull request (pull request merges only) |
## FAQ
----
<AccordionGroup>
<Accordion title="Why did every branch push become a change?">
diff --git a/en/on-call/integration/change-integration/github.mdx b/en/on-call/integration/change-integration/github.mdx
index 07d479f6..2588dc45 100644
--- a/en/on-call/integration/change-integration/github.mdx
+++ b/en/on-call/integration/change-integration/github.mdx
@@ -1,5 +1,6 @@
---
title: "GitHub change integration"
+sidebarTitle: "GitHub"
description: "Sync GitHub deployments and releases to Flashduty On-call through a GitHub webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "GitHub", "Deployment", "Release", "Webhook", "deployment events"]
---
@@ -13,7 +14,6 @@ GitHub Actions jobs that declare an `environment` create deployments automatical
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **GitHub** and enter an integration name
@@ -23,7 +23,6 @@ GitHub Actions jobs that declare an `environment` create deployments automatical
</div>
## Configure GitHub
----
<Steps>
<Step title="Open webhook settings">
@@ -55,7 +54,6 @@ After you save, GitHub sends a `ping`. Flashduty accepts it without creating a c
</Steps>
## What one change is
----
| GitHub object | Change key (change_key) | Notes |
|---|---|---|
@@ -63,7 +61,6 @@ After you save, GitHub sends a `ping`. Flashduty accepts it without creating a c
| Release | `release:<release.id>` | Publishing, unpublishing, and deleting one release update the same change |
## Status mapping
----
| GitHub event | GitHub state | Flashduty change status |
|---|---|---|
@@ -82,7 +79,6 @@ Done, Failed, and Canceled are end states; Flashduty records the change's end ti
These deliveries are accepted without creating a change: `ping`, any other event type, the release actions `created`, `edited`, `released`, and `prereleased` (GitHub also sends `published` when a release is published, and that is the one recorded), and the deployment state `inactive` (an older deployment replaced by a newer one; its earlier result stays as it was).
## Change content
----
| Field | Deployment | Release |
|---|---|---|
@@ -106,7 +102,6 @@ Labels can be used in routes and to filter the change list:
| `prerelease` | — | `true` for a pre-release |
## FAQ
----
<AccordionGroup>
<Accordion title="Why are no deployment changes arriving?">
diff --git a/en/on-call/integration/change-integration/gitlab.mdx b/en/on-call/integration/change-integration/gitlab.mdx
index 7c67c155..93393b96 100644
--- a/en/on-call/integration/change-integration/gitlab.mdx
+++ b/en/on-call/integration/change-integration/gitlab.mdx
@@ -1,5 +1,6 @@
---
title: "GitLab change integration"
+sidebarTitle: "GitLab"
description: "Sync GitLab deployments to Flashduty On-call through a GitLab webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "GitLab", "Deployment", "Webhook", "deployment events"]
---
@@ -13,7 +14,6 @@ GitLab CI/CD jobs that declare an `environment` create deployments automatically
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **GitLab** and enter an integration name
@@ -23,7 +23,6 @@ GitLab CI/CD jobs that declare an `environment` create deployments automatically
</div>
## Configure GitLab
----
<Steps>
<Step title="Open webhook settings">
@@ -53,7 +52,6 @@ GitLab's **Test** feature cannot send deployment events. Other events sent with
</Steps>
## What one change is
----
| GitLab object | Change identifier (change_key) | Notes |
|---|---|---|
@@ -62,7 +60,6 @@ GitLab's **Test** feature cannot send deployment events. Other events sent with
`deployment_id` is unique within one GitLab instance. To connect several GitLab instances (for example GitLab.com and a self-managed instance), create one integration per instance.
## Status mapping
----
| GitLab deployment status | Flashduty change status |
|---|---|
@@ -78,7 +75,6 @@ Done, Failed and Canceled are end states; Flashduty records the change's end tim
These deliveries get a success response but create no change: event types other than Deployment (Push, Pipeline and so on), and the protected-environment approval events `approved` and `rejected`. An approval event describes the approval record, not the deployment itself: after an approval GitLab sends `running` when the deployment starts, and after a rejection it sends `failed`; the change status follows those deployment events.
## Change content
----
| Field | Content |
|---|---|
@@ -101,7 +97,6 @@ Labels can be used for routing and for filtering the change list:
| `state` | Latest GitLab deployment status |
## FAQ
----
<AccordionGroup>
<Accordion title="Why are no deployment changes coming in?">
diff --git a/en/on-call/integration/change-integration/growthbook.mdx b/en/on-call/integration/change-integration/growthbook.mdx
index 9b0b2702..0d572be2 100644
--- a/en/on-call/integration/change-integration/growthbook.mdx
+++ b/en/on-call/integration/change-integration/growthbook.mdx
@@ -1,5 +1,6 @@
---
title: "GrowthBook change integration"
+sidebarTitle: "GrowthBook"
description: "Sync GrowthBook feature revision reviews, publishes and reverts to Flashduty On-call through a GrowthBook Event Webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "GrowthBook", "Feature Flag", "feature flag", "Webhook", "Event Webhook"]
---
@@ -11,7 +12,6 @@ Use a GrowthBook Event Webhook to sync feature revisions to Flashduty On-call. E
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **GrowthBook** and enter an integration name
@@ -21,7 +21,6 @@ Use a GrowthBook Event Webhook to sync feature revisions to Flashduty On-call. E
</div>
## Configure in GrowthBook
----
<Steps>
<Step title="Create an Event Webhook">
@@ -57,7 +56,6 @@ Select the events one by one and do not use the `feature.revision.*` wildcard: r
Your GrowthBook version must support `feature.revision.*` events. Before saving, you can click **Test Connection** in the create dialog: it sends a body without an `event` field, and Flashduty returns 200 and records no change. A saved webhook has no Test button in current versions. Then publish a revision on any feature to see it in the Flashduty change list.
## What one change is
----
| GrowthBook object | Change key (change_key) | Notes |
|---|---|---|
@@ -66,7 +64,6 @@ Your GrowthBook version must support `feature.revision.*` events. Before saving,
A feature ID cannot be changed after creation, and revision versions increase within a feature. If you delete a feature and re-create one with the same ID, versions start over and a new revision is merged into the change with the same version number from the old feature.
## Status mapping
----
| GrowthBook event | Meaning | Flashduty change status |
|---|---|---|
@@ -89,7 +86,6 @@ These deliveries return success and record no change:
A `feature.revision.*` event that GrowthBook adds later returns `InvalidParameter` until it is added to the table above, and no change is recorded.
## Change content
----
| Field | Content |
|---|---|
@@ -110,7 +106,6 @@ Labels can be used for routing and for filtering the change list:
`state`, `actor` and `event_type` are updated by every event, so do not route on them; use `feature_id`, which every event carries. Project and environment scope differs between events, so Flashduty does not record it.
## FAQ
----
<AccordionGroup>
<Accordion title="Does a GrowthBook retry create duplicates?">
diff --git a/en/on-call/integration/change-integration/harness-fme.mdx b/en/on-call/integration/change-integration/harness-fme.mdx
index d93f78c0..b9fe00fd 100644
--- a/en/on-call/integration/change-integration/harness-fme.mdx
+++ b/en/on-call/integration/change-integration/harness-fme.mdx
@@ -1,5 +1,6 @@
---
title: "Harness FME change integration"
+sidebarTitle: "Harness FME"
description: "Sync feature flag changes from Harness FME (formerly Split) to Flashduty On-call through the Audit log outgoing webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Harness FME", "Split", "Feature Flag", "feature flag", "Webhook"]
---
@@ -15,7 +16,6 @@ Metric degradation alerts use a different webhook (Metric Alerts); see [Split al
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Harness FME** and enter an integration name
@@ -25,7 +25,6 @@ Metric degradation alerts use a different webhook (Metric Alerts); see [Split al
</div>
## Configure Harness FME
----
<Steps>
<Step title="Add the Outgoing webhook (Audit log)">
@@ -52,7 +51,6 @@ On a free Harness FME plan the Marketplace tab shows **Outgoing Webhook (Audit L
FME has no test delivery button. After saving, change and save any flag in a checked environment, and the record appears in the Flashduty change list.
## What one change is
----
| FME object | Change key (change_key) | Notes |
|---|---|---|
@@ -61,7 +59,6 @@ FME has no test delivery button. After saving, change and save any flag in a che
The payload has no id of its own, so the key combines the environment name, the flag name and the version. If you rename an environment in FME, later changes are recorded under the new name. The payload does not carry the project name: flags in different projects merge into one change only if they share the flag name, the environment name and the version number.
## Status mapping
----
| FME delivery | Flashduty change status |
|---|---|
@@ -70,7 +67,6 @@ The payload has no id of its own, so the key combines the environment name, the
Deliveries whose `type` is not `split` return success and create no change.
## Change content
----
| Field | Content |
|---|---|
@@ -89,7 +85,6 @@ Labels can be used for routing and for filtering the change list:
| `actor` | The editor (`editor`); not written when `editor` is an email address |
## FAQ
----
<AccordionGroup>
<Accordion title="Does an FME retry record a duplicate?">
diff --git a/en/on-call/integration/change-integration/hcp-terraform.mdx b/en/on-call/integration/change-integration/hcp-terraform.mdx
index b7d708ef..65a8b8a6 100644
--- a/en/on-call/integration/change-integration/hcp-terraform.mdx
+++ b/en/on-call/integration/change-integration/hcp-terraform.mdx
@@ -1,5 +1,6 @@
---
title: "HCP Terraform change integration"
+sidebarTitle: "HCP Terraform"
description: "Sync Terraform runs to Flashduty On-call through HCP Terraform workspace notifications, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "HCP Terraform", "Terraform Cloud", "Run", "Webhook", "infrastructure changes"]
---
@@ -11,7 +12,6 @@ Use HCP Terraform (formerly Terraform Cloud) workspace notifications to sync Ter
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **HCP Terraform** and enter an integration name
@@ -21,7 +21,6 @@ Use HCP Terraform (formerly Terraform Cloud) workspace notifications to sync Ter
</div>
## Configure HCP Terraform
----
Notifications are configured per workspace, so configure one for each workspace you want to connect. You need admin permission on the workspace.
@@ -55,14 +54,12 @@ When you save, HCP Terraform sends a verification request. Flashduty accepts it
You can also manage this configuration with the Terraform `tfe` provider: a `tfe_notification_configuration` resource with `destination_type = "generic"`, `url` set to the Push URL, and `triggers` set to `["run:created", "run:planning", "run:needs_attention", "run:applying", "run:completed", "run:errored"]`.
## What one change is
----
| HCP Terraform object | Change key (change_key) | Notes |
|---|---|---|
| Run | `run_id`, for example `run-FwnENkvDnrpyFC7M` | Every notification of one run updates the same change; two runs of the same workspace are two changes |
## Status mapping
----
| Notification trigger | Run status (run_status) | Flashduty change status |
|---|---|---|
@@ -82,7 +79,6 @@ Done, Failed, and Canceled are end states; Flashduty records the change's end ti
The following deliveries are accepted without creating a change: the verification request sent on save or by **Send a test** (trigger `verification`), health assessment notifications (`assessment:drifted`, `assessment:check_failure`, `assessment:failed`), and workspace notifications (`workspace:auto_destroy_reminder`, `workspace:auto_destroy_run_results`, `workspace:deleted`).
## Change content
----
| Field | Content |
|---|---|
@@ -102,7 +98,6 @@ Use labels for routing and for filtering the change list:
| `actor` | User who created the run |
## FAQ
----
<AccordionGroup>
<Accordion title="Why are no changes arriving?">
diff --git a/en/on-call/integration/change-integration/heroku.mdx b/en/on-call/integration/change-integration/heroku.mdx
index dbbf0670..82972127 100644
--- a/en/on-call/integration/change-integration/heroku.mdx
+++ b/en/on-call/integration/change-integration/heroku.mdx
@@ -1,5 +1,6 @@
---
title: "Heroku Change Integration"
+sidebarTitle: "Heroku"
description: "Sync Heroku app releases to Flashduty On-call through an app webhook, so they appear as changes next to alerts and incidents."
keywords: ["change integration", "Heroku", "release", "webhook"]
---
@@ -11,7 +12,6 @@ Subscribe a Heroku app webhook to `api:release` to sync the app's releases to Fl
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Heroku** and enter an integration name
@@ -21,7 +21,6 @@ Subscribe a Heroku app webhook to `api:release` to sync the app's releases to Fl
</div>
## In Heroku
----
<Steps>
<Step title="Create the app webhook">
@@ -50,7 +49,6 @@ Heroku has no test delivery. Run `git push heroku main`, or change a config var
</Steps>
## What one change is
----
| Heroku object | Change key (`change_key`) | Notes |
|---|---|---|
@@ -59,7 +57,6 @@ Heroku has no test delivery. Run `git push heroku main`, or change a config var
The release version (`v12`) is unique only within an app, so it is not used as the key. It appears in the title and the `version` label only.
## Status mapping
----
| Heroku `data.status` | Flashduty change status |
|---|---|
@@ -77,7 +74,6 @@ Builds are not recorded on their own: a successful build creates the release tha
A `data.status` outside the table returns `InvalidParameter` (see the FAQ).
## Change content
----
| Field | Content |
|---|---|
@@ -101,7 +97,6 @@ Labels can be used for routing and for filtering the change list:
Heroku deliveries identify the user who triggered a release only by email. Emails are never written to labels, so there is no `actor` label.
## FAQ
----
<AccordionGroup>
<Accordion title="Do Heroku retries create duplicate records?">
diff --git a/en/on-call/integration/change-integration/jenkins.mdx b/en/on-call/integration/change-integration/jenkins.mdx
index bf2d842b..fb03a29d 100644
--- a/en/on-call/integration/change-integration/jenkins.mdx
+++ b/en/on-call/integration/change-integration/jenkins.mdx
@@ -1,5 +1,6 @@
---
title: "Jenkins change integration"
+sidebarTitle: "Jenkins"
description: "Sync every build of your Jenkins deployment jobs to Flashduty On-call through the Jenkins Notification plugin, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Jenkins", "Notification plugin", "build", "deployment events"]
---
@@ -13,7 +14,6 @@ Jenkins cannot tell whether a build changed anything, so add the notification on
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Jenkins** and enter an integration name
@@ -23,7 +23,6 @@ Jenkins cannot tell whether a build changed anything, so add the notification on
</div>
## Configure Jenkins
----
<Steps>
<Step title="Check the Jenkins URL">
@@ -61,7 +60,6 @@ Run the job once; the change appears in the Flashduty change list. The Notificat
</Steps>
## What one change is
----
Each build is one change. Its change key (change_key) is `<full build URL>#<queue ID>`, for example `https://jenkins.example.com/job/deploy/18/#4711`.
@@ -71,7 +69,6 @@ Each build is one change. Its change key (change_key) is `<full build URL>#<queu
- When several Jenkins instances send to the same integration, their build URLs differ, so their builds are kept apart
## Status mapping
----
| Build phase (phase) | Build result (status) | Flashduty change status |
|---|---|---|
@@ -90,7 +87,6 @@ The plugin sends QUEUED only when the build starts, never while the build waits
A `notifyEndpoints` step in a pipeline with `phase` set to `NONE` is accepted without creating a change.
## Change content
----
| Field | Content |
|---|---|
@@ -112,7 +108,6 @@ Labels can be used in routes and to filter the change list:
`branch` and `commit` are sent only by freestyle jobs that use Git under **Source Code Management**. A Pipeline job that checks out with the `git` step does not send them. A notification sent when the build starts can carry the values from before this build's checkout, so rely on the values at the end of the build. Route on `job`; otherwise the early and late events of one build can land in different channels.
## FAQ
----
<AccordionGroup>
<Accordion title="Why are no changes arriving?">
diff --git a/en/on-call/integration/change-integration/jfrog-artifactory.mdx b/en/on-call/integration/change-integration/jfrog-artifactory.mdx
index 4dcee68d..50a323a0 100644
--- a/en/on-call/integration/change-integration/jfrog-artifactory.mdx
+++ b/en/on-call/integration/change-integration/jfrog-artifactory.mdx
@@ -1,5 +1,6 @@
---
title: "JFrog Artifactory change integration"
+sidebarTitle: "JFrog Artifactory"
description: "Sync artifact deploys, deletes, moves, and copies from JFrog Artifactory to Flashduty On-call through a webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "JFrog", "Artifactory", "artifact", "Webhook", "change events"]
---
@@ -11,7 +12,6 @@ Use a JFrog Artifactory predefined webhook to sync artifact deploys, deletes, mo
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **JFrog Artifactory** and enter an integration name
@@ -21,7 +21,6 @@ Use a JFrog Artifactory predefined webhook to sync artifact deploys, deletes, mo
</div>
## Configure JFrog Artifactory
----
<Steps>
<Step title="Create a webhook">
@@ -54,7 +53,6 @@ You need admin or project admin permission.
</Steps>
## What one change is
----
JFrog payloads carry no change ID, so Flashduty identifies an artifact by its location plus its content checksum:
@@ -67,7 +65,6 @@ JFrog payloads carry no change ID, so Flashduty identifies an artifact by its lo
For moved and copied, `<repository>/<path>` is the artifact's original location and `<target>` is the payload's `target_repo_path`.
## Status mapping
----
| Artifactory event (event_type) | Flashduty change status |
|---|---|
@@ -81,7 +78,6 @@ Artifactory sends artifact events after the operation completes, so each change
The following deliveries return success but record no change: event domains other than artifacts (Artifact Properties, Docker, Builds, Release Bundles, and so on), `cached` (a remote repository caching a downloaded artifact, which is not a change), and the sample data sent by the **Test** button.
## Change content
----
| Field | deployed, deleted | moved, copied |
|---|---|---|
@@ -105,7 +101,6 @@ Labels can be used in routes and to filter the change list:
| `event_type` | Artifactory event: `deployed`, `deleted`, `moved`, or `copied` |
## FAQ
----
<AccordionGroup>
<Accordion title="Why are no changes arriving?">
diff --git a/en/on-call/integration/change-integration/jira.mdx b/en/on-call/integration/change-integration/jira.mdx
index 9dfacb3d..8e2906c3 100644
--- a/en/on-call/integration/change-integration/jira.mdx
+++ b/en/on-call/integration/change-integration/jira.mdx
@@ -1,5 +1,6 @@
---
title: "Jira Change Integration"
+sidebarTitle: "Jira"
description: "Sync Jira issue creates, updates and deletes to Flashduty On-call through a Jira webhook, so they appear as changes next to alerts and incidents."
keywords: ["change integration", "Jira", "issue", "webhook", "change request"]
---
@@ -17,7 +18,6 @@ This page brings Jira issues in as change events. To create a Jira issue automat
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Jira** and enter an integration name
@@ -27,7 +27,6 @@ This page brings Jira issues in as change events. To create a Jira issue automat
</div>
## In Jira
----
<Steps>
<Step title="Check permissions and network">
@@ -58,7 +57,6 @@ Create an issue that matches the JQL, or change the status of an existing one. T
</Steps>
## What a change is
----
| Jira object | Change key (change_key) | Notes |
|---|---|---|
@@ -69,7 +67,6 @@ Issue updated pushes are handled the same whatever the update type (`issue_event
The following pushes return success without creating a change: events other than issue created, updated and deleted, such as comment, worklog, sprint, version and project events.
## Status mapping
----
Flashduty reads the issue's `status.name` from the push, case-insensitively, and converts it as follows:
@@ -86,7 +83,6 @@ If the status name is not in the table (for example a custom `Waiting for Approv
When an issue is deleted, Flashduty updates the change with the issue's status at deletion time. The change is not set to Canceled automatically.
## Change content
----
| Field | Content |
|---|---|
@@ -110,7 +106,6 @@ Labels can be used for routing and for filtering in the change list:
| `<Jira label>` | Each issue label becomes one label with the value `true` |
## FAQ
----
<AccordionGroup>
<Accordion title="The change did not update after I changed the issue status">
diff --git a/en/on-call/integration/change-integration/launchdarkly.mdx b/en/on-call/integration/change-integration/launchdarkly.mdx
index 1d942206..59567054 100644
--- a/en/on-call/integration/change-integration/launchdarkly.mdx
+++ b/en/on-call/integration/change-integration/launchdarkly.mdx
@@ -1,5 +1,6 @@
---
title: "LaunchDarkly change integration"
+sidebarTitle: "LaunchDarkly"
description: "Sync LaunchDarkly feature flag and segment changes to Flashduty On-call through a LaunchDarkly webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "LaunchDarkly", "Feature Flag", "feature flag", "Webhook"]
---
@@ -13,7 +14,6 @@ LaunchDarkly sends changes that have already taken effect, so each change is rec
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **LaunchDarkly** and enter an integration name
@@ -23,7 +23,6 @@ LaunchDarkly sends changes that have already taken effect, so each change is rec
</div>
## Configure LaunchDarkly
----
<Steps>
<Step title="Open the Webhooks integration">
@@ -70,14 +69,12 @@ Replace `env/*` with a specific environment (such as `env/production`) to send o
LaunchDarkly has no test delivery button. After saving, make one change to any flag and the record appears in the Flashduty change list.
## What one change is
----
| LaunchDarkly object | Change key (change_key) | Notes |
|---|---|---|
| Change history entry | The entry's `_id` | Every save of a flag or segment creates one entry, which becomes one Flashduty change; turning the same flag on and then off is two changes |
## Status mapping
----
| LaunchDarkly entry | Flashduty change status |
|---|---|
@@ -92,7 +89,6 @@ These deliveries are accepted without creating a change:
- Name, description, tags, maintainer, temporary flag, deprecation, custom properties, rule descriptions, code references, flag links, followers, and segment exports
## Change content
----
| Field | Content |
|---|---|
@@ -114,7 +110,6 @@ Labels can be used in routes and to filter the change list:
| `audit_log_id` | Change history entry ID |
## FAQ
----
<AccordionGroup>
<Accordion title="Why are changes from staging or segments not arriving?">
diff --git a/en/on-call/integration/change-integration/nautobot.mdx b/en/on-call/integration/change-integration/nautobot.mdx
index e11ac10c..41d044f4 100644
--- a/en/on-call/integration/change-integration/nautobot.mdx
+++ b/en/on-call/integration/change-integration/nautobot.mdx
@@ -1,5 +1,6 @@
---
title: "Nautobot change integration"
+sidebarTitle: "Nautobot"
description: "Sync creates, updates and deletes of Nautobot network and infrastructure data (devices, IP addresses, locations and more) to Flashduty On-call through a webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Nautobot", "webhook", "network automation", "configuration change", "source of truth"]
---
@@ -13,7 +14,6 @@ A Nautobot webhook is sent once, after the object is saved. There is no start an
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Nautobot** and enter an integration name
@@ -23,7 +23,6 @@ A Nautobot webhook is sent once, after the object is saved. There is no start an
</div>
## Configure Nautobot
----
<Steps>
<Step title="Create a webhook">
@@ -53,7 +52,6 @@ Edit and save an object of a selected type in Nautobot; the change appears in th
<Warning>Nautobot refuses webhook URLs that resolve to loopback or link-local addresses; Flashduty's Push URL is a public address and is not affected. Nautobot sends webhooks from its Celery worker, so make sure the worker is running and can reach the internet.</Warning>
## What one change is
----
The change key (`change_key`) has three parts: `<model>:<object id>:<request id>`, for example `location:a16ea2bb-…:db6c8eb8-…`.
@@ -63,7 +61,6 @@ The change key (`change_key`) has three parts: `<model>:<object id>:<request id>
- Saving through the web UI and through the API are separate requests, so they are separate changes
## Status mapping
----
| Webhook event (`event`) | Flashduty change status |
|---|---|
@@ -74,7 +71,6 @@ The change key (`change_key`) has three parts: `<model>:<object id>:<request id>
Any other event value (for example from a customized body template) is rejected; see the FAQ below.
## Change content
----
| Field | Content |
|---|---|
@@ -98,7 +94,6 @@ Labels can be used for routing and for filtering the change list:
The object's fields and the before/after snapshots (`snapshots`) may contain sensitive data and are not recorded.
## FAQ
----
<AccordionGroup>
<Accordion title="Why don't I see any changes?">
diff --git a/en/on-call/integration/change-integration/netbox.mdx b/en/on-call/integration/change-integration/netbox.mdx
index ba971782..472f250a 100644
--- a/en/on-call/integration/change-integration/netbox.mdx
+++ b/en/on-call/integration/change-integration/netbox.mdx
@@ -1,5 +1,6 @@
---
title: "NetBox change integration"
+sidebarTitle: "NetBox"
description: "Sync additions, edits, and deletions of infrastructure records such as sites, devices, and IP prefixes to Flashduty On-call through a NetBox event rule webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "NetBox", "DCIM", "IPAM", "event rule", "Webhook"]
---
@@ -13,7 +14,6 @@ NetBox sends changes that have already been saved, so each change is recorded as
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **NetBox** and enter an integration name
@@ -23,7 +23,6 @@ NetBox sends changes that have already been saved, so each change is recorded as
</div>
## Configure NetBox
----
This page is based on the default webhook body of NetBox 4.7.
@@ -54,7 +53,6 @@ This page is based on the default webhook body of NetBox 4.7.
NetBox has no test button. After saving, create or edit an object of a selected type and the change appears in the Flashduty change list. NetBox sends webhooks from a background job, so the `rqworker` process must be running.
## What one change is
----
| NetBox object | Change key (change_key) | Notes |
|---|---|---|
@@ -63,7 +61,6 @@ NetBox has no test button. After saving, create or edit an object of a selected
A bulk operation (bulk import, bulk edit, bulk delete) changes several objects in one request and produces one change per object. They share the same `request_id` label, so you can find everything one operation touched in the change list.
## Status mapping
----
| NetBox event (`event`) | Flashduty change status |
|---|---|
@@ -78,7 +75,6 @@ These deliveries return success but record no change:
NetBox sends a webhook only after a change is saved, so there is no failed or canceled state.
## Change content
----
| Field | Content |
|---|---|
@@ -97,7 +93,6 @@ Labels you can route on and filter the change list by:
| `request_id` | NetBox request ID; the same for every change from one bulk operation |
## FAQ
----
<AccordionGroup>
<Accordion title="Why don't I see a change?">
diff --git a/en/on-call/integration/change-integration/netlify.mdx b/en/on-call/integration/change-integration/netlify.mdx
index 7adc35ed..a5c11e7d 100644
--- a/en/on-call/integration/change-integration/netlify.mdx
+++ b/en/on-call/integration/change-integration/netlify.mdx
@@ -1,5 +1,6 @@
---
title: "Netlify change integration"
+sidebarTitle: "Netlify"
description: "Sync Netlify deploys to Flashduty On-call through Netlify deploy notifications (HTTP POST request), as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Netlify", "deploy notifications", "Deploy notifications", "Webhook", "deployment events"]
---
@@ -13,7 +14,6 @@ Production deploys, branch deploys, and Deploy Previews are all sent; the `envir
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Netlify** and enter an integration name
@@ -23,7 +23,6 @@ Production deploys, branch deploys, and Deploy Previews are all sent; the `envir
</div>
## Configure Netlify
----
Each Netlify notification listens to one event, so add one notification for each event in the table below, all with the same Push URL.
@@ -59,7 +58,6 @@ Deploy locked, Deploy unlocked, and Deploy deleted are not needed: they do not c
</Steps>
## What one change is
----
| Netlify object | Change key (change_key) | Notes |
|---|---|---|
@@ -68,7 +66,6 @@ Deploy locked, Deploy unlocked, and Deploy deleted are not needed: they do not c
A rollback (Deploy restored) publishes an existing deploy again, so it updates that deploy's change with status Done. The rollback notification carries no rollback time, so the event time is when Flashduty receives it.
## Status mapping
----
| Netlify event | Flashduty change status |
|---|---|
@@ -83,7 +80,6 @@ A rollback (Deploy restored) publishes an existing deploy again, so it updates t
Done, Failed, and Canceled are end states; Flashduty records the change's end time when one arrives.
## Change content
----
| Field | Content |
|---|---|
@@ -106,7 +102,6 @@ Labels can be used in routes and to filter the change list:
| `error_message` | Netlify's error message when a deploy fails |
## FAQ
----
<AccordionGroup>
<Accordion title="Why do I only see a deploy start, or only its end?">
diff --git a/en/on-call/integration/change-integration/octopus-deploy.mdx b/en/on-call/integration/change-integration/octopus-deploy.mdx
index 9378fa7e..5dc4cd73 100644
--- a/en/on-call/integration/change-integration/octopus-deploy.mdx
+++ b/en/on-call/integration/change-integration/octopus-deploy.mdx
@@ -1,5 +1,6 @@
---
title: "Octopus Deploy change integration"
+sidebarTitle: "Octopus Deploy"
description: "Sync Octopus Deploy deployments (queued, started, succeeded, failed, canceled) to Flashduty On-call through a subscription webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Octopus Deploy", "deployment", "Subscription", "Webhook"]
---
@@ -11,7 +12,6 @@ Use an Octopus Deploy subscription webhook to sync deployment progress to Flashd
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Octopus Deploy** and enter an integration name
@@ -21,7 +21,6 @@ Use an Octopus Deploy subscription webhook to sync deployment progress to Flashd
</div>
## Configure Octopus Deploy
----
<Steps>
<Step title="Create a subscription">
@@ -57,14 +56,12 @@ Under **Webhook Notifications**, turn the **Enabled** switch on (it is off by de
Octopus Deploy has no test button. After saving, run a deployment and the change appears in the Flashduty change list. The change link depends on the Octopus server address in the payload. Octopus Cloud includes it automatically; for a self-hosted instance, set the public URL under **Configuration → Nodes → Configuration Settings**, otherwise the payload carries no server address and the change has no link.
## What one change is
----
| Octopus object | Change key (change_key) | Notes |
|---|---|---|
| Deployment | The deployment ID, for example `Deployments-12519` | The queued, started, and finished events of one deployment are one change. Deploying the same release to the same environment again is another deployment, so another change |
## Status mapping
----
| Octopus event category | Flashduty change status |
|---|---|
@@ -82,7 +79,6 @@ These deliveries return success but record no change:
A category starting with `Deployment` that Flashduty does not recognize returns `InvalidParameter` with the category name in the message; other events are not affected.
## Change content
----
| Field | Content |
|---|---|
@@ -106,7 +102,6 @@ Labels can be used for routing and for filtering the change list:
Names are read from the event message. When one cannot be read, its label is empty and the title uses the ID instead.
## FAQ
----
<AccordionGroup>
<Accordion title="Does a repeated delivery record a duplicate?">
diff --git a/en/on-call/integration/change-integration/pulumi.mdx b/en/on-call/integration/change-integration/pulumi.mdx
index 44426b78..639a4c68 100644
--- a/en/on-call/integration/change-integration/pulumi.mdx
+++ b/en/on-call/integration/change-integration/pulumi.mdx
@@ -1,5 +1,6 @@
---
title: "Pulumi Cloud change integration"
+sidebarTitle: "Pulumi Cloud"
description: "Sync Pulumi stack updates and Pulumi Deployments runs to Flashduty On-call through Pulumi Cloud webhooks, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Pulumi", "Pulumi Cloud", "Webhook", "stack update", "Pulumi Deployments", "infrastructure changes"]
---
@@ -20,7 +21,6 @@ A webhook can be attached to an organization (it receives events from every stac
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Pulumi** and enter an integration name
@@ -30,7 +30,6 @@ A webhook can be attached to an organization (it receives events from every stac
</div>
## Configure Pulumi Cloud
----
<Steps>
<Step title="Create a webhook">
@@ -64,7 +63,6 @@ Click **Create**.
</Steps>
## What one change is
----
| Pulumi object | Change key (change_key) | Notes |
|---|---|---|
@@ -76,7 +74,6 @@ An update run through Pulumi Deployments sends both a `deployment` and a `stack_
Two updates of the same stack are two changes. The update number and the deployment version are per-stack counters and never repeat within a stack.
## Status mapping
----
Stack updates (`result`):
@@ -99,7 +96,6 @@ Deployments runs (`status`):
Pulumi reports an update or deployment you cancel as `failed`, so it is recorded as Failed. Done, Failed, and Canceled are end states; Flashduty records the change's end time. Pulumi's `result` and `status` can also hold `not started`, `requested`, or `running`, which Flashduty records as Ready or Processing; any other value makes the delivery return an error.
## Change content
----
| Field | Content |
|---|---|
@@ -123,7 +119,6 @@ Labels can be used for routing and for filtering the change list:
`actor` and `operation` can differ between the notifications of one change, so do not route on them; route on `organization`, `project`, and `stack`.
## FAQ
----
<AccordionGroup>
<Accordion title="What is the event time? Does a redelivery record a duplicate?">
diff --git a/en/on-call/integration/change-integration/railway.mdx b/en/on-call/integration/change-integration/railway.mdx
index 476f604e..f12f2a1e 100644
--- a/en/on-call/integration/change-integration/railway.mdx
+++ b/en/on-call/integration/change-integration/railway.mdx
@@ -1,5 +1,6 @@
---
title: "Railway change integration"
+sidebarTitle: "Railway"
description: "Sync Railway service deployments to Flashduty On-call through a Railway project webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Railway", "deployment", "Webhook"]
---
@@ -13,7 +14,6 @@ A Railway webhook is configured per project, and deployments of every environmen
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Railway** and enter an integration name
@@ -23,7 +23,6 @@ A Railway webhook is configured per project, and deployments of every environmen
</div>
## Configure Railway
----
<Steps>
<Step title="Open the project's Webhooks settings">
@@ -51,14 +50,12 @@ Click **Test Webhook** before creating the webhook. Railway sends a sample Volum
</Steps>
## What one change is
----
| Railway object | Change key (change_key) | Notes |
|---|---|---|
| Deployment | `resource.deployment.id` (`details.id` when absent) | Each deployment has its own ID, and every status delivery of that deployment belongs to one change; two deployments of the same service and environment are two changes |
## Status mapping
----
Flashduty reads the delivery's `type` (`Deployment.<state>`) to decide the status and does not read `details.status`. Railway's own webhook guide is inconsistent here: its sample for `Deployment.failed` carries `details.status` set to `SUCCESS`. Deliveries sent by Railway itself pair `Deployment.failed` with `FAILED`, but since the guide shows the two fields disagreeing, `type` is the only one used.
@@ -80,7 +77,6 @@ These deliveries return success but record no change:
A `type` that starts with `Deployment.` and is in neither list above returns `InvalidParameter` (see the FAQ).
## Change content
----
| Field | Content |
|---|---|
@@ -109,7 +105,6 @@ Labels can be used for routing and for filtering the change list:
`ref`, `sha`, and `actor` are not on every delivery, so routing on them can send later states of one deployment to another channel. Route on `workspace`, `project`, `service`, or `environment`.
## FAQ
----
<AccordionGroup>
<Accordion title="Does a Railway retry create a duplicate?">
diff --git a/en/on-call/integration/change-integration/rundeck.mdx b/en/on-call/integration/change-integration/rundeck.mdx
index 471bf4ff..3205ef6e 100644
--- a/en/on-call/integration/change-integration/rundeck.mdx
+++ b/en/on-call/integration/change-integration/rundeck.mdx
@@ -1,5 +1,6 @@
---
title: "Rundeck change integration"
+sidebarTitle: "Rundeck"
description: "Sync every execution of your Rundeck jobs to Flashduty On-call through Rundeck's webhook notification, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Rundeck", "webhook notification", "job execution", "runbook automation"]
---
@@ -13,7 +14,6 @@ Rundeck cannot tell whether a job changes production, so add the notification on
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Rundeck** and enter an integration name
@@ -23,7 +23,6 @@ Rundeck cannot tell whether a job changes production, so add the notification on
</div>
## Configure Rundeck
----
<Steps>
<Step title="Open the job's notification settings">
@@ -54,7 +53,6 @@ Save and run the job once; the change appears in the Flashduty change list. The
</Steps>
## What one change is
----
Each job execution is one change. The change key (change_key) is Rundeck's execution id, for example `4711`.
@@ -64,7 +62,6 @@ Each job execution is one change. The change key (change_key) is Rundeck's execu
- An execution id is unique within one Rundeck server. Create a separate integration for each Rundeck server; otherwise equal execution ids from different servers merge into one change
## Status mapping
----
| Trigger | Execution status (status) | Flashduty change status |
|---|---|---|
@@ -81,7 +78,6 @@ Done, Failed, and Canceled are end statuses; Flashduty records the change's end
`On Average Duration Exceeded` reports an execution that is still running, not a new stage; Flashduty accepts it and records nothing.
## Change content
----
| Field | Content |
|---|---|
@@ -105,7 +101,6 @@ Labels can be used for routing and for filtering the change list:
Job option values may contain secrets and are not recorded.
## FAQ
----
<AccordionGroup>
<Accordion title="Why don't I see any change?">
diff --git a/en/on-call/integration/change-integration/scalr.mdx b/en/on-call/integration/change-integration/scalr.mdx
index c084f417..874d6b44 100644
--- a/en/on-call/integration/change-integration/scalr.mdx
+++ b/en/on-call/integration/change-integration/scalr.mdx
@@ -1,5 +1,6 @@
---
title: "Scalr change integration"
+sidebarTitle: "Scalr"
description: "Sync Terraform and OpenTofu runs to Flashduty On-call through Scalr webhooks, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Scalr", "Terraform", "OpenTofu", "Run", "Webhook", "infrastructure changes"]
---
@@ -11,7 +12,6 @@ Use Scalr webhooks to sync Terraform and OpenTofu runs to Flashduty On-call. Eac
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Scalr** and enter an integration name
@@ -21,7 +21,6 @@ Use Scalr webhooks to sync Terraform and OpenTofu runs to Flashduty On-call. Eac
</div>
## Configure Scalr
----
A webhook is created at account scope and then assigned to environments; once assigned, runs of every workspace in that environment trigger it.
@@ -44,7 +43,6 @@ A new webhook is created with **Allow all current and future environments to hav
</Steps>
## What one change is
----
| Scalr object | Change identifier (change_key) | Notes |
|---|---|---|
@@ -53,7 +51,6 @@ A new webhook is created with **Allow all current and future environments to hav
Scalr sends a delivery at only three moments: a run needs a person's confirmation, a run finishes successfully, and a run errors. Canceling a run or discarding it at the confirmation step sends nothing, so such a run's change stays Planned (or is never created). A change therefore has no Ready or Processing state; its first state is Planned (waiting for confirmation) or an end state. A run that applies automatically produces one record, when it ends.
## Status mapping
----
| Delivery event (event_name) | Run status (run.status) | Flashduty change status |
|---|---|---|
@@ -66,7 +63,6 @@ End events are mapped by run status: `applied` is Done and `errored` is Failed (
These deliveries return success and create no change: an end event whose run status is `planned_and_finished` (a plan-only or no-change run, nothing was applied), and any event outside the `run:` family.
## Change content
----
| Field | Content |
|---|---|
@@ -90,7 +86,6 @@ Labels for routing and for filtering the change list:
Run variables (`variables`) and user emails are not recorded.
## FAQ
----
<AccordionGroup>
<Accordion title="Why don't I see any changes?">
diff --git a/en/on-call/integration/change-integration/semaphore.mdx b/en/on-call/integration/change-integration/semaphore.mdx
index 7d9fbf18..13db1daa 100644
--- a/en/on-call/integration/change-integration/semaphore.mdx
+++ b/en/on-call/integration/change-integration/semaphore.mdx
@@ -1,5 +1,6 @@
---
title: "Semaphore change integration"
+sidebarTitle: "Semaphore"
description: "Sync Semaphore pipeline results to Flashduty On-call through a Semaphore webhook notification, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Semaphore", "pipeline", "CI/CD", "Webhook"]
---
@@ -13,7 +14,6 @@ Semaphore sends a notification only when a pipeline is done (state `done`) and h
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Semaphore** and enter an integration name
@@ -23,7 +23,6 @@ Semaphore sends a notification only when a pipeline is done (state `done`) and h
</div>
## Configure Semaphore
----
<Steps>
<Step title="Create a notification">
@@ -66,14 +65,12 @@ Semaphore has no test delivery. Run a pipeline in a project the notification cov
</Steps>
## What one change is
----
| Semaphore object | Change key (`change_key`) | Notes |
|---|---|---|
| Pipeline | `pipeline.id` | Every pipeline of every run has its own ID and becomes one Flashduty change. Two runs on the same branch are two changes; a pipeline started by a promotion inside a workflow is its own change too |
## Status mapping
----
| Semaphore `pipeline.result` | Flashduty change status |
|---|---|
@@ -87,7 +84,6 @@ These deliveries return success but record no change:
- Deliveries whose `pipeline.state` is not `done`
## Change content
----
| Field | Content |
|---|---|
@@ -114,7 +110,6 @@ Labels for routing and for filtering the change list:
| `semaphore_result` | The raw Semaphore pipeline result |
## FAQ
----
<AccordionGroup>
<Accordion title="Why is there no running state for a pipeline?">
diff --git a/en/on-call/integration/change-integration/teamcity.mdx b/en/on-call/integration/change-integration/teamcity.mdx
index 2267915a..9ee5c02b 100644
--- a/en/on-call/integration/change-integration/teamcity.mdx
+++ b/en/on-call/integration/change-integration/teamcity.mdx
@@ -1,5 +1,6 @@
---
title: "TeamCity change integration"
+sidebarTitle: "TeamCity"
description: "Sync TeamCity build queue, start, and finish states to Flashduty On-call through the TeamCity server's built-in webhooks, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "TeamCity", "build", "deployment", "CI/CD", "Webhook"]
---
@@ -13,7 +14,6 @@ TeamCity webhooks are configured at server and project level and send every buil
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **TeamCity** and enter an integration name
@@ -23,7 +23,6 @@ TeamCity webhooks are configured at server and project level and send every buil
</div>
## Configure TeamCity
----
<Steps>
<Step title="Add the webhook parameters">
@@ -60,14 +59,12 @@ TeamCity has no test delivery. Run a build in a project with the webhook configu
</Steps>
## What one change is
----
| TeamCity object | Change key (change_key) | Notes |
|---|---|---|
| Build | `id` | A build ID is unique across the whole TeamCity server, and the queued, running, and finished events all carry it. Two builds of the same build configuration and branch are two changes. The build number (`number`) is not used: it counts per build configuration, is empty while queued, and shows `N/A` for a canceled build |
## Status mapping
----
| TeamCity event | `status` | Flashduty change status |
|---|---|---|
@@ -86,7 +83,6 @@ These deliveries return success without creating a change:
- Other event types, such as `AGENT_REGISTERED`, `AGENT_UNREGISTERED`, `AGENT_REMOVED`, `CHANGES_LOADED`, and `BUILD_PROBLEMS_CHANGED`
## Change content
----
| Field | Content |
|---|---|
@@ -111,7 +107,6 @@ Labels you can use for routing and for filtering the change list:
| `teamcity_status` | The build status, as sent. Absent while queued, so do not route on it |
## FAQ
----
<AccordionGroup>
<Accordion title="Does a TeamCity resend create a duplicate record?">
diff --git a/en/on-call/integration/change-integration/unleash.mdx b/en/on-call/integration/change-integration/unleash.mdx
index 47fa3bde..b931eeab 100644
--- a/en/on-call/integration/change-integration/unleash.mdx
+++ b/en/on-call/integration/change-integration/unleash.mdx
@@ -1,5 +1,6 @@
---
title: "Unleash change integration"
+sidebarTitle: "Unleash"
description: "Sync Unleash feature flag changes to Flashduty On-call through an Unleash webhook integration, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Unleash", "Feature Flag", "feature flag", "Webhook"]
---
@@ -13,7 +14,6 @@ Unleash sends changes that have already taken effect, so each change is recorded
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Unleash** and enter an integration name
@@ -23,7 +23,6 @@ Unleash sends changes that have already taken effect, so each change is recorded
</div>
## Configure in Unleash
----
<Steps>
<Step title="Create a webhook integration">
@@ -60,7 +59,6 @@ You need permission to manage integrations.
Unleash has no test-delivery button. After saving, change any flag (for example enable an environment) and the record appears in the Flashduty change list.
## What one change is
----
| Unleash object | Change key (`change_key`) | Notes |
|---|---|---|
@@ -69,7 +67,6 @@ Unleash has no test-delivery button. After saving, change any flag (for example
Event `id` increments within one Unleash instance. Create one integration per Unleash instance: if several instances share an integration, events with the same `id` are treated as the same change.
## Status mapping
----
| Unleash event | Flashduty change status |
|---|---|
@@ -82,7 +79,6 @@ These deliveries return success but create no change:
- Events about other resources (projects, environments, users, segments) and deliveries without a `type`
## Change content
----
| Field | Content |
|---|---|
@@ -103,7 +99,6 @@ Labels for routing and for filtering the change list:
| `event_id` | Unleash event ID |
## FAQ
----
<AccordionGroup>
<Accordion title="Does an Unleash retry record a duplicate?">
diff --git a/en/on-call/integration/change-integration/vercel.mdx b/en/on-call/integration/change-integration/vercel.mdx
index 89a2c07b..7feeb85d 100644
--- a/en/on-call/integration/change-integration/vercel.mdx
+++ b/en/on-call/integration/change-integration/vercel.mdx
@@ -1,5 +1,6 @@
---
title: "Vercel change integration"
+sidebarTitle: "Vercel"
description: "Sync deployments, promotions and rollbacks from a Vercel team webhook to Flashduty On-call as change events correlated with alerts and incidents."
keywords: ["change integration", "Vercel", "Deployment", "deployment events", "Instant Rollback", "Webhook"]
---
@@ -13,7 +14,6 @@ Use a Vercel team webhook to sync deployments and production rollbacks (Instant
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Vercel** and enter an integration name
@@ -23,7 +23,6 @@ Use a Vercel team webhook to sync deployments and production rollbacks (Instant
</div>
## In Vercel
----
<Steps>
<Step title="Open webhook settings">
@@ -59,7 +58,6 @@ Vercel then shows a secret. Flashduty does not need it; requests are authenticat
</Steps>
## What one change is
----
| Vercel object | Change key (change_key) | Notes |
|---|---|---|
@@ -67,7 +65,6 @@ Vercel then shows a secret. Flashduty does not need it; requests are authenticat
| Rollback | `rollback:<fromDeploymentId>:<toDeploymentId>` | An Instant Rollback is a separate change and does not modify the records of the replaced or restored deployment |
## Status mapping
----
| Vercel event | Flashduty change status |
|---|---|
@@ -84,7 +81,6 @@ Done, Failed and Canceled are end states; Flashduty records the change's end tim
These deliveries return success without recording a change: event types that do not start with `deployment.` (Project, Feature Flag, Firewall and others); deployment events about checks or integration actions; `deployment.cleanup` (the deployment is permanently deleted after its retention period, which does not change its earlier result).
## Change content
----
| Field | Deployment | Rollback |
|---|---|---|
@@ -109,7 +105,6 @@ Labels can be used for routing and for filtering the change list:
`ref`, `sha` and `actor` come from the deployment metadata of a connected GitHub, GitLab or Bitbucket repository; deployments made directly from the CLI do not have them.
## FAQ
----
<AccordionGroup>
<Accordion title="Why does a production deployment reach Done twice?">
diff --git a/en/on-call/integration/change-integration/yunxiao-appstack.mdx b/en/on-call/integration/change-integration/yunxiao-appstack.mdx
index 1e939f70..b22b24a7 100644
--- a/en/on-call/integration/change-integration/yunxiao-appstack.mdx
+++ b/en/on-call/integration/change-integration/yunxiao-appstack.mdx
@@ -1,5 +1,6 @@
---
title: "Alibaba Cloud DevOps AppStack change integration"
+sidebarTitle: "Alibaba Cloud DevOps AppStack"
description: "Sync Alibaba Cloud DevOps (Yunxiao) AppStack deployment orders (preparing, running, succeeded, failed, canceled) to Flashduty On-call through a webhook, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Alibaba Cloud DevOps", "Yunxiao", "AppStack", "deployment order", "Webhook"]
---
@@ -11,7 +12,6 @@ Use an Alibaba Cloud DevOps (云效) AppStack webhook to sync deployment order (
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Alibaba Cloud DevOps AppStack** and enter an integration name
@@ -21,7 +21,6 @@ Use an Alibaba Cloud DevOps (云效) AppStack webhook to sync deployment order (
</div>
## Configure AppStack
----
<Steps>
<Step title="Create a webhook">
@@ -47,7 +46,6 @@ Under **Trigger Events**, select **Deployment Orders → Status Update**. The ot
The **Test Webhook** button sends a mock "new application" event. Flashduty returns success and records no change, so it only confirms that the URL is reachable. To see a change, run a real deployment.
## What one change is
----
| AppStack object | Change identifier (change_key) | Notes |
|---|---|---|
@@ -56,7 +54,6 @@ The **Test Webhook** button sends a mock "new application" event. Flashduty retu
The top-level `id` in the request body is the ID of each delivery record, not of the order, and is not used in the identifier.
## Status mapping
----
| AppStack order state (`objectAttributes.state`) | Flashduty change status |
|---|---|
@@ -75,7 +72,6 @@ These deliveries return success and create no change:
The seven states above are the order states AppStack documents. Any other state returns `InvalidParameter` with the state value in the message; later updates of that order are not affected.
## Change content
----
| Field | Content |
|---|---|
@@ -100,7 +96,6 @@ Labels can be used for routing and for filtering the change list:
Environment names are read from the order's jobs.
## FAQ
----
<AccordionGroup>
<Accordion title="Does a repeated delivery create a duplicate record?">
diff --git a/en/on-call/integration/change-integration/zadig.mdx b/en/on-call/integration/change-integration/zadig.mdx
index f3c93a4a..21e26b19 100644
--- a/en/on-call/integration/change-integration/zadig.mdx
+++ b/en/on-call/integration/change-integration/zadig.mdx
@@ -1,5 +1,6 @@
---
title: "Zadig change integration"
+sidebarTitle: "Zadig"
description: "Sync Zadig workflow task starts and results to Flashduty On-call through Zadig's system hook or a workflow webhook notification, as change events you can correlate with alerts and incidents."
keywords: ["change integration", "Zadig", "workflow", "CI/CD", "Webhook"]
---
@@ -16,7 +17,6 @@ Zadig offers two webhooks with the same payload:
<div className="hide">
## In Flashduty On-call
----
1. In the Flashduty console, go to **Integration Center → Change Events**
2. Select **Zadig** and enter an integration name
@@ -26,7 +26,6 @@ Zadig offers two webhooks with the same payload:
</div>
## Configure Zadig
----
### Option 1: System hook
@@ -60,7 +59,6 @@ Edit the workflow and add a notification of type **Webhook**. Set the webhook ad
Configuring both options does not create duplicate changes: one task records a given status only once.
## What one change is
----
| Zadig object | Change key (change_key) | Notes |
|---|---|---|
@@ -69,7 +67,6 @@ Configuring both options does not create duplicate changes: one task records a g
Clicking **Retry** on an existing task restarts the same task (the task id does not change), so a retry reopens the original change: its status returns to Ready and is then updated again.
## Status mapping
----
| Zadig `workflow.status` | Flashduty change status |
|---|---|
@@ -89,7 +86,6 @@ These deliveries return success and create no change:
- Deliveries with any other `object_kind`
## Change content
----
| Field | Content |
|---|---|
@@ -111,7 +107,6 @@ Labels are available for routing and for filtering the change list:
| `release_plan_id` | Release plan id (when started by a release plan) |
## FAQ
----
<AccordionGroup>
<Accordion title="Do workflows that only build and do not deploy create changes?">
diff --git a/en/on-call/integration/instant-messaging/dingtalk.mdx b/en/on-call/integration/instant-messaging/dingtalk.mdx
index b5b9e7da..18366414 100644
--- a/en/on-call/integration/instant-messaging/dingtalk.mdx
+++ b/en/on-call/integration/instant-messaging/dingtalk.mdx
@@ -12,9 +12,9 @@ This documentation uses the new version of Dingtalk Open Platform as an example.
<span id="aisre-permissions"></span>
<span id="war-room-scope"></span>
-## AI SRE Required Permissions
+## Required Permissions
-The following list includes all permissions required when the Dingtalk IM integration uses AI SRE, including basic notifications, War Room, AI SRE conversations, and AI-generated post-mortem reports. In the Dingtalk Open Platform **Permission Management** page, request each official permission name below.
+Request these permissions on the Dingtalk Open Platform **Permission Management** page. Basic notifications need the first two; War Room adds items 3–5 (item 5 is also used for one-click user linking); a Dingtalk AI streaming card template adds the last two.
| Official permission name | Purpose |
| :--- | :--- |
@@ -30,7 +30,7 @@ The following list includes all permissions required when the Dingtalk IM integr
If no Dingtalk AI streaming card template is configured, AI SRE falls back to standard interactive cards or session-webhook bot replies. Keep `qyapi_robot_sendmsg` granted in that mode.
</Note>
-## 1. Create Dingtalk App and Add Dingtalk Integration
+## Create Dingtalk App and Add Dingtalk Integration
### 1. Create Custom App
@@ -38,7 +38,7 @@ Visit [Dingtalk Developer Console](https://open-dev.dingtalk.com/fe/app) → App
See Dingtalk development documentation [Create Enterprise Internal App - H5 Mini App](https://open.dingtalk.com/document/orgapp/microapplication-creation-and-release-process#title-ovn-666-1ty).
-
+
You can use the [Flashduty official icon](https://flashduty-public.oss-cn-beijing.aliyuncs.com/icons/flashduty-20251216.png) as the app icon.
@@ -46,7 +46,7 @@ You can use the [Flashduty official icon](https://flashduty-public.oss-cn-beijin
Click the enterprise avatar in the top right corner, copy `CorpId` from the dropdown menu.
-
+
Return to Flashduty On-call integration configuration page, fill in the corresponding `CorpId` in the form.
@@ -54,7 +54,7 @@ Return to Flashduty On-call integration configuration page, fill in the correspo
Enter the created app details page, navigate to App Capabilities → **Credentials & Basic Info** via the left menu, copy `AgentId`, `Client ID`, and `Client Secret`.
-
+
Return to Flashduty On-call integration configuration page, fill in the corresponding `AgentId`, `Client ID`, and `Client Secret` in the form.
@@ -62,7 +62,7 @@ Return to Flashduty On-call integration configuration page, fill in the correspo
Go to Development Configuration → **Events & Callbacks** page. Set push method to `HTTP Push`, then click the button to generate `Encryption aes_key` and `Signature Token`, and copy and save them.
-
+
Return to Flashduty On-call integration configuration page, fill in the corresponding `Encryption aes_key` and `Signature Token`, click **Save**.
@@ -72,11 +72,11 @@ Go to Development Configuration → **Event Subscription** page.
Configure **Event Subscription Request URL** using the `Event Subscription Request URL` from Flashduty integration details. Click **Save** after configuration.
-
+
Below the **Save** button, select these three group chat events: `Group chat name changed`, `Cool app installed in group`, and `Cool app uninstalled from group`, then click **Save**.
-
+
### 6. Add App Capabilities
@@ -86,11 +86,11 @@ Enter the **Edit Cool App** page and complete the following steps:
1. Fill in basic information. You can use the [Flashduty official icon](https://flashduty-public.oss-cn-beijing.aliyuncs.com/icons/flashduty-20251216.png) as the icon.
-
+ 
2. Configure feature design. Select **Group Shortcut Entry** and **Message Card** on the left. You can use the [Flashduty official icon](https://flashduty-public.oss-cn-beijing.aliyuncs.com/icons/flashduty-20251216.png) for the group shortcut icon; copy the **Cool App Web URL** from integration details for desktop and mobile access URLs.
-
+ 
3. Skip step three (Feature Development), proceed to step four **Preview & Publish**, click **Publish** and confirm.
@@ -98,7 +98,7 @@ Enter the **Edit Cool App** page and complete the following steps:
Go to App Capabilities → **Bot** page, enable bot configuration, fill in name and upload icon, then click **Save**. You can use the [Flashduty official icon](https://flashduty-public.oss-cn-beijing.aliyuncs.com/icons/flashduty-20251216.png) as the icon.
-
+
### 8. Configure App URLs
@@ -106,40 +106,29 @@ Go to App Capabilities → **Web App** page.
Configure **App Homepage URL** and **PC Homepage URL** using the `App Homepage URL` and `PC Homepage URL` from Flashduty integration details. Click **Save** when done.
-
+
### 9. Request App Permissions
-Go to Development Configuration → **Permission Management** page, request the following permissions for the group app created in previous steps:
+Go to Development Configuration → **Permission Management** page, request `qyapi_chat_manage` and `qyapi_robot_sendmsg`. If you need War Room or AI SRE streaming cards, request the rest of the [required permissions](#aisre-permissions) as well.
-- `qyapi_chat_manage`: Get group chat information
-- `qyapi_robot_sendmsg`: Send messages to group chats or individuals
-
-If you need AI SRE, also confirm that all [AI SRE required permissions](#aisre-permissions) listed at the beginning of this page have been requested.
-
-
+
<Note>
If you need to continue configuring War Room, publish the custom app once first. After the app is published, you can select it from the **Available Apps** list in Scene Groups. See [App Publishing and Usage](#publish) for the publishing path.
</Note>
-## 2. Configure War Room
+## Configure War Room
<Tip>
If you don't need War Room functionality, skip this step and proceed directly to [**App Publishing and Usage**](#publish).
</Tip>
-> Before configuring War Room, confirm that the app has been granted the [AI SRE required permissions](#aisre-permissions) listed at the beginning of this page.
-
### 1. Request App Permissions
-Go to Development Configuration → **Permission Management** page, request the following permissions for the group app created in previous steps:
+Go to Development Configuration → **Permission Management** and request `qyapi_chat_read`, `qyapi_chat_base_read`, and `qyapi_get_member_by_mobile` (see [Required Permissions](#aisre-permissions) for what each is for).
-- `qyapi_chat_read`: Get group chat information
-- `qyapi_chat_base_read`: Get group chat information
-- `qyapi_get_member_by_mobile`: Allow the current app to get Dingtalk users by phone number for inviting users to join group chats
-
-
+
### 2. Configure Group Template
@@ -147,15 +136,15 @@ Navigate to Open Capabilities → **Scene Groups** via the Dingtalk Open Platfor
1. Configure **Group Bot**. Select **Bot** in the left menu, then click **Create Group Bot**.
-<Note>
-The **Group Bot** configured in this step and the **App Bot** are two different concepts. Group bots are used to automatically create group bots when generating group chats. Group bots and app bots have different **Bot IDs**. To enable War Room for Dingtalk, you must additionally configure a **Group Bot**.
-</Note>
+ <Note>
+ The **Group Bot** here is different from the **App Bot** above: it joins war room group chats automatically when they are created, and it has a different **Bot ID**. War Room requires this additional Group Bot.
+ </Note>
-Fill in the group bot configuration. If you need AISRE, configure **Message Callback URL**, **Message Callback Token**, and **Source Website** as shown below. These fields are used for AISRE Dingtalk message callbacks.
+ Fill in the group bot configuration. If you need AI SRE, configure **Message Callback URL**, **Message Callback Token**, and **Source Website** as shown below. These fields are used for AI SRE Dingtalk message callbacks.
-<Note>
-Dingtalk's current certificate validation for message callback URLs is not compatible with the ACME-issued certificate used by `api.flashcat.cloud`. To ensure Dingtalk can validate the callback URL and deliver messages correctly, replace the domain in the message URL provided by the Flashduty integration configuration page with `dingtalk-message.flashcat.cloud`.
-</Note>
+ <Note>
+ Dingtalk's certificate validation doesn't accept the ACME certificate on `api.flashcat.cloud`, so the message callback URL must use the `dingtalk-message.flashcat.cloud` domain instead (see the table).
+ </Note>
**Example Configuration**:
@@ -172,7 +161,7 @@ Dingtalk's current certificate validation for message callback URLs is not compa
After configuration, click **Create**, then click **Approve**. After "Submission successful" appears in the top right corner, Dingtalk has automatically approved the group bot.
- 
+ 
2. Configure **Group Template**. Select **Group Template** in the left menu, click **Create Group Template**.
@@ -193,8 +182,8 @@ Dingtalk's current certificate validation for message callback URLs is not compa
In **Select Bot** configuration, click **Select Created Bot**, select the group bot created in the previous step. Keep other configurations as default. Finally click **Save Edit**.
- 
- 
+ 
+ 
In the **Fill in Gray Group** step, click **Create Gray Group**, then click **Publish Gray**.
@@ -202,7 +191,7 @@ Dingtalk's current certificate validation for message callback URLs is not compa
3. On the published group template details page, copy **Template ID** and **Bot ID**.
- 
+ 
Return to Flashduty On-call integration configuration page, fill in the corresponding `Template ID` and `Bot ID`, click **Save**.
@@ -210,7 +199,7 @@ Dingtalk's current certificate validation for message callback URLs is not compa
Only one IM integration can have War Room enabled at a time. If you've already enabled War Room in another IM integration (such as Feishu/Lark, Slack, or WeCom), you need to disable it there first before enabling it in the current Dingtalk integration.
</Warning>
-### AI SRE Controls
+## AI SRE Controls
Configure the following AI SRE controls under **Enhanced Features**. Both are enabled by default:
@@ -221,7 +210,7 @@ These controls do not take effect until AI SRE is enabled for the account.
<span id="publish"></span>
-## 3. App Publishing and Usage
+## App Publishing and Usage
After completing the above steps, confirm that the custom app has been published with the latest version. If it has not been published yet, or if you changed app settings after publishing, go to App Publishing → **Version Management & Publishing**, create a new version, and publish it.
@@ -229,35 +218,19 @@ After completing the above steps, confirm that the custom app has been published
To ensure everyone can use the app, adjust the app **Visibility** to all employees before publishing.
</Note>
-
+
After publishing, you can access the app via **Mobile** or **Desktop**. First access requires login to link Dingtalk and Flashduty accounts; subsequent access will be passwordless.
-<Tabs>
-<Tab title="Mobile">
-Dingtalk → Workspace → Search app name → **Open App**
-</Tab>
-
-<Tab title="Desktop">
-Dingtalk → Workspace → Search app name → **Open App**
-</Tab>
-</Tabs>
+On both mobile and desktop: Dingtalk → Workspace → search the app name → **Open App**.
-## 4. Linked Users
+## Linked Users
In the **Linked Users** tab of the integration detail page, you can view the linking status between team members and Dingtalk accounts, and quickly complete batch linking.
### View Linking Status
-The linked users list shows all team members and their linking status. You can filter by:
-
-| Filter | Description |
-| :--- | :--- |
-| **All** | View all team members |
-| **Linked** | View only members who have linked their Dingtalk accounts |
-| **Unlinked** | View only members who have not yet linked their Dingtalk accounts |
-
-Search by name or email is supported.
+The list shows every team member and their linking status. Filter by **All / Linked / Unlinked**, or search by name or email.
### One-Click Linking
@@ -267,7 +240,7 @@ When unlinked members exist, click the **One-Click Link** button. The system wil
The system can only push Dingtalk message notifications after members complete linking. If linking fails, verify that the member's phone number matches their Dingtalk account.
</Tip>
-## 5. FAQ
+## FAQ
<AccordionGroup>
<Accordion title="Messages cannot be delivered to individuals, operation log shows 'App not linked'?">
@@ -282,12 +255,12 @@ Go to Dingtalk → Workspace → Search app name → **Open App**, complete one
<Accordion title="Escalation rule Dingtalk group chat list is empty?">
1. Go to Dingtalk, install the Cool App in the target group chat, otherwise the group chat list cannot be obtained
-
+ 
-
+ 
2. Return to escalation rule configuration page, refresh and reselect the group chat list
-3. If still unable to get the group chat list, try uninstalling the Cool App from the group and retry the above steps. If the issue persists, contact customer or dedicated technical support
+3. If still unable to get the group chat list, try uninstalling the Cool App from the group and retry the above steps. If the issue persists, contact customer support or your dedicated technical support
</Accordion>
<Accordion title="Why isn't War Room working as expected?">
diff --git a/en/on-call/integration/instant-messaging/lark.mdx b/en/on-call/integration/instant-messaging/lark.mdx
index 0e8a71a6..e8f7dfed 100644
--- a/en/on-call/integration/instant-messaging/lark.mdx
+++ b/en/on-call/integration/instant-messaging/lark.mdx
@@ -8,9 +8,9 @@ description: "By integrating a Feishu/Lark custom app, you can receive and respo
<span id="aisre-permissions"></span>
<span id="war-room-scope"></span>
-## AI SRE Required Permissions
+## Required Permissions
-The following list includes all permissions required when the Feishu/Lark IM integration uses AI SRE, including basic notifications, War Room, AI SRE conversations, and AI-generated post-mortem reports. In the Feishu/Lark Open Platform **Permission Management** page, request each official permission name below.
+Request all of these on the Feishu/Lark Open Platform **Permission Management** page (they cover basic notifications, War Room, AI SRE conversations, and AI-generated post-mortems). See [Request App Permissions](#request-permissions) below.
| Official permission name | Purpose |
| :--- | :--- |
@@ -32,14 +32,12 @@ The following list includes all permissions required when the Feishu/Lark IM int
<div className="hide">
{/*
## Video Introduction
----
<Video src="https://download.flashcat.cloud/flashduty/video/feishu.mp4"></Video>
*/}
</div>
-## 1. Create Feishu/Lark App
----
+## Create Feishu/Lark App
### 1. Create Custom App
@@ -47,23 +45,22 @@ Visit [Feishu/Lark Developer Console](https://open.feishu.cn/app) to create an e
For details, see Feishu/Lark development documentation [Create Enterprise Custom App](https://open.feishu.cn/document/uYjL24iN/uMTMuMTMuMTM/development-guide/step1#132c1aac).
-
+
### 2. Copy Credential Information
Go to **Credentials & Basic Info** page, copy `App ID` and `App Secret` for later use.
-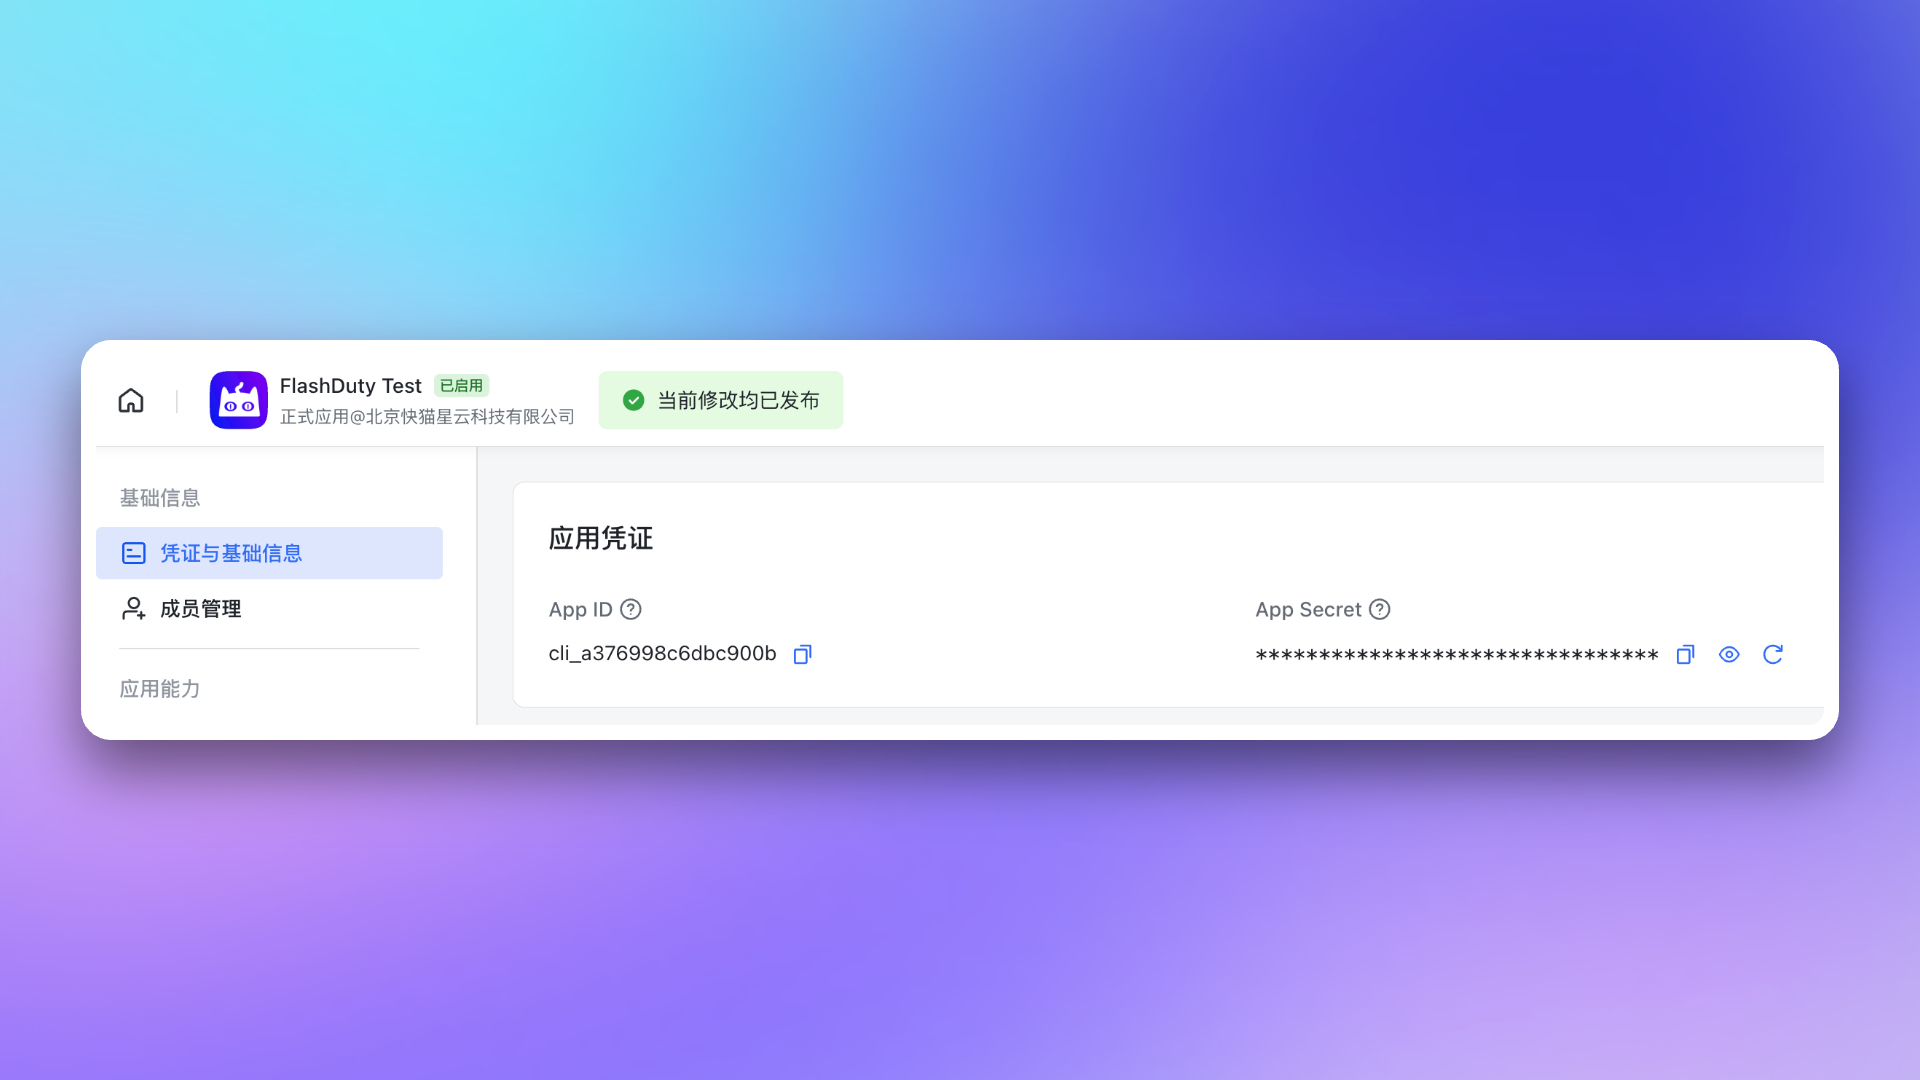
+
### 3. Copy Event Callback Token Information
Go to Development Configuration → Events & Callbacks → **Encryption Strategy** page, generate and copy `Encrypt Key` (recommended for better security) and `Verification Token` for later use.
-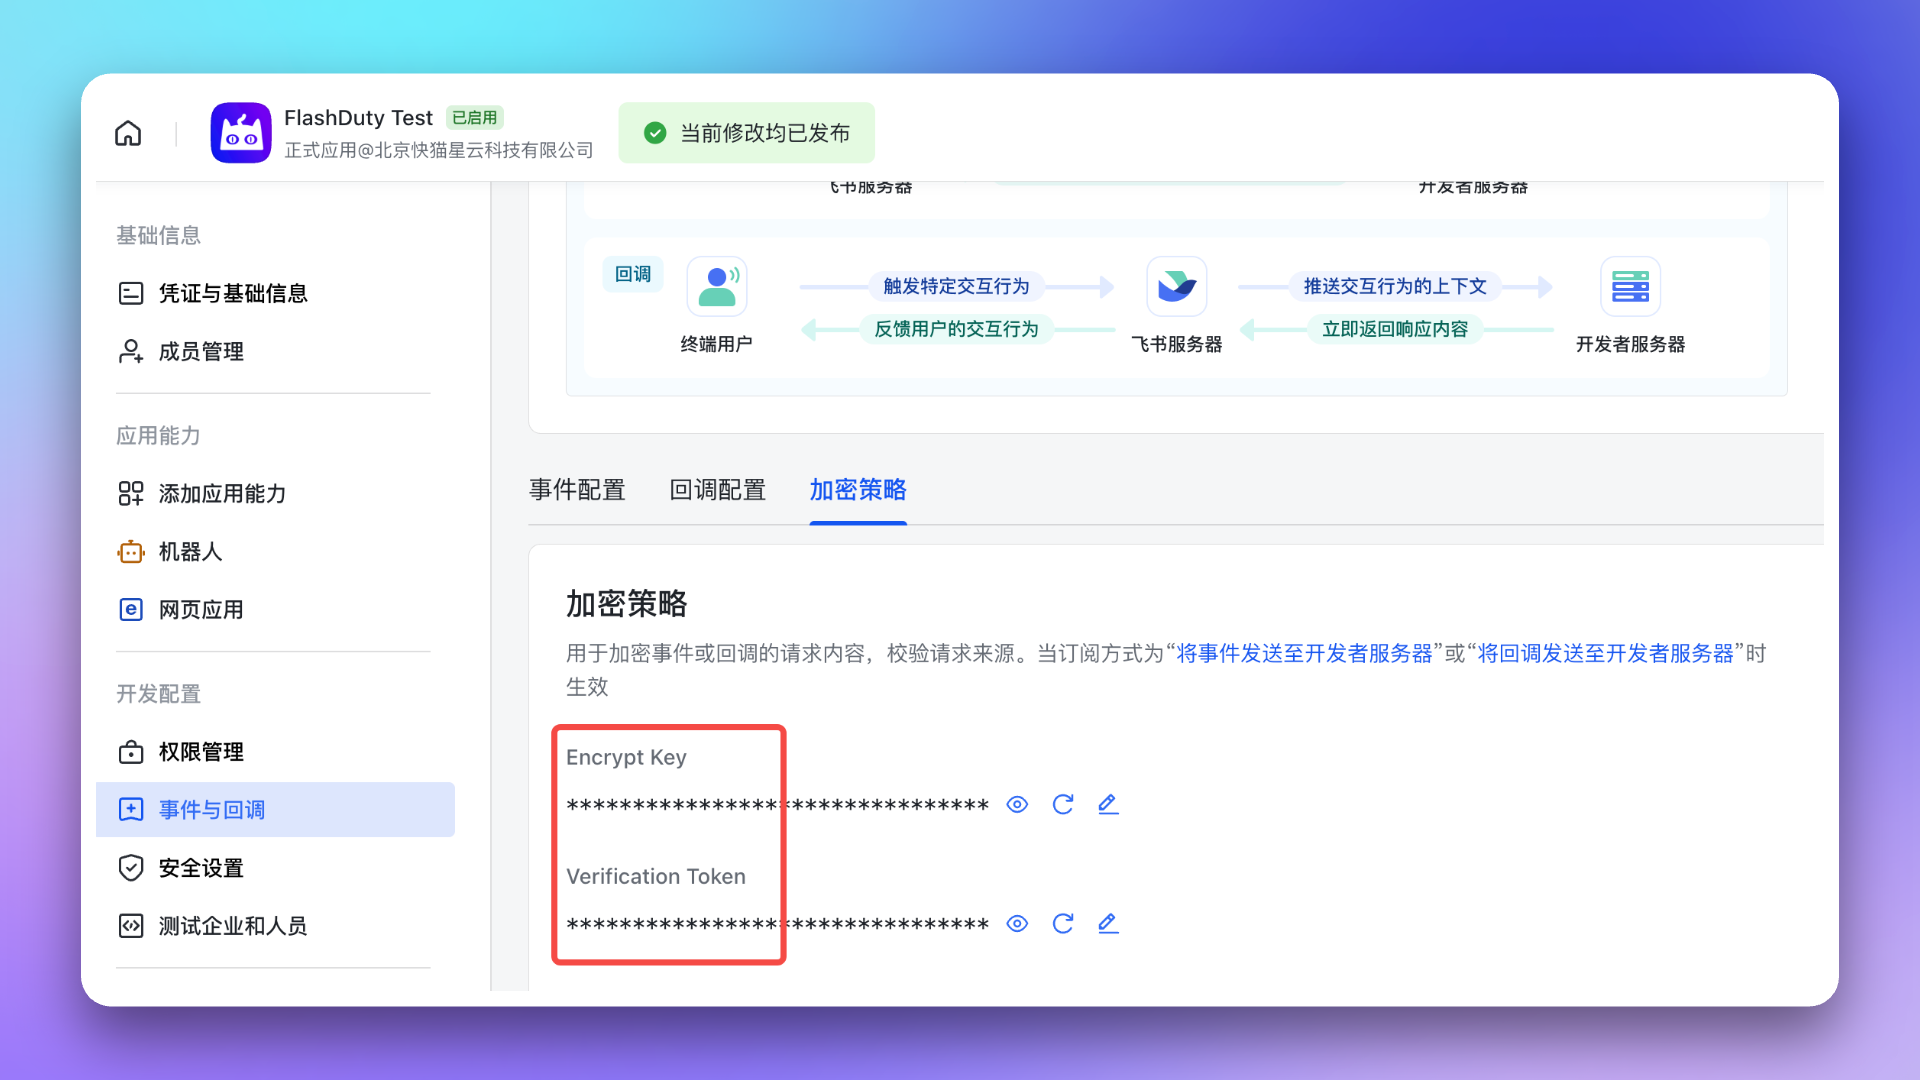
+
-## 2. Add Feishu/Lark Integration
----
+## Add Feishu/Lark Integration
Return to Flashduty On-call **Integration Center** page, select Instant Messaging → **Feishu/Lark**, fill in `Name` and the `App ID`, `App Secret`, `Verification Token`, and `Encrypt Key` copied in the previous step, then click **Save** to complete creation.
@@ -71,34 +68,33 @@ If you use Lark (the international version), also turn on the **Is Lark Version*
After successful creation, you'll see the added Feishu/Lark integration in the list. Click its name to enter the details page to view **Web Configuration** URL, **Redirect URL**, and **Message Card Request URL**, which will be used in subsequent steps.
-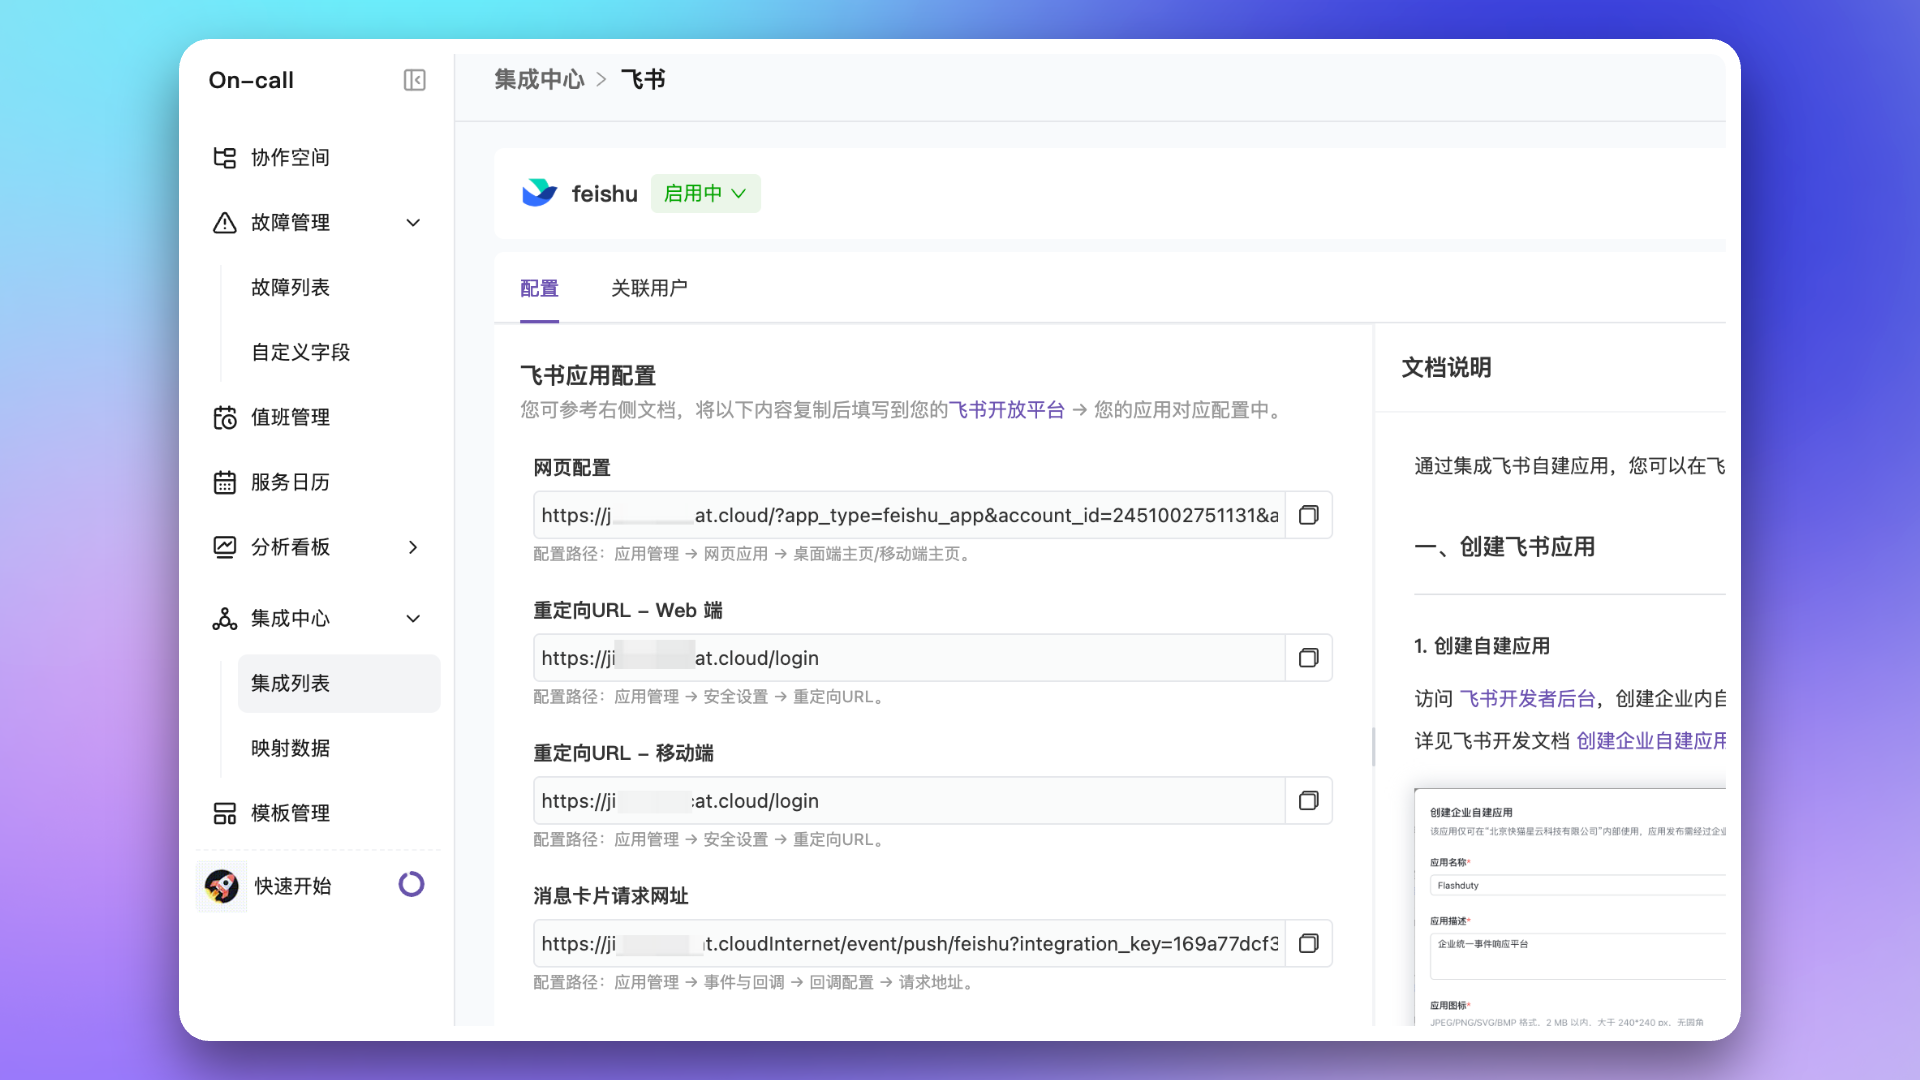
+
-## 3. Configure Feishu/Lark App
----
+## Configure Feishu/Lark App
### 1. Enable and Configure App Capabilities
1. Return to Feishu/Lark Developer Console, enter the Feishu/Lark app you just created, go to Add App Capabilities → **Add by Capability** page, and enable both **Web App** and **Bot** capabilities.
-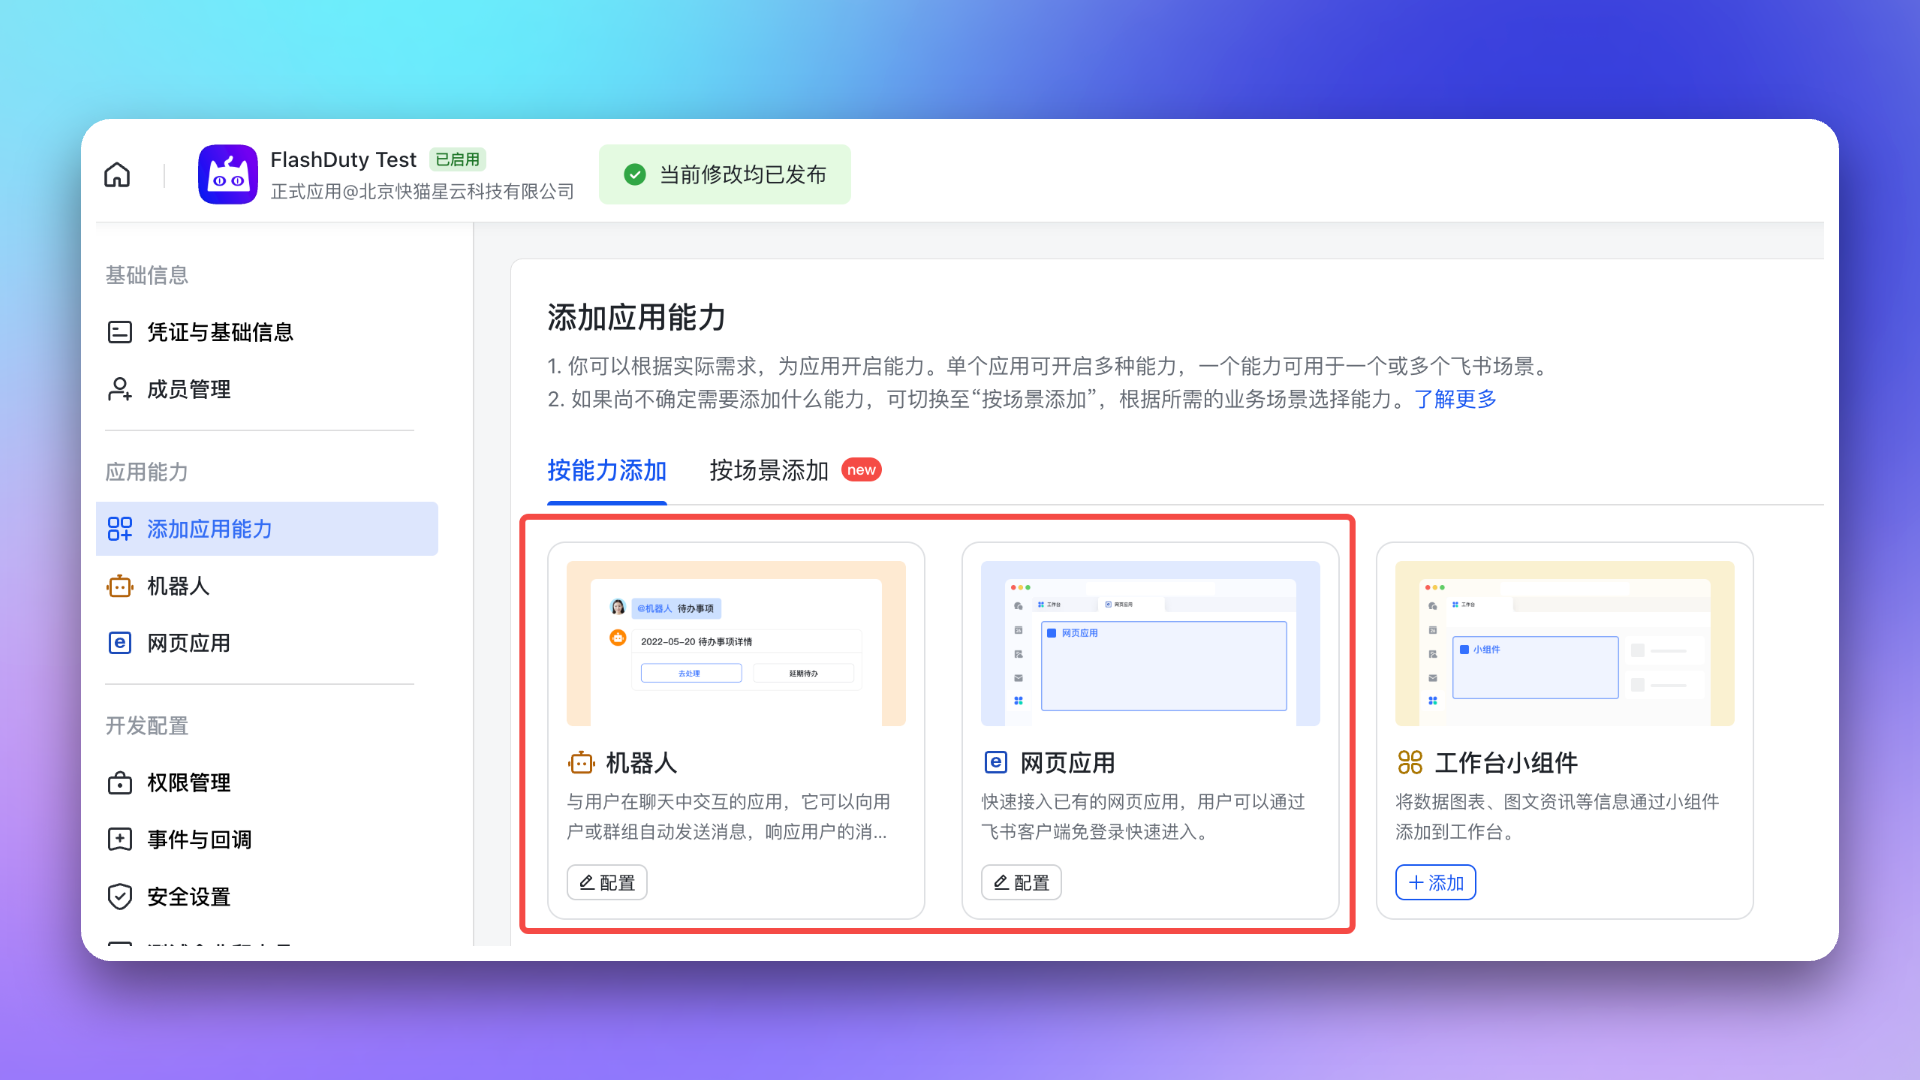
+ 
2. Go to **Web App** page, configure `Desktop Homepage` and `Mobile Homepage`, both using the **Web Configuration** URL from integration details. See Feishu/Lark development documentation [Configure App Homepage URL](https://open.feishu.cn/document/uYjL24iN/uMTMuMTMuMTM/development-guide/step1#8366b844).
-
+ 
3. Go to Event Callbacks → **Event Configuration** page, configure `Subscription Method` (content is the **Message Card Request URL** from integration details). Then add the following events:
-- `im.message.receive_v1`
-- `im.chat.disbanded_v1` (optional; no consumer logic currently)
+ - `im.message.receive_v1`
+ - `im.chat.disbanded_v1` (optional; no consumer logic currently)
-
+ 
4. Go to Event Callbacks → **Callback Configuration** page, configure `Subscription Method` (content is the **Message Card Request URL** from integration details). Then subscribe to the following two callbacks:
-- `card.action.trigger`
-- `card.action.trigger_v1`
+ - `card.action.trigger`
+ - `card.action.trigger_v1`
-
+ 
### 2. Add Redirect URL to Feishu/Lark App
@@ -106,15 +102,17 @@ Go to **Security Settings** page, configure `Redirect URL`, content is the **Red
See Feishu/Lark development documentation [Configure Redirect URL](https://open.feishu.cn/document/uYjL24iN/uYjN3QjL2YzN04iN2cDN?lang=zh-CN#c863e533).
-
+
+
+<span id="request-permissions"></span>
### 3. Request App Permissions
-Go to the **Permission Management** page and request all permissions listed in [AI SRE Required Permissions](#aisre-permissions) for the app created in previous steps. Pay special attention to `im:message.p2p_msg:readonly` and `im:message.group_at_msg:readonly`; without them, Feishu/Lark will not push direct-chat messages or group @bot messages to Flashduty. After changing permissions or event subscriptions, publish a new app version for the changes to take effect in production.
+Go to the **Permission Management** page and request all permissions listed in [Required Permissions](#aisre-permissions) for the app created in previous steps. Pay special attention to `im:message.p2p_msg:readonly` and `im:message.group_at_msg:readonly`; without them, Feishu/Lark will not push direct-chat messages or group @bot messages to Flashduty. After changing permissions or event subscriptions, publish a new app version for the changes to take effect in production.
-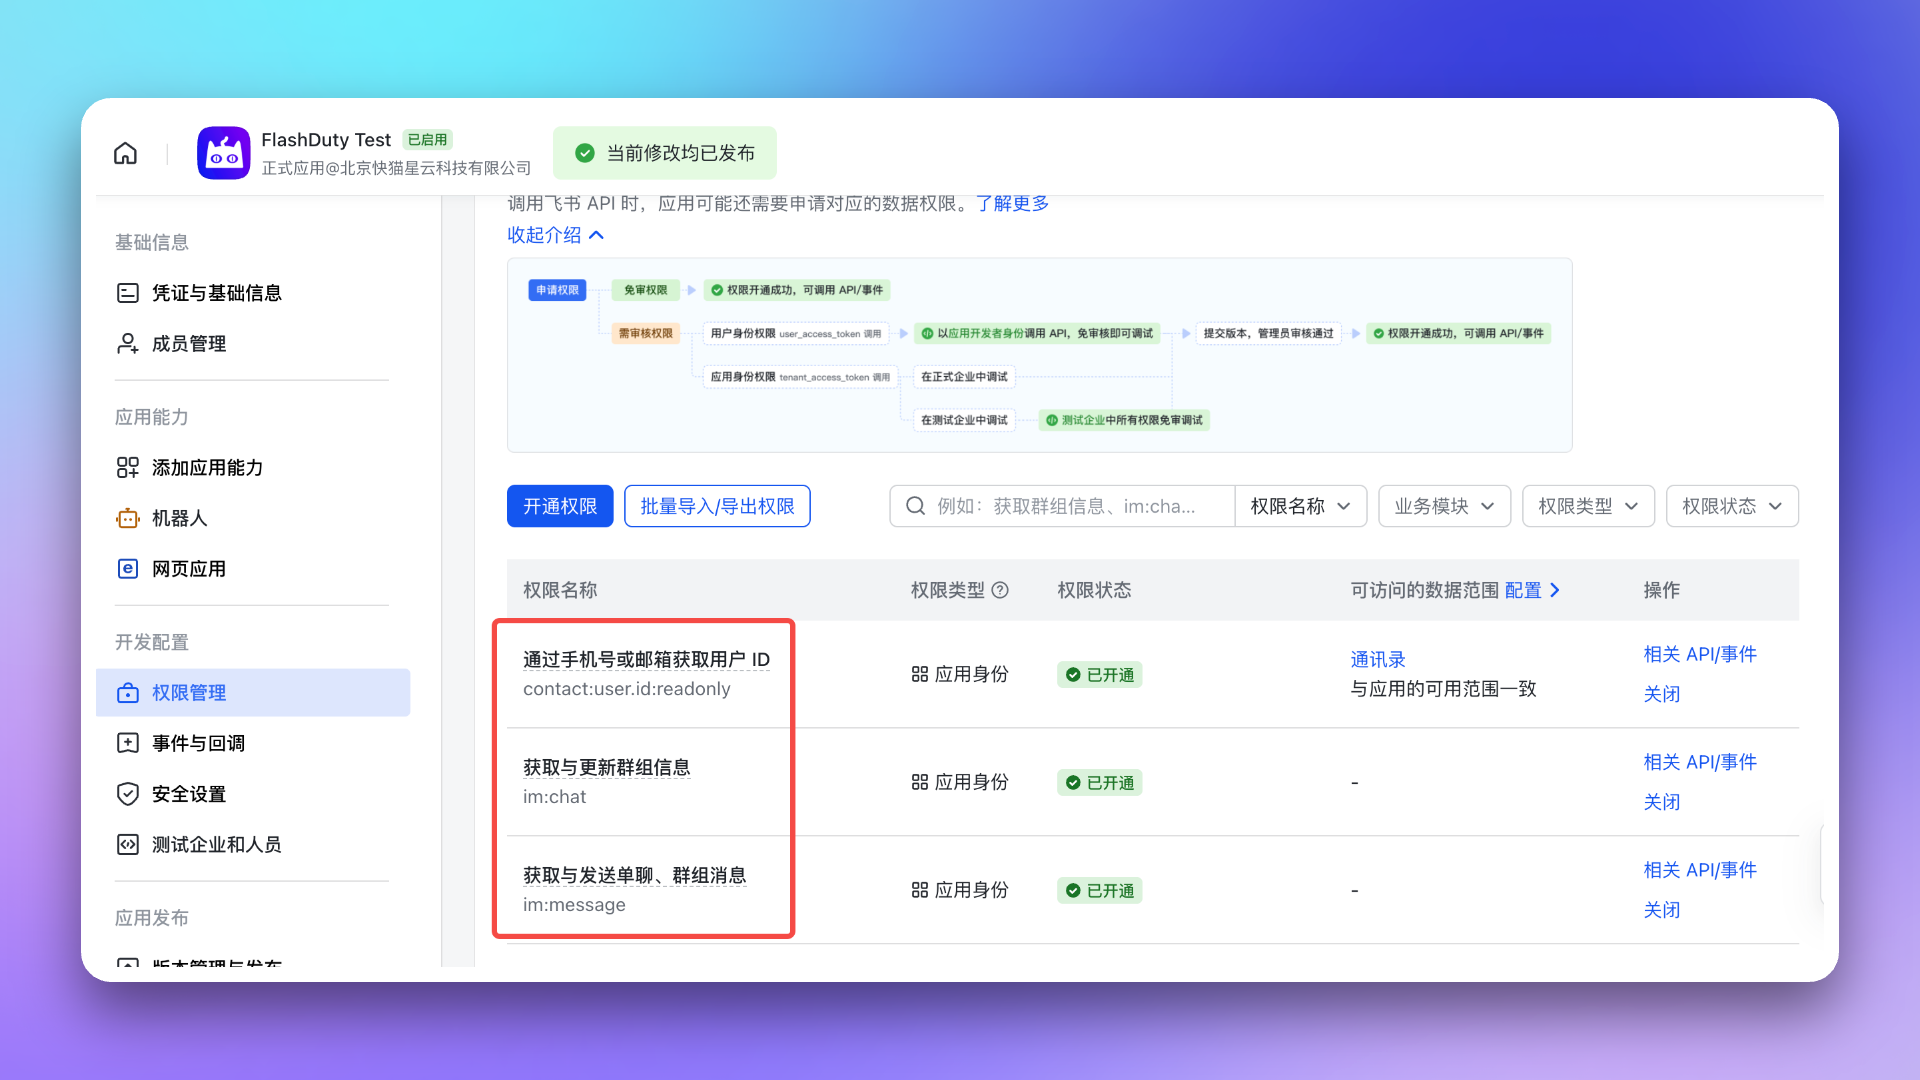
+
-## 4. Publish and Use App
+## Publish and Use App
After completing all the above configurations, please publish the app. It can be used after admin approval. See Feishu/Lark development documentation [App Publishing and Usage](https://open.feishu.cn/document/uYjL24iN/uMTMuMTMuMTM/development-guide/step-4).
@@ -122,25 +120,15 @@ After completing all the above configurations, please publish the app. It can be
To ensure everyone can use the app, adjust the app **Visibility** to all employees before publishing.
</Note>
-
+
After publishing, you can access the app via **Mobile** or **Desktop**. First access requires login to link Feishu/Lark and Flashduty accounts; subsequent access will be passwordless.
-<Tabs>
-<Tab title="Mobile">
-Feishu/Lark → Workspace → Search app name → **Open App**
-</Tab>
+On both mobile and desktop: Feishu/Lark → Workspace → Search app name → **Open App**.
-<Tab title="Desktop">
-Feishu/Lark → Workspace → Search app name → **Open App**
-</Tab>
-</Tabs>
+
-
-
-## 5. Configure War Room
-
-> Ensure the app has been granted the [AI SRE required permissions](#aisre-permissions) listed at the beginning of this page.
+## Configure War Room
After completing the previous steps, in the Flashduty On-call integration configuration page's **Enhanced Features** section, check **Enable War Room** to activate this feature—no additional configuration needed.
@@ -148,7 +136,7 @@ After completing the previous steps, in the Flashduty On-call integration config
Only one IM integration can have War Room enabled at a time. If you've already enabled War Room in another IM integration (such as Dingtalk, Slack, or WeCom), you need to disable it there first before enabling it in the current Feishu/Lark integration.
</Warning>
-### AI SRE Controls
+## AI SRE Controls
Configure the following AI SRE controls separately under **Enhanced Features**. They are enabled by default:
@@ -158,21 +146,13 @@ Configure the following AI SRE controls separately under **Enhanced Features**.
These controls do not take effect until AI SRE is enabled for the account.
-## 6. Linked Users
+## Linked Users
In the **Linked Users** tab of the integration detail page, you can view the linking status between team members and Feishu/Lark accounts, and quickly complete batch linking.
### View Linking Status
-The linked users list shows all team members and their linking status. You can filter by:
-
-| Filter | Description |
-| :--- | :--- |
-| **All** | View all team members |
-| **Linked** | View only members who have linked their Feishu/Lark accounts |
-| **Unlinked** | View only members who have not yet linked their Feishu/Lark accounts |
-
-Search by name or email is supported.
+The list shows every team member and their linking status. Filter by **All / Linked / Unlinked**, or search by name or email.
### One-Click Linking
@@ -182,7 +162,7 @@ When unlinked members exist, click the **One-Click Link** button. The system wil
The system can only push Feishu/Lark message notifications after members complete linking. If linking fails, verify that the member's phone number or email matches their Feishu/Lark account.
</Tip>
-## 7. FAQ
+## FAQ
<AccordionGroup>
<Accordion title="Messages cannot be delivered to individuals, operation log shows 'App not linked'?">
@@ -198,25 +178,25 @@ Go to Feishu/Lark → Workspace → Search app name → **Open App**, complete o
- Go to Feishu/Lark, add the created Flashduty bot to the target group chat
- Return to escalation rule configuration page, refresh and reselect the group chat list
-
+
</Accordion>
<Accordion title="Feishu/Lark custom app API limits?">
**Call Limits:**
- | **Feishu/Lark Version** | **Total Calls/Month** | **Refresh Time** |
- | :---: | :---: | :---: |
- | Basic Free | 10,000 | 1st of each month |
- | Other versions | Unlimited | - |
+| **Feishu/Lark Version** | **Total Calls/Month** | **Refresh Time** |
+| :---: | :---: | :---: |
+| Basic Free | 10,000 | 1st of each month |
+| Other versions | Unlimited | - |
**Rate Limits:**
- | **Scenario** | **Limit** |
- | :---: | :--- |
- | All APIs | Max 50 calls/second per app |
- | Send message API | Max 1000 calls/minute per app |
- | Group bot Webhook | Max 100 calls/minute |
- | Send to same user or group | Max 5 calls/second |
+| **Scenario** | **Limit** |
+| :---: | :--- |
+| All APIs | Max 50 calls/second per app |
+| Send message API | Max 1000 calls/minute per app |
+| Group bot Webhook | Max 100 calls/minute |
+| Send to same user or group | Max 5 calls/second |
<Warning>
After exceeding API call limits, Feishu/Lark app cannot deliver messages properly. Use notification channels reasonably. See [Feishu/Lark official documentation](https://open.feishu.cn/document/uAjLw4CM/ugTN1YjL4UTN24CO1UjN/platform-updates-/custom-app-api-call-limit).
@@ -224,7 +204,7 @@ After exceeding API call limits, Feishu/Lark app cannot deliver messages properl
</Accordion>
<Accordion title="Why isn't War Room working as expected?">
-- Check again that the app has been granted the [AI SRE required permissions](#aisre-permissions) listed at the beginning of this page
+- Check again that the app has been granted the [required permissions](#aisre-permissions) listed at the beginning of this page
- See the **FAQ** section in [War Room documentation](/en/on-call/advanced/war-room)
</Accordion>
</AccordionGroup>
diff --git a/en/on-call/integration/instant-messaging/microsoft-teams.mdx b/en/on-call/integration/instant-messaging/microsoft-teams.mdx
index 1c143419..9595c1e1 100644
--- a/en/on-call/integration/instant-messaging/microsoft-teams.mdx
+++ b/en/on-call/integration/instant-messaging/microsoft-teams.mdx
@@ -6,31 +6,10 @@ description: "By integrating the Microsoft Teams third-party app, you can receiv
<Tip>**Plan requirement**: IM integration requires an On-call Pro or higher subscription. [Learn more](https://flashcat.cloud/flashduty/price/)</Tip>
<Warning>
-If your organization restricts third-party apps, ask a Microsoft Teams administrator to allow Flashduty before you add it.
+If your organization restricts third-party apps, or you cannot find or add Flashduty in the steps below, contact your Microsoft Teams administrator.
</Warning>
-<Note>
-To learn how the Teams app handles Teams users, teams, channels, group chats, and incident card data, see the [Flashduty Microsoft Teams app privacy policy](/en/compliance/microsoft-teams-app-privacy-policy) and [Flashduty Microsoft Teams app terms of use](/en/compliance/microsoft-teams-app-terms-of-use).
-</Note>
-
-## 1. Data and permissions
-
-The Flashduty Teams app processes Teams data only as needed to send alert notifications, complete linking configuration, and handle incident card actions.
-
-| Data or capability | How it is used |
-| --- | --- |
-| Teams user ID and Microsoft Entra ID (AAD Object ID) | Link a Teams user to a Flashduty user; verify the user taking an incident card action; send personal notifications or action feedback |
-| Team ID, team name, and channel ID | Link a Teams team or channel; send alert and incident notifications to the selected Teams channel; retrieve the team details and channel list for a specified Team |
-| Group chat ID and chat name entered by the user | Link a Teams group chat; send alert and incident notifications to the selected group chat |
-| Conversation ID, activity ID, and Bot Framework conversation reference | Send, update, or reply to Teams notification cards after the app is installed |
-| Bot commands and card actions | Handle `help`, `linkUser`, `linkTeam`, and `linkChat` commands, as well as acknowledge, resolve, snooze, and custom action buttons |
-| Flashduty alert and incident card data | Show alert or incident details in Teams and sync card action results back to Flashduty |
-
-The Flashduty Teams app does not read ordinary Teams chat content that is unrelated to Flashduty functionality. It processes only messages sent to the bot in personal chats, messages where the bot is mentioned in teams or group chats, card button actions, installation and conversation reference data required for the app to work, and data needed to send or update Flashduty notifications.
-
-The current app package does not request Microsoft Graph permissions for reading organization-wide chat content. If a future version introduces new Teams permissions or data processing scenarios, Flashduty will update this documentation and the related privacy notice.
-
-## 2. Get the App from Microsoft Teams
+## Get the App from Microsoft Teams
<Steps>
<Step title="Find Flashduty">
@@ -46,15 +25,11 @@ Select **Add**. Choose the destination that matches your use case: a team/channe
In the commands below, replace `{ID}` with the Flashduty Microsoft Teams integration ID. Replace `{ChatName}` with the group chat name.
</Note>
-## 3. Link team
+## Link team
<Steps>
<Step title="Find App">
In Teams, open **Apps**, find **Flashduty**, and select **Add to a team**.
-
-<Note>
-If you cannot find or add the app, contact your Microsoft Teams administrator.
-</Note>
</Step>
<Step title="Add to Team">
@@ -64,13 +39,13 @@ Add the app to the target Team.
This step must select the target Team's General Channel, otherwise incidents cannot be sent to the Team.
</Warning>
-
+
</Step>
<Step title="Send Link Command">
In the Team's General channel, @Flashduty and send `linkTeam {ID}`, then select **Link Now**.
-
+
</Step>
<Step title="Unlink the Team">
@@ -78,27 +53,23 @@ To remove this Team's link, in the same channel send `@Flashduty unlinkTeam {ID}
</Step>
</Steps>
-## 4. Link chat
+## Link chat
<Steps>
<Step title="Find App">
In Teams, open **Apps**, find **Flashduty**, and select **Add to a chat**.
-
-<Note>
-If you cannot find or add the app, contact your Microsoft Teams administrator.
-</Note>
</Step>
<Step title="Add to Chat">
Add the app to the target Chat.
-
+
</Step>
<Step title="Send Link Command">
In the group chat, @Flashduty and send `linkChat {ID} {ChatName}`, then select **Link Now**.
-
+
</Step>
<Step title="Unlink the Chat">
@@ -106,7 +77,7 @@ To remove this group's link, send `@Flashduty unlinkChat {ID}` in the same group
</Step>
</Steps>
-## 5. Notification card actions
+## Notification card actions
When incident notifications are pushed to Microsoft Teams, the notification cards may include the following interactive actions. The available buttons depend on the Flashduty card you receive and the backend configuration:
@@ -119,27 +90,23 @@ When incident notifications are pushed to Microsoft Teams, the notification card
War room functionality is not currently supported for Microsoft Teams. If you need to use the war room feature, consider using Slack, Feishu/Lark, Dingtalk, or WeCom integration instead.
</Note>
-## 6. Link user
+## Link user
<Steps>
<Step title="Find App">
In Teams, open **Apps**, find **Flashduty**, and select **Open**.
-
-<Note>
-If you cannot find or open the app, contact your Microsoft Teams administrator.
-</Note>
</Step>
<Step title="Open App">
Click **Open App**.
-
+
</Step>
<Step title="Send Link Command">
Send `linkUser {ID}` in your personal chat with Flashduty, then select **Link Now**.
-
+
</Step>
<Step title="Unlink Your Account">
@@ -147,7 +114,26 @@ To remove your Teams account link, send `unlinkUser {ID}` in the same personal c
</Step>
</Steps>
-## 7. FAQ
+## Data and permissions
+
+To learn how the Teams app handles Teams users, teams, channels, group chats, and incident card data, see the [Flashduty Microsoft Teams app privacy policy](/en/compliance/microsoft-teams-app-privacy-policy) and [Flashduty Microsoft Teams app terms of use](/en/compliance/microsoft-teams-app-terms-of-use).
+
+The Flashduty Teams app processes Teams data only as needed to send alert notifications, complete linking configuration, and handle incident card actions.
+
+| Data or capability | How it is used |
+| --- | --- |
+| Teams user ID and Microsoft Entra ID (AAD Object ID) | Link a Teams user to a Flashduty user; verify the user taking an incident card action; send personal notifications or action feedback |
+| Team ID, team name, and channel ID | Link a Teams team or channel; send alert and incident notifications to the selected Teams channel; retrieve the team details and channel list for a specified Team |
+| Group chat ID and chat name entered by the user | Link a Teams group chat; send alert and incident notifications to the selected group chat |
+| Conversation ID, activity ID, and Bot Framework conversation reference | Send, update, or reply to Teams notification cards after the app is installed |
+| Bot commands and card actions | Handle `help`, `linkUser`, `linkTeam`, and `linkChat` commands, as well as acknowledge, resolve, snooze, and custom action buttons |
+| Flashduty alert and incident card data | Show alert or incident details in Teams and sync card action results back to Flashduty |
+
+The Flashduty Teams app does not read ordinary Teams chat content that is unrelated to Flashduty functionality. It processes only messages sent to the bot in personal chats, messages where the bot is mentioned in teams or group chats, card button actions, installation and conversation reference data required for the app to work, and data needed to send or update Flashduty notifications.
+
+The current app package does not request Microsoft Graph permissions for reading organization-wide chat content. If a future version introduces new Teams permissions or data processing scenarios, Flashduty will update this documentation and the related privacy notice.
+
+## FAQ
<AccordionGroup>
<Accordion title="Team or individual not receiving messages?">
diff --git a/en/on-call/integration/instant-messaging/slack.mdx b/en/on-call/integration/instant-messaging/slack.mdx
index a57bebde..b9b1a21b 100644
--- a/en/on-call/integration/instant-messaging/slack.mdx
+++ b/en/on-call/integration/instant-messaging/slack.mdx
@@ -5,13 +5,62 @@ description: "By integrating the Slack third-party app, you can receive and resp
<Tip>**Plan requirement**: IM integration requires an On-call Pro or higher subscription. [Learn more](https://flashcat.cloud/flashduty/price/)</Tip>
+<span id="install-app"></span>
+
+## Install App
+
+<Steps>
+<Step title="Add Integration">
+Go to Flashduty On-call Integration Center → Instant Messaging → **Slack**, click **Add**.
+</Step>
+
+<Step title="Authorize App">
+On the redirected Slack page, select **Workspace** in the top right corner, then click **Allow**.
+
+
+</Step>
+
+<Step title="Save Configuration">
+Enter data source name, click **Save**.
+</Step>
+</Steps>
+
+## Configure War Room
+
+After completing the previous steps, in the Flashduty On-call integration configuration page's **Enhanced Features** section, check **Enable War Room** to activate this feature—no additional configuration needed.
+
+## AI SRE Controls
+
+Configure the following AI SRE controls separately under **Enhanced Features**. They are enabled by default:
+
+- **Automatically start AI incident analysis**: Available after you enable War Room. Starts an AI incident analysis when a War Room is created successfully.
+- **Allow AI SRE conversations in IM**: Available without enabling War Room. When enabled, people can @mention AI SRE or use `/fd` in a Slack group connected through this integration, or start a direct conversation with the bot. When disabled, none of these entry points triggers an AI SRE reply.
+- **Use thread replies in normal group chats**: Available without enabling War Room. When enabled, each normal-group thread has an independent session; War Rooms still receive replies directly in the group.
+
+These controls do not take effect until AI SRE is enabled for the account.
+
+## Linked Users
+
+In the **Linked Users** tab of the integration detail page, you can view the linking status between team members and Slack accounts, and quickly complete batch linking.
+
+### View Linking Status
+
+The list shows every team member and their linking status. Filter by **All / Linked / Unlinked**, or search by name or email.
+
+### One-Click Linking
+
+When unlinked members exist, click the **One-Click Link** button. The system will attempt to obtain Slack account IDs via phone numbers or emails and automatically link them, equivalent to members logging into Flashduty using the same information on Slack.
+
+<Tip>
+The system can only push Slack message notifications after members complete linking. If linking fails, verify that the member's email matches their Slack account.
+</Tip>
+
<span id="aisre-permissions"></span>
<span id="war-room-scope"></span>
-<span id="install-app"></span>
-## AI SRE Required Permissions
+## Required Permissions
-The following list includes all permissions required when the Slack IM integration uses AI SRE, including basic notifications, War Room, AI SRE conversations, AI-generated post-mortem reports, and incident notification dispatch. In the Slack app **OAuth & Permissions** page, confirm that each official scope name below is granted. For existing Slack integrations, re-authorize the app if any scope is missing.
+When you install the app, Flashduty requests the scopes below through OAuth in one go. They cover basic notifications, War Room, AI SRE conversations, AI-generated post-mortems, and incident notification dispatch, so you normally don't configure them by hand. If an older integration is missing scopes, click **Re-authorize** on the integration configuration page.
### Bot Token Scopes
@@ -75,71 +124,13 @@ The list above matches the current OAuth authorization request. If it differs fr
If you use Slack Incoming Webhook-based Slack bot notifications instead of the Slack App integration on this page, enable Incoming Webhooks in the corresponding Slack app and include the `incoming-webhook` scope in the OAuth flow.
</Note>
-## 1. Install App
-
-<Steps>
-<Step title="Add Integration">
-Go to Flashduty On-call Integration Center → Instant Messaging → **Slack**, click **Add**.
-</Step>
-
-<Step title="Authorize App">
-On the redirected Slack page, select **Workspace** in the top right corner, then click **Allow**.
-
-
-</Step>
-
-<Step title="Save Configuration">
-Enter data source name, click **Save**.
-</Step>
-</Steps>
-
-## 2. Configure War Room
-
-> Ensure the app has been granted the [AI SRE required permissions](#aisre-permissions) listed at the beginning of this page.
-
-After completing the previous steps, in the Flashduty On-call integration configuration page's **Enhanced Features** section, check **Enable War Room** to activate this feature—no additional configuration needed.
-
-### AI SRE Controls
-
-Configure the following AI SRE controls separately under **Enhanced Features**. They are enabled by default:
-
-- **Automatically start AI incident analysis**: Available after you enable War Room. Starts an AI incident analysis when a War Room is created successfully.
-- **Allow AI SRE conversations in IM**: Available without enabling War Room. When enabled, people can @mention AI SRE or use `/fd` in a Slack group connected through this integration, or start a direct conversation with the bot. When disabled, none of these entry points triggers an AI SRE reply.
-- **Use thread replies in normal group chats**: Available without enabling War Room. When enabled, each normal-group thread has an independent session; War Rooms still receive replies directly in the group.
-
-These controls do not take effect until AI SRE is enabled for the account.
-
-## 3. Linked Users
-
-In the **Linked Users** tab of the integration detail page, you can view the linking status between team members and Slack accounts, and quickly complete batch linking.
-
-### View Linking Status
-
-The linked users list shows all team members and their linking status. You can filter by:
-
-| Filter | Description |
-| :--- | :--- |
-| **All** | View all team members |
-| **Linked** | View only members who have linked their Slack accounts |
-| **Unlinked** | View only members who have not yet linked their Slack accounts |
-
-Search by name or email is supported.
-
-### One-Click Linking
-
-When unlinked members exist, click the **One-Click Link** button. The system will attempt to obtain Slack account IDs via phone numbers or emails and automatically link them, equivalent to members logging into Flashduty using the same information on Slack.
-
-<Tip>
-The system can only push Slack message notifications after members complete linking. If linking fails, verify that the member's email matches their Slack account.
-</Tip>
-
-## 4. FAQ
+## FAQ
<AccordionGroup>
<Accordion title="War Room considerations?">
- Only one IM integration can have War Room enabled at a time. If you have already enabled War Room in another IM integration (such as Dingtalk, Feishu/Lark, or WeCom), you need to disable it there first before enabling it in the current Slack integration
- When enabling War Room, the system automatically verifies whether the current Slack app has all required permissions. If missing permissions are detected, a warning message appears on the page with a **Re-authorize** link
-- Click the **Re-authorize** link to be redirected to the Slack authorization page, which requests the [AI SRE required permissions](#aisre-permissions) listed at the beginning of this page. After completing authorization, the page automatically returns to Flashduty
+- Click the **Re-authorize** link to be redirected to the Slack authorization page, which requests the [required permissions](#aisre-permissions). After completing authorization, the page automatically returns to Flashduty
- If your Slack integration was authorized before the War Room feature was released, you will typically need to re-authorize on first use to add the new permissions. Re-authorization does not affect your existing integration configuration or user associations
</Accordion>
@@ -154,32 +145,21 @@ The system can only push Slack message notifications after members complete link
- Follow the method from the previous question to add the app to the channel
</Accordion>
-<Accordion title="Error when clicking 'Allow' button during authorization?">
-Please try again. This may be due to server-Slack communication exception causing authorization failure. Return to the add data source page and retry. If the error persists after retry, please contact customer service.
-</Accordion>
-
-<Accordion title="Error when clicking 'Save' button?">
-Please try again. This may be due to Flashduty server communication exception with Slack when obtaining permanent authorization code. Return to the add data source page and retry. If the error persists after retry, please contact customer service.
-</Accordion>
-
-<Accordion title="Slack App shows not_authed error?">
-Please try again, this may be a temporary Slack service issue. If the error persists after retry, please contact customer service.
-</Accordion>
-
-<Accordion title="Slack App shows Operation timed out error?">
-Please try again. This may be server-Slack communication timeout. If the error persists after retry, please contact customer service.
-</Accordion>
+<Accordion title="Errors when authorizing, saving, or using the Slack App?">
+Retry once; if the error persists, contact customer support. Common causes:
-<Accordion title="Slack App shows Status Code 500 error?">
-Please try again. This may be a Flashduty On-call server error (e.g., data source was disabled). If the error persists after retry, please contact customer service.
-</Accordion>
-
-<Accordion title="Slack App shows other unknown errors?">
-Please try again. If the error persists after retry, please contact customer service to log and resolve new issues.
+| When it happens | Likely cause |
+| :--- | :--- |
+| After clicking **Allow** on the authorization page | Server–Slack communication failed during authorization; retry from the add data source page |
+| After clicking **Save** | Communication with Slack failed while Flashduty obtained the permanent authorization code; retry from the add data source page |
+| `not_authed` | Temporary Slack service issue |
+| `Operation timed out` | Server–Slack communication timed out |
+| `Status Code 500` | Flashduty On-call server error (for example, the data source was disabled) |
+| Other unknown errors | Contact customer support so the issue can be logged and resolved |
</Accordion>
<Accordion title="Why isn't War Room working as expected?">
-- Check again that the app has been granted the [AI SRE required permissions](#aisre-permissions) listed at the beginning of this page
+- Check again that the app has been granted the [required permissions](#aisre-permissions)
- For previously authorized Slack IM integrations, you need to manually re-authorize Slack in the Flashduty On-call integration configuration page for the app to obtain the permissions required for AI SRE
- See the **FAQ** section in [War Room documentation](/en/on-call/advanced/war-room)
</Accordion>
diff --git a/en/on-call/integration/instant-messaging/wecom.mdx b/en/on-call/integration/instant-messaging/wecom.mdx
index 0f77c53f..cb23046e 100644
--- a/en/on-call/integration/instant-messaging/wecom.mdx
+++ b/en/on-call/integration/instant-messaging/wecom.mdx
@@ -5,27 +5,21 @@ description: "By integrating a WeCom third-party app, you can receive and respon
<Tip>**Plan requirement**: IM integration requires an On-call Pro or higher subscription. [Learn more](https://flashcat.cloud/flashduty/price/)</Tip>
-This documentation supports [Third-Party App Integration](#third-party) or [Custom App Integration](#self) methods.
+Choose one of two methods: [Third-Party App Integration](#third-party) or [Custom App Integration](#self). War Room and @ AI SRE in group chats are available only with a custom app.
<div className="hide">
{/*
## Video Introduction
----
-
<Video src="https://download.flashcat.cloud/flashduty/video/wechat.mp4"></Video>
*/}
</div>
-<Note>
-**Third-Party App Integration** and **Custom App Integration** only need to configure one method as needed.
-</Note>
-
<span id="third-party"></span>
-## 1. Third-Party App Integration
+## Third-Party App Integration
<Info>
As a WeCom service provider, Flashduty provides a long-term free version of the Flashduty app. This app requires WeCom API call authorization to use (passwordless login + message sending). This authorization currently supports **up to 60 days** free; beyond this usage period, Flashduty needs to purchase WeCom licenses for you before you can continue using it.
@@ -33,33 +27,33 @@ As a WeCom service provider, Flashduty provides a long-term free version of the
1. Visit [WeCom Admin Console](https://work.weixin.qq.com/wework_admin/frame#apps), go to App Management → **Apps** page, click **Add Third-Party App**.
- 
+ 
2. Enter `Flashduty` in the search bar, after finding the app, click **Add**.
- 
+ 
3. Modify app **Visibility**, recommend selecting all employees or specific department nodes to avoid modifying when new enterprise members join. Then click **Agree to the above authorization and add** to complete installation.
- 
+ 
4. Visit [WeCom Admin Console](https://work.weixin.qq.com/wework_admin/frame#apps), go to **My Enterprise** page, get `Corp ID`.
- 
+ 
5. Return to Flashduty On-call integration configuration page, fill in the `Corp ID` obtained in the previous step, click **Save** to complete integration.
<span id="self"></span>
-## 2. Custom App Integration
+## Custom App Integration
1. Visit [WeCom Admin Console](https://work.weixin.qq.com/wework_admin/frame#apps), go to App Management → **Apps** page, click **Create App**.
- 
+ 
2. Configure **App Logo**, **App Name**, and **App Visibility**.
- 
+ 
3. Return to Flashduty On-call integration configuration page, select whether your WeCom is `Non-private deployment version` based on your actual situation.
@@ -71,41 +65,47 @@ As a WeCom service provider, Flashduty provides a long-term free version of the
6. On the app details page, get `Secret` and fill it in the Flashduty On-call integration configuration page.
-7. On the app details page, go to **Web Authorization & JS-SDK** page, click **Set Trusted Domain**, and configure as required.
+7. On the app details page, go to **Web Authorization & JS-SDK** and click **Set Trusted Domain**. The domain must point to Flashduty On-call's backend address `{api_host}` (via CNAME or a proxy); see WeCom's [Enterprise Internal Development Domain Configuration Guide](https://open.work.weixin.qq.com/wwopen/common/readDocument/40754) for requirements.
-<Note>
-The trusted domain needs to point to Flashduty On-call's backend address `{api_host}` (achievable via CNAME or proxy forwarding). For trusted domain requirements, see WeCom official documentation [Enterprise Internal Development Domain Configuration Guide](https://open.work.weixin.qq.com/wwopen/common/readDocument/40754).
-</Note>
-
-
+ 
Return to Flashduty On-call integration configuration page, fill in this domain and complete verification.
8. On the app details page, go to **Receive Messages** page, and **Set API Receive**. Click **Random Generate** for `Token` and `EncodingAESKey` respectively, then copy and save the generated values.
- 
+ 
Return to Flashduty On-call integration configuration page, fill in the saved `Token` and `EncodingAESKey`, click **Save** to complete integration.
9. Copy the `Callback URL` from Flashduty On-call integration details page, return to WeCom's **Receive Messages** page. In **API Receive** settings, fill in this `Callback URL` and the `Token` and `EncodingAESKey` saved in the previous step, then click **Save**.
- 
+ 
-10. Configure **Frontend Trusted Domain**
+10. Configure a **Frontend Trusted Domain** pointing to Flashduty On-call's frontend address `console.flashcat.cloud` (via CNAME or a proxy). After it is verified, set the generated **Homepage URL** as the WeCom app's **Workspace App Homepage**.
-<Note>
-The trusted domain needs to point to Flashduty On-call's frontend address `console.flashcat.cloud` (achievable via CNAME or proxy forwarding). For trusted domain requirements, see WeCom official documentation [Enterprise Internal Development Domain Configuration Guide](https://open.work.weixin.qq.com/wwopen/common/readDocument/40754).
-</Note>
+ 
-After frontend trusted domain verification passes, configure the generated **Homepage URL** to the WeCom app's **Workspace App Homepage**
+11. Configure the **Trusted IP Address**: `47.93.12.134`.
-
+ 
-11. Configure **Trusted IP Address**: `47.93.12.134`
+## Linked Users
-
+In the **Linked Users** tab of the integration detail page, you can view the linking status between team members and WeCom accounts, and quickly complete batch linking.
-## 3. Configure War Room
+### View Linking Status
+
+The list shows every team member and their linking status. Filter by **All / Linked / Unlinked**, or search by name or email.
+
+### One-Click Linking
+
+When unlinked members exist, click the **One-Click Link** button. The system will attempt to obtain WeCom account IDs via phone numbers or emails and automatically link them, equivalent to members logging into Flashduty using the same information on WeCom.
+
+<Tip>
+The system can only push WeCom message notifications after members complete linking. If linking fails, verify that the member's phone number or email matches their WeCom account.
+</Tip>
+
+## Configure War Room
<Warning>
War Room functionality is only supported in **Custom App Integration** mode.
@@ -117,7 +117,7 @@ After completing previous steps, in the Flashduty On-call integration configurat
Only one IM integration can have War Room enabled at a time. If you've already enabled War Room in another IM integration (such as Dingtalk, Feishu/Lark, or Slack), you need to disable it there first before enabling it in the current WeCom integration.
</Warning>
-### AI SRE Controls
+## AI SRE Controls
Configure the following AI SRE controls in the integration configuration page's **Enhanced Features** module. They are enabled by default:
@@ -131,109 +131,48 @@ The two WeCom app modes support different AI SRE entry points. **Allow AI SRE co
| **Custom App Integration** | Supported | Supported |
| **Third-party App** | Not supported; switch to **Custom App Integration** mode | Supported |
-In Third-party App mode, the switch is described as "When enabled, people can start a direct conversation with the bot. @ AI SRE in group chats is available only for self-built enterprise apps."
-
These controls do not take effect until AI SRE is enabled for the account.
-## 4. Configure AISRE
+## Configure the AI SRE Smart Robot
-To use AISRE with WeCom, confirm that **Allow AI SRE conversations in IM** is enabled in the Flashduty WeCom integration (War Room is not required), then create an additional Smart Robot in WeCom and connect it to Flashduty in API mode. The Smart Robot credentials are filled in on the integration configuration page of **Custom App Integration** mode.
-
-1. In the WeCom app, open **Workspace** from the left sidebar, then go to Smart Robot management.
-2. Create a new Smart Robot. Select **Manual creation**, then select **Create in API mode**.
+@mention the Smart Robot in a WeCom single chat or group chat to start an AI SRE investigation session without leaving WeCom. The Smart Robot can only be configured in **Custom App Integration** mode.
<Note>
-Have an internal company member create the Smart Robot. Even if its visibility is set to **all internal members**, other members can only see the Smart Robot after the creator shares it.
+- AI SRE must be enabled for your account, and **Allow AI SRE conversations in IM** must be on in the Flashduty WeCom integration (War Room is not required). Otherwise the robot does not respond to messages.
+- Enter and verify the **Trusted Domain** on the integration configuration page first; the Smart Robot callback URL is generated only after that.
</Note>
-3. On the Smart Robot's **API configuration** page, set the connection method to **Use URL callback**, and enter the `URL` provided on the Flashduty WeCom integration configuration page.
-4. Generate the `Token` and `Encoding-AESKey` on the WeCom API configuration page, then enter the same values in the Flashduty WeCom integration configuration page. Make sure the `Token` and `Encoding-AESKey` are exactly the same in both WeCom and Flashduty, then save both configurations.
-
<Warning>
-WeCom does not automatically add the Smart Robot to a War Room group after the War Room is created. To use AISRE in the War Room, manually add the Smart Robot to the corresponding group chat.
+The Smart Robot uses its **own set of credentials** (Token and Encoding-AESKey), different from the **Receive Messages** Token / EncodingAESKey in [Custom App Integration](#self). Mixing the two causes signature verification failures.
</Warning>
-## 5. Linked Users
-
-In the **Linked Users** tab of the integration detail page, you can view the linking status between team members and WeCom accounts, and quickly complete batch linking.
-
-### View Linking Status
-
-The linked users list shows all team members and their linking status. You can filter by:
-
-| Filter | Description |
-| :--- | :--- |
-| **All** | View all team members |
-| **Linked** | View only members who have linked their WeCom accounts |
-| **Unlinked** | View only members who have not yet linked their WeCom accounts |
-
-Search by name or email is supported.
-
-### One-Click Linking
-
-When unlinked members exist, click the **One-Click Link** button. The system will attempt to obtain WeCom account IDs via phone numbers or emails and automatically link them, equivalent to members logging into Flashduty using the same information on WeCom.
-
-<Tip>
-The system can only push WeCom message notifications after members complete linking. If linking fails, verify that the member's phone number or email matches their WeCom account.
-</Tip>
-
-## 6. WeCom Bot (AI SRE) Integration
-
-The WeCom AI Bot (智能体) is WeCom's native AI conversation robot feature. By connecting Flashduty AI SRE to a WeCom Bot, your team can start AI incident investigation sessions directly from any WeCom single-chat or group-chat by @mentioning the bot—without leaving WeCom.
+<Steps>
+ <Step title="Create a Smart Robot in WeCom">
+ In the WeCom app, open **Workspace** from the left sidebar and go to **Smart Robot** management. Create a new Smart Robot, select **Manual creation**, then **Create in API mode**.
+
+ Have an internal company member create it: even with visibility set to **all internal members**, others only see the robot after the creator shares it.
+ </Step>
+ <Step title="Enter the callback URL">
+ On the Smart Robot's **API configuration** page, set the connection method to **Use URL callback** and enter the `URL` shown in the **Smart Robot Configuration** area of the Flashduty WeCom integration page. It has the format:
+
+ ```
+ https://<trusted-domain>/event/push/wecom/bot?integration_key=<integration_key>
+ ```
+
+ WeCom sends a GET request to this URL for verification (echostr challenge); Flashduty answers it automatically.
+ </Step>
+ <Step title="Sync the Token and Encoding-AESKey">
+ Generate the `Token` and `Encoding-AESKey` on the Smart Robot's API configuration page, then enter the same values in the **Smart Robot Configuration** area of the Flashduty integration page. Make sure both sides match exactly, then save both configurations.
+ </Step>
+</Steps>
<Warning>
-The bot integration uses **credentials that are entirely separate from the regular WeCom app** (Bot Token and Bot EncodingAESKey). Do not reuse the Token / EncodingAESKey you generated in [Custom App Integration](#self) step 8—the two sets of credentials are independent, and mixing them will cause signature verification failures.
+WeCom does not automatically add the Smart Robot to a War Room group after the War Room is created. To use AI SRE in the War Room, manually add the Smart Robot to the corresponding group chat.
</Warning>
-<Note>
-AI SRE must be enabled for your account. If it is not, the WeCom Bot will return no response when it receives a message.
-</Note>
-
-### Setup Steps
-
-<Steps>
-
-<Step title="Create an AI Bot in the WeCom Admin Console">
-
-Visit the [WeCom Admin Console](https://work.weixin.qq.com/wework_admin/frame#apps), go to **App Management → AI Assistant**, click **Create AI Assistant** (Bot), and complete the basic information (name, avatar, visibility scope).
-
-</Step>
-
-<Step title="Generate the Bot Token and EncodingAESKey">
-
-Open the details page of the bot you just created, go to the **Receive Messages** section, click **Random Generate** for both `Token` and `EncodingAESKey`, then copy and save both values.
-
-These credentials belong exclusively to this bot and are **completely different** from the Token / EncodingAESKey configured in your WeCom custom app integration.
-
-</Step>
-
-<Step title="Enter bot credentials in Flashduty">
-
-Return to the Flashduty On-call WeCom integration details page, find the **AI SRE Bot** configuration section, enter the `Bot Token` and `Bot EncodingAESKey` obtained above into the corresponding fields, and click **Save**.
-
-After saving, the page displays the `integration_key` for this integration.
-
-</Step>
-
-<Step title="Set the bot callback URL in WeCom">
-
-Copy the **Bot Callback URL** shown on the Flashduty integration details page. It has the format:
-
-```
-https://<your-api-host>/event/push/wecom/bot?integration_key=<integration_key>
-```
-
-Return to the WeCom Admin Console, open the bot's **Receive Messages** settings, fill in the callback URL along with the Token and EncodingAESKey, then click **Save**.
-
-WeCom sends a GET request to the callback URL for URL verification (echostr challenge). The Flashduty server automatically completes the verification response.
-
-</Step>
-
-</Steps>
-
### How to Use
-Once configured, **@mention your bot** in a WeCom single-chat or group-chat, type a question or incident description, and an AI SRE session starts. The bot supports these message types:
+Once configured, **@mention the Smart Robot** in a WeCom single chat or group chat and type a question or incident description to start an AI SRE session. Supported message types:
| Type | Description |
| :--- | :--- |
@@ -243,34 +182,34 @@ Once configured, **@mention your bot** in a WeCom single-chat or group-chat, typ
| **Quoted reply** | Quote a previous message to follow up; AI uses conversation history for context |
<Note>
-WeCom Bots use **pull-based streaming** (stream polling): while AI generates a reply, the WeCom client periodically sends `msgtype=stream` requests to the callback URL to fetch the latest content until the AI response is complete. This is a platform-level mechanism; no extra configuration is needed on your end.
+WeCom Smart Robots use **pull-based streaming** (stream polling): while AI generates a reply, the WeCom client periodically sends `msgtype=stream` requests to the callback URL to fetch the latest content until the reply is complete. This is a WeCom platform mechanism; no extra configuration is needed.
</Note>
### Troubleshooting
<AccordionGroup>
-<Accordion title="Bot receives messages but returns no response">
+<Accordion title="The robot receives messages but returns no response">
Check in order:
-1. Confirm that AI SRE is enabled for your account.
+1. Confirm that AI SRE is enabled for your account and **Allow AI SRE conversations in IM** is on in the integration.
2. Confirm the `integration_key` in the callback URL exactly matches the value shown on the Flashduty integration details page.
-3. Confirm that the `Bot Token` and `Bot EncodingAESKey` saved in Flashduty match the values on the bot's **Receive Messages** page in WeCom Admin Console—not the values from your WeCom custom app.
-4. Check the callback logs in the WeCom Admin Console to see whether requests are reaching the endpoint and whether any error codes are returned.
+3. Confirm the `Token` and `Encoding-AESKey` saved in Flashduty come from the Smart Robot's **API configuration** page, not from the custom app's **Receive Messages** settings.
+4. Check the robot's callback records in WeCom (if available) to see whether requests arrive and whether any error codes are returned.
</Accordion>
<Accordion title="'URL verification failed' when saving the callback URL">
-- Confirm that the Flashduty server is publicly reachable by WeCom servers.
-- Confirm that the `Token` and `EncodingAESKey` you entered in WeCom exactly match what is saved in the Flashduty integration configuration.
+- Confirm that the Flashduty server is publicly reachable by WeCom servers and the Trusted Domain has been verified.
+- Confirm that the `Token` and `Encoding-AESKey` exactly match what is saved in the Flashduty integration configuration.
- Confirm that the `integration_key` parameter in the callback URL is correct and that the corresponding integration is enabled.
</Accordion>
<Accordion title="Signature verification failure (invalid signature)">
-This typically means the Bot Token or Bot EncodingAESKey is incorrect. The bot's Token / EncodingAESKey and the WeCom custom app's Token / EncodingAESKey are **two independent sets of credentials**. Regenerate them on the bot's **Receive Messages** page in WeCom Admin Console and update both values in the Flashduty integration configuration.
+This usually means the `Token` or `Encoding-AESKey` is wrong. The Smart Robot's credentials and the custom app's **Receive Messages** credentials are **two independent sets**. Regenerate them on the Smart Robot's **API configuration** page and update both values in the Flashduty integration configuration.
</Accordion>
</AccordionGroup>
-## 7. FAQ
+## FAQ
<AccordionGroup>
<Accordion title="After clicking integration save button, system shows 'authorize app first' error?">
@@ -293,7 +232,7 @@ This typically means the Bot Token or Bot EncodingAESKey is incorrect. The bot's
Custom area can display up to 8 lines; excess will be truncated by WeCom.
</Note>
-
+
</Accordion>
<Accordion title="How to handle alerts within WeCom?">
diff --git a/en/on-call/integration/sso/keycloak.mdx b/en/on-call/integration/sso/keycloak.mdx
index 5f336e5e..6612f153 100644
--- a/en/on-call/integration/sso/keycloak.mdx
+++ b/en/on-call/integration/sso/keycloak.mdx
@@ -18,13 +18,13 @@ This article does not cover deployment or explanation of Keycloak. For more info
Login to Flashduty console and obtain the ACS URL (needed in subsequent steps).
-Path: **Access Control => Single Sign-On => SAML2.0 Protocol => Flashduty Service Provider Info => Assertion Consumer Service URL**
+Path: **Access Control → Single Sign-On → SAML2.0 Protocol → Flashduty Service Provider Info → Assertion Consumer Service URL**

### 2. Create Client
-Login to Keycloak console, path: **Clients => Create client**
+Login to Keycloak console, path: **Clients → Create client**
- **Client Type**: Select SAML protocol
- **Client ID**: Enter `flashcat.cloud` (fixed value, cannot be changed)
@@ -79,7 +79,7 @@ Completed result:
The downloaded file is a compressed package. After extracting locally, there will be two xml files; only the `idp-metadata.xml` file is needed.
</Note>
-Download locally from **Client => Action**:
+Download locally from **Client → Action**:

@@ -105,7 +105,7 @@ Create user (must bind an email address):
Login to Flashduty console and obtain the Redirect URL (needed in subsequent steps).
-Path: **Access Control => Single Sign-On => OIDC Protocol => Flashduty Service Provider Info => Redirect URL**
+Path: **Access Control → Single Sign-On → OIDC Protocol → Flashduty Service Provider Info → Redirect URL**

@@ -129,11 +129,11 @@ Login to Keycloak console, create new Client:
### 3. Get Client Information
- **Client ID**: The ID entered when creating the Client
-- **Client Secret**: View in **Client Details => Credentials** card
+- **Client Secret**: View in **Client Details → Credentials** card

-- **Issuer**: View in **Realm settings => Endpoints => OpenID Endpoint Configuration**
+- **Issuer**: View in **Realm settings → Endpoints → OpenID Endpoint Configuration**

diff --git a/en/on-call/integration/sso/openldap.mdx b/en/on-call/integration/sso/openldap.mdx
index 9e152bd2..0bf21bc6 100644
--- a/en/on-call/integration/sso/openldap.mdx
+++ b/en/on-call/integration/sso/openldap.mdx
@@ -121,7 +121,7 @@ Access `http://ip:8088/` in your browser and login with the following credential
<Note>
-In **User Path** (e.g., `cn=flash duty` under `ou=people` in the image above) => **Add new attribute** => select **Email** to add the Email attribute for users. Skip if it already exists.
+In **User Path** (e.g., `cn=flash duty` under `ou=people` in the image above) → **Add new attribute** => select **Email** to add the Email attribute for users. Skip if it already exists.
</Note>
## Flashduty Integration
diff --git a/en/on-call/integration/sso/role-team-sync.mdx b/en/on-call/integration/sso/role-team-sync.mdx
index 03717ab9..dfdea665 100644
--- a/en/on-call/integration/sso/role-team-sync.mdx
+++ b/en/on-call/integration/sso/role-team-sync.mdx
@@ -6,17 +6,25 @@ keywords: ["SSO", "single sign-on", "role sync", "team sync", "sync configuratio
In the **Platform Management → Single Sign-On** settings page, the **Sync Configuration** section decides how members get their Flashduty roles and teams when they sign in via SSO:
-- **SAML2.0 / OIDC / CAS**: matching by the **role names / team names** returned by the identity provider (claim / attribute names). When no name matches, **default roles / default teams** apply only to members actually created during this sign-in; existing members keep their assignments.
+- **SAML2.0 / OIDC / CAS**: matching by the **role names / team names** returned by the identity provider (claim / attribute names). This page covers these three protocols.
- **LDAP**: does not use name matching; instead it matches the user's **LDAP Group** DN against mapping rules. See [LDAP Role and Team Synchronization](/en/platform/configure-sso#ldap-role-and-team-synchronization).
-Sync runs on **every SSO sign-in**. This page describes the sync configuration and matching rules for SAML2.0 / OIDC / CAS.
-
<Warning>
**In most cases, leave default roles and default teams empty to keep fallback assignments off.**
-Defaults apply only to members actually created during this sign-in without matches for the corresponding names, not to existing members. They are still shared rules for the whole SSO configuration: every new member meeting these conditions receives the same default roles or joins the same default teams. Do not configure general administrator privileges or sensitive teams just to make a sign-in test work.
+Defaults are shared rules for the whole SSO configuration: every eligible new member receives the same default roles and joins the same default teams. Do not configure general administrator privileges or sensitive teams just to make a sign-in test work.
</Warning>
+## When Sync Takes Effect and Overwrite Semantics
+
+- With sync enabled and matching names, valid mappings update the corresponding roles or teams on **every SSO sign-in**.
+- Valid mappings **replace assignments rather than append to them**, including manually assigned roles or team memberships; they are not merged with existing assignments.
+- Without matching names, eligible defaults apply only to members actually created during this sign-in; existing members keep their corresponding roles or teams.
+- Without matching names or eligible defaults, that dimension is not synced: new members follow the existing creation flow, and existing members' roles or teams are not cleared.
+- When both sync switches are off, sign-in never changes a member's roles or teams.
+
+**A first SSO sign-in does not necessarily create a new member.** Members already created or invited by an administrator, and existing members linked to a stable user ID for the first time, do not receive defaults. Defaults apply only when Just-In-Time (JIT) provisioning creates a new member record during this sign-in. Changing defaults does not reassign existing members' roles or teams.
+
## Sync Configuration Fields
The **Sync Configuration** section contains the following fields:
@@ -27,11 +35,11 @@ The **Sync Configuration** section contains the following fields:
| Sync Teams (`sync_team_enabled`) | Switch. When on, teams are synced by name; when off, sign-in never changes a member's teams |
| Role Field (`roles`) | The name of the claim / attribute that carries the **role names** returned by the identity provider, e.g. `roles`. Accepts a string or an array of strings; names are matched exactly |
| Team Field (`teams`) | The name of the claim / attribute that carries the **team names** returned by the identity provider, e.g. `teams`. Accepts a string or an array of strings; names are matched exactly |
-| Default Roles (`default_role_ids`) | Multi-select of roles (the dropdown lists enabled roles only). With role sync enabled and no names matching an eligible role, defaults apply **only to members created during this sign-in**. Existing members are unaffected. **Usually leave empty** |
-| Default Teams (`default_team_ids`) | Multi-select of teams. With team sync enabled and no names matching an eligible team, defaults apply **only to members created during this sign-in**. Existing members are unaffected. **Usually leave empty** |
+| Default Roles (`default_role_ids`) | Multi-select of roles (the dropdown lists enabled roles only). Used only when role sync is on, no name matches, and this sign-in creates a new member. **Usually leave empty** |
+| Default Teams (`default_team_ids`) | Multi-select of teams. Used only when team sync is on, no name matches, and this sign-in creates a new member. **Usually leave empty** |
<Note>
-If the **Role Field / Team Field is left empty**, no name matches. With the corresponding sync switch on, only newly created members can receive eligible defaults for that dimension; existing members keep their assignments. Without eligible defaults, that dimension is not synced and existing roles or teams are not cleared (see [When Sync Takes Effect and Overwrite Semantics](#when-sync-takes-effect-and-overwrite-semantics)).
+If the **Role Field / Team Field is left empty**, no name matches, which behaves like "no matching names"; see [When Sync Takes Effect and Overwrite Semantics](#when-sync-takes-effect-and-overwrite-semantics).
</Note>
Defaults have no separate toggle: clear the corresponding selection to turn fallback assignments off. To stop SSO from managing roles or teams, disable the corresponding sync option; clearing defaults alone does not prevent valid mappings from replacing existing assignments on every sign-in.
@@ -61,15 +69,15 @@ Role/team name matching happens on the Flashduty server, with these rules:
### Default roles / default teams fallback
-- Eligible defaults apply only when this sign-in **actually creates a new member** and no name matches for that dimension. Roles and teams fall back **independently** of each other. Existing members do not receive defaults on sign-in.
+- Roles and teams fall back **independently**; for when defaults apply, see [When Sync Takes Effect and Overwrite Semantics](#when-sync-takes-effect-and-overwrite-semantics).
- Default roles: the preset roles (`Admin` / `Responder` / `Viewer`) are always eligible; a custom default role must **exist and be enabled**, otherwise it is skipped with a warning logged.
- Default teams: must **exist and not be deleted**, otherwise they are skipped.
- The resolved role IDs / team IDs are deduplicated and sorted in ascending order.
<Warning>
-**A role or team selected as a default role or default team cannot be deleted.** The delete request returns `ReferenceExist` (the resource is still referenced by other entities and cannot be deleted): role deletion is blocked before the member-binding check runs, and forced deletion (`is_force`) does not bypass it either — forced deletion only revokes member assignments; SSO default references must be removed first. Unselect the target role or team in that SSO configuration's **Default Roles / Default Teams** options and save before you can delete it.
+**A role or team selected as a default role or default team cannot be deleted.** Deletion returns `ReferenceExist`, and forced deletion (`is_force`) does not bypass it. Unselect the role or team in the SSO configuration's **Default Roles / Default Teams** and save first, then delete it.
-The check looks at the **saved** defaults: even when SSO or the corresponding sync switch is currently off, the reference remains as long as `default_role_ids` / `default_team_ids` still hold the value — re-enabling the configuration must not restore dangling IDs.
+The reference remains as long as the defaults are saved, even when SSO or the corresponding sync switch is currently off.
</Warning>
## Where Each Protocol Reads the Names
@@ -88,16 +96,6 @@ When saving the SSO configuration, the console discards sync fields that do not
- **LDAP**: keeps the Group field, the Group DN mapping rules (`role_team_mapping`), and the default roles; `roles`, `teams`, and `default_team_ids` are not saved.
- **SAML2.0 / OIDC / CAS**: keeps `roles`, `teams`, `default_role_ids`, and `default_team_ids`; `group` and the mapping rules are not saved.
-## When Sync Takes Effect and Overwrite Semantics
-
-- With sync enabled and matching names, valid mappings update the corresponding roles or teams on **every SSO sign-in**.
-- Valid mappings **replace assignments rather than append to them**, including manually assigned roles or team memberships; they are not merged with existing assignments.
-- Without matching names, eligible defaults apply only to members actually created during this sign-in; existing members keep their corresponding roles or teams.
-- Without matching names or eligible defaults, that dimension is not synced: new members follow the existing creation flow, and existing members' roles or teams are not cleared.
-- When both sync switches are off, sign-in never changes a member's roles or teams.
-
-**A first SSO sign-in does not necessarily create a new member.** Members already created or invited by an administrator, and existing members linked to a stable user ID for the first time, do not receive defaults. Defaults apply only when Just-In-Time (JIT) provisioning creates a new member record during this sign-in. Changing defaults does not reassign existing members' roles or teams.
-
<CardGroup cols={4}>
<Card title="Single Sign-On Configuration" icon="shield-check" href="/en/platform/configure-sso">
Overall configuration guide for every protocol
diff --git a/en/on-call/integration/webhooks/alert-webhook.mdx b/en/on-call/integration/webhooks/alert-webhook.mdx
index 341dbfd6..e6827587 100644
--- a/en/on-call/integration/webhooks/alert-webhook.mdx
+++ b/en/on-call/integration/webhooks/alert-webhook.mdx
@@ -10,7 +10,7 @@ Configure alert Webhook. When specific operations occur on alerts (such as trigg
<span id="EventTypes"></span>
-## 1. Event Types
+## Event Types
The following event types are currently supported; more may be added in the future.
@@ -28,7 +28,7 @@ The following event types are currently supported; more may be added in the futu
Manually closing an alert does not currently trigger a Webhook callback.
</Note>
-## 2. Push Description
+## Push Description
### Request Method
@@ -187,7 +187,7 @@ curl -X POST 'https://example.com/alert/webhook?a=a' \
}' -v
```
-## 3. Configuration Guide
+## Configuration Guide
Go to **Integration Center** → **Webhook** → Add or edit an **Alert Webhook** integration.
@@ -214,7 +214,7 @@ Disabling TLS certificate verification may expose you to man-in-the-middle attac
**Custom request body** and **value mapping** are supported by **Incident Webhook** only. An **Alert Webhook** always pushes the [Payload structure](#request-payload) described above and cannot reorganize it. See the **Custom Request Body** and **Value Mapping** sections of [Incident Webhook](/en/on-call/integration/webhooks/incident-webhook).
</Note>
-## 4. Invocation History
+## Invocation History
Alert Webhook provides a complete invocation history, helping you troubleshoot push delivery and debug callback interfaces.
@@ -250,7 +250,7 @@ Click **View Details** on a record to see the complete request and response info
- **Request**: Includes Endpoint, Request Headers, and Request Payload
- **Response**: On success, shows Response Headers and Response Body; on failure, shows Error Message
-## 5. FAQ
+## FAQ
1. **Is there a response timeout?**
diff --git a/en/on-call/integration/webhooks/custom-actions.mdx b/en/on-call/integration/webhooks/custom-actions.mdx
index 70b1ca04..04a8968a 100644
--- a/en/on-call/integration/webhooks/custom-actions.mdx
+++ b/en/on-call/integration/webhooks/custom-actions.mdx
@@ -1,6 +1,6 @@
---
title: "Webhook Custom Actions"
-sidebarTitle: "Custom Actions"
+sidebarTitle: "Webhook Custom Actions"
description: "Configure custom actions that call external HTTP endpoints from Flashduty incidents for remediation, enrichment, and workflow automation."
keywords: ["custom action", "HTTP callback", "incident automation", "remediation", "webhook"]
---
@@ -9,7 +9,7 @@ keywords: ["custom action", "HTTP callback", "incident automation", "remediation
Configure incident custom actions, allowing you to quickly call external interfaces during incident troubleshooting to achieve self-healing, information enrichment, or any custom operations.
-## 1. Create Action
+## Create Action
1. Login to Flashduty console, go to **Integration Center - Webhook**
2. Click to add Custom Action integration
@@ -28,7 +28,7 @@ Disabling TLS certificate verification may expose you to man-in-the-middle attac
Each channel can have a maximum of 5 custom actions. If a channel has reached this limit, it cannot be selected when adding a new custom action.
</Warning>
-## 2. Push Description
+## Push Description
### Request Method
@@ -349,7 +349,7 @@ curl -X POST 'https://example.com/incident/action?a=a' \
}' -v
```
-## 3. Custom Request Body and Value Mapping
+## Custom Request Body and Value Mapping
### Custom request body (custom_body)
@@ -400,7 +400,7 @@ Value mapping automatically transforms field values during variable resolution i
Used with `"severity": "{{incident.incident_severity}}"` in the custom request body, when the incident severity is `Critical`, the `severity` field in the push result will be `P0`. Values that do not match any mapping are sent as-is.
-## 4. Use Cases
+## Use Cases
### Restart Host
@@ -418,7 +418,7 @@ When an incident occurs, if it's determined to be caused by a change, directly t
When an incident is confirmed to impact production services, trigger external status page updates to promptly notify your customers or upstream/downstream parties.
-## 5. FAQ
+## FAQ
1. **Is there a response timeout?**
diff --git a/en/on-call/integration/webhooks/incident-webhook.mdx b/en/on-call/integration/webhooks/incident-webhook.mdx
index f24ae9cb..5f82fdfc 100644
--- a/en/on-call/integration/webhooks/incident-webhook.mdx
+++ b/en/on-call/integration/webhooks/incident-webhook.mdx
@@ -8,7 +8,7 @@ Configure incident Webhook. When specific operations occur on incidents (such as
<span id="EventTypes"></span>
-## 1. Event Types
+## Event Types
The following event types are currently supported; more may be added in the future.
@@ -43,7 +43,7 @@ The following event types are currently supported; more may be added in the futu
</div>
-## 2. Push Description
+## Push Description
### Request Method
@@ -425,7 +425,7 @@ curl -X POST 'https://example.com/incident/webhook?a=a' \
}' -v
```
-## 3. Configuration Guide
+## Configuration Guide
Go to **Integration Center** → **Webhook** → Add or edit an **Incident Webhook** integration.
@@ -523,7 +523,7 @@ Used with the following custom request body:
When the incident severity is `Critical`, the `severity` field in the push result will be `P0`. Values that do not match any mapping are sent as-is.
-## 4. Invocation History
+## Invocation History
Incident Webhook provides a complete invocation history, helping you troubleshoot push delivery and debug callback interfaces.
@@ -559,7 +559,7 @@ Click **View Details** on a record to see the complete request and response info
- **Request**: Includes Endpoint, Request Headers, and Request Payload
- **Response**: On success, shows Response Headers and Response Body; on failure, shows Error Message
-## 5. FAQ
+## FAQ
1. **Is there a response timeout?**
diff --git a/en/on-call/integration/webhooks/servicedesk-plus-sync.mdx b/en/on-call/integration/webhooks/servicedesk-plus-sync.mdx
index f8625488..5d3b278f 100644
--- a/en/on-call/integration/webhooks/servicedesk-plus-sync.mdx
+++ b/en/on-call/integration/webhooks/servicedesk-plus-sync.mdx
@@ -26,10 +26,12 @@ Select the corresponding Developer Console address based on your ServiceDesk Plu
3. Select the maximum **10 minutes** for `Time Duration`, enter any description in `Scope Description` like: Used for Flashduty sync, and create.
4. Copy the generated **Code**, **Client ID**, and **Client Secret** for later use.
-
-
+
+
-###### Note: The Code is only valid for 10 minutes and can only be used once. After obtaining the Code, please complete [Integration Authorization](#integration-authorization) within the validity period.
+<Note>
+The Code is only valid for 10 minutes and can only be used once. After obtaining the Code, please complete [Integration Authorization](#integration-authorization) within the validity period.
+</Note>
### In Flashduty On-call
#### Step 2: Integration Authorization <span id="integration-authorization"></span>
@@ -44,7 +46,9 @@ Select the corresponding API Endpoint and Accounts Server URL based on your Serv
1. Login to ServiceDesk Plus console, click `Generate API Key` in Personal Center.
2. Select **Never Expire** for `Token Expiration`, copy the generated **Token** for later use, and complete [Integration Authorization](#private-deployment-authorization).
-###### Note: The user generating the API key needs relevant permissions such as create/update requests, get template/priority/custom field lists. Insufficient permissions will prevent completing integration configuration—we recommend using an admin role.
+<Note>
+The user generating the API key needs relevant permissions such as create/update requests, get template/priority/custom field lists. Insufficient permissions will prevent completing integration configuration—we recommend using an admin role.
+</Note>
### In Flashduty On-call
#### Step 2: Integration Authorization <span id="private-deployment-authorization"></span>
@@ -120,7 +124,7 @@ To sync ServiceDesk Plus requests to Flashduty, refer to this configuration item
```
7. Click `Save` to complete configuration.
-
+
##### Step 3: Create Trigger
1. Login to ServiceDesk Plus console, find the `Setup` configuration page.
@@ -132,7 +136,7 @@ To sync ServiceDesk Plus requests to Flashduty, refer to this configuration item
7. In `Actions`, select **Webhook** and check **to_Flashduty** channel.
8. Click `Save` to complete configuration.
-
+
## Sync Information Mapping
diff --git a/en/on-call/integration/webhooks/servicenow-sync.mdx b/en/on-call/integration/webhooks/servicenow-sync.mdx
index f50bdeef..a1a41539 100644
--- a/en/on-call/integration/webhooks/servicenow-sync.mdx
+++ b/en/on-call/integration/webhooks/servicenow-sync.mdx
@@ -18,7 +18,7 @@ Create a user to connect to the ServiceNow instance for Incident synchronization
4. Keep `Password needs reset`, `Web service access only`, and `Internal Integration User` unchecked.
5. Submit to save.
-
+
### Configure User
@@ -34,8 +34,8 @@ Create a user to connect to the ServiceNow instance for Incident synchronization
3. Click `Roles` to add **personalize_dictionary and itil** roles (personalize_dictionary permission is not needed if you don't need to configure custom field mapping).
4. Click `Update` to save configuration.
-
-
+
+
## In Flashduty On-call
diff --git a/en/on-call/quickstart/faq.mdx b/en/on-call/quickstart/faq.mdx
index db58fd74..f9373cbf 100644
--- a/en/on-call/quickstart/faq.mdx
+++ b/en/on-call/quickstart/faq.mdx
@@ -4,77 +4,58 @@ sidebarTitle: "FAQ"
description: "Learn about the most common questions when using Flashduty On-call"
---
-## Product Introduction
+Jump to: [Product](#product-introduction) · [Billing and subscription](#billing-and-subscription) · [Notification channels](#notification-channels) · [Not receiving notifications](#not-receiving-notifications) · [Features and integrations](#features-and-integrations) · [Security and stability](#security-and-stability)
----
+## Product Introduction
<AccordionGroup>
- <Accordion title="What is Flashduty On-call?">
- Flashduty On-call is positioned as a one-stop alert response platform. We provide IT professionals with on-call, noise reduction, escalation, and automation capabilities to accelerate enterprise incident response and reduce losses.
+ <Accordion id="what-is-on-call" title="What is Flashduty On-call?">
+ Flashduty On-call is a one-stop alert response platform. It gives IT teams on-call scheduling, noise reduction, escalation, and automation to speed up incident response and reduce losses.
</Accordion>
- <Accordion title="Is Flashduty On-call right for me?">
- If your organization or team has the following situations, you should use Flashduty On-call:
-
- - Need a place to collect alerts from all sources across the company for unified handling, tracking, and analysis
- - Need to classify alerts by severity, dynamically notify key personnel through different channels, need automatic escalation processes to prevent unhandled alerts
- - Daily alert handling takes most of your energy, need noise reduction to solve alert fatigue
+ <Accordion id="is-it-for-me" title="Is Flashduty On-call right for me?">
+ Flashduty On-call is a good fit if your team:
+
+ - Needs one place to collect alerts from every source in the company for unified handling, tracking, and analysis
+ - Needs to grade alerts by severity, notify key people through different channels, and escalate automatically so no alert goes unhandled
+ - Spends most of its time handling alerts and needs noise reduction to fight alert fatigue
</Accordion>
- <Accordion title="What advantages does Flashduty On-call have over other platforms?">
- 1. We provide more flexible and easy-to-use features
- 2. We provide more professional and attentive service
- 3. We provide more reasonable product pricing
-
- Contact us to get a professional procurement guide.
+ <Accordion id="advantages" title="What advantages does Flashduty On-call have over other platforms?">
+ More flexible and easy-to-use features, more professional service, and more reasonable pricing. Contact us for a procurement guide, or see the comparisons with [PagerDuty](/en/on-call/comparison/vs-pagerduty) and [Opsgenie](/en/on-call/comparison/vs-opsgenie).
</Accordion>
</AccordionGroup>
## Billing and Subscription
----
-
<AccordionGroup>
- <Accordion title="Flashduty On-call billing model">
- Flashduty On-call's billing model is based on the number of Licenses purchased, each License corresponds to one account member.
-
- For example, if you only purchased one License, only one member can use all Flashduty On-call features. You can still invite more members to join, but only members with Licenses can configure the platform, other members **cannot use any platform features** (limited to receiving incident notifications).
-
- ### License Allocation Methods
-
- Administrators can actively allocate Licenses to different members. When allocating, you can set the License type:
-
+ <Accordion id="pricing" title="How is Flashduty On-call priced?">
+ We charge by active users and offer three editions: Free, Standard, and Business. See the [pricing page](https://flashcat.cloud/flashduty/price/) for a detailed comparison.
+
+ - Users who use commercial features in a month are active users and must hold a License.
+ - Each License corresponds to one account member. For example, with one License only one member can use all features; you can still invite more members, but they can only receive incident notifications.
+ - At the end of each monthly cycle, fixed Licenses stay valid and temporary Licenses are released; a deleted member's License is released automatically.
+
+ **License types**: administrators choose a type when allocating a License.
+
| Type | Description |
| --- | --- |
- | **Fixed** | Valid for the purchase period, won't be preempted, suitable for members who need to handle incidents and configure business |
- | **Temporary** | Auto-released at the end of each cycle, can be occupied through allocation or preemption when sufficient Licenses are available |
-
- ### Members Without Licenses
-
- - Cannot use any features, including viewing incident list/details, **can only passively receive alert messages**
- - When configuring escalation rules, you can choose to notify members without Licenses
- - Members without Licenses cannot view, close, or perform other operations on incidents even if they receive messages
- - Members without Licenses share the tenant's email, SMS, phone package quota
- - Members without Licenses will see permission denied when logging into the console to view/handle incidents
- </Accordion>
+ | **Fixed** | Valid for the purchase period and never preempted; for members who handle incidents and configure the platform |
+ | **Temporary** | Released at the end of each cycle; can be taken by allocation or preemption when enough Licenses are available |
- <Accordion title="How is Flashduty On-call priced?">
- We charge by active users and offer three different editions: Free, Standard, and Business.
-
- For detailed comparison, visit: [Pricing Page](https://flashcat.cloud/flashduty/price/)
-
- - We define active users as users who use commercial features that month; they must obtain a License to use
- - At the end of each monthly cycle, fixed Licenses held by active users remain valid, temporary Licenses are released
- - When a member is deleted, their License is automatically released
- - Viewing alerts requires a License; passively receiving notifications doesn't require a License
+ **Members without a License**:
+
+ - Can only passively receive alert messages; escalation rules can still notify them
+ - Cannot view the incident list or details, or acknowledge or close incidents; the console shows a permission notice when they sign in
+ - Share the tenant's email, SMS, and phone quota with other members
</Accordion>
- <Accordion title="What happens after my On-call subscription expires?">
+ <Accordion id="subscription-expired" title="What happens after my On-call subscription expires?">
Once the subscription expires, creating is frozen, while your existing data and configuration stay intact:
- **Alert ingestion stops**: no integration receives new alert events, and no new incidents are created
- - **Historical data stays available**: historical alerts can still be viewed and handled, and existing incidents can still be processed normally
- - **Creating is frozen**: entries for creating a channel, a schedule, a manual incident, and a war room are disabled, with a tooltip explaining why
+ - **Historical data stays available**: historical alerts and existing incidents can still be viewed and handled
+ - **Creating is frozen**: creating a channel, a schedule, a manual incident, or a war room is disabled
- **On-page notices**: the Alert List, the Incident List, and the sidebar show a persistent subscription-expired notice
- **Renewal restores everything**: alert ingestion resumes automatically after renewal — no reconfiguration needed
</Accordion>
@@ -82,10 +63,8 @@ description: "Learn about the most common questions when using Flashduty On-call
## Notification Channels
----
-
<AccordionGroup>
- <Accordion title="What notification methods does Flashduty On-call support?">
+ <Accordion id="notification-channels" title="What notification methods does Flashduty On-call support?">
| Channel | Direct Message | Group Chat |
| --- | :---: | :---: |
| Voice | ✅ | |
@@ -103,280 +82,119 @@ description: "Learn about the most common questions when using Flashduty On-call
| Telegram Bot | | ✅ |
</Accordion>
- <Accordion title="How does Flashduty On-call ensure notifications reach me?">
- Flashduty On-call strives to ensure availability of every channel:
-
- - **Voice, SMS, Email**: We use high-availability services from multiple cloud vendors, can quickly switch when one fails
- - **IM App Messages**: When direct message delivery fails, system uses SMS and email as fallback reminders
- - **Escalation Rule Settings**: We recommend setting loop notifications—if incidents aren't acknowledged, system notifies multiple times in a loop; or set escalation levels—if current level personnel don't handle in time, incident escalates to next level
+ <Accordion id="delivery-reliability" title="How does Flashduty On-call ensure notifications reach me?">
+ - **Voice, SMS, and email**: high-availability services from multiple cloud vendors, with fast failover when one has problems
+ - **IM app messages**: when a direct message fails, SMS and email are used as a fallback
+ - **Escalation rules**: set up loop notifications (notify repeatedly until acknowledged) or escalation levels (escalate to the next level when the current one doesn't respond in time)
</Accordion>
- <Accordion title="Does Flashduty On-call use fixed numbers for voice notifications?">
- Yes, we use fixed numbers for voice notifications. You can download the Flashduty On-call App and authorize automatic contact sync to your address book to avoid missing calls.
-
- <Tabs>
- <Tab title="🇨🇳 China">
- | Number | Location |
- | :--- | :--- |
- | (010) 21364727 | Beijing |
- | (010) 21364713 | Beijing |
- | (010) 21364708 | Beijing |
- | (021) 32017538 | Shanghai |
- | (0571) 23675454 | Hangzhou |
- | (0571) 23675496 | Hangzhou |
- | +1 6465861127 | Hong Kong |
- | +1 6465861127 | Taiwan |
- </Tab>
- <Tab title="🌏 Asia Pacific">
- <CardGroup cols={3}>
- <Card title="🇸🇬 Singapore" icon="phone">
- +65 6531297878
- </Card>
- <Card title="🇯🇵 Japan" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇰🇷 South Korea" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇦🇺 Australia" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇮🇳 India" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇲🇾 Malaysia" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇹🇭 Thailand" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇻🇳 Vietnam" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇮🇩 Indonesia" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇵🇭 Philippines" icon="phone">
- +1 6465861127
- </Card>
- </CardGroup>
- </Tab>
- <Tab title="🌎 Americas & Europe">
- <CardGroup cols={3}>
- <Card title="🇺🇸 United States" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇨🇦 Canada" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇬🇧 United Kingdom" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇩🇪 Germany" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇫🇷 France" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇳🇱 Netherlands" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇮🇹 Italy" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇪🇸 Spain" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇧🇷 Brazil" icon="phone">
- +1 6465861127
- </Card>
- </CardGroup>
- </Tab>
- <Tab title="🌍 Other Regions">
- Beyond the countries and regions listed above, we also support voice notifications in **200+** countries and regions globally:
-
- <CardGroup cols={4}>
- <Card title="🇦🇪 UAE" icon="phone">+1 6465861127</Card>
- <Card title="🇸🇦 Saudi Arabia" icon="phone">+1 6465861127</Card>
- <Card title="🇮🇱 Israel" icon="phone">+1 6465861127</Card>
- <Card title="🇹🇷 Turkey" icon="phone">+1 6465861127</Card>
- <Card title="🇿🇦 South Africa" icon="phone">+1 6465861127</Card>
- <Card title="🇪🇬 Egypt" icon="phone">+1 6465861127</Card>
- <Card title="🇳🇿 New Zealand" icon="phone">+1 6465861127</Card>
- <Card title="🇷🇺 Russia" icon="phone">+1 6465861127</Card>
- <Card title="🇵🇱 Poland" icon="phone">+1 6465861127</Card>
- <Card title="🇸🇪 Sweden" icon="phone">+1 6465861127</Card>
- <Card title="🇨🇭 Switzerland" icon="phone">+1 6465861127</Card>
- <Card title="🇦🇹 Austria" icon="phone">+1 6465861127</Card>
- </CardGroup>
-
- <Note>
- If you cannot receive voice notifications in your region, please contact us: [support@flashcat.cloud](mailto:support@flashcat.cloud)
- </Note>
- </Tab>
- </Tabs>
+ <Accordion id="voice-numbers" title="Which numbers do voice notifications come from?">
+ Voice notifications come from fixed numbers. Install the Flashduty On-call App and allow it to sync contacts to your address book so you don't miss calls.
+
+ | Region | Number |
+ | :--- | :--- |
+ | Mainland China · Beijing | (010) 21364727, (010) 21364713, (010) 21364708 |
+ | Mainland China · Shanghai | (021) 32017538 |
+ | Mainland China · Hangzhou | (0571) 23675454, (0571) 23675496 |
+ | Singapore | +65 6531297878 |
+ | Hong Kong and Taiwan, plus Japan, South Korea, Australia, India, Malaysia, Thailand, Vietnam, Indonesia, the Philippines, the United States, Canada, the United Kingdom, Germany, France, the Netherlands, Italy, Spain, Brazil, the UAE, Saudi Arabia, Israel, Turkey, South Africa, Egypt, New Zealand, Russia, Poland, Sweden, Switzerland, Austria, and more | +1 6465861127 |
+
+ Voice notifications cover **200+** countries and regions. If you can't receive voice notifications in your region, contact [support@flashcat.cloud](mailto:support@flashcat.cloud).
</Accordion>
- <Accordion title="What regions does Flashduty On-call SMS notification support?">
- SMS notifications support almost all regions globally. Currently available regions include:
-
- <Tabs>
- <Tab title="🇨🇳 China">
- <CardGroup cols={4}>
- <Card title="🇨🇳 Mainland China" icon="message" />
- <Card title="🇲🇴 Macao Special Administrative Region of China" icon="message" />
- <Card title="Taiwan region of China" icon="message" />
- <Card title="🇭🇰 Hong Kong Special Administrative Region of China" icon="message" />
- </CardGroup>
- </Tab>
- <Tab title="🌏 Asia Pacific">
- <CardGroup cols={4}>
- <Card title="🇬🇺 Guam" icon="message" />
- <Card title="🇰🇷 South Korea" icon="message" />
- <Card title="🇲🇾 Malaysia" icon="message" />
- <Card title="🇯🇵 Japan" icon="message" />
- <Card title="🇹🇭 Thailand" icon="message" />
- <Card title="🇧🇳 Brunei" icon="message" />
- <Card title="🇸🇬 Singapore" icon="message" />
- <Card title="🇮🇳 India" icon="message" />
- <Card title="🇮🇩 Indonesia" icon="message" />
- </CardGroup>
- </Tab>
- <Tab title="🌎 Americas & Europe">
- <CardGroup cols={4}>
- <Card title="🇮🇪 Ireland" icon="message" />
- <Card title="🇪🇪 Estonia" icon="message" />
- <Card title="🇧🇸 Bahamas" icon="message" />
- <Card title="🇧🇷 Brazil" icon="message" />
- <Card title="🇵🇱 Poland" icon="message" />
- <Card title="🇩🇰 Denmark" icon="message" />
- <Card title="🇩🇪 Germany" icon="message" />
- <Card title="🇫🇷 France" icon="message" />
- <Card title="🇨🇴 Colombia" icon="message" />
- <Card title="🇨🇿 Czech Republic" icon="message" />
- <Card title="🇱🇻 Latvia" icon="message" />
- <Card title="🇱🇹 Lithuania" icon="message" />
- <Card title="🇷🇴 Romania" icon="message" />
- <Card title="🇲🇹 Malta" icon="message" />
- <Card title="🇲🇰 North Macedonia" icon="message" />
- <Card title="🇲🇽 Mexico" icon="message" />
- <Card title="🇳🇴 Norway" icon="message" />
- <Card title="🇵🇹 Portugal" icon="message" />
- <Card title="🇨🇭 Switzerland" icon="message" />
- <Card title="🇸🇰 Slovakia" icon="message" />
- <Card title="🇺🇾 Uruguay" icon="message" />
- <Card title="🇪🇸 Spain" icon="message" />
- <Card title="🇮🇹 Italy" icon="message" />
- <Card title="🇬🇧 United Kingdom" icon="message" />
- <Card title="🇨🇱 Chile" icon="message" />
- </CardGroup>
- </Tab>
- <Tab title="🌍 Other Regions">
- <CardGroup cols={4}>
- <Card title="🇦🇺 Australia" icon="message" />
- <Card title="🇧🇭 Bahrain" icon="message" />
- <Card title="🇰🇮 Kiribati" icon="message" />
- <Card title="🇹🇷 Turkey" icon="message" />
- <Card title="🇳🇿 New Zealand" icon="message" />
- </CardGroup>
- </Tab>
- </Tabs>
-
- <Note>
- If you cannot receive SMS notifications in your region, please contact us: [support@flashcat.cloud](mailto:support@flashcat.cloud)
- </Note>
+ <Accordion id="sms-regions" title="Which regions does SMS notification support?">
+ | Area | Countries and regions |
+ | :--- | :--- |
+ | China | Mainland China, Hong Kong SAR, Macao SAR, Taiwan region |
+ | Asia Pacific | Guam, South Korea, Malaysia, Japan, Thailand, Brunei, Singapore, India, Indonesia |
+ | Americas & Europe | Ireland, Estonia, Bahamas, Brazil, Poland, Denmark, Germany, France, Colombia, Czech Republic, Latvia, Lithuania, Romania, Malta, North Macedonia, Mexico, Norway, Portugal, Switzerland, Slovakia, Uruguay, Spain, Italy, United Kingdom, Chile |
+ | Other | Australia, Bahrain, Kiribati, Turkey, New Zealand |
+
+ If you can't receive SMS notifications in your region, contact [support@flashcat.cloud](mailto:support@flashcat.cloud).
</Accordion>
- <Accordion title="Why can't I receive voice notifications?">
- Voice calls are highly dependent on terminal signal and settings. If you persistently cannot receive voice notifications, try the following:
+ <Accordion id="custom-bot-notifications" title="I don't use Feishu/Dingtalk/WeCom/Telegram — how can I receive bot notifications?">
+ Flashduty does not validate the domain of bot webhook URLs, so you can:
- 1. If you're using a phone number registered outside Mainland China, check our supported region list
- 2. Check your phone's blacklist or call records for blocking, usually landline numbers like 010xxx or 021xx; if found, remove from blacklist and whitelist
- 3. If no blacklist is visible on the phone, there may be carrier-level blocking services enabled:
- - **China Mobile**: Check via WeChat official account "中国移动高频骚扰电话防护"
- - **China Telecom**: Follow official account "天翼防骚扰" to check
- - **China Unicom**: Follow official account "沃助理" to check, or call customer service
- 4. If your number has been ported, check blocking status across multiple carriers
- 5. Try restarting your phone, reinserting the SIM card, inserting the SIM into another phone to rule out terminal or SIM issues
+ 1. Select any bot type (e.g., Dingtalk Bot) in the escalation rule
+ 2. Set the webhook URL to your own server endpoint
+ 3. Parse the request body on your server using that IM platform's message format
- If you still can't find the cause, please contact us.
+ Flashduty sends alert notifications to your server in that platform's message format, and you can process and forward them to any channel.
</Accordion>
+</AccordionGroup>
+
+## Not Receiving Notifications
- <Accordion title="Why can't I receive email notifications?">
- Try the following:
+<AccordionGroup>
+ <Accordion id="no-voice-call" title="Why can't I receive voice notifications?">
+ Voice calls depend heavily on signal and phone settings. If you keep missing them, check in order:
- 1. Check spam folder in your email client; if found, move out manually to receive normally
- 2. Check if your email client has auto-delete rules; if so, modify the rules
- 3. Contact your company email administrator to check if blocked in backend (Enterprise email like Gmail has strict limits; too many emails may cause blocking). If found, whitelist the email source
+ 1. For numbers registered outside Mainland China, make sure your region is [supported](#voice-numbers)
+ 2. Check your phone's blocklist or call log for blocked calls (usually landlines starting with 010 or 021); if found, unblock and allowlist them
+ 3. If the phone shows no blocking, your carrier may have a blocking service enabled:
+ - **China Mobile**: check via the WeChat official account "中国移动高频骚扰电话防护"
+ - **China Telecom**: check via the official account "天翼防骚扰"
+ - **China Unicom**: check via the official account "沃助理", or call customer service
+ 4. If your number has been ported between carriers, check blocking with each carrier
+ 5. Restart the phone, reinsert the SIM, or try the SIM in another phone to rule out device or SIM issues
- If you still can't find the cause, please contact us.
+ If you still can't find the cause, contact us.
</Accordion>
- <Accordion id="custom-bot-notifications" title="I don't use Feishu/Dingtalk/WeCom/Telegram — how can I receive bot notifications?">
- If you don't use any of the above IM platforms, you can still leverage bot notifications. Flashduty does not validate the domain of bot webhook URLs. You can:
-
- 1. Select any bot type (e.g., Dingtalk Bot) in the escalation rules
- 2. Set the webhook URL to your own server endpoint
- 3. Implement the corresponding IM platform's message push protocol on your server (i.e., parse the request body according to that platform's message format)
+ <Accordion id="no-email" title="Why can't I receive email notifications?">
+ 1. Check your spam folder; if the email is there, move it out
+ 2. Check whether your email client has auto-delete rules; if so, change them
+ 3. Ask your company's email administrator whether the server blocks the messages (enterprise mail such as Gmail limits heavy senders); if so, allowlist the sender
- Flashduty will send alert notifications to your server using that IM platform's message format. You can then process and forward them to any notification channel of your choice.
+ If you still can't find the cause, contact us.
</Accordion>
</AccordionGroup>
## Features and Integrations
----
-
<AccordionGroup>
- <Accordion title="Can Flashduty On-call set routing based on alert fields?">
- Yes. Flashduty On-call supports matching based on multiple dimensions of alert events including labels, severity, title, and description, and routing to different channels.
-
- See: Integration Center → Integration Details → Routing Configuration
+ <Accordion id="routing-by-fields" title="Can Flashduty On-call set routing based on alert fields?">
+ Yes. You can match alert events on labels, severity, title, description, and more, and route them to different channels. See [Routing rules](/en/on-call/integration/alert-integration/routing-rules).
</Accordion>
- <Accordion title="What alert systems can Flashduty On-call integrate with?">
- - **Generic Integrations**: Email alerts (suitable for almost all alert systems), Custom Event Standard (for self-developed monitoring systems)
- - **Open Source Integrations**: Zabbix, Prometheus, Nightingale, and other common open-source monitoring
- - **Commercial Integrations**: Alibaba Cloud, Tencent Cloud, Huawei Cloud, AWS, Azure, and other commercial cloud monitoring
-
- If you have other needs, feel free to contact us.
+ <Accordion id="supported-alert-sources" title="What alert systems can Flashduty On-call integrate with?">
+ - **Generic**: email alerts (works with almost any alert system) and the Custom Event Standard (for in-house monitoring)
+ - **Open source**: Zabbix, Prometheus, Nightingale, and other common open-source monitoring
+ - **Commercial**: Alibaba Cloud, Tencent Cloud, Huawei Cloud, AWS, Azure, and other cloud monitoring
+
+ See the [alert integration overview](/en/on-call/integration/alert-integration/overview) for the full list. For anything else, contact us.
</Accordion>
</AccordionGroup>
## Security and Stability
----
-
<AccordionGroup>
- <Accordion title="How does Flashduty On-call ensure its own stability?">
- **SLA Commitment**:
- - **Functional Availability**: Ensure core functionality is available 99.95% of the time
- - **Delivery Timeliness**: Ensure 99.95% of alerts are delivered within 5 minutes of triggering
-
- **How We Guarantee SLA**:
- 1. **Multi-datacenter Active-Active**: Infrastructure built on multiple data centers, stateful components are all multi-datacenter active-active
- 2. **Asynchronous Processing**: Alerts enter async processing immediately after reporting, with retries on errors to reduce alert loss risk
- 3. **Redundant Alerts**: For important alerts, redundant notification mechanisms are provided; customers can choose multiple channels for loop notifications to ensure delivery
- 4. **Global Acceleration**: Global acceleration enabled for api.flashcat.cloud domain to ensure stable reporting links worldwide
- 5. **Continuous Monitoring**: Comprehensive collection of system metrics, regular stress testing, timely or proactive detection of system issues
+ <Accordion id="stability" title="How does Flashduty On-call ensure its own stability?">
+ **SLA commitment**:
+
+ - **Availability**: core functionality is available 99.95% of the time
+ - **Delivery**: 99.95% of alerts are delivered within 5 minutes of triggering
+
+ **How we meet it**:
+
+ 1. **Multi-datacenter active-active**: infrastructure spans multiple data centers, and all stateful components run active-active
+ 2. **Asynchronous processing**: alerts enter an async pipeline immediately, with retries on errors to reduce the risk of loss
+ 3. **Redundant notification**: important alerts can loop through multiple channels to ensure delivery
+ 4. **Global acceleration**: enabled for api.flashcat.cloud to keep reporting stable worldwide
+ 5. **Continuous monitoring**: comprehensive system metrics and regular stress tests to catch problems early
</Accordion>
- <Accordion title="How does Flashduty On-call ensure data security?">
- 1. Full-stack HTTPS ensures secure data transmission
- 2. Sensitive information encrypted in storage, logs anonymized before persisting
- 3. Important data modifications require MFA verification, operation audit supported
- 4. Regular participation in internationally and domestically recognized third-party security certification audits (ISO27001, ISO9001)
- 5. For customers who need it, NDAs can be signed
- 6. Privacy Policy: [View Privacy Policy](/en/compliance/data-security)
+ <Accordion id="data-security" title="How does Flashduty On-call ensure data security?">
+ 1. Full-stack HTTPS for secure transmission
+ 2. Sensitive information encrypted at rest; logs anonymized before they are written
+ 3. MFA required for important data changes, with operation audit
+ 4. Regular third-party security certification audits recognized in China and internationally (ISO27001, ISO9001)
+ 5. NDAs available for customers who need them
+ 6. Privacy: [View Privacy Policy](/en/compliance/data-security)
</Accordion>
- <Accordion title="Does Flashduty On-call support private deployment?">
- Yes. Flashduty On-call provides a private deployment version nearly identical to the SaaS service.
-
- <Warning>
- Due to high maintenance costs of private deployment, the pricing model differs from SaaS service. Unless necessary, we recommend using the cloud service.
- </Warning>
-
- If you need the private version, please contact us.
+ <Accordion id="private-deployment" title="Does Flashduty On-call support private deployment?">
+ Yes. Flashduty On-call offers a private deployment nearly identical to the SaaS service; because it costs more to maintain, its pricing differs from SaaS. Unless you need it, we recommend the cloud service. Contact us if you need the private version.
</Accordion>
</AccordionGroup>
diff --git a/en/on-call/quickstart/mobile-app.mdx b/en/on-call/quickstart/mobile-app.mdx
index 360b2681..33e0fa42 100644
--- a/en/on-call/quickstart/mobile-app.mdx
+++ b/en/on-call/quickstart/mobile-app.mdx
@@ -9,16 +9,12 @@ Flashduty provides mobile capabilities across **iOS, Android, and mobile H5**. W
## Download and Install
----
-
For download and installation options (App Store, major Android app stores, QR-code package download), see [Personal Settings - Flashduty APP](/en/on-call/configuration/personal-settings#flashduty-app).
Once installed, your first successful sign-in automatically binds the device to your account, and push notifications start working from then on. You can view and manage linked devices on the console's **Personal Center → Flashduty APP** page.
## Sign-in Methods
----
-
<Tabs>
<Tab title="App Sign-in">
The App sign-in page offers two methods:
@@ -44,8 +40,6 @@ You can switch between 中文 and English anytime from the upper-right corner of
## Incident Handling
----
-
### Incident List and Filters
The App home page is the incident list, split into two tabs: **Assigned to me** (with an incident-count badge) and **All**. Swipe left on an incident card to quickly **Acknowledge** or **Close** it.
@@ -96,8 +90,6 @@ Tap the create button on the incident list page to manually create an incident:
## Push Notifications
----
-
After you sign in, the current device is bound to your account automatically and starts receiving pushes. **Tapping a notification opens the corresponding incident detail page directly.**
<Tabs>
@@ -124,8 +116,6 @@ If pushes are not arriving, check in order: whether system notification permissi
## Useful Settings
----
-
Tap the **settings icon** in the upper-right corner of the incident list page to open the settings page:
| Setting | Description |
@@ -139,8 +129,6 @@ Tap the **settings icon** in the upper-right corner of the incident list page to
## Mobile H5
----
-
**m.console.flashcat.cloud** is the web build from the same codebase as the App, with identical capabilities:
- **Landing page for notification links**: incident-related links in SMS and IM messages (such as comment @mention notifications) open the incident detail page on H5 on mobile devices
@@ -149,8 +137,6 @@ Tap the **settings icon** in the upper-right corner of the incident list page to
## Capability Boundaries
----
-
The mobile side focuses on **receiving notifications and handling incidents**. The following configuration capabilities require the PC console:
- Schedules, escalation rules, integration setup, and routing rules
@@ -163,8 +149,6 @@ App push is offered only for the incident dispatch scenario. Collaboration notif
## Related Reading
----
-
<CardGroup cols={3}>
<Card title="Handle and Update Incidents" icon="wrench" href="/en/on-call/incident/handle-update-incident">
Learn all incident handling methods across console, IM, and voice
diff --git a/en/on-call/quickstart/quickstart.mdx b/en/on-call/quickstart/quickstart.mdx
index e49594ca..df4b86a0 100644
--- a/en/on-call/quickstart/quickstart.mdx
+++ b/en/on-call/quickstart/quickstart.mdx
@@ -9,17 +9,13 @@ Welcome to Flashduty On-call! This guide will help you complete the entire proce
{ /*
## Video Demo
----
-
<Video src="https://download.flashcat.cloud/%e6%95%b4%e4%bd%93%e6%bc%94%e7%a4%ba.mp4"></Video>
*/}
## Core Workflow
----
-
-The Flashduty On-call workflow is very intuitive: **Alerts** enter **Channels** through **Integrations**, then notify specific **People** according to **Escalation Rules**.
+The core Flashduty On-call flow: alerts enter channels through integrations, and escalation rules then notify specific people.
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/3c008394e4a6bf75558627289bf2693e.png" alt="Flashduty On-call" />
@@ -27,9 +23,7 @@ The Flashduty On-call workflow is very intuitive: **Alerts** enter **Channels**
## Step 1: Create a Channel
----
-
-A **Channel** is the "war room" for managing incidents. We recommend organizing by business line (like "Payment Center") or component (like "MySQL").
+A **Channel** is the workspace where a team receives and handles incidents. We recommend organizing by business line (like "Payment Center") or component (like "MySQL").
<Steps>
<Step title="Enter Channel List">
@@ -48,8 +42,6 @@ A **Channel** is the "war room" for managing incidents. We recommend organizing
## Step 2: Integrate Alert Data
----
-
Now, let's bring monitoring system alerts into the system. Flashduty On-call provides two integration modes:
<Tabs>
@@ -75,8 +67,6 @@ Now, let's bring monitoring system alerts into the system. Flashduty On-call pro
## Step 3: Configure Escalation Rules
----
-
When alerts come in, who should be notified? This is determined by **Escalation Rules**.
<Warning>
@@ -107,8 +97,6 @@ When alerts come in, who should be notified? This is determined by **Escalation
## Advanced Configuration
----
-
Congratulations! You've completed the core workflow. Next, you can try more advanced features:
<CardGroup cols={3}>
@@ -118,15 +106,13 @@ Congratulations! You've completed the core workflow. Next, you can try more adva
<Card title="Noise Reduction" icon="filter" href="/en/on-call/channel/noise-reduction">
Merge 100 similar alerts into 1
</Card>
- <Card title="Routing Rules" icon="route" href="/en/on-call/channel/integrate-data">
+ <Card title="Routing Rules" icon="route" href="/en/on-call/integration/alert-integration/routing-rules">
Auto-distribute to different channels based on alert content
</Card>
</CardGroup>
## FAQ
----
-
<AccordionGroup>
<Accordion title="Can't receive phone/SMS notifications?">
Go to **Personal → Profile** to check whether your phone number is verified, and under **Personal → Notification**, confirm that phone/SMS channels are enabled in **Incident dispatch**.
diff --git a/en/on-call/statuspage/comparison.mdx b/en/on-call/statuspage/comparison.mdx
index 999f2911..3a767c97 100644
--- a/en/on-call/statuspage/comparison.mdx
+++ b/en/on-call/statuspage/comparison.mdx
@@ -5,8 +5,6 @@ description: "In-depth comparison of Flashduty Status Page vs Atlassian Statuspa
## Introduction
----
-
A **status page** is a critical bridge for building service transparency and trust between businesses and their users. When service disruptions or planned maintenance occur, a clear, timely, and subscribable status page significantly reduces customer anxiety, cuts down on support tickets, and demonstrates professional incident communication.
Flashduty Status Page and Atlassian Statuspage are two leading status page products, but they have a **fundamentally different positioning**:
@@ -24,8 +22,6 @@ Flashduty Status Page and Atlassian Statuspage are two leading status page produ
## Why Choose a Third-Party Status Page?
----
-
Before evaluating specific products, there's a more fundamental question to answer: **should you build your own status page or use a third-party service?**
<AccordionGroup>
@@ -51,8 +47,6 @@ Before evaluating specific products, there's a more fundamental question to answ
## Product Feature Comparison
----
-
### Status Page Types
| Core Capability | Flashduty | Atlassian Statuspage |
@@ -123,8 +117,6 @@ Before evaluating specific products, there's a more fundamental question to answ
## Pricing Comparison
----
-
Atlassian Statuspage is billed as a standalone product, with pricing increasing across tiers based on subscribers, components, team members, and more. Flashduty Status Page is **included in the On-call module at no extra cost**.
| Dimension | Flashduty Status Page | Atlassian Statuspage |
@@ -155,8 +147,6 @@ The additional cost of Flashduty Status Page is zero -- it's a built-in capabili
## Flashduty Status Page Reliability
----
-
As a third-party status page service, Flashduty's own reliability is paramount -- you need confidence that when your services go down, the status page stays up.
<CardGroup cols={2}>
@@ -187,8 +177,6 @@ See the [Service Level Agreement (SLA)](/en/compliance/service-sla) for full ava
## Migrating from Atlassian Statuspage
----
-
Flashduty CLI supports one-click migration of components, sections, incident history, and email subscribers from Atlassian Statuspage (migration requires the Pro plan), with `history.rss` and `history.atom` link format compatibility so existing RSS/Atom subscribers need no changes.
<Steps>
@@ -214,8 +202,6 @@ For detailed command flags and a complete migration walkthrough, see the migrati
## Summary
----
-
<CardGroup cols={3}>
<Card title="More Comprehensive Features" icon="layer-group">
Incident subscriptions, component display controls, maintenance excluded from uptime calculation, native IM notifications, and other **differentiated capabilities**
diff --git a/en/on-call/statuspage/create-manage-page.mdx b/en/on-call/statuspage/create-manage-page.mdx
index fb54c2a1..1a0234fc 100644
--- a/en/on-call/statuspage/create-manage-page.mdx
+++ b/en/on-call/statuspage/create-manage-page.mdx
@@ -58,7 +58,7 @@ By default, status pages are accessed through a Flashduty-provided subdomain. To
In your DNS provider, add a CNAME record for your target domain pointing to the Flashduty-provided status page address.
</Step>
<Step title="Configure the custom domain">
- Enter your custom domain in the status page settings. The system verifies domain uniqueness, and the same domain cannot be used by multiple status pages.
+ Enter your custom domain in the status page settings.
</Step>
</Steps>
diff --git a/en/on-call/statuspage/get-started.mdx b/en/on-call/statuspage/get-started.mdx
index e9991674..068e9b12 100644
--- a/en/on-call/statuspage/get-started.mdx
+++ b/en/on-call/statuspage/get-started.mdx
@@ -100,12 +100,12 @@ For more installation options, see the [CLI documentation](/en/developer/cli).
flashduty login
```
-When prompted, paste your APP Key. To obtain one, sign in to the [Flashduty console](https://console.flashcat.cloud) and copy your APP Key from **Profile > Personal Info**.
+When prompted, paste your APP Key. To obtain one, sign in to the [Flashduty console](https://console.flashcat.cloud) and copy your APP Key from **Profile → Personal Info**.
#### Get your Atlassian Statuspage API Key
1. Log in to the [Atlassian Statuspage management panel](https://manage.statuspage.io/)
-2. Go to **User icon > API info** and copy the API Key
+2. Go to **User icon → API info** and copy the API Key
3. Set the environment variable:
```bash
diff --git a/en/on-call/statuspage/statuspage.mdx b/en/on-call/statuspage/statuspage.mdx
index e57c4ca6..b33c1035 100644
--- a/en/on-call/statuspage/statuspage.mdx
+++ b/en/on-call/statuspage/statuspage.mdx
@@ -6,12 +6,12 @@ description: "Achieve efficient internal and external communication during incid
<Tip>**Plan requirement**: All plans can create public status pages (Free and Standard: up to 1, Pro: up to 5). Internal status pages are available on the Pro plan only (up to 20). [Learn more](https://flashcat.cloud/flashduty/price/)</Tip>
<Note>
-**Two admission rules for creating a status page**: both the list-page entry and the create page itself are checked, so opening the create page directly does not get around them.
+You cannot create a new status page in these cases (existing status pages are unaffected and can still be edited and receive events):
-- **You cannot create one while the subscription is expired or disabled**: the create button on the list page is disabled, and opening the create page directly returns an empty state page whose title says the subscription has expired and creation is temporarily unavailable, and whose body adds that creating status pages resumes after renewal and that already-created status pages are still displayed normally and remain editable at any time. Its primary button becomes **Renew now** (alongside **Back to list**). Existing status pages keep being displayed normally — publishing events, editing and subscriber notifications are all unaffected — and you can create new ones again once you renew.
-- **Internal status pages require Pro or higher**: the create page can be opened directly (`/status-page/create?type=internal`), so on top of the plan gate on the list-page entry, the create page validates the plan again; when the plan is insufficient it returns the same kind of empty state page, this time titled as a missing permission, and its body says internal status pages are only available on Pro or higher and repeats that already-created status pages are still displayed normally and remain editable at any time. The primary button is **Upgrade** (alongside **Back to list**).
+- The subscription is expired or disabled: you can create again after renewing.
+- Internal status pages: require Pro or higher.
-For how an expired subscription affects everything else, see [What happens when your subscription expires](/en/platform/pricing#what-happens-when-your-subscription-expires).
+See [What happens when your subscription expires](/en/platform/pricing#what-happens-when-your-subscription-expires).
</Note>
Service interruptions are inevitable, but communication efficiency can be systematically improved.
@@ -70,7 +70,7 @@ To address different audience needs, Flashduty offers two types of status pages:
### Components and Groups
-Status pages organize and present different services through **Components**. Related components can be **Grouped** to make the status page structure clearer.
+Status pages organize and present different services through **Components**. A component is one functional unit of your system; each event states which components it affects, so the scope of impact is clear. Related components can be **Grouped**.
### Event Types
@@ -117,7 +117,7 @@ The key differences are as follows:
If you only need a simple self-monitoring tool for **service availability checks** (such as domain or port probing), an uptime monitoring tool is recommended.
If you need a **formal service status dashboard and notification system** for external customers or internal organizations, Flashduty Status Page is the better choice.
</Accordion>
-<Accordion title="Who can access the status page? Who can manage it?" defaultClose>
+<Accordion title="Who can access the status page? Who can manage it?" defaultClose>
**Access Control**
- **Public status pages** are accessible to anyone on the public internet and do not require login.
- **Internal status pages** are restricted to organization members and require authentication with a Flashduty account.
@@ -127,48 +127,28 @@ Status page management follows Flashduty’s RBAC permission model. Administrato
- **Status Page Management**: Create, edit, and delete status pages; manage subscriptions.
- **Status Page Event Management**: Publish, edit, and delete events on status pages.
</Accordion>
-<Accordion title="What types of events can be published?" defaultClose>
-Flashduty Status Pages support two types of events:
-- **Incidents**: Unplanned events that impact service availability.
-- **Maintenance**: Planned events used to notify users in advance of potential service impact.
-</Accordion>
-<Accordion title="How are events published to the status page?" defaultClose>
+<Accordion title="How are events published to the status page?" defaultClose>
Currently, events are published manually through the Flashduty status page management interface. To simplify this process, Flashduty provides event templates that allow teams to quickly publish incident or maintenance updates with minimal effort.
-In the near future, Flashduty will introduce workflow support within the Oncall incident management module. This will allow predefined rules to automatically publish relevant incidents to associated status pages, enabling seamless integration between Oncall incidents and status page updates.
+In the near future, Flashduty will introduce workflow support within the On-call incident management module. This will allow predefined rules to automatically publish relevant incidents to associated status pages, enabling seamless integration between Oncall incidents and status page updates.
</Accordion>
-<Accordion title="How are services organized on the status page?" defaultClose>
-Flashduty Status Pages use components to organize and represent services. A component represents a specific functional unit within a system or service.
-
-This component-based structure allows services to be broken down into independent units, clearly defining the scope of impact for each event. Related components can be grouped to improve clarity and structure.
-
-**Incident impact levels for components:**
-- Operational
-- Degraded
-- Partial Outage
-- Full Outage
-
-**Maintenance impact levels for components:**
-- Operational
-- Under Maintenance
-</Accordion>
-<Accordion title="How can users subscribe to status updates?" defaultClose>
+<Accordion title="How can users subscribe to status updates?" defaultClose>
Users can actively subscribe to service status updates. When publishing an event, administrators can choose whether to notify subscribers, allowing flexible control over notifications.
- For public status pages, subscribers receive updates via email.
-- For internal status pages, users can bind their preferred IM integrations in Flashduty notification settings to receive real-time direct messages. Flashduty currently supports Feishu, DingTalk, WeCom, and Slack.
+- For internal status pages, users can bind their preferred IM integrations in Flashduty notification settings to receive direct messages. Supported: Feishu, DingTalk, WeCom, and Slack. Public status pages support email subscriptions only, not IM.
</Accordion>
-<Accordion title="Do users have to subscribe to all updates?" defaultClose>
+<Accordion title="Do users have to subscribe to all updates?" defaultClose>
No. Users can choose their subscription scope. They may subscribe to all updates on a status page or only to specific services or events.
Component-based and event-based subscriptions ensure that users receive only relevant information, reducing unnecessary notification noise.
</Accordion>
-<Accordion title="How is service availability calculated?" defaultClose>
+<Accordion title="How is service availability calculated?" defaultClose>
For a component, **Partial Outage** and **Full Outage** durations are counted as downtime. Although maintenance may impact service behavior, maintenance time is excluded from service uptime calculations.
Component availability is calculated over a rolling quarterly window and is defined as the ratio of uptime to total available time.
@@ -177,7 +157,7 @@ Group availability is also calculated quarterly and is defined as the sum of upt
The system calculates impact periods for each component by replaying component status changes from event timelines. **Maintenance** events follow a separate rule: components are marked Under Maintenance only within the actual execution window (from the transition to Ongoing until closure); a scheduled maintenance that has not yet started does not affect availability charts or the calendar view. Components and sections set to "Hide all" are excluded from uptime calculations. Components and sections set to "Hide uptime" are included in calculations but their statistics are not displayed publicly. You can choose the uptime display mode in status page settings: chart and percentage, chart only, or none.
</Accordion>
-<Accordion title="Can historical availability data be added?" defaultClose>
+<Accordion title="Can historical availability data be added?" defaultClose>
In some cases, teams must prioritize investigation and recovery and are unable to update the Flashduty status page in real time. During system migrations, existing availability records may also need to be preserved.
Flashduty supports **retrospective events**, which allow teams to publish service status changes after they have occurred.
@@ -205,12 +185,8 @@ Once both records pass verification, the system issues and publishes the certifi
If your domain still points to the legacy entry `statuspage.flashcat.cloud`, the system pre-issues and publishes the certificate as long as the certificate management record passes verification, so switching DNS to a managed access entry later causes no HTTPS interruption.
</Accordion>
-<Accordion title="Which IM notification channels are supported for internal status pages?" defaultClose>
-Internal status pages support sending event notifications to organization members through IM integrations. Users need to link their IM accounts in Flashduty notification settings to receive direct message push notifications. Currently supported IM platforms include Feishu (Lark), Dingtalk, WeCom, and Slack. Public status pages do not support IM subscriptions — only email subscriptions are available.
-</Accordion>
-
-<Accordion title="How is the status page priced?" defaultClose>
-The Flashduty Status Page is included as part of the **Oncall** module and is not sold separately. Status page limits by plan are as follows:
+<Accordion title="How is the status page priced?" defaultClose>
+The Flashduty Status Page is included as part of the **On-call** module and is not sold separately. Status page limits by plan are as follows:
- **Free and Standard plans**: 1 public status page
- **Professional and Private plans**: up to 5 public status pages and up to 20 internal status pages
diff --git a/en/on-call/statuspage/widgets.mdx b/en/on-call/statuspage/widgets.mdx
index e570ca79..9ddd15eb 100644
--- a/en/on-call/statuspage/widgets.mdx
+++ b/en/on-call/statuspage/widgets.mdx
@@ -9,6 +9,10 @@ Flashduty Status Pages provide **widgets**: a snippet you can paste into any web
Widgets are only available for **public status pages**. The Widget settings page is not available for internal status pages.
</Warning>
+<Tip>
+Widgets are enabled by default — no configuration needed. In self-hosted deployments, an administrator can turn the feature off globally with the `deploy.widgetEnabled` switch (the API then returns 404).
+</Tip>
+
## Two forms
| Form | Description | Best for |
@@ -18,8 +22,6 @@ Widgets are only available for **public status pages**. The Widget settings page
Both forms support theme (Auto / Light / Dark) and language (中文 / English). The badge additionally supports size options, and the banner supports position options.
----
-
## Generate the embed code in the console
<Steps>
@@ -80,8 +82,6 @@ The script tag carries `integrity` (SRI) and `crossorigin="anonymous"` attribute
| `position` | `top` / `bottom` | `top` | Banner only | Pins the banner to the top or bottom of the page |
| `show-upcoming-maintenance` | `true` / `false` | `true` | Banner only | Whether scheduled maintenance appears automatically 24 hours before it starts |
----
-
## Behavior
### Data refresh
@@ -118,8 +118,6 @@ The API declares a freshness window via `max_stale_seconds` (**120 seconds** by
Components set to **hidden** on the status page never appear in widget data — the snapshot only contains incidents and maintenance for components visible to the public.
</Note>
----
-
## Public API: summary.json
If you prefer not to use the ready-made Web Component, call the JSON snapshot endpoint built into every public status page and render or integrate the data yourself. The console's **Widget → API** tab shows the exact URL.
@@ -131,7 +129,7 @@ GET {status page URL}/api/widget/v1/summary.json
- **Public access**: no authentication, no API key
- **Cross-origin**: responses carry `Access-Control-Allow-Origin: *`, so browsers can call it directly; `GET`, `HEAD`, and `OPTIONS` (preflight) are supported
- **Caching**: responses include `Cache-Control: public, max-age=30, s-maxage=30, stale-while-revalidate=120, stale-if-error=3600` and an `ETag` — send `If-None-Match` and receive `304` when nothing changed
-- **Freshness**: the `X-Status-Validated-At` response header records when the snapshot was last successfully validated against the backend; use it to judge whether data is stale
+- **Freshness**: the `X-Status-Validated-At` response header records when the snapshot was last successfully validated; use it to judge whether data is stale
<Warning>
This endpoint is designed for low-frequency polling from browsers. **In high-traffic scenarios, proxy the requests through your own server and cache the responses** — don't let large numbers of clients hit this URL directly.
@@ -231,7 +229,3 @@ Elements of `in_progress_maintenances` and `scheduled_maintenances`:
| --- | --- | --- |
| `404` | `{"error": "status_page_not_found"}` | The status page doesn't exist, is not public, or widgets are disabled at the deployment level |
| `503` | `{"error": "widget_summary_unavailable"}` | Status data is temporarily unavailable; retry later |
-
-<Tip>
-Widgets are enabled by default — no configuration needed. In self-hosted deployments, an administrator can turn the feature off globally with the `deploy.widgetEnabled` switch (the API then returns 404).
-</Tip>
diff --git a/en/openapi.mdx b/en/openapi.mdx
index bd341497..24b17e32 100644
--- a/en/openapi.mdx
+++ b/en/openapi.mdx
@@ -1,6 +1,6 @@
---
title: API Reference
-description: "Flashduty Open API documentation for accessing and operating FlashDuty entity data"
+description: "Flashduty Open API documentation for accessing and operating Flashduty entity data"
keywords: ["API", "Open API", "API documentation", "developer"]
url: /en/openapi/introduction
---
diff --git a/en/openapi/go-sdk.mdx b/en/openapi/go-sdk.mdx
deleted file mode 100644
index ee32029d..00000000
--- a/en/openapi/go-sdk.mdx
+++ /dev/null
@@ -1,171 +0,0 @@
----
-title: "OpenAPI Go SDK"
-sidebarTitle: "Go SDK"
-description: "go-flashduty — the official Go client for the Flashduty Open API"
-keywords: ["Go SDK", "go-flashduty", "Golang", "Open API", "client", "SDK"]
----
-
-[`go-flashduty`](https://github.com/flashcatcloud/go-flashduty) is the official Go client for the Flashduty Open API — a thin, strongly-typed SDK. It is generated from the same OpenAPI specification this documentation is built on, covers every Open API endpoint, and is validated by unit tests and end-to-end against the live API.
-
-If your service is written in Go, use the SDK to call Flashduty rather than hand-writing HTTP requests — you get typed request parameters, response structs, and error codes out of the box, with no manual JSON assembly or response parsing.
-
-<Tip>
-The SDK shares the same endpoint semantics as the Open API. Every request/response structure documented here maps to a corresponding type in the SDK. Authentication uses the same [APP Key](/en/openapi/introduction#authentication), or an OAuth access token — see [Options](#options).
-</Tip>
-
-## Install
-
-Requires Go 1.24 or later.
-
-```bash
-go get github.com/flashcatcloud/go-flashduty
-```
-
-## Quick start
-
-Create a client with your APP Key and call endpoints grouped by service (`client.Incidents`, `client.Alerts`, …). Each method maps to exactly one HTTP call and returns `(*T, *Response, error)`:
-
-```go
-package main
-
-import (
- "context"
- "fmt"
- "log"
-
- flashduty "github.com/flashcatcloud/go-flashduty"
-)
-
-func main() {
- client, err := flashduty.NewClient("YOUR_APP_KEY")
- if err != nil {
- log.Fatal(err)
- }
-
- list, resp, err := client.Incidents.List(context.Background(), &flashduty.ListIncidentsRequest{
- Progress: "Triggered",
- ListOptions: flashduty.ListOptions{Limit: 20},
- })
- if err != nil {
- log.Fatal(err)
- }
-
- fmt.Printf("request_id=%s total=%d has_next=%t\n", resp.RequestID, resp.Total, resp.HasNextPage)
- for _, inc := range list.Items {
- fmt.Printf("[%s] %s\n", inc.IncidentSeverity, inc.Title)
- }
-}
-```
-
-## Design
-
-<CardGroup cols={2}>
- <Card title="Thin and typed" icon="feather">
- Every method maps to exactly one HTTP call and returns `(*T, *Response, error)`. No hidden cross-endpoint enrichment.
- </Card>
- <Card title="Service-grouped" icon="layer-group">
- Endpoints are organized into services on the client (`client.Incidents`, `client.Alerts`, …), generated from the OpenAPI specification.
- </Card>
- <Card title="Composable transport" icon="puzzle-piece">
- Cross-cutting concerns (retry, caching, tracing, rate-limit handling) compose as `http.RoundTripper` middleware via `WithTransport`.
- </Card>
- <Card title="Human-readable timestamps" icon="clock">
- Response time fields are typed `Timestamp` / `TimestampMilli`, rendering as RFC3339 in JSON, logs, and LLM-facing output — while the raw epoch is one call away.
- </Card>
-</CardGroup>
-
-## Options
-
-`NewClient` accepts a set of options:
-
-```go
-client, err := flashduty.NewClient("YOUR_APP_KEY",
- flashduty.WithBaseURL("https://api.flashcat.cloud"),
- flashduty.WithTimeout(10*time.Second),
- flashduty.WithUserAgent("my-app/1.0"),
- flashduty.WithHTTPClient(customHTTPClient),
- flashduty.WithTransport(customRoundTripper),
- flashduty.WithLogger(myLogger),
- flashduty.WithRequestHeaders(staticHeaders),
- flashduty.WithRequestHook(func(req *http.Request) { /* e.g. inject traceparent */ }),
-)
-```
-
-### OAuth access token
-
-Besides `NewClient`, the SDK exports `NewClientWithAccessToken(accessToken, opts...)`: it authenticates with an OAuth access token, sending `Authorization: Bearer <token>` on JSON, GET, and file-upload requests, and does not inject the `app_key` query parameter; an empty token returns an error directly, and the options are exactly the same as for `NewClient`. The token is issued by the Flashduty OAuth authorization server (the API base URL) and is valid only at the deployment that issued it.
-
-```go
-client, err := flashduty.NewClientWithAccessToken(accessToken,
- flashduty.WithTimeout(10*time.Second),
-)
-```
-
-## Errors and rate limits
-
-The SDK returns typed errors you can unwrap with `errors.As`, plus convenience predicates that see through wrapped errors:
-
-```go
-_, _, err := client.Incidents.Info(ctx, &flashduty.IncidentInfoRequest{IncidentID: "does-not-exist"})
-
-var apiErr *flashduty.ErrorResponse
-if errors.As(err, &apiErr) {
- fmt.Println(apiErr.Code, apiErr.RequestID)
-}
-
-var rl *flashduty.RateLimitError
-if errors.As(err, &rl) {
- time.Sleep(rl.RetryAfter)
-}
-
-// Convenience predicates
-if flashduty.IsNotFound(err) { /* ... */ }
-if flashduty.IsRateLimited(err) { /* ... */ }
-switch flashduty.ErrorCodeOf(err) {
-case flashduty.ErrorCodeAccessDenied, flashduty.ErrorCodeUnauthorized:
- // handle auth failures
-}
-```
-
-Error codes map one-to-one to the [Error Code List](/en/openapi/introduction#error-code-list).
-
-## Timestamps
-
-Time fields on responses are typed `Timestamp` (Unix seconds) or `TimestampMilli` (milliseconds). They marshal to an RFC3339 string in the local timezone and unmarshal from either a numeric epoch or an RFC3339 string, so a value round-trips cleanly. The zero value stays the numeric `0` sentinel (never a 1970 date) and is dropped by `omitempty`.
-
-```go
-inc := list.Items[0]
-fmt.Println(inc.StartTime) // 2026-05-30T14:37:11+08:00 (String / fmt / TOON)
-b, _ := json.Marshal(inc.StartTime) // "2026-05-30T14:37:11+08:00"
-epoch := inc.StartTime.Unix() // 1779514631 (raw wire value)
-t := inc.StartTime.Time() // time.Time
-```
-
-<Note>
-Request time fields stay plain `int64` — the API expects a numeric epoch on the wire. Most endpoints take **seconds**, but RUM and webhook-history endpoints take **milliseconds**.
-</Note>
-
-## Retries
-
-Automatic retries are **not** built into the core. Compose them at the transport layer with the optional `retry` subpackage — a safe-by-default retrying `http.RoundTripper` (retries 429 and 5xx, honors `Retry-After`, deterministic exponential backoff, and only replays requests whose body is replayable, which all SDK requests are):
-
-```go
-import "github.com/flashcatcloud/go-flashduty/retry"
-
-client, err := flashduty.NewClient("YOUR_APP_KEY",
- flashduty.WithTransport(retry.New(
- retry.WithMaxRetries(3),
- )),
-)
-```
-
-## Resources
-
-<CardGroup cols={2}>
- <Card title="GitHub repository" icon="github" href="https://github.com/flashcatcloud/go-flashduty">
- Source, full README, and issues. Licensed under Apache-2.0.
- </Card>
- <Card title="API Catalog" icon="list" href="/en/openapi/api-catalog">
- Browse every endpoint — each maps to a typed method in the SDK.
- </Card>
-</CardGroup>
diff --git a/en/openapi/introduction.mdx b/en/openapi/introduction.mdx
index 38cf6b23..e407144d 100644
--- a/en/openapi/introduction.mdx
+++ b/en/openapi/introduction.mdx
@@ -76,7 +76,7 @@ curl -X POST 'https://api.flashcat.cloud/your/api/path?app_key=YOUR_APP_KEY' \
```
<Note>
-Using Go? Use the official [Go SDK](/en/openapi/go-sdk) to call Flashduty — you get typed request parameters, response structs, and error codes out of the box, with no hand-written HTTP.
+Using Go? Use the official [Go SDK](/en/developer/go-sdk) to call Flashduty — you get typed request parameters, response structs, and error codes out of the box, with no hand-written HTTP.
</Note>
---
@@ -217,17 +217,7 @@ Please control your request frequency reasonably and avoid sending a large numbe
## Best Practices
-<CardGroup cols={2}>
- <Card title="Implement Retry Mechanism" icon="rotate">
- For network errors and 5xx errors, it is recommended to implement exponential backoff retry with an initial interval of 1 second and a maximum of 3 retries.
- </Card>
- <Card title="Record request_id" icon="clipboard-list">
- Save the `request_id` returned from each request to facilitate troubleshooting and technical support.
- </Card>
- <Card title="Protect APP Key" icon="shield-check">
- Do not hardcode APP Key in client code. It is recommended to manage it through environment variables or configuration centers.
- </Card>
- <Card title="Rotate Keys Regularly" icon="key">
- Regularly replace APP Keys and promptly delete keys that are no longer in use to reduce the risk of leakage.
- </Card>
-</CardGroup>
+- **Implement Retry Mechanism**: For network errors and 5xx errors, it is recommended to implement exponential backoff retry with an initial interval of 1 second and a maximum of 3 retries.
+- **Record request_id**: Save the `request_id` returned from each request to facilitate troubleshooting and technical support.
+- **Protect APP Key**: Do not hardcode APP Key in client code. It is recommended to manage it through environment variables or configuration centers.
+- **Rotate Keys Regularly**: Regularly replace APP Keys and promptly delete keys that are no longer in use to reduce the risk of leakage.
diff --git a/en/openapi/pagination.mdx b/en/openapi/pagination.mdx
index e37b3ac6..8ba379d1 100644
--- a/en/openapi/pagination.mdx
+++ b/en/openapi/pagination.mdx
@@ -7,8 +7,6 @@ In general, when we pull or retrieve certain data objects, data is returned in b
## Traditional Pagination
----
-
We define pagination technology based on OFFSET and LIMIT queries as traditional pagination. In most Flashduty list query APIs, you can see the following parameter definitions:
### Request Parameters
@@ -71,8 +69,6 @@ PAGE × LIMIT must be ≤ 10000. If it exceeds 10000, the system will directly r
## Cursor Pagination
----
-
We define pagination technology based on SEARCH_AFTER_CTX as cursor pagination. Cursor pagination technology can better handle large datasets and high-performance requirements, providing a more stable and efficient paginated query experience.
### Supported APIs
@@ -123,8 +119,6 @@ We provide cursor pagination support in the following APIs:
## About TOTAL
----
-
Regardless of which pagination technology is used, Flashduty will return `total` and `has_next_page` parameters. However, please note that the `total` value is not always accurate. To ensure the system can respond quickly, we have added the following restrictions:
<Warning>
diff --git a/en/openapi/rate-limits.mdx b/en/openapi/rate-limits.mdx
index baa04fdb..baaabb1b 100644
--- a/en/openapi/rate-limits.mdx
+++ b/en/openapi/rate-limits.mdx
@@ -5,8 +5,6 @@ description: "Flashduty Open API rate limits and error codes"
## Request Limits
----
-
### Rate Limits
To ensure service stability, APIs have rate limits on request frequency. When requests are too frequent, a `429` status code with `RequestTooFrequently` error will be returned.
@@ -26,8 +24,6 @@ Please control your request frequency reasonably and avoid sending a large numbe
## Error Code List
----
-
| Error Code | HTTP Status | Description |
| --- | :---: | --- |
| `InvalidParameter` | 400 | Parameter error, please check if request parameters are correct |
@@ -45,8 +41,6 @@ Please control your request frequency reasonably and avoid sending a large numbe
## Error Handling Recommendations
----
-
<AccordionGroup>
<Accordion title="400 Parameter Error">
**Possible causes**:
@@ -101,19 +95,7 @@ Please control your request frequency reasonably and avoid sending a large numbe
## Best Practices
----
-
-<CardGroup cols={2}>
- <Card title="Implement Retry Mechanism" icon="rotate">
- For network errors and 5xx errors, it is recommended to implement exponential backoff retry with an initial interval of 1 second and a maximum of 3 retries.
- </Card>
- <Card title="Record request_id" icon="clipboard-list">
- Save the `request_id` returned from each request to facilitate troubleshooting and technical support.
- </Card>
- <Card title="Protect APP Key" icon="shield-check">
- Do not hardcode APP Key in client code. It is recommended to manage it through environment variables or configuration centers.
- </Card>
- <Card title="Rotate Keys Regularly" icon="key">
- Regularly replace APP Keys and promptly delete keys that are no longer in use to reduce the risk of leakage.
- </Card>
-</CardGroup>
+- **Implement Retry Mechanism**: For network errors and 5xx errors, it is recommended to implement exponential backoff retry with an initial interval of 1 second and a maximum of 3 retries.
+- **Record request_id**: Save the `request_id` returned from each request to facilitate troubleshooting and technical support.
+- **Protect APP Key**: Do not hardcode APP Key in client code. It is recommended to manage it through environment variables or configuration centers.
+- **Rotate Keys Regularly**: Regularly replace APP Keys and promptly delete keys that are no longer in use to reduce the risk of leakage.
diff --git a/en/platform/audit-log.mdx b/en/platform/audit-log.mdx
index d09a6778..6950fdb1 100644
--- a/en/platform/audit-log.mdx
+++ b/en/platform/audit-log.mdx
@@ -8,8 +8,6 @@ The audit log records all member operations within your account, helping you tra
## Viewing Audit Logs
----
-
**Configuration path**: Platform Management → Audit Log
Audit logs are displayed in a table, with each record containing the following information:
@@ -26,8 +24,6 @@ Click on the time of a record to view the complete request details (JSON format)
## Filtering and Searching
----
-
Audit logs provide multiple filtering criteria to help you quickly locate target operations:
| Filter | Description |
@@ -44,8 +40,6 @@ You can combine multiple filters. For example, you can specify both a time range
## Pagination
----
-
Audit logs display 10 records per page. Use the pagination buttons at the bottom of the page to browse more records. The current page number and total pages are shown at the bottom.
<Note>
@@ -54,8 +48,6 @@ Audit logs are retained for up to 30 days. Logs older than 30 days are automatic
## FAQ
----
-
<AccordionGroup>
<Accordion title="Can audit logs be exported?">
The console does not currently support direct export of audit logs. Please contact technical support if you need to export logs.
diff --git a/en/platform/configure-sso.mdx b/en/platform/configure-sso.mdx
index 946d77a0..009c4aff 100644
--- a/en/platform/configure-sso.mdx
+++ b/en/platform/configure-sso.mdx
@@ -7,8 +7,6 @@ Flashduty supports Single Sign-On (SSO) via SAML2.0, OIDC, CAS, and LDAP (privat
## Network Access Requirements
----
-
Each protocol has different network reachability requirements for your identity provider (IdP). Confirm this before configuring to avoid sign-in failures caused by network access:
| Protocol | Does Flashduty need to reach the IdP? | Details |
@@ -29,8 +27,6 @@ The egress IPs above apply only to Flashduty's **SaaS (public cloud) service**.
## Configuring SAML Protocol
----
-
**Configuration path**: Platform Management → Single Sign-On → Enable → Settings → Select SAML2.0 protocol type
| Field | Description |
@@ -47,8 +43,6 @@ You can sync roles and teams by the names returned by your identity provider. Se
## Configuring OIDC Protocol
----
-
**Configuration path**: Platform Management → Single Sign-On → Enable → Settings → Select OIDC protocol type
| Field | Description |
@@ -72,8 +66,6 @@ Scopes is a required field. The default values `openid`, `profile`, `email`, `ph
## Configuring CAS Protocol
----
-
**Configuration path**: Platform Management → Single Sign-On → Enable → Settings → Select CAS protocol type
| Field | Description |
@@ -90,19 +82,75 @@ Scopes is a required field. The default values `openid`, `profile`, `email`, `ph
You can sync roles and teams by the names returned by your identity provider. See [Role and team mapping](#role-and-team-mapping). **Leave default roles and default teams empty in most cases to keep fallback assignments off.**
-## Role and team mapping
+## Configuring LDAP Protocol
-OIDC, SAML2.0, and CAS support syncing member roles and team membership by the **role names and team names** returned by your identity provider. LDAP continues to use [Group DN mapping](#ldap-role-and-team-synchronization), not the name mapping described here.
+<Note>
+LDAP single sign-on is only supported in the **private deployment version**.
+</Note>
-**Field mappings apply on every sign-in; defaults apply only when creating members.** After you enable the corresponding sync option and configure the role or team field, valid matches replace the member's existing roles or team memberships on every SSO sign-in, including manually assigned ones. With no matches, existing members keep their assignments; only members actually created during this sign-in receive the configured valid defaults. Roles and teams are handled independently.
+**Configuration path**: Platform Management → Single Sign-On → Enable → Settings → Select LDAP protocol type
-<Warning>
-**In most cases, keep default role and default team fallbacks off by leaving both selections empty.**
+| Field | Description |
+| --- | --- |
+| Protocol Type | Select LDAP protocol |
+| LDAP URL | LDAP service address, e.g., `ldap://10.10.10.10:389` |
+| BIND DN | Username for connecting to LDAP, e.g., `cn=admin,dc=flashduty,dc=com` |
+| BIND DN Password | Password for connecting to LDAP, stored encrypted in the database |
+| Encryption | Supports **TLS** and **StartTLS** encryption methods (mutually exclusive, only one can be enabled). After enabling either method, you can optionally **skip SSL/TLS certificate verification**; if not skipped, you can optionally provide the SSL/TLS certificate path |
+| User DN | Defines where to start searching for users, e.g., `ou=people,dc=flashduty,dc=com` |
+| Auth Filter | Custom filter expression for retrieving user DN information, basic form: `(&(mail=%s))`. Note: Opening and closing parentheses are required |
+| Field Mapping | Flashduty extracts user email, username, phone, and Group information from the identity provider through mapped fields. Email is a required mapping field. The Group field defaults to `memberOf` and is used for role and team synchronization |
+| Stable User ID Field (`user_id`) | Optional. The unique user identifier attribute used to recognize the same member; email or phone changes do not affect recognition. If left empty, members are matched by the email/phone fields below. Recommended value: `uid`; you can also use a stable attribute such as `entryUUID`. See [Member Association](#member-association) below |
+| Create Account on Sign In | Enabled by default; when disabled, members must be invited before they can sign in |
+| SSO-only login (`force_sso`) | Enabled by default. When on, every member of this account can sign in only via SSO; password and verification-code sign-in are rejected. See [SSO-only login](#sso-only-login) below |
-Defaults apply **only when the current SSO sign-in actually creates a new member and no names match for the corresponding roles or teams**. Existing members do not receive defaults on sign-in, and changing defaults does not reassign their permissions.
+<Tip>
+Field mapping must be consistent with the identity provider configuration, otherwise it will cause errors. For specific configuration, refer to [OpenLDAP Integration Guide](/en/on-call/integration/sso/openldap).
+</Tip>
-Defaults are still shared rules for this SSO configuration, not settings for an individual member. If a mapping field is empty or incorrect, or the identity provider returns no matching names, **every new member created through this SSO configuration without matches receives the same default roles or joins the same default teams**. Do not select defaults just to make a sign-in test work. In particular, do not use administrator or other privileged roles, or sensitive teams, as general defaults.
-</Warning>
+### LDAP Connection Test
+
+After configuring the LDAP connection information, you can click **Test connection** below the LDAP form in the **Protocol & connection** section to verify that Flashduty can successfully connect to your LDAP server. The system will attempt to establish a connection using the currently entered LDAP URL, BIND DN, and password, and return a success or failure result.
+
+<Tip>
+We recommend running the connection test before saving the configuration to ensure connection parameters are correct, avoiding login failures due to misconfiguration.
+</Tip>
+
+### LDAP Role and Team Synchronization
+
+When using the LDAP protocol, you can automatically synchronize Flashduty roles and teams based on the user's LDAP Group membership.
+
+**Configuration path**: LDAP Settings page → Sync Configuration
+
+<Steps>
+ <Step title="Enable Synchronization">
+ In the sync configuration area, enable the **Sync Roles** and/or **Sync Teams** toggles.
+ </Step>
+ <Step title="Add Mapping Rules">
+ Click **Add Mapping Rule** and configure the following for each rule:
+
+ | Field | Description |
+ | --- | --- |
+ | **Group DN** | The full Distinguished Name of the Group in LDAP, e.g., `cn=devops,ou=groups,dc=example,dc=com` |
+ | **Mapped Roles** | Available when Sync Roles is enabled; select the Flashduty roles this Group maps to |
+ | **Mapped Teams** | Available when Sync Teams is enabled; select the Flashduty teams this Group maps to |
+ </Step>
+ <Step title="Configure Default Roles">
+ When Sync Roles is enabled, you can configure **Default Roles**. When a user's LDAP Groups do not match any mapping rule, the system will assign these default roles.
+ </Step>
+</Steps>
+
+<Note>
+- You can add multiple mapping rules, each corresponding to one LDAP Group
+- When a user signs in, the system automatically matches and synchronizes the corresponding roles and teams based on their LDAP Group membership
+- The Group DN in mapping rules must be the full path of the Group in LDAP
+</Note>
+
+## Role and team mapping
+
+OIDC, SAML2.0, and CAS support syncing member roles and team membership by the **role names and team names** returned by your identity provider. LDAP continues to use [Group DN mapping](#ldap-role-and-team-synchronization), not the name mapping described here.
+
+**Field mappings apply on every sign-in; defaults apply only when creating members.** After you enable the corresponding sync option and configure the role or team field, valid matches replace the member's existing roles or team memberships on every SSO sign-in, including manually assigned ones. With no matches, existing members keep their assignments; only members actually created during this sign-in receive the configured valid defaults. Roles and teams are handled independently.
### Configuration fields
@@ -110,10 +158,10 @@ Defaults are still shared rules for this SSO configuration, not settings for an
| Field | Configuration |
| --- | --- |
-| Sync roles (`sync_role_enabled`) | When enabled, updates roles from valid mapping results on every SSO sign-in. Without matches, only new members can receive default roles. When disabled, role sync does not run |
+| Sync roles (`sync_role_enabled`) | When enabled, updates roles from mapping results on every SSO sign-in; when disabled, roles are not synced |
| Role field (`roles`) | The field containing role names, such as `roles`, not a role name or ID. With role sync enabled, matches replace existing roles on **every sign-in**, including manually assigned roles |
| Default roles (`default_role_ids`) | Supports multiple selections. With role sync enabled and no returned role names matching an available role, **only members created during this sign-in** receive these default roles. Existing members are unaffected. **Usually leave empty** |
-| Sync teams (`sync_team_enabled`) | When enabled, updates team membership from valid mapping results on every SSO sign-in. Without matches, only new members can receive default teams. When disabled, team sync does not run |
+| Sync teams (`sync_team_enabled`) | When enabled, updates team membership from mapping results on every SSO sign-in; when disabled, teams are not synced |
| Team field (`teams`) | The field containing team names, such as `teams`, not a team name or ID. With team sync enabled, matches replace existing team memberships on **every sign-in**, including manually added memberships |
| Default teams (`default_team_ids`) | Supports multiple selections. With team sync enabled and no returned team names matching an available team, **only members created during this sign-in** receive these default teams. Existing members are unaffected. **Usually leave empty** |
@@ -156,7 +204,7 @@ Roles and teams **match and fall back independently**. For example, if roles mat
</Note>
<Warning>
-**Valid mappings replace assignments; they do not append to them.** On an existing member's next SSO sign-in, valid mapping results can still replace manually assigned roles or teams. A dimension with no matches remains unchanged. To manage roles or teams entirely by hand, disable the corresponding sync option instead of only clearing its defaults.
+**In most cases, leave default roles and default teams empty.** Defaults are shared rules for this SSO configuration: if a mapping field is empty or incorrect, or the identity provider returns no matching names, **every new member created through this SSO configuration without matches receives the same default roles or joins the same default teams**. Do not select defaults just to make a sign-in test work, and never use administrator or other privileged roles, or sensitive teams, as general defaults.
</Warning>
### Recommended setup order
@@ -177,76 +225,8 @@ Roles and teams **match and fall back independently**. For example, if roles mat
See [Role and Team Sync](/en/on-call/integration/sso/role-team-sync) for per-protocol name sources, matching rules, and field retention. LDAP uses Group DN mapping, not the name mapping or new-member default rules in this section.
</Note>
-## Configuring LDAP Protocol
-
----
-
-<Note>
-LDAP single sign-on is only supported in the **private deployment version**.
-</Note>
-
-**Configuration path**: Platform Management → Single Sign-On → Enable → Settings → Select LDAP protocol type
-
-| Field | Description |
-| --- | --- |
-| Protocol Type | Select LDAP protocol |
-| LDAP URL | LDAP service address, e.g., `ldap://10.10.10.10:389` |
-| BIND DN | Username for connecting to LDAP, e.g., `cn=admin,dc=flashduty,dc=com` |
-| BIND DN Password | Password for connecting to LDAP, stored encrypted in the database |
-| Encryption | Supports **TLS** and **StartTLS** encryption methods (mutually exclusive, only one can be enabled). After enabling either method, you can optionally **skip SSL/TLS certificate verification**; if not skipped, you can optionally provide the SSL/TLS certificate path |
-| User DN | Defines where to start searching for users, e.g., `ou=people,dc=flashduty,dc=com` |
-| Auth Filter | Custom filter expression for retrieving user DN information, basic form: `(&(mail=%s))`. Note: Opening and closing parentheses are required |
-| Field Mapping | Flashduty extracts user email, username, phone, and Group information from the identity provider through mapped fields. Email is a required mapping field. The Group field defaults to `memberOf` and is used for role and team synchronization |
-| Stable User ID Field (`user_id`) | Optional. The unique user identifier attribute used to recognize the same member; email or phone changes do not affect recognition. If left empty, members are matched by the email/phone fields below. Recommended value: `uid`; you can also use a stable attribute such as `entryUUID`. See [Member Association](#member-association) below |
-| Create Account on Sign In | Enabled by default; when disabled, members must be invited before they can sign in |
-| SSO-only login (`force_sso`) | Enabled by default. When on, every member of this account can sign in only via SSO; password and verification-code sign-in are rejected. See [SSO-only login](#sso-only-login) below |
-
-<Tip>
-Field mapping must be consistent with the identity provider configuration, otherwise it will cause errors. For specific configuration, refer to [OpenLDAP Integration Guide](/en/on-call/integration/sso/openldap).
-</Tip>
-
-### LDAP Connection Test
-
-After configuring the LDAP connection information, you can click **Test connection** below the LDAP form in the **Protocol & connection** section to verify that Flashduty can successfully connect to your LDAP server. The system will attempt to establish a connection using the currently entered LDAP URL, BIND DN, and password, and return a success or failure result.
-
-<Tip>
-We recommend running the connection test before saving the configuration to ensure connection parameters are correct, avoiding login failures due to misconfiguration.
-</Tip>
-
-### LDAP Role and Team Synchronization
-
-When using the LDAP protocol, you can automatically synchronize Flashduty roles and teams based on the user's LDAP Group membership.
-
-**Configuration path**: LDAP Settings page → Sync Configuration
-
-<Steps>
- <Step title="Enable Synchronization">
- In the sync configuration area, enable the **Sync Roles** and/or **Sync Teams** toggles.
- </Step>
- <Step title="Add Mapping Rules">
- Click **Add Mapping Rule** and configure the following for each rule:
-
- | Field | Description |
- | --- | --- |
- | **Group DN** | The full Distinguished Name of the Group in LDAP, e.g., `cn=devops,ou=groups,dc=example,dc=com` |
- | **Mapped Roles** | Available when Sync Roles is enabled; select the Flashduty roles this Group maps to |
- | **Mapped Teams** | Available when Sync Teams is enabled; select the Flashduty teams this Group maps to |
- </Step>
- <Step title="Configure Default Roles">
- When Sync Roles is enabled, you can configure **Default Roles**. When a user's LDAP Groups do not match any mapping rule, the system will assign these default roles.
- </Step>
-</Steps>
-
-<Note>
-- You can add multiple mapping rules, each corresponding to one LDAP Group
-- When a user signs in, the system automatically matches and synchronizes the corresponding roles and teams based on their LDAP Group membership
-- The Group DN in mapping rules must be the full path of the Group in LDAP
-</Note>
-
## Member Association
----
-
During single sign-on, the system associates the user returned by the identity provider with a member of the account. The association method depends on whether the SSO configuration has a **Stable User ID Field** set, and this applies to new and existing configurations alike:
| Configuration | Association method |
@@ -264,8 +244,6 @@ Changing identity-scope settings (protocol type, identity provider address, or t
## SSO-only login
----
-
The `force_sso` option restricts every member of the account to signing in through SSO, fully delegating authentication to the identity provider.
**Configuration path**: Platform Management → Single Sign-On → Enable → Settings → **Members can only sign in via SSO**
@@ -300,8 +278,6 @@ The same restriction applies when switching accounts inside a password session:
## External member management
----
-
When you enable single sign-on, members automatically created through their first SSO login are marked as **external members**. You can enable the **Prevent editing external members** option in SSO settings (disabled by default). When enabled, these external members become read-only in Flashduty — you cannot modify their roles or delete them in Flashduty. All member management must be done through the identity provider.
This feature is ideal for organizations that need to centrally manage user permissions in the identity provider, ensuring member information in Flashduty always stays in sync.
@@ -313,8 +289,6 @@ This feature is ideal for organizations that need to centrally manage user permi
## Login Domain Management
----
-
The login domain is an important identifier for your account, used to locate the correct SSO configuration during single sign-on. Each account's login domain is globally unique.
After configuring the login domain, members can initiate single sign-on directly through the `{domain}.sso.flashcat.cloud` address without manually selecting an identity provider.
@@ -337,8 +311,6 @@ Before modifying, ensure you have checked your email integration configuration a
## Best Practices
----
-
<CardGroup cols={4}>
<Card title="Role and Team Sync" icon="users" href="/en/on-call/integration/sso/role-team-sync">
SAML2.0/OIDC/CAS sync by name on every sign-in; defaults apply only to new members without matches
diff --git a/en/platform/organization-info.mdx b/en/platform/organization-info.mdx
index 2f46094e..e370f059 100644
--- a/en/platform/organization-info.mdx
+++ b/en/platform/organization-info.mdx
@@ -5,8 +5,6 @@ description: "View and manage organization profile, join restrictions, notificat
## Organization Information
----
-
The **Organization Information** page centralizes your organization's identity and org-level default settings, and is accessible to all members. Entry: **Platform Management → Organization → Organization Information**, or click the **Organization Information** button on your profile card in Personal Center.
The page contains the following sections:
@@ -25,17 +23,13 @@ This page is **open to all members**: regular members can view every configurati
## Organization Profile
----
-
-The Organization Profile section maintains the organization's identity. Only the subject account or Account.Admin can edit; other members are read-only.
-
| Item | Description |
| --- | --- |
| **Logo** | Organization logo image, set via a **Logo URL** that must be a reachable http/https address; click **Reset to Default Logo** to clear the custom logo and restore the default |
| **Name** | Organization name, displayed in invitation emails and SMS messages |
| **ID** | Unique identifier of the organization; provide it when integrating APIs or contacting support |
| **Domain** | Dedicated subdomain for login and email integration push |
-| **Time Zone** | The organization time zone. Members without their own personal time zone see all times in it. Only the subject account or an Account.Admin can change it |
+| **Time Zone** | The organization time zone. Members without their own personal time zone see all times in it |
### Organization Time Zone
@@ -64,9 +58,7 @@ See [SSO Configuration](/en/platform/configure-sso) for more information.
## Join Restrictions
----
-
-The Join Restrictions section controls **who can join the organization through an invitation**. It currently offers an email-domain allowlist: only people whose email domain is on the list can join. Only the subject account or an Account.Admin can edit it; other members see the current configuration as read-only text.
+The Join Restrictions section controls **who can join the organization through an invitation**. It currently offers an email-domain allowlist: only people whose email domain is on the list can join.
| Item | Description |
| --- | --- |
@@ -74,33 +66,28 @@ The Join Restrictions section controls **who can join the organization through a
| **Allow subdomains** | Appears only when the allowlist contains at least one valid domain; off by default. When enabled, an allowlisted `corp.com` also covers subdomain addresses such as `mail.corp.com` |
<Note>
-- Matching is **case-insensitive**: `Corp.com` and `corp.com` are the same domain
-- Each entry must be a full domain (at least one dot, e.g. `corp.com`): it cannot start or end with a dot or a hyphen, and it cannot contain consecutive dots or a hyphen next to a dot
-- Saving also checks that **your own email domain** is on the list; a list that leaves it out is rejected with a prompt to add it
+- Enter full domains (e.g. `corp.com`); matching is case-insensitive
+- The list must include **your own email domain**, or it cannot be saved
</Note>
### Where It Applies
-The email-domain allowlist is checked only on the **invite-join** path (one-by-one invitations and joins through an invite link / QR code, including the invite-scoped sign-in). It plays **no part in regular sign-in or authorization**:
+The allowlist only applies when someone **joins the organization**; it does not affect regular sign-in:
-| Scenario | Allowlist checked? |
+| Scenario | Restricted by the allowlist? |
| --- | --- |
-| One-by-one invitation (with an email address) | Yes. An address outside the allowlist is rejected inline in the invite dialog, and the backend rejects it as well |
-| Joining through an invite link / QR code | Yes, against the email domain the invitee signs in with |
-| One-by-one invitation with a phone number only | **No**. Phone invitations are vouched for by the administrator, so those members can join as usual |
-| Regular sign-in and authorization | No. The allowlist is not part of sign-in or authorization |
-| Members who already joined, and the owner account | Unaffected. They keep signing in and working even if their domain is not on the list, and opening an invite link again lets them straight in |
+| Email invitation | Yes. Addresses outside the allowlist cannot be invited |
+| Joining through an invite link / QR code | Yes, based on the email the invitee signs in with, which must be verified |
+| Phone invitation | No |
+| Existing members and the owner account | No, even if their domain is not on the list |
<Note>
-- With an allowlist in place, **anyone joining through an invite link / QR code must present a verified email address**: a phone-only contact with no verified email is rejected with a prompt to verify the address first. In that case the invite sign-in page offers email sign-in only, with the hint "This organization only allows email addresses on its allowlist. Please sign in with your email."
-- Organizations that enable [SSO-only login](/en/platform/configure-sso#sso-only-login) **cannot be joined through an invite link / QR code**: membership is managed by the identity provider, so the join is rejected with a prompt asking the administrator to grant access through SSO.
+Organizations that enable [SSO-only login](/en/platform/configure-sso#sso-only-login) cannot be joined through an invite link / QR code; an administrator grants access through SSO instead.
</Note>
## Notification Settings
----
-
-The Notification Settings section maintains the content and language of system notifications within the organization, applied to all members. Only the subject account or Account.Admin can modify; other members see the current values as read-only text.
+The Notification Settings section maintains the content and language of system notifications within the organization, applied to all members.
### Default Notification Language
@@ -121,23 +108,21 @@ An org-level toggle that controls whether incident alert SMS messages are trunca
| **Enabled** | Incident alert SMS messages are no longer truncated; long content may be split by carriers into multiple messages, billed per message |
| **Disabled** | Incident alert SMS messages are truncated to a single message length |
-Enabling requires confirmation: domestic and international incident alert SMS messages will no longer be truncated, and long content may be split into multiple messages billed separately.
-
<Note>
Verification, invitation, and on-call SMS messages are **unaffected** by this toggle and always follow their original behavior.
</Note>
### Free Notification Quota Reminders
-When your free notification quota (SMS / voice call / email) runs low, Flashduty emails the organization's administrators so notifications do not stop once the quota is used up. This block is **available on SaaS only** and is not shown on private deployments. Both switches are **on by default** and can be turned off independently; only the subject account or an Account.Admin can change them, and other members see the current values as read-only text.
+When your free notification quota (SMS / voice call / email) runs low, Flashduty emails the organization's administrators so notifications do not stop once the quota is used up. This block is **available on SaaS only** and is not shown on private deployments. Both switches are **on by default** and can be turned off independently.
-| Switch | Field | Trigger |
-| --- | --- | --- |
-| **Remind at 20% remaining** | `free_quota_20_reminder_enabled` | Free quota drops to 20% or below while still above 0 |
-| **Remind when exhausted** | `free_quota_exhausted_reminder_enabled` | Free quota reaches 0 for the first time |
+| Switch | Trigger |
+| --- | --- |
+| **Remind at 20% remaining** | Free quota drops to 20% or below while still above 0 |
+| **Remind when exhausted** | Free quota reaches 0 for the first time |
<Note>
-- Both switches are on by default; turning one back on does **not** backfill — a threshold already crossed while it was off is not reminded again
+- Turning a switch back on does **not** backfill thresholds crossed while it was off
- Only **paid accounts** (Standard / Pro, not a trial, not expired) are counted, and only notifications **actually sent successfully and counted toward the quota** — free accounts do not receive this kind of reminder
- SMS, voice calls, and emails are counted and reminded **separately**: at most one reminder per quota period per channel
- Reminders are **email-only** — no SMS or phone call. They go to the account's own email address plus the verified email addresses of currently enabled **Admin** members (up to 20)
@@ -147,8 +132,6 @@ Quota amounts, overage billing, and what happens when a free quota runs out are
## Incident Handling
----
-
The Incident Handling section maintains org-level defaults for incident-handling operations, applied to **the console and IM alert cards**.
### Snooze Time Presets
@@ -160,24 +143,22 @@ When snoozing incidents in the console or IM cards (Feishu/Lark, DingTalk, WeCom
- Presets **cannot be duplicated**
- Defaults are **2 hours / 4 hours / 12 hours**; click **Restore Defaults** to reset quickly
-Click **Save** to apply changes, which take effect immediately in the console and IM cards. Only the subject account or Account.Admin can edit; other members see the current presets as read-only text. See [Snooze](/en/on-call/incident/handle-update-incident) for more snooze operations.
+Saved changes take effect immediately in the console and IM cards. See [Snooze](/en/on-call/incident/handle-update-incident) for more snooze operations.
### Quick-silence label exclusion rules
When you create a [quick silence](/en/on-call/channel/noise-reduction#quick-silence), the matching conditions are generated automatically from the incident's severity and labels. Labels that hit an exclusion rule do not participate in the matching conditions, so labels whose values change on every occurrence (trigger value, current value, links, etc.) don't end up in the conditions and cause similar alerts to escape silencing.
-**Where to configure**: Organization Profile → Fault Handling → **Quick-silence excluded labels** (the configuration dialog is titled "Quick-silence label exclusion rules"). Only the subject account or Account.Admin can modify the rules; other members can open and view the current rules (exclusion rules affect the silences they create, so they need visibility). Changes take effect only for quick silences created afterwards.
+**Where to configure**: Organization Information → Incident Handling → **Quick-silence excluded labels**. Changes apply only to quick silences created afterwards.
Configuration contents:
- **Per-integration exclusion lists**: maintain an excluded label list for each integration separately. When creating a quick silence, a label hitting any exclusion list is excluded
- **System format rule toggles**: `json` (JSON values), `datetime` (datetime format), and `numeric` (numeric values), all enabled by default; label values longer than 235 characters are also excluded automatically (cannot be disabled)
-- **Global blacklist**: about 95 system-curated labels (such as `trigger_value`, `current_value`, `detail_url`, `query`) are always excluded; they are maintained as a frontend constant and cannot be configured
+- **Global blacklist**: about 95 system-curated labels (such as `trigger_value`, `current_value`, `detail_url`, `query`) are always excluded; they are built into the system and cannot be configured
## Related Topics
----
-
<CardGroup cols={2}>
<Card title="SSO Configuration" icon="shield-check" href="/en/platform/configure-sso">
Login domain and SSO single sign-on
diff --git a/en/platform/permission-design.mdx b/en/platform/permission-design.mdx
index 7723d0ee..721dbbc1 100644
--- a/en/platform/permission-design.mdx
+++ b/en/platform/permission-design.mdx
@@ -77,8 +77,8 @@ Custom menu is a standalone permission scope, displayed alongside Platform, On-c
**Custom menu permissions follow different inheritance rules depending on the preset role:**
- **Admin**: Automatically inherits every custom menu visit permission in the account — no additional configuration needed.
-- **Responder**: Automatically includes the current account's permission points where `admin_only=0`. Non-admin-only custom menu access permissions therefore need no additional role binding; permissions reserved for admins are excluded from the Responder preset role.
-- **Viewer**: Does **not** automatically inherit custom menu permissions. The Viewer permission bitmap contains only system-defined permission IDs (`id < 100000`), while custom menu permission IDs are Snowflake-generated and far above that threshold. To allow a Viewer member to see a specific custom menu, explicitly add Viewer in that menu's role binding configuration (`role_ids` field).
+- **Responder**: automatically includes custom menu permissions that are not admin-only; admin-only menus are excluded.
+- **Viewer**: does **not** automatically get custom menu permissions. To let Viewer members access a custom menu, add Viewer explicitly in that menu's role binding.
- **Custom roles**: Also do not automatically inherit custom menu permissions; explicit binding per menu is required.
</Warning>
@@ -192,7 +192,7 @@ In addition to preset roles, you can create custom roles for more granular permi
<Note>
- System preset roles (Admin, Responder, Viewer) cannot be modified or deleted
- Custom roles support editing, copying, enabling/disabling, and deletion
-- A custom role selected as a **default role** (`default_role_ids`) in any saved SAML2.0 / OIDC / CAS SSO configuration cannot be deleted: deletion returns `ReferenceExist` (the resource is still referenced by other entities and cannot be deleted), and forced deletion (`is_force`) does not bypass it either — forced deletion only revokes member assignments; SSO default references must be unselected first. Unselect the role in the corresponding SSO configuration's default role options before deleting it. The restriction also applies when SSO or role sync is currently disabled
+- A custom role selected as the **default role** in any saved SSO configuration (SAML2.0 / OIDC / CAS) cannot be deleted, not even by force delete (which only removes member bindings). Deselect it as the default role in that SSO configuration first; this applies even when SSO or role sync is turned off
- A member can hold multiple roles simultaneously; their effective permissions are the union of all assigned roles
</Note>
@@ -247,8 +247,8 @@ Flashduty **controls data permissions based on teams**, applied in the following
- **Functional permissions**: enabling, disabling, deleting and saving the configuration of a channel-exclusive integration can be done with either **Channels Manage** or **Integrations Manage** — one of the two is enough. This is because **Channels Manage** already covers creating, editing, deleting, enabling, disabling and rotating the key of the integrations inside that channel.
- **Data permissions**: a channel-exclusive integration is judged by the channel's **managing team**; when the channel has no managing team configured, it falls back to the channel's own team. A shared integration is judged by the integration's own creator and responsible team.
-- **The insufficient-permission message differs**: a channel-exclusive integration says "No permission. Only account admins, channel creators or management teams can operate.", while a shared integration says "You do not have permission to operate. Only account administrators, integration creators, or team managers are allowed to operate."
-- Only an integration whose `ref_id` looks like `c_<channel_id>` counts as channel-exclusive: a shared integration opened from the integration detail with a `channel_id` query parameter is still judged as a shared integration.
+- **Who can operate**: a channel-exclusive integration can be operated only by account admins, the channel creator or the managing team; a shared integration only by account admins, the integration creator or the managing team.
+- Only integrations created inside a channel are channel-exclusive; a shared integration opened from a channel is still treated as shared.
</Note>
When you don't have data permissions for a resource, the system will display the following message:
diff --git a/en/platform/pricing.mdx b/en/platform/pricing.mdx
index 394cdcff..c2875f0b 100644
--- a/en/platform/pricing.mdx
+++ b/en/platform/pricing.mdx
@@ -6,8 +6,6 @@ keywords: ["pricing", "license subscription", "pay-as-you-go", "pricing model",
## On-call Pricing
----
-
On-call uses a **License subscription** model, billed by the number of active users.
### Pricing Model
@@ -100,7 +98,7 @@ On the Free plan, notifications **stop** once the quota is exhausted. On Standar
When a free quota is running low, the system sends **reminder emails** (email only — never SMS or a phone call):
-- **Triggers**: when a channel's free quota has **20% or less** remaining, one email titled “[Quota reminder] X free quota has 20% or less remaining” (account setting `free_quota_20_reminder_enabled`); when that channel's quota is **exhausted**, one more titled “[Quota reminder] X free quota exhausted” (account setting `free_quota_exhausted_reminder_enabled`). SMS, voice calls, and emails are counted and reminded separately.
+- **Triggers**: one reminder when a channel's free quota has **20% or less** remaining, and one more when it is **exhausted**. SMS, voice calls, and emails are counted and reminded separately.
- **Recipients**: the account's email address plus the verified email addresses of enabled administrators (up to 20).
- **Frequency**: at most one reminder per channel per quota period.
- Reminder emails **do not count toward** the account's notification quota and never consume the free quota themselves.
@@ -108,7 +106,7 @@ When a free quota is running low, the system sends **reminder emails** (email on
Both switches are on by default. They live under **Platform Management → Organization → Organization Information → Notification Settings → Free Notification Quota Reminders** and can be turned off as needed — see [Organization Information](/en/platform/organization-info#free-notification-quota-reminders).
<Note>
-**Quota reminders** are about a **notification channel's free quota**; the [**Low balance alert**](/en/platform/pricing#low-balance-alert) is about your **account balance** falling below a threshold you set (SMS + email). The two are independent: different triggers, and only the balance alert has a configurable threshold.
+Quota reminders cover each **notification channel's free quota**; the [Low balance alert](#low-balance-alert) covers your **account balance** falling below a threshold you set. The two are independent.
</Note>
### Customer Support
@@ -187,8 +185,6 @@ Members without a License have limited functionality and can only passively rece
## RUM Pricing
----
-
RUM uses a **pay-as-you-go** model, billed by the number of sessions used.
### Plan Comparison
@@ -232,8 +228,6 @@ The Free plan is suitable for evaluating product features. The Pro plan is bille
## Payment and Top-up
----
-
The Payment center is available on SaaS only — On-Premises deployments do not expose this entry. Open **Payment** from the left navigation: the page is titled **Billing** and contains the **Top up** and **Transactions** tabs. The same menu also leads to **Plan** — the page titled **Your Plans**, split into the **On-Call**, **AI SRE** and **RUM** tabs; activating, closing and billing AI SRE are all managed from the **AI SRE** tab (rules: [AI SRE Product Overview](/en/ai-sre/overview#activation-and-billing)).
### What makes up your balance
@@ -253,8 +247,7 @@ The **Top up** tab offers three channels:
Under **Online payment** you can choose **Alipay** (settled in CNY, any amount) or **Stripe** (international credit and debit cards).
- **Alipay**: preset amounts ¥100 / ¥300 / ¥500 / ¥1,000 / ¥3,000 / ¥5,000, or a custom amount between 0.01 and 100,000 CNY with up to two decimals.
-- **Stripe**: charged in USD. Preset amounts come from the server (default $50 / $100 / $200 / $500 / $1,000); custom amounts range from 0.5 to 10,000 USD with up to two decimals. The charge is credited to your balance at a **fixed exchange rate** (1 USD = 7 CNY by default, set per deployment), and each USD option shows the exact CNY credit rather than an estimate.
-- The Stripe channel only appears when payment credentials are configured on the server; otherwise Alipay is the only online option.
+- **Stripe**: charged in USD. Preset amounts default to $50 / $100 / $200 / $500 / $1,000; custom amounts range from 0.5 to 10,000 USD with up to two decimals. The charge is credited to your balance at a **fixed exchange rate** (1 USD = 7 CNY by default, set per deployment), and each USD option shows the exact CNY credit rather than an estimate.
- **The default selected channel follows the interface language**: Alipay on the Chinese UI, Stripe on other languages. Either can be switched before you submit.
### Saving a card and automatic charging
@@ -264,9 +257,8 @@ Paying with Stripe once saves that card. From then on, **the system charges the
- **There is no separate on/off switch**: as long as a valid card is saved and no stop condition applies, a short balance at renewal is charged automatically
- **Charged amount**: the renewal shortfall (fee minus current balance, including a negative balance from usage), rounded up to a whole US dollar
- **Rate limit**: at most one automatic charge per account every 24 hours
-- **Stop condition**: automatic charging stops after 3 consecutive failures, and the page reports "Failed N times in a row". Top up with Stripe once again to replace the card
+- **Stop condition**: automatic charging stops after 3 consecutive failures. Top up with Stripe once again to replace the card
- **Deleting the card**: go to **Available balance → Automation → Automatic charging** and choose **Delete card**. Renewals no longer charge automatically afterwards; top up with Stripe again to bind a new card. This requires the **Payment management** permission
-- On the Chinese UI the **Automatic charging** row stays hidden until a card is actually bound; other languages always show it with a binding entry
### Low balance alert
@@ -308,24 +300,22 @@ The **Transactions** tab lists **Time**, **Type**, **Description**, **Amount**,
## On-Premises License Expiry and Renewal
----
-
On-Premises Licenses are issued by Flashduty with a fixed expiry date. Before expiry the platform reminds the contacts registered for your deployment; once the License expires the platform **stops ingesting data**. On-Premises deployments have no Payment center entry (see [Payment and Top-up](#payment-and-top-up)), so renewals go through our sales team.
### Expiry reminders
Reminders go to the contacts registered for your deployment: every contact's **email** address receives the reminder email, and contacts with a **valid mainland China phone number** also receive an **SMS**.
-- **Timing**: one reminder each time **10, 3 and 1 days** remain on the License — at most three per License. Remaining days are rounded up, and the moment of expiry falls into the 1-day reminder, so no catch-up reminder is sent after the License expires. A License registered with fewer than 10 days left gets only the single reminder it has reached.
-- **Send window**: reminders are sent only between **08:00 and 22:00 Beijing time** (judged by the hour); outside that window nothing is sent.
+- **Timing**: one reminder each time **10, 3 and 1 days** remain — at most three per License; nothing is sent after expiry.
+- **Send window**: only between **08:00 and 22:00 Beijing time**.
- **No reminders**: Licenses that expired more than **7 days** ago are not reminded.
-- **Copy**: the reminder email is **Chinese only** (on-prem customers are in mainland China). Before expiry the subject is “[License 提醒] Flashduty 私有化 License 还剩 N 天到期” — “License reminder: N days until your Flashduty On-Premises License expires” — with the subtitle 到期后将停止接收数据。 (“data ingestion stops at expiry”), and the body shows the **expiry date** and the **days left**. On the expiry day the subject and title become “[License 提醒] Flashduty 私有化 License 已到期” (“…has expired”) with the subtitle 数据已停止接收。 (“data ingestion has stopped”). The SMS reads “您的 Flashduty 私有化部署(`客户名称`)License 将于 `到期日` 到期,还剩 N 天。到期后将停止接收数据,请尽快联系我们续签” (“the License of your Flashduty On-Premises deployment expires on the expiry date, N days left; data ingestion stops at expiry, please contact us to renew”), and once the License has expired, “您的 Flashduty 私有化部署(`客户名称`)License 已于 `到期日` 到期,数据已停止接收,请尽快联系我们续签”.
+- Reminder emails and SMS are in Chinese and show the expiry date and days left.
### What happens at expiry, and renewal
Once the License expires the platform **stops ingesting data**, so renew promptly to avoid a long interruption in data ingestion.
-After you receive the new License, **paste it into the License prompt in the console sidebar** and activate it: the console then reports "License 已更新,将在五分钟内生效" (the License is updated and takes effect within five minutes), and activation **requires no service restart**. The expiry date is then updated and reminders restart on the new date. (The reminder email says it takes about 1–2 minutes; the console message is the one to go by.)
+After you receive the new License, **paste it into the License prompt in the console sidebar** and activate it. The new License takes effect within five minutes and **requires no service restart**; the expiry date is updated and reminders restart on the new date.
<Note>
[Quota reminders](#quota-reminders) and the [Low balance alert](#low-balance-alert) apply to **SaaS** accounts; this section covers the **On-Premises** License expiry and renewal. The two are independent.
@@ -333,72 +323,46 @@ After you receive the new License, **paste it into the License prompt in the con
---
----
-
## What happens when your subscription expires
When your On-call subscription **has expired or is disabled**, Flashduty does two things: it **stops ingesting new alerts**, and it **freezes every create entry point**. Existing configuration and historical data are not deleted, and everything resumes automatically once you renew.
### What counts as expired
-Either condition below marks the account as expired across the product:
+A subscription counts as expired when it is **disabled** or **past its end date**. On-Premises deployments are not subject to subscription control and never expire.
-| Condition | Description |
-| --- | --- |
-| **Subscription disabled** | The subscription resource's status is not `enabled` |
-| **Subscription past its end date** | The current time has reached the subscription's expiry time (`expired_at`) |
-
-Checking the expiry time alone would miss the "resource disabled but the end date has not arrived yet" case — which the backend rejects while the front end would let it through — so either condition on its own counts as expired. On-Premises deployments are not subject to subscription control and are never treated as expired.
-
-### Expiry reminders and how to renew
+### Expiry reminders and renewal
-- The **subscription entry at the bottom of the left navigation** turns amber when **less than 10 days** remain, showing the time left until expiry; hovering explains that alert ingestion will stop after that. Once expired it turns red and shows how long ago it expired; hovering adds that alert ingestion has stopped and that you can click to renew. Clicking the entry opens the **Plan** page (`/wallet/plan`).
-- The **owner account** can click **Renew now** on the banner. **Member accounts** have no renewal permission and are told to ask the account owner to renew.
+- When **less than 10 days** remain, the subscription entry at the bottom of the left navigation turns amber and shows the time left; after expiry it turns red. Click it to open the **Plan** page and renew.
+- Only the **owner account** can renew; member accounts need to ask the owner.
-### Alert ingestion and the banners on each list page
+### What is affected while expired
-Alert ingestion stops once the subscription expires, and the alert list, incident list, integration center and insights dashboard each show a **non-dismissable** banner at the top explaining what that page is affected by:
+**Alert ingestion stops.** The alert list, incident list, integration center and insights dashboard each show a banner explaining the impact on that page:
-| Page | What the banner tells you |
+| Page | Impact |
| --- | --- |
-| Alert list | Alert ingestion has stopped; historical alerts remain viewable and actionable, and ingestion resumes automatically after renewal |
-| Incident list | Alert ingestion has stopped, so no new incidents will be created; existing incidents can still be handled |
-| Integration center | All integrations have stopped receiving alert events; configured integrations are not deleted, and they resume automatically after renewal with no reconfiguration needed |
-| Insights | Alert ingestion has stopped, so no new analytics data is produced; historical data is unaffected and can still be viewed and exported |
-
-In the integration center every integration card also becomes non-interactive, with a tooltip explaining that the expired subscription blocks creating new integrations and that renewal restores it immediately, while existing integrations are unaffected. The insights dashboard keeps producing no new analytics data, so the default time window is naturally empty — this is not data loss. See [Insights](/en/on-call/analytics/insights) for details.
-
-### Create entries that are frozen
+| Alert list | No new alerts are ingested; historical alerts remain viewable and actionable |
+| Incident list | No new incidents are created; existing incidents can still be handled |
+| Integration center | All integrations stop receiving alerts; configured integrations are kept and need no reconfiguration after renewal |
+| Insights | No new analytics data is produced, so the default time window may be empty — this is not data loss; historical data can still be viewed and exported. See [Insights](/en/on-call/analytics/insights) |
-These create entries are disabled while the subscription is expired. Hovering explains that the expired subscription blocks creating a new 〈object〉, that renewal restores it immediately, and that existing ones are unaffected — "object" being the object named in this column, so the channel entry reads "…cannot create a new channel. Renewal restores it immediately; existing ones are not affected." The tooltip also carries the renewal path: **Renew now** for the owner account, "Please ask the account owner to renew." for member accounts.
+**Creation is frozen.** While expired, you cannot create new:
-| Object | Entry that is disabled |
-| --- | --- |
-| Channels | **Create channel** on the channel list |
-| Schedules | **Create schedule** on the schedule page |
-| Incidents | The create entry on the incident list |
-| War rooms | **Create war room** in the incident detail |
-| Status pages | **Create public status page** / **Create internal status page** on the status page list, plus the create page itself |
-| Members | **Invite members** under member management |
-| Custom fields | **Create custom field** on the custom fields page |
-| Notification templates | The create entries on the templates page |
-| Service calendars | **Add Calendar** on the service calendar page |
-| Post-mortems | **Create Post-Mortem** on the post-mortem panel |
+channels, schedules, incidents, war rooms, status pages, members (invitations), integrations, custom fields, notification templates, service calendars, or post-mortems.
<Note>
-Expiry only freezes **creation**. Existing objects can still be **edited, enabled, disabled and deleted**: a channel's noise-reduction configuration and escalation rules remain editable, and a status page that already exists keeps being displayed and stays editable at any time.
+Expiry only freezes **creation**. Existing objects can still be edited, enabled, disabled and deleted — for example a channel's noise-reduction configuration and escalation rules — and existing status pages stay published.
</Note>
### How things recover after renewal
-After you renew or re-enable the subscription you **do not reconfigure anything**: alert events resume being ingested, the frozen create entries become usable immediately, and configured integrations, existing incidents, historical alerts and historical analytics data all stay as they were. AI SRE is also paused while the On-call subscription is lapsed and resumes automatically on renewal — see [AI SRE Product Overview · When the subscription lapses](/en/ai-sre/overview#when-the-subscription-lapses).
+After you renew or re-enable the subscription you **do not need to reconfigure anything**: alerts are ingested again, creation is available immediately, and existing integrations, incidents, historical alerts and analytics data stay as they were. AI SRE pauses while the On-call subscription is lapsed and resumes automatically on renewal — see [AI SRE Product Overview · When the subscription lapses](/en/ai-sre/overview#when-the-subscription-lapses).
---
## FAQ
----
-
<AccordionGroup>
<Accordion title="How does On-call calculate active users?">
Members who use commercial features (viewing or handling incidents) within the month are counted as active users. **Receiving alert notifications alone does not count as active usage.** At the end of each monthly cycle:
@@ -454,8 +418,6 @@ After you renew or re-enable the subscription you **do not reconfigure anything*
## Contact Sales
----
-
<Card title="Get Professional Purchasing Guidance" icon="headset" href="mailto:contact-us@flashcat.cloud">
For more pricing details or enterprise quotes, please contact our sales team.
diff --git a/en/platform/team-members.mdx b/en/platform/team-members.mdx
index 594990d0..5c23c9a2 100644
--- a/en/platform/team-members.mdx
+++ b/en/platform/team-members.mdx
@@ -5,14 +5,10 @@ description: "Create, configure, and manage teams and members"
## About Teams
----
-
A team is a collection of members. You can group members with different responsibilities or projects into a team for managing **channels, notification assignment, schedules, and service calendars**.
## Team Management
----
-
### Searching Teams
- All teams are displayed by default; you can choose to show only "my" teams
@@ -52,25 +48,17 @@ Click a team name to enter the team detail page, where you can:
<Warning>
- Before deleting, confirm whether any channels, escalation rules, etc. are associated with this team
- - A team selected as a **default team** (`default_team_ids`) in any saved SAML2.0 / OIDC / CAS SSO configuration cannot be deleted: deletion returns `ReferenceExist` (the resource is still referenced by other entities and cannot be deleted). Unselect the team in the corresponding SSO configuration's default team options first. The restriction also applies when SSO or team sync is currently disabled
+ - A team selected as a **default team** in an SSO configuration (SAML2.0 / OIDC / CAS) cannot be deleted; unselect it in that SSO configuration first. This applies even when SSO or team sync is disabled
- After deletion, associated configurations will immediately become invalid and cannot be recovered. Please proceed with caution
</Warning>
## Member Management
----
-
In the member list, a warning icon appears next to unverified email addresses or phone numbers. Unverified contact methods cannot receive alert notifications. Please remind members to complete verification promptly. The list also shows each member's **Time Zone**: members without a personal time zone follow the organization time zone — see [Organization Information](/en/platform/organization-info) and [Personal Settings](/en/on-call/configuration/personal-settings) for details.
### Searching Members
-The search box in the member list matches with **OR** semantics — a member is returned when any of the following conditions is met:
-
-- **Name or email**: fuzzy match containing the keyword
-- **Phone number**: exact match when the input parses as a valid phone number
-- **Member ID**: when the input is purely numeric, an additional exact match against the member ID (`member_id`)
-
-For example, entering a member's ID (purely numeric) locates that member directly without knowing their name, email, or phone number.
+The search box finds a member by any of: name or email (fuzzy match), phone number (exact match), or member ID (exact match when you enter digits only).
### Invitation Methods
@@ -83,45 +71,21 @@ For example, entering a member's ID (purely numeric) locates that member directl
3. Set the **Default role on join (select one or more)** as needed — Viewer by default
4. Click **Copy link**; on the QR code tab, click **Save QR code** or **Copy QR code**
- How the link and QR code behave:
-
- - **Only the subject account or an Account.Admin can manage them**: other members do not see these two tabs, and a custom role with member-management permission can still only invite people one by one
- - **One link per organization**: it is generated when you open the invite dialog and stays valid for a fixed **42 days**; the tab shows the expiry date of the link / QR code
- - Clicking **Reset** rotates the link and restarts the clock — every link and QR code handed out before stops working immediately; the configured default roles are unaffected
- - **Copy link** copies a ready-to-forward message carrying the organization name, the link, and (when the organization has [join restrictions](/en/platform/organization-info#join-restrictions)) the email domains allowed to join; **Save QR code** / **Copy QR code** produce a poster image with the organization name and expiry date
- - Adding an admin role such as **Account.Admin** to the default roles requires a second confirmation — everyone who holds the link gets that role
- - A configured default role that has since been deleted falls back to **Viewer** at join time
-
- What invitees see when they open `{console domain}/invite/{token}`:
+ Good to know:
- 1. Before signing in they see the organization card (avatar and name) and click **Sign in to join**; the sign-in page carries the invite token, so they are not asked which organization to sign in to
- 2. After signing in they join the organization automatically and land in the console
-
- - Members who already belong to the organization, and the owner account, go straight in and **keep their roles**
- - People who join through the link get only the configured default roles and are **not added to any team**
- - After a reset or expiry, the landing page shows **This invite is no longer valid**; ask an organization admin for a new link
+ - Only the **owner account** or an **Account.Admin** can use invite links and QR codes; other roles can only invite people one by one
+ - Each organization has one link, valid for **42 days**; clicking **Reset** immediately invalidates every link and QR code handed out before
+ - Adding an admin role to the default roles requires a confirmation, since everyone with the link gets that role; if a default role has been deleted, new members get **Viewer**
+ - People who join through the link are **not added to any team**; existing members who open it keep their roles
+ - Invitees join the organization after opening the link and signing in; after expiry or a reset, ask an admin for a new link
</Tab>
- <Tab title="Email Invitation">
- Enter an email address on the **Email or phone** tab to send an invitation. The user nickname defaults to the email prefix and can be modified after activation.
-
- 1. Go to the member management page
- 2. Click **Invite Members**
- 3. Switch to the **Email or phone** tab and enter the email address
- 4. Enter the member name
- 5. Select role (optional)
- 6. Send invitation
+ <Tab title="Email or Phone Invitation">
+ 1. Go to the member management page and click **Invite Members**
+ 2. On the **Email or phone** tab, enter an email address or a phone number (international country codes supported)
+ 3. Enter the member name (for email invitations it defaults to the email prefix and can be changed after activation) and optionally select a role
+ 4. Send the invitation
- You can add multiple invitation entries in a single operation for batch invitations.
- </Tab>
- <Tab title="Phone Invitation">
- You can also invite members by filling in a phone number on the same **Email or phone** tab.
-
- 1. Go to the member management page
- 2. Click **Invite Members**
- 3. Switch to the **Email or phone** tab and enter the phone number (international country code supported)
- 4. Enter the member name
- 5. Select role (optional)
- 6. Send invitation
+ You can add multiple entries at once for batch invitations.
</Tab>
<Tab title="API Invitation">
Invite via [Open API](/en/api-reference/platform/members/member-invite), which supports both email and phone number invitations.
@@ -135,12 +99,8 @@ For example, entering a member's ID (purely numeric) locates that member directl
- The system will send SMS or email notifications to invitees
- Daily invitation limit is 200 people, with a maximum of 20 per invitation and up to 5 resends per day
- Unactivated accounts cannot receive alert-related notifications
- - When the organization configures an email-domain allowlist under [join restrictions](/en/platform/organization-info#join-restrictions), one-by-one invitations only accept addresses on that allowlist (the invite dialog lists the allowed domains); phone invitations are unaffected, and link joins are checked against the email domain used to sign in
- - When the subscription is expired or disabled, the **Invite members** entry is disabled: hovering tells you that the expired subscription blocks creating a new member and that existing members are not affected. The owner account can click **Renew now**, while member accounts are told to ask the account owner to renew. The entry becomes usable again as soon as you renew, and existing members are unaffected. See [What happens when your subscription expires](/en/platform/pricing#what-happens-when-your-subscription-expires)
-</Note>
-
-<Note>
-Inviting new members requires an active subscription. Once the subscription expires, the **Invite members** button on the member management page is disabled, and hovering it shows "Your subscription has expired, so you cannot create a new member. Existing members are unaffected." Existing members can keep working as usual.
+ - When the organization sets an email-domain allowlist under [join restrictions](/en/platform/organization-info#join-restrictions), email invitations and invite links only accept those domains; phone invitations are not restricted
+ - You cannot invite new members while the subscription is expired or disabled; existing members are unaffected. See [What happens when your subscription expires](/en/platform/pricing#what-happens-when-your-subscription-expires)
</Note>
### Changing Roles
@@ -194,8 +154,6 @@ For members auto-created via SSO, the profile and roles are maintained by the id
## FAQ
----
-
<AccordionGroup>
<Accordion title="Email invitation - member did not receive verification email">
Please check the following in order:
@@ -227,8 +185,6 @@ For members auto-created via SSO, the profile and roles are maintained by the id
## Related Topics
----
-
<CardGroup cols={2}>
<Card title="Permission Design" icon="shield-check" href="/en/platform/permission-design">
Learn about functional and data permission design
diff --git a/en/rum.mdx b/en/rum.mdx
index 6ff459d9..df5d3170 100644
--- a/en/rum.mdx
+++ b/en/rum.mdx
@@ -12,13 +12,11 @@ Flashduty RUM enables developers, operations engineers, and business stakeholder
## Core Capabilities
----
-
<AccordionGroup>
<Accordion title="Performance Monitoring" icon="gauge-high">
Monitor key performance metrics in real-time including page load times, resource loading efficiency, and JavaScript execution to quickly identify bottlenecks affecting user experience.
- - **Page performance**: Core Web Vitals including LCP, FID, CLS
+ - **Page performance**: Core Web Vitals including LCP, INP, CLS
- **Resource analysis**: Load times for images, scripts, and stylesheets
- **API monitoring**: API request response times and success rates
</Accordion>
@@ -47,8 +45,6 @@ Flashduty RUM enables developers, operations engineers, and business stakeholder
## Why Choose Flashduty RUM?
----
-
<CardGroup cols={2}>
<Card title="Full-spectrum Visibility" icon="eye">
Understand application performance from the user perspective across different browsers, devices, and regions
@@ -70,8 +66,6 @@ Flashduty RUM enables developers, operations engineers, and business stakeholder
## How It Works
----
-
Flashduty RUM collects data by embedding a lightweight JavaScript SDK in your web application:
<Steps>
@@ -99,9 +93,14 @@ Flashduty RUM collects data by embedding a lightweight JavaScript SDK in your we
| Error information | JavaScript exceptions, network failures, console errors |
| Long tasks | Time-consuming JavaScript tasks that may cause page stuttering |
-## Quick Start
+## Use Cases
----
+- Monitor Core Web Vitals (LCP, INP, CLS) for web applications
+- Track and analyze frontend errors to improve application stability
+- Analyze user behavior paths to optimize product experience
+- Correlate with backend traces for full-stack observability
+
+## Quick Start
<CardGroup cols={2}>
<Card title="Quick Start" icon="rocket" href="/en/rum/quickstart/quickstart">
diff --git a/en/rum/analytics/miniprogram.mdx b/en/rum/analytics/miniprogram.mdx
index e570bd5b..48b82f22 100644
--- a/en/rum/analytics/miniprogram.mdx
+++ b/en/rum/analytics/miniprogram.mdx
@@ -9,17 +9,17 @@ Flashduty WeChat Mini Program RUM Insights dashboard provides out-of-the-box vis
The Insights dashboard includes 2 core analysis dimensions: **Overview** and **Performance Analysis**
</Info>
-## Overview — Key Metrics at a Glance
+## Overview
The Overview tab focuses on the core multi-dimensional metrics of your Mini Program, helping you quickly assess overall health.
-#### Traffic and Sessions
+### Traffic and Sessions
- **UV**: Number of unique visitors after deduplication. Combined with the trend chart, this reveals user activity patterns.
- **Sessions**: Total number of sessions in which the Mini Program was opened. Click the card to drill into the session list.
- **User Access Trend**: Time-series chart showing UV and Session changes over time, helping you identify traffic peaks and unusual fluctuations.
-#### Core Metrics
+### Core Metrics
- **error_count**: Monitors the total number of error events and their time-series trend, surfacing anomaly spikes early.
- **Session Error Rate**: Percentage of sessions that contain at least one error, reflecting overall Mini Program stability.
@@ -28,15 +28,15 @@ The Overview tab focuses on the core multi-dimensional metrics of your Mini Prog
- **setDataCount (avg)**: Average number of `setData` calls per page view. A high call rate increases communication overhead between the JS thread and the render thread.
- **setDataDuration P75**: The P75 percentile of a single `setData` call's duration.
-#### Session Analysis
+### Session Analysis
- **Average Session Duration**: Total session duration divided by session count, used to assess user stickiness and engagement depth. The accompanying time-series chart helps identify behavioral shifts among active users.
-## Performance Analysis — Full Control over Mini Program Experience
+## Performance Analysis
The Performance Analysis tab provides end-to-end monitoring of the core experience metrics: launch, page rendering, and `setData`.
-#### Core Performance Metrics
+### Core Performance Metrics
Five key performance metric cards are displayed at the top. Click any card to switch the trend chart and sample distribution below to that metric:
@@ -50,7 +50,7 @@ Five key performance metric cards are displayed at the top. Click any card to sw
Each card displays a health-status badge (good / warning / poor) in the top-left corner, calculated against built-in thresholds.
-#### Trend Analysis
+### Trend Analysis
The trend chart below supports a **Trend Mode** selector that breaks down the current metric by different dimensions:
@@ -66,11 +66,11 @@ The trend chart below supports a **Trend Mode** selector that breaks down the cu
Switch to **By Version** during a gradual rollout to validate release quality. Switch to **By Loading Type** to observe cold-start (`initial_load`) and warm-start (`route_change`) durations independently.
</Tip>
-#### Sample Distribution
+### Sample Distribution
The sample distribution bar chart shows the count of samples falling into each time bucket for the current metric, surfacing long-tail behavior. For example, when viewing App Launch Time, the distribution clearly shows how many users launch within 1s, 1-2s, more than 2s, and so on.
-#### Per-Page Performance Detail
+### Per-Page Performance Detail
A per-page table breaks down performance metrics by view name, helping you identify pages with slow loading or excessive `setData` calls:
@@ -88,7 +88,7 @@ A per-page table breaks down performance metrics by view name, helping you ident
Click any row to drill into the detailed analysis view for that page.
-#### Loading Type Trends
+### Loading Type Trends
Two charts at the bottom compare cold start (`initial_load`) and warm start (`route_change`):
diff --git a/en/rum/analytics/native.mdx b/en/rum/analytics/native.mdx
index 76f2ffdd..cf0524e6 100644
--- a/en/rum/analytics/native.mdx
+++ b/en/rum/analytics/native.mdx
@@ -19,7 +19,7 @@ The Native dashboard applies to Android, iOS, HarmonyOS, Flutter, and React Nati
- **Electron**: Does not use the Native dashboard — Electron apps reuse the **Web Insights dashboard**, but UV is keyed on the anonymous ID (the Electron SDK does not report `usr_id`). See "Metrics Reference" below.
</Note>
-## Overview — Key Metrics at a Glance
+## Overview
<Frame>
<img src="https://docs-cdn.flashcat.cloud/imges/png/84bd82ffe44022ebeaab64a56a1e9ed1.png" alt="Native RUM Insights Overview showing UV, sessions, crash rate and other core health metrics" />
@@ -34,7 +34,7 @@ The Overview module focuses on core metrics across multiple dimensions for mobil
- **Session Analysis** - Track average session duration distribution trends to evaluate user engagement and usage depth
- **Version Distribution** - Monitor user distribution across different system versions (Android/iOS) and app versions to support compatibility optimization and version iteration
-## Performance Analysis — Comprehensive App Experience Monitoring
+## Performance Analysis
<Frame>
<img src="https://docs-cdn.flashcat.cloud/imges/png/ad17864ce4854b7ded905a7a88bdbc87.png" alt="Performance analysis dashboard showing startup time, frame rate, CPU and memory usage metrics" />
@@ -42,7 +42,7 @@ The Overview module focuses on core metrics across multiple dimensions for mobil
The Performance Analysis module focuses on full-chain monitoring of core experience metrics including app startup, page rendering, and interaction smoothness.
-#### Core Performance Metrics
+### Core Performance Metrics
The top section displays P75 percentile values for four key performance metrics:
@@ -52,12 +52,12 @@ The top section displays P75 percentile values for four key performance metrics:
- **Memory Usage (P75)**: Monitor the P75 percentile of app memory usage to detect memory leaks or abnormal growth early.
- **JS Thread Frame Rate (P75)**: Monitor the P75 percentile of the React Native JS thread's frame rate (FPS). Compared with the native frame rate, it reflects jank caused by business JavaScript more directly (re-renders, synchronous work on the bridge). Reported only by the React Native SDK.
-#### App Startup Time Analysis
+### App Startup Time Analysis
- **Startup Time Trend Chart**: Shows how app startup time changes over time, helping you evaluate optimization effectiveness and detect performance regressions.
- **Sample Distribution Histogram**: Statistics of startup duration distribution by time intervals (e.g., 0.9425s-0.9642s, 1.1162s-1.1379s), providing insights into real user startup experience distribution and identifying long-tail performance issues.
-#### View Performance Details
+### View Performance Details
Performance metrics by view name (Page/Activity/ViewController):
@@ -68,7 +68,7 @@ Performance metrics by view name (Page/Activity/ViewController):
- **CPU Usage**: Statistics of CPU utilization for each view to optimize compute-intensive pages.
- **Memory Usage**: Monitor memory usage for each view to detect memory leak risks.
-#### Smoothness Analysis
+### Smoothness Analysis
App smoothness metrics by view name:
@@ -91,7 +91,7 @@ If you disabled long-task collection to reduce event volume, raising the thresho
**Slow Frame Share is not comparable across platforms.** The numerator is slow-frame time on both, but the denominator differs: Android divides by total frame render time, iOS by view duration. The same user experience usually scores much higher on Android, because a static screen produces almost no frames — a small denominator — while the first frame is by definition a slow one. Compare values within a single platform over time.
</Note>
-#### Memory Analysis
+### Memory Analysis
Memory usage details by view name:
@@ -99,7 +99,7 @@ Memory usage details by view name:
- **Peak Memory**: Records peak memory usage during view runtime to identify memory pressure peaks and prevent system termination due to insufficient memory (OOM).
- **P75 Memory**: Shows the P75 percentile of memory usage, reflecting memory usage for most users, more representative of real experience than averages.
-## Error Analysis — Quick Error Identification and Diagnosis
+## Error Analysis
<Frame>
<img src="https://docs-cdn.flashcat.cloud/imges/png/b5868b87e52ddc7b82c61f685b2d0bd9.png" alt="Error analysis dashboard showing crash count, crash-free rate, ANR rate and unresponsive time rate" />
@@ -107,60 +107,51 @@ Memory usage details by view name:
The Error Analysis module provides comprehensive error monitoring and diagnosis capabilities.
-#### Core Stability Metrics
+### Core Stability Metrics
- **Crash Count**: Monitor total crash occurrences and trends to detect abnormal spikes early. Crashes force app termination and severely impact user experience.
- **Crash-free Rate**: Track the percentage of crash-free sessions to evaluate overall app stability. Industry standard recommends maintaining crash-free rate above 99.5%.
- **ANR Rate**: Statistics of Android Application Not Responding occurrence rate. ANR indicates the app's main thread has been blocked for more than 5 seconds, causing users to see the "App Not Responding" dialog.
- **Unresponsive Time Rate**: Seconds the main thread was unresponsive per hour of view time (seconds/hour), averaged by view time and counted only over views the SDK finished measuring. **This card is shown for iOS and Flutter apps only**; Android-only apps show the ANR Rate above instead. See "How to reduce unresponsive time rate?" below.
-#### Error Statistics
+### Error Statistics
- **Error Count**: Shows total error count and time-series trends to understand overall app health changes.
- **Error Type Distribution Trend Chart**: Stacked bar chart showing distribution changes of crash errors (crash_count) and non-crash errors (non_crash_count) over time, quickly identifying abnormal periods and error type change trends.
- **Crash Errors (crash_count)**: Severe errors causing forced app termination
- **Non-crash Errors (non_crash_count)**: Caught exceptions where the app can continue running but functionality may be affected
-#### Page Crash Ranking (Top 10)
+### Page Crash Ranking and Top Issues (Top 10)
-Lists pages or view controllers with the most crashes, each record containing:
+Both rankings show the same fields:
-- **Error Type**: Exception type of the crash (e.g., java.lang.RuntimeException, SIGTRAP, etc.)
-- **Error Message**: Detailed error description to help quickly locate the issue
-- **Error Count**: Total occurrences of this error on this page
-- **Session Count**: Number of sessions (user visits) affected by this error
+| Field | Page Crash Ranking | Top Issues |
+| --- | --- | --- |
+| **Error Type** | Exception type of the crash (e.g., java.lang.RuntimeException, SIGTRAP) | Primary error type of the Issue (e.g., java.lang.RuntimeException, TypeError) |
+| **Error Message** | Error description | Typical error description; click for stack traces and sessions |
+| **Error Count** | Occurrences of this error on this page | Errors in this Issue |
+| **Session Count** | Sessions affected | Sessions affected |
-This ranking helps you prioritize the most impactful page crash issues.
+Page Crash Ranking lists the pages or view controllers with the most crashes; Top Issues ranks Issues by the users they affect. Each Issue groups errors with the same root cause; see [Error Grouping](/en/rum/error-tracking/error-aggregation).
-#### Top Issues (Top 10)
-
-Shows ranking of issues affecting the most users. Each Issue is an aggregated collection of errors containing:
-
-- **Error Type**: Primary error type of the Issue (e.g., java.lang.RuntimeException, TypeError, ReferenceError, etc.)
-- **Error Message**: Typical error description of the Issue; click to view detailed stack traces and session information
-- **Error Count**: Total error occurrences in this Issue
-- **Session Count**: Number of sessions affected by this Issue
-
-**Note**: An Issue may aggregate multiple errors with the same root cause. For Issue aggregation strategy, see [Error Grouping](/en/rum/error-tracking/error-aggregation).
-
-#### Error Type Distribution
+### Error Type Distribution
- **Error Type Proportion (Pie Chart)**: Shows proportion of different error types (e.g., ReferenceError, java.lang.RuntimeException, etc.) to quickly identify main error sources.
- **Error Type Distribution Trend (Stacked Bar Chart)**: Monitor changes in each error type over time to detect new error types or abnormal growth of certain errors.
-#### Version Crash Distribution
+### Version Crash Distribution
- **Version Crash Distribution (Pie Chart)**: Statistics of crash distribution across different app versions to identify high-risk versions.
- **Version Crash Distribution Trend (Stacked Bar Chart)**: Monitor crash changes across versions over time to evaluate new version quality and perform hotfixes or rollbacks when necessary.
-#### System Version Error Distribution
+### System Version Error Distribution
- **System Version Error Distribution (Pie Chart)**: Statistics of error distribution across different OS versions (e.g., Android 11, Android 12, iOS 15, etc.) to identify system compatibility issues.
- **System Version Error Trend (Stacked Bar Chart)**: Monitor error changes across system versions over time to support system compatibility optimization.
For in-depth analysis of specific errors, see [Error Tracking](/en/rum/error-tracking/overview) to learn how to investigate critical errors, view error stacks, track new error occurrences, and verify fixes.
-## Resource Analysis — Fine-grained Network Performance Optimization
+## Resource Analysis
<Frame>
<img src="https://docs-cdn.flashcat.cloud/imges/png/97a80ff169a3c3e625e1c2e6d9d6a5b8.png" alt="Resource analysis dashboard showing request count, success rate, response time and resource timing rankings" />
@@ -413,7 +404,7 @@ The data source and threshold differ per platform:
For apps requiring user login (e.g., e-commerce, social, finance), you can call the SDK's user identification method after user login:
- Android: See [Android User Session Configuration](/en/rum/sdk/android/advanced-config#enrich-user-sessions)
-- iOS: See [iOS User Session Configuration](/en/rum/sdk/ios/advanced-config#enrich-user-sessions)
+- iOS: See [iOS User Session Configuration](/en/rum/sdk/ios/advanced-config#track-user-sessions)
**Device Fingerprint Identification**
@@ -530,7 +521,7 @@ Flashduty RUM typically completes data collection and display within **1-3 minut
| Metric | Calculation | Description |
|--------|------------|-------------|
| Crash Count | Direct count | Total crashes caused by unhandled exceptions or signals |
-| Crash-free Rate | Session-based: 1 minus (sessions with at least one crash / total sessions) | Recommended to maintain above 99%; a session that crashes several times still counts once. Android ANRs are not crashes and do not affect this metric |
+| Crash-free Rate | Session-based: 1 minus (sessions with at least one crash / total sessions) | Recommended to maintain above 99.5%; a session that crashes several times still counts once. Android ANRs are not crashes and do not affect this metric |
| ANR Rate | ANR sessions divided by total sessions | Triggered when UI thread blocked over 5 seconds (Android) |
| Unresponsive Time Rate | Total unresponsive main-thread time divided by total view time, expressed as seconds/hour | iOS counts App Hangs and requires `appHangThreshold`; Android counts main-thread freezes that reach 5 seconds |
diff --git a/en/rum/best-practices/distributed-tracing.mdx b/en/rum/best-practices/distributed-tracing.mdx
index a63194de..78f9fdd0 100644
--- a/en/rum/best-practices/distributed-tracing.mdx
+++ b/en/rum/best-practices/distributed-tracing.mdx
@@ -245,6 +245,15 @@ If your HTTP requests involve cross-origin issues, ensure:
- Monitor storage and query performance of tracing data
- Adjust tracing strategy based on business needs
+## Important Notes
+
+<Warning>
+- **Privacy Compliance**: Ensure trace data collection complies with relevant privacy regulations
+- **Performance Impact**: Set sampling rate appropriately to avoid significant impact on application performance
+- **Data Security**: Avoid including sensitive information in trace data
+- **Cross-Origin Configuration**: Ensure backend services have CORS properly configured to support tracing headers
+</Warning>
+
## Frequently Asked Questions
<AccordionGroup>
@@ -266,11 +275,3 @@ You can verify through the following methods:
</Accordion>
</AccordionGroup>
-## Important Notes
-
-<Warning>
-- **Privacy Compliance**: Ensure trace data collection complies with relevant privacy regulations
-- **Performance Impact**: Set sampling rate appropriately to avoid significant impact on application performance
-- **Data Security**: Avoid including sensitive information in trace data
-- **Cross-Origin Configuration**: Ensure backend services have CORS properly configured to support tracing headers
-</Warning>
diff --git a/en/rum/error-tracking/error-reporting.mdx b/en/rum/error-tracking/error-reporting.mdx
deleted file mode 100644
index 23054e68..00000000
--- a/en/rum/error-tracking/error-reporting.mdx
+++ /dev/null
@@ -1,241 +0,0 @@
----
-title: "Error Reporting"
-description: "Learn about RUM's error reporting mechanism."
----
-
-This document covers exception types, capture mechanisms, manual reporting methods, React integration, and the data structure definition for reported exceptions.
-
-## Exception Types
-
-RUM can monitor the following types of exceptions:
-
-<Tabs>
- <Tab title="JavaScript Exceptions">
- Includes code syntax errors, runtime exceptions, and unhandled Promise rejections. These issues can cause page functionality to fail, severely affecting user experience.
- </Tab>
- <Tab title="Network Exceptions">
- Monitors communication issues with backend services or third-party APIs:
-
- - XHR/Fetch request failures
- - Request timeouts
- - Cross-origin (CORS) errors
- - HTTP 4xx/5xx status codes
- </Tab>
- <Tab title="Resource Loading Exceptions">
- Monitors webpage resource loading failures:
-
- - Image loading failures
- - Script loading failures
- - Stylesheet loading failures
- - Font file loading failures
- </Tab>
- <Tab title="Custom Exceptions">
- In addition to automatically captured exceptions, you can use the RUM SDK to manually report custom exceptions for tracking specific issues like business logic errors.
- </Tab>
-</Tabs>
-
-## Reporting Methods
-
-### Automatic Error Capture
-
-RUM SDK automatically captures the following types of browser errors:
-
-| Error Type | Description |
-|----------|------|
-| Uncaught Exceptions | JavaScript exceptions thrown at runtime (e.g., `TypeError`, `ReferenceError`) |
-| Unhandled Promise Rejections | Promise errors not handled by `.catch()` |
-| Network Errors | XHR or Fetch request failures (e.g., 4xx, 5xx status codes or network interruption) |
-| React Rendering Errors | Exceptions during React component rendering (requires error boundaries) |
-
-<Note>
-- Automatically captured errors include stack traces, error messages, and source information by default.
-- Errors from browser extensions or third-party scripts (such as `network` source) are filtered to avoid data pollution.
-</Note>
-
-### Manual Error Reporting
-
-Through the `addError` API, you can manually report handled exceptions, custom errors, or other errors not automatically captured.
-
-**Applicable Scenarios:**
-- Log handled errors in business logic
-- Attach context information (such as user ID, page state) for troubleshooting
-- Monitor exceptions from third-party services or asynchronous operations
-
-<CodeGroup>
-```javascript Report Custom Error
-// Report custom error with context
-const error = new Error("Login failed");
-window.FC_RUM.addError(error, {
- pageStatus: "beta",
- userId: "12345",
- action: "login_attempt",
-});
-```
-
-```javascript Report Network Error
-fetch("https://api.example.com/data").catch((error) => {
- window.FC_RUM.addError(error, {
- requestUrl: "https://api.example.com/data",
- method: "GET",
- });
-});
-```
-
-```javascript Report Handled Exception
-try {
- // Business logic that might throw an exception
- riskyOperation();
-} catch (error) {
- window.FC_RUM.addError(error, {
- operation: "riskyOperation",
- timestamp: Date.now(),
- });
-}
-```
-</CodeGroup>
-
-### React Error Boundary Integration
-
-RUM supports capturing component rendering errors through React [Error Boundaries](https://legacy.reactjs.org/docs/error-boundaries.html) and reporting error information. You can call the `addError` API in `componentDidCatch`, attaching component stack information for debugging.
-
-<Steps>
- <Step title="Create Error Boundary Component">
- ```javascript
- class ErrorBoundary extends React.Component {
- componentDidCatch(error, info) {
- const renderingError = new Error(error.message);
- renderingError.name = "ReactRenderingError";
- renderingError.stack = info.componentStack; // Component stack
- renderingError.cause = error; // Original error
-
- window.FC_RUM.addError(renderingError, {
- component: this.props.componentName || "Unknown",
- version: "1.0.0",
- });
- }
-
- render() {
- return this.props.children;
- }
- }
- ```
- </Step>
- <Step title="Wrap Components with Error Boundary">
- ```jsx
- <ErrorBoundary componentName="UserProfile">
- <UserProfile />
- </ErrorBoundary>
- ```
- </Step>
-</Steps>
-
-## Error Data Structure
-
-Each error record contains the following attributes to describe error details and context:
-
-<ParamField path="error.source" type="string">
- Error source (e.g., `console`, `network`, `custom`, `source`, `report`)
-</ParamField>
-
-<ParamField path="error.type" type="string">
- Error type or error code (e.g., `TypeError`, `NetworkError`)
-</ParamField>
-
-<ParamField path="error.message" type="string">
- Concise, readable error message
-</ParamField>
-
-<ParamField path="error.stack" type="string">
- Error stack trace or supplementary information
-</ParamField>
-
-<ParamField path="error.causes" type="Array">
- List of related errors providing additional context (optional)
-</ParamField>
-
-<ParamField path="context" type="Object">
- Custom context information (e.g., page state, user ID), passed via `addError`
-</ParamField>
-
-## Error Filtering and Configuration
-
-To ensure accuracy and relevance of error data, RUM applies the following filtering rules:
-
-<AccordionGroup>
- <Accordion title="Default Filtering Rules">
- - Only processes errors with `source` of `custom`, `source`, `report`, or `console`
- - Ignores irrelevant errors from browser extensions, third-party scripts, or `network` source
- </Accordion>
- <Accordion title="Stack Requirements">
- Errors must contain stack trace information, otherwise they may be ignored
- </Accordion>
- <Accordion title="Custom Filtering">
- Use `beforeSend` callback to customize error handling logic, filtering or modifying error data
- </Accordion>
-</AccordionGroup>
-
-### Custom Error Filtering Example
-
-```javascript
-window.FC_RUM.init({
- beforeSend: (event) => {
- if (event.type === "error") {
- // Ignore specific error messages
- if (event.error.message.includes("ThirdPartyScript")) {
- return false; // Discard this error
- }
- // Add global context
- event.context = { ...event.context, appVersion: "2.1.0" };
- }
- return true;
- },
-});
-```
-
-## FAQ
-
-<AccordionGroup>
- <Accordion title="Why aren't some errors being grouped?">
- - Confirm stack trace is complete, or check if custom fingerprints conflict
- - Check if `sourcemap` is correctly uploaded; if not, stacks may not be parsed correctly
- </Accordion>
- <Accordion title="How to reduce third-party script error noise?">
- Use `beforeSend` callback to filter specific error sources or messages:
-
- ```javascript
- beforeSend: (event) => {
- if (event.error.source === "network") return false;
- return true;
- };
- ```
- </Accordion>
- <Accordion title="What if custom grouping isn't working?">
- - Ensure `fingerprint` attribute is correctly set and value is a string
- - Check if `beforeSend` callback is being called correctly
- </Accordion>
-</AccordionGroup>
-
-## Best Practices
-
-<CardGroup cols={2}>
- <Card title="Enrich Context Information" icon="info-circle">
- Attach business-related context in `addError` (such as user ID, action type) for easier problem location.
-
- Example: `{ userId: "12345", action: "submit_form" }`
- </Card>
- <Card title="Optimize Error Boundaries" icon="shield">
- Configure error boundaries for key React components to ensure rendering errors are captured. Record component names and versions for easier issue tracking.
- </Card>
- <Card title="Control Error Volume" icon="filter">
- Use sampling rates or `beforeSend` to filter low-value errors and avoid data overload. Prioritize monitoring critical errors affecting user experience.
- </Card>
- <Card title="Analysis & Visualization" icon="chart-line">
- View error data trends and distribution in the "Insights" - "Exception Analysis" Tab to resolve key exception issues.
- </Card>
-</CardGroup>
-
-## Next Steps
-
-<Card title="View Exceptions" icon="eye" href="./error-viewing">
- Learn how to view and analyze Issues in the error tracking module
-</Card>
diff --git a/en/rum/error-tracking/erro-reporting/android.mdx b/en/rum/error-tracking/error-reporting/android.mdx
similarity index 97%
rename from en/rum/error-tracking/erro-reporting/android.mdx
rename to en/rum/error-tracking/error-reporting/android.mdx
index e5a4088d..3d52be36 100644
--- a/en/rum/error-tracking/erro-reporting/android.mdx
+++ b/en/rum/error-tracking/error-reporting/android.mdx
@@ -272,11 +272,11 @@ Tracking background events may generate additional sessions, which could affect
1. Add test code to trigger a crash in your app:
-```kotlin
-fun onEvent() {
- throw RuntimeException("Test crash")
-}
-```
+ ```kotlin
+ fun onEvent() {
+ throw RuntimeException("Test crash")
+ }
+ ```
2. Run the app and trigger the crash
3. Restart the app and wait for the SDK to upload the crash report
@@ -286,12 +286,12 @@ fun onEvent() {
1. Add a test crash in native code:
-```cpp
-void crash() {
- int* ptr = nullptr;
- *ptr = 42; // Trigger null pointer crash
-}
-```
+ ```cpp
+ void crash() {
+ int* ptr = nullptr;
+ *ptr = 42; // Trigger null pointer crash
+ }
+ ```
2. Call this native method from Java/Kotlin code
3. Restart the app and wait for the SDK to upload the crash report
@@ -301,11 +301,11 @@ void crash() {
1. Execute a time-consuming operation on the main thread:
-```kotlin
-fun blockMainThread() {
- Thread.sleep(10000) // Block main thread for 10 seconds
-}
-```
+ ```kotlin
+ fun blockMainThread() {
+ Thread.sleep(10000) // Block main thread for 10 seconds
+ }
+ ```
2. Trigger this operation and try to interact with the app
3. Check if the Flashcat console received the ANR report
diff --git a/en/rum/error-tracking/erro-reporting/ios.mdx b/en/rum/error-tracking/error-reporting/ios.mdx
similarity index 98%
rename from en/rum/error-tracking/erro-reporting/ios.mdx
rename to en/rum/error-tracking/error-reporting/ios.mdx
index d54d773d..a7b55fdb 100644
--- a/en/rum/error-tracking/erro-reporting/ios.mdx
+++ b/en/rum/error-tracking/error-reporting/ios.mdx
@@ -333,11 +333,11 @@ Tracking background events may generate additional sessions, which could affect
2. **Trigger a test crash**:
-```swift
-func triggerTestCrash() {
- fatalError("Test crash")
-}
-```
+ ```swift
+ func triggerTestCrash() {
+ fatalError("Test crash")
+ }
+ ```
3. **Restart the app**: After the crash occurs, restart the app from the device and wait for the SDK to upload the crash report.
@@ -347,11 +347,11 @@ func triggerTestCrash() {
1. Execute a time-consuming operation on the main thread:
-```swift
-func blockMainThread() {
- Thread.sleep(forTimeInterval: 5) // Block main thread for 5 seconds
-}
-```
+ ```swift
+ func blockMainThread() {
+ Thread.sleep(forTimeInterval: 5) // Block main thread for 5 seconds
+ }
+ ```
2. Trigger this operation and try to interact with the app.
diff --git a/en/rum/error-tracking/erro-reporting/web.mdx b/en/rum/error-tracking/error-reporting/web.mdx
similarity index 89%
rename from en/rum/error-tracking/erro-reporting/web.mdx
rename to en/rum/error-tracking/error-reporting/web.mdx
index 58fd175a..a43b9890 100644
--- a/en/rum/error-tracking/erro-reporting/web.mdx
+++ b/en/rum/error-tracking/error-reporting/web.mdx
@@ -193,6 +193,13 @@ window.FC_RUM.init({
});
```
+## Best Practices
+
+- **Enrich Context Information**: Attach business-related context in `addError` (e.g., user ID, action type) for easier troubleshooting. Example: `{ userId: "12345", action: "submit_form" }`
+- **Optimize Error Boundaries**: Configure error boundaries for critical React components to ensure rendering errors are captured. Record component names and versions for easier tracking.
+- **Control Error Volume**: Use sampling rates or `beforeSend` to filter low-value errors and avoid data overload. Prioritize monitoring critical errors that impact user experience.
+- **Analysis and Visualization**: View error data trends and distribution in the Analytics Dashboard - Error Analysis tab to address key issues.
+
## Frequently Asked Questions
<AccordionGroup>
@@ -216,25 +223,6 @@ window.FC_RUM.init({
</Accordion>
</AccordionGroup>
-## Best Practices
-
-<CardGroup cols={2}>
- <Card title="Enrich Context Information" icon="info-circle">
- Attach business-related context in `addError` (e.g., user ID, action type) for easier troubleshooting.
-
- Example: `{ userId: "12345", action: "submit_form" }`
- </Card>
- <Card title="Optimize Error Boundaries" icon="shield">
- Configure error boundaries for critical React components to ensure rendering errors are captured. Record component names and versions for easier tracking.
- </Card>
- <Card title="Control Error Volume" icon="filter">
- Use sampling rates or `beforeSend` to filter low-value errors and avoid data overload. Prioritize monitoring critical errors that impact user experience.
- </Card>
- <Card title="Analysis and Visualization" icon="chart-line">
- View error data trends and distribution in the Analytics Dashboard - Error Analysis tab to address key issues.
- </Card>
-</CardGroup>
-
## Next Steps
<Card title="View Errors" icon="eye" href="/en/rum/error-tracking/error-viewing">
diff --git a/en/rum/error-tracking/error-viewing.mdx b/en/rum/error-tracking/error-viewing.mdx
index 4651ed9d..8dd1e851 100644
--- a/en/rum/error-tracking/error-viewing.mdx
+++ b/en/rum/error-tracking/error-viewing.mdx
@@ -114,7 +114,7 @@ Error samples only exist within the error data retention window; older Issues ex
The export always includes the Issue's 18 fields (Issue ID, Issue URL, Application, Service, Error type, Error message, Status, Severity, Is crash, Error count, Affected sessions, First seen, First seen version, Last seen, Last seen version, Versions, Suspected cause, Resolved at); the sample columns are appended when "Include error samples" is enabled.
<Warning>
-- A single export is capped at **100 rows**. When more than 100 Issues match, a tooltip on the button says "At most 100 rows can be exported. Narrow the time range or add filters."; if the exported file was truncated, the page shows a toast with the exported count.
+- A single export is capped at **100 rows**. If more match, narrow the time range or add filters.
- Time columns (First seen / Last seen / Resolved at / sample time) carry the timezone in the header (e.g. `First seen (Asia/Shanghai)`) with cell values as `YYYY-MM-DD HH:mm:ss` text in that timezone, so spreadsheets sort them as dates.
- Sample stacks are truncated to the first 20 lines. Full stacks are available in the Issue detail (where they are symbolicated per platform); the export contains the raw frames as reported, without symbolication.
- To prevent formula injection, cells starting with `=`, `+`, `-`, or `@` are prefixed with a quote.
@@ -201,7 +201,7 @@ Click any Issue to open the details panel and view more information.
<Accordion title="Error Sample">
By default, displays the most recent error information reported during the Issue's occurrence as an error sample. You can also switch through the navigation bar.
- For native crashes, each sample in the navigation list carries a symbolication badge ("Parsed" / "Unparsed"). When the latest sample cannot be symbolicated but an older sample can, the detail auto-switches to the symbolatable sample and shows the notice "Switched to a sample that can be symbolicated (the latest one is not)." Click "Back to latest" to return to the most recent sample. The auto-switch tries at most 5 older samples; if none of them can be symbolicated, the detail switches back to the latest sample and stops auto-switching.
+ Each native crash sample shows whether it is symbolicated. If the latest sample is not, the detail switches automatically to an earlier sample that can be symbolicated (trying up to 5), and you can switch back to the latest one.
</Accordion>
<Accordion title="Error Stack and Source Mapping">
View error context and stack information. If the corresponding SourceMap, Android mapping file, iOS dSYM file, or Flutter symbol file has been uploaded, you can see mapped original source code locations and code snippets.
@@ -241,13 +241,11 @@ Click any Issue to open the details panel and view more information.
**Symbols Required by This Crash (Non-System)**
- When a crash carries non-system binary images (native crashes that resolve addresses through binary images, such as iOS and Electron, including Flutter's iOS native crashes), a "Symbols required by this crash (non-system)" section appears above the stack, listing every non-system binary image this crash references and its symbolication status:
+ For native crashes such as iOS and Electron (including Flutter's iOS native crashes), the non-system binary images the crash references are listed above the stack, each with its name, UUID and whether it is symbolicated (the list is expanded while anything is missing). You can:
- - The section header summarizes the status as "symbolicated/total symbolicated"; it collapses to a one-line summary when everything is resolved and expands by default while anything is missing
- - Each image is a row showing its name, UUID, and a "Parsed" / "Unparsed" badge, with a copy-UUID button
- - "Look up in symbol list" opens the Source Mapping page pre-filtered by that image's UUID
- - Unparsed images also provide an "Upload" link that goes straight to the upload entry of the Source Mapping page
- - While anything is unresolved, the "Re-symbolicate" button in the section forces a fresh symbolication run and refreshes the stack
+ - copy the UUID, or click **Look up in symbol list** to open Source Mapping filtered by that UUID;
+ - click **Upload** on an unparsed image to upload its symbols;
+ - click **Re-symbolicate** after uploading to refresh the stack.
**Flutter Support**
@@ -307,26 +305,12 @@ For detailed alert configuration instructions, please refer to [Issue Alerts](./
## Best Practices
-<CardGroup cols={2}>
- <Card title="Configure Source Mapping" icon="code">
- Facilitates problem localization in production environments
- </Card>
- <Card title="Add User Information" icon="user">
- Configure user-related information to provide better error context
- </Card>
- <Card title="Set Alert Policies" icon="bell">
- Configure appropriate channels and escalation rules for errors
- </Card>
- <Card title="Regular Error Analysis" icon="chart-line">
- Regularly check error reports to discover potential issues
- </Card>
- <Card title="Team Collaboration" icon="users">
- Use team ownership features to ensure issues are quickly assigned to relevant teams
- </Card>
- <Card title="Monitor Regressions" icon="rotate">
- Closely monitor potential regressions of resolved issues
- </Card>
-</CardGroup>
+- **Configure Source Mapping**: Facilitates problem localization in production environments
+- **Add User Information**: Configure user-related information to provide better error context
+- **Set Alert Policies**: Configure appropriate channels and escalation rules for errors
+- **Regular Error Analysis**: Regularly check error reports to discover potential issues
+- **Team Collaboration**: Use team ownership features to ensure issues are quickly assigned to relevant teams
+- **Monitor Regressions**: Closely monitor potential regressions of resolved issues
## Next Steps
diff --git a/en/rum/error-tracking/issue-status.mdx b/en/rum/error-tracking/issue-status.mdx
index 673e24d8..bf4c5875 100644
--- a/en/rum/error-tracking/issue-status.mdx
+++ b/en/rum/error-tracking/issue-status.mdx
@@ -90,14 +90,8 @@ Simply click the current status and select the new status from the dropdown menu
## Best Practices
-<CardGroup cols={2}>
- <Card title="Continuous Monitoring" icon="eye">
- Regularly check Issues in **For Review (for_review)** status to ensure new issues and regressions are handled promptly
- </Card>
- <Card title="Version Management" icon="code-branch">
- Always configure the correct version tag for your application so the system can accurately identify resolved issues
- </Card>
-</CardGroup>
+- **Continuous Monitoring**: Regularly check Issues in **For Review (for_review)** status to ensure new issues and regressions are handled promptly
+- **Version Management**: Always configure the correct version tag for your application so the system can accurately identify resolved issues
<Tip>
By effectively managing Issue status, your team can focus more on solving important problems, reduce time spent handling noise, and improve overall development efficiency.
diff --git a/en/rum/error-tracking/overview.mdx b/en/rum/error-tracking/overview.mdx
index bc07f345..413a0721 100644
--- a/en/rum/error-tracking/overview.mdx
+++ b/en/rum/error-tracking/overview.mdx
@@ -112,7 +112,7 @@ After resolving a problem, you can transition the Issue status in the system and
## Next Steps
<CardGroup cols={2}>
- <Card title="Error Reporting" icon="upload" href="./erro-reporting/web">
+ <Card title="Error Reporting" icon="upload" href="./error-reporting/web">
Learn about error reporting rules and methods
</Card>
<Card title="View Errors" icon="eye" href="./error-viewing">
diff --git a/en/rum/error-tracking/source-mapping.mdx b/en/rum/error-tracking/source-mapping.mdx
index e74bc2fd..2fa0c50e 100644
--- a/en/rum/error-tracking/source-mapping.mdx
+++ b/en/rum/error-tracking/source-mapping.mdx
@@ -471,7 +471,7 @@ Symbol files are matched to crash events by build ID; `service` and `release-ver
React Native JS error stacks are de-minified with sourcemaps. Like Flutter, a React Native app layers Android/iOS native code on top of one JS codebase: the two platforms' sourcemaps are stored separately, so same-named bundles never overwrite each other — the server matches by the `react-native` type plus the platform (iOS / Android), which lets both sides use the same bundle file name.
-In **App Management > Source Maps**, select the **React Native** tab; the upload panel generates the relevant script for the selected platform:
+In **App Management → Source Maps**, select the **React Native** tab; the upload panel generates the relevant script for the selected platform:
| Field | Description |
|-------|-------------|
diff --git a/en/rum/explorer/analytics.mdx b/en/rum/explorer/analytics.mdx
index 5a5dabea..6c3c4d35 100644
--- a/en/rum/explorer/analytics.mdx
+++ b/en/rum/explorer/analytics.mdx
@@ -9,14 +9,7 @@ The RUM Explorer gives you two view modes: **List** and **Analytics**. The **Ana
## List and analytics
-The top of the Explorer has two tabs: **List** shows events one by one, **Analytics** aggregates them into charts. Both share the same event type, query conditions and time range, so switching tabs never drops your current filters.
-
-The mode is recorded in the `mode` URL parameter: `mode=analytics` opens analytics, and omitting `mode` opens the list, so existing Explorer links keep opening the list. Copy the URL of an analytics view to share the same chart with others.
-
-| Tab | `mode` value | What it shows |
-|-----|--------------|---------------|
-| **List** | omitted | Event trend graph and event table, drilling into individual event details |
-| **Analytics** | `analytics` | Charts aggregated by the aggregation and group |
+The top of the Explorer has two tabs: **List** shows events one by one, and **Analytics** aggregates them into charts. Both share the same event type, query conditions and time range, so switching tabs never drops your filters. The analytics view is kept in the URL, so you can copy the link to share the same chart (see [URL parameters](#url-parameters)).
## Choosing the aggregation and fields
@@ -24,98 +17,83 @@ The **Measure** row at the top of the analytics view decides what is computed: p
### Aggregations
-| Aggregation | `agg` value | Description |
-|-------------|-------------|-------------|
-| **Count** | `count` | Number of events; takes no field |
-| **Unique count** | `count_distinct` | Number of distinct values of a field |
-| **Average** | `avg` | Mean of a numeric field |
-| **Sum** | `sum` | Total of a numeric field |
-| **Min** | `min` | Smallest value of a numeric field |
-| **Max** | `max` | Largest value of a numeric field |
-| **P50 / P75 / P90 / P95 / P99** | `p50` / `p75` / `p90` / `p95` / `p99` | Approximate percentiles of a numeric field, for watching the long tail |
+| Aggregation | Description |
+|-------------|-------------|
+| **Count** | Number of events; takes no field |
+| **Unique count** | Number of distinct values of a field |
+| **Average** | Mean of a numeric field |
+| **Sum** | Total of a numeric field |
+| **Min** | Smallest value of a numeric field |
+| **Max** | Largest value of a numeric field |
+| **P50 / P75 / P90 / P95 / P99** | Approximate percentiles of a numeric field, for watching the long tail |
-Every aggregation except **Count** needs a **Measured field**. With Average, Sum, Min, Max or any percentile, the field picker lists numeric fields only; timestamp fields (unit `unix_millisecond`) are excluded, since averaging them is meaningless. With **Unique count**, the field picker lists the scalar facets that can be grouped by. After you switch the event type, a field that does not exist on the new event type is reported as missing and you are asked to pick another one, rather than the question silently becoming a count.
+Every aggregation except **Count** needs a **Measured field**:
-The legend, the table columns and the CSV header all use the same naming: the measure of **Count** and of a **Distribution** reads "Events"; every other aggregation reads "Aggregation (field name)", for example "Average (view_loading_time)".
+- Average, Sum, Min, Max and percentiles accept numeric fields only (timestamps excluded).
+- Unique count accepts any field you can group by.
+- If you switch to an event type that lacks the field, pick another one.
-### Group-by field
+In the legend, table and CSV, Count and Distribution measures read "Events"; other aggregations read "Aggregation (field name)", such as "Average (view_loading_time)".
-The **Group-by field** decides what the measure is split by. Once one is chosen, the chart draws each group value separately and a **top** selector appears next to it, offering `5`, `10`, `20` and `50` groups, `10` by default. The group-by field can be cleared (the placeholder reads "No grouping"), and the result then collapses into a single number. Only scalar facets can be grouped by; an array field holds several values per event and therefore has no meaningful grouping.
+### Group-by field
-A **Distribution** does not use a group-by field, and that selector is not shown.
+The **Group-by field** splits the measure so each value is shown separately. Use **top** to keep the top `5`, `10` (default), `20` or `50` groups; without a group-by, the result is a single number. Array fields cannot be grouped by, and a **Distribution** does not use a group-by.
## Chart types
The analytics view offers five chart types:
-| Chart type | `viz` value | Description |
-|------------|-------------|-------------|
-| **Timeseries** | `timeseries` | The measure over time buckets; the default chart type |
-| **Top list** | `toplist` | Groups ranked by the measure, largest first |
-| **Pie** | `pie` | Share of each group, subject to the constraints below |
-| **Table** | `table` | Two columns: the group and the measure |
-| **Distribution** | `distribution` | Histogram of events per value range of one numeric field |
-
-A **Timeseries** also offers a **Draw style** selector that switches between **Line** (`line`) and **Bars** (`bar`), bars by default. When a group-by field is set, the draw style is bars and the aggregation is **Count** or **Sum**, the bars are stacked by group and the bar height is the total; the other aggregations (averages, percentiles, unique counts) cannot stack, because their per-group values do not add up.
+| Chart type | Description |
+|------------|-------------|
+| **Timeseries** | The measure over time (default) |
+| **Top list** | Groups ranked by the measure, largest first |
+| **Pie** | Share of each group. Requires a group-by and **Count** or **Sum** (the only aggregations that add up to a whole) |
+| **Table** | Two columns: the group and the measure |
+| **Distribution** | Histogram of events per value range of one numeric field; see [Distribution](#distribution) |
-Without a group-by field, **Top list** and **Table** print the measure itself instead of drawing a single bar; a **Timeseries** still plots one line over time.
+A **Timeseries** can be drawn as **Bars** (default) or **Line**. With a group-by and Count or Sum, bars are stacked by group so the bar height is the total; other aggregations do not add up, so they are not stacked.
## Drilling down
-Clicking an element on a chart opens a drill-down menu that takes you from the aggregate back to individual events: a point in time on a timeseries, a row in the top list or table, a slice of a pie, or a range of a distribution.
+Click a point in time, row, slice or range on a chart to drill down from the aggregate to individual events:
| Menu item | What it does |
|-----------|--------------|
| **View in list** | Switches to the list tab, showing only the events behind the clicked element |
-| **Split "value"** | Keeps only the clicked group value and opens the group-by picker so you can break it down by another field; a distribution range has no group, so the item reads **Filter to "range"** and keeps only the events in that range |
+| **Split "value"** | Keeps only that value and lets you pick the next group-by field (**Filter to "range"** on a distribution) |
| **Exclude "value"** | Drops the clicked group value from the result |
-A drill-down writes the same filters the facet list on the left writes, so they show up in the search box and can be undone the same way. Drilling down from a timeseries point narrows the list to that time bucket, and drilling down from a distribution range filters the list by that numeric range.
-
-After **View in list**, a **Back to analytics** bar appears above the list with the note "The list is filtered by the drill-down; going back restores the previous query". Clicking it returns to the analytics view and restores the query you drilled from. Switching tabs by hand ends that drill-down, and the bar disappears with it.
+A drill-down adds ordinary filters (a time-point drill-down narrows the time range), which you can see and undo in the search box. After **View in list**, click **Back to analytics** at the top of the list to return to the analysis you drilled from.
<Note>
-The empty group, shown on charts as "(empty)", cannot be drilled into yet, so **Split** and **Exclude** are both unavailable for it.
+The empty group (shown as "(empty)") cannot be split or excluded yet.
</Note>
## Zooming a timeseries
-Drag across a **Timeseries** to zoom into that window. The zoom applies to this chart only; the Explorer's own time range stays as it is. While zoomed, the **Zoomed** badge in the top-right corner of the chart shows the current window, and the close button on it (**Reset zoom**) restores the full time range. Changing the event type, the query conditions or the Explorer's time range resets the zoom.
+Drag across a **Timeseries** to zoom in. The zoom affects this chart only, not the Explorer's time range. Click the close button on the **Zoomed** badge to reset it; changing the event type, query or time range also resets it.
## Downloading an image and exporting CSV
-Two export buttons sit in the top-right corner of the chart:
-
-| Button | Description |
-|--------|-------------|
-| **Download image** | Exports the current chart as a PNG rendered at twice the pixel density. A Table, or a single number without a group-by, is not a chart, so the button is unavailable |
-| **CSV** | Exports the current chart's data as CSV, named like `rum-<event type>-analytics-<timestamp>.csv`. A timeseries exports one row per time, group and measure (long format); the other charts export one row per group |
+From the top-right corner of the chart:
-Both buttons are unavailable while the result is empty.
+- **Download image**: exports a PNG at 2× resolution. Not available for tables or a single ungrouped number.
+- **CSV**: exports the chart data. A timeseries has one row per time, group and measure; other charts have one row per group.
## Distribution
-A **Distribution** buckets one numeric field by value range and shows the number of events in each range. It ignores the aggregation and the group-by.
-
-- Buckets span from the field's minimum up to `P99`: RUM timings have a long tail (one 46s page load among thousands of 1s ones), and splitting up to the maximum would crush the whole body of values into the first bar.
-- The bucket width is rounded to `1`, `2` or `5` times a power of ten, so bucket edges read as round numbers; the observed range is split into about 40 buckets.
-- Everything above `P99` goes into one open-ended last bucket, shown on the chart and in the CSV as "≥ edge".
-- Ranges are labelled in the field's own unit, for example `1s–1.5s` for a duration field.
-
-## When a Pie applies
-
-A Pie requires both of the following; otherwise the chart area shows "Pie charts need a group-by and only apply to count and sum":
+A **Distribution** buckets one numeric field by value range and shows the number of events in each range, without an aggregation or group-by.
-- a **Group-by field** is set;
-- the aggregation is **Count** or **Sum** — only these two add up to a whole, which is what a pie claims. Unique counts, averages and percentiles do not.
+- Buckets cover the minimum up to `P99` in about 40 round-numbered buckets; values above `P99` go into a final "≥ edge" bucket, so a long tail does not squeeze most data into the first bar.
+- Ranges use the field's unit, such as `1s–1.5s`.
## Sampled estimates
-When the data volume is large enough that the result is estimated from a sample, the **Sampled** badge appears in the top-right corner of the chart, with the tooltip "Large data volume: results are estimated from a sample".
+With large data volumes, results are estimated from a sample and the chart shows a **Sampled** badge in its top-right corner.
## URL parameters
-The analytics view keeps its state in the URL, so a copied link reproduces the same analysis. Values that are not allowed fall back to the default.
+The analytics view keeps its state in the URL, so a copied link reproduces the same analysis, and you can build links from the table below. Invalid values fall back to the default.
| Parameter | Meaning | Values | Default |
|-----------|---------|--------|---------|
diff --git a/en/rum/explorer/data-query.mdx b/en/rum/explorer/data-query.mdx
index 4178c5c4..6b8865ee 100644
--- a/en/rum/explorer/data-query.mdx
+++ b/en/rum/explorer/data-query.mdx
@@ -3,18 +3,15 @@ title: "Data Query Syntax Guide"
description: "Master Flashduty RUM Explorer search syntax to quickly locate and analyze user data through flexible query conditions."
---
-Flashduty RUM Explorer provides powerful search capabilities, allowing you to quickly locate and analyze RUM data through flexible query syntax. Queries consist of **terms** and **operators**, supporting complex search condition combinations.
+RUM Explorer queries are made of **terms** and **operators** that combine into complex conditions; if you don't know the syntax yet, you can query in natural language instead.
-## AI natural-language query
+## AI Natural-Language Queries
-If you are not yet familiar with the query syntax, you can describe the data you want to find in plain language, and AI will convert it into a query for you.
+If you are not familiar with the query syntax, describe the data you want in plain language (Chinese or English) and AI converts it into a standard query (DQL) that uses the same fields and syntax as manual queries. Click the **AI Natural-Language Query** (magic wand) icon on the left of the query field, or press <kbd>⌘</kbd> + <kbd>Enter</kbd> from the normal query mode (<kbd>Ctrl</kbd> + <kbd>Enter</kbd> on Windows and Linux); the input border is highlighted while AI mode is active.
<Steps>
- <Step title="Enter AI query">
- Click the **magic wand** icon in the query input to enter AI natural-language query mode. Once active, the input border is highlighted to clearly distinguish it from regular query mode.
- </Step>
- <Step title="Describe your intent">
- Describe the data you want to find in plain language (Chinese or English supported), then press **Enter** to convert. For example:
+ <Step title="Describe what you want to find">
+ Describe the data in plain language and press <kbd>Enter</kbd> to generate a preview. For example:
```
5xx resource requests from Chrome that took longer than 2 seconds
@@ -25,24 +22,28 @@ If you are not yet familiar with the query syntax, you can describe the data you
```
browser_name:Chrome resource_status_code:>=500 resource_duration:>2s
```
+
+ You don't need to remember field names — AI picks the queryable fields for the current event type.
+ </Step>
+ <Step title="Review the preview">
+ The preview shows the DQL condition to add. When the request better fits another event type (for example, "Switch event type to Errors") or time range, it also shows that change. If the result isn't right, refine your description and press Enter again to regenerate.
</Step>
- <Step title="Preview and apply">
- AI generates the corresponding query and shows a preview. When it looks right, click **Apply** and the query takes effect immediately; if the result is not what you expected, refine your description and press Enter again to regenerate, or click **Undo** to revert to the state before applying.
+ <Step title="Apply or undo">
+ Click **Apply**, **Append to Query**, or **Switch and Apply** to confirm the change. After applying, the confirmation message offers **Undo** to restore the previous query, event type, and time range.
</Step>
</Steps>
-<Note>
-AI generates a standard query (DQL) using the same fields and syntax as manual queries (see below). You do not need to remember field names — AI automatically picks the queryable fields based on the current event type.
-</Note>
-
### Append instead of replace
-When the input already contains query conditions, the AI-generated conditions are **appended** to the existing query rather than overwriting it. This lets you build on an existing query and add filters incrementally in plain language. If the query is currently empty, the generated result is applied directly.
+When the input already contains conditions, AI-generated conditions are **appended** rather than overwriting them, so you can add filters step by step in plain language. If the query is empty, the generated result is applied directly.
-If your description fits a different event type better, AI prompts you to switch (for example, "Switch event type to Errors") and generates the query within that event type's queryable fields.
+<Note>
+- Time expressions such as "last hour," "yesterday," and "past 7 days" update the Explorer time picker; they are not written as DQL conditions such as `client_time`. Performance-duration conditions remain DQL, for example `view_loading_time:>2s`.
+- The time range is limited to **14 days**. If you ask for more, the preview says it was truncated to the most recent 14 days: a relative range becomes the past 14 days, and an absolute range keeps the requested end time and starts 14 days earlier.
+</Note>
<Tip>
-Describe your intent in **plain language** in the AI input — there is no need to hand-write query syntax (such as `browser_name:Chrome`), as entering query syntax directly lowers conversion accuracy. When you need precise control over conditions, use the query syntax below instead.
+Describe your intent in **plain language** in the AI input; typing query syntax (such as `browser_name:Chrome`) lowers conversion accuracy. When you need precise control, use the query syntax below.
</Tip>
## Query Basics
@@ -62,30 +63,6 @@ Queries support two types of terms:
| `OR` | Union: either term is contained in the selected view, must be wrapped in `()` | `(error OR warning)` |
| `-` | Exclusion: the following term is not in the view | `error -timeout` |
-## AI Natural-Language Queries
-
-When you do not want to write DQL by hand, let AI turn a natural-language request into query conditions. In the RUM Explorer query field, click the **AI Natural-Language Query** icon on the left. You can also press <kbd>⌘</kbd> + <kbd>Enter</kbd> from the normal query mode, or <kbd>Ctrl</kbd> + <kbd>Enter</kbd> on Windows and Linux.
-
-<Steps>
- <Step title="Describe what you want to find">
- Use natural language, such as “errors on Chrome,” “resource requests slower than 2 seconds,” or “checkout pages from the last 24 hours.” Press <kbd>Enter</kbd> to generate a preview.
- </Step>
- <Step title="Review the preview">
- The preview shows the DQL condition to add. When the request better fits another event type or time range, it also shows the event-type or time-range change.
- </Step>
- <Step title="Apply or undo">
- Click **Apply**, **Append to Query**, or **Switch and Apply** to confirm the change. After applying it, the confirmation message offers **Undo** to restore the previous query, event type, and time range.
- </Step>
-</Steps>
-
-<Note>
-Time expressions such as “last hour,” “yesterday,” and “past 7 days” update the Explorer time picker; they are not written as DQL conditions such as `client_time`. Performance-duration conditions remain DQL, for example `view_loading_time:>2s`.
-</Note>
-
-<Note>
-AI natural-language queries support a maximum time range of **14 days**. If the requested range is longer, the preview indicates that it has been truncated to the most recent 14 days; after you apply it, the time picker uses that truncated range. A relative range becomes the past 14 days, while an absolute range keeps the requested end time and starts 14 days earlier.
-</Note>
-
## Full-Text Search
<Warning>
@@ -240,24 +217,11 @@ The on-error capture switches live in [Remote Configuration](../quickstart/app-m
## Best Practices
-<CardGroup cols={2}>
- <Card title="Use Quotes for Phrases" icon="quote-left">
- Ensure exact matching of multi-word phrases
- </Card>
- <Card title="Use Wildcards Wisely" icon="asterisk">
- Avoid overly broad search conditions
- </Card>
- <Card title="Combine Multiple Conditions" icon="layer-group">
- Build precise queries through AND/OR operators
- </Card>
- <Card title="Use Auto-Complete" icon="keyboard">
- Reduce input errors and improve search accuracy
- </Card>
-</CardGroup>
-
-<Tip>
-Save frequently used search conditions to improve efficiency for repeated queries.
-</Tip>
+- Wrap multi-word phrases in double quotes for exact matching.
+- Use wildcards sparingly to avoid overly broad conditions.
+- Combine conditions with `AND` / `OR` to build precise queries.
+- Rely on auto-complete to avoid typos.
+- Save frequently used search conditions for repeated queries.
## Next Steps
diff --git a/en/rum/explorer/overview.mdx b/en/rum/explorer/overview.mdx
index 96e8d236..3692a6f5 100644
--- a/en/rum/explorer/overview.mdx
+++ b/en/rum/explorer/overview.mdx
@@ -1,85 +1,35 @@
---
title: "RUM Explorer Overview"
sidebarTitle: "Feature Overview"
-description: "Master the powerful features of Flashduty RUM Explorer to deeply analyze user data, performance metrics, and application behavior through a visual interface."
+description: "Use the RUM Explorer to search and analyze RUM events: select an application, search and filter, view event details, save views, and export CSV."
---
-Flashduty RUM **Explorer** is a powerful data analysis tool designed to help developers deeply inspect data collected from applications and obtain detailed information about RUM events. Through an intuitive visual interface, you can gain a comprehensive understanding of user behavior, application performance, and system health.
+The RUM **Explorer** is where you search and analyze the RUM events your applications report: browse complete user session paths, investigate performance issues affecting pages, resources, or actions, troubleshoot errors and long tasks, and aggregate events into charts (see [Analytics](./analytics)).
-## Core Features
+## Select an Application
-<CardGroup cols={2}>
- <Card title="User Session Navigation" icon="route">
- Browse and analyze complete user session paths to understand user behavior patterns within the application
- </Card>
- <Card title="Performance Issue Investigation" icon="gauge-high">
- Deeply analyze performance issues affecting page views, resource loading, or user operations
- </Card>
- <Card title="Application Error Troubleshooting" icon="bug">
- Quickly locate and diagnose application errors and long-running tasks
- </Card>
- <Card title="Data Search & Filtering" icon="filter">
- Precisely filter and select RUM events through the search bar and visualization type selection
- </Card>
- <Card title="Analytics" icon="chart-line" href="./analytics">
- Aggregate RUM events into charts by aggregation and group, and drill from an aggregate down to the raw events
- </Card>
-</CardGroup>
+Use the application selector in the top navigation bar to pick an application; the Explorer then shows only that application's RUM data. Switch applications to switch data views.
-## Value and Benefits
+## Search and Filter
-| Benefit | Description |
-|------|------|
-| **Data-Driven Decisions** | Make product optimization and performance improvement decisions based on real user data |
-| **Quick Problem Location** | Quickly identify performance bottlenecks and user experience issues through visual interface |
-| **User Behavior Insights** | Gain deep understanding of how users interact with your application and discover improvement opportunities |
-| **Comprehensive Monitoring Coverage** | Full-chain monitoring and analysis from page load to user operations |
-
-## Use Cases
-
-<AccordionGroup>
- <Accordion title="Performance Optimization">
- Analyze page load times and resource loading efficiency to identify performance bottlenecks.
- </Accordion>
- <Accordion title="User Experience Improvement">
- Understand user operation paths and discover issues in interaction design.
- </Accordion>
- <Accordion title="Error Troubleshooting">
- Quickly locate the specific scenarios and context where application errors occur.
- </Accordion>
- <Accordion title="Business Analysis">
- Analyze user behavior patterns to provide data support for product feature optimization.
- </Accordion>
-</AccordionGroup>
-
-## Main Features Explained
-
-<Tabs>
- <Tab title="View by Application">
- Use the application selector in the top navigation bar to select a specific application and view all its RUM data.
-
- Through the application selector, you can quickly switch between data views for different applications, focusing on performance and user behavior analysis for specific applications.
- </Tab>
- <Tab title="Search & Filter">
- In the RUM Explorer, you can search and filter RUM events by entering query conditions in the search bar and selecting visualization types.
-
- <Frame>
- <img src="https://docs-cdn.flashcat.cloud/imges/png/bbe48a6dbfeb660ec86ba1e56d580ced.png" alt="Search and Filter" />
- </Frame>
- </Tab>
- <Tab title="View Details">
- Click on data items to view details. RUM events can be displayed from various perspectives to help you discover key information.
-
- - View data relationships, drill down into data, or view parent node details
- - View resource traces and correlate with existing monitoring system traces
-
- For Electron sessions, the event list marks main-process events with a "Main Process" badge (unbadged rows are renderer events), and the event detail panel adds a virtual `process` attribute (`main` / `renderer`) in the Other attribute group to tell the two runtimes apart.
-
- <Frame>
- <img src="https://docs-cdn.flashcat.cloud/imges/png/4e22a5803c1fb290de7093c9ffab7dc6.png" alt="Data Details" />
- </Frame>
- </Tab>
-</Tabs>
+Enter query conditions in the search bar and choose a visualization type to search and filter RUM events. For query syntax, see the [Data Query Guide](./data-query).
+
+<Frame>
+ <img src="https://docs-cdn.flashcat.cloud/imges/png/bbe48a6dbfeb660ec86ba1e56d580ced.png" alt="Search and Filter" />
+</Frame>
+
+## View Event Details
+
+Click a data item to open its details and see the RUM event from several angles:
+
+- View data relationships, drill down into data, or view parent node details
+- View resource traces and correlate with existing monitoring system traces
+
+For Electron sessions, the event list marks main-process events with a "Main Process" badge (unbadged rows are renderer events), and the event detail panel adds a virtual `process` attribute (`main` / `renderer`) in the Other attribute group to tell the two runtimes apart.
+
+<Frame>
+ <img src="https://docs-cdn.flashcat.cloud/imges/png/4e22a5803c1fb290de7093c9ffab7dc6.png" alt="Data Details" />
+</Frame>
## Platform-Aware View Metrics
@@ -96,16 +46,14 @@ When you open the detail panel for a View, the metric cards on the **Performance
The platform is determined by the View event's own `source` field — no manual switching needed. For Mini Programs, `onload_to_onshow` and `onshow_to_onready` cover the two segments of the page lifecycle and help diagnose slow cold starts.
</Note>
-The EventTable column picker also supports the following Mini Program-only fields as queryable columns: `view_first_render`, `view_onload_to_onshow`, `view_onshow_to_onready`.
+The event table column picker can also add these Mini Program-only fields: `view_first_render`, `view_onload_to_onshow`, `view_onshow_to_onready`.
## Saved Views
-The saved views feature allows you to save your current query state as a reusable view for quickly switching between different analysis scenarios. Each account can create up to **20** saved views, and views are only visible to you.
+Save the current query state as a view to switch quickly between analysis scenarios. Each account can create up to **20** saved views, and views are only visible to you.
### What a View Saves
-Each saved view contains the following information:
-
| Saved Item | Description |
|------------|-------------|
| **Time Range** | The currently selected time filter |
@@ -115,26 +63,14 @@ Each saved view contains the following information:
### View Operations
-<Tabs>
- <Tab title="Create View">
- Click the view menu at the top of the Explorer, select "Save as New View", enter a view name, and confirm. View names must be unique.
- </Tab>
- <Tab title="Switch View">
- Click the view menu and select the target view from the list. After switching, the Explorer automatically restores the saved time range, query type, query statement, and column configuration.
- </Tab>
- <Tab title="Edit View">
- In the view list, click the action menu on the right side of the target view and select "Edit View" to modify the view name. If you have modified the current view's query conditions, you can also use "Save Changes" to update the view with the latest state.
- </Tab>
- <Tab title="Delete View">
- Select "Delete View" from the view list or action menu and confirm. After deleting the currently active view, the Explorer automatically switches back to the default view.
- </Tab>
- <Tab title="Copy Shareable Link">
- In the view list, click the action menu on the right side of the target view and select "Copy Link" to get a shareable link for that view. Share the link with team members so they can open the same query view directly.
- </Tab>
- <Tab title="Reset to Default View">
- Select "Switch to Default View" from the action menu to clear all filter conditions and restore the Explorer to its initial state.
- </Tab>
-</Tabs>
+| Action | How |
+|------|------|
+| **Create** | Click the view menu at the top of the Explorer, select "Save as New View", and enter a name (names must be unique) |
+| **Switch** | Click the target view in the view menu; the Explorer restores its time range, query type, query statement, and columns |
+| **Edit** | Select "Edit View" from the target view's action menu to rename it; after changing the current view's query conditions, use "Save Changes" to update the view |
+| **Delete** | Select "Delete View" from the view list or action menu; deleting the active view switches back to the default view |
+| **Share** | Select "Copy Link" from the action menu; team members who open the link see the same query view |
+| **Reset** | Select "Switch to Default View" from the action menu to clear all filters |
## Event Export
diff --git a/en/rum/others/compliance-guide.mdx b/en/rum/others/compliance-guide.mdx
index 77a2a398..6f5bea61 100644
--- a/en/rum/others/compliance-guide.mdx
+++ b/en/rum/others/compliance-guide.mdx
@@ -130,7 +130,7 @@ Personal information collected: device information (model, brand, OS and version
uplink/downlink bandwidth, signal strength), app runtime and crash log information, view access and actions
during app usage, and a randomly generated session identifier
Website: https://flashcat.cloud
-privacy policy: https://docs.flashduty.com/en/compliance/data-security
+privacy policy: /en/compliance/data-security
```
</CodeGroup>
diff --git a/en/rum/others/data-security.mdx b/en/rum/others/data-security.mdx
index 4201048b..5ff49455 100644
--- a/en/rum/others/data-security.mdx
+++ b/en/rum/others/data-security.mdx
@@ -66,14 +66,14 @@ Scenarios where PII may appear in RUM include:
After initializing the RUM application, you can choose whether to include IP or geolocation data in the **User Data Collection** tab.
<Note>
- After disabling IP data collection, changes take effect immediately. Any events collected before disabling will not have IP data removed. This is performed on the backend; the browser SDK still sends data, but IP addresses are omitted and discarded by the Flashduty backend pipeline during processing.
+ After disabling IP data collection, changes take effect immediately. Any events collected before disabling will not have IP data removed. The browser SDK still sends data; IP addresses are discarded when Flashduty processes it on the server side.
</Note>
</Tab>
<Tab title="Geolocation">
In addition to removing client IP, you can also choose to disable collection of geolocation (country, city, county) or GeoIP information from all future collected data.
<Note>
- If you uncheck the **Collect geolocation data** box, changes take effect immediately. Any events collected before disabling will not have corresponding geolocation data removed. Data omission is done at the backend level.
+ If you uncheck the **Collect geolocation data** box, changes take effect immediately. Any events collected before disabling will not have corresponding geolocation data removed. Geolocation data is discarded when Flashduty processes events on the server side.
</Note>
</Tab>
</Tabs>
diff --git a/en/rum/performance/diagnosis-optimization.mdx b/en/rum/performance/diagnosis-optimization.mdx
index 78c89981..ac33825a 100644
--- a/en/rum/performance/diagnosis-optimization.mdx
+++ b/en/rum/performance/diagnosis-optimization.mdx
@@ -1,15 +1,13 @@
---
title: "Diagnosis Guide"
-description: "This document details how to use FlashCat RUM for performance problem diagnosis and optimization."
+description: "Use the optimization page to find why pages load slowly from real user data: pick a metric, compare breakdowns, inspect resources and errors, and analyze event samples."
---
-The optimization page helps identify the root causes of browser performance issues based on real user traffic data. Use browser metrics (such as Core Web Vitals and Flashduty custom loading time metrics) to troubleshoot slow page loading. These metrics can evaluate complete page load time from the user's perspective.
-
-For deeper analysis, the optimization page provides detailed breakdowns of Core Web Vitals by user demographics (such as browser, region, and app version). You can use this information to track performance trends, understand the most affected user groups, and optimize precisely.
+The optimization page uses real user traffic — Core Web Vitals and Flashduty's custom loading-time metrics — to find, from the user's point of view, why pages load slowly. Metrics can be broken down by browser, region, app version, and more, so you can track trends and find the most affected user groups.
## Diagnosis and Optimization Workflow
-You can navigate to the optimization page, located under the Performance Monitoring menu, and select the metric you want to analyze. You can also jump to this feature by viewing corresponding performance data in the analytics dashboard.
+Open the optimization page from the **Performance Monitoring** menu, or jump to it from performance data in an analytics dashboard.
<Steps>
<Step title="Metric Selection">
@@ -27,11 +25,11 @@ You can navigate to the optimization page, located under the Performance Monitor
| **WeChat Mini Program** | `first_render` (First Render), `lcp`, `fcp`, `onload_to_onshow`, `onshow_to_onready` |
<Note>
- The platform is determined by the application's own type, so no manual switching is required. `first_render`, `onload_to_onshow`, and `onshow_to_onready` come from the WeChat Mini Program SDK: `first_render` is the time to first render, while `onload_to_onshow` and `onshow_to_onready` correspond to the two segments of the mini program page lifecycle and help you troubleshoot slow cold starts. After you switch applications, the metric cards refresh to the new platform's metric set, and the tree map (metric view) metric dropdown likewise lists only the metrics available for the current application platform.
+ The platform follows the application type; when you switch applications, the metric cards and the tree map (metric view) dropdown refresh to match. For mini programs, `onload_to_onshow` and `onshow_to_onready` are the two page-lifecycle segments and help diagnose slow cold starts.
</Note>
</Step>
<Step title="Data Viewing">
- You can view the data performance of the metric under different conditions by adjusting the data aggregation method or modifying filter conditions, thereby advancing diagnosis and optimization work.
+ Change the aggregation or filters to compare how the metric behaves under different conditions.
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/65dd3ca92d67ae9175955502d91552dc.png" alt="Data Viewing" />
@@ -78,12 +76,14 @@ You can navigate to the optimization page, located under the Performance Monitor
| AVG START TIME | Average loading start time |
| AVG DURATION | Average loading duration, with a color bar positioned at real time offsets showing each loading phase: redirect, Service Worker, queueing, DNS resolution, connection establishment (including TLS), time to first byte, and download |
+ Hover over the duration bar to see each phase's timing. When one phase takes 50% or more of the time, the card marks it as the **dominant phase** and suggests optimizations, so you can tell whether network connection, server response, or resource size is the bottleneck (TLS is part of connection setup and is never the dominant phase on its own).
+
<Tip>
- Hover over the duration color bar to view the specific timing values for each phase. When one phase accounts for 50% or more of the duration, the card explains the dominant phase and suggests optimizations (TLS is nested inside connection establishment and never becomes the dominant phase alone), helping you determine whether slow loading is caused by network connection, server response, or resource size. If [Link Integration - Built-in Tracing](/en/rum/quickstart/app-management#link-integration) is configured and the resource carries a trace_id, you can drill down to the corresponding trace. When the browser does not expose phase timings (commonly caused by cross-origin responses missing the `Timing-Allow-Origin` header), the bar area shows an "phase timings unavailable" hint.
+ If [Link Integration - Built-in Tracing](/en/rum/quickstart/app-management#link-integration) is configured and the resource carries a trace_id, you can drill down to the corresponding trace. When the browser does not expose phase timings (commonly caused by cross-origin responses missing the `Timing-Allow-Origin` header), the bar area shows **phase timings unavailable**.
</Tip>
</Tab>
<Tab title="Resolve Errors">
- - Focus on recurring errors that may cause problems, as these anomalies also affect page performance
+ Look for recurring errors; they slow pages down too.
</Tab>
<Tab title="Waterfall Chart Analysis">
- The waterfall chart shows the timeline of events when the metric was captured
diff --git a/en/rum/performance/overview.mdx b/en/rum/performance/overview.mdx
index 51e281b1..5999b7c2 100644
--- a/en/rum/performance/overview.mdx
+++ b/en/rum/performance/overview.mdx
@@ -9,7 +9,7 @@ Flashduty RUM (Real User Monitoring) provides powerful tools to help you quickly
<CardGroup cols={2}>
<Card title="Performance Metrics Monitoring" icon="gauge-high">
- Automatically collect and analyze key performance metrics (such as FCP, LCP, CLS, FID, etc.), providing a comprehensive view of performance data
+ Automatically collect and analyze key performance metrics (such as FCP, LCP, CLS, INP, etc.), providing a comprehensive view of performance data
</Card>
<Card title="Resource Loading Analysis" icon="download">
Monitor and analyze the loading performance of static resources (such as JS, CSS, images, etc.) to identify slow-loading resources
@@ -141,20 +141,10 @@ Flashduty RUM performance optimization consists of three key phases:
After locating the root cause, you can implement optimizations based on the analysis results:
-<CardGroup cols={2}>
- <Card title="Slow Page Loading" icon="hourglass">
- Compress resources, optimize critical CSS, enable CDN
- </Card>
- <Card title="Interaction Response Delay" icon="hand-pointer">
- Reduce JavaScript execution time, optimize event listeners
- </Card>
- <Card title="Resource Loading Errors" icon="image">
- Check CDN configuration, ensure correct resource paths
- </Card>
- <Card title="JavaScript Errors" icon="bug">
- Fix code logic, add error boundaries, optimize memory usage
- </Card>
-</CardGroup>
+- **Slow Page Loading**: Compress resources, optimize critical CSS, enable CDN
+- **Interaction Response Delay**: Reduce JavaScript execution time, optimize event listeners
+- **Resource Loading Errors**: Check CDN configuration, ensure correct resource paths
+- **JavaScript Errors**: Fix code logic, add error boundaries, optimize memory usage
## Next Steps
diff --git a/en/rum/quickstart/app-management.mdx b/en/rum/quickstart/app-management.mdx
index bc30e9c8..14cf9b87 100644
--- a/en/rum/quickstart/app-management.mdx
+++ b/en/rum/quickstart/app-management.mdx
@@ -68,7 +68,7 @@ See [Issue Alerts](/en/rum/error-tracking/issue-alerts).
src="https://docs-cdn.flashcat.cloud/videos/rum-app-set-sdk.mov"
></video>
-You can modify parameters and preview the initialization code in real-time in **Application Configuration > SDK Configuration** to quickly integrate the SDK.
+You can modify parameters and preview the initialization code in real-time in **Application Configuration → SDK Configuration** to quickly integrate the SDK.
The console provides detailed integration guides for each platform:
@@ -124,7 +124,7 @@ flashcatRum.init({
### WeChat Mini Program SDK Configuration Assistant
-When the application type is **WeChat Mini Program**, **Application Configuration > SDK Configuration** displays a dedicated Mini Program integration wizard: fill in the form on the left and a ready-to-copy initialization snippet is generated on the right in real time.
+When the application type is **WeChat Mini Program**, **Application Configuration → SDK Configuration** displays a dedicated Mini Program integration wizard: fill in the form on the left and a ready-to-copy initialization snippet is generated on the right in real time.
#### Form Fields
@@ -340,9 +340,9 @@ The repository names shown in the list link to the corresponding repository on G
### How it relates to AI SRE
- Linking a repository **grants no access by itself**. AI sessions in the cloud sandbox can only reach repositories granted to the account's GitHub App installations; manually entered repositories are only meaningful to [BYOC](/en/ai-sre/environments) sessions, which use the host's own credentials.
-- When the account has no GitHub App installation connected, a banner at the top of the page reads "GitHub App is not connected: manually entered repositories only work with local AI agents, and cloud AI sessions cannot read the code." with a **Connect** action that opens **Plugins → Apps**.
-- With a GitHub App connected, any entry outside the granted range shows a warning marker reading "Outside the GitHub App's granted repositories, so cloud AI sessions can't read it. Click to grant it in the GitHub App." — clicking it opens **Plugins → Apps** to grant more repositories to that installation. Members without the **Apps plugin visit** permission see "Outside the GitHub App's granted repositories, so cloud AI sessions can't read it. Ask an administrator to grant it in the GitHub App." instead.
-- If the deployment returns no GitHub App authorization at all (a RUM-only private deployment, for example), the page shows no "not connected" banner and keeps manual entry only.
+- When the account has no GitHub App connected, a banner warns that cloud AI sessions cannot read manually entered repositories and offers a **Connect** entry (**Plugins → Apps**).
+- With a GitHub App connected, repositories outside its granted range carry a warning mark, meaning cloud AI sessions cannot read them. Members with **Apps plugin access** can click the mark to grant more repositories under **Plugins → Apps**; other members need to ask an admin.
+- Deployments without a GitHub App (such as RUM-only private deployments) support manual entry only and show no connection banner.
## Remote Configuration
diff --git a/en/rum/quickstart/faq.mdx b/en/rum/quickstart/faq.mdx
index 97eda803..93685b5f 100644
--- a/en/rum/quickstart/faq.mdx
+++ b/en/rum/quickstart/faq.mdx
@@ -102,12 +102,12 @@ Some ad blocking extensions may block the RUM SDK from running. We recommend add
3. **Check Sampling Rate**: Confirm sampling rate is set appropriately
-```javascript
-flashcatRum.init({
- // ... other configuration
- sessionSampleRate: 100 // Set to 100 to collect all sessions
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... other configuration
+ sessionSampleRate: 100 // Set to 100 to collect all sessions
+ });
+ ```
4. **Check User Consent**: Confirm user tracking consent status
@@ -123,18 +123,18 @@ flashcatRum.setTrackingConsent("granted");
1. **Enable Behavior Tracking**:
-```javascript
-flashcatRum.init({
- // ... other configuration
- trackUserInteractions: true
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... other configuration
+ trackUserInteractions: true
+ });
+ ```
2. **Add Labels to Custom Elements**:
-```html
-<button data-action-name="Submit Form">Submit</button>
-```
+ ```html
+ <button data-action-name="Submit Form">Submit</button>
+ ```
3. **Manually Record Complex Interactions**:
@@ -150,23 +150,23 @@ flashcatRum.addAction("click", "Custom Button Click");
1. **Enable Exception Tracking**:
-```javascript
-flashcatRum.init({
- // ... other configuration
- trackErrors: true
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... other configuration
+ trackErrors: true
+ });
+ ```
2. **Manually Report Exceptions in try-catch**:
-```javascript
-try {
- // Code that might error
-} catch (error) {
- console.error(error);
- flashcatRum.addError(error);
-}
-```
+ ```javascript
+ try {
+ // Code that might error
+ } catch (error) {
+ console.error(error);
+ flashcatRum.addError(error);
+ }
+ ```
3. **Configure Source Map**: For locating issues in production, see [Source Mapping](/en/rum/error-tracking/source-mapping)
</Accordion>
@@ -178,24 +178,24 @@ try {
1. **Only Enable Necessary Features**:
-```javascript
-flashcatRum.init({
- // ... other configuration
- trackResources: true,
- trackLongTasks: false, // Disable unnecessary features
- trackErrors: true,
- trackUserInteractions: true
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... other configuration
+ trackResources: true,
+ trackLongTasks: false, // Disable unnecessary features
+ trackErrors: true,
+ trackUserInteractions: true
+ });
+ ```
2. **Adjust Sampling Rate**:
-```javascript
-flashcatRum.init({
- // ... other configuration
- sessionSampleRate: 50 // Only collect 50% of sessions
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... other configuration
+ sessionSampleRate: 50 // Only collect 50% of sessions
+ });
+ ```
3. **Filter Non-Critical Resources**:
diff --git a/en/rum/sdk/android/advanced-config.mdx b/en/rum/sdk/android/advanced-config.mdx
index 0b95ec23..2c136bee 100644
--- a/en/rum/sdk/android/advanced-config.mdx
+++ b/en/rum/sdk/android/advanced-config.mdx
@@ -214,7 +214,7 @@ GlobalRumMonitor.get().addError(
</Tabs>
<Note>
-For more error reporting details, see [Android Error Reporting](/en/rum/error-tracking/erro-reporting/android).
+For more error reporting details, see [Android Error Reporting](/en/rum/error-tracking/error-reporting/android).
</Note>
### Custom Timing
diff --git a/en/rum/sdk/flutter/advanced-config.mdx b/en/rum/sdk/flutter/advanced-config.mdx
index 24c59070..c9c77b9e 100644
--- a/en/rum/sdk/flutter/advanced-config.mdx
+++ b/en/rum/sdk/flutter/advanced-config.mdx
@@ -18,7 +18,7 @@ DatadogRumConfiguration(
## Remote configuration
-Starting with `flashcat_flutter_plugin` 0.2.0, the session sample rate can be adjusted online from the console under **Application Management > Remote Configuration**, with no code change or new release. The feature is off by default and has to be enabled at initialization:
+Starting with `flashcat_flutter_plugin` 0.2.0, the session sample rate can be adjusted online from the console under **Application Management → Remote Configuration**, with no code change or new release. The feature is off by default and has to be enabled at initialization:
```dart
DatadogRumConfiguration(
diff --git a/en/rum/sdk/ios/advanced-config.mdx b/en/rum/sdk/ios/advanced-config.mdx
index bbf543a2..7c28788b 100644
--- a/en/rum/sdk/ios/advanced-config.mdx
+++ b/en/rum/sdk/ios/advanced-config.mdx
@@ -4,142 +4,170 @@ sidebarTitle: "Advanced Configuration"
description: "Configure advanced features of iOS RUM SDK, including custom events, user tracking, sampling control, and data security"
---
-<Note>
-**About Dependencies and Package Names**
-
-Flashduty iOS SDK is fully compatible with the Datadog open-source protocol. When adding dependencies via Swift Package Manager or CocoaPods, use names like `FlashcatCore` and `FlashcatRUM`, but in code, import modules like `DatadogCore` and `DatadogRUM`. You can seamlessly leverage Datadog ecosystem documentation, examples, and best practices while enjoying Flashduty platform services.
+This page covers advanced use of the iOS RUM SDK: manually tracking views, actions, resources and errors; adding global attributes and user information; modifying or discarding events; sampling and remote configuration; and correlating with distributed tracing.
+<Note>
+The SDK is compatible with the Datadog open-source protocol. Dependencies added via Swift Package Manager or CocoaPods use names like `FlashcatCore` and `FlashcatRUM`, while code imports modules like `DatadogCore` and `DatadogRUM`, so Datadog ecosystem docs and examples apply directly.
</Note>
-Flashduty iOS RUM SDK provides rich advanced configuration options to help you customize data collection and context information based on business needs.
-
-<Info>
-**Supported Configuration Scenarios:**
-- Enrich user sessions - Add custom views, actions, resources, and error information
-- Protect sensitive data - Mask personally identifiable information and sensitive data
-- Associate user sessions - Link user sessions with internal user identifiers
-- Control data volume - Optimize data collection through sampling and event filtering
-- Enhance context - Add custom attributes to data
-</Info>
-
## Enrich User Sessions
### Custom Views
-In addition to auto-tracked views, you can manually track custom views:
+By default, the RUM SDK automatically tracks `UIViewController` and SwiftUI `View`. You can also track specific views manually, or add custom attributes to automatically tracked views.
+
+<Note>
+Call `RUMMonitor.shared().startView()` to start tracking a new RUM view. All views with the same `key` are grouped together in the RUM Explorer.
+</Note>
<Tabs>
<Tab title="Swift">
```swift
import DatadogRUM
-// Start tracking view
-RUMMonitor.shared().startView(
- key: "view-key",
- name: "View Name",
- attributes: [:]
-)
+// In your UIViewController
+override func viewDidAppear(_ animated: Bool) {
+ super.viewDidAppear(animated)
+ RUMMonitor.shared().startView(
+ key: "view-key",
+ name: "View Name",
+ attributes: ["foo": "bar"]
+ )
+}
-// Stop tracking view
-RUMMonitor.shared().stopView(
- key: "view-key",
- attributes: [:]
-)
+override func viewDidDisappear(_ animated: Bool) {
+ super.viewDidDisappear(animated)
+ RUMMonitor.shared().stopView(
+ key: "view-key",
+ attributes: ["foo": "bar"]
+ )
+}
```
</Tab>
<Tab title="Objective-C">
-```objectivec
-@import DatadogRUM;
-
-// Start tracking view
-[[RUMMonitor shared] startViewWithKey:@"view-key"
- name:@"View Name"
- attributes:@{}];
+```objective-c
+@import DatadogObjc;
-// Stop tracking view
-[[RUMMonitor shared] stopViewWithKey:@"view-key"
- attributes:@{}];
+// In your UIViewController
+- (void)viewDidAppear:(BOOL)animated {
+ [super viewDidAppear:animated];
+ [[RUMMonitor shared] startViewWithKey:@"view-key"
+ name:@"View Name"
+ attributes:@{@"foo": @"bar"}];
+}
+
+- (void)viewDidDisappear:(BOOL)animated {
+ [super viewDidDisappear:animated];
+ [[RUMMonitor shared] stopViewWithKey:@"view-key"
+ attributes:@{@"foo": @"bar"}];
+}
```
</Tab>
</Tabs>
<Note>
-**Parameter Description:**
-- `key` (String) - Unique identifier for the view, same key used for `startView` and `stopView`
+**Parameters:**
+- `key` (String) - Unique identifier for the view; use the same key for `startView` and `stopView`
- `name` (String) - Name of the view
- `attributes` (Dictionary) - Attributes attached to the view (optional)
</Note>
### Custom Actions
-Track specific custom user actions:
+In addition to automatically tracked user actions, you can manually track specific custom actions (taps, scrolls, swipes, and so on).
<Tabs>
<Tab title="Swift">
```swift
import DatadogRUM
-RUMMonitor.shared().addAction(
- type: .tap,
- name: "Button Tapped",
- attributes: ["button_id": "submit"]
-)
+// In your UIViewController
+@IBAction func didTapDownloadResourceButton(_ sender: UIButton) {
+ RUMMonitor.shared().addAction(
+ type: .tap,
+ name: sender.currentTitle ?? "",
+ attributes: ["resource_id": "123"]
+ )
+}
```
</Tab>
<Tab title="Objective-C">
-```objectivec
-@import DatadogRUM;
+```objective-c
+@import DatadogObjc;
-[[RUMMonitor shared] addActionWithType:RUMActionTypeTap
- name:@"Button Tapped"
- attributes:@{@"button_id": @"submit"}];
+- (IBAction)didTapDownloadResourceButton:(UIButton *)sender {
+ [[RUMMonitor shared] addActionWithType:RUMActionTypeTap
+ name:sender.currentTitle
+ attributes:@{@"resource_id": @"123"}];
+}
```
</Tab>
</Tabs>
+<Note>
+When you call `addAction()`, the RUM SDK creates a RUM action and attaches all new resources, errors, and long tasks to it until the view is considered fully loaded.
+</Note>
+
### Custom Resources
-Manually track specific custom resources:
+The Flashduty iOS SDK automatically tracks network requests made through an instrumented `URLSession`. You can also track custom resources manually (third-party APIs, GraphQL queries, and so on).
<Tabs>
<Tab title="Swift">
```swift
import DatadogRUM
-// Start resource tracking
+// In your network client
RUMMonitor.shared().startResource(
resourceKey: "resource-key",
- httpMethod: .get,
- urlString: "https://api.example.com/data",
- attributes: [:]
+ request: request,
+ attributes: ["foo": "bar"]
)
-// Stop resource tracking (success)
+// On success
RUMMonitor.shared().stopResource(
resourceKey: "resource-key",
- statusCode: 200,
- kind: .native,
- size: 1024,
- attributes: [:]
+ response: response,
+ size: size,
+ attributes: ["foo": "bar"]
)
-// Stop resource tracking (error)
+// On failure
RUMMonitor.shared().stopResourceWithError(
resourceKey: "resource-key",
- message: "Network error",
- type: "NetworkError",
- response: nil,
- attributes: [:]
+ error: error,
+ attributes: ["foo": "bar"]
)
```
</Tab>
+
+<Tab title="Objective-C">
+```objective-c
+@import DatadogObjc;
+
+// In your network client
+[[RUMMonitor shared] startResourceWithResourceKey:@"resource-key"
+ request:request
+ attributes:@{@"foo": @"bar"}];
+
+// On success
+[[RUMMonitor shared] stopResourceWithResourceKey:@"resource-key"
+ response:response
+ size:size
+ attributes:@{@"foo": @"bar"}];
+```
+</Tab>
</Tabs>
+<Warning>
+The `resourceKey` must be unique per call so the RUM iOS SDK can match a resource's start with its completion.
+</Warning>
+
### Custom Errors
-Record specific errors:
+To track a specific error, notify `RUMMonitor` when it happens:
<Tabs>
<Tab title="Swift">
@@ -147,35 +175,73 @@ Record specific errors:
import DatadogRUM
RUMMonitor.shared().addError(
- message: "Network request failed",
- type: "NetworkError",
- source: .network,
- attributes: [
- "url": "https://api.example.com",
- "status_code": 500
- ]
+ message: "Error message",
+ type: "ErrorType",
+ source: .source,
+ stack: "Error stack trace",
+ attributes: ["foo": "bar"],
+ file: #file,
+ line: #line
)
```
</Tab>
<Tab title="Objective-C">
-```objectivec
-@import DatadogRUM;
+```objective-c
+@import DatadogObjc;
+
+[[RUMMonitor shared] addErrorWithMessage:@"Error message"
+ type:@"ErrorType"
+ source:DDRUMErrorSourceCustom
+ stack:@"Error stack trace"
+ attributes:@{@"foo": @"bar"}
+ file:file
+ line:line];
+```
+</Tab>
+</Tabs>
+
+<Note>
+For more on error reporting, see [iOS Error Reporting](/en/rum/error-tracking/error-reporting/ios).
+</Note>
+
+## Track Custom Global Attributes
+
+Besides the default attributes the SDK captures, you can add custom global attributes to every RUM event. Use them to filter and group by business information (cart value, user tier, ad campaign) and to compare performance and error distribution across user groups.
+
+<Tabs>
+<Tab title="Swift">
+```swift
+import DatadogRUM
+
+// Add a global attribute
+RUMMonitor.shared().addAttribute(forKey: "user_plan", value: "premium")
+
+// Remove a global attribute
+RUMMonitor.shared().removeAttribute(forKey: "user_plan")
+```
+</Tab>
+
+<Tab title="Objective-C">
+```objective-c
+@import DatadogObjc;
-[[RUMMonitor shared] addErrorWithMessage:@"Network request failed"
- type:@"NetworkError"
- source:RUMErrorSourceNetwork
- attributes:@{
- @"url": @"https://api.example.com",
- @"status_code": @500
- }];
+// Add a global attribute
+[[RUMMonitor shared] addAttributeForKey:@"user_plan" value:@"premium"];
+
+// Remove a global attribute
+[[RUMMonitor shared] removeAttributeForKey:@"user_plan"];
```
</Tab>
</Tabs>
-### Set User Information
+<Warning>
+**Reserved keys:** the following keys are used internally by the SDK and cannot be used: `date`, `error.kind`, `error.message`, `error.stack`, `error.source_type`, `view.id`, `view.url`, `view.loading_time`, `view.referrer`, `application.id`
+</Warning>
-Set user information for the current session:
+## Track User Sessions
+
+Adding user information to RUM sessions lets you follow a specific user's journey and see which users are most affected by errors.
<Tabs>
<Tab title="Swift">
@@ -183,20 +249,20 @@ Set user information for the current session:
import DatadogCore
Datadog.setUserInfo(
- id: "user-123",
+ id: "1234",
name: "John Doe",
- email: "john.doe@example.com"
+ email: "john@doe.com"
)
```
</Tab>
<Tab title="Objective-C">
-```objectivec
-@import DatadogCore;
+```objective-c
+@import DatadogObjc;
-[DDDatadog setUserInfoWithId:@"user-123"
+[DDDatadog setUserInfoWithId:@"1234"
name:@"John Doe"
- email:@"john.doe@example.com"
+ email:@"john@doe.com"
extraInfo:nil];
```
</Tab>
@@ -206,50 +272,429 @@ Datadog.setUserInfo(
Only standard user fields are supported: `id`, `name`, `email`, and `anonymous_id`. Other user attributes are not supported. If needed, configure them under `context`.
</Warning>
-## Event and Data Management
+<Note>
+**Parameters:**
+- `usr.id` (String) - Unique user identifier
+- `usr.name` (String) - User-friendly name, displayed by default in the RUM UI
+- `usr.email` (String) - User email, displayed when no name is set
+- All attributes are optional; provide at least one
+</Note>
-### Clear All Data
+## Track Background Events
-Clear all unsent data currently stored in the SDK:
+You can track events that happen while the app runs in the background (such as crashes and network requests).
<Tabs>
<Tab title="Swift">
```swift
-import DatadogCore
+import DatadogRUM
-Datadog.clearAllData()
+RUM.enable(
+ with: RUM.Configuration(
+ applicationID: "<RUM_APPLICATION_ID>",
+ trackBackgroundEvents: true
+ )
+)
```
</Tab>
<Tab title="Objective-C">
-```objectivec
-@import DatadogCore;
+```objective-c
+@import DatadogObjc;
-[DDDatadog clearAllData];
+DDRUMConfiguration *configuration = [[DDRUMConfiguration alloc]
+ initWithApplicationID:@"<RUM_APPLICATION_ID>"];
+configuration.trackBackgroundEvents = YES;
+
+[RUM enableWith:configuration];
```
</Tab>
</Tabs>
+<Warning>
+Tracking background events may create additional sessions, which can affect billing. If you have questions, contact Flashduty support.
+</Warning>
+
+## Initialization Parameters
+
+You can set the following properties when creating the SDK configuration:
+
+<AccordionGroup>
+
+<Accordion title="Datadog core configuration">
+
+| Parameter | Type | Required | Description |
+|------|------|------|------|
+| `clientToken` | String | ✅ | Client token |
+| `env` | String | ✅ | Environment name (for example `production`, `staging`) |
+| `service` | String | Optional | Service name; defaults to the app bundle identifier |
+| `batchSize` | BatchSize | Optional | Upload batch size (`.small`, `.medium`, `.large`) |
+| `uploadFrequency` | UploadFrequency | Optional | Upload frequency (`.frequent`, `.average`, `.rare`) |
+
+</Accordion>
+
+<Accordion title="RUM configuration">
+
+| Parameter | Type | Required | Description |
+| --- | --- | --- | --- |
+| `applicationID` | String | Yes | RUM application ID |
+| `sessionSampleRate` | Float | No | Session sample rate (0–100), default 100 |
+| `uiKitViewsPredicate` | UIKitRUMViewsPredicate | No | UIKit view tracking strategy |
+| `uiKitActionsPredicate` | UIKitRUMActionsPredicate | No | UIKit action tracking strategy |
+| `swiftUIViewsPredicate` | SwiftUIRUMViewsPredicate | No | SwiftUI view tracking strategy |
+| `swiftUIActionsPredicate` | SwiftUIRUMActionsPredicate | No | SwiftUI action tracking strategy |
+| `urlSessionTracking` | URLSessionTracking | No | URLSession network request tracking configuration |
+| `trackBackgroundEvents` | Bool | No | Whether to track background events, default `false` |
+| `trackFrustrations` | Bool | No | Whether to track user frustration (such as error taps), default `true` |
+| `trackLongTasks` | Bool | No | Whether to track long tasks, default `true` |
+| `longTaskThreshold` | TimeInterval | No | Long task threshold in seconds, default 0.1 |
+| `appHangThreshold` | TimeInterval? | No | App Hang detection threshold in seconds; **defaults to `nil` (off)**, see below |
+| `vitalsUpdateFrequency` | VitalsFrequency | No | Vitals update frequency: `.frequent`, `.average`, `.rare`, `.never` |
+
+</Accordion>
+
+</AccordionGroup>
+
+### App Hang Detection
+
+An App Hang is a period during which the main thread is blocked and the UI cannot respond to user input. On iOS it is the only data source behind the **Unresponsive Time Rate** metric in the analytics dashboard.
+
+<Warning>
+`appHangThreshold` **defaults to `nil`, which means App Hang detection is off**. Unless you set it explicitly, your iOS app reports no App Hang data and the "Unresponsive Time Rate" card stays empty.
+</Warning>
+
+```swift
+RUM.enable(
+ with: RUM.Configuration(
+ applicationID: "<RUM_APPLICATION_ID>",
+ appHangThreshold: 0.25 // Record main-thread blocks longer than 250ms
+ )
+)
+```
+
+Notes:
+
+- The minimum allowed value is `0.1` seconds; lower values are raised to 0.1 automatically. For production, **0.25–0.5 seconds** is recommended, as a lower threshold produces a lot of noise.
+- The SDK detects hangs with a 2.5% tolerance, so hangs lasting very close to the threshold may not be reported.
+- Enable crash reporting as well, otherwise App Hang errors are reported without a stack trace.
+- An App Hang that never recovers, and ends with the system terminating the app, is recorded as a fatal error: it counts toward the crash count and lowers the crash-free rate. Non-fatal hangs are recorded as errors with `error.category = App Hang`.
+- Android has no equivalent option: its main-thread freeze threshold is fixed at 5 seconds.
+
+### Automatically Track Views
+
+To track views automatically, set `uiKitViewsPredicate` or `swiftUIViewsPredicate` when initializing RUM.
+
+For **UIKit**, use the `DefaultUIKitRUMViewsPredicate` class:
+
+```swift
+import DatadogRUM
+
+RUM.enable(
+ with: RUM.Configuration(
+ applicationID: "<RUM_APPLICATION_ID>",
+ uiKitViewsPredicate: DefaultUIKitRUMViewsPredicate()
+ )
+)
+```
+
+For **SwiftUI**, use the `DefaultSwiftUIRUMViewsPredicate` class:
+
+```swift
+import DatadogRUM
+
+RUM.enable(
+ with: RUM.Configuration(
+ applicationID: "<RUM_APPLICATION_ID>",
+ swiftUIViewsPredicate: DefaultSwiftUIRUMViewsPredicate()
+ )
+)
+```
+
+You can also implement a custom `predicate` to customize tracking behavior.
+
+### Automatically Track User Actions
+
+To track user actions automatically, set `uiKitActionsPredicate` or `swiftUIActionsPredicate` when initializing RUM.
+
+For **UIKit**:
+
+```swift
+import DatadogRUM
+
+RUM.enable(
+ with: RUM.Configuration(
+ applicationID: "<RUM_APPLICATION_ID>",
+ uiKitActionsPredicate: DefaultUIKitRUMActionsPredicate()
+ )
+)
+```
+
+For **SwiftUI**:
+
+```swift
+import DatadogRUM
+
+RUM.enable(
+ with: RUM.Configuration(
+ applicationID: "<RUM_APPLICATION_ID>",
+ swiftUIActionsPredicate: DefaultSwiftUIRUMActionsPredicate(isLegacyDetectionEnabled: true)
+ )
+)
+```
+
+### Automatically Track Network Requests
+
+To track network requests (resources and errors) automatically, set `urlSessionTracking` when initializing RUM and enable `URLSessionInstrumentation`:
+
+```swift
+import DatadogRUM
+
+RUM.enable(
+ with: RUM.Configuration(
+ applicationID: "<RUM_APPLICATION_ID>",
+ urlSessionTracking: RUM.Configuration.URLSessionTracking()
+ )
+)
+
+URLSessionInstrumentation.enable(
+ with: .init(
+ delegateClass: SessionDelegate.self
+ )
+)
+```
+
+To correlate RUM resources with backend traces, configure `firstPartyHostsTracing`; see [Integrate RUM with Distributed Tracing](#integrate-rum-with-distributed-tracing).
+
+### Automatically Track Errors
+
+All fatal and non-fatal iOS errors are collected automatically, with full error details and the metadata of the current RUM view attached.
+
+Fatal errors include app crashes. Non-fatal errors include:
+
+- **Swift errors**: errors thrown with Swift `throw`
+- **Objective-C exceptions**: Objective-C exceptions
+
+View error details in the RUM Explorer and Error Tracking.
+
+## Modify or Discard RUM Events
+
+Before RUM events are sent to Flashduty, you can modify them or drop them entirely with event mappers, which you set when creating the RUM configuration:
+
+```swift
+import DatadogRUM
+
+let configuration = RUM.Configuration(
+ applicationID: "<RUM_APPLICATION_ID>",
+ viewEventMapper: { RUMViewEvent in
+ return RUMViewEvent
+ },
+ errorEventMapper: { RUMErrorEvent in
+ return RUMErrorEvent
+ },
+ resourceEventMapper: { RUMResourceEvent in
+ return RUMResourceEvent
+ },
+ actionEventMapper: { RUMActionEvent in
+ return RUMActionEvent
+ },
+ longTaskEventMapper: { RUMLongTaskEvent in
+ return RUMLongTaskEvent
+ }
+)
+
+RUM.enable(with: configuration)
+```
+
+```objective-c
+@import DatadogObjc;
+
+DDRUMConfiguration *configuration = [[DDRUMConfiguration alloc] initWithApplicationID:@"<RUM_APPLICATION_ID>"];
+
+[configuration setViewEventMapper:^DDRUMViewEvent * _Nonnull(DDRUMViewEvent * _Nonnull RUMViewEvent) {
+ return RUMViewEvent;
+}];
+
+[configuration setErrorEventMapper:^DDRUMErrorEvent * _Nullable(DDRUMErrorEvent * _Nonnull RUMErrorEvent) {
+ return RUMErrorEvent;
+}];
+
+[configuration setResourceEventMapper:^DDRUMResourceEvent * _Nullable(DDRUMResourceEvent * _Nonnull RUMResourceEvent) {
+ return RUMResourceEvent;
+}];
+
+[configuration setActionEventMapper:^DDRUMActionEvent * _Nullable(DDRUMActionEvent * _Nonnull RUMActionEvent) {
+ return RUMActionEvent;
+}];
+
+[configuration setLongTaskEventMapper:^DDRUMLongTaskEvent * _Nullable(DDRUMLongTaskEvent * _Nonnull RUMLongTaskEvent) {
+ return RUMLongTaskEvent;
+}];
+```
+
+Each mapper is a Swift closure with the signature `(T) -> T?`, where `T` is the concrete RUM event type. This lets you change parts of an event before it is sent.
+
+For example, to redact sensitive information in a RUM resource's `url`, implement a custom `redacted(_:) -> String` function and use it in `resourceEventMapper`:
+
+```swift
+let configuration = RUM.Configuration(
+ applicationID: "<RUM_APPLICATION_ID>",
+ resourceEventMapper: { RUMResourceEvent in
+ var RUMResourceEvent = RUMResourceEvent
+ RUMResourceEvent.resource.url = redacted(RUMResourceEvent.resource.url)
+ return RUMResourceEvent
+ }
+)
+```
+
+```objective-c
+DDRUMConfiguration *configuration = [[DDRUMConfiguration alloc] initWithApplicationID:@"<RUM_APPLICATION_ID>"];
+
+[configuration setResourceEventMapper:^DDRUMResourceEvent * _Nullable(DDRUMResourceEvent * _Nonnull RUMResourceEvent) {
+ return RUMResourceEvent;
+}];
+```
+
+Returning `nil` from the error, resource, or action mapper drops the event entirely; it is not sent to Flashduty. The view event mapper must not return `nil` (to drop a view, customize your `UIKitRUMViewsPredicate` implementation; see [Automatically Track Views](#automatically-track-views)). For example, to drop actions whose target name contains "password":
+
+```swift
+actionEventMapper: { actionEvent in
+ if actionEvent.action.target?.name?.contains("password") == true {
+ return nil // Discard this event
+ }
+ return actionEvent
+}
+```
+
+Depending on the event type, only certain attributes can be modified:
+
+| Event type | Attribute key | Description |
+| --- | --- | --- |
+| RUMActionEvent | `RUMActionEvent.action.target?.name` | Action name |
+| | `RUMActionEvent.view.url` | URL of the view linked to this action |
+| RUMErrorEvent | `RUMErrorEvent.error.message` | Error message |
+| | `RUMErrorEvent.error.stack` | Error stack trace |
+| | `RUMErrorEvent.error.resource?.url` | URL of the resource the error refers to |
+| | `RUMErrorEvent.view.url` | URL of the view linked to this error |
+| RUMResourceEvent | `RUMResourceEvent.resource.url` | Resource URL |
+| | `RUMResourceEvent.view.url` | URL of the view linked to this resource |
+| RUMViewEvent | `RUMViewEvent.view.name` | View name |
+| | `RUMViewEvent.view.url` | View URL |
+| | `RUMViewEvent.view.referrer` | URL that linked to the initial view of the page |
+
+## Get the RUM Session ID
+
+The RUM session ID is useful for troubleshooting. For example, attach it to support requests, emails, or bug reports so your support team can find the user's session in Flashduty later.
+
+You can read the session ID at runtime without waiting for the `sessionStarted` event:
+
+```swift
+import DatadogRUM
+
+RUMMonitor.shared().currentSessionID(completion: { sessionId in
+ currentSessionId = sessionId
+})
+```
+
+```objective-c
+@import DatadogObjc;
+
+[[RUMMonitor shared] currentSessionIDWithCompletion:^(NSString * _Nullable sessionId) {
+ // use session ID
+}];
+```
+
+## Set Tracking Consent (GDPR Compliance)
+
+To comply with GDPR, the Flashduty iOS SDK requires a tracking consent value at initialization. `trackingConsent` can be one of:
+
+| Value | Behavior |
+| --- | --- |
+| `.pending` | The SDK collects and batches data but does not send it to Flashduty; it waits for a new consent value to decide what to do with the batched data |
+| `.granted` | The SDK collects data and sends it to Flashduty |
+| `.notGranted` | The SDK collects no data; no logs, traces, or RUM events are sent |
+
+To change the consent value after initialization, call `Datadog.set(trackingConsent:)`. The SDK changes its behavior accordingly. For example, if the current consent is `.pending`:
+
+- changing it to `.granted` sends all current and future data to Flashduty;
+- changing it to `.notGranted` wipes all current data and stops collecting future data.
+
+```swift
+import DatadogCore
+
+Datadog.set(trackingConsent: .granted)
+```
+
+```objective-c
+@import DatadogObjc;
+
+[DDDatadog setWithTrackingConsent:DDTrackingConsentGranted];
+```
+
+## Data Management
+
+### Clear All Data
+
+Delete all unsent data stored by the SDK with the `Datadog.clearAllData()` API:
+
+```swift
+import DatadogCore
+
+Datadog.clearAllData()
+```
+
+```objective-c
+@import DatadogObjc;
+
+[DDDatadog clearAllData];
+```
+
+### Stop Data Collection
+
+Use the `Datadog.stopInstance()` API to stop a named SDK instance (or the default instance if the name is `nil`) from collecting and uploading further data.
+
+```swift
+import DatadogCore
+
+Datadog.stopInstance()
+```
+
+```objective-c
+@import DatadogObjc;
+
+[DDDatadog stopInstance];
+```
+
+Calling this disables the SDK and all active features such as RUM. To resume collection, you must initialize the SDK again. Use this API if you want to change the configuration dynamically.
+
## Sampling
-Control the percentage of sessions that collect RUM data:
+By default, RUM collects data for all sessions. Set a sample rate (percentage) with `sessionSampleRate` to reduce the number of sessions collected. For example, to collect 90% of sessions:
```swift
+import DatadogRUM
+
RUM.enable(
with: RUM.Configuration(
applicationID: "<RUM_APPLICATION_ID>",
- sessionSampleRate: 80 // Collect 80% of sessions
+ sessionSampleRate: 90
)
)
```
-<Warning>
-Sampled-out sessions will not collect any page views or related telemetry data.
-</Warning>
+```objective-c
+@import DatadogObjc;
+
+DDRUMConfiguration *configuration = [[DDRUMConfiguration alloc] initWithApplicationID:@"<RUM_APPLICATION_ID>"];
+configuration.sessionSampleRate = 90;
+
+[RUM enableWith:configuration];
+```
+
+Sampled-out sessions collect no views or related telemetry.
## Remote Configuration
-Starting with SDK 0.6.0, the session sample rate can be adjusted online from the console under **Application Management > Remote Configuration**, with no code change or new release. The feature is off by default and has to be enabled at initialization:
+Starting with SDK 0.6.0, the session sample rate can be adjusted online from the console under **Application Management → Remote Configuration**, with no code change or new release. The feature is off by default and has to be enabled at initialization:
```swift
import DatadogRUM
@@ -298,130 +743,105 @@ To collect the current user regardless of the sample rate (for example while inv
For the console side (settings, publishing and when a version takes effect), see [Application Management · Remote Configuration](/en/rum/quickstart/app-management#remote-configuration).
-## App Hang Detection
+## Integrate RUM with Distributed Tracing
-An App Hang is a period during which the main thread is blocked and the UI cannot respond to user input. On iOS it is the only data source behind the **Unresponsive Time Rate** metric in the analytics dashboard.
+Correlating requests from your iOS app with their backend traces lets you see the frontend experience together with backend, infrastructure, and log information in one place, so you can pinpoint where a problem is.
-<Warning>
-`appHangThreshold` **defaults to `nil`, which means App Hang detection is off**. Unless you set it explicitly, your iOS app reports no App Hang data and the "Unresponsive Time Rate" card stays empty.
-</Warning>
+### Configuration
+
+Initialize the RUM SDK and use `firstPartyHostsTracing` to list your app's API domains:
```swift
+import DatadogRUM
+
RUM.enable(
with: RUM.Configuration(
applicationID: "<RUM_APPLICATION_ID>",
- appHangThreshold: 0.25 // Record main-thread blocks longer than 250ms
+ urlSessionTracking: RUM.Configuration.URLSessionTracking(
+ firstPartyHostsTracing: .trace(
+ hosts: [
+ "api.example.com",
+ "example.com"
+ ],
+ sampleRate: 20
+ )
+ )
)
)
-```
-Notes:
+URLSessionInstrumentation.enable(
+ with: .init(
+ delegateClass: SessionDelegate.self
+ )
+)
+```
-- The minimum allowed value is `0.1` seconds; lower values are raised to 0.1 automatically. For production, **0.25–0.5 seconds** is recommended, as a lower threshold produces a lot of noise.
-- The SDK detects hangs with a 2.5% tolerance, so hangs lasting very close to the threshold may not be reported.
-- Enable crash reporting as well, otherwise App Hang errors are reported without a stack trace.
-- An App Hang that never recovers, and ends with the system terminating the app, is recorded as a fatal error: it counts toward the crash count and lowers the crash-free rate. Non-fatal hangs are recorded as errors with `error.category = App Hang`.
-- Android has no equivalent option: its main-thread freeze threshold is fixed at 5 seconds.
+```objective-c
+@import DatadogObjc;
-## User Tracking Consent
+DDRUMConfiguration *configuration = [[DDRUMConfiguration alloc] initWithApplicationID:@"<RUM_APPLICATION_ID>"];
-To comply with privacy regulations like GDPR and CCPA, you can set user tracking consent state:
+DDURLSessionTracking *urlSessionTracking = [DDURLSessionTracking new];
+[urlSessionTracking setFirstPartyHostsTracing:[DDRUMFirstPartyHostsTracing alloc] initWithHosts:@[@"api.example.com", @"example.com"] sampleRate:20];
-```swift
-// Set consent state during initialization
-Datadog.initialize(
- with: configuration,
- trackingConsent: .pending
-)
+configuration.urlSessionTracking = urlSessionTracking;
-// Update consent state when user grants permission
-Datadog.set(trackingConsent: .granted)
+[RUM enableWith:configuration];
-// Update consent state when user revokes permission
-Datadog.set(trackingConsent: .notGranted)
+[DDURLSessionInstrumentation enableWithConfiguration:[DDURLSessionInstrumentationConfiguration alloc] initWithDelegateClass:[SessionDelegate class]]];
```
-| State | Behavior |
-|-------|----------|
-| `.granted` | Start collecting data and send to Flashduty |
-| `.notGranted` | Do not collect any data |
-| `.pending` | Collect but do not send, wait for user decision |
+**Parameters:**
-## Global Context
+- `hosts`: list of domains to trace
+- `sampleRate`: percentage of requests to trace (0–100), default 100
-Add global context attributes that will be attached to all RUM events:
+### How Correlation Works
-<Tabs>
-<Tab title="Swift">
-```swift
-import DatadogRUM
+The distributed tracing protocol adds the `traceparent` and `tracestate` HTTP headers:
+
+```
+traceparent: [version]-[trace id]-[parent id]-[trace flags]
+```
-// Add attribute
-RUMMonitor.shared().addAttribute(forKey: "user_type", value: "premium")
+- `version`: currently `00`
+- `trace id`: 128-bit trace ID, hex-encoded to 32 characters
+- `parent id`: 64-bit span ID, hex-encoded to 16 characters
+- `trace flags`: whether the trace is sampled; `01` means sampled, `00` means not sampled
-// Remove attribute
-RUMMonitor.shared().removeAttribute(forKey: "user_type")
```
-</Tab>
+tracestate: dd=s:[sampling priority];o:[origin]
+```
-<Tab title="Objective-C">
-```objectivec
-@import DatadogRUM;
+- `sampling priority`: `1` means the trace is sampled
+- `origin`: always `rum`, meaning collected by the RUM SDK
-// Add attribute
-[[RUMMonitor shared] addAttributeForKey:@"user_type" value:@"premium"];
+**Example:**
-// Remove attribute
-[[RUMMonitor shared] removeAttributeForKey:@"user_type"];
```
-</Tab>
-</Tabs>
+traceparent: 00-00000000000000008448eb211c80319c-b7ad6b7169203331-01
+tracestate: dd=s:1;o:rum
+```
-## Event Mappers
+### Verification
-Use Event Mappers to modify or filter events before they are sent:
+After adding the configuration, inspect requests sent from your app in Xcode's network debugging tools or a proxy (such as Charles or Proxyman). If they carry these headers, the configuration is correct.
-```swift
-RUM.enable(
- with: RUM.Configuration(
- applicationID: "<RUM_APPLICATION_ID>",
- viewEventMapper: { viewEvent in
- // Modify view event
- var modifiedEvent = viewEvent
- modifiedEvent.view.url = viewEvent.view.url?.replacingOccurrences(of: "sensitive", with: "redacted")
- return modifiedEvent
- },
- actionEventMapper: { actionEvent in
- // Filter specific actions
- if actionEvent.action.target?.name?.contains("password") == true {
- return nil // Discard this event
- }
- return actionEvent
- },
- errorEventMapper: { errorEvent in
- // Modify error event
- return errorEvent
- },
- resourceEventMapper: { resourceEvent in
- // Modify resource event
- return resourceEvent
- }
- )
-)
-```
+## Best Practices
-<Warning>
-View events cannot be discarded (returning nil has no effect).
-</Warning>
+- Make sure `applicationID` and `clientToken` are configured correctly, or data cannot be uploaded.
+- Tune the sample rate and privacy settings to your app's needs to balance data volume and compliance.
+- In event mappers, only modify the attributes listed as modifiable above.
+- For complex view tracking scenarios, implement a custom `ViewsPredicate`.
## Related Documentation
<CardGroup cols={3}>
<Card title="SDK Integration" icon="plug" href="/en/rum/sdk/ios/sdk-integration">
- Learn how to quickly integrate the RUM SDK
+ Learn how to integrate the iOS SDK
</Card>
<Card title="Data Collection" icon="database" href="/en/rum/sdk/ios/data-collection">
- Learn about data types and attributes collected by the SDK
+ Learn about the data types the SDK collects
</Card>
<Card title="Compatibility" icon="check" href="/en/rum/sdk/ios/compatible">
Learn about SDK compatibility requirements
diff --git a/en/rum/sdk/ios/data-collection.mdx b/en/rum/sdk/ios/data-collection.mdx
index ab7efb01..52c98423 100644
--- a/en/rum/sdk/ios/data-collection.mdx
+++ b/en/rum/sdk/ios/data-collection.mdx
@@ -204,6 +204,9 @@ Different event types have specific attributes and metrics.
| `resource.first_byte.duration` | Number (ns) | Time waiting for first byte response (responseStart - requestStart) |
| `resource.download.duration` | Number (ns) | Time to download response (responseEnd - responseStart) |
| `resource.redirect.duration` | Number (ns) | Time for subsequent HTTP requests (redirectEnd - redirectStart) |
+| `resource.provider.name` | String | Resource provider name, defaults to `unknown` |
+| `resource.provider.domain` | String | Resource provider domain |
+| `resource.provider.type` | String | Resource provider type (e.g., `first-party`, `cdn`, `ad`, `analytics`) |
</Accordion>
@@ -216,7 +219,22 @@ Different event types have specific attributes and metrics.
| `error.source` | String | Error source (e.g., `network`, `source`, `console`, `webview`) |
| `error.stack` | String | Error stack trace or supplementary information |
| `error.type` | String | Error type or error code |
+| `error.issue_id` | String | Unique identifier of the error issue |
+| `error.category` | String | High-level grouping of the error type. Possible values: `ANR`, `App Hang`, `Exception`, `Watchdog Termination`, `Memory Warning`, `Network` |
+| `error.file` | String | File in which error tracking found the issue |
| `error.is_crash` | Boolean | Whether this error caused app crash |
+| `freeze.duration` | Number (ns) | Duration of the main-thread freeze (App Hang only) |
+
+**Network errors** carry information about the failed HTTP request in these additional attributes:
+
+| Attribute | Type | Description |
+|-----------|------|-------------|
+| `error.resource.status_code` | Number | HTTP response status code |
+| `error.resource.method` | String | HTTP method (e.g., `GET`, `POST`) |
+| `error.resource.url` | String | Resource URL |
+| `error.resource.provider.name` | String | Resource provider name, defaults to `unknown` |
+| `error.resource.provider.domain` | String | Resource provider domain |
+| `error.resource.provider.type` | String | Resource provider type (e.g., `first-party`, `cdn`, `ad`, `analytics`) |
</Accordion>
@@ -231,20 +249,30 @@ Different event types have specific attributes and metrics.
| `action.loading_time` | Number (ns) | Action loading time |
| `action.resource.count` | Number | Number of resources triggered by this action |
| `action.error.count` | Number | Number of errors triggered by this action |
+| `action.long_task.count` | Number | Number of long tasks triggered by this action |
+
+</Accordion>
+
+<Accordion title="Crash Attributes">
+
+When the app crashes, these additional attributes are collected:
+
+| Attribute | Type | Description |
+|-----------|------|-------------|
+| `error.signal` | String | Name of the signal that caused the crash (e.g., `SIGABRT`, `SIGSEGV`) |
+| `error.binary_images` | Array | Binary images loaded at crash time |
+| `error.threads` | Array | State of all threads at crash time |
+| `error.meta` | Object | Crash-related metadata |
</Accordion>
</AccordionGroup>
-## Data Storage
+## Data Storage and Security
-Before data is uploaded to Flashcat, it is stored in plaintext in the app's cache directory.
+### Local Storage
-<Check>
-**Security Protection:**
-- Cache folder is protected by iOS app sandbox
-- Other apps cannot read this data
-</Check>
+Before data is uploaded to Flashduty, it is stored in plaintext in the app sandbox's cache directory (`Library/Caches`). This directory is protected by the iOS app sandbox, so other apps on the device cannot read it.
<Warning>
**Security Notes:**
@@ -252,6 +280,18 @@ Before data is uploaded to Flashcat, it is stored in plaintext in the app's cach
- Sensitive data should not be included in RUM events, or should be obfuscated or filtered via Event Mapper before sending
</Warning>
+### Data Management
+
+To keep disk usage in check, the SDK manages local data automatically:
+
+| Policy | Description |
+|------|------|
+| **Smart upload** | Data is sent in batches when the network is available and battery is sufficient |
+| **Retry on failure** | If the network is unavailable or an upload fails, the batch is kept until it is sent successfully |
+| **Automatic cleanup** | Data older than a certain age is deleted automatically |
+
+Data collected while the user is offline is kept and uploaded once the network is back, so no monitoring data is lost.
+
## Related Documentation
<CardGroup cols={3}>
diff --git a/en/rum/sdk/ios/sdk-integration.mdx b/en/rum/sdk/ios/sdk-integration.mdx
index ffb67cee..53b5bf13 100644
--- a/en/rum/sdk/ios/sdk-integration.mdx
+++ b/en/rum/sdk/ios/sdk-integration.mdx
@@ -25,7 +25,7 @@ Flashduty iOS SDK supports Swift Package Manager and CocoaPods:
<Tabs>
<Tab title="Swift Package Manager">
-1. In Xcode, open your project and select **File > Add Package Dependencies**
+1. In Xcode, open your project and select **File → Add Package Dependencies**
2. Enter the Flashduty SDK Git repository URL:
```
@@ -390,7 +390,7 @@ All error information is displayed in the console's RUM Explorer, including erro
</Check>
<Note>
-For detailed error reporting configuration, see [iOS Error Reporting](/en/rum/error-tracking/erro-reporting/ios).
+For detailed error reporting configuration, see [iOS Error Reporting](/en/rum/error-tracking/error-reporting/ios).
</Note>
### Track Background Events
diff --git a/en/rum/sdk/web/data-collection.mdx b/en/rum/sdk/web/data-collection.mdx
index b7aa3f0d..8d5b805f 100644
--- a/en/rum/sdk/web/data-collection.mdx
+++ b/en/rum/sdk/web/data-collection.mdx
@@ -381,20 +381,10 @@ Web RUM SDK uploads collected events to the server in batches to optimize networ
## Privacy and Compliance
-<CardGroup cols={2}>
-<Card title="IP Address Anonymization" icon="eye-slash">
- SDK can be configured to anonymize IP addresses
-</Card>
-<Card title="Sensitive Data Filtering" icon="filter">
- Use `beforeSend` callback to filter or obfuscate sensitive information
-</Card>
-<Card title="Cookie and Storage Control" icon="cookie">
- Configurable whether to use cookies and local storage
-</Card>
-<Card title="GDPR/CCPA Compliance" icon="shield-check">
- Supports user privacy opt-out mechanism
-</Card>
-</CardGroup>
+- **IP Address Anonymization**: SDK can be configured to anonymize IP addresses
+- **Sensitive Data Filtering**: Use `beforeSend` callback to filter or obfuscate sensitive information
+- **Cookie and Storage Control**: Configurable whether to use cookies and local storage
+- **GDPR/CCPA Compliance**: Supports user privacy opt-out mechanism
<Tip>
For detailed privacy configuration information, see [Advanced Configuration](/en/rum/sdk/web/advanced-config#user-tracking-consent).
diff --git a/en/rum/sdk/web/faq.mdx b/en/rum/sdk/web/faq.mdx
index 56b61116..d2661b70 100644
--- a/en/rum/sdk/web/faq.mdx
+++ b/en/rum/sdk/web/faq.mdx
@@ -102,12 +102,12 @@ Some ad blocker plugins may block RUM SDK operation. We recommend adding your do
3. **Check Sample Rate**: Confirm sample rate is set appropriately
-```javascript
-flashcatRum.init({
- // ... other config
- sessionSampleRate: 100 // Set to 100 to collect all sessions
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... other config
+ sessionSampleRate: 100 // Set to 100 to collect all sessions
+ });
+ ```
4. **Check User Authorization**: Confirm user tracking consent status
@@ -123,18 +123,18 @@ flashcatRum.setTrackingConsent("granted");
1. **Enable Behavior Tracking**:
-```javascript
-flashcatRum.init({
- // ... other config
- trackUserInteractions: true
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... other config
+ trackUserInteractions: true
+ });
+ ```
2. **Add Markers to Custom Elements**:
-```html
-<button data-action-name="Submit Form">Submit</button>
-```
+ ```html
+ <button data-action-name="Submit Form">Submit</button>
+ ```
3. **Manually Record Complex Interactions**:
@@ -150,23 +150,23 @@ flashcatRum.addAction("click", "Custom Button Click");
1. **Enable Error Tracking**:
-```javascript
-flashcatRum.init({
- // ... other config
- trackErrors: true
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... other config
+ trackErrors: true
+ });
+ ```
2. **Manually Report Errors in try-catch**:
-```javascript
-try {
- // Code that might error
-} catch (error) {
- console.error(error);
- flashcatRum.addError(error);
-}
-```
+ ```javascript
+ try {
+ // Code that might error
+ } catch (error) {
+ console.error(error);
+ flashcatRum.addError(error);
+ }
+ ```
3. **Configure Source Maps**: For easier production debugging, see [Source Mapping](/en/rum/error-tracking/source-mapping)
</Accordion>
@@ -178,24 +178,24 @@ try {
1. **Only Enable Necessary Features**:
-```javascript
-flashcatRum.init({
- // ... other config
- trackResources: true,
- trackLongTasks: false, // Disable unneeded features
- trackErrors: true,
- trackUserInteractions: true
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... other config
+ trackResources: true,
+ trackLongTasks: false, // Disable unneeded features
+ trackErrors: true,
+ trackUserInteractions: true
+ });
+ ```
2. **Adjust Sample Rate**:
-```javascript
-flashcatRum.init({
- // ... other config
- sessionSampleRate: 50 // Only collect 50% of sessions
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... other config
+ sessionSampleRate: 50 // Only collect 50% of sessions
+ });
+ ```
3. **Filter Non-critical Resources**:
diff --git a/en/rum/sdk/web/sdk-integration.mdx b/en/rum/sdk/web/sdk-integration.mdx
index de44a08c..5d8374fc 100644
--- a/en/rum/sdk/web/sdk-integration.mdx
+++ b/en/rum/sdk/web/sdk-integration.mdx
@@ -4,13 +4,9 @@ description: "Learn how to integrate Web RUM SDK in Web applications, including
keywords: ["RUM", "Web SDK", "User Monitoring", "Frontend Monitoring"]
---
-<Info>
-RUM SDK supports multiple integration methods. Choose the one that best fits your project requirements.
-</Info>
-
## Integration Methods
-We provide three integration methods:
+Choose one of three integration methods:
| Method | Recommended For | Features |
|--------|-----------------|----------|
@@ -22,6 +18,18 @@ We provide three integration methods:
NPM and CDN async methods may miss errors, resources, and user actions triggered before SDK initialization. Use CDN sync for complete collection.
</Warning>
+## Get Application Credentials
+
+On the [RUM Application Management](https://console.flashcat.cloud/rum/apps) page in the Flashduty console:
+
+1. Create or select a Web application
+2. Get the following credentials:
+ - **Application ID** - unique application identifier
+ - **Client Token** - client access token
+
+<Frame>
+ 
+</Frame>
## Integration Code
diff --git a/en/rum/sdk/wechat-miniprogram/compatible.mdx b/en/rum/sdk/wechat-miniprogram/compatible.mdx
index 90a22f5b..7ee9d065 100644
--- a/en/rum/sdk/wechat-miniprogram/compatible.mdx
+++ b/en/rum/sdk/wechat-miniprogram/compatible.mdx
@@ -13,7 +13,7 @@ The WeChat Mini Program RUM SDK runs in the WeChat Mini Program environment and
|------|-------------|-------------|
| Mini Program base library | `2.10.0+` | SDK initialization registers `wx.onUnhandledRejection`; runtimes below this version are not recommended |
| Recommended base library | `2.12.0+` | Enables complete page rendering, startup, script execution, and setData update timing collection |
-| WeChat DevTools | Recent stable version | Must support npm dependency installation and **Tools > Build npm** |
+| WeChat DevTools | Recent stable version | Must support npm dependency installation and **Tools → Build npm** |
| npm package | `@flashcatcloud/miniprogram-rum` | Includes core functionality, platform adapter, and the RUM entry point |
<Warning>
@@ -52,7 +52,7 @@ When integrating through npm, build npm dependencies in WeChat DevTools:
1. Run `npm install @flashcatcloud/miniprogram-rum` in the Mini Program project root
2. Open the project in WeChat DevTools
-3. Run **Tools > Build npm**
+3. Run **Tools → Build npm**
4. Confirm that the generated `miniprogram_npm` can be referenced by Mini Program code
<Tip>
diff --git a/en/rum/sdk/wechat-miniprogram/sdk-integration.mdx b/en/rum/sdk/wechat-miniprogram/sdk-integration.mdx
index 0997f237..7cc6ba52 100644
--- a/en/rum/sdk/wechat-miniprogram/sdk-integration.mdx
+++ b/en/rum/sdk/wechat-miniprogram/sdk-integration.mdx
@@ -12,7 +12,7 @@ Before integrating the SDK, complete these steps:
- Create or select a RUM application in the Flashduty console, then obtain the **Application ID** and **Client Token**
- Confirm that your Mini Program can access the RUM intake URL. The default URL is `https://browser.flashcat.cloud/api/v2/rum`; configure `proxy` if your network policy requires forwarding
-- Configure the request domain allowlist in the WeChat Official Platform: go to **Development > Development Management > Development Settings > Server Domain** and add `https://browser.flashcat.cloud` (or your proxy domain) to the **request legal domains**. Without this, WeChat blocks all reporting requests on real devices; during development, you can temporarily check the "Do not verify legal domains" option in WeChat DevTools
+- Configure the request domain allowlist in the WeChat Official Platform: go to **Development → Development Management → Development Settings → Server Domain** and add `https://browser.flashcat.cloud` (or your proxy domain) to the **request legal domains**. Without this, WeChat blocks all reporting requests on real devices; during development, you can temporarily check the "Do not verify legal domains" option in WeChat DevTools
- If you use WeChat DevTools, build npm so `miniprogram_npm` can reference the SDK package
## Install the SDK
@@ -23,7 +23,7 @@ Install the RUM SDK in the Mini Program project root:
npm install @flashcatcloud/miniprogram-rum
```
-After installation, run **Tools > Build npm** in WeChat DevTools.
+After installation, run **Tools → Build npm** in WeChat DevTools.
## Initialize the SDK
diff --git a/en/statuspage.mdx b/en/statuspage.mdx
index b6e1a838..7da15e62 100644
--- a/en/statuspage.mdx
+++ b/en/statuspage.mdx
@@ -1,5 +1,5 @@
---
-title: Status Page
+title: "Flashduty Service Status"
description: "View real-time operational status and historical availability of Flashduty service components"
keywords: ["status page", "service status", "availability", "uptime"]
url: https://status.flashcat.cloud
diff --git a/integration-docs/scripts/build-docs-bundle.test.mjs b/integration-docs/scripts/build-docs-bundle.test.mjs
index 358efb5b..0f7c5112 100644
--- a/integration-docs/scripts/build-docs-bundle.test.mjs
+++ b/integration-docs/scripts/build-docs-bundle.test.mjs
@@ -41,7 +41,7 @@ test('derivePublicUrl prefers frontmatter url, else derives from the path', () =
'https://docs.flashduty.com/zh/on-call/integration/instant-messaging/lark'
);
assert.equal(
- derivePublicUrl('zh/stsatuspage.mdx', { url: 'https://status.flashcat.cloud' }),
+ derivePublicUrl('zh/statuspage.mdx', { url: 'https://status.flashcat.cloud' }),
'https://status.flashcat.cloud'
);
});
diff --git a/zh/ai-sre.mdx b/zh/ai-sre.mdx
index 43e90cf7..808fcd54 100644
--- a/zh/ai-sre.mdx
+++ b/zh/ai-sre.mdx
@@ -11,9 +11,9 @@ sidebarTitle: AI SRE
## 什么是 AI SRE?
-Flashduty AI SRE 是一个对话式的自治 SRE Agent 平台。你用自然语言下达指令,它便自主规划步骤、查询监控与日志、执行命令、调用外部工具(MCP),在需要时把子任务委派出去,最终给出有调查过程支撑的结论。
+Flashduty AI SRE 是一个对话式的自治 SRE Agent 平台。您用自然语言下达指令,它便自主规划步骤、查询监控与日志、执行命令、调用外部工具(MCP),在需要时把子任务委派出去,最终给出有调查过程支撑的结论。
-它不是只会问答的聊天机器人,而是一个**能动手的排障工作者**,并与 Flashduty 的故障响应体系深度联动:故障触发或开启作战室时,可一键拉起会话,让 Agent 带着故障上下文进入排查现场——既能在控制台对话,也能直接在你的 IM 群(Slack / 飞书 / 钉钉 / 企业微信)里 @ 它。
+它不是只会问答的聊天机器人,而是一个**能动手的排障工作者**,并与 Flashduty 的故障响应体系深度联动:故障触发或开启作战室时,可一键拉起会话,让 Agent 带着故障上下文进入排查现场——既能在控制台对话,也能直接在您的 IM 群(Slack / 飞书 / 钉钉 / 企业微信)里 @ 它。
## 核心能力
@@ -28,7 +28,7 @@ Flashduty AI SRE 是一个对话式的自治 SRE Agent 平台。你用自然语
以 DUTY.md 为入口的知识承载服务清单、runbook、值班路径等长期上下文
</Card>
<Card title="可扩展的工具生态" icon="plug">
- 通过 Skill、MCP、A2A Agent 扩展能力;自托管 Runner 让排障进入你的内网
+ 通过 Skill、MCP、A2A Agent 扩展能力;自托管 Runner 让排障进入您的内网
</Card>
</CardGroup>
@@ -51,16 +51,7 @@ Flashduty AI SRE 是一个对话式的自治 SRE Agent 平台。你用自然语
## 开通与计费
-AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。
-
-<AccordionGroup>
- <Accordion title="计费规则" icon="gift">
- AI SRE 自 2026 年 9 月 16 日 8 点(北京时间)起按实际用量计费,以 credits 结算,1 credit = ¥1;此前的用量不收费。计量项为模型用量、沙箱在线时长和联网检索。开通免费,符合条件的账户每个计费周期赠送体验额度,也可以购买资源包(1,000 / 5,000 / 20,000 credits,对应 ¥950 / ¥4,500 / ¥17,000,自支付起 365 天有效)。按量付费默认关闭,由管理员开启,可设置每周期上限。完整规则见[《AI SRE credits 资源包购买协议》](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
- </Accordion>
- <Accordion title="人工授权" icon="user-check">
- 生产变更、重启、回滚和外部通知,最终都由你确认后才会执行。
- </Accordion>
-</AccordionGroup>
+AI SRE 需在控制台开通,按实际用量以 credits 计费。生产变更、重启、回滚和外部通知,最终都由您确认后才会执行。开通、计费规则与订阅要求详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 快速开始
diff --git a/zh/ai-sre/agents.mdx b/zh/ai-sre/agents.mdx
index 2edbb2e9..75ef8ecd 100644
--- a/zh/ai-sre/agents.mdx
+++ b/zh/ai-sre/agents.mdx
@@ -5,14 +5,10 @@ keywords: ["AI SRE", "Agent", "A2A", "Agent-to-Agent", "Agent Card", "委派", "
sidebarTitle: Agent
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
**Agent** 是把 AI SRE 接入外部 Agent 生态的资源类别。当前支持的类型是 **A2A(Agent-to-Agent)**——一套让不同 Agent 相互调用的标准协议(后续可能扩展更多 Agent 类型)。A2A 把 AI SRE 接入外部 Agent,有两个方向:
<CardGroup cols={2}>
@@ -24,55 +20,22 @@ sidebarTitle: Agent
</Card>
</CardGroup>
-委派后无需等待:AI SRE 把任务交给远端 Agent 后会立即继续当前对话,您可以继续工作或同时委派多个任务;远端完成后,其结果作为一条新消息出现在对话中。每次 A2A 委派在对话流里以一张**任务卡片**呈现,卡片带 `A2A` 徽标,显示远端 Agent 名、本次任务意图、运行状态(初始化 / 进行中 / 等待输入 / 等待授权 / 完成 / 失败(含孤儿任务)/ 中断 / 已终止)以及工具调用数、Token、耗时等用量;点击卡片可在右侧面板里查看该次委派的完整过程。
+委派后无需等待:AI SRE 把任务交给远端 Agent 后会立即继续当前对话,您可以继续工作或同时委派多个任务;远端完成后,其结果作为一条新消息出现在对话中。
+
+每次 A2A 委派在对话流里以一张带 `A2A` 徽标的**任务卡片**呈现,显示远端 Agent 名、本次任务意图、运行状态(初始化 / 进行中 / 等待输入 / 等待授权 / 完成 / 失败(含孤儿任务)/ 中断 / 已终止)以及工具调用数、Token、耗时等用量;点击卡片可在右侧面板里查看该次委派的完整过程。
<Tip>
-**调用说明分两层,是 Agent 选择信号**。AI SRE 委派前看到的「可用 Agent 清单」里,每一项只有 `名称:简介`——简介来自调用说明开头的 `summary:` 一行(不写则自动截取正文开头),AI SRE 靠它判断**要不要、什么时候**把任务派给这个 Agent,务必写清楚何时优先选用它、擅长什么、不适合做什么。简介之后的正文不会常驻清单,只在**首次委派给这个 Agent 时**才完整送达——放心写长、写细(操作步骤、硬性规则、示例),不会拖慢日常对话。写法详见下文「[调用说明的写法](#调用说明的写法)」。
+**调用说明决定 AI SRE 会不会选中这个 Agent。** 委派前,AI SRE 只看到清单里的一行 `名称:简介`(简介取自调用说明开头的 `summary:`),据此判断要不要派给它;正文只在首次委派时完整送达,可以写长写细。写法见[调用说明的写法](#调用说明的写法)。
</Tip>
-A2A Agent 的列表与管理入口在 **自定义 → 插件 → Agents** 页面(菜单标签为 **Agents**)。
-
-<Note>
-**Agents 涵盖两类不同的概念。** 本页(Agents)当前管理的是 **A2A Agent**(外部 Agent 互调)。另一类是 **Subagent(任务子代理)**——平台内置、由 AI SRE 在会话中按需派发的任务执行器,没有创建 / 编辑入口,只能在会话中观察其行为,详见下文「[Subagent 任务子代理](#subagent-任务子代理)」。
-</Note>
-
-## Subagent 任务子代理
-
----
-
-**Subagent** 是平台**内置**的任务执行器。AI SRE 在排障过程中,可以把一个自包含的子任务**派发(dispatch)**给一个 Subagent 去独立完成——派发统一通过单一的长时运行工具 `agent_dispatch` 进行,而不是为每个 Subagent 生成一个独立工具。
-
-平台预置了若干**引导(bootstrap)Subagent**,开箱即用:
-
-| 名称 | 角色 |
-| --- | --- |
-| `general` | 通用执行器,拥有完整工具权限,适合把中间步骤会污染主对话上下文的工作(长报告、多文件改动、端到端构建、反复探查)整体外包出去;可并行派发多个处理相互独立的工作单元 |
-| `explore` | 只读调查器,仅限 `grep` / `glob` / `read`,不能写入或执行;返回浓缩摘要而非原始搜索输出,适合在代码库或知识转储中定位证据 |
-
-**会话中的呈现**:每次派发在对话流里同样以一张**任务卡片**呈现,与 A2A 委派共用同一套状态生命周期(初始化 / 进行中 / 等待输入 / 等待授权 / 完成 / 失败(含孤儿任务)/ 中断 / 已终止)。区别在于徽标——Subagent 任务卡片带 `Agent` 徽标,而 A2A 委派带 `A2A` 徽标。Subagent 卡片的引用行右侧还会先标出**这次派发落在哪个执行环境**(云端环境,或该 BYOC Runner 的名称),因此从卡片上就能看出子任务在哪儿执行,详见下文「派发目标环境」。
-
-**运行约束**:
-
-- **并发上限**:每个会话**最多同时运行 20 个 Subagent**(`TaskMaxConcurrentPerSession = 20`)。这里限制的是「同一时刻并发运行」的数量而非会话累计派发数——每完成一个就释放一个名额,因此会话整体可完成的工作量不受限。达到上限时再派发会报错(`too many active subagents (… running, limit 20)`),提示模型先停下等待运行中的任务完成、再派发其余的。
-- **嵌套深度**:派发链**最多嵌套 3 层**(`TaskMaxNestingDepth = 3`),防止 Subagent 无限自我派生。
-
-**派发目标环境**:`agent_dispatch` 还有一个可选参数 `environment`,决定这个子任务在**哪个运行环境**里执行。它的取值为:
-
-- **省略(默认)**:子代理与当前会话在**同一个**环境里运行,**共用同一套文件系统**——它能直接看到你 workspace 里的文件。点名会话**已经在**的那个环境(例如在一个云端会话里传 `cloud`)结果相同,也是继承,不会另起一个沙箱。
-- **`cloud`**:在一个**全新的云端环境**里运行——临时容器、独立的文件系统,出网按账户的默认策略。
-- **某个 BYOC Runner 的 environment_id**:在**那台 Runner** 上运行。可选目标是**账户级 Runner**,加上**当前会话所绑定团队**的 Runner,且只列出**在线**的;同名 Runner 会带团队后缀以示区分。`agent_dispatch` 的说明里直接给出这份清单,每个 Runner 的 id 就是可传的值。传了不可用的 Runner(离线、不存在、属于别的团队)时派发会被直接拒绝并给出原因,不会静默改派到别处。
-- **只对 Subagent 有效**:给 A2A Agent 传 `environment` 会被拒绝——远端 Agent 在它自己的环境里执行,没有可选位置;要换环境就派一个 Subagent 去做。
-
-**跨环境派发读不到父会话的文件**:子会话只有在自己的执行环境与父会话**完全相同**时才共用父会话的沙箱 / workspace;一旦派到另一个环境,它就会得到**自己的**沙箱或 Runner scratch 目录,**看不到你(父会话)的文件**。因此把它需要的一切**写进 prompt**(文件内容、路径、参数、约束),不要只写「读 workspace 里的某个文件」;结果会以**文本**回来,或者经外部系统(git、工单)流转。运行环境本身的区别与选择方式见 [运行环境(BYOC)](/zh/ai-sre/environments)。
+A2A Agent 的列表与管理入口在 **自定义 → 插件 → Agents** 页面。
<Note>
-**Subagent 目前没有面向用户的创建 / 管理界面。** 它是一项内置运行能力:您可以在会话中观察 Subagent 任务卡片及其子会话过程,但无法像 A2A Agent 那样新增、编辑或删除 Subagent。本页(Agents)当前管理的仅是 A2A Agent。
+**Agents 涵盖两类不同的概念。** 本页(Agents)当前管理的是 **A2A Agent**(外部 Agent 互调)。另一类是 **Subagent(任务子代理)**——平台内置、由 AI SRE 在会话中按需派发的任务执行器,没有创建 / 编辑入口,只能在会话中观察其行为,详见下文[Subagent 任务子代理](#subagent-任务子代理)。
</Note>
## 注册出站 A2A Agent
----
-
在 A2A Agents 列表页点击 **添加 A2A Agent**,在表单中填写:
| 字段 | 类型 | 默认值 | 说明 |
@@ -80,11 +43,11 @@ A2A Agent 的列表与管理入口在 **自定义 → 插件 → Agents** 页面
| 名称 | string | — | A2A Agent 标识(如 `metrics-analyzer`)。必填 |
| 范围 | 共享 / 团队 | — | 作用域:**共享**(即账户级,账户内全局可见)或某个**团队**(仅该团队成员可见和可编辑)。必填,详见下文「作用域」 |
| 执行环境 | 云端环境 / BYOC Runner(可多选) | 所有环境 | 决定该 A2A Agent 在哪些执行环境中可用。可以选择云端环境和一个或多个当前可见的 BYOC Runner;不选择时默认在所有环境可用。它不指定委派调用路由:A2A 调用仍在当前 AI SRE 会话自身的执行环境中运行。若远端 Agent 只在某个内网可访问,请只选择能访问它的 Runner |
-| 调用说明 | string | — | 面向 AI SRE 的 Agent 选择信号,是**一份文档**:可选的 `summary:` frontmatter + 正文。简介(`summary`)进入「可用 Agent 清单」,正文在首次委派时才完整送达。必填;整份文档最多 50 KB,`summary` 最多 1,024 个字符且不能包含 `<` `>`。写法见下文「[调用说明的写法](#调用说明的写法)」 |
-| Card URL | string | — | 远端 A2A Agent 的 Agent Card 地址,或仅填写遵循默认 well-known 规则的服务根地址(如 `https://agents.example.com`)。如果 URL 已带路径,平台会按该地址原样读取;如果只填服务根地址,平台按 A2A 约定查找 `/.well-known/agent-card.json`。必填。平台只校验 URL 格式合法(scheme 为 http/https、host 非空),不做主机或 IP 分类;实际的网络可达性与出站限制取决于发起委派的 AI SRE 会话所在执行环境,上面的执行环境字段只限制该 Agent 在哪些环境中可用。远端 Agent 需实现 A2A Protocol 1.0,见下文「[协议版本与 Agent Card 要求](#协议版本与-agent-card-要求)」 |
-| 服务授权 | enum | `none` | AI SRE 作为**服务**访问远端 Agent 时使用的身份(字段 `auth_type`):`none`(无)/ `bearer`(Bearer Token)/ `api_key`(自定义 Header + Key)。表单中标记为**推荐**。详见下文「[授权模式](#授权模式)」 |
+| 调用说明 | string | — | 面向 AI SRE 的 Agent 选择信号,是**一份文档**:可选的 `summary:` frontmatter + 正文。简介(`summary`)进入「可用 Agent 清单」,正文在首次委派时才完整送达。必填;整份文档最多 50 KB,`summary` 最多 1,024 个字符且不能包含 `<` `>`。写法见下文[调用说明的写法](#调用说明的写法) |
+| Card URL | string | — | 远端 A2A Agent 的 Agent Card 地址,或仅填写遵循默认 well-known 规则的服务根地址(如 `https://agents.example.com`)。如果 URL 已带路径,平台会按该地址原样读取;如果只填服务根地址,平台按 A2A 约定查找 `/.well-known/agent-card.json`。必填,须为 http/https 地址。能否连通取决于发起委派的会话所在执行环境。远端 Agent 需实现 A2A Protocol 1.0,见下文[协议版本与 Agent Card 要求](#协议版本与-agent-card-要求) |
+| 服务授权 | enum | `none` | AI SRE 作为**服务**访问远端 Agent 时使用的身份(字段 `auth_type`):`none`(无)/ `bearer`(Bearer Token)/ `api_key`(自定义 Header + Key)。表单中标记为**推荐**。详见下文[授权模式](#授权模式) |
| 流式传输 | bool | 开 | 是否以流式方式与远端交互 |
-| 成员授权 | enum | `shared`(无) | 每位成员各自持有的身份(字段 `auth_mode`):`shared`(无)/ `per_user_secret`(密钥(Header))/ `per_user_oauth`(OAuth 2.1)。详见下文「[授权模式](#授权模式)」 |
+| 成员授权 | enum | `shared`(无) | 每位成员各自持有的身份(字段 `auth_mode`):`shared`(无)/ `per_user_secret`(密钥(Header))/ `per_user_oauth`(OAuth 2.1)。详见下文[授权模式](#授权模式) |
| 跳过 TLS 证书校验 | bool | 关 | 仅当 Card URL 为 HTTPS 时显示。只在远端使用自签证书且网络受控时开启;开启后会跳过证书链和主机名校验 |
| 允许通过 HTTP 获取 OAuth 配置(仅限测试环境) | bool | 关 | 仅当**成员授权**选择「OAuth 2.1」且 Card URL 是非本地 HTTP 地址时需要确认。只用于受控测试环境;开启后 AI SRE 服务端会访问该主机的 OAuth metadata |
@@ -147,7 +110,7 @@ summary: 一句话简介,AI 据此决定是否派发
- **硬性限制**:整份调用说明(frontmatter + 正文)不超过 **50 KB**;`summary` 不超过 **1,024 个字符**,且不能包含 `<` 或 `>`;正文不能为空。
- 如果开头写了 `---`,就必须再用一行 `---` 把 frontmatter 闭合,否则保存会失败。
-下文「[使用 FlashAI 模板](#使用-flashai-模板)」的调用说明就是一份实际生效的范例,可以参考它的结构。
+下文[使用 FlashAI 模板](#使用-flashai-模板)的调用说明就是一份实际生效的范例,可以参考它的结构。
### 使用 FlashAI 模板
@@ -194,7 +157,7 @@ FlashAI 侧需要先完成以下配置:
https://demo.flashcat.cloud/api/fc-model/a2a/.well-known/agent-card.json
```
-模板只负责预填通用信息;你仍需在表单中选择**范围**(共享或团队)并按需配置认证。A2A Agent 可以按不同范围安装多次,因此 FlashAI 折叠卡片不会因为已有某个 FlashAI Agent 就自动消失。Agent 名称在账户内仍需唯一;如果同一个 FlashAI 域名需要安装多次,请在表单里调整名称。
+模板只预填通用信息;**范围**(共享或团队)和认证仍需您在表单中设置。同一个 FlashAI 可以按不同范围安装多次,但 Agent 名称在账户内须唯一,重复安装时请修改名称。
<Tip>
不建议删除 FlashAI 模板生成的调用说明,尤其是开头的 `summary:` 简介——注册后 FlashAI 一定会出现在「可用 Agent 清单」里,但 AI SRE 是否把任务派给它,直接依据就是这行简介。说明过短或过于泛化时,AI SRE 可能继续在本地推理,或把普通 metrics / logs 问题错误委派给 FlashAI。
@@ -223,7 +186,7 @@ A2A Agent 的身份由两条**互相独立**的轴决定,两条轴可以同时
- **只配了服务授权**:所有场景都使用服务授权。
- **只配了成员授权**:IM 群聊会逐轮使用发言成员的个人授权。如果远端系统不接受同一会话内多人轮流的身份(会因身份校验失败而拒绝),请补配服务授权。
-- **两条轴都为「无」**:调用不携带任何身份。保存时会弹出确认框「该 Agent 将不携带身份调用,确认保存?」。远端需要认证时,推荐配置服务授权。
+- **两条轴都为「无」**:调用不携带任何身份。保存时需要二次确认。远端需要认证时,推荐配置服务授权。
<Warning>
服务授权意味着账户内任何团队范围会话与 IM 群聊都能以这个服务身份调用远端系统。若该系统涉及成员个人数据或高危写操作,建议同时启用成员授权。
@@ -245,16 +208,51 @@ OAuth 2.1 只出现在**成员授权**这条轴上。服务授权是账户内共
</Note>
<Note>
-出于安全考虑,已保存的敏感字段(如 `token`、`api_key`、`client_secret`)在读取时会被**掩码**返回。编辑时若把敏感字段留空,表示「保留当前值」而非「清空」——只有当您显式修改它时才会覆盖已存储的凭证。
+已保存的敏感字段(如令牌、API Key、Client Secret)会**掩码**显示。编辑时留空表示保留原值,不会清空。
</Note>
<Warning>
成员授权(OAuth 2.1)的发现地址优先使用 HTTPS。只有在受控测试环境中,才为非本地 HTTP Card URL 勾选「允许通过 HTTP 获取 OAuth 配置(仅限测试环境)」。如果 HTTPS 端点使用自签证书,也只应在可信网络内临时开启「跳过 TLS 证书校验」。
</Warning>
-## 入站:让外部 Agent 调用 AI SRE
+## 创建与管理
----
+A2A Agent 的完整生命周期可在 **自定义 → 插件 → Agents** 页面管理。
+
+<AccordionGroup>
+ <Accordion title="创建" icon="plus">
+ 点击 **添加 A2A Agent**,填写名称、范围、调用说明、Card URL、认证等并保存。创建时需选定一个明确的作用域(共享或团队),未选定前提交按钮保持禁用。
+ </Accordion>
+ <Accordion title="启用 / 禁用" icon="toggle-on">
+ 用列表中的开关切换 A2A Agent 的启用状态。仅**已启用**的 Agent 会进入 AI SRE 的可用清单、可被委派任务;禁用后立即对委派不可见。
+ </Accordion>
+ <Accordion title="检视 / 编辑" icon="pen-to-square">
+ 点击列表中的任意一行打开表单,可查看与编辑名称、调用说明、范围、Card URL、服务授权、成员授权与流式设置。无编辑权限时表单显示为**只读**。
+ </Accordion>
+ <Accordion title="删除" icon="trash">
+ 从当前范围移除一个 A2A Agent。**委派给它的活跃会话将会失败。** 删除有确认提示。
+ </Accordion>
+ <Accordion title="按范围筛选与搜索" icon="filter">
+ 列表顶部可按范围(全部 / 共享 / 指定团队)筛选,或按名称、调用说明、Card URL 中的关键词搜索。每行标注其范围(共享 / 团队名)。
+ </Accordion>
+</AccordionGroup>
+
+## 作用域
+
+A2A Agent 与其他资源(Skill、知识、MCP、运行环境)共用同一套**两级作用域**模型,分为账户级与团队级。控制台界面中,账户级这一档显示为「**共享**」/「**共享范围**」,与账户级同义(整个账户内可见):
+
+| 作用域 | 可见性 |
+| --- | --- |
+| 账户级 | 账户内所有成员可见 |
+| 团队级 | 仅该团队成员可见 |
+
+**编辑权限**:团队级 Agent 仅该团队的成员可以操作,组织管理员也需要先加入该团队;账户级 Agent 仅账户所有者或管理员可以操作;没有「创建者保留权限」这一例外。无编辑权限时,列表对应行显示为**只读**。
+
+**创建与改归属**:创建新的团队级 Agent 时,您必须是目标团队成员;账户级创建仅限账户所有者或管理员。编辑已有 Agent 时,账户所有者或管理员可以把它移动到任意团队,用于恢复空团队或离职成员留下的资源;普通成员只能移动到自己所属的团队。
+
+**运行时可见性**:会话开始时,AI SRE 的可用 Agent 清单中只会呈现**账户级**资源,以及**当前会话所绑定团队**的资源(如故障 / 作战室带入的团队,或界面上显式选择的团队)。当 Agent 在排障中读取另一个团队的知识后,该团队的 Skill、MCP 与 A2A Agent 才会被按需挂载进当前会话。**账户是运行时唯一的安全边界,团队只是归属与编辑的标记。**
+
+## 入站:让外部 Agent 调用 AI SRE
在 A2A Agents 页面顶部展开「**让外部 Agent 调用 Flashduty 的 AI SRE**」面板,即可获取本账户 AI SRE 的 **Agent Card** 地址:
@@ -281,56 +279,40 @@ Agent Card 同时声明了 Flashduty 的「运行选项」A2A 扩展:调用方
当一个会话**经由故障路由进入**(例如从故障或作战室触发 AI SRE)时,平台会把对应的故障绑定到本次会话,并作为上下文带入,让排障从一开始就锚定在正确的故障上。基于此,AI SRE 可在对话中借助内置 Skill 进一步操作故障——读取故障详情、查询时间线、创建 / 查看作战室、关联变更等。IM 侧的作战室自动诊断详见 [IM 集成](/zh/ai-sre/im)。
<Warning>
-A2A 与故障的**自动联动**目前在概念上受支持、并在持续演进中:故障自动绑定尚未完整可用,跨 Agent 的双向事件流会随版本逐步完善。请勿将其视为已完整可用的能力,以实际开通的功能为准。
+A2A 与故障的**自动联动**仍在开发中:故障自动绑定尚未完整可用,跨 Agent 的双向事件流会随版本逐步完善。请以实际开通的功能为准。
</Warning>
-## 创建与管理
-
----
+## Subagent 任务子代理
-A2A Agent 的完整生命周期可在 **自定义 → 插件 → Agents** 页面管理。
+**Subagent** 是平台**内置**的任务执行器。AI SRE 在排障过程中,可以把一个自包含的子任务<strong>派发(dispatch)</strong>给一个 Subagent 去独立完成(通过 `agent_dispatch` 工具派发)。
-<AccordionGroup>
- <Accordion title="创建" icon="plus">
- 点击 **添加 A2A Agent**,填写名称、范围、调用说明、Card URL、认证等并保存。创建时需选定一个明确的作用域(共享或团队),未选定前提交按钮保持禁用。
- </Accordion>
- <Accordion title="启用 / 禁用" icon="toggle-on">
- 用列表中的开关切换 A2A Agent 的启用状态。仅**已启用**的 Agent 会进入 AI SRE 的可用清单、可被委派任务;禁用后立即对委派不可见。
- </Accordion>
- <Accordion title="检视 / 编辑" icon="pen-to-square">
- 点击列表中的任意一行打开表单,可查看与编辑名称、调用说明、范围、Card URL、服务授权、成员授权与流式设置。无编辑权限时表单显示为**只读**。
- </Accordion>
- <Accordion title="删除" icon="trash">
- 从当前范围移除一个 A2A Agent。**委派给它的活跃会话将会失败。** 删除有确认提示。
- </Accordion>
- <Accordion title="按范围筛选与搜索" icon="filter">
- 列表顶部的范围筛选条可在「全部」「共享」「指定团队」之间切换,便于在大量资源中聚焦查看。每行还会以标签标注其范围(共享 / 团队名)。筛选条右侧的搜索框支持按名称、调用说明或 Card URL 中的关键词过滤列表。
- </Accordion>
-</AccordionGroup>
+平台预置了若干**引导(bootstrap)Subagent**,开箱即用:
-## 作用域
+| 名称 | 角色 |
+| --- | --- |
+| `general` | 通用执行器,拥有完整工具权限,适合把中间步骤会污染主对话上下文的工作(长报告、多文件改动、端到端构建、反复探查)整体外包出去;可并行派发多个处理相互独立的工作单元 |
+| `explore` | 只读调查器,仅限 `grep` / `glob` / `read`,不能写入或执行;返回浓缩摘要而非原始搜索输出,适合在代码库或知识转储中定位证据 |
----
+**会话中的呈现**:每次派发在对话流里同样以一张**任务卡片**呈现,状态与 A2A 委派相同,但徽标是 `Agent`(A2A 委派为 `A2A`)。卡片右侧还标出这次派发所在的**执行环境**(云端环境或 BYOC Runner 名称),见下文「派发目标环境」。
-A2A Agent 与其他资源(Skill、知识、MCP、运行环境)共用同一套**两级作用域**模型,分为账户级与团队级。控制台界面中,账户级这一档显示为「**共享**」/「**共享范围**」,与账户级同义(整个账户内可见):
+**运行约束**:
-| 作用域 | 可见性 |
-| --- | --- |
-| 账户级 | 账户内所有成员可见 |
-| 团队级 | 仅该团队成员可见 |
+- **并发上限**:每个会话**同一时刻最多运行 20 个 Subagent**。累计派发数不限,完成一个就释放一个名额;达到上限时,AI SRE 会等运行中的任务完成后再派发其余的。
+- **嵌套深度**:派发链**最多嵌套 3 层**,防止 Subagent 无限自我派生。
-**编辑权限**:团队级 Agent 仅该团队的成员可以操作,组织管理员也需要先加入该团队;账户级 Agent 仅账户所有者或管理员可以操作;没有「创建者保留权限」这一例外。无编辑权限时,列表对应行显示为**只读**。
+**派发目标环境**:`agent_dispatch` 还有一个可选参数 `environment`,决定这个子任务在**哪个运行环境**里执行。它的取值为:
-**创建与改归属**:创建新的团队级 Agent 时,您必须是目标团队成员;账户级创建仅限账户所有者或管理员。编辑已有 Agent 时,账户所有者或管理员可以把它移动到任意团队,用于恢复空团队或离职成员留下的资源;普通成员只能移动到自己所属的团队。
+- **省略(默认)**:子代理与当前会话在**同一个**环境里运行,**共用同一套文件系统**——它能直接看到您 workspace 里的文件。点名会话**已经在**的那个环境(例如在一个云端会话里传 `cloud`)结果相同,也是继承,不会另起一个沙箱。
+- **`cloud`**:在一个**全新的云端环境**里运行——临时容器、独立的文件系统,出网按账户的默认策略。
+- **某个 BYOC Runner 的 environment_id**:在**那台 Runner** 上运行。可选目标是**账户级 Runner**,加上**当前会话所绑定团队**的 Runner,且只列出**在线**的;指定不可用的 Runner(离线、不存在或属于其他团队)时,派发会失败并说明原因,不会改派到其他环境。
+- **只对 Subagent 有效**:给 A2A Agent 传 `environment` 会被拒绝——远端 Agent 在它自己的环境里执行,没有可选位置;要换环境就派一个 Subagent 去做。
-**运行时可见性**:会话开始时,AI SRE 的可用 Agent 清单中只会呈现**账户级**资源,以及**当前会话所绑定团队**的资源(如故障 / 作战室带入的团队,或界面上显式选择的团队)。当 Agent 在排障中读取另一个团队的知识后,该团队的 Skill、MCP 与 A2A Agent 才会被按需挂载进当前会话。**账户是运行时唯一的安全边界,团队只是归属与编辑的标记。**
+**跨环境派发读不到父会话的文件**:子会话只有在自己的执行环境与父会话**完全相同**时才共用父会话的沙箱 / workspace;一旦派到另一个环境,它就会得到**自己的**沙箱或 Runner scratch 目录,**看不到您(父会话)的文件**。因此把它需要的一切**写进 prompt**(文件内容、路径、参数、约束),不要只写「读 workspace 里的某个文件」;结果会以**文本**回来,或者经外部系统(git、工单)流转。运行环境本身的区别与选择方式见 [运行环境(BYOC)](/zh/ai-sre/environments)。
## 相关页面
----
-
<CardGroup cols={2}>
- <Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+ <Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
在会话中观察 A2A 委派的任务卡片及其子会话面板。
</Card>
<Card title="MCP(外部工具)" icon="plug" href="/zh/ai-sre/mcp">
diff --git a/zh/ai-sre/apps.mdx b/zh/ai-sre/apps.mdx
index 60ab5dc2..c725be27 100644
--- a/zh/ai-sre/apps.mdx
+++ b/zh/ai-sre/apps.mdx
@@ -1,30 +1,24 @@
---
title: Apps
-description: Apps 用于管理 AI SRE 已授权的外部应用,包括 GitHub、GitLab 与 Kubernetes App。你可以授权代码仓库,或将 Kubernetes 集群以指定的 namespace 与权限边界接入 AI SRE。
+description: Apps 用于管理 AI SRE 已授权的外部应用,包括 GitHub、GitLab 与 Kubernetes App。您可以授权代码仓库,或将 Kubernetes 集群以指定的 namespace 与权限边界接入 AI SRE。
keywords: ["AI SRE", "Apps", "App", "GitHub", "GitHub App", "GitLab", "GitLab App", "Kubernetes", "Kubernetes App", "K8s", "代码仓库", "集群", "namespace", "gh", "glab", "git", "Pull Request", "Merge Request", "MR", "Issue", "云端沙箱"]
sidebarTitle: Apps
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
-**Apps** 是管理「已授权的外部应用」的地方。每个外部应用以一张**应用卡片**呈现——你在它的卡片上完成授权、管理安装、并随时启停或撤销。
+**Apps** 是管理「已授权的外部应用」的地方。每个外部应用以一张**应用卡片**呈现——您在它的卡片上完成授权、管理安装、并随时启停或撤销。
Apps 包含 **GitHub**、**GitLab** 和 **Kubernetes App**。GitHub 与 GitLab 用于授权代码仓库:AI SRE 可以在会话中读代码、调查变更 / 提交 / PR(GitLab 中为 MR),并按需修改缺陷、创建 PR / MR 或 issue。Kubernetes App 则把指定 Kubernetes 集群接入 AI SRE,并通过配置的 namespace 与权限边界限制 Agent 的操作范围。
-## 主要场景:让云端沙箱访问你的仓库
+## 主要场景:让云端沙箱访问您的仓库
----
-
-AI SRE 的会话默认运行在 **Flashduty 云端沙箱**里。沙箱是干净、隔离的临时环境,**不带你的任何 git 登录凭证**——这正是 App 要解决的问题。授权 GitHub App 或 GitLab App 后,沙箱里的 Agent 才能 clone 你的仓库、读 diff、开 PR / MR,而**你无需向它交出任何密码或 token**;它的访问被限制在你授权的那些仓库,且仅为完成任务所需的最小权限。**这是这两个 App 的主要用途。**
+AI SRE 的会话默认运行在 **Flashduty 云端沙箱**里。沙箱是干净、隔离的临时环境,**不带您的任何 git 登录凭证**——这正是 App 要解决的问题。授权 GitHub App 或 GitLab App 后,沙箱里的 Agent 才能 clone 您的仓库、读 diff、开 PR / MR,而**您无需向它交出任何密码或 token**;它的访问被限制在您授权的那些仓库,且仅为完成任务所需的最小权限。**这是这两个 App 的主要用途。**
<Note>
-**BYOC(自托管 Runner)一般用不到它。** Runner 跑在你自己的机器上,那台机器通常**已经配好了 `gh` / `glab` / `git` 凭证**(你平时就在上面操作仓库)。这种情况下 Agent 直接用宿主机自带的凭证即可,**不需要再授权对应的 App**。(若宿主机恰好没配相应凭证,授权 App 同样能让 BYOC 会话用上。)运行环境的差异见 [运行环境(BYOC)](/zh/ai-sre/environments)。
+**BYOC(自托管 Runner)一般用不到它。** Runner 跑在您自己的机器上,那台机器通常**已经配好了 `gh` / `glab` / `git` 凭证**(您平时就在上面操作仓库)。这种情况下 Agent 直接用宿主机自带的凭证即可,**不需要再授权对应的 App**。(若宿主机恰好没配相应凭证,授权 App 同样能让 BYOC 会话用上。)运行环境的差异见 [运行环境(BYOC)](/zh/ai-sre/environments)。
</Note>
<Tip>
@@ -33,8 +27,6 @@ RUM 应用也可以记录构建它的代码仓库(可关联多个,第一个
## 位置
----
-
进入 **AI SRE → 自定义 → 插件 → Apps**。插件分组在自定义侧栏中依次列出 概览 / Apps / Skill / MCP / Agents,点击 **自定义** 时默认打开 **概览**。
<Note>
@@ -43,9 +35,7 @@ RUM 应用也可以记录构建它的代码仓库(可关联多个,第一个
## Kubernetes App
----
-
-Kubernetes App 将集群中的 Agent 接入 AI SRE。创建后,AI SRE 可以在授权范围内查询集群信息并执行可用的 Kubernetes 工具;它只能访问你在配置中指定的 namespace 和权限级别。
+Kubernetes App 将集群中的 Agent 接入 AI SRE。创建后,AI SRE 可以在授权范围内查询集群信息并执行可用的 Kubernetes 工具;它只能访问您在配置中指定的 namespace 和权限级别。
### 创建并安装
@@ -80,56 +70,48 @@ Kubernetes App 将集群中的 Agent 接入 AI SRE。创建后,AI SRE 可以
| 驱逐 Pod(用于重启工作负载) | 否 | 是 | 是 |
| 扩缩容 Deployment 和 StatefulSet | 否 | 是 | 是 |
| 调整 HPA 副本数上下限 | 否 | 是 | 是 |
-| 回滚工作负载 | 否 | 否(AI SRE 推算出目标 revision 并给出完整命令,由你执行) | 是 |
+| 回滚工作负载 | 否 | 否(AI SRE 推算出目标 revision 并给出完整命令,由您执行) | 是 |
| 修改工作负载配置(镜像、启动命令、环境变量等) | 否 | 否 | 是 |
| 修改 ConfigMap 和 Secret | 否 | 否 | 是 |
| 创建或删除资源 | 否 | 否 | 是 |
| 修改 namespace 内的 RBAC | 否 | 否 | 是 |
| 操作集群级资源和集群 RBAC | 否 | 否 | 仅「全部 namespace」 |
-- **只读**:授权 namespace 内的读取权限直接绑定 Kubernetes 内置的 `view` 角色,不再由 FlashDuty 自行维护资源清单。它覆盖 Pod、日志、工作负载、事件、ConfigMap 等资源,不含 Secret;集群中的组件如果把自己的 CRD 标记为 view 可读,也会一并包含。此外还会授予 nodes、namespaces、persistentvolumes、storageclasses、ingressclasses 等集群级只读权限
-- **读取 + 有限修改**:在只读基础上,额外允许驱逐 Pod(`pods/eviction`)、扩缩容 Deployment 和 StatefulSet(`deployments/scale`、`statefulsets/scale`)以及调整 HPA 副本数上下限(`horizontalpodautoscalers`)。这些规则只能改变已有工作负载运行几个副本、以及用同一份配置重建 Pod,无法改动任何 Pod 的镜像、启动命令、环境变量、身份或挂载——因此 `kubectl rollout restart` 和 `kubectl rollout undo` 都会被拒绝(两者在 Kubernetes 里都是对工作负载的 patch),重启工作负载请改用逐个驱逐 Pod。回滚工作负载时,AI SRE 会从 ReplicaSet 历史推算出目标 revision,给出完整的 `kubectl rollout undo --to-revision=N` 命令,由你在集群中执行
+- **只读**:授权 namespace 内的读取权限直接绑定 Kubernetes 内置的 `view` 角色,不再由 Flashduty 自行维护资源清单。它覆盖 Pod、日志、工作负载、事件、ConfigMap 等资源,不含 Secret;集群中的组件如果把自己的 CRD 标记为 view 可读,也会一并包含。此外还会授予 nodes、namespaces、persistentvolumes、storageclasses、ingressclasses 等集群级只读权限
+- **读取 + 有限修改**:在只读基础上,额外允许驱逐 Pod(`pods/eviction`)、扩缩容 Deployment 和 StatefulSet(`deployments/scale`、`statefulsets/scale`)以及调整 HPA 副本数上下限(`horizontalpodautoscalers`)。这些规则只能改变已有工作负载运行几个副本、以及用同一份配置重建 Pod,无法改动任何 Pod 的镜像、启动命令、环境变量、身份或挂载——因此 `kubectl rollout restart` 和 `kubectl rollout undo` 都会被拒绝(两者在 Kubernetes 里都是对工作负载的 patch),重启工作负载请改用逐个驱逐 Pod。回滚工作负载时,AI SRE 会从 ReplicaSet 历史推算出目标 revision,给出完整的 `kubectl rollout undo --to-revision=N` 命令,由您在集群中执行
- **完全权限**:可读取 Secret、修改 ConfigMap 和 Secret、修改工作负载配置、创建或删除资源、修改 namespace 内的 RBAC;「全部 namespace + 完全权限」还会通过 `ClusterRoleBinding` 授予 `cluster-admin`,可操作集群级资源和集群 RBAC
### 编辑与撤销
-你可以在 Kubernetes App 列表中编辑集群名称、范围和 namespace 权限。将范围改为**共享**与创建共享 App 同门槛:仅限账户 Owner / 管理员操作,普通成员即使编辑自己团队的 App 也不能把它提升为共享,只能把 App 移动到其所属的团队。撤销会立即使连接和 Token 失效,但不会自动删除集群中的 Agent 与 RBAC。控制台会提供卸载命令;请在对应集群执行它。该命令只删除当前 Kubernetes App 的资源,不会删除共享的 `flashduty` namespace。
+您可以在 Kubernetes App 列表中编辑集群名称、范围和 namespace 权限。将范围改为**共享**与创建共享 App 同门槛:仅限账户 Owner / 管理员操作,普通成员即使编辑自己团队的 App 也不能把它提升为共享,只能把 App 移动到其所属的团队。撤销会立即使连接和 Token 失效,但不会自动删除集群中的 Agent 与 RBAC。控制台会提供卸载命令;请在对应集群执行它。该命令只删除当前 Kubernetes App 的资源,不会删除共享的 `flashduty` namespace。
## GitHub 应用
----
-
下面先以 **GitHub** 为例,介绍授权、安装管理与仓库授权的调整;**GitLab** 的流程见下一节。
### 连接 GitHub 组织
-在 GitHub 卡片上发起授权,整个安装在一个弹窗里、通过 GitHub 官方的安装页完成,回调后列表自动刷新。
+授权通过弹窗中的 GitHub 官方安装页完成。
<Steps>
<Step title="发起授权">
- 在 GitHub 卡片上点击 **去授权**(如果该 App 已有安装,按钮显示为 **更多仓库**,带一个 + 号图标)。前端随即打开一个弹窗,加载 GitHub 官方的安装页。
+ 在 GitHub 卡片上点击 **去授权**(已有安装时为 **更多仓库**),在弹出的 GitHub 安装页中继续。
</Step>
<Step title="在 GitHub 上选择组织与仓库">
选择要安装到的**组织**(或个人账户),并授予仓库范围——**所有仓库(All repositories)**或**仅选定仓库(Only select repositories)**。授予的仓库集合决定了 AI SRE 之后能访问哪些仓库。
</Step>
<Step title="确认后自动刷新">
- 你在 GitHub 上确认后,弹窗自动关闭,Apps 页提示 **授权成功** 并刷新安装列表,新组织随即出现。
+ 在 GitHub 上确认后,弹窗自动关闭,新组织出现在安装列表中。
</Step>
</Steps>
<Note>
-若你不是该组织的所有者,GitHub 会把请求转交给组织所有者走「请求安装」的审批流程;审批通过后该安装才会激活。安装到哪个组织、授予哪些仓库,完全由 GitHub 侧的安装页决定,Flashduty 不在中间代为选择。
+如果您不是该组织的所有者,GitHub 会把请求转交组织所有者审批,审批通过后安装才生效。
</Note>
### 安装管理
-每授权一个组织,就在 GitHub 卡片下多出一行安装记录。每行展示:
-
-| 元素 | 说明 |
-|---|---|
-| 组织名 | 安装所在的 GitHub 组织 / 账户登录名 |
-| 状态点 | 一个彩色小圆点 + 文案:**已连接**、**已暂停**、**已撤销** |
-| 仓库数 | 该安装当前授予的仓库数量 |
+每授权一个组织,GitHub 卡片下就多一行安装记录,显示组织名、状态(**已连接**、**已暂停**、**已撤销**)和已授予的仓库数。
<AccordionGroup>
<Accordion title="启用 / 禁用(暂停 / 恢复)" icon="toggle-on">
@@ -146,17 +128,15 @@ Kubernetes App 将集群中的 Agent 接入 AI SRE。创建后,AI SRE 可以
### 新增或调整仓库授权
-某个组织已经连接好了,但你想让 AI SRE 访问该组织里更多的仓库——不必撤销重连。在 **自定义 → 插件 → Apps** 里,对该组织再次点击 **更多仓库**(或直接打开该 App 在 GitHub 上的 **Configure** 页),GitHub 会展示 **Repository access** 选择界面;勾选你要新增的仓库并保存,AI SRE 会**自动重新同步**已授予的仓库列表,新仓库无需重建连接就能用。
+某个组织已经连接好了,但您想让 AI SRE 访问该组织里更多的仓库——不必撤销重连。在 **自定义 → 插件 → Apps** 里,对该组织再次点击 **更多仓库**(或直接打开该 App 在 GitHub 上的 **Configure** 页),GitHub 会展示 **Repository access** 选择界面;勾选您要新增的仓库并保存,AI SRE 会**自动重新同步**已授予的仓库列表,新仓库无需重建连接就能用。
<Note>
-**兜底**:如果新加的仓库在会话里仍报「无法访问 / 404 / 403」,到 GitHub 上打开该 App 的页面(如 `github.com/apps/flashduty`)→ **Configure** → 选中对应组织 → 拉到底部的 **Danger zone** → **Uninstall** 卸载该安装。然后回到 Flashduty 的 **自定义 → 插件 → Apps** 重新授权该组织,并在这一次里一并勾选你需要的**全部**仓库。
+**兜底**:如果新加的仓库在会话里仍报「无法访问 / 404 / 403」,到 GitHub 上打开该 App 的页面(如 `github.com/apps/flashduty`)→ **Configure** → 选中对应组织 → 拉到底部的 **Danger zone** → **Uninstall** 卸载该安装。然后回到 Flashduty 的 **自定义 → 插件 → Apps** 重新授权该组织,并在这一次里一并勾选您需要的**全部**仓库。
</Note>
## GitLab 应用
----
-
-**GitLab** 应用连接一个 GitLab 实例——不管是 **GitLab.com**、**极狐 GitLab**(jihulab.com SaaS 或私有化发行版),还是你自己的其他**自建(Self-managed)**实例,连接方式都**完全一样**:先在该实例上注册一个 OAuth 应用,再完成授权。授权之后,AI SRE 就能在授权范围内的仓库里读代码、调查变更 / MR、并在你需要时提 issue、开 MR。和 GitHub 一样,**你不需要粘贴任何个人令牌**:Flashduty 通过 OAuth 拿到授权后,会为你的账户配置一个专属的机器人身份来完成实际访问。
+**GitLab** 应用可以连接 **GitLab.com**、**极狐 GitLab**(jihulab.com SaaS 或私有化发行版)或其他**自建**实例,方式完全相同:先在该实例上注册一个 OAuth 应用,再完成授权。之后 AI SRE 就能在授权范围内读代码、调查变更 / MR,并按您的要求提 issue 或开 MR。和 GitHub 一样,**无需粘贴个人令牌**,Flashduty 会为您的账户配置专属机器人身份完成访问。
### 连接 GitLab 实例
@@ -172,15 +152,14 @@ Kubernetes App 将集群中的 Agent 接入 AI SRE。创建后,AI SRE 可以
连接和重新授权 GitLab 时的网络请求会从这里选择的环境发出。GitLab.com、极狐 GitLab 等公网实例可使用默认云端环境;只有内网可访问的自建实例,请选择能够访问它的 BYOC Runner。系统不会在 Runner 离线或不可达时自动切换环境,请选择可用环境后重新发起连接或授权。
</Step>
<Step title="在该实例上注册一个 OAuth 应用">
- 连接向导会展示一个**可复制的 Redirect URI**。带着它去你填写的 GitLab 实例创建一个 OAuth 应用:group **Owner** 在 **Group Settings → Applications** 创建一个归属分组的应用;在 **GitLab.com** 上,如果你不是任何分组的 Owner,也可以在 **User Settings → Applications** 创建一个归属你个人账户的应用;实例管理员也可以在 **Admin Area → Applications** 创建。填入向导给出的 Redirect URI,勾选 **Confidential**,Scopes 只勾 **api**。创建后 GitLab 会给出一个 **Application ID** 和一个 **Secret**,回到连接向导粘贴这两项。
+ 连接向导会展示一个**可复制的 Redirect URI**。带着它去您填写的 GitLab 实例创建一个 OAuth 应用:group **Owner** 在 **Group Settings → Applications** 创建一个归属分组的应用;在 **GitLab.com** 上,如果您不是任何分组的 Owner,也可以在 **User Settings → Applications** 创建一个归属您个人账户的应用;实例管理员也可以在 **Admin Area → Applications** 创建。填入向导给出的 Redirect URI,勾选 **Confidential**,Scopes 只勾 **api**。创建后 GitLab 会给出一个 **Application ID** 和一个 **Secret**,回到连接向导粘贴这两项。
- <Tip>这一步对**每一个** GitLab 实例都一样——GitLab.com、极狐 GitLab(jihulab.com SaaS 及其私有化发行版)、或任何其他自建实例:地址不同,注册 OAuth 应用、粘贴 Application ID / Secret 的步骤完全相同。</Tip>
</Step>
<Step title="在弹出的窗口中完成 GitLab 授权">
- 这一步会显示这次要用哪个实例的哪个 OAuth 应用来授权;如果想换一个应用,点击 **更换 OAuth 应用** 回到上一步重新注册。确认无误后,向导打开一个弹窗,跳转到 GitLab 的官方授权页;用你的 GitLab 账户登录并确认授权。授权完成后弹窗自动关闭,向导进入下一步。
+ 确认要使用的实例和 OAuth 应用(需要换应用时点击 **更换 OAuth 应用**),然后在弹出的 GitLab 授权页登录并确认。
</Step>
<Step title="选择要授权的分组与项目">
- AI SRE 展示一个仓库选择器,列出**你拥有 Owner 角色的分组**和**你拥有 Maintainer 角色的项目**。勾选想让 AI SRE 访问的分组 / 项目并保存——勾选一个分组即覆盖其下的所有项目,包括之后新建的项目。
+ AI SRE 展示一个仓库选择器,列出**您拥有 Owner 角色的分组**和**您拥有 Maintainer 角色的项目**。勾选想让 AI SRE 访问的分组 / 项目并保存——勾选一个分组即覆盖其下的所有项目,包括之后新建的项目。
</Step>
</Steps>
@@ -190,12 +169,12 @@ Kubernetes App 将集群中的 Agent 接入 AI SRE。创建后,AI SRE 可以
### 机器人身份与权限
-保存仓库选择后,Flashduty 会在这些分组 / 项目下为账户配置一个专属机器人(优先使用服务账号;实例不支持服务账号时,回退为分组 / 项目级的访问令牌),供 AI SRE 会话使用。无论哪种方式,机器人的权限都被限制在 **Developer** 级别,和你在 GitLab 里能授予的最小权限一致。令牌会在到期前**自动轮换**,无需你手动处理。
+保存仓库选择后,Flashduty 会在这些分组 / 项目下为账户配置一个专属机器人(优先使用服务账号;实例不支持服务账号时,回退为分组 / 项目级的访问令牌),供 AI SRE 会话使用。无论哪种方式,机器人的权限都被限制在 **Developer** 级别,和您在 GitLab 里能授予的最小权限一致。令牌会在到期前**自动轮换**,无需您手动处理。
-如果这个 GitLab 实例不支持服务账号,机器人会回退为分组 / 项目级令牌——这类令牌本身只能绑定单个分组或项目,因此仓库选择器会限制为最多选择**一个**分组或一个项目。若你在多选状态下勾选了多个分组 / 项目并保存,Flashduty 会提示「该 GitLab 实例不支持服务账号,请仅选择一个分组或一个项目后重试」,并把选择器切换为**单选模式**:之后再勾选新的分组或项目会自动清空其余已选项,需要重新只保留一个分组或一个项目后再次保存。
+如果实例不支持服务账号,机器人会改用分组 / 项目级令牌,此时只能选择**一个**分组或一个项目。
<Warning>
-**GitLab.com 上的一条限制**:GitLab 官方规定,分组 / 项目级访问令牌只在**付费(非免费、非试用)命名空间**上可用。连接 GitLab.com 本身不受影响,但如果你要授权的分组 / 项目所在命名空间是免费版或试用版,机器人配置会失败,界面上会展示一条来自 GitLab 的说明("provisioning_denied")。把对应命名空间升级到付费版后重新授权即可。
+**GitLab.com 上的一条限制**:GitLab 官方规定,分组 / 项目级访问令牌只在**付费(非免费、非试用)命名空间**上可用。连接 GitLab.com 本身不受影响,但如果您要授权的分组 / 项目所在命名空间是免费版或试用版,机器人配置会失败,界面上会展示一条来自 GitLab 的说明("provisioning_denied")。把对应命名空间升级到付费版后重新授权即可。
</Warning>
### 管理已连接的实例
@@ -213,43 +192,37 @@ GitLab 卡片下会显示当前连接的实例地址与状态。
## AI SRE 如何在仓库里工作
----
-
-授权之后你无需任何额外配置。当你在会话里让 AI SRE 处理某个仓库的任务时,它会像一名加入项目的工程师那样工作——先理解,再动手,最后验证。这套行为分别由内置的 `github` Skill 与 `gitlab` Skill 约束。
+授权之后您无需任何额外配置。当您在会话里让 AI SRE 处理某个仓库的任务时,它会像一名加入项目的工程师那样工作——先理解,再动手,最后验证。这套行为分别由内置的 `github` Skill 与 `gitlab` Skill 约束。
**典型动作**
- **进入仓库**:把仓库 clone 进自己的工作区,并优先阅读仓库自带的约定(`CLAUDE.md`、`AGENTS.md`、`README`、`CONTRIBUTING`)。
- **调查变更 / PR / MR**:用 `git log`,以及 GitHub 上的 `gh pr list` / `gh pr view` / `gh pr diff` / `gh search prs`,或 GitLab 上等效的 `glab mr list` / `glab mr view` / `glab mr diff`,追溯故障 / 变更工单里提到的 PR / MR、看某次发布包含了什么、在决策前读懂一段 diff。
-- **改动并提交**:新建分支、用最小的 diff 改动,用 `gh pr create` 或 `glab mr create` 开一个可评审的 PR / MR,或用 `gh issue create` / `glab issue create` 提一个 issue,并把链接回报给你。
+- **改动并提交**:新建分支、用最小的 diff 改动,用 `gh pr create` 或 `glab mr create` 开一个可评审的 PR / MR,或用 `gh issue create` / `glab issue create` 提一个 issue,并把链接回报给您。
**硬性护栏**——这些规则 Agent 绝不逾越:
- **绝不强推**(`git push --force`),**绝不直接推默认分支**——一律走「分支 + PR / MR」。
-- **一个 PR / MR 只装一处逻辑变更**,保持可评审;改动一旦膨胀超出聚焦的 diff,就停下把分析交回给你。
+- **一个 PR / MR 只装一处逻辑变更**,保持可评审;改动一旦膨胀超出聚焦的 diff,就停下把分析交回给您。
- 绝不删分支、关闭他人的 issue / PR / MR,或改动仓库设置;绝不提交密钥、凭证或构建产物。
<Note>
-如果在云会话里 Agent 报告无法访问仓库,通常是账户尚未授权对应的 App(GitHub 或 GitLab)、或没有把目标仓库 / 分组纳入授权范围——到 **自定义 → 插件 → Apps** 补充授权即可。Agent **不会**向你索要任何令牌。
+如果在云会话里 Agent 报告无法访问仓库,通常是账户尚未授权对应的 App(GitHub 或 GitLab)、或没有把目标仓库 / 分组纳入授权范围——到 **自定义 → 插件 → Apps** 补充授权即可。Agent **不会**向您索要任何令牌。
</Note>
## 权限与范围
----
-
-GitHub App 与 GitLab App 的**授权**与**撤销 / 断开**都是**账户级**操作。**账户是唯一的安全边界**,团队在这里只是归属 / 审计标记:账户内任何具备相应权限的成员都可以完成授权、撤销 / 断开、或启停整个 App;会话在用到某仓库时,也从账户内当前有效的安装取得访问凭证。账户内的成员共享同一套授权——这与 AI SRE 其它资源「使用 = 账户级、归属 = 团队标记」的模型一致。
+GitHub App 与 GitLab App 的授权、撤销 / 断开都是**账户级**操作:账户内有相应权限的成员都可以操作,成员共享同一套授权,会话使用账户内当前有效的安装访问仓库。团队只用于归属标记,**账户是唯一的安全边界**。
两者的范围模型略有差别:**GitHub App** 允许同一账户安装多个组织,各自独立启停 / 撤销;**GitLab App** 每个账户**同一时间只能连接一个** GitLab 实例——要切换到另一个实例,需要先断开当前这个。
## 相关页面
----
-
<CardGroup cols={2}>
<Card title="MCP(外部工具)" icon="plug" href="/zh/ai-sre/mcp">
通过 Model Context Protocol 接入外部工具与数据源。
</Card>
- <Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+ <Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
在会话中观察 Agent 如何 clone 仓库、读 diff、开 PR / MR。
</Card>
<Card title="运行环境(BYOC)" icon="server" href="/zh/ai-sre/environments">
diff --git a/zh/ai-sre/artifacts.mdx b/zh/ai-sre/artifacts.mdx
index 65279e94..ada8dd70 100644
--- a/zh/ai-sre/artifacts.mdx
+++ b/zh/ai-sre/artifacts.mdx
@@ -5,152 +5,92 @@ keywords: ["AI SRE", "产物", "Artifacts", "present_files", "publish_artifact",
sidebarTitle: 产物
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
产物(Artifact)是 AI SRE 在会话中用 `present_files` 工具产出、再发布到产物库的文件。发布有两条路径,两者能接受的类型并不相同:
- **Agent 工具 `publish_artifact`**:只发布 HTML / Markdown 文档(`.html` `.htm` `.md` `.markdown`)——一份自包含的报告或页面,最典型的是在会话里输入 `/insight` 生成的运营洞察报告。其它类型一律被拒绝,返回 `unsupported_format`。
- **控制台里 `present_files` 文件旁的「发布到产物库」按钮**(见下文 [新建产物](#新建产物)):可发布的类型更宽:
-| 类别 | 常见扩展名 |
-|---|---|
-| 网页与文档 | `.html` `.htm` `.md` `.markdown` `.txt` `.log` |
-| 数据与配置 | `.csv` `.tsv` `.json` `.yaml` `.yml` `.xml` `.toml` `.ini` |
-| 图片 | `.png` `.jpg` `.jpeg` `.gif` `.svg` `.webp` |
-| PDF | `.pdf` |
-| 源码 | `.py` `.go` `.js` `.mjs` `.ts` `.jsx` `.tsx` `.java` `.c` `.h` `.cpp` `.cs` `.rb` `.rs` `.php` `.sh` `.sql` `.kt` `.swift` `.scala` `.css` `.vue` `.svelte` `.proto` `.tf` `.hcl` 等 |
-| 压缩包 | `.zip` `.tar` `.gz` `.tgz` |
+ <Accordion title="查看可发布的文件类型">
+
+ | 类别 | 常见扩展名 |
+ |---|---|
+ | 网页与文档 | `.html` `.htm` `.md` `.markdown` `.txt` `.log` |
+ | 数据与配置 | `.csv` `.tsv` `.json` `.yaml` `.yml` `.xml` `.toml` `.ini` |
+ | 图片 | `.png` `.jpg` `.jpeg` `.gif` `.svg` `.webp` |
+ | PDF | `.pdf` |
+ | 源码 | `.py` `.go` `.js` `.mjs` `.ts` `.jsx` `.tsx` `.java` `.c` `.h` `.cpp` `.cs` `.rb` `.rs` `.php` `.sh` `.sql` `.kt` `.swift` `.scala` `.css` `.vue` `.svelte` `.proto` `.tf` `.hcl` 等 |
+ | 压缩包 | `.zip` `.tar` `.gz` `.tgz` |
+
+ </Accordion>
不在上表范围内的文件,会话中不会出现「发布到产物库」按钮。
发布后的产物初始继承来源会话的作用域:来自个人会话的产物归创建者「个人」所有;来自绑定了团队的会话的产物归该「团队」所有,可分享给账户内的其它成员查看。拥有编辑权限时,之后还可以修改产物范围。
-入口:左侧导航 **AI SRE → 产物**,对应路由 `/ai-sre/artifacts`。
+入口:左侧导航 **AI SRE → 产物**。
<Note>
-产物库本身没有手动上传或创建文件的入口——产物都是 Agent 在会话中用工具产出并发布的;控制台只提供浏览、检索与管理已发布产物的能力。
+产物库不能直接上传文件:产物都由 Agent 在会话中产出并发布,**新建产物** 也是跳转到会话完成。产物库负责浏览、检索与管理已发布的产物。
</Note>
## 列表页
----
-
-### 搜索与范围筛选
-
-- **搜索框**:按标题模糊搜索已发布产物,输入停顿 300 毫秒后自动查询。
-- **范围**:**全部 / 个人 / 团队** 三态切换(与 AI SRE 下其它资源统一的两级作用域一致)。选择「团队」后会展开一个可搜索、可多选具体团队的选择器;不选择任何团队等价于「我可见的全部团队」。
-
-### 视图切换与排序
+- **搜索与筛选**:按标题搜索;按范围(**全部 / 个人 / 团队**)筛选,选择「团队」后可多选具体团队,不选则为您可见的全部团队。
+- **视图**:右上角可切换卡片视图(默认)或列表视图,选择会保存在浏览器中。列表视图显示名称、所属范围(团队名或个人产物的创建者)、来源对话(可点击跳转;会话已删除时显示「会话已删除」)、生成时间、修改时间、置顶按钮和操作。
+- **排序**:可按生成时间或修改时间排序,默认按**修改时间降序**。无论按什么排序,您置顶的产物始终排在最前面(最近置顶的在前)。
+- **分页**:每页 12 / 24 / 48 条,默认 24 条。
+- **地址可分享**:范围、搜索词、排序和页码都记录在页面地址中,复制地址即可分享或收藏筛选后的列表;从详情页返回时也会回到原来的位置。
-列表页右上角提供 **卡片视图 / 列表视图** 切换,选择会保存在浏览器本地(下次进入沿用);卡片视图为默认展示。
-
-**列表视图** 以表格展示产物,列定义如下:
-
-| 列 | 说明 |
-|---|---|
-| 名称 | 产物标题,点击进入详情页 |
-| 所属范围 | 团队产物显示团队名称,个人产物显示创建者姓名 |
-| 来自对话 | 产物来源会话标题,点击跳转到对应会话;来源会话已删除或无标题时显示「会话已删除」纯文本 |
-| 生成时间 | 产物创建时间 |
-| 修改时间 | 产物最后更新时间 |
-| 置顶 | 一个只有图标的按钮(该列没有表头),点击即可为自己置顶或取消置顶,详见下文 [置顶](#置顶) |
-| 操作 | 重命名、下载、删除等 |
-
-**生成时间** 与 **修改时间** 列支持点击列头排序(升序 / 降序切换),排序在服务端执行;默认按 **修改时间降序**。
-
-无论选哪种排序,**你置顶的产物始终排在最前面**(最近置顶的排在更前),其后才按所选字段排序。
-
-范围、搜索词、排序、页码与每页条数都会反映在页面地址上(形如 `?scope=team&teams=1,2&q=重建&page=2&size=48`),因此直接复制地址就能分享或收藏一份**已筛选**的列表;从产物详情页返回时也会回到原来的筛选与位置,而不是被重置成默认视图。
-
-每页条数可选 **12 / 24 / 48**,默认 **24**(对应地址里的 `?size=`,等于默认值时不会写进地址)。地址里被手工改成其它数值时,会取最接近的一档生效,而不是照单执行。
-
-### 产物卡片
-
-每张卡片展示:
-
-- 顶部预览区渲染的是产物**自身内容的缩略图**:HTML 取文件开头(最多 256 KiB)按一个 1200×630 的桌面页面缩放成小页面,Markdown 在同样的缩放页上排版,图片直接显示图片本身,纯文本显示开头 24 行(最多 1400 字符);PDF 以及其它无法渲染的类型显示一个空框。缩略图是一张不可交互的静态画面——它以 `sandbox=''` 渲染,脚本不会执行,链接与按钮也点不动。它还是懒加载的:卡片接近视口(约 400px)之前不签名、不下载,显示为空框骨架;
-- 类型图标:按文件扩展名与内容类型区分,图片、PDF、HTML、Markdown、表格(CSV / TSV)、JSON、压缩包、源码各有专属图标,无法识别时回退为通用文件图标。它是骑在缩略图与正文之间分隔线上的 30×30 角标,不再占据预览区;
-- 标题(单行显示,超出省略;鼠标悬停可看到完整标题);
-- 时间信息为标题下方灰色说明行里的 **「编辑于 …」** 相对时间(取产物的最后更新时间;创建后再未更新过的产物,更新时间即创建时间)——刚刚 / N 分钟前 / N 小时前 / N 天前;相对时间适用于任何时长,**再久的产物也只显示「N 天前」,不会回退为具体日期**;鼠标悬停该时间可看到精确到分钟的时刻,列表视图的 **生成时间 / 修改时间** 两列则直接给出精确时刻;
-- 同一条说明行里还有作用域(小图标 + 名称:团队产物显示团队名称,个人产物显示创建者姓名)——卡片上不使用彩色作用域徽标,徽标只出现在列表视图与详情页;产物开启了公开链接时,说明行开头还会多一个带 tooltip 的小地球字形;已置顶的产物在说明行末尾显示一个图钉字形。
-
-点击卡片正文会打开该产物的详情页;鼠标悬停在卡片上会在右上角露出「更多操作」按钮(触屏设备上始终可见),它旁边还有一个同样是悬停露出的图钉按钮,点一下即可置顶或取消置顶。分享面板里的公开链接预览用的也是这套缩略图。
+卡片展示内容缩略图(HTML、Markdown、图片和纯文本有静态预览,PDF 等显示空框)、类型图标、标题、编辑时间(悬停可看精确时刻)、作用域,以及是否已开启公开链接、是否已置顶。
### 置顶
-列表视图的每一行和每张卡片都有图钉按钮——卡片上的图钉与「更多操作」一起放在右上角,悬停露出(触屏设备常显);列表行里的图钉是一个固定宽度的独立列,位于「修改时间」与操作按钮之间。「更多操作」菜单的第一项也是这个开关,按当前状态显示为「置顶」或「取消置顶」。
-
-置顶是**每个人自己的偏好**,不是一次编辑:
+在列表或卡片上点击图钉按钮,或在 **更多操作** 菜单中选择 **置顶** / **取消置顶**。
-- 任何你能看到的产物都可以置顶——他人的个人产物、团队产物都包括在内,**不需要编辑权限**(重命名、修改范围、删除才需要);
-- 置顶只把产物排到**你自己的**产物库最前面,不修改产物的内容、标题或作用范围,也不影响其它成员看到的顺序;
-- 置顶与取消置顶都是幂等的:重复置顶只会刷新置顶时间(置顶时间较晚的排在更前面),取消一个从未置顶过的产物也不会报错;
-- 置顶后列表会整页重新拉取。排序由服务端负责,所以在第 2 页置顶的产物会移动到第 1 页,而不是就地重排。
-
-产物列表项上的 `pinned_at` 字段就是**调用者本人的**置顶时间(Unix 毫秒),未置顶时不返回该字段——同一条产物在不同成员那里可以有不同的 `pinned_at`。
+置顶是**您个人的偏好**,不是编辑:任何您能看到的产物(包括他人的个人产物和团队产物)都能置顶,**不需要编辑权限**;它只把产物排到您自己的产物库最前面,不改变产物本身,也不影响其他成员看到的顺序。在第 2 页置顶的产物会移到第 1 页。
### 新建产物
-点击页面右上角的 **新建产物**,会跳转到会话页面并预填一段引导草稿:
-
-> 我想在 Flashduty AI-SRE 中创建一个可发布的产物:一个自包含的网页或报告,完成后发布到产物库。请先问我几个必要问题,包括目标读者、内容/数据、交互和视觉风格,然后构建并发布它。
-
-Agent 会先向你确认目标读者、内容/数据来源、交互与视觉风格等细节,再动手构建并发布,而不是打开一个表单直接创建。
+点击页面右上角的 **新建产物**,会跳转到会话页面并预填一段引导草稿。Agent 会先向您确认目标读者、内容/数据来源、交互与视觉风格,再构建并发布产物——不需要填写表单。
<Tip>
-除此之外,任何一次会话中用 `present_files` 展示出来的文件旁边也带有一个「发布到产物库」按钮,可以把该次会话已经产出的文件直接发布为产物——这是比「新建产物」更直接的路径,不必再走一次完整对话。
+如果会话里已经产出了文件,直接点击该文件旁的「发布到产物库」按钮更快,不必再走一次完整对话。
</Tip>
## 卡片操作
----
-
每张卡片右上角的「更多操作」菜单提供:
| 操作 | 说明 |
|---|---|
-| 置顶 / 取消置顶 | 菜单的第一项,按当前状态显示为「置顶」(未置顶时)或「取消置顶」。置顶是**个人偏好**,不经过编辑权限判断——任何你能看到的产物都能为自己置顶,且只改变你自己的列表顺序,不修改产物本身(详见上文 [置顶](#置顶)) |
-| 复制链接 | 复制该产物详情页的完整 URL,可分享给账户内的其它成员打开 |
-| 下载 | 仅当产物关联着文件(`file_id` 非空)时出现,下载原始文件 |
-| 重命名 | 仅当你对该产物有编辑权限时出现;打开一个对话框修改标题 |
-| 修改范围 | 仅当你对该产物有编辑权限时出现;选择个人或可访问的团队。只有产物创建者可以将范围改为个人 |
-| 删除 | 仅当你对该产物有编辑权限时出现;删除前需二次确认,删除后产物从产物库移除,但来源会话与文件本身保留不受影响 |
+| 置顶 / 取消置顶 | 只改变您自己的列表顺序,不需要编辑权限,见上文 [置顶](#置顶) |
+| 复制链接 | 复制该产物详情页的链接,可分享给账户内的其他成员 |
+| 下载 | 产物有关联文件时出现,下载原始文件 |
+| 重命名 | 需要编辑权限 |
+| 修改范围 | 需要编辑权限;可选个人或可访问的团队,只有创建者可以改回个人 |
+| 删除 | 需要编辑权限,删除前需确认。只从产物库移除,来源会话与文件本身保留 |
## 详情页
----
-
-详情页路由为 `/ai-sre/artifacts/:artifactId`,顶部工具栏提供:
-
-- **标题**:对有编辑权限的产物可直接点击标题进行行内编辑(无需跳转到独立表单),按 Enter 保存、Esc 取消;
-- **创建者**:标题下方显示「〈创建者〉创建的产物」;
-- **分享**:打开分享面板,可选择「仅账户内」或「公开链接」两种可见范围,详见下文 [分享产物](#分享产物);
-- **删除**:仅在你有编辑权限时显示,删除前需二次确认;
-- **更多操作**:只有以下至少一项可用时才会出现这个菜单——
- - **下载**:仅当产物关联着文件时出现。
- - **修改范围**:仅当你有编辑权限时出现,可将产物移至可访问的团队;产物创建者还可以改回个人范围。
+详情页顶部提供:
-标题下方是一条 **来源会话信息条**:
+- **标题**:有编辑权限时可直接点击标题修改,按 Enter 保存、Esc 取消;标题下方显示创建者;
+- **分享**:选择「仅账户内」或「公开链接」,见下文 [分享产物](#分享产物);
+- **删除**、**修改范围**(需要编辑权限)与 **下载**(有关联文件时);
+- **来源会话**:显示编辑时间与「最近更新来自会话 〈会话名〉」,点击可打开来源会话的完整对话。来源会话已删除或您无权访问时不显示,产物本身仍可查看。
-- 展示产物自身的 **「编辑于 …」** 相对时间(与列表卡片一致,鼠标悬停该时间可看到精确到分钟的时刻);
-- 当产物的来源会话你仍有权限访问时,信息条里会出现 **「最近更新来自会话 〈会话名〉」** 按钮——会话名由 `/safari/session/get` 解析来源会话得到,点击跳转到该会话的完整对话(`chat?session_id=<会话ID>`,消息、工具调用、产物历史)。来源会话已删除或无权访问时,该按钮隐藏,产物本身仍可正常查看。
-
-正文区域按产物的实际内容类型渲染(例如 HTML 报告会直接内联展示为页面)。
+正文按产物的内容类型渲染(例如 HTML 报告直接内联展示为页面)。
<Note>
-在手机上打开的详情页会退化为**只读阅读器**:标题不再可行内编辑,分享、修改范围、删除入口一并隐藏,工具栏也不再显示返回列表按钮、文件类型图标、作用域徽标、公开链接徽标、「编辑于」时间与「最近更新来自会话」入口,只保留标题与产物正文;产物关联着文件时,「更多操作」里仍可下载原件。列表页与卡片视图不受影响。
+在手机上,详情页是**只读阅读器**:只显示标题和正文,不能编辑、分享、修改范围或删除;产物有关联文件时,仍可在「更多操作」里下载。
</Note>
## 分享产物
----
-
详情页工具栏的 **分享** 按钮会打开分享面板。面板顶部的 **管理权限** 列出谁可以管理这个产物的分享(创建者标记为「所有者」,团队产物还会列出团队成员);下方的 **可见权限** 提供两种模式:
| 模式 | 谁能打开 | 内容 |
@@ -162,19 +102,19 @@ Agent 会先向你确认目标读者、内容/数据来源、交互与视觉风
<Tip>**版本要求**:公开链接需要 On-call 专业版及以上订阅。[了解更多](https://flashcat.cloud/flashduty/price/)</Tip>
-选择 **公开链接** 后,面板会先展示一段内容预览和风险提示,再由你点击 **生成公开链接** 才真正生效:
+选择 **公开链接** 后,面板会先展示一段内容预览和风险提示,再由您点击 **生成公开链接** 才真正生效:
<Warning>
生成公开链接后,任何拿到链接的人都可以查看此产物,链接也可能被继续转发。请勿分享密钥、个人信息或未经授权的第三方内容。
</Warning>
-生成成功后链接会自动复制到剪贴板(提示「公开链接已生成,已复制到剪贴板」)。公开链接的形式为 `https://<控制台域名>/share/artifact/<产物 ID>`——它以产物自身的 ID 为标识,不携带令牌;匿名访问完全由 CDN 提供,不经过任何需要登录的接口。
+生成后链接会自动复制到剪贴板。公开链接的形式为 `https://<控制台域名>/share/artifact/<产物 ID>`,不含令牌,任何拿到链接的人都能访问。
<Note>
私有化部署下,公开链接依赖实例配置了可达的分享静态资源地址(CDN)。未配置时,分享面板不会出现「公开链接」选项,仅可「仅账户内」分享;此前已生成的公开链接仍可正常管理与撤销。SaaS 环境不受此限制。
</Note>
-打开公开链接的访问者会看到只读的内容页:页面顶部在标题旁标注「**内容由用户生成,未经核实。**」声明,并提供「**反馈**」入口——点击跳转到举报表单(已自动预填当前链接),任何人都可以向 Flashduty 举报不当内容;页面同时提供「登录」入口,引导访问者登录控制台。
+访问者看到的是只读页面,标题旁注明「内容由用户生成,未经核实」,并提供 **反馈**(举报不当内容)和 **登录** 入口。
| 操作 | 说明 |
|---|---|
@@ -188,50 +128,43 @@ Agent 会先向你确认目标读者、内容/数据来源、交互与视觉风
## 更新已发布产物
----
+再次发布同一个文件**不会**静默覆盖已发布的产物。Agent 更新产物时必须指明要更新哪个产物,以及它基于哪个版本修改;如果产物在此期间被别人改过,Agent 会先读取当前已发布的内容、合并后再重试,而不是直接覆盖。更新后产物链接与 ID 不变。
-重新发布同一个文件**不会**静默覆盖已发布的产物。Agent 用 `publish_artifact` 更新时,必须同时带上该产物的 `artifact_id` 和上一次发布返回的 `if_revision`(一个不透明的版本指纹,形如 `rev_…`):
+另外几点:
-| 情况 | 返回 | 结果 |
-|---|---|---|
-| `artifact_id` 与 `if_revision` 都对得上 | `status: published`,附 `operation`(`created` / `updated` / `unchanged`)与新的 `revision` | 产物原地更新(`unchanged` 表示内容没变),链接与产物 ID 不变 |
-| 只给了文件路径(没给 `artifact_id`),且内容与已发布版本不同 | `status: needs_review`,`reason: explicit_artifact_id_required` | 什么都不发布 |
-| 给了 `artifact_id` 但没给 `if_revision` | `status: needs_review`,`reason: revision_required` | 什么都不发布 |
-| `if_revision` 与当前版本不一致(产物在你拿到 revision 之后被改过) | `status: needs_review`,`reason: revision_conflict` | 什么都不发布 |
+- 内容没有变化时,产物不会被改动。
+- 在会话中重新展示同一个文件**不会**更新已发布的产物;要更新,请让 Agent 重新发布。
+- 已删除的产物不会被 Agent 重新发布「复活」;只有您在会话里点击文件旁的「发布到产物库」按钮,才能恢复已删除的产物。
-返回 `needs_review` 时,Agent 会同时把**当前已发布内容**的副本写进会话工作区,并带上当前的 `revision`;它先读这份副本、确认合并后再用同一个 `artifact_id` 与新的 `revision` 重试,而不是直接覆盖。
+<Accordion title="技术细节:publish_artifact 的版本校验与返回值">
+Agent 用 `publish_artifact` 更新时,须同时带上该产物的 `artifact_id` 和上一次发布返回的 `if_revision`(形如 `rev_…` 的版本指纹):
-另外几点:
+| 情况 | 返回 | 结果 |
+|---|---|---|
+| `artifact_id` 与 `if_revision` 都对得上 | `status: published`,附 `operation`(`created` / `updated` / `unchanged`)与新的 `revision` | 产物原地更新 |
+| 只给了文件路径,且内容与已发布版本不同 | `status: needs_review`,`reason: explicit_artifact_id_required` | 不发布 |
+| 给了 `artifact_id` 但没给 `if_revision` | `status: needs_review`,`reason: revision_required` | 不发布 |
+| `if_revision` 与当前版本不一致 | `status: needs_review`,`reason: revision_conflict` | 不发布 |
-- 内容与已发布版本逐字节一致时返回 `operation: unchanged`,产物不会被改动。
-- 用 `present_files` 重新展示同一个文件**不会**更新已发布的产物——它只提供预览与下载,发布更新要走 `publish_artifact`。
-- 产物已被删除时,Agent 用路径重新发布会以 `artifact_deleted` 失败,而不是把删掉的产物复活;只有你在会话里点 `present_files` 文件旁的「发布到产物库」按钮,才会恢复一个已删除的产物。
-- 发布失败会带一个错误码返回:`unsupported_format` / `permission_denied` / `artifact_deleted` / `storage_unavailable` / `file_too_large` / `invalid_path`,其中 `storage_unavailable` 可以重试。提交结果无法确认时返回 `status: unknown` 与一个 `op_…` 操作 ID,此时 Agent 不会另建一份产物。
+返回 `needs_review` 时,当前已发布内容的副本与当前 `revision` 会写进会话工作区。失败时返回错误码:`unsupported_format` / `permission_denied` / `artifact_deleted` / `storage_unavailable`(可重试)/ `file_too_large` / `invalid_path`;提交结果无法确认时返回 `status: unknown` 与 `op_…` 操作 ID,Agent 不会另建一份产物。
+</Accordion>
## 权限
----
-
-产物是否可编辑(重命名、修改范围、删除)由后端返回的 `can_edit` 字段决定,满足以下任一条件即可管理该产物:
+满足以下任一条件,即可重命名、修改范围或删除产物:
| 条件 | 说明 |
|---|---|
| 创建者本人 | 发布该产物所属会话的所有者 |
-| 账户 Owner / 管理员 | 对账户内任意产物(无论个人还是团队作用域)都有管理权限 |
-| 团队成员(仅团队产物) | 当产物属于某个团队(`team_id > 0`)时,该团队的其它成员也可以管理它 |
+| 账户 Owner / 管理员 | 账户内任意产物,包括他人的个人产物(这一点与自动化规则不同) |
+| 团队成员 | 团队产物的该团队成员 |
-没有编辑权限的产物,卡片与详情页只提供「置顶」「复制链接」「下载」等只读操作,「重命名」「删除」按钮不会出现。其中**置顶不参与这套判断**:它是个人偏好而不是编辑,任何你能看到的产物(包括他人的个人产物)都能为自己置顶,只改变你自己的列表顺序,不影响任何人。
-
-<Note>
-这与自动化规则的权限模型不同:账户 Owner / 管理员对**任意**产物(含他人的个人产物)都有管理权限,不存在『个人资源管理员无豁免』的限制。
-</Note>
+没有编辑权限时,只能置顶、复制链接和下载。
## 相关页面
----
-
<CardGroup cols={2}>
- <Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+ <Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
了解会话如何用 present_files 工具展示文件——产物正是从这些文件发布而来。
</Card>
<Card title="使用洞察" icon="gauge-high" href="/zh/ai-sre/insight">
diff --git a/zh/ai-sre/automations.mdx b/zh/ai-sre/automations.mdx
index b7e9a6f9..39c0523d 100644
--- a/zh/ai-sre/automations.mdx
+++ b/zh/ai-sre/automations.mdx
@@ -5,42 +5,36 @@ keywords: ["AI SRE", "自动化", "Automation", "巡检", "定时任务", "cron"
sidebarTitle: 自动化
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
-自动化(Automation)让 AI SRE 按你设定的节奏自行跑一次 **隐藏会话**——它不出现在控制台左侧的会话列表里,而是在后台用一段固定的 **任务提示词** 驱动 Agent 完成工作,产出巡检、运营洞察或故障复盘等结果。
+自动化(Automation)让 AI SRE 按您设定的节奏自行跑一次 **隐藏会话**——它不出现在控制台左侧的会话列表里,而是在后台用一段固定的 **任务提示词** 驱动 Agent 完成工作,产出巡检、运营洞察或故障复盘等结果。
每条自动化是一条 **规则(rule)**。一条规则至少携带一种触发方式:
- **按周期执行**:用 4 段或 5 段 cron 设定运行节奏(例如每周一上午、每天 09:15),到点自动跑。
-- **经 API 调用**:生成一个带 Bearer Token 的触发地址,你在外部系统里用 `POST` 按需触发,把本次运行的上下文随请求体一起带进来。
+- **经 API 调用**:生成一个带 Bearer Token 的触发地址,您在外部系统里用 `POST` 按需触发,把本次运行的上下文随请求体一起带进来。
- **On-call 故障触发**:选择要监听的 On-call 协作空间与严重程度,当匹配故障产生时自动拉起一次诊断运行。
-什么时候用它:把重复的例行巡检(如每日健康巡检)、定期产出的洞察 / 复盘报告交给 AI SRE 自动跑;或者把 AI SRE 接进你已有的流水线、变更系统或 On-call 故障流,在事件发生时拉起一次诊断。
+什么时候用它:把重复的例行巡检(如每日健康巡检)、定期产出的洞察 / 复盘报告交给 AI SRE 自动跑;或者把 AI SRE 接进您已有的流水线、变更系统或 On-call 故障流,在事件发生时拉起一次诊断。
入口:左侧导航 **AI SRE → 自动化**,对应路由 `/ai-sre/automations`。
<Note>
-自动化跑出的每一次运行,本质上仍是一个 AI SRE 会话——只是它被标记为隐藏,不混进你的日常会话列表。你随时可以从运行历史点进去,看到这次运行完整的对话、工具调用与产物。
+自动化跑出的每一次运行,本质上仍是一个 AI SRE 会话——只是它被标记为隐藏,不混进您的日常会话列表。您随时可以从运行历史点进去,看到这次运行完整的对话、工具调用与产物。
</Note>
## 新建自动化
----
-
-页面右上角提供两个创建入口:outline 样式的 **通过聊天创建** 按钮,点击后跳转到会话页面并带一段预填的引导提示——「我们来创建一个自动化任务。先说明自动化任务如何运作。然后通过提问了解我需要安排什么任务,以及它应在何时运行。」——由 Agent 通过对话帮你确定任务内容和触发方式,跳过表单;以及 primary 样式的 **创建** 按钮,点击后会弹出一个起始选择面板,提供两条入口:
+页面右上角有两个创建入口:**通过聊天创建** 会打开一条预填提示的会话,由 Agent 通过提问帮您确定任务内容和触发时间,不用填表单;**创建** 会打开起始选择面板,提供两条入口:
<Steps>
<Step title="从零开始">
- 选择 **从零开始**,进入空白表单,手动填写名称、任务提示词与触发方式。适合你已经清楚要让 Agent 做什么、想完全自定义提示词的场景。
+ 选择 **从零开始**,进入空白表单,手动填写名称、任务提示词与触发方式。适合您已经清楚要让 Agent 做什么、想完全自定义提示词的场景。
</Step>
<Step title="基于预设模板">
- 下方列出一组 **预设模板** 卡片(由后端按界面语言下发,中文环境取 `zh-CN`、英文环境取 `en-US`),常见的有 **值班周报**、**告警治理**、**故障自动分析**、**On-call 负载分析** 等。点击任一模板卡片,会用模板预置的名称与任务提示词预填表单,你在此基础上微调即可。
+ 下方列出一组 **预设模板** 卡片(随界面语言显示中文或英文版本),常见的有 **值班周报**、**告警治理**、**故障自动分析**、**On-call 负载分析** 等。点击任一模板卡片,会用模板预置的名称与任务提示词预填表单,您在此基础上微调即可。
</Step>
</Steps>
@@ -48,26 +42,22 @@ sidebarTitle: 自动化
## 配置字段
----
-
配置表单的字段如下:
| 字段 | 必填 | 说明 |
|---|---|---|
| 名称 | 是 | 规则名称,最长 255 字符。占位示例:`每周值班洞察`。 |
| 范围 | 是 | 通过 **范围选择器** 选 **个人**(`team_id=0`)或某个 **团队**(`team_id>0`)。范围既决定这条规则的归属与编辑权限,也限定 **执行 Environment** 里可选的自托管 Runner——只有账户全局的 Runner,以及与该范围同团队的 Runner 才可选。 |
-| 执行环境 | 否 | 通过 **环境选择器** 选运行环境:**自动**(由后端挑选最优可用环境,默认值)、**云端沙箱**,或某个 **自托管(BYOC)Runner**。选了某个团队范围后,不属于该范围的团队 Runner 会被自动清除。 |
+| 执行环境 | 否 | 通过 **环境选择器** 选运行环境:**自动**(由系统挑选最优可用环境,默认值)、**云端沙箱**,或某个 **自托管(BYOC)Runner**。选了某个团队范围后,不属于该范围的团队 Runner 会被自动清除。 |
| 任务提示词 | 是 | 描述要让 AI SRE 执行的任务,用富文本编辑器撰写。这段提示词就是每次运行时发给 Agent 的内容。占位提示:`描述 Flashduty AI SRE 要执行的任务。` |
| 时区 | 否 | **按周期执行** 触发卡片里的字段(见下文「按周期执行(cron)」):cron 表达式所依据的 **规则时区**,用一个可搜索的下拉框选择 IANA 时区名(如 `Asia/Shanghai`),选项按下拉框里的 UTC 偏移排列。新建规则时默认为你的生效时区(成员时区优先,成员未设置时回退账户时区);没有可用时区时该字段留空,创建请求不携带它。 |
<Note>
-**执行环境** 的「自动」会在每次运行时由后端挑选当前最优的可用环境;「云端沙箱」是平台托管的临时沙箱;自托管 Runner 则把运行落在你自己的机器上。三者的差异与连接方式见 <a href="/zh/ai-sre/environments">运行环境</a>。
+**执行环境** 的「自动」会在每次运行时由系统挑选当前最优的可用环境;「云端沙箱」是平台托管的临时沙箱;自托管 Runner 则把运行落在您自己的机器上。三者的差异与连接方式见 <a href="/zh/ai-sre/environments">运行环境</a>。
</Note>
## 触发方式
----
-
一条规则必须 **至少配置一种触发方式**。当前控制台表单在「触发方式」区提供 **按周期执行**、**经 API 调用** 与 **On-call 故障触发** 三种入口,三者可同时启用。
### 按周期执行(cron)
@@ -97,7 +87,7 @@ sidebarTitle: 自动化
| 自定义 | 直接填 4 段或 5 段 cron 表达式 |
<Warning>
-**时区**:**按周期执行** 的运行按 cron 的 **规则时区** 读表——时区在触发卡片里的 **时区** 下拉框中选定,**每小时 / 每天 / 每周 / 自定义** 四种模式共用这一个字段,不存在「哪种模式按本地时区、哪种模式按 UTC」的区别。保存时按你选中的 IANA 时区原样存入规则,不再把时分换算成 UTC,节奏摘要旁也不再另外标注时区。
+**时区**:**按周期执行** 按触发卡片中选择的 **时区** 计算,**每小时 / 每天 / 每周 / 自定义** 四种模式共用这一设置。
</Warning>
<Note>
@@ -110,7 +100,7 @@ sidebarTitle: 自动化
### 经 API 调用(HTTP POST)
-让你在外部系统里按需触发这条自动化,而不依赖时间周期。
+让您在外部系统里按需触发这条自动化,而不依赖时间周期。
<Steps>
<Step title="启用并保存">
@@ -133,7 +123,7 @@ curl -X POST 'https://<触发地址>' \
请求体里的 `text` 会作为本次运行的上下文交给 Agent,叠加在规则配置好的任务提示词之上。
-请求成功后,响应的 `data` 会返回新建隐藏会话的信息。你可以保存 `session_id`,或直接使用 `session_url` 打开这次运行的完整对话、工具调用和产物:
+请求成功后,响应的 `data` 会返回新建隐藏会话的信息。您可以保存 `session_id`,或直接使用 `session_url` 打开这次运行的完整对话、工具调用和产物:
```json
{
@@ -151,7 +141,7 @@ curl -X POST 'https://<触发地址>' \
### On-call 故障触发
-当你希望 AI SRE 随 On-call 故障自动启动时,添加 **On-call incident** 触发方式。触发器会向 On-call 侧注册订阅,只有匹配指定协作空间和严重程度的故障事件才会启动运行。
+当您希望 AI SRE 随 On-call 故障自动启动时,添加 **On-call incident** 触发方式。触发器会向 On-call 侧注册订阅,只有匹配指定协作空间和严重程度的故障事件才会启动运行。
<Steps>
<Step title="添加触发方式">
@@ -164,7 +154,7 @@ curl -X POST 'https://<触发地址>' \
在 **严重程度** 中选择 `Critical`、`Warning`、`Info` 中的一个或多个值。启用该触发器时,协作空间和严重程度都至少需要一个值。
</Step>
<Step title="设置相似故障合并分析">
- **相似故障合并分析** 开关默认开启:开启后,本规则触发的新故障会先与正在分析中(或 10 分钟内刚分析完)的故障比较相似度,相似度不低于 0.9 的故障并入那次分析、不再单独开会话;关闭后每个故障各自分析。详见下文「相似故障合并分析」。
+ **相似故障合并分析** 默认开启:与正在分析的故障足够相似的新故障会并入那次分析,不再单独开会话;关闭后每个故障各自分析。规则详见[相似故障合并分析](#相似故障合并分析)。
</Step>
</Steps>
@@ -204,15 +194,13 @@ curl -X POST 'https://<触发地址>' \
## 运行历史
----
-
-每条规则都保留它的运行历史。点击规则行的任意位置(而不是某个专门的历史图标)会打开该规则的详情页 `/ai-sre/automations/:ruleId`:左侧栏是「配置信息」,右侧栏是「执行历史」,两栏并排展示;右侧栏顶部自带一个 **手动执行** 按钮,可以直接在详情页里触发一次运行。
+每条规则都保留它的运行历史。点击规则行即可打开规则详情页(`/ai-sre/automations/:ruleId`):左栏是 **配置信息**,右栏是 **执行历史**;右栏顶部的 **手动执行** 按钮可直接触发一次运行。
运行历史以表格呈现,列为:
| 列 | 说明 |
|---|---|
-| 名称 | 本次运行对应的隐藏会话名称。后端会为每条运行批量解析其隐藏会话的标题(`session_name`,即该隐藏会话自动生成的会话名);解析不到时回退显示会话 ID(`session_id`)。被并入其它分析的运行(见上文「相似故障合并分析」)没有自己的会话,这一列改显示它对应的故障(`#<num> <title>`),并在下一行标明它并入了哪次分析 |
+| 名称 | 本次运行对应的隐藏会话标题(`session_name`),解析不到时显示会话 ID(`session_id`)。被并入其它分析的运行没有自己的会话,改显示对应的故障(`#<num> <title>`),并在下一行标明并入了哪次分析 |
| 执行时间 | 本次运行的开始时间 |
| 耗时 | 本次运行的持续时长 |
| 触发方式 | 本次运行的触发类型标签,如 `定时`(schedule)、`HTTP POST`、`On-call incident` 或 `手动执行` |
@@ -239,32 +227,29 @@ curl -X POST 'https://<触发地址>' \
API 返回的运行记录还包含 `trigger_kind`,可能取值为 `schedule`、`manual`、`http_post`、`oncall_incident` 或 `debug`。其中 `manual` 表示通过立即执行接口启动,`oncall_incident` 表示由匹配的 On-call 故障事件启动。被并入其它分析的运行不返回自己的 `session_id`,而是返回它并入的那次分析的会话 ID `joined_session_id` 与会话名 `joined_session_name`;这两个字段为空,表示这次运行有自己的隐藏会话。
-点击一行,会跳转到这次运行对应的隐藏会话对话页(`chat?session_id=<会话ID>`),让你查看该次运行完整的消息、工具调用与产物。被并入其它分析的运行没有自己的会话,点击它会打开接管这个故障的那次分析。
+点击一行,会跳转到这次运行对应的隐藏会话对话页,让您查看该次运行完整的消息、工具调用与产物。被并入其它分析的运行没有自己的会话,点击它会打开接管这个故障的那次分析。
### 未成功运行的原因行
-运行状态为 `failed`、`blocked`、`abandoned`、`skipped` 之一时,「名称」单元格会在会话名下方多显示一行 **原因**——文本按一行截断,鼠标悬停可看全文。若这次运行没有可显示的会话名,原因行会直接占据这一格。原因行右侧有时还带一个跳转入口,在新标签页打开。
+运行状态为 `failed`、`blocked`、`abandoned` 或 `skipped` 时,「名称」列会在会话名下方显示失败**原因**(悬停查看全文)。常见原因:
-平台自己判定的原因有固定文案:
+| 原因(`error_code`) | 处理 |
+|---|---|
+| AI SRE 未开通,或本周期额度/余额不足,本次未执行(`BalanceNotEnough`) | 到 **费用中心 → 订阅** 的 AI SRE 页签开通或充值 |
+| On-call 订阅已失效或版本不含 AI SRE,AI SRE 已暂停(`NoLicense`) | 到 **费用中心 → 订阅** 的 On-call 页签续订或升级 |
+| 执行超时未完成,已放弃(`task_run_stale`) | — |
+| 本次执行被中断(`interrupted`) | — |
+| 执行已结束,但没有生成最终回复(`no_final_response`) | — |
+| 已并入另一次分析(`similar_incident_fan_in`) | 点击该行打开接管故障的分析 |
-| `error_code` | 显示的原因 | 跳转入口 |
-|---|---|---|
-| `BalanceNotEnough` | AI SRE 未开通,或本周期额度/余额不足,本次未执行 | 前往 AI SRE 计费(`/wallet/plan?product=ai-sre`) |
-| `NoLicense` | On-call 订阅已失效或版本不含 AI SRE,AI SRE 已暂停 | 前往 On-Call 订阅(`/wallet/plan?product=oncall`) |
-| `task_run_stale` | 执行超时未完成,已放弃 | 无 |
-| `interrupted` | 本次执行被中断 | 无 |
-| `no_final_response` | 执行已结束,但没有生成最终回复 | 无 |
-| `similar_incident_fan_in` | 已并入「`<分析名>`」;分析名解析不到时显示「另一次分析」 | 无 |
-| 其它 `error_code` | 直接显示后端记录的原因文本;没有文本时显示 `error_code` 本身 | 无 |
+其他原因直接显示系统记录的文本。
<Note>
-运行历史内嵌在规则详情页中,而打开详情页本身就要求你对该规则有编辑权限——没有编辑权限的规则连详情页都无法打开(会提示「自动化规则不存在或无权访问」),因此其运行历史也无法查看。
+运行历史在规则详情页中查看,因此需要对该规则有编辑权限。
</Note>
## 管理与权限
----
-
### 启用 / 停用、编辑与删除
每条规则在 **操作** 列提供一组操作:
@@ -276,7 +261,7 @@ API 返回的运行记录还包含 `trigger_kind`,可能取值为 `schedule`
点击规则行任意位置会打开该规则的详情页,在详情页里可以编辑配置、删除规则,也能看到运行历史(见上文「运行历史」一节)。
-对你 **没有编辑权限** 的只读规则(`can_edit=false`),开关与全部操作按钮都会被禁用;打开其表单时顶部会显示「只读 — 你可以查看此自动化,但无法编辑。」
+对您**没有编辑权限**的规则只能查看,不能启停或操作。
列表上方还提供两个筛选器:**范围**(全部 / 个人 / 团队,选「团队」后可多选具体团队)与 **状态**(全部状态 / 已启用 / 未启用)。
@@ -286,10 +271,10 @@ API 返回的运行记录还包含 `trigger_kind`,可能取值为 `schedule`
| 维度 | 规则 |
|---|---|
-| 归属 | **个人规则**(`team_id=0`)归创建者所有;**团队规则**(`team_id>0`)归该团队。**范围在创建时固定,创建后不可修改**:编辑规则时范围选择器处于禁用状态,并提示「范围创建后不可修改」。需要换一个范围时,请使用规则详情页的**克隆**按钮——克隆会打开预填的创建表单,为副本选好新范围保存即可(更新接口也不再接受 `team_id`,即使绕过界面也无法改范围)。创建团队规则时,**操作者本人**必须是目标团队的真实成员(join-to-govern);账户 Owner 和管理员也没有豁免。团队规则不随创建者去留而停用:即使创建者已离开团队,规则仍由团队继续运行;只有个人规则会在其 Owner 不再是账户有效成员时被停用——系统在下一次触发尝试的预检中发现 Owner 已失效,就会自动禁用该规则。 |
+| 归属 | **个人规则**归创建者所有;**团队规则**归该团队。**范围创建后不可修改**,需要换范围时,在规则详情页点击**克隆**,为副本选择新范围。创建团队规则时,操作者本人必须是该团队成员,账户 Owner 和管理员也不例外。团队规则在创建者离开团队后继续运行;个人规则在创建者不再是账户有效成员时会自动停用。 |
| 可见 / 列表 | 账户 Owner 与管理员可见全部规则;普通成员可见自己创建的规则,以及自己所属团队的规则。 |
| 编辑 / 管理(团队规则) | 仅规则归属团队的**当前成员**可操作(启用 / 停用、编辑、删除、立即执行);创建者一旦离开该团队,就不再保留任何特权。账户 Owner 与管理员没有豁免,需要先加入该团队。 |
-| 编辑 / 管理(个人规则) | 仅创建者本人可管理。账户 Owner 与管理员对他人的个人规则 **没有** 管理豁免,甚至无法查看其详情页——打开会直接返回「无权访问」,不是单纯的按钮置灰。 |
+| 编辑 / 管理(个人规则) | 仅创建者本人可管理和查看。账户 Owner 与管理员也无法查看或管理他人的个人规则。 |
| HTTP POST 触发 | 通过触发地址发起一次真实运行时,鉴权只看该 trigger 的 Bearer Token;持有 Token 的外部系统可以触发,运行会按规则的个人或团队作用域创建隐藏会话。 |
| On-call 故障触发 | 由已注册的故障订阅触发,不使用 HTTP POST Bearer Token;运行仍按规则的个人或团队作用域创建隐藏会话。 |
@@ -303,10 +288,8 @@ API 返回的运行记录还包含 `trigger_kind`,可能取值为 `schedule`
## 相关页面
----
-
<CardGroup cols={2}>
- <Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+ <Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
了解会话如何承载一次完整对话——自动化跑出的每次运行本质上就是一个隐藏会话。
</Card>
<Card title="运行环境" icon="server" href="/zh/ai-sre/environments">
diff --git a/zh/ai-sre/context.mdx b/zh/ai-sre/context.mdx
index e8d0fffb..630259ac 100644
--- a/zh/ai-sre/context.mdx
+++ b/zh/ai-sre/context.mdx
@@ -2,33 +2,27 @@
title: 了解上下文
description: 上下文是 AI SRE 排障时带着的两类长期资料。知识由人维护,记忆由系统整理。控制台在 自定义 → 上下文 分组下为它们各设一页。
keywords: ["AI SRE", "上下文", "知识", "记忆", "DUTY.md"]
-sidebarTitle: 了解上下文
+sidebarTitle: "上下文"
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 上下文是什么
----
-
上下文是 AI SRE 在一次排障里能反复用到的长期资料。它分成两种,在控制台 **AI SRE → 自定义** 侧栏的 **上下文** 分组下各有一页。
-- **[知识](/zh/ai-sre/knowledge)**是人维护的。它写的是这个环境怎么运转:一份使用说明 `DUTY.md`,加上运行手册、服务清单等文件。会话开始时会读使用说明,其它文件在需要时再打开。入口:**AI SRE → 自定义 → 上下文 → 知识**。
-- **[记忆](/zh/ai-sre/memory)**是系统整理的。会话结束后,系统从对话里留下以后还会用到的偏好、做法、事实和教训。你也可以在对话里直接说记住或忘掉一件事。入口:**AI SRE → 自定义 → 上下文 → 记忆**。
+- [**知识**](/zh/ai-sre/knowledge)是人维护的。它写的是这个环境怎么运转:一份使用说明 `DUTY.md`,加上运行手册、服务清单等文件。会话开始时会读使用说明,其它文件在需要时再打开。入口:**AI SRE → 自定义 → 上下文 → 知识**。
+- [**记忆**](/zh/ai-sre/memory)是系统整理的。会话结束后,系统从对话里留下以后还会用到的偏好、做法、事实和教训。您也可以在对话里直接说记住或忘掉一件事。入口:**AI SRE → 自定义 → 上下文 → 记忆**。
-两页底部都有一个输入框:写下要改什么,控制台会打开新对话,由 AI 先说明改动、经你同意后保存。
+两页底部都有一个输入框:写下要改什么,控制台会打开新对话,由 AI 先说明改动、经您同意后保存。
## 三个范围
----
-
两类资料都按范围组织,但支持的范围不同。
| 范围 | 记忆 | 知识 |
| --- | --- | --- |
-| 个人 | 你自己的 | 没有 |
+| 个人 | 您自己的 | 没有 |
| 团队 | 这个团队的 | 这个团队的那一份(每个团队最多 1 个) |
| 共享 | 没有 | 整个账户的那一份 |
@@ -36,8 +30,6 @@ sidebarTitle: 了解上下文
## 接着看
----
-
<CardGroup cols={2}>
<Card title="了解知识" icon="book" href="/zh/ai-sre/knowledge">
使用说明、运行手册和文件怎么组织,以及助手在会话里怎么读它们。
diff --git a/zh/ai-sre/environments.mdx b/zh/ai-sre/environments.mdx
index 311e609e..af4e61a8 100644
--- a/zh/ai-sre/environments.mdx
+++ b/zh/ai-sre/environments.mdx
@@ -5,14 +5,10 @@ keywords: ["AI SRE", "运行环境", "Environment", "Sandbox", "BYOC", "Runner",
sidebarTitle: 运行环境
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
**运行环境**(Environment)是 AI SRE Agent 实际执行动作的地方。Agent 的每一次工具调用,包括执行命令、读写文件、运行 Skill、连接 MCP 服务,都会落在一个运行环境里。
AI SRE 提供两类运行环境:
@@ -36,8 +32,6 @@ AI SRE 提供两类运行环境:
## 云端 Sandbox
----
-
云端 Sandbox 是 Flashduty 托管的临时执行容器。它适合快速上手、演示,以及不需要访问您内网的排查。您不需要安装任何进程,也不需要维护机器。
适合使用云端 Sandbox 的场景:
@@ -55,8 +49,6 @@ AI SRE 提供两类运行环境:
## 云端环境模板
----
-
云端环境模板是为 Flashduty 托管的云端 Sandbox 预定义的可复用配置:出口网络策略、环境变量与启动脚本。会话使用的云端 Sandbox 如果没有绑定模板,就用系统默认配置启动;绑定了模板后,新建的 Sandbox 会按模板配置启动。
进入 **AI SRE → 自定义 → 环境 → 云端**,即可查看、创建、编辑或删除云端环境模板。
@@ -67,7 +59,7 @@ AI SRE 提供两类运行环境:
|---|---|---|
| 名称 | 是 | 在账户范围内必须唯一,最长 128 字符。 |
| 范围 | 是 | 共享范围的模板在整个账户内可见;团队范围的模板仅对该团队成员可见和可编辑。 |
-| 网络访问 | 否,默认「全部允许」 | 下拉框展示「默认允许列表」「自定义(你的域名列表)」「全部允许」三个选项,但目前只有**「全部允许」**可以选择——「默认允许列表」与「自定义」选项已在界面上展示但处于禁用状态,属于已知限制,尚未开放。也就是说,当前创建或编辑云端环境模板,都会让绑定它的 Sandbox 处于完全放开出网的状态。 |
+| 网络访问 | 否,默认「全部允许」 | 目前只能选择「全部允许」,即 Sandbox 可以访问任意外网;「默认允许列表」和「自定义」暂未开放 |
| 环境变量 | 否 | `.env` 格式(`KEY=value`,每行一条,支持带引号的多行值),最大 32 KB,界面会实时显示已用字节数。 |
| 启动脚本 | 否 | Bash 脚本,最大 64 KB,界面会实时显示已用字节数。 |
@@ -75,7 +67,7 @@ AI SRE 提供两类运行环境:
环境变量以明文形式对所有使用该云端环境模板的人可见——请勿在这里填写密钥或凭据。
</Warning>
-**平台保留的环境变量名。** 有一部分变量名由平台自己注入到会话的运行环境里,模板不得设置——写了会在**保存时被拒绝**(服务端是这份名单的唯一真相源,界面上的提示清单可能滞后):
+**平台保留的环境变量名。** 以下变量由平台注入,模板不能设置,否则保存时会被拒绝:
| 保留名 | 说明 |
|---|---|
@@ -83,11 +75,11 @@ AI SRE 提供两类运行环境:
| `FLASHDUTY_DOCS_URL` | 官方文档包的静态地址;内置的 `flashduty-docs` Skill 从这里下载文档副本。 |
| `GH_TOKEN`、`GH_TOKEN_` 前缀、`GH_PROMPT_DISABLED`、`GIT_CONFIG_` 前缀 | GitHub 侧由平台注入的令牌与 git 配置(一个账户可能有多个 GitHub App 安装,因此 `GH_TOKEN_1`、`GH_TOKEN_2` 这类也保留)。 |
| `PATH` / `HOME` | 运行环境的基础环境变量。 |
-| `GITLAB_TOKEN`、`GITLAB_ACCESS_TOKEN`、`OAUTH_TOKEN`、`GITLAB_HOST`、`GL_HOST`、`GITLAB_URI`、`GITLAB_API_HOST`、`GITLAB_SSH_HOST`、`GITLAB_SUBFOLDER`、`CA_CERT`、`SKIP_TLS_VERIFY`、`GLAB_` 前缀 | GitLab / `glab` 的认证、主机与 TLS 配置;允许模板覆盖其中任何一项,都等于让会话绕过平台注入的机器人身份去改 `glab` 的传输目标。 |
+| `GITLAB_TOKEN`、`GITLAB_ACCESS_TOKEN`、`OAUTH_TOKEN`、`GITLAB_HOST`、`GL_HOST`、`GITLAB_URI`、`GITLAB_API_HOST`、`GITLAB_SSH_HOST`、`GITLAB_SUBFOLDER`、`CA_CERT`、`SKIP_TLS_VERIFY`、`GLAB_` 前缀 | GitLab / `glab` 的认证、主机与 TLS 配置,防止会话绕过平台注入的机器人身份。 |
-这些名字在**每次执行命令前**由平台注入,覆盖平台的同名项会被丢弃,以平台值为准(这一点在云端 Sandbox 与 BYOC Runner 上一致)。因此模板里的环境变量只用来放业务相关的非敏感配置——需要密钥时,请用 MCP 的成员授权或相应的 App 集成。
+即使通过其他方式设置了同名变量,执行命令时也以平台的值为准(云端 Sandbox 与 BYOC Runner 相同)。模板中的环境变量只用于非敏感的业务配置;需要密钥时,请使用 MCP 的成员授权或相应的 App 集成。
-启动脚本在**全新沙箱(Ubuntu 24.04,以 root 身份运行)**内、**Agent 启动前**执行,典型用途是用 `apt` 安装 Agent 需要的软件包。
+启动脚本在<strong>全新沙箱(Ubuntu 24.04,以 root 身份运行)</strong>内、**Agent 启动前**执行,典型用途是用 `apt` 安装 Agent 需要的软件包。
### 删除云端环境模板
@@ -99,8 +91,6 @@ AI SRE 提供两类运行环境:
## BYOC Runner
----
-
BYOC(Bring Your Own Compute)Runner 是您部署在自己机器上的 `flashduty-runner` 进程。它与 AI SRE 保持常驻 WebSocket 连接,收到任务后在本机执行命令、读写文件、运行 Skill,并按需连接本机可达的 MCP 服务。
BYOC Runner 的价值来自执行位置:
@@ -183,7 +173,7 @@ BYOC Runner 的出网策略由您的机器和防火墙决定。云端 Sandbox
</Tabs>
<Note>
-`connect-url` 与 `install_script_url` 都由后端下发,前端不会硬编码。私有化或离线部署可以把安装脚本分发源替换为内部镜像,但镜像需要同时提供 `install.sh`、`releases/latest` 与 `releases/download/<version>/...` release assets。
+`connect-url` 与 `install_script_url` 都由平台动态下发,不是固定地址。私有化或离线部署可以把安装脚本分发源替换为内部镜像,但镜像需要同时提供 `install.sh`、`releases/latest` 与 `releases/download/<version>/...` release assets。
</Note>
### 连接使用自签证书的私有化端点
@@ -295,8 +285,6 @@ Runner 版本由服务端在心跳中比对。发现新版本时,Runner 会收
## 权限配置
----
-
Runner 默认使用允许全部命令的规则,这与直接在自己的 shell 里运行 AI 模型、信任模型的判断是同一套信任模型:
```yaml
@@ -411,35 +399,31 @@ permission:
## 在会话中选择环境
----
-
聊天输入框底部的环境选择器决定新会话在哪里执行:
| 选项 | 含义 |
|---|---|
| **自动** | 新会话默认值。依次尝试会话绑定团队名下在线的 BYOC Runner、共享范围(账户级)在线的 Runner,均不可用时回退云端 Sandbox。 |
| **云端 Sandbox · 默认** | 强制使用系统托管的云端 Sandbox,忽略自托管 Runner。 |
-| **自托管环境** | 列出当前成员可使用的 Runner。离线、从未连接或团队权限不匹配的 Runner 不可选;处于 **性能下降(degraded)** 的 Runner **仍然可选**,选中后会提示「性能下降 — 可继续使用,响应可能变慢」。 |
+| **自托管环境** | 您可以使用的 Runner。离线、从未连接或无团队权限的 Runner 不可选;**性能下降**的 Runner 仍可选,但响应可能变慢。 |
<Warning>
-环境选择对一条会话是一次性锁定的:会话首次发送消息时确定的运行环境会被记录,后续轮次始终沿用,不会因为您之后切换选择器而改变。要换环境,请新建会话。
+会话的运行环境在首次发送消息时确定,之后不会因为切换选择器而改变。要换环境,请新建会话。
</Warning>
-历史会话打开时,选择器会以只读形式展示这条会话当初锁定的环境及其当前状态。如果绑定的 Runner 已离线或被删除,该会话不能继续发送消息;请先恢复 Runner,或新建会话改用云端 Sandbox。
+打开历史会话时,选择器只读显示该会话的环境及其状态。如果绑定的 Runner 已离线或被删除,该会话不能继续发送消息;请先恢复 Runner,或新建会话。
### 子会话的执行环境
派发出去的子代理会带出一条自己的**子会话**,它的执行环境规则与根会话不同:
-- **默认继承父会话**:`agent_dispatch` 不指定 `environment` 时,子会话与父会话**共用同一个沙箱 / workspace**,因此它能直接看到父会话的文件——子会话面板里显示的环境也就与父会话相同。
-- **只有跨环境派发才有自己的环境**:把子任务派到另一个环境(`agent_dispatch` 的 `environment` 参数,例如另一个 BYOC Runner 或云端环境,见 [Agent](/zh/ai-sre/agents))时,子会话会得到**自己的**沙箱 / Runner scratch 目录,读不到父会话的文件。
-- **子会话面板不提供环境选择器**:它只以**只读**方式展示该子会话绑定的环境及其当前状态——云端环境,或自托管 Runner 的名称,与根会话的只读展示共用同一套状态语义(正常运行时不额外标注;离线 / 性能下降 / 未连接 / 已删除时给出短标签与悬停说明)。
+- **默认与父会话共用环境**:子会话与父会话共用同一个沙箱 / workspace,可以直接看到父会话的文件。
+- **派到其他环境时使用独立环境**:子任务派到另一个 BYOC Runner 或云端环境(见 [Agent](/zh/ai-sre/agents))时,子会话有自己的沙箱或 Runner 目录,看不到父会话的文件。
+- **子会话面板只读显示环境**:不能在子会话中切换环境。
- **A2A 子会话不显示运行环境**:远端 Agent 在它自己的环境里执行,位置不由本平台决定。
## 作用域
----
-
每个 BYOC 环境都有共享范围与团队范围两档作用域:
| 作用域 | 可见范围 |
@@ -459,8 +443,6 @@ permission:
## 故障排查
----
-
排查 Runner 问题时,先看自托管环境列表的**状态**与**最后心跳**。
<AccordionGroup>
@@ -484,13 +466,11 @@ permission:
## 相关页面
----
-
<CardGroup cols={2}>
<Card title="Sandbox" icon="cloud" href="/zh/ai-sre/sandbox">
了解云端 Sandbox 的生命周期、适用场景与出网边界。
</Card>
- <Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+ <Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
在会话中查看绑定的运行环境、团队与 Agent 调用的资源。
</Card>
<Card title="MCP(外部工具)" icon="plug" href="/zh/ai-sre/mcp">
diff --git a/zh/ai-sre/im.mdx b/zh/ai-sre/im.mdx
index 6dd66965..9f61c4a3 100644
--- a/zh/ai-sre/im.mdx
+++ b/zh/ai-sre/im.mdx
@@ -5,15 +5,11 @@ keywords: ["AI SRE", "IM", "Slack", "飞书", "钉钉", "企业微信", "作战
sidebarTitle: IM 平台
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
-排障往往就发生在你的 IM 群里——告警推过来、大家在群里讨论、拉个作战室。AI SRE 把 Agent 直接放进这条协作链路:**你不必切换到控制台,就能在 IM 里召唤它排查**,团队成员也能全程看到它的分析过程。
+排障往往就发生在您的 IM 群里——告警推过来、大家在群里讨论、拉个作战室。AI SRE 把 Agent 直接放进这条协作链路:**您不必切换到控制台,就能在 IM 里召唤它排查**,团队成员也能全程看到它的分析过程。
AI SRE 的 IM 集成有两种触发方式:
@@ -28,8 +24,6 @@ AI SRE 的 IM 集成有两种触发方式:
## 支持的 IM 平台
----
-
AI SRE 的 IM 交互覆盖四个主流平台,每个平台都支持入站的 @ 提及(webhook)、历史消息读取与出站回复:
| 平台 | 群聊 @ 提及 | 私聊(DM) | 处理中回执 | 作战室自动诊断 |
@@ -39,16 +33,14 @@ AI SRE 的 IM 交互覆盖四个主流平台,每个平台都支持入站的 @
| 钉钉 / DingTalk | ✅ | ✅ | ✅ 内置表情 | ✅ |
| 企业微信 / WeCom | ✅ | ✅ | ✅ 占位消息 | ✅ |
-「处理中回执」是机器人收到你的消息后给出的即时信号,各平台的具体形式见[处理中回执](#处理中回执)。
+「处理中回执」是机器人收到您的消息后给出的即时信号,各平台的具体形式见[处理中回执](#处理中回执)。
<Note>
-IM 交互依赖你已在 Flashduty 中接入对应平台的机器人(用于告警通知与协作的同一套 IM 机器人)。请先在 Flashduty 的 IM 集成中完成机器人配置,AI SRE 才能在该平台收发消息。
+IM 交互依赖您已在 Flashduty 中接入对应平台的机器人(用于告警通知与协作的同一套 IM 机器人)。请先在 Flashduty 的 IM 集成中完成机器人配置,AI SRE 才能在该平台收发消息。
</Note>
## IM 集成中的 AI SRE 设置
----
-
在 **On-call → 集成中心 → 集成列表 → 即时消息** 打开对应 IM 集成详情,在 **增强功能** 中分别配置该集成的 AI SRE 行为。以下开关默认均为开启:
- **自动发起 AI 故障分析**:开启作战室后可配置;集成成功创建作战室时,自动发起一次 AI SRE 初步诊断并把结果回贴到作战室。
@@ -61,9 +53,7 @@ IM 交互依赖你已在 Flashduty 中接入对应平台的机器人(用于告
## @ 提及召唤
----
-
-在已接入并开启了 **允许在 IM 中使用 AI SRE** 的 IM 群里 **@ 机器人** 并写下你的问题(例如「@AI SRE 看下 payment 服务为什么 5xx 飙升」),消息会通过平台 webhook 转给 AI SRE 处理:
+在已接入并开启了 **允许在 IM 中使用 AI SRE** 的 IM 群里 **@ 机器人** 并写下您的问题(例如「@AI SRE 看下 payment 服务为什么 5xx 飙升」),消息会通过平台 webhook 转给 AI SRE 处理:
<Steps>
<Step title="识别提及">
@@ -99,24 +89,22 @@ Slack 除此之外还会显示一条原生的「正在处理」状态,与表
### 答复如何抵达聊天
-AI SRE 在 IM 里的答复**只经 `reply` 工具投递**——模型输出的普通文本是内部草稿,不会自动发到聊天。你把一次排查交给它之后,群里出现的每一条消息都是它主动提交的,属于两类之一:
+AI SRE 在 IM 里的答复**只经 `reply` 工具投递**——模型输出的普通文本是内部草稿,不会自动发到聊天。您把一次排查交给它之后,群里出现的每一条消息都是它主动提交的,属于两类之一:
-- **结论**:回答你的具体问题,或给出一个可行动的阶段性结论。
+- **结论**:回答您的具体问题,或给出一个可行动的阶段性结论。
- **进展**:工作仍在进行时的一两句话更新——确认的进展、当前在等什么、遇到的真实阻塞。进展消息**不是结论**,它不结束这轮任务,结论会照常单独投递。
-如果一轮以自然收尾结束,而结论只写成了普通文本、没有经 `reply` 提交,系统会自动补一次**只允许投递**的纠正:这次纠正只开放 `reply`,不执行任何调查或变更类操作;纠正后仍未提交,该轮以错误结束——那份草稿始终不会出现在群里。取消、被新消息打断、派发子代理、等待子代理回报、输出被截断等非自然结束的回合不会触发这次纠正。
+如果结论没有以答复形式提交,系统会让 AI SRE 再补交一次(只允许提交,不做任何调查或变更);仍未提交则该轮以错误结束,草稿不会出现在群里。
-这套交付契约只作用于**由人发起的 IM 请求**:控制台会话仍按流式文本作答;作战室自动诊断是无人值守的后台回合,也保持原生流式输出。
+这套回复方式只作用于**由人发起的 IM 请求**:控制台会话仍按流式文本作答;作战室自动诊断是无人值守的后台回合,也保持原生流式输出。
<Note>
-单条答复还有阅读长度上的软约束:过长时 `reply` 会拒绝一次,并建议精简重复内容,或把详细的证据与对比发布为产物、只把关键结论和产物链接发到聊天。因此 IM 里的长分析通常长成「结论 + 产物链接」,而不是一条很长的消息,详见[产物](/zh/ai-sre/artifacts)。当你在消息里明确要求「把完整报告直接贴在聊天里」时,这条约束不生效。
+答复过长时,AI SRE 会精简内容,或把详细证据发布为产物,只在聊天里发结论和产物链接(见[产物](/zh/ai-sre/artifacts))。如果您明确要求把完整报告贴在聊天里,则不受此限制。
</Note>
## 作战室自动诊断
----
-
-当你为一个故障在 IM 中开启**作战室**(war room)且该集成保留 **自动发起 AI 故障分析** 开关时,AI SRE 会自动介入——无需任何人 @ 它:
+当您为一个故障在 IM 中开启**作战室**(war room)且该集成保留 **自动发起 AI 故障分析** 开关时,AI SRE 会自动介入——无需任何人 @ 它:
<Steps>
<Step title="创建作战室">
@@ -136,8 +124,6 @@ AI SRE 在 IM 里的答复**只经 `reply` 工具投递**——模型输出的
## 常驻任务与监控中卡片
----
-
Agent 的当前回合结束时,如果它留下的**常驻进程类任务**还在运行(例如 monitor 监视器、后台命令),AI SRE 会向聊天中投递一条监控中卡片:
```
@@ -151,15 +137,15 @@ Agent 的当前回合结束时,如果它留下的**常驻进程类任务**还
常驻任务存活期间,本次 IM 会话的根消息保持打开(不关闭事故视图):后续由任务通知触发的回合继续投递到**同一个聊天**,无需重新 @ 召唤。
</Note>
-通知回合遵循「无消息 = 没有新进展」的静默语义:如果某个通知回合没有新内容要投递,AI SRE 会静默关闭该回合,**不向聊天发送任何占位回执**,也不会重复投递监控中卡片;只有真正有新结论时才会在聊天里出现新消息。
+通知回合没有新内容时,AI SRE 不会向聊天发送任何消息;只有出现新结论时才会发言。
### 长排查中的进展消息
-排查链路长的时候,聊天里可能长时间没有动静——过程性文字不下发,监控中卡片也要等出现常驻任务才会发。为此,当一次 IM 请求**连续静默约 60 秒**仍没有任何公开回复提交时,系统会视情况给模型加一条瞬态提醒,把「你已经等了多久」告诉它,由它自己决定要不要发一条进展消息:
+排查时间较长时,如果一次请求**约 60 秒**内没有任何答复,AI SRE 会收到提醒,并自行判断是否发一条进展消息:
-- **提醒节奏**:同一请求两次提醒至少间隔 **3 分钟**,一段连续静默里**最多提醒 2 次**。任何一次提交成功的回复(结论或进展)都会开启新的静默段、重新计数,但不会缩短那 3 分钟的最小间隔。
-- **等待时长从哪算起**:从你的消息进入平台待处理队列的时刻起算,排队时间同样计入——不是从 Agent 真正开始处理的时刻起算。
-- **提醒不会自己发消息**:它只是把等待时长告诉模型,不替它往群里写任何东西;已经说过的等待、且没有新变化时,或者模型正在等你补充信息时,不发才是正确的。
+- 同一请求两次提醒至少间隔 **3 分钟**,每段连续静默最多提醒 **2 次**;任何一次答复都会重新开始计时。
+- 等待时间从您的消息进入队列时算起,包括排队时间。
+- 提醒本身不会发消息;如果没有新进展,或正在等您补充信息,AI SRE 可以不发。
- **进展消息不是结论**:它表示「还在查、卡在哪、下一步看什么」,不结束这轮任务,结论随后单独投递。
<Note>
@@ -170,23 +156,19 @@ Agent 的当前回合结束时,如果它留下的**常驻进程类任务**还
## 连接与授权
----
-
-控制台在凭证缺失时会渲染内联卡片(**授权〈资源名〉以继续**、**连接〈厂商名〉以继续**,见 [控制台](/zh/ai-sre/sessions#需要授权时))。**IM 与 API 渠道不出卡**——Agent 会根据本次会话的渠道改用下面这套办法把这件事交给你:
+控制台中缺少凭证时会显示授权卡片(见[控制台对话](/zh/ai-sre/sessions#需要授权时)),**IM 与 API 渠道没有卡片**,处理方式如下:
| 情况 | IM / API 渠道的行为 |
| --- | --- |
-| 缺少你的 OAuth 授权(`per_user_oauth`) | Agent 把授权链接原样贴成一条普通消息(不是卡片),请你在**桌面 / PC 浏览器**打开完成授权,然后回到会话回复 **「已授权」**(英文会话回复 `authorized`)继续。继续是你的一次显式动作,OAuth 成功回调本身不会自动接着跑 |
-| 缺少你的密钥类凭证(`per_user_secret`) | IM 里没有安全的收取渠道:Agent 只会请你在**网页控制台打开同一个会话**完成填写,不会让你在聊天里粘贴密钥,也不会把你指到某个设置页 |
-| 缺少整个连接(市场目录里有、账户未连接) | Agent 把连接地址(控制台插件页的深链)作为一条普通链接给出,请你连接后回复 **「继续」**(英文会话回复 `continue`)再接着做 |
+| 缺少您的 OAuth 授权 | Agent 发出授权链接,请在**电脑浏览器**中打开完成授权,然后回复 **「已授权」**(英文会话回复 `authorized`)继续。授权成功不会自动继续 |
+| 缺少您的密钥 | Agent 会请您在**网页控制台打开同一会话**填写,不会让您在聊天里粘贴密钥 |
+| 账户尚未连接所需的集成 | Agent 发出控制台中的连接链接,连接后回复 **「继续」**(英文会话回复 `continue`) |
| 共享服务器自身的凭证(环境变量 / Header) | 不走上面任何流程:在 **自定义 → 插件 → MCP**(该服务器)里填写,填完让 Agent 重试 |
自动化(`automation`)渠道没有人值守、也不会有回复:Agent 不会等待、不会把话写成问句,而是把缺失的连接或授权**记为阻塞项**写进最终报告,并交付已有证据能支持的部分。
## IM 会话内切换命令
----
-
IM 会话没有控制台那样的选择器 UI,但支持两条斜杠命令在**对话进行中**动态切换绑定——控制台会话不支持这两个操作,其环境与团队绑定在创建时固定、不可变更。
### /env — 切换运行环境
@@ -227,36 +209,30 @@ IM 会话没有控制台那样的选择器 UI,但支持两条斜杠命令在**
## /feedback — 评价 AI SRE 的回复
----
+AI SRE 的回复进入群聊后,群里任何人都可以评价它——不只是发起排查的人。向机器人发送 `/feedback`,即可对您正在看的那条回复给出评价或评论:
-AI SRE 的回复进入群聊后,群里任何人都可以评价它——不只是发起排查的人。向机器人发送 `/feedback`,即可对你正在看的那条回复给出评价或评论:
-
-- **入口与定位**:`/feedback` 由 AI SRE 侧提供后端(POST /safari/session/latest-reply → POST /safari/feedback/create),它能把你「当前看中的那条消息」解析为对应的回复事件,即使你没有参与过那次对话。
+- **入口与定位**:`/feedback` 由 AI SRE 处理,它能把您「当前看中的那条消息」解析为对应的回复事件,即使您没有参与过那次对话。
- **评价资格**:**不限会话成员**——账户内任何可使用 AI SRE 的成员都可以评价(只读群聊读者同样可以);群聊里 AI SRE 的回答是公开的,看错的人正是我们想收集反馈的人。
-- **评价方式**:可选 `like` / `dislike` / `none`;只写评论不选评价也可以提交(空评价不会清掉你之前给过的评价),显式的 `none` 才会清除已有评价。
-- **独立存储**:每条回复按 **(回复事件, 评价人)** 分开存储——同一条回复被群里多个人评价,会各留一行,互不覆盖。
+- **评价方式**:可选 `like` / `dislike` / `none`;只写评论不选评价也可以提交(空评价不会清掉您之前给过的评价),显式的 `none` 才会清除已有评价。
+- **独立存储**:每条回复按 **(回复事件, 评价人)** 分开存储——同一条回复被群里多个人评价,会各留一行,互不覆盖。
- **控制台侧**:控制台会话头部也有对回复的点赞反馈(见 [会话反馈](/zh/ai-sre/sessions#会话反馈)),与 IM 的 `/feedback` 共用同一套评价体系。
## 与控制台会话的关系
----
-
无论从 IM 还是控制台发起,**都是同一个 AI SRE**:按顺序处理消息、流式输出、长对话自动压缩上下文、可绑定团队与运行环境。区别只在入口——
- **控制台**:在「对话」工作区里逐条提问、查看完整的工具调用与子会话面板;环境与团队绑定在创建时固定,后续不可变更。
-- **IM**:在你日常协作的群里 @ 召唤,结论回贴到线程;支持 `/env` 和 `/scope` 命令在对话中途动态切换绑定,适合在故障现场快速拿到分析,再到控制台深入。
+- **IM**:在您日常协作的群里 @ 召唤,结论回贴到线程;支持 `/env` 和 `/scope` 命令在对话中途动态切换绑定,适合在故障现场快速拿到分析,再到控制台深入。
会话的更多细节见 [对话](/zh/ai-sre/sessions)。
## 相关页面
----
-
<CardGroup cols={2}>
<Card title="概述" icon="gauge-high" href="/zh/ai-sre/overview">
了解 AI SRE 的整体能力、典型场景与控制台导航。
</Card>
- <Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+ <Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
了解会话、流式输出、取消与上下文压缩。
</Card>
<Card title="Agent" icon="satellite-dish" href="/zh/ai-sre/agents">
diff --git a/zh/ai-sre/init.mdx b/zh/ai-sre/init.mdx
index 124796d2..8b3a0824 100644
--- a/zh/ai-sre/init.mdx
+++ b/zh/ai-sre/init.mdx
@@ -1,30 +1,24 @@
---
title: 初始化(/init)
-description: 在 AI SRE 会话中输入 /init,由 Agent 以访谈的方式带你从零搭建运维知识(DUTY.md + runbook + 服务清单等)并按需接入 MCP——每一项写入都需你逐条确认。
+description: 在 AI SRE 会话中输入 /init,由 Agent 以访谈的方式带您从零搭建运维知识(DUTY.md + runbook + 服务清单等)并按需接入 MCP——每一项写入都需您逐条确认。
keywords: ["AI SRE", "init", "运营作战图", "知识", "onboarding", "DUTY.md", "runbook", "MCP"]
sidebarTitle: 初始化
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
-在任意 AI SRE 会话的输入框中输入 `/init`,Agent 会切换成一名**运维 onboarding 访谈者**,带你从零搭建一份运维知识——也就是这个团队的「运营作战图」。它会扫描你的 Flashduty 故障与通知渠道、向你提问、把你口述的服务拓扑、排查手册、集群访问方式等沉淀成知识文件,并在需要时帮你接入外部工具(MCP)。
+在任意 AI SRE 会话的输入框中输入 `/init`,Agent 会切换成一名**运维 onboarding 访谈者**,带您从零搭建一份运维知识——也就是这个团队的「运营作战图」。它会扫描您的 Flashduty 故障与通知渠道、向您提问、把您口述的服务拓扑、排查手册、集群访问方式等沉淀成知识文件,并在需要时帮您接入外部工具(MCP)。
-`/init` 是搭建知识的**起点**。AI SRE 的诊断质量直接取决于它能读到多少关于你系统的真实知识:[知识](/zh/ai-sre/knowledge)维护得越完整、越准确,Agent 定位根因就越快、越靠谱。`/init` 就是把这份知识从零建立起来的引导流程,建完之后每一次会话都会自动加载它。
+`/init` 是搭建知识的**起点**。AI SRE 的诊断质量直接取决于它能读到多少关于您系统的真实知识:[知识](/zh/ai-sre/knowledge)维护得越完整、越准确,Agent 定位根因就越快、越靠谱。`/init` 就是把这份知识从零建立起来的引导流程,建完之后每一次会话都会自动加载它。
<Note>
-`/init` **不会**在未经你同意的情况下写入或安装任何东西。每个阶段在写入文件前都会列出「将要创建/更新哪些文件」的清单,由你逐条确认后才执行。凭证(token、密码、AK/SK)永远不会在对话里明文回显,只记为 `<已记录(长度=N)>`。详见 [安全与同意](#安全与同意)。
+`/init` 写入或安装任何内容前都会先征得您的逐项确认,凭证也不会在对话里明文回显,详见[安全与同意](#安全与同意)。
</Note>
## 何时用 /init,何时直接说
----
-
`/init` 解决的是**结构化的从零搭建 / 系统性补全**;零散的小修小补不需要它。
| 场景 | 用法 |
@@ -39,44 +33,40 @@ sidebarTitle: 初始化
## 如何运行
----
-
<Steps>
<Step title="在会话中输入 /init">
在任意一个 AI SRE 会话的输入框输入 `/init` 并发送。无需参数。
</Step>
<Step title="确认作用域">
- `/init` 先锁定本次要写入的范围:**账户级**(账户内所有会话可见)或**某个团队级**(仅该团队会话加载)。范围由当前会话是否绑定团队决定,Agent 会先反问你确认;一次会话只锁定一个范围,中途不切换。
+ Agent 先和您确认本次写入的范围:会话绑定了团队就写入该**团队级**(仅该团队会话加载),否则写入**账户级**(账户内所有会话可见)。一次会话只用一个范围。
</Step>
<Step title="跟着访谈走">
- Agent 按主题逐阶段提问(服务与拓扑、可观测性、runbook、常见故障、集群访问……),把你的回答整理成知识文件草稿。每个阶段结束都会问你「继续下一项,还是先停在这里」。
+ Agent 按主题逐阶段提问(服务与拓扑、可观测性、runbook、常见故障、集群访问……),把您的回答整理成知识文件草稿。每个阶段结束都会问您「继续下一项,还是先停在这里」。
</Step>
<Step title="逐项确认后写入">
- 每个阶段写入文件前,Agent 会给出一份「将创建/更新哪些文件」的清单,每个文件配 3–5 行摘要。你确认后它才写入知识,并把新文件链接进 `DUTY.md` 目录。
+ 每个阶段写入前,Agent 会列出将创建或更新的文件(各附 3–5 行摘要)。您确认后才写入,并把新文件链接进 `DUTY.md` 目录。
</Step>
<Step title="随时暂停或重跑">
- 你可以随时说「跳过这项」「回到第 N 步」「先到这里」。`/init` 不是一次性的——之后任何时候重新输入 `/init` 都能基于已有知识继续补全。
+ 您可以随时说「跳过这项」「回到第 N 步」「先到这里」。`/init` 不是一次性的——之后任何时候重新输入 `/init` 都能基于已有知识继续补全。
</Step>
</Steps>
## 访谈流程
----
-
-`/init` 按固定顺序走一套阶段,每个阶段有明确的进入与退出条件。你可以随时跳过、回退或叫停。
+`/init` 按固定顺序走一套阶段,每个阶段有明确的进入与退出条件。您可以随时跳过、回退或叫停。
<AccordionGroup>
<Accordion title="阶段 0 — 锁定作用域" icon="crosshairs">
- 读取当前会话绑定的团队:若绑定了团队,本次 `/init` 落在该团队级;若是账户级会话,则落在账户级(对所有团队可见)。Agent 会先和你确认这一点,确认后整场会话固定使用这个范围。想换团队范围,需退出后从目标团队重新打开 `/init`。
+ 读取当前会话绑定的团队:若绑定了团队,本次 `/init` 落在该团队级;若是账户级会话,则落在账户级(对所有团队可见)。Agent 会先和您确认这一点,确认后整场会话固定使用这个范围。想换团队范围,需退出后从目标团队重新打开 `/init`。
</Accordion>
<Accordion title="阶段 1 — 扫描" icon="radar">
- 通过 Flashduty MCP 拉取你的渠道、近 30 天故障、团队与成员,归纳出你在用的集成类型与高频故障标签。若扫描结果为空(全新账户),切换到「冷启动」模式,改为完全靠访谈采集。
+ 通过 Flashduty MCP 拉取您的渠道、近 30 天故障、团队与成员,归纳出您在用的集成类型与高频故障标签。若扫描结果为空(全新账户),切换到「冷启动」模式,改为完全靠访谈采集。
</Accordion>
<Accordion title="阶段 1.5 — 从本地 AI 编程工具导入(可选)" icon="file-import">
- 可选步骤,需你主动同意,绝不自动触发。如果你已经在 Claude Code / Codex / Cursor / Windsurf / Copilot / Gemini CLI 等本地工具里积累了知识与记忆,可一次性导入,避免后续被反复追问。当 Runner 能直接访问到这些文件时(装在你本机的自托管 Runner),Agent 直接读取 `~/.claude/CLAUDE.md`、各仓库的 `CLAUDE.md` / `AGENTS.md`、`.cursor/rules`、记忆库等;否则(云端沙箱或装在另一台机器上)Agent 给你两段通用提示词,你在本地工具里运行后把结果粘贴 / 上传回来。导入内容按其性质分流:运维 / 服务知识写入知识文件,个人偏好 / 可复用习惯写入 Agent 记忆,重复或无用的则丢弃。所有导入内容在预览或写入前都会先做**密钥脱敏**,密钥永远不会落盘。
+ 可选步骤,需您主动同意,绝不自动触发。如果您已经在 Claude Code / Codex / Cursor / Windsurf / Copilot / Gemini CLI 等本地工具里积累了知识与记忆,可一次性导入,避免后续被反复追问。当 Runner 能直接访问到这些文件时(装在您本机的自托管 Runner),Agent 直接读取 `~/.claude/CLAUDE.md`、各仓库的 `CLAUDE.md` / `AGENTS.md`、`.cursor/rules`、记忆库等;否则(云端沙箱或装在另一台机器上)Agent 给您两段通用提示词,您在本地工具里运行后把结果粘贴 / 上传回来。导入内容按其性质分流:运维 / 服务知识写入知识文件,个人偏好 / 可复用习惯写入 Agent 记忆,重复或无用的则丢弃。所有导入内容在预览或写入前都会先做**密钥脱敏**,密钥永远不会落盘。
</Accordion>
<Accordion title="阶段 2 — 归纳与校正" icon="circle-check">
- Agent 用一段话回述它看到的画面:「我看到 N 个渠道、近 30 天 M 个故障、你似乎在用 [列表]、高频标签包括 [列表]。对吗?还缺什么?」等你确认或纠正,**此时还不写入任何文件**。
+ Agent 用一段话回述它看到的画面:「我看到 N 个渠道、近 30 天 M 个故障、你似乎在用 [列表]、高频标签包括 [列表]。对吗?还缺什么?」等您确认或纠正,**此时还不写入任何文件**。
</Accordion>
<Accordion title="阶段 3–7 — 主题逐项采集" icon="layer-group">
按主题逐阶段采集并成文,每一阶段都遵循「采集 → 草拟文件 → 出清单预览 → 你确认 → 写入并更新 DUTY.md 目录」:
@@ -90,7 +80,7 @@ sidebarTitle: 初始化
| 7 | 集群访问与运行时探查 | `clusters.md`(k8s)/ 追加到 `tools.md`(MCP) |
<Note>
- 阶段 4 中,每一项数据源缺口都按「Monitors 优先」的两步路由处理:扫描摘要中已有 Monitors 使用证据(存在数据源或告警规则)时,Agent 会给出缺口对应的 `type_ident` 与控制台深链 `/monit/datasource?create=<type_ident>`——打开该深链会进入 Monitors 的添加数据源表单并预选该类型;`type_ident` 取值为 prometheus / loki / victorialogs / tencent_cls / sls / mysql / postgres / oracle / clickhouse / elasticsearch。数据源启用后,内置 `monit-query` 能力自动生效,无需安装任何东西。完全没有 Monitors 证据时,才改为通过 MCP 直连登记你在用的工具(见 [MCP](/zh/ai-sre/mcp))。`/init` 自身不会创建或修改 Monitors 数据源。
+ 阶段 4 中,数据源缺口优先通过 Monitors 补齐:如果账户已在使用 Monitors(存在数据源或告警规则),Agent 会给出一个链接,直接打开 Monitors 中已预选对应类型的添加数据源表单(支持 Prometheus、Loki、VictoriaLogs、腾讯云 CLS、SLS、MySQL、PostgreSQL、Oracle、ClickHouse、Elasticsearch)。数据源启用后 AI SRE 即可查询,无需安装其他东西。完全没有使用 Monitors 时,才改为通过 MCP 直连您在用的工具(见 [MCP](/zh/ai-sre/mcp))。`/init` 本身不会创建或修改 Monitors 数据源。
</Note>
<Note>
@@ -98,35 +88,21 @@ sidebarTitle: 初始化
</Note>
</Accordion>
<Accordion title="阶段 8 — 收尾" icon="flag-checkered">
- 当你表示完成时,Agent 给出一段小结:本次创建/更新了哪些文件、登记了哪些 MCP,并提示「任何时候重跑 `/init` 都能继续」。知识本身就是这次会话的持久成果。
+ 当您表示完成时,Agent 给出一段小结:本次创建/更新了哪些文件、登记了哪些 MCP,并提示「任何时候重跑 `/init` 都能继续」。知识本身就是这次会话的持久成果。
</Accordion>
</AccordionGroup>
## 安全与同意
----
-
`/init` 会写知识、可能装 MCP、还会碰到凭证,因此同意与最小权限是它的硬性约束:
-<AccordionGroup>
- <Accordion title="逐项显式同意" icon="hand">
- 任何写入或安装都必须经你明确同意。每个采集阶段在写入文件前都会列出「将创建/更新哪些文件」的清单(每项配 3–5 行摘要),你点头后才执行——绝不会拿一句模糊的「好」直接触发写入。
- </Accordion>
- <Accordion title="凭证永不明文回显" icon="key">
- 当你提供 token、密码、AK/SK 等敏感信息时,Agent 只确认「已记录(长度=N)」,绝不在对话里重复打印明文。
- </Accordion>
- <Accordion title="最小权限凭证" icon="lock">
- 每当需要你提供或生成凭证(kubeconfig、云 AK/SK、数据库账号、API token),Agent 都会要求你按**只读 / 最小权限**来配置;在边界可机器校验时,它会先做一次只读边界检查再记录。
- </Accordion>
- <Accordion title="极简原则" icon="filter">
- 不是所有信息都值得写进知识。Agent 只写「缺了它,AI 在故障里会做出更糟决定」的内容——可有可无的细节不会被塞进去,避免知识变臃肿。
- </Accordion>
-</AccordionGroup>
+- **逐项显式同意**:任何写入或安装都必须经您明确同意。每个阶段写入前都会列出将创建或更新的文件(各附 3–5 行摘要),您点头后才执行,不会凭一句含糊的「好」就写入。
+- **凭证不明文回显**:您提供 token、密码、AK/SK 等敏感信息时,Agent 只记为 `<已记录(长度=N)>`,不在对话里重复明文。
+- **最小权限凭证**:需要提供或生成凭证(kubeconfig、云 AK/SK、数据库账号、API token)时,Agent 会要求按**只读 / 最小权限**配置;能机器校验边界时,会先做一次只读边界检查再记录。
+- **极简原则**:只写缺了就会让 AI 在故障中做出更差决定的内容,可有可无的细节不写,避免知识臃肿。
## 产出什么
----
-
`/init` 的成果是一份可被后续每次会话自动加载的[知识](/zh/ai-sre/knowledge):
- **`DUTY.md`**——知识的目录入口,只放一句话导引和一份 `@文件名` 链接清单,指向各主题文件;
@@ -134,21 +110,19 @@ sidebarTitle: 初始化
- **MCP 登记**(可选)——若访谈中接入了外部工具,会在 `tools.md` 记录并完成 MCP 服务器注册。
<Note>
-`/init` 的主要产出是**知识**,不是 Skill。它不会把内容存成 Skill,除非你明确要求。它也不会自动安装 Agent——这类资源目前需你在控制台手动添加。
+`/init` 的主要产出是**知识**,不是 Skill。它不会把内容存成 Skill,除非您明确要求。它也不会自动安装 Agent——这类资源目前需您在控制台手动添加。
</Note>
## /init 与 /insight:一对最佳实践
----
-
`/init` 和 [`/insight`](/zh/ai-sre/insight) 是运维知识「建立 → 打磨」闭环的两端:
<CardGroup cols={2}>
<Card title="/init — 建底子" icon="seedling">
- 从零把知识搭起来:服务、拓扑、runbook、集群访问一次成体系地沉淀,让 Agent 一上来就懂你的系统。
+ 从零把知识搭起来:服务、拓扑、runbook、集群访问一次成体系地沉淀,让 Agent 一上来就懂您的系统。
</Card>
<Card title="/insight — 持续打磨" icon="gauge-high">
- 回看近 30 天会话,找出反复粘贴的上下文、缺失的 runbook、用错的数据源,告诉你**下一步该往知识里补什么**。
+ 回看近 30 天会话,找出反复粘贴的上下文、缺失的 runbook、用错的数据源,告诉您**下一步该往知识里补什么**。
</Card>
</CardGroup>
@@ -158,16 +132,14 @@ sidebarTitle: 初始化
## 相关页面
----
-
<CardGroup cols={2}>
<Card title="管理知识" icon="book" href="/zh/ai-sre/knowledge">
`/init` 的产出落在这里——了解 DUTY.md 结构、文件约束,以及如何手动编辑与维护。
</Card>
<Card title="使用洞察" icon="gauge-high" href="/zh/ai-sre/insight">
- 用 `/insight` 复盘会话、发现运维摩擦,指导你持续补全知识。
+ 用 `/insight` 复盘会话、发现运维摩擦,指导您持续补全知识。
</Card>
<Card title="MCP(外部工具)" icon="plug" href="/zh/ai-sre/mcp">
- `/init` 可在访谈中帮你接入的外部工具,了解 MCP 的连接与管理。
+ `/init` 可在访谈中帮您接入的外部工具,了解 MCP 的连接与管理。
</Card>
</CardGroup>
diff --git a/zh/ai-sre/insight.mdx b/zh/ai-sre/insight.mdx
index cbb00b0e..890755c5 100644
--- a/zh/ai-sre/insight.mdx
+++ b/zh/ai-sre/insight.mdx
@@ -5,14 +5,10 @@ keywords: ["AI SRE", "insight", "运营洞察", "摩擦报告", "知识", "复
sidebarTitle: 使用洞察
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
在任意 AI SRE 会话的输入框中输入 `/insight`,AI SRE 会回看**您**近 30 天的会话,产出一份单页的运营洞察报告。报告采用羊皮纸样式的 HTML,会作为聊天卡片直接渲染在会话中,您可以预览和下载。
这是一份**教练视角的月度复盘**,而不是一张问题清单:它先讲**做得好的地方**——这一个月 AI SRE 在哪些地方真正帮上了忙;再讲**值得现在就消除的摩擦**——那些一再消耗您时间的模式,比如同一个数据库连接串您在多个会话里反复粘贴、Agent 缺少某个本该已知的排查手册、或它反复查错了数据源;最后给出 **2–3 条更高杠杆的下一步建议**——在「怎么用 AI SRE」这件事上可以尝试的方向。
@@ -21,12 +17,8 @@ sidebarTitle: 使用洞察
`/insight` 是**只读**的。它只做分析和呈现,**不会**自动改动任何知识、Skill 或 MCP 配置。每一条建议都是可复制的文本,是否采纳由您决定。详见 [如何处理建议](#如何处理建议)。
</Note>
-`/insight` 是 AI SRE 内置的一项 Skill:它会自动导出你的历史会话、统计量化指标、逐段分析会话内容,最后汇总渲染成一份报告。整个过程对您透明,您只需要输入 `/insight`。
-
## 如何生成
----
-
<Steps>
<Step title="在会话中输入 /insight">
在任意一个 AI SRE 会话的输入框输入 `/insight` 并发送。无需任何参数。
@@ -58,20 +50,18 @@ sidebarTitle: 使用洞察
<AccordionGroup>
<Accordion title="导出会话并筛选" icon="download">
- AI SRE 先列出范围内近 30 天的会话(默认最多 200 个),覆盖**全部四种入口**——网页(web)、IM、API、自动化(automation);IM 是 AI SRE 的主要入口之一,因此 IM 触发的会话也会一并纳入分析。导出完整记录后,保留**有真实信号**的会话:**用户消息 ≥ 2 轮,或工具调用 ≥ 3 次**(二者满足其一即可,对应 `INSIGHT_MIN_MSGS` / `INSIGHT_MIN_CALLS`)。「工具调用」这一条很关键——它让那些由告警或定时触发的自主会话(可能没有任何人工轮次,却做了十几次工具调用的真实排查)也能进入报告,而不会被「只看人工轮数」的旧规则误删。报告还会在量化总览里给出一行**会话来源**(`entry_mix`),让您看到这些会话分别来自哪些入口。
+ AI SRE 先列出范围内近 30 天的会话(默认最多 200 个),覆盖网页、IM、API、自动化四种入口,然后只保留**有真实信号**的会话:**用户消息 ≥ 2 轮,或工具调用 ≥ 3 次**(满足其一即可)。因此由告警或定时触发、没有人工轮次但做了真实排查的自主会话也会纳入分析。
</Accordion>
<Accordion title="计算量化指标" icon="gauge-high">
- 报告的量化总览——会话数、您的轮数、工具调用数、平均轮数、按天的活跃度、工具与 Skill 分布、会话来源、结果分布——由程序在所有会话上确定性地统计得出,而非由模型估计,因此可靠且始终存在,即便没发现任何摩擦也照常呈现。
+ 报告的量化总览——会话数、您的轮数、工具调用数、平均轮数、按天的活跃度、工具与 Skill 分布、会话来源、结果分布——由程序统计得出,而非模型估计,即使没发现任何摩擦也照常呈现。
</Accordion>
<Accordion title="逐段分析并汇总" icon="layer-group">
- AI SRE 分段阅读会话记录,从每一段提炼出「会话主题」「做得好的地方」与「摩擦发现」,再把全部结果汇总:主题聚合成叙事概述,做得好的地方挑出最有代表性的几条,摩擦发现去重、聚类并按重要度排序成摩擦卡片。每条结论都配一句**逐字引用**作为证据;会话 ID 仅在内部用于统计某个摩擦重复出现的次数,**不会**展示在报告里。报告只包含提炼出的主题与发现,不会逐字搬运您的整段原始会话内容。
+ AI SRE 分段阅读会话记录,从每一段提炼出「会话主题」「做得好的地方」与「摩擦发现」,再把全部结果汇总:主题聚合成叙事概述,做得好的地方挑出最有代表性的几条,摩擦发现去重、聚类并按重要度排序成摩擦卡片。每条结论都配一句**逐字引用**作为证据。报告不展示会话 ID,也不会搬运整段原始会话内容。
</Accordion>
</AccordionGroup>
## 报告内容
----
-
报告自上而下分为**六个部分**。无论是否发现摩擦,量化总览始终呈现。
### 1. 一句话综述(At a glance)
@@ -80,18 +70,18 @@ sidebarTitle: 使用洞察
### 2. 量化总览(Overview)
-由程序确定性计算,而非模型估计;模型只负责把数字誊写进报告。包含:
+由程序统计,而非模型估计。包含:
| 指标 | 说明 |
|---|---|
-| 会话数 | 本次分析的会话数量(`sessions`) |
-| 您的轮数 | 这些会话里您发出的消息总轮数(`your turns`) |
-| 工具调用数 | Agent 发起的工具调用总数(`tool calls`) |
-| 平均轮数 | 每个会话的平均轮数(`avg turns / session`,保留一位小数) |
+| 会话数 | 本次分析的会话数量 |
+| 您的轮数 | 这些会话里您发出的消息总轮数 |
+| 工具调用数 | Agent 发起的工具调用总数 |
+| 平均轮数 | 每个会话的平均轮数(保留一位小数) |
| 活跃度 | 按天的会话活跃柱状图,标出起止日期 |
| 工具分布 | Agent 最常依赖的工具排行(取前 ~6 项) |
| Skill 分布 | 会话中调用过的 Skill 排行;若没有调用过任何 Skill,则显示「未调用任何 Skill」 |
-| 会话来源 | 这些会话分别来自哪些入口,形如 `web(60)· IM(25)· automation(5)`(`entry_mix`) |
+| 会话来源 | 这些会话分别来自哪些入口,形如 `web(60)· IM(25)· automation(5)` |
| 结果分布 | 完成 / 未完成 / 出错的会话数(某项为 0 时省略) |
### 3. 叙事概述(Narrative)
@@ -109,25 +99,24 @@ sidebarTitle: 使用洞察
- **排名**与**摩擦类型标签**(五类之一,见下节);
- 一个**频次徽标**,表示这个摩擦在多少个不同会话里消耗过您(去重后的证据会话数);
- 一句话标题与一段第二人称的解释;
-- **证据**:一句来自会话记录的**逐字引用**(最能说明问题的那句用户或 Agent 的话);会话 ID 仅用于内部去重计数,**不展示**;
-- **可复制的建议**:一段可直接粘贴的文本,其第一行即落点(`Add this to knowledge/<范围>/…`),把目标文件随复制一并带走。
+- **证据**:一句来自会话记录的**逐字引用**(最能说明问题的那句用户或 Agent 的话);
+- **可复制的建议**:一段可直接粘贴的文本,第一行(`Add this to knowledge/<范围>/…`)指明要写入的文件。
### 6. 下一步建议(Next steps)
约 **2–3 条**面向未来、有据可依的建议。它们是**策略层面**的(在「怎么用 AI SRE」上更高杠杆的转变),区别于摩擦卡片那种逐文件的战术修复;每条都点明它所依据的具体观察(某个总览数字或某一类摩擦),并对应一项真实存在的 AI SRE 能力。
-当报告浮现出 `expensive-automation` 涌现模式——某个自动化(automation)入口的会话把大量原始清单拉进上下文、再由 Agent 自己在上下文里计数 / 分组 / 排名,而不是用脚本完成聚合——下一步建议会给出 **Tested-script automation rewrite**:在对话中让 Agent 把该自动化确定性的采集与聚合搬进它知识目录(`knowledge/<范围>/automations/<slug>/`)下一个经过测试的脚本,任务提示只保留目标、交付方式,以及指向该目录的指引。
+两类常见的下一步建议:
-当会话暴露出数据源侧的根因定位缺口时,下一步建议会推荐到 Monitors 添加对应类型的数据源(10 种 `type_ident`:prometheus / loki / victorialogs / sls / tencent_cls / elasticsearch / mysql / postgres / oracle / clickhouse)。这类建议有证据门槛:同一个 `type_ident` 的缺口需在 ≥ 2 个不同会话中出现,或单个会话给出了明确证据。数据源添加后,内置 `monit-query` 查询能力自动可用,无需安装任何 Skill;报告只给建议,不会代为创建或启用数据源,也不会再出现「去市场安装 Skill」式的建议。
+- **Tested-script automation rewrite**:当某个自动化会话把大量原始清单拉进上下文、由 Agent 自己计数 / 分组 / 排名(`expensive-automation` 模式)时,建议在对话中让 Agent 把采集与聚合搬进知识目录 `knowledge/<范围>/automations/<slug>/` 下一个经过测试的脚本,任务提示只保留目标、交付方式和指向该目录的指引。
+- **添加数据源**:当会话暴露出数据源侧的根因定位缺口(同一类型在 ≥ 2 个会话中出现,或单个会话有明确证据)时,建议到 Monitors 添加对应数据源(prometheus / loki / victorialogs / sls / tencent_cls / elasticsearch / mysql / postgres / oracle / clickhouse)。添加后内置的 `monit-query` 查询能力自动可用,无需安装 Skill;报告不会代为创建数据源。
<Note>
-每条摩擦与亮点都必须扎根于至少一个真实会话,并配一句逐字引用作为证据——报告不会凭空捏造会话、事实或排查手册缺口。如果没有发现任何可排序的摩擦,摩擦部分会显示一段空状态提示,而其余部分照常呈现——此时「总览本身就是报告」。
+每条摩擦与亮点都必须扎根于至少一个真实会话,并配一句逐字引用作为证据——报告不会凭空捏造会话、事实或排查手册缺口。没有发现摩擦时,摩擦部分只显示空状态提示,其余部分照常呈现。
</Note>
## 摩擦类型
----
-
`/insight` 只识别五类摩擦,每一类都对应一个明确、可调整的「旋钮」。按默认重要度排序如下:
| 摩擦类型 | 在会话里的样子 | 建议落点 |
@@ -144,36 +133,32 @@ sidebarTitle: 使用洞察
## 如何处理建议
----
-
-报告是**只读**的:它呈现问题、给出可复制的修复文本,但**绝不**自动应用任何改动。目前所有建议都是复制粘贴式的,需要您确认后,再到对应的资源里手动修改。
+报告只给出可复制的修复文本,需要您到对应资源里手动应用。
<Steps>
<Step title="阅读报告,挑出值得做的">
摩擦卡片已按重要度排好序。优先看排名靠前、频次徽标数字高的那几张——它们是最反复消耗您时间的模式。
</Step>
<Step title="复制建议文本">
- 每张卡片的「可复制的建议」里是一段可直接粘贴的文本,其第一行(`Add this to knowledge/<范围>/…`)就是落点,告诉您它该写到哪个文件——复制时会把目标路径一并带上。
+ 复制卡片里「可复制的建议」的文本,第一行(`Add this to knowledge/<范围>/…`)指明要写入的文件。
</Step>
<Step title="到对应资源里手动应用">
根据摩擦类型,到相应的资源里粘贴并保存:重复上下文与臆测实体写进知识的 `services.md` 或 DUTY.md;缺少运行手册则在知识里新增一份 runbook;数据源用错就固定到 `observability.md` / `clusters.md`;知识过期则直接更新那个文件。这些都属于 [知识](/zh/ai-sre/knowledge) 的常规编辑。
</Step>
</Steps>
-<Warning>
-`/insight` 永远不会替您执行写入——它不调用任何同步/安装动作,也不改动知识、Skill 或 MCP。如果您后续想让 AI SRE「把这条 runbook 加进去」,那是一次**独立**的自然语言指令,不属于 `/insight` 的范围。
-</Warning>
+<Tip>
+也可以在之后的对话里直接让 AI SRE「把这条 runbook 加进去」——这是一条独立的指令,不由 `/insight` 执行。
+</Tip>
<Note>
-`/insight` 按需运行、一次一份——它不会「持续盯着」或定时生成报告。建议在又积累了几次故障排查之后再跑一次,看看哪些摩擦已被消除、又冒出了哪些新的。
+`/insight` 只在您输入时运行,不会定时生成。积累几次排障后再跑一次,可以看到哪些摩擦已消除、又出现了哪些新的。
</Note>
## 相关页面
----
-
<CardGroup cols={2}>
- <Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+ <Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
了解会话的创建、团队绑定与作战室——这些决定了 `/insight` 的分析范围。
</Card>
<Card title="管理知识" icon="book" href="/zh/ai-sre/knowledge">
diff --git a/zh/ai-sre/knowledge.mdx b/zh/ai-sre/knowledge.mdx
index cce853ce..74229b28 100644
--- a/zh/ai-sre/knowledge.mdx
+++ b/zh/ai-sre/knowledge.mdx
@@ -2,24 +2,20 @@
title: 了解知识
description: 知识由人维护,写这个环境怎么运转。一份 DUTY.md 加上运行手册、服务清单等文件,会话开始时先读使用说明,其余按需打开。
keywords: ["AI SRE", "知识", "DUTY.md", "运行手册", "上下文"]
-sidebarTitle: 了解知识
+sidebarTitle: "知识"
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
知识是您交给 AI SRE 的运维资料:一份 `DUTY.md` 加上一组运行手册(runbook)、FAQ、服务清单、集群配置等文件。会话开始时,Agent 先读取 `DUTY.md`,再按需打开其它文件,从而把您团队的处置经验、命名约定与系统拓扑带进每一次诊断。
控制台入口:**AI SRE → 自定义 → 上下文 → 知识**。同一分组下的 [记忆](/zh/ai-sre/memory) 是另一页,两者分开管理。
整个账户只能有 1 份共享知识,每个团队最多有 1 份团队知识:
-- **共享(即账户级)**知识对账户内所有 Agent 可见。
+- <strong>共享(即账户级)</strong>知识对账户内所有 Agent 可见。
- **团队级**知识仅在该团队的会话中加载。
知识是 AI SRE 资源的一种,遵循统一的两级作用域模型。其他资源(Skill、MCP、Agent、运行环境)的作用域规则与本页一致。
@@ -30,8 +26,6 @@ sidebarTitle: 了解知识
## DUTY.md 结构
----
-
`DUTY.md` 是整份知识的**目录入口**,每次会话自动加载。Agent 会全文读取 `DUTY.md`,再通过 `@文件名` 引用按需拉取其它文件。系统不会在 `DUTY.md` 之外另附文件列表:知识文件放在会话工作区的 `knowledge/` 目录下,Agent 像浏览代码仓库一样用 ls / glob / grep 查找,`DUTY.md` 没有引用到的文件也能被找到。
如果某个作用域还没有 `DUTY.md`,该作用域不会被静默跳过:系统会告诉 Agent 这个范围没有使用说明、文件在哪个目录下,并要求它在开展实质工作前先列出目录、阅读相关文件。
@@ -71,8 +65,6 @@ Agent 读取 `DUTY.md` 后,会根据当前故障判断需要展开哪些 `@引
## 在控制台维护
----
-
进入 **AI SRE → 自定义 → 上下文 → 知识**。列表每行是一份知识,按范围(「共享」或团队名)标识,列出文件数、`DUTY.md` 状态和最近修改时间。`DUTY.md` 状态有三种:**未创建**、**已同步**,以及 **需梳理 · 之后改了 N 次**(`DUTY.md` 写好之后,这份知识里其它文件又改过)。点击 **创建** 可以为共享范围或您所属的团队新建知识;账户和所有可用团队都已有知识时,按钮置灰。
还没有任何知识时,页面改为引导:**初始化 AI-SRE** 会打开新对话并运行 [`/init`](/zh/ai-sre/init),**上传已有文档** 会打开新对话并弹出附件选择。
@@ -87,13 +79,13 @@ Agent 读取 `DUTY.md` 后,会根据当前故障判断需要展开哪些 `@引
### 让 AI 修改
-正文下方有一个输入框(提示语为「想让 AI 怎么改这份知识?例如:补一份 OOM 排查手册」)。写下要改什么并发送,控制台会打开一个新对话,输入框里已带上这份知识的引用和您的要求;团队知识会把对话切到对应团队。发出后,AI 先用文字说明要改哪些文件、怎么改,您同意后才保存。页面本身不提供改动预览或逐条审阅。
+在正文下方的输入框中写下要改什么(例如「补一份 OOM 排查手册」)并发送,控制台会打开一个带有这份知识引用和您要求的新对话(团队知识会切换到对应团队)。AI 会先说明要改哪些文件、怎么改,经您同意后才保存。
**让 AI 生成** 与下面的 **让 AI 梳理** 也是同样的流程:转到新对话,请求已经写好。
### DUTY.md 需要梳理时
-`DUTY.md` 写好之后,如果这份知识里其它文件又被改过,文件树上方会出现提示:「DUTY.md 写好之后,知识又改了 N 次,可能需要重新梳理」。有编辑权限时,提示下方有两个操作:
+`DUTY.md` 写好之后,如果知识中的其他文件又被修改,文件树上方会提示可能需要重新梳理。有编辑权限时,可以:
- **让 AI 梳理**:转到新对话,让 AI 对照现有文件更新 `DUTY.md` 的索引,改动先经您确认。
- **已核对,不用改**:确认 `DUTY.md` 仍然准确。提示随即消失,直到下一次文件改动。
@@ -104,8 +96,6 @@ Agent 读取 `DUTY.md` 后,会根据当前故障判断需要展开哪些 `@引
## Agent 如何使用知识
----
-
知识不是一次性全量加载,而是**目录先行、按需展开**:
<Steps>
@@ -125,13 +115,11 @@ Agent 读取 `DUTY.md` 后,会根据当前故障判断需要展开哪些 `@引
</Tip>
<Warning>
- 若知识未能成功加载进当前会话,消息列表上方会出现一条警告横幅:「知识加载失败 — 本次会话中 AI-SRE 可能无法访问 DUTY.md 与 runbook。」,并附带 **重试** 按钮,点击后会重新尝试加载。重试成功前,Agent 在该会话中可能无法读取 DUTY.md 与运行手册。
+ 如果知识没能加载到当前会话,消息列表上方会出现警告,此时 Agent 可能无法读取 DUTY.md 与运行手册。点击 **重试** 重新加载。
</Warning>
## 作用域与可见性
----
-
每份知识都有一个作用域:共享范围(即账户级,账户内全局可见)或团队范围。
| 维度 | 共享 | 团队 |
@@ -141,7 +129,7 @@ Agent 读取 `DUTY.md` 后,会根据当前故障判断需要展开哪些 `@引
| 会话中加载 | 所有会话 | 仅绑定该团队的会话 |
| 运行时可读 | 所有会话 | 绑定该团队的会话;以及创建者属于该团队的个人会话(读取即挂载) |
-**编辑权限**:团队知识仅该团队的成员可以操作,组织管理员也需要先加入该团队;共享知识仅账户 Owner 或管理员可以操作;不存在「创建者额外保留权限」的规则。控制台会把你无权编辑的行置灰,并禁用其开关与操作按钮。
+**编辑权限**:团队知识只有该团队成员可以编辑(组织管理员也需先加入该团队);共享知识只有账户 Owner 或管理员可以编辑。创建者没有额外权限。
**创建与改归属**:创建新的团队知识时,您必须是目标团队成员;共享范围创建仅限账户 Owner 或管理员。编辑已有知识时,账户 Owner 或管理员可以把它移动到任意团队,用于恢复空团队或离职成员留下的资源;普通成员只能移动到自己所属的团队。把已有知识提升为共享范围(**设为共享**)与共享范围创建同门槛:仅限账户 Owner 或管理员操作,普通成员即使属于这份知识所在团队也不能自助提升。
@@ -155,8 +143,6 @@ Agent 读取 `DUTY.md` 后,会根据当前故障判断需要展开哪些 `@引
## 最佳实践
----
-
<AccordionGroup>
<Accordion title="把 DUTY.md 当目录,不当正文" icon="book">
`DUTY.md` 只放链接列表与一句话导引,所有实质内容下沉到被 `@引用` 的兄弟文件。这样目录精简、可读,Agent 也能只展开当前故障相关的分支,避免无关内容占用上下文。
@@ -173,15 +159,13 @@ Agent 读取 `DUTY.md` 后,会根据当前故障判断需要展开哪些 `@引
<Accordion title="共享范围放通用、团队范围放专属" icon="users">
共享知识放跨团队通用的约定(命名规范、通用排障方法、平台访问方式);团队知识放该团队专属的服务清单、值班手册与上下游。绑定团队的会话会同时拿到两者。
</Accordion>
- <Accordion title="让 Agent 帮你维护" icon="comments">
+ <Accordion title="让 Agent 帮您维护" icon="comments">
排障过程中沉淀出的新处置经验,可以直接让 Agent「补一篇 runbook」或「记录这个故障模式」,它会对当前作用域读取→编辑→保存,把经验回写进知识,形成持续积累的闭环。
</Accordion>
</AccordionGroup>
## 相关页面
----
-
<CardGroup cols={2}>
<Card title="Skill" icon="rocket" href="/zh/ai-sre/skills">
把可复用的诊断流程封装为 Skill,与知识共享同一套作用域。
@@ -192,7 +176,7 @@ Agent 读取 `DUTY.md` 后,会根据当前故障判断需要展开哪些 `@引
<Card title="了解记忆" icon="brain" href="/zh/ai-sre/memory">
AI 在对话里记下的偏好、做法、事实和教训,与知识分开管理。
</Card>
- <Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+ <Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
了解会话如何绑定团队,以及知识在会话中如何被读取与挂载。
</Card>
</CardGroup>
diff --git a/zh/ai-sre/mcp.mdx b/zh/ai-sre/mcp.mdx
index bf7233db..1767caa8 100644
--- a/zh/ai-sre/mcp.mdx
+++ b/zh/ai-sre/mcp.mdx
@@ -2,17 +2,13 @@
title: MCP(外部工具连接)
description: 通过 Model Context Protocol(MCP),让 AI SRE Agent 接入外部工具与数据源——如 GitHub、Slack、Kubernetes、可观测平台等。在控制台中配置 MCP 服务器、认证方式与作用域,Agent 即可在会话中按需调用其工具。
keywords: ["AI SRE", "MCP", "Model Context Protocol", "MCP 服务器", "外部工具", "OAuth", "API Key", "Agent"]
-sidebarTitle: MCP
+sidebarTitle: "MCP 外部工具"
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
**MCP**(Model Context Protocol)让 AI SRE Agent 接入外部工具与数据源。每台 **MCP 服务器**是一个对外暴露一组工具(函数)的标准化端点,例如查询 GitHub Issue、向 Slack 发消息、读取 Kubernetes 资源、检索可观测平台指标等。
在控制台里配置好 MCP 服务器并启用后,Agent 会在排障故障时**自主判断**何时需要外部能力,并直接调用对应工具,无需您手工搬运数据。
@@ -25,8 +21,6 @@ sidebarTitle: MCP
## 什么是 MCP
----
-
**MCP**(Model Context Protocol,模型上下文协议)是一套开放协议,用统一的方式描述「一台服务器对外提供哪些工具、每个工具接收什么参数、返回什么结果」。它就像 AI Agent 世界的「USB 接口」——任何遵循 MCP 的服务器都能被 Agent 即插即用地发现和调用,无需为每个外部系统单独写适配代码。
在 AI SRE 中,MCP 的作用是把 Agent 的能力从「内置工具」扩展到「任意外部系统」:
@@ -41,61 +35,51 @@ sidebarTitle: MCP
## 从市场安装 MCP 服务器
----
-
进入 **自定义 → 插件 → 概览** 页面,即可看到 Flashduty 精选的第三方 MCP 模板目录。目录按类别分页签展示(全部 / 可观测 / 云与基础设施 / 数据库与中间件 / 代码与协作 / Skill),右上角的搜索框按名称或描述过滤。
-目录上方的 **推荐** 区(说明文字:「按告警来源和常用程度推荐。连接后,AI SRE 排查时能直接用。」)按您账户**已配置的告警集成**挑出匹配的模板(按近 30 天告警量排序),再补上当前语言的精选项,最多展示 3 个;已安装、需要 Runner、或您无权安装的模板不会出现在推荐里。
+目录上方的 **推荐** 区会根据您账户已配置的告警集成(按近 30 天告警量排序)推荐最多 3 个模板,不包括已安装、需要 Runner 或您无权安装的模板。
<Steps>
<Step title="找到要连接的模板">
- 目录每一行展示模板名称与简介;同一屏里混有 MCP / App / Skill 多种类型时,还会带一个类型标签。未安装的行右侧有一个圆形 **+** 按钮:点击 **+** 或点击整行,都会打开「**连接**」对话框。模板需要自托管 Runner、而当前账户又没有可用 Runner 时,行的标签会显示 **需要自托管 Runner**;您无权安装的模板,行上不显示 **+**、整行也不可点击。
+ 点击模板行或其右侧的 **+**,打开 **连接** 对话框。需要自托管 Runner 而账户没有可用 Runner 的模板会标注 **需要自托管 Runner**;您无权安装的模板不能点击。
</Step>
<Step title="核对模板信息并填写连接参数">
- 对话框先展示模板信息:供应商(如「Datadog 官方 · MCP」或「社区版 · MCP」)、官方文档链接、简介,以及一组「**连接后可以这样问**」示例问题。随后是模板声明的连接参数字段——URL / 端点占位符与环境变量等;**共享**字段(服务授权模式下全账号共用)下方标注「全账号共用。」。若模板是「成员授权(密钥)」模式,另有「**你的 API Token**」字段(密码输入框),下方标注「只给你自己用,其他成员第一次使用时各自填写。」,并在字段旁给出「如何获取」文档链接。
+ 对话框会显示模板的供应商、官方文档、简介和示例问题,然后填写连接参数。**共享**字段由全账号共用;成员授权(密钥)模式的模板还需要填写**您自己的 API Token**,其他成员首次使用时各自填写。
</Step>
<Step title="选择运行环境并提交">
- 在「**运行环境**」里选择这次连接从哪个环境发起——默认在会话所在的环境里连接;模板需要自托管 Runner 时,提示「〈名称〉只在内网能访问时,选内网里的自托管 Runner。」。主按钮是 **连接**;若模板是「成员授权(OAuth)」模式,主按钮为「**去〈名称〉授权**」,点击后先创建连接器、再打开浏览器授权窗口(OAuth 的发现、动态客户端注册与令牌交换都从所选环境发起;授权服务器不支持 DCR 时改用 Client ID Metadata Document,见下文「认证」)。
+ 选择从哪个**运行环境**发起连接(默认为会话所在环境)。只能在内网访问的系统,请选择内网中的自托管 Runner。成员授权(OAuth)模式的模板,点击 **去〈名称〉授权** 后会在浏览器中完成授权,见下文[认证](#认证)。
</Step>
<Step title="确认连接结果">
- 提交后系统创建连接器并对它执行一次连接测试。通过则显示「**〈名称〉已连接**」与示例问题,点 **完成** 关闭对话框,或直接点某个示例问题新建一条**已预填**该问题的对话(不会自动发送)。不通过则显示「**连接测试没通过**」与原始错误:可点 **重试** 重跑测试;需要 Runner 的模板在非云端环境下还会给出「让 AI SRE 在 Runner 上装好」入口,新建一条不含任何令牌的对话,让 Agent 到自托管 Runner 上安装缺失的命令行工具(如 `npx` 对应的 Node.js、`uvx` 对应的 uv)。
+ 提交后系统会创建连接器并测试连接。成功后可以点击示例问题,新建一条预填该问题的对话。失败时会显示错误,可以 **重试**;需要 Runner 的模板还可以让 AI SRE 在 Runner 上安装缺失的命令行工具(如 `npx` 需要的 Node.js、`uvx` 需要的 uv)。
</Step>
</Steps>
<Note>
-对话框只在**首次提交**时创建连接器。提交后其中的连接参数即被锁定,并提示「连接器已创建,参数以首次提交为准;如需修改,请到「插件 → MCP」编辑。」。名称与账户内已有连接器冲突时,不再回显后端错误,而是提示「这个账号里已经有名为「〈名称〉」的连接器。要用的就是它,请到「插件 → MCP」完成授权;否则需要账户所有者或管理员先在那里改名或删除,再回来连接。」。
+连接参数以首次提交为准,之后如需修改,请到 **插件 → MCP** 编辑。如果账户中已有同名连接器,请直接使用它,或由账户所有者或管理员改名或删除后再连接。
</Note>
-安装完成的 MCP 服务器会在其配置中记录 `source_template_name`,指向来源模板名称,便于日后追溯其原始出处。**市场安装的 MCP 服务器固定为共享范围**(即账户级,`team_id` 为 0),账户内所有成员可用,安装时不提供团队归属选择;同一模板在同一账户内只能安装出一个实例。
+从市场安装的 MCP 服务器会记录来源模板,**固定为共享范围**(账户内所有成员可用)。同一模板在一个账户内只能安装一次。
<Warning>
-需要 **BYOC Runner** 的模板(详情中的 `requires_runner` 标识)只能在您自己部署了 Runner 的运行环境中使用,云 Sandbox 不支持。`requires_runner` 与传输方式相互独立,当前市场的 50 个模板里两种都有:23 个是 **HTTP 流式**、不需要 Runner,另外 27 个是 **stdio**、需要 Runner——包括阿里云 OpenAPI、阿里云可观测、夜莺 Nightingale、Gitee、GreptimeDB、Prometheus、Grafana (Self-Hosted)、Kafka (Confluent)、AWS、ClickHouse、MySQL、PostgreSQL、阿里云 RDS、Redis、MongoDB 等。这些 stdio 模板以 `uvx` / `npx` 命令在各环境上本地启动,云 Sandbox 无法启动本地子进程,因此安装前请确认您的账户已配置可用的 BYOC Runner,详见 [运行环境(BYOC)](/zh/ai-sre/environments)。
+需要 **BYOC Runner** 的模板只能在您自己部署的 Runner 上使用,云 Sandbox 不支持。当前市场的 50 个模板中,23 个是 **HTTP 流式**、不需要 Runner;27 个是 **stdio**、需要 Runner,包括阿里云 OpenAPI、阿里云可观测、夜莺 Nightingale、Gitee、GreptimeDB、Prometheus、Grafana (Self-Hosted)、Kafka (Confluent)、AWS、ClickHouse、MySQL、PostgreSQL、阿里云 RDS、Redis、MongoDB 等。这些模板通过 `uvx` / `npx` 在本地启动,安装前请确认账户已有可用的 BYOC Runner,详见 [运行环境(BYOC)](/zh/ai-sre/environments)。
</Warning>
### 只能由 Monitors 查询的系统
-目录里还有一类行,代表**只有 Monitors 能查询的系统**(当前是 Loki、VictoriaLogs、Oracle):它们列在对应类别下(可观测 / 数据库);同一屏混有 MCP / App / Skill 等多种类型时,行上带 `Monitors` 类型标签。它们**不是可以通过市场接入的连接器**,只是「在 Monitors 里添加数据源之后,AI SRE 就能查这个系统」的入口,因此不会出现在上方的 **推荐** 区(推荐区是可连接模板的清单)。
+目录中还列出了**通过 Monitors 查询的系统**(当前是 Loki、VictoriaLogs、Oracle)。它们不能在市场中连接:在 Monitors 中添加这类数据源后,AI SRE 就能直接查询,不需要地址、令牌或 Runner。点击这类行可以看到账户中已有的该类数据源;已有数据源时可以点击 **在对话里试试**,还没有时可以点击 **去 Monitors 添加更多 →**(需要添加数据源的权限)。
-点击这样的一行(或它右侧的 **+**,两者打开的是同一个面板)后,面板里**没有「连接」按钮**,只有:
-
-- 账户里**该类型的数据源清单**与状态,形如「已接入 N 个 · 走告警引擎,不用地址、令牌和 Runner」;还没有这类数据源时,显示「还没有 〈类型〉 数据源 · 在 Monitors 里添加后就能查,不用 Runner」。行右侧的 **+** 只在账户还没有该类型数据源、且你有添加数据源权限时才出现,否则该位置显示「已接入 N 个」或「由 Monitors 管理员添加」。
-- 已经接入该类型数据源时,主按钮是 **在对话里试试**:用你的数据源预填一条提问并新建会话(不会自动发送)。
-- 还没有这类数据源时,给出 **去 Monitors 添加更多 →**,新开一页到 Monitors → 数据源 → 添加(类型已选好);没有添加权限的成员只看到「由 Monitors 管理员添加后,这里自动更新」,不给出这个动作。
-
-有些 MCP 模板同时支持「直连 MCP」和「走 Monitors」两条路(例如 Prometheus、MySQL、PostgreSQL、ClickHouse、Elasticsearch、SLS),这类行的标签会写成 `MCP · Monitors`,连接对话框里多一个「接入方式」二选一。
+部分模板(如 Prometheus、MySQL、PostgreSQL、ClickHouse、Elasticsearch、SLS)同时支持直连 MCP 和通过 Monitors 查询,标签为 `MCP · Monitors`,连接时可以选择接入方式。
<Note>
-行名与模板名共用同一套命名空间:如果某个系统已经有同名模板,就只显示模板行(模板行才是带连接参数的那一行)。私有化部署若**不含 Monitors 模块**,上述行不会列出,模板的对话框里也不提供 Monitors 这一路——列表接口会返回 `monit_available: false`,控制台据此隐藏相关入口。
+行名与模板名共用同一套命名空间:如果某个系统已经有同名模板,就只显示模板行(模板行才是带连接参数的那一行)。私有化部署如果**不含 Monitors 模块**,不会显示这些行和 Monitors 接入方式。
</Note>
## 添加 MCP 服务器
----
-
进入 **自定义 → 插件 → MCP** 页面,列表页右上角有两个入口:
- **添加 MCP**:点击后弹出表单,手工定义一台 MCP 服务器(字段见下文「基础字段」)。
-- **在对话中添加**:新建一条 AI SRE 会话,并预填提示词「我想添加一个 MCP。先问我是接入自己的服务,还是找现成的来装。找现成的就问我要接什么系统,插件目录里有就直接装,没有再上网搜几个给我挑,我选好再装。」——由 Agent 先问您要接入自己的服务还是装现成的;装现成的先查插件目录,目录里没有再联网搜索候选给您挑,选好后再完成接入(不会自动发送,您可以先修改提示词)。该按钮只在有明确可写入范围时显示:您能授权到账户范围时始终显示,否则需要当前范围筛选恰好只选中一个您所属的团队(或您只属于一个团队)。
+- **在对话中添加**:新建一条预填提示的会话,由 Agent 询问您要接入自己的服务还是安装现成的,先查插件目录,没有再联网搜索候选供您选择。只有在能确定写入范围时(您有账户级权限,或当前只选中了一个您所属的团队)才显示此按钮。
### 基础字段
@@ -104,11 +88,11 @@ sidebarTitle: MCP
| 名称 | string | 是 | 服务器名,会作为 Agent 调用时的标识(如 `mcp:sqlite-explorer/query` 中的 `sqlite-explorer`)。须以字母开头,仅含字母、数字、`-`、`_`,长度 1–255。同一账户内**不区分大小写、不可重名**,也不能与内置服务器同名 |
| 传输方式 | 枚举 | 是 | Agent 与服务器通信的方式,见下文「传输方式」 |
| 范围 | 共享 / 团队 | 是 | 该 MCP 服务器的作用域:**共享**(账户内全局可见)或某个**团队**(仅该团队成员可见)。详见下文「作用域」 |
-| 执行环境 | 云端环境 / BYOC Runner(可多选) | 否 | 决定该 MCP 服务器在哪些执行环境中可用。可以选择云端环境和一个或多个当前可见的 BYOC Runner;不选择时默认在所有环境可用。它不指定调用路由:MCP 调用仍在当前 AI SRE 会话自身的执行环境中运行。若服务只在某个内网可访问,请只选择能访问它的 Runner。反过来,当这个列表**不包含**当前会话所在的环境时,该会话不能直接调用它——但 Agent 仍然知道它存在、以及它能在哪个环境里运行,见下文「跨环境连接器」。详见 [运行环境(BYOC)](/zh/ai-sre/environments) |
+| 执行环境 | 云端环境 / BYOC Runner(可多选) | 否 | 该服务器在哪些执行环境中可用;不选则所有环境可用。调用总是在会话自身的环境中发起,因此只能内网访问的服务请只选能访问它的 Runner。会话环境不在列表中时,见下文[跨环境连接器](#跨环境连接器)。详见 [运行环境(BYOC)](/zh/ai-sre/environments) |
| 描述 | string | 是 | 描述此服务器的功能,便于在列表中识别 |
<Note>
-MCP 服务器还有一个 **AI 描述**:Agent 首次列出某服务器的工具后,系统会根据工具清单自动生成一段服务器能力摘要并展示在列表中。它随工具集变化自动刷新,无需您手工维护。
+Agent 首次列出某服务器的工具后,系统会自动生成一段 **AI 描述** 显示在列表中,并随工具变化自动更新。
</Note>
### 传输方式
@@ -124,13 +108,13 @@ MCP 服务器还有一个 **AI 描述**:Agent 首次列出某服务器的工
</Warning>
<Note>
-stdio 服务器的命令在 **Runner 所在机器**上运行,而不是配置者本人的电脑。共享配置要求命令与参数对机器通用——不要写个人机器路径(如 `/Users/你的用户名/...`、`/home/你的用户名/...`),并确保执行环境中已安装命令所需的运行时(如 `uv` / `uvx` / `node` / `npx`);运行时缺失会导致服务器连接失败。
+stdio 命令在 **Runner 所在机器**上运行,而不是您的电脑。不要使用个人路径(如 `/Users/<用户名>/...`),并确保 Runner 上已安装所需的运行时(如 `uv` / `uvx` / `node` / `npx`),否则连接会失败。
</Note>
连接与调用各有一个默认超时:连接超时默认 10 秒,工具调用超时默认 60 秒。
<Warning>
-「跳过 TLS 证书校验」只在远端 HTTPS MCP 服务器使用自签证书、且网络环境受控时开启。开启后,Agent 运行环境连接该服务器时会跳过证书链和主机名校验;不要用于公网不可信端点。
+只有当 HTTPS 服务器使用自签证书、且网络环境受控时,才开启「跳过 TLS 证书校验」。不要对公网上不可信的端点开启。
</Warning>
### 认证
@@ -141,12 +125,15 @@ MCP 服务器支持三种**授权模式**,决定凭证如何提供给服务器
<Tab title="服务授权(默认)">
所有会话以同一个服务身份调用。凭证直接写在服务器配置里——HTTP/SSE 传输写进 **Headers**(JSON)(如 `{ "Authorization": "Bearer xxx" }`),stdio 传输写进**环境变量**(JSON)(如 `{ "API_KEY": "xxx" }`)。适合用账户级服务令牌访问的内部系统。
- 凭证**加密存储**:保存时,键名中含 `KEY`、`SECRET`、`TOKEN`、`PASSWORD`、`PASSWD`、`CREDENTIAL`、`AUTHORIZATION`(不区分大小写)的项,其值会被加密后落库,读取时以掩码返回;另外,键名按非字母数字字符切分出的**整段**等于 `PWD` 或 `PASS` 的项同样按此处理——`REDIS_PWD`、`db-pass` 以及裸 `PWD` 都会命中,只是整段中包含该字样的 `BYPASS`、`COMPASS` 不受影响。不匹配上述任何一条规则的项仍按原样保存,因此请把凭证放在能被识别的键名下(如 `Authorization`、`X-API-Key`、`GITHUB_TOKEN`)。
+ 以下键名(不区分大小写)的值会**加密存储**并以掩码显示,其余按原样保存,因此请把凭证放在这类键名下(如 `Authorization`、`X-API-Key`、`GITHUB_TOKEN`):
+
+ - 包含 `KEY`、`SECRET`、`TOKEN`、`PASSWORD`、`PASSWD`、`CREDENTIAL` 或 `AUTHORIZATION`;
+ - 或按非字母数字字符拆分后,某一段正好是 `PWD` 或 `PASS`(如 `REDIS_PWD`、`db-pass`;`BYPASS`、`COMPASS` 不算)。
- 服务授权意味着账户内任何会话都能以这个服务身份调用该系统。若涉及成员个人数据或高危写操作,建议改用「成员授权(密钥)」或「成员授权(OAuth)」。
+ 账户内任何会话都能以这个身份调用该系统。涉及个人数据或高危写操作时,建议改用成员授权。
</Tab>
<Tab title="成员授权(密钥)">
- 每位成员在**首次调用**该服务器的工具时单独提供自己的密钥,密钥加密存储在账户级别、按成员隔离。
+ 每位成员在**首次调用**时提供自己的密钥,密钥加密存储并按成员隔离。
选择此模式需要填写**密钥 Schema**:
@@ -158,47 +145,41 @@ MCP 服务器支持三种**授权模式**,决定凭证如何提供给服务器
适合每个工程师使用各自 API Key 的第三方 SaaS(如个人 GitHub Token)。
</Tab>
<Tab title="成员授权(OAuth)">
- 成员通过 **OAuth 2.1** 流程各自授权;首次调用该服务器的工具时自动弹出授权窗口,授权服务器的发现(discovery)与客户端注册按需进行:授权服务器提供注册端点时走**动态客户端注册(DCR)**;没有注册端点、但声明支持 Client ID Metadata Document 时,fc-safari 不注册客户端,而是把自己公开的 `/safari/oauth/client-metadata.json` 作为 `client_id`,由授权服务器按这个 URL 来取文档,你这一侧不需要任何额外配置。令牌按成员存储并在临近过期时自动刷新。适合支持 OAuth 的服务。
+ 成员通过 **OAuth 2.1** 各自授权,首次调用时自动弹出授权窗口。支持动态客户端注册(DCR);授权服务器不支持 DCR 但支持 Client ID Metadata Document 时也能自动完成,无需额外配置。令牌按成员存储,临近过期时自动刷新。适合支持 OAuth 的服务。
</Tab>
</Tabs>
<Note>
-对于「成员授权(密钥)」与「成员授权(OAuth)」,缺失凭证时 Agent 的工具调用会暂停,并向当前成员弹出凭证录入 / 授权界面;补齐后继续。服务授权模式下不会向成员索取凭证。
+成员授权模式下,缺少凭证时工具调用会暂停,提示当前成员填写或授权,完成后继续。
</Note>
### MCP 服务器授权(设置页)
-「成员授权(密钥)」与「成员授权(OAuth)」的凭证是**按成员**隔离的,因此除了上面那条「对话中按需弹出」的路径,您也可以**在设置页里主动管理**自己对某台 MCP 服务器的授权——两条路径写入的是**同一份**按成员凭证。
+成员授权(密钥 / OAuth)的凭证按成员隔离。除了在对话中按提示授权,您也可以在 MCP 列表中主动管理自己的授权,两种方式保存的是同一份凭证。
-**列表里的授权状态**:MCP 列表的「**成员授权**」列为每台 MCP 服务器显示一个**当前查看者**视角的授权状态角标;文案随授权模式而异——「成员授权(密钥)」保存后系统从不校验其有效性,因此刻意不用「已连接」这个措辞:
+**授权状态**:MCP 列表的「**成员授权**」列显示您自己的授权状态:
- **成员授权(OAuth)**:**● 已连接**(已保存有效凭证)/ **○ 未连接**(尚未提供凭证)。
-- **成员授权(密钥)**:**● 已保存**(已保存密钥)/ **○ 未填写**(尚未提供密钥)。
+- **成员授权(密钥)**:**● 已保存** / **○ 未填写**。系统不会验证密钥是否有效。
- 两种模式通用:**⚠ 已过期**(凭证已过期,OAuth 令牌到期,需重新授权)。
-服务授权模式的 MCP 服务器不涉及按成员授权,此处显示为「—」。对需要个人凭证的服务器,从列表的授权入口打开**凭证**对话框;它只管理您自己的凭证,不会修改服务器的端点、授权模式或作用域配置。
+服务授权模式显示为「—」。点击授权入口打开**凭证**对话框,它只管理您自己的凭证,不会改动服务器配置。
-**凭证对话框里的授权操作**:对话框会根据其授权模式与您当前的凭证状态给出操作:
+**凭证对话框中的操作**:
-- **成员授权(OAuth)**:先选择**执行环境**,再点击 **去授权**(未连接时)/ **重新授权**(已连接或已过期时)。可选择云端 Sandbox 或在线的 BYOC Runner,不能选择「自动」;OAuth 的发现、动态客户端注册、令牌交换和后续刷新都从所选环境发起(授权服务器不支持 DCR 时改用 Client ID Metadata Document,见上文「认证」)。每次打开时会优先预选上次成功授权且仍在线的环境,否则预选绑定且在线的 Runner,最后回退到云端 Sandbox。OAuth 服务只能从内网访问时,请选择能访问它的 BYOC Runner。浏览器随后会弹出授权窗口(经 `/safari/credentials/oauth/initiate` 发起,返回授权链接后在弹窗中打开)。
-- **成员授权(密钥)**:点击 **填密钥**(未连接时)/ **更新密钥**(已连接时),弹出密钥录入弹窗,提交到 `/safari/credentials/secret`。
-- **撤销**:已有凭证时可点击 **撤销**(经 `/safari/credentials/revoke`)删除自己保存的凭证,状态回到「未连接」。
-
-<Note>
-OAuth 授权通过一个浏览器**中转页** `/oauth-callback` 完成:授权服务器回调到 fc-safari,后端再 302 跳到该中转页,中转页用 `postMessage` 把结果回传给发起授权的窗口(设置页或对话页),随后自动关闭。整个过程无需手动复制粘贴令牌。
-</Note>
+- **成员授权(OAuth)**:选择**执行环境**(云端 Sandbox 或在线的 BYOC Runner,不能选「自动」),然后点击 **去授权** 或 **重新授权**,在弹出的浏览器窗口中完成授权,无需复制令牌。只能从内网访问的 OAuth 服务,请选择能访问它的 Runner。系统会默认选中上次授权成功且在线的环境。
+- **成员授权(密钥)**:点击 **填密钥** 或 **更新密钥**。
+- **撤销**:删除您保存的凭证。
## 管理与检视
----
-
-MCP 列表以表格展示每台服务器的**名称**(含 AI 描述)、**范围**(共享或团队名)、**传输方式**、**启用**开关与**操作**列——列表只包含您在账户中添加的 MCP 服务器;内置 Flashduty MCP 服务器由运行时自动注入,不出现在此列表中,详见下文「检视」小节。顶部的范围筛选条(ScopeBar)可在「全部 / 共享 / 团队」之间切换查看;筛选条右侧的搜索框支持按名称、描述、传输方式、URL 等关键词过滤列表。
+MCP 列表显示您添加的每台服务器的名称与描述、范围(共享或团队)、传输方式和启用状态。可以按「全部 / 共享 / 团队」筛选,并按名称、描述、传输方式或 URL 搜索。内置的 Flashduty MCP 服务器不在此列表中。
<AccordionGroup>
<Accordion title="启用 / 禁用" icon="toggle-on">
用列表里的开关切换。只有**已启用**的服务器才会对 Agent 可见;禁用后 Agent 看不到、也无法调用它。
- 已停用(状态不是 `enabled`)的连接器在「连接」入口里**不会被当作已连接**:打开它的「连接」对话框会显示「**连接器已停用**」与「该连接器已停用,AI SRE 暂时无法使用它。需要账户所有者或管理员在「插件 → MCP」里重新启用。」,并给出 **去「插件 → MCP」** 按钮直接跳到该连接器所在行。恢复方式是由账户所有者或管理员在那里用**启用**开关重新启用。已停用的连接器也不再出现在「插件 → 概览」的**已启用**区。
+ 已停用的连接器不能在 **连接** 入口中使用,也不会出现在 **插件 → 概览** 的已启用区,需要账户所有者或管理员在 **插件 → MCP** 中重新启用。
</Accordion>
<Accordion title="编辑" icon="pen-to-square">
点击编辑按钮(或直接点击行)打开表单,可修改名称、传输方式、描述、端点 / 命令、授权模式与作用域。无编辑权限时表单以**只读**模式打开,并提示原因。
@@ -210,33 +191,29 @@ MCP 列表以表格展示每台服务器的**名称**(含 AI 描述)、**范
### 检视:查看某台服务器暴露的工具
-一台 MCP 服务器暴露哪些工具,是在**会话中**由 Agent 按需发现的,而不是在控制台静态展示——因为同一台 MCP 服务器在不同运行环境(Runner)下可达性与工具集可能不同,连接状态与工具数量是「按运行环境」而非「全局」的属性。
+控制台不展示 MCP 服务器的工具列表,因为同一台服务器在不同运行环境中的可达性和工具可能不同。
<Tip>
想确认某台 MCP 服务器在某个运行环境下实际暴露了哪些工具,最直接的方式是在**对话**里让 Agent 列出该服务器的工具,它会把工具清单与每个工具的用法列出来。详见 [对话](/zh/ai-sre/sessions)。
</Tip>
<Note>
-Agent 读取 Flashduty 故障、告警等数据的能力是**内置**的:**Flashduty MCP 服务器**在每个会话启动时由运行时直接注入给 Agent,不经过本页的 MCP 服务器列表接口——它不会出现在上方的服务器列表中,也无需(也无法)在此手动配置、启用或查看。该能力由平台维护,随账户默认可用。
+Agent 读取 Flashduty 故障、告警等数据的能力是**内置**的(Flashduty MCP 服务器),默认可用,不需要也不能在此配置。
</Note>
### 跨环境连接器
-一台 MCP 服务器可以被绑定到**当前会话之外的执行环境**。这时该会话不能直接调用它——不同执行环境之间网络并不互通,工具调用只在会话自身的环境里发起。但 Agent 不会因此以为它不存在:
+MCP 服务器可能绑定在**当前会话之外的执行环境**中。由于不同环境的网络不互通,会话不能直接调用它,但 Agent 知道它的存在:
-- **Agent 一开始就知道它**:会话启动时,Agent 会看到已连接、但绑定在别的执行环境上的连接器清单——名称、用途,以及**这台连接器在哪些执行环境里可用**。同一台连接器在不同环境里可能解析出不同的名称,目录里会带上团队标注以便区分。
-- **搜索会给出它的可用环境**:某次搜索正好匹配到这台连接器时,结果里会附带它能在哪些执行环境运行。
-- **点名提问不会得到「找不到」**:Agent 直接按名字找这台连接器时,会得到「已连接,但绑在别的执行环境」的说明以及该怎么用,而不是当作账户里没有它。
-- **用法是派一个在那个环境里运行的子代理过去**:Agent 会把任务派发给一个在目标执行环境里运行的子代理(`agent_dispatch` 的 `environment` 参数,见 [Agent](/zh/ai-sre/agents)),由子代理在自己那一侧发现并调用这台服务器的工具,再把结果带回当前对话。
-- **只列出现在真正派得过去的环境**:目录里的目标环境是**账户级 Runner** 加上**当前会话所绑定团队**的 Runner,且必须**在线**(以及绑定的云端环境);离线、从未连接、已删除、或属于会话不能派发的团队的环境会被标注出来并给出原因,Agent 会如实说明「现在没法派过去」,而不是假装能调。
-- **只有对话的主会话会看到这份目录**:派发出去的子代理没有自己的派发能力,它只报告自己所在的环境里能直接调用的连接器;需要换环境时由子代理回报父会话处理。
+- Agent 能看到这类连接器的名称、用途和可用环境,按名字询问时也会得到说明,而不是「找不到」。
+- Agent 会派一个子代理到目标环境中调用它(见 [Agent](/zh/ai-sre/agents)),再把结果带回当前对话。
+- 只能派往**在线**的账户级 Runner、当前会话所绑定团队的 Runner,以及绑定的云端环境;其他环境 Agent 会说明暂时无法使用。
+- 只有主会话能这样派发,子代理不能再派发。
-反过来,如果想让某台连接器在**当前**环境里直接可用,把它加进该服务器的「执行环境」列表即可(前提是它对这个会话可达)。运行环境本身的区别见 [运行环境(BYOC)](/zh/ai-sre/environments)。
+在**当前**环境里直接可用,把它加进该服务器的「执行环境」列表即可(前提是它对这个会话可达)。运行环境本身的区别见 [运行环境(BYOC)](/zh/ai-sre/environments)。
## 作用域
----
-
MCP 与其他资源(Skill、知识、Agent、运行环境)共用同一套**两级作用域**模型,分为共享范围与团队范围:
| 作用域 | 可见性 |
@@ -244,15 +221,18 @@ MCP 与其他资源(Skill、知识、Agent、运行环境)共用同一套**
| 共享 | 账户内所有成员可见 |
| 团队级 | 仅该团队成员可见 |
-**编辑权限**:团队级 MCP 服务器仅该团队的成员可以操作,组织管理员也需要先加入该团队;共享范围 MCP 服务器仅账户所有者或管理员可以操作;没有「创建者保留权限」这一例外。无编辑权限时,列表对应行的开关与操作显示为**只读**。
+**编辑权限**:团队级 MCP 服务器只有该团队成员可以编辑(组织管理员也需先加入该团队);共享范围的服务器只有账户所有者或管理员可以编辑。
-**创建与改归属**:创建新的团队级 MCP 服务器时,您必须是目标团队成员;共享范围创建仅限账户所有者或管理员。**从市场安装是例外**:安装固定为共享范围,由安装者发起,普通模板账户内任何成员都可以安装,不需要所有者或管理员权限。但有一类模板例外:在**成员授权**模式(密钥或 OAuth)下还要求填写自由格式的地址 / 主机参数时,安装者实际上决定了其他成员凭证发往哪个主机,为避免他人凭证流向安装者指定的地址,这类模板的安装与连接**仅限账户 Owner 或管理员**——普通成员在该模板行上看不到 **+**、行不可点击,直接打开「连接」对话框会提示「你没有安装权限,请联系账户所有者或管理员。」。编辑已有 MCP 服务器时,账户所有者或管理员可以把它移动到任意团队,用于恢复空团队或离职成员留下的资源;普通成员只能移动到自己所属的团队。但**市场安装的 MCP 服务器不可改归属到团队**——编辑表单中其作用域固定显示为共享;极少量早期遗留的团队级市场行仍可把作用域改回共享,反向则不允许。**该提升操作与共享范围创建同门槛,仅限账户 Owner 或管理员**:普通成员即使属于该服务器所在团队也不能自助操作,被拒绝时会提示「请管理员把它设为共享」。
+**创建与改归属**:
-**运行时可见性**:会话开始时,只会向 Agent 提供**共享范围** MCP 服务器,以及**当前会话所绑定团队**的服务器。当 Agent 在排障中读取另一个团队的知识后,该团队的 MCP 服务器与 Skill 才会被按需挂载进当前会话。**账户是运行时唯一的安全边界,团队只是归属与编辑的标记。**
+- 创建团队级服务器需要是该团队成员;创建共享范围的服务器仅限账户所有者或管理员。
+- 从市场安装的服务器固定为共享范围,任何成员都可以安装。例外:成员授权模式下还需要填写自定义地址的模板,只有账户所有者或管理员能安装,以免其他成员的凭证被发往安装者指定的地址。
+- 账户所有者或管理员可以把服务器移到任意团队(用于接管空团队或离职成员的资源);普通成员只能移到自己所属的团队。
+- 市场安装的服务器不能改为团队范围;少数早期安装的团队级服务器可以由账户所有者或管理员改为共享范围。
-## 相关页面
+**运行时可见性**:会话开始时,Agent 只能使用共享范围和会话所绑定团队的 MCP 服务器;读取其他团队的知识后,才会按需加载该团队的 MCP 服务器与 Skill。**账户是运行时唯一的安全边界,团队只用于归属与编辑权限。**
----
+## 相关页面
<CardGroup cols={2}>
<Card title="Skill" icon="wrench" href="/zh/ai-sre/skills">
@@ -264,7 +244,7 @@ MCP 与其他资源(Skill、知识、Agent、运行环境)共用同一套**
<Card title="BYOC" icon="server" href="/zh/ai-sre/environments">
stdio MCP 服务器需运行在 BYOC Runner 上;了解云 Sandbox 与自托管运行环境的区别。
</Card>
- <Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+ <Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
在会话中观察 Agent 如何检视并调用 MCP 工具。
</Card>
<Card title="Flashduty MCP Server(开发者)" icon="code" href="/zh/developer/mcp-server">
diff --git a/zh/ai-sre/memory.mdx b/zh/ai-sre/memory.mdx
index 3f40c4c6..b7c0fd7a 100644
--- a/zh/ai-sre/memory.mdx
+++ b/zh/ai-sre/memory.mdx
@@ -2,25 +2,19 @@
title: 了解记忆
description: 记忆是 AI 在对话里记下的偏好、做法、事实和教训,之后的对话会自动参考。在 AI SRE → 自定义 → 上下文 → 记忆 查看和修改,个人和团队各看各的。
keywords: ["AI SRE", "记忆", "偏好", "上下文", "个人", "团队"]
-sidebarTitle: 了解记忆
+sidebarTitle: "记忆"
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
AI SRE 每次新会话都从当前范围里已有的记忆文件读起。如果每次都要重新说明您的习惯、某类故障先看哪里、上次为什么放弃了某个做法,排障就得从头介绍背景。记忆把这些从对话里留下来,写成一份份 Markdown 文件,后面的会话继续用。
记忆和[知识](/zh/ai-sre/knowledge)是两回事。知识由人维护,写的是环境怎么运转。记忆由系统整理,写的是从对话里留下来的偏好、做法、事实和教训。两者同属控制台的 [上下文](/zh/ai-sre/context) 分组,但各有一页:**AI SRE → 自定义 → 上下文 → 记忆**。
## 记忆类型
----
-
每份记忆文件开头写明名称、一句话说明和类型。类型只有四种:
| 类型 | 适合记下的内容 |
@@ -34,8 +28,6 @@ AI SRE 每次新会话都从当前范围里已有的记忆文件读起。如果
## 记忆如何产生
----
-
记忆有两条来路:
- **您直接说**:在对话里要求记住、改掉或忘掉一件事,助手会写成或改掉对应的记忆文件。
@@ -45,16 +37,12 @@ AI SRE 每次新会话都从当前范围里已有的记忆文件读起。如果
## Agent 如何使用记忆
----
-
-会话开始时,当前范围里的记忆文件会准备好。助手先看到每份文件的名称和说明,需要细节时再打开正文。绑定了团队的会话用的是这个团队的记忆;没有绑定团队的会话用的是你个人的记忆。
+会话开始时,当前范围里的记忆文件会准备好。助手先看到每份文件的名称和说明,需要细节时再打开正文。绑定了团队的会话用的是这个团队的记忆;没有绑定团队的会话用的是您个人的记忆。
四类记忆的分量不同:procedure、fact、lesson 是过去的记录,用之前需要按当前情况核实;preference(偏好)是您明确提出的要求,在它说明的范围内照做,与 Skill 或工具的默认做法冲突时,以偏好为准。
## 作用域与隔离
----
-
记忆只有 personal(个人)与 team(团队)两种作用域,没有账户级记忆,跨账号读取会被直接拒绝。
| 维度 | personal(个人) | team(团队) |
@@ -68,8 +56,6 @@ AI SRE 每次新会话都从当前范围里已有的记忆文件读起。如果
## 在控制台查看和修改
----
-
进入 **AI SRE → 自定义 → 上下文 → 记忆**。
- **选范围**:顶部在 **个人** 和 **团队** 之间切换;选团队时再从下拉里挑一个您所属的团队。没有共享(账户级)记忆。范围和团队记在页面地址里,刷新或分享链接会打开同一组记忆。
@@ -85,8 +71,6 @@ AI SRE 每次新会话都从当前范围里已有的记忆文件读起。如果
## 相关页面
----
-
<CardGroup cols={2}>
<Card title="了解上下文" icon="layer-group" href="/zh/ai-sre/context">
记忆和知识怎么分,以及个人、团队、共享范围各自有什么。
diff --git a/zh/ai-sre/overview.mdx b/zh/ai-sre/overview.mdx
index cf6f532f..e0b322a4 100644
--- a/zh/ai-sre/overview.mdx
+++ b/zh/ai-sre/overview.mdx
@@ -11,13 +11,11 @@ sidebarTitle: 概述
## 什么是 AI SRE
----
-
AI SRE 是 Flashduty 推出的自治 SRE Agent 平台。您通过对话向 AI 下达指令,由它自主调查故障、排查根因、调用工具执行诊断,并把每次排障中沉淀的运维知识固化下来供后续复用。
它不是一个只会问答的聊天机器人,而是一个**能动手的排障工作者**:会自己规划步骤、读写文件、查询监控与日志、执行命令、调用外部工具(MCP),并在需要时把子任务委派出去,最终给出有调查过程支撑的结论。
-AI SRE 与 Flashduty 的故障响应体系深度联动:当 Flashduty 产生故障(incident)或开启作战室协作时,可直接触发一个 AI SRE 会话,让 Agent 带着故障上下文进入排查现场——既可以在控制台里对话,也可以**直接在你的 IM 群(Slack / 飞书 / 钉钉 / 企业微信)里 @ 它**。
+AI SRE 与 Flashduty 的故障响应体系深度联动:当 Flashduty 产生故障(incident)或开启作战室协作时,可直接触发一个 AI SRE 会话,让 Agent 带着故障上下文进入排查现场——既可以在控制台里对话,也可以**直接在您的 IM 群(Slack / 飞书 / 钉钉 / 企业微信)里 @ 它**。
<CardGroup cols={2}>
<Card title="对话即排障" icon="comments">
@@ -30,8 +28,6 @@ AI SRE 与 Flashduty 的故障响应体系深度联动:当 Flashduty 产生故
## 典型场景
----
-
AI SRE 不止是控制台里的一个对话框——它围绕「故障从触发到复盘」的完整生命周期,覆盖多个协作入口:
<CardGroup cols={2}>
@@ -45,21 +41,19 @@ AI SRE 不止是控制台里的一个对话框——它围绕「故障从触发
为故障开启 IM 作战室时,AI SRE **自动跑一轮初步诊断**并把结论回贴到作战室——人还没开始排查,第一手分析就已经在群里了。
</Card>
<Card title="运营复盘洞察" icon="gauge-high">
- 用 [`/insight`](/zh/ai-sre/insight) 复盘最近 30 天的会话,量化你把时间花在了哪里、哪些 runbook 缺失、哪些上下文被反复粘贴,输出可复制的改进建议。
+ 用 [`/insight`](/zh/ai-sre/insight) 复盘最近 30 天的会话,量化您把时间花在了哪里、哪些 runbook 缺失、哪些上下文被反复粘贴,输出可复制的改进建议。
</Card>
</CardGroup>
## 开通与计费
----
-
-AI SRE 面向持有**有效(已启用)**On-call 专业版及以上订阅的账户开放,无需申请。
+AI SRE 面向持有<strong>有效(已启用)</strong>On-call 专业版及以上订阅的账户开放,无需申请。
<AccordionGroup>
<Accordion title="计费规则" icon="gift">
AI SRE 自 2026 年 9 月 16 日 8 点(北京时间)起按实际用量计费,以 credits 结算,1 credit = ¥1;此前的用量不收费。计量项为模型用量、沙箱在线时长和联网检索。开通免费,符合条件的账户每个计费周期赠送体验额度,也可以购买资源包(1,000 / 5,000 / 20,000 credits,对应 ¥950 / ¥4,500 / ¥17,000,自支付起 365 天有效)。按量付费默认关闭,由管理员开启,可设置每周期上限。完整规则见[《AI SRE credits 资源包购买协议》](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
- 体验额度、资源包与钱包余额都用尽时,AI SRE 会拒绝新的对话请求:输入区被禁用,上方常驻一条**不可关闭**的提示(文案由服务端给出,覆盖「尚未开通」「已关闭」「本周期额度用尽」「钱包余额不足」四种情形),并附带 **前往 AI SRE 计费** 入口,跳转到费用中心(`/wallet/plan?product=ai-sre`)。由管理员在那里开通按量付费、购买资源包或充值,状态恢复后即可继续对话。订阅失效或版本不含 AI SRE 是另一类拦截,横幅按钮会换成 **前往 On-Call 订阅**,见[订阅失效与恢复](#订阅失效与恢复)。
+ 体验额度、资源包与钱包余额都用尽时,AI SRE 会暂停新的对话,并在输入区上方提示原因和 **前往 AI SRE 计费** 入口。管理员可以在那里开启按量付费、购买资源包或充值,之后即可继续对话。
</Accordion>
<Accordion title="人工授权" icon="user-check">
生产变更、重启、回滚和外部通知,最终都由您确认后才会执行。
@@ -68,63 +62,38 @@ AI SRE 面向持有**有效(已启用)**On-call 专业版及以上订阅的
### 开通与关闭 AI SRE
-开通和关闭都在控制台的同一张卡片上自助完成:左侧菜单进入 **费用中心**,打开 **订阅**(页面标题为「您的订阅」),选中 **AI SRE** 页签,也就是 `/wallet/plan?product=ai-sre`——额度提示里的 **前往 AI SRE 计费** 入口跳转的也是这里。费用中心只对 SaaS 版本开放,私有化部署没有这个页签。
+在控制台进入 **费用中心 → 订阅**,选择 **AI SRE** 页签,即可自助开通或关闭。此功能仅 SaaS 版提供,需要**费用查看**和钱包交易权限。
-进入该页需要 **费用查看** 权限;**开通 AI SRE** 与 **关闭 AI SRE** 按钮还要求钱包交易权限(控制台在开通入口旁的原话是「需钱包交易权限」),缺少该权限时按钮为禁用状态,鼠标悬停会提示「您无权进行该操作」。
-
-| 操作 | 按钮 | 费用 | 结果 |
-|------|------|------|------|
-| 开通 | **开通 AI SRE**(卡片显示 **未开通** 时出现) | ¥0,不扣款 | 提交一张 ¥0 订单,订单完成后卡片状态变为 **已开通** |
-| 关闭 | **关闭 AI SRE**(卡片显示 **已开通** 时出现) | ¥0,不扣款也不退款 | 提交一张 ¥0 退订订单,服务端确认关停后订单完成,卡片状态回到 **未开通** |
-
-点 **关闭 AI SRE** 会先弹出二次确认「关闭 AI SRE?」,正文是「关闭后本账户无法再发起 AI SRE 调查。已购资源包和体验赠送额度会保留,随时可以重新开通。」确认后控制台会轮询订单状态,并按下列文案反馈:
-
-| 订单结果 | 控制台提示 |
-|----------|------------|
-| 完成 | AI SRE 已关闭 |
-| 轮询约 1 分钟仍未拿到终态(订单仍在处理中) | 关闭请求已提交,正在处理中,请稍后刷新查看 |
-| 失败 | AI SRE 关闭失败,请重试。 |
-
-关闭的影响:
+| 操作 | 费用 | 结果 |
+|------|------|------|
+| **开通 AI SRE** | 免费 | 开通后即可使用 |
+| **关闭 AI SRE** | 不扣款,也不退款 | 关闭后本账户不能再发起新的调查;已在进行中的运行不会中断,其用量照常计量 |
-- **不能再发起新的调查**:关闭后本账户无法再发起 AI SRE 调查,被拒时服务端给出的提示是「本账户已关闭 AI SRE,重新开启后即可使用。」(额度总览上报 `blocked_reason=turned_off`)。已经开始的一个顶层运行不会被中断,它后续产生的用量仍照常计量。
-- **额度和资源包保留**:体验赠送额度与已购资源包的余额、有效期都不会因为关闭而被清零,重新开通后继续可用(赠送额度本身仍按协议只在发放所属的计费周期内可用)。重新开通就是再走一次 **开通 AI SRE**,不需要额外操作。
-- **不收费也不退款**:关闭本身不产生费用,也不触发退款;资源包的退款仍按[《AI SRE credits 资源包购买协议》](/zh/compliance/ai-sre-credit-package-purchase-agreement)处理。
-- **欠费、订阅失效都不影响关闭**:关闭不检查钱包余额,也不要求有效的 On-call 订阅,欠费或订阅已失效的账户同样可以关闭。
+关闭后:
-<Warning>
-关闭需要服务端确认关停。确认不成功时订单不会完成,控制台提示「AI SRE 关闭失败,请重试。」——直接重试即可,不需要先做其他操作。
-</Warning>
+- 体验额度和已购资源包的余额、有效期都**保留**,重新开通后继续可用(体验额度仍只在发放的计费周期内有效)。
+- 资源包退款按[《AI SRE credits 资源包购买协议》](/zh/compliance/ai-sre-credit-package-purchase-agreement)处理。
+- 欠费或订阅已失效时也可以关闭。
+- 如果关闭失败,直接重试即可。
### 订阅失效与恢复
-AI SRE 的准入在每次请求时都会重新校验账户的 On-call 订阅,所以订阅一旦失效,AI SRE 会立即暂停。界面会直接给出服务端生成的提示,并区分两种情形——它们的处理方式不同,别照着错误的那个做:
+AI SRE 需要**有效的** On-call 专业版及以上订阅。订阅不满足条件时,AI SRE 会立即暂停,控制台、IM、自动化和 A2A 调用都会收到提示:
-| 情形 | 提示 | 处理方式 |
-|------|------|----------|
-| 订阅版本高于或等于专业版,但订阅未启用(已过期,或因其它原因被停用) | 「本账户的 On-call 订阅已失效(已过期或已停用),AI SRE 已暂停;续费 On-call 订阅后自动恢复。」 | 续费 On-call 订阅 |
-| 账户没有订阅,或订阅版本低于专业版(无论是否已启用) | 「AI SRE 需要 On-call 专业版订阅,升级订阅后即可使用。」 | 升级到专业版及以上 |
+| 情形 | 处理方式 |
+|------|----------|
+| 专业版及以上订阅已过期或被停用 | 续费 On-call 订阅 |
+| 没有订阅,或订阅低于专业版 | 升级到专业版及以上 |
-该提示会出现在控制台对话页、IM 会话、自动化运行记录与 A2A 调用错误里;额度总览也会以 `blocked_reason=no_license` 上报同一句提示。
-
-控制台对话页在输入区上方常驻一条横幅,右侧按钮**按被拦原因分流**:
-
-| 被拦原因 | 按钮 | 去向 |
-|----------|------|------|
-| 订阅失效或版本不含 AI SRE(`blocked_reason=no_license`,也就是本节这两种情形) | **前往 On-Call 订阅** | 售卖 On-call 订阅的订阅页 `/wallet/plan?product=oncall` |
-| 其余原因(尚未开通、已关闭、本周期额度用尽、钱包余额不足等) | **前往 AI SRE 计费** | 售卖 AI SRE credits 的订阅页 `/wallet/plan?product=ai-sre` |
-
-订阅类拦截不会指向 AI SRE 计费页——那一页卖的是 AI SRE credits,解决不了订阅问题。恢复不需要重新开通:续费或升级成功后,下一次请求即自动放行。
+这时控制台提示旁的按钮是 **前往 On-Call 订阅**(其他原因则是 **前往 AI SRE 计费**)。续费或升级后,AI SRE 自动恢复,无需重新开通。
## 核心能力
----
-
AI SRE 围绕"对话排障 + 知识沉淀 + 自主执行"构建了一套完整能力,每一项都可在控制台中配置和管理。
<CardGroup cols={2}>
<Card title="对话式排障" icon="comments" href="/zh/ai-sre/sessions">
- 以会话为单位与 Agent 协作。会话按顺序处理你的每条消息,支持流式输出、随时取消、长对话自动压缩上下文,以及从故障一键拉起。
+ 以会话为单位与 Agent 协作。会话按顺序处理您的每条消息,支持流式输出、随时取消、长对话自动压缩上下文,以及从故障一键拉起。
</Card>
<Card title="IM 平台" icon="comment-dots" href="/zh/ai-sre/im">
在 Slack / 飞书 / 钉钉 / 企业微信中 @ Agent 发起或续接排查,并在故障作战室里自动给出初步诊断。
@@ -151,19 +120,17 @@ AI SRE 围绕"对话排障 + 知识沉淀 + 自主执行"构建了一套完整
让 AI SRE 按周期、API 调用或 On-call 故障事件触发执行隐藏会话,自动产出巡检、洞察或复盘结果。
</Card>
<Card title="Apps" icon="grid-2" href="/zh/ai-sre/apps">
- 授权外部应用(目前为 GitHub),让 AI SRE 直接进入你的代码仓库工作:理解代码、调查 PR 与提交、按需开 PR 或提 Issue。
+ 授权外部应用(目前为 GitHub),让 AI SRE 直接进入您的代码仓库工作:理解代码、调查 PR 与提交、按需开 PR 或提 Issue。
</Card>
</CardGroup>
## 控制台导航
----
-
进入 AI SRE 后,左侧导航有四个入口(菜单名与控制台一致):
| 入口 | 作用 |
|------|------|
-| 新对话 | 与 Agent 协作排障的主工作区。侧边栏列出会话(支持搜索、筛选、置顶、归档),右侧为对话与调查过程。详见[控制台](/zh/ai-sre/sessions)。 |
+| 新对话 | 与 Agent 协作排障的主工作区。侧边栏列出会话(支持搜索、筛选、置顶、归档),右侧为对话与调查过程。详见[控制台对话](/zh/ai-sre/sessions)。 |
| 自动化 | 按周期、API 调用或 On-call 故障事件触发的后台任务。详见[自动化](/zh/ai-sre/automations)。 |
| 产物 | 查看和管理 Agent 通过 present_files 工具发布的文件与报告:支持搜索、按个人 / 团队筛选;每个产物可复制链接、下载、重命名或删除(重命名与删除需编辑权限)。详见[产物](/zh/ai-sre/artifacts)。 |
| 自定义 | 打开二级侧栏,管理 Agent 用到的资料、扩展和执行环境,分三组(见下表)。点击后默认进入 **插件 → 概览**。 |
@@ -182,16 +149,12 @@ AI SRE 围绕"对话排障 + 知识沉淀 + 自主执行"构建了一套完整
## 快速开始
----
-
从登录控制台到跑完第一次排障,详细步骤见 [快速开始](/zh/ai-sre/quickstart)。
## 下一步
----
-
<CardGroup cols={2}>
-<Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+<Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
了解会话、流式输出、取消与上下文压缩,以及如何从故障拉起排查。
</Card>
<Card title="IM 平台" icon="comment-dots" href="/zh/ai-sre/im">
diff --git a/zh/ai-sre/quickstart.mdx b/zh/ai-sre/quickstart.mdx
index d83832d4..cfa75fe1 100644
--- a/zh/ai-sre/quickstart.mdx
+++ b/zh/ai-sre/quickstart.mdx
@@ -11,26 +11,22 @@ sidebarTitle: 快速开始
## 必要概念(30 秒)
----
-
上手前只需要知道这四件事:
| 概念 | 是什么 |
|---|---|
-| 会话 | 你和 Agent 的一次协作,控制台或 IM 里都能开 → [控制台](/zh/ai-sre/sessions) |
-| @ 引用 | 把故障现场带进对话的方式,输入 `@` 搜索并插入故障 → [控制台](/zh/ai-sre/sessions) |
-| 知识 | 你维护的、关于你系统的长期资料(DUTY.md、运行手册、服务清单),越完整定位越准 → [了解知识](/zh/ai-sre/knowledge) |
-| 运行环境 | Agent 动手的地方——云端 Sandbox 或你内网的 BYOC Runner → [运行环境](/zh/ai-sre/environments) |
+| 会话 | 您和 Agent 的一次协作,控制台或 IM 里都能开 → [控制台对话](/zh/ai-sre/sessions) |
+| @ 引用 | 把故障现场带进对话的方式,输入 `@` 搜索并插入故障 → [控制台对话](/zh/ai-sre/sessions) |
+| 知识 | 您维护的、关于您系统的长期资料(DUTY.md、运行手册、服务清单),越完整定位越准 → [了解知识](/zh/ai-sre/knowledge) |
+| 运行环境 | Agent 动手的地方——云端 Sandbox 或您内网的 BYOC Runner → [运行环境](/zh/ai-sre/environments) |
## 三个入口(从哪儿开始)
----
-
-AI SRE 没有唯一入口,从你现在所在的场景开始就好:
+AI SRE 没有唯一入口,从您现在所在的场景开始就好:
### 控制台对话(Chat)
-适合主动排查一个问题、深入追问、沉淀知识。进入 **AI SRE**,点击左侧的 **新对话**;输入框下方有场景卡,点击即可填入现成提示词;输入 `@` 可引用故障。→ 详见[控制台](/zh/ai-sre/sessions)
+适合主动排查一个问题、深入追问、沉淀知识。进入 **AI SRE**,点击左侧的 **新对话**;输入框下方有场景卡,点击即可填入现成提示词;输入 `@` 可引用故障。→ 详见[控制台对话](/zh/ai-sre/sessions)
### 自动化(Automations)
@@ -42,18 +38,16 @@ AI SRE 没有唯一入口,从你现在所在的场景开始就好:
## 第一次排障(约 5 分钟)
----
-
前提条件:账户内至少有一条故障记录。AI SRE 无需申请;自 2026 年 9 月 16 日 8 点(北京时间)起,需先在控制台开通。
-如果你现在手头没有故障,可以先跳到下面的「之后:把它建设成你的 SRE」。
+如果您现在手头没有故障,可以先跳到下面的「之后:把它建设成你的 SRE」。
<Steps>
<Step title="新建一个对话">
进入 **AI SRE**,点击左侧边栏的 **新对话**。
</Step>
<Step title="带上故障上下文">
- 在输入框里输入 `@`,会弹出故障搜索列表,选中你要排查的那条故障——它会作为一枚引用胶囊插入到输入框里。也可以直接点输入框下方的场景卡 **排查一个故障**:它会把一段现成的提示词填进输入框,你可以在发送前用 `@` 补上具体的故障引用。
+ 在输入框里输入 `@`,会弹出故障搜索列表,选中您要排查的那条故障——它会作为一枚引用胶囊插入到输入框里。也可以直接点输入框下方的场景卡 **排查一个故障**:它会把一段现成的提示词填进输入框,您可以在发送前用 `@` 补上具体的故障引用。
</Step>
<Step title="发送指令">
发送类似这样的一句话:
@@ -67,36 +61,34 @@ AI SRE 没有唯一入口,从你现在所在的场景开始就好:
</Step>
</Steps>
-**完成标志**:你收到一份包含调查计划、工具调用记录和结论的回复,并且可以针对结论继续追问。
+**完成标志**:您收到一份包含调查计划、工具调用记录和结论的回复,并且可以针对结论继续追问。
**如果卡住,检查这些**:
- 输入 `@` 没搜到目标故障——确认这条故障确实存在于当前账户,名称或编号没有拼错;
- 长时间没有响应或停在"运行环境初始化"——多半是云端 Sandbox 或 Runner 正在启动,稍等片刻;持续无响应见[运行环境](/zh/ai-sre/environments)的故障排查;
- 只给了结论、没给调查计划——直接追问"先给我一份调查计划,再逐条给证据",Agent 会补上;
-- 看不到 **AI SRE** 入口——入口按角色权限展示,请联系账户管理员确认你的角色具备 AI SRE 相关权限。
-
-**下一步**:想了解流式输出、取消、Fork、上下文压缩等控制台细节,见[控制台](/zh/ai-sre/sessions)。
+- 看不到 **AI SRE** 入口——入口按角色权限展示,请联系账户管理员确认您的角色具备 AI SRE 相关权限。
-## 之后:把它建设成你的 SRE(按需)
+**下一步**:想了解流式输出、取消、Fork、上下文压缩等控制台细节,见[控制台对话](/zh/ai-sre/sessions)。
----
+## 之后:把它建设成您的 SRE(按需)
-跑完第一次排障只是起点。接下来可以把分析变成自动动作,并持续提升它排查的准头——后者取决于它对你系统的了解程度、以及能连到多少真实数据。这些都可以按需慢慢建设,不必一次做完。
+跑完第一次排障只是起点。接下来可以把分析变成自动动作,并持续提升它排查的准头——后者取决于它对您系统的了解程度、以及能连到多少真实数据。这些都可以按需慢慢建设,不必一次做完。
### 让每条新故障自动得到第一轮分析
手动排查顺了之后,把它变成默认动作:进入 **AI SRE → 自动化**,从内置模板 **故障自动分析** 创建规则,在「触发方式」里启用 **On-call incident** 卡片,选好要监听的协作空间和严重程度。之后每条匹配的新故障创建时,AI SRE 都会自动跑一轮排查,并把一条总结评论写回这条故障——结论在最前面,末尾附完整会话链接;评论沿故障现有的通知链路推送,响应人在 IM 里就能看到第一手分析。配置细节见[自动化 · On-call 故障触发](/zh/ai-sre/automations#on-call-故障触发)。
-它与作战室自动诊断是两条独立链路:这条对每一条匹配的新故障生效,结果写回故障评论;作战室自动诊断在你为故障开启 IM 作战室时运行,结果回贴到作战室群里(见 [IM 平台](/zh/ai-sre/im))。
+它与作战室自动诊断是两条独立链路:这条对每一条匹配的新故障生效,结果写回故障评论;作战室自动诊断在您为故障开启 IM 作战室时运行,结果回贴到作战室群里(见 [IM 平台](/zh/ai-sre/im))。
### 建一份团队知识
-Agent 每次排障都从零猜「这是什么服务」「谁负责」「以前是怎么处理的」,效率就上不去。在会话里输入 `/init`,Agent 会用访谈的方式带你梳理服务清单、runbook、值班路径等知识,逐条确认后写入知识,后续会话自动加载。完整访谈流程见[初始化(/init)](/zh/ai-sre/init),知识结构与最佳实践见[管理知识](/zh/ai-sre/knowledge)。
+Agent 每次排障都从零猜「这是什么服务」「谁负责」「以前是怎么处理的」,效率就上不去。在会话里输入 `/init`,Agent 会用访谈的方式带您梳理服务清单、runbook、值班路径等知识,逐条确认后写入知识,后续会话自动加载。完整访谈流程见[初始化(/init)](/zh/ai-sre/init),知识结构与最佳实践见[管理知识](/zh/ai-sre/knowledge)。
### 接入真实数据源
-默认情况下 Agent 只能看到 Flashduty 自身的数据。要让它查到你系统里的真实信息——日志、指标、代码仓库、内网数据库,需要接入 MCP 服务器或部署 BYOC Runner。公网可达的服务(如可观测平台、GitHub)从 MCP 市场一键安装并授权即可,见 [MCP(外部工具)](/zh/ai-sre/mcp);VPC、内网数据库或本地命令,则需要在能访问目标资源的机器上部署 Runner——往下看,大约 3 分钟。
+默认情况下 Agent 只能看到 Flashduty 自身的数据。要让它查到您系统里的真实信息——日志、指标、代码仓库、内网数据库,需要接入 MCP 服务器或部署 BYOC Runner。公网可达的服务(如可观测平台、GitHub)从 MCP 市场一键安装并授权即可,见 [MCP(外部工具)](/zh/ai-sre/mcp);VPC、内网数据库或本地命令,则需要在能访问目标资源的机器上部署 Runner——往下看,大约 3 分钟。
### 部署一个 BYOC Runner(约 3 分钟)
@@ -119,13 +111,11 @@ Agent 每次排障都从零猜「这是什么服务」「谁负责」「以前
## 下一步
----
-
<CardGroup cols={2}>
<Card title="产品概述" icon="robot" href="/zh/ai-sre/overview">
了解 AI SRE 的定位、能力全景与控制台导航。
</Card>
-<Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+<Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
会话的新建与管理、流式输出、Fork、上下文压缩。
</Card>
<Card title="IM 平台" icon="comment-dots" href="/zh/ai-sre/im">
diff --git a/zh/ai-sre/sandbox.mdx b/zh/ai-sre/sandbox.mdx
index 21f293d0..6a1963dd 100644
--- a/zh/ai-sre/sandbox.mdx
+++ b/zh/ai-sre/sandbox.mdx
@@ -5,14 +5,10 @@ keywords: ["AI SRE", "云端沙箱", "Sandbox", "运行环境", "回退", "出
sidebarTitle: Sandbox
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
**云端沙箱**(Sandbox)是由 Flashduty 托管的**临时执行环境**——一个开箱即用的隔离容器。AI SRE Agent 的工具调用(执行命令、读写文件、运行 Skill、连接 MCP)都可以在其中完成,您**无需安装或维护任何东西**。
它是 AI SRE 的**默认回退环境**:当没有当前成员可用的在线自托管 Runner([BYOC Runner](/zh/ai-sre/environments#byoc-runner))时,会话会自动在云端沙箱里执行;您也可以在会话里**手动指定**使用它。
@@ -30,8 +26,6 @@ sidebarTitle: Sandbox
## 什么时候用云端沙箱
----
-
云端沙箱适合**不依赖您内网的排查**,以及快速上手:
- **快速上手 / 演示**:还没有部署 Runner,想先体验 AI SRE 的排障能力;
@@ -44,8 +38,6 @@ sidebarTitle: Sandbox
## 在会话中使用
----
-
聊天输入框底部的**环境选择器**决定本次会话在哪里执行,与云端沙箱相关的有两个选项:
| 选项 | 行为 |
@@ -59,8 +51,6 @@ sidebarTitle: Sandbox
## 云端沙箱 vs. 自托管 Runner
----
-
| 维度 | 云端沙箱(Sandbox) | 自托管 Runner([BYOC Runner](/zh/ai-sre/environments#byoc-runner)) |
|---|---|---|
| 部署 | 无需安装,系统托管 | 在您自己的机器上部署常驻进程 |
@@ -75,13 +65,11 @@ sidebarTitle: Sandbox
## 相关页面
----
-
<CardGroup cols={2}>
<Card title="BYOC Runner" icon="server" href="/zh/ai-sre/environments#byoc-runner">
在自己的机器上部署常驻 Runner,让排查直连您的内网。
</Card>
- <Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+ <Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
在会话中查看本次绑定的执行环境与状态。
</Card>
<Card title="MCP(外部工具)" icon="plug" href="/zh/ai-sre/mcp">
diff --git a/zh/ai-sre/sessions.mdx b/zh/ai-sre/sessions.mdx
index 5af8df8f..64a9618e 100644
--- a/zh/ai-sre/sessions.mdx
+++ b/zh/ai-sre/sessions.mdx
@@ -1,545 +1,334 @@
---
-title: 控制台
+title: "控制台对话"
description: AI SRE 会话承载您与 Agent 的一次完整对话,包含消息、流式响应、工具调用与产物;本文介绍会话的新建与管理、分享、消息发送、任务面板与后台任务、产物预览、会话 Fork、上下文压缩、团队绑定与会话数据导出。
keywords: ["AI SRE", "会话", "对话", "流式响应", "工具调用", "任务面板", "后台任务", "Artifacts", "Fork", "上下文压缩", "绑定团队", "导出", "NDJSON"]
-sidebarTitle: 控制台
+sidebarTitle: "控制台对话"
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
会话(Session)是您与 AI SRE 的一次完整对话。它承载您发送的每一条消息、Agent 的流式回复、过程中的工具调用,以及 Agent 产出的产物(Artifacts,例如代码、报告、图表或 Skill 压缩包)。
-每个会话相互独立,拥有自己的上下文、绑定的团队与运行环境。您在左侧边栏切换会话,在中间的对话区收发消息、查看回复与产物。
-
-<Note>
-会话之间彼此隔离:上下文、绑定团队、运行环境互不影响。切换会话不会中断正在运行的回合——AI SRE 会持续把进展写入会话,您返回时可继续看到流式输出。
-</Note>
+每个会话相互隔离,拥有自己的上下文、绑定团队与运行环境。您在左侧边栏切换会话,在中间的对话区收发消息、查看回复与产物。切换会话不会中断正在运行的回合,返回时可以继续看到流式输出。
## 新建与管理会话
----
-
-左侧边栏是会话的统一入口。点击 **新对话** 即可开启一个全新会话;列表按最近活动倒序排列,初始显示最近的若干条,更多历史通过 **显示更多** 逐步展开。
+在左侧边栏点击 **新对话** 开启新会话。列表按最近活动排序,点击 **显示更多** 查看更早的会话。
-在空白的 AI SRE 新会话中,输入框上方会显示四张场景建议卡片:**排查一个故障**、**用自然语言查数据**、**治理告警噪音**和**定时自动巡检**。点击卡片只会把预置提示填入输入框,不会立即发送;你可以修改后再按 Enter。
+新会话的输入框上方有四张场景建议卡片:**排查一个故障**、**用自然语言查数据**、**治理告警噪音**和**定时自动巡检**。点击卡片会把提示填入输入框,修改后再发送。
### 搜索与筛选
-<Steps>
- <Step title="搜索对话">
- 顶部搜索框按会话名称过滤;无结果时显示 **未找到匹配对话**。
- </Step>
- <Step title="按范围 / 发起人 / 状态 / 活动筛选">
- 点击列表右上角的 **筛选** 图标打开筛选面板,按下列维度组合过滤;当存在非默认筛选时,筛选按钮上会出现一个小圆点提示。
- </Step>
-</Steps>
-
-筛选面板支持的维度:
+顶部搜索框按会话名称搜索。点击列表右上角的 **筛选** 图标可以按以下维度组合筛选(有筛选生效时图标上会显示小圆点):
-| 维度 | 可选值 | 说明 |
-|---|---|---|
-| 范围 | 全部 / 个人 / 团队 | 选择 **团队** 后可在 **我的团队 / 指定团队** 之间切换,默认 **我的团队**;只有切到 **指定团队** 才会展开内联列表,可搜索并多选你所属的团队 |
-| 发起人 | 全部 / 我发起的 / 指定成员 | 按会话的创建者收窄结果:**我发起的** 只看你自己创建的会话;**指定成员** 展开可搜索的成员列表(一次最多加载 50 人,列表为空、无匹配和加载失败各有对应提示),命中其中任一成员的会话即保留,一个成员都不选等同于不按发起人过滤。该维度仅在 **范围** 不是 **个人** 时出现 |
-| 状态 | 活跃 / 归档 / 全部 | 默认仅显示 **活跃** 会话;切到 **归档** 查看已归档会话 |
-| 最近活动 | 全部 / 24 小时 / 7 天 / 30 天 | 按会话最近一次活动时间收窄结果 |
-
-面板底部提供 **重置**(恢复默认筛选)与 **完成**(关闭面板)。
+| 维度 | 可选值 |
+|---|---|
+| 范围 | 全部 / 个人 / 团队(团队可选 **我的团队** 或指定您所属的团队) |
+| 发起人 | 全部 / 我发起的 / 指定成员(范围为个人时不显示) |
+| 状态 | 活跃(默认)/ 归档 / 全部 |
+| 最近活动 | 全部 / 24 小时 / 7 天 / 30 天 |
### 会话可见性与操作权限
-会话以账户为硬边界,跨账户永远不可访问。在同一账户内,个人会话和团队会话的读取、继续对话与管理权限不同:
+会话不能跨账户访问。在同一账户内:
| 会话类型 | 可读取 / 继续对话 | 可重命名、归档、删除或关联故障 |
|---|---|---|
| 个人会话(未绑定团队) | 仅创建者本人 | 仅创建者本人 |
-| 团队会话(绑定团队) | 同账户内拿到会话 ID 的成员 | 会话创建者、账户 Owner / 管理员、或该团队成员 |
+| 团队会话(绑定团队) | 同账户内拿到会话链接的成员 | 会话创建者、账户 Owner / 管理员、或该团队成员 |
-置顶是个人偏好,不会修改会话本身;只要您有权读取这条会话,就可以为自己置顶或取消置顶。账户 Owner / 管理员可以管理团队会话,但不能读取或管理其他成员的个人会话。
+置顶只影响您自己的列表。账户 Owner / 管理员可以管理团队会话,但不能读取其他成员的个人会话。
### 分享会话
-聊天页头部提供分享入口,仅当您对当前会话有管理权限时显示。点击 **复制分享链接** 按钮即可开启分享并把链接复制到剪贴板(提示「分享链接已复制」);链接在当前会话地址上附加 `share_token`,令牌位于 URL 片段(`#` 之后)中。分享链接是**稳定链接**:分享保持开启期间,重复复制得到的是同一条链接。
+对会话有管理权限时,可以点击聊天页头部的 **复制分享链接**。
-| 事项 | 说明 |
-|---|---|
-| 谁能分享 | 对会话有管理权限的成员——个人会话的创建者,或团队会话的创建者 / 账户 Owner / 管理员 / 团队成员 |
-| 谁能打开 | 持有链接、且登录了**同一账户**的成员;链接不跨账户,也不支持匿名访问 |
-| 持链接者看到什么 | 会话以**只读**模式打开,对话区提示「这是一个只读分享会话」:可查看完整上下文(消息、工具调用、产物),也可以点开 Subagent 派发卡片查看子会话的执行详情(同样只读);但输入框被只读提示替换,不能继续对话或修改原会话 |
-| 如何继续排查 | 持链接者可点击 **Fork 为新会话**,把会话派生为自己的新会话后继续处理 |
-| 如何撤销 | 分享开启后头部出现 **取消分享** 按钮,点击后链接立即失效(提示「分享已取消」);之后重新开启分享会生成新链接,旧链接不会恢复可用 |
-
-分享主要改变**个人会话**的可见性:团队会话本来就允许同账户成员凭会话 ID 读取(见上表),而个人会话默认只有创建者可见,分享链接是同账户其他成员打开它的唯一方式。
+- 只有登录了**同一账户**的成员能打开链接,不支持匿名访问。分享开启期间,链接保持不变。
+- 打开链接的人以**只读**方式查看完整会话(包括子任务的执行详情),不能继续对话;可以点击 **Fork 为新会话** 在自己的新会话中继续排查。
+- 点击 **取消分享** 后链接立即失效;再次分享会生成新链接。
+- 个人会话默认只有创建者可见,分享链接是让同账户其他成员查看它的方式。
<Note>
-隐身(incognito)会话不支持分享。
-
-Subagent / A2A 子会话本身也不能单独开启分享——分享只能在**根会话**上开启。但当你分享了根会话后,持链接者在只读视图里点开 Subagent 派发卡片时,可以一并只读查看对应的子会话执行详情;子会话是纯查看的,不提供 **Fork 为新会话**。撤销根会话的分享后,子会话的访问同时失效。
+隐身会话不能分享。分享只能在根会话上开启,不能单独分享子任务(Subagent / A2A)会话。
</Note>
### 单条会话操作
-将鼠标悬停在会话行上,会显示置顶与归档操作;置顶的会话在名称左侧常驻一个图钉标记。
-
| 操作 | 入口 | 说明 |
|---|---|---|
-| 置顶对话 / 取消置顶 | 行内悬停的图钉按钮 | 置顶会话排在列表前列 |
-| 归档对话 / 取消归档 | 行内悬停的归档按钮 | 归档后默认从活跃列表隐藏,可在筛选中切到 **归档** 找回 |
-| 重命名 | 对话标题处点击直接编辑 | 回车或失焦提交,Esc 取消;名称最长 60 字 |
-| 删除 | 聊天页头部的删除按钮(需管理权限) | 确认后删除会话,对话历史不可恢复;删除会一并尽力终止会话仍在运行的后台命令 / 监视器进程——终止不成功也不阻塞删除,且不再发送任务通知 |
+| 置顶 / 取消置顶 | 鼠标悬停在会话行上 | 置顶的会话排在列表前列 |
+| 归档 / 取消归档 | 鼠标悬停在会话行上 | 归档的会话在筛选中切到 **归档** 可以找回 |
+| 重命名 | 点击对话标题 | 最长 60 字 |
+| 删除 | 聊天页头部(需管理权限) | 删除后不可恢复,会话中仍在运行的后台任务也会被终止 |
-新会话无需手动命名:第一回合结束后,系统会在服务端根据会话内容自动生成标题,并通过会话流以 `session.renamed` 帧推送回来,前端据此就地更新侧边栏与标题;在生成完成前,会先用你的第一条消息派生一个临时标题占位,避免侧边栏长时间停在「未命名」。你随时可以**重命名**来覆盖自动生成的标题(标题最长 60 字)。
-
-<Tip>
-在会话行上停留片刻,会弹出工具提示,显示完整会话名、所属团队与精确时间——便于在名称被截断时确认这是不是您要找的会话。
-</Tip>
+新会话会在第一轮对话结束后自动生成标题,您可以随时重命名。
### 列表状态指示
-每行右侧按优先级显示状态标记:会话正在运行时只显示转圈;否则可同时出现后台任务角标与未读点;都没有时显示相对时间。
-
| 标记 | 含义 |
|---|---|
-| 旋转的圆圈 | 该会话的 Agent 正在运行(有回合在进行中,或正在等待子任务回报);优先于其他所有标记 |
-| 🔭 + 数字 | 该会话有对应数量存活的后台任务(监视器 / 后台命令),详见下文「任务面板与后台任务」 |
-| 蓝色小圆点(未读) | Agent 产出了您尚未查看的新内容;可与 🔭 角标同时出现 |
-| 相对时间 | 以上都没有时,显示最近活动的相对时间(如 `5m`、`3h`、`3d`) |
-
-打开会话即会清除该会话的未读小圆点。
+| 旋转的圆圈 | Agent 正在运行 |
+| 🔭 + 数字 | 正在运行的后台任务数,见[任务面板与后台任务](#任务面板与后台任务) |
+| 蓝色小圆点 | 有您尚未查看的新内容,打开会话后消失 |
+| 相对时间 | 最近活动时间(如 `5m`、`3h`) |
## 发送消息与流式响应
----
-
-在底部输入框输入消息后回车发送。输入框支持 Markdown,并支持以斜杠命令(输入 `/` 调出命令菜单)触发内置 Skill 与命令。
-
-当控制台发布了新版本时,输入框上方会显示一条**版本更新提示**:「控制台已发布新版本,刷新页面后继续」。点击 **刷新** 会重新加载页面以使用新版本;点击关闭按钮可隐藏提示,同一版本不再重复提示(提示仅在全功能 Web 控制台显示,嵌入模式与私有化部署不显示)。
+在底部输入框输入消息后按回车发送。输入框支持 Markdown,输入 `/` 可以调出 Skill 与命令菜单。控制台发布新版本时,输入框上方会提示刷新页面。
### 附件与上下文引用
<AccordionGroup>
<Accordion title="上传附件" icon="paperclip">
- 点击输入框左下角的加号按钮选择文件,或直接粘贴图片。支持图片、PDF、文本 / Markdown / CSV / HTML、Office 文档(Word / Excel / PowerPoint),以及压缩包(`.zip` / `.rar`),单个文件最大 **50MB**。HTML 文件按纯文本读取,并在沙箱中渲染,不会执行其中的脚本。压缩包**不会被解析成文本内联**:Agent 只拿到它在沙箱中的路径,需要先查看压缩包目录清单(`unzip -l` / `bsdtar -tv`),再在沙箱内解包后读取内容——一个不大的压缩包也可能展开出大量文件。单条消息最多上传 **9 个文件**,且全部附件总大小不超过 **50MB**;**单文件上限**与**单条消息附件总量上限**是两个独立的限制,当前数值恰好都是 50MB,不要混为一谈。文件数与总量上限都会在选择附件时由前端立即校验并分别给出提示——此时附件只是本地暂存(以待发胶囊展示),发送消息时才统一实际上传。截图可直接在对话中粘贴。
-
- 未在上面列出的扩展名(如 `.go`、`.py`、`.yaml` 等代码与配置文件),只要文件全文是合法的 UTF-8 文本,也会按纯文本接收;空文件除外,仍会被拒绝。
-
- 除单个文件外,还可以**整个文件夹上传**:点击加号菜单中的 **上传文件夹** 选择本地文件夹,或直接把文件夹拖进输入区。文件夹按以下规则处理:
+ 点击输入框左下角的加号选择文件,或直接粘贴截图。
- - **文件数上限**:单个文件夹最多包含 **50 个文件**;超过上限时整个文件夹会被拒绝(提示「该文件夹超过 50 个文件上限,请选择更小的文件夹」),而不是只保留前 50 个。`node_modules` 目录与以 `.` 开头的文件 / 目录会被静默忽略,不计入文件数。
- - **逐文件校验**:文件夹内的每个文件仍按单文件规则校验(单文件 50MB、附件总量 50MB、类型校验)。不满足的文件会被跳过,选择文件夹后输入区会显示「已跳过 N 个文件」清单,逐条列出文件名与跳过原因(超过 50MB / 超出附件总量 50MB / 非文本文件 / 不支持的文件类型)。
- - **附件计数**:整个文件夹在一条消息里只算 **1 个附件**,同样计入单条消息 9 个附件的上限。
- - **目录结构保留**:文件夹内文件的相对路径(含顶层文件夹名)会被完整保留并 staging 进沙箱。Agent 看到的是一份按路径排序的文件清单(信封形式,含文件数与总大小),而不是把文件内容内联进上下文;它通过沙箱内的 read / bash / grep 等工具按需读取具体文件。
-
- **大文件的内联截断**:除压缩包以外(压缩包不解析文本,只把沙箱路径交给 Agent),附件以解析出的文本形式内联进 Agent 上下文。解析文本超过 **64KB** 时,只内联开头 **32KB**(在有效的 UTF-8 边界截断),并在附件末尾附上完整文件在沙箱中的路径提示(形如 `~/.flashduty/attachments/...`)——Agent 需要完整内容时,会用沙箱内的 read / bash 等工具按该路径读取原文件,不会丢失内容。此外,超过 **3MB** 的 PDF 不再以原生形式直传模型,而是回退为文本抽取,同样受上述截断规则约束。
+ - **支持的类型**:图片、PDF、文本 / Markdown / CSV / HTML、Office 文档、压缩包(`.zip` / `.rar`),以及任何 UTF-8 编码的文本文件(如 `.go`、`.py`、`.yaml`)。空文件不能上传。
+ - **大小与数量**:单个文件最大 **50MB**;每条消息最多 **9 个附件**,总大小不超过 **50MB**。
+ - **文件夹**:可以从加号菜单选择 **上传文件夹**,或把文件夹拖进输入区。一个文件夹最多 **50 个文件**(`node_modules` 和以 `.` 开头的文件不计入),超过时整个文件夹会被拒绝;不符合要求的单个文件会被跳过并列出原因。一个文件夹算 1 个附件,目录结构会保留。
+ - **Agent 如何读取**:附件以文本形式提供给 Agent;超过 64KB 的文本只直接提供开头部分,Agent 会在需要时从沙箱中读取完整文件。压缩包和文件夹不会直接展开,Agent 在沙箱中按需解包和读取。
</Accordion>
<Accordion title="上下文引用" icon="link">
- 从故障、告警、监控规则、监控对象、数据源、RUM 异常详情页(右上角的 **AI 修复** 按钮)等页面进入 AI SRE 时,相关对象会作为**引用胶囊**自动嵌入输入框——它是一枚内联的小标签,标明所引用对象的类型——故障、告警事件、告警、监控规则、主机、监控对象、数据源、告警分析或 RUM 异常——并随消息一起发送给 Agent,让它直接基于该对象开始分析。点击胶囊可在新标签页打开对应对象;点击胶囊上的关闭按钮即可在发送前移除引用。
+ 从故障、告警、监控规则、监控对象、数据源或 RUM 异常详情页(**AI 修复** 按钮)进入 AI SRE 时,相关对象会作为**引用标签**自动放进输入框,随消息一起发给 Agent。点击标签可以打开该对象,发送前也可以移除。
- **这类入口还会附带一句默认提问**,胶囊就落在提问句中入口标记的位置。例如从监控对象页进入时,输入框预填的是「请分析这个监控对象 〈引用胶囊〉:基于真实观测数据判断当前是否有问题或隐患,说明依据与影响面,并给出下一步排查或处置建议。请区分已确认事实、合理推断和待确认项;证据不足时明确说明不确定,不要过度归因」;从数据源列表进入时预填「调用 〈引用胶囊〉 的 overview tool,校验 overview tool 是否可用」;在 RUM 异常详情页点击 **AI 修复** 进入时预填「请用 rum skill 修复这个 RUM 异常 〈引用胶囊〉:先按 issue-fix 流程拉取 issue 上下文,再从应用关联的代码仓库定位出错代码。能确认根因且改动有把握时,新建分支提交 Draft PR,并在 PR 描述里附上这个 issue 的链接;没有把握时只给出分析结论和修复建议,不要提 PR。不要直接推送默认分支。请区分已确认事实、合理推断和待确认项。」,该按钮仅在账户已开通 AI SRE 时显示。预填只是草稿,发送前可以随意修改或删掉,也可以不改直接发送。
+ 这些入口通常还会预填一句提问(例如要求 Agent 区分已确认事实与推断),您可以修改后再发送。一次带入多个引用时不会预填提问。
- **交接只带一个引用时会预填提问**:当本次交接合并后恰好只剩一个引用、且该引用里带了入口维护的默认提问时,输入框会预填这句提问,`[[ref]]` 占位处则落成引用胶囊。例如在故障列表里对多条故障批量点击 **AI 分析**,输入框预填的就是「请批量分析这些故障 〈引用胶囊〉:先判断它们之间的关联性(同一根因、连锁反应或彼此独立)并分组;再按组给出可能根因与影响面;最后给出整体处置建议与优先级。需要单个故障的细节时用工具按需拉取,不必逐个展开全部故障。请区分已确认事实、合理推断和待确认项;证据不足时明确说明,不要声称执行了未执行的操作。」,胶囊标题为「故障清单(N)」;带多个引用的交接则不预填提问,输入框保持原样。一条消息可携带多个引用。除了从相关页面自动携带引用外,也可以在任意会话的输入框里直接输入 `@` 触发故障搜索下拉(支持关键词模糊匹配与近期故障列表),选中后插入与自动携带相同的引用胶囊——这是一个随时可用的独立引用入口。输入邮箱地址不会误触发该下拉:当 `@` 紧跟在邮箱地址字符(字母、数字或 `._%+-`)之后时,选择器不会弹出;而空格之后、或与中文相邻的 `@` 仍正常触发。
+ 在任意会话中输入 `@` 可以搜索故障并插入引用。输入邮箱地址时不会触发搜索。
</Accordion>
<Accordion title="知识与 Skill" icon="book">
- 会话启动时会按绑定团队自动加载对应的知识与 Skill;详见下文 <a href="/zh/ai-sre/knowledge">知识</a> 与 <a href="/zh/ai-sre/skills">Skill</a>。
+ 会话启动时会按绑定团队自动加载对应的知识与 Skill;详见 <a href="/zh/ai-sre/knowledge">知识</a> 与 <a href="/zh/ai-sre/skills">Skill</a>。
</Accordion>
</AccordionGroup>
### 实时流式输出
-发送后,Agent 的回复实时流式返回——文本逐字显示,工具调用与思考过程也会即时呈现。
-
-发送瞬间,前端会乐观地把回合标记为「运行中」;约 300ms 后由后端的运行状态确认接管,因此即便您切换页面再回来,运行状态也不会丢失。
+Agent 的回复会实时显示,包括文本、工具调用和思考过程。切换页面再回来,运行状态不会丢失。
<Note>
-回合运行期间,**发送按钮会变为停止按钮**。点击停止会立即中断当前回合:界面随即反馈,被中断的回合会带上「已中断」标记,刷新后依然可见。
-</Note>
-
-<Note>
-会话流以**帧**的形式推送进展,每一帧都可能携带 `is_error` 与 `error_code` 两个字段,用来标记**运行时失败**。判定刻意收得很窄:只有运行环境把一次真实失败转换成面向用户的错误、并在持久化的事件行上打了标记之后,这一帧才会带上它们;**平台内部的控制行(回合结算、自动化回合结果等簿记事件)与模型 / 供应商返回的原始错误文本都不会进入这条路径**。所以带 `error_code` 的帧可以当作「平台对用户暴露的运行时错误」来消费;反过来,没有这两个字段也不代表这一帧内部没有诊断信息。这与下方「[会话数据导出](#会话数据导出)」里那条表示导出流出错的 `error` 行不是一回事:`is_error` / `error_code` 挂在正常的事件帧上,`error` 是流本身出问题时追加的独立行。
+运行期间,发送按钮会变为停止按钮。点击停止会立即中断当前回合,该回合会标记为「已中断」。
</Note>
### 运行中继续输入(排队)
-回合运行期间输入框依然可用:您可以继续输入并发送,消息会进入队列,在当前回合结束后依次执行。排队消息以一张可折叠的卡片展示在输入框上方,标题显示排队条数(如「3 条排队」);队列中的消息可逐条编辑或移除,超过一条时卡片右上角还提供 **全部清空** 一键清空整个队列。
-
-队列以服务端为准:已发送但 Agent(Actor)尚未读取的消息保存在服务端队列中,`POST /safari/session/get` 响应的 `pending_messages` 字段就是它的投影(按执行顺序排列)。在 Agent 开始处理前,您可以**撤回**一条这样的消息——撤回接口为 `POST /safari/session/message/cancel`,请求体携带 `session_id` 与 `invocation_id`(即发送消息时 202 回执 / `user_message_enqueued` 帧下发的调用 ID),响应中的 `result` 字段给出结果:
-
-| 结果 | 含义 |
-|---|---|
-| `removed` | 消息已从队列移除,**永远不会执行**;服务端向所有订阅方推送 `user_message_cancelled` 帧,各客户端据此丢弃对应的待处理(pending)气泡 |
-| `consumed` | Agent 已读取该消息,它属于运行中的回合——撤回不生效,该回合照常执行(「来不及了」) |
-| `forbidden` | 只有消息作者本人可以撤回;非作者调用返回 `ErrAccessDenied` |
-
-撤回只触碰等待队列:Agent 已读取的信封不再可撤回(返回 `consumed`),想中断正在执行的回合请使用**停止**。只有「普通人类消息」可撤回——提问作答(`function_response`)、内部生产者(自动化、子会话通知、父会话初启消息等)的信封不在其列。该能力同样适用于 API 集成发送的排队消息。调用方需要具备该会话的**参与权限**(与发送消息、中断同一门控),并且只有消息作者本人能成功撤回——两个条件都满足才是 `removed`。
+运行期间仍可以继续发送消息,消息会排队,在当前回合结束后依次执行。排队的消息显示在输入框上方,可以逐条编辑、移除或全部清空。Agent 开始处理某条消息后,就不能再撤回它;如需中断,请点击停止。
### 运行环境初始化
-会话首次运行时,对话流中会出现一张 **运行环境初始化** 卡片,分步展示运行环境(沙箱)的就绪过程:**建立云端容器 → 启动运行时**;若云端模板本身带有启动脚本,新建或重建时还会追加第三个阶段 **运行 setup 脚本**(恢复已有沙箱时不会重跑该脚本)。各阶段串行推进,每次只显示当前正在进行的一步;全部完成后卡片折叠为一行结果,按本次是新建、恢复还是重建分别显示:
+会话首次运行时,对话中会出现 **运行环境初始化** 卡片,显示沙箱的准备进度,完成后折叠为一行:
-| 模式 | 折叠后的提示 | 含义 |
-|---|---|---|
-| 新建 | 已初始化会话 | 首次为会话创建全新的云端容器 |
-| 恢复 | 已恢复会话 | 复用此前的沙箱,文件保持不变 |
-| 重建 | 已重建会话 | 原沙箱已被回收,已创建一个新的容器 |
+| 提示 | 含义 |
+|---|---|
+| 已初始化会话 | 为会话创建了新的云端沙箱 |
+| 已恢复会话 | 复用此前的沙箱,文件保持不变 |
+| 已重建会话 | 原沙箱已被回收,创建了新的沙箱 |
-<Note>
-绑定自托管 [BYOC Runner](/zh/ai-sre/environments#byoc-runner) 的会话不显示云端阶段:初始化卡片只含一个阶段——**正在连接自托管运行器**(新建、恢复、重建均是如此),连接成功后变为 **已连接自托管运行器**,随后同样折叠为对应的结果行。若连接自托管运行器失败,卡片会收缩为一行简短的错误提示 **连接自托管运行器失败**(附具体原因),不提供云端阶段历史展开。
-</Note>
+使用自托管 [BYOC Runner](/zh/ai-sre/environments#byoc-runner) 的会话只显示连接 Runner 这一步。
<Warning>
-当上一个沙箱因空闲被回收时,卡片会给出警示:**原沙箱因闲置 N 分钟被回收 — 已保存的文件被重置**。这意味着此前写入沙箱文件系统的内容已不复存在。请将需要长期留存的产出**保存为 Artifact 或沉淀到知识**,而不要依赖沙箱内的临时文件。
-</Warning>
-
-<Warning>
-若初始化过程中出现错误,卡片会转为 **初始化失败** 的错误态,点击可展开查看各阶段的历史与具体错误信息。此时通常需要重试新建会话,或联系 Flashduty 支持。
+沙箱因闲置被回收后,其中的文件会被重置。需要保留的产出请**保存为 Artifact 或沉淀到知识**。初始化失败时,点击卡片可以查看错误详情,通常重新发起会话即可,或联系 Flashduty 支持。
</Warning>
## 工具调用与产物
----
-
-Agent 在回合中调用的工具(读写文件、查询监控、执行命令、调用 MCP 工具等)以内联可折叠的形式呈现在对话流中,点击即可展开查看输入与输出,默认折叠以保持对话整洁。
+Agent 调用的工具(读写文件、查询监控、执行命令、调用 MCP 工具等)默认折叠显示在对话中,点击可以查看输入与输出。
### 任务计划(Todo List)
-执行多步骤任务时,Agent 会在对话流中放置一枚可点击的进度徽标(形如「第 X / N 步」,带环形进度指示),点击展开为任务计划清单:每一步都带状态图标(未开始 / 执行中 / 已完成 / 已取消)与优先级标签(高 / 中 / 低)。当 Agent 结束回合但某一步仍处于「执行中」时,该步会呈现为「已暂停」,提示您需要发送新消息才能推进,而不是仍在后台运行。
+执行三个及以上步骤的任务时,Agent 会在对话中显示进度徽标(如「第 X / N 步」),点击可以展开任务清单,查看每一步的状态与优先级。如果回合结束时某一步仍未完成,它会显示为「已暂停」,需要您发送新消息才会继续。
-任务计划只在**确实有人看清单**的渠道维护:`write_todos`(维护清单的内置工具)仅在控制台(`web`)与 IM 渠道会话中提供——web 面板渲染 TodoList 卡片,IM 侧渲染为进度卡。**自动化(`automation`)与 API(`api`)会话没有该工具**:Agent 在这些会话中调用不到 `write_todos`,也收不到「请维护待办清单」的提醒,多步任务直接执行、不产出进度清单(自动化运行仍可在控制台查看完整消息与工具调用记录,但没有清单)。被派发的子会话(Subagent / A2A)同样不提供该工具——待办状态按会话隔离,子会话写入会覆盖父会话的清单。
-
-清单只在任务确实多步时才建立:**三个及以上独立步骤**的任务才会触发(此前按「2 次及以上工具调用」判定,已收紧)。单步查询、以及没有排查性质的纯对话不会生成清单。会话入口类型见上文「会话入口类型(entry_kind)」。
+任务清单只在控制台和 IM 会话中提供,自动化、API 和子任务会话不生成清单。
### Agent 提问
-排障过程中,Agent 可能需要您澄清信息,这时会在对话流中插入一张交互式提问卡片:单选(点击选项即自动进入下一题)、多选(勾选后需点击 **确认** / **下一步** 才继续)或自定义文本输入(回车提交)。卡片右上角的 **✕** 按钮可跳过整卡提问(必答题不显示该按钮);多题批次时会额外显示「第 i / N 题」的翻页控件,可用键盘 ←→ 或点击翻页在题目间切换,切换回已答过的题目会保留之前的选择。支持键盘操作:↑↓ 移动选项、Enter 确认、Esc 跳过。
+Agent 需要您澄清信息时,会在对话中插入提问卡片,可能是单选、多选或文本输入。可以用键盘操作(↑↓ 选择、Enter 确认、Esc 跳过);非必答题可以点击 **✕** 跳过。
-**挂起中的提问会被新消息自动跳过**:当模型停在提问卡片上等待回答(卡片挂起)时,您直接发送一条新消息,挂起的提问会被自动标记为跳过——服务端写入一条 `function_response`(`reason=user_replied_with_message`,多题批次按题逐条标记),**不驱动模型**;您的新消息作为下一回合立即执行,该回合模型同时看到「提问已跳过 + 你说的话」,不会被挂起的问题挡住。反过来,**迟到的作答不会恢复该提问分支**:对已经有过用户侧响应(已被自动跳过,或已在其它设备作答)的提问,再提交答案会被转换为一条普通消息(按「(已跳过)」或答案文本方式渲染)参与下一回合——同一个提问绝不会被恢复执行两次。
+如果您不回答卡片而是直接发送新消息,提问会被视为跳过,您的消息立即执行。已经跳过或在其他设备回答过的提问,再提交答案会作为一条普通消息发送。
### 需要授权时
-当工具或 MCP 调用因缺少凭证或未完成 OAuth 授权而受阻时,对话流中会内联出现一张 **授权〈资源名〉以继续** 卡片,按授权方式分两种:
+工具或 MCP 调用缺少凭证或 OAuth 授权时,对话中会出现 **授权〈资源名〉以继续** 卡片:
-- **密钥类**:点击卡片按钮弹出输入框,粘贴 API Key / Token 并保存后任务会自动继续;若配置了帮助链接,卡片会附带「如何获取密钥?」。
-- **OAuth 类**:点击 **去授权** 在弹出的授权窗口中完成第三方授权;授权完成后卡片按钮变为 **继续任务**,需要您手动点击才会真正恢复被阻塞的工具调用。
+- **密钥类**:点击按钮,粘贴 API Key / Token 并保存,任务会自动继续。
+- **OAuth 类**:点击 **去授权** 完成第三方授权,然后点击 **继续任务**。授权链接过期后,需要重新发起任务。
<Note>
-OAuth 授权链接有过期时间;过期后卡片会提示「授权链接已过期,请重新触发任务」,需要重新发起一次任务才能拿到新的授权链接。
-</Note>
-
-<Note>
-渠道差异:只有控制台(`web`)渲染这张卡片。IM 与 API 渠道不出卡——OAuth 授权链接由 Agent 直接贴在回复里,请在桌面浏览器打开、完成授权后回复「已授权」继续(继续是你的一次显式动作,不是 OAuth 回调自动触发);密钥类凭证在 IM 里没有安全的收取方式,Agent 只会请你在**网页控制台打开同一个会话**填写,且**永远不会**让你把密钥粘进聊天。自动化渠道没有人值守,Agent 不会等待,而是把缺失的授权记为阻塞项继续交付。详见 [IM 平台](/zh/ai-sre/im#连接与授权)。
+只有控制台显示授权卡片。在 IM 和 API 会话中,Agent 会直接给出 OAuth 链接,请在浏览器中完成授权后回复「已授权」;密钥类凭证需要在网页控制台打开同一会话填写,**不要**把密钥发到聊天中。自动化会话不会等待授权,会把缺失的授权列为阻塞项。详见 [IM 平台](/zh/ai-sre/im#连接与授权)。
</Note>
### 需要连接时
-当 Agent 为完成你的请求去搜索能力(`tool_search`),而这次搜索一个工具都没匹配到、查询又正好指向一个**市场目录里存在、但你这个账户还没连接**的厂商时,对话流中会内联出现一张 **连接〈厂商名〉以继续** 卡片:左侧是厂商图标与名称,右侧一枚 **连接** 按钮,卡片上没有别的操作。
-
-这意味着你**不必先去插件市场翻找**:直接在对话里点名厂商(例如「帮我接一下 Datadog」)就能走到连接这一步;若该厂商在目录里根本没有连接器,Agent 会直接说明,而不是让卡片出现。
+当您要求 Agent 使用某个插件市场中有、但账户还没连接的厂商(例如「帮我接一下 Datadog」)时,对话中会出现 **连接〈厂商名〉以继续** 卡片,不必先去插件市场查找。
-点击 **连接** 会打开该厂商的连接对话框(与插件市场里的是同一个:填入凭证、完成授权与连接测试)。连接成功后卡片就地翻转:
-
-| 阶段 | 卡片状态 |
-|---|---|
-| 待连接 | 标题 **连接〈厂商名〉以继续**,副文案为该厂商的简介,按钮为 **连接** |
-| 已连接 | 标题 **〈厂商名〉 已连接**,副文案「点击继续任务,AI SRE 会接着查」,按钮变为 **继续任务** |
+1. 点击 **连接**,在弹出的对话框中填写凭证并完成连接测试。
+2. 连接成功后,卡片变为 **〈厂商名〉 已连接**,点击 **继续任务**,Agent 会接着完成原来的任务。
-点击 **继续任务** 后,控制台会替你把「连接已完成,请继续之前的任务。」发给 Agent,让它接着做原来的任务——**关掉连接对话框本身不会恢复回合**,恢复始终是你的一次显式点击。刷新页面后卡片仍呈现已连接状态:控制台按该模板在账户里的安装状态重新推导,不依赖浏览器里的临时状态。
-
-以下几种情况**不会**出现卡片,Agent 只给一句话说明:
-
-- 账户里已经有该厂商的连接(任何团队、任何环境):Agent 会说明它已连接(或需要先启用、需要重新填写凭证)。
-- 该厂商的连接只允许账户 Owner 或管理员发起:Agent 会说明需要管理员操作。
-- 该厂商的模板要求自托管 Runner,而当前会话没有可用的 Runner。
-- 搜索命中了已连接的工具——只有「零匹配 + 查询指向未连接的市场模板」才出连接卡。
+以下情况不会出现卡片,Agent 会直接说明:该厂商已连接(可能需要启用或重新填写凭证)、只有 Owner 或管理员能连接、需要自托管 Runner 但当前会话没有可用的 Runner,或者插件市场中没有该厂商。
<Note>
-渠道差异:只有控制台(`web`)渲染这张卡片。IM 与 API 渠道不出卡——Agent 会把连接地址作为一条普通链接给出,请你连接后回复「继续」或「continue」再接着做;自动化渠道没有人值守,Agent 不会等待,而是把这个缺失的连接记为阻塞项继续交付。各渠道的完整行为见 [IM 平台](/zh/ai-sre/im#连接与授权)。
+只有控制台显示连接卡片。在 IM 和 API 会话中,Agent 会给出连接链接,连接后回复「继续」即可;自动化会话不会等待,会把缺失的连接列为阻塞项。详见 [IM 平台](/zh/ai-sre/im#连接与授权)。
</Note>
### 子任务(Subagent)
-Agent 委派子任务时,对话中会出现一行可点击的**派发引用**:状态环 + 类型徽标(Agent / A2A)+ 子任务名称与当前意图,右侧对齐显示**目标执行环境**、状态与耗时;结束后补上工具调用数 / Token 用量 / 总耗时,失败时在下方附一行红色的失败原因。环境这一段只标位置——**云端环境**,或该 BYOC Runner 的名称(解析不到名称时只显示「自托管」),**不带状态点**;A2A 委派(远端 Agent 在自己那边执行)与没有环境绑定的历史任务不显示这一段。引用行是紧凑的一行,**不带停止按钮**——停止操作统一放在任务面板的详情头部(见下文「任务面板与后台任务」)。点击引用行会在右侧打开一个与主对话并排的子会话面板——主对话区域随之收窄,而不是被弹窗遮挡;面板可展开为占满主区域的全屏视图,也可以收起回并排布局。
+Agent 委派子任务时,对话中会出现一行子任务引用,显示类型(Agent / A2A)、名称、执行环境、状态与耗时,结束后显示工具调用数、Token 用量和失败原因。点击它会在右侧并排打开子会话,可以展开为全屏。
-除进行中、完成、失败、已中断外,子任务还可能处于两种「需要你」的状态:
+子任务还可能处于两种需要您处理的状态:
-- **等待授权**:引用行下方展开操作区,点击 **去授权** 弹出 OAuth 授权窗口;完成授权后按钮变为 **继续任务**,点击后主代理会在原任务上续跑,不会另起新任务。
-- **等待输入**:子任务向您提问后挂起等待回答;问题文本在任务面板的对应任务行内查看,不再内联在引用行上。
+- **等待授权**:点击 **去授权** 完成授权,再点击 **继续任务**,子任务会在原任务上继续。
+- **等待输入**:在任务面板中查看并回答子任务的问题。
-孤儿任务(子会话的执行者丢失)在界面上按 **失败** 呈现;被平台终止的任务显示为 **已终止**。
+停止子任务请在任务面板中操作。执行者丢失的子任务显示为 **失败**,被平台终止的显示为 **已终止**。
### 任务面板与后台任务
-除了子代理,Agent 还可以把耗时工作放到后台执行。会话中派生的任务分三类:
-
-| 类型 | 来源 | 说明 |
-|---|---|---|
-| agent | Subagent / A2A 子代理派发 | 拥有独立子会话,见上文「子任务(Subagent)」 |
-| shell | `bash` 工具加 `run_in_background` 发起 | 一次性长命令(构建、批处理、数据拉取等),只需在结束时回报结果 |
-| monitor | `monitor` 工具发起 | 监视器常驻任务:watch 一个条件直到命中或到达截止时间,脚本输出会作为事件分批回流给 Agent;一次性的延迟工作(如「半小时后检查一次」)用 monitor 加 `sleep` 实现 |
-
-会话右侧提供统一的 **任务** 面板,集中跟踪本会话的所有任务,按 **需要你 / 运行中 / 已结束** 三组展示。打开入口有三个:
-
-- **聊天页头部的任务按钮**:带数量角标,数字为「需要你 + 运行中」的任务数,超过 9 显示 `9+`;有任务需要您处理(等待授权 / 等待输入)时角标为红色,仅为运行中时角标为蓝色。
-- **回合进行中的生成状态行**:显示「N 个任务 · X 需要你」,点击同样打开任务面板。
-- **发起 monitor / 后台 bash 的工具行**:对话流中发起 `monitor` 或后台命令(`bash` 加 `run_in_background`)的工具行——单独成组时即该工具组的头部——本身就是该任务在对话中的句柄:行尾以外链图标标示可点击,悬停提示 **打开任务详情**,点击直接打开该任务的任务详情面板。这类行不再展开原始输入 / 输出(后台 bash 行展开后原本只有命令本身,没有状态与输出)。只读分享会话中打开的任务详情同样为只读。
-
-任务详情按类型区分:点击 **agent** 任务打开子会话的执行转录(见上文);点击 **shell / monitor** 任务打开它的事件时间线详情,包含状态(运行中的任务还会显示最近一次探活距今的秒数,探活约每 30 秒一次)、运行时长、事件数、输出字节数、monitor 的截止时间(无截止的常驻任务显示「常驻」)、退出码、完整命令,以及按序排列的事件时间线。**停止按钮位于详情头部**——shell / monitor 任务为 **停止任务**,子代理为 **停止子代理**,只中断该任务,不影响主会话。
+除了子任务,Agent 还可以在后台运行长时间命令(如构建、批量拉取数据),或启动监视器持续观察某个条件,直到满足条件或到达截止时间。
-对话流中的对应呈现:
+点击聊天页头部的 **任务** 按钮,可以按 **需要您 / 运行中 / 已结束** 查看本会话的全部任务。按钮上的数字是需要您处理和正在运行的任务数,有任务需要您处理时显示为红色。也可以点击对话中发起该任务的那一行打开详情。
-- 发起后台命令的工具行显示 **Started background command**;同一回合前后台命令混合时,折叠的工具组按类别分别计数(如 `Ran 1 command, started 1 background command`)。
-- monitor 每次命中条件,对话流中内联出现一条 🔭 系统行:首行显示监视器描述与该批输出的首行摘要,点击就地展开整批输出。
-- 任务结束时对话流出现一条终止行,包含结束状态与结果摘要,以及退出码和备注(任务信封携带时)。
-- monitor 工具行本身不展开输入 / 输出——点击该行会打开对应任务的任务详情面板,它返回的登记信息(任务 ID、输出文件、截止时间等)在详情中有更完整的呈现。
+- **子任务**的详情是子会话的执行记录。
+- **后台命令和监视器**的详情包括状态、运行时长、截止时间、退出码、完整命令和事件时间线。
+- 点击详情头部的 **停止任务** 或 **停止子代理**,只会停止该任务,不影响主会话。
-与后台任务相关的两个状态指示:
-
-- **会话列表行的 🔭 角标**表示该会话有存活的后台任务(`standing_tasks`,数字为个数);会话正在运行时优先显示转圈。
-- 会话的 **「运行中」指示只反映 Agent 回合与子代理任务**:常驻的监视器 / 后台命令不会让会话保持「运行中」——只剩常驻任务存活的会话显示为空闲。
+监视器每次命中条件时,对话中会出现一行 🔭 记录,点击可以展开输出;任务结束时会显示结束状态与结果摘要。只剩监视器或后台命令在运行时,会话显示为空闲,列表中显示 🔭 和任务数。
### Artifacts 预览
-Agent 产出的文件会以产物形式提供预览。点击产物即在右侧打开预览面板,按类型渲染:
+点击 Agent 产出的文件,会在右侧打开预览:
| 类型 | 预览方式 |
|---|---|
-| 代码(多语言) | 语法高亮 + 行号 |
-| Markdown | 默认渲染视图,可切换 **源码** |
-| HTML | 默认渲染视图(iframe 沙箱),可切换 **源码** |
-| 图片 | 直接显示;加载失败时给出可重试提示 |
-| PDF | 浏览器内置查看器渲染 |
-| Skill 压缩包(`.skill`) | 左侧文件树 + 右侧内容,可整包下载,并可一键 **保存 Skill** 到账户 |
-
-预览面板提供 **复制**、**下载** 与 **关闭** 操作。
-
-<Tip>
-报告类产物(如运营洞察报告)可生成包含 Mermaid 图、图表的 HTML,并在渲染视图中直接查看。运营洞察相关能力见 <a href="/zh/ai-sre/insight">运营洞察报告</a>。
-</Tip>
+| 代码 | 语法高亮与行号 |
+| Markdown / HTML | 渲染视图,可切换 **源码** |
+| 图片、PDF | 直接显示 |
+| Skill 压缩包(`.skill`) | 文件树与内容,可以下载或 **保存 Skill** 到账户 |
-所有已发布的产物也可在左侧导航 **产物** 页统一查看与管理(列表、搜索、按个人 / 团队筛选、卡片 / 列表视图切换、按创建 / 修改时间排序、重命名、下载与删除),详见 <a href="/zh/ai-sre/artifacts">产物</a>。
+预览支持 **复制** 和 **下载**。所有产物也可以在左侧导航的 **产物** 页统一管理,见 <a href="/zh/ai-sre/artifacts">产物</a>。
### 状态页更新草稿
-Agent 可以调用 `statuspage_draft` 工具,为公开状态页**起草**一份公告——新建故障或维护计划事件,或向已有事件追加一条更新。草稿保存在服务端,并在对话流中渲染为一张**状态页更新草稿卡**;但草稿**永远不会被自动发布**:发布状态页会立刻触达订阅者且不可撤回,所以这一步始终留给人工——在控制台的状态页发布表单里逐项核对后再点击发布。
+Agent 可以为公开状态页**起草**公告:新建故障或维护事件,或为已有事件追加更新。草稿**不会自动发布**,必须由您审阅后在控制台手动发布,因为发布会立即通知订阅者且无法撤回。
-#### 草稿卡上有什么
+草稿卡展示的就是将要发布的内容:标题、状态或计划时间、Markdown 正文、受影响组件及其状态、目标状态页与事件类型。如果正文中有状态页不支持的格式(如标题、代码块、引用、图片),卡片会列出提醒,这些内容在发布时会丢失。
-卡片复用控制台同类卡片(IncidentCard / MaintenanceCard)的视觉、字段顺序与组件状态图标,让审阅者看到的就是将要发布的内容:
-
-| 内容 | 说明 |
-|---|---|
-| 标题 | 新建事件时为表单的 `name` 字段(后端 `title`,最长 255 字符);追加更新时为其挂靠事件的标题——追加更新表单没有标题字段,此处仅作标识(未提供时显示「未命名状态页更新」) |
-| 状态 / 计划时间 | 新建维护计划显示「计划于 〈开始〉 → 〈结束〉」(未设置时显示「未设置计划时间」);其余情况显示状态文案——故障:排查中 / 已定位 / 监控中 / 已恢复;维护追加更新:已排期 / 进行中 / 已完成 |
-| 正文 | `message` 字段**完整渲染**为 Markdown——这是客户将要读到的话,审阅者必须看到全貌,不以纯文本形式出现 |
-| 受影响组件 | 每个组件一枚芯片:组件状态图标 + 名称(悬停显示「名称 · 状态」) |
-| 目标与类型 | 底部左侧「将发布到 〈状态页〉」(追加更新显示「追加更新 · 〈事件标题〉」),右侧标明类型:故障 / 维护计划 |
-| 警示条 | 草稿消息若含有状态页编辑器不支持、加载进表单时会被**静默丢弃**的 Markdown(标题、代码块、引用、图片、删除线、行内代码),卡片会以警示条逐条列出——这是起草时工具已检测到的 |
-
-#### 卡片状态
-
-| 状态 | 表现 |
-|---|---|
-| 起草中 | 骨架屏,底部显示「正在起草状态页更新…」 |
-| 工具报错 | 「没能生成草稿」+ 具体原因;可让 AI 再试一次,或直接去状态页手动创建 |
-| 草稿不完整 | 「草稿不完整」+ 同样提示(工具返回了结果但缺少可用的草稿对象) |
-| 可审阅 | 按钮为 **审阅 →**:在新标签页打开控制台状态页对应表单,草稿内容自动填入(URL 约定见下) |
-| 已发布 | 按钮变为禁用的 **已发布**;底部目标变为**已发布变更**的链接(`/status-page/{page_id}?menu=incidents\|maintenance&incident\|maintenance={change_id}`),可回看草稿最终发布成了什么 |
-| 草稿已过期 / 不存在 | 按钮变为禁用的 **草稿已过期**,提示「草稿已过期或不存在,请让 AI 重新起草一份」——控制台查询返回 ResourceNotFound 或网络错误时都按此处理 |
-
-「是否已发布」是卡片自己无法观察的事实(发布发生在另一个标签页的控制台里),因此卡片会按草稿 ID 请求 `GET /status-page/draft/info?draft_id=...`,返回 `status: pending | published`。草稿仍为 pending 时,窗口每次重新获得焦点都会刷新(「在这里审阅、去那里发布、再回来」是常规路径);`published` 与「草稿不存在」都是终态,结果缓存在当前页面的生命周期内。只读分享会话不渲染审阅按钮,对草稿状态的查询也一并跳过。
-
-#### 审阅交接 URL
-
-草稿本身保存在服务端(fc-statuspage 的草稿存储),跨到控制台的只有 `draft_id`:表单按 ID 从 `/status-page/draft/info` 拉取正文。URL 按「新建 / 追加」×「故障 / 维护」组合为四种:
-
-| 场景 | URL |
-|---|---|
-| 新建故障 | `/status-page/{page_id}?menu=incidents&incident=new&draft={draft_id}` |
-| 新建维护计划 | `/status-page/{page_id}?menu=maintenance&maintenance=new&draft={draft_id}` |
-| 追加故障更新 | `/status-page/{page_id}?menu=incidents&incident={change_id}&action=add-update&draft={draft_id}` |
-| 追加维护更新 | `/status-page/{page_id}?menu=maintenance&maintenance={change_id}&action=add-update&draft={draft_id}` |
-
-`action=add-update` 让详情页自动展开追加更新表单;缺了它,路由只会打开事件本身,草稿不会被读取。`?draft=` 只携带草稿 ID——草稿是服务端状态,不是 URL 里的一段 JSON。
-
-#### 工具要点
-
-| 字段 | 说明 |
-|---|---|
-| `page_id` / `page_name` | 目标状态页(必填)与其显示名(用于卡片展示) |
-| `type` | `incident`(故障)/ `maintenance`(维护计划) |
-| `change_id` | 省略 = 新建事件;设置 = 向该事件追加更新。起草前工具会先查 `fduty status-page list` 与 `fduty status-page change-active-list`——目标已有进行中的事件时应追加,而不是再开一个(二次事件会被客户读成又一次独立故障) |
-| `title` / `message` | 新建事件的标题(≤255 字符)与正文(必填,Markdown;状态页编辑器只保留加粗、斜体、链接、有序 / 无序列表、表格与 `---` 分隔线) |
-| `status` | 新建故障:`investigating` / `identified` / `monitoring` / `resolved`;新建维护:省略(是否按计划自动推进由发布表单的开关决定);追加维护更新:`scheduled` / `ongoing` / `completed` |
-| `affected_components` | 受影响组件(`component_id` + `status`,可带显示名 `name`);故障组件状态:`operational` / `degraded` / `partial_outage` / `full_outage`,维护组件状态:`operational` / `under_maintenance` |
-| `start_at_seconds` / `end_at_seconds` | 仅新建维护计划:计划窗口起止,unix **秒**(毫秒与 ISO 字符串都会被视为非法) |
+点击 **审阅 →** 会在新标签页打开状态页发布表单,并自动填入草稿。发布后按钮变为 **已发布**,并链接到已发布的事件;草稿过期或不存在时,请让 Agent 重新起草。
<Note>
-渠道差异:控制台(`web`)与自动化渠道渲染上述卡片;IM 与 API 渠道不渲染卡片——Agent 会在**回复开头**放一个「[审阅并发布](〈同样的交接 URL〉)」链接,再用一两句话总结草稿要点(IM 消息截断不识别 Markdown,链接放开头才安全)。若草稿保存失败(没有 `review_url`),它会改为文字总结,并引导你到控制台的状态页手动核对。
+IM 和 API 会话不显示草稿卡,Agent 会在回复开头给出「审阅并发布」链接并概括草稿要点。草稿保存失败时,Agent 会改为文字总结,并请您在控制台手动核对。
</Note>
### 消息操作
-将鼠标悬停在消息上会显示操作按钮:
+将鼠标悬停在消息上,可以:
| 操作 | 适用 | 说明 |
|---|---|---|
-| 复制 | 用户消息 / 产物 | 复制消息或文件内容到剪贴板 |
-| 重试 | 用户消息 | 以该消息重新发起回合 |
-| 编辑 | 用户消息 | 将该消息内容回填到输入框重新编辑;若当前有回合正在运行会先被中断,编辑期间无法添加附件,发送按钮文案变为 **发送回滚** |
-| Fork | 已完成回合的 Agent 回复 | 从这条回复所在的完成回合派生一个新会话,继续尝试另一条排查路径 |
+| 复制 | 用户消息 / 产物 | 复制内容 |
+| 重试 | 用户消息 | 用该消息重新运行一轮 |
+| 编辑 | 用户消息 | 修改后重新发送,见下方说明 |
+| Fork | 已完成回合的回复 | 从这里派生新会话,尝试另一条排查思路 |
<Note>
-编辑一条历史消息本质上是一次 **回滚(rewind)** 操作:提交后会从该消息处重新生成对话,这条消息之后的内容会被替换,请确认后再提交。若目标消息所在的回合仍在运行或正在停止,回滚会被拒绝(`rewind target invocation is still active`),请等待该回合结束后再提交。若会话正被其它操作占用(例如正在压缩上下文),回滚同样会被拒绝,并提示「会话正忙,请稍后重试」(`The session is busy with another operation. Please try again in a moment.`)——这不是永久失败,稍等片刻后重新提交即可。回滚生效时,被抹除回合派生的后台进程与已派发的子代理会被一并停止,对应的任务行随之从任务面板中删除。
+编辑历史消息会**回滚**会话:这条消息之后的内容会被替换,相关的后台任务和子任务也会停止。该回合仍在运行,或会话正忙(如正在压缩上下文)时无法编辑,请稍后重试。
</Note>
### Fork 会话
-当一个回合已经完整结束后,Agent 回复右侧会出现 **Fork** 按钮。点击后会弹出「Fork 新对话」对话框:对话框会以源会话的范围和运行环境作为预填建议,但 Fork 必须明确选择目标范围与运行环境。你可以选择个人或可访问的团队,并从 **自动**、云端 Sandbox 或在线的 BYOC Runner 中选择运行环境;点击 **确认** 后才会从该回复所在的回合派生一个新会话,并自动打开。
+回合结束后,点击回复旁的 **Fork**,选择新会话的范围(个人或您能访问的团队)和运行环境,确认后即会派生并打开新会话。
-Fork 适合在同一段排查上下文上尝试另一条路线:新会话保留截至所选回合为止的对话与工具调用记录,但不会在后端继承源会话的环境绑定。环境选项会按目标范围过滤;如果你不属于源团队,系统会改为个人范围;如果源环境已删除、离线、从未连接,或不属于目标范围,系统会改为 **自动**。后续回合不会带入新会话。新会话会写入一条「由 Chat 派生」分隔线,点击分隔线可回到原会话的来源位置。
-
-<Note>
-只能从**已经完成**的主会话回合 Fork。源会话仍在运行、所选回合尚未完成,或目标是 Subagent 子会话时,系统会拒绝 Fork。
-</Note>
-
-如果被 Fork 的这段对话里派发过 Subagent 或 A2A 任务,那些派发卡片会连同各自的子会话一起复制到新会话下,点开仍能查看执行详情,不会指向你无权访问的原始任务。**已在源会话完成或失败的派发会保留其真实状态**(完成 / 失败),连同执行结果一并复制过来;只有 **Fork 时仍在进行中的派发**才会显示为「已中断」——新会话没有承接它的执行者,无法继续执行。需要重跑时,在新会话里重新发起一次派发即可。
-
-Fork 会话会清理只属于运行中的临时状态,例如当前回合缓存、待挂载状态、未持久化的前端状态与本轮计数;已经持久化在历史中的消息、工具调用、可复用的压缩状态会保留,团队与环境绑定则按您在派生对话框中的选择写入新会话。Fork 后的新会话拥有独立的上下文,之后的消息、压缩与运行结果都不会写回原会话。
+- 新会话包含截至该回合的对话和工具调用记录,之后的内容互不影响。
+- 源会话的团队或环境不可用时,会分别改为个人范围和 **自动**。
+- 已完成或失败的子任务会连同结果复制到新会话;Fork 时仍在运行的子任务显示为「已中断」,需要时可以重新发起。
+- 只能从已完成的主会话回合 Fork,不能从子任务会话 Fork。
### 会话反馈
-聊天页头部提供一对会话级反馈按钮 **有帮助** / **没帮助**(拇指向上 / 向下),用于对整个会话的质量打分。
-
-点击 **没帮助** 会弹出一张反馈卡片,可勾选预置原因并补充说明:
-
-| 预置原因 | 说明 |
-|---|---|
-| 诊断/根因错误 | 诊断结论或定位的根因不正确 |
-| 没定位到问题 | 没有找到真正的根因 |
-| 处置建议不可用 | 给出的处置建议无法落地 |
-| 答非所问 | 回复偏离了你的问题 |
-
-卡片底部还有一个自由文本框,可补充具体问题(可选)。提交后反馈通过 `POST /safari/feedback/create` 持久化;重新打开该会话时,之前的评分会自动回填到头部按钮上。
+点击聊天页头部的 **有帮助** 或 **没帮助** 为整个会话评分。选择 **没帮助** 时可以勾选原因(诊断 / 根因错误、没定位到问题、处置建议不可用、答非所问)并补充说明。
## 上下文压缩
----
-
-随着对话变长,会话上下文会逼近模型的上下文窗口上限。AI SRE 会自动压缩较早的对话历史——把它总结为一段摘要并保留最近内容,从而在不丢失关键信息的前提下腾出上下文空间。
-
-每次压缩产生的边界摘要末尾还会附加一段确定性的**已折叠资源清单(Folded resources)**:列出本轮被折叠出上下文的资源及其重新获取方式——Skill 通过 `skill(name)` 重读、MCP 服务器的工具定义通过 `tool_search` 重新发现、A2A Agent 的使用说明会在下次派发 / 消息时自动重新投递。压缩后的回合可以据此按需恢复这些定义,而不必把它们长期留在上下文里。
+对话变长后,AI SRE 会自动把较早的历史压缩为摘要,保留最近内容和关键结论,对话不会中断。Skill、MCP 工具定义等被折叠出上下文的内容,Agent 会在需要时重新加载。
-压缩有四种触发方式:
-
-| 方式 | 触发时机 |
+| 触发方式 | 时机 |
|---|---|
-| 自动(回合开始前) | 回合开始前,上下文占用超过阈值时自动压缩 |
-| 自动(回合进行中) | 回合进行中上下文继续增长并越过阈值时再次压缩 |
-| 自动(事件数触发) | 会话事件累计达到约 **500 条**时自动压缩,即使 token 占用仍在阈值以下 |
-| 手动 | 您主动通过 `/compact` 命令触发压缩 |
-
-**事件数触发**是兜底机制:当会话由大量短小回合组成时,token 估算可能长期低于阈值,但事件(消息、工具调用等)数量持续增长。事件数达到约 500 条时强制压缩一次,避免历史窗口因逼近模型单次加载上限而冻结。若您观察到 Context 占用百分比远低于阈值时也发生了压缩,即属此情况。
-
-### 您会看到什么
+| 自动 | 上下文占用超过阈值时(回合开始前或进行中),或会话事件累计约 **500 条**时 |
+| 手动 | 输入 `/compact` |
-- **压缩进行中**:对话流中出现一行「正在压缩对话上下文…」的状态提示,并显示已用时长与进度,压缩完成后自动消失。
-- **压缩完成**:对话保持连贯,无需您介入;最直接的指示是聊天页头部的 **Context** 占用百分比随之下降——它反映当前上下文窗口的利用率,将鼠标悬停可查看具体的 token 用量。
-- **无需压缩**:当上下文无需压缩(如对话历史太短、已是压缩态)时,手动触发会给出相应提示,例如「上下文无需压缩」「对话历史太短,无需压缩」。
-
-<Note>
-压缩对您是透明的:您感知到的是一段连续的对话。Agent 在后台保留了被压缩内容的摘要,因此后续回合仍能基于此前的关键结论继续工作。
-</Note>
+压缩时对话中会显示进度,完成后聊天页头部的 **Context** 占用百分比会下降(悬停可查看 token 用量)。如果看到占用远低于阈值时也发生了压缩,是因为事件数达到了上限。
## 选择运行环境
----
-
-新建会话时,输入区除了团队选择器外还有一个独立的 **运行环境** 选择器,用来决定 Agent 的工具、Skill 与 MCP 调用具体在哪里执行。选择器分三段:
+新建会话时,可以在输入区选择 **运行环境**,决定 Agent 的工具、Skill 和 MCP 在哪里执行:
| 选项 | 说明 |
|---|---|
-| 自动(默认) | 由后端自动选择一个可用环境;无可用项时回退到云端沙箱 |
-| 云端环境 | 使用 Flashduty 托管的云端沙箱(默认模板,或账户 / 团队下已创建的云端环境模板) |
-| 指定 BYOC Runner | 从您账户内在线的自托管 Runner 中选择一台,让排障进入您的内网 |
-
-自托管 Runner 会按当前状态展示:离线或从未连接过的 Runner 在列表中会置灰,无法选中;若已选中的 Runner 之后离线,也会阻止发送消息并给出提示。
+| 自动(默认) | 系统选择可用环境,没有可用环境时使用云端沙箱 |
+| 云端环境 | Flashduty 托管的云端沙箱(默认模板或您创建的模板) |
+| BYOC Runner | 选择一台在线的自托管 Runner,在您的内网中排障 |
-环境选择在发送第一条消息、创建会话时即固定;如需切换,可参考下文「会话入口类型」中 IM 会话的就地切换能力,或 Fork 出一个新会话。
+离线的 Runner 不能选择;已选的 Runner 离线后无法发送消息。运行环境在会话创建后固定,如需更换,可以 Fork 一个新会话(IM 会话可以就地切换)。
## 绑定团队
----
+新建会话时可以 **绑定团队**,会话启动时会加载该团队的知识、Skill 与 MCP。团队选择会被记住。未绑定团队的个人会话中,Agent 可以按需加载您所属团队的知识;绑定了团队的会话只使用账户共享内容和该团队的内容。
-新建会话时可以为会话 **绑定团队**。绑定后,会话在启动时会自动加载该团队的知识、Skill 与 MCP,让 Agent 一开始就具备这个团队的领域上下文与能力。未绑定团队时,会话以账户范围运行。
+<Note>
+故障和作战室场景下自动绑定团队的能力仍在完善中。
+</Note>
-<Steps>
- <Step title="选择团队">
- 在新建会话的输入区通过团队选择器挑选要绑定的团队;您上次的选择会被记住,省去每次重复选择。
- </Step>
- <Step title="自动加载团队上下文">
- 会话启动即加载「账户范围 + 绑定团队」的知识 / Skill / MCP 元数据,Agent 随即可用。
- </Step>
- <Step title="个人会话按需挂载团队知识">
- 未绑定团队的个人会话里,Agent 可以按需读取会话创建者所属团队的知识,将该团队的知识与能力作为持久上下文挂载进当前会话——一次挂载在本会话内持续有效。绑定了团队的会话只用共享范围和这个团队的知识,不能挂载其它团队的。
- </Step>
-</Steps>
-绑定的团队会随会话保留:重新打开同一会话时,仍是原先绑定的团队;该会话所属团队也会在侧边栏的会话提示中标注。
+## 会话来源
-<Warning>
-故障 / 作战室与团队的自动联动仍在演进中。当前您可以为会话显式 **绑定团队**;后续故障场景下的自动绑定能力会持续完善。
-</Warning>
+每个会话都记录它的来源,来源决定了一些行为差异:
-资源的团队作用域(账户范围与团队范围、可见性与编辑权限)规则,详见各资源页面的「作用域」一节。
+| 来源 | 说明 |
+|---|---|
+| 控制台 | 运行环境与团队在创建时固定 |
+| IM 平台(飞书 / 钉钉 / 企业微信 / Slack) | 可以在对话中用 `/env` 和 `/scope` 命令切换运行环境与团队 |
+| API | 程序化集成。通过 `POST /safari/session/create` 创建时可以传入 `entry_kind`(`web` / `im` / `api` / `automation`,默认 `web`),创建后不可修改 |
+| 自动化 | 由自动化规则触发 |
-## 会话入口类型(entry_kind)
+## 回复语言
----
+会话创建时确定 **回复语言**,Agent 在整个会话中都使用该语言。
-每个会话在创建时都带有一个 **入口类型(entry_kind)**,用于标识本次会话由哪个接入面产生。该字段持久化到数据库,并在创建响应中返回。
+| 来源 | 回复语言 |
+|---|---|
+| 控制台 | 创建会话时的控制台界面语言,之后切换界面语言不影响已有会话 |
+| IM / API / 自动化 | 账户的默认通知语言 |
-| 值 | 来源 | 说明 |
-|---|---|---|
-| `web` | 控制台 | 默认值;未传入或传入未知值时自动归一为 `web` |
-| `im` | IM 平台(飞书 / 钉钉 / 企业微信 / Slack) | 由 IM 渠道自动设置;启用会话的**就地切换**能力(见下方) |
-| `api` | 外部 API 调用 | 用于程序化集成场景 |
-| `automation` | 自动化流程 | 由自动化任务触发的会话 |
+## 通过 API 集成会话
-通过 `POST /safari/session/create` 创建会话时,可在请求体中传入 `entry_kind`(可选,省略即为 `web`)。`entry_kind` 一经创建不可修改。
+本节面向通过 [Open API](/zh/api-reference/ai-sre/sessions/session-read-info) 集成 AI SRE 会话的开发者。
-<Note>
-`entry_kind=im` 的会话支持**就地切换运行环境与团队范围**——即通过 IM 中的 `/env` 与 `/scope` 命令,在不中断对话的情况下重新绑定运行环境(BYOC Runner 或云端沙箱)或团队。控制台会话(`web`)的环境与团队在创建时固定,不支持就地切换。
-</Note>
+### 撤回排队消息
-## 回复语言
+`POST /safari/session/get` 响应中的 `pending_messages` 字段是 Agent 尚未读取的排队消息(按执行顺序排列)。在 Agent 读取前,消息作者本人可以调用 `POST /safari/session/message/cancel` 撤回,请求体携带 `session_id` 与 `invocation_id`(发送消息时回执中的调用 ID)。响应的 `result` 字段:
----
+| 结果 | 含义 |
+|---|---|
+| `removed` | 已从队列移除,不会执行;各客户端会收到 `user_message_cancelled` 帧 |
+| `consumed` | Agent 已读取,撤回不生效;如需中断请使用停止 |
+| `forbidden` | 调用者不是消息作者 |
-每个会话在创建时会确定一个 **回复语言**,Agent 在整个会话期间都用该语言回复,不会中途切换;之后重新打开会话时也沿用该语言。
+只能撤回普通的人工消息,提问作答和系统内部产生的消息不能撤回。调用方需要具备该会话的对话权限。
-| 入口类型 | 回复语言来源 |
-|---|---|
-| 控制台(`web`) | 跟随创建会话时的控制台界面语言;创建后即固定,之后切换界面语言不影响已有会话 |
-| IM / API / 自动化(`im` / `api` / `automation`) | 这些入口不携带界面语言信号,默认使用账户的通知语言 |
+### 流式事件中的错误标记
-## 会话数据导出
+会话流中的事件帧可能带有 `is_error` 与 `error_code` 字段,表示平台向用户暴露的运行时错误。没有这两个字段不代表该帧不含诊断信息;它们也不同于下文导出流中表示流本身出错的 `error` 行。
----
+### 会话数据导出
通过 `POST /safari/session/export` 可以将一个会话的全部事件以 **NDJSON**(`application/x-ndjson`)格式流式导出,每行一个 JSON 对象。这一能力适用于审计、归档、离线分析或将会话数据接入外部系统等场景。
-### 请求参数
+#### 请求参数
| 字段 | 类型 | 必填 | 说明 |
|---|---|---|---|
| `session_id` | string | 是 | 要导出的会话 ID |
| `include_subagents` | bool | 否 | 为 `true` 时递归包含所有子 Agent 会话的事件流;默认 `false` |
-### 响应格式
+#### 响应格式
响应的 `Content-Type` 为 `application/x-ndjson`,**第一行始终**是 `session_meta` 类型的会话元数据信封,后续各行为会话事件。启用 `include_subagents=true` 时,每遇到一条 `subagent_dispatch` 类型的行,其后紧跟该子会话的完整事件流,子会话同样以自己的 `session_meta` 行作为起始。
@@ -554,7 +343,8 @@ Fork 会话会清理只属于运行中的临时状态,例如当前回合缓存
{"type":"final_answer","seq":5,"session_id":"s_...","content":"...","usage":{"input_tokens":0,"output_tokens":0,"cache_read":0,"cache_creation":0},"ts":"2026-09-08T08:05:00Z"} // 回合结束的最终回答
```
-#### 行类型
+<AccordionGroup>
+<Accordion title="行类型">
导出流只包含以下行类型(`type` 字段),不会出现其它类型:
@@ -571,26 +361,28 @@ Fork 会话会清理只属于运行中的临时状态,例如当前回合缓存
| `session_fork` | 「Fork 新对话」分隔线行 | `content` |
| `error` | 流已开始后出错时追加在流末尾;或 `include_subagents` 下子会话不可用时内联 | `content`(错误文本;消费方需检测该行以判断流是否完整,见下方 Warning) |
-#### 字段与行为约定
+</Accordion>
+<Accordion title="字段与行为约定">
- **`seq`**:从 1 开始、按**输出行**计数的单调序号(按子会话重置;跨分页不重置)。一个 DB 事件产生多行时(见下),多行按 part 顺序连续编号。`session_meta` 行不携带 `seq`。
-- **`call_id`(配对依据)**:ADK `function_call` / `function_response` 的 ID(两侧共用同一个 `id`)。一个模型响应可以把多次工具调用**合并进一个 DB 事件**(例如同一事件里 2 个 `agent_dispatch` + 1 个 `bash`);导出按 part 各输出一行(顺序与原事件一致),`call_id` 让消费方把回执行与对应的调用行重新配对,而不依赖输出顺序。
+- **`call_id`(配对依据)**:`function_call` / `function_response` 的 ID(两侧共用同一个 `id`)。一个模型响应可以把多次工具调用**合并进一个 DB 事件**(例如同一事件里 2 个 `agent_dispatch` + 1 个 `bash`);导出按 part 各输出一行(顺序与原事件一致),`call_id` 让消费方把回执行与对应的调用行重新配对,而不依赖输出顺序。
- **`usage`(token 用量)**:事件级计数(`input_tokens` / `output_tokens` / `cache_read` / `cache_creation`),无值时输出 `0` 而非省略。**只在事件的首行盖章**——一次批处理派发的多条行共享同一份用量,按行累计的消费方不会被多算 N 倍。
-- **不含模型标识**:导出刻意**不携带服务模型标识**——`session_meta` 与 `llm_call` 行都没有 `model` 字段。导出是供客户下载的制品,服务模型标识与逐次 token 用量组合起来足以反推底层用量成本,因此该标识只保留在服务端(`t_session.chat_model`),面向客户的导出与查询接口都不返回它(`/safari/session/get` 同样不暴露),依赖该字段解析导出结果的脚本需要另行调整。
+- **不含模型标识**:导出刻意**不携带服务模型标识**——`session_meta` 与 `llm_call` 行都没有 `model` 字段。导出是供客户下载的制品,服务模型标识与逐次 token 用量组合起来足以反推底层用量成本,因此导出与查询接口(包括 `/safari/session/get`)都不返回它。
- **时间与耗时**:`ts` 为事件写入时间(RFC 3339)。`llm_call` 与 `tool_call` 行以该时间近似**结束时间**(`ended_at`);开始时间与耗时(`started_at` / `duration_ms`)当前不提供(为空 / 0)。
- **`include_subagents=true`**:每个 `subagent_dispatch` 行之后立即递归内联该子会话的完整导出流(批量派发的每个 dispatch 行都会内联一次);子会话的 `seq` 从 1 重新计数,其 `session_meta` 携带 `parent_session_id`。子会话不存在或导出失败时不中断父流,输出一条内联的 `error` 行继续。
- 部分簿记行不产生导出行(例如 OAuth 授权成功标记),因此事件行数可能少于会话事件数。
+</Accordion>
+</AccordionGroup>
+
<Warning>
若流式传输已开始后发生错误,服务器**无法**切换回标准 JSON 错误包。此时会在流末尾追加一行 JSON 编码的错误对象,消费方需检测该行以判断流是否完整。
</Warning>
-**权限**:导出端点使用与发送消息相同的权限门控(`CanChatSession`),即要求调用方具备该会话的消息收发权限,单纯的只读访问权限不够。个人会话只能由创建者导出;团队会话可由同账户内具备会话访问能力的成员导出。
+**权限**:导出端点使用与发送消息相同的权限门控,即要求调用方具备该会话的消息收发权限,单纯的只读访问权限不够。个人会话只能由创建者导出;团队会话可由同账户内具备会话访问能力的成员导出。
## 相关页面
----
-
<CardGroup cols={2}>
<Card title="概述" icon="robot" href="/zh/ai-sre/overview">
了解 AI SRE 的定位、能力与适用场景。
diff --git a/zh/ai-sre/skills.mdx b/zh/ai-sre/skills.mdx
index 1d53614a..0c3d0492 100644
--- a/zh/ai-sre/skills.mdx
+++ b/zh/ai-sre/skills.mdx
@@ -5,14 +5,10 @@ keywords: ["AI SRE", "Skill", "SKILL.md", "市场", "Marketplace", "skill-creato
sidebarTitle: Skill
---
-<Info>
- AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起,需在控制台开通后使用,并按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-</Info>
+> AI SRE 需在控制台开通,面向 On-call 专业版及以上订阅,按实际用量计费,详见[开通与计费](/zh/ai-sre/overview#开通与计费)。
## 概述
----
-
Skill 是一个**可复用的能力包**。一个 Skill 由两部分组成:
- 一段 **SKILL.md** 说明文档,告诉 Agent「什么场景下用、怎么用、按什么步骤做」;
@@ -34,7 +30,7 @@ Skill 被打包成 Skill 归档(`.zip` 或 `.tar.gz`,扩展名 `.zip` / `.sk
Skill 与 MCP 的区别:MCP 提供**外部工具的接入能力**,Skill 提供**如何编排这些工具完成一类任务的方法论**。两者配合使用——Skill 在 SKILL.md 里声明它需要哪些工具,包括内置工具和 `mcp:服务名/工具名` 形式的 MCP 工具。
</Tip>
-### SKILL.md 格式
+## SKILL.md 格式
`SKILL.md` 由 YAML frontmatter(元数据)和正文(Agent 可读的说明)两部分组成,以 `---` 分隔:
@@ -82,28 +78,29 @@ frontmatter 字段如下:
- **内置工具**:直接写工具名。可用的内置工具包括 `read`、`write`、`edit`、`bash`、`grep`、`glob`、`skill`、`mcp`、`todo`、`time`、`webfetch`、`web_search` 等。
- **MCP 工具**:写成 `mcp:服务名/工具名`(如 `mcp:my-server/query`)。上传时只校验该 MCP 服务是否存在,具体工具名在会话中加载 MCP 时才会被验证。
-<Note>
-AI SRE 运行时内置了几个 Skill,无需安装即可使用。`flashduty` 是其中一个范例:它通过 `fduty` 命令行覆盖整个 Flashduty API,让 Agent 可以排障故障、读取 AI 详情、查询告警、关联变更等。您可以参考它来编写自己的 Skill。另一个内置 Skill 是 `github`,Agent 会从 `<available_skills>` 中自主选用它,让 AI SRE 直接在 GitHub 仓库里工作——探索代码、调查 PR / 提交、按需开 PR 或 Issue;它需要安装 GitHub App(云端)或运行环境主机上的 `gh`(BYOC)。第三个内置 Skill 是 `gitlab`,能力与 `github` 对称:Agent 自主选用它在 GitLab 仓库里探索代码、追溯 MR / Issue、按需开 MR 或 Issue;它需要安装 GitLab App(云端)或运行环境主机上的 `glab`(BYOC)。详见 [Apps](/zh/ai-sre/apps)。
+## 内置 Skill
-还有 `flashduty-docs`:它把 Flashduty 的**官方文档**(中英文两套页面、术语表与 Open API 规范)下载到运行环境本地,按主题检索后回答**产品本身怎么用**的问题——功能、设置、上限、套餐、兼容性、SDK 行为与影响、API 字段与错误码,覆盖 On-call、RUM、Monitors、AI SRE、状态页、平台与 Open API;回答会附上 docs.flashduty.com 的公开链接,并且只依据文档作答,文档没写到的地方会直说。它只读文档,不代替动手排查(RUM 的实际接入工作归 `rum`),文档包的地址由平台注入,无需配置。
-</Note>
+AI SRE 运行时内置了以下 Skill,无需安装即可使用:
-<Note>
-上面几个只是举例,不是全部:运行时还内置 `init`、`insight`、`artifact-design`、`alert-governance`、`monit-query` 等 Skill,并会随版本增补。会话里 Agent 实际看到的可用清单以 `<available_skills>` 为准;想确认某条会话里到底有哪些内置 Skill,直接问 Agent 即可。
-</Note>
+| Skill | 用途 | 前提 |
+| --- | --- | --- |
+| `flashduty` | 通过 `fduty` 命令行覆盖整个 Flashduty API:排查故障、读取 AI 详情、查询告警、关联变更等。编写自己的 Skill 时可以参考它 | — |
+| `github` | 在 GitHub 仓库里工作:探索代码、调查 PR / 提交、按需开 PR 或 Issue | 安装 GitHub App(云端)或运行环境主机上的 `gh`(BYOC),见 [Apps](/zh/ai-sre/apps) |
+| `gitlab` | 与 `github` 对称:探索代码、追溯 MR / Issue、按需开 MR 或 Issue | 安装 GitLab App(云端)或运行环境主机上的 `glab`(BYOC) |
+| `flashduty-docs` | 检索 Flashduty 官方文档(中英文页面、术语表与 Open API 规范),回答产品本身怎么用(功能、设置、上限、套餐、兼容性、SDK 行为、API 字段与错误码),附 docs.flashduty.com 链接;只依据文档作答,文档没写的会直说。不代替动手排查(RUM 接入归 `rum`) | 无需配置 |
-## 从市场安装
+此外还有 `init`、`insight`、`artifact-design`、`alert-governance`、`monit-query` 等,并随版本增补。某条会话里实际可用的 Skill,直接问 Agent 即可。
----
+## 从市场安装
-Skill 市场目录是 **自定义 → 插件 → 概览** 页插件目录的一部分:与 MCP 模板、内置 App 一起按类别列出,Skill 单独归在 **Skill** 类别(在「全部」页签下也会出现,行上带 `Skill` 类型标签)。目录上方的搜索框按名称或描述过滤,页签可只看某一类,类别标题右侧的「查看全部 N」可展开该类别;搜索词与所选页签都记在页面地址里,离开再回来仍在原来的位置。
+Skill 市场位于 **自定义 → 插件 → 概览** 的插件目录中,归在 **Skill** 类别下,可按名称或描述搜索。
<Steps>
<Step title="找到要安装的模板">
在 **自定义 → 插件 → 概览** 的 **Skill** 类别里找到目标模板,每行展示模板名称与简介。
</Step>
<Step title="确认安装">
- 未安装的模板行右侧是一个圆形 **+** 按钮,点击 **+** 或点击整行,都会弹出「**安装 Skill「〈模板名〉」**」确认对话框,提示「将安装到账户,账号内所有成员可用。」——市场安装的 Skill 固定为**共享范围**(共享即账户级),不提供归属选择。点 **安装** 才真正调用安装接口,把模板内容复制到您的账户,成为一个普通 Skill 行,并标记其来源模板(列表上以 `来自 Marketplace — 〈模板名〉 v〈版本〉` 的悬停提示标识)。安装成功会提示「「〈模板名〉」安装成功」。
+ 点击模板行或其右侧的 **+**,确认后即可安装。市场安装的 Skill 固定为**共享范围**(账户内所有成员可用),会作为普通 Skill 复制到您的账户,并标注来源模板与版本。
</Step>
<Step title="管理已安装项">
已安装的模板行不再显示 **+**,而是显示 **已启用**。安装后的管理与更新都在 **自定义 → 插件 → Skill** 的 Skill 列表里进行,见下文「管理与检视」与「自动更新与手动更新」。
@@ -137,8 +134,6 @@ Skill 市场目录是 **自定义 → 插件 → 概览** 页插件目录的一
## 自定义 Skill
----
-
除了从市场安装,您也可以上传自己的 Skill 包。在 Skill 列表页点击 **上传 Skill**,在表单中填写:
| 字段 | 类型 | 是否必填 | 说明 |
@@ -154,26 +149,19 @@ Skill 名以外的元数据(描述、版本、标签、作者、工具等)
### 覆盖上传(Replace)
-当您要用新版本替换已有 Skill 时,上传端点支持两种覆盖模式,界面会在适当时机弹出「替换」确认对话框:
-
-| 模式 | 触发条件 | 行为 |
-| --- | --- | --- |
-| **按名称覆盖** | 上传 zip 时携带 `replace=true`,且不指定 `skill_id` | 以新归档的 `SKILL.md` 中 `name` 字段匹配账户内同名 Skill 并覆盖其内容;SkillID 不变,所有对该 Skill 的引用(如 `/<skill-name>` 触发)继续生效 |
-| **按 ID 覆盖** | 上传 zip 时携带 `replace=true` 且指定 `skill_id` | 不依赖 zip 内的 `name` 字段,直接以指定 ID 定位并替换对应 Skill;适合在重命名后仍要覆盖原记录的场景 |
+默认情况下,上传与已有 Skill 同名的归档会被拒绝。要用新版本替换已有 Skill,在检视面板选择「替换」,或在上传同名 Skill 时确认弹出的「替换」对话框。替换后 SkillID 不变,`/<skill-name>` 等引用继续有效;目标 Skill 不存在时不会新建。
-两种模式在替换成功后均返回更新后的 Skill 对象;若目标 Skill 不存在,返回 404 错误而非新建。**不携带 `replace` 参数时(默认),重名归档会被直接拒绝**,上传端点不会隐式覆盖已有 Skill。
+通过 API 上传时,携带 `replace=true` 按 `SKILL.md` 中的 `name` 匹配并覆盖;再指定 `skill_id` 则按 ID 覆盖(适合 Skill 已重命名的情况),目标不存在时返回 404。
### 在对话中添加(skill-creator)
除了上传 zip,您还可以**直接在 AI SRE 会话里创建和打磨 Skill**。`skill-creator` 是 Flashduty 在 Marketplace 提供、并默认预置到账户的一个 Skill,专门用来「造 Skill」。在任意会话里用 `/skill-creator` 触发,或直接用自然语言提出需求即可:
-Skill 列表页右上角的 **在对话中添加** 会新建一条会话,并预填一段需求描述:「我想添加一个 Skill。先问我是自己新建,还是从网上找现成的来装。找现成的就搜几个给我挑,我选好再装。」——即 Agent 会先问您要**自己新建**还是**装现成的**;选现成的先查插件目录/市场,目录里没有再联网搜索候选供您挑选,选好后再安装。提示词只是预填,不会自动发送。该按钮只在您有明确的可写入范围时显示:能授权到账户范围时始终显示,否则需要当前范围筛选恰好只选中一个您所属的团队(或您只属于一个团队)。
-
- **从零创建**:说「帮我创建一个用于排查 X 的 Skill」,或在一次排障结束后说「把刚才这套流程固化成一个 Skill」。skill-creator 会与您澄清意图、起草 `SKILL.md`、(可选)建立测试用例并据此迭代,满意后一键保存为账户里的 Skill。
-- **从网上找现成的**:从「在对话中添加」进入并选择装现成的时,Agent 先查插件目录,目录里没有再联网搜索候选;选定后由它完成安装,成为一个普通 Skill 行。
+- **安装现成的**:点击 Skill 列表页右上角的 **在对话中添加**,选择装现成的。Agent 先查插件目录,没有再联网搜索候选;您选定后由它完成安装。(只有在能确定写入范围时——您有账户级权限,或当前只选中了一个您所属的团队——才显示此按钮。)
- **改写与优化**:在某个 Skill 的检视面板点击 **「在聊天中编辑」**,会以 skill-creator 改写该 Skill;它也能帮您打磨 `description`,提升被正确触发的准确度。
-Agent 完成起草后可一键把内容保存为 Skill;与已有 Skill 重名时,保存前会弹出「替换」确认对话框——底层即走按名称覆盖模式(`replace=true`,无 `skill_id`)。
+Agent 完成起草后可一键把内容保存为 Skill;与已有 Skill 重名时,保存前会弹出「替换」确认对话框。
<Warning>
Skill 归档大小有上限:通过对话中 Agent 打包保存的归档上限为 **10 MB**,通过网页表单或会话内呈现文件上传的归档上限为 **100 MB**。
@@ -181,9 +169,7 @@ Skill 归档大小有上限:通过对话中 Agent 打包保存的归档上限
## 管理与检视
----
-
-Skill 列表以表格展示每个 Skill 的**名称**(含来源模板角标、「有更新」标记与「仅本地 Runner」角标)、**范围**(共享或团队)、**版本**、**启用**开关与**操作**列。仅声明了 `venues: [byoc]` 的 Skill 会带上「**仅本地 Runner**」角标,鼠标悬停显示「仅在绑定本地 Runner 的会话中可用,云沙箱会话中不可用」;Marketplace 的模板卡片上也有同样的角标,方便您在安装前就知道它需要自托管 Runner。列表上方的工具条提供范围筛选(全部 / 账户 / 团队)与搜索框,搜索按名称、描述或作者中的关键词过滤列表。
+Skill 列表显示每个 Skill 的名称、范围(共享或团队)、版本和启用状态,并标注来源模板、**有更新** 和 **仅本地 Runner**。声明了 `venues: [byoc]` 的 Skill 标为 **仅本地 Runner**,只能在绑定本地 Runner 的会话中使用,云沙箱会话中不可用;市场模板上也有同样的标记,便于安装前确认。可以按范围(全部 / 账户 / 团队)筛选,并按名称、描述或作者搜索。
<AccordionGroup>
<Accordion title="启用 / 禁用" icon="toggle-on">
@@ -209,9 +195,9 @@ Skill 列表以表格展示每个 Skill 的**名称**(含来源模板角标、
- **左侧**:Skill 包的文件树(`SKILL.md`、`README.md` 等会优先作为默认预览文件)。
- **右侧**:选中文件的内容预览,顶部显示 Skill 描述。
-- **标题区**:Skill 名(短引用形如 `skill-xxxxxx`)、范围标签(共享 / 团队名)、来源模板版本角标(鼠标悬停显示「来自 Marketplace — 模板名 v版本」)、**有更新**标记、作者、`version`、以及完整 SkillID。
+- **标题区**:Skill 名与短引用(如 `skill-xxxxxx`)、范围、来源模板版本、**有更新** 标记、作者、`version` 与完整 SkillID。
- **操作**:在聊天中试用(向新会话注入 `/<skill-name>`)、更新到最新版本、在聊天中编辑、替换、下载、卸载。
-- **试试这样问**:若该 Skill 在 `SKILL.md` 的 frontmatter 里声明了 `examples`,检视面板标题区下方会出现一个 **试试这样问** 开关,**默认收起**——示例问题不会直接铺开;点击展开后才列出最多 2 条示例问题,点击其中一条即以该 Skill 加该问题预填一条新会话消息(不会自动发送)。展开区底部提示「点问题会新建对话并填好,确认后再发送」。
+- **试试这样问**:如果 `SKILL.md` 的 frontmatter 声明了 `examples`,可以展开查看最多 2 条示例问题;点击其中一条会新建一条预填该 Skill 和问题的对话,确认后再发送。
<Tip>
Skill 包**过大无法预览**时,检视面板会提示体积并建议改用「下载」查看。
@@ -219,8 +205,6 @@ Skill 包**过大无法预览**时,检视面板会提示体积并建议改用
## 作用域
----
-
Skill 与其他资源(知识、MCP、Agent、运行环境)共用同一套**两级作用域**模型,分为账户级与团队级:
| 作用域 | 可见性 |
@@ -230,18 +214,21 @@ Skill 与其他资源(知识、MCP、Agent、运行环境)共用同一套**
**编辑权限**:团队级 Skill 仅该团队的成员可以操作,组织管理员也需要先加入该团队;账户级 Skill 仅账户所有者或管理员可以操作;没有「创建者保留权限」这一例外。无编辑权限时,列表对应行显示为**只读**。
-**创建与改归属**:上传新的团队级 Skill 时,您必须是目标团队成员;账户级上传仅限账户所有者或管理员。**从市场安装是例外**:安装固定为共享范围(账户级),账户内任何成员都可以安装,不需要所有者或管理员权限,也不能在安装时选择团队。编辑已有 Skill 时,账户所有者或管理员可以把它移动到任意团队,用于恢复空团队或离职成员留下的资源;普通成员只能移动到自己所属的团队。但**市场安装的 Skill 不可改归属到团队**——编辑表单中其作用域固定显示为账户;极少量早期遗留的团队级市场 Skill 可通过检视面板的「设为共享」提升为账户级。**「设为共享」与账户级上传同门槛,仅限账户 Owner 或管理员**:普通成员即使属于该 Skill 所在团队也不能自助提升,操作被拒绝时会提示「请管理员把它设为共享」。
+**创建与改归属**:
+
+- 上传团队级 Skill 须是目标团队成员;上传账户级 Skill 仅限账户所有者或管理员。
+- **从市场安装是例外**:固定为共享范围,任何成员都可以安装,安装时不能选团队;安装后也不能改归属到团队。
+- 编辑已有 Skill 时,账户所有者或管理员可以把它移动到任意团队(用于恢复空团队或离职成员留下的资源);普通成员只能移到自己所属的团队。
+- 少量早期遗留的团队级市场 Skill 可通过检视面板的「设为共享」提升为账户级,**仅限账户所有者或管理员**操作。
**运行时可见性**:会话开始时,只会加载**共享范围(账户级)**的 Skill,以及**当前会话所绑定团队**的 Skill。当 Agent 在排障中读取另一个团队的知识后,该团队的 Skill 与 MCP 才会被按需挂载进当前会话。**账户是运行时唯一的安全边界;对团队级 Skill 的使用同样受此可见性约束,团队不只是归属与编辑的标记。**
<Note>
-对话框 `/` 自动补全下拉只展示**共享范围的 Skill** 以及**您所属团队**的团队级 Skill——这不只是菜单显示问题:手动输入的斜杠命令与自动补全受同一套按行范围门控(「可见即可解析」),不在当前会话可见范围内的团队级 Skill 不会被解析执行。具体而言:团队会话中调用其他团队的命令会被拒绝并提示不可用的原因;个人会话中,该 Skill 所在团队的成员手动输入命令可以解析(并按需挂载该团队),非成员输入则与输入了不存在的命令一样被拒绝。
+对话框 `/` 自动补全只列出共享范围的 Skill 和您所属团队的 Skill;手动输入的斜杠命令遵循同样的范围。团队会话中调用其他团队的 Skill 会被拒绝并说明原因;个人会话中,只有该团队的成员才能调用它(会按需挂载该团队)。
</Note>
## 相关页面
----
-
<CardGroup cols={2}>
<Card title="管理知识" icon="book" href="/zh/ai-sre/knowledge">
用 DUTY.md 与知识为 Agent 提供团队上下文与排障经验。
@@ -252,7 +239,7 @@ Skill 与其他资源(知识、MCP、Agent、运行环境)共用同一套**
<Card title="Agent" icon="satellite-dish" href="/zh/ai-sre/agents">
用 Agent 扩展 AI SRE 的协作与分工能力。
</Card>
- <Card title="控制台" icon="comments" href="/zh/ai-sre/sessions">
+ <Card title="控制台对话" icon="comments" href="/zh/ai-sre/sessions">
在会话中用 `/<skill-name>` 显式触发 Skill,或让 Agent 自主调用。
</Card>
<Card title="概述" icon="gauge-high" href="/zh/ai-sre/overview">
diff --git a/zh/changelog/changelog.mdx b/zh/changelog/changelog.mdx
index dc5fe4ee..ecb8a230 100644
--- a/zh/changelog/changelog.mdx
+++ b/zh/changelog/changelog.mdx
@@ -187,7 +187,7 @@ AI SRE 代某位成员执行的动作(例如自动化规则跑完一轮排查
- 合法配置只有三种:都不配置(全租户可查可管);只配置管理团队(全员可查、仅负责团队可管);管理团队与只读团队都配置(查询与管理都受限)。只配置 `readonly_team_ids` 而不配 `manage_team_id` 会被拒绝——限制了查询的数据源必须有明确的负责团队;`manage` 恒含 `readonly`
- 数据源创建者、主体账号与 Admin 角色始终可管理;列表只返回您有权查询的实例(每行带 `my_perm`,取值 `manage` 或 `readonly`),保存告警规则时按规则引用到的数据源校验 readonly(含名称通配在保存当下匹配到的数据源),纯停用是唯一豁免
- 无权查询的实例整条不出现在列表、查询入口与规则数据源选择器里,无权操作被明确拒绝且不暴露数据源细节,授权字段的变更写入审计
-- 控制台的数据源表单暂未提供这两个字段的输入项,需要由管理员通过 API 设置**(2026-09-23 起控制台表单已支持这两个字段,见 2026-09-23 条目)**
+- 控制台的数据源表单暂未提供这两个字段的输入项,需要由管理员通过 API 设置<strong>(2026-09-23 起控制台表单已支持这两个字段,见 2026-09-23 条目)</strong>
详见 [数据源管理](/zh/monitors/data-sources/data-sources) 的「数据源权限(团队授权)」一节。
@@ -197,7 +197,7 @@ AI SRE 代某位成员执行的动作(例如自动化规则跑完一轮排查
### 云日志数据源不再支持按曲线无数据检测
-腾讯云 CLS 与阿里云 SLS 属于云日志类数据源,不再支持「之前查到过数据,现在查不到了,就告警」这种**按曲线(per-series)**的无数据检测,只保留「**所有查询均无返回数据时告警**」:
+腾讯云 CLS 与阿里云 SLS 属于云日志类数据源,不再支持「之前查到过数据,现在查不到了,就告警」这种<strong>按曲线(per-series)</strong>的无数据检测,只保留「**所有查询均无返回数据时告警**」:
- 编辑告警规则时,云日志类数据源下不再出现按曲线的检测卡;这类告警的**恢复方式**固定为「任一查询重新查到数据后自动恢复」,界面上只读展示,不再提供下拉选项
- 存量已开启按曲线检测的规则,打开编辑页时该判定会被**自动关闭**并弹出提示,保存后生效;不打开编辑页则规则配置不变。若规则除此之外没有其它已启用的判定,保存会被「至少启用一项」校验拦下,需要显式改配
@@ -363,7 +363,7 @@ SAML2.0 / OIDC / CAS 协议的 SSO 设置页新增**同步配置**区块,登
- **默认支付渠道跟随界面语言**:中文界面默认支付宝,非中文界面默认 Stripe,提交前均可切换
- **Stripe 按固定汇率折算入账**:每个美元档位直接显示精确折算的人民币金额,不再是估算
- **绑卡自动扣款的触发条件收窄**:仅在**到期续费余额不足**时从已保存的卡扣款,不再因欠费扣款;每账户每 24 小时最多一次,连续失败 3 次自动停止
-- **收支明细区分扣款来源**:系统代扣的流水标注为自动充值(Auto top-up),与你手动发起的 Stripe 充值分列
+- **收支明细区分扣款来源**:系统代扣的流水标注为自动充值(Auto top-up),与您手动发起的 Stripe 充值分列
- **发票入口收紧**:仅已开具的 Stripe 充值订单在「发票」列给出直链,其余渠道仍走开票申请单
- 左侧菜单一级项 **订阅管理** 更名为 **订阅**
@@ -503,7 +503,7 @@ Kubernetes App 的权限矩阵更新,明确了各档位的能力边界:
- 所有档位都不支持进入容器(exec)、Attach、端口转发,以及 watch 和日志实时跟随(`-f`)——这是接入方式的限制,与权限档位无关
- **读取 + 有限修改**:仅支持驱逐 Pod 重启工作负载、扩缩容 Deployment 和 StatefulSet、调整 HPA 副本数上下限;`kubectl rollout restart` 和 `kubectl rollout undo` 会被拒绝(两者都是对工作负载的 patch),重启请改用逐个驱逐 Pod
- **只读**:授权 namespace 内的读取权限直接绑定 Kubernetes 内置的 `view` 角色,可读 Pod、日志、ConfigMap 等非敏感资源,不含 Secret
-- 回滚:在只读与读取 + 有限修改档位下,AI SRE 会推算出目标 revision 并给出完整命令,由你执行
+- 回滚:在只读与读取 + 有限修改档位下,AI SRE 会推算出目标 revision 并给出完整命令,由您执行
### 快速静默标签排除规则
@@ -580,12 +580,12 @@ Monitors 告警规则管理能力全面升级,规则运行可观测、批量
### 状态页嵌入组件(Widget)
-公开状态页新增**嵌入组件**:一段可直接粘贴到任意网站 HTML 中的代码,把服务实时状态展示在你的官网、帮助中心或内部系统里。
+公开状态页新增**嵌入组件**:一段可直接粘贴到任意网站 HTML 中的代码,把服务实时状态展示在您的官网、帮助中心或内部系统里。
- **两种形态**:**状态徽标**常显当前整体状态,适合放在页脚或帮助中心;**事件横幅**仅在故障或维护时出现在页面顶部/底部,访客可关闭,计划维护开始前 24 小时自动显示
- **外观可配**:主题(自动/亮色/暗色)、语言(中文/English)、徽标尺寸、横幅位置
- **嵌入简单**:控制台 状态页详情 → 设置 → 嵌入组件,实时预览并一键复制嵌入代码(`<script>` + `<flashduty-status-widget>` Web Component)
-- **公开 JSON 接口**:`GET {状态页地址}/api/widget/v1/summary.json`,无需密钥、支持 CORS 与 ETag,可自行渲染或集成到你的监控体系
+- **公开 JSON 接口**:`GET {状态页地址}/api/widget/v1/summary.json`,无需密钥、支持 CORS 与 ETag,可自行渲染或集成到您的监控体系
- 仅公开状态页可用,默认开启,无需配置
详见 [嵌入组件(Widget)](/zh/on-call/statuspage/widgets)。
@@ -641,7 +641,7 @@ AI SRE 向所有账户全量开放公测:无需申请,登录控制台即可
### AI SRE 自治排障 Agent
-Flashduty AI SRE 进入内测阶段,提供对话式自治排障能力。你可以用自然语言描述问题,让 Agent 自主规划步骤、查询监控与日志、执行命令、调用 MCP 工具,并在需要时委派 Subagent,最终给出带调查过程的结论。
+Flashduty AI SRE 进入内测阶段,提供对话式自治排障能力。您可以用自然语言描述问题,让 Agent 自主规划步骤、查询监控与日志、执行命令、调用 MCP 工具,并在需要时委派 Subagent,最终给出带调查过程的结论。
- 支持从控制台对话工作区发起排障会话,查看流式输出、工具调用与结论
- 支持从故障或作战室带入上下文,让 AI SRE 围绕具体故障进行调查
@@ -652,7 +652,7 @@ Flashduty AI SRE 进入内测阶段,提供对话式自治排障能力。你可
### IM 原生排障与作战室自动诊断
-AI SRE 可以直接接入 Slack、飞书、钉钉和企业微信。你可以在群聊或私聊中 @ AI SRE 发起或续接排查,团队成员无需切换到控制台即可看到分析过程。
+AI SRE 可以直接接入 Slack、飞书、钉钉和企业微信。您可以在群聊或私聊中 @ AI SRE 发起或续接排查,团队成员无需切换到控制台即可看到分析过程。
- 支持 IM 线程内回复,避免在群聊中刷屏
- 支持作战室创建后自动拉起一轮初步诊断,并将结论回贴到作战室
@@ -678,7 +678,7 @@ AI SRE 新增自动化能力,可按周期、API 或 On-call 故障事件触发
### 微信小程序 RUM
-RUM 新增微信小程序 SDK 与分析看板,帮助你采集和分析小程序真实用户体验。
+RUM 新增微信小程序 SDK 与分析看板,帮助您采集和分析小程序真实用户体验。
- SDK 自动采集页面生命周期、用户操作、网络请求、应用错误和性能指标
- 支持 `service`、`env`、`version`、会话采样率和代理上报配置
@@ -700,7 +700,7 @@ RUM 新增 HarmonyOS NEXT SDK 文档,覆盖 ArkTS 应用中的 RUM、Trace 和
### 移动端符号化与合规指南
-RUM 源码管理能力扩展到更多移动端场景,帮助你在异常详情中还原混淆或编译后的堆栈。
+RUM 源码管理能力扩展到更多移动端场景,帮助您在异常详情中还原混淆或编译后的堆栈。
- 支持微信小程序 `sourcemap.zip` 上传与堆栈还原
- 支持 Android ProGuard/R8 mapping 文件和 NDK 原生符号文件
@@ -727,7 +727,7 @@ On-call 新增两类拉取式告警接入,适用于无法主动推送 webhook
### 动态分派追加模式
-动态分派新增 append 追加模式。你可以在保留模板分派策略原有通知对象的基础上,根据告警标签额外追加负责人、团队或群聊机器人。
+动态分派新增 append 追加模式。您可以在保留模板分派策略原有通知对象的基础上,根据告警标签额外追加负责人、团队或群聊机器人。
- `reset` 模式用于替换模板分派对象
- `append` 模式用于追加通知对象,适合在默认团队之外补充业务负责人
diff --git a/zh/compliance/service-sla.mdx b/zh/compliance/service-sla.mdx
index d0f069d5..e817dd0d 100644
--- a/zh/compliance/service-sla.mdx
+++ b/zh/compliance/service-sla.mdx
@@ -11,7 +11,6 @@ keywords: ["SLA", "服务等级协议", "可用性承诺", "服务保障", "赔
特别提示您,除非另有约定,本协议不适用于 Flashduty 公测、邀测、免费的功能及版本,也不适用于 Flashduty 私有化版本。
## 我们如何保证 SLA
----
1. **同城多活**:基础设施构建在多个数据中心之上,有状态组件均为同城多活;
2. **异步处理**:告警上报后会立即进入异步流程,出错有重试,减少告警丢失风险;
@@ -20,7 +19,6 @@ keywords: ["SLA", "服务等级协议", "可用性承诺", "服务保障", "赔
5. **持续监控**:全面采集系统各方面指标,定期进行压测,及时或提前发现系统问题。
## 我们的 SLA 承诺
----
- **功能可用(错误率)**:核心功能,在99.9%的时间内是可用的
- **投递时效(延迟率)**:99.9%的告警,在触发后5分钟内完成投递
@@ -61,7 +59,6 @@ keywords: ["SLA", "服务等级协议", "可用性承诺", "服务保障", "赔
## 如何申请赔偿
----
### 赔偿标准
@@ -78,7 +75,6 @@ keywords: ["SLA", "服务等级协议", "可用性承诺", "服务保障", "赔
赔偿申请最迟不应晚于 Flashduty 未达到服务可用性承诺的相关月份结束后两(2)个月内提出。
## 其他说明
----
快猫星云有权对本SLA条款作出修改。
diff --git a/zh/compliance/terms-of-service.mdx b/zh/compliance/terms-of-service.mdx
index ff5878e3..04c8610a 100644
--- a/zh/compliance/terms-of-service.mdx
+++ b/zh/compliance/terms-of-service.mdx
@@ -9,7 +9,6 @@ keywords: ["服务条款", "服务协议", "用户权利", "法律条款", "快
欢迎您与北京快猫星云科技有限公司(以下简称“快猫星云”)共同签署本《快猫星云产品服务协议》(下称“本协议”)并使用快猫星云服务!
## **一般条款**
----
1.1. 您确认:您在使用本服务之前,已经充分阅读、理解并接受本协议及其他相关协议和规则的全部内容(特别是以加粗和/或加下划线标注的内容),一旦您在本网站上选择“同意”(具体措辞详见注册页面)并完成购买流程或以任何其他方式选择使用本服务,即表示您同意遵守前述所有协议和/或规则项下的所有条款,并愿意受之约束。
@@ -20,7 +19,6 @@ keywords: ["服务条款", "服务协议", "用户权利", "法律条款", "快
1.4. 快猫星云仅向您提供快猫星云服务相关的技术服务及技术支持,是中立的信息存储空间等网络服务与中立的相关技术服务提供者。您自己所拥有、通过快猫星云上传、存储或以任何形式管理、控制、运营的网站、应用等任何产品、服务及其相关内容等,均由您自行开发、运营且自行承担全部责任,快猫星云不就任何该等产品、服务及其相关内容等承担任何责任。
## **通用服务条款**
----
### **1. 签约主体及协议范围**
diff --git a/zh/compliance/user-agreement.mdx b/zh/compliance/user-agreement.mdx
index 0922efe3..ee2158a6 100644
--- a/zh/compliance/user-agreement.mdx
+++ b/zh/compliance/user-agreement.mdx
@@ -12,7 +12,6 @@ keywords: ["用户协议", "账户管理", "隐私政策", "个人信息保护",
请您务必审慎阅读、充分理解本协议各条款的内容,以及在开通或使用某项快猫星云服务时所应适用和遵守的单独协议或规则(以下简称“其他相关协议和规则”),特别是以加粗或加下划线的形式提示您重点注意的条款。
## **1 一般条款**
----
1.1 您确认:您在使用本服务之前,已经充分阅读、理解并接受本协议及其他相关协议和规则的全部内容(特别是以加粗和/或加下划线标注的内容),一旦您在本网站上选择“同意”(具体措辞详见注册页面)并完成注册流程或以任何其他方式选择使用本服务,即表示您同意遵守前述所有协议和/或规则项下的所有条款,并愿意受之约束。
@@ -23,7 +22,6 @@ keywords: ["用户协议", "账户管理", "隐私政策", "个人信息保护",
1.4 快猫星云仅向您提供快猫星云服务相关的技术服务及技术支持,是中立的信息存储空间等网络服务与中立的相关技术服务提供者。您自己所拥有、通过快猫星云上传、存储或以任何形式管理、控制、运营的网站、应用等任何产品、服务及其相关内容等,均由您自行开发、运营且自行承担全部责任,快猫星云不就任何该等产品、服务及其相关内容等承担任何责任。
## **2 用户服务账户**
----
### **2.1 账户注册**
@@ -65,7 +63,6 @@ keywords: ["用户协议", "账户管理", "隐私政策", "个人信息保护",
2.4.3 您有权主动注销您的账户,您可以发送电子邮件至 [support@flashcat.cloud](mailto:support@flashcat.cloud) 申请注销账号。
## **3 服务规则**
----
3.1 您以如下方式向快猫星云发出的指令,均是您本人发出的不可撤回或撤销的指令对于快猫星云执行该等指令所产生的任何结果和责任,均由您自行承担:
@@ -113,7 +110,6 @@ keywords: ["用户协议", "账户管理", "隐私政策", "个人信息保护",
3.10.5 如您认为 AI 功能生成的内容违法违规、存在错误或侵害您的合法权益,您可通过产品内的反馈入口或发送邮件至 [contact-us@flashcat.cloud](mailto:contact-us@flashcat.cloud) 进行投诉、举报,快猫星云将及时核查并处置。
## **4 您的权利和义务**
----
4.1 快猫星云将为您提供网络技术和信息服务,并将在向您提供服务时提供快猫星云的技术支持、客户咨询等服务,该等服务的内容详见本网站相关页面。
@@ -168,7 +164,6 @@ keywords: ["用户协议", "账户管理", "隐私政策", "个人信息保护",
4.6 您知晓并认可,在快猫星云服务上安装、使用盗版软件等识不被允许且违反本服务协议的。与此同时,您应当按照国家有关规定对您使用的计算机信息系统采取一切必要且合适的安全保护措施,包括但不限于安装经国家许可的计算机信息系统安全专用产品等。
## **5 快猫星云的权利和义务**
----
5.1 根据您选择的服务以及交纳款项的情况,快猫星云将向您提供合格的网络技术和信息服务。
@@ -196,7 +191,6 @@ keywords: ["用户协议", "账户管理", "隐私政策", "个人信息保护",
如发生按照前述规定对您的账户资金进行冻结的情形,快猫星云将通过邮件、站内信、短信或电话等一种方式或多种对您进行通知。您可以按照相应的程序进行申诉。如果您按照本协议第 3.8 条的要求进行申诉并经快猫星云审核通过的,快猫星云将立即解除资金冻结措施;如果您未能在规定时间内进行申诉,或您的申诉未能通过快猫星云审核,则您认可快猫星云有权长期冻结该等资金,或将相关冻结款项按原路退回该笔款项的充值来源账户,包括但不限于银行账户、微信账户、支付宝账户等。
## **6 个人信息保护**
----
6.1 快猫星云依据《[隐私政策](/zh/compliance/privacy-policy)》收集、使用、存储、共享和保护您的个人信息。《隐私政策》载明了我们收集的信息类别、使用目的、共享对象、跨境传输、留存期限、设备权限与第三方 SDK 使用说明,以及您就个人信息享有的权利。
@@ -205,7 +199,6 @@ keywords: ["用户协议", "账户管理", "隐私政策", "个人信息保护",
6.3 关于您账户和密码的保管责任,见本协议第 2.3 条。
## **7 系统中断或故障**
----
发生下列情形时,快猫星云服务系统可能无法正常运行,因此导致您无法使用服务并由此产生相应的后果,快猫星云不承担任何责任:
@@ -219,7 +212,6 @@ keywords: ["用户协议", "账户管理", "隐私政策", "个人信息保护",
- 8. 其他非快猫星云过错、快猫星云无法控制或合理预见的情形。
## **8 责任范围及责任限制**
----
8.1 快猫星云仅在本协议中列明的责任范围内承担责任。
@@ -232,14 +224,12 @@ keywords: ["用户协议", "账户管理", "隐私政策", "个人信息保护",
8.5 在任何情况下,除本协议另有规定或快猫星云与您就某一具体产品和/或服务另有约定外,您同意快猫星云在本协议条款及其他有关协议和规则项下所承担的赔偿责任总额不超过向您收取的当次服务费用总额。
## **9 知识产权**
----
9.1 除第三方产品或服务外,本网站上所有内容,包括但不限于相关产品或服务的全部内容,以及图片、标识、档案、资讯、资料、架构、页面设计等,均由快猫星云或快猫星云关联公司依法拥有其知识产权,包括但不限于著作权、商标权、专利权、商业秘密等。对于任何侵犯快猫星云知识产权的行为,快猫星云有权依照相关适用法律及本协议的规定要求承担法律责任。
9.2 非经快猫星云或快猫星云关联公司书面许可,任何人不得以任何方式或理由对本网站上的产品、服务、软件、程序、信息等的任何部分进行擅自使用、修改、复制、传播、散布、发行或公开发表,或与其他产品捆绑使用、销售,或以超级链路链接或传送或者以其他任何商业目的进行使用。
## **10 保密**
----
10.1 在本协议项下,对于任何一方(“接收方”)从另一方(“披露方”)所接收之信息,如有标明或可合理认为属于披露方的机密或专有信息的(包括但不限于技术、商业相关信息,以下简称“保密信息”),接收方应予以保密,且未经披露方书面同意,不得用于本协议以外的任何目的。接收方应以对待其自身保密信息相同的注意程度(且不得低于合理审慎义务)处理披露方的保密信息。
@@ -255,7 +245,6 @@ keywords: ["用户协议", "账户管理", "隐私政策", "个人信息保护",
10.4 双方的保密义务在本协议有效期限内及期限届满后持续有效,直至相关信息不再具有保密意义。
## **11 完整协议**
----
11.1 本协议由本协议条款与本网站公示的各项规则组成,如对本协议与本网站公示的各项规则所用措辞之含义有不同理解,则应以本协议条款为准。
@@ -266,14 +255,12 @@ keywords: ["用户协议", "账户管理", "隐私政策", "个人信息保护",
11.4 本协议部分内容被有管辖权的法院认定为无效或不具有执行力的,不因此影响其他内容的效力或执行力。
## **12 通知送达**
----
12.1 您理解并认可,经合理判断,快猫星云可自行通过网页公告、电子邮件、手机短信或常规的信件传送等方式向您发送通知,且快猫星云可以推定您提供给本网站的联系信息是完整、准确且当前有效的;上述通知于发送之日视为已送达收件人。
12.2 除非本协议条款另有约定或快猫星云与您另行签订的专门协议明确规定了通知的方式,否则您发送给快猫星云的任何通知,均需通过快猫星云对外正式公布的通信地址、传真号码、电子邮件地址等联系信息进行送达。
## **13 法律适用与争议解决**
----
13.1 本协议的签订地为北京市海淀区。
diff --git a/zh/developer/cli.mdx b/zh/developer/cli.mdx
index ff845af1..22e4b2e3 100644
--- a/zh/developer/cli.mdx
+++ b/zh/developer/cli.mdx
@@ -54,7 +54,7 @@ irm https://static.flashcat.cloud/flashduty-cli/install.ps1 | iex
flashduty login
```
-按提示输入 APP Key。获取方式:登录 [Flashduty 控制台](https://console.flashcat.cloud),进入 **个人中心 > 个人信息**,复制 APP Key。
+按提示输入 APP Key。获取方式:登录 [Flashduty 控制台](https://console.flashcat.cloud),进入 **个人中心 → 个人信息**,复制 APP Key。
### 凭证解析顺序
@@ -892,7 +892,7 @@ TOON 不能直接用 `jq` 解析;需要管道给 `jq` 时请改用 `--json`。
</Tab>
</Tabs>
-#### 生成命令的输出上限
+### 生成命令的输出上限
由 OpenAPI 代码生成提供覆盖的生成命令(如 `safari session-list`、`monit datasource-list`、`safari a2a-agent-list` 等),其 `json` / `toon` 输出对**列表形态**的响应按 16 KiB 上限处理。缩减分三级,另外会有一个机读标记:
diff --git a/zh/developer/go-sdk.mdx b/zh/developer/go-sdk.mdx
index 8fc21b5e..3ef955cb 100644
--- a/zh/developer/go-sdk.mdx
+++ b/zh/developer/go-sdk.mdx
@@ -7,17 +7,15 @@ keywords: ["Go SDK", "go-flashduty", "Open API", "Golang", "客户端"]
## 概述
----
-
`go-flashduty` 是 Flashduty 官方开源的 Go 客户端,覆盖 Flashduty Open API 的每一个 REST 接口。它采用与 [go-github](https://github.com/google/go-github) 一致的设计风格——服务分组、类型化请求与响应、可组合传输层——并与 OpenAPI 规范保持严格 1:1:每个方法对应且仅对应一次 HTTP 调用,返回 `(*T, *Response, error)`,不做任何跨接口的隐式聚合或增强。
SDK 的类型化接口由 Flashduty OpenAPI 规范生成,经单元测试覆盖,并针对线上 API 做过端到端验证。
<Note>
-SDK 故意保持"薄"。诸如短 ID 解析、跨接口编排等消费侧逻辑应放在调用方(CLI / MCP)中,而不是塞进 SDK 或滥用某个接口。这样 SDK 始终与 API 一一对应,可预测、可生成、可校验。
+SDK 故意保持"薄"。诸如短 ID 解析、跨接口编排等消费侧逻辑应放在调用方(CLI / MCP)中,而不是塞进 SDK 或滥用某个接口。这样 SDK 始终与 API 一一对应,可预测、可生成、可校验。
</Note>
-模块路径为 `github.com/flashcatcloud/go-flashduty`,包名为 `flashduty`,源码遵循 Apache-2.0 协议开源在 [flashcatcloud/go-flashduty](https://github.com/flashcatcloud/go-flashduty)。
+模块路径为 `github.com/flashcatcloud/go-flashduty`,包名为 `flashduty`,源码遵循 Apache-2.0 协议开源在 [flashcatcloud/go-flashduty](https://github.com/flashcatcloud/go-flashduty)。
<CardGroup cols={2}>
<Card title="Open API 参考" icon="book" href="/zh/openapi/introduction">
@@ -30,8 +28,6 @@ SDK 故意保持"薄"。诸如短 ID 解析、跨接口编排等消费侧逻辑
## 安装
----
-
<Steps>
<Step title="要求 Go 1.24+">
请确认本地 Go 工具链版本不低于 1.24。
@@ -50,8 +46,6 @@ import flashduty "github.com/flashcatcloud/go-flashduty"
## 快速开始
----
-
以下是一个最小可运行示例:构造客户端、列出处于"已触发"状态的故障,并处理返回的三元组 `(数据, *Response, error)`。
```go
@@ -91,7 +85,7 @@ func main() {
| 返回值 | 类型 | 说明 |
|--------|------|------|
| 数据 | `*T` | 接口对应的类型化响应体(如 `*ListIncidentsResponse`);调用失败时为 `nil` |
-| `*Response` | `*flashduty.Response` | 包裹 `*http.Response`,并附带 `RequestID`、分页等信封元信息 |
+| `*Response` | `*flashduty.Response` | 包裹 `*http.Response`,并附带 `RequestID`、分页等信封元信息 |
| `error` | `error` | 失败时为 `*ErrorResponse`,429 时为 `*RateLimitError` |
<Tip>
@@ -100,9 +94,7 @@ func main() {
## 创建客户端
----
-
-`NewClient` 接收 `app_key` 与零到多个 `Option`。`app_key` 为空会直接返回错误。默认 Base URL 为 `https://api.flashcat.cloud`,默认 HTTP 超时为 30 秒,默认 User-Agent 为 `go-flashduty`。
+`NewClient` 接收 `app_key` 与零到多个 `Option`。`app_key` 为空会直接返回错误。默认 Base URL 为 `https://api.flashcat.cloud`,默认 HTTP 超时为 30 秒,默认 User-Agent 为 `go-flashduty`。
```go
client, err := flashduty.NewClient("YOUR_APP_KEY",
@@ -122,14 +114,14 @@ client, err := flashduty.NewClient("YOUR_APP_KEY",
| `WithBaseURL(raw string)` | 覆盖 API 基础地址(默认 `https://api.flashcat.cloud`)。私有化部署用它指向自有网关;地址可带路径前缀(如 `https://gateway.example.com/api`,请求会打到 `/api/<endpoint>`,结尾带不带 `/` 均可);非法 URL 会在 `NewClient` 阶段报错 |
| `WithTimeout(d time.Duration)` | 设置底层 HTTP 客户端的整体超时 |
| `WithUserAgent(ua string)` | 设置每个请求携带的 `User-Agent` 头 |
-| `WithHTTPClient(hc *http.Client)` | 替换底层 `*http.Client`;传入 `nil` 时忽略 |
-| `WithTransport(rt http.RoundTripper)` | 设置自定义 `http.RoundTripper`,是接入重试、缓存、链路追踪、限流等中间件的惯用切入点;传入 `nil` 时忽略 |
-| `WithLogger(l Logger)` | 设置自定义日志器;传入 `nil` 时忽略 |
-| `WithRequestHeaders(h http.Header)` | 设置追加到每个请求的静态头,在 SDK 自身的头(`Content-Type`、`Accept`、`User-Agent`)之后应用 |
-| `WithRequestHook(hook func(*http.Request))` | 注册回调,在每个请求发出前调用,用于注入逐请求的头(如 W3C `traceparent`) |
+| `WithHTTPClient(hc *http.Client)` | 替换底层 `*http.Client`;传入 `nil` 时忽略 |
+| `WithTransport(rt http.RoundTripper)` | 设置自定义 `http.RoundTripper`,是接入重试、缓存、链路追踪、限流等中间件的惯用切入点;传入 `nil` 时忽略 |
+| `WithLogger(l Logger)` | 设置自定义日志器;传入 `nil` 时忽略 |
+| `WithRequestHeaders(h http.Header)` | 设置追加到每个请求的静态头,在 SDK 自身的头(`Content-Type`、`Accept`、`User-Agent`)之后应用 |
+| `WithRequestHook(hook func(*http.Request))` | 注册回调,在每个请求发出前调用,用于注入逐请求的头(如 W3C `traceparent`) |
<Info>
-**私有化部署**:用 `WithBaseURL` 将客户端指向您自有的 Flashduty 网关地址即可,其余调用方式完全不变。
+**私有化部署**:用 `WithBaseURL` 将客户端指向您自有的 Flashduty 网关地址即可,其余调用方式完全不变。
</Info>
### OAuth 访问令牌
@@ -146,9 +138,7 @@ client, err := flashduty.NewClientWithAccessToken(accessToken,
## 服务与方法
----
-
-接口按服务分组挂在客户端上:调用约定统一为 `client.<Service>.<Method>(ctx, req)`,返回 `(*T, *Response, error)`。例如 `client.Incidents.List(ctx, req)`、`client.Sessions.Info(ctx, req)`。
+接口按服务分组挂在客户端上:调用约定统一为 `client.<Service>.<Method>(ctx, req)`,返回 `(*T, *Response, error)`。例如 `client.Incidents.List(ctx, req)`、`client.Sessions.Info(ctx, req)`。
| 服务字段 | 说明 |
|----------|------|
@@ -190,20 +180,40 @@ client, err := flashduty.NewClientWithAccessToken(accessToken,
| `client.SessionReplay` | RUM 会话回放 |
| `client.Sourcemaps` | RUM Sourcemap |
+<Note>
+所有标识符、服务字段名与方法名均与生成代码保持一致。具体每个服务有哪些方法、请求与响应类型,请以 `services_gen.go` 与各服务文件,以及 [Open API 参考](/zh/openapi/introduction) 为准。
+</Note>
+
+以下服务有需要额外说明的行为:
+
+### 状态页草稿
+
`client.StatusPages.DraftCreate`(`POST /status-page/draft/create`)把一次状态页事件草稿存下来,供人工在控制台审阅后发布,不会直接对外可见:`draft` 为任意 JSON,按原文存储、序列化后不超过 64 KB,其中 `page_id`、`type`(`incident` 或 `maintenance`)、`name`、`message` 会被校验;`change_id`(> 0 时表示追加到已有事件的一次更新)、`status`、`affected_components` 可选,新建 maintenance 时可用 `start_time` / `end_time`(Unix 秒)指定窗口。请求上的 `source` 是草稿来源标记(≤ 64 字符,如 `ai_sre:sess_xxx`);响应返回 `draft_id`(匹配 `draft_[A-Za-z0-9]{22}`),控制台的审阅链接即携带它。
+### 知识
+
`client.Knowledge` 对应 `/safari/knowledge/*` 的 9 个 API 操作:知识侧为 `PackReadGet`(获取账户知识)、`PackReadList`(列出知识)、`PackWriteEnsure`(确保知识存在)、`PackWriteUpdate`(变更知识作用域)、`PackWriteDelete`(删除知识);知识文件侧为 `FileReadGet`、`FileReadList`、`FileWritePut`(上传/覆盖)、`FileWriteDelete`。相关导出类型包括 `KnowledgePackItem`、`KnowledgeFileItem`、`KnowledgeWarning` 以及各 `Knowledge*Request` / `Knowledge*Response`。
+### AI SRE 产物
+
`client.Artifacts`(AI SRE 产物)对应 `/safari/artifact/*` 的 11 个 API 操作:画廊读取侧 `ReadGet`(按 ID 获取单个已发布产物)、`ReadList`(分页列出调用方可见的产物,支持标题子串搜索、`scope`(`all` / `personal` / `team`)与 `team_ids` 过滤)、`ReadGetFileState`(批量探测会话展示文件(`pf_` 前缀)是否已有上线产物,单次至多 50 个 ID);文件侧 `ReadSign`(为展示文件签发短期有效的下载/预览 URL,有效期 5 分钟,`expires_in` 固定 300 秒)与 `ReadStream`(凭签名 token 下载或预览文件,成功响应体是文件而非 JSON 信封,原始字节放在 `Response.Raw`);写入侧 `WritePublish`(把会话产生的文件发布为画廊产物)、`WriteUpdate`(重命名或转移个人/团队作用域)、`WriteDelete`(从画廊移除,源文件仍保留在会话中);公开分享 `WriteShareEnable`(开启匿名公开分享并返回公开链接,任何人凭链接即可查看、无需登录)、`WriteShareRevoke`(关闭分享,链接立即失效)、`WriteShareSync`(把公开快照刷新为最新内容——当 `share_enabled` 为 true 且 `share_file_id` 与 `file_id` 不一致时表示快照已过期,调用它刷新)。相关导出类型包括 `PublishedArtifactItem`、`ArtifactShareState`、`SignedUrLs` 以及各 `Artifact*Request` / `Artifact*Response`。
+### 成员邮件通知
+
`client.Members.MemberNotify`(`POST /member/notify`,`memberNotify`)以调用方身份向账户成员发送邮件,仅可使用 AI SRE 会话凭据调用——其他凭据(包括普通 `app_key`)一律以 `AccessDenied` 拒绝(用 `IsAccessDenied` / `ErrorCodeOf` 判定)。请求字段:`subject`(必填,1–200 字符)与 `html`(必填,收件人看到的完整邮件正文,不超过 102,400 字节),`person_ids` 可选(至多 20 个且不可重复,省略或为空时只发送给调用方本人)。`html` 中的 `script`、`meta`、`link`、`base` 标签及 `on*` 事件属性会在发送前被静默清除;而 `style`、`svg`、`iframe`、`object`、`embed`、`form`、`input`、`button` 标签,没有 `https` `src` 的 `img`,或者链接不属于 `http`/`https`/`mailto` 的,会在入队前直接以 `InvalidParameter` 拒绝调用,并在错误信息中逐一列出触发的构造。投递是异步的,`accepted` 只表示邮件已入队;响应的 `recipients[]` 按收件人逐条返回(`person_id` 与 `status`),`status` 为 `accepted` 或 `skipped`,后者带 `reason`:`not_member`、`no_email`、`email_disabled`、`duplicate`、`rate_limited`(同一收件人每小时最多 20 封)、`send_failed`。响应只有 `recipients[]` 和可选的 `agent_instructions` 两个字段,不回显清洗后的邮件 HTML;当提交的 `html` 不符合默认邮件版式(缺少 `max-width:600px` 外层包裹表格)时会返回 `agent_instructions`,内容是写给调用的 AI SRE agent 的版式对齐指引——仅为建议,调用方有意选择的格式无需改动。
+### 诊断查询
+
`client.Diagnostics.QueryData` 通过 `POST /monit/query/data` 执行同步查询,返回稳定的 `query_result.v1` 结构化结果(`result.kind` 为 `frames` / `records` / `samples` 之一),要求 monit-edge v0.65.0 及以上版本。日志模式和指标趋势分析统一使用 `client.DataSources.ToolsInvoke`,工具名称为 `prometheus.metric_trends`、`loki.log_patterns` 或 `victorialogs.log_patterns`。
`client.Diagnostics.QueryExplore`(`POST /monit/query/explore`,`monit-read-query-explore`)对已配置的数据源执行探索查询,返回数据源原生形态的 `explore_result.v1`:`ExploreData.format` 恒为 `explore_result.v1`,`result.kind` 取 `frames`(列式表格或时序,见 `ExploreFrame` / `ExploreField`)、`samples`(带标签的瞬时值 `ExploreSample`)或 `logs`(日志条目 `ExploreLogEntry`,最多 1000 条,被截断时 `has_more` 为 true、`applied_limit` 给出实际生效的上限),`execution.effective_step_seconds` 回显应用 `max_data_points` 与 `min_step_seconds` 之后实际使用的步长。请求字段:`datasource_id`(取自 `/monit/datasource/list`,必须是当前账户下的数据源)、`expr`(数据源原生语言的查询表达式,如 PromQL、LogsQL、SQL)、`args`(Grafana 风格宏变量替换的字符串键值;请求中必填,没有宏变量时传空表 `map[string]string{}`——Go 的 `nil` map 会序列化为 `null`,不符合 schema)与 `execution`(`QueryExploreExecution`:`kind` 取 `instant` / `range` / `window`,`to_ms` 在三种模式下都必填,`range` 另需 `from_ms` 与 `max_data_points`,`window` 另需 `from_ms`,`min_step_seconds` 仅在 `range` 下接受)。与 `QueryData` 的分工:需要数据源原生结果形态(含原始日志)时用 `QueryExplore`,需要稳定的 `query_result.v1` 契约时用 `QueryData`。该接口需要「数据源查看」(`monit`)权限,并要求受支持的部署运行 monit-edge v0.68.0 及以上版本。
+### RUM 远程配置与仓库关联
+
`client.Applications`(RUM 应用)除应用管理外还覆盖 **RUM 远程配置**的 5 个方法:`RemoteConfigReadGet`(`POST /rum/application/remote-config/get`,读取当前生效的配置与 `version`)、`RemoteConfigReadHistoryList`(`/rum/application/remote-config/history/list`,分页列出已发布的历史版本)、`RemoteConfigReadPreview`(`/rum/application/remote-config/preview`,用模拟客户端的 `env` / `app_version` / `sdk` 上下文评估一份草稿配置,返回命中的 `hit_rule_index` 与最终下发的 `values`,不发布)、`RemoteConfigWriteUpdate`(`/rum/application/remote-config/update`,发布一份完整的新配置)、`RemoteConfigWriteHistoryRevert`(`/rum/application/remote-config/history/revert`,把历史版本的内容重新发布为新版本)。主要类型:`RemoteConfig`(`enabled`、`activation`、`default`、`rules`、`custom`、`refresh_on_foreground`)、`RemoteConfigValues`(四个可下调的 SDK 开关)、`RemoteConfigRule`(`match` 条件加 `set` 取值)、`RemoteConfigHistoryItem`(含 `version`、`reason`、`content_hash`、`updated_by`),以及 `GetRemoteConfigRequest` / `ListRemoteConfigHistoryRequest` / `PreviewRemoteConfigRequest` / `UpdateRemoteConfigRequest` / `RevertRemoteConfigRequest` 与各自的 `*Response`。应用本身的 `WriteCreate` / `WriteUpdate` / `ReadInfo` / `ReadInfos` / `ReadList` 还带 `repositories` 字段(`[]RUMApplicationRepository`,仅存在于请求体,不是顶层标志):把应用关联到构建它的代码仓库,有序,第一项为主仓库,最多 10 项;每项为 `Repo`(`owner/name` 形式的 GitHub 仓库,必填)加可选的 `Subdir`(应用在仓库内所在的目录,相对仓库根目录,`.` 表示仓库根目录,空值保存为 `.`)。创建时传入即建立关联;更新时按 presence 处理——传入即整体替换、传空数组清空关联、省略则保持不变;`ReadInfo` / `ReadInfos` / `ReadList` 会把它回显在 `RUMApplicationItem` 上。关联本身不授予任何访问权限:AI 会话只能读取账户 GitHub App 安装已授权的仓库。该字段目前只在 API/SDK 层提供,控制台的应用管理页不暴露仓库关联设置。
+### 数据源工具调用
+
`client.DataSources.ToolsInvoke`(`POST /monit/datasource/tools/invoke`,`monit-datasource-tools-invoke`)在某个已配置数据源上执行一个确定性工具:`tool` 名称由数据源类型前缀修饰(如 `mysql.overview`),`params` 为工具专属 JSON 参数(省略视为 `{}`,显式 `null` 非法);除诊断工具外,入口支持 `<type>.query` 查询工具(`prometheus`、`mysql`、`postgres`、`oracle`、`clickhouse`、`elasticsearch`、`loki`、`victorialogs`、`sls`、`tencent_cls`),`/monit/query/data` 入口保持不变。该接口要求集群中所有在线可路由的 Edge 会话都支持 v0.71.0 基础调用协议(单个工具可能要求更新的实现),无工具目录、无自动重放、也不会回退到旧版 diagnose。请求体上限 128 KiB,完整成功响应上限 10 MiB,单工具超时至多 25 秒;响应为 `DatasourceToolResult`(`data` 为工具专属 JSON、永不为 null,`summary` 可选,出现 `truncated` 时其 `reason` 说明截断原因)。
调用 `<type>.query` 查询工具时用 `NewDatasourceQueryInvokeRequest(datasourceID, tool, params)` 构造请求,`params` 传对应的类型化结构(每个工具一种):`PrometheusQueryParams`、`MySQLQueryParams`、`PostgresQueryParams`、`OracleQueryParams`、`ClickHouseQueryParams`、`ElasticsearchQueryParams`、`LokiQueryParams`、`VictoriaLogsQueryParams`、`SLSQueryParams`、`TencentCLSQueryParams`。这些结构都由 `expr` 加 `execution` 组成(`DatasourceQueryExecution`:`kind` 取 `instant` / `range` / `window`,`from_ms` / `to_ms` 为 Unix 毫秒的 `*int64`;`range` 还要求 `max_data_points`,可选 `min_step_seconds` 抬高计算步长),可选字段都是指针——nil 时不发送该键,由服务端取默认值。查询工具的 `params` 不可为空:`NewDatasourceQueryInvokeRequest(..., nil)` 直接返回错误,与通用请求「省略即 `{}`」的规则不同。执行模式受数据源类型约束:Prometheus 与 Loki 用 `instant` / `range`(`instant` 只带 `to_ms`),SQL 类型(MySQL、Postgres、Oracle、ClickHouse 以及走 SQL 的 Elasticsearch)与 SLS、Tencent CLS 用 `window`,VictoriaLogs 原始日志用 `window`、统计查询用 `instant` / `range`;Loki、VictoriaLogs、SLS、Tencent CLS 的 `limit` / `direction` 只作用于原始日志检索,`SLSQueryParams` 另需 `project` / `logstore`,`TencentCLSQueryParams` 另需 `region` / `topic_id` / `syntax`。
@@ -223,24 +233,22 @@ if err != nil {
out, _, err := client.DataSources.ToolsInvoke(ctx, req)
```
+### Prometheus 标签值
+
`client.DataSources.ReadPrometheusLabelValues(ctx, dataSourceID, labelName)`(`GET /monit/prometheus/api/v1/label/{label_name}/values`,`monit-prometheus-read-label-values`)通过监控代理列出某个 Prometheus 兼容数据源上单个标签的全部取值:标签名放在 URL 路径上(SDK 会做路径转义),目标数据源由 `X-DSID` 请求头指定——SDK 用 `dataSourceID` 自动设置该头(传 `0` 或 `labelName` 为空都直接报错),ID 从 `/monit/datasource/list` 获取,必须是当前账户下 Prometheus 兼容类型的数据源。这是唯一一个成功响应体不是 Flashduty `{request_id, data}` 信封的方法:响应直接解码为 `PrometheusLabelValuesResponse`(`status` 为 `success` 时 `data` 是标签值字符串数组;为 `error` 时携带 `errorType` 与 `error`)。未到达数据源前的失败(`X-DSID` 缺失或非法、数据源不存在、数据源不是 Prometheus 类型)以 `text/plain` 返回,数据源自身的失败则用它自己的 JSON 错误形态;SDK 对两者一视同仁,把原始响应体原样放进 `*ErrorResponse.Message`。受支持的部署要求 monit-edge v0.35.0 及以上版本。
+### 数据源配置
+
`client.DataSources` 的 `payload` 按 `type_ident` 选择类型专属配置块。当前允许的 `type_ident` 共 15 种:`prometheus`、`loki`、`mysql`、`oracle`、`postgres`、`clickhouse`、`elasticsearch`、`sls`、`tencent_cls`、`victorialogs`,以及新增的诊断专用类型 `redis_node`、`redis_sentinel`、`mongodb_mongod`、`mongodb_mongos`、`kafka`——诊断专用类型的 `alerting_enabled` 恒为 false(不阻止非告警查询与工具调用),且拒绝传 true。连接地址规则:Redis/MongoDB 诊断类型为单个 `host:port`(IPv6 需加方括号),不接受 URI、userinfo 或 query;`kafka` 为 1–32 个以逗号分隔、互不重复的 `host:port` bootstrap 地址(规范化后至多 4096 字符,`payload` 中不再有 broker 列表);`mongodb_mongod` / `mongodb_mongos` 的配置块中 `auth_source` 默认为 `admin`,用户名与密码必须成对配置,不支持客户端证书;Redis 节点配置的 `database` 默认为 0。诊断类型的 `password` 与 Kafka 的 `tls_key` 等敏感字段支持 `${env:NAME}` 引用:响应中字面值会被省略(仅当存储值本身就是 `${env:...}` 引用时才回显),更新时省略这些字段即保留原值,显式传空字符串则清除。
`enabled` 与 `alerting_enabled` 相互独立:`enabled`(业务执行开关)创建时默认 true,`alerting_enabled`(是否允许参与告警评估;告警还要求 `enabled` 为 true 且类型支持告警)创建时对告警类型默认 true、对诊断专用类型默认 false;二者更新时省略均保留当前值,显式传 `null` 非法;当有启用的告警规则引用该数据源时,将其 `enabled` 置为 false 会以 conflict 拒绝。另外 `/monit/datasource/list` 响应中 `payload` 恒为 `null`(列表查询不读 payload 列),create/update/info 响应中才会填充。
-<Note>
-所有标识符、服务字段名与方法名均与生成代码保持一致。具体每个服务有哪些方法、请求与响应类型,请以 `services_gen.go` 与各服务文件,以及 [Open API 参考](/zh/openapi/introduction) 为准。
-</Note>
-
## 响应时间戳
----
-
-响应中的时间字段不再是裸整数,而是自描述的 `Timestamp`(Unix 秒)或 `TimestampMilli`(毫秒)类型(请求与响应共用的类型是例外,见下方警告)。它们序列化为本地时区的 RFC3339 字符串,因此 JSON、日志以及面向 LLM 的输出都直接可读;原始 epoch 仍只需一次方法调用即可取到。
+响应中的时间字段不再是裸整数,而是自描述的 `Timestamp`(Unix 秒)或 `TimestampMilli`(毫秒)类型(请求与响应共用的类型是例外,见下方警告)。它们序列化为本地时区的 RFC3339 字符串,因此 JSON、日志以及面向 LLM 的输出都直接可读;原始 epoch 仍只需一次方法调用即可取到。
-- **序列化(出站)**:非零值序列化为带引号的 RFC3339 字符串(`TimestampMilli` 用 RFC3339Nano 以保留毫秒精度)。零值序列化为裸整数 `0`——一个"未设置"哨兵,而非 1970 年的日期,并被 `json:",omitempty"` 丢弃。
-- **反序列化(入站)**:既兼容数字 epoch(线上原始形态),也兼容 RFC3339 字符串(使序列化后的值可无损往返),还接受 `null`(→ 0)。
+- **序列化(出站)**:非零值序列化为带引号的 RFC3339 字符串(`TimestampMilli` 用 RFC3339Nano 以保留毫秒精度)。零值序列化为裸整数 `0`——一个"未设置"哨兵,而非 1970 年的日期,并被 `json:",omitempty"` 丢弃。
+- **反序列化(入站)**:既兼容数字 epoch(线上原始形态),也兼容 RFC3339 字符串(使序列化后的值可无损往返),还接受 `null`(→ 0)。
```go
inc := list.Items[0]
@@ -255,14 +263,14 @@ zero := inc.StartTime.IsZero() // 是否为未设置哨兵
| 方法 | 返回 | 说明 |
|------|------|------|
| `.Time()` | `time.Time` | 取为标准时间值 |
-| `.Unix()` | `int64` | 取原始 wire 值(`Timestamp` 为秒,`TimestampMilli` 为毫秒) |
+| `.Unix()` | `int64` | 取原始 wire 值(`Timestamp` 为秒,`TimestampMilli` 为毫秒) |
| `.IsZero()` | `bool` | 是否为未设置哨兵(0) |
-| `.String()` | `string` | 本地时区 RFC3339,未设置时为 `"0"` |
+| `.String()` | `string` | 本地时区 RFC3339,未设置时为 `"0"` |
<Warning>
-**请求侧时间字段仍为 `int64`**,API 在 wire 上要求数字 epoch。注意:多数接口取**秒**,但 RUM 与 webhook 历史相关接口取**毫秒**。
+**请求侧时间字段仍为 `int64`**,API 在 wire 上要求数字 epoch。注意:多数接口取**秒**,但 RUM 与 webhook 历史相关接口取**毫秒**。
-**请求与响应共用的类型同样如此**:`AlertRuleV2`(`AlertRules.ReadInfoV2` / `WriteCreateV2` / `WriteUpdateV2` 的返回类型,对应 `POST /monit/rule/v2/info`、`/v2/create`、`/v2/update`)的 `created_at` / `updated_at` 在 SDK 中仍是裸 `int64`(Unix 秒,带 `omitempty`),而不是 `Timestamp`。这类字段不支持 `Unix()` / `String()` / `IsZero()`,需要自行把秒值转成时间;按 `Timestamp` 示例写 `rule.UpdatedAt.Unix()` 会编译不过。
+**请求与响应共用的类型同样如此**:`AlertRuleV2`(`AlertRules.ReadInfoV2` / `WriteCreateV2` / `WriteUpdateV2` 的返回类型,对应 `POST /monit/rule/v2/info`、`/v2/create`、`/v2/update`)的 `created_at` / `updated_at` 在 SDK 中仍是裸 `int64`(Unix 秒,带 `omitempty`),而不是 `Timestamp`。这类字段不支持 `Unix()` / `String()` / `IsZero()`,需要自行把秒值转成时间;按 `Timestamp` 示例写 `rule.UpdatedAt.Unix()` 会编译不过。
</Warning>
<Note>
@@ -277,17 +285,15 @@ zero := inc.StartTime.IsZero() // 是否为未设置哨兵
## 分页
----
-
-所有列表接口共享 `ListOptions`,将其内嵌在请求结构体中即可。零值会被省略,不会覆盖服务端默认值(后端默认 `p=1`、`limit=20`)。
+所有列表接口共享 `ListOptions`,将其内嵌在请求结构体中即可。零值会被省略,不会覆盖服务端默认值(后端默认 `p=1`、`limit=20`)。
| 字段 | 类型 | wire 字段 | 说明 |
|------|------|-----------|------|
| `Page` | `int` | `p` | 从 1 开始的页码 |
| `Limit` | `int` | `limit` | 每页返回条数上限 |
-| `SearchAfterCtx` | `string` | `search_after_ctx` | 上一页回显的不透明游标,用于深分页;回传它即可取下一页 |
+| `SearchAfterCtx` | `string` | `search_after_ctx` | 上一页回显的不透明游标,用于深分页;回传它即可取下一页 |
-响应侧,`*Response` 携带 `Total`、`HasNextPage` 与 `SearchAfterCtx`。推荐用 search-after 游标逐页遍历:
+响应侧,`*Response` 携带 `Total`、`HasNextPage` 与 `SearchAfterCtx`。推荐用 search-after 游标逐页遍历:
```go
req := &flashduty.ListIncidentsRequest{
@@ -315,14 +321,12 @@ for page := 0; page < 100; page++ {
## 错误处理
----
-
-Flashduty API 返回的未成功调用——无论是信封中携带了错误,还是 HTTP 状态非 2xx——都会返回 `*ErrorResponse`。它带有 `Code`、`Message`、可选的 `Reason` 与 `RequestID` 字段,排障时把 `RequestID` 提供给支持团队即可定位。`Reason` 携带服务端给出的可选原因(信封内的 `DutyError` 同样带有该字段,JSON 字段为 `reason`,omitempty);非空时它也会被追加到错误字符串末尾,形如 `, reason X`。
+Flashduty API 返回的未成功调用——无论是信封中携带了错误,还是 HTTP 状态非 2xx——都会返回 `*ErrorResponse`。它带有 `Code`、`Message`、可选的 `Reason` 与 `RequestID` 字段,排障时把 `RequestID` 提供给支持团队即可定位。`Reason` 携带服务端给出的可选原因(信封内的 `DutyError` 同样带有该字段,JSON 字段为 `reason`,omitempty);非空时它也会被追加到错误字符串末尾,形如 `, reason X`。
-当 API 返回 429 时,错误被提升为 `*RateLimitError`:它内嵌 `*ErrorResponse`(所以 `errors.As` 取 `*ErrorResponse` 仍然成立),并额外带上 `RetryAfter` 提示。
+当 API 返回 429 时,错误被提升为 `*RateLimitError`:它内嵌 `*ErrorResponse`(所以 `errors.As` 取 `*ErrorResponse` 仍然成立),并额外带上 `RetryAfter` 提示。`Code` 与 Open API 的[错误码列表](/zh/openapi/introduction#错误码列表)一一对应。
<Note>
-对于**生成接口**,如果你收到的是带非 JSON 响应体的非 2xx 响应,SDK 会返回普通 `error`,而不是 `*ErrorResponse`。这表示响应来自网关、负载均衡器或代理等中间层,通常是请求超过了中间层超时。你可以重试请求,或将耗时较长的批量请求拆分为更小的批次;不要假定 `errors.As(err, &apiErr)` 能匹配此类错误。
+对于**生成接口**,如果您收到的是带非 JSON 响应体的非 2xx 响应,SDK 会返回普通 `error`,而不是 `*ErrorResponse`。这表示响应来自网关、负载均衡器或代理等中间层,通常是请求超过了中间层超时。您可以重试请求,或将耗时较长的批量请求拆分为更小的批次;不要假定 `errors.As(err, &apiErr)` 能匹配此类错误。
手写方法 `client.DataSources.ReadPrometheusLabelValues` 是例外:它不解析信封,而是把非 2xx 的原始响应体按原文放进 `*ErrorResponse.Message` 返回——平台的 `text/plain` 4xx/5xx 与数据源自身的 JSON 错误形态一视同仁,429 仍提升为 `*RateLimitError`。因此在这个方法上 `errors.As(err, &apiErr)` 是成立的,只是 `Code` 通常为空,需要读 `Message` 与 `Response.StatusCode` 判断原因。
</Note>
@@ -346,7 +350,7 @@ if errors.As(err, &apiErr) {
}
```
-类型化判定函数能省去字符串比较,并能穿透被包裹的错误(内部用 `errors.As`):
+类型化判定函数能省去字符串比较,并能穿透被包裹的错误(内部用 `errors.As`):
| 辅助函数 | 说明 |
|----------|------|
@@ -355,7 +359,7 @@ if errors.As(err, &apiErr) {
| `IsUnauthorized(err)` | 是否为未授权 |
| `IsAccessDenied(err)` | 是否为访问被拒 |
| `IsInvalidParameter(err)` | 是否为参数非法 |
-| `ErrorCodeOf(err)` | 提取错误码,返回 `ErrorCode` 常量(如 `ErrorCodeAccessDenied`、`ErrorCodeUnauthorized`) |
+| `ErrorCodeOf(err)` | 提取错误码,返回 `ErrorCode` 常量(如 `ErrorCodeAccessDenied`、`ErrorCodeUnauthorized`) |
```go
switch flashduty.ErrorCodeOf(err) {
@@ -366,16 +370,14 @@ case flashduty.ErrorCodeAccessDenied, flashduty.ErrorCodeUnauthorized:
## 重试
----
-
核心客户端**不内置**自动重试。请通过传输层组合可选的 `retry` 子包——一个安全默认的重试型 `http.RoundTripper`。
`github.com/flashcatcloud/go-flashduty/retry` 的特性:
-- **重试条件**:HTTP 429、任意 5xx(状态码 ≥ 500),以及传输错误。其他 4xx 与所有 2xx/3xx 立即返回。
-- **退避策略**:确定性指数退避(`MinWait * 2^attempt`,每次上限为 `MaxWait`);无随机抖动。存在合法的整数 `Retry-After` 头时,以其为准(同样不超过 `MaxWait`)。
-- **安全回放**:仅当请求体可回放(`req.Body` 为 nil 或 `req.GetBody` 非空)时才重试,每次重试都在请求的克隆上重建请求体,绝不修改调用方的原始 `*http.Request`。SDK 构造的所有请求都设置了 `GetBody`,因此 POST 请求体都可安全回放。
-- **尊重取消**:等待退避期间若请求 context 被取消,立即返回 context 错误。
+- **重试条件**:HTTP 429、任意 5xx(状态码 ≥ 500),以及传输错误。其他 4xx 与所有 2xx/3xx 立即返回。
+- **退避策略**:确定性指数退避(`MinWait * 2^attempt`,每次上限为 `MaxWait`);无随机抖动。存在合法的整数 `Retry-After` 头时,以其为准(同样不超过 `MaxWait`)。
+- **安全回放**:仅当请求体可回放(`req.Body` 为 nil 或 `req.GetBody` 非空)时才重试,每次重试都在请求的克隆上重建请求体,绝不修改调用方的原始 `*http.Request`。SDK 构造的所有请求都设置了 `GetBody`,因此 POST 请求体都可安全回放。
+- **尊重取消**:等待退避期间若请求 context 被取消,立即返回 context 错误。
```go
import "github.com/flashcatcloud/go-flashduty/retry"
@@ -389,22 +391,20 @@ client, err := flashduty.NewClient("YOUR_APP_KEY",
| 配置项 | 默认值 | 说明 |
|--------|--------|------|
-| `retry.WithMaxRetries(n int)` | `3` | 首次尝试之后的最大重试次数;负数表示禁用重试 |
+| `retry.WithMaxRetries(n int)` | `3` | 首次尝试之后的最大重试次数;负数表示禁用重试 |
| `retry.WithMinWait(d time.Duration)` | `500ms` | 基础退避时长(首次重试前的等待) |
| `retry.WithMaxWait(d time.Duration)` | `30s` | 单次退避等待的上限 |
| `retry.WithBase(base http.RoundTripper)` | `http.DefaultTransport` | 底层实际执行请求的 RoundTripper |
<Tip>
-`retry` 子包是纯 `net/http` 实现,刻意不导入父级 `flashduty` 包,因此永远不会引入循环依赖。`retry.New()` 与 `&retry.Transport{}`(零值)都开箱即用。
+`retry` 子包是纯 `net/http` 实现,刻意不导入父级 `flashduty` 包,因此永远不会引入循环依赖。`retry.New()` 与 `&retry.Transport{}`(零值)都开箱即用。
</Tip>
## 流式导出
----
-
-`client.Sessions.Export` 用于导出一个 AI SRE 会话的完整事件转录,返回的是 `io.ReadCloser`(NDJSON 流,`application/x-ndjson`),而非 JSON 信封。首行始终是一条 `session_meta` 信封,其后每行是一个会话事件;当 `req.IncludeSubagents` 为 true 时,每条 `subagent_dispatch` 行后会跟随子会话自身的完整事件流。
+`client.Sessions.Export` 用于导出一个 AI SRE 会话的完整事件转录,返回的是 `io.ReadCloser`(NDJSON 流,`application/x-ndjson`),而非 JSON 信封。首行始终是一条 `session_meta` 信封,其后每行是一个会话事件;当 `req.IncludeSubagents` 为 true 时,每条 `subagent_dispatch` 行后会跟随子会话自身的完整事件流。
-由于响应体可能很大,应当逐行读取并直接写入文件,**不要**把整段转录缓冲进内存。返回的 `io.ReadCloser` 是活动 HTTP 响应体,由调用方持有并**必须** `Close`(`defer` 关闭即正确)。配合 `NewExportScanner` 可按行扫描,`DecodeExportLine` 可将一行解码为 `ExportLine`:
+由于响应体可能很大,应当逐行读取并直接写入文件,**不要**把整段转录缓冲进内存。返回的 `io.ReadCloser` 是活动 HTTP 响应体,由调用方持有并**必须** `Close`(`defer` 关闭即正确)。配合 `NewExportScanner` 可按行扫描,`DecodeExportLine` 可将一行解码为 `ExportLine`:
```go
rc, _, err := client.Sessions.Export(ctx, &flashduty.SessionExportRequest{
@@ -431,5 +431,5 @@ return sc.Err()
```
<Note>
-`NewExportScanner` 配置的单行缓冲区足以容纳转录中较宽的事件行(如 tool 输出、LLM 调用),不受默认 64KB token 上限限制。任何非 2xx 状态下,响应体仍是常规 JSON 错误信封——`Export` 会读取并关闭它,返回类型化错误(`*ErrorResponse`,429 时为 `*RateLimitError`),此时 `io.ReadCloser` 为 `nil`,与其他生成接口行为一致。
+`NewExportScanner` 配置的单行缓冲区足以容纳转录中较宽的事件行(如 tool 输出、LLM 调用),不受默认 64KB token 上限限制。任何非 2xx 状态下,响应体仍是常规 JSON 错误信封——`Export` 会读取并关闭它,返回类型化错误(`*ErrorResponse`,429 时为 `*RateLimitError`),此时 `io.ReadCloser` 为 `nil`,与其他生成接口行为一致。
</Note>
diff --git a/zh/developer/mcp-server.mdx b/zh/developer/mcp-server.mdx
index 942cd6aa..d6af585c 100644
--- a/zh/developer/mcp-server.mdx
+++ b/zh/developer/mcp-server.mdx
@@ -1,6 +1,6 @@
---
title: MCP Server
-sidebarTitle: MCP Server
+sidebarTitle: "Flashduty MCP Server"
description: "通过 MCP 协议将 Flashduty API 接入 AI 工具,在 Cursor、Claude 等客户端中实现智能化故障管理与自动化。"
keywords: ["MCP", "Model Context Protocol", "AI", "Claude", "Cursor", "Flashduty", "故障管理"]
---
@@ -13,8 +13,6 @@ Flashduty MCP Server 是一个 [Model Context Protocol (MCP)](https://modelconte
## 适用场景
----
-
<CardGroup cols={2}>
<Card title="自动化故障流程" icon="robot">
将 Flashduty 的故障创建、确认、关闭等操作交给 AI 编排,串联到您的运维工作流中。
@@ -32,8 +30,6 @@ Flashduty MCP Server 是一个 [Model Context Protocol (MCP)](https://modelconte
## 部署方式
----
-
Flashduty MCP Server 提供三种部署方式,您可以根据 MCP 客户端的能力与运行环境选择。
<Tabs>
@@ -131,8 +127,6 @@ Flashduty MCP Server 提供三种部署方式,您可以根据 MCP 客户端的
## 认证与传输
----
-
| 项目 | 说明 |
| --- | --- |
| 认证(本地) | 通过 `FLASHDUTY_APP_KEY` 环境变量或 `--app-key` 命令行参数提供 Flashduty APP Key。 |
@@ -161,8 +155,6 @@ Flashduty MCP Server 提供三种部署方式,您可以根据 MCP 客户端的
## 配置项
----
-
Flashduty MCP Server 支持工具集裁剪、只读模式、输出格式等配置,以适配不同使用场景。本地部署可通过环境变量或命令行参数配置;远程服务可通过在 URL 上追加查询参数动态配置。
### 环境变量
@@ -241,8 +233,6 @@ docker run -i --rm \
## 工具集与工具
----
-
服务端共提供 **8 个工具集、23 个工具**,默认全部启用。下表为各工具集概览:
| 工具集 | 工具数 | 说明 |
@@ -366,8 +356,6 @@ docker run -i --rm \
## 相关资源
----
-
<CardGroup cols={2}>
<Card title="go-flashduty SDK" icon="code" href="/zh/developer/go-sdk">
MCP Server 底层依赖的 Go SDK,覆盖 Flashduty 全部开放 API。
diff --git a/zh/home.mdx b/zh/home.mdx
index eb13d9f9..aa830bfe 100644
--- a/zh/home.mdx
+++ b/zh/home.mdx
@@ -1,202 +1,125 @@
---
title: Flashduty
-description: 一站式可观测性平台,涵盖 On-call 告警管理、RUM 用户体验监控和 Monitors 统一监控
-keywords: ["Flashduty", "可观测性平台", "On-call", "RUM", "Monitors"]
+description: Flashduty 官方文档,涵盖 AI SRE 自治排障、On-call 告警响应、RUM 用户体验监控和 Monitors 告警引擎
+keywords: ["Flashduty", "可观测性平台", "AI SRE", "On-call", "RUM", "Monitors"]
sidebarTitle: 概览
---
-<video
- controls
- autoPlay
- muted
- playsInline
- preload="metadata"
- className="w-full aspect-video rounded-xl"
- src="https://static.flashcat.cloud/flashduty-docs/videos/film-zh-7229cb04.mp4"
- poster="https://static.flashcat.cloud/videos/flashduty/flashduty-film-v9-zh.jpg"
- aria-label="Flashduty 产品介绍视频"
-></video>
+Flashduty 是面向 DevOps、SRE 和运维团队的一站式可观测性平台,覆盖监控、告警到故障响应的完整流程。从下面挑一个任务开始,或在顶部搜索框(Ctrl K)直接搜索。
-## 产品矩阵
+## 从这里开始
-Flashduty 是面向 DevOps、SRE 和运维团队的一站式可观测性平台,提供从监控、告警到事件响应的完整解决方案。
-
-<CardGroup cols={2}>
- <Card title="AI SRE" icon="robot" href="./ai-sre">
- 自治排障 Agent
+<CardGroup cols={3}>
+ <Card title="接入第一条告警" icon="bell" href="/zh/on-call/quickstart/quickstart">
+ 跑通从告警接入到电话通知的完整流程
</Card>
- <Card title="On-call" icon="bell" href="./on-call/quickstart/quickstart">
- 加速企业告警响应
+ <Card title="配置值班与分派" icon="calendar" href="/zh/on-call/configuration/schedule">
+ 设置值班表,再用分派策略把故障通知到值班人
</Card>
- <Card title="RUM" icon="chart-line" href="./rum/quickstart/quickstart">
- 真实用户体验监控
+ <Card title="查找告警集成" icon="plug" href="/zh/on-call/integration/alert-integration/overview">
+ 按名称查找监控工具或云平台的接入文档
</Card>
- <Card title="Monitors" icon="desktop" href="./monitors/quickstart/quickstart">
- 统一监控管理平台
+ <Card title="开始 AI 排障" icon="robot" href="/zh/ai-sre/quickstart">
+ 完成第一次 AI SRE 排障
+ </Card>
+ <Card title="接入 RUM SDK" icon="chart-line" href="/zh/rum/quickstart/quickstart">
+ 为 Web、移动端或小程序接入真实用户监控
+ </Card>
+ <Card title="创建告警规则" icon="desktop" href="/zh/monitors/quickstart/quickstart">
+ 部署 monitedge 并创建首条 Monitors 告警规则
</Card>
</CardGroup>
----
+## 产品
-## AI SRE 自治排障
+### AI SRE:自治排障 Agent
-对话式的自治 SRE Agent:用自然语言下达指令,AI 自主调查故障、排查根因、调用工具,并把运维知识沉淀复用。与 Flashduty 故障响应体系及 IM 协作深度联动。
+用自然语言下达指令,AI 自主调查故障、排查根因、调用工具,并把运维知识沉淀复用;与 Flashduty 故障响应体系及 IM 协作联动。
-<AccordionGroup>
- <Accordion title="核心能力" icon="star">
- - **对话即排障**:Agent 自主规划、调用工具、流式输出调查过程与结论
- - **与故障响应联动**:从故障或作战室一键拉起会话,携带上下文进入排查
- - **知识沉淀与复用**:以 DUTY.md 为入口的知识承载长期运维上下文
- - **可扩展工具生态**:Skill、MCP、A2A Agent 与自托管 Runner
- </Accordion>
+- **对话即排障**:Agent 自主规划、调用工具、流式输出调查过程与结论
+- **与故障响应联动**:从故障或作战室一键拉起会话,携带上下文进入排查
+- **知识沉淀与复用**:以 DUTY.md 为入口的知识承载长期运维上下文
+- **可扩展工具生态**:Skill、MCP、A2A Agent 与自托管 Runner
- <Accordion title="适用场景" icon="bullseye">
- - 在控制台或 IM 群里随手发起排查,团队全程可见
- - 故障作战室自动跑初步诊断并回贴结论
- - 用 /insight 复盘近 30 天会话,量化运维摩擦
- - 沉淀可复用的 runbook 与排障流程
- </Accordion>
-</AccordionGroup>
+AI SRE 面向 On-call 专业版及以上订阅的账户开放,按实际用量计费,详见[计费规则](/zh/compliance/ai-sre-credit-package-purchase-agreement)。
-<Note>
-AI SRE 面向 On-call 专业版及以上订阅的账户开放,无需申请。自 2026 年 9 月 16 日 8 点(北京时间)起按实际用量计费,详见 [AI SRE 产品介绍](./ai-sre) 与[计费规则](./compliance/ai-sre-credit-package-purchase-agreement)。
-</Note>
+[产品介绍](/zh/ai-sre) · [产品概述](/zh/ai-sre/overview) · [快速开始](/zh/ai-sre/quickstart)
-<CardGroup cols={2}>
- <Card title="产品概述" icon="rocket" href="./ai-sre/overview">
- 了解能力全景与控制台导航
- </Card>
- <Card title="快速开始" icon="comments" href="./ai-sre/sessions">
- 新建会话,开始对话式排障
- </Card>
-</CardGroup>
+### On-call:告警响应
----
+降噪、值班、分派、升级、触达,帮助团队快速响应和处理生产故障。
-## On-call 告警管理
-
-一站式智能化的告警响应平台:降噪、值班、分派、升级、触达,帮助团队快速响应和处理生产事件。
-
-<AccordionGroup>
- <Accordion title="核心能力" icon="star">
- - **智能降噪**:告警聚合、抑制、去重,减少 90% 的告警噪音
- - **灵活分派**:多级升级、动态路由、轮询值班
- - **多渠道通知**:飞书、钉钉、企业微信、Slack、电话、短信
- - **丰富集成**:267 个告警源原生支持
- </Accordion>
-
- <Accordion title="适用场景" icon="bullseye">
- - 构建 7x24 值班体系,保障服务可用性
- - 聚合多源告警,统一事件管理入口
- - 建立告警升级机制,确保问题及时响应
- - 分析告警数据,持续优化监控质量
- </Accordion>
-</AccordionGroup>
+- **降噪**:告警聚合、抑制、去重,减少重复打扰
+- **灵活分派**:多级升级、动态路由、轮询值班
+- **多渠道通知**:飞书、钉钉、企业微信、Slack、Microsoft Teams、电话、短信、邮件
+- **丰富集成**:290+ 告警集成,覆盖主流监控工具与云平台
-<CardGroup cols={2}>
- <Card title="快速开始" icon="rocket" href="./on-call/quickstart/quickstart">
- 5 分钟完成首个告警集成
- </Card>
- <Card title="产品对比" icon="scale-balanced" href="./on-call/comparison/vs-pagerduty">
- 与 PagerDuty / Opsgenie 深度对比
- </Card>
-</CardGroup>
+[产品介绍](/zh/on-call) · [入门指南](/zh/on-call/quickstart/quickstart) · [与 PagerDuty / Opsgenie 对比](/zh/on-call/comparison/vs-pagerduty)
----
+### RUM:真实用户监控
-## RUM 用户体验监控
-
-Real User Monitoring(真实用户监控)帮助您了解真实用户如何体验您的应用,快速定位和解决前端问题。
-
-<AccordionGroup>
- <Accordion title="核心能力" icon="star">
- - **性能监控**:页面加载、资源加载、API 调用全链路追踪
- - **错误追踪**:JS 错误、网络错误自动采集和聚合
- - **会话重放**:还原用户操作路径,快速复现问题
- - **自定义指标**:上报业务自定义指标,满足个性化需求
- </Accordion>
-
- <Accordion title="适用场景" icon="bullseye">
- - 监控 Web 应用的核心性能指标(LCP、FID、CLS)
- - 追踪和分析前端错误,提升应用稳定性
- - 分析用户行为路径,优化产品体验
- - 关联后端 Trace,实现全链路可观测
- </Accordion>
-</AccordionGroup>
+了解真实用户如何体验您的应用,快速定位和解决前端问题。
-<CardGroup cols={2}>
- <Card title="快速开始" icon="rocket" href="./rum/quickstart/quickstart">
- 接入 SDK 开始监控
- </Card>
- <Card title="性能分析" icon="gauge-high" href="./rum/performance/overview">
- 了解性能指标和分析方法
- </Card>
-</CardGroup>
+- **性能监控**:页面加载、资源加载、API 调用全链路追踪
+- **错误追踪**:JS 错误、网络错误自动采集和聚合
+- **会话重放**:还原用户操作路径,快速复现问题
+- **自定义指标**:上报业务自定义指标
----
+[产品介绍](/zh/rum) · [入门指南](/zh/rum/quickstart/quickstart) · [性能监控](/zh/rum/performance/overview)
-## Monitors 监控管理
+### Monitors:告警引擎
把分散在各网络域的数据源统一接入,集中管理告警规则;规则由部署在数据侧的告警引擎本地评估,产生的事件直接进入 On-call 响应流程。
-<AccordionGroup>
- <Accordion title="核心能力" icon="star">
- - **多类型数据源**:统一接入 Prometheus、VictoriaLogs、Loki、Elasticsearch、SLS、腾讯云 CLS 等监控与日志数据源,以及 MySQL、PostgreSQL、Oracle、ClickHouse、Redis、Kafka、MongoDB 等数据库与中间件
- - **数据侧本地评估**:`monitedge` 部署在您的私有网络内,从 SaaS 同步规则后本地查询数据源并判定,数据不出网;同一集群的多个引擎实例自动分片分摊规则
- - **三种判定方式**:阈值判定、数据缺失、数据存在,支持连续命中与累计命中,以及按级别区分的恢复语义
- - **统一管理视图**:树形分组集中管理规则,提供概览、活跃告警、查询工作台、实体树与仪表盘,并支持规则导入导出与变更审计
- </Accordion>
-
- <Accordion title="适用场景" icon="bullseye">
- - 监控系统分散在多个云、多个机房,需要统一接入并集中管理告警规则
- - 数据源位于私有网络、不允许公网访问,希望告警评估留在本地
- - 用一套流程统一管理 Prometheus、日志、数据库与中间件等多类型告警
- - 规则产生的告警事件直接进入 Flashduty 的聚合、分派与升级流程
- </Accordion>
-</AccordionGroup>
+- **多类型数据源**:Prometheus、VictoriaLogs、Loki、Elasticsearch、SLS、腾讯云 CLS 等监控与日志数据源,以及 MySQL、PostgreSQL、Oracle、ClickHouse、Redis、Kafka、MongoDB 等数据库与中间件
+- **数据侧本地评估**:`monitedge` 部署在您的私有网络内,从 SaaS 同步规则后本地查询数据源并判定,数据不出网;同一集群的多个引擎实例自动分片分摊规则
+- **三种判定方式**:阈值判定、数据缺失、数据存在,支持连续命中与累计命中,以及按级别区分的恢复语义
+- **统一管理视图**:树形分组集中管理规则,提供概览、活跃告警、查询工作台、实体树与仪表盘,并支持规则导入导出与变更审计
-<CardGroup cols={2}>
- <Card title="快速开始" icon="rocket" href="./monitors/quickstart/quickstart">
- 创建首个监控任务
- </Card>
- <Card title="常见问题" icon="circle-question" href="./monitors/faq/faq">
- 使用中的常见问题解答
- </Card>
-</CardGroup>
+[产品介绍](/zh/monitors) · [入门指南](/zh/monitors/quickstart/quickstart) · [常见问题](/zh/monitors/faq/faq)
----
+## 产品介绍视频
+
+<video
+ controls
+ muted
+ playsInline
+ preload="metadata"
+ className="w-full aspect-video rounded-xl"
+ src="https://static.flashcat.cloud/flashduty-docs/videos/film-zh-7229cb04.mp4"
+ poster="https://static.flashcat.cloud/videos/flashduty/flashduty-film-v9-zh.jpg"
+ aria-label="Flashduty 产品介绍视频"
+></video>
## 开发者
-通过 Open API 和 Webhook 集成 Flashduty,实现自动化运维和二次开发。
+通过 Open API、CLI、SDK 和 Webhook 集成 Flashduty,实现自动化运维和二次开发。
<CardGroup cols={3}>
- <Card title="快速入门" icon="rocket" href="/zh/openapi/introduction">
+ <Card title="Open API 快速入门" icon="rocket" href="/zh/openapi/introduction">
认证方式、请求规范、错误处理
</Card>
- <Card title="API 总览" icon="list" href="/zh/openapi/api-catalog">
- 全部 354 个接口,按模块分类
+ <Card title="API 目录" icon="list" href="/zh/openapi/api-catalog">
+ 全部接口,按模块分类
</Card>
- <Card title="关于分页" icon="file-lines" href="/zh/openapi/pagination">
- 传统分页与游标分页机制
+ <Card title="开发者工具" icon="code" href="/zh/developer/overview">
+ CLI、Go SDK、MCP Server 与 Terraform Provider
</Card>
</CardGroup>
----
-
## 联系我们
<CardGroup cols={2}>
<Card title="技术支持" icon="headset">
扫码添加企业微信,获取一对一技术支持
- <img src="https://docs-cdn.flashcat.cloud/images/png/447591.png" alt="技术支持企业微信" width="100" />
+ <img src="https://docs-cdn.flashcat.cloud/images/png/447591.png" alt="技术支持企业微信二维码" width="100" />
</Card>
<Card title="商务合作" icon="handshake">
扫码添加商务经理企业微信
- <img src="https://docs-cdn.flashcat.cloud/images/png/447590.png" alt="商务经理企业微信" width="100" />
+ <img src="https://docs-cdn.flashcat.cloud/images/png/447590.png" alt="商务经理企业微信二维码" width="100" />
</Card>
<Card title="控制台反馈" icon="comment" href="https://console.flashcat.cloud">
- 登录控制台左下角,提交反馈建议
+ 登录控制台,在左下角提交反馈建议
</Card>
<Card title="邮件联系" icon="envelope" href="mailto:support@flashcat.cloud">
support@flashcat.cloud
diff --git a/zh/monitors.mdx b/zh/monitors.mdx
index 7b9d14cf..282dc445 100644
--- a/zh/monitors.mdx
+++ b/zh/monitors.mdx
@@ -99,6 +99,13 @@ Monitors 支持集群部署,保证告警引擎的高可用:
</Card>
</CardGroup>
+## 适用场景
+
+- 监控系统分散在多个云、多个机房,需要统一接入并集中管理告警规则
+- 数据源位于私有网络、不允许公网访问,希望告警评估留在本地
+- 用一套流程统一管理 Prometheus、日志、数据库与中间件等多类型告警
+- 规则产生的告警事件直接进入 Flashduty 的聚合、分派与升级流程
+
## 快速开始
<CardGroup cols={2}>
diff --git a/zh/monitors/alert-rules/clickhouse.mdx b/zh/monitors/alert-rules/clickhouse.mdx
index 5a72a171..d8a169bc 100644
--- a/zh/monitors/alert-rules/clickhouse.mdx
+++ b/zh/monitors/alert-rules/clickhouse.mdx
@@ -14,29 +14,29 @@ Monitors 支持使用标准 SQL 语法对 ClickHouse 进行查询,并根据查
| **字段处理** | 所有字段名自动转换为小写,配置时请使用小写字母 |
| **类型转换** | 建议使用 `toString()`、`toFloat64()` 等函数转换复杂类型 |
-## 1. 阈值判定模式
+## 阈值判定模式
此模式适用于需要对聚合后的数值进行阈值比对的场景。
### 配置方式
1. **查询语句**:编写 SQL 聚合查询,返回数值列和(可选的)标签列。
- - 示例:统计最近 5 分钟内,各服务的错误日志数量。
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE timestamp > now() - INTERVAL 5 MINUTE AND level = 'error'
- GROUP BY service_name
- ```
+ - 示例:统计最近 5 分钟内,各服务的错误日志数量。
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE timestamp > now() - INTERVAL 5 MINUTE AND level = 'error'
+ GROUP BY service_name
+ ```
2. **字段映射**:
- - **值字段**:选择 `error_cnt`,用于阈值判定。
- - **标签字段**:选择 `service_name`,用于标识告警对象。明确选择标签字段后,其他非值字段会作为附加信息随告警携带。
- - 详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
+ - **值字段**:选择 `error_cnt`,用于阈值判定。
+ - **标签字段**:选择 `service_name`,用于标识告警对象。明确选择标签字段后,其他非值字段会作为附加信息随告警携带。
+ - 详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
3. **阈值条件**:
- - 使用 `$A.field_name` 引用数值。
- - 示例:`Critical: $A.error_cnt > 50`,`Warning: $A.error_cnt > 10`。
+ - 使用 `$A.field_name` 引用数值。
+ - 示例:`Critical: $A.error_cnt > 50`,`Warning: $A.error_cnt > 10`。
### 工作原理
@@ -51,23 +51,23 @@ Monitors 按标签字段区分告警对象,并使用值字段进行阈值判
| **恢复查询** | 独立 SQL 用于恢复判定,支持 `${label_name}` 变量 |
| **手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 2. 数据存在模式
+## 数据存在模式
此模式适用于将过滤逻辑直接写在 SQL 中的场景。
### 配置方式
1. **查询语句**:在 SQL 中使用 `HAVING` 子句直接过滤出异常数据。
- - 示例:直接查询错误数超过 50 的服务。
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE timestamp > now() - INTERVAL 5 MINUTE AND level = 'error'
- GROUP BY service_name
- HAVING count(*) > 50
- ```
+ - 示例:直接查询错误数超过 50 的服务。
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE timestamp > now() - INTERVAL 5 MINUTE AND level = 'error'
+ GROUP BY service_name
+ HAVING count(*) > 50
+ ```
2. **判定规则**:只要 SQL 查询返回了数据,即触发告警。
### 优缺点分析
@@ -83,20 +83,20 @@ Monitors 按标签字段区分告警对象,并使用值字段进行阈值判
- **恢复查询**:支持配置额外的查询语句用于辅助判断恢复状态
- **手工关闭**:告警保持活动,直到用户手工关闭
-## 3. 数据缺失模式
+## 数据缺失模式
此模式用于监控"预期应该有数据,但实际没有数据"的场景。
### 配置方式
1. **查询语句**:编写一个预期应该持续返回数据的 SQL 查询。
- - 示例:查询所有探针的心跳上报。
- ```sql
- SELECT probe_id, max(timestamp) as last_seen
- FROM probe_heartbeat
- WHERE timestamp > now() - INTERVAL 5 MINUTE
- GROUP BY probe_id
- ```
+ - 示例:查询所有探针的心跳上报。
+ ```sql
+ SELECT probe_id, max(timestamp) as last_seen
+ FROM probe_heartbeat
+ WHERE timestamp > now() - INTERVAL 5 MINUTE
+ GROUP BY probe_id
+ ```
2. **判定规则**:如果某个 `probe_id` 在之前的周期中出现过,但在当前及连续 N 个周期中查不到数据,则触发"数据缺失"告警。
### 恢复逻辑
@@ -109,7 +109,7 @@ Monitors 按标签字段区分告警对象,并使用值字段进行阈值判
| **数据恢复或超时后自动结束** | 数据重新出现或达到自动关闭时间后,告警自动结束。自动关闭时间单位为秒,最小为 1;仅开启「之前查到过数据,现在查不到了」模式时可选 |
| **仅允许手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 4. 最佳实践
+## 最佳实践
<AccordionGroup>
<Accordion title="类型转换">
diff --git a/zh/monitors/alert-rules/description-template.mdx b/zh/monitors/alert-rules/description-template.mdx
index ea295a13..d3e0c112 100644
--- a/zh/monitors/alert-rules/description-template.mdx
+++ b/zh/monitors/alert-rules/description-template.mdx
@@ -4,7 +4,7 @@ description: "配置 Monitors 告警规则备注描述的 Go Template 变量、
keywords: ["Description 模板", "告警规则", "备注描述", "Go Template", "Sprig", "关联查询"]
---
-Monitors 告警规则的 **备注描述(Description)** 用于定义告警和恢复事件中的说明文本。你可以使用 Go `text/template` 引用告警标签、查询值、关联查询结果和安全的 Sprig 函数,生成 Text 或 Markdown 格式的描述内容。
+Monitors 告警规则的 **备注描述(Description)** 用于定义告警和恢复事件中的说明文本。您可以使用 Go `text/template` 引用告警标签、查询值、关联查询结果和安全的 Sprig 函数,生成 Text 或 Markdown 格式的描述内容。
<Warning>
本文描述的基础模板变量、Sprig 函数名和标签增强后再渲染 `Description` 的行为需要 monit-edge `v0.42.0` 或以上版本。通过 `$annotations` 读取 `$<查询名称>.<字段名称>` 格式的查询附加信息需要 monit-edge `v0.53.0` 或以上版本;使用该能力前,请先升级告警引擎。
diff --git a/zh/monitors/alert-rules/elasticsearch.mdx b/zh/monitors/alert-rules/elasticsearch.mdx
index 0325aeaa..9bee2cb7 100644
--- a/zh/monitors/alert-rules/elasticsearch.mdx
+++ b/zh/monitors/alert-rules/elasticsearch.mdx
@@ -21,28 +21,28 @@ Monitors 通过 ElasticSearch SQL 功能实现对日志和指标数据的监控
建议在 SQL 中使用明确且稳定的列别名,并在字段映射中使用完全相同的大小写,避免查询字段变更后无法匹配。
</Tip>
-## 1. 阈值判定模式 (Threshold)
+## 阈值判定模式 (Threshold)
此模式适用于需要对聚合后的数值进行阈值比对的场景,例如监控"最近 5 分钟错误日志数量"。
### 配置方式
1. **查询语句**:编写 SQL 聚合查询,返回数值列和(可选的)分组列。
- - 示例:统计最近 5 分钟内,各服务的错误日志数量。
- ```sql
- SELECT service_name, count(*) AS error_cnt
- FROM "app-logs-*"
- WHERE "@timestamp" > now() - INTERVAL 5 MINUTES AND log_level = 'ERROR'
- GROUP BY service_name
- ```
+ - 示例:统计最近 5 分钟内,各服务的错误日志数量。
+ ```sql
+ SELECT service_name, count(*) AS error_cnt
+ FROM "app-logs-*"
+ WHERE "@timestamp" > now() - INTERVAL 5 MINUTES AND log_level = 'ERROR'
+ GROUP BY service_name
+ ```
2. **字段映射**:
- - **标签字段**:选择 `service_name`,用于标识告警对象。明确选择后,其他非值字段会作为附加信息随告警携带。
- - **值字段**:选择 `error_cnt`,用于阈值判定。
- - 标签字段留空时,除值字段外的所有返回字段都会作为标签。详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
+ - **标签字段**:选择 `service_name`,用于标识告警对象。明确选择后,其他非值字段会作为附加信息随告警携带。
+ - **值字段**:选择 `error_cnt`,用于阈值判定。
+ - 标签字段留空时,除值字段外的所有返回字段都会作为标签。详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
3. **阈值条件**:
- - 使用 `$A.字段名` 引用数值。
- - 示例:`Critical: $A.error_cnt > 50`,`Warning: $A.error_cnt > 10`。
- - 简写:如果只配置了一个值字段,可以直接使用 `$A`,如 `$A > 50`。
+ - 使用 `$A.字段名` 引用数值。
+ - 示例:`Critical: $A.error_cnt > 50`,`Warning: $A.error_cnt > 10`。
+ - 简写:如果只配置了一个值字段,可以直接使用 `$A`,如 `$A > 50`。
### 工作原理
@@ -75,24 +75,24 @@ WHERE "@timestamp" > now() - INTERVAL 5 MINUTES
引擎会将变量替换为实际值后执行查询,如果查到数据,则判定恢复。
</Accordion>
-## 2. 数据存在模式 (Data Exists)
+## 数据存在模式 (Data Exists)
此模式适用于将过滤逻辑直接写在 SQL 中的场景,或者只需要关注"是否有数据返回"的情况。
### 配置方式
1. **查询语句**:在 SQL 中使用 `HAVING` 子句直接过滤出异常数据。
- - 示例:直接查询错误数超过 50 的服务。
- ```sql
- SELECT service_name, count(*) AS error_cnt
- FROM "app-logs-*"
- WHERE "@timestamp" > now() - INTERVAL 5 MINUTES AND log_level = 'ERROR'
- GROUP BY service_name
- HAVING count(*) > 50
- ```
+ - 示例:直接查询错误数超过 50 的服务。
+ ```sql
+ SELECT service_name, count(*) AS error_cnt
+ FROM "app-logs-*"
+ WHERE "@timestamp" > now() - INTERVAL 5 MINUTES AND log_level = 'ERROR'
+ GROUP BY service_name
+ HAVING count(*) > 50
+ ```
2. **字段映射**:
- - 在此模式下,标签字段和值字段为**非必填项**。如果都留空,Monitors 会将查询结果中的所有字段作为标签。
- - 如果你只想用稳定字段标识告警对象,并把其他列作为排障上下文,请明确选择标签字段。参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
+ - 在此模式下,标签字段和值字段为**非必填项**。如果都留空,Monitors 会将查询结果中的所有字段作为标签。
+ - 如果您只想用稳定字段标识告警对象,并把其他列作为排障上下文,请明确选择标签字段。参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
### 恢复逻辑
@@ -110,24 +110,24 @@ WHERE "@timestamp" > now() - INTERVAL 5 MINUTES
| **优点** | 利用 ES 集群的计算能力进行过滤,减少网络传输,性能更好 |
| **缺点** | 无法区分多级告警(如 Info/Warning),SQL 只能返回满足特定条件的数据 |
-## 3. 数据缺失模式 (No Data)
+## 数据缺失模式 (No Data)
此模式用于监控"预期应该有数据,但实际没有数据"的场景,常用于监控日志采集链路中断或周期性任务未执行。
### 配置方式
1. **查询语句**:编写一个预期应该持续返回数据的 SQL 查询。
- - 示例:查询所有主机的日志上报心跳。
- ```sql
- SELECT host_name
- FROM "heartbeat-logs-*"
- WHERE "@timestamp" > now() - INTERVAL 5 MINUTES
- GROUP BY host_name
- ```
+ - 示例:查询所有主机的日志上报心跳。
+ ```sql
+ SELECT host_name
+ FROM "heartbeat-logs-*"
+ WHERE "@timestamp" > now() - INTERVAL 5 MINUTES
+ GROUP BY host_name
+ ```
2. **判定规则**:
- - 引擎会周期性执行该 SQL。
- - 如果某个 `host_name` 在之前的周期中出现过,但在当前周期(以及连续的 N 个周期)中不再出现在查询结果中,则触发"数据缺失"告警。
- - 注意:这与 Data Exists 模式相反。Data Exists 是"查到数据就告警",No Data 是"查不到数据就告警"。
+ - 引擎会周期性执行该 SQL。
+ - 如果某个 `host_name` 在之前的周期中出现过,但在当前周期(以及连续的 N 个周期)中不再出现在查询结果中,则触发"数据缺失"告警。
+ - 注意:这与 Data Exists 模式相反。Data Exists 是"查到数据就告警",No Data 是"查不到数据就告警"。
### 恢复逻辑
@@ -139,7 +139,7 @@ WHERE "@timestamp" > now() - INTERVAL 5 MINUTES
| **数据恢复或超时后自动结束** | 数据重新出现或达到自动关闭时间后,告警自动结束。自动关闭时间单位为秒,最小为 1;仅开启「之前查到过数据,现在查不到了」模式时可选 |
| **仅允许手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 4. 案例说明
+## 案例说明
日志告警经常遇到如下需求:统计最近 5 分钟的 ERROR 日志数量,如果超过阈值则告警,同时在告警消息中展示最近一条 ERROR 日志作为样例。配置方案如下:
diff --git a/zh/monitors/alert-rules/loki.mdx b/zh/monitors/alert-rules/loki.mdx
index 1b620f82..f38e20af 100644
--- a/zh/monitors/alert-rules/loki.mdx
+++ b/zh/monitors/alert-rules/loki.mdx
@@ -16,10 +16,10 @@ Loki 的查询语言 LogQL 分为两类:
| **指标查询 (Metric Queries)** | 对日志进行计数或聚合,如 `count_over_time` 返回数值(Vector) |
<Tip>
-编写 LogQL 时,查询输入框会根据数据源自动补全标签名和标签值,帮助你快速定位日志流。
+编写 LogQL 时,查询输入框会根据数据源自动补全标签名和标签值,帮助您快速定位日志流。
</Tip>
-## 1. 阈值判定模式 (Threshold)
+## 阈值判定模式 (Threshold)
此模式适用于需要对日志聚合值进行多级阈值判定(如 Info/Warning/Critical)的场景。
@@ -49,7 +49,7 @@ count_over_time({job="mysql"} |= "error" [5m])
| **恢复查询** | 支持独立 LogQL 用于恢复判定 |
| **手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 2. 数据存在模式 (Data Exists)
+## 数据存在模式 (Data Exists)
此模式适用于习惯在 LogQL 中直接写过滤条件,或者只关心"是否有异常数据"的场景。推荐使用此模式做日志异常检测告警。
@@ -78,7 +78,7 @@ count_over_time({job="ingress"} |= "error-code-500" [5m]) / count_over_time({job
- **恢复查询**:支持配置额外的查询语句用于辅助判断恢复状态
- **手工关闭**:告警保持活动,直到用户手工关闭
-## 3. 数据缺失模式 (No Data)
+## 数据缺失模式 (No Data)
此模式用于监控日志上报链路是否中断,或者预期应该持续产生的日志是否停止了。
@@ -109,9 +109,9 @@ rate({job="node-logs"} [1m])
- 监控 Promtail/Fluentd 等采集 Agent 是否停止工作
- 监控关键业务日志(如订单创建日志)是否异常中断
-## 4. 使用查原文模式作为主查询
+## 使用查原文模式作为主查询
-当你希望“查到符合条件的日志就告警”时,可以选择**查原文**模式,并使用**数据存在**判定。假设查询返回 `job`、`service`、`__time__`、`__log__` 等字段:
+当您希望“查到符合条件的日志就告警”时,可以选择**查原文**模式,并使用**数据存在**判定。假设查询返回 `job`、`service`、`__time__`、`__log__` 等字段:
- **标签字段**:选择 `job`、`service` 等稳定维度,用于标识告警对象。
- **值字段**:数据存在模式下可以留空。如果使用阈值判定,请选择能转换为数字的字段。
@@ -123,11 +123,11 @@ rate({job="node-logs"} [1m])
详细的默认行为、阈值引用方式和多查询对齐要求,请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
-## 5. 通过关联查询获取日志原文
+## 通过关联查询获取日志原文
告警时可以通过关联查询获取日志原文。但通常不建议获取太多,只获取 1 条作为日志样例放置到告警消息中。
-
+
关联查询的结果可以渲染在"备注描述"中,示例:
diff --git a/zh/monitors/alert-rules/mysql.mdx b/zh/monitors/alert-rules/mysql.mdx
index 9eb9f5d4..2e62f0f4 100644
--- a/zh/monitors/alert-rules/mysql.mdx
+++ b/zh/monitors/alert-rules/mysql.mdx
@@ -14,29 +14,29 @@ Monitors 支持使用标准 SQL 语法对 MySQL 进行查询,并根据查询
| **字段处理** | 所有字段名自动转换为小写,配置时请使用小写字母 |
| **时间处理** | 建议使用 `now()`、`unix_timestamp()` 等函数进行时间过滤 |
-## 1. 阈值判定模式
+## 阈值判定模式
此模式适用于需要对聚合后的数值进行阈值比对的场景。
### 配置方式
1. **查询语句**:编写 SQL 聚合查询,返回数值列和(可选的)标签列。
- - 示例:统计最近 5 分钟内,各服务的错误日志数量(假设有一个日志表)。
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE log_time > now() - INTERVAL 5 MINUTE AND level = 'error'
- GROUP BY service_name
- ```
+ - 示例:统计最近 5 分钟内,各服务的错误日志数量(假设有一个日志表)。
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE log_time > now() - INTERVAL 5 MINUTE AND level = 'error'
+ GROUP BY service_name
+ ```
2. **字段映射**:
- - **值字段**:选择 `error_cnt`,用于阈值判定。
- - **标签字段**:选择 `service_name`,用于标识告警对象。明确选择标签字段后,其他非值字段会作为附加信息随告警携带。
- - 详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
+ - **值字段**:选择 `error_cnt`,用于阈值判定。
+ - **标签字段**:选择 `service_name`,用于标识告警对象。明确选择标签字段后,其他非值字段会作为附加信息随告警携带。
+ - 详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
3. **阈值条件**:
- - 使用 `$A.field_name` 引用数值。
- - 示例:`Critical: $A.error_cnt > 50`,`Warning: $A.error_cnt > 10`。
+ - 使用 `$A.field_name` 引用数值。
+ - 示例:`Critical: $A.error_cnt > 50`,`Warning: $A.error_cnt > 10`。
### 工作原理
@@ -51,23 +51,23 @@ Monitors 按标签字段区分告警对象,并使用值字段进行阈值判
| **恢复查询** | 独立 SQL 用于恢复判定,支持 `${label_name}` 变量 |
| **手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 2. 数据存在模式
+## 数据存在模式
此模式适用于将过滤逻辑直接写在 SQL 中的场景。
### 配置方式
1. **查询语句**:在 SQL 中使用 `HAVING` 子句直接过滤出异常数据。
- - 示例:直接查询错误数超过 50 的服务。
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE log_time > now() - INTERVAL 5 MINUTE AND level = 'error'
- GROUP BY service_name
- HAVING count(*) > 50
- ```
+ - 示例:直接查询错误数超过 50 的服务。
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE log_time > now() - INTERVAL 5 MINUTE AND level = 'error'
+ GROUP BY service_name
+ HAVING count(*) > 50
+ ```
2. **判定规则**:只要 SQL 查询返回了数据(Result Set 不为空),即触发告警。
### 优缺点分析
@@ -83,20 +83,20 @@ Monitors 按标签字段区分告警对象,并使用值字段进行阈值判
- **恢复查询**:支持配置额外的查询语句用于辅助判断恢复状态
- **手工关闭**:告警保持活动,直到用户手工关闭
-## 3. 数据缺失模式
+## 数据缺失模式
此模式用于监控"预期应该有数据,但实际没有数据"的场景。
### 配置方式
1. **查询语句**:编写一个预期应该持续返回数据的 SQL 查询。
- - 示例:查询所有探针的心跳上报。
- ```sql
- SELECT probe_id, max(check_time) as last_seen
- FROM probe_heartbeat
- WHERE check_time > now() - INTERVAL 5 MINUTE
- GROUP BY probe_id
- ```
+ - 示例:查询所有探针的心跳上报。
+ ```sql
+ SELECT probe_id, max(check_time) as last_seen
+ FROM probe_heartbeat
+ WHERE check_time > now() - INTERVAL 5 MINUTE
+ GROUP BY probe_id
+ ```
2. **判定规则**:如果某个 `probe_id` 在之前的周期中出现过,但在当前及连续 N 个周期中查不到数据,则触发"数据缺失"告警。
### 恢复逻辑
@@ -109,7 +109,7 @@ Monitors 按标签字段区分告警对象,并使用值字段进行阈值判
| **数据恢复或超时后自动结束** | 数据重新出现或达到自动关闭时间后,告警自动结束。自动关闭时间单位为秒,最小为 1;仅开启「之前查到过数据,现在查不到了」模式时可选 |
| **仅允许手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 4. 最佳实践
+## 最佳实践
<AccordionGroup>
<Accordion title="索引优化">
diff --git a/zh/monitors/alert-rules/oracle.mdx b/zh/monitors/alert-rules/oracle.mdx
index 91b2e262..6c91a6ee 100644
--- a/zh/monitors/alert-rules/oracle.mdx
+++ b/zh/monitors/alert-rules/oracle.mdx
@@ -14,29 +14,29 @@ Monitors 支持使用标准 SQL 语法对 Oracle 进行查询,并根据查询
| **字段处理** | 所有字段名自动转换为小写,配置时请使用小写字母 |
| **时间处理** | 建议使用 `SYSDATE`、`SYSTIMESTAMP` 等函数进行时间过滤 |
-## 1. 阈值判定模式
+## 阈值判定模式
此模式适用于需要对聚合后的数值进行阈值比对的场景。
### 配置方式
1. **查询语句**:编写 SQL 聚合查询,返回数值列和(可选的)标签列。
- - 示例:统计最近 5 分钟内,各服务的错误日志数量。
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE log_time > SYSDATE - INTERVAL '5' MINUTE AND level = 'error'
- GROUP BY service_name
- ```
+ - 示例:统计最近 5 分钟内,各服务的错误日志数量。
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE log_time > SYSDATE - INTERVAL '5' MINUTE AND level = 'error'
+ GROUP BY service_name
+ ```
2. **字段映射**:
- - **值字段**:选择 `error_cnt`,用于阈值判定。
- - **标签字段**:选择 `service_name`,用于标识告警对象。明确选择标签字段后,其他非值字段会作为附加信息随告警携带。
- - 详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
+ - **值字段**:选择 `error_cnt`,用于阈值判定。
+ - **标签字段**:选择 `service_name`,用于标识告警对象。明确选择标签字段后,其他非值字段会作为附加信息随告警携带。
+ - 详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
3. **阈值条件**:
- - 使用 `$A.field_name` 引用数值。
- - 示例:`Critical: $A.error_cnt > 50`,`Warning: $A.error_cnt > 10`。
+ - 使用 `$A.field_name` 引用数值。
+ - 示例:`Critical: $A.error_cnt > 50`,`Warning: $A.error_cnt > 10`。
### 工作原理
@@ -51,23 +51,23 @@ Monitors 按标签字段区分告警对象,并使用值字段进行阈值判
| **恢复查询** | 独立 SQL 用于恢复判定,支持 `${label_name}` 变量 |
| **手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 2. 数据存在模式
+## 数据存在模式
此模式适用于将过滤逻辑直接写在 SQL 中的场景。
### 配置方式
1. **查询语句**:在 SQL 中使用 `HAVING` 子句直接过滤出异常数据。
- - 示例:直接查询错误数超过 50 的服务。
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE log_time > SYSDATE - INTERVAL '5' MINUTE AND level = 'error'
- GROUP BY service_name
- HAVING count(*) > 50
- ```
+ - 示例:直接查询错误数超过 50 的服务。
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE log_time > SYSDATE - INTERVAL '5' MINUTE AND level = 'error'
+ GROUP BY service_name
+ HAVING count(*) > 50
+ ```
2. **判定规则**:只要 SQL 查询返回了数据,即触发告警。
### 优缺点分析
@@ -83,20 +83,20 @@ Monitors 按标签字段区分告警对象,并使用值字段进行阈值判
- **恢复查询**:支持配置额外的查询语句用于辅助判断恢复状态
- **手工关闭**:告警保持活动,直到用户手工关闭
-## 3. 数据缺失模式
+## 数据缺失模式
此模式用于监控"预期应该有数据,但实际没有数据"的场景。
### 配置方式
1. **查询语句**:编写一个预期应该持续返回数据的 SQL 查询。
- - 示例:查询所有探针的心跳上报。
- ```sql
- SELECT probe_id, max(check_time) as last_seen
- FROM probe_heartbeat
- WHERE check_time > SYSDATE - INTERVAL '5' MINUTE
- GROUP BY probe_id
- ```
+ - 示例:查询所有探针的心跳上报。
+ ```sql
+ SELECT probe_id, max(check_time) as last_seen
+ FROM probe_heartbeat
+ WHERE check_time > SYSDATE - INTERVAL '5' MINUTE
+ GROUP BY probe_id
+ ```
2. **判定规则**:如果某个 `probe_id` 在之前的周期中出现过,但在当前及连续 N 个周期中查不到数据,则触发"数据缺失"告警。
### 恢复逻辑
@@ -109,7 +109,7 @@ Monitors 按标签字段区分告警对象,并使用值字段进行阈值判
| **数据恢复或超时后自动结束** | 数据重新出现或达到自动关闭时间后,告警自动结束。自动关闭时间单位为秒,最小为 1;仅开启「之前查到过数据,现在查不到了」模式时可选 |
| **仅允许手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 4. 最佳实践
+## 最佳实践
<AccordionGroup>
<Accordion title="索引优化">
diff --git a/zh/monitors/alert-rules/postgres.mdx b/zh/monitors/alert-rules/postgres.mdx
index 918bc946..b9426061 100644
--- a/zh/monitors/alert-rules/postgres.mdx
+++ b/zh/monitors/alert-rules/postgres.mdx
@@ -14,29 +14,29 @@ Monitors 支持使用标准 SQL 语法对 PostgreSQL 进行查询,并根据查
| **字段处理** | 所有字段名自动转换为小写,配置时请使用小写字母 |
| **时间处理** | 建议使用 `NOW()`、`CURRENT_TIMESTAMP` 等函数进行时间过滤 |
-## 1. 阈值判定模式
+## 阈值判定模式
此模式适用于需要对聚合后的数值进行阈值比对的场景。
### 配置方式
1. **查询语句**:编写 SQL 聚合查询,返回数值列和(可选的)标签列。
- - 示例:统计最近 5 分钟内,各服务的错误日志数量。
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE log_time > NOW() - INTERVAL '5 minutes' AND level = 'error'
- GROUP BY service_name
- ```
+ - 示例:统计最近 5 分钟内,各服务的错误日志数量。
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE log_time > NOW() - INTERVAL '5 minutes' AND level = 'error'
+ GROUP BY service_name
+ ```
2. **字段映射**:
- - **值字段**:选择 `error_cnt`,用于阈值判定。
- - **标签字段**:选择 `service_name`,用于标识告警对象。明确选择标签字段后,其他非值字段会作为附加信息随告警携带。
- - 详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
+ - **值字段**:选择 `error_cnt`,用于阈值判定。
+ - **标签字段**:选择 `service_name`,用于标识告警对象。明确选择标签字段后,其他非值字段会作为附加信息随告警携带。
+ - 详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
3. **阈值条件**:
- - 使用 `$A.field_name` 引用数值。
- - 示例:`Critical: $A.error_cnt > 50`,`Warning: $A.error_cnt > 10`。
+ - 使用 `$A.field_name` 引用数值。
+ - 示例:`Critical: $A.error_cnt > 50`,`Warning: $A.error_cnt > 10`。
### 工作原理
@@ -51,23 +51,23 @@ Monitors 按标签字段区分告警对象,并使用值字段进行阈值判
| **恢复查询** | 独立 SQL 用于恢复判定,支持 `${label_name}` 变量 |
| **手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 2. 数据存在模式
+## 数据存在模式
此模式适用于将过滤逻辑直接写在 SQL 中的场景。
### 配置方式
1. **查询语句**:在 SQL 中使用 `HAVING` 子句直接过滤出异常数据。
- - 示例:直接查询错误数超过 50 的服务。
- ```sql
- SELECT
- service_name,
- count(*) AS error_cnt
- FROM app_log
- WHERE log_time > NOW() - INTERVAL '5 minutes' AND level = 'error'
- GROUP BY service_name
- HAVING count(*) > 50
- ```
+ - 示例:直接查询错误数超过 50 的服务。
+ ```sql
+ SELECT
+ service_name,
+ count(*) AS error_cnt
+ FROM app_log
+ WHERE log_time > NOW() - INTERVAL '5 minutes' AND level = 'error'
+ GROUP BY service_name
+ HAVING count(*) > 50
+ ```
2. **判定规则**:只要 SQL 查询返回了数据,即触发告警。
### 优缺点分析
@@ -83,20 +83,20 @@ Monitors 按标签字段区分告警对象,并使用值字段进行阈值判
- **恢复查询**:支持配置额外的查询语句用于辅助判断恢复状态
- **手工关闭**:告警保持活动,直到用户手工关闭
-## 3. 数据缺失模式
+## 数据缺失模式
此模式用于监控"预期应该有数据,但实际没有数据"的场景。
### 配置方式
1. **查询语句**:编写一个预期应该持续返回数据的 SQL 查询。
- - 示例:查询所有探针的心跳上报。
- ```sql
- SELECT probe_id, max(check_time) as last_seen
- FROM probe_heartbeat
- WHERE check_time > NOW() - INTERVAL '5 minutes'
- GROUP BY probe_id
- ```
+ - 示例:查询所有探针的心跳上报。
+ ```sql
+ SELECT probe_id, max(check_time) as last_seen
+ FROM probe_heartbeat
+ WHERE check_time > NOW() - INTERVAL '5 minutes'
+ GROUP BY probe_id
+ ```
2. **判定规则**:如果某个 `probe_id` 在之前的周期中出现过,但在当前及连续 N 个周期中查不到数据,则触发"数据缺失"告警。
### 恢复逻辑
@@ -109,7 +109,7 @@ Monitors 按标签字段区分告警对象,并使用值字段进行阈值判
| **数据恢复或超时后自动结束** | 数据重新出现或达到自动关闭时间后,告警自动结束。自动关闭时间单位为秒,最小为 1;仅开启「之前查到过数据,现在查不到了」模式时可选 |
| **仅允许手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 4. 最佳实践
+## 最佳实践
<AccordionGroup>
<Accordion title="索引优化">
diff --git a/zh/monitors/alert-rules/prometheus.mdx b/zh/monitors/alert-rules/prometheus.mdx
index b0046e00..f450878e 100644
--- a/zh/monitors/alert-rules/prometheus.mdx
+++ b/zh/monitors/alert-rules/prometheus.mdx
@@ -22,7 +22,7 @@ Monitors 兼容 Prometheus 的 PromQL 查询语法,并提供了灵活的告警
</Card>
</CardGroup>
-## 1. 阈值判定模式
+## 阈值判定模式
此模式适用于需要对同一指标进行多级告警(如 Info/Warning/Critical)或需要获取精确恢复值的场景。
@@ -70,7 +70,7 @@ Monitors 支持在一个告警规则中配置多条查询语句(分别命名
恢复查询语句支持嵌入变量(格式为 `${label_name}`),会被自动替换为告警事件中对应的标签值,实现针对具体告警对象的精确检测。
</Note>
-## 2. 数据存在模式 (Data Exists)
+## 数据存在模式 (Data Exists)
此模式与 Prometheus 原生告警规则(Alerting Rules)的行为一致。适用于习惯直接在 PromQL 中定义阈值的用户,或需要高性能处理大量 Series 的场景。
@@ -102,7 +102,7 @@ Monitors 支持在一个告警规则中配置多条查询语句(分别命名
</Tab>
</Tabs>
-## 3. 数据缺失模式 (No Data)
+## 数据缺失模式 (No Data)
此模式专门用于监控监控对象是否存活或数据上报链路是否正常。
@@ -179,7 +179,7 @@ Monitors 支持在一个告警规则中配置多条查询语句(分别命名
- **长度限制**:单条查询语句最长 64KB,超限同样无法保存。
<Note>
-保存时校验只做语法层面的保守检查,通过校验不代表后端 Prometheus/VictoriaMetrics 实例一定能执行该语句。
+保存时校验只做语法层面的保守检查,通过校验不代表数据源(Prometheus/VictoriaMetrics 实例)一定能执行该语句。
</Note>
### 标签与变量
diff --git a/zh/monitors/alert-rules/query-result-fields.mdx b/zh/monitors/alert-rules/query-result-fields.mdx
index 7bb05554..3d579147 100644
--- a/zh/monitors/alert-rules/query-result-fields.mdx
+++ b/zh/monitors/alert-rules/query-result-fields.mdx
@@ -4,7 +4,7 @@ description: "说明如何把 SQL 和原文日志查询结果配置为值字段
keywords: ["查询结果", "值字段", "标签字段", "附加信息", "阈值表达式", "多查询"]
---
-MySQL、PostgreSQL、Oracle、ClickHouse、Elasticsearch、SLS 和 Tencent CLS 等表格型查询,以及 Loki、VictoriaLogs、SLS 和 Tencent CLS 的**原始日志**查询,都会返回包含多列数据的结果。你可以通过**值字段**和**标签字段**决定每一列的用途;其余列无需单独配置,会作为附加信息随告警携带。
+MySQL、PostgreSQL、Oracle、ClickHouse、Elasticsearch、SLS 和 Tencent CLS 等表格型查询,以及 Loki、VictoriaLogs、SLS 和 Tencent CLS 的**原始日志**查询,都会返回包含多列数据的结果。您可以通过**值字段**和**标签字段**决定每一列的用途;其余列无需单独配置,会作为附加信息随告警携带。
<Warning>
本页描述的完整字段映射行为需要 monit-edge `v0.53.0` 或以上版本,尤其是将查询附加信息统一命名为 `$<查询名称>.<字段名称>` 的能力。使用这些配置前,请先将告警引擎升级到 `v0.53.0` 或更高版本。
@@ -27,7 +27,7 @@ MySQL、PostgreSQL、Oracle、ClickHouse、Elasticsearch、SLS 和 Tencent CLS
| 附加信息 | `sample_message`、`latest_at` | 自动随告警携带,用于补充排障上下文,但不参与告警身份计算。 |
<Note>
-附加信息不是需要填写的第三组字段。只要你明确选择了标签字段,查询结果中既不是标签字段、也不是值字段的列就会自动成为附加信息。
+附加信息不是需要填写的第三组字段。只要您明确选择了标签字段,查询结果中既不是标签字段、也不是值字段的列就会自动成为附加信息。
</Note>
### 值字段
@@ -111,7 +111,7 @@ Critical: $A.error_count > 20 or $A.latency_ms > 1000
| A | checkout | prod | `error_count=27` |
| B | checkout | prod | `latency_ms=1350` |
-你可以配置:
+您可以配置:
```text
Critical: $A.error_count > 20 and $B.latency_ms > 1000
@@ -155,7 +155,7 @@ Edge 分别限制周期告警查询和交互预览查询。以下是默认值,
查询超过实际生效上限时会直接失败(错误信息 `too many rows`),不会返回部分结果,也不会使用截断后的数据继续判定。
-规则编辑页的查询预览表格在前端分页展示:默认每页 100 行,可切换 100 / 200 / 500,结果不足一页时隐藏分页器。分页只影响展示,与 Edge 的 `--alerter.previewMaxRows` 上限相互独立——超过 Edge 上限的查询仍会因 `too many rows` 失败。
+规则编辑页的查询预览表格分页展示:默认每页 100 行,可切换 100 / 200 / 500,结果不足一页时隐藏分页器。分页只影响展示,与 Edge 的 `--alerter.previewMaxRows` 上限相互独立——超过 Edge 上限的查询仍会因 `too many rows` 失败。
<Warning>
提高 Edge 行数上限不会取消响应字节数、字段大小或结果值数量等资源保护。高基数 Prometheus 查询或大型 SQL 结果仍可能因为其他资源上限而失败。
diff --git a/zh/monitors/alert-rules/sls.mdx b/zh/monitors/alert-rules/sls.mdx
index 51f04c18..9919b1fd 100644
--- a/zh/monitors/alert-rules/sls.mdx
+++ b/zh/monitors/alert-rules/sls.mdx
@@ -15,29 +15,29 @@ Monitors 通过 SLS 的 SQL 查询接口(GetLogsV3)获取数据,并根据
| **时间范围** | 由 API 参数控制,无需在 SQL 中写 `WHERE __time__ > ...` |
| **字段处理** | `__source__` 和 `__time__` 字段默认被忽略 |
-## 1. 阈值判定模式
+## 阈值判定模式
此模式适用于需要对聚合后的数值进行阈值比对的场景。
### 配置方式
1. **查询语句**:编写 SLS SQL 聚合查询。
- - 示例:统计最近 15 分钟内,各主机的错误日志数量。
- ```sql
- * | SELECT host, count(*) as error_cnt WHERE level = 'ERROR' GROUP BY host
- ```
+ - 示例:统计最近 15 分钟内,各主机的错误日志数量。
+ ```sql
+ * | SELECT host, count(*) as error_cnt WHERE level = 'ERROR' GROUP BY host
+ ```
2. **查询参数**:
- - `sls.project`:(必填)项目名称。
- - `sls.logstore`:(必填)日志库名称。
- - `sls.timespan.value`:(选填)时间跨度数值,默认为 15。
- - `sls.timespan.unit`:(选填)时间跨度单位,支持 `s`(秒)、`m`(分)、`h`(时)、`d`(天)。默认为 `m`。
+ - `sls.project`:(必填)项目名称。
+ - `sls.logstore`:(必填)日志库名称。
+ - `sls.timespan.value`:(选填)时间跨度数值,默认为 15。
+ - `sls.timespan.unit`:(选填)时间跨度单位,支持 `s`(秒)、`m`(分)、`h`(时)、`d`(天)。默认为 `m`。
3. **字段映射**:
- - **值字段**:选择 `error_cnt`,用于阈值判定。
- - **标签字段**:选择 `host`,用于标识告警对象。明确选择标签字段后,其他非值字段会作为附加信息随告警携带。
- - 详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
+ - **值字段**:选择 `error_cnt`,用于阈值判定。
+ - **标签字段**:选择 `host`,用于标识告警对象。明确选择标签字段后,其他非值字段会作为附加信息随告警携带。
+ - 详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
4. **阈值条件**:
- - 使用 `$A.field_name` 引用数值。
- - 示例:`Critical: $A.error_cnt > 50`,`Warning: $A.error_cnt > 10`。
+ - 使用 `$A.field_name` 引用数值。
+ - 示例:`Critical: $A.error_cnt > 50`,`Warning: $A.error_cnt > 10`。
### 工作原理
@@ -52,17 +52,17 @@ Monitors 按配置的时间范围执行 SLS 查询,按标签字段区分告警
| **恢复查询** | 独立 SQL 用于恢复判定,支持 `${label_name}` 变量 |
| **手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 2. 数据存在模式
+## 数据存在模式
此模式适用于将过滤逻辑直接写在 SQL 中的场景。
### 配置方式
1. **查询语句**:使用 `HAVING` 子句过滤异常数据。
- - 示例:查询错误数超过 50 的主机。
- ```sql
- * | SELECT host, count(*) as error_cnt WHERE level = 'ERROR' GROUP BY host HAVING error_cnt > 50
- ```
+ - 示例:查询错误数超过 50 的主机。
+ ```sql
+ * | SELECT host, count(*) as error_cnt WHERE level = 'ERROR' GROUP BY host HAVING error_cnt > 50
+ ```
2. **查询参数**:同上,需配置 `sls.project` 和 `sls.logstore`。
3. **判定规则**:只要查询返回了数据,即触发告警。
@@ -79,39 +79,29 @@ Monitors 按配置的时间范围执行 SLS 查询,按标签字段区分告警
- **恢复查询**:支持配置额外的查询语句
- **手工关闭**:告警保持活动,直到用户手工关闭
-## 3. 数据缺失模式
+## 数据缺失模式
此模式用于监控"预期应该有数据,但实际没有数据"的场景。
-SLS 属于云日志类数据源,不支持按曲线(per-series)的无数据检测,只保留「**所有查询均无返回数据时告警**」这一种判定:
-
-- 界面上只有一张判定卡「所有查询均无返回数据时告警」,对应 `alert_on_empty_result` 与 `alert_on_empty_result_severity` 两个字段。
-- 「之前查到过数据,现在查不到了,就告警」那张按曲线的检测卡在 SLS 规则里不渲染,它的配置项 `check_nodata.enabled` 因此无从设置。
-- 同类数据源腾讯云 CLS 也禁用该判定,且在后端是硬校验(提交 `check_nodata.enabled` 直接返回 400);SLS 目前由前端禁用,后端未加拦截。
+SLS 不支持按曲线(per-series)的无数据检测,只能使用「**所有查询均无返回数据时告警**」判定,不支持「之前查到过数据,现在查不到了,就告警」。
### 配置方式
1. **查询语句**:编写一个预期应该持续返回数据的查询。
- - 示例:查询所有主机的日志上报心跳。
- ```sql
- * | SELECT host, max(__time__) as last_seen GROUP BY host
- ```
+ - 示例:查询所有主机的日志上报心跳。
+ ```sql
+ * | SELECT host, max(__time__) as last_seen GROUP BY host
+ ```
2. **判定规则**:所有查询在连续 N 次检测中都返回空结果时,触发"数据缺失"告警。N 由该页签共享的「触发条件」决定。
### 存量已启用按曲线检测的规则
-以 SLS 为数据源、且已开启按曲线无数据检测的存量规则,打开编辑页时该判定会被自动关闭(`check_nodata.enabled` 以关闭状态回填),并弹出提示:
-
-<Warning>
-当前数据源类型不支持「之前查到过数据,现在查不到了,就告警」,该判定已自动关闭,保存后生效
-</Warning>
-
-规则详情页是只读的,不弹这条提示。这条判定是在编辑页里被关掉的:不打开编辑页,规则配置不会变;打开并保存后,关闭状态才会写回规则。自动关闭只作用于这一项判定,保存时:
+如果已有的 SLS 规则开启了按曲线的无数据检测,打开编辑页时该判定会被自动关闭,保存后生效;不打开编辑页,规则不会变化。
-- 规则若还有其它已启用的判定(阈值判定、数据存在),「至少启用一项」校验不会拦下这次降级,按曲线检测会随这次保存一起失效——上面那条提示就是为此而弹的。
-- 规则若只有这一项判定,保存会被「阈值判定、数据缺失、数据存在至少启用一项」校验拦下,必须显式改配才能保存。
+- 规则还有其他已启用的判定(阈值判定、数据存在)时,可以直接保存。
+- 这是规则唯一的判定时,需要先启用至少一项判定才能保存。
-建议打开这类规则后,把无数据检测改为「所有查询均无返回数据时告警」,确认告警判定里至少有一项已启用,再保存。
+建议改用「所有查询均无返回数据时告警」,确认至少启用了一项判定后再保存。
### 恢复逻辑
@@ -123,7 +113,7 @@ SLS 属于云日志类数据源,不支持按曲线(per-series)的无数据
原先的恢复方式下拉(`数据重新出现后自动结束` / `数据恢复或超时后自动结束` / `仅允许手工关闭`)只存在于按曲线的检测卡内部,SLS 下不可用。无数据页签里可配置的共享项只有触发与恢复条件(`触发方式`、`触发条件`、`恢复条件`)。
-## 4. 高级配置
+## 高级配置
<AccordionGroup>
<Accordion title="Power SQL">
diff --git a/zh/monitors/alert-rules/tencent-cls.mdx b/zh/monitors/alert-rules/tencent-cls.mdx
index a6d2c7d2..3a8dd621 100644
--- a/zh/monitors/alert-rules/tencent-cls.mdx
+++ b/zh/monitors/alert-rules/tencent-cls.mdx
@@ -11,7 +11,7 @@ Monitors 通过腾讯云日志服务 CLS 的检索与分析接口获取数据,
| 配置项 | 说明 |
|--------|------|
| **查询资源** | 每条查询必须指定 `tencent_cls.region`(地域)和 `tencent_cls.topic_id`(日志主题);日志集只用于界面筛选,不参与保存与执行 |
-| **查询模式** | `raw` 原始日志检索返回日志行;`analysis` SQL 分析返回聚合结果。后端按存储的参数值执行,不从表达式推断 |
+| **查询模式** | `raw` 原始日志检索返回日志行;`analysis` SQL 分析返回聚合结果。按所选模式执行,不会根据查询语句自动判断 |
| **检索语法** | 原始日志检索使用 `tencent_cls.syntax` 指定的语法:`CQL` 或 `Lucene` |
| **时间范围** | 由参数控制,无需在查询语句中书写时间过滤条件 |
| **执行标识** | 执行时只认日志主题 ID,主题名称仅用于展示 |
@@ -51,7 +51,7 @@ Monitors 通过腾讯云日志服务 CLS 的检索与分析接口获取数据,
对日志进行 SQL 聚合,返回聚合结果,适合阈值判定与数据存在判定。
- 时间窗口最长 **24 小时**。
-- 不允许携带 `tencent_cls.limit`,携带会被后端拒绝。
+- 不允许携带 `tencent_cls.limit`,携带时会被拒绝。
## 时间范围
@@ -61,23 +61,22 @@ Monitors 通过腾讯云日志服务 CLS 的检索与分析接口获取数据,
### 单数据源绑定
-Tencent CLS 规则只能**精确绑定一个数据源**,且不支持名称通配。创建规则时数据源选择为单选,名称通配输入被隐藏;配置非法时保存会提示「该数据源类型只能绑定一个数据源」或「该数据源类型不支持名称通配,请清空后重新选择」。
+Tencent CLS 规则只能**精确绑定一个数据源**,不支持名称通配。
### 主题索引要求
-日志主题必须开启索引,检索和 SQL 分析才能返回结果。主题列表中未开启索引的主题带有「未开启索引」标记;选中未开启索引的主题后,编辑器会提示「该日志主题未开启索引,检索和 SQL 分析都不会有结果。请先在腾讯云控制台配置索引。」——这类查询会持续返回空结果。
+日志主题必须开启索引,否则检索和 SQL 分析都不会返回结果。主题列表会标出未开启索引的主题,请先在腾讯云控制台配置索引。
### 主题 ID 执行
-主题选择器支持按名称搜索或直接粘贴主题 ID。保存进规则的只有主题 ID,执行时也只认主题 ID;日志集筛选仅用于界面过滤,不会被保存。编辑已有规则时,若主题已被删除,界面会提示「主题不存在或已被删除」,需要重新选择主题。
+可以按名称搜索主题,或直接粘贴主题 ID。规则只保存并使用主题 ID(日志集筛选只用于查找,不会保存)。如果主题已被删除,编辑规则时需要重新选择。
## 无数据检测
Tencent CLS 不支持按曲线(per-series)的无数据检测:
-- 仅支持「**所有查询均无返回数据时告警**」这一张判定卡。
-- 不提供「之前查到过数据,现在查不到了,就告警」选项——开启该判定要提交 `check_nodata.enabled`,后端直接返回 400 拒绝,因此这张检测卡在界面上不出现。
-- **恢复方式**不可配置:这类告警没有可选项,引擎固定为「任一查询重新查到数据后自动恢复」,界面上以只读文本展示。「仅允许手工关闭」在这里不存在——恢复方式选择器(`数据重新出现后自动结束` / `数据恢复或超时后自动结束` / `仅允许手工关闭`)只渲染在按曲线的检测卡内部,该卡在 CLS 规则里不出现,这三档都选不到。
+- 只能使用「**所有查询均无返回数据时告警**」判定,不支持「之前查到过数据,现在查不到了,就告警」(通过 API 也无法开启)。
+- 恢复方式固定为**任一查询重新查到数据后自动恢复**,不可配置,也不支持仅手工关闭。
## 恢复查询与关联查询
diff --git a/zh/monitors/alert-rules/victorialogs.mdx b/zh/monitors/alert-rules/victorialogs.mdx
index 2056477c..9f166498 100644
--- a/zh/monitors/alert-rules/victorialogs.mdx
+++ b/zh/monitors/alert-rules/victorialogs.mdx
@@ -6,7 +6,7 @@ keywords: ["VictoriaLogs", "日志告警", "日志监控", "时序数据库", "
Monitors 通过 HTTP 查询 VictoriaLogs,支持查询日志原文、做统计分析,并基于结果进行阈值判定和数据存在/缺失判断。
-## 1. 前置说明
+## 前置说明
### 查询模式
@@ -40,7 +40,7 @@ Monitors 通过 HTTP 查询 VictoriaLogs,支持查询日志原文、做统计
VictoriaLogs 数据源最推荐使用"数据存在模式",最适合日志场景。
</Tip>
-## 2. 阈值判定模式 (Threshold)
+## 阈值判定模式 (Threshold)
**查原文**和**做统计**两种查询模式都可以使用。下面分别举例说明。
@@ -90,7 +90,7 @@ total{level="ERROR"} 150
| **恢复查询** | 独立查询用于恢复判定,支持 `${label_name}` 变量 |
| **手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 3. 数据存在模式 (Data Exists)
+## 数据存在模式 (Data Exists)
<Note>
这是**最推荐的 VictoriaLogs 告警配置方式**,因为日志场景更适合采用"有异常数据就告警"的模式。
@@ -116,7 +116,7 @@ _time:15m and level:ERROR | stats by (level) count(*) total | filter total:>10
详细规则请参见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
-## 4. 数据缺失模式 (No Data)
+## 数据缺失模式 (No Data)
数据缺失模式用于监控"原本应该持续产生的日志不再出现"的情况,常见于:
@@ -143,11 +143,11 @@ _time:15m and level:INFO | stats by (level) count(*) total
| **数据恢复或超时后自动结束** | 数据重新出现或达到自动关闭时间后,告警自动结束。自动关闭时间单位为秒,最小为 1;仅开启「之前查到过数据,现在查不到了」模式时可选 |
| **仅允许手工关闭** | 告警保持活动,直到用户手工关闭 |
-## 5. 获取告警时日志原文
+## 获取告警时日志原文
告警查询条件通常使用 “做统计” 模式,这种模式没有返回日志原文。Monitors 支持在告警规则中配置“关联查询”,用于在告警触发时额外查询日志原文。
-
+
“关联查询”的结果可以渲染在 “备注描述” 中,示例:
diff --git a/zh/monitors/dashboards/dashboards.mdx b/zh/monitors/dashboards/dashboards.mdx
index f5e62785..010254ce 100644
--- a/zh/monitors/dashboards/dashboards.mdx
+++ b/zh/monitors/dashboards/dashboards.mdx
@@ -6,175 +6,154 @@ keywords: ["仪表盘", "Dashboard", "面板", "模板变量", "同环比", "版
仪表盘(Dashboard)把查询固化成图表:一个仪表盘由页签、分组和面板组成,每个面板绑定一个数据源与一组查询,打开时按当前时间范围和变量选择实时取数。它适合把日常巡检、故障复盘反复要看的几张图固定下来,不必每次去[查询工作台](/zh/monitors/explore/explore)重写查询。
-## 概述与入口
+## 入口
-- **菜单入口**:左侧菜单 **可视化 → 仪表盘**(前端路由 `/monit/dashboards`)。菜单与页面路由挂的是「数据源查看」权限,所以能看数据源的人就能看到仪表盘入口。
-- **从查询工作台**:工作台里跑出结果的查询可以直接**保存到仪表盘**,固化成一张面板,见[新建与保存](#新建与保存仪表盘)。
+- **菜单**:左侧菜单 **可视化 → 仪表盘**。能查看数据源的成员即可看到该入口。
+- **从查询工作台**:把跑出结果的查询直接**保存到仪表盘**,见[新建与保存](#新建与保存仪表盘)。
-仪表盘的读写权限不在面板本身,而在它所属的**目录**:读取继承目录的读权限,写操作要求「仪表盘管理」权限且对所在目录可读。详见[权限模型](#权限模型)。
+能否查看或编辑某个仪表盘,取决于它所在的**目录**,详见[权限](#权限)。
## 列表与目录
-**菜单入口**:可视化 → 仪表盘
+页面左侧是与告警规则共用的目录树,右侧是当前目录下的仪表盘。目录的创建、重命名、移动和删除都在树上完成,规则见[文件夹管理](/zh/monitors/folders/folders)。
-页面左侧是与告警规则共用的目录树(同一个 `/monit/folder/list` 接口),右侧是当前目录下的仪表盘列表。目录的创建、重命名、移动、删除都在树上完成,受文件夹权限控制,规则见[文件夹管理](/zh/monitors/folders/folders)。
-
-| 列 | 说明 |
-|----|------|
-| **标题** | 仪表盘名称,点击进入查看页 |
-| **更新人** | 最后一个保存该仪表盘的用户 |
-| **更新时间** | 最后一次保存的时间 |
-| **操作** | 有「仪表盘管理」权限时出现:编辑、删除,以及「更多」菜单(移动到其他分组 / 克隆到本分组 / 克隆到其他分组) |
-
-- **搜索框只搜当前目录**,不跨目录搜索;输入有 300ms 防抖,目录、搜索词、页码都写在 URL 上(`folder_id`、`q`),因此链接可以分享、刷新可保持。从仪表盘的查看页点面包屑返回列表时,会还原你离开时的那一组条件。
-- **分页**默认每页 20 条。
-- 当前目录没有仪表盘时显示「当前目录还没有仪表盘」,有管理权限的用户可以直接在空态里新建。
+- 搜索只在**当前目录**内进行。
+- 目录、搜索词和页码会保留在页面地址中,链接可以分享,从仪表盘返回列表时也会还原。
+- 每行的 **更多** 菜单提供:移动到其他分组、克隆到本分组、克隆到其他分组。克隆会生成一个标题带「副本」后缀的新仪表盘,**不带历史版本**;移动或克隆到其他目录时,您需要对目标目录可读。
## 新建与保存仪表盘
-**新建**:列表页右上角 **新建仪表盘**(需管理权限),进入 `/monit/dashboards/new?edit=1`。新盘的初始状态是:标题「未命名仪表盘」、默认时间范围「过去 1 小时」、自动刷新关闭、一个标题为 `Overview` 的页签、没有任何面板。
-
-**从查询工作台保存**:工作台的 **保存到仪表盘** 按钮把当前查询固化成面板,弹窗中可选:
-
-| 选项 | 说明 |
-|------|------|
-| **新建仪表盘** | 选目录 + 填仪表盘标题,会先在所选目录真正创建这个仪表盘,再打开它的编辑态 |
-| **现有仪表盘** | 先选目录、再从该目录的仪表盘列表里选一个;会打开该仪表盘的编辑态并把这个面板追加到首个页签底部,**保存前不产生任何数据** |
-| **图表标题** | 面板标题,留空为「未命名图表」 |
-| **图表类型** | 按最近一次成功结果推荐(日志→Logs、采样时序→Time series、其余→Table),可以改 |
-
-Prometheus 在工作台里同时跑区间与即时两条查询(Both),固化到面板时按 `Range` 保存并提示「查询方式 Both 已按 Range 保存」——仪表盘的查询方式不接受 Both。
+**新建**:在列表页右上角点击 **新建仪表盘**(需「仪表盘管理」权限)。新仪表盘默认时间范围为「过去 1 小时」,包含一个空的 `Overview` 页签。
-**编辑态**是一个整盘的浏览器草稿:
+**从查询工作台保存**:在工作台点击 **保存到仪表盘**,选择新建仪表盘或现有仪表盘,填写图表标题并选择图表类型(会按查询结果推荐,可以修改)。保存到现有仪表盘时,面板会追加到第一个页签的底部,在您点击保存前不会生效。
-- 顶部可改目录(仅新建时)与标题;右侧是时间范围、撤销 / 重做(`⌘Z` / `⌘⇧Z`)、取消、保存。
-- 所有修改(加面板、拖动布局、改变量、改配置)都进草稿,一步一档可撤销,**刷新页面即丢**(服务端没有草稿),带着未保存修改离开页面会被拦截提示「草稿尚未保存,确定离开?」。
-- **保存**:标题必填,新建时必须选目录;弹窗里可填**版本说明**(选填,最多 1024 字符),并提示「将提交完整配置并产生新版本(当前 vN)」。提交的是完整定义,保存成功即产生一个新版本;服务端判定内容没变时提示「没有变化」。已有仪表盘没有改动时保存按钮不可点。
-- **把当前时间范围设为本盘默认**:当你在预览时选择的时间范围是相对档(15m/30m/1h/3h/6h/12h/24h/7d 之一)且与盘上默认值不同,保存弹窗里会出现「将当前时间范围(xx)设为本盘默认」勾选项。
-- **并发冲突**:如果别人在你编辑期间保存过,保存失败并弹出「仪表盘已被他人更新」,三选:**另存为副本…**(选目录另存一份)、**放弃草稿,载入最新**(丢弃你的草稿并回到查看页)、**继续编辑**(保留草稿,不做合并)。
-- **校验失败**:弹出「保存失败:配置校验未通过」,逐条列出出错的 JSON Pointer 路径与原因。
+<Note>
+仪表盘不支持 Prometheus 的 Both 查询方式。工作台里以 Both 运行的查询,保存为面板时会按 Range 保存。
+</Note>
-**列表页的其余动作**:
+**编辑与保存**:
-| 动作 | 说明 |
-|------|------|
-| **克隆到本分组 / 克隆到其他分组** | 取完整定义另建一个仪表盘(新 ID、标题加「副本」后缀),**不带历史版本** |
-| **移动到其他分组** | 换目录,需要目标目录可读 |
-| **编辑** | 打开该仪表盘的编辑态 |
-| **删除** | 见[删除与回收站](#删除与回收站) |
+- 编辑时的所有修改都是草稿,可以撤销 / 重做(`⌘Z` / `⌘⇧Z`)。草稿只保存在当前浏览器页面,**刷新即丢失**,离开页面前会提醒您。
+- 保存时可以填写**版本说明**(选填,最多 1024 字符)。每次保存都会产生一个新版本。
+- 如果您预览时选择的相对时间范围与默认值不同,保存时可以勾选把它设为本仪表盘的默认时间范围。
+- 如果别人在您编辑期间保存过,保存会失败,您可以选择另存为副本、放弃草稿并载入最新版本,或继续编辑。草稿不会自动合并。
## 页签、分组与面板布局
-- **页签(Tab)** 是仪表盘的一级分区,默认一个,最多 10 个。页签标题双击即可重命名;删除页签会先确认,并提示「含 N 个分组、M 个图表」。
-- **分组(Section)** 位于页签内,像 Grafana 的 Row:标题行常显,可以折叠;**折叠的分组不加载数据**,折叠中的分组标题会显示「(N 个图表 · 折叠中不加载)」。每个页签最多 10 个分组。
-- **面板**用 24 列网格摆放,新增的面板默认 `12×8`,落在所属容器的最底部;在画布上可拖动、可缩放,也可以复制(复制一份插在原面板下方)和删除。
-- 一个页签最多 30 个面板,整个仪表盘最多 100 个面板。
-- 面板标题旁可以带描述:默认收在标题右侧的 ⓘ 提示里,勾选面板选项**作为副标题**后改为显示在标题下方;描述与文本面板的 Markdown 一样不支持图片与 HTML。
-- 空画布会给出引导「从第一张图表开始 / 选择数据源、写一条查询,边预览边完善」,并提供 **添加图表** 与 **新建分组**。
+- **页签**是仪表盘的一级分区。双击标题可以重命名。
+- **分组**位于页签内,可以折叠。**折叠的分组不加载数据**,适合放不常看的图。
+- **面板**按 24 列网格摆放,可以拖动、缩放、复制和删除。
+- 面板描述默认显示在标题右侧的 ⓘ 提示中,也可以设为显示在标题下方的副标题;描述不支持图片与 HTML。
+- 只有当前页签和已展开分组中的面板会加载,视口内的面板优先。
-仪表盘内的面板是**懒加载**的:只调度当前页签和已展开分组里的面板,页面上同时最多 4 个查询在飞,视口内的面板优先;刷新时旧图以半透明保留在页面上,首次加载才用骨架屏。
+数量上限见[配额与限制](#配额与限制)。
## 面板类型与查询
-面板编辑器左侧是预览,右侧是配置,分组与 Grafana 相近:面板 / 图例 / 图形样式 / 标准选项 / 阈值 / 下钻。**图表类型**里有 7 种:
+面板编辑器左侧是预览,右侧是配置。目前可用的图表类型:
-| 图表类型 | 说明 | 是否可选 |
-|---------|------|---------|
-| **时序** | 随时间变化的趋势,支持多条曲线对比 | 可选 |
-| **表格** | 按行列展示明细,适合即时查询结果 | 可选 |
-| **单值** | 一个关键数字,支持阈值着色 | 可选 |
-| **文本** | Markdown 说明文字,不带数据源与查询 | 可选 |
-| **柱状** | 分类数据的大小对比 | 置灰,标注「后续版本支持」 |
-| **仪表** | 数值在范围内的位置 | 置灰,标注「后续版本支持」 |
-| **日志** | 日志明细流 | 置灰,标注「后续版本支持」 |
+| 图表类型 | 适合展示 |
+|---------|------|
+| **时序** | 随时间变化的趋势,支持多条曲线对比 |
+| **表格** | 按行列展示明细,适合即时查询结果 |
+| **单值** | 一个关键数字,支持阈值着色 |
+| **文本** | Markdown 说明文字,不需要数据源与查询 |
-柱状、仪表、日志三种类型后端契约已经支持,但前端渲染器尚未落地,因此不能在类型选择器里选中;如果通过查询工作台「保存到仪表盘」存下了 Logs 面板,查看时会显示「该图表类型(logs)将在后续版本支持」。
+柱状、仪表与日志类型将在后续版本支持。
-**数据源**下拉只列仪表盘运行时能查询的类型——**prometheus、mysql、loki**(与 Dashboard Runtime 同口径,诊断类数据源不出现在候选里),并且可以选**固定数据源**,也可以选**数据源变量**(切换变量即换数据源,不必逐个面板改)。
+**数据源**:支持 Prometheus、MySQL 和 Loki。可以选固定数据源,也可以选**数据源变量**,切换变量即可让整个仪表盘换数据源。
-**查询方式**由数据源与图表类型决定,不开放手选:MySQL 数据源用时间窗口查询(`window`),表格取即时快照(`instant`),时序与单值取区间(`range`)。
+**查询方式**由数据源和图表类型自动决定:表格取即时值,时序图和单值图取区间数据,MySQL 按时间窗口查询。
| 配置项 | 说明 |
|--------|------|
-| **查询表达式** | Prometheus / Loki 面板支持 `${variable}` 模板(大括号可省略,写成 `$variable` 也认),并可以使用 `$__interval` 等内置时间变量,见[内置时间变量](#内置时间变量);MySQL 面板不支持变量插值;PromQL 数据源提示「输入 PromQL 查询」,其它数据源按类型提示 |
-| **多查询** | 查询用 `A`~`Z` 编号,只有时序图支持多查询;切到其它图表类型时必须明确选一个保留,其余会被删除 |
-| **序列名称** | 只有时序图显示,写每条序列展示的名字(图例、提示框、数据链接都用它),如 `{{instance}}` 会替换为该序列 `instance` 标签的值,留空显示全部标签;图例与提示框都隐藏时会提示该配置当前看不到效果 |
-| **最小步长** | 只有 Prometheus 的区间查询显示,是查询步长(step)的下限,默认 15s(对齐 Prometheus 默认抓取间隔);切换到不接受该字段的数据源 / 查询方式时会被移除 |
-| **取值字段** | 单值图显示哪些字段(多个字段并排显示,字段名区分大小写);Prometheus 的结果只有 `value` 一个值,单值图的取值字段固定为它 |
-| **单位 / 小数位 / 阈值** | 阈值方向「越高越差 / 越低越差」,可配 warning / critical 两级并按「文字 / 背景」着色 |
-| **表格列配置** | 表格按数值列配置单位、阈值与着色;Prometheus 表格只有 `value` 一列可配。着色可选「不着色 / 文字 / 背景」,选背景时可以把该列的阈值色「应用到整行」 |
-| **值映射** | 把数值换成文字和颜色(如 0 显示为「离线」并标红),从上到下取第一条命中的映射,映射的颜色优先于阈值色 |
-| **下钻** | 面板链接与数据链接,见[点值筛选看板与下钻链接](#点值筛选看板与下钻链接) |
+| **查询表达式** | Prometheus / Loki 面板可以使用 `$变量名` 或 `${变量名}` 引用模板变量,以及[内置时间变量](#内置时间变量)。MySQL 面板不支持变量 |
+| **多查询** | 只有时序图支持多条查询(`A`~`Z`)。切换到其他图表类型时需要选择保留哪一条 |
+| **序列名称** | 时序图中每条曲线的显示名,如 `{{instance}}` 会替换为 `instance` 标签的值;留空显示全部标签 |
+| **最小步长** | Prometheus 区间查询的步长下限,默认 15s |
+| **取值字段** | 单值图显示的字段,区分大小写 |
+| **单位 / 小数位 / 阈值** | 阈值可设「越高越差」或「越低越差」,分 warning / critical 两级,按文字或背景着色 |
+| **表格列配置** | 为数值列设置单位、阈值和着色;背景着色可以应用到整行 |
+| **值映射** | 把数值显示为文字和颜色(如 0 显示为「离线」并标红)。按顺序取第一条命中的映射,映射颜色优先于阈值色 |
+| **下钻** | 面板链接与数据链接,见[点值筛选与下钻链接](#点值筛选与下钻链接) |
+
+修改查询后按回车(或 `⌘/Ctrl + Enter`)运行预览;修改数据源、图表类型或时间会自动重跑,显示配置(单位、阈值等)即时生效。**保存不要求预览成功。**
### 面板级查询选项
-**查询选项**和数据源放在一起,作用于该面板的**全部查询**(A / B 共用):
+以下选项作用于该面板的**全部查询**:
| 选项 | 说明 |
|------|------|
-| **最大点数** | 每条序列最多返回的点数,决定查询步长(时间范围 ÷ 最大点数);留空按面板宽度自动计算,输入框占位符会给出当前实际生效的值 |
-| **相对时间** | 这个面板固定查询「现在往前 N」,不跟随仪表盘的时间范围,例如 `5m` 表示始终看最近 5 分钟 |
-| **时间偏移** | 把查询的时间范围整体往前挪 N,例如 `1d` 可与昨天同一时段对比 |
+| **最大点数** | 每条序列最多返回的点数,决定查询步长。留空时按面板宽度自动计算 |
+| **相对时间** | 让面板固定查询最近一段时间,不跟随仪表盘的时间范围,如 `5m` |
+| **时间偏移** | 把查询时间整体前移,如 `1d` 可以和昨天同一时段对比 |
| **对比** | 同环比,见[同环比对比](#同环比对比) |
-时长一律写作「数字 + 单位」(`s` / `m` / `h` / `d` / `w`),如 `5m`、`1h`、`1d`;格式不对时输入框标红并提示「格式如 5m、1h、1d」。配了相对时间或时间偏移的面板,会在标题旁用蓝字标出实际查询的时间(如「最近 5 分钟 · 偏移 1 天」),提醒查看者它不跟随全局时间。
-
-预览在面板编辑器里实时进行:改查询本身后按回车(或 `⌘/Ctrl + Enter`)才跑,改数据源、图表类型、时间这类上下文会自动重跑;显示层配置(单位、阈值、别名等)改了即时生效不用重查。**保存不要求预览成功**。新建仪表盘时如果还没选保存目录,预览区会提示「先选择保存位置才能预览」。
+时长写作「数字 + 单位」(`s` / `m` / `h` / `d` / `w`),如 `5m`、`1h`、`1d`。设置了相对时间或时间偏移的面板会在标题旁标出实际查询的时间,提醒查看者它不跟随全局时间。
### 内置时间变量
-面板查询的表达式里可以直接写内置时间变量,它们由这个面板自己的执行窗口与步长算出秒数——写 `$__range` 就不必为了「窗口有多长」再手工维护一个变量。
+在面板的查询表达式中可以直接使用以下变量,它们按该面板的时间窗口和步长自动计算:
-| 变量 | 渲染成什么 |
+| 变量 | 含义 |
|------|-----------|
-| `$__interval` | 面板查询的步长(秒),如 `30s`;步长由时间范围与**最大点数**算出,并受**最小步长**约束 |
-| `$__rate_interval` | `步长 + 15s` 与 `60s` 里的较大者(15s 是假定的抓取间隔),适合直接喂给 `rate()` |
-| `$__range` | 面板执行窗口的长度(秒),如 24 小时的窗口渲染成 `86400s` |
-| `$__auto` | Loki 即时查询里是整个窗口的时长,按能整除的最大单位写成 `1h`、`5m`、`90s` 或 `90500ms`;Loki 区间查询里与 `$__interval` 一样给步长秒数 |
+| `$__interval` | 查询步长,如 `30s`,由时间范围与最大点数算出,不小于最小步长 |
+| `$__rate_interval` | `步长 + 15s` 与 `60s` 中的较大值,适合直接用于 `rate()` |
+| `$__range` | 时间窗口的长度,如 24 小时窗口为 `86400s` |
+| `$__auto` | Loki 即时查询中为整个窗口的时长(如 `1h`、`5m`);Loki 区间查询中等同于 `$__interval` |
-写法与变量一致:`${__interval}` 与 `$__interval` 都接受(大括号可省略),但内置时间变量不吃格式化后缀,写成 `${__interval:raw}` 之类的会被判为非法。
+可用范围:
-可用范围由数据源与查询方式决定,下表之外的组合(包括 MySQL)都用不了;这种组合在保存校验时就会被拒(保存弹窗按 JSON Pointer 列出原因),面板运行起来也不会取数:
-
-| 数据源 · 查询方式 | 可用的内置时间变量 |
+| 数据源 · 查询方式 | 可用变量 |
|------------------|------------------|
| Prometheus · 区间 | `$__interval`、`$__rate_interval`、`$__range` |
| Loki · 区间 | `$__auto`、`$__interval`、`$__range` |
| Loki · 即时 | `$__auto`、`$__range` |
-内置时间变量只在**面板查询的表达式**里存在:模板变量的候选查询、面板查询的 args 都解析不了它们,保存时同样会被拒。
+<Note>
+内置时间变量只能用在**面板查询表达式**中,不能用于模板变量的候选查询,也不支持 `:raw` 之类的格式后缀。MySQL 面板不可用。用在不支持的位置时,仪表盘无法保存。
+</Note>
## 模板变量
-变量栏在画布上方,用全站统一的筛选控件呈现:每个变量是一个常驻筛选项,单选 / 多选由变量配置决定。编辑态在变量栏末尾多了 **管理变量**(变量管理抽屉),可以增、改、删全部变量。
-
-**变量类型**有三类:
+变量栏位于画布上方,每个变量是一个筛选项。编辑时点击变量栏末尾的 **管理变量** 可以新增、修改或删除变量。
| 类型 | 取值来源 | 配置项 |
|------|---------|--------|
-| **Datasource** | 一个具体数据源 | 数据源类型(只列 prometheus / mysql / loki)、默认数据源 |
-| **Custom** | 手写的固定候选列表 | 候选项(每行一个,`显示名=值` 或纯值) |
-| **Query** | 对数据源查询得到候选 | 数据源(固定数据源或数据源变量)+ 查询方式 + 候选刷新时机 |
+| **Datasource** | 一个具体数据源 | 数据源类型(Prometheus / MySQL / Loki)、默认数据源 |
+| **Custom** | 手写的候选列表 | 每行一个候选,`显示名=值` 或纯值 |
+| **Query** | 查询数据源得到候选 | 数据源(固定或数据源变量)+ 查询 + 候选刷新时机 |
+
+**Query 变量的候选查询**:
+
+- **Prometheus**:填写 `label`(必填)和 `metric`(选填),可添加 `= / != / =~ / !~` 标签过滤。
+- **SQL 数据源**:填写表达式和取值字段。
+- **Loki**:填写表达式和字段。字段必须是流的标签名(不支持点分或 JSON 字段名),候选值取自仪表盘时间范围内选中流的该标签值;表达式留空表示所有流。
+
+表达式中可以引用其他仪表盘变量,但不能使用内置时间变量。点击 **预览候选** 可以确认查询是否正确。
-**Query 变量的候选查询**按数据源类型分三种:Prometheus 需要填 `label`(必填)、`metric`(选填),并可用「标签过滤」逐条添加 `= / != / =~ / !~` 条件;SQL 数据源填表达式与取值字段;Loki 填表达式与字段——字段必须是流的标签名(`^[A-Za-z_][A-Za-z0-9_]*$`,点分字段名、JSON 里的字段名都不行),候选值取自表达式选中的那些流在**仪表盘时间范围内**的该标签取值,表达式留空即在所有流上取;表达式里可以用仪表盘变量,但不能用内置时间变量(它们只在面板查询的表达式里可用,见[内置时间变量](#内置时间变量))。抽屉里的 **预览候选** 会带上当前配置试拉一次,用来确认数据源与查询写对了,失败时在变量旁显示错误原因。
+**命名与引用**:
-**名称与引用**:变量名必须匹配 `^[A-Za-z_][A-Za-z0-9_]{0,63}$`,也不能以 `__` 开头(这个前缀留给内置时间变量),与已有变量重名会被拒绝;改名是前端的原子重构——会把全部 `${旧名}` 引用(查询表达式、查询 args、数据源变量引用、变量自身的候选查询)一起改掉,改动前提示「将同步更新 N 处引用」。被引用着的变量不能删除,会提示「变量 x 被 N 处引用,请先清理引用」。一个仪表盘最多 20 个变量。
+- 变量名以字母或下划线开头,只能包含字母、数字和下划线,最长 64 个字符,不能以 `__` 开头,不能重名。
+- 改名会自动更新所有引用该变量的地方。
+- 仍被引用的变量不能删除,需要先清理引用。
-**选择模式与「全部」**:
+**单选、多选与「全部」**:
-- **单选**:必须有一个具体值,打开时默认取第一个候选。
-- **多选**:可以不选,**不选即查看全部**;此时控件占位符显示「全部」。「全部」不是候选项,它是「没有具体选择」的状态,因此不会把之后新增的候选也包含进来,也没有「全选」按钮。
-- **清空即全部**:允许「全部」的变量有自己的清除入口(标签上的 × 或下拉里的「清除」),清空会显式写成「全部」,不会回落到默认值;不允许「全部」的变量没有清除入口,必须始终保留一个具体值。
-- 打开仪表盘时,URL 里没有值的变量会先套用默认值,没有默认值的自动取第一个候选(允许「全部」的变量则落到「全部」),并把这个选择写回 URL。
-- **候选外的值**(从 URL 或告警入口带进来)照常参与运行,只是在控件里以「值(不在候选中)」显示并给出警示,不阻断。
+- **单选**变量必须有一个值,默认取第一个候选。
+- **多选**变量可以不选,**不选即「全部」**。「全部」表示不做筛选,而不是勾选当前所有候选。
+- 允许「全部」的变量可以清空选择;不允许的变量必须保留一个值。
+- 地址中没有指定值时,变量取默认值;没有默认值则取第一个候选(允许「全部」的变量取「全部」)。
+- 通过链接带入的值即使不在候选中也会生效,控件会标出该值不在候选中。
-URL 是变量选择的唯一事实源:单值写 `var-<名字>=值`,多值重复同名参数,全部写 `var-<名字>=$__all`——与仪表盘 URL 用的是同一套参数,所以链接可以带着变量一起分享。
+变量的选择会写入页面地址,分享链接时会一起带上。
## 时间范围与自动刷新
-- **时间范围**由 URL 的 `from` / `to` 决定,可以是绝对毫秒,也可以是 `now-*` 相对表达式;没有 URL 参数时用盘上保存的**默认时间范围**(新建时为「过去 1 小时」,保存时可在 15m / 30m / 1h / 3h / 6h / 12h / 24h / 7d 八档里固化,且必须以「现在」为终点)。
-- **自动刷新**:盘上保存的频率是 关闭 / 30s / 1m / 5m 四档;查看页的刷新控件提供更细的档位(关闭 / 10s / 30s / 1m / 5m / 15m / 30m / 1h),选择后会写进 URL 的 `refresh` 参数,并立即刷新一次,不必等满一个周期。相对时间档在刷新时会跟着「现在」滚动窗口。左侧的刷新按钮随时可以手动刷新,页面还有查询在跑时图标转圈。
-- **显示时区**:时间选择器弹层底部是一行时区设置——左侧是当前时区(城市 + 缩写)与 UTC 偏移,右侧 **修改时区** 按钮打开一个可搜索的城市列表(可按城市名、缩写或 IANA 名搜),列表按大洲分组,首组 **常用** 是下表的三个特殊项。它只作用于仪表盘(查看页、编辑态、面板编辑器与面板全屏),决定时间选择器的显示与解析、时序图的横轴刻度与提示框时间、时间范围文案;真正按时区渲染的是绝对时刻,相对档(如「过去 1 小时」)表示的是时长,不随时区平移。显示时区与个人生效时区不一致时,时间选择器上会带该时区的缩写提醒。
+- **时间范围**:默认使用仪表盘保存的默认时间范围。可设为默认的选项有 15m / 30m / 1h / 3h / 6h / 12h / 24h / 7d。
+- **自动刷新**:仪表盘可保存的刷新频率为关闭 / 30s / 1m / 5m;查看时可以临时选择更多档位(10s 到 1h)。选择后立即刷新一次。
+- **显示时区**:在时间选择器底部点击 **修改时区**,可以选择城市时区,或以下三个常用项。设置只作用于仪表盘,保存在当前浏览器中。相对时间范围(如「过去 1 小时」)表示时长,不受时区影响。
| 常用项 | 含义 |
|--------|------|
@@ -182,126 +161,89 @@ URL 是变量选择的唯一事实源:单值写 `var-<名字>=值`,多值重
| **浏览器时间** | 跟随当前浏览器所在时区 |
| **协调世界时** | 固定使用 UTC |
-选择记在本浏览器(localStorage 键 `monit.dashboards.timeZone`),下次打开沿用;选 **默认** 就清掉这条记录,回到个人设置的生效时区。
-
## 同环比对比
-面板的**查询选项**里有 **对比** 一栏:选了「前 1 天」或「前 1 周」后,同一条查询会在往前挪一个周期的时间段**再跑一次**,两次结果并进同一张图。
+在时序图或单值图的**查询选项 → 对比**中选择「前 1 天」或「前 1 周」,同一条查询会在前一个周期再运行一次,结果显示在同一张图中:
-- **支持范围**:只有**时序图**与**单值图**有这一栏,其它图表类型既没有配置入口也不会多发请求。
-- **可选周期**:只开放「前 1 天」与「前 1 周」(外加「不对比」),不开放任意时长。
-- **时序图**:对比那一次画成**同色虚线**,图例写明它是哪个周期,形如「`序列名(1 天前)`」。
-- **单值图**:显示与对比周期的变化百分比,形如「▲ 12.3% 较 1 天前」(持平不带箭头,避免 0% 被读成上涨);对比那一次的值为 0 或缺失时不给百分比。
-- **失败降级**:对比那次查询失败只会少掉一条对比线,本期结果照常渲染;面板整体仍按本期查询的成功 / 失败状态展示。
+- **时序图**:对比曲线显示为同色虚线,图例标注周期,如「序列名(1 天前)」。
+- **单值图**:显示相对对比周期的变化百分比,如「▲ 12.3% 较 1 天前」。对比值为 0 或缺失时不显示百分比。
+- 对比查询失败只会少一条对比线,不影响本期结果。
## 多图光标联动
-同一个仪表盘里的**时序图**共享一个光标同步组,鼠标在任意一张时序图上移动时,其它时序图会同步画出**竖线与圆点**,方便对齐同一时刻的多个指标。
-
-- 只同步鼠标移动与移出,异步按下 / 松开(否则框选缩放会在每张图上各放大一次),**纵轴不同步**,只画竖线。
-- 提示框只留在鼠标所在的那张图上,联动过来的光标不弹提示框。
-- **配了相对时间或时间偏移的面板不参与联动**——它的时间轴与看板不一致,按时间戳联动会指错时刻。
-- 编辑态的预览画布与面板全屏视图不开启联动,只有仪表盘网格里的时序图参与。
-
-## 点值筛选看板与下钻链接
+在任意一张时序图上移动鼠标,同一仪表盘中的其他时序图会同步显示该时刻的竖线,方便对齐多个指标。设置了相对时间或时间偏移的面板不参与联动。
-**点值筛选看板**:点击图表里的数据(时序图的点、单值图、表格的数值单元格 / 标签单元格),如果被点数据带有的**标签名或表格列名与仪表盘变量同名**,点击浮层里会多出「按 `k = v` 筛选」这一项,点它就把该变量设为这个值,整个看板随之重新取数。
+## 点值筛选与下钻链接
-- 参与筛选的变量是**除数据源变量之外**的全部变量(数据源变量在变量栏里是单选的数据源选择,不参与筛选)。
-- 时序图的点带时刻时,浮层头部会显示这条曲线的名字(可一键复制)、该点时刻与按面板单位格式化后的值。
-- 表格的标签单元格只提供筛选,不提供下钻——下钻链接按整行 / 整条曲线的标签展开,只带一个标签会拼出残缺地址。
+**点值筛选**:点击图表中的数据(时序图的点、单值、表格单元格)时,如果数据的标签名或列名与某个仪表盘变量同名,可以选择「按 `k = v` 筛选」,把该变量设为这个值,整个仪表盘随之刷新。数据源变量不参与筛选。
-**下钻链接(数据链接)**:给面板配数据链接后,点数据点可以跳转到 `http(s)://` 或站内 `/` 开头的地址,链接里可以带上被点数据的值、标签与时间。规则如下:
+**数据链接**:为面板配置数据链接后,点击数据点可以跳转到外部地址(`http(s)://`)或站内地址(`/` 开头),链接中可以带上被点数据的值、标签和时间:
-- 时序图可以选择一条链接开启**单击直达**(点数据点直接打开、不弹菜单,同一个面板最多一条开启);单值图与表格只有一条可用的链接时直接打开,多条则弹菜单。
-- 链接是在**点击时**展开的:仪表盘变量与时间范围取当前查看上下文,数据点相关的取被点的那一个点;插入的值一律 URL 编码,写在路径里时用 `${xxx:raw}` 原样拼接。
-- 可用的占位符:`${__value.raw}`(点的值)、`${__value.time}`(点的时间,毫秒)、`${__series.name}`(序列名)、`${__field.labels.<标签名>}`(标签值)、`${__from}` / `${__to}`(当前时间范围的起止毫秒)、`${__url_time_range}`(`from=…&to=…` 时间参数)、`${__all_variables}`(全部仪表盘变量的 URL 参数),以及任意仪表盘变量名。
+- 时序图可以把一条链接设为**单击直达**(每个面板最多一条)。单值图和表格只有一条链接时直接打开,多条时弹出菜单。
+- 插入的值会自动 URL 编码;需要原样拼接到路径中时写成 `${xxx:raw}`。
+- 可用占位符:`${__value.raw}`(值)、`${__value.time}`(时间,毫秒)、`${__series.name}`(序列名)、`${__field.labels.<标签名>}`(标签值)、`${__from}` / `${__to}`(时间范围起止,毫秒)、`${__url_time_range}`(时间范围参数)、`${__all_variables}`(全部变量参数),以及任意仪表盘变量名。
-**面板链接(Panel links)**:配在面板标题旁,一条时直接点开,多条时弹出菜单;默认新标签页打开。取值同上(不涉及数据点)。
+**面板链接**:显示在面板标题旁,默认在新标签页打开,可使用上述除数据点外的占位符。
-## 分享与 URL 状态
+## 分享
-仪表盘把状态都放在 URL 上,因此「分享」就是把地址发出去——查看页的 URL 参数有:
-
-| 参数 | 说明 |
-|------|------|
-| `from` / `to` | 时间范围,绝对毫秒或 `now-*` 相对表达式 |
-| `var-<变量名>` | 变量选择;多值重复同名参数,全部为 `$__all` |
-| `target` | 定位到某个页签 / 分组 / 面板,打开后滚动到该对象并短暂高亮;目标已不存在时提示「链接指向的内容已不存在,已为你打开第一个页签」 |
-| `view` | 面板全屏,值为面板 ID |
-| `refresh` | 自动刷新频率 |
-| `edit` | `1` 时进入编辑态(需管理权限,否则回列表页) |
-
-面板全屏弹窗里的 **复制面板链接** 会一次性写好 `target` 与 `view`,复制出来的地址打开就直接是全屏的那张图。
+仪表盘的时间范围、变量选择、全屏面板和自动刷新都保存在页面地址中,直接复制地址即可分享当前视图。在面板全屏时点击 **复制面板链接**,打开后会直接全屏显示该面板。
<Note>
-仪表盘**没有**匿名或公开分享能力:所有接口都在登录态下校验目录与数据源权限,一条 URL 只能被对目录、数据源都有权限的人看出同样的内容。查不到或无权查看时,页面提示「仪表盘不存在或无权查看」。
+仪表盘**不支持**公开或匿名分享。打开链接的人需要登录,并对仪表盘所在目录及面板使用的数据源有权限。
</Note>
## 全屏与查询详情
-面板标题栏在鼠标悬停时显示操作图标:**编辑**(需管理权限,直接进入编辑态并打开该面板的编辑器)、**全屏**、**重试**(面板已出结果时)。
+鼠标悬停在面板标题上时,可以 **编辑**(需管理权限)、**全屏** 或 **重试**。
-- **全屏**由 URL 的 `view=<面板ID>` 控制,因此可以分享、刷新保持、按返回键退出;文字面板全屏只展示内容,不提供时间选择与下载。
-- 全屏内可以**单独改时间段**(会话态,不写 URL,也不影响主网格),改完只重跑这一个面板。
-- 全屏里可以 **复制面板链接**、**下载数据 CSV**(文件名取面板标题)。
-- 底部 **查询详情** 逐条列出该面板的查询:`Ref`、表达式(已保存)、`request ID`、状态,以及每条查询右侧的 **在查询工作台打开** 图标——它带着已展开的变量与当前时间(或全屏里改过的时间)跳到[查询工作台](/zh/monitors/explore/explore)单独调试。
-- 键盘快捷键:鼠标悬停的面板(或已全屏的面板)上,`v` 切换全屏,`e` 进入编辑(需管理权限)。输入框聚焦时快捷键不生效。
+- 全屏时可以单独修改该面板的时间范围,不影响其他面板。
+- 全屏时可以 **复制面板链接** 或 **下载数据 CSV**。
+- **查询详情**列出每条查询的表达式和状态,点击 **在查询工作台打开** 可以带着当前变量和时间去[查询工作台](/zh/monitors/explore/explore)调试。
+- 快捷键:在面板上按 `v` 切换全屏,按 `e` 进入编辑。
## 版本历史与恢复
-查看页右上角 **⋮ → 版本历史**。列表按版本倒序展示,列为 **版本 / 时间 / 操作人 / 说明**,当前版本带「当前」徽标;打开时默认勾选最新两版。
-
-- **版本对比**:勾选两个版本后点 **对比**,进入版本对比页,左右两侧各自可以选择要比的版本(左侧只能选比右侧旧的),以 **JSON diff** 展示两版保存的定义差异;键顺序不同不算差异,两版内容相同时显示「没有变更」。
-- **恢复**:在对比页点 **恢复到 vN**,二次确认(「恢复会以该版本内容产生一个新版本(当前 vM 仍保留在历史中,可再恢复回来)」)后执行。恢复的实质是用旧版定义走一次保存,因此**会再产生一个新版本**,而且新版本的说明会写成「恢复自 vN」。
-- **保留量**:每个仪表盘只保留最近 **20** 个版本,更早的版本在保存时被淘汰——恢复也只能恢复到还留在历史里的版本。
+在查看页右上角点击 **⋮ → 版本历史**:
-这与告警规则的[规则变更记录 · 版本对比](/zh/monitors/quickstart/quickstart)是同一套交互。
+- **对比**:勾选两个版本后点击 **对比**,查看两版定义的 JSON 差异。
+- **恢复**:在对比页点击 **恢复到 vN**。恢复会以旧版内容**产生一个新版本**,当前版本仍保留在历史中。
+- 每个仪表盘只保留最近 **20** 个版本。
## 删除与回收站
-在列表行点 **删除** 并确认后,仪表盘进入回收站,确认弹窗写明「『标题』将进入回收站,30 天后自动清除」。后端有定时任务按小时清理超过 30 天的回收站数据(连历史版本一起物理删除)。
+删除的仪表盘进入回收站,**30 天**后连同历史版本永久删除。
-- 已删除的仪表盘被直接打开时提示「该仪表盘已被删除」。
-- 控制台目前**没有**回收站列表页,也没有恢复入口;后端提供了回收站列表与恢复接口,恢复时可以指定目标目录,而原目录已经不存在时必须显式指定,否则返回「需要指定恢复目录」。
-- 删除需要对该仪表盘所在目录可读且有管理权限;删除请求会带上当前版本号,因此不会误删别人刚保存的新版本。
+控制台暂无回收站页面。如需恢复,请使用 Open API 查询回收站(`/monit/dashboard/trash/list`)并恢复(`/monit/dashboard/restore`);原目录已不存在时,需要指定恢复到哪个目录。
-## 权限模型
+## 权限
-| 能力 | 需要的权限 |
+| 操作 | 需要的权限 |
|------|-----------|
-| 看到「仪表盘」菜单、打开列表与查看页 | 「数据源查看」权限;且该目录对你可读 |
-| 新建、编辑、移动、删除、克隆、恢复版本 | 「仪表盘管理」权限(`monitDashboard:manage`),且当前目录可读 |
-| 面板取数(查询数据源) | 对面板引用的数据源有只读(readonly)权限 |
+| 查看仪表盘 | 「数据源查看」权限,且对所在目录可读 |
+| 新建、编辑、移动、删除、克隆、恢复版本 | 「仪表盘管理」权限,且对所在目录(及目标目录)可读 |
+| 面板显示数据 | 对面板使用的数据源有查询权限 |
-几点实现上的事实,决定了上面的表现:
-
-- **读取没有独立的权限点**:后端对仪表盘的读取继承目录的读权限(Folder Read 过滤),所以前端路由可见性照查询工作台的先例挂在「数据源查看」上。
-- **目录决定可见性**:账号主体账号与 Admin 对所有目录可读;其他成员的可见范围由目录链路上绑定的团队决定(目录或其任一父级绑定了团队时,成员必须属于对应团队;整条链路都没绑团队则所有成员可读)。目录不在可读范围内时,读接口返回「仪表盘不存在」(不暴露是否存在),写接口返回无权限。目录权限的判定规则见[文件夹管理](/zh/monitors/folders/folders)。
-- **写操作的两道门**:既要求管理权限,也要求对目标目录可读——把仪表盘移动 / 克隆到别的目录时,目标目录同样要可读。
-- **取数与数据源授权联动**:面板运行时只把「你当前有权查询的数据源」纳入解析,面板引用的数据源缺失、被停用或你无权查询时,该面板显示「无该数据源权限」,而不是暴露数据源细节。数据源授权配置见[数据源管理](/zh/monitors/data-sources/data-sources)。
-- **公开分享**:不支持。仪表盘没有对外匿名访问的入口或开关,URL 只在登录态下、且校验目录与数据源权限后才有意义(见[分享与 URL 状态](#分享与-url-状态))。
+- 目录的可读范围由目录上绑定的团队决定,主体账号和 Admin 可以读取所有目录,规则见[文件夹管理](/zh/monitors/folders/folders)。
+- 对面板使用的数据源没有权限(或数据源已停用、不存在)时,该面板显示「无该数据源权限」。数据源授权见[数据源管理](/zh/monitors/data-sources/data-sources)。
## 导出 JSON
-查看页 **⋮ → 导出 JSON** 会把当前版本的定义下载成一个 JSON 文件,文件名取仪表盘标题(没有标题时用 `dashboard`)。文件内容是 `schema_version`、`dashboard_id` 与完整的 `definition`,可以用于备份或提交到版本库对比。控制台**没有**对应的导入入口。
-
-## 面板状态与常见错误
+在查看页点击 **⋮ → 导出 JSON**,可以下载当前版本的完整定义,用于备份或提交到版本库对比。控制台暂不支持导入。
-每个面板独立展示自己的运行状态,常用状态如下:
+## 面板状态与常见问题
-| 状态 / 提示 | 含义 |
+| 面板显示 | 原因与处理 |
|------------|------|
-| 「查询成功,但该范围内没有数据」 | 查询成功但该时间范围无数据 |
-| **部分失败** 徽标 | 面板的多个查询里只有一部分成功,悬停可看每个失败的 `Ref` 与原因;成功的部分照常渲染 |
-| 「结果与图表配置不匹配」 | 结果形态与该图表类型要求的形态不符(例如表格图拿到了纯时序帧),面板不会自动换渲染方式 |
-| 「变量 x 未解析 / 请先在上方完成选择」 | 面板依赖的变量还没有有效值,该面板**不发请求**,等你在变量栏完成选择 |
-| 「无该数据源权限」 | 面板引用的数据源你无权查询(或已停用 / 不存在) |
-| 「查询超时」 | 运行期查询超时 |
-| 「结果超出大小限制,请缩小时间范围或精简查询」 | 结果体积超限,需要缩小范围或精简查询 |
-| 「查询失败」+ 重试 | 其余查询错误按服务端返回的错误信息展示,可点 **重试** 单独重跑这个面板 |
+| 没有数据 | 查询成功,但该时间范围内没有数据 |
+| **部分失败** | 部分查询失败,悬停查看原因;成功的部分照常显示 |
+| 结果与图表配置不匹配 | 查询结果的形态不适合该图表类型(如表格拿到了时序数据),请更换图表类型或调整查询 |
+| 变量未解析 | 面板依赖的变量还没有值,请先在变量栏完成选择 |
+| 无该数据源权限 | 见[权限](#权限) |
+| 查询超时 / 结果超出大小限制 | 缩小时间范围或精简查询 |
+| 查询失败 | 查看错误信息,点击 **重试** 重新运行该面板 |
-另外:如果在你浏览期间别人保存了这个仪表盘,页面会检测到版本过期并**静默重新载入最新定义**,不需要你手动刷新。
+如果别人在您查看期间保存了仪表盘,页面会自动载入最新版本。
## 配额与限制
@@ -315,6 +257,4 @@ URL 是变量选择的唯一事实源:单值写 `var-<名字>=值`,多值重
| 表格的数据链接(含链接列) | 5 条 |
| 保留的历史版本 | 20 |
| 回收站保留时长 | 30 天 |
-| 单个定义(保存时提交的 JSON) | 1 MiB |
-
-超过面板 / 页签 / 变量上限时,页面上会直接提示「图表数量已达上限」「页签数量已达上限」或禁用新增按钮;定义超限时保存会返回超出大小限制的错误。
+| 单个仪表盘定义 | 1 MiB |
diff --git a/zh/monitors/data-sources/data-sources.mdx b/zh/monitors/data-sources/data-sources.mdx
index c333d473..16fe22d0 100644
--- a/zh/monitors/data-sources/data-sources.mdx
+++ b/zh/monitors/data-sources/data-sources.mdx
@@ -4,7 +4,7 @@ description: "配置和管理 Monitors 的数据源,包括 Prometheus、Elasti
keywords: ["数据源", "Prometheus", "Elasticsearch", "Loki", "ClickHouse", "MySQL", "Oracle", "PostgreSQL", "SLS", "Tencent CLS", "VictoriaLogs", "Redis", "MongoDB", "Kafka", "数据源工具"]
---
-数据源是告警引擎查询数据的来源。你需要先配置数据源,告警引擎才能从中读取数据进行异常判定。
+数据源是告警引擎查询数据的来源。您需要先配置数据源,告警引擎才能从中读取数据进行异常判定。
**菜单入口**:数据源
@@ -30,99 +30,46 @@ Monitors 支持以下 15 种数据源类型:
| **MongoDB Mongos**(`mongodb_mongos`) | MongoDB 分片集群路由,仅诊断类型 |
| **Kafka**(`kafka`) | Apache Kafka 集群,仅诊断类型 |
-其中 Redis Node、Redis Sentinel、MongoDB(mongod/mongos)与 Kafka 这 5 种**仅诊断类型**用于数据库与中间件诊断,不能用于告警评估:它们不允许开启 `alerting_enabled`(恒为 `false`),无法参与告警规则的查询与评估;它们也进不了查询工作台,只在 AI SRE 里通过诊断工具使用(见下方「数据源行操作:查询与 AI 分析」)。连接地址等配置要求见[各数据源类型配置](#各数据源类型配置)。
+其中 Redis Node、Redis Sentinel、MongoDB(mongod/mongos)与 Kafka 这 5 种是**仅诊断类型**:它们不能用于告警规则,也不能在查询工作台中查询,只供 AI SRE 诊断数据库与中间件时使用(见[查询与 AI 分析](#数据源行操作查询与-ai-分析))。
## 数据源列表
-数据源列表只展示你有权查询的数据源,包括以下信息:
+列表只显示您有权查询的数据源,包括以下列:
-- **名称**:数据源的标识名称;配置了团队授权的行,名称后面还会跟「负责团队」「可查询团队」标签(见[名称列上的授权标签](#名称列上的授权标签))
-- **类型**:数据源类型及图标
-- **连接地址**:数据源的访问地址
-- **关联告警引擎**:绑定的告警引擎集群名称,附带引擎在线状态指示
-- **启用数据源**:行内开关,控制该数据源是否参与业务查询与诊断,控制台里开启/停用数据源的入口就在这一列
-- **备注**:补充说明
+- **名称**:配置了团队授权的数据源,名称后会显示绿色的**负责团队**和灰色的**可查询团队**标签。团队已被删除时显示**已删除团队**,该授权随之失效,可由创建者或管理员修正。
+- **类型**、**连接地址**、**备注**
+- **关联告警引擎**:负责查询的引擎集群及其在线状态
+- **启用数据源**:开启或停用该数据源,见[启用与告警评估](#启用与告警评估)
-列表按查询权限过滤:对某个数据源没有查询(readonly)权限时,这一行整条不会返回,既看不到也搜不到,因此列表条数可能少于账号内实际的数据源数量。账号主体、Admin 角色、数据源创建者、管理团队与只读团队的成员始终可见。授权模型见下方「数据源权限(团队授权)」一节。
-
-你可以通过搜索框按名称、类型、连接地址或备注过滤数据源。列表每 5 秒自动刷新,实时反映引擎连接状态。
-
-### 名称列上的授权标签
-
-名称列直接标出这条数据源的授权角色,扫一眼就能分辨哪些数据源是「有主」的:
-
-- 配置了 `manage_team_id` 的行,名称后跟一枚绿色**负责团队**标签,标签上是团队名。
-- `readonly_team_ids` 里的每个团队各一枚灰色**可查询团队**标签,标签上同样是团队名。
-- 悬浮任意一枚标签都会标明它的角色(负责团队 / 可查询团队)。
-- 两个字段都没配置的行不打任何标签——全租户可查可管是常态,不需要标出来。
-- 团队名是异步查来的:负责团队的名字还没到时会先显示占位骨架,避免闪一下错误的「已删除团队」;查完仍取不到名字时显示**已删除团队**,此时该条授权自然失效(团队被删除后,创建者或管理员可以接手修正,语义见上方「校验与归一化」)。
-
-### 启用数据源
-
-列表右侧的**启用数据源**列是控制台里开启、停用数据源的入口,切换后立即生效。列头右侧有提示图标,说明停用会造成什么影响:
-
-| 状态 | 含义 |
-|------|------|
-| **开启** | 数据源正常参与业务查询与数据源诊断。 |
-| **关闭** | 该数据源不再执行查询、诊断与告警,但连接参数、凭据、关联告警引擎等配置完整保留,随时可以重新开启;关闭不会改变 `alerting_enabled`。 |
-
-- **权限**:这一列是否可操作由数据源编辑权限(`MonitDatasourceUpdate`)决定;没有该权限时开关为禁用状态,只能查看。开关本身调用的是数据源详情与更新接口,这两个接口还会做实例级 `manage` 校验:即使持有 `MonitDatasourceUpdate`,只要你不是创建者、不是主体账号或 Admin 角色、也不属于该数据源的管理团队,切换依然会被后端拒绝(`only the managing team can manage this datasource`)。判定规则见下方「数据源权限(团队授权)」一节。
-- **新建的数据源默认启用**:新建时一律以 `enabled=true` 创建,新建/编辑抽屉里没有这个开关;要停用数据源,请在创建完成后到列表里切换。
-- **列表徽章**:名称列不再单独显示「已停用」徽章,启停状态只由这颗开关表达。名称列上的「不用于告警」徽章表示 `alerting_enabled=false`,它只在数据源处于启用状态、且该类型支持告警评估时才显示:被停用的数据源不显示该徽章(启停状态由这颗开关表达),5 种仅诊断类型也不显示(它们本就与告警评估无关)。
+可以按名称、类型、连接地址或备注搜索。列表每 5 秒自动刷新引擎连接状态。
## 数据源权限(团队授权)
-数据源可以按团队限制两类操作:**查询与引用**(readonly)和**管理**(manage)。不配置任何授权时,行为与默认完全一致——全租户可查可管;存量数据源的两个授权字段为 `NULL`,无需做任何处理。
+默认情况下,所有成员都可以查询和管理每个数据源。如需限制,可以在新建或编辑数据源时设置:
-| 字段 | 取值 | 含义 |
-|------|------|------|
-| `manage_team_id` | 团队 ID,可为 `NULL` | 该数据源唯一的管理团队。为 `NULL` 表示管理操作不受限 |
-| `readonly_team_ids` | 团队 ID 数组,可为 `NULL` | 允许查询与引用该数据源的团队集合。为 `NULL` 表示查询与引用不受限 |
-| `creator_id` | 成员 ID,可为 `NULL` | 创建者,创建时自动写入;存量数据为 `NULL` 时,管理权只由管理团队与管理员判定 |
+| 字段 | 作用 |
+|----------|----------|
+| **负责团队**(单选) | 只有负责团队的成员可以编辑、删除、启停该数据源 |
+| **可查询团队**(多选) | 只有这些团队(以及负责团队)的成员可以查询该数据源,或在告警规则、仪表盘中引用它 |
-合法的授权配置只有三种:
+留空即不限制。有效的组合有三种:
-| 配置 | 谁能查询/引用 | 谁能管理 |
+| 配置 | 谁能查询与引用 | 谁能管理 |
|------|--------------|----------|
-| 两个字段都不配置(`NULL`) | 全租户 | 全租户 |
-| 只配置 `manage_team_id` | 全租户 | 数据源创建者、主体账号、Admin 角色、管理团队成员 |
-| `manage_team_id` 与 `readonly_team_ids` 都配置 | 数据源创建者、主体账号、Admin 角色、管理团队与只读团队的成员 | 数据源创建者、主体账号、Admin 角色、管理团队成员 |
-
-`manage` 恒含 `readonly`:能管理就一定能查询。团队范围取自当前用户的团队归属;团队信息读取失败时按「无团队命中」从严处理,不放开权限。
-
-**校验与归一化**:
-
-- `readonly_team_ids` 非空而 `manage_team_id` 为空会被拒绝(HTTP 400,错误信息指明两个字段的依赖关系)——限制了查询的数据源必须有明确的负责团队。
-- 更新时按「旧值 + 入参」合并后的终态校验,清空 `manage_team_id` 而保留 `readonly_team_ids` 同样被拒。
-- 写入前会归一化:`manage_team_id` 为 `0` 视为 `NULL`;`readonly_team_ids` 去重、剔除 `0`、排序,空集合视为 `NULL`。不校验团队是否真实存在,悬空 ID 自然失效(团队被删除后,创建者或管理员可以接手修正)。
-
-### 授权之后会发生什么
+| 都不设置 | 所有成员 | 所有成员 |
+| 只设置负责团队 | 所有成员 | 创建者、主体账号、Admin、负责团队成员 |
+| 两者都设置 | 创建者、主体账号、Admin、负责团队与可查询团队成员 | 创建者、主体账号、Admin、负责团队成员 |
-- **列表**:只返回你有权查询的数据源。没有 readonly 权限的数据源整条不出现在响应里;每行附带 `my_perm` 字段,取值为 `manage` 或 `readonly`,授权字段(`manage_team_id`、`readonly_team_ids`、`creator_id`)也随行返回。前端只消费这些判断,不自己计算。
-- **管理类操作**:返回连接凭据的数据源详情、编辑、删除、启停都要求 `manage`,否则返回无权限错误(`only the managing team can manage this datasource`)。对没有 `manage` 权限的行,控制台另外提供一个只读视图(见「编辑和删除」一节):它按列表行渲染、连接凭据一律打码,不改变服务端的这道门。
-- **查询与引用**:即时查询、数据探索、仪表盘面板取数、数据源工具调用,以及在告警规则中引用该数据源,都要求 `readonly`;无权时返回明确的拒绝,不暴露数据源细节。
-- **告警规则保存**:保存规则时要求作者对规则引用到的每个数据源都有 `readonly`,包括名称通配在保存当下匹配到的数据源;不满足则拒绝保存并指明无权引用的数据源名称。唯一的豁免是纯停用(字段更新只含 `enabled` 且置为 `false`)。规则保存后由系统身份执行,成员权限之后的变化不影响已保存规则运行。
-- **审计**:授权字段的变更会写入一条 `datasource_auth_update` 审计记录。
+- 设置了可查询团队时,**必须同时设置负责团队**。
+- 除主体账号与 Admin 外,负责团队只能从您所在的团队中选择。
+- 能管理的人一定能查询。授权只能到团队,如需为个别成员授权,可以为其建一个小团队。
+- 授权的变更会记录在审计日志中。
-### 如何配置
+设置授权后:
-新建与编辑抽屉里各有一个团队输入项,保存后生效,留空即不限制:
-
-| 表单字段 | 字段名 | 选择方式 | 作用 |
-|----------|--------|----------|------|
-| **负责团队** | `manage_team_id` | 单选 | 负责团队的成员可以编辑、删除、启停该数据源。不选则所有人可管理;创建者和管理员始终可管理 |
-| **可查询团队** | `readonly_team_ids` | 多选 | 限制哪些团队能查询和引用该数据源。不选则所有人可查询;负责团队始终可查询 |
-
-两个字段的取值随数据源的创建与更新请求一起提交(`POST /monit/datasource/create`、`POST /monit/datasource/update`):创建时可以一并设置;修改已有数据源的授权字段是管理操作,需要具备该数据源的 `manage`。提交前会做归一化:清空 `manage_team_id` 落成显式 `null`,`readonly_team_ids` 去重后为空同样落成 `null`。更新请求里缺键表示保持原值、`null` 表示清空,所以**清空选择就是取消对应授权**。不用控制台时,也可以直接通过 API 提交这两个字段。
-
-两条控制台侧的约束:
-
-- **可查询团队非空时「负责团队」必填**:只选了可查询团队而没选负责团队,表单在提交前就会在**负责团队**下方报「配置了可查询团队后,必须指定负责团队」,不必等后端 400。
-- **负责团队只能选自己所在的团队**:除主体账号与 Admin 角色外,**负责团队**的候选项只有当前用户所属的团队——把负责团队指给自己不在的团队,保存后就会当场失去这条数据源的管理权(创建者有兜底,普通管理成员没有)。已经选中、但自己不属于的团队仍会正常显示团队名。
-
-<Note>
-授权粒度只到团队,不支持按成员单独授权;需要给个别成员授权时,可以为其建立一个小团队。
-</Note>
+- 没有查询权限的成员在列表中看不到该数据源,查询工作台、仪表盘和数据源工具也无法使用它。
+- 只有查询权限的成员可以以只读方式查看数据源配置,连接凭据会被隐藏。
+- **保存告警规则时**,您需要对规则引用的每个数据源(包括名称通配在保存时匹配到的数据源)都有查询权限。只停用规则不受此限制。规则保存后,成员权限的变化不影响它继续运行。
## 新建数据源
@@ -134,50 +81,44 @@ Monitors 支持以下 15 种数据源类型:
| 配置项 | 说明 |
|--------|------|
-| **名称** | 数据源的唯一标识名称,告警规则可通过名称通配或精确匹配两种方式关联数据源(详见下方说明) |
+| **名称** | 数据源的唯一名称,告警规则可以按名称通配或精确匹配关联数据源(见下文) |
| **备注** | 可选的补充说明 |
-| **关联告警引擎** | 选择负责查询该数据源的引擎集群,通常选择与数据源同机房的集群 |
+| **关联告警引擎** | 负责查询该数据源的引擎集群,通常选择与数据源同机房的集群 |
</Step>
<Step title="配置连接参数">
-根据数据源类型填写对应的连接参数,详见下方各类型说明。
+根据数据源类型填写连接参数,见[各数据源类型配置](#各数据源类型配置)。
</Step>
<Step title="保存">
-点击**确定**完成创建。
+点击**确定**完成创建。新数据源默认启用。
</Step>
</Steps>
### 告警规则关联数据源的两种方式
-告警规则支持两种方式绑定数据源,可以同时使用,至少填写一种。规则会作用于两种方式匹配到的所有数据源的并集。
+告警规则至少使用以下一种方式绑定数据源,两种方式可以同时使用,规则作用于两者匹配结果的并集。
-| 绑定方式 | 字段 | 匹配逻辑 | 适用场景 |
-|----------|------|----------|----------|
-| **名称通配** | `数据源(名称通配)` | 按名称做通配符匹配。`*` 匹配所有数据源;`Prom*` 匹配名称以 Prom 开头的数据源 | 需要动态匹配一批数据源,例如同类型数据源统一命名前缀 |
-| **精确匹配** | `数据源(精确匹配)` | 按数据源 ID 精确关联,从下拉列表中选择具体数据源 | 需要精确绑定特定数据源,不受数据源改名影响 |
+| 绑定方式 | 匹配逻辑 | 适用场景 |
+|----------|----------|----------|
+| **名称通配** | 按名称通配符匹配,`*` 匹配所有数据源,`Prom*` 匹配以 Prom 开头的数据源 | 动态匹配一批统一命名的数据源 |
+| **精确匹配** | 从下拉列表选择具体数据源 | 绑定特定数据源,不受改名影响 |
<Warning>
-名称通配方式存储的是名称字符串,如果数据源改名,已有的通配规则可能不再匹配。精确匹配方式存储的是数据源 ID,不受改名影响。如果对稳定性要求高,建议优先使用精确匹配。
+数据源改名后,已有的名称通配可能不再匹配。对稳定性要求高的规则,建议使用精确匹配。
</Warning>
-<Note>
-保存规则时,作者还需要对规则引用到的每个数据源具备查询(readonly)权限——既包括**精确匹配**选中的数据源,也包括**名称通配**在保存当下匹配到的数据源;只要有一个不满足,保存就会被拒绝并提示无权引用该数据源。唯一的例外是纯停用:只把 `enabled` 改为 `false` 的批量字段更新始终放行。详见下方「数据源权限(团队授权)」一节。
-</Note>
-
-## 启用与告警评估开关
+## 启用与告警评估
-数据源有两个相互独立的开关,分别控制业务执行与告警评估:
+数据源有两个相互独立的开关:
-| 开关 | 字段 | 含义 |
+| 开关 | 位置 | 关闭后 |
|------|------|------|
-| **启用** | `enabled` | 是否开启业务执行。关闭后数据源不接受业务查询与数据源工具调用,但不会改变 `alerting_enabled` |
-| **用于告警** | `alerting_enabled` | 是否允许该数据源参与告警规则的查询与评估;关闭后列表名称列会显示「不用于告警」徽章。告警评估同时要求 `enabled=true` 且数据源类型支持告警;`false` 不会阻断非告警查询与数据源工具 |
+| **启用数据源** | 数据源列表中的开关 | 数据源不再执行任何查询、诊断与告警,但配置完整保留,随时可以重新开启 |
+| **用于告警** | 新建 / 编辑表单 | 数据源不再参与告警规则评估(列表中显示「不用于告警」),其他查询不受影响 |
-- **控制台入口**:`enabled` 的开关是数据源列表里的**启用数据源**列(见[启用数据源](#启用数据源)),新建/编辑抽屉里没有这个开关;`alerting_enabled` 则在新建/编辑抽屉中设置。
-- **创建时的默认值**:`enabled` 默认为 `true`;`alerting_enabled` 对支持告警的类型默认为 `true`,对仅诊断类型默认为 `false`。
-- **更新时的行为**:两个字段省略时均保留当前值;显式传入 `null` 非法。
-- **仅诊断类型**(`redis_node`、`redis_sentinel`、`mongodb_mongod`、`mongodb_mongos`、`kafka`)不允许设置 `alerting_enabled=true`。
-- **冲突保护**:存在启用中的告警规则引用该数据源时,关闭 `alerting_enabled` 会被拒绝并返回冲突(HTTP 409),需要先处理引用该数据源的告警规则。实际执行告警评估时,数据源还必须处于 `enabled=true` 状态。
+- 新数据源默认启用;支持告警的类型默认用于告警,仅诊断类型不能用于告警。
+- 停用数据源需要您对它有管理权限。
+- 仍有启用中的告警规则引用某数据源时,不能关闭它的「用于告警」,请先处理这些规则。
## 各数据源类型配置
@@ -340,26 +281,26 @@ SecretKey 为只写字段:保存后列表与详情均不返回字面量密钥
| **unsupported** | 告警引擎版本过低,暂不支持腾讯云 CLS |
| **unavailable** | 没有找到已注册的告警引擎 |
-该门禁在告警规则页同样生效:集群可能因回滚或新加入旧实例而退化,届时即使数据源已存在,保存规则也会被后端拒绝。
+该门禁在告警规则页同样生效:集群可能因回滚或新加入旧实例而退化,届时即使数据源已存在,保存规则也会失败。
#### 连接测试
保存数据源后可使用**连接测试**验证连接:
-1. 新建状态下测试不可用,需先保存数据源(提示「保存数据源后才能测试连接」)。
+1. 先保存数据源,才能测试连接。
2. 选择用于测试的地域。数据源本身不保存地域,测试时现场选择一次。
-3. 点击**测试**。请求按所选地域路由到单个 Edge 实例执行,结果标注**仅当前执行实例**,不代表整个集群都已验证。
-4. 失败时结果会透出腾讯云返回的原始错误码与 RequestId,可直接用于排查。
+3. 点击**测试**。测试只在一个告警引擎实例上执行,不代表整个集群都已验证。
+4. 失败时会显示腾讯云返回的错误码与 RequestId,便于排查。
测试结果分为**连接正常**、**连接可用,但有告警**与**连接失败**三种。
#### 地域选择
-规则查询与连接测试共用同一个地域选择器,提供常用地域建议列表:广州(ap-guangzhou)、上海(ap-shanghai)、北京(ap-beijing)、南京(ap-nanjing)、成都(ap-chengdu)、重庆(ap-chongqing)、中国香港(ap-hongkong)、新加坡(ap-singapore)、曼谷(ap-bangkok)、雅加达(ap-jakarta)、首尔(ap-seoul)、东京(ap-tokyo)、硅谷(na-siliconvalley)、弗吉尼亚(na-ashburn)、法兰克福(eu-frankfurt)、圣保罗(sa-saopaulo)、利雅得(me-saudi-arabia)。该列表只是建议而非白名单——腾讯云随时可能开设新地域,因此也可以输入任意符合 `[a-z0-9-]` 形状的地域 code,能否使用由腾讯云判定。
+规则查询与连接测试共用同一个地域选择器,提供常用地域建议列表:广州(ap-guangzhou)、上海(ap-shanghai)、北京(ap-beijing)、南京(ap-nanjing)、成都(ap-chengdu)、重庆(ap-chongqing)、中国香港(ap-hongkong)、新加坡(ap-singapore)、曼谷(ap-bangkok)、雅加达(ap-jakarta)、首尔(ap-seoul)、东京(ap-tokyo)、硅谷(na-siliconvalley)、弗吉尼亚(na-ashburn)、法兰克福(eu-frankfurt)、圣保罗(sa-saopaulo)、利雅得(me-saudi-arabia)。列表之外的地域也可以直接输入地域代码(如 `ap-xxx`)。
#### 规则绑定约束
-Tencent CLS 类型的告警规则只能精确绑定一个数据源,不支持名称通配。创建规则时数据源选择为单选、名称通配输入被隐藏;配置非法时保存会提示「该数据源类型只能绑定一个数据源」或「该数据源类型不支持名称通配,请清空后重新选择」。详见 [Tencent CLS 告警规则](/zh/monitors/alert-rules/tencent-cls)。
+Tencent CLS 类型的告警规则只能精确绑定一个数据源,不支持名称通配。详见 [Tencent CLS 告警规则](/zh/monitors/alert-rules/tencent-cls)。
### Redis Node / Redis Sentinel
@@ -385,7 +326,7 @@ Tencent CLS 类型的告警规则只能精确绑定一个数据源,不支持
| **超时时间(毫秒)** | 连接超时,范围 1000–10000 | `3000` |
| **TLS** | 是否启用 TLS | 关闭 |
| **CA 证书** | PEM 格式 CA 证书或 `${env:NAME}` 引用 | - |
-| **最低 / 最高 TLS 版本** | 表单候选 TLS 1.0、1.1、1.2、1.3,且不做预选(可清空);服务端要求最低版本不低于 1.2,选 1.0 或 1.1 会在保存时被拒绝;最高版本不得低于最低版本 | 留空按 1.2 / 不限制 |
+| **最低 / 最高 TLS 版本** | 最低版本不能低于 TLS 1.2,最高版本不能低于最低版本 | 留空按 1.2 / 不限制 |
| **服务端名称** | TLS 握手 SNI / 证书校验主机名;留空取连接地址中的主机名 | - |
| **跳过服务端证书校验** | 启用 TLS 时是否不校验服务端证书 | 否 |
@@ -404,17 +345,17 @@ MongoDB 不支持客户端证书认证(mTLS)。
| **TLS** | 是否启用 TLS | 关闭 |
| **CA 证书** | PEM 格式 CA 证书或 `${env:NAME}` 引用 | - |
| **客户端证书 / 私钥** | PEM 格式,必须成对配置;私钥保存后不回显字面值,支持 `${env:NAME}` 引用 | - |
-| **最低 / 最高 TLS 版本** | 表单候选 TLS 1.0、1.1、1.2、1.3,且不做预选(可清空);服务端要求最低版本不低于 1.2,选 1.0 或 1.1 会在保存时被拒绝;最高版本不得低于最低版本 | 留空按 1.2 / 不限制 |
+| **最低 / 最高 TLS 版本** | 最低版本不能低于 TLS 1.2,最高版本不能低于最低版本 | 留空按 1.2 / 不限制 |
| **服务端名称** | TLS 握手 SNI / 证书校验主机名;留空取连接地址中的主机名 | - |
| **跳过服务端证书校验** | 启用 TLS 时是否不校验服务端证书 | 否 |
### 凭据的保存语义
-以上 5 种诊断类型与 Tencent CLS 一致:密码(以及 Kafka 的客户端私钥)为只写字段,保存后列表与详情均不返回字面值;以 `${env:}` 引用保存的值不是秘密,会正常回显。更新时省略该字段表示保持原值,显式传空字符串表示清除。
+以上 5 种诊断类型与 Tencent CLS 的密码(以及 Kafka 的客户端私钥)保存后不再显示;以 `${env:}` 引用填写的值会正常显示。编辑时留空表示保持原值。
## 在 Edge 本地引用凭据
-使用 `v0.46.0` 或更高版本的 Edge 时,你可以在受支持的数据源连接字段中使用环境变量引用,而不必将凭据直接写入数据源配置。Edge 会在本地进程中解析引用值;解析后的凭据不会回写到同步的数据源配置、调试输出或 API 载荷中。
+使用 `v0.46.0` 或更高版本的 Edge 时,您可以在受支持的数据源连接字段中使用环境变量引用,而不必将凭据直接写入数据源配置。Edge 会在本地进程中解析引用值;解析后的凭据不会回写到同步的数据源配置、调试输出或 API 载荷中。
<Steps>
<Step title="设置 Edge 进程环境变量">
@@ -436,40 +377,22 @@ MongoDB 不支持客户端证书认证(mTLS)。
## 数据源行操作:查询与 AI 分析
-数据源列表的操作列里只有一个主操作按钮,它按数据源类型分流:
+每行的主操作按数据源类型而定:
-| 数据源类型 | 主操作 | 点击后 |
+| 数据源类型 | 主操作 | 用途 |
|------------|--------|--------|
-| 可查询类型:Prometheus、Elasticsearch、Loki、ClickHouse、MySQL、Oracle、PostgreSQL、Aliyun SLS、Tencent CLS、VictoriaLogs | **查询** | 打开[查询工作台](/zh/monitors/explore/explore)并带上这条数据源,查询语句留空;在工作台里执行一条查询即可验证连接是否正常、预览查询结果 |
-| 仅诊断类型:`redis_node`、`redis_sentinel`、`mongodb_mongod`、`mongodb_mongos`、`kafka` | **AI 分析** | 停靠在当前页打开 AI SRE 面板,把这条数据源作为引用上下文提问 |
-
-### 仅诊断类型如何验证连接
+| 可查询类型:Prometheus、Elasticsearch、Loki、ClickHouse、MySQL、Oracle、PostgreSQL、Aliyun SLS、Tencent CLS、VictoriaLogs | **查询** | 打开[查询工作台](/zh/monitors/explore/explore)并选好该数据源,执行一条查询即可验证连接 |
+| 仅诊断类型:Redis Node、Redis Sentinel、MongoDB、Kafka | **AI 分析** | 打开 AI SRE 面板,以该数据源为上下文提问。这也是验证这类数据源能否连通的方式 |
-仅诊断类型进不了查询工作台,所以列表里没有**查询**入口,也没有通用的连接测试按钮(腾讯云 CLS 表单另有自己的连接测试,见上方腾讯云 CLS 一节的**连接测试**)。要确认这类数据源能否连上,用行内的 **AI 分析** 把它交给 AI SRE,让诊断工具实际连一次,例如 `redis_node.overview`、`redis_sentinel.overview`、`mongodb_mongod.overview`、`kafka.overview`。
-
-### 「AI 分析」的显示条件
-
-- 只有**进不了查询工作台**的类型(即上表 5 种仅诊断类型)才会显示这个按钮;能查询的类型显示的是**查询**,两者不并存。
-- 需要账户已开通 AI SRE,否则这一行只有编辑与删除,没有任何主操作。
-- 需要 AI SRE 对话访问权限(`AiSreChatVisit`):没有该权限时按钮可见但为禁用状态。
+**AI 分析** 需要账户已开通 AI SRE,且您有 AI SRE 对话权限。
## 编辑和删除
- **编辑**:在数据源列表中点击**编辑**按钮,修改数据源配置后保存。
-- **查看**:对只有 readonly 权限的行,同一个编辑入口的悬浮提示变成**查看**,点开的是只读抽屉(标题**查看数据源**)。
+- **查看**:只有查询权限时,可以以只读方式查看数据源配置,连接凭据会被隐藏。
- **删除**:在数据源列表中点击**删除**按钮,确认后删除数据源。
-编辑、删除、启停都需要先通过数据源的 `manage` 校验:你必须是该数据源的创建者、主体账号或 Admin 角色,或者属于它的管理团队;否则请求会被拒绝(`only the managing team can manage this datasource`)。编辑抽屉加载的是数据源详情,详情会返回连接凭据,因此「查看连接凭据」与编辑、删除、启停走同一道门。判定规则见「数据源权限(团队授权)」一节。
-
-编辑入口本身不做行级门控,但仍要求账号具备数据源编辑权限(`MonitDatasourceUpdate`):没有该权限时这个入口也是禁用的。
-
-### 只读视图能看到什么
-
-对某条数据源只有 readonly 权限时,控制台不会让入口消失,而是把它降级成只读:
-
-- 抽屉标题是**查看数据源**,整张表单不可编辑,数据源类型选择器与腾讯云 CLS 的连接测试一并禁用。
-- 基础字段取自列表行;连接配置按原表单样式展示,但字符串类字段一律显示 `******`(开关、数字、枚举类字段留空)。只读视图刻意不调用数据源详情接口(该接口按 `manage` 卡),真实凭据不会下发到浏览器。
-- **确定**按钮为禁用状态,提交路径也做了同样的硬闸;**删除**按钮与**启用数据源**开关改为禁用控件,悬浮提示会列出谁能操作(组织管理员、创建者、负责团队)。
+编辑、删除和启停需要数据源编辑权限,并且您是该数据源的创建者、主体账号、Admin,或属于它的负责团队,见[数据源权限](#数据源权限团队授权)。
<Warning>
删除数据源前,请确保没有告警规则引用该数据源,否则相关告警规则将无法正常执行。
diff --git a/zh/monitors/engine/engine-lost-alert.mdx b/zh/monitors/engine/engine-lost-alert.mdx
index ec99d7f9..9d15d9ad 100644
--- a/zh/monitors/engine/engine-lost-alert.mdx
+++ b/zh/monitors/engine/engine-lost-alert.mdx
@@ -14,19 +14,7 @@ keywords: ["引擎失联", "告警引擎", "monitedge", "失联告警", "健康
## 告警规则列表
-列表展示所有已配置的引擎失联告警规则,支持按关键字搜索和自定义显示列。
-
-| 列信息 | 说明 |
-|--------|------|
-| **规则标题** | 告警规则的名称 |
-| **告警级别** | Critical(红色)、Warning(橙色)、Info(黄色)|
-| **匹配引擎名字** | 该规则监控的引擎集群名称模式,支持通配符 `*` |
-| **排除引擎名字** | 排除不需要监控的引擎集群名称模式 |
-| **失联时长(秒)** | 引擎集群无心跳超过该时长后触发告警 |
-| **发给协作空间** | 告警事件投递到的协作空间 |
-| **事件生成次数** | 失联期间最多生成的告警事件次数 |
-| **事件生成频率(秒)** | 重复生成告警事件的时间间隔 |
-| **启用** | 规则的启用/禁用开关 |
+列表展示已配置的规则及其主要参数(含义见下文 [新建告警规则](#新建告警规则)),支持按关键字搜索、自定义显示列,并可用开关直接启用或禁用规则。
## 新建告警规则
@@ -75,6 +63,4 @@ keywords: ["引擎失联", "告警引擎", "monitedge", "失联告警", "健康
## 编辑和删除
-- **编辑**:在列表中点击**编辑**按钮修改规则配置。只有规则创建者、主账号或管理员角色可以编辑。
-- **删除**:在列表中点击**删除**按钮。只有规则创建者、主账号或管理员角色可以删除。
-- **启用/禁用**:通过列表中的开关快速切换规则状态。
+在列表中点击 **编辑** 或 **删除** 即可修改或删除规则。只有规则创建者、主账号或管理员角色可以编辑和删除。
diff --git a/zh/monitors/engine/engine.mdx b/zh/monitors/engine/engine.mdx
index e9baa3de..d5c1b6bd 100644
--- a/zh/monitors/engine/engine.mdx
+++ b/zh/monitors/engine/engine.mdx
@@ -4,7 +4,7 @@ description: "管理告警引擎的安装、状态监控和 API Key,确保告
keywords: ["告警引擎", "monitedge", "引擎安装", "引擎状态", "API Key"]
---
-告警引擎(`monitedge`)是部署在你私有网络中的核心组件,负责从 Flashduty SaaS 端同步告警规则,从本地数据源读取数据进行异常判定,并将告警事件推送到 SaaS 端进行后续处理。
+告警引擎(`monitedge`)是部署在您私有网络中的核心组件,负责从 Flashduty SaaS 端同步告警规则,从本地数据源读取数据进行异常判定,并将告警事件推送到 SaaS 端进行后续处理。
**菜单入口**:告警引擎
@@ -23,12 +23,12 @@ keywords: ["告警引擎", "monitedge", "引擎安装", "引擎状态", "API Key
| **引擎实例版本** | 当前运行的 `monitedge` 版本号 |
<Note>
-引擎实例超过 30 秒未上报心跳,状态会标记为离线(红色)。离线的引擎实例会显示**删除**按钮,你可以点击清除已不存在的实例记录。
+引擎实例超过 30 秒未上报心跳,状态会标记为离线(红色)。离线的引擎实例会显示**删除**按钮,您可以点击清除已不存在的实例记录。
</Note>
### 集群数据源 MD5 校验
-同一集群内的多个引擎实例应该使用相同的数据源配置。如果系统检测到集群内不同实例的数据源配置 MD5 不一致,会在集群名称前显示红色警示标记,提示你尽快检查引擎配置。
+同一集群内的多个引擎实例应该使用相同的数据源配置。如果系统检测到集群内不同实例的数据源配置 MD5 不一致,会在集群名称前显示红色警示标记,提示您尽快检查引擎配置。
## 引擎安装/升级
@@ -51,7 +51,7 @@ keywords: ["告警引擎", "monitedge", "引擎安装", "引擎状态", "API Key
从下拉列表中选择已有的 API Key,或点击**管理 API Key**创建新的 Key。
</Step>
<Step title="复制命令执行">
-页面会根据你的选择自动生成安装命令和升级命令,复制后在目标机器上执行即可。
+页面会根据您的选择自动生成安装命令和升级命令,复制后在目标机器上执行即可。
</Step>
</Steps>
@@ -90,7 +90,7 @@ Linux 部署的告警引擎支持由服务端推送的自动升级,部署方
## API Key 管理
-API Key 用于告警引擎与 SaaS 端的身份认证。你可以在引擎安装/升级页面点击**管理 API Key**打开管理面板。
+API Key 用于告警引擎与 SaaS 端的身份认证。您可以在引擎安装/升级页面点击**管理 API Key**打开管理面板。
### 功能说明
@@ -116,7 +116,7 @@ API Key 用于告警引擎与 SaaS 端的身份认证。你可以在引擎安装
- 创建 API Key 需要 `ApiKeyCreate` 权限
- 删除 API Key 需要 `ApiKeyDelete` 权限
-如果你没有操作权限,请联系管理员前往访问控制页面授权。
+如果您没有操作权限,请联系管理员前往访问控制页面授权。
## 引擎 CLI 参数参考
@@ -126,7 +126,7 @@ API Key 用于告警引擎与 SaaS 端的身份认证。你可以在引擎安装
| 参数 | 默认值 | 说明 |
|------|--------|------|
-| `alerter.serverURL` | `https://api.flashcat.cloud` | FlashDuty SaaS 服务地址 |
+| `alerter.serverURL` | `https://api.flashcat.cloud` | Flashduty SaaS 服务地址 |
| `alerter.serverAPIKey` | —(必填) | 用于与 SaaS 端认证的 API Key |
| `alerter.serverTimeout` | `30s` | 单次推送请求的超时时间 |
| `alerter.alertRuleDeliveryWorkers` | `64` | 普通告警规则事件投递的 worker 数量。事件按告警 key 分区到各 worker 队列,同一条告警的事件始终由同一个 worker 串行投递 |
diff --git a/zh/monitors/entity-tree/entity-tree.mdx b/zh/monitors/entity-tree/entity-tree.mdx
index f9398bd6..02d71c03 100644
--- a/zh/monitors/entity-tree/entity-tree.mdx
+++ b/zh/monitors/entity-tree/entity-tree.mdx
@@ -6,7 +6,7 @@ keywords: ["实体树", "实体告警", "动态分组", "规则继承", "Prometh
当主机、容器、实例或业务模块持续扩缩容时,逐个维护监控对象和告警规则很容易失效。实体树从 Prometheus 查询结果中自动发现这些动态资源,将它们整理为稳定的实体,并根据标签自动归入不同分组。
-你可以在上层分组配置通用告警规则,让规则自动作用于匹配的后代实体;当某个环境或业务需要不同阈值时,只需在对应分组覆盖参数。这样既能减少重复规则,也能让告警策略跟随实体变化。
+您可以在上层分组配置通用告警规则,让规则自动作用于匹配的后代实体;当某个环境或业务需要不同阈值时,只需在对应分组覆盖参数。这样既能减少重复规则,也能让告警策略跟随实体变化。
当前版本以实体告警为主要使用场景。实体树先建立统一、稳定的实体视图,也为后续围绕实体查看指标和分析上下文提供一致入口。
@@ -23,7 +23,7 @@ keywords: ["实体树", "实体告警", "动态分组", "规则继承", "Prometh
- Kubernetes Pod、云主机、数据库实例等对象频繁创建、销毁或变化
- 多个环境或业务使用相同指标,但告警阈值不同
-- 你希望按区域、环境、集群、团队或服务等标签自动管理告警范围
+- 您希望按区域、环境、集群、团队或服务等标签自动管理告警范围
- 多个 Prometheus 数据源需要复用同一套实体定义和告警策略
如果监控对象固定、每条规则只对应一个明确查询,继续使用普通告警规则通常更直接。
@@ -39,7 +39,7 @@ keywords: ["实体树", "实体告警", "动态分组", "规则继承", "Prometh
| **规则覆盖** | 在子分组调整继承规则的告警级别、参数或连续命中次数 | 生产环境阈值 90%,测试环境阈值 95% |
<Note>
-同一组身份标签值在不同数据源中会形成不同实体。你可以在工作区切换数据源,分别查看实体、规则执行结果和活跃告警。
+同一组身份标签值在不同数据源中会形成不同实体。您可以在工作区切换数据源,分别查看实体、规则执行结果和活跃告警。
</Note>
## 使用前准备
@@ -48,7 +48,7 @@ keywords: ["实体树", "实体告警", "动态分组", "规则继承", "Prometh
- 当前租户已启用 Monitors,并已部署告警引擎
- 已创建至少一个 Prometheus 数据源
-- 你的账号拥有实体树查看权限;创建或修改配置还需要实体树管理权限、相应实体类别或分组的管理权限,以及对所选用数据源的查询权限
+- 您的账号拥有实体树查看权限;创建或修改配置还需要实体树管理权限、相应实体类别或分组的管理权限,以及对所选用数据源的查询权限
- 告警引擎版本满足实体树页面提示的要求
<Warning>
@@ -59,7 +59,7 @@ keywords: ["实体树", "实体告警", "动态分组", "规则继承", "Prometh
### 1. 申请开通
-进入 **Monitors > 实体树**。如果当前租户尚未开通,点击 **申请开通**。申请提交后,页面会显示申请时间;审核通过后即可开始配置。
+进入 **Monitors → 实体树**。如果当前租户尚未开通,点击 **申请开通**。申请提交后,页面会显示申请时间;审核通过后即可开始配置。
### 2. 创建实体类别
@@ -80,7 +80,7 @@ keywords: ["实体树", "实体告警", "动态分组", "规则继承", "Prometh
精确匹配和名称通配可以同时使用,系统会使用两者匹配到的全部数据源。至少配置一种匹配方式。
<Note>
-保存实体类别时还会校验数据源权限:主体账号和租户管理员不受此限制,其他成员必须对本次选中的每个 Prometheus 数据源都拥有查询(只读)权限;名称通配按保存当下匹配到的数据源逐个校验,匹配到任一你无权查询的数据源即拒绝保存,并返回无权限引用该数据源的错误。缩小或移除数据源选择不受此限制——失去某个数据源的权限后,仍然可以把该数据源从实体类别中去掉。实体类别的数据源列表同样按查看者权限过滤,你无权查询的数据源不会出现在它的数据源配置和已解析数据源列表中。
+保存实体类别时还会校验数据源权限:主体账号和租户管理员不受此限制,其他成员必须对本次选中的每个 Prometheus 数据源都拥有查询(只读)权限;名称通配按保存当下匹配到的数据源逐个校验,匹配到任一您无权查询的数据源即拒绝保存,并返回无权限引用该数据源的错误。缩小或移除数据源选择不受此限制——失去某个数据源的权限后,仍然可以把该数据源从实体类别中去掉。实体类别的数据源列表同样按查看者权限过滤,您无权查询的数据源不会出现在它的数据源配置和已解析数据源列表中。
</Note>
配置时有以下约束:名称通配不支持 `{}` 花括号语法;名称最多 128 个字符,发现 PromQL 最多 1024 个字符;编辑已有实体类别时,不能在同一次保存中同时修改身份标签和多值标签,需要分两次完成。
@@ -93,7 +93,7 @@ keywords: ["实体树", "实体告警", "动态分组", "规则继承", "Prometh
up{job="node"}
~~~
-填写查询后,点击 **预览**,再从查询结果中选择身份标签。预览会帮助你检查:
+填写查询后,点击 **预览**,再从查询结果中选择身份标签。预览会帮助您检查:
- 每条结果是否都包含身份标签
- 同一身份是否出现普通单值标签冲突
@@ -122,7 +122,7 @@ up{job="node"}
同一分组中的多个条件必须全部满足。子分组还会继承全部上级分组的条件。
-例如,你可以先创建 env = prod 的“生产环境”分组,再在其下创建 service = payment 的“支付服务”分组。第二个分组最终只包含同时满足两个条件的实体。
+例如,您可以先创建 env = prod 的“生产环境”分组,再在其下创建 service = payment 的“支付服务”分组。第二个分组最终只包含同时满足两个条件的实体。
<Note>
实体可以同时命中多个同级分组。请让同级分组表达清晰、互不冲突的管理维度,并在配置不同规则覆盖时检查最终告警范围。
@@ -142,7 +142,7 @@ up{job="node"}
| **高级配置** | 配置执行周期、时区、执行延迟和重复通知。执行周期支持 `@every` 固定间隔(如 `@every 60s`)或六字段 Cron(秒 分 时 日 月 周,如 `0 */5 * * * *`);使用 Cron 必须选择有效 IANA 时区(默认 `Asia/Shanghai`),Cron 中不能内嵌时区,`@every` 周期无需填写时区。新建规则默认每 60 秒执行一次,每 3600 秒重复通知一次、最多重复 3 次 |
| **标签与注解** | 为告警补充路由标签和说明;规则名称与注解支持模板变量 |
-规则创建在当前分组,并自动作用于当前分组和所有匹配的后代实体。规则列表会分别展示 **本组规则** 和 **继承规则**,帮助你判断规则来自哪个层级。
+规则创建在当前分组,并自动作用于当前分组和所有匹配的后代实体。规则列表会分别展示 **本组规则** 和 **继承规则**,帮助您判断规则来自哪个层级。
告警条件 PromQL 输入框的右上角同样提供 **AI 帮我写** 入口,可以让 AI 查询助手生成或改写语句;实体树中助手只回填查询语句,不会切换数据源。详见 [AI 查询助手](/zh/monitors/quickstart/quickstart#ai-查询助手)。
@@ -179,7 +179,7 @@ up{job="node"}
### 5. 导入告警规则
-除了逐条创建,你还可以在分组的 **规则** 标签页点击 **导入规则**,上传 YAML 文件批量导入到当前分组。系统会自动识别三种来源格式:
+除了逐条创建,您还可以在分组的 **规则** 标签页点击 **导入规则**,上传 YAML 文件批量导入到当前分组。系统会自动识别三种来源格式:
| 来源格式 | 说明 |
| --- | --- |
@@ -219,7 +219,7 @@ up{job="node"}
### 6. 覆盖继承规则
-如果子分组需要不同阈值,在子分组的 **继承规则** 列表中选择 **覆盖继承规则**。你可以调整:
+如果子分组需要不同阈值,在子分组的 **继承规则** 列表中选择 **覆盖继承规则**。您可以调整:
- 告警级别是否继承、启用或停用
- 各告警级别的参数和连续命中次数
@@ -328,7 +328,7 @@ URL 中的各 ID 均为正整数。参数缺失、非法或未携带 `open=edit`
## 规则名称与注解模板变量
-规则名称和注解支持 Go `text/template` 语法。模板在告警引擎侧、每次产生告警事件时渲染,可以引用当次评估的标签、数值和实体上下文。渲染失败时,对应字段会显示 `<error expanding template: ...>`,你可以在规则的执行错误摘要中查看原因。
+规则名称和注解支持 Go `text/template` 语法。模板在告警引擎侧、每次产生告警事件时渲染,可以引用当次评估的标签、数值和实体上下文。渲染失败时,对应字段会显示 `<error expanding template: ...>`,您可以在规则的执行错误摘要中查看原因。
### 内置变量
@@ -430,10 +430,10 @@ https://example.com/runbooks/node-cpu?entity={{ .EntityAlert.entity_key }}
以下操作会改变实体身份、分组范围或告警生命周期:
-- **修改身份标签**:页面会先预览身份迁移对实体和恢复规则的影响,列出所有受影响的恢复规则并分为 **自动改写** 与 **需要人工处理**(附原因)。你可以编辑迁移后的恢复 PromQL;**需要人工处理**的规则必须勾选“我已检查并确认此恢复 PromQL”后才能提交。确认迁移后,旧身份关联的活跃告警会关闭,新身份会重新发现实体。该操作不能无损撤销
+- **修改身份标签**:页面会先预览身份迁移对实体和恢复规则的影响,列出所有受影响的恢复规则并分为 **自动改写** 与 **需要人工处理**(附原因)。您可以编辑迁移后的恢复 PromQL;**需要人工处理**的规则必须勾选“我已检查并确认此恢复 PromQL”后才能提交。确认迁移后,旧身份关联的活跃告警会关闭,新身份会重新发现实体。该操作不能无损撤销
- **修改多值标签**:实体会重新分类,相关告警会按新配置重新评估
- **修改分组条件或规则覆盖**:实体的有效范围或策略可能变化,当前告警可能结束并按新配置重新评估
-- **修改本组规则**:保存前页面会预览本次修改对后代节点覆盖配置的影响,并列出受影响的覆盖数量。如果修改导致部分级别覆盖或参数覆盖失效,对话框会要求你确认后永久清理;清理后的覆盖配置无法恢复
+- **修改本组规则**:保存前页面会预览本次修改对后代节点覆盖配置的影响,并列出受影响的覆盖数量。如果修改导致部分级别覆盖或参数覆盖失效,对话框会要求您确认后永久清理;清理后的覆盖配置无法恢复
- **停用或删除规则**:相关活跃告警会异步结束;重新启用不会恢复已经结束的告警
- **删除实体类别或分组**:必须先清理页面提示的依赖项,受影响的活跃告警会异步结束
diff --git a/zh/monitors/explore/explore.mdx b/zh/monitors/explore/explore.mdx
index 04181238..f748438f 100644
--- a/zh/monitors/explore/explore.mdx
+++ b/zh/monitors/explore/explore.mdx
@@ -9,7 +9,7 @@ keywords: ["查询工作台", "Explore", "即时查询", "Prometheus", "Loki", "
## 访问入口
- **从数据源列表**:进入 **监控 → 数据源**,点击目标数据源行的「查询工作台」入口。
-- **直接 URL**:访问 `/monit/explore`,在页面内选择数据源。
+- **直接打开**:进入查询工作台后,在页面内选择数据源。
- **从故障/告警标签**:在故障详情或告警详情的标签区域,查询类标签行右侧的「去查询」图标会带着告警触发时的查询和时间窗口直接打开工作台。
## 查询类型
@@ -29,7 +29,7 @@ keywords: ["查询工作台", "Explore", "即时查询", "Prometheus", "Loki", "
| SLS / CLS | — | 无查询类型选择器,由供应商分类日志/表格 |
| MySQL / PostgreSQL / Oracle / ClickHouse / ES | — | SQL/查询表达式直接执行 |
-> 查询在路由到 Edge 执行前会先经过语法校验:Prometheus 数据源的查询表达式必须通过 PromQL/MetricsQL 语法检查,非法表达式会被提前拒绝并返回解析器错误详情,不会下发执行;其他数据源类型不受此校验影响。
+> Prometheus 查询会先做 PromQL / MetricsQL 语法检查,表达式有误时直接返回错误详情,不会执行。
## 结果展示
@@ -38,13 +38,13 @@ keywords: ["查询工作台", "Explore", "即时查询", "Prometheus", "Loki", "
- **Prometheus**:上下分屏,上方折线图(Graph)、下方原始样本(Raw),支持拖拽分隔。
- **其他数据源**:单结果区,根据查询类型展示日志视图、表格视图或样本视图。
-样本视图和表格视图在浏览器端分页展示,不再一次性渲染全部行:样本视图每页 20 条;表格视图默认每页 100 条,可切换 100 / 200 / 500。结果不足一页时自动隐藏分页器。
+样本视图每页 20 条;表格视图默认每页 100 条,可切换为 200 或 500 条。
### 图表功能
- **拖拽缩放**:在折线图上拖选时间段可缩放至该范围。
-- **曲线图例筛选**:图例区支持按标签值筛选维度和关键词搜索,可按 metric 名称分组;曲线超过 10 条时出现关键词搜索框,图例区高度上限为面板高度的 45%,超出的行滚动查看。
-- **Tooltip**:悬停时显示离光标最近的那一条曲线在该时间点的值与标签,沿时间轴移动光标即可逐条查看其它曲线;需要同时对比多条曲线时用图例筛选,或改看原始数据。
+- **曲线图例筛选**:可以按标签值筛选、按 metric 名称分组;曲线超过 10 条时可以按关键词搜索。
+- **提示框**:显示离光标最近的曲线在该时刻的值与标签。需要同时对比多条曲线时,使用图例筛选或查看原始数据。
### 日志时间分布
@@ -56,15 +56,14 @@ keywords: ["查询工作台", "Explore", "即时查询", "Prometheus", "Loki", "
### 日志视图
-日志类查询的结果以行为单位展示,每行包含时间、正文及字段摘要。若本批结果中存在每行取值都相同的字段(公共字段,如 Loki 的 stream labels),这些字段默认会逐行展示在摘要中,但会重复占据每行的宽度。
+日志按行展示,每行包含时间、正文和字段摘要。
-- 工具条上的 **公共字段** 按钮会列出本批结果中每行相同的字段及其取值;勾选浮层中的 **行内隐藏** 后,这些公共字段将从行内摘要中折叠,行内只保留有差异的内容(并显示「+N 个字段」提示)
-- **行内隐藏** 默认关闭(公共字段默认展示);该开关为会话内状态,不持久化,刷新页面后恢复默认展示
-- 点击行可展开详情,详情始终展示该行的全部字段,不受 **行内隐藏** 开关影响
+- 点击工具条上的 **公共字段**,可以查看本批结果中每行都相同的字段(如 Loki 的 stream labels);勾选 **行内隐藏** 后,这些字段不再在每行重复显示。刷新页面后恢复显示。
+- 点击某一行可以展开查看它的全部字段。
### 查询失败提示
-查询失败时,结果区按失败原因给出对应提示(如查询超时、结果行数超过上限、Edge 版本过低等)。其中,数据源级授权拒绝(HTTP 403,错误码 `AccessDenied`)会显示专门提示「无权访问该数据源,请联系数据源的负责团队或管理员。」,而不是通用的「查询失败,请稍后重试」。数据源的团队授权规则参见[数据源权限(团队授权)](/zh/monitors/data-sources/data-sources#数据源权限团队授权)。
+查询失败时,结果区会说明原因,如查询超时、结果行数超过上限或告警引擎版本过低。无权查询该数据源时,见[数据源权限](#数据源权限)。
## 查询参数
@@ -83,54 +82,44 @@ keywords: ["查询工作台", "Explore", "即时查询", "Prometheus", "Loki", "
### 内置时间变量
-Prometheus 和 Loki 查询支持内置时间变量:变量在查询执行前由本次查询的时间窗口与 step 渲染成具体时长,因此查询会跟随页面选择的时间范围,不必把时间写死。变量名以 `$` 起头,也可以写成 `${...}` 形式。
+Prometheus 和 Loki 的区间查询可以使用内置时间变量,让查询跟随页面选择的时间范围,不必把时间写死。写法为 `$__interval` 或 `${__interval}`。
-| 变量 | 渲染成的值 |
+| 变量 | 含义 |
|------|-----------|
-| `$__interval` | 本次查询的 step(秒),例如 `30s`;与下发给 Edge 的 step 相同,取后端按数据点数反推的值与 **最小 step** 中较大者 |
-| `$__rate_interval` | step 加 15 秒、且不低于 60 秒,例如 `60s`;15 秒是 `$__rate_interval` 假定的抓取间隔 |
-| `$__range` | 本次查询的时间窗口长度(秒),最小 1 秒,例如 `3600s` |
-| `$__auto` | Loki 区间查询里等于 step(例如 `30s`);Loki 即时查询里本应取整个时间窗口的最大可整除单位(例如 `1h`),但即时查询不带起始时间,用不了(见下) |
+| `$__interval` | 查询步长,如 `30s`,不小于 **最小 step** |
+| `$__rate_interval` | 步长加 15 秒,且不低于 60 秒,适合用于 `rate()` |
+| `$__range` | 时间窗口的长度,如 `3600s` |
+| `$__auto` | Loki 区间查询中等于步长 |
-可用范围由数据源和查询类型共同决定:
-
-| 查询 | 可用的内置时间变量 |
+| 查询 | 可用变量 |
|------|------------------|
-| Prometheus 区间(**仅图表**,以及 **图表 + 原始** 的图表部分) | `$__interval`、`$__rate_interval`、`$__range` |
-| Prometheus 即时(**仅原始**,以及 **图表 + 原始** 的原始部分) | 无 |
+| Prometheus 区间(**仅图表**) | `$__interval`、`$__rate_interval`、`$__range` |
| Loki 区间 | `$__auto`、`$__interval`、`$__range` |
-| Loki 即时 | 无 |
+| Prometheus / Loki 即时查询 | 无 |
-- 即时查询里没有能用的内置时间变量:Prometheus 即时查询不接受区间变量,Loki 即时查询不带起始时间,`$__auto`、`$__range` 这类需要窗口长度的变量渲染不出来。写了这些变量,结果区会提示「查询或参数不合法,请检查后重试。」,并在提示下方给出后端原因(例如 `built-in variable "__rate_interval" is not available in prometheus instant queries`、`built-in variable "__range" requires from_ms`)。
-- Prometheus 默认的 **图表 + 原始** 会同时下发一条区间查询和一条即时查询,两者共用同一份查询语句:`$__rate_interval` 在图表那一半正常渲染,在原始那一半失败。要在这类查询里用 `$__rate_interval`,把查询类型切到 **仅图表**。
-- 内置时间变量与仪表盘的内置时间变量同名,由同一套渲染逻辑按本次查询的时间窗口和 step 计算。除上表中的变量名外,其他 `$` 文本(包括 `${名称}`、`$1` 这类正则捕获组引用)原样送给数据源,不做替换——工作台没有仪表盘变量。
+- 即时查询中使用这些变量会报错。
+- Prometheus 默认的 **图表 + 原始** 会同时执行区间查询和即时查询,因此其中的即时部分无法使用 `$__rate_interval`。需要使用时,请切换到 **仅图表**。
+- 这些变量与[仪表盘](/zh/monitors/dashboards/dashboards#内置时间变量)中的同名变量含义相同。工作台没有仪表盘变量,其他 `$` 文本会原样发给数据源。
## AI 查询助手
-查询编辑器输入框的右上角有一颗悬停或聚焦时渐显的彩虹色 **AI 帮我写** 按钮(需先选择数据源)。点击后打开 **查询助手** 面板,助手能看到当前数据源、查询类型、私有参数、时间窗口,以及这条查询实际会怎么执行(instant / range / range+instant / window;Prometheus 的默认模式 **图表 + 原始** 同时执行一条 range 查询和一条 instant 查询,对应 `range+instant`),据此生成或改写查询语句。
+选择数据源后,点击查询输入框右上角的 **AI 帮我写**,查询助手会结合当前数据源、查询类型、参数和时间范围,帮您生成或改写查询。
-- 结果会自动落位,并按整套处理:查询语句、私有参数和查询类型一起写回。如果助手选定的数据源与当前不同,会先切换到该数据源再落位,同时清空当前结果,并把该数据源记为下次进入工作台时的默认数据源
-- 结果交付时会自动执行一次查询,直接把结果显示在下方;结果卡片上的 **回填** 按钮可以把这一版查询重新填回编辑器(不自动运行),之后按回车或点击 **运行查询** 手动执行
-- 回填会用助手的语句覆盖编辑器中的查询语句,并把助手给出的私有参数合并进现有参数(未出现在回填结果中的参数保持原值),请确认结果符合预期后再继续使用或分享
+- 助手会把查询语句、参数和查询类型一起填入,并自动运行一次。如果助手选用了另一个数据源,工作台会切换到该数据源。
+- 点击结果卡片上的 **回填** 可以把这一版查询重新填入编辑器(不会自动运行)。
## 查询历史
-每次成功执行的查询会自动存入查询历史,仅保存查询表达式,不含时间范围和结果。历史按数据源隔离,存储在浏览器本地,最多保留 200 条。超出 200 条时最早的记录会被淘汰;查询表达式过大时不会存入历史但查询本身已成功执行。可以在历史面板中删除单条或清空当前数据源的全部历史。
+成功执行的查询会自动存入查询历史(只保存查询表达式)。历史按数据源分开保存在当前浏览器中,每个数据源最多 200 条,可以删除单条或清空。
## 分享与 URL 状态
-工作台会将当前数据源、查询表达式、时间范围和查询类型编码到 URL 参数中。复制浏览器地址栏即可分享当前查询状态,打开链接后会自动恢复。若链接中的数据源不存在、已停用或无权限,页面会提示且不自动执行。
-
-## 数据源权限与拒绝提示
-
-工作台的数据源选项只包含你有查询(readonly)权限的数据源,无权查询的数据源不会出现在候选里,也查不到它的内容(授权模型见[数据源管理](/zh/monitors/data-sources/data-sources)的「数据源权限(团队授权)」一节)。
-
-如果一条查询在服务端被数据源级授权拦下(HTTP 403、错误码 `AccessDenied`,例如页面打开后权限被改动),工作台不会落进通用的查询失败提示,而是直接给出:
+当前数据源、查询表达式、时间范围和查询类型都保存在页面地址中,复制地址即可分享。链接中的数据源不存在、已停用或无权访问时,查询不会自动执行。
-> 无权访问该数据源,请联系数据源的负责团队或管理员。
+## 数据源权限
-结果区下方同时展示后端返回的原始信息与本次请求的 RequestId,便于排查。要恢复访问,请联系数据源的负责团队或管理员,在数据源管理页调整该数据源的「负责团队」与「可查询团队」。
+数据源列表中只出现您有查询权限的数据源。如果查询时提示「无权访问该数据源」(例如权限在您打开页面后被修改),请联系数据源的负责团队或管理员调整该数据源的「负责团队」与「可查询团队」,见[数据源权限(团队授权)](/zh/monitors/data-sources/data-sources#数据源权限团队授权)。
## Edge 版本要求
-查询工作台依赖 monit-edge 执行实际查询。若数据源所在集群的 Edge 版本过低或版本不一致(混合版本),页面会显示升级提示并禁用查询。需要将集群内所有 Edge 升级至要求版本后才能使用。
+查询由数据源关联的告警引擎(Edge)执行。如果集群中的 Edge 版本过低或版本不一致,页面会提示升级,升级集群内所有 Edge 后即可查询。
diff --git a/zh/monitors/faq/faq.mdx b/zh/monitors/faq/faq.mdx
index 74c0b3fd..60bd4898 100644
--- a/zh/monitors/faq/faq.mdx
+++ b/zh/monitors/faq/faq.mdx
@@ -6,7 +6,7 @@ keywords: ["常见问题", "FAQ", "调试日志", "故障排查", "monitedge"]
---
<AccordionGroup>
-<Accordion title="告警规则的执行不符合预期,如何调试?">
+<Accordion id="debug-rule" title="告警规则的执行不符合预期,如何调试?">
在告警规则的列表页面,有一个**调试日志开关**,您可以打开这个开关,之后告警引擎进程 `monitedge` 会输出该规则的详细执行日志,方便您排查问题。
`monitedge` 会把日志输出到标准输出(`stdout`),查看方式取决于部署方式:
@@ -22,33 +22,39 @@ keywords: ["常见问题", "FAQ", "调试日志", "故障排查", "monitedge"]
</Note>
</Accordion>
-<Accordion title="概览仪表盘展示了哪些信息?">
+<Accordion id="overview-dashboard" title="概览仪表盘展示了哪些信息?">
**菜单入口**:概览
概览页面提供告警规则的全局视图,由以下卡片组成:
-| 卡片名称 | 说明 |
+| 卡片 | 说明 |
|----------|------|
-| **告警规则总量历史趋势图** | 面积图展示告警规则总数随时间的变化趋势,横轴为日期,纵轴为规则数量,帮助您掌握规则增长或缩减的整体走势 |
-| **各协作空间告警规则数量对比** | 饼图展示各协作空间关联的告警规则数量分布。默认显示 Top 10 的协作空间,超出部分汇总为"其他",可点击展开查看全部详情 |
-| **系统事件列表** | 展示告警引擎产生的系统事件(如引擎失联、配置异常等),支持分页浏览和删除操作,帮助您及时发现并处理基础设施层面的问题 |
+| **告警规则总量历史趋势图** | 告警规则总数随时间的变化趋势(面积图) |
+| **各协作空间告警规则数量对比** | 各协作空间的告警规则数量分布(饼图)。默认显示 Top 10,其余汇总为「其他」,可点击展开 |
+| **系统事件列表** | 告警引擎产生的系统事件(如引擎失联、配置异常),可分页浏览和删除 |
<Tip>
概览页面顶部会检查您是否已安装告警引擎。如果尚未安装,系统会显示引导提示,引导您前往告警引擎页面完成安装。
</Tip>
</Accordion>
-<Accordion title="如何快速克隆一条告警规则?">
-在告警规则的编辑页面或详情页面,你可以找到**克隆**操作按钮。点击后会基于当前规则的配置创建一条新规则,所有配置项会被复制过来(名称除外),方便你快速创建相似的告警规则。
+<Accordion id="clone-rule" title="如何快速克隆一条告警规则?">
+在告警规则的编辑页面或详情页面,您可以找到**克隆**操作按钮。点击后会基于当前规则的配置创建一条新规则,所有配置项会被复制过来(名称除外),方便您快速创建相似的告警规则。
</Accordion>
-<Accordion title="如何预览告警规则的查询结果?">
-在创建或编辑告警规则时,配置好查询条件后,可以点击**查询预览**按钮。系统会立即执行一次查询并展示结果,帮助你验证查询表达式是否正确、返回的数据是否符合预期,无需等到下一个检测周期。
+<Accordion id="preview-query" title="如何预览告警规则的查询结果?">
+在创建或编辑告警规则时,配置好查询条件后,可以点击**查询预览**按钮。系统会立即执行一次查询并展示结果,帮助您验证查询表达式是否正确、返回的数据是否符合预期,无需等到下一个检测周期。
-如果后端返回无法识别的结果格式,预览会提示「无法识别查询结果格式,可能是前后端版本不一致,请联系管理员」。SLS / VictoriaLogs / Loki 的调试参数(debug JSON)格式非法或包含嵌套结构时,预览会直接报错并中止查询(「JSON 格式错误」「不支持嵌套结构」),不会静默忽略。如果数据源返回授权拒绝(HTTP 403,错误码 `AccessDenied`),预览会给出固定提示「无权访问该数据源,请联系数据源的负责团队或管理员。」,可参照[数据源权限(团队授权)](/zh/monitors/data-sources/data-sources#数据源权限团队授权)检查该数据源的授权配置。
+预览报错时,常见原因:
+
+| 提示 | 原因与处理 |
+| --- | --- |
+| 无法识别查询结果格式 | 前后端版本可能不一致,请联系管理员 |
+| JSON 格式错误 / 不支持嵌套结构 | SLS / VictoriaLogs / Loki 的调试参数(debug JSON)非法或包含嵌套结构,修正后重试 |
+| 无权访问该数据源 | 数据源拒绝了授权(HTTP 403)。参照[数据源权限(团队授权)](/zh/monitors/data-sources/data-sources#数据源权限团队授权)检查授权配置,或联系数据源的负责团队 |
</Accordion>
-<Accordion title="告警规则的备注描述支持什么格式?">
-备注描述支持 Markdown 格式,你可以使用标题、列表、链接、代码块等 Markdown 语法来组织内容。同时支持引用变量,将告警事件的标签值、查询结果等动态信息嵌入到备注中,方便值班人员快速了解告警上下文。
+<Accordion id="notes-format" title="告警规则的备注描述支持什么格式?">
+备注描述支持 Markdown 格式,您可以使用标题、列表、链接、代码块等 Markdown 语法来组织内容。同时支持引用变量,将告警事件的标签值、查询结果等动态信息嵌入到备注中,方便值班人员快速了解告警上下文。
</Accordion>
</AccordionGroup>
diff --git a/zh/monitors/folders/folders.mdx b/zh/monitors/folders/folders.mdx
index 64993124..4f25302f 100644
--- a/zh/monitors/folders/folders.mdx
+++ b/zh/monitors/folders/folders.mdx
@@ -4,13 +4,13 @@ description: "使用树形文件夹结构组织告警规则,支持团队级别
keywords: ["文件夹", "分组", "告警规则", "权限", "团队"]
---
-Monitors 使用树形文件夹结构来组织和管理告警规则。每条告警规则都必须归属于某个文件夹,你可以通过层级结构进行分类管理,并为不同层级配置团队访问权限。
+Monitors 使用树形文件夹结构来组织和管理告警规则。每条告警规则都必须归属于某个文件夹,您可以通过层级结构进行分类管理,并为不同层级配置团队访问权限。
**菜单入口**:告警规则(左侧树形导航)
## 文件夹树
-页面左侧展示文件夹树形结构。你可以:
+页面左侧展示文件夹树形结构。您可以:
- **新建文件夹**:在树中创建子文件夹
- **选择文件夹**:点击文件夹查看其详情和所属的告警规则
diff --git a/zh/monitors/quickstart/quickstart.mdx b/zh/monitors/quickstart/quickstart.mdx
index 6c3f435f..41c10f07 100644
--- a/zh/monitors/quickstart/quickstart.mdx
+++ b/zh/monitors/quickstart/quickstart.mdx
@@ -67,7 +67,7 @@ keywords: ["入门指南", "monitedge", "数据源", "告警规则", "快速开
告警规则可能会很多,Monitors 提供树形分组结构进行分类管理。每个告警规则都要属于某个分组,您可以先创建分组,再在分组下创建告警规则。
-创建/编辑告警规则的页面是一个单页表单,按编号分为五个区块:**基础配置**、**数据源与查询**、**告警判定**、**检测频率 & 生效时间**、**事件配置**,自上而下排列,在一个页面内滚动填写即可,不再使用分步骤向导。
+创建 / 编辑告警规则的页面是一个单页表单,自上而下分为五个区块:**基础配置**、**数据源与查询**、**告警判定**、**检测频率 & 生效时间**、**事件配置**。
### 基础配置
@@ -75,7 +75,7 @@ keywords: ["入门指南", "monitedge", "数据源", "告警规则", "快速开
| 配置项 | 说明 |
|--------|------|
-| **所属分组** | 以面包屑形式展示当前规则所属的分组路径(如「默认分组 / 数据库告警」)。当分组不可用(已被删除或您对其无权限)时,面板会以错误样式提示「当前分组不可用,请返回告警规则列表重新选择」,需要返回告警规则列表重新选择分组 |
+| **所属分组** | 规则所在的分组路径(如「默认分组 / 数据库告警」)。如果分组已被删除或您无权访问,需要返回规则列表重新选择分组 |
| **规则名称** | 告警规则的名称,不支持引用变量(固定名称便于过滤、聚合操作)。同一分组内必须唯一;导入、编辑或移动规则时如与目标分组中已有规则重名,操作会失败 |
| **附加标签** | 类似 Prometheus 中的 `labels`,会附加到所有告警事件上,便于过滤、路由、抑制 |
@@ -87,64 +87,55 @@ keywords: ["入门指南", "monitedge", "数据源", "告警规则", "快速开

-子标题右侧是一个说明绑定生效范围的提示图标,以及 **前往数据源管理页面** 入口——它在新标签页打开,避免当前表单里未保存的修改被丢弃。
+先选择 **数据源类型**。这里只列出已配置过数据源的类型;如果还没有任何数据源,点击 **前往数据源管理页面**(在新标签页打开,不会丢失当前表单)先创建。
-先选择 **数据源类型**。这里只会列出**已经配置过至少一个数据源**的类型——没有配置过的类型不会出现,避免你选中一个查不到任何数据源的类型。编辑一条已有规则时,它当前使用的类型始终可见,即使该类型下的数据源后来被删光了。
+然后选择规则生效到哪些数据源,一个规则可以生效到多个数据源:
-如果列表为空(提示「暂无可用数据源」),说明当前账户还没有配置任何数据源,可以点击 **前往数据源管理页面** 先创建;如果只是当前选中的类型没有可用数据源,页面会提示「当前数据源类型暂无可用数据源,请先创建数据源或切换类型」。类型列表加载失败时会显示 **重新加载** 按钮。
+- **名称通配**:按名称匹配,新建规则时默认为 `*`(该类型下的所有数据源)。`*` 匹配任意字符串(如 `db-*`),`?` 匹配单个字符,`[0-9]`、`[a-z]` 匹配字符范围,`[!0-9]` 匹配不在范围内的字符。数据源改名会影响匹配。
+- **精确匹配**:从下拉列表选择具体数据源,不受改名影响。
-选定类型后,Monitors 支持一个规则生效到多个数据源,提供两种绑定方式:
-
-- **名称通配**:通过通配符匹配数据源名称。`*` 匹配任意长度的字符串(`*` 匹配所有数据源,`db-*` 匹配所有以 `db-` 开头的数据源),`?` 匹配任意单个字符;还支持字符类,例如 `db-[0-9]` 匹配 `db-0` 到 `db-9`、`svc-[a-z]` 匹配 `svc-a` 到 `svc-z`(字符范围按 Unicode 码点判断),`[!0-9]` 表示匹配非数字字符。存储的是名称字符串,数据源改名会影响匹配。
-- **精确匹配**:从下拉列表中按 ID 选择具体数据源,不受数据源改名影响。
-
-两种方式可以同时使用,至少需要填写一种。规则会生效到两种方式匹配到的所有数据源。
-
-新建规则时(以及之后每次切换**数据源类型**卡片时),**名称通配**会预填一个 `*`,也就是默认生效到该类型下的所有数据源;唯一例外是腾讯云 CLS——它只允许精确绑定一个数据源,表单不会给出通配值,保存时必须恰好选中一个。在通配选择框里 `*` 与其它通配项互斥:选中 `*` 会清空其它项,选择任何非 `*` 的项会去掉 `*`。两种方式都为空时,保存会报「名称通配和精确匹配不能同时为空」。
+两种方式至少填一种,可以同时使用,规则生效到两者匹配结果的并集。腾讯云 CLS 例外:只能精确绑定一个数据源。
<Tip>
-如果对规则绑定的稳定性要求高(避免数据源改名导致规则失效),建议使用精确匹配。详情参见[数据源管理](/zh/monitors/data-sources/data-sources)。
+需要不受数据源改名影响的稳定绑定时,建议使用精确匹配。详情参见[数据源管理](/zh/monitors/data-sources/data-sources)。
</Tip>
<Note>
-**保存规则还要求作者对规则引用的数据源有查询权限。** 除账户主体账号与 Admin 外,新建规则、编辑规则、批量更新字段(含批量修改自定义字段与附加标签)时,作者必须对规则引用的每个数据源具备查询(只读)权限:既包括**精确匹配**里显式选中的数据源,也包括**名称通配**在保存那一刻匹配到的数据源——所以一条通配规则可能因为你从未显式选过某个数据源而保存失败。任一数据源无权限时,新建/编辑会直接失败并返回 `no permission to reference datasource "<数据源名>"`;批量更新字段时该规则单独列为失败原因,其余规则仍会更新(提示形如「2 / 10 条规则更新失败,首个错误:…」)。
-
-**纯停用是唯一豁免的操作**:只把规则停用(列表里的启用开关,或批量禁用,本质都是「只改 `enabled`」)不校验数据源权限,因此失去数据源权限的成员仍能把规则关掉;重新启用或同时改动其它字段则照常校验。数据源自身的授权配置(谁能查询、谁能管理)参见[数据源管理](/zh/monitors/data-sources/data-sources)。
+保存规则时,您需要对规则引用的每个数据源都有查询权限,包括名称通配在保存时匹配到的数据源(主体账号与 Admin 除外)。因此一条通配规则可能因为匹配到您无权查询的数据源而无法保存。只停用规则不受此限制。数据源授权见[数据源管理](/zh/monitors/data-sources/data-sources#数据源权限团队授权)。
</Note>
#### 查询语句

-在**查询语句**子标题下方配置查询类型与查询语句本身。子标题右侧是 **使用说明** 入口,打开标题同为「查询语句」的抽屉,里面是查询语句的写法说明。表格型查询的值字段、标签字段与附加信息如何映射,详见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
+配置查询类型与查询语句。点击 **使用说明** 可以查看写法说明。表格型查询的值字段、标签字段与附加信息如何映射,详见[查询结果字段映射](/zh/monitors/alert-rules/query-result-fields)。
#### AI 查询助手
-每个查询语句输入框的右上角都有一颗彩虹色的 **AI 帮我写** 按钮:鼠标悬停或光标聚焦到输入框时渐显,需要先选择数据源类型。点击后打开 **查询助手** 面板,助手会读取当前规则的上下文——数据源、查询类型、已填写的告警阈值,以及其它查询语句——用来生成或改写当前查询。
+选择数据源类型后,点击查询输入框右上角的 **AI 帮我写**,查询助手会结合当前规则的数据源、查询类型、阈值和其他查询,帮您生成或改写查询语句。
-- 生成结果会自动写回输入框:查询语句与数据源私有参数(如 SLS 的项目/日志库、腾讯云 CLS 的地域/日志主题、Loki 与 VictoriaLogs 的返回条目限制)一起落位,并立即重新校验该字段,必填的「请输入」提示随之消失;结果卡片上的 **回填** 按钮可以把这一版语句重新填回输入框
-- 可用的位置包括主查询、阈值判定与数据存在模式的恢复查询、关联查询、查询预览弹窗,以及实体树的规则 PromQL 与实体类别的发现 PromQL。在实体树中,助手只回填查询语句,不会切换数据源
-- 回填只改当前表单,不会自动保存规则;保存前请确认语句与告警阈值是否匹配
+- 生成的语句和相关参数(如 SLS 的项目 / 日志库、腾讯云 CLS 的地域 / 日志主题)会自动填入表单,也可以点击结果卡片上的 **回填** 重新填入。
+- 主查询、恢复查询、关联查询、查询预览,以及实体树中的 PromQL 都可以使用查询助手。
+- 回填不会自动保存规则,保存前请确认语句与阈值匹配。
### 告警判定
-区块 3 提供三种检测方式,以页签形式呈现:**阈值判定**、**数据缺失**、**数据存在**。启用开关不在页签标题上,而在页签内容里对应的启用卡片标题右侧:**阈值判定**是「高级别的阈值触发则不再校验低级别的阈值」,**数据存在**是「查到数据就告警」;**数据缺失**有两张可以分别启用的卡片——「所有查询均无返回数据时告警」和「之前查到过数据,现在查不到了,就告警」——因此这个页签有两个开关。页签本身仍会标记启用状态:页签内任一条件启用后,页签标题后会显示一个对勾标记。
+告警判定提供三种检测方式,每种是一个页签,在页签内的卡片标题右侧启用。已启用的页签标题后会显示对勾。
+
-| 页签 | 判定什么 |
|------|----------|
-| **阈值判定** | 按级别填写阈值表达式,满足条件并达到触发次数后,产生对应级别的告警。高一级别的阈值触发后不再校验低级别的阈值;启用本页签时 Critical、Warning、Info 至少要填写一项 |
-| **数据缺失** | 按「之前查到过数据,现在查不到了」或「所有查询均无返回数据」判定,两张卡片可以分别启用 |
+| **阈值判定** | 按级别填写阈值表达式,满足条件并达到触发次数后,产生对应级别的告警。高级别触发后不再判断低级别;Critical、Warning、Info 至少填写一项 |
+| **数据缺失** | 「之前查到过数据,现在查不到了」或「所有查询均无返回数据」时告警,两个条件可以分别启用 |
| **数据存在** | 查询到数据即视为满足条件,达到触发次数后按设定级别产生告警 |
-判定配置按卡片分组:除**数据缺失**页签外,每个页签分为「**告警触发**」和「**告警恢复**」两张卡片;**数据缺失**页签把两者合并成一张「**触发与恢复条件**」卡片,其配置作用于该页签内所有已启用的条件。卡片内各行含义如下:
+每个页签分为「**告警触发**」和「**告警恢复**」两张卡片(**数据缺失**页签合并为一张「**触发与恢复条件**」)。主要字段:
| 字段 | 说明 |
|------|------|
| **触发方式** | `连续命中` 或 `累计命中`,两者的区别见下一节 |
-| **触发条件** | 触发方式对应的判定句子。**阈值判定**页签下,级别表达式行(`Critical` / `Warning` / `Info`)排在触发方式上方,就是这张卡片的触发条件本体 |
-| **告警级别** | `Critical`、`Warning`、`Info` 三选一,默认 `Critical`。**阈值判定**页签下没有这一行——级别由命中的表达式行决定;**数据存在**与**数据缺失**页签下按条件单独设置 |
-| **恢复方式** | 位于「告警恢复」卡片中;**数据缺失**页签下按条件单独设置(见本节末尾) |
-| **恢复条件** | **N 次连续正常即恢复**,默认 1。设置为 1 时,只要有一次满足恢复条件就生成恢复事件;大于 1 时,要求连续多次都正常才生成恢复事件 |
+| **告警级别** | `Critical`、`Warning`、`Info` 三选一,默认 `Critical`。阈值判定的级别由命中的表达式决定 |
+| **恢复方式** | 见下文[告警恢复](#告警恢复) |
+| **恢复条件** | 连续 N 次正常才恢复,默认 1 |
#### 触发方式:连续命中与累计命中
@@ -153,12 +144,10 @@ keywords: ["入门指南", "monitedge", "数据源", "告警规则", "快速开
| **连续命中**(默认) | 连续满足条件达到设定次数才告警 | 连续 N 次检测都满足条件才告警,N 即**命中次数**,默认 3 |
| **累计命中** | 最近几次检测中,满足条件的次数达标即可,无需连续 | 最近 M 次检测中,有 N 次满足条件就告警,M 即**检测次数**,切到累计命中时默认取 `max(命中次数, 5)` |
-- **累计命中**下,命中次数不能大于检测次数,检测次数不能小于命中次数;命中次数和检测次数都不能超过 10000,超出会直接报校验错误,而不是被自动截断为上限值
-- 两种方式互斥:切回**连续命中**后,检测次数不再随规则提交(服务端按该字段是否存在区分两种模式),因此「最近 M 次」的语义不会残留
-- 对应的规则字段:命中次数 `alerting_check_times`、检测次数 `alerting_window_size`、恢复条件 `recovery_check_times`
+- 累计命中下,命中次数不能大于检测次数,两者都不能超过 10000
<Note>
-**累计命中需要告警引擎 ≥ `v0.69.0`。** 选中**累计命中**时,选项旁会显示「支持 v0.69.0+ 版本」徽章;低于该版本的引擎会退化为按连续命中执行,可能延迟或漏报告警,但不会比新语义更早触发。
+**累计命中需要告警引擎 `v0.69.0` 及以上。** 更早版本的引擎会按连续命中执行,告警可能延迟或漏报。
</Note>
#### 告警恢复
@@ -173,18 +162,14 @@ keywords: ["入门指南", "monitedge", "数据源", "告警规则", "快速开
### 检测频率与生效时间
-该区块是常显区块:没有一行摘要,也没有「展开/收起」按钮,检测频率、查询时间偏移、规则时区、生效时间四个配置项直接铺在区块里。
-
-点击保存时,如果某个字段校验失败,页面会滚动定位到第一个出错的字段并高亮它:错误落在**告警判定**的某个页签里时会先切到该页签,落在**事件配置**的「自定义字段与关联查询」里时会先展开该区域。
-

| 配置项 | 说明 |
|--------|------|
-| **检测频率** | 通常是周期性检测,也支持 `cron` 表达式(精确到秒)和 `@every` 快捷写法。新建规则默认 `@every 15s`;下拉候选档位为 `@every 15s`、`@every 30s`、`@every 45s`、`@every 60s`、`@every 120s`、`@every 150s`、`@every 180s`、`@every 300s`,也可以直接输入其它合法表达式 |
+| **检测频率** | 通常是周期性检测,也支持 `cron` 表达式(精确到秒)和 `@every` 快捷写法。默认 `@every 15s`,可以从下拉选项中选择,也可以直接输入 |
| **查询时间偏移** | 设置查询时间偏移量(秒),用于处理数据源存在采集延迟的场景。例如设置为 60,则查询窗口整体向前偏移 60 秒,确保数据已完成写入后再查询。仅适用于 Prometheus、Loki、VictoriaLogs、SLS、Tencent CLS 数据源 |
| **规则时区** | 告警规则的执行时区,决定 `cron` 调度时间和**生效时间**窗口的解释方式。默认 `Asia/Shanghai`,必须填写有效的 IANA 时区名(如 `Asia/Shanghai`、`UTC`、`Europe/London`、`America/New_York`) |
-| **生效时间** | 告警规则的生效时间段,非生效时间段内不会触发告警;时间窗口按上面配置的**规则时区**计算。它是一组可增删的时间窗:每一行由**星期**(多选,可勾选周一至周日中的任意几天)、**开始时间**和**结束时间**(均为 `HH:mm`)组成,三项都必填;新建规则默认一行,覆盖全部 7 天 `00:00`–`23:59`,即全天生效。**新增生效时间**按钮加一行,每行末尾的删除按钮移除该行(查看规则详情时两个按钮均不可用) |
+| **生效时间** | 告警规则的生效时间段,非生效时间段内不会触发告警;时间窗口按上面配置的**规则时区**计算。可以添加多个时间窗,每个时间窗由星期(多选)和开始 / 结束时间(`HH:mm`)组成。默认全天生效 |
<Warning>
**时区填写规则**:
@@ -196,16 +181,16 @@ keywords: ["入门指南", "monitedge", "数据源", "告警规则", "快速开
- `cron` 表达式必须是 **6 段秒级表达式**,顺序为秒、分、时、日、月、周。5 段写法(例如 `*/5 * * * *`)会被拒绝,需要补充秒字段(例如 `0 */5 * * * *`)
- 支持 `@every` 快捷写法,例如 `@every 30s`,表示每 30 秒检测一次。时长必须是**不小于 1 秒的整数秒**,支持 `@every 1m30s` 这类组合时长;`@every 0s`、`@every 1500ms` 等亚秒或不满足整秒的写法会被拒绝
-- 修改已有规则时同样会校验检测频率,历史上保存的不合规表达式需要先修正才能保存
+- 编辑旧规则时,不符合上述格式的检测频率需要先修正才能保存
</Warning>
<Note>
-规则保存时还会校验运行时配置:重复通知的**最大次数**(`repeat_total`)和**重复间隔**(`repeat_interval`),以及各检测模式(阈值、数据存在、数据缺失)的**连续命中次数**和**连续恢复次数**都必须 ≥ 1。校验失败的规则不会被调度执行,告警引擎会将失败原因上报为 `alert-rule-schedule-invalid` 问题,请根据错误信息修正规则配置。
+重复通知的最大次数和重复间隔,以及各检测方式的命中次数和恢复次数都必须不小于 1,否则规则不会执行。
</Note>
### 事件配置
-区块 5 的顺序是:「自定义字段与关联查询」(一个默认折叠的区域,标题右侧显示「展开 / 收起」,折叠时摘要行显示已配置的自定义字段与关联查询数量,都没有配置时改显示一行提示文案)、备注描述,以及重复发送配置。
+事件配置包括自定义字段与关联查询(默认折叠)、备注描述和重复发送配置。
| 配置项 | 说明 |
|--------|------|
@@ -235,7 +220,7 @@ keywords: ["入门指南", "monitedge", "数据源", "告警规则", "快速开
## 规则运行详情
-告警规则列表的每一行都提供运行时自省能力。点击行操作菜单(行尾 `⋮`)中的**运行详情**,打开规则运行详情抽屉,帮助你判断规则的执行健康度并快速排障。
+告警规则列表的每一行都提供运行时自省能力。点击行操作菜单(行尾 `⋮`)中的**运行详情**,打开规则运行详情抽屉,帮助您判断规则的执行健康度并快速排障。
抽屉顶部可以选择要查看的**数据源**(规则可能绑定多个数据源);这个选择器按查看者对各数据源的查询(`readonly`)权限过滤,没有查询权限的数据源会被静默丢弃,受限查看者看到的数据源可能少于规则实际绑定的数量。下方分为两个标签页:
@@ -253,7 +238,7 @@ keywords: ["入门指南", "monitedge", "数据源", "告警规则", "快速开
按时间范围查询该规则的历史执行记录(支持最近 15 分钟、1 小时、4 小时、1 天,最长 24 小时)。每条记录带执行摘要徽章:`执行失败`、`产生事件`、`告警恢复`、`定期采样`;展开后可查看日志入库时间、Edge 实例与集群、运行阶段、连续失败次数、各检测模式活跃实例数、产生的事件以及错误摘要。
<Note>
-执行历史依赖服务端 VictoriaLogs 查询:服务端未配置查询地址或查询服务不可用时会提示「执行历史暂不可用」。记录只包含关键执行摘要(异常、事件、恢复和定期采样),不保证每轮评估都生成记录;匹配记录超过 200 条时仅展示最近 200 条,请缩小时间范围。
+执行历史只记录关键执行摘要(异常、事件、恢复和定期采样),不保证每轮评估都生成记录;匹配记录超过 200 条时仅展示最近 200 条,请缩小时间范围。
</Note>
## 批量操作
@@ -275,7 +260,7 @@ keywords: ["入门指南", "monitedge", "数据源", "告警规则", "快速开
| **检测频率** | 统一调整检测周期 |
| **规则时区** | 统一切换告警规则的 IANA 时区 |
| **生效时间** | 统一配置生效时间段 |
-| **查询时间偏移** | 统一设置查询时间偏移。仅当所有选中规则的数据源都支持查询时间偏移(Prometheus、Loki、VictoriaLogs、SLS、Tencent CLS)时才可批量更新,否则该项禁用 |
+| **查询时间偏移** | 统一设置查询时间偏移。仅当所有选中规则的数据源都支持(Prometheus、Loki、VictoriaLogs、SLS、Tencent CLS)时可用 |
| **自定义字段** | 统一配置 annotations,支持增量修改与全量替换两种方式 |
| **协作空间** | 统一指定告警投递的协作空间 |
| **重复发送配置** | 统一设置重复通知间隔和次数 |
@@ -287,14 +272,14 @@ keywords: ["入门指南", "monitedge", "数据源", "告警规则", "快速开
| 更新方式 | 说明 |
|---------|------|
-| **增量修改**(默认) | 逐条添加修改操作(`设置` / `删除`),每个操作指定键和值。键与值的候选值来自所选规则的现有内容(自动补全,附各候选值的命中数),并实时展示预计影响,例如「设置 key=value:新增 X 条,更新 Y 条,Z 条不变」「删除 key:影响 N 条,其余规则不变」。所选规则超过 500 条时不加载候选值,仍可手动输入。注意自定义字段的键不能以 `$` 开头。键会自动去除首尾空白;去除后为空、或与其他操作的键重复(例如同时出现 `env` 与 `" env"`)时,整批校验失败并报错 |
+| **增量修改**(默认) | 逐条添加「设置」或「删除」操作,指定键和值。编辑时会根据所选规则的现有内容自动补全,并预览每个操作会影响多少条规则。自定义字段的键不能以 `$` 开头,同一批操作中的键不能重复 |
| **全量替换** | 用下方填写的内容完全替换每条规则的该字段,会删除每条规则中未在下方填写的其他内容 |
<Warning>
修改附加标签可能影响告警路由、聚合或降噪,请谨慎操作。
</Warning>
-批量更新失败时,会提示失败条数和首个失败原因(例如「2 / 10 条规则更新失败,首个错误:…」),便于逐条排查。
+部分规则更新失败时,会提示失败条数和第一个失败原因,其余规则照常更新。
### 批量移动
@@ -323,7 +308,7 @@ keywords: ["入门指南", "monitedge", "数据源", "告警规则", "快速开
### 预检结果
-系统解析文件后展示预检结果表格,逐条列出规则的导入名称、状态(`可导入` / `跳过` / `无效`)和说明。你可以在表格中勾选要导入的规则(默认选中所有可导入规则),然后点击底部「导入 N 条规则」提交。
+系统解析文件后展示预检结果表格,逐条列出规则的导入名称、状态(`可导入` / `跳过` / `无效`)和说明。勾选要导入的规则(默认选中所有可导入的规则)后提交。
<Note>
Nightingale 规则导入后统一保持停用,需检查数据源匹配和转换警告后再手动启用。常见的转换说明包括:Doris 数据源映射为 MySQL、仅保留最高级别告警条件、级别抑制/查询关联/通知目标等配置未保留、恢复语义按 Flashduty 规则能力近似转换、`Local` 时区转换为 `Asia/Shanghai`、全天生效时间转换为 `00:00-23:59`、缺少评估间隔时持续时间按 15 秒间隔换算等。
@@ -331,11 +316,11 @@ Nightingale 规则导入后统一保持停用,需检查数据源匹配和转
### 导入结果
-提交后系统展示导入结果:成功、跳过和无效的条数。全部成功时提示导入成功;如果一条都没有导入成功,弹窗会保留,方便你查看跳过/无效的原因后重新选择。
+提交后系统展示导入结果:成功、跳过和无效的条数。如果一条都没有导入成功,可以在弹窗中查看原因后重新选择。
## 导出告警规则
-在列表中勾选需要导出的规则,点击**导出**按钮。系统以 YAML 格式(Flashduty Rules YAML bundle)展示所选规则的完整配置,你可以:
+在列表中勾选需要导出的规则,点击**导出**按钮。系统以 YAML 格式(Flashduty Rules YAML bundle)展示所选规则的完整配置,您可以:
- **下载**:将 YAML 保存为 `alert-rules.yaml` 文件
- **复制**:将 YAML 内容复制到剪贴板
@@ -344,7 +329,7 @@ Nightingale 规则导入后统一保持停用,需检查数据源匹配和转
## 规则变更记录
-每条告警规则都有完整的变更审计记录。你可以在规则详情中查看**变更记录**,了解规则的历史修改情况。
+每条告警规则都有完整的变更审计记录。您可以在规则详情中查看**变更记录**,了解规则的历史修改情况。
### 查看变更记录
@@ -358,4 +343,4 @@ Nightingale 规则导入后统一保持停用,需检查数据源匹配和转
### 版本对比
-在变更记录列表中勾选两条记录,点击**对比**按钮,系统会以 JSON diff 的方式展示两个版本之间的差异,帮助你快速了解具体修改了哪些配置项。
+在变更记录列表中勾选两条记录,点击**对比**按钮,系统会以 JSON diff 的方式展示两个版本之间的差异,帮助您快速了解具体修改了哪些配置项。
diff --git a/zh/on-call.mdx b/zh/on-call.mdx
index 76161550..370b5269 100644
--- a/zh/on-call.mdx
+++ b/zh/on-call.mdx
@@ -26,7 +26,7 @@ On-call 是 Flashduty 的核心产品,已服务数千家企业,处理超过
飞书、钉钉、企业微信、Slack、Microsoft Teams、电话、短信、邮件
</Card>
<Card title="丰富集成" icon="plug">
- 100+ 监控工具和云平台原生支持,5 分钟完成接入
+ 290+ 告警集成,覆盖主流监控工具与云平台
</Card>
</CardGroup>
@@ -69,6 +69,13 @@ Flashduty On-call 的工作流非常直观:
</Accordion>
</AccordionGroup>
+## 适用场景
+
+- 构建 7x24 值班体系,保障服务可用性
+- 聚合多源告警,统一事件管理入口
+- 建立告警升级机制,确保问题及时响应
+- 分析告警数据,持续优化监控质量
+
## 快速开始
<CardGroup cols={2}>
@@ -78,7 +85,7 @@ Flashduty On-call 的工作流非常直观:
<Card title="创建协作空间" icon="folder-plus" href="/zh/on-call/channel/create-edit">
了解如何创建和配置协作空间,管理团队故障响应
</Card>
- <Card title="通知触达" icon="sitemap" href="/zh/on-call/channel/escalation-rule">
+ <Card title="分派策略" icon="sitemap" href="/zh/on-call/channel/escalation-rule">
设置告警通知规则、升级路径和值班人员
</Card>
<Card title="值班排班" icon="calendar" href="/zh/on-call/configuration/schedule">
diff --git a/zh/on-call/advanced/war-room.mdx b/zh/on-call/advanced/war-room.mdx
index 99c53da1..e141aeca 100644
--- a/zh/on-call/advanced/war-room.mdx
+++ b/zh/on-call/advanced/war-room.mdx
@@ -116,17 +116,17 @@ Flashduty On-call 作战室(War Room)是专为故障应急响应设计的自
</Warning>
<Info>
-**平台创建的作战室群聊不能作为常驻通知目标。** 系统会给每个群聊标注来源:`origin=system` 表示这是平台创建的群聊(目前只有故障作战室),与人工创建的群聊区分开。因此,分派策略的 **IM 应用群**(飞书/钉钉、Slack、Microsoft Teams 群聊)与值班计划换班通知的 **群聊渠道**(飞书/钉钉、Slack 群聊)选择器会自动排除作战室——飞书/钉钉与 Slack 选择器的提示文案为「请选择…群聊(不含故障作战室)」。作战室随故障生、随故障关,如果把它配置为常驻通知目标,这条配置指向的群聊注定会消失;若此前已保存的群聊 ID 已失效(作战室已解散、机器人被移出群、群聊已删除),选择器会把该目标显示为 **群聊不存在**,并可通过移除按钮清掉。
+**作战室群聊不能作为常驻通知目标。** 作战室随故障创建和关闭,因此分派策略的 **IM 应用群** 和值班计划换班通知的 **群聊渠道** 中不会列出作战室。如果之前保存的群聊已失效(作战室已解散、机器人被移出或群聊已删除),会显示为 **群聊不存在**,可以将其移除。
</Info>
### 移动端 App
-Flashduty App 已支持完整的作战室生命周期,与控制台、IM 应用共享同一套作战室能力。移动端行为要点如下:
+Flashduty App 支持完整的作战室生命周期,与控制台和 IM 应用一致:
-- **能力门控**:移动端作战室同样要求 On-call 专业版及以上订阅,且账户下至少有一个已开启作战室功能的 IM 集成;版本不足时,概览入口与作战室相关操作均不展示
-- **概览入口卡片**:当故障已创建作战室时,故障详情概览页会展示 **作战室** 入口卡片。点击后,支持深链的 IM 集成会直接拉起 IM 进入群聊;若拉起失败或集成未提供分享链接,则弹窗展示群聊名称(可一键复制),您可打开对应 IM 应用搜索群名进入
-- **创建作战室**:入口位于故障详情页底部 **更多操作** 中。当故障已存在作战室或故障已关闭时,入口隐藏;当故障没有处理人员时,入口禁用并提示「当前故障没有处理人员,无法创建作战室」(作战室由后端按处理人员建群)
-- **添加关注人员进入作战室 / 解散作战室**:同样位于 **更多操作** 中,故障关闭后仍可用(便于复盘),解散需二次确认;但要求作战室所在的 IM 集成仍可用。集成被禁用或删除后,这两项从 **更多操作** 中消失,需由管理员在控制台的故障详情页解除关联;概览页的 **作战室** 入口卡片仍会保留,点击后提示「原集成已禁用或删除。请管理员在 PC 端故障详情页解除关联,原群聊不会解散。」
+- **使用条件**:与控制台相同,需要 On-call 专业版及以上,且至少有一个 IM 集成开启了作战室功能
+- **进入作战室**:故障详情概览页的 **作战室** 卡片可以直接打开 IM 群聊;无法直接打开时,会显示群聊名称供您复制后搜索
+- **创建作战室**:在故障详情页底部的 **更多操作** 中。故障已有作战室或已关闭时不显示;故障没有处理人员时不可用(作战室按处理人员建群)
+- **添加关注人员进入作战室 / 解散作战室**:也在 **更多操作** 中,故障关闭后仍可使用(便于复盘),解散需二次确认。如果作战室所在的 IM 集成被禁用或删除,这两项不再显示,需要管理员在控制台的故障详情页解除关联(原群聊不会解散)
<Check>
通过将应急流程与即时通讯工具深度整合,Flashduty 作战室为您带来了 **自动化**、**可视化**、**可追溯** 的故障协同体验。
@@ -146,6 +146,30 @@ Flashduty App 已支持完整的作战室生命周期,与控制台、IM 应用
- 跟进项的同类操作消息中,`Action` 字样会替换为 `Follow-up`
- 当操作人无法解析为具体成员时,消息中的操作人显示为 **系统**
+## AI SRE
+
+作战室与 **AI SRE** 深度联动:作战室创建后,AI SRE 会自动进行一轮初步诊断并把结论回贴到群里;您也可以在群聊中 **@ AI SRE** 继续追问或发起新的排查。详见 [AI SRE 产品介绍](/zh/ai-sre)与 [IM 平台](/zh/ai-sre/im)。
+
+### 作战室中的 AI SRE
+
+<CardGroup cols={2}>
+ <Card title="自动初步诊断" icon="robot">
+ 作战室创建后自动分析故障并回贴第一轮结论——人还没开始排查,第一手分析已经在群里
+ </Card>
+ <Card title="群内追问" icon="comment-dots">
+ 在群聊中 @ AI SRE 发起或续接排查,Agent 在线程内回答,团队成员全程可见
+ </Card>
+ <Card title="带上下文调查" icon="chart-line">
+ 回复告警或故障卡片即可让 Agent 自动定位对应故障,无需手工粘贴上下文
+ </Card>
+ <Card title="故障复盘" icon="file-lines">
+ 基于故障时间线与调查证据,生成结构化的复盘文档
+ </Card>
+</CardGroup>
+
+<Info>
+为了获取更完整的故障全生命周期上下文,AI 生成复盘报告需要读取作战室聊天记录。请确保您的 IM 集成已授予相应权限 —— 详见[飞书](/zh/on-call/integration/instant-messaging/lark)或 [Slack](/zh/on-call/integration/instant-messaging/slack) 集成指南。
+</Info>
## 常见问题
<AccordionGroup>
@@ -204,27 +228,3 @@ Flashduty App 已支持完整的作战室生命周期,与控制台、IM 应用
</Accordion>
</AccordionGroup>
-## AI SRE
-
-作战室与 **AI SRE** 深度联动:作战室创建后,AI SRE 会自动进行一轮初步诊断并把结论回贴到群里;你也可以在群聊中 **@ AI SRE** 继续追问或发起新的排查。详见 [AI SRE 产品介绍](/zh/ai-sre)与 [IM 平台](/zh/ai-sre/im)。
-
-### 作战室中的 AI SRE
-
-<CardGroup cols={2}>
- <Card title="自动初步诊断" icon="robot">
- 作战室创建后自动分析故障并回贴第一轮结论——人还没开始排查,第一手分析已经在群里
- </Card>
- <Card title="群内追问" icon="comment-dots">
- 在群聊中 @ AI SRE 发起或续接排查,Agent 在线程内回答,团队成员全程可见
- </Card>
- <Card title="带上下文调查" icon="chart-line">
- 回复告警或故障卡片即可让 Agent 自动定位对应故障,无需手工粘贴上下文
- </Card>
- <Card title="故障复盘" icon="file-lines">
- 基于故障时间线与调查证据,生成结构化的复盘文档
- </Card>
-</CardGroup>
-
-<Info>
-为了获取更完整的故障全生命周期上下文,AI 生成复盘报告需要读取作战室聊天记录。请确保您的 IM 集成已授予相应权限 —— 详见[飞书](/zh/on-call/integration/instant-messaging/lark)或 [Slack](/zh/on-call/integration/instant-messaging/slack) 集成指南。
-</Info>
\ No newline at end of file
diff --git a/zh/on-call/analytics/insights.mdx b/zh/on-call/analytics/insights.mdx
index ff129247..d0180b1e 100644
--- a/zh/on-call/analytics/insights.mdx
+++ b/zh/on-call/analytics/insights.mdx
@@ -7,7 +7,7 @@ keywords: ["分析看板", "数据分析", "故障统计", "报表导出", "运
<Tip>**版本要求**:此功能需要 On-call 标准版及以上订阅。[了解更多](https://flashcat.cloud/flashduty/price/)</Tip>
<Note>
-**订阅过期后看板可能是空的**:On-call 订阅过期或被停用后告警停止接入,看板此后不再产生新的统计数据,默认时间窗内自然是空的——这不是数据丢失。页面顶部会常驻一条不可关闭的提示条「订阅已过期,告警已停止接入,此后不再产生新的统计数据。历史数据不受影响,仍可查看与导出。」,历史数据仍可查看与导出,续费后自动恢复。账户级说明见[订阅过期后会发生什么](/zh/platform/pricing#订阅过期后会发生什么)。
+**订阅过期后看板可能是空的**:订阅过期或停用后告警停止接入,不再产生新的统计数据,因此默认时间窗内可能为空,这不是数据丢失。历史数据仍可查看与导出,续费后自动恢复。详见[订阅过期后会发生什么](/zh/platform/pricing#订阅过期后会发生什么)。
</Note>
## 关键特性
@@ -41,8 +41,8 @@ keywords: ["分析看板", "数据分析", "故障统计", "报表导出", "运
| 协作空间 | 选择需要查询的协作空间名称,支持多选,选中后会按选中的协作空间更新仪表盘中的数据 |
| 严重程度 | 选择需要查询的严重程度,支持多选,选中后会按选中的严重程度更新仪表盘中的数据 |
| 时间范围 | 选择需要查询的时间范围,支持按本周、最近两周、本月、上个月以及自定义时间的维度进行查询,最长支持查询最近 **2 年(720 天)** 的数据(具体上限以您的订阅版本为准) |
-| 数据间隔 | 支持天、周、月的维度进行查询,默认按小时进行查询,但查询的时间范围大于 31 天时,无法以天的维度进行预览;天 / 周 / 月的分桶按查看者的生效时区(个人时区优先,回退组织时区)划分 |
-| 时区 | 看板中的时间、日 / 周 / 月聚合与查询均按查看者的生效时区(个人时区优先,回退组织时区)展示与统计。筛选栏右侧显示当前生效时区标识,悬停提示「时间按你所在时区展示与统计」 |
+| 数据间隔 | 默认按小时,也可以按天、周、月查看;时间范围超过 31 天时不能按天查看 |
+| 时区 | 时间显示和天 / 周 / 月统计均按您的时区(个人时区优先,否则为组织时区),当前时区显示在筛选栏右侧 |
| 排序 | 团队、协作空间和个人维度的仪表盘可以选择倒排和正排,默认只显示 TOP 10 的数据,单独放大后可以展示更多 |
## 按小时拆分
@@ -150,7 +150,7 @@ keywords: ["分析看板", "数据分析", "故障统计", "报表导出", "运
| **故障数量** | 统计故障的创建数量趋势 |
| **变更数量** | 统计变更事件的数量趋势 |
-用量数据帮助你了解平台整体使用情况,便于进行容量规划和成本评估。
+用量数据帮助您了解平台整体使用情况,便于进行容量规划和成本评估。
## 常见问题
diff --git a/zh/on-call/channel/create-edit.mdx b/zh/on-call/channel/create-edit.mdx
index a27a1d03..5508752b 100644
--- a/zh/on-call/channel/create-edit.mdx
+++ b/zh/on-call/channel/create-edit.mdx
@@ -64,7 +64,7 @@ keywords: ["协作空间", "创建管理", "业务隔离", "团队协作", "告
开启后,故障列表及通知内容中将带有"新奇故障"标识,便于快速识别。[了解更多](/zh/on-call/incident/outlier-incidents)
</Step>
<Step title="开启外部提报(可选)">
- 开启后,外部人员可通过外部提报链接提交故障工单,无需登录系统。系统会生成一个可分享的链接,你可以将该链接发送给外部人员。关闭外部提报后,已分享的链接将立即失效;再次开启将生成新的链接。
+ 开启后,外部人员可通过外部提报链接提交故障工单,无需登录系统。系统会生成一个可分享的链接,您可以将该链接发送给外部人员。关闭外部提报后,已分享的链接将立即失效;再次开启将生成新的链接。
</Step>
</Steps>
@@ -134,7 +134,7 @@ keywords: ["协作空间", "创建管理", "业务隔离", "团队协作", "告
配置过滤条件,支持按 **集成来源** 和 **严重程度** 进行匹配。
</Step>
<Step title="保存规则">
- 保存后规则默认启用,你可以随时在排除规则列表中启用或禁用某条规则。
+ 保存后规则默认启用,您可以随时在排除规则列表中启用或禁用某条规则。
</Step>
</Steps>
diff --git a/zh/on-call/channel/escalation-rule.mdx b/zh/on-call/channel/escalation-rule.mdx
index e531cbee..9c7143f9 100644
--- a/zh/on-call/channel/escalation-rule.mdx
+++ b/zh/on-call/channel/escalation-rule.mdx
@@ -21,20 +21,7 @@ src="https://download.flashcat.cloud/flashduty/video/escalate-rule.mp4"
一条分派策略包含六个核心要素,系统按从上到下的顺序匹配策略,**匹配成功后停止匹配后续策略**。
-您可以对每条分派策略进行启用或禁用操作。禁用的策略在匹配时会被跳过,不会触发通知。此外,您还可以将分派策略复制到当前协作空间或其他协作空间,快速复用已有配置。
-
-### 复制分派策略
-
-每条分派策略卡片在悬停时显示 **复制** 图标按钮,点击后弹出复制弹窗(与静默策略复制共用同一弹窗组件),包含以下字段:
-
-| 字段 | 说明 |
-| :--- | :--- |
-| **策略名称** | 必填,默认以「复制 」加原策略名称填充,最多 **39 个字符**(后端限制 40),超长输入会被直接截断 |
-| **协作空间** | 选择 **此协作空间** 或 **其他协作空间**。选择其他空间时需从下拉列表指定目标空间,列表会自动排除源策略所在空间;非管理员用户仅显示自己管理的空间 |
-| **策略描述** | 可选,默认沿用原策略描述,最多 **500 个字符**,超长输入会被直接截断 |
-
-- 复制策略复用原策略的完整配置(触发条件、通知对象、通知方式、延迟窗口、通知模板、升级规则),但 **优先级(列表匹配顺序)不随复制携带**,复制后请在列表中调整新策略到合适的位置
-- 复制到当前协作空间成功后,新策略立即出现在列表中;复制到其他协作空间后弹出 **复制成功** 结果对话框,展示目标协作空间、策略名称、策略描述和创建者,点击 **去查看** 可打开目标空间并定位到该策略
+您可以对每条分派策略进行启用或禁用操作。禁用的策略在匹配时会被跳过,不会触发通知。此外,您还可以将分派策略复制到当前协作空间或其他协作空间,快速复用已有配置,详见[复制分派策略](#复制分派策略)。
### 1. 触发条件
@@ -50,7 +37,7 @@ src="https://download.flashcat.cloud/flashduty/video/escalate-rule.mp4"
**故障筛选**:控制策略匹配哪些故障。
- **关闭(默认)**:所有故障均可能命中该策略
-- **开启**:仅符合筛选条件的故障才会命中该策略,未匹配的故障将继续匹配后续策略。你可以添加多个条件组,组内条件为「且」关系,条件组之间为「或」关系;每个条件支持 **匹配** / **不匹配** 两种操作符,可选 Key 包括:
+- **开启**:仅符合筛选条件的故障才会命中该策略,未匹配的故障将继续匹配后续策略。您可以添加多个条件组,组内条件为「且」关系,条件组之间为「或」关系;每个条件支持 **匹配** / **不匹配** 两种操作符,可选 Key 包括:
- **集成来源(首条告警)**:按故障首条告警的来源集成匹配,候选项为当前协作空间可用的集成(含共享和专属)
- **严重程度**:多选 Critical / Warning / Info
- **标题**、**描述**:支持精确、通配、正则、CIDR、数值比较等多种匹配模式
@@ -128,7 +115,7 @@ src="https://download.flashcat.cloud/flashduty/video/escalate-rule.mp4"
**重复通知**:
-在每个分派环节中,你可以开启 **重复通知** 功能。开启后,如果故障在当前环节未被处理完成,系统将按照设定的间隔时间(最小 0.5 分钟,步长 0.5 分钟)重复发送通知,最多重复通知指定的次数。
+在每个分派环节中,您可以开启 **重复通知** 功能。开启后,如果故障在当前环节未被处理完成,系统将按照设定的间隔时间(最小 0.5 分钟,步长 0.5 分钟)重复发送通知,最多重复通知指定的次数。
**升级条件**:
@@ -151,6 +138,18 @@ src="https://download.flashcat.cloud/flashduty/video/escalate-rule.mp4"
- **增删环节**:支持任意添加或删除环节;策略至少保留 1 个环节
- **调整顺序**:支持将环节上移、下移,或在任意两个环节之间插入新的环节
+## 复制分派策略
+
+在分派策略卡片上点击 **复制** 图标,可以设置新策略的名称、目标协作空间和描述:
+
+| 字段 | 说明 |
+| :--- | :--- |
+| **策略名称** | 必填,默认为「复制 原策略名称」,最多 **39 个字符** |
+| **协作空间** | 当前协作空间或其他协作空间(非管理员只能选择自己管理的空间) |
+| **策略描述** | 可选,默认沿用原策略描述,最多 **500 个字符** |
+
+复制会沿用原策略的完整配置(触发条件、通知对象、通知方式、延迟窗口、通知模板、升级规则),但 **不保留列表中的匹配顺序**,复制后请把新策略调整到合适的位置。复制到其他协作空间后,可以点击 **去查看** 打开新策略。
+
## 最佳实践
<AccordionGroup>
diff --git a/zh/on-call/channel/integrate-data.mdx b/zh/on-call/channel/integrate-data.mdx
index c60b8fd6..fc40f0c6 100644
--- a/zh/on-call/channel/integrate-data.mdx
+++ b/zh/on-call/channel/integrate-data.mdx
@@ -48,7 +48,7 @@ Flashduty On-call 提供两种告警接入方式:
</Frame>
<Note>
-专属集成归属于所在协作空间:**编辑、启停与删除**需要「协作空间管理」或「集成管理」功能权限,并同时满足该协作空间的数据权限——仅**账户管理员、协作空间创建者或协作空间管理团队**允许操作。不满足时对应按钮为禁用状态,悬停会说明原因。
+专属集成归属于所在协作空间。**编辑、启停与删除**需要「协作空间管理」或「集成管理」权限,且您必须是账户管理员、协作空间创建者或协作空间管理团队成员。
</Note>
### 共享集成
@@ -99,7 +99,7 @@ Flashduty On-call 提供两种告警接入方式:
- 标题右侧是该目录收录的集成总数,顶部搜索框跨全部集成查找。
- 左侧分类导航列出每个分类及其条目数,点击即在右侧滚动定位到该分类(同时清空搜索)。
-- 右侧按分类平铺卡片(图标、名称、两行简介),鼠标悬停出现 **添加**,点击进入该系统的新建集成页。
+- 右侧按分类列出可接入的系统,点击 **添加** 进入新建集成页。
目录底部还有一块「没有找到你要接的系统?」的兜底区,给出两条出路:用通用集成接入,或提交集成需求。
@@ -241,7 +241,7 @@ Flashduty On-call 提供两种告警接入方式:
</Accordion>
<Accordion title="订阅过期后集成会怎样?" icon="circle-question">
- 订阅过期后,所有集成(含专属集成与共享集成)都会停止接收告警事件,集成中心顶部会常驻一条订阅过期提示,新建集成的卡片同时被禁用(悬停可见原因)。已配置的集成不会被删除,续费后自动恢复接入,无需重新配置。
+ 订阅过期后,所有集成(含专属集成与共享集成)都会停止接收告警事件,也无法新建集成。已配置的集成不会被删除,续费后自动恢复,无需重新配置。
</Accordion>
</AccordionGroup>
diff --git a/zh/on-call/channel/noise-reduction.mdx b/zh/on-call/channel/noise-reduction.mdx
index 8fb42d3f..5fd10556 100644
--- a/zh/on-call/channel/noise-reduction.mdx
+++ b/zh/on-call/channel/noise-reduction.mdx
@@ -145,7 +145,7 @@ Flashduty On-call 提供两种聚合模式:
选择 **智能聚合** 模式
</Step>
<Step title="指定参与计算字段">
- 选择参与相似度计算的字段。默认字段包括:标题(title)、描述(description)、labels.service、labels.resource。你可以根据业务需要添加或移除字段,最多支持选择 **10 个** 字段。点击 **重置** 可恢复默认配置。
+ 选择参与相似度计算的字段。默认字段包括:标题(title)、描述(description)、labels.service、labels.resource。您可以根据业务需要添加或移除字段,最多支持选择 **10 个** 字段。点击 **重置** 可恢复默认配置。
</Step>
</Steps>
@@ -163,7 +163,7 @@ Flashduty On-call 提供两种聚合模式:
<Frame caption="统一控制配置">

</Frame>
- **细粒度控制**:按条件匹配不同聚合维度,针对不同类型的告警采用不同的聚合策略。你可以添加多个条件分支,每个分支包含匹配条件和对应的聚合维度:
+ **细粒度控制**:按条件匹配不同聚合维度,针对不同类型的告警采用不同的聚合策略。您可以添加多个条件分支,每个分支包含匹配条件和对应的聚合维度:
- 系统从上到下依次匹配条件,命中第一个满足条件的分支后使用该分支的聚合维度
- 支持上下移动条件分支的优先级顺序
@@ -177,7 +177,7 @@ Flashduty On-call 提供两种聚合模式:
### 配置限制
-为保证聚合性能与稳定性,以下字段存在后端硬上限:
+为保证聚合性能与稳定性,以下字段存在系统硬上限:
| 聚合模式 | 限制项 | 上限 | 说明 |
| :--- | :--- | :--- | :--- |
@@ -318,7 +318,7 @@ src="https://download.flashcat.cloud/flashduty/video/silence.mp4"

</Frame>
-创建时抽屉会显示「已识别到 N 个标签,M 个标签被自动排除」,并逐一列出被排除标签及原因:系统格式规则标注为 **JSON 类型 / 纯数字 / 内容过长 / 时间格式**,账户规则标注为 **全局排除** 或所属集成名称。抽屉内可点击 **管理排除规则** 或 **查看排除规则** 前往账户配置(仅主体账户或 Account.Admin 可修改,其余成员只读查看)。匹配条件由来源故障的标签自动生成,过于精确可能会导致同类告警无法被静默,创建时请注意逐条确认。
+创建时会列出因格式(JSON、纯数字、内容过长、时间格式)或账户排除规则而被自动排除的标签及原因。账户排除规则只有主账户或账户管理员可以修改。匹配条件由来源故障的标签自动生成,过于精确可能导致同类告警无法被静默,请逐条确认。
<Note>
同一故障重复操作快速静默时,会编辑原规则而非创建新规则。
@@ -326,18 +326,16 @@ src="https://download.flashcat.cloud/flashduty/video/silence.mp4"
### 复制静默策略
-静默策略列表中的每条规则卡片(**快速静默** 生成的规则除外)在悬停时显示 **复制** 图标按钮。点击后弹出复制弹窗,可设置新规则的名称、描述并选择目标协作空间:
+在静默策略卡片上点击 **复制** 图标(**快速静默** 生成的规则不支持),可以设置新规则的名称、描述和目标协作空间:
| 配置项 | 说明 |
| :--- | :--- |
-| **策略名称** | 必填,默认以「复制 」加原规则名称填充(如 `复制 数据库维护`),最多 **39 个字符**,超长输入会被直接截断 |
-| **策略描述** | 默认沿用原规则描述,最多 **500 个字符**,超长输入会被直接截断 |
-| **协作空间** | 选择 **此协作空间**(当前空间)或 **其他协作空间**。选择其他空间时需从下拉列表指定目标空间,列表会自动排除源规则所在空间;非管理员用户仅显示自己管理的空间 |
+| **策略名称** | 必填,默认为「复制 原规则名称」,最多 **39 个字符** |
+| **策略描述** | 默认沿用原规则描述,最多 **500 个字符** |
+| **协作空间** | 当前协作空间或其他协作空间(非管理员只能选择自己管理的空间) |
-复制生成的是 **一条独立的新规则**:复用原规则的静默条件、静默行为(直接丢弃 / 保留标记)、到期自动删除设置和静默时间(单次或周期),但不会携带原规则的 `rule_id`、`from_incident_id` 等身份信息,也不会继承快速静默与来源故障的关联关系。
+复制生成 **一条独立的新规则**,沿用原规则的静默条件、静默行为、到期自动删除设置和静默时间,但不再与来源故障关联。复制到其他协作空间后,可以点击 **去查看** 打开新规则。
-- **复制到当前协作空间**:复制成功后新规则立即出现在列表中,并提示「复制成功」。
-- **复制到其他协作空间**:复制成功后弹出 **复制成功** 结果对话框,展示目标协作空间、策略名称、策略描述和创建者;点击 **去查看** 可打开新规则所在空间,并直接定位到该规则详情页。
<Note>
**快速静默** 规则不可复制:快速静默与来源故障绑定(对同一故障重复操作会编辑原规则),其卡片上不显示「复制」操作。
diff --git a/zh/on-call/comparison/vs-opsgenie.mdx b/zh/on-call/comparison/vs-opsgenie.mdx
index a693defb..53bdf5f7 100644
--- a/zh/on-call/comparison/vs-opsgenie.mdx
+++ b/zh/on-call/comparison/vs-opsgenie.mdx
@@ -6,8 +6,6 @@ keywords: ["Opsgenie", "Opsgenie 替代", "Opsgenie 停服", "Opsgenie 迁移",
## 前言
----
-
Atlassian 已经给 Opsgenie 画出了明确的终点:**2025 年 6 月 4 日停止新购**,现有客户可继续使用至 **2027 年 4 月 5 日停止支持**,到期后 Opsgenie 关闭访问,未迁出的客户数据将被删除(见 [Atlassian Opsgenie Licensing FAQ](https://www.atlassian.com/licensing/opsgenie))。
<Note>
@@ -33,8 +31,6 @@ Atlassian 已经给 Opsgenie 画出了明确的终点:**2025 年 6 月 4 日
## 停服时间线与官方迁移路径
----
-
### 关键日期
| 日期 | 事件 | 影响 |
@@ -57,8 +53,6 @@ Atlassian 引导团队通过**应用内迁移工具**迁入 Jira Service Managem
## 产品功能对比
----
-
### On-call
On-call 解决「告警找到对的人」:先降噪,再按排班和升级策略通知到人。
@@ -137,7 +131,7 @@ Response 解决「找到人之后怎么快速闭环」:一条时间线、一
| 核心能力 | Flashduty | Opsgenie |
| --- | --- | --- |
-| **告警集成** | 267 集成源,国内云与监控生态全覆盖(阿里云、腾讯云、华为云等),兼容 PagerDuty 协议 | 200+ 集成,海外生态成熟 |
+| **告警集成** | 290+ 集成源,国内云与监控生态全覆盖(阿里云、腾讯云、华为云等),兼容 PagerDuty 协议 | 200+ 集成,海外生态成熟 |
| **心跳监控** | 监控类心跳由 [Monitors 引擎失联告警](/zh/monitors/engine/engine-lost-alert)覆盖,On-call 侧无独立的定时任务心跳能力 | ✅ Heartbeats 是 Opsgenie 的成熟能力,Cron/定时任务场景迁出前请单独评估替代方案 |
| **告警流水线与标签增强** | 路由、过滤、等级重设、正则提取、[数据映射](/zh/on-call/integration/alert-integration/label-enhancement)(导入 CMDB 表格动态生成标签) | Alert Policies 支持基础的过滤与字段修改 |
| **洞察报表** | MTTA/MTTR、人员工作量、频发分析、**时段分析**(工作/休息/睡眠) | 基础报表 |
@@ -148,8 +142,6 @@ Response 解决「找到人之后怎么快速闭环」:一条时间线、一
## 价格对比
----
-
| 对比维度 | Flashduty | Opsgenie / JSM 路径 |
| --- | --- | --- |
| **收费模式** | License 费 + 超额通信费用 | 按用户席位;迁入 JSM 后按 JSM 套餐计费 |
@@ -176,8 +168,6 @@ Opsgenie 席位单价不高,但它已是停服产品——真正的成本比
## 迁移路径对比
----
-
### 路径一:迁入 Jira Service Management(留在 Atlassian)
适合已经标准化在 Atlassian 套件上的组织。官方应用内迁移工具会把大部分配置同步到选定的 JSM 套餐,但请注意:
@@ -216,8 +206,6 @@ Opsgenie 席位单价不高,但它已是停服产品——真正的成本比
## 如何选择
----
-
<CardGroup cols={2}>
<Card title="选择 Flashduty 的情况" icon="star">
- 需要一个不依赖 Atlassian 合并路径、可长期运行的 On-call / 故障响应产品
@@ -241,8 +229,6 @@ Opsgenie 席位单价不高,但它已是停服产品——真正的成本比
## 总结
----
-
Opsgenie 曾是一款优秀的告警与值班产品,但它的产品周期已经进入倒计时。对存量用户来说,2027 年 4 月 5 日是一个确定的规划边界:**迁移不是要不要做的问题,而是迁到哪里的问题**。
- 如果您的组织已经运行在 Atlassian 体系内,JSM 是摩擦最低的官方路径;
diff --git a/zh/on-call/comparison/vs-pagerduty.mdx b/zh/on-call/comparison/vs-pagerduty.mdx
index 359d2255..a3626c30 100644
--- a/zh/on-call/comparison/vs-pagerduty.mdx
+++ b/zh/on-call/comparison/vs-pagerduty.mdx
@@ -6,8 +6,6 @@ keywords: ["产品对比", "PagerDuty", "功能对比", "价格对比", "竞品
## 前言
----
-
在瞬息万变的数字化时代,企业对**监控和事件管理工具**的依赖程度与日俱增,这些工具是确保业务连续性和服务稳定性的重要基石。然而,随着监控系统规模的不断扩展,**海量告警与事件通知**也如潮水般涌现,给 IT 团队带来了前所未有的运维挑战。
<Note>
@@ -37,8 +35,6 @@ keywords: ["产品对比", "PagerDuty", "功能对比", "价格对比", "竞品
## 采购指南概览
----
-
本指南将为您提供**全面的 On-call 工具采购建议**,我们将从 **产品功能**、**服务质量** 与 **价格策略** 三个核心维度出发,深入分析 IT 管理人员在为开发和运维团队寻找高效协作的故障管理解决方案时应该关注的要点。
同时,我们将提供 **Flashduty** 与 **PagerDuty** 两大主流 On-call 供应商的详细对比分析,助您做出明智的选择。
@@ -51,8 +47,6 @@ keywords: ["产品对比", "PagerDuty", "功能对比", "价格对比", "竞品
## 产品功能对比
----
-
产品功能按 Flashduty 当前的产品模块逐块对比:**On-call**(降噪、排班、升级、通知)、**Response**(作战室协同与故障闭环)、**Status Pages**(对外状态沟通)、**AI SRE**(自治排障 Agent),以及支撑它们的**平台底座**(集成接入、告警流水线、洞察、安全与开放生态)。这一划分与 PagerDuty 的产品线基本对应,方便逐块对照。
### On-call
@@ -177,7 +171,7 @@ PagerDuty AIOps 在超大规模事件关联场景上打磨多年,能力成熟
| 核心能力 | Flashduty | PagerDuty | 说明 |
| --- | --- | --- | --- |
-| **告警集成** | 267 集成源,国内云与监控生态全覆盖(阿里云、腾讯云、华为云、京东云、金山云、UCloud 等),**兼容 PagerDuty 协议** | 750+ 集成,海外生态覆盖广 | PagerDuty 集成数量更多;Flashduty 对国内技术栈覆盖更完整,且存量 PagerDuty 集成配置可直接切换 |
+| **告警集成** | 290+ 集成源,国内云与监控生态全覆盖(阿里云、腾讯云、华为云、京东云、金山云、UCloud 等),**兼容 PagerDuty 协议** | 750+ 集成,海外生态覆盖广 | PagerDuty 集成数量更多;Flashduty 对国内技术栈覆盖更完整,且存量 PagerDuty 集成配置可直接切换 |
| **拉取式接入** | [HTTP Pull](/zh/on-call/integration/alert-integration/alert-sources/http-pull) 周期拉取接口、[DB Pull](/zh/on-call/integration/alert-integration/alert-sources/db-pull) 直查 MySQL/PostgreSQL/ClickHouse 增量生成告警 | 以推送式集成为主 | 老系统没有 Webhook 推送能力也能接入 Flashduty |
| **工单双向同步** | [Jira](/zh/on-call/integration/webhooks/jira-sync)(状态映射可配置,字段映射支持故障 ID / 故障链接)、[ServiceNow](/zh/on-call/integration/webhooks/servicenow-sync)、[ServiceDesk Plus](/zh/on-call/integration/webhooks/servicedesk-plus-sync) | Jira、ServiceNow 等 | 两者均支持 |
| **变更事件集成** | ✅ 支持变更事件接入、动态路由与标签二次加工 | ✅ Change Events | 两者均支持 |
@@ -239,8 +233,6 @@ PagerDuty AIOps 在超大规模事件关联场景上打磨多年,能力成熟
## 价格对比
----
-
价格是企业决策的重要因素,需要在满足需求的前提下选择性价比最优的方案。
| 对比维度 | Flashduty | PagerDuty |
@@ -296,8 +288,6 @@ PagerDuty AIOps 在超大规模事件关联场景上打磨多年,能力成熟
## 服务质量对比
----
-
优质的服务支持是产品成功实施的重要保障。
| 服务项目 | Flashduty | PagerDuty |
@@ -317,8 +307,6 @@ PagerDuty AIOps 在超大规模事件关联场景上打磨多年,能力成熟
## 从 PagerDuty / Opsgenie 迁移
----
-
<CardGroup cols={2}>
<Card title="从 PagerDuty 迁移" icon="arrow-right-arrow-left">
Flashduty **兼容 PagerDuty 协议**,存量告警集成配置基本免改造直接切换;专属服务群提供专家一对一迁移陪跑。
@@ -332,8 +320,6 @@ PagerDuty AIOps 在超大规模事件关联场景上打磨多年,能力成熟
## 总结与建议
----
-
### 核心优势对比
<CardGroup cols={2}>
diff --git a/zh/on-call/configuration/custom-forms.mdx b/zh/on-call/configuration/custom-forms.mdx
index 1758c5a7..c7dce561 100644
--- a/zh/on-call/configuration/custom-forms.mdx
+++ b/zh/on-call/configuration/custom-forms.mdx
@@ -4,7 +4,7 @@ description: "为创建、认领和关闭故障配置按条件展示的补充信
keywords: ["自定义表单", "故障创建", "故障认领", "故障关闭", "自定义字段"]
---
-自定义表单让你在处理故障的关键步骤收集一致的信息。你可以分别为 **创建故障**、**认领故障** 和 **关闭故障** 配置一份账户级表单;配置变更会立即应用到相应操作。
+自定义表单让您在处理故障的关键步骤收集一致的信息。您可以分别为 **创建故障**、**认领故障** 和 **关闭故障** 配置一份账户级表单;配置变更会立即应用到相应操作。
表单适合收集值班交接信息、影响范围、处理结论或截图等内容。需要复用业务属性时,先在[自定义字段](/zh/on-call/configuration/custom-fields)中创建字段,再将它加入表单。
@@ -24,7 +24,7 @@ keywords: ["自定义表单", "故障创建", "故障认领", "故障关闭", "
| 图片上传 | 允许填写人在提交操作时上传图片。 |
</Step>
<Step title="设置填写规则">
- 点击已添加的元素,设置帮助说明、占位提示和必填规则。你可以让元素始终显示、在条件满足时显示,或仅在条件满足时必填。
+ 点击已添加的元素,设置帮助说明、占位提示和必填规则。您可以让元素始终显示、在条件满足时显示,或仅在条件满足时必填。
</Step>
<Step title="调整顺序">
拖拽元素调整显示顺序。顺序变更会自动保存,新的填写规则立即生效。
@@ -39,7 +39,7 @@ keywords: ["自定义表单", "故障创建", "故障认领", "故障关闭", "
| 认领故障 | 故障从待处理进入处理中时 | 认领状态与填写的自定义字段会一并提交;说明和图片会记录在认领操作中。 |
| 关闭故障 | 故障从未关闭进入已关闭时 | 关闭状态与填写的自定义字段会一并提交。 |
-表单的显示和必填条件会在用户操作时重新计算。例如,你可以只在特定严重程度、特定标签或特定团队成员处理故障时要求填写某个字段。
+表单的显示和必填条件会在用户操作时重新计算。例如,您可以只在特定严重程度、特定标签或特定团队成员处理故障时要求填写某个字段。
这些表单在 Flashduty App 中同样生效:创建、认领、关闭故障时 App 会弹出同一份表单,两端共用同一配置,显示条件、必填规则和图片上传等行为一致。
@@ -47,21 +47,17 @@ keywords: ["自定义表单", "故障创建", "故障认领", "故障关闭", "
如果某个操作没有配置表单元素,或当前故障和用户不满足表单元素的显示条件,系统会直接执行原有的创建、认领或关闭流程,不会额外要求填写内容。
</Note>
-## 批量操作与自定义表单的并集交互
+## 批量认领或关闭
-在故障列表中勾选 **多条** 故障后批量 **认领** 或 **关闭** 时,系统会先按表单的适用情况把选中项拆成两类,再分别处理:
+在故障列表中批量 **认领** 或 **关闭** 多条故障时:
-- **无需填表的故障**:该操作没有配置表单元素,或当前故障/用户不满足任何元素的显示条件——点击 **认领 / 关闭** 后 **立即执行**,并从选中列表中反选移除,随后才为其余项弹出填写表单
-- **需要填表的故障**:弹出 **并集表单**,填写一次,内容通过一次请求同时写入每一条故障(整体成败;失败时弹窗保持打开,可直接重试)
+- **无需填表的故障**(该操作没有配置表单元素,或故障/用户不满足任何元素的显示条件)立即执行,并从选中列表中移除。
+- **其余故障**弹出一份 **并集表单**:任一故障可见的元素即出现,任一故障必填的元素即必填。填写一次后,内容通过一次请求写入每一条故障,整体成功或失败;失败时弹窗保持打开,可直接重试。
-并集表单的字段由所有待填写故障的并集决定:任一故障可见的元素即出现,任一故障必填的元素即必填。
-
-**混合场景的概览**:当选中项中既有无需填表的、又有需要填表的时,弹窗顶部先显示概览——「已认领 N 条故障 / 待认领 M 条故障」(关闭操作对应「已关闭 / 待关闭」),并注明「以下故障需填写表单后认领,表单内容会同时写入每一条」;如果全部选中项都需要填表,则直接进入表单,不显示概览。
-
-**中途放弃的提示**:如果未提交就关闭弹窗(如点击取消或右上角关闭),且此前已有部分故障被先行执行,会提示「已认领 N 条,其余 M 条未填写表单、未处理」(关闭操作对应「已关闭…」),避免误以为整批操作都已完成。
+两类故障同时存在时,弹窗顶部会显示已执行和待处理的数量;全部需要填表时直接进入表单。如果未提交就关闭弹窗,系统会提示其余故障未填写表单、未处理,避免误以为整批都已完成。
<Note>
- **表单解析异常时的兜底**:单条认领 / 关闭保持原有语义——解析失败直接提示错误,不会静默绕过;批量认领 / 关闭时解析失败不拦截操作,按「无需填表」直接执行整批(与后端对无表单批量请求的降级行为一致)。
+表单解析失败时,单条认领 / 关闭会直接报错;批量认领 / 关闭则不拦截,按无需填表执行整批。
</Note>
## 使用建议
diff --git a/zh/on-call/configuration/filter-conditions.mdx b/zh/on-call/configuration/filter-conditions.mdx
index e136f789..437b8b1a 100644
--- a/zh/on-call/configuration/filter-conditions.mdx
+++ b/zh/on-call/configuration/filter-conditions.mdx
@@ -6,8 +6,6 @@ keywords: ["过滤条件", "条件匹配", "告警筛选", "规则配置", "标
## 在哪里使用过滤条件?
----
-
过滤条件应用于以下场景:
| 场景 | 说明 |
@@ -22,13 +20,9 @@ keywords: ["过滤条件", "条件匹配", "告警筛选", "规则配置", "标
## 如何配置过滤条件?
----
-
### 规则设计
-Flashduty On-call 将整个过滤条件做了抽象,期望做到最小化配置且满足大部分场景需求。
-
-整体判断逻辑分为多组条件:
+过滤条件由多组条件组成:
- **组内条件**:`AND` 关系,即每一个条件均匹配,整个组才为匹配
- **组与组之间**:`OR` 关系,即任一组条件匹配,整体即为匹配
@@ -66,10 +60,6 @@ Flashduty On-call 将整个过滤条件做了抽象,期望做到最小化配
历史上曾分别使用 `alert_severity`(告警严重级别)和 `incident_severity`(故障严重级别)两个字段。目前已统一为 `severity`,加载旧规则时系统会自动将这两个 key 迁移为 `severity`,您无需手动修改,正常保存即可持久化新 key。
</Note>
-<Tip>
-条件中的目标值 value,全部为字符串,支持**精确**、**正则**、**通配**、**IP 段**和**数值大小**等多种匹配方式。
-</Tip>
-

如上图所示,我们有两组条件,每组条件内有两个条件,条件匹配值有多个。表达式如下:
@@ -82,6 +72,8 @@ or
### 匹配方式
+目标值(value)都是字符串,系统按格式识别匹配方式:**正则**、**通配**、**IP 段**、**数值大小**,其余均为**精确**匹配。
+
<Tabs>
<Tab title="正则匹配">
当 value 字符串以 `/` 为前后缀,整个 value 将被识别为**正则**。
@@ -114,7 +106,7 @@ or
当 value 以 `cidr` 作为前缀,整个 value 将被识别为 **IP 段**。
**示例**:
- - `labels.host`:`cidr:10.0.0.206/24` — ip 标签在"10.0.0.206/24"这个 IP 段内,即匹配
+ - `labels.host`:`cidr:10.0.0.206/24` — host 标签在 10.0.0.206/24 这个 IP 段内,即匹配
<Warning>
此过滤条件在以下情况不适用:故障列表按 labels 筛选、告警列表按 labels 筛选、以及告警抑制规则对于活跃告警的筛选。
@@ -146,8 +138,6 @@ or
## 常见问题
----
-
<AccordionGroup>
<Accordion title="为什么系统不提示我可选标签?">
Flashduty On-call 接受大量数据上报,为了保证系统的稳定性,系统仅查找过去 24 小时内,最多 500 条告警事件进行标签的去重操作。因此提取到的标签范围可能会动态变化,甚至在过去 24 小时没有新数据时提取不到任何标签。
diff --git a/zh/on-call/configuration/notifications.mdx b/zh/on-call/configuration/notifications.mdx
index c44bb8b4..ebccc031 100644
--- a/zh/on-call/configuration/notifications.mdx
+++ b/zh/on-call/configuration/notifications.mdx
@@ -5,8 +5,6 @@ keywords: ["通知渠道", "App推送", "语音通知", "短信通知", "邮件
---
## 概览
----
-
### 支持的渠道矩阵
Flashduty On-call 提供覆盖移动端 App、传统通信和主流即时消息 (IM) 工具的全方位通知矩阵。
@@ -24,8 +22,6 @@ Flashduty On-call 提供覆盖移动端 App、传统通信和主流即时消息
## 核心通知渠道配置
----
-
### Flashduty App
Flashduty App 是 On-call 工程师最高效的移动办公工具。无论您身在何处,都能像在电脑前一样全面掌控故障处理流程。
@@ -120,8 +116,6 @@ Flashduty App 是 On-call 工程师最高效的移动办公工具。无论您身
## 即时消息 (IM) 集成
----
-
通过将 Flashduty On-call 与您团队日常使用的 IM 工具(如飞书、钉钉)集成,可以在熟悉的协作环境中接收和处理故障,极大提升 On-call 效率。
### 应用集成(推荐)
@@ -365,8 +359,6 @@ Flashduty App 是 On-call 工程师最高效的移动办公工具。无论您身
## 通用配置
----
-
<AccordionGroup>
<Accordion title="如何自定义通知内容?" icon="paint-brush">
Flashduty On-call 允许您为不同渠道定制个性化的通知消息。
@@ -398,8 +390,6 @@ Flashduty On-call 允许您为不同渠道定制个性化的通知消息。
## 延伸阅读
----
-
<CardGroup cols={2}>
<Card title="分派策略" icon="sitemap" href="/zh/on-call/channel/escalation-rule">
配置告警通知规则和升级路径
diff --git a/zh/on-call/configuration/personal-settings.mdx b/zh/on-call/configuration/personal-settings.mdx
index e2e2865c..1a3440c1 100644
--- a/zh/on-call/configuration/personal-settings.mdx
+++ b/zh/on-call/configuration/personal-settings.mdx
@@ -11,16 +11,12 @@ keywords: ["个人设置", "联系方式", "通知偏好", "API密钥", "账户
## 访问个人中心
----
-
将鼠标悬停在左下角用户图标上,选择 **个人信息**。个人相关设置(**通知偏好**、APP Key、Flashduty APP)位于同一菜单中;组织级设置请前往 **平台管理 → 组织 → 组织信息**。

## 个人信息
----
-
个人设置入口为左下角用户图标 → **个人信息**。页面顶部为**账号名片**,下方为**登录与安全**与**显示偏好**设置。
### 账号名片
@@ -54,7 +50,7 @@ SSO 同步成员的资料由身份提供方维护,页面上的编辑入口不
| 配置项 | 说明 |
| --- | --- |
-| **时区** | 成员账号可设置自己的时区,控制台各页面的时间按此时区显示;留空表示**跟随组织时区**。当检测到的浏览器时区与当前生效时区不一致时,下方会出现「检测到你在某个时区 · 使用」提示,点击 **使用** 即可一键采用;系统不会自动改动你已保存的时区。主体账号没有个人时区——它的显示时区就是组织时区,请前往 **组织信息** 页修改 |
+| **时区** | 成员账号可设置自己的时区,控制台各页面的时间按此时区显示;留空表示**跟随组织时区**。当检测到的浏览器时区与当前生效时区不一致时,下方会出现「检测到你在某个时区 · 使用」提示,点击 **使用** 即可一键采用;系统不会自动改动您已保存的时区。主体账号没有个人时区——它的显示时区就是组织时区,请前往 **组织信息** 页修改 |
<Note>
组织时区由主体账号或 Account.Admin 在 [组织信息](/zh/platform/organization-info) 页统一维护;修改组织时区会影响所有「跟随组织」的成员的时间显示。
@@ -62,8 +58,6 @@ SSO 同步成员的资料由身份提供方维护,页面上的编辑入口不
## 通知偏好
----
-
通知偏好页面按**通知场景**分别配置通知渠道,包含 **故障分派**、**协作与跟进**、**值班轮换** 和 **内部状态页** 四个场景。
各场景支持的通知渠道如下:
@@ -85,7 +79,7 @@ SSO 同步成员的资料由身份提供方维护,页面上的编辑入口不
当故障分派给我时,按故障等级分别选择通知方式。系统支持为 **Critical(紧急)**、**Warning(警告)** 和 **Info(提醒)** 三个级别分别设置通知渠道。
-你可以为每个级别选择以下通知渠道:
+您可以为每个级别选择以下通知渠道:
| 渠道类型 | 说明 |
| --- | --- |
@@ -93,7 +87,7 @@ SSO 同步成员的资料由身份提供方维护,页面上的编辑入口不
| **短信** | 通过短信通知 |
| **邮件** | 通过邮箱发送通知 |
| **Flashduty APP** | 通过 Flashduty 移动端应用推送通知 |
-| **IM 应用** | 通过已集成的钉钉、飞书、企业微信、**Slack**、Microsoft Teams 应用发送通知。每种 IM 类型下你可以进一步选择**具体的集成实例**(例如你的租户内有多个飞书应用时,可以指定使用哪一个) |
+| **IM 应用** | 通过已集成的钉钉、飞书、企业微信、**Slack**、Microsoft Teams 应用发送通知。每种 IM 类型下您可以进一步选择**具体的集成实例**(例如您的租户内有多个飞书应用时,可以指定使用哪一个) |
<Tip>
@@ -141,8 +135,6 @@ SSO 同步成员的资料由身份提供方维护,页面上的编辑入口不
## APP Key
----
-
APP Key 用于 API 请求认证。
| 限制 | 说明 |
@@ -160,8 +152,6 @@ APP Key 用于 API 请求认证。
## Flashduty APP
----
-
### 下载应用
| 平台 | 下载方式 |
@@ -198,8 +188,6 @@ Flashduty APP 支持免费推送告警通知,确保关键告警能即时触达
## 常见问题
----
-
<AccordionGroup>
<Accordion title="设置了个人偏好通知方式,为什么没有触发通知?">
1. 检查协作空间是否配置了分派策略。未配置分派策略时,故障不会触发通知
@@ -211,8 +199,6 @@ Flashduty APP 支持免费推送告警通知,确保关键告警能即时触达
## 延伸阅读
----
-
<CardGroup cols={2}>
<Card title="分派策略" icon="sitemap" href="/zh/on-call/channel/escalation-rule">
设置通知渠道为"遵循个人偏好"
diff --git a/zh/on-call/configuration/schedule.mdx b/zh/on-call/configuration/schedule.mdx
index 429f9867..067ffe25 100644
--- a/zh/on-call/configuration/schedule.mdx
+++ b/zh/on-call/configuration/schedule.mdx
@@ -11,15 +11,11 @@ Flashduty On-call 提供极具灵活性的值班编排能力,支持按天、
{/*
## 视频介绍
----
-
<Video src="https://download.flashcat.cloud/flashduty/video/schedule.mp4"></Video>
*/}
## 核心概念
----
-
在配置之前,理解以下概念有助于您更好地规划值班:
| 概念 | 说明 |
@@ -36,8 +32,6 @@ Flashduty On-call 提供极具灵活性的值班编排能力,支持按天、
## 配置流程
----
-
<Steps>
<Step title="创建值班表">
进入 **值班管理**,点击"创建值班表"
@@ -97,8 +91,6 @@ Flashduty On-call 提供极具灵活性的值班编排能力,支持按天、
## 删除值班表
----
-
您可以在值班管理列表或值班表详情页删除值班表,删除前系统会要求二次确认。
<Warning>
@@ -107,8 +99,6 @@ Flashduty On-call 提供极具灵活性的值班编排能力,支持按天、
## 值班角色
----
-
值班角色用于区分同一值班表中不同职责的值班人员(如"主值班"、"备值班"),是一种账户级资源:
- **账户级共享**:角色在账户层面全局生效,所有值班表共享同一套角色
@@ -121,15 +111,13 @@ Flashduty On-call 提供极具灵活性的值班编排能力,支持按天、
## 临时调班与请假
----
-
当值班人员需要请假或临时有事时,**不要修改永久的值班规则**,请使用"临时调班"(Override)功能。临时调班是一种独立的规则类型,会在其生效窗口内**完全抢占**同一时段的正常值班规则,窗口结束后自动恢复原规则。
### 两种创建入口
<Steps>
<Step title="日历点击创建">
- 进入值班表详情页,在日历视图中点击需要调整的时间段,选择 **临时调班**。系统会自动将默认时间窗口填为 **[今日 00:00, 次日 00:00]**,您可以按需调整。
+ 进入值班表详情页,在日历视图中点击需要调整的时间段,选择 **临时调班**。系统会自动将默认时间窗口填为 **[今日 00:00,次日 00:00]**,您可以按需调整。
</Step>
<Step title="通过 新增规则 创建">
在值班规则列表中点击 **新增规则**,将规则类型切换为 **临时调班**。该入口适合提前批量安排请假或替班。
@@ -156,8 +144,6 @@ Flashduty On-call 提供极具灵活性的值班编排能力,支持按天、
## 日期掩码与连续轮换
----
-
### 日期掩码
日期掩码用于控制值班规则在一周中的哪些天生效。通过选择不同的星期组合,可以灵活实现工作日与周末的差异化排班。
@@ -187,8 +173,6 @@ Flashduty On-call 提供极具灵活性的值班编排能力,支持按天、
## 常见排班场景
----
-
<Tabs>
<Tab title="7x24 简单轮换">
**需求**:运维组有 A、B、C 三位同学,每人值班一周,周一上午 10:00 交接。
@@ -235,8 +219,6 @@ Flashduty On-call 提供极具灵活性的值班编排能力,支持按天、
## 查看值班详情
----
-
点击值班表名称进入详情页,您可以查看排班日历和管理值班规则。页面右上角提供以下操作:
- **视图切换**:在"一周"、"两周"和"日历"(月视图)之间切换
@@ -246,9 +228,7 @@ Flashduty On-call 提供极具灵活性的值班编排能力,支持按天、
## 查看我的值班
----
-
-**值班管理** 列表页顶部内嵌「我的值班」区块,以周视图汇总展示你参与的值班安排:左侧列出本周有值班安排的值班表名称,右侧日历展示你在各值班表中的值班时段。
+**值班管理** 列表页顶部内嵌「我的值班」区块,以周视图汇总展示您参与的值班安排:左侧列出本周有值班安排的值班表名称,右侧日历展示您在各值班表中的值班时段。
点击标题右侧的左右箭头可按周翻看此前或之后的值班安排,点击中间的圆点按钮可快速回到本周。
@@ -256,8 +236,6 @@ Flashduty On-call 提供极具灵活性的值班编排能力,支持按天、
## 延伸阅读
----
-
<CardGroup cols={2}>
<Card title="分派策略" icon="sitemap" href="/zh/on-call/channel/escalation-rule">
配置告警通知规则和升级路径
diff --git a/zh/on-call/configuration/service-calendar.mdx b/zh/on-call/configuration/service-calendar.mdx
index 537fa195..12829246 100644
--- a/zh/on-call/configuration/service-calendar.mdx
+++ b/zh/on-call/configuration/service-calendar.mdx
@@ -10,16 +10,12 @@ keywords: ["服务日历", "工作日", "休息日", "节假日", "差异化处
{/*
## 视频介绍
----
-
<Video src="https://download.flashcat.cloud/flashduty/video/calendar.mp4"></Video>
*/}
## 应用场景
----
-
| 场景 | 说明 |
| --- | --- |
| **分派策略** | 按工作日/休息日分派给不同的值班人员 |
@@ -27,8 +23,6 @@ keywords: ["服务日历", "工作日", "休息日", "节假日", "差异化处
## 创建日历
----
-
进入 **配置中心 → 服务日历**,点击 **新增日历**。
| 配置项 | 说明 |
@@ -49,8 +43,6 @@ keywords: ["服务日历", "工作日", "休息日", "节假日", "差异化处
## 编辑日历
----
-
| 操作 | 说明 |
| --- | --- |
| **修改基础信息** | 日历名称、描述、管理团队 |
@@ -66,8 +58,6 @@ keywords: ["服务日历", "工作日", "休息日", "节假日", "差异化处
## 常见问题
----
-
<AccordionGroup>
<Accordion title="服务日历与值班表有什么区别?">
两者定位不同:
@@ -81,8 +71,6 @@ keywords: ["服务日历", "工作日", "休息日", "节假日", "差异化处
## 延伸阅读
----
-
<CardGroup cols={2}>
<Card title="分派策略" icon="sitemap" href="/zh/on-call/channel/escalation-rule">
在分派策略中引用服务日历
diff --git a/zh/on-call/configuration/templates.mdx b/zh/on-call/configuration/templates.mdx
index 03b792a6..5a54605c 100644
--- a/zh/on-call/configuration/templates.mdx
+++ b/zh/on-call/configuration/templates.mdx
@@ -165,192 +165,6 @@ keywords: ["通知模板", "模板配置", "消息格式", "模板变量", "通
</Accordion>
</AccordionGroup>
-## 常见问题
-
-<AccordionGroup>
-<Accordion title="如何知道 Labels 有哪些标签?">
-- 手动创建的故障没有标签
-- 自动创建的故障存在标签,与合入的第一条告警的标签相同
-
-前往 **故障列表** → 查看故障详情,可以看到全部标签信息。
-</Accordion>
-
-<Accordion title="配置了自定义模板,实际却使用了默认模板?">
-创建自定义模板时,系统使用 mock 数据检查语法。mock 数据覆盖场景有限,实际运行时可能渲染失败,系统将使用默认模板兜底。
-
-<Tip>
-建议在引用变量前先判断是否存在:
-
-```go
-// ❌ 错误:直接读取标签
-{{.Labels.resource}}
-
-// ✅ 推荐:先判断再读取
-{{if .Labels.resource}}{{.Labels.resource}}{{end}}
-```
-</Tip>
-</Accordion>
-
-<Accordion title="故障标题含有字符转义(如 >)?">
-使用 `toHtml` 函数处理:
-
-```go
-// 转义 HTML 字符
-{{toHtml .Title}}
-
-// 使用第一个不为空的值渲染
-{{toHtml .Title .TitleEnglish}}
-```
-</Accordion>
-
-<Accordion title="如何转换时间格式?">
-```go
-// date 函数:将时间戳转换为可读格式
-{{date "2006-01-02 15:04:05" .StartTime}}
-
-// ago 函数:将时间差转换为可读格式(如 "5 分钟前")
-{{ago .StartTime}}
-```
-</Accordion>
-
-<Accordion title="如何在 for 循环内部引用外部变量?">
-在外部变量前增加 `$`:
-
-```go
-{{range .Responders}}
- {{if eq $.Progress "Triggered"}}
- 【待处理】{{.Email}}
- {{end}}
-{{end}}
-```
-</Accordion>
-
-<Accordion title="如何提取带 . 的字段值(如 obj.instance)?">
-使用 `index` 函数:
-
-```go
-{{index .Labels "obj.instance"}}
-```
-</Accordion>
-
-<Accordion title="如何提取关联告警中的 label 并去重?">
-```go
-// alertLabels:得到去重后的数组
-{{alertLabels . "resource"}}
-
-// joinAlertLabels:去重后按分隔符拼接为字符串
-{{joinAlertLabels . "resource" ", "}}
-```
-</Accordion>
-
-<Accordion title="如何遍历并打印 Labels?">
-```go
-// 完整遍历
-{{range $k, $v := .Labels}}
- {{$k}} : {{toHtml $v}}
-{{end}}
-
-// 排除单个 label
-{{range $k, $v := .Labels}}
- {{if ne $k "resource"}}
- {{$k}} : {{toHtml $v}}
- {{end}}
-{{end}}
-
-// 排除多个 labels
-{{range $k, $v := .Labels}}
- {{if not (in $k "resource" "body_text")}}
- {{$k}} : {{toHtml $v}}
- {{end}}
-{{end}}
-```
-</Accordion>
-
-<Accordion title="如何从 JSON 字段中提取信息?">
-使用 `jsonGet` 函数从合法 JSON 中按 path 提取值。语法参考 [gjson.dev](https://gjson.dev/)。
-
-```go
-// 提取 rule_note 标签中的 detail_url 字段
-{{jsonGet .Labels.rule_note "detail_url"}}
-
-// 提取 JSON 数组中第一个元素的 name 字段
-{{jsonGet .Labels.slice "0.name"}}
-
-// 遍历数组,匹配 userId==7777 的 instanceId 字段
-{{jsonGet .Labels.rule_note "#(userId==7777)#.instanceId"}}
-```
-</Accordion>
-
-<Accordion title="如何在发送应用消息时携带图片?">
-### 通过 imageSrcToURL 获取图片 URL
-
-**imageSrcToURL** 函数用于将图片的 `Src` 属性转换为可访问的 URL。
-
-**参数说明:**
-- `$root`:根上下文对象
-- `Src`:图片源,可以是 `image_key` 或 http/https URL
-
-**处理逻辑:**
-- 如果 `Src` 是从图片上传界面获取的 `image_key`,会转换为可访问的 URL(短期有效)
-- 如果 `Src` 是 http/https 地址,直接返回该地址
-
-**适用平台:** 钉钉应用、Slack 应用
-
-**使用示例:**
-
-```go
-{{ $root := . }}
-{{ range $i, $v := .Images }}
- {{ $imageURL := imageSrcToURL $root $v.Src }}
- {{ if $imageURL }}{{ end }}
-{{ end }}
-```
-
-### 通过 transferImage 上传图片到第三方平台
-
-**transferImage** 函数用于将图片转换并上传到第三方通知平台。
-
-**参数说明:**
-- `$root`:根上下文对象
-- `Src`:图片源,可以是 `image_key` 或 http/https URL
-
-**限制条件:**
-- 最大图片大小:10 MB
-- 支持格式:JPG、JPEG、PNG、WEBP、GIF、BMP、ICO、TIFF、HEIC
-
-**权限要求:** 需要应用具备"获取与上传图片或文件资源"的权限
-
-**适用平台:** 飞书应用(Lark App)
-
-**使用示例:**
-
-```go
-{{ $root := . }}
-{{ range $i, $v := .Images }}
- {{ $transferURL := transferImage $root $v.Src }}
- {{ if $transferURL }}{{ end }}
-{{ end }}
-```
-</Accordion>
-
-<Accordion title="如何使用逻辑运算?">
-| 函数 | 说明 | 示例 |
-| :--- | :--- | :--- |
-| `and` | 逻辑与 | `{{if and (eq .A "x") (eq .B "y")}}` |
-| `or` | 逻辑或 | `{{if or (eq .A "x") (eq .A "y")}}` |
-| `not` | 逻辑非 | `{{if not (eq .A "x")}}` |
-| `eq` | 等于 | `{{if eq .A "x"}}` |
-| `ne` | 不等于 | `{{if ne .A "x"}}` |
-| `gt` / `ge` | 大于 / 大于等于 | `{{if gt .AlertCnt 1}}` |
-| `lt` / `le` | 小于 / 小于等于 | `{{if lt .AlertCnt 10}}` |
-</Accordion>
-
-<Accordion title="如何查阅更多函数?">
-- 函数列表:[functions.go](https://github.com/flashcatcloud/sprig/blob/master/functions.go#L97)
-- 使用示例:查看对应的 `_test.go` 文件,如 [date_test.go](https://github.com/flashcatcloud/sprig/blob/master/date_test.go)
-</Accordion>
-</AccordionGroup>
-
## 渠道模板
不同通知渠道支持的模板格式和限制不同。
@@ -392,21 +206,21 @@ keywords: ["通知模板", "模板配置", "消息格式", "模板变量", "通
### 卡片字段与底部操作按钮
-编辑飞书应用模板时,**正文内容** 旁的 **附加信息** 页签提供卡片字段开关面板(面板提示「以下内容由系统渲染,可通过开关控制是否展示在消息底部。」),用于控制协作空间、暂缓截止时间、严重程度、聚合告警数、处理人员、详情按钮、AI 分析共 7 个系统字段是否渲染在卡片底部。
-
-其中 **创建作战室** 开关在飞书应用、钉钉应用、Slack 应用模板中均可配置(分别对应字段 `feishu_app_war_room_enabled`、`dingtalk_app_war_room_enabled`、`slack_app_war_room_enabled`,默认**关闭**,开启后需保存模板生效)。开关文案即 **创建作战室**,面板中的说明为「开启后,满足建群条件时,在卡片底部展示独立的创建作战室按钮。」
+**正文内容** 旁的 **附加信息** 页签用于控制卡片底部展示哪些系统内容。各渠道支持的开关如下:
-- **开启**:故障未关闭、未创建作战室且存在处理人员时,对应渠道的故障卡片底部会展示独立的 **👥 创建作战室** 按钮,点击按钮即可发起建群
-- **关闭**:卡片底部不展示该按钮
+| 开关 | 飞书应用 | 钉钉应用 | Slack 应用 | Microsoft Teams | 企业微信应用 |
+| --- | --- | --- | --- | --- | --- |
+| 协作空间、暂缓截止时间、严重程度、聚合告警数、处理人员、详情按钮 | ✓ | ✓ | ✓ | ✓ | ✓ |
+| AI 分析 | ✓ | ✓ | ✓ | — | — |
+| 创建作战室 | ✓ | ✓ | ✓ | — | — |
+| 故障关闭后保留自定义操作 | ✓ | ✓ | ✓ | ✓ | — |
-**故障关闭后保留自定义操作** 开关在飞书应用、钉钉应用、Slack 应用、Microsoft Teams 模板中均提供,企业微信应用模板不提供(面板不渲染该开关)。对应字段 `incident_card_closed_action_apps` 为字符串数组,存放已开启该能力的渠道 key(如 `["feishu_app"]`),默认**关闭**(数组为空即关闭),开启后需保存模板生效。
+- **创建作战室**(默认关闭):开启后,故障未关闭、尚无作战室且有处理人员时,卡片底部显示 **👥 创建作战室** 按钮,点击即可建群。
+- **故障关闭后保留自定义操作**(默认关闭):开启后,故障关闭后 3 天内仍可在消息卡片上执行已配置的自定义操作;关闭时或超过 3 天,请到故障详情页执行。
-- **开启**:面板说明为「已开启,故障关闭后 3 天内可从消息卡片中执行已配置的自定义操作,超过有效期请进入详情页执行。」故障关闭后 3 天内已配置的自定义操作仍可从消息卡片直接执行,超过 3 天需进入故障详情页执行
-- **关闭**:面板说明为「已关闭,故障关闭后将隐藏消息卡片中的自定义操作入口,仍可进入详情页执行。」故障关闭后消息卡片不再展示自定义操作入口,仍需进入故障详情页执行
+修改开关后需保存模板才会生效。
-加上上文 7 个卡片字段开关,飞书应用、钉钉应用、Slack 应用模板的 **附加信息** 面板各有 **9 个开关**,Microsoft Teams 模板 **7 个**,企业微信应用模板 **6 个**(见下方各渠道模板说明)。
-
-同时,飞书应用卡片底部的操作区已调整:**更多操作**(占位文案即「更多操作」)改为下拉选择菜单,菜单内为自定义操作、暂缓时长与取消认领等选项,作战室按钮不再位于该菜单中。
+飞书应用卡片底部的 **更多操作** 是一个下拉菜单,包含自定义操作、暂缓时长与取消认领等选项;**👥 创建作战室** 按钮单独显示,不在该菜单中。
</Tab>
<Tab title="钉钉应用">
@@ -429,7 +243,7 @@ keywords: ["通知模板", "模板配置", "消息格式", "模板变量", "通
<img src="https://download.flashcat.cloud/flashduty/changelog/20230720/dingtalk_app_render.png" alt="钉钉应用通知" />
</Frame>
-与飞书应用一致,**正文内容** 旁的 **附加信息** 页签提供卡片字段开关面板(面板提示「以下内容由系统渲染,可通过开关控制是否展示在消息底部。」),用于控制协作空间、暂缓截止时间、严重程度、聚合告警数、处理人员、详情按钮、AI 分析共 7 个系统字段是否渲染在卡片底部;钉钉应用同样提供 **创建作战室** 开关(对应字段 `dingtalk_app_war_room_enabled`,默认**关闭**,开启后需保存模板生效)与 **故障关闭后保留自定义操作** 开关(记入 `incident_card_closed_action_apps` 渠道 key 数组,默认**关闭**),**附加信息** 面板共 **9 个开关**。
+**正文内容** 旁 **附加信息** 页签中的开关见上文[卡片字段与底部操作按钮](#卡片字段与底部操作按钮)。
</Tab>
<Tab title="企业微信应用">
@@ -455,7 +269,7 @@ keywords: ["通知模板", "模板配置", "消息格式", "模板变量", "通
<img src="https://download.flashcat.cloud/flashduty/changelog/20230720/wecom_app_render.png" alt="企业微信应用通知" />
</Frame>
-与飞书应用一致,**正文内容** 旁的 **附加信息** 页签提供卡片字段开关面板(面板提示「以下内容由系统渲染,可通过开关控制是否展示在消息底部。」),用于控制协作空间、暂缓截止时间、严重程度、聚合告警数、处理人员、详情按钮共 6 个系统字段是否渲染在卡片底部。企业微信应用模板不提供 **AI 分析**、**创建作战室**、**故障关闭后保留自定义操作** 开关,**附加信息** 面板共 **6 个开关**。
+**正文内容** 旁 **附加信息** 页签中的开关见上文[卡片字段与底部操作按钮](#卡片字段与底部操作按钮)。
</Tab>
<Tab title="Slack 应用">
@@ -486,7 +300,7 @@ keywords: ["通知模板", "模板配置", "消息格式", "模板变量", "通
<img src="https://download.flashcat.cloud/flashduty/integration/slack/slack_app_message.png" alt="Slack 应用通知" />
</Frame>
-与飞书应用一致,**正文内容** 旁的 **附加信息** 页签提供卡片字段开关面板(面板提示「以下内容由系统渲染,可通过开关控制是否展示在消息底部。」),用于控制协作空间、暂缓截止时间、严重程度、聚合告警数、处理人员、详情按钮、AI 分析共 7 个系统字段是否渲染在卡片底部;Slack 应用同样提供 **创建作战室** 开关(对应字段 `slack_app_war_room_enabled`,默认**关闭**,开启后需保存模板生效)与 **故障关闭后保留自定义操作** 开关(记入 `incident_card_closed_action_apps` 渠道 key 数组,默认**关闭**),**附加信息** 面板共 **9 个开关**。
+**正文内容** 旁 **附加信息** 页签中的开关见上文[卡片字段与底部操作按钮](#卡片字段与底部操作按钮)。
</Tab>
<Tab title="Microsoft Teams">
@@ -505,7 +319,7 @@ keywords: ["通知模板", "模板配置", "消息格式", "模板变量", "通
<img src="https://download.flashcat.cloud/flashduty/integration/microsoft-teams/teams_app_message.png" alt="Teams 应用通知" />
</Frame>
-与飞书应用一致,**正文内容** 旁的 **附加信息** 页签提供卡片字段开关面板(面板提示「以下内容由系统渲染,可通过开关控制是否展示在消息底部。」),用于控制协作空间、暂缓截止时间、严重程度、聚合告警数、处理人员、详情按钮共 6 个系统字段是否渲染在卡片底部,另有 **故障关闭后保留自定义操作** 开关(记入 `incident_card_closed_action_apps` 渠道 key 数组,默认**关闭**),**附加信息** 面板共 **7 个开关**。Microsoft Teams 模板不提供 **AI 分析**、**创建作战室** 开关。
+**正文内容** 旁 **附加信息** 页签中的开关见上文[卡片字段与底部操作按钮](#卡片字段与底部操作按钮)。
</Tab>
</Tabs>
@@ -748,6 +562,192 @@ Markdown v2 按 UTF-8 字节计算,消息最大为 **4096 字节**。中文通
</Tab>
</Tabs>
+## 常见问题
+
+<AccordionGroup>
+<Accordion title="如何知道 Labels 有哪些标签?">
+- 手动创建的故障没有标签
+- 自动创建的故障存在标签,与合入的第一条告警的标签相同
+
+前往 **故障列表** → 查看故障详情,可以看到全部标签信息。
+</Accordion>
+
+<Accordion title="配置了自定义模板,实际却使用了默认模板?">
+创建自定义模板时,系统使用 mock 数据检查语法。mock 数据覆盖场景有限,实际运行时可能渲染失败,系统将使用默认模板兜底。
+
+<Tip>
+建议在引用变量前先判断是否存在:
+
+```go
+// ❌ 错误:直接读取标签
+{{.Labels.resource}}
+
+// ✅ 推荐:先判断再读取
+{{if .Labels.resource}}{{.Labels.resource}}{{end}}
+```
+</Tip>
+</Accordion>
+
+<Accordion title="故障标题含有字符转义(如 >)?">
+使用 `toHtml` 函数处理:
+
+```go
+// 转义 HTML 字符
+{{toHtml .Title}}
+
+// 使用第一个不为空的值渲染
+{{toHtml .Title .TitleEnglish}}
+```
+</Accordion>
+
+<Accordion title="如何转换时间格式?">
+```go
+// date 函数:将时间戳转换为可读格式
+{{date "2006-01-02 15:04:05" .StartTime}}
+
+// ago 函数:将时间差转换为可读格式(如 "5 分钟前")
+{{ago .StartTime}}
+```
+</Accordion>
+
+<Accordion title="如何在 for 循环内部引用外部变量?">
+在外部变量前增加 `$`:
+
+```go
+{{range .Responders}}
+ {{if eq $.Progress "Triggered"}}
+ 【待处理】{{.Email}}
+ {{end}}
+{{end}}
+```
+</Accordion>
+
+<Accordion title="如何提取带 . 的字段值(如 obj.instance)?">
+使用 `index` 函数:
+
+```go
+{{index .Labels "obj.instance"}}
+```
+</Accordion>
+
+<Accordion title="如何提取关联告警中的 label 并去重?">
+```go
+// alertLabels:得到去重后的数组
+{{alertLabels . "resource"}}
+
+// joinAlertLabels:去重后按分隔符拼接为字符串
+{{joinAlertLabels . "resource" ", "}}
+```
+</Accordion>
+
+<Accordion title="如何遍历并打印 Labels?">
+```go
+// 完整遍历
+{{range $k, $v := .Labels}}
+ {{$k}} : {{toHtml $v}}
+{{end}}
+
+// 排除单个 label
+{{range $k, $v := .Labels}}
+ {{if ne $k "resource"}}
+ {{$k}} : {{toHtml $v}}
+ {{end}}
+{{end}}
+
+// 排除多个 labels
+{{range $k, $v := .Labels}}
+ {{if not (in $k "resource" "body_text")}}
+ {{$k}} : {{toHtml $v}}
+ {{end}}
+{{end}}
+```
+</Accordion>
+
+<Accordion title="如何从 JSON 字段中提取信息?">
+使用 `jsonGet` 函数从合法 JSON 中按 path 提取值。语法参考 [gjson.dev](https://gjson.dev/)。
+
+```go
+// 提取 rule_note 标签中的 detail_url 字段
+{{jsonGet .Labels.rule_note "detail_url"}}
+
+// 提取 JSON 数组中第一个元素的 name 字段
+{{jsonGet .Labels.slice "0.name"}}
+
+// 遍历数组,匹配 userId==7777 的 instanceId 字段
+{{jsonGet .Labels.rule_note "#(userId==7777)#.instanceId"}}
+```
+</Accordion>
+
+<Accordion title="如何在发送应用消息时携带图片?">
+**通过 imageSrcToURL 获取图片 URL**
+
+**imageSrcToURL** 函数用于将图片的 `Src` 属性转换为可访问的 URL。
+
+**参数说明:**
+- `$root`:根上下文对象
+- `Src`:图片源,可以是 `image_key` 或 http/https URL
+
+**处理逻辑:**
+- 如果 `Src` 是从图片上传界面获取的 `image_key`,会转换为可访问的 URL(短期有效)
+- 如果 `Src` 是 http/https 地址,直接返回该地址
+
+**适用平台:** 钉钉应用、Slack 应用
+
+**使用示例:**
+
+```go
+{{ $root := . }}
+{{ range $i, $v := .Images }}
+ {{ $imageURL := imageSrcToURL $root $v.Src }}
+ {{ if $imageURL }}{{ end }}
+{{ end }}
+```
+
+**通过 transferImage 上传图片到第三方平台**
+
+**transferImage** 函数用于将图片转换并上传到第三方通知平台。
+
+**参数说明:**
+- `$root`:根上下文对象
+- `Src`:图片源,可以是 `image_key` 或 http/https URL
+
+**限制条件:**
+- 最大图片大小:10 MB
+- 支持格式:JPG、JPEG、PNG、WEBP、GIF、BMP、ICO、TIFF、HEIC
+
+**权限要求:** 需要应用具备"获取与上传图片或文件资源"的权限
+
+**适用平台:** 飞书应用(Lark App)
+
+**使用示例:**
+
+```go
+{{ $root := . }}
+{{ range $i, $v := .Images }}
+ {{ $transferURL := transferImage $root $v.Src }}
+ {{ if $transferURL }}{{ end }}
+{{ end }}
+```
+</Accordion>
+
+<Accordion title="如何使用逻辑运算?">
+| 函数 | 说明 | 示例 |
+| :--- | :--- | :--- |
+| `and` | 逻辑与 | `{{if and (eq .A "x") (eq .B "y")}}` |
+| `or` | 逻辑或 | `{{if or (eq .A "x") (eq .A "y")}}` |
+| `not` | 逻辑非 | `{{if not (eq .A "x")}}` |
+| `eq` | 等于 | `{{if eq .A "x"}}` |
+| `ne` | 不等于 | `{{if ne .A "x"}}` |
+| `gt` / `ge` | 大于 / 大于等于 | `{{if gt .AlertCnt 1}}` |
+| `lt` / `le` | 小于 / 小于等于 | `{{if lt .AlertCnt 10}}` |
+</Accordion>
+
+<Accordion title="如何查阅更多函数?">
+- 函数列表:[functions.go](https://github.com/flashcatcloud/sprig/blob/master/functions.go#L97)
+- 使用示例:查看对应的 `_test.go` 文件,如 [date_test.go](https://github.com/flashcatcloud/sprig/blob/master/date_test.go)
+</Accordion>
+</AccordionGroup>
+
## 延伸阅读
<CardGroup cols={2}>
diff --git a/zh/on-call/incident/alert-management.mdx b/zh/on-call/incident/alert-management.mdx
index a289ad70..5d7ddace 100644
--- a/zh/on-call/incident/alert-management.mdx
+++ b/zh/on-call/incident/alert-management.mdx
@@ -6,7 +6,7 @@ keywords: ["告警管理", "告警列表", "告警详情", "聚合视图", "告
## 告警列表
-告警管理页面提供了独立于故障的告警视角,你可以在此查看所有告警的详细信息,无论这些告警是否已被聚合到故障中。
+告警管理页面提供了独立于故障的告警视角,您可以在此查看所有告警的详细信息,无论这些告警是否已被聚合到故障中。
进入 **故障列表** → **告警列表**,即可访问告警管理页面。
@@ -25,7 +25,7 @@ keywords: ["告警管理", "告警列表", "告警详情", "聚合视图", "告
| **协作空间** | 告警所属的协作空间 |
<Note>
-被静默或抑制的告警会在标题前显示特殊标记,帮助你快速识别。
+被静默或抑制的告警会在标题前显示特殊标记,帮助您快速识别。
</Note>
### 字段说明
@@ -60,15 +60,15 @@ keywords: ["告警管理", "告警列表", "告警详情", "聚合视图", "告
| 选项 | 说明 |
| :--- | :--- |
-| **详情展示** | 选择点击告警后以 **页面** 还是 **右侧面板** 打开详情 |
+| **详情展示** | 选择点击告警后以 **页面** 还是 **右侧面板** 打开详情;右侧面板无需跳转即可快速浏览 |
| **自动刷新** | 可选 关闭 / 5 秒 / 10 秒 / 20 秒 / 30 秒 / 1 分钟 / 2 分钟 / 3 分钟 / 5 分钟 / 10 分钟,默认 10 秒 |
| **展示属性** | 切换是否恢复、故障处理进度、关联事件、关联故障、触发时间、集成来源、协作空间等列的显隐 |
-视图设置会按视图保留,在当前浏览器中长期保留。
+视图设置按视图分别保存在当前浏览器中。
### 批量操作
-你可以在列表中勾选多条告警,点击顶部的 **并入** 按钮将所选告警一次性并入指定故障。
+您可以在列表中勾选多条告警,点击顶部的 **并入** 按钮将所选告警一次性并入指定故障。
### 使用聚合视图
@@ -76,7 +76,7 @@ keywords: ["告警管理", "告警列表", "告警详情", "聚合视图", "告
<Steps>
<Step title="创建聚合视图">
-切换到聚合视图后,如果尚未创建聚合规则,系统将引导你创建第一个聚合视图。
+切换到聚合视图后,如果尚未创建聚合规则,系统将引导您创建第一个聚合视图。
</Step>
<Step title="选择分组维度">
选择用于分组的聚合规则,系统将按该维度对告警进行分组。
@@ -92,7 +92,7 @@ keywords: ["告警管理", "告警列表", "告警详情", "聚合视图", "告
## 告警详情
-点击告警标题进入告警详情页。告警详情页顶部为 **HeaderInfo 信息栏**,展示告警标题、严重级别标签、告警 ID(悬停可复制全量 ID)、恢复状态(已恢复 / 未恢复)以及所属故障的处理进度标签。若告警曾被静默或抑制,标题前会显示对应图标。信息栏右侧提供 **并入** 操作按钮,可将当前告警并入某个故障。
+点击告警标题进入告警详情页。告警详情页顶部的信息栏展示告警标题、严重级别标签、告警 ID(悬停可复制全量 ID)、恢复状态(已恢复 / 未恢复)以及所属故障的处理进度标签。若告警曾被静默或抑制,标题前会显示对应图标。信息栏右侧提供 **并入** 操作按钮,可将当前告警并入某个故障。
详情页主体区分为两个 Tab:
@@ -101,17 +101,13 @@ keywords: ["告警管理", "告警列表", "告警详情", "聚合视图", "告
| **告警概览** | 左侧展示告警描述、标签、**关联事件预览**(最多 5 条,可跳转到 *关联事件* Tab 查看全部);右侧展示属性(协作空间、触发时间)、图片、告警来源、所属故障、Links |
| **关联事件** | 展示该告警关联的所有原始事件列表 |
-页签状态由 URL 参数 `tab` 控制:在告警详情地址后附加 `?tab=events`(如 `/alert/detail/{id}?tab=events`)可直达 **关联事件** 页签,页签切换也会同步到浏览器地址栏。故障详情中「仅展示最新 N 条告警事件」提示的 **查看完整事件历史** 入口即使用该方式打开。
+在告警详情地址后附加 `?tab=events`(如 `/alert/detail/{id}?tab=events`)可直达 **关联事件** 页签;切换页签时地址栏会同步更新。故障详情中的 **查看完整事件历史** 链接就是这样打开的。
-**告警来源**支持点击跳转,便于你快速溯源:
+**告警来源**支持点击跳转,便于您快速溯源:
- **Monit 集成的告警**:显示产生该告警的规则名称,点击跳转到对应告警规则——实体树规则直接打开实体树的规则编辑视图,独立规则跳转到规则详情页;老数据缺少规则标签时,回退显示集成名称并跳转集成详情
- **其他集成的告警**:显示集成名称和类型标记(共享或专属),点击跳转到对应集成详情页
-<Tip>
-你也可以在告警列表的视图设置中,选择以 **右侧面板** 模式查看详情,无需跳转新页面即可快速浏览告警信息。
-</Tip>
-
### 告警生命周期记录
告警从触发到关闭的整个过程会被系统完整记录,常见的记录类型如下:
diff --git a/zh/on-call/incident/custom-actions.mdx b/zh/on-call/incident/custom-actions.mdx
index fe22d55d..58db1156 100644
--- a/zh/on-call/incident/custom-actions.mdx
+++ b/zh/on-call/incident/custom-actions.mdx
@@ -1,6 +1,6 @@
---
title: "故障自定义操作"
-sidebarTitle: "自定义操作"
+sidebarTitle: "故障自定义操作"
description: "了解自定义操作的使用场景和配置方式"
keywords: ["自定义操作", "Webhook", "自动化", "故障处理", "操作配置"]
---
@@ -28,7 +28,7 @@ keywords: ["自定义操作", "Webhook", "自动化", "故障处理", "操作配
<Steps>
<Step title="进入集成中心">
-登录控制台,进入 **集成中心 => Webhook**。
+登录控制台,进入 **集成中心 → Webhook**。
</Step>
<Step title="添加集成">
diff --git a/zh/on-call/incident/escalate-dispatch-incident.mdx b/zh/on-call/incident/escalate-dispatch-incident.mdx
index 85b50df4..a26dec8b 100644
--- a/zh/on-call/incident/escalate-dispatch-incident.mdx
+++ b/zh/on-call/incident/escalate-dispatch-incident.mdx
@@ -26,7 +26,7 @@ keywords: ["故障升级", "重新分派", "处理人", "故障分派", "升级
## 添加处理人
-当故障分派给您,但您需要其他人员(此人员不在处理人员中)一同参与处理,你可以选择添加处理人。
+当故障分派给您,但您需要其他人员(此人员不在处理人员中)一同参与处理,您可以选择添加处理人。
与 **重新分派** 类似,添加处理人,只能选择值班表或者个人作为分派目标。系统会按照个人偏好来通知这些人员。
diff --git a/zh/on-call/incident/handle-update-incident.mdx b/zh/on-call/incident/handle-update-incident.mdx
index c6034d00..a2f70941 100644
--- a/zh/on-call/incident/handle-update-incident.mdx
+++ b/zh/on-call/incident/handle-update-incident.mdx
@@ -66,12 +66,12 @@ keywords: ["故障处理", "故障更新", "认领故障", "关闭故障", "状
<Tab title="通过控制台认领">
- **单个认领**:控制台点击故障详情,点击 **认领** 按钮,完成认领
- **批量操作**:控制台故障列表,选中多个待处理的故障,点击 **认领** 按钮,完成批量认领
-- **AI 分析**:选中多个故障后,点击 **AI 分析** 按钮,可将选中的故障作为上下文批量推送给 AI SRE Agent 进行分析。该按钮需要 AI SRE 模块开启且有 `AiSreChatVisit` 权限;若选中的故障分属同一团队,会自动以该团队为会话范围。
+- **AI 分析**:选中多个故障后,点击 **AI 分析** 按钮,可将选中的故障作为上下文批量推送给 AI SRE Agent 进行分析。需已开通 AI SRE 并有使用 AI SRE 对话的权限;若选中的故障分属同一团队,会自动以该团队为会话范围。
</Tab>
<Tab title="通过 IM 应用认领">
-- **应用消息**:应用类消息主卡片,提供一个 **认领** 按钮,点击卡片即可完成认领。如果您点击卡片没有任何反应,可能是您没有在应用内完成登录账户关联或其他原因。详情请参考[飞书集成指引](/zh/on-call/integration/instant-messaging/lark)
-- **机器人消息**:大部分机器人通道,均以 Markdown 形式推送消息。您可以修改通知模板,增加一个 **认领** 跳转链接,以实现跳转到控制台进行认领。详情请参考默认模板
+- **应用消息**:点击消息卡片上的 **认领** 按钮即可认领。如果点击没有反应,通常是您还没有在应用内关联 Flashduty 账户。详情请参考[飞书集成指引](/zh/on-call/integration/instant-messaging/lark)
+- **机器人消息**:大部分机器人通道,均以 Markdown 形式推送消息。您可以在[通知模板](/zh/on-call/configuration/templates)中增加一个 **认领** 链接,跳转到控制台认领。
</Tab>
<Tab title="通过语音电话认领">
@@ -136,7 +136,7 @@ Flashduty On-call 推送的语音告警,在语音播报结束时,会提醒
## 关闭故障
-您有多种方式关闭一个故障。
+任何处理进度的故障都可以关闭,关闭后处理进度变为 **已关闭**,关联的告警不再合入新事件。如果告警在原监控系统中没有恢复,后续事件会在 Flashduty On-call 中触发新的告警和故障。
<Tabs>
<Tab title="通过控制台关闭">
@@ -145,7 +145,7 @@ Flashduty On-call 推送的语音告警,在语音播报结束时,会提醒
</Tab>
<Tab title="通过 IM 应用关闭">
-应用类消息主卡片,提供一个 **关闭** 按钮,点击卡片即可完成认领。如果您点击卡片没有任何反应,可能是您没有在应用内完成登录账户关联或其他原因。详情请参考[飞书集成指引](/zh/on-call/integration/instant-messaging/lark)。
+点击消息卡片上的 **关闭** 按钮即可关闭。如果点击没有反应,通常是您还没有在应用内关联 Flashduty 账户。详情请参考[飞书集成指引](/zh/on-call/integration/instant-messaging/lark)。
</Tab>
<Tab title="通过 Flashduty App 关闭">
@@ -159,9 +159,7 @@ Flashduty On-call 推送的语音告警,在语音播报结束时,会提醒
### 重新打开故障
-手动关闭故障,会将故障的处理进度变更为 **已关闭**。您可以在任何状态下,点击 **关闭** 按钮。一个故障手动关闭之后,其关联的告警也将停止合入新的事件。如果告警在原告警系统中没有恢复,可能会产生新的通知事件,这将导致在 Flashduty On-call 触发新的告警和故障。
-
-您可以在误关闭故障之后,重新打开故障。操作步骤如下:
+误关闭故障后,可以重新打开:
<Steps>
<Step title="发起重新打开">
@@ -176,7 +174,7 @@ Flashduty On-call 推送的语音告警,在语音播报结束时,会提醒
</Steps>
<Note>
-重新打开操作支持批量操作,你可以在故障列表中选中多个已关闭的故障一起重新打开。
+重新打开操作支持批量操作,您可以在故障列表中选中多个已关闭的故障一起重新打开。
</Note>
## 更多操作
@@ -209,7 +207,7 @@ Flashduty On-call 推送的语音告警,在语音播报结束时,会提醒
| 并入告警到故障 | 告警因为聚合策略合并到某故障中,但您可能想要调整故障和告警的关联关系。您可以进到告警详情下,点击 **并入** 按钮,将告警迁移至目标故障 |
<Note>
-合并的本质是:改变告警和故障的关联关系。加入一个故障的告警全部并入其他故障,此故障将直接关闭,您后续只需要处理目标故障。时间线完整将完整记录您的修改过程。
+合并改变的是告警和故障的关联关系。如果一个故障的告警全部并入其他故障,该故障会直接关闭,您只需处理目标故障。时间线会完整记录合并过程。
</Note>
## 常见问题
diff --git a/zh/on-call/incident/search-view-incident.mdx b/zh/on-call/incident/search-view-incident.mdx
index b0e70f78..dcaf8b07 100644
--- a/zh/on-call/incident/search-view-incident.mdx
+++ b/zh/on-call/incident/search-view-incident.mdx
@@ -6,7 +6,7 @@ keywords: ["故障检索", "故障列表", "聚合视图", "时间线", "故障
## 故障列表
-Flashduty On-call 提供了两个入口查看故障列表。一个是协作空间内,一个故障管理菜单下。区别在于,故障管理菜单下,可以看到多个协作空间,甚至是全公司的所有故障。
+故障列表有两个入口:协作空间内的列表只显示该协作空间的故障;**故障管理** 菜单下的列表可跨协作空间查看,最多覆盖全公司的故障。
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/988781efcb13781c33c986b6f19ef1f9.png" alt="故障列表界面" />
@@ -14,7 +14,7 @@ Flashduty On-call 提供了两个入口查看故障列表。一个是协作空
| 序号 | 功能 | 说明 |
| :---: | :--- | :--- |
-| 1 | 分派切换 | 筛选条行首的三态切换:**全部** / **分派给我**(处理人员是我的故障)/ **我的团队**(我所在协作空间内的故障)。该切换与「更多筛选」中的 **处理人员**、**协作空间** 互斥:手动选择这两个筛选任一有值时,切换自动归为「全部」(手动选择优先并保留);清空手动筛选后切换方可继续生效 |
+| 1 | 分派切换 | 筛选条行首的三态切换:**全部** / **分派给我**(处理人员是我)/ **我的团队**(我所在协作空间内)。在 **更多筛选** 中手动选择 **处理人员** 或 **协作空间** 时,切换自动归为 **全部**,以手动选择为准;清空这两个筛选后切换才重新生效 |
| 2 | 时间筛选 | 支持相对时间和自定义区间筛选 |
| 3 | 严重程度 | 按照严重程度筛选故障 |
| 4 | 处理进度 | 按照处理进度筛选故障,默认为 **全部** |
@@ -34,12 +34,12 @@ Flashduty On-call 提供了两个入口查看故障列表。一个是协作空
</Warning>
<Note>
-为了提升性能,当检索条件匹配到超过 **1000** 条故障,系统仅展示 1000+,而不是精确的数字。因此,您通过跳页,也只能查看 1000 条故障,如果需要查看更多,请调整你的检索时间区间。或通过 [故障查询 API](/zh/api-reference/on-call/incidents/incident-list) 获取全部数据。
+为了提升性能,当检索条件匹配到超过 **1000** 条故障,系统仅展示 1000+,而不是精确的数字。因此,您通过跳页,也只能查看 1000 条故障,如果需要查看更多,请调整您的检索时间区间。或通过 [故障查询 API](/zh/api-reference/on-call/incidents/incident-list) 获取全部数据。
</Note>
### 使用聚合视图
-聚合视图提供了一个不同的视角来查看故障,您可以定义不同的聚合维度。聚合维度的本质是实时 Group By,比如按照严重程度来聚合查看。
+聚合视图按您定义的维度对故障做实时 Group By,例如按严重程度分组查看。
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/c0b5d9a41a35c47f928da0d44e96f2aa.png" alt="聚合视图" />
@@ -58,14 +58,14 @@ Flashduty On-call 提供了两个入口查看故障列表。一个是协作空
### 使用更多筛选
-Flashduty On-call 提供各种维度的筛选能力,并给您足够多的灵活度。最典型的场景是:
+**更多筛选** 可以组合多个维度,常见用法:
- 根据 `check` 标签,检索由告警策略"主机宕机"触发的相关故障
- 根据误报字段,检索被标记为"误报"的相关故障
- 将 **未完成的行动项/跟进项** 设为 **有**,集中查看仍有未完成工作项、尚未收尾的故障
<Tip>
-灵活常常意味着低性能,在 Flashduty On-call 也不例外,尽管我们已经做了很多性能优化的工作。我们永远建议,缩小您的时间查询区间,尽量通过 **分派给我**、**处理进度** 等条件缩小查询范围。
+为保证查询速度,建议缩小时间范围,并尽量用 **分派给我**、**处理进度** 等条件缩小查询范围。
</Tip>
### 保存筛选视图
@@ -74,6 +74,7 @@ Flashduty On-call 提供各种维度的筛选能力,并给您足够多的灵
「保存筛选视图」功能当前暂时下线,筛选条上暂不提供保存、套用和管理筛选视图的入口,恢复时间以后续版本为准。
</Warning>
+<Accordion title="功能恢复后的用法">
您可以将筛选条上当前的筛选条件保存为命名的**筛选视图**,后续一键套用,适合高频使用的检索组合:
- **保存视图**:配置好筛选条件后,将其保存为命名视图;视图名称不可重复,每人最多保存 **10** 个
@@ -83,6 +84,7 @@ Flashduty On-call 提供各种维度的筛选能力,并给您足够多的灵
<Note>
筛选视图按用户保存,仅自己可见。视图保存除**时间范围**外的全部筛选条件,套用视图时时间范围保持当前选择不变。
</Note>
+</Accordion>
### 列表内容说明
@@ -123,7 +125,7 @@ Flashduty On-call 提供各种维度的筛选能力,并给您足够多的灵
## 故障详情
-故障详情是调查故障的主入口,这里展示了我们能拿到的所有信息。尤其是在故障概览页面,Flashduty On-call 集中展示了您最需要的信息。
+故障详情是调查故障的主入口,集中展示与故障相关的全部信息;默认打开的 **故障概览** 页签汇总了最常用的内容。
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/390e0ab50c4747c881e6ed03c86b9742.png" alt="故障详情界面" />
@@ -139,18 +141,49 @@ Flashduty On-call 提供各种维度的筛选能力,并给您足够多的灵
### 标签快捷跳转
-故障的标签信息展示在详情页的 **详细信息** 区域。当故障由监控集成(`monit.alert`)或 RUM 集成(`rum.alert`)的告警聚合而成时,部分标签值会自动渲染为深链,方便您直接跳转到产生该告警的规则或 Issue:
+故障标签显示在详情页的 **详细信息** 区域。由 Monitors 或 RUM 告警聚合而成的故障,部分标签旁会显示跳转链接:
-| 集成类型 | 标签 Key | 跳转行为 |
+| 告警来源 | 标签 | 链接 |
| :--- | :--- | :--- |
-| `rum.alert` | `issue_id` | 标签值旁渲染 **查看Issue** 链接,跳转到 RUM 错误追踪中对应的 Issue 详情页 |
-| `monit.alert` | `rule_id` | 标签值旁渲染 **查看规则** 链接,跳转到产生该告警的独立告警规则详情页 |
-| `monit.alert` | `__alert_rule_id` | 标签值旁渲染 **查看规则** 链接,跳转到产生该告警的独立告警规则详情页。新数据优先使用该标签,历史数据回退到 `rule_id` |
-| `monit.alert` | `__entity_alert_rule_id` | 标签值旁渲染 **查看规则** 链接,跳转到实体树中对应告警规则的编辑页 |
+| RUM | `issue_id` | **查看Issue**:打开对应的 RUM Issue |
+| Monitors 告警规则 | `__alert_rule_id`(历史数据为 `rule_id`) | **查看规则**:打开产生告警的告警规则 |
+| Monitors 实体树 | `__entity_alert_rule_id` | **查看规则**:打开实体树中对应的告警规则 |
+
+标签值无效或定位信息不完整时,只显示为普通文本。告警详情页的标签同样支持这些链接。
+
+如果标签携带告警当时的查询(如 PromQL 或日志表达式),标签右侧会显示 **去查询** 图标,点击会在新页签打开查询工作台,填好该查询,默认时间范围为触发前的时间窗口;有多条查询时可从列表中选择。
+
+### AI 总结
-实体树规则的跳转需要 `__entity_alert_account_id`、`__entity_alert_entity_definition_id`、`__entity_alert_data_source_id`、`__entity_alert_policy_scope_group_id` 等上下文标签共同定位;当任一必备定位标签缺失或非法时,标签值仅以纯文本展示。独立告警规则(`rule_id` / `__alert_rule_id`)同样要求标签值为正整数(如 `123`),值为空、`0` 或非数字时标签仅以纯文本展示,避免生成无效链接。该深链能力在告警详情页的标签区域同样生效。
+<Tip>
+**版本要求**:此功能需要 On-call 专业版及以上订阅。[了解更多](https://flashcat.cloud/flashduty/price/)
+</Tip>
-此外,当标签携带查询类信息(如告警触发时的 PromQL / 日志表达式)时,标签行右侧会渲染一个 **去查询** 图标。点击后会在新页签打开监控查询工作台,并自动填入告警当时的那条查询、以触发前的时间窗口为默认范围。单条查询直接跳转,多条查询(主查询 + 关联查询)弹出列表供选择。
+点击详细信息区域的 **AI 总结** 按钮,系统会基于故障关联的告警内容(最多 20 条)生成结构化摘要:
+
+- **概述**:一句话描述发生了什么
+- **影响**:受影响的关键资源,如服务、系统、环境、实例等
+- **建议**:即时可执行的排查和修复操作(最多 3 条)
+
+AI 总结固定使用 DeepSeek V4 Pro(`deepseek-v4-pro`)模型生成,控制台不提供模型选择入口。生成的摘要支持实时流式输出,可以重新生成,也可以保存为故障描述。
+
+<Tip>
+AI 总结仅适用于由告警自动触发的故障,手动创建的故障不支持此功能。
+</Tip>
+
+### 综合信息面板
+
+故障详情右侧的综合信息面板集中展示围绕该故障的辅助信息,自上而下依次为:
+
+| 区块 | 说明 |
+| :--- | :--- |
+| **属性** | 协作空间、故障触发时间、告警数量等基础属性 |
+| **图片** | 当故障关联的告警通过 API 上报了图片信息时展示。点击缩略图可预览,悬浮可查看图片的 Alt 描述和来源链接 |
+| **关键时间节点** | 以时间轴形式展示故障生命周期中的关键时间戳,包括 **触发时间**、**首次认领时间**、**关闭时间** 以及重新打开等节点,便于快速掌握故障进展 |
+| **处理人员** | 列出分派到该故障的所有处理人员(个人或值班人员)及其认领状态 |
+| **关联链接** | 所属协作空间预配置的快捷链接(如监控大盘、Runbook、知识库),支持基于当前故障的标签或字段动态渲染参数,便于一键跳转到相关系统。关联链接的模板在协作空间设置中维护 |
+| **自定义字段** | 展示并允许编辑该故障的自定义字段取值,未设置的字段以 `-` 显示 |
+| **外部工单** | 如果您配置了 Jira、ServiceNow 或 ServiceDesk Plus 等工单集成,此处展示由该故障联动生成的外部工单,可直接点击跳转查看详情 |
### 详情 Tab
@@ -166,30 +199,6 @@ Flashduty On-call 提供各种维度的筛选能力,并给您足够多的灵
| **故障复盘** | 内置复盘编辑器,无需离开详情即可完成复盘报告的创建、编辑、AI 生成与发布 | 按订阅版本开启,始终显示 |
| **历史故障** | 展示与当前故障相似的历史故障,便于借鉴以往的处置经验 | 始终显示 |
-### 行动项与跟进项事件
-
-[行动项与跟进项](/zh/on-call/incident/work-items)的每一次操作都会以带图标的记录写入时间线,与评论、认领等事件并列展示。支持的事件类型如下:
-
-| 事件类型 | 时间线记录 |
-| :--- | :--- |
-| `i_wi_created` | 创建了行动项 / 创建了跟进项 |
-| `i_wi_updated` | 更新了行动项 / 更新了跟进项 |
-| `i_wi_assignees` | 更新了行动项负责人 / 更新了跟进项负责人 |
-| `i_wi_completed` | 完成了行动项 / 完成了跟进项 |
-| `i_wi_converted` | 将行动项转换为跟进项 |
-| `i_wi_bound` | 将跟进项关联到故障复盘 |
-| `i_wi_auto_converted` | 将 N 个未完成行动项转为跟进项:标题、标题…(故障关闭时批量转换,一条记录汇总全部条目) |
-| `i_wi_deleted` | 删除了行动项 / 删除了跟进项 |
-
-### AI SRE 代操作记录
-
-AI SRE 代某位成员执行的动作(例如[自动化规则](/zh/ai-sre/automations)跑完一轮排查后把结论写回故障)会以 **联合署名** 记入时间线:署名文案为 `{{name}} 和 AI SRE`,两个名字并列同权,因为 AI SRE 使用的是该成员的身份和权限。这类记录在后端以 `via: ai_sre` 标记。
-
-- **署名悬浮卡**:把鼠标移到署名中的 **AI SRE** 上会弹出悬浮卡,写明「以 `{{name}}` 的身份和权限执行」,并提供 **接续对话** 按钮,点击后在 AI SRE 面板中打开当时那次会话
-- **常显入口**:每条 AI 代操作记录右侧还常驻一个带 ↗ 图标的 **接续对话** 入口,无需悬停即可直接进入对应会话;一个故障可能包含多场 AI 会话,因此入口挂在每一条记录上,而不是故障级的总入口
-
-两类入口都需要账户启用 AI SRE 且当前成员拥有 `AiSreChatVisit` 权限。会话为个人会话(仅创建者可见)或已失效时,常显入口不渲染,悬浮卡则改为显示「该会话仅创建者可见或已失效」;这条记录没有关联会话时,悬浮卡显示「该操作没有关联到会话」。
-
### 时间线评论
时间线 Tab 顶部提供了一个 Markdown 评论框,支持以下能力:
@@ -205,7 +214,7 @@ AI SRE 代某位成员执行的动作(例如[自动化规则](/zh/ai-sre/autom
</Note>
<Tip>
-评论需要您对该故障有更新权限。在时间线 Tab 中,评论输入框对所有成员常驻可见,但仅拥有故障更新权限的成员可以看到 **发送** 按钮;在故障概览页的「最近时间线」区域,**发表评论** 按钮及其唤起的评论输入框也仅对拥有更新权限的成员可见。
+发表评论需要该故障的更新权限,没有权限的成员看不到发送入口。
</Tip>
### 评论类型
@@ -234,45 +243,32 @@ AI SRE 代某位成员执行的动作(例如[自动化规则](/zh/ai-sre/autom
- 重命名、更换颜色、删除与排序等管理操作请在控制台完成
</Note>
-### 作战室运营
+### 行动项与跟进项事件
-如果故障已创建作战室(需在 IM 集成中开启[作战室](/zh/on-call/advanced/war-room)),操作栏的 **更多** 菜单会额外出现两项作战室管理操作:
+[行动项与跟进项](/zh/on-call/incident/work-items)的每一次操作都会以带图标的记录写入时间线,与评论、认领等事件并列展示:创建、更新、更换负责人、完成、删除,行动项转为跟进项,跟进项关联到复盘。故障关闭时自动转换的未完成行动项会汇总为一条记录。
-| 操作 | 说明 |
+<Accordion title="事件类型对照">
+| 事件类型 | 时间线记录 |
| :--- | :--- |
-| **添加关注人员进入作战室** | 将更多成员拉入已经创建的 IM 作战群组,便于多方协同处置 |
-| **解散作战室** | 结束当前作战,关闭 IM 作战群组。解散后若后续需要再次协作,可重新创建作战室 |
-
-<Note>
-作战室相关操作仅当当前故障已存在作战室时可见;创建动作仍由操作栏的 **创建作战室** 按钮发起。
-</Note>
-
-若作战室所用的 IM 集成事后被禁用或删除,**添加关注人员进入作战室** 与 **解散作战室** 两项会一并隐藏(此时无法再操作原群聊)。**查看作战室** 弹窗会提示「原集成已禁用或删除。管理员可解除关联,原群聊不会解散;如需重新建群,请先确认原群已妥善处理。」,并为账号所有者/账号管理员(且具备故障更新权限)提供 **确认解除关联** 按钮:该操作只解除故障与原群聊的关联,**不会解散群聊**,时间线记录为「发起解除作战室关联」。
-
-在 Flashduty App(移动端)中,作战室行为与控制台保持一致:故障详情概览页提供 **作战室** 入口卡片(支持深链的 IM 集成直接拉起群聊,否则弹窗展示群聊名称供搜索进入);**创建作战室** 位于底部 **更多操作** 中,故障已存在作战室或故障已关闭时隐藏,无处理人员时禁用并提示;**添加关注人员进入作战室** 与 **解散作战室** 在故障关闭后仍可用,但依赖作战室所在 IM 集成可用——集成被禁用或删除后,这两项从 **更多操作** 中消失,概览页入口卡片仍保留,点击后提示「原集成已禁用或删除。请管理员在 PC 端故障详情页解除关联,原群聊不会解散。」。
-
-### 故障复盘
-
-故障详情页内置了完整的复盘编辑器,您无需离开当前页面即可完成整个复盘流程。操作区域的快捷按钮可以直接跳转到 **故障复盘** 页签。
+| `i_wi_created` | 创建了行动项 / 创建了跟进项 |
+| `i_wi_updated` | 更新了行动项 / 更新了跟进项 |
+| `i_wi_assignees` | 更新了行动项负责人 / 更新了跟进项负责人 |
+| `i_wi_completed` | 完成了行动项 / 完成了跟进项 |
+| `i_wi_converted` | 将行动项转换为跟进项 |
+| `i_wi_bound` | 将跟进项关联到故障复盘 |
+| `i_wi_auto_converted` | 将 N 个未完成行动项转为跟进项:标题、标题…(故障关闭时批量转换,一条记录汇总全部条目) |
+| `i_wi_deleted` | 删除了行动项 / 删除了跟进项 |
+</Accordion>
-在故障复盘页签中,您可以进行以下操作:
+### AI SRE 代操作记录
-| 操作 | 说明 |
-| :--- | :--- |
-| **创建复盘** | 点击创建按钮,开始编写复盘报告 |
-| **AI 生成** | 借助 AI 自动生成复盘报告的初始内容,您可以在此基础上进行修改 |
-| **编辑标题** | 修改复盘报告的标题,使其准确反映故障本质 |
-| **编辑内容** | 使用富文本编辑器编写和修改复盘内容 |
-| **发布** | 完成编辑后发布复盘报告,使其对团队可见 |
-| **重新编辑** | 已发布的复盘报告支持重新进入编辑状态进行修改 |
-| **删除** | 删除不再需要的复盘报告 |
-| **导出 Markdown** | 将复盘报告导出为 Markdown 格式,便于在其他平台分享或归档 |
+AI SRE 代某位成员执行的动作(例如[自动化规则](/zh/ai-sre/automations)跑完一轮排查后把结论写回故障)会以 **`{{name}} 和 AI SRE`** 联合署名记入时间线,因为 AI SRE 使用的是该成员的身份和权限。
-详见[故障复盘](/zh/on-call/post-mortem/create-edit-post-mortem)。
+每条这样的记录右侧都有 **接续对话** 入口,点击会在 AI SRE 面板中打开当时的会话(一个故障可能有多场会话)。需要账户已启用 AI SRE,且您有使用 AI SRE 对话的权限;个人会话(仅创建者可见)或已失效的会话无法接续。
### 历史变更
-历史变更 Tab 展示与当前故障在时间上相关联的变更事件,帮助你快速定位故障根因是否与近期的部署或配置变更有关。
+历史变更 Tab 展示与当前故障在时间上相关联的变更事件,帮助您快速定位故障根因是否与近期的部署或配置变更有关。
变更事件列表展示以下信息:
@@ -287,39 +283,30 @@ AI SRE 代某位成员执行的动作(例如[自动化规则](/zh/ai-sre/autom
| **时长** | 变更事件的持续时长,进行中的事件将实时更新 |
| **链接** | 跳转到变更事件原始来源的外部链接 |
-你可以通过顶部的筛选条件调整变更事件的查询范围,包括时间范围和变更来源。展开任意一行,可查看该变更事件的时间线可视化,与故障触发时间进行对比分析。
+您可以通过顶部的筛选条件调整变更事件的查询范围,包括时间范围和变更来源。展开任意一行,可查看该变更事件的时间线可视化,与故障触发时间进行对比分析。
-### AI 总结
+### 故障复盘
-故障详情页支持一键生成 AI 总结,帮助您快速理解故障全貌。点击详细信息区域的 **AI 总结** 按钮,系统将基于故障关联的告警内容(最多 20 条),自动生成结构化摘要,包括:
+故障详情页内置复盘编辑器,操作区域的快捷按钮可直接跳到 **故障复盘** 页签。在页签中可以创建复盘、用 AI 生成初稿、编辑标题和正文(富文本)、发布、发布后重新编辑、删除,以及导出为 Markdown。
-<Tip>
-**版本要求**:此功能需要 On-call 专业版及以上订阅。[了解更多](https://flashcat.cloud/flashduty/price/)
-</Tip>
+详见[故障复盘](/zh/on-call/post-mortem/create-edit-post-mortem)。
-- **概述**:一句话描述发生了什么
-- **影响**:受影响的关键资源,如服务、系统、环境、实例等
-- **建议**:即时可执行的排查和修复操作(最多 3 条)
+### 作战室运营
-AI 总结固定使用 DeepSeek V4 Pro(`deepseek-v4-pro`)模型生成,控制台不提供模型选择入口。生成的摘要支持实时流式输出,可以重新生成,也可以保存为故障描述。
+如果故障已创建作战室(需在 IM 集成中开启[作战室](/zh/on-call/advanced/war-room)),操作栏的 **更多** 菜单会额外出现两项作战室管理操作:
-<Tip>
-AI 总结仅适用于由告警自动触发的故障,手动创建的故障不支持此功能。
-</Tip>
+| 操作 | 说明 |
+| :--- | :--- |
+| **添加关注人员进入作战室** | 将更多成员拉入已经创建的 IM 作战群组,便于多方协同处置 |
+| **解散作战室** | 结束当前作战,关闭 IM 作战群组。解散后若后续需要再次协作,可重新创建作战室 |
-### 综合信息面板
+<Note>
+作战室相关操作仅当当前故障已存在作战室时可见;创建动作仍由操作栏的 **创建作战室** 按钮发起。
+</Note>
-故障详情右侧的综合信息面板集中展示围绕该故障的辅助信息,自上而下依次为:
+如果作战室所用的 IM 集成被禁用或删除,**添加关注人员进入作战室** 与 **解散作战室** 将不再显示。账号所有者或管理员(需有故障更新权限)可以在 **查看作战室** 中 **确认解除关联**:只解除故障与原群聊的关联,**不会解散群聊**,并记入时间线。
-| 区块 | 说明 |
-| :--- | :--- |
-| **属性** | 协作空间、故障触发时间、告警数量等基础属性 |
-| **图片** | 当故障关联的告警通过 API 上报了图片信息时展示。点击缩略图可预览,悬浮可查看图片的 Alt 描述和来源链接 |
-| **关键时间节点** | 以时间轴形式展示故障生命周期中的关键时间戳,包括 **触发时间**、**首次认领时间**、**关闭时间** 以及重新打开等节点,便于快速掌握故障进展 |
-| **处理人员** | 列出分派到该故障的所有处理人员(个人或值班人员)及其认领状态 |
-| **关联链接** | 所属协作空间预配置的快捷链接(如监控大盘、Runbook、知识库),支持基于当前故障的标签或字段动态渲染参数,便于一键跳转到相关系统。关联链接的模板在协作空间设置中维护 |
-| **自定义字段** | 展示并允许编辑该故障的自定义字段取值,未设置的字段以 `-` 显示 |
-| **外部工单** | 如果您配置了 Jira、ServiceNow 或 ServiceDesk Plus 等工单集成,此处展示由该故障联动生成的外部工单,可直接点击跳转查看详情 |
+Flashduty App(移动端)中的作战室操作与控制台一致,详见[作战室 · 移动端 App](/zh/on-call/advanced/war-room#移动端-app)。
## 常见问题
diff --git a/zh/on-call/incident/what-is-incident.mdx b/zh/on-call/incident/what-is-incident.mdx
index 4dae813b..bc617412 100644
--- a/zh/on-call/incident/what-is-incident.mdx
+++ b/zh/on-call/incident/what-is-incident.mdx
@@ -158,7 +158,7 @@ Flashduty On-call 提供了一个邮件集成,允许您通过发送邮件来
### 通过控制台触发故障
-你可以在故障列表页面点击 **创建** 按钮手动创建故障。按照以下步骤操作:
+您可以在故障列表页面点击 **创建** 按钮手动创建故障。按照以下步骤操作:
<Steps>
<Step title="填写故障标题">
@@ -168,7 +168,7 @@ Flashduty On-call 提供了一个邮件集成,允许您通过发送邮件来
选择 Critical(严重)、Warning(警告)或 Info(提醒)三个级别之一。
</Step>
<Step title="选择协作空间">
-选择故障归属的协作空间。如果你在协作空间内创建故障,该字段已自动填充且不可更改。
+选择故障归属的协作空间。如果您在协作空间内创建故障,该字段已自动填充且不可更改。
</Step>
<Step title="选择分派方式">
选中协作空间后,系统会展示分派方式选项:
diff --git a/zh/on-call/incident/work-items.mdx b/zh/on-call/incident/work-items.mdx
index c0cc6198..25ec7266 100644
--- a/zh/on-call/incident/work-items.mdx
+++ b/zh/on-call/incident/work-items.mdx
@@ -60,7 +60,7 @@ keywords: ["行动项", "跟进项", "工作项", "故障处理", "故障复盘"
## 转为跟进项与关联复盘
-跟进项属于已结束的故障。系统会在故障关闭时自动完成转换,你也可以在故障关闭后继续补充:
+跟进项属于已结束的故障。系统会在故障关闭时自动完成转换,您也可以在故障关闭后继续补充:
- **关闭时自动转换**:关闭故障时,系统会把该故障下所有未完成的行动项批量转为跟进项(工作项类型从 Action 变为 Follow-up),并在时间线上写入一条 **将 N 个未完成行动项转为跟进项:标题、标题…** 事件(`i_wi_auto_converted`)。已完成或已标记为不处理的行动项保持原状,仍以行动项展示(只读)
- **自动关联复盘**:转换或创建跟进项时,若故障已有复盘报告,系统会自动把跟进项关联到该复盘;若尚无复盘,跟进项先保持未关联,待该故障的复盘报告创建后,系统会自动把故障下所有未关联的跟进项绑定到该复盘
@@ -85,8 +85,8 @@ keywords: ["行动项", "跟进项", "工作项", "故障处理", "故障复盘"
故障关闭后,行动项卡片进入只读状态,跟进项卡片同时解锁为可编辑:
-- **行动项**:不能创建、编辑、删除行动项,也不能变更状态(界面隐藏添加按钮与操作入口,后端同时拒绝为已关闭故障创建行动项)。关闭那一刻,系统已把未完成的行动项自动转为跟进项,因此卡片中通常只剩下已完成或标记为不处理的行动项
-- **跟进项**:可直接在故障下新增、编辑、完成或删除跟进项,不要求先创建复盘报告;若故障已有复盘报告,服务端会自动为新建的跟进项回填复盘关联
+- **行动项**:不能创建、编辑、删除行动项,也不能变更状态(界面隐藏添加按钮与操作入口,通过 API 也无法为已关闭故障创建行动项)。关闭那一刻,系统已把未完成的行动项自动转为跟进项,因此卡片中通常只剩下已完成或标记为不处理的行动项
+- **跟进项**:可直接在故障下新增、编辑、完成或删除跟进项,不要求先创建复盘报告;若故障已有复盘报告,系统会自动为新建的跟进项回填复盘关联
- 关闭故障前无需专门处理未完成的行动项;若希望某项工作保留为行动项,请在关闭前将其标记为 **已完成** 或 **不处理**,否则它会在关闭时被转为跟进项
## 延伸阅读
diff --git a/zh/on-call/integration/alert-integration/alert-pipelines.mdx b/zh/on-call/integration/alert-integration/alert-pipelines.mdx
index c8436eba..ea0c6616 100644
--- a/zh/on-call/integration/alert-integration/alert-pipelines.mdx
+++ b/zh/on-call/integration/alert-integration/alert-pipelines.mdx
@@ -51,7 +51,7 @@ Pipeline 位于 **标签增强** 和 **路由分发** 之间。它的执行逻
## 配置入口
-进入 **集成中心** => 选择已创建的集成 => **告警处理** 页签。
+进入 **集成中心** → 选择已创建的集成 → **告警处理** 页签。
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/e581fe9fc4ba1a505f0c47c7864c55ac.png" alt="告警处理配置入口" />
@@ -129,9 +129,9 @@ Pipeline 中的抑制功能与协作空间的抑制规则类似,都支持基
## 参考历史数据
-在编辑告警处理规则时,页面右侧提供 **关联告警** 面板,展示通过当前集成接入的历史告警数据。你可以一边编写处理规则,一边参考实际告警内容,确保规则的条件表达式和动作配置符合预期。
+在编辑告警处理规则时,页面右侧提供 **关联告警** 面板,展示通过当前集成接入的历史告警数据。您可以一边编写处理规则,一边参考实际告警内容,确保规则的条件表达式和动作配置符合预期。
-点击编辑页面右上角的 **参考历史数据** 按钮,即可打开或关闭右侧的关联告警面板。面板支持拖拽调整宽度,方便你在编辑区域和数据预览之间灵活切换。
+点击编辑页面右上角的 **参考历史数据** 按钮,即可打开或关闭右侧的关联告警面板。面板支持拖拽调整宽度,方便您在编辑区域和数据预览之间灵活切换。
<Tip>
在首次配置 Pipeline 时,建议打开关联告警面板,参考真实的告警标签和字段值来编写匹配条件,避免因字段名称不一致导致规则无法命中。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/aikido.mdx b/zh/on-call/integration/alert-integration/alert-sources/aikido.mdx
index 8f2905f0..7cb3f985 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/aikido.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/aikido.mdx
@@ -1,5 +1,6 @@
---
title: "Aikido Security 告警集成"
+sidebarTitle: "Aikido Security"
description: "通过 Webhook 将 Aikido 的安全问题(issue)创建、严重度变化和关闭事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Aikido", "Aikido Security", "Webhook", "安全漏洞", "issue_id"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Aikido", "Aikido Security", "Webhook", "安全漏洞
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Aikido", "Aikido Security", "Webhook", "安全漏洞
</div>
## 在 Aikido 中配置
----
<Steps>
<Step title="创建 Webhook">
@@ -65,12 +64,10 @@ Webhook 需要由 Aikido 工作区管理员在 [Settings → Integrations → We
</Steps>
## Alert Key
----
Flashduty 使用 `payload.issue_id` 作为 Alert Key。Aikido 官方文档将其定义为 issue 的 ID,同一个 issue 的所有事件都带有这个 ID。严重度、状态和事件类型的变化不会改变 Alert Key。缺少 `payload.issue_id` 的 issue 事件会被拒绝,因为无法关联后续更新和恢复。
## 状态和告警等级
----
| Aikido `event_type` | Flashduty 处理 |
| :--- | :--- |
@@ -94,7 +91,6 @@ Flashduty 使用 `payload.issue_id` 作为 Alert Key。Aikido 官方文档将其
Aikido 负载中没有标题字段,告警标题形如 `Aikido open_source issue #123 (critical)`。issue 类型(`open_source`、`leaked_secret`、`cloud`、`iac`、`sast`、`surface_monitoring`、`malware`)、`severity_score`、`workspace_id` 等写入告警标签。
## 排查问题
----
- **Aikido 返回非 200 并重试**:Aikido 对非 200 响应或超时会重试 5 次;请确认推送地址完整且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求体是有效 JSON,且 issue 事件带有 `payload.issue_id`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/airbrake.mdx b/zh/on-call/integration/alert-integration/alert-sources/airbrake.mdx
index dfb13044..b27e6914 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/airbrake.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/airbrake.mdx
@@ -1,5 +1,6 @@
---
title: "Airbrake 告警集成"
+sidebarTitle: "Airbrake"
description: "通过 Webhook 将 Airbrake 项目的错误通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Airbrake", "Webhook", "错误监控", "异常监控"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Airbrake", "Webhook", "错误监控", "异常监控"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Airbrake", "Webhook", "错误监控", "异常监控"
</div>
## 在 Airbrake 中配置
----
<Steps>
<Step title="添加 Webhook 集成">
@@ -60,17 +59,14 @@ Airbrake 文档没有说明测试通知的内容,Flashduty 不对测试推送
</Steps>
## Alert Key
----
Flashduty 用 Webhook 内容中的 `error.id`(Airbrake 错误 ID)计算 Alert Key。同一个错误的多次推送使用同一个 Alert Key,错误消息、发生次数、环境、最近一次事件等字段变化不会改变它。缺少 `error.id` 的推送会被拒绝。
## 告警等级
----
Airbrake Webhook 不携带等级,所有推送均为 Warning,状态为触发。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -84,7 +80,6 @@ Airbrake Webhook 不携带等级,所有推送均为 Warning,状态为触发
| `url` | Airbrake 中该错误页面的链接(`airbrake_error_url`) |
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`
- **告警没有恢复**:Airbrake 不推送恢复通知,请开启协作空间的超时自动关闭,或手动关闭告警
diff --git a/zh/on-call/integration/alert-integration/alert-sources/alertsite.mdx b/zh/on-call/integration/alert-integration/alert-sources/alertsite.mdx
index 899ba38f..d3154785 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/alertsite.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/alertsite.mdx
@@ -1,5 +1,6 @@
---
title: "SmartBear AlertSite 告警集成"
+sidebarTitle: "SmartBear AlertSite"
description: "通过 JSON 告警将 SmartBear AlertSite 监控的可用性告警和性能告警同步到 Flashduty On-call。"
keywords: ["告警集成", "AlertSite", "SmartBear", "拨测", "Synthetic", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "AlertSite", "SmartBear", "拨测", "Synthetic", "Web
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "AlertSite", "SmartBear", "拨测", "Synthetic", "Web
</div>
## 在 AlertSite 中配置
----
<Steps>
<Step title="创建 JSON 告警接收人">
@@ -68,14 +67,12 @@ keywords: ["告警集成", "AlertSite", "SmartBear", "拨测", "Synthetic", "Web
</Warning>
## Alert Key
----
Flashduty 用告警类型(可用性或性能)加 `device_id` 计算 Alert Key。AlertSite 文档说明监控名称可能被修改,应以 `device_id` 作为标识;同一监控的出错和恢复告警携带相同的 `device_id`,因此会落在同一条告警上。
可用性告警(`error` / `clear`)和性能告警(`perf_warning` / `perf_error` / `perf_clear`)分开计算:性能恢复不会关闭仍在出错的可用性告警。监控名称、出错节点、出错步骤、状态码、时间和响应时间的变化都不会改变 Alert Key。请求缺少 `device_id` 时 Flashduty 会拒绝,因为无法关联后续恢复。
## 状态和告警等级
----
| AlertSite `notify_type` | Flashduty 状态 | Flashduty 等级 |
| :--- | :--- | :--- |
@@ -89,14 +86,12 @@ Flashduty 用告警类型(可用性或性能)加 `device_id` 计算 Alert Ke
空值或其他 `notify_type` 会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 告警内容
----
- **标题**:监控名称 `device_name`
- **描述**:状态说明、出错节点、URL、HTTP 状态、出错步骤、检测时间;轮换节点(`rotated_locations`)各节点的状态;性能告警中各节点的响应时间和阈值(`locations`)
- **标签**:`device_id`、`device_type`、`custid`、`notify_type`、`alert_type`(`availability` 或 `performance`)、`status_code`(AlertSite 状态码,`0` 表示正常)、`status_text`、`location`、`location_num`、`http_status`、`check`(监控名称)、`resource`(被监控的 URL)、`source`(固定为 `alertsite`)
## 排查问题
----
- **AlertSite 投递失败**:确认 **Recipient** 填写的是完整推送地址,包含 `https://` 和 `integration_key`
- **Flashduty 返回参数错误**:确认使用默认模板,请求中有 `notify_type` 和 `device_id`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/aliyun-arms.mdx b/zh/on-call/integration/alert-integration/alert-sources/aliyun-arms.mdx
index ce50a8d9..515e40ee 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/aliyun-arms.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/aliyun-arms.mdx
@@ -1,5 +1,6 @@
---
title: "阿里云 ARMS 集成"
+sidebarTitle: "阿里云 ARMS"
description: "通过 webhook 的方式同步阿里云 ARMS 监控告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "阿里云 ARMS 集成", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "阿里云 ARMS 集成", "监控告警", "数据接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "阿里云 ARMS 集成", "监控告警", "数据接
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "阿里云 ARMS 集成", "监控告警", "数据接
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **阿里云 ARMS** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,23 +45,22 @@ keywords: ["告警集成", "阿里云 ARMS 集成", "监控告警", "数据接
</div>
-## 在 阿里云 ARMS
----
-**步骤 1:配置 通知对象**
+## 在阿里云 ARMS
+**步骤 1:配置通知对象**
<div className="md-block">
1. 登录您的阿里云控制台,选择ARMS监控产品;
-2. 进入 `告警管理 -> 通知对象` 页面,选择 `Webhook集成`,单击 新建Webhook 按钮,开始编辑内容;
+2. 进入 `告警管理 -> 通知对象` 页面,选择 `Webhook集成`,单击 **新建Webhook** 按钮,开始编辑内容;
3. 如图,设定对象名称,并选择 `Post` ,复制写入集成的推送地址;
4. 添加 `Header`,输入 `Content-Type` 和 `application/json`;
5. 通知模板内输入:`$alertmanager_content`;
-6. 点击 确定 按钮,提交保存。
+6. 点击 **确定** 按钮,提交保存。
<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-arms/notify_target.png" />
-**步骤 2:配置 通知策略**
+**步骤 2:配置通知策略**
1. 进入 `告警管理 -> 通知策略` 页面,单击 新建通知策略 或 选择已有的策略进行编辑;
2. 如下图所示,在 `通知对象` 页面,选择已创建好的 `通用Webhook` 对象;
@@ -72,7 +71,6 @@ keywords: ["告警集成", "阿里云 ARMS 集成", "监控告警", "数据接
</div>
## 状态对照
----
<div className="md-block">
阿里云 ARMS 监控到 Flashduty 告警等级映射关系:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-event.mdx b/zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-event.mdx
index 22c4e2f5..13b77f28 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-event.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-event.mdx
@@ -1,5 +1,6 @@
---
title: "阿里云监控 CM 事件集成"
+sidebarTitle: "阿里云监控 CM 事件"
description: "通过 webhook 的方式同步阿里云云监控事件中心告警到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "阿里云监控 CM 事件集成", "监控告警", "数据接入"]
---
@@ -8,7 +9,6 @@ keywords: ["告警集成", "阿里云监控 CM 事件集成", "监控告警", "
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -16,7 +16,7 @@ keywords: ["告警集成", "阿里云监控 CM 事件集成", "监控告警", "
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -32,9 +32,9 @@ keywords: ["告警集成", "阿里云监控 CM 事件集成", "监控告警", "
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **阿里云 CM 事件** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,15 +46,14 @@ keywords: ["告警集成", "阿里云监控 CM 事件集成", "监控告警", "
</div>
## 在阿里云监控 CM 事件
----
**步骤 1:添加推送渠道**
<div className="md-block">
1. 登录您的阿里云控制台,选择云监控产品
-2. 进入 **事件中心 -> 事件订阅** 页面,切换到 **推送渠道** 标签页,单击 创建推送渠道 按钮,开始编辑内容
+2. 进入 **事件中心 → 事件订阅** 页面,切换到 **推送渠道** 标签页,单击 **创建推送渠道** 按钮,开始编辑内容
3. 如图,**请求方法** 选择 **POST**,**地址** 填写集成的推送地址
-4. 点击 确认 按钮,提交更新
+4. 点击 **确认** 按钮,提交更新
<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-cm-event/aliyun-cm-event-channel.png" />
@@ -65,9 +64,9 @@ keywords: ["告警集成", "阿里云监控 CM 事件集成", "监控告警", "
<div className="md-block">
1. 登录您的阿里云控制台,选择云监控产品
-2. 进入 **事件中心 -> 事件订阅** 页面,切换到 **订阅策略** 标签页,单击 创建订阅策略 按钮,开始编辑内容
+2. 进入 **事件中心 → 事件订阅** 页面,切换到 **订阅策略** 标签页,单击 **创建订阅策略** 按钮,开始编辑内容
3. 填写订阅名称,选择事件类型以及范围,最下方配置推送渠道为为前边创建的 Flashduty 渠道
-4. 点击 确认 按钮,提交更新
+4. 点击 **确认** 按钮,提交更新
5. 下图为阈值和系统两种类型事件的订阅结果
<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-cm-event/aliyun-cm-event-subscribe.png" />
@@ -75,7 +74,6 @@ keywords: ["告警集成", "阿里云监控 CM 事件集成", "监控告警", "
</div>
## 状态对照
----
<div className="md-block">
阿里云云监控事件告警到 Flashduty 告警等级映射关系:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics.mdx b/zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics.mdx
index 43064e47..5a45f80c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics.mdx
@@ -1,5 +1,6 @@
---
title: "阿里云监控 CM 指标集成"
+sidebarTitle: "阿里云监控 CM 指标"
description: "通过 webhook 的方式同步阿里云云监控告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "阿里云监控 CM 指标集成", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "阿里云监控 CM 指标集成", "监控告警", "
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "阿里云监控 CM 指标集成", "监控告警", "
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "阿里云监控 CM 指标集成", "监控告警", "
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **阿里云 CM 指标** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,7 +46,6 @@ keywords: ["告警集成", "阿里云监控 CM 指标集成", "监控告警", "
</div>
## 在阿里云监控
----
以下两种方式任选其一。
**方式 1:按规则配置**
@@ -54,11 +53,11 @@ keywords: ["告警集成", "阿里云监控 CM 指标集成", "监控告警", "
<div className="md-block">
1. 登录您的阿里云控制台,选择云监控产品
-2. 进入 报警服务 -> 报警规则 页面,选择一个规则,单击 修改 按钮,开始编辑规则内容
+2. 进入 **报警服务 → 报警规则** 页面,选择一个规则,单击 **修改** 按钮,开始编辑规则内容
3. 如图,在 高级设置 下填写回调地址为集成的推送地址
-4. 点击 确认 按钮,提交更新
+4. 点击 **确认** 按钮,提交更新
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-cm/aliyun-cm-rule.jpg" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-cm/aliyun-cm-rule.jpg" />
5. 对于所有期望同步事件的告警规则,重复上述步骤
6. 回到集成列表,如果展示了最新事件时间,说明配置成功且收到事件
@@ -71,11 +70,11 @@ keywords: ["告警集成", "阿里云监控 CM 指标集成", "监控告警", "
<div className="md-block">
1. 登录您的阿里云控制台,选择云监控产品
-2. 进入 报警服务 -> 报警联系人 页面,选择修改某一个联系人
+2. 进入 **报警服务 → 报警联系人** 页面,选择修改某一个联系人
3. 如图,在 Webhook 下填写集成的推送地址
-4. 点击 确认 按钮,提交更新
+4. 点击 **确认** 按钮,提交更新
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-cm/aliyun-cm-contact.jpg" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-cm/aliyun-cm-contact.jpg" />
5. 对于所有期望同步事件的联系人,重复上述步骤
6. 回到集成列表,如果展示了最新事件时间,说明配置成功且收到事件
@@ -84,7 +83,6 @@ keywords: ["告警集成", "阿里云监控 CM 指标集成", "监控告警", "
</div>
## 状态对照
----
<div className="md-block">
阿里云云监控到 Flashduty 告警等级映射关系:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op.mdx b/zh/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op.mdx
index 09c4d31c..4d328bba 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op.mdx
@@ -1,5 +1,6 @@
---
title: "DataWorks 运维中心集成"
+sidebarTitle: "DataWorks 运维中心"
description: "通过自定义 Webhook 的方式同步阿里云 DataWorks 智能监控(运维中心)告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "阿里云 DataWorks 集成", "DataWorks 智能监控", "运维中心", "监控告警", "数据接入"]
---
@@ -8,7 +9,6 @@ keywords: ["告警集成", "阿里云 DataWorks 集成", "DataWorks 智能监控
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -16,7 +16,7 @@ keywords: ["告警集成", "阿里云 DataWorks 集成", "DataWorks 智能监控
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -32,9 +32,9 @@ keywords: ["告警集成", "阿里云 DataWorks 集成", "DataWorks 智能监控
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **DataWorks 运维中心** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,7 +46,6 @@ keywords: ["告警集成", "阿里云 DataWorks 集成", "DataWorks 智能监控
</div>
## 在阿里云 DataWorks
----
**步骤 1:创建自定义 Webhook**
<div className="md-block">
@@ -70,7 +69,6 @@ keywords: ["告警集成", "阿里云 DataWorks 集成", "DataWorks 智能监控
</div>
## 支持的告警类型
----
<div className="md-block">
DataWorks 智能监控自定义 Webhook 推送的消息统一包裹在 `message` 字段中,通过 `message.title` 区分类型,本集成支持以下三类告警:
@@ -86,7 +84,6 @@ DataWorks 智能监控自定义 Webhook 推送的消息统一包裹在 `message`
</div>
## 严重程度对照
----
<div className="md-block">
DataWorks 自定义告警 `remind_type` 到 Flashduty 告警等级(Severity)映射关系:
@@ -122,7 +119,6 @@ DataWorks 自定义告警 `remind_type` 到 Flashduty 告警等级(Severity)
</div>
## Alert Key 与告警合并
----
<div className="md-block">
DataWorks 智能监控 Webhook 属于**一次性事件**(one-shot):官方协议只定义告警通知,**不恢复**、无更新语义,也没有提供厂商级别的去重 ID 或指纹字段。因此本集成不会自动恢复(关闭)任何告警,所有事件均以触发状态投递。
@@ -132,7 +128,6 @@ DataWorks 智能监控 Webhook 属于**一次性事件**(one-shot):官方
</div>
## 字段标签对照
----
<div className="md-block">
推送消息中的主要字段会以标签(Labels)形式保留在告警事件中,可用于路由、静默与模板渲染:
@@ -156,7 +151,6 @@ DataWorks 智能监控 Webhook 属于**一次性事件**(one-shot):官方
</div>
## 常见问题
----
<div className="md-block">
**为什么告警不会自动恢复?**
diff --git a/zh/on-call/integration/alert-integration/alert-sources/aliyun-prometheus.mdx b/zh/on-call/integration/alert-integration/alert-sources/aliyun-prometheus.mdx
index 70b6ac14..96e9754b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/aliyun-prometheus.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/aliyun-prometheus.mdx
@@ -1,5 +1,6 @@
---
title: "阿里云 Prometheus 监控集成"
+sidebarTitle: "阿里云 Prometheus 监控"
description: "通过 webhook 的方式同步阿里云 Prometheus 监控告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "阿里云 Prometheus 集成", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "阿里云 Prometheus 集成", "监控告警", "数
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "阿里云 Prometheus 集成", "监控告警", "数
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "阿里云 Prometheus 集成", "监控告警", "数
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **阿里云监控 Prometheus** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,7 +45,6 @@ keywords: ["告警集成", "阿里云 Prometheus 集成", "监控告警", "数
</div>
## 在阿里云
----
<Steps>
<Step title="创建自定义 Webhook">
@@ -76,7 +75,6 @@ keywords: ["告警集成", "阿里云 Prometheus 集成", "监控告警", "数
</Steps>
## 状态对照
----
<div className="md-block">
阿里云 Prometheus 监控到 Flashduty 告警等级映射关系:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/aliyun-sls.mdx b/zh/on-call/integration/alert-integration/alert-sources/aliyun-sls.mdx
index 8856a2f4..31650fc1 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/aliyun-sls.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/aliyun-sls.mdx
@@ -1,5 +1,6 @@
---
-title: "阿里云 SLS集成"
+title: "阿里云 SLS 集成"
+sidebarTitle: "阿里云 SLS"
description: "通过 webhook 的方式同步阿里云日志服务 SLS 监控告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "阿里云 SLS集成", "监控告警", "数据接入"]
---
@@ -8,7 +9,6 @@ keywords: ["告警集成", "阿里云 SLS集成", "监控告警", "数据接入"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -16,7 +16,7 @@ keywords: ["告警集成", "阿里云 SLS集成", "监控告警", "数据接入"
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -32,9 +32,9 @@ keywords: ["告警集成", "阿里云 SLS集成", "监控告警", "数据接入"
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **阿里云 SLS** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,7 +46,6 @@ keywords: ["告警集成", "阿里云 SLS集成", "监控告警", "数据接入"
</div>
## 在阿里云 SLS
----
**步骤 1:配置 Webhook**
<div className="md-block">
@@ -54,11 +53,11 @@ keywords: ["告警集成", "阿里云 SLS集成", "监控告警", "数据接入"
1. 登录您的阿里云控制台,选择日志服务 SLS 产品,选择一个 Project
2. 进入 `告警`->`告警管理`->`Webhook集成` 页面,单击 `新建` 按钮,开始编辑
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-sls/aliyun-sls-alert-management.jpg" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-sls/aliyun-sls-alert-management.jpg" />
3. 如图,`类型`选择“通用 Webhook”,`请求方法`选择 POST,`请求地址`填写集成的推送地址(保存后得到)
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-sls/aliyun-sls-create-webhook.jpg" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-sls/aliyun-sls-create-webhook.jpg" />
4. 点击`确认`按钮,提交保存
@@ -71,11 +70,11 @@ keywords: ["告警集成", "阿里云 SLS集成", "监控告警", "数据接入"
1. 切换到`内容模板`页面,点击`添加`按钮,开始编辑
2. 进入`Webhook-自定义`配置项,`发送方式`选择“逐条发送”,`发送内容`复制以下内容:
-```
-{{ alert | to_json}}
-```
+ ```
+ {{ alert | to_json}}
+ ```
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-sls/aliyun-sls-create-template.jpg" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-sls/aliyun-sls-create-template.jpg" />
3. 点击`确认`按钮,提交保存
@@ -89,7 +88,7 @@ keywords: ["告警集成", "阿里云 SLS集成", "监控告警", "数据接入"
2. 进入`第一行动列表`配置项,点击添加一个`行动组`节点。
3. `渠道`选择“通用 Webhook”,`选择Webhook`和`内容模板`使用前边创建的对象,`发送时段`选择“任意”
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-sls/aliyun-sls-create-action-policy.jpg" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-sls/aliyun-sls-create-action-policy.jpg" />
4. 点击`结束`,完成第一行动列表创建
5. 点击`确认`按钮,提交保存
@@ -104,7 +103,7 @@ keywords: ["告警集成", "阿里云 SLS集成", "监控告警", "数据接入"
2. 进入`告警规则`编辑页面,`告警策略`。
3. `告警策略`选择“普通模式”,`行动策略`使用前边创建的对象
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-sls/aliyun-sls-update-alert-rule.jpg" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/aliyun-sls/aliyun-sls-update-alert-rule.jpg" />
4. 点击`确定`按钮,提交保存
5. 针对所有其他规则,重复上述步骤,可以将全部告警推送到 Flashduty
@@ -112,7 +111,6 @@ keywords: ["告警集成", "阿里云 SLS集成", "监控告警", "数据接入"
</div>
## 状态对照
----
<div className="md-block">
阿里云SLS监控到 Flashduty 告警等级映射关系:
@@ -128,7 +126,6 @@ keywords: ["告警集成", "阿里云 SLS集成", "监控告警", "数据接入"
</div>
## 阿里云操作审计 ActionTrail
----
<div className="md-block">
操作审计 ActionTrail 的"事件告警"功能由日志服务 SLS 提供,不是独立的推送通道:先创建一条跟踪(Trail)把事件投递到一个 Logstore,再在该 Logstore 上配置 SLS 告警,通知渠道复用上文的 Webhook 集成步骤,无需为 ActionTrail 单独接入。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/amazon-inspector.mdx b/zh/on-call/integration/alert-integration/alert-sources/amazon-inspector.mdx
index 7068a8e6..20c3f1ba 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/amazon-inspector.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/amazon-inspector.mdx
@@ -1,5 +1,6 @@
---
title: "Amazon Inspector 告警集成"
+sidebarTitle: "Amazon Inspector"
description: "通过 EventBridge 规则把 Amazon Inspector 的漏洞和网络可达性发现推送到 Flashduty 的 AWS EventBridge 集成,发现关闭或被抑制时自动恢复告警。"
keywords: ["告警集成", "Amazon Inspector", "Inspector2", "漏洞扫描", "EventBridge", "AWS"]
---
@@ -9,7 +10,6 @@ Amazon Inspector 在发现新漏洞或状态变化时向 Amazon EventBridge 发
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 AWS EventBridge**,不是 Amazon Inspector。
@@ -30,7 +30,6 @@ Amazon Inspector 在发现新漏洞或状态变化时向 Amazon EventBridge 发
</div>
## 在 AWS 中配置
----
Inspector 把事件发到启用 Inspector 的每个区域的默认事件总线,规则要在每个区域分别创建。
@@ -67,7 +66,6 @@ Inspector 把事件发到启用 Inspector 的每个区域的默认事件总线
Inspector 的其他事件(`Inspector2 Scan`、`Inspector2 Coverage`、`Inspector2 AutoEnable`)不是发现,不要转发到 Flashduty;上面的 `detail-type` 已经把它们排除在外。
## 字段映射
----
以下映射来自 Flashduty 对 AWS EventBridge 事件的处理:
@@ -83,7 +81,6 @@ Inspector 的其他事件(`Inspector2 Scan`、`Inspector2 Coverage`、`Inspect
| 事件的 `source`、`region`、`account`、`detail-type`、`detail`、`resources` | 标签 `source`、`region`、`account`、`check`、`detail`、`resources` |
## 恢复与去重
----
- Inspector 在漏洞被修复、发现状态变化时对同一个 `findingArn` 再发一次事件。`status` 为 `CLOSED`(已修复)或 `SUPPRESSED` 时,Flashduty 关闭对应告警。
- 如果账号是 Inspector 的委派管理员,成员账号的发现也会发到管理员账号,可以用标签 `aws_account_id` 区分来源账号。
@@ -91,7 +88,6 @@ Inspector 的其他事件(`Inspector2 Scan`、`Inspector2 Coverage`、`Inspect
- 代码漏洞类发现的 `detail` 里含有文件路径和检测器名称,会随 `detail` 标签一起进入告警。
## 排查问题
----
- **API destination 调用失败**:确认 endpoint 是完整推送地址且包含 `integration_key`,`HTTP method` 为 `POST`
- **告警没有恢复**:检查规则的事件模式是否按 `status` 过滤,以及目标是否配置了 Input transformer(需要发送完整事件)
diff --git a/zh/on-call/integration/alert-integration/alert-sources/apcupsd.mdx b/zh/on-call/integration/alert-integration/alert-sources/apcupsd.mdx
index 5a6c4103..475248c6 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/apcupsd.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/apcupsd.mdx
@@ -1,5 +1,6 @@
---
title: "apcupsd 告警集成"
+sidebarTitle: "apcupsd"
description: "通过 apcupsd 的事件脚本把 APC UPS 的断电、电池故障、通信中断等事件推送到 Flashduty 的标准告警事件集成,恢复事件自动关闭告警。"
keywords: ["告警集成", "apcupsd", "APC UPS", "UPS", "断电告警", "apccontrol", "标准告警事件"]
---
@@ -9,7 +10,6 @@ apcupsd 检测到 UPS 状态变化时会调用 `apccontrol`,`apccontrol` 再
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 标准告警事件**,不是 apcupsd。
@@ -30,7 +30,6 @@ apcupsd 检测到 UPS 状态变化时会调用 `apccontrol`,`apccontrol` 再
</div>
## 在 apcupsd 中配置
----
### 步骤 1:创建推送脚本
@@ -73,7 +72,7 @@ exit 0
apcupsd 的定制方式(见 `apccontrol` 手册):在 `/etc/apcupsd` 目录创建与事件同名的可执行文件,事件发生时 `apccontrol` 会先执行它,脚本以退出码 0 结束时,`apccontrol` 继续执行该事件的默认动作;以退出码 99 结束则跳过默认动作。上面的脚本始终以 0 退出,不会改变 apcupsd 的默认行为(包括关机流程)。
-下面的命令为每个事件创建一个只调用推送脚本的事件文件;目录里已经存在同名文件的事件(apcupsd 默认安装的 `onbattery`、`offbattery`、`commfailure`、`commok`、`changeme` 示例脚本就是这种情况)不会被覆盖,命令会提示你手动在文件开头附近加一行调用:
+下面的命令为每个事件创建一个只调用推送脚本的事件文件;目录里已经存在同名文件的事件(apcupsd 默认安装的 `onbattery`、`offbattery`、`commfailure`、`commok`、`changeme` 示例脚本就是这种情况)不会被覆盖,命令会提示您手动在文件开头附近加一行调用:
```sh
for e in onbattery offbattery mainsback failing timeout loadlimit runlimit commfailure commok changeme emergency battdetach battattach; do
@@ -114,7 +113,6 @@ done
在 Flashduty 中应先看到告警 `UPS myups: on battery`,随后被恢复。手动运行 `onbattery` 会同时执行该事件文件里已有的其他内容;只想测试推送时,直接运行 `/etc/apcupsd/flashduty-notify.sh onbattery myups`。
## 恢复与去重
----
- `onbattery`、失效类事件(`failing`、`timeout`、`loadlimit`、`runlimit`)与 `offbattery`、`mainsback` 共用 Alert Key `apcupsd:<UPS 名称>:power`:`onbattery` 触发告警,随后的失效类事件把它升级为 Critical,市电恢复时被恢复
- `commfailure` 与 `commok`、`battdetach` 与 `battattach` 各自成对
@@ -122,7 +120,6 @@ done
- 多台 UPS 的告警互不影响:Alert Key 中带有 UPS 名称(`apcupsd.conf` 中配置的名称)
## 排查问题
----
- **没有收到告警**:确认 `/etc/apcupsd` 下与事件同名的文件存在且可执行,`flashduty-notify.sh` 中的 `URL` 正确;手动运行事件文件检查输出
- **告警没有恢复**:确认恢复事件(`offbattery`、`mainsback`、`commok`、`battattach`)也挂接了脚本
diff --git a/zh/on-call/integration/alert-integration/alert-sources/apimetrics.mdx b/zh/on-call/integration/alert-integration/alert-sources/apimetrics.mdx
index 7f987857..0cccfaf8 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/apimetrics.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/apimetrics.mdx
@@ -1,5 +1,6 @@
---
title: "APIContext(APImetrics)告警集成"
+sidebarTitle: "APIContext(APImetrics)"
description: "通过 APIContext(原 APImetrics)的 Performance Results Webhook,将 API 调用的失败、告警、变慢和恢复结果同步到 Flashduty On-call。"
keywords: ["告警集成", "APIContext", "APImetrics", "API 监控", "Webhook", "call_id", "result_class"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "APIContext", "APImetrics", "API 监控", "Webhook",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "APIContext", "APImetrics", "API 监控", "Webhook",
</div>
## 在 APIContext 中配置
----
<Steps>
<Step title="新增 Generic Webhook">
@@ -65,7 +64,6 @@ keywords: ["告警集成", "APIContext", "APImetrics", "API 监控", "Webhook",
</Steps>
## 推送内容
----
APIContext 以 HTTP POST 发送 JSON,每个请求对应一次调用结果,无需配置模板。Flashduty 使用以下字段:
@@ -86,14 +84,12 @@ APIContext 以 HTTP POST 发送 JSON,每个请求对应一次调用结果,
告警标题为“调用名称: result”,例如 `Orders API: HTTP_SERVER_ERROR`。
## Alert Key
----
Alert Key 由 `call_id` 计算得到,每个 API 调用对应一条告警。APIContext 文档说明 `call_id` 是“每次执行该调用都相同的固定 ID”,所以同一个调用的失败和恢复结果落在同一条告警上,无论结果来自哪个探测地点。默认调度下每次执行只从一个随机地点探测,因此任一地点返回的 `PASS` 都会关闭该调用的告警,下一次失败再重新打开。`location_id` 只作为标签和描述保留。
修改调用名称、结果详情、响应时间或 HTTP 状态码不会改变 Alert Key。请求缺少 `call_id` 时,Flashduty 返回参数错误,因为无法可靠地把恢复关联到原告警;不含 `call_id`、`result_id` 和 `result_class` 的请求(如空对象)视为测试请求,返回成功且不创建告警。
## 状态和告警等级
----
| `result_class` | Flashduty 状态或等级 |
| :--- | :--- |
@@ -106,7 +102,6 @@ Alert Key 由 `call_id` 计算得到,每个 API 调用对应一条告警。API
`SLOW` 表示调用成功但响应慢,Flashduty 记为 Warning,不会关闭已有的失败告警。需要调整等级时,可在协作空间的 **配置** 中用规则改写。
## 常见问题
----
<AccordionGroup>
<Accordion title="告警没有自动恢复?">
@@ -129,7 +124,6 @@ Alert Key 由 `call_id` 计算得到,每个 API 调用对应一条告警。API
</AccordionGroup>
## 排查问题
----
- **APIContext 收不到成功响应**:确认 URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:请求体缺少 `call_id`。请确认使用的是 Generic Webhook,而不是 OpenTelemetry 或其他类型的导出
diff --git a/zh/on-call/integration/alert-integration/alert-sources/appdynamics.mdx b/zh/on-call/integration/alert-integration/alert-sources/appdynamics.mdx
index b5d3eeff..8b7ae6a6 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/appdynamics.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/appdynamics.mdx
@@ -1,5 +1,6 @@
---
title: "AppDynamics 告警事件"
+sidebarTitle: "AppDynamics"
description: "通过 webhook 的方式同步 AppDynamics 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "AppDynamics 告警事件", "监控告警", "数据接入"]
---
@@ -8,7 +9,6 @@ keywords: ["告警集成", "AppDynamics 告警事件", "监控告警", "数据
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -16,7 +16,7 @@ keywords: ["告警集成", "AppDynamics 告警事件", "监控告警", "数据
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -32,9 +32,9 @@ keywords: ["告警集成", "AppDynamics 告警事件", "监控告警", "数据
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **AppDynamics** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -47,23 +47,21 @@ keywords: ["告警集成", "AppDynamics 告警事件", "监控告警", "数据
</div>
## 在 AppDynamics
----
<div className="md-block">
-## 一、AppDynamics 告警推送配置
-### 步骤1:配置 FlashDudy 告警通道
+### 步骤1:配置 Flashduty 告警通道
1. 登录您的 AppDynamics 控制台。
2. 找到 `Alert Respond` ,选择 `HTTP Request Templates` 并点击 `New` 新建告警通道。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-1.png" />
3. 在模版配置中,`Name` 填写 **Flashduty** 。
4. 在 `Request URL` 部分,`Method` 选择 **POST** ,`Raw URL` 填写集成的推送地址(当前页面填写集成名称,保存后即可生成地址)。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-2.png" />
5. 在 `Payload` 部分,`MIME Type` 选择 `application/json`,`Payload Encoding` 选择 `UTF-8`。
6. 在 `Payload` 文本框中,粘贴一下内容:
@@ -127,7 +125,7 @@ keywords: ["告警集成", "AppDynamics 告警事件", "监控告警", "数据
7. 在 `Response Handling Criteria` 部分,将 `Failure Criteria` 状态代码设置为 400,将 `Success Criteria` 状态代码设置为 201。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-4.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-4.png" />
8. 点击 `Save` 保存即可。
@@ -136,7 +134,7 @@ keywords: ["告警集成", "AppDynamics 告警事件", "监控告警", "数据
1. 在左侧导航栏中选择 `Actions`,选择要为哪个应用类型创建,并点击 `Create`。
2. 在弹出的 `Create Action` 框中,选择 `Make an HTTP Request` 并点击 `OK`。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-6.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-6.png" />
3. 在弹出的 `Create HTTP Action` 框中,输入 Name,`HTTP Request Template` 选择 `步骤1` 创建的 **Flashduty** 并点击 `SAVE`。
@@ -148,13 +146,13 @@ keywords: ["告警集成", "AppDynamics 告警事件", "监控告警", "数据
2. 创建或编辑已有的策略(告警规则按需配置即可,此处省略告警规则的配置)。
3. 在弹出的配置策略页面的 `Actions` 处,点击添加并选择 `步骤2` 创建的 Action 。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-8.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/appdyn-8.png" />
4. 其他配置完成后,点击 `Save` 保存即可。
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/appsignal.mdx b/zh/on-call/integration/alert-integration/alert-sources/appsignal.mdx
index 2f30f3ab..df1546e4 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/appsignal.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/appsignal.mdx
@@ -1,5 +1,6 @@
---
title: "AppSignal 告警集成"
+sidebarTitle: "AppSignal"
description: "通过 Webhook 通知器将 AppSignal 的异常事件、性能事件和异常检测告警同步到 Flashduty On-call。"
keywords: ["告警集成", "AppSignal", "Webhook", "APM", "异常检测", "错误监控"]
---
@@ -13,7 +14,6 @@ keywords: ["告警集成", "AppSignal", "Webhook", "APM", "异常检测", "错
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -34,7 +34,6 @@ keywords: ["告警集成", "AppSignal", "Webhook", "APM", "异常检测", "错
</div>
## 在 AppSignal 中配置
----
<Steps>
<Step title="添加 Webhook 通知器">
@@ -69,7 +68,6 @@ AppSignal 文档没有描述 Webhook 通知器的测试推送按钮,请用真
</Steps>
## 事件和恢复
----
| AppSignal payload | 触发条件 | 在 Flashduty 中的效果 |
| :--- | :--- | :--- |
@@ -82,7 +80,6 @@ AppSignal 文档没有描述 Webhook 通知器的测试推送按钮,请用真
AppSignal 只在异常检测告警打开和解决这两次状态变化时通知 Webhook,预热(warming up)和冷却(cooldown)阶段不会推送。
## Alert Key
----
Flashduty 按事件的对象生成 Alert Key,同一对象的多次推送使用同一个 Alert Key:
@@ -94,17 +91,14 @@ Flashduty 按事件的对象生成 Alert Key,同一对象的多次推送使用
异常事件和性能事件共用同一套事件编号,Alert Key 由对象类型和上表字段共同计算。触发器名称、当前值、时间、异常消息、版本号等字段变化不会改变 Alert Key。缺少对应字段的推送会被拒绝,并在错误信息中指出字段名。
## 告警等级
----
AppSignal 的 payload 不携带等级,所有告警在 Flashduty 中都是 Warning,恢复时状态变为已恢复。如需区分等级,可在集成的路由或告警处理规则中按标签设置。
## 异常和性能事件不会恢复
----
异常事件和性能事件没有恢复通知。在接收该集成的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时,并按团队处理异常的时效调整。同一事件再次发生时会更新同一条告警;告警被关闭后再次发生,会创建新的告警。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -123,7 +117,6 @@ AppSignal 的 payload 不携带等级,所有告警在 Flashduty 中都是 Warn
| `url` | AppSignal 中对应告警或事件页面的链接 |
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`
- **没有收到任何推送**:确认 Webhook 通知器已在触发器(告警)或应用通知设置(事件)中选中,并且勾选了对应的 payload 类型
diff --git a/zh/on-call/integration/alert-integration/alert-sources/argocd.mdx b/zh/on-call/integration/alert-integration/alert-sources/argocd.mdx
index 66037e32..de5e234b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/argocd.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/argocd.mdx
@@ -1,5 +1,6 @@
---
title: "Argo CD 告警集成"
+sidebarTitle: "Argo CD"
description: "通过 Argo CD Notifications 的 Webhook 服务将应用同步失败和健康降级同步到 Flashduty On-call,同步成功或恢复健康时自动关闭告警。"
keywords: ["告警集成", "Argo CD", "ArgoCD", "GitOps", "Notifications", "Webhook", "Kubernetes"]
---
@@ -12,7 +13,6 @@ Argo CD 通过内置的 **Notifications**(`argocd-notifications-controller`)
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -33,7 +33,6 @@ Argo CD 通过内置的 **Notifications**(`argocd-notifications-controller`)
</div>
## 在 Argo CD 中配置
----
以下操作需要能修改 Argo CD 所在命名空间(默认 `argocd`)中 ConfigMap 的 Kubernetes 权限,以及修改 Application 或 AppProject 注解的权限。Argo CD 集群需要能访问推送地址所在的域名。
@@ -160,7 +159,6 @@ kubectl exec -n argocd deploy/argocd-notifications-controller -- \
</Steps>
## Alert Key
----
Flashduty 使用 `event_type` 和应用的 `app_uid`(`app.metadata.uid`)计算 Alert Key。Kubernetes 为每个对象分配的 UID 在集群的整个生命周期内唯一,因此:
@@ -173,7 +171,6 @@ Flashduty 使用 `event_type` 和应用的 `app_uid`(`app.metadata.uid`)计
请求缺少 `event_type` 或 `app_uid`,或者同步消息缺少 `phase`、健康消息缺少 `health_status` 时,Flashduty 会拒绝该请求。
## 告警生命周期
----
| `event_type` | 状态字段 | 值 | Flashduty 处理 |
| :--- | :--- | :--- | :--- |
@@ -189,7 +186,6 @@ Flashduty 使用 `event_type` 和应用的 `app_uid`(`app.metadata.uid`)计
应用在告警期间被删除时,Argo CD 不会再发送恢复消息,需要在 Flashduty 中手动关闭该告警,或开启协作空间的[超时自动关闭](/zh/on-call/channel/create-edit)(建议 24 小时)。
## 告警等级
----
| 告警 | 等级 |
| :--- | :--- |
@@ -199,7 +195,6 @@ Flashduty 使用 `event_type` 和应用的 `app_uid`(`app.metadata.uid`)计
如需统一改为其他等级,在推送地址后追加 `&severity=Critical`(或 `Warning`、`Info`)。恢复事件保留原告警的等级。
## 告警内容
----
- **标题**:`Argo CD application <应用名> sync <phase>` 或 `Argo CD application <应用名> health <health_status>`
- **描述**:同步失败为 Argo CD 的同步结果信息(`operationState.message`);健康降级为 `Health status: Degraded`
@@ -208,7 +203,6 @@ Flashduty 使用 `event_type` 和应用的 `app_uid`(`app.metadata.uid`)计
值为空的字段不会写入标签。
## 排查问题
----
- **没有收到告警**:查看 `argocd-notifications-controller` 的日志(`kubectl logs -n argocd deploy/argocd-notifications-controller`),确认应用上有 `notifications.argoproj.io/subscribe.on-flashduty.flashduty` 注解,或 `subscriptions` 中包含 `on-flashduty`
- **日志中出现 `failed with error code 400`**:确认模板与本文一致,所有值都经过 `toJson`;响应内容会指出缺少或不支持的字段
diff --git a/zh/on-call/integration/alert-integration/alert-sources/atatus.mdx b/zh/on-call/integration/alert-integration/alert-sources/atatus.mdx
index 986da26e..a39e162d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/atatus.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/atatus.mdx
@@ -1,5 +1,6 @@
---
title: "Atatus 告警集成"
+sidebarTitle: "Atatus"
description: "通过 Webhook 通知渠道将 Atatus 告警事件的触发和关闭同步到 Flashduty On-call。"
keywords: ["告警集成", "Atatus", "APM", "Webhook", "Notification Channel", "Alert Policy", "incident_id"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Atatus", "APM", "Webhook", "Notification Channel", "
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Atatus", "APM", "Webhook", "Notification Channel", "
</div>
## 在 Atatus 中配置
----
<Steps>
<Step title="创建 Webhook 通知渠道">
@@ -57,7 +56,6 @@ keywords: ["告警集成", "Atatus", "APM", "Webhook", "Notification Channel", "
</Steps>
## 推送内容
----
Atatus 以 `application/json` 格式 POST 以下字段,Flashduty 直接解析,无需配置模板:
@@ -77,14 +75,12 @@ Atatus 以 `application/json` 格式 POST 以下字段,Flashduty 直接解析
`target_name`、`acknowledge_url`、`account_id`、`alert_url`、`timestamp` 等其他字段不会保存。
## Alert Key
----
Flashduty 使用 `incident_id` 作为 Alert Key。同一个 Atatus 事件的开启和关闭通知携带相同的 `incident_id`,因此会落在同一条告警上。事件范围由告警策略的 **Incident preference** 决定(按策略、按规则、按规则和目标),Flashduty 与 Atatus 保持一致。
请求中缺少 `incident_id` 时,Flashduty 会返回参数错误,因为无法可靠地把关闭通知关联到原告警。
## 状态和告警等级
----
| Atatus 字段 | Flashduty 状态或等级 |
| :--- | :--- |
@@ -96,7 +92,6 @@ Flashduty 使用 `incident_id` 作为 Alert Key。同一个 Atatus 事件的开
`status` 为空或为其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="在 Atatus 中确认(Acknowledge)事件会影响 Flashduty 告警吗?">
@@ -113,7 +108,6 @@ Flashduty 使用 `incident_id` 作为 Alert Key。同一个 Atatus 事件的开
</AccordionGroup>
## 排查问题
----
- **Atatus 推送失败**:确认 URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求中带有 `incident_id`,且 `status` 为 `Opened`、`Closed` 或 `Acknowledged`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/auth0.mdx b/zh/on-call/integration/alert-integration/alert-sources/auth0.mdx
index aa58fc63..34cdf361 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/auth0.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/auth0.mdx
@@ -1,5 +1,6 @@
---
title: "Auth0 告警集成"
+sidebarTitle: "Auth0"
description: "通过 Auth0 自定义 Webhook 日志流,将攻击防护、泄露密码和登录失败等租户日志同步到 Flashduty On-call。"
keywords: ["告警集成", "Auth0", "日志流", "Log Stream", "身份认证", "安全告警", "泄露密码"]
---
@@ -9,7 +10,6 @@ Auth0 的日志流(Log Streams)可以把租户日志实时 POST 到自定义
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Auth0 的日志流(Log Streams)可以把租户日志实时 POST 到自定义
</div>
## 在 Auth0 中配置
----
<Steps>
<Step title="创建日志流">
@@ -39,12 +38,12 @@ Auth0 的日志流(Log Streams)可以把租户日志实时 POST 到自定义
2. 点击 **Create Log Stream**,选择 **Custom Webhook**,输入名称
3. 填写以下设置:
-| 设置 | 值 |
-| :--- | :--- |
-| Payload URL | Flashduty 推送地址 |
-| Content Type | `application/json` |
-| Content Format | JSON Lines、JSON Array 或 JSON Object,三种都支持 |
-| Authorization Token | 留空。Flashduty 通过地址中的 `integration_key` 认证 |
+ | 设置 | 值 |
+ | :--- | :--- |
+ | Payload URL | Flashduty 推送地址 |
+ | Content Type | `application/json` |
+ | Content Format | JSON Lines、JSON Array 或 JSON Object,三种都支持 |
+ | Authorization Token | 留空。Flashduty 通过地址中的 `integration_key` 认证 |
4. 在 **Filter by Log Event Category** 中只勾选错误和警告类日志,减少推送量;不过滤也可以,Flashduty 会忽略成功类日志
5. 点击 **Save**
@@ -65,19 +64,16 @@ Auth0 日志流没有“发送测试通知”功能。
</Steps>
## 事件与恢复
----
Auth0 每生成一条租户日志只推送一次,不会推送更新或恢复通知。每条日志有唯一的 `log_id`,Flashduty 用它作为 Alert Key,因此 Auth0 重试投递同一条日志时不会重复告警,不同的日志各自产生一条 Flashduty 告警,不会自动恢复。
请在协作空间中开启[超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时;也可以处理完成后手动关闭。同一个来源 IP 反复触发时,可以在协作空间中配置降噪规则,把它们合并成一个故障。
## Alert Key
----
Alert Key 由日志的 `log_id` 计算。缺少 `log_id` 的告警类日志会被拒绝并返回参数错误。
## 告警等级
----
按日志类型代码(`type`)映射,其他类型代码的日志被忽略:
@@ -92,7 +88,6 @@ Alert Key 由日志的 `log_id` 计算。缺少 `log_id` 的告警类日志会
完整的类型代码见 [Auth0 日志事件类型代码](https://auth0.com/docs/deploy-monitor/logs/log-event-type-codes)。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -109,7 +104,6 @@ Alert Key 由日志的 `log_id` 计算。缺少 `log_id` 的告警类日志会
告警描述取自日志的 `description` 和 `details.error.message`。Flashduty 不读取用户邮箱、User-Agent 等字段。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 Content Type 为 `application/json`,并检查 Payload URL 中的 `integration_key`
- **没有收到告警**:确认日志类型在上表中;Health 页状态为 Active;日志流的事件类别过滤没有排除对应类型
diff --git a/zh/on-call/integration/alert-integration/alert-sources/auvik.mdx b/zh/on-call/integration/alert-integration/alert-sources/auvik.mdx
index 79742be1..32b73b92 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/auvik.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/auvik.mdx
@@ -1,5 +1,6 @@
---
title: "Auvik 告警集成"
+sidebarTitle: "Auvik"
description: "通过 Webhook 集成将 Auvik 网络监控的告警触发和清除通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Auvik", "Webhook", "网络监控", "MSP"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Auvik", "Webhook", "网络监控", "MSP"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Auvik", "Webhook", "网络监控", "MSP"]
</div>
## 在 Auvik 中配置
----
Webhook 集成只能在 Auvik 的 MSP 全局视图中管理,需要相应的管理权限。推送地址必须是 HTTPS,Flashduty 的推送地址满足该要求。
@@ -70,12 +69,10 @@ Auvik 要求组织名称使用标准英文字符,否则 Webhook 告警可能
</Note>
## Alert Key
----
Flashduty 使用通知中的 `correlationId`(Auvik 文档:告警触发的唯一 API 标识)作为 Alert Key。同一次告警的触发通知和清除通知携带相同的 `correlationId`,但 `alertId` 不同,因此 Flashduty 不使用 `alertId`。告警名称、等级、描述和时间等字段变化不会改变 Alert Key。带有状态但缺少 `correlationId` 的通知会被拒绝。
## 状态和告警等级
----
Flashduty 按 `alertStatusString`(缺失时按 `alertStatus`)确定状态,按 `alertSeverity`(缺失时按 `alertSeverityString`)确定等级:
@@ -94,7 +91,6 @@ Flashduty 按 `alertStatusString`(缺失时按 `alertStatus`)确定状态,
等级缺失或取值不在上表中时按 Warning 处理。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -108,7 +104,6 @@ Flashduty 按 `alertStatusString`(缺失时按 `alertStatus`)确定状态,
| `url` | Auvik 中该告警页面的链接 |
## 排查问题
----
- **Test Connection 失败**:确认 Webhook URL 完整、包含 `integration_key`,且使用 HTTPS
- **没有收到告警**:确认通知渠道已关联到对应告警,且通知渠道的联系方式选择了这个 Webhook 集成
diff --git a/zh/on-call/integration/alert-integration/alert-sources/aws-cloudwatch.mdx b/zh/on-call/integration/alert-integration/alert-sources/aws-cloudwatch.mdx
index 000424a2..7d673689 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/aws-cloudwatch.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/aws-cloudwatch.mdx
@@ -1,5 +1,6 @@
---
-title: "AWS CloudWatch集成"
+title: "AWS CloudWatch 集成"
+sidebarTitle: "AWS CloudWatch"
description: "通过 Amazon SNS 把 CloudWatch 告警、Cost Anomaly Detection、Amazon Managed Service for Prometheus 和 AWS Budgets 通知同步到 Flashduty On-call"
keywords: ["告警集成", "AWS CloudWatch集成", "Amazon SNS", "Cost Anomaly Detection", "Amazon Managed Service for Prometheus", "AWS Budgets"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "AWS CloudWatch集成", "Amazon SNS", "Cost Anomaly D
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -17,7 +17,7 @@ keywords: ["告警集成", "AWS CloudWatch集成", "Amazon SNS", "Cost Anomaly D
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -33,9 +33,9 @@ keywords: ["告警集成", "AWS CloudWatch集成", "Amazon SNS", "Cost Anomaly D
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **AWS CloudWatch** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -48,7 +48,6 @@ keywords: ["告警集成", "AWS CloudWatch集成", "Amazon SNS", "Cost Anomaly D
</div>
## 在 AWS 中配置
----
<div className="md-block">
1. 登录 AWS 控制台,打开 `Simple Notification Service`
@@ -57,13 +56,13 @@ keywords: ["告警集成", "AWS CloudWatch集成", "Amazon SNS", "Cost Anomaly D
4. `Topic ARN` 选择 `Flashduty`,`Protocol` 选择 `HTTPS`,`Endpoint` 填写集成的推送地址
5. 单击 `Create subscription`
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/aws-cloudwatch-subscribe.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/aws-cloudwatch-subscribe.png" />
6. 回到 `Subscriptions` 页面,订阅状态变为 `Confirmed` 说明 Flashduty 已完成订阅确认
7. 打开 `CloudWatch` 控制台,进入 `All alarms`,创建或编辑告警
8. 在 `Notification` 这一步,为 `In alarm`、`OK` 和 `Insufficient data` 三种状态都选择 SNS 主题 `Flashduty`。不选 `OK` 时告警不会自动恢复
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/aws-cloudwatch-alram.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/aws-cloudwatch-alram.png" />
9. 回到集成列表,显示最新事件时间即说明已收到事件
@@ -74,7 +73,6 @@ keywords: ["告警集成", "AWS CloudWatch集成", "Amazon SNS", "Cost Anomaly D
</Note>
## 其他发布到 SNS 的 AWS 服务
----
把下列服务的通知发送到同一个 `Flashduty` 主题即可,无需额外配置。
@@ -103,7 +101,6 @@ keywords: ["告警集成", "AWS CloudWatch集成", "Amazon SNS", "Cost Anomaly D
无法识别的消息(纯文本或其他 JSON)每条生成一条 Warning 告警:Alert Key 为 SNS `MessageId`,SNS 重试同一条消息时不会重复建告警;标题取 SNS `Subject`,没有时取消息第一行。这类告警不会自动恢复。
## Alert Key
----
| 消息 | Alert Key | 恢复条件 |
| :--- | :--- | :--- |
@@ -115,7 +112,6 @@ keywords: ["告警集成", "AWS CloudWatch集成", "Amazon SNS", "Cost Anomaly D
CloudWatch 告警的 `ALARM`、`INSUFFICIENT_DATA`、`OK` 使用同一个 Alert Key,告警名称、阈值、原因和描述的变化不会拆分告警。缺少 `AlarmArn` 的 CloudWatch 告警消息会被拒绝。
## 状态和告警等级
----
<div className="md-block">
CloudWatch 告警没有等级字段,`ALARM` 和 `INSUFFICIENT_DATA` 默认对应 Warning,`OK` 对应恢复。
@@ -129,7 +125,6 @@ CloudWatch 告警没有等级字段,`ALARM` 和 `INSUFFICIENT_DATA` 默认对
</div>
## 标签
----
- 单指标告警:`trigger_metric_name`、`trigger_namespace`、`trigger_dimensions_<维度名>` 等,维度含 `InstanceId` 时写入 `resource`
- 指标数学和异常检测告警:每个查询写入 `trigger_expression_<查询 ID>`、`trigger_metric_<查询 ID>`(`命名空间/指标名`)和 `trigger_dimensions_<维度名>`;`metric` 和 `check` 取返回数据的查询
@@ -137,7 +132,6 @@ CloudWatch 告警没有等级字段,`ALARM` 和 `INSUFFICIENT_DATA` 默认对
- 所有告警:`alarm_arn`、`aws_account_id`、`region`、`new_state_value`、`old_state_value`
## 排查问题
----
- **订阅停留在 `Pending confirmation`**:确认 Endpoint 是完整推送地址且包含 `integration_key`,然后在 SNS 控制台对该订阅执行 **Request confirmation**
- **Flashduty 返回 SubscribeURL 错误**:Flashduty 只访问 `sns.<region>.amazonaws.com`、`sns.<region>.amazonaws.com.cn` 和 `sns.<region>.amazonaws.eu` 上的订阅确认地址,请确认订阅请求来自 Amazon SNS
diff --git a/zh/on-call/integration/alert-integration/alert-sources/aws-eventbridge.mdx b/zh/on-call/integration/alert-integration/alert-sources/aws-eventbridge.mdx
index 4adfc3f4..c1ce7104 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/aws-eventbridge.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/aws-eventbridge.mdx
@@ -1,5 +1,6 @@
---
title: "AWS EventBridge 告警事件"
+sidebarTitle: "AWS EventBridge"
description: "通过 EventBridge 把 CloudWatch 告警、GuardDuty、Security Hub、AWS Health、Inspector、Config 和 DevOps Guru 事件同步到 Flashduty On-call,并自动合并和恢复"
keywords: ["告警集成", "AWS EventBridge", "GuardDuty", "Security Hub", "AWS Health", "Amazon Inspector", "AWS Config", "DevOps Guru"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "AWS EventBridge", "GuardDuty", "Security Hub", "AWS
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -17,7 +17,7 @@ keywords: ["告警集成", "AWS EventBridge", "GuardDuty", "Security Hub", "AWS
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -33,9 +33,9 @@ keywords: ["告警集成", "AWS EventBridge", "GuardDuty", "Security Hub", "AWS
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **AWS EventBridge** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -48,7 +48,6 @@ keywords: ["告警集成", "AWS EventBridge", "GuardDuty", "Security Hub", "AWS
</div>
## 在 AWS EventBridge 中配置
----
以下两种推送方式任选其一。
@@ -61,7 +60,7 @@ keywords: ["告警集成", "AWS EventBridge", "GuardDuty", "Security Hub", "AWS
2. 在左侧导航栏选择 `Integration=>API destinations`。
3. 点击 `connection`,并点击 `Create connection` 创建链接。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/aws-eb-3.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/aws-eb-3.png" />
4. 在 `Connection details` 部分中,`Connection name` 处填写 `Flashduty`。
5. 在 `Authorization` 部分中,`Destination type` 选择 `Other`。
@@ -75,7 +74,7 @@ keywords: ["告警集成", "AWS EventBridge", "GuardDuty", "Security Hub", "AWS
1. 回到 `API destinations` 界面,并点击 `Create API destination`。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/aws-eb-5.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/aws-eb-5.png" />
2. 在 `API destination detail` 编辑界面填写相关信息,`Name` 填写 `Flashduty` 。
3. `API destination endpoint` 填写集成的推送地址(当前页面填写集成名称,保存后即可生成地址)。
@@ -107,7 +106,6 @@ keywords: ["告警集成", "AWS EventBridge", "GuardDuty", "Security Hub", "AWS
Flashduty 只访问 `sns.<region>.amazonaws.com`、`sns.<region>.amazonaws.com.cn` 和 `sns.<region>.amazonaws.eu` 上的订阅确认地址。
## 事件规则
----
在规则中填写事件模式,例如:
@@ -137,7 +135,6 @@ Flashduty 只访问 `sns.<region>.amazonaws.com`、`sns.<region>.amazonaws.com.c
AWS Health 事件发往事件发生的区域,全局服务的事件在 `us-east-1`。需要在每个关心的区域创建规则。
## Alert Key 和恢复
----
| 来源 | `detail-type` | Alert Key | 恢复条件 |
| :--- | :--- | :--- | :--- |
@@ -156,7 +153,6 @@ AWS Health 事件发往事件发生的区域,全局服务的事件在 `us-east
- GuardDuty 归档发现时不发送事件,告警需要手动关闭
## 告警等级
----
EventBridge 事件没有统一的等级字段,所有事件都以 Warning 触发,与接入以来的行为一致。来源自带的等级保留在标签中,可以在 [告警处理](/zh/on-call/integration/alert-integration/alert-pipelines) 中按标签改写等级:
@@ -172,7 +168,6 @@ EventBridge 事件没有统一的等级字段,所有事件都以 Warning 触
CloudWatch 告警可以在 **Alarm description** 中写 `flashduty_severity: critical`(可选 `critical`、`warning`、`info`)指定等级,写法与 [AWS CloudWatch 集成](/zh/on-call/integration/alert-integration/alert-sources/aws-cloudwatch) 相同。
## 标题和标签
----
- 告警标题为 `来源::detail-type`,例如 `aws.guardduty::GuardDuty Finding`
- 所有事件都带 `source`、`region`、`account`、`check`(`detail-type`)、`detail`(事件 `detail` 的 JSON)和 `resources` 标签
@@ -180,7 +175,6 @@ CloudWatch 告警可以在 **Alarm description** 中写 `flashduty_severity: cri
- 有专门处理的来源还会附加 `finding_id`、`finding_arn`、`event_arn`、`config_rule_name`、`insight_id` 等来源字段,`resource` 取受影响资源(DevOps Guru 洞察没有该标签)
## 排查问题
----
- **API destination 调用失败**:确认 endpoint 是完整推送地址且包含 `integration_key`,`HTTP method` 为 `POST`
- **SNS 订阅停留在 `Pending confirmation`**:确认订阅的是本集成的推送地址,然后在 SNS 控制台执行 **Request confirmation**
diff --git a/zh/on-call/integration/alert-integration/alert-sources/aws-health.mdx b/zh/on-call/integration/alert-integration/alert-sources/aws-health.mdx
index 0a214e99..0bf48444 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/aws-health.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/aws-health.mdx
@@ -1,15 +1,15 @@
---
title: "AWS Health 告警集成"
+sidebarTitle: "AWS Health"
description: "通过 Amazon EventBridge 规则接收 AWS Health 事件,使用 Flashduty 的 AWS EventBridge 集成,事件关闭时自动恢复告警。"
keywords: ["告警集成", "AWS Health", "AWS Health Dashboard", "EventBridge", "服务健康", "计划变更"]
---
-AWS Health 把影响你账号的服务事件(运行故障、计划变更、账号通知)作为 `source` 为 `aws.health`、`detail-type` 为 `AWS Health Event` 的事件发送到 Amazon EventBridge。Flashduty 的 [AWS EventBridge 集成](/zh/on-call/integration/alert-integration/alert-sources/aws-eventbridge) 对这类事件有专门处理,因此不需要单独的 AWS Health 集成:在 Flashduty 创建 AWS EventBridge 集成,把它的推送地址设为 EventBridge 规则的目标即可。
+AWS Health 把影响您账号的服务事件(运行故障、计划变更、账号通知)作为 `source` 为 `aws.health`、`detail-type` 为 `AWS Health Event` 的事件发送到 Amazon EventBridge。Flashduty 的 [AWS EventBridge 集成](/zh/on-call/integration/alert-integration/alert-sources/aws-eventbridge) 对这类事件有专门处理,因此不需要单独的 AWS Health 集成:在 Flashduty 创建 AWS EventBridge 集成,把它的推送地址设为 EventBridge 规则的目标即可。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 AWS EventBridge**,不是 AWS Health。
@@ -30,31 +30,30 @@ AWS Health 把影响你账号的服务事件(运行故障、计划变更、账
</div>
## 在 AWS 中配置
----
AWS Health 事件要通过 EventBridge 规则转发,规则的目标使用指向 Flashduty 推送地址的 API destination(也可以经 SNS 主题转发)。API destination 和 SNS 两种目标的具体步骤见 [AWS EventBridge 集成](/zh/on-call/integration/alert-integration/alert-sources/aws-eventbridge),AWS Health 只需要在规则里使用下面的事件模式。
1. 在 EventBridge 中创建规则,事件模式填写:
-```json
-{
- "source": ["aws.health"],
- "detail-type": ["AWS Health Event"]
-}
-```
+ ```json
+ {
+ "source": ["aws.health"],
+ "detail-type": ["AWS Health Event"]
+ }
+ ```
2. 需要缩小范围时,在 `detail` 中增加过滤条件。例如只接收 Amazon EC2 的 `issue` 类事件:
-```json
-{
- "source": ["aws.health"],
- "detail-type": ["AWS Health Event"],
- "detail": {
- "eventTypeCategory": ["issue"],
- "service": ["EC2"]
- }
-}
-```
+ ```json
+ {
+ "source": ["aws.health"],
+ "detail-type": ["AWS Health Event"],
+ "detail": {
+ "eventTypeCategory": ["issue"],
+ "service": ["EC2"]
+ }
+ }
+ ```
3. 在规则的目标中选择指向 Flashduty 推送地址的 API destination,保存规则
4. 创建规则时,可在 EventBridge 控制台的 **Test event pattern** 面板选择 AWS 提供的 AWS Health 示例事件,确认事件模式能匹配
@@ -66,14 +65,12 @@ AWS 的说明:规则只接收本账号的事件;公共(PUBLIC)事件在
</Warning>
## 区域和备份规则
----
- 每个需要接收事件的区域都要创建规则;全局事件(例如 IAM 相关事件)发送到 US East (N. Virginia),即 `us-east-1`
- 在标准 AWS 分区中,事件还会同时发送到备份区域 US West (Oregon)。如果在主区域和备份区域都创建了规则,同一事件会到达两次;这两次事件的 `eventArn` 和受影响账号相同,Flashduty 按相同的 Alert Key 合并为一条告警
- 只想保留主区域的事件时,在备份区域的规则里增加 `"backupEvent": ["false"]` 过滤条件(`detail.backupEvent`)
## 字段映射
----
| AWS Health 字段 | Flashduty |
| :--- | :--- |
@@ -88,12 +85,10 @@ AWS 的说明:规则只接收本账号的事件;公共(PUBLIC)事件在
| `region`、`account`、`resources`、`detail` | 标签 `region`、`account`、`resources`、`detail`(`detail` 为事件详情的 JSON) |
## 告警等级
----
EventBridge 事件没有统一的等级字段,所有 AWS Health 事件都以 Warning 触发。需要区分等级时,在 [告警处理](/zh/on-call/integration/alert-integration/alert-pipelines) 中按 `event_type_category` 标签改写等级,例如把 `issue` 改为 Critical,把 `scheduledChange` 保持为 Warning 或降为 Info。
## 恢复与去重
----
- AWS Health 在事件结束时发送 `statusCode` 为 `closed` 的更新,Flashduty 按相同 Alert Key 恢复对应告警
- 计划变更类事件(`scheduledChange`)在开始前就会以 `upcoming` 状态发送,Flashduty 会提前触发告警。只关心正在发生的故障时,在事件模式中限定 `eventTypeCategory` 为 `issue`
@@ -101,7 +96,6 @@ EventBridge 事件没有统一的等级字段,所有 AWS Health 事件都以 W
- `detail.eventArn` 缺失的事件会被拒绝(HTTP 400)
## 排查问题
----
- **规则没有触发**:检查事件模式;公共事件在创建规则后最长可能延迟一小时;确认已在事件所属区域和 `us-east-1`(全局事件)创建规则
- **告警没有恢复**:确认事件模式没有过滤掉 `closed` 状态,且目标没有配置 Input transformer(需要发送完整事件)
diff --git a/zh/on-call/integration/alert-integration/alert-sources/aws-security-hub.mdx b/zh/on-call/integration/alert-integration/alert-sources/aws-security-hub.mdx
index 2c2a9813..408c9d87 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/aws-security-hub.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/aws-security-hub.mdx
@@ -1,5 +1,6 @@
---
title: "AWS Security Hub 告警集成"
+sidebarTitle: "AWS Security Hub"
description: "通过 EventBridge 规则把 AWS Security Hub 的发现(finding)推送到 Flashduty 的 AWS EventBridge 集成,按发现合并,处置状态变化时自动恢复告警。"
keywords: ["告警集成", "AWS Security Hub", "Security Hub", "ASFF", "EventBridge", "云安全", "AWS"]
---
@@ -9,7 +10,6 @@ AWS Security Hub 把每条发现作为 **Security Hub Findings - Imported** 事
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 AWS EventBridge**,不是 AWS Security Hub。
@@ -30,7 +30,6 @@ AWS Security Hub 把每条发现作为 **Security Hub Findings - Imported** 事
</div>
## 在 AWS 中配置
----
1. 按 [AWS EventBridge 集成](/zh/on-call/integration/alert-integration/alert-sources/aws-eventbridge) 中的「方式一:API destination」创建 Connection 和 API destination,endpoint 填 Flashduty 推送地址。也可以用「方式二:SNS 主题」
2. 在 EventBridge 控制台创建规则:**Rule type** 选择 **Rule with an event pattern**
@@ -67,7 +66,6 @@ AWS Security Hub 把每条发现作为 **Security Hub Findings - Imported** 事
Security Hub 的规则在每个启用了 Security Hub 的区域分别创建。自定义动作触发的 **Security Hub Findings - Custom Action** 事件也带有发现,Flashduty 用同样的方式处理,把 `detail-type` 加进规则即可。
## 字段映射
----
**Security Hub Findings - Imported** 事件的 `detail.findings` 每次只包含一条发现。以下映射来自 Flashduty 对 AWS EventBridge 事件的处理:
@@ -82,14 +80,12 @@ Security Hub 的规则在每个启用了 Security Hub 的区域分别创建。
| 事件的 `source`、`region`、`account`、`detail-type`、`detail` | 标签 `source`、`region`、`account`、`check`、`detail` |
## 恢复与去重
----
- 在 Security Hub 中把发现的工作流状态改为 **Resolved** 或 **Suppressed**,或发现被归档,都会产生新的 **Security Hub Findings - Imported** 事件,Flashduty 收到后按相同的 Alert Key 关闭告警。
- 一个事件里有多条发现时,每条发现单独生成告警。
- 事件缺少 `Id` 或 `ProductArn` 时,Flashduty 返回 HTTP 400。
## 排查问题
----
- **API destination 调用失败**:确认 endpoint 是完整推送地址且包含 `integration_key`,`HTTP method` 为 `POST`
- **告警没有恢复**:检查规则的事件模式是否按 `Workflow.Status`、`RecordState` 过滤,以及目标是否配置了 Input transformer(需要发送完整事件)
diff --git a/zh/on-call/integration/alert-integration/alert-sources/axiom.mdx b/zh/on-call/integration/alert-integration/alert-sources/axiom.mdx
index 2b9b9dd2..2a6de9c3 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/axiom.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/axiom.mdx
@@ -1,5 +1,6 @@
---
title: "Axiom 告警集成"
+sidebarTitle: "Axiom"
description: "通过 Axiom 的自定义 Webhook 通知方式(Custom webhook notifier)将 Monitor 的触发与恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Axiom", "Monitor", "Notifier", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Axiom", "Monitor", "Notifier", "Webhook"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Axiom", "Monitor", "Notifier", "Webhook"]
</div>
## 在 Axiom 中配置
----
<Steps>
<Step title="创建 Custom webhook notifier">
@@ -96,7 +95,6 @@ Match monitor 每匹配到一条事件就发送一次 `Open` 通知,不会发
</Steps>
## Alert Key
----
Flashduty 用 `event.monitorID` 生成 Alert Key;通知带有分组(`event.groupKeys` 非空)时,把分组名和分组值也纳入 Alert Key。Axiom 文档将 `.MonitorID` 定义为通知所属 Monitor 的唯一标识;开启 **Notify by group** 后,每个分组单独触发,通知中带有对应的分组值。
@@ -105,7 +103,6 @@ Flashduty 用 `event.monitorID` 生成 Alert Key;通知带有分组(`event.g
- Monitor 名称、描述、当前值和时间的变化都不会改变 Alert Key
## 状态和告警等级
----
Axiom 的通知不带告警等级,Flashduty 将所有 Axiom 告警设为 Critical。需要其他等级时,可以通过[告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines) 按 `check` 或 `monitor_id` 标签调整。
@@ -116,7 +113,6 @@ Axiom 的通知不带告警等级,Flashduty 将所有 Axiom 告警设为 Criti
| 空值或其他值 | 拒绝请求 |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -133,7 +129,6 @@ Axiom 的通知不带告警等级,Flashduty 将所有 Axiom 告警设为 Criti
告警描述为通知的 `event.body`:Threshold monitor 为当前值与阈值的比较说明,Match monitor 为匹配到的事件。
## 排查问题
----
- **Flashduty 返回参数错误**:确认请求体仍是上文的默认模板,`monitorID` 和 `action` 非空
- **告警没有恢复**:Match monitor 不发送恢复通知,请开启超时自动关闭;Threshold monitor 在下一次运行不再越过阈值时才发送 `Closed`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/azure-monitor.mdx b/zh/on-call/integration/alert-integration/alert-sources/azure-monitor.mdx
index 50cb593a..a8374e95 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/azure-monitor.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/azure-monitor.mdx
@@ -1,5 +1,6 @@
---
-title: "Azure Monitor集成"
+title: "Azure Monitor 集成"
+sidebarTitle: "Azure Monitor"
description: "通过 webhook 的方式同步 Azure Monitor 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "Azure Monitor集成", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "Azure Monitor集成", "监控告警", "数据接入"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "Azure Monitor集成", "监控告警", "数据接入"
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "Azure Monitor集成", "监控告警", "数据接入"
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Azure Monitor** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,16 +46,15 @@ keywords: ["告警集成", "Azure Monitor集成", "监控告警", "数据接入"
</div>
## 在 Azure Monitor
----
**步骤 1:配置 Webhook**
<div className="md-block">
1. 登录您的 Azure 门户,选择 Monitor 产品;
-2. 进入 `Alerts -> Action groups` 页面,单击 Create 按钮,开始编辑;
+2. 进入 `Alerts -> Action groups` 页面,单击 **Create** 按钮,开始编辑;
3. 如图,`Actions` 选项选择 `Action type` 为 `Webhook`;
4. 填写名称,`URI` 部分复制写入集成的推送地址,建议 `Enable` 通用告警架构(common alert schema);
-5. 点击 Create 按钮,提交保存。
+5. 点击 **Create** 按钮,提交保存。
<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/azure-mon/action_group.png" />
@@ -66,7 +65,7 @@ keywords: ["告警集成", "Azure Monitor集成", "监控告警", "数据接入"
1. 进入 `Alerts -> Alert rules` 页面,单击 Create 或 选择已有的策略进行编辑;
2. 如下图所示,在 `Actions` 页面,选择已创建好的 Action group;
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/azure-mon/alert_rule.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/azure-mon/alert_rule.png" />
3. 提交保存,等待告警触发。
@@ -75,7 +74,6 @@ keywords: ["告警集成", "Azure Monitor集成", "监控告警", "数据接入"
</div>
## 服务运行状况(Service Health)
----
<div className="md-block">
1. 在 Azure 门户进入 `Service Health -> Health alerts`,点击 `Create service health alert`;
@@ -89,7 +87,6 @@ Action group 的 `Test action group` 发送的 Service Health 示例处于 `Reso
</div>
## 资源运行状况(Resource Health)
----
<div className="md-block">
1. 在 Azure 门户进入 `Service Health -> Resource health`,点击 `Add resource health alert`;
@@ -101,7 +98,6 @@ Action group 的 `Test action group` 发送的 Service Health 示例处于 `Reso
</div>
## Defender for Cloud 安全告警
----
<div className="md-block">
Defender for Cloud 的安全告警会写入活动日志的 `Security` 类别。在 `Alerts -> Alert rules` 新建告警规则,条件选择活动日志信号,类别(Category)为 `Security`,Action 选择上面创建的 Action group。
@@ -111,7 +107,6 @@ Defender for Cloud 的安全告警会写入活动日志的 `Security` 类别。
</div>
## 其他活动日志告警
----
<div className="md-block">
管理操作(Administrative)、策略(Policy)、自动缩放(Autoscale)和顾问建议(Recommendation)的活动日志告警是一次性事件:每条通知对应一个 Flashduty 告警,不会自动恢复。开启通用告警架构时,告警标题为“告警规则名称 on 资源名”,操作名写入 `operation_name` 标签;未开启时,Payload 不含规则名称,标题为“操作名 on 资源名”,例如 `Microsoft.Compute/virtualMachines/restart/action on test-VM`。
@@ -119,7 +114,6 @@ Defender for Cloud 的安全告警会写入活动日志的 `Security` 类别。
</div>
## Alert Key 与恢复
----
<div className="md-block">
| 告警类型 | Alert Key 来源 | 恢复条件 |
@@ -136,7 +130,6 @@ Defender for Cloud 的安全告警会写入活动日志的 `Security` 类别。
</div>
## 状态对照
----
<div className="md-block">
Azure Monitor 到 Flashduty 告警等级映射关系:
@@ -154,7 +147,6 @@ Azure Monitor 到 Flashduty 告警等级映射关系:
</div>
## 常见问题
----
<div className="md-block">
- **Azure 显示 Webhook 调用失败(400)**:检查日志搜索告警是否配置了自定义 JSON Payload,改为开启通用告警架构后重试。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/azure-service-health.mdx b/zh/on-call/integration/alert-integration/alert-sources/azure-service-health.mdx
index 0aae1b3b..d8b6c944 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/azure-service-health.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/azure-service-health.mdx
@@ -1,5 +1,6 @@
---
title: "Azure Service Health 告警集成"
+sidebarTitle: "Azure Service Health"
description: "通过 Service Health 告警规则和 Action group 的 Webhook 接收 Azure 服务事件,使用 Flashduty 的 Azure Monitor 集成,事件解决后自动恢复告警。"
keywords: ["告警集成", "Azure Service Health", "Azure 服务运行状况", "Action group", "Webhook", "Azure Monitor"]
---
@@ -9,7 +10,6 @@ Azure 把服务问题、计划内维护、运行状况公告和安全公告作
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 Azure Monitor**,不是 Azure Service Health。
@@ -30,7 +30,6 @@ Azure 把服务问题、计划内维护、运行状况公告和安全公告作
</div>
## 在 Azure 中配置
----
### 步骤 1:创建带 Webhook 的 Action group
@@ -46,12 +45,11 @@ Azure 要求:Service Health 告警使用的 Action group,其区域必须设
1. 在 Azure 门户选择 **Service Health**,在 **Service Issues** 面板点击 **Create service health alert**
2. 在 **Scope** 中按订阅选择范围
-3. 在 **Condition** 中选择 **Services**、**Regions** 和 **Event types**(服务问题、计划内维护、运行状况公告、安全公告)。Azure 建议同时选择全部服务和区域:只有影响你所用区域的事件才会触发告警,不会因未使用的服务产生告警
+3. 在 **Condition** 中选择 **Services**、**Regions** 和 **Event types**(服务问题、计划内维护、运行状况公告、安全公告)。Azure 建议同时选择全部服务和区域:只有影响您所用区域的事件才会触发告警,不会因未使用的服务产生告警
4. 在 **Details** 中选择资源组并填写告警规则名称
5. 点击 **Advanced options**,在 **Actions** 标签页选择步骤 1 创建的 Action group,然后创建
## 字段映射
----
| Service Health 字段 | Flashduty |
| :--- | :--- |
@@ -64,7 +62,6 @@ Azure 要求:Service Health 告警使用的 Action group,其区域必须设
| 订阅 ID + `trackingId` | 标签 `service_health_url`,指向该事件的 Service Health 页面 |
## 标题和描述
----
| | 启用通用告警架构 | 未启用(旧版 `Microsoft.Insights/activityLogs`) |
| :--- | :--- | :--- |
@@ -75,14 +72,12 @@ Azure 要求:Service Health 告警使用的 Action group,其区域必须设
通用架构下,事件标题和正文保留在 `alertContext` 标签的 JSON 中。需要在通知里直接看到事件标题时,使用旧版负载(不启用通用告警架构)。
## 恢复与去重
----
- Azure 在事件进展时向同一个 Tracking ID 发送多条通知,Flashduty 按 Alert Key 合并;事件进入解决阶段时恢复告警
- 缺少 `properties.trackingId` 的旧版通知会被拒绝(HTTP 400);通用架构下缺少 Tracking ID 的通知每条单独成为一条告警,不会自动恢复
- 计划内维护在 `Complete` 或 `Canceled` 阶段恢复;在维护开始前,告警处于触发状态
## 排查问题
----
- **Action group 没有触发**:确认 Action group 的区域是 **Global**,且告警规则的 **Actions** 标签页已选择该 Action group
- **告警没有恢复**:确认告警规则仍然启用,并等待 Azure 发出事件解决阶段的通知
diff --git a/zh/on-call/integration/alert-integration/alert-sources/baidu-bcm.mdx b/zh/on-call/integration/alert-integration/alert-sources/baidu-bcm.mdx
index a047fc08..8e405979 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/baidu-bcm.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/baidu-bcm.mdx
@@ -1,5 +1,6 @@
---
title: "百度云BCM监控集成"
+sidebarTitle: "百度云BCM监控"
description: "通过 webhook 的方式同步百度云 BCM 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "百度云BCM监控集成", "监控告警", "数据接入"]
---
@@ -8,7 +9,6 @@ keywords: ["告警集成", "百度云BCM监控集成", "监控告警", "数据
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -16,7 +16,7 @@ keywords: ["告警集成", "百度云BCM监控集成", "监控告警", "数据
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -32,9 +32,9 @@ keywords: ["告警集成", "百度云BCM监控集成", "监控告警", "数据
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **百度云监控BCM** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,7 +46,6 @@ keywords: ["告警集成", "百度云BCM监控集成", "监控告警", "数据
</div>
## 在百度云监控 BCM
----
<div className="md-block">
1. 登录您的百度云控制台,检索 `云监控` 产品,并进入对应控制台
@@ -54,14 +53,13 @@ keywords: ["告警集成", "百度云BCM监控集成", "监控告警", "数据
3. 进入 `报警管理-报警策略` 页面,选择编辑已有或创建新的报警策略
4. 报警策略中 `回调地址` 一栏,填写集成的推送地址(当前页面填写集成名称,保存后即可生成地址)
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/baidu-bcm.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/baidu-bcm.png" />
5. 完成
</div>
## 状态对照
----
<div className="md-block">
百度云监控到 Flashduty 告警等级映射关系:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/bgpalerter.mdx b/zh/on-call/integration/alert-integration/alert-sources/bgpalerter.mdx
index afdfad70..0ab97df4 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/bgpalerter.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/bgpalerter.mdx
@@ -1,5 +1,6 @@
---
title: "BGPalerter 告警集成"
+sidebarTitle: "BGPalerter"
description: "通过 reportHTTP 报告模块将 BGPalerter 检测到的 BGP 劫持、前缀可见性下降、RPKI 无效等事件同步到 Flashduty On-call。"
keywords: ["告警集成", "BGPalerter", "BGP", "BGP 劫持", "RPKI", "前缀监控", "Webhook"]
---
@@ -11,7 +12,6 @@ BGPalerter 只在事件发生时推送一次,不会推送恢复通知。因此
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ BGPalerter 只在事件发生时推送一次,不会推送恢复通知。因此
</div>
## 在 BGPalerter 中配置
----
BGPalerter 没有固定的 Webhook 格式,请求体由 `config.yml` 中 `reportHTTP` 的模板决定。Flashduty 只解析下面这份模板生成的 JSON,请原样使用。
@@ -87,7 +86,6 @@ BGPalerter 没有独立的"发送测试通知"按钮。执行 `bgpalerter -t`(
</Steps>
## 事件与恢复
----
`channels` 中每个通道对应一类事件:
@@ -106,7 +104,6 @@ BGPalerter 没有独立的"发送测试通知"按钮。执行 `bgpalerter -t`(
BGPalerter 不推送恢复通知,Flashduty 不会自动恢复这些告警。请在协作空间中开启[超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时;劫持类事件通常需要人工确认,也可以在处理完成后手动关闭。
## Alert Key
----
Flashduty 用事件涉及的路由信息计算 Alert Key:通道(`channel`)、被监控前缀(`prefix`)、被监控 AS(`asn`)、新的来源 AS(`neworigin`)和实际发布的前缀(`newprefix`)。BGPalerter 自身对劫持事件也以"来源 AS + 前缀"为分组依据。
@@ -118,7 +115,6 @@ Flashduty 用事件涉及的路由信息计算 Alert Key:通道(`channel`)
`channel` 缺失,或前缀、AS、摘要都缺失的请求会被拒绝并返回错误。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -136,7 +132,6 @@ Flashduty 用事件涉及的路由信息计算 Alert Key:通道(`channel`)
告警标题取自 BGPalerter 的事件摘要,描述为前缀描述。
## 排查问题
----
- **Flashduty 没有收到告警**:确认 `hooks.default` 是完整的 HTTPS 推送地址并包含 `integration_key`;BGPalerter 推送失败只会写入自己的日志,不会重试
- **BGPalerter 日志报 JSON 解析错误**:检查 `prefixes.yml` 中的前缀描述是否含有英文双引号或换行
diff --git a/zh/on-call/integration/alert-integration/alert-sources/bigpanda.mdx b/zh/on-call/integration/alert-integration/alert-sources/bigpanda.mdx
index d5c592ab..8bc922c8 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/bigpanda.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/bigpanda.mdx
@@ -1,5 +1,6 @@
---
title: "BigPanda 告警集成"
+sidebarTitle: "BigPanda"
description: "通过 BigPanda 的 Notifications Webhook v2 集成,将 BigPanda 事件关联后生成的 Incident 同步到 Flashduty On-call。"
keywords: ["告警集成", "BigPanda", "AIOps", "Notifications Webhook v2", "AutoShare", "incident.id"]
---
@@ -11,7 +12,6 @@ Notifications Webhook v2 目前只能通过 BigPanda 的 REST API 创建和修
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -20,7 +20,7 @@ Notifications Webhook v2 目前只能通过 BigPanda 的 REST API 创建和修
当您不需要将告警路由到不同的协作空间时,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,打开一个协作空间
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**
@@ -35,7 +35,7 @@ Notifications Webhook v2 目前只能通过 BigPanda 的 REST API 创建和修
当您需要根据 Payload 将告警路由到不同的协作空间时,选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**
2. 选择 **BigPanda**,填写集成名称
@@ -48,14 +48,12 @@ Notifications Webhook v2 目前只能通过 BigPanda 的 REST API 创建和修
</div>
## 前提条件
----
- **权限**:调用 Notifications Webhook v2 API 需要账号拥有 **Integrations** 权限;创建 AutoShare 规则需要 **Notifications**(查看、新增、编辑、删除 AutoShare 规则)权限。
- **认证方式**:Notifications Webhook v2 API 目前只接受 **User Account** 的认证信息,Service Account 无法调用。
- 本集成不解析 BigPanda 的固定字段,而是解析下面第二步中您粘贴进请求体的 JSON 模板;请不要修改模板里的字段名。
## 在 BigPanda 中配置
----
<Steps>
<Step title="创建 Notifications Webhook v2 集成">
@@ -120,14 +118,12 @@ Webhook v2 集成创建后本身不会收到任何数据,需要一条 AutoShar
</Steps>
## Alert Key
----
Flashduty 直接使用请求体中的 `incident_id`(来自 BigPanda 模板变量 `{{incident.id}}`)作为 Alert Key。BigPanda 官方文档将 `incident.id` 定义为 Incident 的系统生成唯一标识;同一个 Incident 的新建、更新、关闭共享同一个 `incident.id`。
`status`、`environment`、`host`、`check`、`description`、`url` 的变化都不会改变 Alert Key。
## 状态和告警等级
----
| BigPanda `incident.status` | Flashduty 状态 | Flashduty 告警等级 |
| :--- | :--- | :--- |
@@ -139,7 +135,6 @@ Flashduty 直接使用请求体中的 `incident_id`(来自 BigPanda 模板变
`incident.status` 取 Incident 内所有关联告警中最严重的状态;`unknown` 表示 BigPanda 无法从关联告警判断健康状况,Incident 仍处于未恢复状态,因此按 Warning 处理。空值或未识别的 `status` 会被 Flashduty 拒绝。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -153,7 +148,6 @@ Flashduty 直接使用请求体中的 `incident_id`(来自 BigPanda 模板变
告警标题优先使用 `check`;模板中的 `{{primaryAlert.tags.check}}` 为空时,退回使用 `description`。
## 常见问题
----
<AccordionGroup>
<Accordion title="创建集成后一直没有收到任何请求?">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/bitdefender.mdx b/zh/on-call/integration/alert-integration/alert-sources/bitdefender.mdx
index 08eb7d21..1d403813 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/bitdefender.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/bitdefender.mdx
@@ -1,5 +1,6 @@
---
title: "Bitdefender GravityZone 告警集成"
+sidebarTitle: "Bitdefender GravityZone"
description: "通过 Event Push Service 将 Bitdefender GravityZone 的恶意软件、勒索软件、网络攻击和事件(Incident)检测同步到 Flashduty On-call。"
keywords: ["告警集成", "Bitdefender", "GravityZone", "Event Push Service", "EDR", "安全"]
---
@@ -9,7 +10,6 @@ Bitdefender GravityZone 的 Event Push Service 可以把检测事件以 JSON-RPC
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Bitdefender GravityZone 的 Event Push Service 可以把检测事件以 JSON-RPC
</div>
## 在 GravityZone 中配置
----
Event Push Service 只能通过 GravityZone 公共 API 配置,控制台界面没有对应入口。
@@ -99,12 +98,10 @@ Flashduty 会创建一条 Info 级别、标题为 `Bitdefender GravityZone test
</Steps>
## 开启超时自动关闭
----
检测事件是一次性的,GravityZone 不会推送恢复。请在接收这些告警的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议超时时长为 24 小时,计时起点选择 **故障触发**。同一个威胁在告警未关闭期间再次被检测到,会合并到原有告警;关闭后再次出现,会创建新的告警。
## 支持的事件类型
----
只有下表中的检测类事件会创建告警。状态和资产类事件(如 `modules`、`sva`、`registration`、`task-status`、`install`、`uninstall`、`uc`、`adcloud`)会被忽略,Flashduty 直接返回成功,不建议订阅。
@@ -126,19 +123,16 @@ Flashduty 会创建一条 Info 级别、标题为 `Bitdefender GravityZone test
GravityZone 没有为检测事件公布统一的严重程度,以上等级是根据事件字段作出的映射。如需调整,可在协作空间中按标签配置路由或告警处理规则。
## Alert Key
----
GravityZone 的检测事件没有事件编号,Flashduty 用事件中不会变化的部分计算 Alert Key:`module`、`companyId`、终端编号(`computer_id`,Sandbox Analyzer 为 `endpointId`)以及该类事件的威胁标识,例如 Antimalware 用恶意软件类型、名称和文件路径,Antiphishing 用钓鱼类型和 URL,勒索软件防护用攻击类型和攻击来源。处置状态、计数、时间、哈希、主机名和 IP 的变化不会改变 Alert Key。
事件(Incident)使用 `incident_id`,`new-incident` 与 `new-extended-incident` 共用同一个 Alert Key,同一个事件的版本更新会合并到同一条告警。缺少终端编号或 `incident_id` 的事件会被拒绝。
## 批量推送
----
一次 `addEvents` 请求可以包含多个事件,Flashduty 为每个事件创建一条告警,并按 Alert Key 排序处理。每次请求最多处理 100 个事件,超出部分不会创建告警,并在响应中返回错误。某个事件格式有误时,其余事件仍会创建,响应会返回该事件的序号和原因。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -153,12 +147,10 @@ GravityZone 的检测事件没有事件编号,Flashduty 用事件中不会变
用户名、邮件发件人和收件人、邮件主题、事件节点(`nodes`)不会写入标签或描述。
## 关于签名
----
GravityZone 会在请求头 `Event-Push-Service-Md5` 中带上 `md5(api_key, md5(请求体))`,也可以在 `serviceSettings` 中设置 `authorization` 请求头。Flashduty 不校验这两项,推送地址中的 `integration_key` 是唯一的凭证,请妥善保管。
## 排查问题
----
- **`setPushEventSettings` 返回错误**:确认 API Key 已勾选 Event Push Service API,且 `serviceType` 为 `jsonRPC`
- **Flashduty 没有收到推送**:确认推送地址是公网可访问的 HTTPS 地址且支持 TLS 1.2 以上;GravityZone 要求接收端返回 2xx,否则视为失败
diff --git a/zh/on-call/integration/alert-integration/alert-sources/bleemeo.mdx b/zh/on-call/integration/alert-integration/alert-sources/bleemeo.mdx
index 0a3a5799..97025b6d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/bleemeo.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/bleemeo.mdx
@@ -1,5 +1,6 @@
---
title: "Bleemeo 告警集成"
+sidebarTitle: "Bleemeo"
description: "通过 Webhook 集成将 Bleemeo 的指标状态变化(告警与恢复)同步到 Flashduty On-call。"
keywords: ["告警集成", "Bleemeo", "监控", "Webhook", "状态变化"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Bleemeo", "监控", "Webhook", "状态变化"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Bleemeo", "监控", "Webhook", "状态变化"]
</div>
## 在 Bleemeo 中配置
----
<Steps>
<Step title="添加 Webhook 通知目标">
@@ -56,7 +55,6 @@ keywords: ["告警集成", "Bleemeo", "监控", "Webhook", "状态变化"]
</Steps>
## 推送内容
----
Bleemeo 以 JSON 格式 POST 通知,Flashduty 直接解析,无需配置模板:
@@ -70,14 +68,12 @@ Bleemeo 以 JSON 格式 POST 通知,Flashduty 直接解析,无需配置模
| `status_text` | 状态文本 | 标签 `status_text` |
## Alert Key
----
使用 `metric` 作为 Alert Key。同一个指标的告警通知和恢复通知携带相同的 `metric`,落在同一条告警上;不同指标会生成不同的告警。顶层 `id` 不参与 Alert Key,标题、数值和时间的变化也不会改变 Alert Key。
请求中缺少 `metric` 时,Flashduty 会返回参数错误,因为无法可靠地把恢复通知关联到原告警。
## 状态和告警等级
----
| Bleemeo `status` | Flashduty 状态或等级 |
| :--- | :--- |
@@ -89,7 +85,6 @@ Bleemeo 以 JSON 格式 POST 通知,Flashduty 直接解析,无需配置模
`status` 为空或其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="Bleemeo 的 Webhook 需要什么套餐?">
@@ -112,7 +107,6 @@ Bleemeo 以 JSON 格式 POST 通知,Flashduty 直接解析,无需配置模
</AccordionGroup>
## 排查问题
----
- **测试通知产生了一条 Info 告警**:保存目标后发送的测试通知不带指标,Flashduty 按其固定内容(status 为 `10`、title 为 `Test`)识别,并产生一条独立的 Info 告警,不会自动恢复,请手动关闭
diff --git a/zh/on-call/integration/alert-integration/alert-sources/blueking.mdx b/zh/on-call/integration/alert-integration/alert-sources/blueking.mdx
index d347e740..b197cd9f 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/blueking.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/blueking.mdx
@@ -1,5 +1,6 @@
---
title: "蓝鲸智云集成"
+sidebarTitle: "蓝鲸智云"
description: "通过 webhook 的方式同步蓝鲸智云监控事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "蓝鲸智云集成", "监控告警", "数据接入"]
---
@@ -8,7 +9,6 @@ keywords: ["告警集成", "蓝鲸智云集成", "监控告警", "数据接入"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -16,7 +16,7 @@ keywords: ["告警集成", "蓝鲸智云集成", "监控告警", "数据接入"]
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -32,9 +32,9 @@ keywords: ["告警集成", "蓝鲸智云集成", "监控告警", "数据接入"]
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **蓝鲸智云** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,12 +46,11 @@ keywords: ["告警集成", "蓝鲸智云集成", "监控告警", "数据接入"]
</div>
## 在蓝鲸智云
----
以下内容已经在`蓝鲸V6/7版本`完成验证,V5 及以下版本官方已不再支持,建议您升级。
蓝鲸告警策略可以触发`处理套餐`,处理套餐可与周边系统打通,来完成复杂功能。我们首先创建一个处理套餐,配置 Flashduty 的回调地址,然后编辑告警策略,关联动作到该处理套餐,实现告警变更自动推送到 Flashduty。具体步骤如下:
-#### 步骤 1、创建处理套餐
+### 步骤 1、创建处理套餐
<div className="md-block">
@@ -59,25 +58,25 @@ keywords: ["告警集成", "蓝鲸智云集成", "监控告警", "数据接入"]
2. 进入`配置-处理套餐`页面,单击`添加套餐`按钮,开始创建处理套餐;
3. 填写名称为`Send To Flashduty`,套餐类型选择`HTTP回调`,推送方式选择`POST`,并填写集成的推送地址(保存集成后获得),如下图所示:
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/tencent-bk/create_package.jpg" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/tencent-bk/create_package.jpg" />
4. 切换到`主体`,选择`JSON`类型,消息体复制并填入以下信息(实际产生告警时,蓝鲸会渲染变量内容作为 Payload 推送到目标回调地址):
-```
-{{alarm.callback_message}}
-```
+ ```
+ {{alarm.callback_message}}
+ ```
5. 保存套餐,完成创建。
</div>
-#### 步骤 2、编辑告警策略
+### 步骤 2、编辑告警策略
<div className="md-block">
1. 进入`配置-告警策略`页面,选择一个已有的策略进行编辑,或新建一个告警策略;
2. 下拉到`告警处理`部分,三种场景均选择`Send To Flashduty`处理套餐,并关闭`防御规则`,如下图:
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/tencent-bk/update_alert_rule.jpg" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/tencent-bk/update_alert_rule.jpg" />
3. 提交保存,完成;
4. 对于其他想要推送到 Flashduty 的告警,重复以上步骤。
@@ -85,7 +84,6 @@ keywords: ["告警集成", "蓝鲸智云集成", "监控告警", "数据接入"]
</div>
## 状态对照
----
<div className="md-block">
蓝鲸智云到 Flashduty 告警等级映射关系:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/blumira.mdx b/zh/on-call/integration/alert-integration/alert-sources/blumira.mdx
index b9398683..9917e682 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/blumira.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/blumira.mdx
@@ -1,5 +1,6 @@
---
title: "Blumira 告警集成"
+sidebarTitle: "Blumira"
description: "通过 Blumira Webhook 将安全发现(Finding)的创建和解决事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Blumira", "Webhook", "安全告警", "Finding", "SIEM"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Blumira", "Webhook", "安全告警", "Finding", "SIE
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Blumira", "Webhook", "安全告警", "Finding", "SIE
</div>
## 在 Blumira 中配置
----
<Steps>
<Step title="创建 Webhook">
@@ -74,19 +73,16 @@ keywords: ["告警集成", "Blumira", "Webhook", "安全告警", "Finding", "SIE
</Steps>
## 关于签名
----
Blumira 会在请求头 `X-Blumira-Signature`(格式 `t=<时间戳>,v1=<HMAC-SHA256>`)中带上签名。Flashduty 不校验该签名,也不需要您提供签名密钥;推送地址中的 `integration_key` 是唯一的凭证,请妥善保管。
## Alert Key
----
Flashduty 使用 `data.finding_id` 作为 Alert Key。Blumira 文档中的 `finding.created` 与 `finding.status.changed` 示例携带同一个 `finding_id`,因此触发、状态更新和恢复落在同一条告警上。
标题、优先级、状态和时间的变化不会改变 Alert Key。请求缺少 `data.finding_id` 时 Flashduty 会返回参数错误。
## 状态和告警等级
----
| Blumira 事件 | Flashduty 处理 |
| :--- | :--- |
@@ -108,7 +104,6 @@ Flashduty 只把 `resolved` 视为恢复状态。Blumira 文档只给出了这
告警标签包含 Finding 的 ID、短 ID、类型、分类、优先级、来源国家和链接。负责人和操作人的姓名、邮箱不会写入告警。
## 排查问题
----
- **Blumira 显示投递失败或 Webhook 被自动禁用**:确认推送地址完整且包含 `integration_key`;连续失败的 Webhook 会被 Blumira 自动禁用,修复后在 **Edit** 中重新启用
- **没有收到告警**:确认 Webhook 已启用,并检查事件过滤是否包含 `finding.created`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/bugsnag.mdx b/zh/on-call/integration/alert-integration/alert-sources/bugsnag.mdx
index e17532b1..e1e86066 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/bugsnag.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/bugsnag.mdx
@@ -1,5 +1,6 @@
---
title: "BugSnag 告警集成"
+sidebarTitle: "BugSnag"
description: "通过 Data forwarding 中的 Webhook 将 BugSnag 项目的错误事件同步到 Flashduty On-call。"
keywords: ["告警集成", "BugSnag", "Webhook", "错误监控", "Data forwarding"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "BugSnag", "Webhook", "错误监控", "Data forwardin
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "BugSnag", "Webhook", "错误监控", "Data forwardin
</div>
## 在 BugSnag 中配置
----
Webhook 集成按项目配置,需要项目的管理员权限。每个需要接入的项目都要单独配置一次。
@@ -82,14 +81,12 @@ Webhook 集成按项目配置,需要项目的管理员权限。每个需要接
</Steps>
## Alert Key
----
Flashduty 使用 BugSnag 的错误 ID(`error.errorId`)作为 Alert Key。BugSnag 把同一类异常的多次发生归为一个错误,同一错误的每次发生、频率提醒、重新打开和状态变更都携带同一个 `errorId`,因此会合并到同一条告警,并由该错误的状态变更恢复。
每次发生各自的事件 ID(`error.id`)、错误消息、发布阶段和严重程度变化不会改变 Alert Key。缺少 `errorId` 的错误事件会被拒绝。
## 状态和告警等级
----
Flashduty 按错误的严重程度(`error.severity`)确定告警等级:
@@ -109,7 +106,6 @@ Flashduty 按错误的严重程度(`error.severity`)确定告警等级:
| `errorStateManualChange`,状态变为 `reopened`、`snoozeCancelled`、`unignored` | 触发 |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -128,7 +124,6 @@ Flashduty 按错误的严重程度(`error.severity`)确定告警等级:
| `url` | BugSnag 中该错误的链接 |
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`
- **点击 Test 后没有告警**:这是预期行为,测试请求不会创建告警;请用真实错误验证
diff --git a/zh/on-call/integration/alert-integration/alert-sources/calibre.mdx b/zh/on-call/integration/alert-integration/alert-sources/calibre.mdx
index a28779cd..a176421a 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/calibre.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/calibre.mdx
@@ -1,5 +1,6 @@
---
title: "Calibre 告警集成"
+sidebarTitle: "Calibre"
description: "通过 Calibre 站点 Webhook 将性能预算(Budget)的风险、超标和达标通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Calibre", "性能预算", "Performance Budget", "Webhook", "Core Web Vitals"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Calibre", "性能预算", "Performance Budget", "Web
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Calibre", "性能预算", "Performance Budget", "Web
</div>
## 在 Calibre 中配置
----
<Steps>
<Step title="添加 Webhook">
@@ -60,7 +59,6 @@ Calibre 的 Webhook 没有测试按钮,也可以在 **Synthetic → Settings
</Note>
## 推送内容
----
预算通知的主要字段如下,Flashduty 直接解析,无需配置模板:
@@ -77,14 +75,12 @@ Calibre 的 Webhook 没有测试按钮,也可以在 **Synthetic → Settings
| `budgets` | 各测试配置(Profile)和页面的状态与测量值 | 写入告警描述 |
## Alert Key
----
Flashduty 使用站点标识 `site_id` 和预算 ID `id` 组合出 Alert Key。同一个预算的风险、超标和达标通知使用相同的 Alert Key,落在同一条告警上;不同预算或不同站点生成不同的告警。修改预算名称、状态或测量值不会改变 Alert Key。
请求中缺少 `id` 或 `site_id` 时,Flashduty 会返回参数错误,因为无法可靠地把达标通知关联到原告警。
## 状态和告警等级
----
| Calibre `status` | Flashduty 状态或等级 |
| :--- | :--- |
@@ -95,7 +91,6 @@ Flashduty 使用站点标识 `site_id` 和预算 ID `id` 组合出 Alert Key。
`status` 为空或为其他值的预算通知会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="没有收到预算通知?">
@@ -112,7 +107,6 @@ Calibre 默认不发送预算通知,需要在站点 Webhook 中勾选 Budget n
</AccordionGroup>
## 排查问题
----
- **Calibre 推送失败**:确认 Payload URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求为预算通知,且 `id`、`site_id`、`status` 非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/canarytokens.mdx b/zh/on-call/integration/alert-integration/alert-sources/canarytokens.mdx
index 15c0159d..898e93fd 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/canarytokens.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/canarytokens.mdx
@@ -1,5 +1,6 @@
---
title: "Canarytokens 告警集成"
+sidebarTitle: "Canarytokens"
description: "通过 Webhook 将 Canarytokens(canarytokens.org 或自建)中蜜标被触碰的告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Canarytokens", "Webhook", "蜜标", "Honeytoken", "入侵检测", "安全"]
---
@@ -9,7 +10,6 @@ Canarytokens 是 Thinkst 提供的蜜标服务,可以创建 Web bug、DNS、Wo
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Canarytokens 是 Thinkst 提供的蜜标服务,可以创建 Web bug、DNS、Wo
</div>
## 在 Canarytokens 中配置
----
<Steps>
<Step title="为蜜标填写 Webhook 地址">
@@ -60,7 +59,6 @@ Canarytokens 的告警是一次性事件,不会推送恢复。请在接收这
</Steps>
## 事件类型
----
Canarytokens 每次推送一个 JSON 对象,不推送恢复。
@@ -71,17 +69,14 @@ Canarytokens 每次推送一个 JSON 对象,不推送恢复。
| 保存 Webhook 时的测试请求 | 创建一条独立的 Info 告警,不会恢复 |
## Alert Key
----
Flashduty 使用 `token`(蜜标的固定编号)计算 Alert Key。同一蜜标无论从哪个来源 IP、通过哪个通道被触碰,都使用相同的 Alert Key;备注、来源 IP、时间的变化不会改变它,缺少 `token` 的请求会被拒绝。蜜标暴露通知使用 `token` 加 `key_id`,不会合并到该蜜标的触碰告警。
## 状态和告警等级
----
蜜标没有合法的访问者,任何一次触碰都可能是入侵迹象,因此触碰告警固定为 Critical。暴露通知为 Warning,测试请求为 Info。如需区分不同蜜标的严重程度,可在协作空间中按标签(例如 `token_type`)配置路由或告警处理规则调整等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -97,12 +92,10 @@ Flashduty 使用 `token`(蜜标的固定编号)计算 Alert Key。同一蜜
推送中的 `manage_url` 包含蜜标管理权限的认证参数,Flashduty 不读取、不保存。请到 Canarytokens 的管理页面查看蜜标详情和触碰历史。
## 关于签名
----
Canarytokens 的 Webhook 没有签名机制,请求也没有专用的请求头,Flashduty 不做签名校验。推送地址中的 `integration_key` 是唯一的凭证,请妥善保管。
## 排查问题
----
- **Flashduty 没有收到推送**:确认 Webhook 地址是公网可访问的 HTTPS 或 HTTP 地址,不是内网地址。Canarytokens 请求超时时间为 2 秒,不会重试
- **蜜标的 Webhook 被停用**:Canarytokens 在 Webhook 连续 5 次返回错误后会停用它,需要修正推送地址后重新保存 Webhook;请确认推送地址完整且包含 `integration_key`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/catchpoint.mdx b/zh/on-call/integration/alert-integration/alert-sources/catchpoint.mdx
index 84ad9804..2e8fde28 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/catchpoint.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/catchpoint.mdx
@@ -1,5 +1,6 @@
---
title: "Catchpoint 告警集成"
+sidebarTitle: "Catchpoint"
description: "通过 Alert Webhook 的自定义 Template,将 Catchpoint 测试的告警触发、升级和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Catchpoint", "Alert Webhook", "Template", "TestId"]
---
@@ -11,7 +12,6 @@ Catchpoint 的 Alert Webhook 默认发送的 [JSON 格式](https://docs.catchpoi
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Catchpoint 的 Alert Webhook 默认发送的 [JSON 格式](https://docs.catchpoi
</div>
## 在 Catchpoint 中配置
----
<Steps>
<Step title="创建 Alert Webhook">
@@ -96,7 +95,6 @@ Alert Webhook Endpoint 需要在具体告警上启用才会收到推送:
</Steps>
## Alert Key
----
Flashduty 使用 `test_id`、`alert_group_item_id` 和 `alert_initial_trigger_epoch` 三个字段组合计算 Alert Key。
@@ -105,7 +103,6 @@ Catchpoint 官方发布的 [PagerDuty Events API v2 集成模板](https://docs.c
标题、描述、等级、触发节点数、阈值等字段的变化都不会改变 Alert Key。
## 状态和告警等级
----
Catchpoint 的 `notification_level_id` 共有 4 个官方取值:
@@ -119,7 +116,6 @@ Catchpoint 的 `notification_level_id` 共有 4 个官方取值:
`notification_level_id` 为空或不在以上 4 个值中的请求会被拒绝。Improved 通知本身不携带"从哪个等级恢复"的信息,Flashduty 按 Critical 处理其展示等级,实际状态以恢复(Ok)为准。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 Format 已经切换成 **Template**,且模板是有效 JSON;确认 `test_id`、`alert_group_item_id`、`alert_initial_trigger_epoch` 三个宏都保留在模板里,没有被删除或改成别的宏
- **告警没有触发**:确认对应 Test / Folder / Product 的 **Alerts** 设置里,**API Endpoints** 下拉框已经勾选了这个 Endpoint,或者 Endpoint 上启用了 **Apply to All Alerts**
diff --git a/zh/on-call/integration/alert-integration/alert-sources/cato.mdx b/zh/on-call/integration/alert-integration/alert-sources/cato.mdx
index 2af029e5..fad3afb8 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/cato.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/cato.mdx
@@ -1,5 +1,6 @@
---
title: "Cato Networks 告警集成"
+sidebarTitle: "Cato Networks"
description: "通过 Cato 管理控制台(CMA)的自定义 Body Webhook,将站点运维事件(Site Operations story)和其他告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Cato Networks", "Cato", "SASE", "Webhook", "站点运维"]
---
@@ -9,7 +10,6 @@ Cato Networks 的 Webhook 没有固定的请求体,Body 由用户在 CMA 中
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,14 +30,13 @@ Cato Networks 的 Webhook 没有固定的请求体,Body 由用户在 CMA 中
</div>
## 在 Cato 中配置
----
需要具备在 CMA 中管理订阅(Subscriptions)的权限。
<Steps>
<Step title="新建 Webhook">
-1. 进入 CMA,选择 **Account > Subscriptions**,打开 **Webhooks** 页签,点击 **New Webhook**
+1. 进入 CMA,选择 **Account → Subscriptions**,打开 **Webhooks** 页签,点击 **New Webhook**
2. 填写名称并启用
3. 请求方式选择 **POST**(Create),URL 粘贴 Flashduty 的完整推送地址,地址中需包含 `integration_key`
4. 认证方式选择无需认证即可,`integration_key` 已在地址中
@@ -71,7 +70,7 @@ Body 选择 **Custom**,粘贴以下模板。`${字段:}` 会被 Cato 替换为
<Step title="选择订阅并验证">
-1. 在 **Account > Subscriptions** 中,将该 Webhook 作为需要接收的告警类型(站点运维事件等)的订阅投递目标
+1. 在 **Account → Subscriptions** 中,将该 Webhook 作为需要接收的告警类型(站点运维事件等)的订阅投递目标
2. 点击 Webhook 页面的 **Test**,Cato 文档没有给出测试请求的内容,Flashduty 按普通告警处理;若测试请求不含 `storyId` 与 `correlationId` 会返回参数错误,若含有则产生一条独立告警,请在验证后手动关闭
3. 触发真实事件(如断开测试站点的 Socket),确认 Flashduty 收到活动告警;事件解决后确认该告警恢复
@@ -83,12 +82,10 @@ Body 选择 **Custom**,粘贴以下模板。`${字段:}` 会被 Cato 替换为
</Warning>
## Alert Key
----
Flashduty 使用 `storyId` 作为 Alert Key,`storyId` 为空时使用 `correlationId`。Cato 文档对两者的定义:`storyId` 是 "Unique identifier for the Site Operations story",`correlationId` 是 "Unique identifier used to correlate related events, messages, or operations"。标题、等级、时间的变化不会改变 Alert Key。两者都缺失的请求会被拒绝并提示字段名。
## 状态和告警等级
----
`storyStatus` 为 `RESOLVED`,或 `endDate` 不为空时,告警恢复;`OPEN`、`IN_PROGRESS` 等其他状态为触发或更新。告警等级由 `level` 决定:
@@ -101,7 +98,6 @@ Flashduty 使用 `storyId` 作为 Alert Key,`storyId` 为空时使用 `correla
| 空值或其他值 | Warning |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -116,7 +112,6 @@ Flashduty 使用 `storyId` 作为 Alert Key,`storyId` 为空时使用 `correla
| `isp` | `ISPName` |
## 排查问题
----
- **Cato 测试失败**:确认 URL 完整且包含 `integration_key`,请求方式为 POST
- **Flashduty 返回参数错误**:确认 Body 是合法 JSON,且包含 `storyId` 或 `correlationId`。如果标题或摘要中含有双引号,Cato 替换后可能破坏 JSON,可从模板中去掉 `title` 或 `subject` 字段
diff --git a/zh/on-call/integration/alert-integration/alert-sources/censys.mdx b/zh/on-call/integration/alert-integration/alert-sources/censys.mdx
index 5a7af127..3c0fcabf 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/censys.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/censys.mdx
@@ -1,5 +1,6 @@
---
title: "Censys 告警集成"
+sidebarTitle: "Censys"
description: "通过 Webhook 将 Censys ASM 发现的新风险同步到 Flashduty On-call。"
keywords: ["告警集成", "Censys", "Censys ASM", "Webhook", "攻击面管理", "风险"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Censys", "Censys ASM", "Webhook", "攻击面管理",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Censys", "Censys ASM", "Webhook", "攻击面管理",
</div>
## 在 Censys ASM 中配置
----
Webhook Connection 仅对 Censys ASM 的 Advanced 和 Enterprise 访问级别开放。如果您的防火墙或网关限制来源 IP,请放行 Censys 的出口地址 `52.5.142.59`、`34.226.132.221` 和 `52.54.43.157`。
@@ -67,14 +66,12 @@ Censys 的 Webhook 文档没有提供测试按钮。ASM 在攻击面上发现新
</Steps>
## Alert Key
----
Flashduty 用 `event.data.risk_id`(风险类型 ID)和 `event.data.impacted_asset`(受影响资产,如 `Host: 1.1.1.1`)共同计算 Alert Key。Censys 将风险实例定义为某资产上的某个风险类型,但没有明确说明 `risk_id` 和 `impacted_asset` 在多次推送间保持不变。同一类风险出现在同一个资产上,Alert Key 相同,重复推送会合并到同一条告警;同一类风险出现在不同资产上,或同一资产上出现不同类风险,生成不同的告警。
风险名称、描述、等级、首次和最近发现时间以及事件 ID 的变化不会改变 Alert Key。缺少 `risk_id` 或 `impacted_asset` 的事件会被拒绝。`event.type` 不是 `risk_instance_opened` 的事件不会创建告警,Flashduty 收到后直接返回成功。
## 状态和告警等级
----
所有事件都是触发事件,Flashduty 按 `risk_severity` 确定等级:
@@ -86,7 +83,6 @@ Flashduty 用 `event.data.risk_id`(风险类型 ID)和 `event.data.impacted_
| 空值或其他值 | Warning |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -103,7 +99,6 @@ Flashduty 用 `event.data.risk_id`(风险类型 ID)和 `event.data.impacted_
告警标题由风险描述(`risk_description`,为空时用风险名称)和受影响资产组成。
## 排查问题
----
- **找不到 Webhook Connection**:确认 Censys ASM 的访问级别为 Advanced 或 Enterprise
- **集成不生效**:Censys 要求接收端接受顶层的 `event` 字段,使用 Flashduty 推送地址时无需额外处理
diff --git a/zh/on-call/integration/alert-integration/alert-sources/centreon.mdx b/zh/on-call/integration/alert-integration/alert-sources/centreon.mdx
index 6f54a025..c57f66d0 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/centreon.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/centreon.mdx
@@ -1,5 +1,6 @@
---
title: "Centreon 告警集成"
+sidebarTitle: "Centreon"
description: "通过 Centreon 的 PagerDuty Events 流连接器把主机和服务告警推送到 Flashduty 的 PagerDuty 兼容集成,恢复状态自动关闭告警。"
keywords: ["告警集成", "Centreon", "Stream connector", "PagerDuty", "Broker", "基础设施监控"]
---
@@ -9,7 +10,6 @@ Centreon 自带 PagerDuty Events 流连接器(`pagerduty-events-apiv2.lua`)
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 PagerDuty 兼容**,不是 Centreon。
@@ -30,7 +30,6 @@ Centreon 自带 PagerDuty Events 流连接器(`pagerduty-events-apiv2.lua`)
</div>
## 在 Centreon 中配置
----
### 步骤 1:安装流连接器
@@ -50,19 +49,19 @@ apt install centreon-stream-connector-pagerduty
2. 在 **Output** 标签页选择 **Generic - Stream connector**,点击 **Add**,新增一个输出
3. 按下表填写:
-| 字段 | 值 |
-| :--- | :--- |
-| Name | `Flashduty` |
-| Path | `/usr/share/centreon-broker/lua/pagerduty-events-apiv2.lua` |
-| Filter category | `Neb` |
+ | 字段 | 值 |
+ | :--- | :--- |
+ | Name | `Flashduty` |
+ | Path | `/usr/share/centreon-broker/lua/pagerduty-events-apiv2.lua` |
+ | Filter category | `Neb` |
4. 点击 **Filter category** 表格下方的 **+Add a new entry** 添加以下参数:
-| 类型 | 名称 | 值 |
-| :--- | :--- | :--- |
-| string | `pdy_routing_key` | 上一步推送地址中的 `integration_key` 值(必填参数) |
-| string | `http_server_url` | 完整的推送地址(包含 `integration_key`) |
-| string | `pdy_centreon_url` | 你的 Centreon 服务器地址(可选,用于告警中的链接) |
+ | 类型 | 名称 | 值 |
+ | :--- | :--- | :--- |
+ | string | `pdy_routing_key` | 上一步推送地址中的 `integration_key` 值(必填参数) |
+ | string | `http_server_url` | 完整的推送地址(包含 `integration_key`) |
+ | string | `pdy_centreon_url` | 您的 Centreon 服务器地址(可选,用于告警中的链接) |
5. 部署配置,并在所有轮询器上重启 `centengine`:
@@ -83,7 +82,6 @@ curl -X POST -H 'content-type: application/json' '<推送地址>' -d '{"dedup_ke
Flashduty 应返回 HTTP 202,并出现一条告警;把 `event_action` 改为 `resolve` 再发一次,告警恢复。
## 字段映射
----
Centreon 连接器发出的字段(见连接器源码)与 Flashduty 的对应关系:
@@ -107,14 +105,12 @@ Centreon 连接器发出的字段(见连接器源码)与 Flashduty 的对应
| 服务 UNKNOWN | `error` | Critical |
## 恢复与去重
----
- 同一个主机或服务始终使用同一个 Alert Key,状态从 WARNING 变为 CRITICAL 时更新同一条告警,回到 OK 或 UP 时恢复
- 连接器库的默认参数只发送 HARD 状态,并且不发送已确认(acknowledged)或处于停机维护(downtime)的对象;如需改变,在连接器参数中调整 `hard_only`、`acknowledged`、`in_downtime`
- 只推送部分对象时,使用连接器的过滤参数,例如 `accepted_hostgroups`、`accepted_servicegroups`、`accepted_pollers`
## 排查问题
----
- **Flashduty 没有收到告警**:检查 `/var/log/centreon-broker/pagerduty-events.log`(默认日志文件,`log_level` 最高为 3);确认 `http_server_url` 是完整的推送地址,`pdy_routing_key` 已填写
- **连接器日志显示 POST 失败**:连接器只把 HTTP 202 视为成功,Flashduty 对 PagerDuty Events API v2 请求返回 202;其他状态码请检查 `integration_key` 是否正确
diff --git a/zh/on-call/integration/alert-integration/alert-sources/cert-spotter.mdx b/zh/on-call/integration/alert-integration/alert-sources/cert-spotter.mdx
index ba233367..8e5ebdec 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/cert-spotter.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/cert-spotter.mdx
@@ -1,5 +1,6 @@
---
title: "Cert Spotter 告警集成"
+sidebarTitle: "Cert Spotter"
description: "通过 Webhook 将 Cert Spotter 发现的未知证书同步到 Flashduty On-call。"
keywords: ["告警集成", "Cert Spotter", "SSLMate", "证书透明度", "未授权证书", "Webhook"]
---
@@ -9,7 +10,6 @@ Cert Spotter 是 SSLMate 的证书监控服务,它持续检查证书透明度
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Cert Spotter 是 SSLMate 的证书监控服务,它持续检查证书透明度
</div>
## 在 Cert Spotter 中配置
----
Webhook 通知从 Cert Spotter 的 Startup 套餐开始提供,Hobbyist 套餐只能收邮件。
@@ -59,7 +58,6 @@ Cert Spotter 没有发送测试推送的按钮。可以为一个已在监控中
</Steps>
## 推送内容
----
| Cert Spotter 事件 | 在 Flashduty 中的效果 |
| :--- | :--- |
@@ -69,19 +67,16 @@ Cert Spotter 没有发送测试推送的按钮。可以为一个已在监控中
Cert Spotter 的证书到期提醒和安装问题只通过邮件、Slack 发送,不经过 Webhook,因此不会进入本集成。
## Alert Key
----
Flashduty 使用证书签发记录的 ID(Webhook 中的 `id`)作为 Alert Key。网络问题可能让同一个请求重复送达,重复的请求带有相同的 `id`,会合并到同一条告警;不同的证书会产生不同的告警。
缺少 `id` 的推送会被拒绝。
## 告警等级
----
Cert Spotter 不提供严重程度,所有未知证书都以 **Warning** 等级触发。证书是否已被吊销记录在 `revoked` 标签中,不影响等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -99,7 +94,6 @@ Cert Spotter 不提供严重程度,所有未知证书都以 **Warning** 等级
告警标题为 `Unknown certificate for <第一个监控域名>`,覆盖多个域名时追加 `(+N more)`。
## 常见问题
----
<AccordionGroup>
diff --git a/zh/on-call/integration/alert-integration/alert-sources/cfengine.mdx b/zh/on-call/integration/alert-integration/alert-sources/cfengine.mdx
index 48d964b4..fc2a8830 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/cfengine.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/cfengine.mdx
@@ -1,5 +1,6 @@
---
title: "CFEngine 告警集成"
+sidebarTitle: "CFEngine"
description: "通过 Mission Portal 自定义动作脚本将 CFEngine Enterprise 告警同步到 Flashduty On-call,告警解除时自动关闭。"
keywords: ["告警集成", "CFEngine", "Mission Portal", "Custom action", "自定义动作"]
---
@@ -11,7 +12,6 @@ CFEngine Enterprise 的 Mission Portal 没有 Webhook 通知方式,但告警
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ CFEngine Enterprise 的 Mission Portal 没有 Webhook 通知方式,但告警
</div>
## 在 CFEngine 中配置
----
以下步骤基于 CFEngine Enterprise 3.27。上传和关联自定义动作脚本需要 Mission Portal 的 admin 角色。脚本只依赖 Hub 上的 `bash` 和 `curl`。
@@ -97,7 +96,6 @@ CFEngine 没有「发送测试通知」按钮。要验证真实告警,可以
</Steps>
## Alert Key
----
Flashduty 用 CFEngine 的告警编号 `ALERT_ID` 作为 Alert Key。CFEngine 文档说明它是告警的唯一编号;同一条告警的触发、提醒和解除推送都携带相同的 `ALERT_ID`,因此落在同一条 Flashduty 告警上。告警名称、等级、失败主机数和时间的变化都不会改变 Alert Key。
@@ -106,7 +104,6 @@ Flashduty 用 CFEngine 的告警编号 `ALERT_ID` 作为 Alert Key。CFEngine
请求缺少 `ALERT_ID`,或 `ALERT_STATUS` 不是 `fail` / `success` 时,Flashduty 会拒绝该请求。
## 告警生命周期
----
一条 CFEngine 告警覆盖它定义的所有主机,Flashduty 为它生成一条告警,失败主机数写在描述和标签中。
@@ -117,7 +114,6 @@ Flashduty 用 CFEngine 的告警编号 `ALERT_ID` 作为 Alert Key。CFEngine
| 告警解除 | `success` | 恢复告警 |
## 告警等级
----
告警等级取自创建告警时选择的严重度 `ALERT_SEVERITY`:
@@ -131,7 +127,6 @@ Flashduty 用 CFEngine 的告警编号 `ALERT_ID` 作为 Alert Key。CFEngine
恢复事件保留告警的严重度作为等级。
## 告警内容
----
- **标题**:告警名称 `ALERT_NAME`
- **描述**:条件描述 `ALERT_CONDITION_DESCRIPTION`,以及 `Triggered on <失败主机数> of <主机总数> hosts.`
@@ -140,7 +135,6 @@ Flashduty 用 CFEngine 的告警编号 `ALERT_ID` 作为 Alert Key。CFEngine
时间戳参数(`ALERT_LAST_CHECK`、`ALERT_LAST_EVENT_TIME`、`ALERT_LAST_STATUS_CHANGE`)、`ALERT_STATUS` 和条件描述不写入标签,空值参数也不写入。每条告警最多 50 个标签;标签过多时,按名称排序后超出部分不写入。
## 排查问题
----
- **脚本报 HTTP 4xx**:确认 `FLASHDUTY_URL` 是完整推送地址且包含 `integration_key`
- **Mission Portal 中选不到脚本**:确认当前用户属于 admin 角色,且脚本已在 **Custom notification scripts** 中保存
diff --git a/zh/on-call/integration/alert-integration/alert-sources/check-point-smartevent.mdx b/zh/on-call/integration/alert-integration/alert-sources/check-point-smartevent.mdx
index 78affd21..11139ddb 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/check-point-smartevent.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/check-point-smartevent.mdx
@@ -1,5 +1,6 @@
---
title: "Check Point SmartEvent 告警集成"
+sidebarTitle: "Check Point SmartEvent"
description: "Check Point SmartEvent 的自动响应可以发送邮件,使用 Flashduty 的邮件集成将 SmartEvent 事件接入 Flashduty。"
keywords: ["告警集成", "Check Point", "SmartEvent", "邮件", "Email", "安全事件"]
---
@@ -9,7 +10,6 @@ SmartEvent 的自动响应(Automatic Reaction)提供邮件、SNMP Trap、封
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成邮件地址,任选其一即可。**集成类型都选择邮件 Email**,不是 Check Point。
@@ -29,12 +29,10 @@ SmartEvent 的自动响应(Automatic Reaction)提供邮件、SNMP Trap、封
</div>
## 在 Flashduty 中确认推送模式
----
SmartEvent 每个事件只发一封邮件,没有恢复邮件,标题里带有事件编号(见下文 [邮件标题格式](#邮件标题格式)),每封邮件都是独立的事件。邮件集成的 **推送模式** 选择 **总是触发新告警**(新建集成时页面可能预选了其他模式,请确认):系统为每一封邮件创建一条新告警,标题为邮件标题,描述为邮件内容。不需要配置触发和关闭规则。
## 在 Check Point SmartConsole 中配置
----
以下路径取自 Check Point R81.10 管理指南。
@@ -47,12 +45,10 @@ SmartEvent 每个事件只发一封邮件,没有恢复邮件,标题里带有
7. 保存后,在需要通知的事件定义中引用这个自动响应,并安装策略
## 邮件标题格式
----
Mail 响应的 **Subject** 默认值为 `[EventNumber] - [Severity] - [Name]`,分别是事件编号、严重程度和事件名称。Flashduty 把邮件标题作为告警标题。
## 限制
----
- **没有恢复**:SmartEvent 不发送恢复邮件。请在接收该集成的协作空间开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时,或在 Flashduty 中手动关闭。
- **不去重**:标题含事件编号,每个事件生成一条独立告警。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/checkly.mdx b/zh/on-call/integration/alert-integration/alert-sources/checkly.mdx
index 2493a09c..0bf66bf1 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/checkly.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/checkly.mdx
@@ -1,5 +1,6 @@
---
title: "Checkly 告警集成"
+sidebarTitle: "Checkly"
description: "通过 Webhook Alert Channel 将 Checkly 的失败、性能降级、恢复和 SSL 证书告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Checkly", "Webhook", "合成监控", "API 监控"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Checkly", "Webhook", "合成监控", "API 监控"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Checkly", "Webhook", "合成监控", "API 监控"]
</div>
## 在 Checkly 中配置
----
<Steps>
<Step title="创建 Webhook Alert Channel">
@@ -95,7 +94,6 @@ Checkly 的测试发送或 Webhook HTTP 200 只能证明地址可达,不能证
</Steps>
## Alert Key
----
普通检查状态通知使用去除首尾空格后的 `check_id`(Checkly 变量 `CHECK_ID`)作为 Alert Key。标题、错误、执行区域、响应时间、结果 ID 和告警状态变化都不会改变 Alert Key。
@@ -106,7 +104,6 @@ Checkly 的测试发送或 Webhook HTTP 200 只能证明地址可达,不能证
`ALERT_SSL` 是独立的单次 Warning 事件,即使 Payload 中有 `check_id`,也会使用新的随机 UUID。它不会更新或恢复该 Check 的普通状态告警。
## 状态和告警等级
----
| Checkly `ALERT_TYPE` | Flashduty 状态 | Flashduty 等级 |
| :--- | :--- | :--- |
@@ -120,7 +117,6 @@ Checkly 的测试发送或 Webhook HTTP 200 只能证明地址可达,不能证
空值或未知的 `alert_type` 会返回参数错误。恢复只根据 `alert_type` 判断,与标题或错误文本无关。
## 标签和描述
----
Flashduty 会生成以下标签:
@@ -148,7 +144,6 @@ Flashduty 会生成以下标签:
去除首尾空格后为空的标签值不会写入告警。
## 投递和排查
----
Checkly 对失败的 Webhook 投递最多重试 5 次,每次间隔约 20 秒。可在 Checkly 的 Alert Notification Log 中查看最终投递结果。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/checkmk.mdx b/zh/on-call/integration/alert-integration/alert-sources/checkmk.mdx
index ab852f05..9828b3e9 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/checkmk.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/checkmk.mdx
@@ -1,5 +1,6 @@
---
title: "Checkmk 告警集成"
+sidebarTitle: "Checkmk"
description: "通过通知脚本将 Checkmk 主机和服务的告警通知同步到 Flashduty On-call,问题恢复时自动关闭告警。"
keywords: ["告警集成", "Checkmk", "Check_MK", "通知脚本", "Nagios"]
---
@@ -9,7 +10,6 @@ Checkmk 没有通用 Webhook 通知方式。本集成提供一个通知脚本:
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Checkmk 没有通用 Webhook 通知方式。本集成提供一个通知脚本:
</div>
## 在 Checkmk 中配置
----
以下步骤基于 Checkmk 2.5,其他 2.x 版本菜单名称可能略有不同。脚本只依赖 Checkmk 自带的 Python 3,不需要安装其他软件。
@@ -113,7 +112,6 @@ chmod +x ~/local/share/check_mk/notifications/flashduty
</Steps>
## Alert Key
----
Flashduty 用主机名 `HOSTNAME` 加服务名 `SERVICEDESC` 计算 Alert Key;主机通知的服务名为空。同一个主机或服务的问题和恢复通知携带相同的主机名和服务名,因此落在同一条告警上。状态升到更高等级时(例如服务从 WARN 变为 CRIT),Flashduty 会新建一条更高等级的告警,原告警保持触发;恢复通知会同时关闭这两条告警。
@@ -122,7 +120,6 @@ Flashduty 用主机名 `HOSTNAME` 加服务名 `SERVICEDESC` 计算 Alert Key;
请求缺少 `HOSTNAME`、`WHAT`、当前状态或 `NOTIFICATIONTYPE`,或服务通知缺少 `SERVICEDESC` 时,Flashduty 会拒绝该请求。
## 告警生命周期
----
Checkmk 只在发出过问题通知之后才会发送恢复通知。确认、维护、抖动和自定义通知在问题通知被抑制时(例如服务正在抖动)也会发出,如果用它们打开告警,之后不会有恢复通知来关闭。因此只有问题通知会打开告警,Flashduty 按通知类型 `NOTIFICATIONTYPE` 处理:
@@ -139,7 +136,6 @@ Checkmk 只在发出过问题通知之后才会发送恢复通知。确认、维
被忽略的通知返回成功,Checkmk 不会重试。
## 告警等级
----
告警等级来自当前状态:服务通知取 `SERVICESTATE`,主机通知取 `HOSTSTATE`。
@@ -155,7 +151,6 @@ Checkmk 只在发出过问题通知之后才会发送恢复通知。确认、维
恢复事件的等级取恢复前的硬状态(`PREVIOUSSERVICEHARDSTATE` 或 `PREVIOUSHOSTHARDSTATE`)。
## 告警内容
----
- **标题**:服务通知为 `<服务名> on <主机名>`,主机通知为 `Host <主机名>`
- **描述**:插件输出 `SERVICEOUTPUT` 或 `HOSTOUTPUT`,有长输出时附在后面
@@ -164,7 +159,6 @@ Checkmk 只在发出过问题通知之后才会发送恢复通知。确认、维
每条告警最多 50 个标签;标签过多时,按名称排序后超出部分不写入。联系人姓名、邮箱等联系人信息不会写入标签。
## 排查问题
----
- **Checkmk 界面找不到 Flashduty 方法**:确认脚本位于站点目录的 `local/share/check_mk/notifications/` 下,文件名为 `flashduty`,有执行权限,第二行是 `# Flashduty`
- **通知没有发出**:查看站点的 `var/log/notify.log`,确认规则匹配到了该事件,且 **Recipient** 中的用户没有关闭通知
diff --git a/zh/on-call/integration/alert-integration/alert-sources/chronosphere.mdx b/zh/on-call/integration/alert-integration/alert-sources/chronosphere.mdx
index 7bc671c7..8306d049 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/chronosphere.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/chronosphere.mdx
@@ -1,15 +1,15 @@
---
title: "Chronosphere 告警集成"
+sidebarTitle: "Chronosphere"
description: "通过 Chronosphere 的 Webhook 通知器,使用 Flashduty 的 Prometheus 集成接收 Chronosphere 告警,开启恢复通知后自动关闭告警。"
keywords: ["告警集成", "Chronosphere", "Webhook", "Prometheus", "Alertmanager", "可观测性"]
---
-Chronosphere 的 Webhook 通知器(Notifier)向你填写的 URL 发送 HTTP POST 请求,请求体是 Prometheus Alertmanager 格式的 JSON(`version` 为 `4`,包含 `status`、`alerts`、`fingerprint`、`labels`、`annotations`、`startsAt`、`endsAt`,另有一个 `notifier` 字段)。Flashduty 的 [Prometheus 集成](/zh/on-call/integration/alert-integration/alert-sources/prometheus) 与该格式兼容,因此不需要单独的 Chronosphere 集成:在 Flashduty 创建 Prometheus 集成,把它的推送地址填进 Chronosphere 即可。
+Chronosphere 的 Webhook 通知器(Notifier)向您填写的 URL 发送 HTTP POST 请求,请求体是 Prometheus Alertmanager 格式的 JSON(`version` 为 `4`,包含 `status`、`alerts`、`fingerprint`、`labels`、`annotations`、`startsAt`、`endsAt`,另有一个 `notifier` 字段)。Flashduty 的 [Prometheus 集成](/zh/on-call/integration/alert-integration/alert-sources/prometheus) 与该格式兼容,因此不需要单独的 Chronosphere 集成:在 Flashduty 创建 Prometheus 集成,把它的推送地址填进 Chronosphere 即可。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 Prometheus**,不是 Chronosphere。
@@ -30,7 +30,6 @@ Chronosphere 的 Webhook 通知器(Notifier)向你填写的 URL 发送 HTTP
</div>
## 在 Chronosphere 中配置
----
<Steps>
<Step title="创建 Webhook 通知器">
@@ -59,7 +58,6 @@ Chronosphere 的 Webhook 通知器(Notifier)向你填写的 URL 发送 HTTP
</Steps>
## 字段映射
----
| Chronosphere 字段 | Flashduty |
| :--- | :--- |
@@ -75,7 +73,6 @@ Chronosphere 的 Webhook 通知器(Notifier)向你填写的 URL 发送 HTTP
一次通知可以包含多条告警,Flashduty 逐条处理(单次最多 100 条)。
## 恢复与去重
----
- Chronosphere 发送 `status` 为 `resolved` 的通知时,Flashduty 按相同的 `fingerprint` 关闭对应告警。
- 通知器没有开启恢复通知时,Flashduty 不会收到恢复请求,告警会一直保持活动。此时请在协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit)。
@@ -83,7 +80,6 @@ Chronosphere 的 Webhook 通知器(Notifier)向你填写的 URL 发送 HTTP
- Chronosphere 官方文档没有说明 Webhook 通知器是否有测试发送功能。首次配置后,用一条真实告警验证触发与恢复是否都出现在 Flashduty 中。
## 排查问题
----
- **Flashduty 返回 `Invalid parameters`**:推送地址不完整,缺少 `integration_key`,或集成类型不是 Prometheus
- **告警没有恢复**:确认通知器已选择 **Notify when resolved**(Terraform 的 `send_resolved` 为 `true`、Chronoctl 的 `skip_resolved` 为 `false`),并且恢复通知的 `fingerprint` 与触发时一致
diff --git a/zh/on-call/integration/alert-integration/alert-sources/circonus.mdx b/zh/on-call/integration/alert-integration/alert-sources/circonus.mdx
index 8c6aa67b..0a8b1242 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/circonus.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/circonus.mdx
@@ -1,5 +1,6 @@
---
title: "Circonus 告警集成"
+sidebarTitle: "Circonus"
description: "通过联系组的 Webhook 将 Circonus 规则集的告警和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Circonus", "Webhook", "联系组", "alert_id"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Circonus", "Webhook", "联系组", "alert_id"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Circonus", "Webhook", "联系组", "alert_id"]
</div>
## 在 Circonus 中配置
----
<Steps>
<Step title="在联系组中添加 Webhook">
@@ -63,14 +62,12 @@ https://api.flashcat.cloud/event/push/alert/circonus?integration_key=<your_key>&
</Steps>
## Alert Key
----
Flashduty 使用每条告警的 `alert_id` 作为 Alert Key。Circonus 的告警链接为 `...fault-detection?alert_id=<id>`,恢复通知在原告警的全部字段之外仅追加 `clear_value` 和 `clear_time`,所以触发和恢复携带同一个 `alert_id`。
一次请求的 `alerts` 数组可以包含多条告警,每条告警各生成一个 Flashduty 事件。规则、指标、等级、数值和时间的变化都不会改变 Alert Key。缺少 `alert_id` 的请求会被拒绝,因为无法可靠关联后续恢复。
## 状态和告警等级
----
Circonus 告警等级为 1 到 5,1 最严重。
@@ -84,7 +81,6 @@ Circonus 告警等级为 1 到 5,1 最严重。
带有 `clear_time` 或 `clear_value` 的通知视为恢复,恢复事件保留原等级。请求体中没有 `alerts` 或 `alerts` 为空时,Flashduty 返回成功且不创建告警。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 带有 `&format=json`,且每条告警的 `alert_id` 非空
- **告警没有恢复**:确认联系组已被指定给该规则的对应等级,并且 Circonus 已清除该告警;恢复通知的 `alert_id` 必须与触发时一致
diff --git a/zh/on-call/integration/alert-integration/alert-sources/cloudamqp.mdx b/zh/on-call/integration/alert-integration/alert-sources/cloudamqp.mdx
index 5b6f789e..5b33f0a0 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/cloudamqp.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/cloudamqp.mdx
@@ -1,5 +1,6 @@
---
title: "CloudAMQP 告警集成"
+sidebarTitle: "CloudAMQP"
description: "通过 Webhook 收件人将 CloudAMQP 实例的告警(队列积压、消费者数、CPU、内存、磁盘、连接数等)同步到 Flashduty On-call。"
keywords: ["告警集成", "CloudAMQP", "Webhook", "RabbitMQ", "LavinMQ", "消息队列"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "CloudAMQP", "Webhook", "RabbitMQ", "LavinMQ", "消
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "CloudAMQP", "Webhook", "RabbitMQ", "LavinMQ", "消
</div>
## 在 CloudAMQP 中配置
----
<Steps>
<Step title="添加 Webhook 收件人">
@@ -59,7 +58,6 @@ CloudAMQP 的告警只会发给已指定的收件人。在 **Alarms** 中新建
</Steps>
## 事件类型
----
CloudAMQP 每次推送一个告警对象,请求体为 JSON。
@@ -72,17 +70,14 @@ CloudAMQP 每次推送一个告警对象,请求体为 JSON。
CloudAMQP 在 Webhook 返回非 2xx 时会重试,重复的推送使用同一个 Alert Key,会合并到同一条告警。
## Alert Key
----
Flashduty 使用 `dedup_key` 计算 Alert Key。`dedup_key` 由告警类型和对象组成,例如队列告警为 `queue::<vhost>/<queue>`,同一个对象的触发、提醒和恢复推送使用相同的值。阈值、时间阈值、当前值、主题等字段变化不会改变 Alert Key,缺少 `dedup_key` 的请求会被拒绝。
## 状态和告警等级
----
CloudAMQP 的推送不携带等级,所有告警类型在 Flashduty 中都是 Warning,`resolved` 为 `true` 时恢复。如需区分严重程度,可在 Flashduty 的协作空间中按标签(例如 `alarm_type`)配置路由或告警处理规则调整等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -96,7 +91,6 @@ CloudAMQP 的推送不携带等级,所有告警类型在 Flashduty 中都是 W
| `data_*` | 推送中 `data` 对象的字段,如 `data_value`、`data_name`、`data_type` |
## 排查问题
----
- **Flashduty 没有收到推送**:确认 Webhook 收件人已加入对应告警的 Recipients,并检查告警列表中收件人的状态列是否报错
- **返回参数错误**:确认 URL 完整且包含 `integration_key`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/cloudflare.mdx b/zh/on-call/integration/alert-integration/alert-sources/cloudflare.mdx
index e326949b..fd0158ef 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/cloudflare.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/cloudflare.mdx
@@ -1,5 +1,6 @@
---
title: "Cloudflare 告警事件"
+sidebarTitle: "Cloudflare"
description: "通过 webhook 的方式同步 Cloudflare 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "Cloudflare 告警事件", "监控告警", "数据接入"]
---
@@ -8,7 +9,6 @@ keywords: ["告警集成", "Cloudflare 告警事件", "监控告警", "数据接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -16,7 +16,7 @@ keywords: ["告警集成", "Cloudflare 告警事件", "监控告警", "数据接
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -32,9 +32,9 @@ keywords: ["告警集成", "Cloudflare 告警事件", "监控告警", "数据接
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Cloudflare** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,11 +46,9 @@ keywords: ["告警集成", "Cloudflare 告警事件", "监控告警", "数据接
</div>
## 在 Cloudflare
----
<div className="md-block">
-## 一、告警推送配置
1. 登录您的 `Cloudflare` 控制台,转到 `通知` 菜单中,。
2. 在`Webhooks` 中点击创建。
@@ -60,7 +58,7 @@ keywords: ["告警集成", "Cloudflare 告警事件", "监控告警", "数据接
配置 Webhook 通道后,即可在通知策略中使用。
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/clustercontrol.mdx b/zh/on-call/integration/alert-integration/alert-sources/clustercontrol.mdx
index 64c06e9c..d6e521b3 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/clustercontrol.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/clustercontrol.mdx
@@ -1,5 +1,6 @@
---
title: "ClusterControl 告警集成"
+sidebarTitle: "ClusterControl"
description: "通过 ClusterControl 通知服务(Notification Services)的 Webhook,将 Severalnines ClusterControl 的告警和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "ClusterControl", "Severalnines", "Notification Services", "Webhook", "数据库运维", "cmon-events"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "ClusterControl", "Severalnines", "Notification Servi
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "ClusterControl", "Severalnines", "Notification Servi
</div>
## 在 ClusterControl 中配置
----
<Steps>
<Step title="添加 Webhook 集成">
@@ -62,7 +61,6 @@ ClusterControl 只对集成创建之后产生的告警发送通知,此前已
</Warning>
## 推送内容
----
ClusterControl 以 JSON 格式 POST 以下字段,Flashduty 直接解析,无需配置模板:
@@ -80,7 +78,6 @@ ClusterControl 以 JSON 格式 POST 以下字段,Flashduty 直接解析,无
告警标题使用 `title`;为空时使用 `ClusterControl alarm <id>`。
## Alert Key
----
Flashduty 使用告警 `id` 作为 Alert Key。ClusterControl 文档说明,告警恢复时会发送同一个告警 ID、`status` 为 `ENDED` 的通知,因此产生、更新和恢复通知落在同一条 Flashduty 告警上;不同 `id` 生成不同的告警。修改标题、主机或等级不会改变 Alert Key。
@@ -89,7 +86,6 @@ Flashduty 使用告警 `id` 作为 Alert Key。ClusterControl 文档说明,告
请求中缺少 `id` 时,Flashduty 会返回参数错误,因为无法可靠地把恢复通知关联到原告警。
## 状态和告警等级
----
| ClusterControl 字段 | Flashduty 状态或等级 |
| :--- | :--- |
@@ -101,7 +97,6 @@ Flashduty 使用告警 `id` 作为 Alert Key。ClusterControl 文档说明,告
`status` 为空或为其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。ClusterControl 默认只转发 `CREATED` 和 `ENDED`;`CHANGED` 需要通过 `cmon-events` 的 `allowed_events` 参数开启。
## 常见问题
----
<AccordionGroup>
<Accordion title="点击 Test credentials 后 ClusterControl 提示失败?">
@@ -124,7 +119,6 @@ ClusterControl 中被静音的告警类型在取消静音前不会发送任何
</AccordionGroup>
## 排查问题
----
- **Flashduty 没有收到告警**:确认 URL 是完整的推送地址(含 `integration_key`),并检查 `cmon-events` 进程运行正常、已为对应集群和事件开启通知
- **Flashduty 返回参数错误**:确认请求体为 ClusterControl 的 JSON,且 `id`、`status` 非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/consul.mdx b/zh/on-call/integration/alert-integration/alert-sources/consul.mdx
index 99b620af..e425e175 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/consul.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/consul.mdx
@@ -1,5 +1,6 @@
---
title: "HashiCorp Consul 告警集成"
+sidebarTitle: "HashiCorp Consul"
description: "通过 Consul Agent 的 checks 类型 Watch 和 HTTP handler,将 Consul 健康检查的异常和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Consul", "HashiCorp Consul", "Watch", "健康检查", "http_handler_config"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "Consul", "HashiCorp Consul", "Watch", "健康检查"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -20,7 +20,7 @@ keywords: ["告警集成", "Consul", "HashiCorp Consul", "Watch", "健康检查"
当您不需要将告警路由到不同的协作空间时,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,打开一个协作空间
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**
@@ -35,7 +35,7 @@ keywords: ["告警集成", "Consul", "HashiCorp Consul", "Watch", "健康检查"
当您需要根据 Payload 将告警路由到不同的协作空间时,选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**
2. 选择 **HashiCorp Consul**,填写集成名称
@@ -48,7 +48,6 @@ keywords: ["告警集成", "Consul", "HashiCorp Consul", "Watch", "健康检查"
</div>
## 工作方式
----
Consul 的 `checks` 类型 Watch 在任意一个被监听的健康检查发生变化时(包括状态和输出内容的变化),把**所有**被监听检查的当前状态作为一个 JSON 数组 POST 到推送地址。Flashduty 把数组中的每个检查转换为一个事件:
@@ -59,14 +58,12 @@ Consul 的 `checks` 类型 Watch 在任意一个被监听的健康检查发生
Watch 加载后会立即发送一次当前状态,所以已经处于 `warning` 或 `critical` 的检查会马上产生告警。
## 前提条件
----
- **网络**:运行 Watch 的 Consul Agent 需要能访问 Flashduty 推送地址(如 `https://api.flashcat.cloud`)。
- **权限**:需要能修改该 Agent 的配置目录(例如 `/etc/consul.d`)并执行 `consul reload`。
- **ACL**:如果开启了 ACL,Watch 使用的 Token 需要有全部节点和服务的读权限,见下方步骤。
## 在 Consul 中配置
----
<Steps>
<Step title="选择运行 Watch 的 Agent">
@@ -149,7 +146,6 @@ curl -X PUT http://127.0.0.1:8500/v1/agent/check/deregister/flashduty-test
</Steps>
## Alert Key
----
Flashduty 使用 `Partition`、`Node` 和 `CheckID` 共同生成 Alert Key。
@@ -162,7 +158,6 @@ Flashduty 使用 `Partition`、`Node` 和 `CheckID` 共同生成 Alert Key。
Watch 只返回所在数据中心的检查,且 Payload 中不含数据中心名称。多个数据中心使用同一个集成时,如果不同数据中心有同名节点,这些节点上相同 ID 的检查会合并为同一条告警。建议每个数据中心使用一个单独的集成。
## 状态和告警等级
----
| Consul `Status` | Flashduty 状态 | Flashduty 告警等级 |
| :--- | :--- | :--- |
@@ -173,7 +168,6 @@ Watch 只返回所在数据中心的检查,且 Payload 中不含数据中心
检查在 `warning` 和 `critical` 之间变化时,Flashduty 按告警等级分别建立告警:`warning` 变为 `critical` 会新建一条 Critical 告警,`passing` 会同时恢复两条告警。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -190,7 +184,6 @@ Watch 只返回所在数据中心的检查,且 Payload 中不含数据中心
告警标题为 `<检查名称> on <节点名>`,告警描述为检查的 `Output` 和 `Notes`。
## 常见问题
----
<AccordionGroup>
<Accordion title="检查或节点被删除后,告警没有恢复怎么办?">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/contrast.mdx b/zh/on-call/integration/alert-integration/alert-sources/contrast.mdx
index de8bbf92..8f80e1ab 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/contrast.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/contrast.mdx
@@ -1,5 +1,6 @@
---
title: "Contrast Security 告警集成"
+sidebarTitle: "Contrast Security"
description: "通过 Generic Webhook 将 Contrast Security 的新漏洞、漏洞关闭、服务器离线等事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Contrast Security", "Webhook", "漏洞", "应用安全", "IAST"]
---
@@ -11,7 +12,6 @@ Contrast 的 Generic Webhook 没有固定的推送格式,推送内容由您在
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Contrast 的 Generic Webhook 没有固定的推送格式,推送内容由您在
</div>
## 在 Contrast Security 中配置
----
<Steps>
<Step title="添加 Generic Webhook">
@@ -67,7 +66,6 @@ Contrast 会把 `$` 开头的变量替换为实际值后以 POST 发送。请不
</Steps>
## 事件和 Alert Key
----
| Contrast 事件 | `event_type` | 在 Flashduty 中的效果 | Alert Key 使用的字段 |
| :--- | :--- | :--- | :--- |
@@ -81,7 +79,6 @@ Contrast 会把 `$` 开头的变量替换为实际值后以 POST 发送。请不
服务器离线和最后一行的事件没有对应的恢复事件,请在集成或协作空间中配置 **超时自动关闭**(例如 24 小时),否则需要手动关闭。
## 告警等级
----
按 `$Severity` 映射:
@@ -95,7 +92,6 @@ Contrast 会把 `$` 开头的变量替换为实际值后以 POST 发送。请不
漏洞被关闭时告警恢复,等级保留关闭事件中的严重程度。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -110,7 +106,6 @@ Contrast 会把 `$` 开头的变量替换为实际值后以 POST 发送。请不
| `organization` / `organization_id` | 组织名称和 ID |
## 排查问题
----
- **Contrast 提示 Webhook 已断开**:Flashduty 返回了非 2XX 响应。检查 URL 是否包含 `integration_key`,Payload 是否为上文的模板且是合法 JSON,然后在 Contrast 中重新测试并保存
- **告警没有恢复**:确认 Contrast 中该漏洞的状态为 Closed 类状态。其他状态变化(如 Confirmed、Suspicious)不会推送事件
diff --git a/zh/on-call/integration/alert-integration/alert-sources/coralogix.mdx b/zh/on-call/integration/alert-integration/alert-sources/coralogix.mdx
index 6127cdb6..217b7411 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/coralogix.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/coralogix.mdx
@@ -1,5 +1,6 @@
---
title: "Coralogix 告警集成"
+sidebarTitle: "Coralogix"
description: "通过 Notification Center 的 Generic HTTPS 连接器,将 Coralogix 告警的触发和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Coralogix", "Notification Center", "Generic HTTPS", "groupingKey"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Coralogix", "Notification Center", "Generic HTTPS",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Coralogix", "Notification Center", "Generic HTTPS",
</div>
## 在 Coralogix 中配置
----
以下步骤需要 Notification Center 的管理权限(创建连接器、预设和路由器,编辑告警定义的标签)。
@@ -101,7 +100,6 @@ keywords: ["告警集成", "Coralogix", "Notification Center", "Generic HTTPS",
</Steps>
## Alert Key
----
Flashduty 直接使用 `alert.groupingKey` 作为 Alert Key。Coralogix 在告警通知的字段说明中将 `groupingKey` 定义为去重键,其官方 Opsgenie 和 Jira Service Management 配置也在 `Resolved` 时用 `groupingKey` 关闭对应的告警。
@@ -110,7 +108,6 @@ Flashduty 直接使用 `alert.groupingKey` 作为 Alert Key。Coralogix 在告
标题、描述、优先级和分组取值的变化都不会改变 Alert Key。
## 状态和告警等级
----
Flashduty 根据 `status` 判断触发或恢复,根据 `priority`(`alert.highestPriority`,缺省时取告警定义的优先级)确定告警等级。
@@ -126,7 +123,6 @@ Flashduty 根据 `status` 判断触发或恢复,根据 `priority`(`alert.hig
`status` 为 `Resolved` 时,Flashduty 恢复原告警,并保留最后一次的告警等级。空值或其他 `status` 会被拒绝。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -142,7 +138,6 @@ Flashduty 根据 `status` 判断触发或恢复,根据 `priority`(`alert.hig
单条告警最多 50 个标签,超出时请求会被拒绝。
## 排查问题
----
- **Coralogix 显示投递失败**:确认连接器 URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认预设 Body 与上文一致,渲染结果是有效 JSON,`grouping_key` 和 `status` 非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/coroot.mdx b/zh/on-call/integration/alert-integration/alert-sources/coroot.mdx
index 0bfd10bf..31d15d0c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/coroot.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/coroot.mdx
@@ -1,5 +1,6 @@
---
title: "Coroot 告警集成"
+sidebarTitle: "Coroot"
description: "通过 Webhook 将 Coroot 的告警(Alert)和 SLO 事件(Incident)的触发、恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Coroot", "Webhook", "Incident", "Alert", "可观测性"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Coroot", "Webhook", "Incident", "Alert", "可观测
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Coroot", "Webhook", "Incident", "Alert", "可观测
</div>
## 在 Coroot 中配置
----
<Steps>
<Step title="创建 Webhook 集成">
@@ -76,7 +75,6 @@ Coroot 只对已开启通知的类别发送 Webhook。
</Steps>
## Alert Key
----
Flashduty 使用 Coroot 通知中 `url` 字段携带的 ID 作为 Alert Key:
@@ -88,7 +86,6 @@ Flashduty 使用 Coroot 通知中 `url` 字段携带的 ID 作为 Alert Key:
每个 Coroot 告警和事件在创建时生成唯一 ID,打开和恢复通知使用同一个 ID。同一条规则在同一个应用上再次触发会生成新的 ID,因此是一条新的 Flashduty 告警。严重程度、规则名称、摘要和 `url` 的域名变化都不会改变 Alert Key。
## 状态和告警等级
----
Coroot 只在告警或事件打开、恢复时发送通知;打开后严重程度变化不会再通知。
@@ -104,7 +101,6 @@ Coroot 只在告警或事件打开、恢复时发送通知;打开后严重程
- 无法识别的 `status` 按 Warning 处理,避免 Flashduty 返回错误后 Coroot 暂停后续通知
## 标签
----
| 标签 | 含义 |
| :--- | :--- |
@@ -117,7 +113,6 @@ Coroot 只在告警或事件打开、恢复时发送通知;打开后严重程
| 自定义字段 | 集成中配置的 Custom fields |
## 排查问题
----
<AccordionGroup>
<Accordion title="Coroot 日志出现 failed to send alert ... 400">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/cronicle.mdx b/zh/on-call/integration/alert-integration/alert-sources/cronicle.mdx
index 8c6816f8..e66290b1 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/cronicle.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/cronicle.mdx
@@ -1,5 +1,6 @@
---
title: "Cronicle 告警集成"
+sidebarTitle: "Cronicle"
description: "通过 Cronicle 的事件 Web Hook,将定时任务失败和启动失败同步到 Flashduty On-call,下一次成功执行时自动恢复。"
keywords: ["告警集成", "Cronicle", "定时任务", "任务调度", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Cronicle", "定时任务", "任务调度", "Webhook"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Cronicle", "定时任务", "任务调度", "Webhook"
</div>
## 在 Cronicle 中配置
----
<Steps>
<Step title="填写 Web Hook URL">
@@ -61,7 +60,6 @@ Cronicle 在任务开始和结束时都会发送 HTTP POST 请求(JSON 格式
</Steps>
## 推送内容
----
Cronicle 以 JSON 格式 POST 以下字段,Flashduty 直接解析,无需配置模板:
@@ -80,12 +78,10 @@ Cronicle 以 JSON 格式 POST 以下字段,Flashduty 直接解析,无需配
请求体中还包含事件参数 `params` 和 Web Hook 地址 `web_hook`,Flashduty 不读取也不保存这两项。
## Alert Key
----
Flashduty 使用 `event`(事件 ID)作为 Alert Key。同一事件的每次任务都携带相同的 `event`,只有任务 ID `id` 每次不同,因此同一事件的失败、启动失败和后续成功会落在同一条告警上。修改事件标题、退出码或执行服务器不会改变 Alert Key。
## 状态和告警等级
----
Cronicle 的通知不区分告警等级,定时任务失败按 Critical 处理:
@@ -99,7 +95,6 @@ Cronicle 的通知不区分告警等级,定时任务失败按 Critical 处理
Cronicle 的 Web Hook 没有测试按钮;需要验证连通性时,运行一次事件即可。
## 常见问题
----
<AccordionGroup>
<Accordion title="任务设置了失败重试,会在每次重试失败时都收到通知吗?">
@@ -122,7 +117,6 @@ Web Hook URL 可以设置在单个事件或分类上,只在需要的位置填
</AccordionGroup>
## 排查问题
----
- **Cronicle 没有推送**:确认 Web Hook URL 是包含 `integration_key` 的完整推送地址,并把 `debug_level` 调到 9,在 Cronicle 日志中查看 `Web Hook Error` 和 `Web Hook Response` 记录
- **Flashduty 返回参数错误**:确认请求体包含 `action`、`event`,且 `job_complete` 通知包含 `code`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/cronitor.mdx b/zh/on-call/integration/alert-integration/alert-sources/cronitor.mdx
index 3c3309d0..185060d3 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/cronitor.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/cronitor.mdx
@@ -1,5 +1,6 @@
---
title: "Cronitor 告警集成"
+sidebarTitle: "Cronitor"
description: "通过 Webhook 将 Cronitor 监控的告警和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Cronitor", "Cron", "心跳监控", "Webhook"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "Cronitor", "Cron", "心跳监控", "Webhook"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ keywords: ["告警集成", "Cronitor", "Cron", "心跳监控", "Webhook"]
</div>
## 在 Cronitor 中配置
----
<Steps>
<Step title="创建 Webhook 集成">
@@ -70,7 +69,6 @@ Cronitor 推荐用一个心跳监控测试告警:
</Steps>
## 推送内容
----
Cronitor 以 JSON 格式推送以下字段:
@@ -90,7 +88,6 @@ Cronitor 以 JSON 格式推送以下字段:
告警标题使用问题名称;为空时依次使用监控名称、监控 key。每条告警还带有标签 `source=cronitor`。
## Alert Key
----
Flashduty 使用监控 key(`id`)和环境(`environment`)一起生成 Alert Key:
@@ -103,7 +100,6 @@ Flashduty 使用监控 key(`id`)和环境(`environment`)一起生成 Ale
修改监控 key,或删除后重新创建监控,会得到新的 Alert Key,与旧告警不再关联。
## 状态和告警等级
----
Cronitor 的 Webhook 不携带严重程度,Flashduty 按下表映射:
@@ -115,7 +111,6 @@ Cronitor 的 Webhook 不携带严重程度,Flashduty 按下表映射:
`type` 不区分大小写。缺少 `id`、`type` 为空或为其他值的请求会被拒绝。
## 常见问题
----
<AccordionGroup>
<Accordion title="监控持续失败时会重复推送吗?">
@@ -134,7 +129,6 @@ Cronitor 的 Webhook 不携带严重程度,Flashduty 按下表映射:
</AccordionGroup>
## 排查问题
----
- **Flashduty 返回参数错误**:确认推送地址完整(包含 `integration_key`),请求体中有 `id` 和 `type` 字段
- **收不到任何通知**:确认监控关联的通知列表中选中了该 Webhook,且通知列表的生效环境包含告警所在环境
diff --git a/zh/on-call/integration/alert-integration/alert-sources/crowdsec.mdx b/zh/on-call/integration/alert-integration/alert-sources/crowdsec.mdx
index e5cc1884..36133cb3 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/crowdsec.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/crowdsec.mdx
@@ -1,5 +1,6 @@
---
title: "CrowdSec 告警集成"
+sidebarTitle: "CrowdSec"
description: "通过 HTTP 通知插件将 CrowdSec Security Engine 检测到的攻击来源同步到 Flashduty On-call。"
keywords: ["告警集成", "CrowdSec", "Security Engine", "入侵防护", "IPS", "HTTP 通知插件", "Webhook"]
---
@@ -9,7 +10,6 @@ CrowdSec Security Engine 是开源、可自建的入侵检测与防护引擎。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ CrowdSec Security Engine 是开源、可自建的入侵检测与防护引擎。
</div>
## 在 CrowdSec 中配置
----
以下操作在运行 CrowdSec 本地 API(LAPI)的机器上完成。HTTP 通知插件随 CrowdSec 一起安装,无需另装。
@@ -98,24 +97,20 @@ Flashduty 中会出现一条标题为 `test alert`、等级为 Info 的告警。
</Steps>
## 推送内容
----
CrowdSec 每次请求推送一个 JSON 数组,每个元素是一条告警;启用 `group_wait` 或 `group_threshold` 后,CrowdSec 会攒到下一次推送时机再发出,推送最多比检测晚 `group_wait`,一个请求可能包含多条。Flashduty 为数组中的每个元素创建一条告警。事件明细(`events`)和 `meta` 中的原始日志不会进入 Flashduty。
## Alert Key
----
Flashduty 使用 CrowdSec 为每条告警生成的 `uuid` 作为 Alert Key。请求重试时会带相同的 `uuid`,合并到同一条告警;同一个来源 IP 后续再次触发,会是新的 `uuid`,产生新的告警。
个别没有 `uuid` 的旧版本,Flashduty 用场景、来源类型、来源值和 `start_at` 计算 Alert Key。这些字段缺失时请求会被拒绝。
## 告警等级
----
CrowdSec 不提供严重程度,所有告警都以 **Warning** 等级触发,处于模拟模式(`simulated`)的告警也是。`cscli notifications test` 发出的测试告警为 **Info**,并使用独立的 Alert Key,不会与真实告警合并。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -136,7 +131,6 @@ CrowdSec 不提供严重程度,所有告警都以 **Warning** 等级触发,
告警标题为 `<场景> from <来源值>`,描述为 CrowdSec 的 `message`。
## 常见问题
----
<AccordionGroup>
diff --git a/zh/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale.mdx b/zh/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale.mdx
index b2063b81..29a3eefa 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale.mdx
@@ -1,5 +1,6 @@
---
title: "CrowdStrike Falcon LogScale 告警集成"
+sidebarTitle: "CrowdStrike Falcon LogScale"
description: "通过 Falcon LogScale(原 Humio)触发器的 Webhook Action,把命中查询的日志告警同步到 Flashduty On-call。"
keywords: ["告警集成", "CrowdStrike", "Falcon LogScale", "Humio", "Webhook Action", "Trigger"]
---
@@ -12,7 +13,6 @@ Falcon LogScale(原 Humio)用 **Trigger(触发器)** 描述一条持续
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -33,7 +33,6 @@ Falcon LogScale(原 Humio)用 **Trigger(触发器)** 描述一条持续
</div>
## 在 Falcon LogScale 中配置
----
<Steps>
<Step title="创建 Webhook Action">
@@ -75,7 +74,6 @@ LogScale 触发器只会触发,不会发送任何“已恢复”的通知,
</Steps>
## 推送内容
----
Flashduty 按 LogScale 自动生成的默认 Message Body Template 解析请求体,请求体为 `application/json`:
@@ -115,7 +113,6 @@ Flashduty 按 LogScale 自动生成的默认 Message Body Template 解析请求
请不要修改默认模板里这些字段的名称或位置;模板允许添加更多变量,但 Flashduty 只读取上表列出的字段,多余字段会被忽略。
## Alert Key
----
Flashduty 直接使用 `alert.id`(LogScale 官方文档中定义的 Trigger ID)作为 Alert Key:
@@ -124,12 +121,10 @@ Flashduty 直接使用 `alert.id`(LogScale 官方文档中定义的 Trigger ID
- 缺少 `alert.id` 的请求会被拒绝
## 状态和告警等级
----
LogScale 的默认模板不携带任何告警等级字段,所有告警统一为 Warning。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么告警不会自动恢复?">
@@ -152,7 +147,6 @@ LogScale 的触发器是单向的:查询命中就触发关联的 Action,条
</AccordionGroup>
## 排查问题
----
- **点击 Test action 显示 Problem invoking test action**:这通常是因为测试时模板里的 `{id}` 等字段还没有真实值,Flashduty 拒绝了空 `alert.id`;用真实查询命中触发一次即可验证
- **Flashduty 没有收到告警**:确认 Action 的 URL 完整(包含 `integration_key`),且该 Action 已关联到触发器
diff --git a/zh/on-call/integration/alert-integration/alert-sources/crowdstrike.mdx b/zh/on-call/integration/alert-integration/alert-sources/crowdstrike.mdx
index 40fa1431..48a0fe71 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/crowdstrike.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/crowdstrike.mdx
@@ -1,5 +1,6 @@
---
title: "CrowdStrike Falcon 告警集成"
+sidebarTitle: "CrowdStrike Falcon"
description: "通过 CrowdStrike Falcon Fusion SOAR 工作流的 Cloud HTTP Request 动作,把 EPP / NG-SIEM 检测推送到 Flashduty On-call。"
keywords: ["告警集成", "CrowdStrike", "Falcon", "Fusion SOAR", "EDR", "NG-SIEM", "Webhook"]
---
@@ -9,7 +10,6 @@ CrowdStrike Falcon 没有内置的通用告警 webhook:检测通知通过 **Fa
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ CrowdStrike Falcon 没有内置的通用告警 webhook:检测通知通过 **Fa
</div>
## 在 CrowdStrike Falcon 中配置
----
以下操作需要能在 Falcon 控制台创建和发布(Release)Fusion SOAR 工作流的权限;NG-SIEM 检测触发器需要开通 Next-Gen SIEM 模块,EPP 检测触发器需要 Falcon Insight/Prevent 端点检测能力。Falcon 云端需要能访问推送地址所在的域名。
@@ -85,7 +84,6 @@ Fusion 会把 `${...}` 的值原样填入 JSON 字符串,未发现官方提供
</Steps>
## Alert Key
----
Flashduty 使用请求体中的 `detection_id` 作为 Alert Key。这个字段对应 Falcon Fusion 触发器变量 `${data['Trigger.Detection.DetectionID']}`——CrowdStrike 官方 Fusion 工作流开发参考称其为"release-verified"(工作流发布时会校验这个路径存在),NG-SIEM 与 EPP 两种检测触发器都会给出这个字段,同一次检测在两种触发器下返回相同格式的复合 ID。
@@ -97,7 +95,6 @@ Flashduty 使用请求体中的 `detection_id` 作为 Alert Key。这个字段
Falcon Fusion 没有携带检测 ID 的"检测已关闭"触发器,因此本集成是一次性事件:Flashduty 不会因为检测在 Falcon 中被关闭而自动关闭告警。**请给对应的协作空间开启[超时自动关闭](/zh/on-call/channel/create-edit),安全类检测建议 24 小时**;同一检测在超时内再次触发会刷新同一条告警。
## 告警等级
----
| CrowdStrike `severity`(SeverityDisplayName) | Flashduty 等级 |
| :--- | :--- |
@@ -109,7 +106,6 @@ Falcon Fusion 没有携带检测 ID 的"检测已关闭"触发器,因此本集
| (空) | **Warning** |
## 告警内容
----
- **标题**:`name`(检测名称),缺失时使用 `CrowdStrike detection`
- **标签**:`detection_id`、`product`(`NGSIEM` 或 `EPP`)、`severity_raw`(原始 `severity` 值);NG-SIEM 模板另带 `source_url`;EPP 模板另带 `resource`/`host`(`hostname`)、`process_sha256`、`ioc_value`、`ioc_type`
@@ -117,11 +113,10 @@ Falcon Fusion 没有携带检测 ID 的"检测已关闭"触发器,因此本集
值为空的字段不会写入标签。
## 排查问题
----
- **工作流没有报错但 Flashduty 没收到告警**:确认工作流已点击 **Release** 发布,而不是仅保存草稿——草稿状态的工作流不会执行
- **HTTP Action 报错,日志中出现 400**:检查请求体字段名是否与上文模板完全一致;响应内容会指出缺失或不支持的字段(例如 `detection_id is required`)
-- **HTTP Action 提示 "unknown variable" / "property ... contains unknown variable"**:说明这个变量路径在你的检测类型/触发器下不可用,用 Falcon 控制台的变量选择器确认该触发器实际能取到的字段,替换成可用路径
+- **HTTP Action 提示 "unknown variable" / "property ... contains unknown variable"**:说明这个变量路径在您的检测类型/触发器下不可用,用 Falcon 控制台的变量选择器确认该触发器实际能取到的字段,替换成可用路径
- **告警一直不关闭**:本集成不会收到关闭事件,请按上文「Alert Key」一节开启超时自动关闭
参阅 CrowdStrike 官方资料:[Build API integrations with Falcon Fusion SOAR HTTP Actions](https://www.crowdstrike.com/tech-hub/ng-siem/build-api-integrations-with-falcon-fusion-soar-http-actions/)、CrowdStrike 官方 GitHub [fusion-skills](https://github.com/CrowdStrike/fusion-skills)(工作流触发器与 HTTP Action 的字段参考)。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/ctyun.mdx b/zh/on-call/integration/alert-integration/alert-sources/ctyun.mdx
index d82ff498..524ebfbe 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/ctyun.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/ctyun.mdx
@@ -1,5 +1,6 @@
---
title: "天翼云告警事件"
+sidebarTitle: "天翼云"
description: "通过 webhook 的方式同步天翼云告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "天翼云告警事件", "监控告警", "数据接入"]
---
@@ -10,7 +11,6 @@ keywords: ["告警集成", "天翼云告警事件", "监控告警", "数据接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -18,7 +18,7 @@ keywords: ["告警集成", "天翼云告警事件", "监控告警", "数据接
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -34,9 +34,9 @@ keywords: ["告警集成", "天翼云告警事件", "监控告警", "数据接
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **天翼云** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -48,11 +48,9 @@ keywords: ["告警集成", "天翼云告警事件", "监控告警", "数据接
</div>
## 在天翼云
----
<div className="md-block">
-## 一、天翼云告警推送配置
1. 登录您的 `天翼云` 控制台,检索 `云监控服务` 产品,并进入对应产品控制台。
2. 在 `告警服务` 中,选择 `告警联系人/组`,并完成创建相应的告警联系人/组。
@@ -64,7 +62,7 @@ keywords: ["告警集成", "天翼云告警事件", "监控告警", "数据接
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
@@ -74,7 +72,7 @@ keywords: ["告警集成", "天翼云告警事件", "监控告警", "数据接
| 警示 | Warning | 警告 |
| 普通 | Info | 提醒 |
-## 三、天翼云二级节点列表<span id="二级节点"></span>
+## 天翼云二级节点列表<span id="二级节点"></span>
| 地区 | 城市 |
| ---------- | -------- |
diff --git a/zh/on-call/integration/alert-integration/alert-sources/cubeapm.mdx b/zh/on-call/integration/alert-integration/alert-sources/cubeapm.mdx
index 3a2fb1c9..80020ac5 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/cubeapm.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/cubeapm.mdx
@@ -1,5 +1,6 @@
---
title: "CubeAPM 告警集成"
+sidebarTitle: "CubeAPM"
description: "通过 CubeAPM 的 Webhook 接收器,使用 Flashduty 的 Prometheus 集成接收 CubeAPM 告警,恢复时自动关闭告警。"
keywords: ["告警集成", "CubeAPM", "Webhook", "Prometheus", "Alertmanager", "可观测性"]
---
@@ -9,7 +10,6 @@ CubeAPM 支持把告警通知以 HTTP POST 的方式发送到任意 Webhook URL
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 Prometheus**,不是 CubeAPM。
@@ -30,7 +30,6 @@ CubeAPM 支持把告警通知以 HTTP POST 的方式发送到任意 Webhook URL
</div>
## 在 CubeAPM 中配置
----
<Steps>
<Step title="创建 Webhook 接收器">
@@ -49,7 +48,6 @@ CubeAPM 文档说明,Webhook 的 JSON 请求体默认与 Alertmanager 格式
</Steps>
## 字段映射
----
| CubeAPM 字段 | Flashduty |
| :--- | :--- |
@@ -65,13 +63,11 @@ CubeAPM 文档说明,Webhook 的 JSON 请求体默认与 Alertmanager 格式
一次通知可以包含多条告警,Flashduty 逐条处理(单次最多 100 条)。
## 恢复与去重
----
- CubeAPM 发送 `status` 不为 `firing`(例如 `resolved`)的通知时,Flashduty 按相同的 `fingerprint` 关闭对应告警。CubeAPM 官方的 PagerDuty 与 Zenduty 对接示例也是据此把非 `firing` 状态映射为恢复。
- CubeAPM 文档没有说明 Webhook 是否有测试发送功能。首次配置后,用一条真实告警验证触发与恢复是否都出现在 Flashduty 中。
## 排查问题
----
- **Flashduty 返回 `Invalid parameters`**:推送地址不完整,缺少 `integration_key`,或集成类型不是 Prometheus
- **告警没有恢复**:确认自定义 Payload 中每条告警的 `status` 和 `fingerprint` 都存在,且恢复通知的 `fingerprint` 与触发时一致
diff --git a/zh/on-call/integration/alert-integration/alert-sources/dash0.mdx b/zh/on-call/integration/alert-integration/alert-sources/dash0.mdx
index ed3db016..d63f4be0 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/dash0.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/dash0.mdx
@@ -1,5 +1,6 @@
---
title: "Dash0 告警集成"
+sidebarTitle: "Dash0"
description: "通过 Webhook 通知渠道将 Dash0 Check Rule 的触发和恢复事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Dash0", "Check Rule", "Webhook", "issueIdentifier"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Dash0", "Check Rule", "Webhook", "issueIdentifier"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Dash0", "Check Rule", "Webhook", "issueIdentifier"]
</div>
## 在 Dash0 中配置
----
<Steps>
<Step title="创建 Webhook 通知渠道">
@@ -56,14 +55,12 @@ keywords: ["告警集成", "Dash0", "Check Rule", "Webhook", "issueIdentifier"]
</Steps>
## Alert Key
----
Flashduty 直接使用 `data.issue.issueIdentifier` 作为 Alert Key。Dash0 官方将其定义为“Check Rule 与资源的组合的标识,在不同的 Issue 实例之间保持稳定”,因此触发、更新和恢复携带同一个值。
`data.issue.id` 是单个 Issue 实例的 ID,`data.issue.checkrules[].id` 是 Check Rule 的 ID,二者都只作为标签,不参与 Alert Key。标题、状态、描述、开始时间和 Check Rule 版本的变化都不会改变 Alert Key。缺少 `issueIdentifier` 的告警类型请求会被拒绝,因为无法可靠关联后续恢复。
## 事件类型和告警等级
----
| Dash0 `type` | Flashduty 处理 |
| :--- | :--- |
@@ -82,7 +79,6 @@ Flashduty 直接使用 `data.issue.issueIdentifier` 作为 Alert Key。Dash0 官
Dash0 未公开说明 `alert.closed` 和 `alert.superseded` 的具体语义。Flashduty 按保守方式处理:`closed` 视为 Issue 已结束,`superseded` 认为同一标识随后会有新的 `alert.ongoing`,因此不改变告警状态。
## 排查问题
----
- **Dash0 返回非 2xx**:确认推送地址完整且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求体是有效 JSON,且 `data.issue.issueIdentifier` 非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/datadog.mdx b/zh/on-call/integration/alert-integration/alert-sources/datadog.mdx
index e0651902..64ca6a0a 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/datadog.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/datadog.mdx
@@ -1,5 +1,6 @@
---
title: "Datadog 告警集成"
+sidebarTitle: "Datadog"
description: "通过 Webhook 将 Datadog Monitor 告警同步到 Flashduty On-call,并正确关联告警触发、更新和恢复。"
keywords: ["告警集成", "Datadog", "Webhook", "Monitor", "告警恢复"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Datadog", "Webhook", "Monitor", "告警恢复"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
### 使用专属集成
@@ -17,7 +17,7 @@ keywords: ["告警集成", "Datadog", "Webhook", "Monitor", "告警恢复"]
当您不需要将告警路由到不同的协作空间时,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,打开一个协作空间
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**
@@ -32,7 +32,7 @@ keywords: ["告警集成", "Datadog", "Webhook", "Monitor", "告警恢复"]
当您需要根据 Payload 将告警路由到不同的协作空间时,选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**
2. 选择 **Datadog**,填写集成名称
@@ -45,7 +45,6 @@ keywords: ["告警集成", "Datadog", "Webhook", "Monitor", "告警恢复"]
</div>
## 在 Datadog 中配置 Webhook
----
<Steps>
<Step title="创建 Webhook">
@@ -123,7 +122,6 @@ Datadog 的测试通知可以验证 Webhook 是否可达,但只有真实触发
</Steps>
## 增加自定义标签
----
默认 Payload 已包含常用的环境、服务、团队和地域标签。如果还需要传递其他 Datadog 变量,请在 Payload 顶层增加 `custom_labels` 对象:
@@ -152,7 +150,6 @@ Datadog 的测试通知可以验证 Webhook 是否可达,但只有真实触发
</Warning>
## Alert Key
----
Flashduty 优先使用 `$ALERT_CYCLE_KEY` 作为 Alert Key。Datadog 将该字段定义为从告警触发到恢复期间关联事件的 ID,因此重复通知和恢复事件会更新同一条 Flashduty 告警。
@@ -161,7 +158,6 @@ Flashduty 优先使用 `$ALERT_CYCLE_KEY` 作为 Alert Key。Datadog 将该字
`$ID`、`$ALERT_ID`、`$AGGREG_KEY`、标题、等级、时间和自定义标签都不会参与 Alert Key 计算。
## 状态和告警等级
----
恢复状态只根据 `$ALERT_TRANSITION` 判断,与等级映射相互独立。
@@ -177,7 +173,6 @@ Flashduty 优先使用 `$ALERT_CYCLE_KEY` 作为 Alert Key。Datadog 将该字
如需调整等级,可通过[告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines)重新映射。
## 排查问题
----
- **Datadog 没有发送请求**:确认 Monitor 通知消息包含正确的 `@webhook-<name>`
- **Flashduty 返回参数错误**:确认 Payload 是有效 JSON,并且包含非空的 `alert_transition`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/datto-rmm.mdx b/zh/on-call/integration/alert-integration/alert-sources/datto-rmm.mdx
index 1ad3f46d..d38c4dd1 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/datto-rmm.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/datto-rmm.mdx
@@ -1,5 +1,6 @@
---
title: "Datto RMM 告警集成"
+sidebarTitle: "Datto RMM"
description: "通过 Datto RMM 的 Webhook 将设备告警的触发和自动恢复事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Datto RMM", "Webhook", "alert_uid", "RMM"]
---
@@ -11,7 +12,6 @@ Datto RMM 的 Webhook 请求体由您自己编写,因此需要把下文提供
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Datto RMM 的 Webhook 请求体由您自己编写,因此需要把下文提供
</div>
## 在 Datto RMM 中配置
----
Datto RMM 有两种配置位置:单个监控器(Monitor)的响应设置,或全局 Webhook。**开启全局 Webhook 会自动停用所有监控器上单独设置的 Webhook**,请二选一。
@@ -107,12 +106,10 @@ Datto RMM 有两种配置位置:单个监控器(Monitor)的响应设置,
</Steps>
## Alert Key
----
Flashduty 使用 `alert_uid`(Datto RMM 变量 `[alert_uid]`,文档定义为 "The alert ID")作为 Alert Key。触发和恢复 Payload 使用同一个变量,因此对应同一条告警。设备、站点、告警类型、消息和等级的变化都不会改变 Alert Key。
## 状态和告警等级
----
| `event` | Flashduty 状态 |
| :--- | :--- |
@@ -127,12 +124,10 @@ Flashduty 使用 `alert_uid`(Datto RMM 变量 `[alert_uid]`,文档定义为
| 空值或其他值 | Warning |
## 关于恢复
----
Datto RMM 只在告警被**自动**解决时发送恢复 Payload;在控制台手动解决告警不会发送任何请求。请在接收这些告警的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议时长 24 小时,避免手动解决的告警一直保持未恢复。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 Payload 是有效 JSON,`alert_uid` 非空,`event` 为 `triggered` 或 `resolved`
- **告警没有恢复**:确认已开启 **When alert is resolved (optional)** 并使用了 `resolved` 模板;手动解决的告警不会发送恢复
diff --git a/zh/on-call/integration/alert-integration/alert-sources/db-pull.mdx b/zh/on-call/integration/alert-integration/alert-sources/db-pull.mdx
index 17bdd072..916e4393 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/db-pull.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/db-pull.mdx
@@ -1,5 +1,6 @@
---
title: "数据库拉取告警 (DB Pull)"
+sidebarTitle: "数据库拉取 (DB Pull)"
description: "Flashduty 按周期主动查询 MySQL、PostgreSQL 或 ClickHouse 数据库,将符合条件的行转换为标准告警事件;适用于告警数据已写入关系型数据库、无法主动推送的场景。"
keywords: ["告警集成", "DB Pull", "数据库", "MySQL", "PostgreSQL", "ClickHouse", "拉取", "轮询", "数据接入"]
---
@@ -13,12 +14,11 @@ DB Pull 适合 **告警数据已落入关系型数据库**、**无法或不希
<div className="hide">
## 操作步骤
----
### 在 Flashduty
<AccordionGroup>
-<Accordion title="使用专属集成">
+<Accordion title="查看专属集成的配置步骤">
当您不需要根据告警内容路由到不同的协作空间时,优先选择此方式,更简单。
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面。
@@ -27,7 +27,7 @@ DB Pull 适合 **告警数据已落入关系型数据库**、**无法或不希
4. 按下文「配置项」说明填写表单,点击 **保存**。
</Accordion>
-<Accordion title="使用共享集成">
+<Accordion title="查看共享集成的配置步骤">
当您需要根据告警事件的 Payload 信息,将告警路由到不同协作空间时,优先选择此方式。
1. 进入 Flashduty 控制台,选择 **集成中心 ⇒ 告警事件**,进入集成选择页面。
@@ -40,7 +40,6 @@ DB Pull 适合 **告警数据已落入关系型数据库**、**无法或不希
</div>
## 配置项
----
### 数据库驱动
@@ -147,14 +146,12 @@ LIMIT <page_size>
```
## 默认路由
----
新增「共享集成」时必须配置默认路由,否则拉取到的事件将被丢弃。集成创建后可在 **路由** 中追加更细粒度的规则。
「专属集成」(在某个协作空间的 **配置 → 集成数据 → 专属集成** 中创建)会自动绑定到所在空间,不需要单独配置默认路由。
## 注意事项
----
- **数据库账号权限**:建议为 DB Pull 单独创建只读账号,仅授予目标表的 `SELECT` 权限,禁止写入权限,降低安全风险。
- **网络可达性**:Flashduty 服务端必须能够通过公网或专线访问到数据库的 `host:port`。私有网段(`10.x.x.x`、`192.168.x.x`、`172.16~31.x.x`)和回环地址会被系统拒绝连接。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/dbmarlin.mdx b/zh/on-call/integration/alert-integration/alert-sources/dbmarlin.mdx
index c07dbdbb..108a5f7c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/dbmarlin.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/dbmarlin.mdx
@@ -1,5 +1,6 @@
---
title: "DBmarlin 告警集成"
+sidebarTitle: "DBmarlin"
description: "通过 DBmarlin 的 Webhook 集成把数据库实例和主机的告警开始与结束事件同步到 Flashduty On-call。"
keywords: ["告警集成", "DBmarlin", "数据库监控", "Webhook"]
---
@@ -11,7 +12,6 @@ DBmarlin 的 Webhook 没有固定格式,请求体由您在 **Content Template*
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ DBmarlin 的 Webhook 没有固定格式,请求体由您在 **Content Template*
</div>
## 在 DBmarlin 中配置
----
Webhook 集成需要 DBmarlin v5.11 及以上版本,创建的 Webhook 默认标记为 **Default** 且已启用,告警由它发出。
@@ -109,7 +108,6 @@ Webhook 集成需要 DBmarlin v5.11 及以上版本,创建的 Webhook 默认
</Steps>
## Alert Key
----
Flashduty 用规则 ID(`ruleid`)加实例名(`instance`)或主机名(`node`)计算 Alert Key,实例告警和主机告警互不相同。同一规则在同一实例或主机上的“开始”和“结束”共用一个 Alert Key;`from`、`to`、数值和规则名称的变化不会改变它。
@@ -117,7 +115,6 @@ Flashduty 用规则 ID(`ruleid`)加实例名(`instance`)或主机名(`
- 同一规则再次触发时,使用同一个 Alert Key
## 状态和告警等级
----
| DBmarlin `startedended` | Flashduty 状态或等级 |
| :--- | :--- |
@@ -127,12 +124,10 @@ Flashduty 用规则 ID(`ruleid`)加实例名(`instance`)或主机名(`
Webhook 请求体不带告警等级,因此所有告警按 Warning 处理。DBmarlin 发送的 `startedended` 为大写(`STARTED`、`ENDED`),Flashduty 不区分大小写,把以 `end` 开头的值当作结束,其余值按开始处理。
## 恢复与自动关闭
----
DBmarlin 在告警结束时发送“结束”通知,Flashduty 据此恢复告警。为避免通知丢失导致告警一直打开,建议在协作空间或集成上配置 **超时自动关闭**,时长大于您规则可能持续的最长时间。
## 排查问题
----
- **DBmarlin 日志出现 `status code 400`**:确认模板是合法 JSON,且包含 `ruleid`,以及 `instance`(实例告警)或 `node`(主机告警)
- **出现 `404` 或 `401`**:确认 Webhook URL 完整并包含 `integration_key`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/dead-mans-snitch.mdx b/zh/on-call/integration/alert-integration/alert-sources/dead-mans-snitch.mdx
index 511e0311..3794caf6 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/dead-mans-snitch.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/dead-mans-snitch.mdx
@@ -1,5 +1,6 @@
---
title: "Dead Man's Snitch 告警集成"
+sidebarTitle: "Dead Man's Snitch"
description: "通过 Webhook 将 Dead Man's Snitch 的 Snitch 缺失、出错和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Dead Man's Snitch", "Cron", "心跳监控", "Webhook"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "Dead Man's Snitch", "Cron", "心跳监控", "Webhook
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ keywords: ["告警集成", "Dead Man's Snitch", "Cron", "心跳监控", "Webhook
</div>
## 在 Dead Man's Snitch 中配置
----
<Steps>
<Step title="添加 Webhook 集成">
@@ -67,7 +66,6 @@ keywords: ["告警集成", "Dead Man's Snitch", "Cron", "心跳监控", "Webhook
</Steps>
## 推送内容
----
Dead Man's Snitch 以 JSON 格式推送以下字段:
@@ -84,7 +82,6 @@ Dead Man's Snitch 以 JSON 格式推送以下字段:
告警标题为 Snitch 名称加状态说明,例如 `Nightly Backup is missing`;名称为空时使用 `Snitch`。每条告警还带有标签 `source=dead-mans-snitch`。
## Alert Key
----
token 是 Snitch 的签到凭据,任何持有它的人都可以向 Snitch 签到。因此 Flashduty 不在告警中展示 token,而是用 token 的 MD5 值作为 Alert Key:
@@ -94,7 +91,6 @@ token 是 Snitch 的签到凭据,任何持有它的人都可以向 Snitch 签
token 在 Snitch 的整个生命周期中不变。上一条告警恢复后,同一 Snitch 再次缺失会生成一条新告警,不会重新打开已恢复的告警。删除后重新创建 Snitch 会得到新的 token,与旧告警不再关联。
## 状态和告警等级
----
Dead Man's Snitch 的 Webhook 不携带严重程度,Flashduty 按下表映射:
@@ -108,7 +104,6 @@ Dead Man's Snitch 的 Webhook 不携带严重程度,Flashduty 按下表映射
`type` 不区分大小写。缺少 `data.snitch.token`、`type` 为空或为其他值的请求会被拒绝。
## 常见问题
----
<AccordionGroup>
<Accordion title="Snitch 持续缺失时会重复推送吗?">
@@ -131,7 +126,6 @@ Dead Man's Snitch 的 FAQ 说明邮件告警会在每个缺失周期重复发送
</AccordionGroup>
## 排查问题
----
- **Flashduty 返回参数错误**:确认推送地址完整(包含 `integration_key`),请求体中有 `type` 和 `data.snitch.token` 字段
- **收不到任何通知**:确认账户计划包含集成功能;如果 Webhook 设置了标签过滤,确认 Snitch 带有其中一个标签
diff --git a/zh/on-call/integration/alert-integration/alert-sources/dependency-track.mdx b/zh/on-call/integration/alert-integration/alert-sources/dependency-track.mdx
index a568b938..8b2fe147 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/dependency-track.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/dependency-track.mdx
@@ -1,5 +1,6 @@
---
title: "Dependency-Track 告警集成"
+sidebarTitle: "Dependency-Track"
description: "通过 Outbound Webhook 将 Dependency-Track 发现的新漏洞、带漏洞的新依赖和策略违规同步到 Flashduty On-call。"
keywords: ["告警集成", "Dependency-Track", "Webhook", "SBOM", "漏洞", "策略违规", "软件供应链"]
---
@@ -17,7 +18,6 @@ Dependency-Track 只在发现问题时通知一次,不会在问题修复后再
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -38,7 +38,6 @@ Dependency-Track 只在发现问题时通知一次,不会在问题修复后再
</div>
## 在 Dependency-Track 中配置
----
<Steps>
<Step title="创建通知规则">
@@ -76,7 +75,6 @@ Outbound Webhook 使用内置的默认模板,以 `Content-Type: application/js
</Steps>
## Alert Key
----
Flashduty 用通知里的 `uuid` 组合出 Alert Key,各部分之间用不可见分隔符连接后取 MD5:
@@ -93,7 +91,6 @@ Flashduty 用通知里的 `uuid` 组合出 Alert Key,各部分之间用不可
- 缺少项目、组件、漏洞或策略违规的 `uuid` 时,Flashduty 返回 400 并指出缺少的字段
## 状态和告警等级
----
NEW_VULNERABILITY 取 `subject.vulnerability.severity`,NEW_VULNERABLE_DEPENDENCY 取其中最严重的漏洞:
@@ -112,21 +109,18 @@ POLICY_VIOLATION 不带漏洞,按策略的违规状态(Violation State)判
| `INFO` 或其他值 | Info |
## 告警不会自动恢复
----
Dependency-Track 对每个问题只通知一次,没有“漏洞已修复”或“策略违规已解除”的通知,所以所有这些告警都保持打开,直到被关闭。请在接收该集成的协作空间中开启[超时自动关闭](/zh/on-call/channel/create-edit),时长按团队处理漏洞的时效设定,例如 7 天。
同一个问题再次推送(例如重新分析后再次发现同一漏洞)会合并到仍然打开的同一条告警;告警被关闭后再次推送,会创建新的告警。
## 告警内容
----
- **标题**:NEW_VULNERABILITY 为 `Dependency-Track: <漏洞 ID> in <组件> (<项目>)`;NEW_VULNERABLE_DEPENDENCY 为 `Dependency-Track: vulnerable dependency <组件> in <项目> (<N> vulnerabilities)`;POLICY_VIOLATION 为 `Dependency-Track: policy violation <策略名> on <组件> (<项目>)`
- **描述**:通知内容,项目和组件,以及漏洞的来源、严重程度、CVSS 评分、别名和修复建议(带漏洞的新依赖最多列出 10 个,按严重程度排序);策略违规则列出策略、违规类型和条件
- **标签**:`source=dependency_track`、`group`、`project_uuid`、`project_name`、`project_version`、`component_uuid`、`component_group`、`component_name`、`component_version`、`component_purl`、`vuln_id`、`vuln_source`、`vuln_uuid`、`vuln_severity`、`vuln_count`、`vuln_ids`、`policy_name`、`violation_type`、`violation_state`、`violation_uuid`
## 排查问题
----
<AccordionGroup>
<Accordion title="规则保存了,但 Flashduty 没有收到任何请求">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/dingtalk-alert.mdx b/zh/on-call/integration/alert-integration/alert-sources/dingtalk-alert.mdx
index 350ca7c4..50694de7 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/dingtalk-alert.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/dingtalk-alert.mdx
@@ -1,5 +1,6 @@
---
title: "钉钉机器人兼容集成"
+sidebarTitle: "钉钉机器人兼容"
description: "Flashduty 生成钉钉自定义机器人格式的 Webhook 地址。已在向钉钉自定义机器人推送告警的工具,把地址改为它即可将告警的发生与恢复接入 Flashduty。"
keywords: ["告警集成", "钉钉", "监控告警", "数据接入", "钉钉机器人兼容", "钉钉自定义机器人"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "钉钉", "监控告警", "数据接入", "钉钉机
<div className="hide">
## 操作步骤
----
### 创建钉钉机器人兼容集成
@@ -18,7 +18,7 @@ keywords: ["告警集成", "钉钉", "监控告警", "数据接入", "钉钉机
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -33,9 +33,9 @@ keywords: ["告警集成", "钉钉", "监控告警", "数据接入", "钉钉机
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **钉钉机器人兼容** 集成:
- **集成名称**:为当前集成定义一个名称。
- **消息类型**:选择钉钉告警消息类型,目前仅支持 Text、Markdown。
@@ -76,12 +76,10 @@ keywords: ["告警集成", "钉钉", "监控告警", "数据接入", "钉钉机
- 当钉钉消息类型是Text 时,Flashduty On-call 会生成默认告警标题 “钉钉告警”。
## 严重程度映射关系
----
当前钉钉机器人兼容集成推送到 Flashduty 的严重程度均为Warning,但您可以通过[告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines) 来自定义严重程度。
## 阿里云账号消息中心
----
<div className="md-block">
阿里云账号消息中心的"机器人接收"支持将账户、产品、安全等通知推送到自定义 Webhook,其数据格式可以复用钉钉机器人协议,能直接对接本页的钉钉机器人兼容集成。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/dkron.mdx b/zh/on-call/integration/alert-integration/alert-sources/dkron.mdx
index 865990e2..0e6396cc 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/dkron.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/dkron.mdx
@@ -1,5 +1,6 @@
---
title: "Dkron 告警集成"
+sidebarTitle: "Dkron"
description: "通过 Dkron 的 Webhook 通知,将定时任务的失败和恢复事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Dkron", "定时任务", "Webhook", "cron"]
---
@@ -9,7 +10,6 @@ Dkron 在每次任务执行结束后,都可以向一个 Webhook 地址发送
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Dkron 在每次任务执行结束后,都可以向一个 Webhook 地址发送
</div>
## 在 Dkron 中配置
----
Dkron 没有固定格式的 Webhook 请求体,而是按您配置的 `webhook-payload` Go 模板渲染后发送。Flashduty 只解析下面这份模板产生的字段,请原样使用。Webhook 是 Dkron 服务端的全局配置,对所有任务生效;它在选出的 Leader 节点上、每个任务执行结束(重试次数用完后)时发送一次,成功和失败都会发送。
@@ -70,12 +69,10 @@ webhook-payload: '{"job_name":{{printf "%q" .JobName}},"success":{{.Success}},"n
</Steps>
## Alert Key
----
Flashduty 使用任务名 `job_name`(Dkron 的 `JobName`)作为 Alert Key。Dkron 中任务名是任务的唯一标识,同一个任务的每次执行结果,无论成功或失败,都带有相同的任务名,所以失败和之后的成功会落在同一条告警上。节点、开始和结束时间、成功与否的变化都不会改变 Alert Key。
## 状态和告警等级
----
| Dkron 的执行结果 | Flashduty 状态或等级 |
| :--- | :--- |
@@ -85,7 +82,6 @@ Flashduty 使用任务名 `job_name`(Dkron 的 `JobName`)作为 Alert Key。
Dkron 不提供告警等级,任务失败一律按 Critical 处理。`success` 为空或不是 `true`、`false` 时请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 告警标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -95,7 +91,6 @@ Dkron 不提供告警等级,任务失败一律按 Critical 处理。`success`
| `started_at`、`finished_at` | 本次执行的开始和结束时间 |
## 排查问题
----
- **Flashduty 没有收到告警**:Dkron 只在日志里记录 Webhook 的发送错误,不会重发。确认服务端能访问 `api.flashcat.cloud`,推送地址完整且包含 `integration_key`
- **Dkron 日志出现 `notifier: error parsing template`**:`webhook-payload` 模板有语法错误,对照上面的模板检查引号和花括号
diff --git a/zh/on-call/integration/alert-integration/alert-sources/dolphinscheduler.mdx b/zh/on-call/integration/alert-integration/alert-sources/dolphinscheduler.mdx
index 7849b50a..8bae945a 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/dolphinscheduler.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/dolphinscheduler.mdx
@@ -1,5 +1,6 @@
---
title: "Apache DolphinScheduler 告警集成"
+sidebarTitle: "Apache DolphinScheduler"
description: "通过 DolphinScheduler 的 HTTP 告警插件,把工作流实例的失败、成功和超时通知同步到 Flashduty On-call。"
keywords: ["告警集成", "DolphinScheduler", "海豚调度", "工作流", "Webhook", "任务调度"]
---
@@ -11,7 +12,6 @@ Apache DolphinScheduler 的工作流实例结束或超时时,会把通知发
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Apache DolphinScheduler 的工作流实例结束或超时时,会把通知发
</div>
## 在 DolphinScheduler 中配置
----
<Steps>
<Step title="创建 HTTP 告警实例">
@@ -41,14 +40,14 @@ Apache DolphinScheduler 的工作流实例结束或超时时,会把通知发
2. **选择插件** 选 `Http`,填写 **告警实例名称**
3. 按下表填写插件参数:
-| 参数 | 取值 |
-| :--- | :--- |
-| URL | Flashduty 集成的完整推送地址(含 `integration_key`) |
-| 请求方式 | `POST` |
-| 请求头 | 留空 |
-| 请求体 | `{"content":"${msg}"}` |
-| Content Type | `application/json` |
-| 超时时间(秒) | 默认 120 |
+ | 参数 | 取值 |
+ | :--- | :--- |
+ | URL | Flashduty 集成的完整推送地址(含 `integration_key`) |
+ | 请求方式 | `POST` |
+ | 请求头 | 留空 |
+ | 请求体 | `{"content":"${msg}"}` |
+ | Content Type | `application/json` |
+ | 超时时间(秒) | 默认 120 |
4. 保存。DolphinScheduler 服务端需要能访问公网上的 Flashduty。
@@ -82,7 +81,6 @@ Apache DolphinScheduler 的工作流实例结束或超时时,会把通知发
</Steps>
## 告警恢复和自动关闭
----
DolphinScheduler 按工作流实例结束时的状态发送通知:
@@ -99,7 +97,6 @@ DolphinScheduler 按工作流实例结束时的状态发送通知:
子工作流的状态不会单独通知。
## 告警类型
----
一次请求的 `content` 数组中可以有多个告警对象,每个对象对应一条 Flashduty 告警。
@@ -111,7 +108,6 @@ DolphinScheduler 按工作流实例结束时的状态发送通知:
告警组中如果还收到不带工作流信息的告警(例如服务下线),Flashduty 会拒绝(返回参数错误)。如果不想在 DolphinScheduler 中看到发送失败,请为本集成单独建立告警组。
## Alert Key
----
| 告警类型 | Alert Key |
| :--- | :--- |
@@ -122,7 +118,6 @@ DolphinScheduler 按工作流实例结束时的状态发送通知:
工作流实例名称、状态、运行次数、时间的变化不会改变 Alert Key。同一个实例的失败和后续成功使用同一个 Alert Key,所以成功会恢复失败。缺少 `projectCode` 或 `workflowInstanceId` 的告警对象会使整个请求被拒绝。
## 状态和告警等级
----
| 来源 | 状态 | 等级 |
| :--- | :--- | :--- |
@@ -131,7 +126,6 @@ DolphinScheduler 按工作流实例结束时的状态发送通知:
| 超时 | 触发 | Warning |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -149,7 +143,6 @@ DolphinScheduler 按工作流实例结束时的状态发送通知:
| `task_code` / `task_name` | 任务编码、任务名称(任务超时) |
## 排查问题
----
- **Flashduty 没有收到事件**:确认工作流启动时选了告警组且通知策略不是 **都不发**;确认告警组包含该告警实例;确认推送地址完整且包含 `integration_key`。在告警实例的创建或编辑对话框中点击 **测试发送** 可以验证网络
- **Flashduty 返回参数错误**:多半是 **请求体** 没有写成 `{"content":"${msg}"}`,或收到了不带工作流信息的告警(例如服务下线)
diff --git a/zh/on-call/integration/alert-integration/alert-sources/domotz.mdx b/zh/on-call/integration/alert-integration/alert-sources/domotz.mdx
index e73e91c9..437130c2 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/domotz.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/domotz.mdx
@@ -1,5 +1,6 @@
---
title: "Domotz 告警集成"
+sidebarTitle: "Domotz"
description: "通过 Webhook 联系渠道,将 Domotz Alert Rule 的设备与采集器状态、TCP 服务、延迟等通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Domotz", "Webhook", "网络监控", "MSP"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "Domotz", "Webhook", "网络监控", "MSP"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ keywords: ["告警集成", "Domotz", "Webhook", "网络监控", "MSP"]
</div>
## 在 Domotz 中配置
----
需要在 Domotz 门户中有创建联系渠道和 Alert Rule 的权限。
@@ -71,12 +70,10 @@ keywords: ["告警集成", "Domotz", "Webhook", "网络监控", "MSP"]
</Warning>
## Alert Key
----
Alert Rule 通知(`monitoring_profile_state_changed`)的 Alert Key 由事件名称和 `alert_id` 组成。同一次异常的 Problem 通知和 Resolved 通知携带相同的 `alert_id`,状态变为 Resolved 时告警关闭;下一次异常会有新的 `alert_id`,创建新告警。缺少 `alert_id`,或状态不是 Problem / Resolved 的通知会被拒绝。
## 状态和告警等级
----
| Alert Rule 的 Severity | Flashduty 告警等级 |
| :--- | :--- |
@@ -87,7 +84,6 @@ Alert Rule 通知(`monitoring_profile_state_changed`)的 Alert Key 由事件
由 `data.state.current` 决定状态:`Problem` 触发告警,`Resolved` 恢复告警。
## Public API alert profile 事件
----
通过 Domotz Public API 的 alert-profile 绑定接口生成的通知使用下面的事件。Flashduty 用事件名称、`agent_id`(采集器 ID)和 `device_id`(设备 ID)组合出 Alert Key,TCP 服务再加上端口,字段之间以不可见分隔符连接后取 MD5。这些标识来自 Domotz Public API 定义中各 Webhook 事件的结构。设备名称、状态值、时间等变化不会改变 Alert Key。
@@ -110,7 +106,6 @@ Alert Rule 通知(`monitoring_profile_state_changed`)的 Alert Key 由事件
一次 `device_tcp` 通知可以包含多个端口,Flashduty 按端口升序为每个端口生成一条事件,最多处理 50 个。设备发现、功能发现、MIB 发现会被接收但不创建告警。状态值不在上表中时返回参数错误。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -125,7 +120,6 @@ Alert Rule 通知(`monitoring_profile_state_changed`)的 Alert Key 由事件
| `trigger_name` | SNMP 触发器名称 |
## 排查问题
----
- **没有收到告警**:确认 Alert Rule 已应用到设备或采集器(**Applied To** 不是 `-`),并在 **Notification Channels** 中选择了这个 Webhook 渠道
- **告警没有恢复**:只有上表中有恢复条件的事件会自动恢复;其他事件请依赖超时自动关闭
diff --git a/zh/on-call/integration/alert-integration/alert-sources/dotcom-monitor.mdx b/zh/on-call/integration/alert-integration/alert-sources/dotcom-monitor.mdx
index 1c23701d..d0256c0c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/dotcom-monitor.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/dotcom-monitor.mdx
@@ -1,15 +1,15 @@
---
title: "Dotcom-Monitor 告警集成"
+sidebarTitle: "Dotcom-Monitor"
description: "通过 Dotcom-Monitor 的 HTTP Webhook 和 JSON 告警模板,将网站、API 和服务器监控告警同步到 Flashduty On-call,设备恢复时自动关闭告警。"
keywords: ["告警集成", "Dotcom-Monitor", "Webhook", "网站监控", "合成监控", "UserView", "WebView"]
---
-Dotcom-Monitor 是云端的网站、API 和服务器监控服务。它的 **HTTP Webhook** 地址类型可以在设备状态变化时,用你写的告警模板向指定地址发送请求。Dotcom-Monitor 没有固定的 Webhook 请求体,所以本集成要求你在告警模板中粘贴下文的 JSON 模板,Flashduty 按这个模板的字段解析。每个监控设备对应一条 Flashduty 告警:设备出错时打开,收到恢复通知(ALL CLEAR)时自动关闭。
+Dotcom-Monitor 是云端的网站、API 和服务器监控服务。它的 **HTTP Webhook** 地址类型可以在设备状态变化时,用您写的告警模板向指定地址发送请求。Dotcom-Monitor 没有固定的 Webhook 请求体,所以本集成要求您在告警模板中粘贴下文的 JSON 模板,Flashduty 按这个模板的字段解析。每个监控设备对应一条 Flashduty 告警:设备出错时打开,收到恢复通知(ALL CLEAR)时自动关闭。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Dotcom-Monitor 是云端的网站、API 和服务器监控服务。它的 **HTTP
</div>
## 在 Dotcom-Monitor 中配置
----
<Steps>
<Step title="创建告警模板">
@@ -76,7 +75,6 @@ Dotcom-Monitor 是云端的网站、API 和服务器监控服务。它的 **HTTP
</Steps>
## Alert Key
----
Flashduty 使用设备名称(`device_name`)计算 Alert Key。Dotcom-Monitor 的告警和恢复通知都针对同一个监控设备,因此落在同一条 Flashduty 告警上。
@@ -87,7 +85,6 @@ Flashduty 使用设备名称(`device_name`)计算 Alert Key。Dotcom-Monitor
请求缺少 `device_name` 时,Flashduty 会拒绝该请求。
## 告警生命周期
----
Flashduty 按 `notification_type` 字段处理消息,不区分大小写:
@@ -99,12 +96,10 @@ Flashduty 按 `notification_type` 字段处理消息,不区分大小写:
其他取值(包括 `TEST`)会被拒绝,返回参数错误。Dotcom-Monitor 的变量参考列出了 `TEST` 类型,但没有说明测试发送是否使用它,所以 Flashduty 不为它设置单独的处理,请用真实的设备状态变化验证。设备持续出错期间收到的重复通知会合并到同一条告警。
## 告警等级
----
Dotcom-Monitor 的消息没有等级字段。设备出错表示监控目标不可用,固定为 **Critical**。恢复事件保留原告警的等级。
## 告警内容
----
- **标题**:设备名称
- **描述**:错误类型、错误码、错误原因和出错的目标地址
@@ -113,7 +108,6 @@ Dotcom-Monitor 的消息没有等级字段。设备出错表示监控目标不
Dotcom-Monitor 会对模板中的文本做 HTML 转义,Flashduty 会还原后再使用。
## 排查问题
----
- **测试通知返回参数错误**:`notification_type` 为 `TEST` 的请求不被接受,不会创建告警,这不表示配置有误;请用真实的设备状态变化验证
- **请求被拒绝,提示 `device_name` 缺失或 `notification_type` 不支持**:检查告警模板的字段名是否与上文一致,以及 Data Type 是否选择了 Raw JSON
diff --git a/zh/on-call/integration/alert-integration/alert-sources/duplicati.mdx b/zh/on-call/integration/alert-integration/alert-sources/duplicati.mdx
index 99a89d3c..f0edfa98 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/duplicati.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/duplicati.mdx
@@ -1,5 +1,6 @@
---
title: "Duplicati 告警集成"
+sidebarTitle: "Duplicati"
description: "通过 Duplicati 的 HTTP JSON 通知,把备份任务的失败、警告和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Duplicati", "备份", "Webhook", "send-http-json-urls"]
---
@@ -9,7 +10,6 @@ Duplicati 每次备份结束后,都可以向指定地址发送一份 JSON 报
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Duplicati 每次备份结束后,都可以向指定地址发送一份 JSON 报
</div>
## 在 Duplicati 中配置
----
Duplicati 2.0.9.106 及以上版本支持 `--send-http-json-urls` 选项,本集成基于 2.4.0.0 验证。
@@ -66,7 +65,6 @@ Duplicati 没有“发送测试通知”按钮,只能通过真实备份运行
</Steps>
## Alert Key
----
Flashduty 用 Duplicati 报告里的 `Extra.machine-id` 和 `Extra.backup-id` 共同生成 Alert Key。Duplicati 官方文档把 `%machine-id%` 定义为分配给这台机器的唯一随机标识,把 `%backup-id%` 定义为分配给该备份任务的标识;我们在真实的 Duplicati 2.4.0.0 上验证过,同一个备份任务先失败、后成功时,两个字段保持不变。
@@ -78,7 +76,6 @@ Flashduty 用 Duplicati 报告里的 `Extra.machine-id` 和 `Extra.backup-id`
删除任务后重新创建,会得到新的 `backup-id`,旧任务上未恢复的告警需要手动关闭。
## 状态和告警等级
----
| Duplicati `Data.ParsedResult` | Flashduty 状态或等级 |
| :--- | :--- |
@@ -90,7 +87,6 @@ Flashduty 用 Duplicati 报告里的 `Extra.machine-id` 和 `Extra.backup-id`
空值或其他值(包括 `Unknown`)会被拒绝。Duplicati 只在备份运行时发送报告:如果任务被停用或不再运行,已有告警不会恢复,需要手动关闭。
## 排查问题
----
- **Flashduty 没有收到事件**:确认选项名是 `send-http-json-urls`,Push URL 完整且包含 `integration_key`
- **Flashduty 返回参数错误**:确认没有误用 `--send-http-url` 或表单格式,报告必须是 JSON,且包含 `Extra.backup-id`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/dynatrace.mdx b/zh/on-call/integration/alert-integration/alert-sources/dynatrace.mdx
index b68637fc..e70f243d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/dynatrace.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/dynatrace.mdx
@@ -1,5 +1,6 @@
---
title: "Dynatrace 告警事件"
+sidebarTitle: "Dynatrace"
description: "通过 webhook 的方式同步 Dynatrace 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理。"
keywords: ["告警集成", "Dynatrace 告警事件", "监控告警", "数据接入"]
---
@@ -8,7 +9,6 @@ keywords: ["告警集成", "Dynatrace 告警事件", "监控告警", "数据接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -16,7 +16,7 @@ keywords: ["告警集成", "Dynatrace 告警事件", "监控告警", "数据接
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -32,9 +32,9 @@ keywords: ["告警集成", "Dynatrace 告警事件", "监控告警", "数据接
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Dynatrace** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -47,16 +47,14 @@ keywords: ["告警集成", "Dynatrace 告警事件", "监控告警", "数据接
</div>
## 在 Dynatrace
----
<div className="md-block">
-## 一、Dynatrace 告警推送配置
1. 登录您的 Dynatrace 控制台。
2. 在左侧导航栏选择 `Apps`,在 `Manage` 区域找到 `Settings`。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-1.png" />
3. 找到 `Integration`,选择 `Problem notifications`。
<div style={{textAlign: "center"}}>
@@ -67,41 +65,41 @@ keywords: ["告警集成", "Dynatrace 告警事件", "监控告警", "数据接
4. 点击 `Add notifycation`。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-3.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-3.png" />
5. 在 `Notification type` 处,选择 `Custom Integraion`。
6. `Display name` 填写 `Flashduty`。
7. `Webhook URL` 填写集成的推送地址(当前页面填写集成名称,保存后即可生成地址)。
8. `Call webhook if problem is closed` 保持开启状态。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-4.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-4.png" />
9. `Custom payload` 处,填写以下内容:
-```
-{
- "State":"{State}",
- "PID":"{PID}",
- "ProblemTitle":"{ProblemTitle}",
- "ProblemImpact":"{ProblemImpact}",
- "ProblemDetails":"{ProblemDetailsText}",
- "ProblemURL":"{ProblemURL}",
- "ProblemSeverity":"{ProblemSeverity}",
- "ImpactedEntityNames":"{ImpactedEntityNames}",
- "Tags":"{Tags}"
-}
+ ```
+ {
+ "State":"{State}",
+ "PID":"{PID}",
+ "ProblemTitle":"{ProblemTitle}",
+ "ProblemImpact":"{ProblemImpact}",
+ "ProblemDetails":"{ProblemDetailsText}",
+ "ProblemURL":"{ProblemURL}",
+ "ProblemSeverity":"{ProblemSeverity}",
+ "ImpactedEntityNames":"{ImpactedEntityNames}",
+ "Tags":"{Tags}"
+ }
-```
+ ```
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-5.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/dyn-5.png" />
10. 点击 `Save changes` 保存即可 。
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/ecloud-cm.mdx b/zh/on-call/integration/alert-integration/alert-sources/ecloud-cm.mdx
index 2ee3583f..f5ffa3d5 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/ecloud-cm.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/ecloud-cm.mdx
@@ -1,5 +1,6 @@
---
title: "移动云云监控告警集成"
+sidebarTitle: "移动云云监控"
description: "通过移动云云监控告警联系人的自定义 Webhook,将云监控告警同步到 Flashduty On-call,告警恢复时自动关闭。"
keywords: ["告警集成", "移动云", "云监控", "China Mobile Cloud", "ecloud", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "移动云", "云监控", "China Mobile Cloud", "eclo
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "移动云", "云监控", "China Mobile Cloud", "eclo
</div>
## 在移动云中配置
----
<Steps>
<Step title="创建带 Webhook 地址的告警联系人">
@@ -62,7 +61,6 @@ keywords: ["告警集成", "移动云", "云监控", "China Mobile Cloud", "eclo
</Steps>
## Alert Key
----
移动云每次推送都带有告警 ID(`alarmId`)。按移动云的说明,同一资源、同一告警规则持续产生的告警,`alarmId` 保持不变。Flashduty 以 `alarmId` 计算 Alert Key,因此:
@@ -73,7 +71,6 @@ keywords: ["告警集成", "移动云", "云监控", "China Mobile Cloud", "eclo
缺少 `alarmId` 的请求会被拒绝。
## 状态和告警等级
----
`recover` 为 `true` 时告警恢复,其余情况均视为触发。告警等级来自告警级别(`alarmLevel`):
@@ -88,7 +85,6 @@ keywords: ["告警集成", "移动云", "云监控", "China Mobile Cloud", "eclo
告警恢复时保留恢复前的告警等级。
## 告警内容和标签
----
告警标题由资源名称(`resourceName`)和告警指标名称(`metricName`)组成,例如 `ECS-45273803 CPU利用率`。告警描述为移动云推送的告警内容(`content`),包含触发值和触发时间。
@@ -111,7 +107,6 @@ keywords: ["告警集成", "移动云", "云监控", "China Mobile Cloud", "eclo
| `notify_time` | 本次告警通知的时间(`notifyTime`) |
## 排查问题
----
- **Flashduty 没有收到告警**:确认告警策略的通知对象中选择了填写 Webhook 地址的告警联系人,且地址完整、包含 `integration_key`
- **Flashduty 返回参数错误**:确认推送内容中带有 `alarmId`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/edge-delta.mdx b/zh/on-call/integration/alert-integration/alert-sources/edge-delta.mdx
index 9b5d9331..7cbd6329 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/edge-delta.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/edge-delta.mdx
@@ -1,5 +1,6 @@
---
title: "Edge Delta 告警集成"
+sidebarTitle: "Edge Delta"
description: "通过 Edge Delta 的 Webhook 集成和监控项通知,将监控项的告警、预警和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Edge Delta", "可观测性", "Webhook", "Monitor"]
---
@@ -9,7 +10,6 @@ Edge Delta 的 Webhook 集成没有固定的请求体,请求体由用户自己
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Edge Delta 的 Webhook 集成没有固定的请求体,请求体由用户自己
</div>
## 在 Edge Delta 中配置
----
<Steps>
<Step title="为每个状态创建一个 Webhook 集成">
@@ -90,7 +89,6 @@ Edge Delta 的 Webhook 集成没有固定的请求体,请求体由用户自己
</Steps>
## 推送内容
----
| 字段 | 含义 | 在 Flashduty 中 |
| :--- | :--- | :--- |
@@ -104,7 +102,6 @@ Edge Delta 的 Webhook 集成没有固定的请求体,请求体由用户自己
| `time` | `$EVENT_DATE`,事件时间 | 写入描述 |
## Alert Key
----
Flashduty 用 `monitor` 加 `group` 生成 Alert Key。同一个监控项(以及同一个分组)的告警、预警和恢复请求携带相同的 `monitor` 和 `group`,因此落在同一条告警上;不同分组各自独立。没有设置 group by 的监控项,`group` 为 `*`,整个监控项对应一条告警;设置了 group by 的监控项,`group` 形如 `<标签>:<值>`(例如 `ed.tag:docker-logs`)。`value`、`metric` 和时间不参与 Alert Key。
@@ -113,7 +110,6 @@ Edge Delta 官方文档没有给出监控项事件的稳定 ID,所以 Alert Ke
</Note>
## 状态和告警等级
----
| `status` | Flashduty 状态或等级 |
| :--- | :--- |
@@ -124,7 +120,6 @@ Edge Delta 官方文档没有给出监控项事件的稳定 ID,所以 Alert Ke
请求缺少 `monitor` 或 `status`,或 `status` 不是上表中的值时,Flashduty 返回参数错误。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么 monitor 要手写,不能用变量?">
@@ -141,7 +136,6 @@ Edge Delta 官方文档列出的 `$EVENT_*` 变量里没有监控项 ID 或名
</AccordionGroup>
## 排查问题
----
- **监控项提示 `Receiver webhook-flashduty-warning does not exist`**:通知里的每个 `@webhook-...` 都必须对应一个已创建的集成,请创建该集成或删掉对应的块
- **Edge Delta 没有推送**:确认监控项的 Notifications 中引用了 `@webhook-<集成名称>`,且位于对应的 `{{#is_alert}}` 等条件块内
diff --git a/zh/on-call/integration/alert-integration/alert-sources/elastalert2.mdx b/zh/on-call/integration/alert-integration/alert-sources/elastalert2.mdx
index fb414cee..e80ddb25 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/elastalert2.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/elastalert2.mdx
@@ -1,5 +1,6 @@
---
title: "ElastAlert2 告警集成指引"
+sidebarTitle: "ElastAlert2"
description: "通过 ElastAlert2 的 Provider 将告警事件推送到 Flashduty On-call,实现告警事件自动化降噪处理。"
keywords: ["告警集成", "ElastAlert2 告警集成指引", "监控告警", "数据接入"]
---
@@ -10,12 +11,12 @@ keywords: ["告警集成", "ElastAlert2 告警集成指引", "监控告警", "
您可通过以下2种方式,获取一个集成秘钥,任选其一即可。
-#### 使用专属集成
+### 使用专属集成
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -25,14 +26,14 @@ keywords: ["告警集成", "ElastAlert2 告警集成指引", "监控告警", "
</Accordion>
</AccordionGroup>
-#### 使用共享集成
+### 使用共享集成
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **ElastAlert 2** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,7 +46,6 @@ keywords: ["告警集成", "ElastAlert2 告警集成指引", "监控告警", "
## 在 ElastAlert 2
----
### 配置 ElastAlert 2 告警
遵循 [ElastAlert Flashduty](https://elastalert2.readthedocs.io/en/latest/alerts.html#flashduty) 推送配置文档
diff --git a/zh/on-call/integration/alert-integration/alert-sources/elastic.mdx b/zh/on-call/integration/alert-integration/alert-sources/elastic.mdx
index ff52922a..448a4655 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/elastic.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/elastic.mdx
@@ -1,5 +1,6 @@
---
title: "Elastic 告警集成"
+sidebarTitle: "Elastic"
description: "通过 Kibana Webhook 连接器将 Elastic(Kibana Alerting)规则的触发和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Elastic", "Kibana", "Kibana Alerting", "Webhook", "Elastic Observability", "Elastic Security"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "Elastic", "Kibana", "Kibana Alerting", "Webhook", "E
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -20,7 +20,7 @@ keywords: ["告警集成", "Elastic", "Kibana", "Kibana Alerting", "Webhook", "E
当您不需要将告警路由到不同的协作空间时,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,打开一个协作空间
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**
@@ -35,7 +35,7 @@ keywords: ["告警集成", "Elastic", "Kibana", "Kibana Alerting", "Webhook", "E
当您需要根据 Payload 将告警路由到不同的协作空间时,选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**
2. 选择 **Elastic**,填写集成名称
@@ -48,14 +48,12 @@ keywords: ["告警集成", "Elastic", "Kibana", "Kibana Alerting", "Webhook", "E
</div>
## 前提条件
----
- **订阅级别**:Kibana 的 Webhook 和 PagerDuty 连接器属于 Elastic Gold 及以上订阅(Basic 不包含),30 天试用许可证也可以使用。详见 [Elastic 订阅对比](https://www.elastic.co/subscriptions)。
- **网络**:Kibana 需要能访问 Flashduty 推送地址。如果自建 Kibana 在 `kibana.yml` 中配置了 [`xpack.actions.allowedHosts`](https://www.elastic.co/docs/reference/kibana/configuration-reference/alerting-settings#action-settings),请把推送地址的主机名(如 `api.flashcat.cloud`)加入该列表,否则连接器会拒绝发送。
- **权限**:需要有创建连接器和编辑规则的 Kibana 权限,详见 [Alerting 权限说明](https://www.elastic.co/docs/explore-analyze/alerting/alerts/alerting-setup#alerting-security)。
## 在 Kibana 中配置
----
<Steps>
<Step title="创建 Webhook 连接器">
@@ -99,7 +97,6 @@ Kibana 的恢复通知是独立的动作。缺少 Recovered 动作时,Flashdut
</Steps>
## 动作模板
----
把下面的 JSON 粘贴到每个动作的 **Body**:
@@ -147,7 +144,6 @@ Kibana 会对 Body 中的变量做 JSON 转义,规则名称或描述中的引
自定义标签与内置标签合计不超过 50 个,键只能包含字母、数字和下划线,且不能以数字开头。与内置标签同名的自定义标签会被内置标签覆盖。
## Alert Key
----
Flashduty 使用 `rule_id` 和 `alert_id` 共同生成 Alert Key。
@@ -160,7 +156,6 @@ Flashduty 使用 `rule_id` 和 `alert_id` 共同生成 Alert Key。
规则名称、标签、等级、描述、动作组的变化都不会改变 Alert Key。例如 Metric threshold 规则的同一分组从 `Warning` 变为 `Alert` 时,两次通知的 Alert Key 相同。
## 状态和告警等级
----
| 条件 | Flashduty 状态或等级 |
| :--- | :--- |
@@ -175,7 +170,6 @@ Flashduty 使用 `rule_id` 和 `alert_id` 共同生成 Alert Key。
Security 检测规则不会发送 Recovered 通知,每条检测告警都会在 Flashduty 中生成一条独立告警,需要在 Flashduty 中手动关闭或配置自动关闭。
## 使用 PagerDuty 连接器(可选)
----
如果已有规则在使用 Kibana 的 PagerDuty 连接器,也可以把它指向 Flashduty 的 [PagerDuty 兼容集成](/zh/on-call/integration/alert-integration/alert-sources/pagerduty),无需改写动作内容。此方式接入的是 Flashduty 的 PagerDuty 兼容集成,不是本页的 Elastic 集成。
@@ -185,7 +179,6 @@ Security 检测规则不会发送 Recovered 通知,每条检测告警都会在
4. 两个动作的 **DedupKey** 都保留 Kibana 预填的 `{{rule.id}}:{{alert.id}}`,不要清空,这样恢复事件会关闭对应的告警。Trigger 动作的 DedupKey 为空时,Kibana 不发送 `dedup_key`,Flashduty 会为每次触发生成随机的 Alert Key,恢复事件将无法关闭它
## 排查问题
----
- **Kibana 报 `target url "..." is not added to the Kibana config xpack.actions.allowedHosts`**:将 Flashduty 推送地址的主机名加入 `xpack.actions.allowedHosts`
- **Flashduty 返回以 `alert_id is required` 开头的错误**:动作的 **Action frequency** 选择了 Summary of alerts,请改为 For each alert
diff --git a/zh/on-call/integration/alert-integration/alert-sources/email.mdx b/zh/on-call/integration/alert-integration/alert-sources/email.mdx
index fd81b8d9..3ff70d20 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/email.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/email.mdx
@@ -1,5 +1,6 @@
---
-title: "邮件Email集成"
+title: "邮件(Email)集成"
+sidebarTitle: "邮件(Email)"
description: "在 Flashduty On-call 生成唯一的邮件地址,通过邮件的方式将告警的发生与恢复同步到 Flashduty On-call"
keywords: ["告警集成", "邮件Email集成", "监控告警", "数据接入"]
---
@@ -8,7 +9,6 @@ keywords: ["告警集成", "邮件Email集成", "监控告警", "数据接入"]
<div className="hide">
## 操作步骤
----
### 创建邮件集成
@@ -19,7 +19,7 @@ keywords: ["告警集成", "邮件Email集成", "监控告警", "数据接入"]
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -34,9 +34,9 @@ keywords: ["告警集成", "邮件Email集成", "监控告警", "数据接入"]
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **邮件 Email** 集成:
- **集成名称**:为当前集成定义一个名称。
- **邮件地址**:为邮件设定一个方便记忆的前缀,需要保证在账户下唯一。
@@ -89,15 +89,15 @@ keywords: ["告警集成", "邮件Email集成", "监控告警", "数据接入"]
1. 如果邮件消息体大于 5MB,系统会直接拒绝接收。
2. 如果邮件文字内容长度超过 128KB,系统会进行截断,并在故障详情中增加标签提示:
-```
-body_cut = true
-```
+ ```
+ body_cut = true
+ ```
3. 如果邮件中包含附件,系统会直接丢弃附件,并在故障详情中增加标签提示:
-```
-attachment_stripped = true
-```
+ ```
+ attachment_stripped = true
+ ```
4. 邮件触发的新告警中,**标题即邮件标题,描述即邮件内容**。
@@ -106,7 +106,6 @@ attachment_stripped = true
## 严重程度映射关系
----
当前邮件集成推送到 Flashduty On-call 的告警等级均为Warning,但您可以通过[告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines) 来自定义严重程度。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/emqx.mdx b/zh/on-call/integration/alert-integration/alert-sources/emqx.mdx
index 1c322d22..be9d42dc 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/emqx.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/emqx.mdx
@@ -1,5 +1,6 @@
---
title: "EMQX 告警集成"
+sidebarTitle: "EMQX"
description: "通过 Webhook 将 EMQX 的告警事件推送到 Flashduty,实现告警事件自动化降噪处理"
keywords: ["告警集成", "EMQX", "MQTT", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "EMQX", "MQTT", "监控告警", "数据接入"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
@@ -16,7 +16,7 @@ keywords: ["告警集成", "EMQX", "MQTT", "监控告警", "数据接入"]
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "EMQX", "MQTT", "监控告警", "数据接入"]
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **EMQX** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,7 +45,6 @@ keywords: ["告警集成", "EMQX", "MQTT", "监控告警", "数据接入"]
</div>
## 在 EMQX
----
EMQX Cloud(托管服务)与自建 EMQX 的接入方式不同,请根据您的部署形态选择。
@@ -132,7 +131,6 @@ FROM
</div>
## 严重程度映射关系
----
<div className="md-block">
@@ -149,7 +147,6 @@ FROM
</div>
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么在 Flashduty 没有收到告警?">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/extrahop.mdx b/zh/on-call/integration/alert-integration/alert-sources/extrahop.mdx
index 10766a29..24d9dabd 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/extrahop.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/extrahop.mdx
@@ -1,5 +1,6 @@
---
title: "ExtraHop 告警集成"
+sidebarTitle: "ExtraHop"
description: "通过检测通知规则的自定义 Webhook,将 ExtraHop Reveal(x) 的安全和性能检测同步到 Flashduty On-call。"
keywords: ["告警集成", "ExtraHop", "Reveal(x)", "RevealX", "NDR", "NPM", "网络检测", "Webhook"]
---
@@ -11,7 +12,6 @@ ExtraHop 的文档没有说明检测被关闭或解决时会发送通知,所
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ ExtraHop 的文档没有说明检测被关闭或解决时会发送通知,所
</div>
## 在 ExtraHop 中配置
----
需要 NDR 或 NPM 模块权限,并拥有完全写入(full write)及以上权限。Webhook 通过 TCP 443(HTTPS)发送,ExtraHop 需要能访问 Flashduty 推送地址。
@@ -80,19 +79,16 @@ ExtraHop 的文档没有说明检测被关闭或解决时会发送通知,所
</Steps>
## Alert Key
----
Flashduty 使用 `id`(ExtraHop 文档定义为 "The unique identifier for the detection")作为 Alert Key。同一个检测每次更新推送的 `id` 相同,会合并到同一条告警;标题、描述、风险分和时间变化不会改变 Alert Key。缺少 `id` 的请求会被拒绝。
## 检测与恢复
----
ExtraHop 的检测通知只有"创建"和"更新"两种情形,文档没有描述检测关闭或解决时的通知。Flashduty 收到的每条通知都是触发状态,不会自动恢复。
请在协作空间中开启[超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时;也可以在检测处理完成后手动关闭告警。
## 告警等级
----
告警等级取自 `risk_score`,分段与 ExtraHop 控制台的颜色一致:
@@ -104,7 +100,6 @@ ExtraHop 的检测通知只有"创建"和"更新"两种情形,文档没有描
| 缺失、0 或非数字(性能检测没有风险分) | Warning |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -122,7 +117,6 @@ ExtraHop 的检测通知只有"创建"和"更新"两种情形,文档没有描
告警标题取自 `title`,为空时依次取 `type` 和 `ExtraHop detection <id>`。描述为检测描述加上检测详情链接。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,并且 payload 中有 `id`
- **告警一直未关闭**:ExtraHop 没有恢复通知,请开启协作空间的超时自动关闭,或手动关闭
diff --git a/zh/on-call/integration/alert-integration/alert-sources/fail2ban.mdx b/zh/on-call/integration/alert-integration/alert-sources/fail2ban.mdx
index 24664d98..6c794916 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/fail2ban.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/fail2ban.mdx
@@ -1,5 +1,6 @@
---
title: "Fail2ban 告警集成"
+sidebarTitle: "Fail2ban"
description: "在 Fail2ban 中添加自定义 action,用 curl 把封禁和解封事件推送到 Flashduty 的标准告警事件集成,解封时自动关闭告警。"
keywords: ["告警集成", "Fail2ban", "入侵防御", "封禁 IP", "curl", "标准告警事件"]
---
@@ -9,7 +10,6 @@ Fail2ban 没有内置的 Webhook 通知,但它的 action 就是在封禁或解
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择标准告警事件**,不是 Fail2ban。
@@ -30,7 +30,6 @@ Fail2ban 没有内置的 Webhook 通知,但它的 action 就是在封禁或解
</div>
## 在 Fail2ban 中配置
----
以下操作在运行 Fail2ban 的主机上进行,需要 root 权限。
@@ -91,7 +90,6 @@ fail2ban-client set sshd unbanip 192.0.2.10
</Steps>
## 字段映射
----
| Fail2ban | Flashduty |
| :--- | :--- |
@@ -103,7 +101,6 @@ fail2ban-client set sshd unbanip 192.0.2.10
| `labels` | 标签 `jail`、`ip`、`failures`、`bantime` |
## 恢复与去重
----
- Fail2ban 在封禁时间到期后执行 `actionunban`,Flashduty 用相同的 `alert_key` 关闭对应告警。
- 封禁时间设为永久(`bantime = -1`)时不会解封,告警不会自动关闭。请在接收该集成的协作空间开启 [超时自动关闭](/zh/on-call/channel/create-edit),或处理完成后手动关闭。
@@ -111,7 +108,6 @@ fail2ban-client set sshd unbanip 192.0.2.10
- `norestored = 1` 让 Fail2ban 重启后从数据库恢复的封禁不再通知,避免重启时产生一批重复告警。
## 排查问题
----
- **Flashduty 没有收到告警**:确认 `fail2ban-client reload` 已执行;用 `curl` 在同一台主机上手动请求推送地址,看响应和网络是否可达 api.flashcat.cloud
- **返回 `InvalidParameter`**:推送地址缺少 `integration_key`,或 JSON 因引号被破坏;确认 `[Definition]` 里没有多余的换行
diff --git a/zh/on-call/integration/alert-integration/alert-sources/falco.mdx b/zh/on-call/integration/alert-integration/alert-sources/falco.mdx
index 4ce06e4a..6fba289c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/falco.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/falco.mdx
@@ -1,5 +1,6 @@
---
title: "Falco 告警集成"
+sidebarTitle: "Falco"
description: "通过 Falcosidekick 的 Webhook 输出,或 Falco 自带的 http_output,将运行时安全检测事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Falco", "Falcosidekick", "Webhook", "运行时安全"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Falco", "Falcosidekick", "Webhook", "运行时安全
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Falco", "Falcosidekick", "Webhook", "运行时安全
</div>
## 在 Falco 中配置
----
推荐通过 Falcosidekick 推送,可以用 `minimumpriority` 在源头过滤低优先级事件。没有部署 Falcosidekick 时,可让 Falco 直接推送。
@@ -78,7 +77,6 @@ http_output:
</Warning>
## 验证
----
向 Falcosidekick 的 `/test` 接口发一次请求(默认监听 2801 端口):
@@ -91,7 +89,6 @@ Flashduty 会新建一条标题为 `Test rule`、等级为 Info 的告警。该
随后在被监控主机或容器里触发一条真实规则(例如在容器中打开一个交互式 shell 触发 `Terminal shell in container`),确认 Flashduty 出现对应告警。
## Alert Key
----
Falco 的每条事件是一次独立的检测,没有生命周期,所以每条事件对应一条告警:
@@ -101,7 +98,6 @@ Falco 的每条事件是一次独立的检测,没有生命周期,所以每
请求缺少 `rule` 时 Flashduty 会拒绝,因为无法确定这是哪条规则的事件。
## 告警等级
----
| Falco `priority` | Flashduty 等级 |
| :--- | :--- |
@@ -111,17 +107,14 @@ Falco 的每条事件是一次独立的检测,没有生命周期,所以每
| 空值或未知值 | Warning |
## 标签
----
标题为规则名(`rule`),描述为 `output`。以下字段写入标签:`rule`、`priority`、`hostname`(同时作为 `resource`)、`falco_source`、`falco_uuid`、`tags`(逗号分隔)。`output_fields` 中的每个字段也会写入标签,键名中的 `.` 替换为 `_`,例如 `container.id` 变为 `container_id`、`k8s.pod.name` 变为 `k8s_pod_name`,总数上限为 50 个标签。
## 告警恢复
----
Falco 不发送恢复事件,告警不会自动恢复。请为接收 Falco 告警的协作空间开启[超时自动关闭](/zh/on-call/channel/create-edit),建议设置为 24 小时,按需要处理的时效调整。也可以在处理完成后手动关闭告警。
## 排查问题
----
- **Falcosidekick 日志出现 webhook 错误**:确认地址完整且包含 `integration_key`,并能从 Falcosidekick 所在网络访问 `api.flashcat.cloud`
- **Flashduty 返回参数错误**:确认 Falco 已开启 `json_output: true`,且请求体是有效 JSON、包含 `rule`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/fastnetmon.mdx b/zh/on-call/integration/alert-integration/alert-sources/fastnetmon.mdx
index 312c4048..902d328f 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/fastnetmon.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/fastnetmon.mdx
@@ -1,5 +1,6 @@
---
title: "FastNetMon 告警集成"
+sidebarTitle: "FastNetMon"
description: "通过 FastNetMon Advanced 的 Web Callback 将 DDoS 攻击的封禁与解封通知同步到 Flashduty On-call。"
keywords: ["告警集成", "FastNetMon", "DDoS", "Web Callback", "ban", "unban", "BGP Blackhole", "Flow Spec"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "FastNetMon", "DDoS", "Web Callback", "ban", "unban",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "FastNetMon", "DDoS", "Web Callback", "ban", "unban",
</div>
## 在 FastNetMon 中配置
----
<Steps>
<Step title="启用 Web Callback">
@@ -69,7 +68,6 @@ sudo fcli commit
</Steps>
## 推送内容
----
| 字段 | 含义 | 在 Flashduty 中 |
| :--- | :--- | :--- |
@@ -85,7 +83,6 @@ sudo fcli commit
封禁通知中的数据包采样(`packet_dump`)和 Flow Spec 规则不会写入告警。
## Alert Key
----
按被攻击对象生成 Alert Key:主机范围使用 `ip`,主机组范围使用 `hostgroup_name`。同一个 IP 的封禁、状态更新和解封落在同一条告警上;不同 IP 或不同主机组是不同的告警。攻击等级、流量数据和 `attack_uuid` 的变化不会改变 Alert Key。
@@ -96,7 +93,6 @@ sudo fcli commit
请求缺少 `ip`(或主机组范围缺少 `hostgroup_name`)时,Flashduty 会返回参数错误,因为无法可靠地把解封通知关联到原告警。`action` 或 `alert_scope` 为其他值的请求同样被拒绝。
## 状态和告警等级
----
| FastNetMon `attack_severity` | Flashduty 等级 |
| :--- | :--- |
@@ -108,7 +104,6 @@ sudo fcli commit
官方示例只出现 `middle`,其他取值按常见命名映射。解封时告警恢复,原等级保持为最后一次攻击等级。
## 常见问题
----
<AccordionGroup>
<Accordion title="FastNetMon 有测试按钮吗?">
@@ -131,7 +126,6 @@ sudo fcli commit
</AccordionGroup>
## 排查问题
----
- **收不到告警**:在 FastNetMon 服务器上确认 `web_callback_enabled` 已启用,`fcli commit` 已执行,且服务器能访问 Flashduty 推送地址
- **Flashduty 返回参数错误**:确认请求是 FastNetMon 的 JSON 通知,且 `ip`(主机范围)或 `hostgroup_name`(主机组范围)非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/firebase-crashlytics.mdx b/zh/on-call/integration/alert-integration/alert-sources/firebase-crashlytics.mdx
index 5295ca86..e9f5462f 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/firebase-crashlytics.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/firebase-crashlytics.mdx
@@ -1,5 +1,6 @@
---
title: "Firebase Crashlytics 告警集成"
+sidebarTitle: "Firebase Crashlytics"
description: "通过一段 Cloud Functions 代码,把 Firebase Crashlytics 的新增致命问题、回归和速率告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Firebase", "Crashlytics", "Cloud Functions", "Eventarc", "崩溃", "移动应用"]
---
@@ -19,7 +20,6 @@ Firebase 还会发送**稳定性摘要**(`onStabilityDigestPublished`),按
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -40,7 +40,6 @@ Firebase 还会发送**稳定性摘要**(`onStabilityDigestPublished`),按
</div>
## 在 Firebase 中配置
----
Crashlytics 告警函数运行在 Cloud Functions(2nd gen)之上,Firebase 项目需要在 **Blaze(按量付费)** 方案下才能部署,即使实际用量落在免费额度内也需要绑定结算账号。
@@ -155,7 +154,6 @@ Crashlytics 不会为这些事件发送“已解决”通知,Flashduty 中的
</Steps>
## Alert Key
----
Flashduty 使用事件类型 `alert_type`、应用 ID `app_id` 和 Crashlytics 的问题 ID `issue_id`(对应官方 `Issue.id`)共同计算 Alert Key。一个 Cloud Function 部署(一个推送地址)可以转发项目下所有应用的事件(见上文“按需限定应用”),而 Firebase 并未说明 `issue_id` 在不同应用之间也互不重复,因此 `app_id` 也参与计算,避免两个应用凑巧拿到相同的问题 ID 时被合并成一条告警。因此:
@@ -167,7 +165,6 @@ Flashduty 使用事件类型 `alert_type`、应用 ID `app_id` 和 Crashlytics
请求缺少 `issue_id` 时,Flashduty 会拒绝该请求。
## 告警等级
----
Crashlytics 的告警事件不携带等级,Flashduty 按事件类型确定等级:
@@ -182,7 +179,6 @@ Crashlytics 的告警事件不携带等级,Flashduty 按事件类型确定等
如需统一改为其他等级,在推送地址后追加 `&severity=Critical`(或 `Warning`、`Info`)。
## 告警内容
----
告警标题为 `Firebase Crashlytics <事件类型>: <issue_title>`,如 `Firebase Crashlytics new fatal issue: java.lang.NullPointerException`。描述包含问题副标题(崩溃发生的类和方法)、应用版本号;回归事件额外包含上次被标记解决的时间,速率告警额外包含崩溃会话数、崩溃率和首次出现的版本号。
@@ -198,7 +194,6 @@ Crashlytics 的告警事件不携带等级,Flashduty 按事件类型确定等
| `crash_count` / `crash_percentage` / `first_version` | 仅速率告警:崩溃会话数、崩溃率、首次出现的版本号 |
## 排查问题
----
- **函数部署失败或报权限错误**:确认 Firebase 项目已开通 Blaze 方案,且执行部署的账号对该项目有 Cloud Functions 部署权限
- **崩溃已发生,但迟迟没有告警**:Crashlytics 处理崩溃日志和触发告警函数通常有几分钟延迟;用 `firebase functions:log` 查看对应函数有没有被触发、`fetch` 有没有抛错
diff --git a/zh/on-call/integration/alert-integration/alert-sources/firefly.mdx b/zh/on-call/integration/alert-integration/alert-sources/firefly.mdx
index 90fd18b9..50dafa6a 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/firefly.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/firefly.mdx
@@ -1,5 +1,6 @@
---
title: "Firefly 告警集成"
+sidebarTitle: "Firefly"
description: "通过 Webhook 将 Firefly 检测到的配置漂移、未托管资源、幽灵资源和 Insight 同步到 Flashduty On-call。"
keywords: ["告警集成", "Firefly", "Webhook", "配置漂移", "Drift", "IaC", "未托管资源"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Firefly", "Webhook", "配置漂移", "Drift", "IaC",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Firefly", "Webhook", "配置漂移", "Drift", "IaC",
</div>
## 在 Firefly 中配置
----
<Steps>
<Step title="添加 Webhook 集成">
@@ -77,7 +76,6 @@ Firefly 未公开测试按钮推送的内容。测试内容如果不含资源,
</Steps>
## Alert Key
----
每个资源(`samples` 中的一项)生成一条告警,Alert Key 由事件类型 `notificationType` 和资源的 `FRN` 共同计算;`FRN` 为空时使用资源的 `ARN`。因此:
@@ -88,7 +86,6 @@ Firefly 未公开测试按钮推送的内容。测试内容如果不含资源,
资源同时缺少 `FRN` 和 `ARN` 时,Flashduty 拒绝整次推送。
## 状态和告警等级
----
Firefly 的 Webhook 通知不携带等级,Flashduty 按事件类型确定等级,所有事件都是触发状态:
@@ -98,7 +95,6 @@ Firefly 的 Webhook 通知不携带等级,Flashduty 按事件类型确定等
| `UnmanagedResource` | Info |
## 标题、描述和标签
----
告警标题为 `Firefly <事件类型>: <资源名称> (<资源类型>)`,如 `Firefly drift detected: web-1 (aws_instance)`。`Drift` 告警的描述逐行列出漂移的属性、IaC 中的值和云上的实际值。
@@ -119,7 +115,6 @@ Firefly 的 Webhook 通知不携带等级,Flashduty 按事件类型确定等
Firefly 推送中的操作人信息(`ownerData.userIdentity`)不会写入标签。
## 排查问题
----
- **创建 Webhook 集成时提示地址无效**:确认 URL 完整且包含 `integration_key`,并且没有勾选 **Add custom credentials**
- **Flashduty 返回参数错误**:确认推送地址中的 `integration_key` 属于 Firefly 集成
diff --git a/zh/on-call/integration/alert-integration/alert-sources/fivetran.mdx b/zh/on-call/integration/alert-integration/alert-sources/fivetran.mdx
index baafd88e..cd6341b3 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/fivetran.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/fivetran.mdx
@@ -1,5 +1,6 @@
---
title: "Fivetran 告警集成"
+sidebarTitle: "Fivetran"
description: "通过 Fivetran Webhook 将数据同步(sync)失败、连接测试失败以及随后的恢复事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Fivetran", "数据管道", "同步失败", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Fivetran", "数据管道", "同步失败", "Webhook"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Fivetran", "数据管道", "同步失败", "Webhook"
</div>
## 在 Fivetran 中配置
----
Fivetran 的 Webhook 通过 [Webhook REST API](https://fivetran.com/docs/developer-resources/webhooks) 创建,使用 Fivetran API Key 和 API Secret 进行 Basic 认证。Webhook 分为账户级(覆盖账户下所有连接)和分组级(只覆盖某个 Group 下的连接)两种。
@@ -82,14 +81,12 @@ Fivetran 的 **Test a Webhook**(`POST /v1/webhooks/{webhookId}/test`,请求
</Steps>
## Alert Key
----
Flashduty 使用连接 ID(Webhook 中的 `connector_id`)加事件类别(同步、连接测试)作为 Alert Key。Fivetran 文档说明 `connector_id` 是「发送 Webhook 的连接的 ID」,同一连接的每次同步和连接测试都携带相同的值。同步和连接测试分属两个 Alert Key,因此一次成功的同步不会关闭尚未修复的连接测试告警。
每次同步的 `sync_id`、失败原因和时间的变化都不会改变 Alert Key。缺少 `connector_id` 的同步或连接测试事件会被拒绝。
## 状态和告警等级
----
| 事件 | `data.status` | 状态 | Flashduty 等级 |
| :--- | :--- | :--- | :--- |
@@ -107,7 +104,6 @@ Flashduty 使用连接 ID(Webhook 中的 `connector_id`)加事件类别(
每次 `sync_end` 都是一次独立投递,没有进度更新事件:触发后的告警保持活动,直到同一连接的下一次 `SUCCESSFUL` 同步。如果连接被暂停或删除,已触发的告警不会自动恢复,请在 Flashduty 中手动关闭,或在协作空间中为告警配置超时自动关闭。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -125,7 +121,6 @@ Flashduty 使用连接 ID(Webhook 中的 `connector_id`)加事件类别(
告警描述取自失败原因(`data.reason`)或连接测试消息(`data.message`)。
## 排查问题
----
- **创建 Webhook 时 Fivetran 返回 400**:确认地址为 HTTPS 且 Flashduty 可访问;Fivetran 在创建和激活时都会先发送一次测试请求,需返回 2xx。Flashduty 对该测试请求返回 200,并按上文打开一条独立的 Info 告警
- **告警没有恢复**:确认 Webhook 订阅了 `sync_end` 和 `connection_successful`;预期内的重新调度和 `CANCELED` 不会产生恢复事件
diff --git a/zh/on-call/integration/alert-integration/alert-sources/flashcat.mdx b/zh/on-call/integration/alert-integration/alert-sources/flashcat.mdx
index 548097d6..da3a506b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/flashcat.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/flashcat.mdx
@@ -1,5 +1,6 @@
---
title: "夜莺/Flashcat 集成"
+sidebarTitle: "夜莺/Flashcat"
description: "通过 Webhook 将夜莺(Nightingale / n9e)或 Flashcat 告警事件推送到 Flashduty,实现告警的触发与自动恢复"
keywords: ["告警集成", "夜莺集成", "Flashcat集成", "n9e", "监控告警", "数据接入"]
---
@@ -15,8 +16,6 @@ keywords: ["告警集成", "夜莺集成", "Flashcat集成", "n9e", "监控告
## 前置条件
----
-
<Tabs>
<Tab title="在夜莺/Flashcat">
- 您必须拥有修改 **系统配置 → 全局通知** 或 **告警管理 → 告警规则** 的权限
@@ -30,8 +29,6 @@ keywords: ["告警集成", "夜莺集成", "Flashcat集成", "n9e", "监控告
## 版本说明
----
-
<CardGroup cols={2}>
<Card title="v8.0.0-beta.7+" icon="sparkles" href="#v8">
推荐使用,支持在通知规则中直接配置协作空间,无需配置路由规则
@@ -43,8 +40,6 @@ keywords: ["告警集成", "夜莺集成", "Flashcat集成", "n9e", "监控告
## 在 Flashduty 获取推送地址
----
-
您可以通过以下两种方式获取推送地址,请根据您的需求选择。
### 方式一:专属集成(推荐)
@@ -92,8 +87,6 @@ keywords: ["告警集成", "夜莺集成", "Flashcat集成", "n9e", "监控告
## 在夜莺/Flashcat 配置通知
----
-
<span id="v8"></span>
### v8.0.0-beta.7+ 版本配置
@@ -213,8 +206,6 @@ keywords: ["告警集成", "夜莺集成", "Flashcat集成", "n9e", "监控告
## 静默检测
----
-
在集成卡片(编辑与预览)中,告警推送设置下方提供 **静默检测**(Heartbeat)配置:在指定时间内未收到有效事件时,系统会生成一条 Warning 告警。
| 配置项 | 说明 |
@@ -225,8 +216,6 @@ keywords: ["告警集成", "夜莺集成", "Flashcat集成", "n9e", "监控告
## 严重程度映射
----
-
夜莺/Flashcat 与 Flashduty 的告警等级映射关系如下:
| 夜莺等级 | Flashduty 等级 | 说明 |
@@ -237,8 +226,6 @@ keywords: ["告警集成", "夜莺集成", "Flashcat集成", "n9e", "监控告
## 常见问题
----
-
<AccordionGroup>
<Accordion title="为什么 Flashduty 没有收到告警?">
#### 在 Flashduty 排查
diff --git a/zh/on-call/integration/alert-integration/alert-sources/fleet.mdx b/zh/on-call/integration/alert-integration/alert-sources/fleet.mdx
index 6fe5ddc0..dd56230b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/fleet.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/fleet.mdx
@@ -1,5 +1,6 @@
---
title: "Fleet 告警集成"
+sidebarTitle: "Fleet"
description: "通过 Fleet 的自动化 Webhook,将策略检查失败和新发现的漏洞(CVE)同步到 Flashduty On-call。"
keywords: ["告警集成", "Fleet", "osquery", "端点管理", "策略", "漏洞", "Webhook"]
---
@@ -14,7 +15,6 @@ Fleet 的这两类 Webhook 只在事件发生时推送一次,不会发送恢
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -35,7 +35,6 @@ Fleet 的这两类 Webhook 只在事件发生时推送一次,不会发送恢
</div>
## 在 Fleet 中配置
----
Fleet 的 Webhook 在管理后台的 **Manage automations** 中启用,也可以通过 GitOps / 配置文件设置,下面以配置文件为例。两种 Webhook 的 `destination_url` 都填 Flashduty 集成的完整推送地址,地址中需包含 `integration_key`。
@@ -87,7 +86,6 @@ Fleet 文档没有描述 Webhook 的测试推送按钮。请让一台主机上
</Steps>
## 事件和恢复
----
| Fleet 推送 | 在 Flashduty 中的效果 |
| :--- | :--- |
@@ -100,7 +98,6 @@ Fleet 文档没有描述 Webhook 的测试推送按钮。请让一台主机上
主机修复后 Fleet 不会通知 Flashduty。请在接收这些告警的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议窗口为 24 小时到 7 天,具体取决于你们处理策略失败的周期。同一主机上的同一条策略再次失败(例如 Fleet 中重置了该策略)时,会合并到同一条告警。
## Alert Key
----
- 策略失败:由策略编号(`policy.id`)和主机编号(`hosts[].id`)共同计算
- 漏洞:由 CVE 编号和主机编号共同计算
@@ -108,7 +105,6 @@ Fleet 文档没有描述 Webhook 的测试推送按钮。请让一台主机上
两者都是 Fleet 数据库中的编号,在同一个 Fleet 实例内保持不变。策略名称、主机名、失败主机计数等变化不会改变 Alert Key。缺少策略编号、CVE 编号或主机编号的推送会被拒绝,并在错误信息中指出字段名。
## 告警等级
----
| 来源 | 条件 | Flashduty 等级 |
| :--- | :--- | :--- |
@@ -122,7 +118,6 @@ Fleet 文档没有描述 Webhook 的测试推送按钮。请让一台主机上
策略的 `critical` 选项需要 Fleet Premium 许可证,免费版 Fleet 设置时会返回 `option critical requires a premium license`。因此在免费版 Fleet 上,所有策略告警都是 Warning。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -136,7 +131,6 @@ Fleet 文档没有描述 Webhook 的测试推送按钮。请让一台主机上
推送中的策略查询语句、作者信息和软件安装路径不会保存到标签中。
## 排查问题
----
- **Flashduty 返回参数错误**:错误信息会指出缺少的字段;如果提示只支持策略失败和漏洞 Webhook,请检查是否把主机状态或活动 Webhook 指向了此地址
- **没有收到告警**:策略 Webhook 只在策略由通过变为失败时触发,一直处于失败的主机不会再次推送;主机按 `FLEET_OSQUERY_POLICY_UPDATE_INTERVAL`(默认 1 小时)执行策略,结果变化后才会推送
diff --git a/zh/on-call/integration/alert-integration/alert-sources/flowmon-ads.mdx b/zh/on-call/integration/alert-integration/alert-sources/flowmon-ads.mdx
index 98d0648b..8955a98d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/flowmon-ads.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/flowmon-ads.mdx
@@ -1,5 +1,6 @@
---
title: "Flowmon ADS 告警集成"
+sidebarTitle: "Flowmon ADS"
description: "Flowmon ADS 通过邮件报告发送检测到的网络异常事件,使用 Flashduty 的邮件集成把每个事件接入为一条告警。"
keywords: ["告警集成", "Flowmon ADS", "Flowmon", "Progress", "邮件", "Email", "网络异常检测", "NDR"]
---
@@ -9,7 +10,6 @@ Flowmon ADS(Anomaly Detection System)检测到网络异常事件后,可以
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成邮件地址,任选其一即可。**集成类型都选择邮件 Email**,不是 Flowmon ADS。
@@ -30,7 +30,6 @@ Flowmon ADS(Anomaly Detection System)检测到网络异常事件后,可以
</div>
## 在 Flowmon ADS 中配置
----
1. 在 Flowmon ADS 的 **Event Response** 中打开 **Email notifications**,新建一个邮件报告。每个邮件报告绑定且只能绑定一个视角(perspective)
2. 点击 **Add new email**,添加 Flashduty 邮件集成的地址作为收件人
@@ -55,12 +54,10 @@ Flowmon ADS 按优先级决定发送时机:CRITICAL 在处理完流数据后
| `Ports involved` | 事件相关的端口号,可能为空 |
## 在 Flashduty 中配置推送模式
----
保持邮件集成默认的推送模式,即每封邮件都新建一条告警:告警标题是邮件标题,告警描述是邮件正文,其中包含上表字段。每个 Flowmon ADS 事件只发一封邮件,事件之间不需要合并,因此不需要配置规则。
## 限制
----
- **没有恢复邮件**:Flowmon ADS 的事件是一次性通知,不会发送恢复邮件,告警不会自动关闭。请在接收该集成的协作空间开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时。
- **严重程度**:告警在 Flashduty 中显示的集成类型是邮件 Email;严重程度统一为 Warning,事件优先级在正文的 `Severity` 字段中。可以通过 [告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines) 调整。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/flowtriq.mdx b/zh/on-call/integration/alert-integration/alert-sources/flowtriq.mdx
index 3838dca3..0d36c830 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/flowtriq.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/flowtriq.mdx
@@ -1,5 +1,6 @@
---
title: "Flowtriq 告警集成"
+sidebarTitle: "Flowtriq"
description: "通过 Webhook 告警渠道将 Flowtriq 检测到的 DDoS 攻击事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Flowtriq", "Webhook", "DDoS", "DDoS 检测", "攻击告警"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Flowtriq", "Webhook", "DDoS", "DDoS 检测", "攻击
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Flowtriq", "Webhook", "DDoS", "DDoS 检测", "攻击
</div>
## 在 Flowtriq 中配置
----
<Steps>
<Step title="添加 Webhook 告警渠道">
@@ -58,7 +57,6 @@ keywords: ["告警集成", "Flowtriq", "Webhook", "DDoS", "DDoS 检测", "攻击
Flowtriq 对失败的推送最多重试 3 次(间隔 10 秒、60 秒、5 分钟),单次请求超时 10 秒,返回非 2xx 状态码视为失败。
## 事件与恢复
----
Flowtriq 在每个 Incident 事件发生时向 Webhook 推送,事件类型在 `event_type` 中:
@@ -72,12 +70,10 @@ Flowtriq 在每个 Incident 事件发生时向 Webhook 推送,事件类型在
其他事件类型(包括 Flowtriq 后续新增的类型)不会创建告警,Flashduty 收到后直接返回成功。
## Alert Key
----
Flashduty 以 Incident 标识作为 Alert Key 的依据:优先使用 `incident.uuid`,没有时使用 `incident.id`。Webhook 推送目前携带数字 `incident.id`,不带 `uuid`。同一次攻击的开始和结束事件共用同一个 Alert Key,因此结束事件会恢复对应的告警。两者都缺失的事件会被拒绝。标题、等级、峰值流量等字段变化不会改变 Alert Key。
## 告警等级
----
| `incident.severity` | Flashduty 等级 |
| :--- | :--- |
@@ -89,7 +85,6 @@ Flashduty 以 Incident 标识作为 Alert Key 的依据:优先使用 `incident
恢复事件的等级保持攻击期间的最后一次等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -105,7 +100,6 @@ Flashduty 以 Incident 标识作为 Alert Key 的依据:优先使用 `incident
告警描述取自 Flowtriq 的 AI 摘要(`ai_summary`)。`attack_start` 推送时还没有摘要,此时描述为空。
## 排查问题
----
- **Flowtriq 显示推送失败**:确认 URL 完整且包含 `integration_key`,并且是 HTTPS 地址;失败记录可在 Flowtriq 的 Incident 详情页通知日志中查看
- **告警没有恢复**:确认 Flowtriq 渠道推送了 `attack_end` 事件。恢复依赖攻击开始和结束事件中的 `incident.id` 一致,若长时间未恢复,请在 Flashduty 中手动关闭该告警
diff --git a/zh/on-call/integration/alert-integration/alert-sources/fluxcd.mdx b/zh/on-call/integration/alert-integration/alert-sources/fluxcd.mdx
index eb758f14..3e6dea6f 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/fluxcd.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/fluxcd.mdx
@@ -1,5 +1,6 @@
---
title: "Flux CD 告警集成"
+sidebarTitle: "Flux CD"
description: "通过 Flux notification-controller 的 generic Provider 将 Flux 对象的对账失败同步到 Flashduty On-call,对账恢复成功后自动关闭告警。"
keywords: ["告警集成", "Flux CD", "Flux", "GitOps", "notification-controller", "Kustomization", "HelmRelease", "Kubernetes"]
---
@@ -9,7 +10,6 @@ Flux 的 notification-controller 通过 **Provider** 和 **Alert** 两种对象
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Flux 的 notification-controller 通过 **Provider** 和 **Alert** 两种对象
</div>
## 在 Flux 中配置
----
以下操作需要能在集群中创建 Secret 以及 Flux `Provider`、`Alert` 对象的 `kubectl` 权限。示例使用 `notification.toolkit.fluxcd.io/v1beta3` API 和 `flux-system` 命名空间;Provider、Alert 和 Secret 必须位于同一命名空间。集群需要能访问 Flashduty 推送地址所在的域名。
@@ -113,7 +112,6 @@ Flux 没有发送测试消息的按钮。可以用一个临时 Kustomization 验
</Steps>
## Alert Key
----
Flashduty 使用 `involvedObject.uid`(Flux 对象在 Kubernetes 中的 UID)作为 Alert Key。Flux 自带的 `pagerduty` Provider 也使用这个 UID 作为触发和恢复的去重键。同一个 Flux 对象的所有失败事件落在同一条 Flashduty 告警上,失败原因(`reason`)、消息、版本(revision)的变化都不会改变 Alert Key。
@@ -123,7 +121,6 @@ Flashduty 使用 `involvedObject.uid`(Flux 对象在 Kubernetes 中的 UID)
请求缺少 `involvedObject.uid` 时,Flashduty 会拒绝该请求。
## 告警生命周期
----
Flashduty 按事件的 `severity` 和 `reason` 字段处理:
@@ -140,12 +137,10 @@ Flashduty 按事件的 `severity` 和 `reason` 字段处理:
**只转发 `error` 事件时**:如果 Alert 的 `eventSeverity` 设为 `error`,或 `exclusionList` 过滤掉了成功事件,Flashduty 收不到恢复事件,告警不会自动关闭。此时请在协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),超时计时起点选择 **故障触发**,建议超时时长 12 小时:对象仍然失败时,下一次对账失败会重新触发告警。
## 告警等级
----
Flux 的失败事件只有 `error` 一个等级,所有告警默认为 **Critical**。如需其他等级,在推送地址后追加 `&severity=Warning`(或 `Info`)。恢复事件保留原告警的等级。
## 告警内容
----
- **标题**:`<Kind> <命名空间>/<名称>: <reason>`,例如 `Kustomization apps/webapp: ValidationFailed`
- **描述**:事件的 `message`
@@ -154,7 +149,6 @@ Flux 的失败事件只有 `error` 一个等级,所有告警默认为 **Critic
`metadata` 键名中 `a-z`、`A-Z`、`0-9`、`_` 以外的字符会被替换为 `_`(例如旧版 Flux 发送的 `kustomize.toolkit.fluxcd.io/revision` 变为 `kustomize_toolkit_fluxcd_io_revision`),与内置标签同名的键不会覆盖内置标签。值为空的字段不会写入标签。
## 排查问题
----
- **没有收到告警**:执行 `kubectl -n flux-system logs deploy/notification-controller`,查找 `failed to dispatch notification` 等错误;执行 `kubectl -n flux-system get events --field-selector involvedObject.kind=Alert` 查看 Alert 上的告警事件
- **只收到部分对象的告警**:确认对象的 `kind` 列在 `eventSources` 中,且对象与 Alert 在同一命名空间或已填写 `namespace`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/formant.mdx b/zh/on-call/integration/alert-integration/alert-sources/formant.mdx
index 7eb015ee..4a8c70e3 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/formant.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/formant.mdx
@@ -1,5 +1,6 @@
---
title: "Formant 告警集成"
+sidebarTitle: "Formant"
description: "通过 Formant 事件的 Webhook 转发,把机器人和设备事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Formant", "机器人", "设备监控", "Webhook", "事件"]
---
@@ -11,7 +12,6 @@ Formant 事件只发送一次,没有恢复通知,Flashduty 中的告警不
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Formant 事件只发送一次,没有恢复通知,Flashduty 中的告警不
</div>
## 在 Formant 中配置
----
<Steps>
<Step title="创建 Webhook">
@@ -61,19 +60,16 @@ Formant 事件只发送一次,没有恢复通知,Flashduty 中的告警不
</Steps>
## 告警恢复和自动关闭
----
Formant 事件一经触发就不可修改,Webhook 对每个事件只发送一次。请求体中没有表示事件结束或恢复的字段,所以 Flashduty 中的告警不会自动恢复。
每个 Formant 事件对应一条独立的 Flashduty 告警,需要手动关闭,或在接收该集成的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit)。建议 2 小时,并按设备问题的处理时效调整。
## Alert Key
----
Alert Key 为 Formant 事件 ID(`payload.id`)。同一个事件重复投递会合并到同一条告警;不同事件(即使来自同一个事件触发器和同一台设备)是不同的告警。请求中缺少事件 ID 时,Flashduty 会生成随机 Alert Key,这条告警同样不会被合并。
## 状态和告警等级
----
告警的状态等于告警等级,不会恢复。
@@ -86,7 +82,6 @@ Alert Key 为 Formant 事件 ID(`payload.id`)。同一个事件重复投递
| 缺失或其他值 | Warning |
## 告警内容
----
- **标题**:事件消息 `message`;缺失时为 `Formant event on <数据流名称>`,再缺失时为 `Formant event`
- **描述**:设备 ID、数据流、数据点取值、事件时间和 Formant 中的事件链接
@@ -103,7 +98,6 @@ Alert Key 为 Formant 事件 ID(`payload.id`)。同一个事件重复投递
| 设备标签 | 事件 `tags` 中的每个键值;键中的 `.`、`-` 等字符替换为 `_`,不覆盖上面的标签 |
## 排查问题
----
- **Flashduty 没有收到事件**:确认事件的 **Actions** 中已在 **Webhook forwarding** 选择了该 Webhook;确认 Webhook 的 URL 是完整的推送地址,包含 `integration_key`
- **Flashduty 返回参数错误**:请求体不是 JSON,或缺少 `payload` 对象。请使用 Formant 自带的 Webhook 转发,不要改写请求体
diff --git a/zh/on-call/integration/alert-integration/alert-sources/fortimonitor.mdx b/zh/on-call/integration/alert-integration/alert-sources/fortimonitor.mdx
index 2c217946..3ac14d7f 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/fortimonitor.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/fortimonitor.mdx
@@ -1,5 +1,6 @@
---
title: "FortiMonitor 告警集成"
+sidebarTitle: "FortiMonitor"
description: "通过 Webhook 将 FortiMonitor 的故障和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "FortiMonitor", "Panopta", "Fortinet", "Webhook", "Alert Timeline", "outage_id"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "FortiMonitor", "Panopta", "Fortinet", "Webhook", "Al
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "FortiMonitor", "Panopta", "Fortinet", "Webhook", "Al
</div>
## 在 FortiMonitor 中配置
----
<Steps>
<Step title="创建 Webhook 集成">
@@ -43,18 +42,18 @@ keywords: ["告警集成", "FortiMonitor", "Panopta", "Fortinet", "Webhook", "Al
6. **Authentication Method** 选择 **None**
7. **Payload Type** 选择 **Form Variables**,按下表逐行添加变量(变量名区分大小写,值为 FortiMonitor 宏):
-| 变量名 | 值 |
-| :--- | :--- |
-| `trigger` | `$trigger` |
-| `outage_id` | `$outage_id` |
-| `severity` | `$severity` |
-| `name` | `$name` |
-| `fqdn` | `$fqdn` |
-| `server_id` | `$server_id` |
-| `items` | `$items` |
-| `reasons` | `$reasons` |
-| `duration` | `$duration` |
-| `tags` | `$tags` |
+ | 变量名 | 值 |
+ | :--- | :--- |
+ | `trigger` | `$trigger` |
+ | `outage_id` | `$outage_id` |
+ | `severity` | `$severity` |
+ | `name` | `$name` |
+ | `fqdn` | `$fqdn` |
+ | `server_id` | `$server_id` |
+ | `items` | `$items` |
+ | `reasons` | `$reasons` |
+ | `duration` | `$duration` |
+ | `tags` | `$tags` |
8. 点击 **Save**
@@ -92,7 +91,6 @@ FortiMonitor 的 Webhook 请求来自固定 IP:`104.197.35.194/32` 和 `35.185
</Warning>
## 推送内容
----
FortiMonitor 按上表以表单格式 POST 以下字段,每个故障、每次事件单独发送一次请求:
@@ -112,14 +110,12 @@ FortiMonitor 按上表以表单格式 POST 以下字段,每个故障、每次
告警标题为 `<实例名称>: <故障指标>`;实例名称为空时使用完整域名,两者都为空时使用 `FortiMonitor incident <outage_id>`。
## Alert Key
----
Flashduty 使用 `outage_id`(FortiMonitor 故障 ID)作为 Alert Key。同一个故障的发生、升级通知和恢复通知携带相同的 `outage_id`,因此会落在同一条告警上。同一个实例、同一个指标恢复后再次出故障时,FortiMonitor 会生成新的故障 ID,Flashduty 也会生成新的告警。修改实例名称、故障原因或告警等级不会改变 Alert Key。
请求中缺少 `outage_id`,或值仍是未替换的 `$outage_id` 时,Flashduty 会返回参数错误,因为无法把恢复通知关联到原告警。
## 状态和告警等级
----
| FortiMonitor `trigger` | Flashduty 处理 |
| :--- | :--- |
@@ -136,7 +132,6 @@ Flashduty 使用 `outage_id`(FortiMonitor 故障 ID)作为 Alert Key。同
`trigger` 为空或为其他值的请求会被拒绝。
## 常见问题
----
<AccordionGroup>
<Accordion title="告警时间线里有多个通知事件,会产生多条告警吗?">
@@ -159,7 +154,6 @@ Flashduty 使用 `outage_id`(FortiMonitor 故障 ID)作为 Alert Key。同
</AccordionGroup>
## 排查问题
----
- **推送失败**:确认 Postback URL 是完整的推送地址,且包含 `integration_key`;网络有访问限制时放行 FortiMonitor 的推送 IP
- **Flashduty 返回参数错误**:确认 Payload Type 为 Form Variables,变量名与上表一致,且 `trigger`、`outage_id` 的值分别为 `$trigger`、`$outage_id`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/fortisiem.mdx b/zh/on-call/integration/alert-integration/alert-sources/fortisiem.mdx
index 25c8e26d..279e495b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/fortisiem.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/fortisiem.mdx
@@ -1,5 +1,6 @@
---
title: "FortiSIEM 告警集成"
+sidebarTitle: "FortiSIEM"
description: "通过 Incident HTTP Notification 将 FortiSIEM 事件(Incident)的触发、更新和清除同步到 Flashduty On-call。"
keywords: ["告警集成", "FortiSIEM", "Fortinet", "SIEM", "Incident HTTP Notification", "incidentId"]
---
@@ -9,7 +10,6 @@ FortiSIEM 的 Incident HTTP Notification 会在规则触发事件(Incident)
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ FortiSIEM 的 Incident HTTP Notification 会在规则触发事件(Incident)
</div>
## 在 FortiSIEM 中配置
----
<Steps>
<Step title="填写 Incident HTTP Notification">
@@ -56,14 +55,12 @@ Incident HTTP Notification 是 FortiSIEM 的全局通知通道,按官方文档
</Steps>
## Alert Key
----
-Flashduty 直接使用 `incident` 元素的 `incidentId` 属性作为 Alert Key。FortiSIEM 官方文档将其定义为 "Unique ID of the incident in FortiSIEM",`status` 取值为 "New, Update or Clear",同一个 Incident 的各条通知预期使用同一个 `incidentId`。XML 结构来自 FortiSIEM 6.7.0 版 Integration API 指南,请在你的 7.x 版本上用第一条真实通知核对下文字段。规则名称、等级、重复次数、发生时间和事件明细的变化都不会改变 Alert Key。
+Flashduty 直接使用 `incident` 元素的 `incidentId` 属性作为 Alert Key。FortiSIEM 官方文档将其定义为 "Unique ID of the incident in FortiSIEM",`status` 取值为 "New, Update or Clear",同一个 Incident 的各条通知预期使用同一个 `incidentId`。XML 结构来自 FortiSIEM 6.7.0 版 Integration API 指南,请在您的 7.x 版本上用第一条真实通知核对下文字段。规则名称、等级、重复次数、发生时间和事件明细的变化都不会改变 Alert Key。
缺少 `incidentId` 时 Flashduty 会拒绝请求(HTTP 400),因为无法可靠关联后续更新和恢复。
## 状态和告警等级
----
`status` 属性:
@@ -84,7 +81,6 @@ Flashduty 直接使用 `incident` 元素的 `incidentId` 属性作为 Alert Key
| 空值或无法识别 | Warning |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -97,7 +93,6 @@ Flashduty 直接使用 `incident` 元素的 `incidentId` 属性作为 Alert Key
包含用户姓名和邮箱的 `deviceDetails` 不会写入标签。
## 排查问题
----
- **FortiSIEM 侧推送失败**:确认 **HTTP(S) Server URL** 以 `https://` 开头、包含完整的 `integration_key`,且 FortiSIEM 所在网络可以访问 `api.flashcat.cloud`
- **Flashduty 返回参数错误**:确认发送的是 FortiSIEM 的 Incident XML(根元素为 `incident`),且带有 `incidentId` 属性
diff --git a/zh/on-call/integration/alert-integration/alert-sources/gatus.mdx b/zh/on-call/integration/alert-integration/alert-sources/gatus.mdx
index 94fec8f7..ec653d4b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/gatus.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/gatus.mdx
@@ -1,5 +1,6 @@
---
title: "Gatus 告警集成"
+sidebarTitle: "Gatus"
description: "通过 Gatus 的自定义告警提供商(custom provider)将端点的触发和恢复事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Gatus", "健康检查", "Webhook", "custom provider"]
---
@@ -11,7 +12,6 @@ Gatus 没有固定的 Webhook 格式,请求体由您在配置里书写。本
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Gatus 没有固定的 Webhook 格式,请求体由您在配置里书写。本
</div>
## 在 Gatus 中配置
----
<Steps>
<Step title="配置 custom 提供商">
@@ -95,7 +94,6 @@ endpoints:
</Steps>
## Alert Key
----
Flashduty 用端点的 `group` 与 `name` 计算 Alert Key。Gatus 文档用 `<group>_<name>` 标识一个端点,官方没有为单次告警提供独立 ID,因此同一端点的触发、提醒和恢复共用一个 Alert Key;没有分组时只用 `name`。
@@ -104,7 +102,6 @@ Flashduty 用端点的 `group` 与 `name` 计算 Alert Key。Gatus 文档用 `<g
- `url`、`description`、`errors` 的变化不会改变 Alert Key
## 状态和告警等级
----
| Gatus `[ALERT_TRIGGERED_OR_RESOLVED]` | Flashduty 状态或等级 |
| :--- | :--- |
@@ -114,7 +111,6 @@ Flashduty 用端点的 `group` 与 `name` 计算 Alert Key。Gatus 文档用 `<g
Gatus 告警没有等级字段,端点健康检查失败按 Critical 处理。空值或其他状态值会被拒绝。
## 排查问题
----
- **Gatus 日志出现 `status code 400`**:确认 `method` 为 `POST`,请求体是有效 JSON,且 `name`、`status` 非空。Gatus 只对 `[RESULT_ERRORS]` 转义双引号,端点名称、分组或描述里含有双引号、反斜杠或换行时会破坏 JSON,请避免这些字符
- **Gatus 日志出现 `status code 404` 或 `401`**:确认推送地址完整并包含 `integration_key`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/gcp-personalized-service-health.mdx b/zh/on-call/integration/alert-integration/alert-sources/gcp-personalized-service-health.mdx
index 2f74983e..d87a481c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/gcp-personalized-service-health.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/gcp-personalized-service-health.mdx
@@ -1,15 +1,15 @@
---
title: "Google Cloud Personalized Service Health 告警集成"
+sidebarTitle: "Google Cloud Personalized Service Health"
description: "通过 Cloud Monitoring 日志告警策略和 Webhook 通知渠道接收 Personalized Service Health 事件,使用 Flashduty 的 Google Cloud Monitoring 集成,配合超时自动关闭收敛告警。"
keywords: ["告警集成", "Google Cloud", "Personalized Service Health", "Service Health", "Cloud Monitoring", "日志告警", "Webhook"]
---
-Personalized Service Health 把影响你项目的 Google Cloud 事件(事件的创建和更新)写入 Cloud Logging,并与 Cloud Monitoring 的日志告警策略集成。日志告警策略可以通过 Webhook 通知渠道把通知发出去。Flashduty 的 [Google Cloud Monitoring 集成](/zh/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring) 接收这种 Webhook,因此不需要单独的 Personalized Service Health 集成:在 Flashduty 创建 Google Cloud Monitoring 集成,把它的推送地址填进 Webhook 通知渠道,再把渠道用在 Service Health 的告警策略上即可。
+Personalized Service Health 把影响您项目的 Google Cloud 事件(事件的创建和更新)写入 Cloud Logging,并与 Cloud Monitoring 的日志告警策略集成。日志告警策略可以通过 Webhook 通知渠道把通知发出去。Flashduty 的 [Google Cloud Monitoring 集成](/zh/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring) 接收这种 Webhook,因此不需要单独的 Personalized Service Health 集成:在 Flashduty 创建 Google Cloud Monitoring 集成,把它的推送地址填进 Webhook 通知渠道,再把渠道用在 Service Health 的告警策略上即可。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 Google Cloud Monitoring(GCP 云监控)**,不是 Personalized Service Health。
@@ -30,7 +30,6 @@ Personalized Service Health 把影响你项目的 Google Cloud 事件(事件
</div>
## 在 Google Cloud 中配置
----
### 步骤 1:准备
@@ -101,14 +100,12 @@ gcloud logging write --payload-type=json LOG_NAME '{ "category": "INCIDENT", "re
`LOG_NAME` 使用 Service Health 的日志名,Google 文档中的格式为 `projects/PROJECT_ID/logs/servicehealth.googleapis.com%2Factivity`。
## 开启超时自动关闭
----
-对于日志告警策略,Cloud Monitoring 只在事件打开时发送通知,不会在关闭时发送通知(API 中日志告警策略的通知时机固定为 `OPENED`),所以 Flashduty 收不到恢复通知。请在接收这些告警的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),超时计时起点选择 **故障触发**,建议时长 24 小时,再按你所关心事件的常见持续时间调整。
+对于日志告警策略,Cloud Monitoring 只在事件打开时发送通知,不会在关闭时发送通知(API 中日志告警策略的通知时机固定为 `OPENED`),所以 Flashduty 收不到恢复通知。请在接收这些告警的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),超时计时起点选择 **故障触发**,建议时长 24 小时,再按您所关心事件的常见持续时间调整。
告警策略里的 `autoClose` 只决定 Cloud Monitoring 中事件何时关闭(日志告警默认 7 天),不会通知 Flashduty。
## 字段映射
----
| Cloud Monitoring 字段 | Flashduty |
| :--- | :--- |
@@ -123,7 +120,6 @@ gcloud logging write --payload-type=json LOG_NAME '{ "category": "INCIDENT", "re
| `incident.policy_user_labels` | 每个键展开为一个标签 |
## 排查问题
----
- **没有收到告警**:在 **Monitoring** → **Incidents** 确认事件已打开;检查日志过滤条件是否匹配,通知有频率限制(Google 文档中的示例为每个策略每天每个项目 20 条告警)
- **告警没有恢复**:日志告警不发送关闭通知,请开启协作空间的超时自动关闭
diff --git a/zh/on-call/integration/alert-integration/alert-sources/ghost-inspector.mdx b/zh/on-call/integration/alert-integration/alert-sources/ghost-inspector.mdx
index 442b4c74..59484fce 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/ghost-inspector.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/ghost-inspector.mdx
@@ -1,5 +1,6 @@
---
title: "Ghost Inspector 告警集成"
+sidebarTitle: "Ghost Inspector"
description: "通过 Webhook 将 Ghost Inspector 测试的失败和恢复结果同步到 Flashduty On-call。"
keywords: ["告警集成", "Ghost Inspector", "Webhook", "自动化测试", "端到端测试"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Ghost Inspector", "Webhook", "自动化测试", "端
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Ghost Inspector", "Webhook", "自动化测试", "端
</div>
## 在 Ghost Inspector 中配置
----
Ghost Inspector 的通知设置分为账号(Organization)、测试套件(Suite)、单个测试(Test)三个层级,下层默认继承上层设置,也可以单独覆盖。按需要的粒度选择其一配置即可;配置在账号或套件层级可以一次覆盖其下所有测试。
@@ -55,12 +54,10 @@ Ghost Inspector 没有独立的「测试通知」按钮:每次测试运行(
</Steps>
## Alert Key
----
Flashduty 使用测试的 `test._id` 作为 Alert Key,即 Webhook 请求体中 `data.test._id` 字段。Ghost Inspector 每次运行同一个测试都会带上相同的 `test._id`(区别于 `data._id`——这是每次运行结果自身的 ID,每次都不同),因此一个测试的失败和之后的恢复能可靠关联到同一条告警。测试名称、浏览器、地域、起止 URL 等字段的变化不会改变 Alert Key。
## 状态和告警等级
----
Ghost Inspector 不区分告警等级,只有通过或失败两种结果:
@@ -72,7 +69,6 @@ Ghost Inspector 不区分告警等级,只有通过或失败两种结果:
缺少 `passing` 字段的请求会被拒绝,避免把无法判断状态的请求当作失败处理。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -86,7 +82,6 @@ Ghost Inspector 不区分告警等级,只有通过或失败两种结果:
| `passing` | 本次运行是否通过 |
## 排查问题
----
- **Flashduty 返回参数错误**:确认推送地址包含 `integration_key`,且 Payload 中包含 `data.test._id` 和 `data.passing`
- **告警没有恢复**:确认恢复用的是同一个测试,且配置了 Webhook 的层级(测试 / 套件 / 账号)确实覆盖了这个测试
diff --git a/zh/on-call/integration/alert-integration/alert-sources/gitguardian.mdx b/zh/on-call/integration/alert-integration/alert-sources/gitguardian.mdx
index 2f9b51c6..5d9ee926 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/gitguardian.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/gitguardian.mdx
@@ -1,5 +1,6 @@
---
title: "GitGuardian 告警集成"
+sidebarTitle: "GitGuardian"
description: "通过 Custom webhook 将 GitGuardian 检测到的密钥泄露事件(Incident)的触发、更新和关闭同步到 Flashduty On-call。"
keywords: ["告警集成", "GitGuardian", "密钥泄露", "Incident", "Webhook", "Secrets Detection"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "GitGuardian", "密钥泄露", "Incident", "Webhook",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "GitGuardian", "密钥泄露", "Incident", "Webhook",
</div>
## 在 GitGuardian 中配置
----
需要在 GitGuardian 工作区中有管理集成的权限。
@@ -81,14 +80,12 @@ GitGuardian 会为 webhook 生成一个签名令牌(signature token)。Flash
</Steps>
## Alert Key
----
Flashduty 使用 Incident 的 `id`(Webhook 中的 `incident.id`)作为 Alert Key。GitGuardian 官方 Webhook 示例中,同一个 Incident 的 New incident、New occurrence、Resolved、Ignored 和 Reopened 事件携带相同的 `incident.id`。
严重程度、有效性、事件发生次数和检测器名称的变化都不会改变 Alert Key。缺少 `incident.id` 的 Incident 事件会被拒绝。
## 状态和告警等级
----
告警状态由 `action` 决定:`incident_resolved` 和 `incident_ignored` 为恢复,上表中其余事件为触发。已解决或已忽略的 Incident 发生有效性、严重程度或风险评分变化时,该事件会被忽略,不会重新打开告警。Incident 被重新打开后会以同一个 Alert Key 触发新的告警。
@@ -104,7 +101,6 @@ Flashduty 使用 Incident 的 `id`(Webhook 中的 `incident.id`)作为 Alert
`unknown` 表示 GitGuardian 尚未评级,Flashduty 按 Warning 处理。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -121,7 +117,6 @@ Flashduty 使用 Incident 的 `id`(Webhook 中的 `incident.id`)作为 Alert
| `repository` / `filepath` / `occurrence_url` | `new_occurrence` 事件中新泄露位置的仓库、文件路径和链接 |
## 排查问题
----
- **告警没有创建**:确认已勾选对应事件,并检查 webhook 的过滤规则是否排除了该 Incident。GitGuardian 说明 webhook 为尽力投递,不保证送达
- **告警没有恢复**:确认已在 **Incident status change** 下勾选 **Resolved** 和 **Ignored**
diff --git a/zh/on-call/integration/alert-integration/alert-sources/github.mdx b/zh/on-call/integration/alert-integration/alert-sources/github.mdx
index 820b9d2c..27d60b21 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/github.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/github.mdx
@@ -1,5 +1,6 @@
---
title: "GitHub 告警集成"
+sidebarTitle: "GitHub"
description: "通过仓库或组织 Webhook,将 GitHub 的 Dependabot、代码扫描、密钥扫描告警和 Actions 工作流失败同步到 Flashduty On-call,修复后自动恢复。"
keywords: ["告警集成", "GitHub", "Dependabot", "Code scanning", "Secret scanning", "GitHub Actions", "Webhook"]
---
@@ -14,7 +15,6 @@ keywords: ["告警集成", "GitHub", "Dependabot", "Code scanning", "Secret scan
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -35,7 +35,6 @@ keywords: ["告警集成", "GitHub", "Dependabot", "Code scanning", "Secret scan
</div>
## 在 GitHub 中配置
----
Webhook 可以建在单个仓库上,也可以建在组织上(覆盖组织内所有仓库)。仓库 Webhook 需要仓库的 Admin 权限,组织 Webhook 需要组织 Owner 权限。
@@ -83,7 +82,6 @@ GitHub 不会自动重试失败的推送。可在 **Recent Deliveries** 中对 3
</Steps>
## 事件与告警状态
----
GitHub 在请求头 `X-GitHub-Event` 中给出事件类型,在请求体的 `action` 中给出动作。Flashduty 按下表处理:
@@ -97,7 +95,6 @@ GitHub 在请求头 `X-GitHub-Event` 中给出事件类型,在请求体的 `ac
`ping` 和其他事件类型(如误勾选的 `push`)同样返回成功,不创建告警。
## Alert Key
----
- **安全告警**:Alert Key 由事件类型、仓库 ID(`repository.id`)和告警编号(`alert.number`)组成。告警编号在同一仓库、同一类告警内唯一,GitHub 也用它在 API 中定位告警(如 `/repos/{owner}/{repo}/dependabot/alerts/{alert_number}`)。同一条告警从创建到修复、忽略、重新打开,Alert Key 保持不变;仓库改名不会影响 Alert Key。
- **Actions 失败**:Alert Key 由仓库 ID、工作流 ID(`workflow_run.workflow_id`)、发起运行的仓库 ID(`workflow_run.head_repository.id`)和分支(`workflow_run.head_branch`)组成。同一工作流在同一分支上后续的运行(包括 **Re-run**)都合并到这条告警,任何一次成功就恢复。不同分支、不同工作流各自一条告警;来自 Fork 仓库的 Pull Request 即使分支同名,也不会和本仓库的分支合并。没有分支信息的运行按运行 ID(`workflow_run.id`)单独成一条告警,只有这次运行的 **Re-run** 成功时才会恢复。
@@ -105,7 +102,6 @@ GitHub 在请求头 `X-GitHub-Event` 中给出事件类型,在请求体的 `ac
缺少 `repository.id`、`alert.number`、`workflow_run.id` 或 `workflow_run.workflow_id` 的事件会被拒绝。
## 告警不会自动恢复的情况
----
以下情况之后不会再有成功事件,告警不会自动恢复:
@@ -116,7 +112,6 @@ GitHub 在请求头 `X-GitHub-Event` 中给出事件类型,在请求体的 `ac
建议在协作空间开启[超时自动关闭](/zh/on-call/channel/create-edit),超时计时起点选 **故障触发**,超时时长建议 24 小时。工作流失败的正常修复一般在一个工作日内完成;安全告警会在 GitHub 中修复、忽略或关闭时恢复,如果协作空间只接收安全告警,可以不开启。
## 告警等级
----
| 事件 | GitHub 字段 | GitHub 值 | Flashduty 等级 |
| :--- | :--- | :--- | :--- |
@@ -134,7 +129,6 @@ GitHub 在请求头 `X-GitHub-Event` 中给出事件类型,在请求体的 `ac
恢复事件保留告警原有等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -151,7 +145,6 @@ GitHub 在请求头 `X-GitHub-Event` 中给出事件类型,在请求体的 `ac
| `run_id` / `run_number` / `run_attempt` / `run_url` / `head_sha` | 工作流运行 ID、编号、尝试次数、链接和提交 |
## 排查问题
----
- **Recent Deliveries 显示失败**:查看该推送的 **Response**。响应非 `200` 时确认推送地址完整且包含 `integration_key`;GitHub 等待响应最长 10 秒
- **收到 ping 但没有告警**:确认勾选了上文的 4 类事件,且仓库已开启对应的安全功能;取消或跳过的工作流运行不会产生告警,成功的运行只会恢复已有告警
diff --git a/zh/on-call/integration/alert-integration/alert-sources/gitlab.mdx b/zh/on-call/integration/alert-integration/alert-sources/gitlab.mdx
index bec8c011..33f35bbb 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/gitlab.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/gitlab.mdx
@@ -1,5 +1,6 @@
---
title: "GitLab 告警集成"
+sidebarTitle: "GitLab"
description: "通过 Webhook 将 GitLab 的流水线失败、部署失败和安全漏洞同步到 Flashduty On-call,修复后自动恢复。"
keywords: ["告警集成", "GitLab", "Webhook", "CI/CD", "流水线", "部署", "漏洞"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "GitLab", "Webhook", "CI/CD", "流水线", "部署",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "GitLab", "Webhook", "CI/CD", "流水线", "部署",
</div>
## 在 GitLab 中配置
----
GitLab.com、GitLab 自托管版和 GitLab Dedicated 都支持 Webhook。项目 Webhook 所有版本都有,需要项目的 Maintainer 或 Owner 角色;群组 Webhook 需要 Premium 或 Ultimate 版本和群组的 Owner 角色,会推送群组及其子群组下所有项目的事件。
@@ -71,7 +70,6 @@ Vulnerability events 需要 GitLab 17.11 或更高版本(17.7 到 17.10 需要
</Steps>
## Alert Key
----
Flashduty 按业务对象生成 Alert Key,同一对象的触发和恢复事件使用同一个 Alert Key:
@@ -84,7 +82,6 @@ Flashduty 按业务对象生成 Alert Key,同一对象的触发和恢复事件
Alert Key 由对象类型和上表字段共同计算,分支和同名标签、分支和同名环境不会互相合并。项目改名或迁移路径不影响 Alert Key。缺少上表字段的失败或成功事件会被拒绝。
## 状态和告警等级
----
| 事件 | 状态 | Flashduty 等级 |
| :--- | :--- | :--- |
@@ -97,7 +94,6 @@ Alert Key 由对象类型和上表字段共同计算,分支和同名标签、
| 流水线 `success`、部署 `success`、漏洞 `resolved` / `dismissed` | 恢复 | - |
## 告警不会自动恢复的情况
----
以下对象之后不会再有成功事件,告警不会自动恢复:
@@ -108,7 +104,6 @@ Alert Key 由对象类型和上表字段共同计算,分支和同名标签、
建议在协作空间开启[超时自动关闭](/zh/on-call/channel/create-edit),超时计时起点选 **故障触发**,超时时长建议 24 小时。流水线和部署的正常修复一般在一个工作日内完成;漏洞告警会在漏洞被解决或忽略时恢复,如果协作空间只接收漏洞告警,可以不开启。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -130,7 +125,6 @@ Alert Key 由对象类型和上表字段共同计算,分支和同名标签、
流水线变量(`variables`)和用户邮箱不会写入标签。
## 排查问题
----
- **Webhook 显示 Temporarily disabled 或 Disabled**:GitLab 在连续 4 次推送失败后会临时停用 Webhook,连续 40 次失败后永久停用。确认推送地址完整且包含 `integration_key`,然后点击 **Test** 发送一次测试请求重新启用
- **部署被驳回后收到告警**:受保护环境的部署被驳回时,GitLab 先推送 `rejected`,丢弃部署作业后再推送同一部署的 `failed`,Flashduty 会按部署失败创建告警,可手动关闭或等下一次成功部署恢复
diff --git a/zh/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring.mdx b/zh/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring.mdx
index 73231149..1b629c6b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring.mdx
@@ -1,5 +1,6 @@
---
title: "GoogleCloudMonitoring 告警事件"
+sidebarTitle: "GoogleCloudMonitoring"
description: "通过 webhook 或 Pub/Sub 推送订阅,把 Google Cloud Monitoring、Error Reporting、Security Command Center 和 Cloud Billing 预算告警同步到 Flashduty On-call"
keywords: ["告警集成", "GoogleCloudMonitoring 告警事件", "Google Cloud", "Pub/Sub", "Error Reporting", "Security Command Center", "预算告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "GoogleCloudMonitoring 告警事件", "Google Cloud",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "GoogleCloudMonitoring 告警事件", "Google Cloud",
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "GoogleCloudMonitoring 告警事件", "Google Cloud",
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **GCP 云监控** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,7 +46,6 @@ keywords: ["告警集成", "GoogleCloudMonitoring 告警事件", "Google Cloud",
</div>
## 在 Google Cloud
----
<div className="md-block">
@@ -61,13 +60,15 @@ keywords: ["告警集成", "GoogleCloudMonitoring 告警事件", "Google Cloud",
下文的 **推送地址** 指上一步复制的集成推送地址,形如 `https://api.flashcat.cloud/event/push/alert/google-cm?integration_key=<集成密钥>`。
-## 一、Cloud Monitoring:Webhook 通知渠道
+<span id="webhook-channel"></span>
+
+## Cloud Monitoring:Webhook 通知渠道
### 步骤1:配置告警通道
1. 登录 GoogleCloud 控制台,检索 `Monitoring` 产品,并进入对应产品控制台
2. 在左侧菜单中找到 `Alerting` 并点击 `EDIT NOTIFICATION CHANNELS` 创建通道。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/google-cm-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/google-cm-1.png" />
3. 在 Notification channels 页面找到 `Webhooks` 并点击 `ADD NEW`。
4. 在 `Endpoint URL` 处输入集成的推送地址(当前页面填写集成名称,保存后即可生成地址。
@@ -89,20 +90,20 @@ keywords: ["告警集成", "GoogleCloudMonitoring 告警事件", "Google Cloud",
指标告警、正常运行时间检查、基于日志的告警和 PromQL 告警(Managed Service for Prometheus)都通过告警策略发送,配置方式相同。
-## 二、Cloud Monitoring:Pub/Sub 通知渠道
+## Cloud Monitoring:Pub/Sub 通知渠道
如果您的组织要求告警经 Pub/Sub 转发,可以使用 Pub/Sub 通知渠道。告警的 Alert Key 与 Webhook 渠道相同(`incident_id`),两种渠道可以互相替换。
-1. 按 **第六节 创建 Pub/Sub 推送订阅** 创建主题和推送订阅。
+1. 按 [创建 Pub/Sub 推送订阅](#pubsub-subscription) 创建主题和推送订阅。
2. 在 `Alerting` → `EDIT NOTIFICATION CHANNELS` 的 `Pub/Sub` 部分点击 `ADD NEW`,填写主题名称。
3. 按页面提示,为 `service-<项目编号>@gcp-sa-monitoring-notification.iam.gserviceaccount.com` 授予该主题的 `Pub/Sub Publisher` 角色。
4. 在告警策略的 `Notification channels` 中选择该 Pub/Sub 渠道,并勾选 `Notify on incident closure`。
-## 三、Error Reporting
+## Error Reporting
Error Reporting 通过 Cloud Monitoring 的 Webhook 通知渠道发送通知(1.0 版本格式),只支持 Webhook,不支持 Pub/Sub。
-1. 按 **第一节步骤1** 创建一个 Webhook 通知渠道(可以复用同一个 **Flashduty** 渠道)。
+1. 按 [Webhook 通知渠道](#webhook-channel) 的步骤 1 创建一个 Webhook 通知渠道(可以复用同一个 **Flashduty** 渠道)。
2. 进入 `Error Reporting` 页面,点击 `Configure notifications`。
3. 在 `Notification channels` 中选择 **Flashduty** 渠道并保存。
@@ -112,11 +113,11 @@ Error Reporting 在以下两种情况发送通知:出现无法归入已有错
- Error Reporting 不发送"已解决"通知,告警不会自动恢复,请在 Flashduty 中手动关闭。
- 告警等级固定为 Warning。如需其他等级,在推送地址后追加 `&severity=Critical`(或 `Info`)。
-## 四、Security Command Center
+## Security Command Center
Security Command Center(SCC)只能把发现(finding)持续导出到 Pub/Sub,再由推送订阅转发给 Flashduty。
-1. 按 **第六节 创建 Pub/Sub 推送订阅** 创建主题和推送订阅。
+1. 按 [创建 Pub/Sub 推送订阅](#pubsub-subscription) 创建主题和推送订阅。
2. 为 SCC 服务账号授予主题的 `Pub/Sub Publisher` 角色,然后创建持续导出(NotificationConfig),例如:
```bash
@@ -135,11 +136,11 @@ gcloud scc notifications create flashduty-findings \
- 发现 `state` 变为 `INACTIVE`(已修复、资源已删除或手动标记),或 `mute` 变为 `MUTED` 时,告警恢复;再次变为 `ACTIVE` 或 `UNMUTED` 时重新触发。
- 威胁类发现(例如 Event Threat Detection)不会自动变为 INACTIVE,需要在 SCC 中手动修改状态或静音。
-## 五、Cloud Billing 预算
+## Cloud Billing 预算
预算告警只能通过 Pub/Sub 以程序化通知的方式发出。
-1. 按 **第六节 创建 Pub/Sub 推送订阅** 创建主题和推送订阅。
+1. 按 [创建 Pub/Sub 推送订阅](#pubsub-subscription) 创建主题和推送订阅。
2. 进入 `Billing` → `Budgets & alerts`,创建或编辑预算,设置阈值规则(实际费用和/或预测费用)。
3. 在 `Manage notifications` 中勾选 `Connect a Pub/Sub topic to this budget`,选择上面的主题并保存。
@@ -150,7 +151,9 @@ Cloud Billing 每天会向主题多次推送预算的当前状态,首次推送
- Alert Key 由结算账号、预算、预算周期、费用类型和已超过的最高阈值组成:同一阈值的重复推送合并为一条告警;超过更高阈值时产生一条新告警。
- 预算告警不会自动恢复。新的预算周期开始后,告警按新周期重新计算,旧周期的告警请手动关闭。
-## 六、创建 Pub/Sub 推送订阅
+<span id="pubsub-subscription"></span>
+
+## 创建 Pub/Sub 推送订阅
第二、四、五节共用以下步骤。一个推送订阅可以同时承载多种来源。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/google-scc.mdx b/zh/on-call/integration/alert-integration/alert-sources/google-scc.mdx
index 7104d08a..0e899cac 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/google-scc.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/google-scc.mdx
@@ -1,5 +1,6 @@
---
title: "Google Security Command Center 告警集成"
+sidebarTitle: "Google Security Command Center"
description: "通过 Pub/Sub 推送订阅,将 Google Security Command Center 的 Finding 通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Google Security Command Center", "SCC", "Pub/Sub", "Finding"]
---
@@ -9,7 +10,6 @@ Google Security Command Center(SCC)把 Finding 的新增和更新发布到 P
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Google Security Command Center(SCC)把 Finding 的新增和更新发布到 P
</div>
## 在 Google Cloud 中配置
----
需要一个已启用 Security Command Center 的组织,以及一个存放 Pub/Sub 主题的项目。创建通知配置需要组织上的 Security Center Admin(`roles/securitycenter.admin`)权限,以及主题所在项目的 Project IAM Admin(`roles/resourcemanager.projectIamAdmin`)权限。
@@ -88,14 +87,12 @@ Pub/Sub 推送订阅没有测试按钮。让 SCC 产生一个符合过滤条件
</Steps>
## Alert Key
----
Flashduty 使用 `finding.name` 作为 Alert Key,格式为 `organizations/{组织 ID}/sources/{来源 ID}/findings/{Finding ID}`。SCC 的 Finding 资源定义里,`name` 是 Finding 的相对资源名称,同一个 Finding 的新增、更新和变为 `INACTIVE` 的通知都携带相同的值。
标题、等级、状态、类别、事件时间的变化都不会改变 Alert Key。缺少 `finding.name` 的请求会被拒绝,因为无法可靠关联后续更新和恢复。
## 状态和告警等级
----
| SCC 字段 | Flashduty 状态或等级 |
| :--- | :--- |
@@ -112,7 +109,6 @@ Flashduty 使用 `finding.name` 作为 Alert Key,格式为 `organizations/{组
Flashduty 还会把以下字段写入标签:`category`、`resource_name`、`resource_type`、`project`、`location`、`service`、`finding_name`、`finding_state`、`finding_severity`、`finding_class`、`finding_source`、`notification_config_name`、`external_uri`。不会读取 `securityMarks`。
## 排查问题
----
- **Pub/Sub 反复重发同一条消息**:Flashduty 对无法解析的请求返回 4xx,Pub/Sub 会按退避策略重发。检查推送端点是否带有 `integration_key`,以及是否误开了 payload unwrapping;可为订阅配置死信主题,避免无限重试
- **Flashduty 返回参数错误**:错误信息会指出缺失的字段,例如 `finding.name is required` 表示通知里没有 Finding
diff --git a/zh/on-call/integration/alert-integration/alert-sources/grafana.mdx b/zh/on-call/integration/alert-integration/alert-sources/grafana.mdx
index 90dad4ac..181864de 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/grafana.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/grafana.mdx
@@ -1,12 +1,12 @@
---
-title: "Grafana集成"
+title: "Grafana 集成"
+sidebarTitle: "Grafana"
description: "通过 webhook 的方式同步 Grafana 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理。"
keywords: ["告警集成", "Grafana集成", "监控告警", "数据接入"]
---
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -14,7 +14,7 @@ keywords: ["告警集成", "Grafana集成", "监控告警", "数据接入"]
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -30,9 +30,9 @@ keywords: ["告警集成", "Grafana集成", "监控告警", "数据接入"]
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Grafana** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -43,19 +43,18 @@ keywords: ["告警集成", "Grafana集成", "监控告警", "数据接入"]
</AccordionGroup>
</div>
-## 在 Grafana
----
+## 在 Grafana
Grafana V4~V8 版本默认开启 Legacy Alerting 功能,在 V9 之后默认开启 Grafana Alerting 功能,功能区分以及启用方式请参考[官方文档](https://grafana.com/docs/grafana/v8.4/alerting/unified-alerting/opt-in/#opt-in-to-grafana-alerting),请您根据您部署的版本进行集成,步骤如下。
### Legacy Alerting
<div className="md-block">
-1. 打开您的 Grafana 控制台,选择 Alerting > Notification channels 页面
+1. 打开您的 Grafana 控制台,选择 Alerting → Notification channels 页面
2. 点击 Add Channel,打开配置 Channel 弹窗页面
3. 配置名称,Type 选择 webhook,Url 填写集成的推送地址, Method 选择 POST,如下图所示:
-<img src="https://download.flashcat.cloud/grafana-legacy-alerting.png" alt="drawing" width="600"/>
+ <img src="https://download.flashcat.cloud/grafana-legacy-alerting.png" alt="drawing" width="600"/>
4. 保存,回到集成列表,等待产生告警后,如果展示了最新事件时间,说明配置成功且收到事件
5. 完成
@@ -66,27 +65,26 @@ Grafana V4~V8 版本默认开启 Legacy Alerting 功能,在 V9 之后默认开
<div className="md-block">
-1. 打开您的 Grafana 控制台,选择 Alerting > Contact points 页面
+1. 打开您的 Grafana 控制台,选择 Alerting → Contact points 页面
2. 点击 New contact point,打开配置弹窗页面
3. 配置名称,Type 选择 webhook,Url 填写集成的推送地址, Method 选择 POST,如下图所示:
-<img src="https://download.flashcat.cloud/grafana-contact-point.png" alt="drawing" width="600"/>
+ <img src="https://download.flashcat.cloud/grafana-contact-point.png" alt="drawing" width="600"/>
4. 打开 Notification policies 页面,根据情况编辑或新增 policy,选择上一步创建的 contact point 作为发送渠道,如下图所示:
-<img src="https://download.flashcat.cloud/grafana-notification-policy.png" alt="drawing" width="600"/>
+ <img src="https://download.flashcat.cloud/grafana-notification-policy.png" alt="drawing" width="600"/>
5. 保存,回到集成列表,等待产生告警后,如果展示了最新事件时间,说明配置成功且收到事件
6. 默认告警等级为 warning,如果需要自定义,可以在告警详情页面配置 severity 标签(枚举参考下文状态对照),具体操作如下图所示:
-<img src="https://download.flashcat.cloud/grafana-alert-rule.png" alt="drawing" width="600"/>
+ <img src="https://download.flashcat.cloud/grafana-alert-rule.png" alt="drawing" width="600"/>
7. 完成
</div>
## 状态对照
----
<div className="md-block">
Legacy Alerting 到 Flashduty 告警等级映射关系:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/graylog.mdx b/zh/on-call/integration/alert-integration/alert-sources/graylog.mdx
index 81257308..0d31e30d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/graylog.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/graylog.mdx
@@ -1,5 +1,6 @@
---
title: "Graylog 告警事件"
+sidebarTitle: "Graylog"
description: "通过 webhook 的方式同步Graylog告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "Graylog 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "Graylog 告警事件", "监控告警", "数据接入
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "Graylog 告警事件", "监控告警", "数据接入
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "Graylog 告警事件", "监控告警", "数据接入
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Graylog** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,10 +46,8 @@ keywords: ["告警集成", "Graylog 告警事件", "监控告警", "数据接入
## 在 Graylog
----
<div className="md-block">
-## 一、Graylog 告警推送配置
### 步骤1:配置告警通道
1. 登录 Graylog 控制台。
@@ -58,15 +56,15 @@ keywords: ["告警集成", "Graylog 告警事件", "监控告警", "数据接入
4. 输入 Title 和 Description。
5. Notification Type 选择 **HTTP Notification**,如下图。
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-2.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-2.png" />
6. 输入 Flashduty 获取到的 URL (第一次输入需要对 URL 加白)。
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-3.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-3.png" />
7. 点击 Save 保存加白的 URL
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-1.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-1.png" />
8. 保存后,提交 Create。
@@ -83,7 +81,7 @@ keywords: ["告警集成", "Graylog 告警事件", "监控告警", "数据接入
<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/graylog-4.png" />
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/guance.mdx b/zh/on-call/integration/alert-integration/alert-sources/guance.mdx
index 1a96f4b6..5a9cfef8 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/guance.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/guance.mdx
@@ -1,5 +1,6 @@
---
title: "观测云告警事件"
+sidebarTitle: "观测云"
description: "通过 webhook 的方式同步观测云告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "观测云告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "观测云告警事件", "监控告警", "数据接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "观测云告警事件", "监控告警", "数据接
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "观测云告警事件", "监控告警", "数据接
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **观测云** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,11 +45,9 @@ keywords: ["告警集成", "观测云告警事件", "监控告警", "数据接
</div>
## 在观测云
----
<div className="md-block">
-## 一、告警推送配置
### 步骤1:创建通知对象
1. 登录您的 `观测云` 控制台,在 `监控` 中,选择 `通知对象管理`。
@@ -72,7 +70,7 @@ keywords: ["告警集成", "观测云告警事件", "监控告警", "数据接
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/hackerone.mdx b/zh/on-call/integration/alert-integration/alert-sources/hackerone.mdx
index 8648ae31..01544533 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/hackerone.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/hackerone.mdx
@@ -1,5 +1,6 @@
---
title: "HackerOne 告警集成"
+sidebarTitle: "HackerOne"
description: "通过 Webhook 将 HackerOne 项目中漏洞报告的提交、分诊和关闭事件同步到 Flashduty On-call。"
keywords: ["告警集成", "HackerOne", "漏洞报告", "Webhook", "漏洞悬赏"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "HackerOne", "漏洞报告", "Webhook", "漏洞悬赏
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "HackerOne", "漏洞报告", "Webhook", "漏洞悬赏
</div>
## 在 HackerOne 中配置
----
Webhook 按项目配置,并继承创建者的权限:创建者需要能查看该项目的报告,并有权修改项目设置。
@@ -79,14 +78,12 @@ Webhook 按项目配置,并继承创建者的权限:创建者需要能查看
</Steps>
## Alert Key
----
Flashduty 使用报告 ID(Webhook 中的 `data.report.id`)作为 Alert Key。HackerOne 的每次推送都携带该报告的完整信息,同一份报告在提交、分诊、关闭、重新打开时的 `data.report.id` 相同,它也是报告地址 `https://hackerone.com/reports/<id>` 中的编号。
标题、状态、严重程度的变化都不会改变 Alert Key。含有报告但缺少 `data.report.id` 的推送会被拒绝。
## 状态和告警等级
----
告警状态由报告当前状态(`data.report.attributes.state`)决定,而不是事件名:
@@ -111,7 +108,6 @@ Flashduty 使用报告 ID(Webhook 中的 `data.report.id`)作为 Alert Key
分诊时调整了严重程度的报告,会以新的等级更新原告警。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -126,7 +122,6 @@ Flashduty 使用报告 ID(Webhook 中的 `data.report.id`)作为 Alert Key
告警描述为报告的漏洞详情(`vulnerability_information`),超过 8 KB 的部分会被截断。
## 排查问题
----
- **HackerOne 显示推送失败**:在 Webhook 编辑页的 **Recent deliveries** 中点开失败的请求,在 **Response** 中查看 Flashduty 的返回信息;确认 **Payload URL** 完整且包含 `integration_key`
- **告警没有恢复**:确认已勾选 `report_resolved` 和四个 `report_closed_as_*` 事件。未勾选这些事件时关闭的报告,对应告警需在 Flashduty 中手动关闭
diff --git a/zh/on-call/integration/alert-integration/alert-sources/harbor.mdx b/zh/on-call/integration/alert-integration/alert-sources/harbor.mdx
index a581fb02..576efb6e 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/harbor.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/harbor.mdx
@@ -1,5 +1,6 @@
---
title: "Harbor 告警集成"
+sidebarTitle: "Harbor"
description: "通过 webhook 的方式同步 Harbor 的告警事件到 Flashduty,实现告警事件自动化降噪处理"
keywords: ["Harbor", "告警集成", "webhook", "容器镜像"]
---
@@ -18,7 +19,7 @@ keywords: ["Harbor", "告警集成", "webhook", "容器镜像"]
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
-<Accordion title="展开">
+<Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
3. 选择 **Harbor** 集成,点击 **保存**,生成卡片。
@@ -29,8 +30,8 @@ keywords: ["Harbor", "告警集成", "webhook", "容器镜像"]
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
-<Accordion title="展开">
-1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+<Accordion title="查看共享集成的配置步骤">
+1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Harbor** 集成:
- **集成名称**:为当前集成定义一个名称。
- **推送模式**:选择告警在何种情况下触发或恢复告警。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/harness.mdx b/zh/on-call/integration/alert-integration/alert-sources/harness.mdx
index d465e43e..79d83236 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/harness.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/harness.mdx
@@ -1,5 +1,6 @@
---
title: "Harness 告警集成"
+sidebarTitle: "Harness"
description: "通过 Harness 流水线通知的 Webhook 方式,将流水线失败、阶段失败和触发器失败同步到 Flashduty On-call,再次成功后自动恢复。"
keywords: ["告警集成", "Harness", "Webhook", "CI/CD", "流水线", "Pipeline", "部署"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Harness", "Webhook", "CI/CD", "流水线", "Pipeline
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Harness", "Webhook", "CI/CD", "流水线", "Pipeline
</div>
## 在 Harness 中配置
----
Harness SaaS 的各个版本都可以在流水线上配置通知规则,需要对该流水线有 **Create/Edit** 权限。以下步骤在单条流水线上配置;如果账号开启了集中通知(Centralised Notifications),也可以在 **Account Settings → Notification Rules** 中为多条流水线统一配置,事件和通知方式的选择与下面相同。
@@ -80,7 +79,6 @@ Harness SaaS 的各个版本都可以在流水线上配置通知规则,需要
</Steps>
## Alert Key
----
Flashduty 按流水线和阶段生成 Alert Key,同一对象的失败和成功事件使用同一个 Alert Key:
@@ -95,7 +93,6 @@ Flashduty 按流水线和阶段生成 Alert Key,同一对象的失败和成功
同时勾选流水线事件和阶段事件时,一次失败会产生两条告警:一条是流水线告警,一条是失败阶段的告警。只需要一个层级时,只勾选该层级的事件。
## 状态和告警等级
----
| 事件 | 状态 | Flashduty 等级 |
| :--- | :--- | :--- |
@@ -105,7 +102,6 @@ Flashduty 按流水线和阶段生成 Alert Key,同一对象的失败和成功
| `PipelineSuccess`、`StageSuccess` | 恢复 | - |
## 告警不会自动恢复的情况
----
以下情况之后不会再有同一对象的成功事件,告警不会自动恢复:
@@ -116,7 +112,6 @@ Flashduty 按流水线和阶段生成 Alert Key,同一对象的失败和成功
建议在协作空间开启[超时自动关闭](/zh/on-call/channel/create-edit),超时计时起点选 **故障触发**,超时时长建议 12 小时。流水线的正常修复一般在当天完成,未恢复的告警会在超时后关闭。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -134,7 +129,6 @@ Flashduty 按流水线和阶段生成 Alert Key,同一对象的失败和成功
用户邮箱不会写入标签。
## 排查问题
----
- **收不到告警**:确认通知规则处于启用状态,**Notification Method** 为 **Webhook**,推送地址完整且包含 `integration_key`;使用 Delegate 连接时,确认 Delegate 可以访问 Flashduty 的推送地址
- **告警不恢复**:确认勾选了 **Pipeline Success**(或 **Stage Success**),并且之后同一条流水线有一次成功运行
diff --git a/zh/on-call/integration/alert-integration/alert-sources/healthchecks-io.mdx b/zh/on-call/integration/alert-integration/alert-sources/healthchecks-io.mdx
index a019adfb..5163b470 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/healthchecks-io.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/healthchecks-io.mdx
@@ -1,5 +1,6 @@
---
title: "Healthchecks.io 告警集成"
+sidebarTitle: "Healthchecks.io"
description: "通过 Webhook 将 Healthchecks.io 检查的宕机和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Healthchecks.io", "Cron", "心跳监控", "Webhook"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "Healthchecks.io", "Cron", "心跳监控", "Webhook"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ keywords: ["告警集成", "Healthchecks.io", "Cron", "心跳监控", "Webhook"]
</div>
## 在 Healthchecks.io 中配置
----
<Steps>
<Step title="添加 Webhook 集成">
@@ -94,7 +93,6 @@ keywords: ["告警集成", "Healthchecks.io", "Cron", "心跳监控", "Webhook"]
</Steps>
## 推送内容
----
| 字段 | 占位符 | 说明 | 在 Flashduty 中的用途 |
| :--- | :--- | :--- | :--- |
@@ -110,14 +108,12 @@ keywords: ["告警集成", "Healthchecks.io", "Cron", "心跳监控", "Webhook"]
告警标题使用检查名称;名称为空时依次使用 slug、`Healthchecks.io check <code>`。每条告警还带有标签 `source=healthchecks-io`。
## Alert Key
----
Flashduty 使用 `$CODE`(即 `code`,检查的 UUID)作为 Alert Key。同一个检查的宕机和恢复通知携带相同的 UUID,因此会落在同一条告警上;不同检查即使名称相同,也会生成不同的告警。修改检查名称、slug 或标签不会改变 Alert Key。
删除后重新创建的检查会得到新的 UUID,与旧告警不再关联。
## 状态和告警等级
----
Healthchecks.io 的通知不区分严重程度,Flashduty 按下表映射:
@@ -129,7 +125,6 @@ Healthchecks.io 的通知不区分严重程度,Flashduty 按下表映射:
空值或其他 `status` 会被拒绝。
## 常见问题
----
<AccordionGroup>
<Accordion title="检查持续宕机时会重复推送吗?">
@@ -152,7 +147,6 @@ Healthchecks.io 的通知不区分严重程度,Flashduty 按下表映射:
</AccordionGroup>
## 排查问题
----
- **Flashduty 返回参数错误**:确认方法为 POST,请求体是上面的 JSON,`code` 和 `status` 保留原样
- **JSON 解析失败**:检查标签中是否包含双引号或反斜杠。`$TAGS` 会原样插入,这类字符会让请求体不再是合法 JSON;请修改标签,或从模板中删除 `tags` 一行
diff --git a/zh/on-call/integration/alert-integration/alert-sources/hertzbeat.mdx b/zh/on-call/integration/alert-integration/alert-sources/hertzbeat.mdx
index 3f5f4563..00f0fb0c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/hertzbeat.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/hertzbeat.mdx
@@ -1,5 +1,6 @@
---
title: "Apache HertzBeat 告警集成"
+sidebarTitle: "Apache HertzBeat"
description: "通过 Apache HertzBeat 通知接收人(Notice Receiver)的 Webhook,将 HertzBeat 的告警和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Apache HertzBeat", "HertzBeat", "Webhook", "通知接收人", "监控", "告警规则"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Apache HertzBeat", "HertzBeat", "Webhook", "通知
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Apache HertzBeat", "HertzBeat", "Webhook", "通知
</div>
## 在 HertzBeat 中配置
----
<Steps>
<Step title="新增接收对象">
@@ -60,7 +59,6 @@ Flashduty 只解析 HertzBeat 自带的默认 Webhook 模板。如果修改了
</Warning>
## 推送内容
----
HertzBeat 以 JSON 格式 POST 默认模板,一次请求可包含多条告警(`alerts`),Flashduty 逐条处理:
@@ -78,14 +76,12 @@ HertzBeat 以 JSON 格式 POST 默认模板,一次请求可包含多条告警
`commonLabels` 和 `commonAnnotations` 不被读取。
## Alert Key
----
HertzBeat 的推送内容不含告警 ID。Flashduty 使用 `alerts[].labels` 中的 `alertname`、`instance` 和 `defineid` 三项组合生成 Alert Key。在 HertzBeat 1.9.0 的实际推送中,这三项在告警触发、持续告警重复通知和恢复时完全一致,因此三类通知落在同一条 Flashduty 告警上。修改等级、内容或监控名称不会改变 Alert Key。
请求中缺少 `labels.alertname` 时,Flashduty 返回参数错误,因为无法可靠地把恢复通知关联到原告警。`instance` 或 `defineid` 缺失时按空值参与计算。
## 状态和告警等级
----
| HertzBeat 字段 | Flashduty 状态或等级 |
| :--- | :--- |
@@ -98,7 +94,6 @@ HertzBeat 的推送内容不含告警 ID。Flashduty 使用 `alerts[].labels`
`status` 为其他值或 `alerts` 为空的请求会被拒绝。`commonLabels.severity` 在默认模板中被改写成带图标的文字(如 "Critical"),不用于判断等级。
## 常见问题
----
<AccordionGroup>
<Accordion title="点击发送测试消息后 Flashduty 出现了什么?">
@@ -121,7 +116,6 @@ HertzBeat 的推送内容不含告警 ID。Flashduty 使用 `alerts[].labels`
</AccordionGroup>
## 排查问题
----
- **Flashduty 没有收到告警**:确认 URL 是完整的推送地址(含 `integration_key`),并确认已配置通知策略且告警命中该策略
- **Flashduty 返回参数错误**:确认请求体为 HertzBeat 默认模板的 JSON,`status` 为 `firing` 或 `resolved`,且每条告警含 `labels.alertname`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/hetrixtools.mdx b/zh/on-call/integration/alert-integration/alert-sources/hetrixtools.mdx
index 3a041a11..056ec7e4 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/hetrixtools.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/hetrixtools.mdx
@@ -1,5 +1,6 @@
---
title: "HetrixTools 告警集成"
+sidebarTitle: "HetrixTools"
description: "通过联系人列表的 Webhook 将 HetrixTools 可用性监控、服务器资源告警和黑名单监控通知同步到 Flashduty On-call。"
keywords: ["告警集成", "HetrixTools", "Webhook", "可用性监控", "黑名单监控"]
---
@@ -13,7 +14,6 @@ keywords: ["告警集成", "HetrixTools", "Webhook", "可用性监控", "黑名
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -34,7 +34,6 @@ keywords: ["告警集成", "HetrixTools", "Webhook", "可用性监控", "黑名
</div>
## 在 HetrixTools 中配置
----
<Steps>
<Step title="创建联系人列表">
@@ -70,14 +69,12 @@ HetrixTools 按联系人列表投递通知:只有分配了该联系人列表
</Tip>
## Alert Key
----
**可用性监控**:Flashduty 用 `monitor_id`(HetrixTools 监控 ID)计算 Alert Key。同一个监控的离线(`offline`)和在线(`online`)通知携带相同的 `monitor_id`,因此会落在同一条告警上;持续离线期间的重复通知也会合并到这条告警。监控名称、地址、分类、时间和失败位置的变化都不会改变 Alert Key。请求缺少 `monitor_id` 时 Flashduty 会拒绝,因为无法关联后续恢复。
**服务器资源告警和黑名单监控**:HetrixTools 不会为这两类通知发送恢复消息,Flashduty 为每次通知(黑名单通知中的每个 IP 或域名)生成一条独立告警,处理后请手动关闭。
## 状态和告警等级
----
可用性监控按 `monitor_status` 处理:
@@ -99,7 +96,6 @@ HetrixTools 按联系人列表投递通知:只有分配了该联系人列表
黑名单监控按 `blacklisted_now` 定级:大于 0(仍在黑名单中)为 Warning,等于 0(已从所有黑名单移除)为 Info。
## 告警内容
----
**可用性监控**
@@ -120,7 +116,6 @@ HetrixTools 按联系人列表投递通知:只有分配了该联系人列表
- **标签**:`check`(监控标签)、`resource`(IP 或域名)、`source`、`notification`(固定为 `blacklist`)、`blacklisted_before`、`blacklisted_now`、`blacklisted_on`(逗号分隔)、`report_link`
## 排查问题
----
- **HetrixTools 投递失败**:确认 Webhook 填写的是完整推送地址且包含 `integration_key`
- **Flashduty 返回参数错误**:可用性和资源告警通知需要 `monitor_id`,可用性通知的 `monitor_status` 需为 `offline` 或 `online`;黑名单通知中每一项需要 `monitor`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/honeybadger.mdx b/zh/on-call/integration/alert-integration/alert-sources/honeybadger.mdx
index a991952e..8529578c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/honeybadger.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/honeybadger.mdx
@@ -1,5 +1,6 @@
---
title: "Honeybadger 告警集成"
+sidebarTitle: "Honeybadger"
description: "通过 Webhook 将 Honeybadger 项目的错误、可用性检查和 Check-in 事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Honeybadger", "Webhook", "错误监控", "可用性监控", "Check-in"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Honeybadger", "Webhook", "错误监控", "可用性
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Honeybadger", "Webhook", "错误监控", "可用性
</div>
## 在 Honeybadger 中配置
----
Webhook 集成按项目配置,只有 Honeybadger 的 Team、Business 和 Enterprise 套餐提供,需要项目的管理员权限。
@@ -78,7 +77,6 @@ Webhook 集成按项目配置,只有 Honeybadger 的 Team、Business 和 Enter
</Steps>
## Alert Key
----
Flashduty 按事件的对象生成 Alert Key,同一对象的触发和恢复事件使用同一个 Alert Key:
@@ -93,7 +91,6 @@ Flashduty 按事件的对象生成 Alert Key,同一对象的触发和恢复事
Alert Key 由对象类型和上表中的 ID 共同计算,因此证书过期告警不会被同一站点的 `up` 事件恢复,数字相同的错误 ID 和项目 ID 也不会互相合并。错误消息、环境、发生次数、站点名称等字段变化不会改变 Alert Key。缺少对应 ID 的事件会被拒绝。
## 状态和告警等级
----
Honeybadger 事件不携带等级,Flashduty 按事件名确定状态和等级:
@@ -107,7 +104,6 @@ Honeybadger 事件不携带等级,Flashduty 按事件名确定状态和等级
`cert_will_expire` 和 `volume_spike` 没有对应的恢复事件,处理后需在 Flashduty 中手动关闭告警。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -130,7 +126,6 @@ Honeybadger 事件不携带等级,Flashduty 按事件名确定状态和等级
| `url` | Honeybadger 中对应错误、检查或 Check-in 页面的链接 |
## 排查问题
----
- **集成列表中没有 Webhook**:确认项目所属账号的套餐为 Team 或更高,并且您是项目管理员
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/honeycomb.mdx b/zh/on-call/integration/alert-integration/alert-sources/honeycomb.mdx
index b6f9d5e6..63d52cf6 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/honeycomb.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/honeycomb.mdx
@@ -1,5 +1,6 @@
---
title: "Honeycomb 告警集成"
+sidebarTitle: "Honeycomb"
description: "通过 Webhook 接收方的自定义 Payload 模板,将 Honeycomb Trigger 和 SLO Burn Alert 的触发与恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Honeycomb", "Trigger", "SLO", "Burn Alert", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Honeycomb", "Trigger", "SLO", "Burn Alert", "Webhook
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Honeycomb", "Trigger", "SLO", "Burn Alert", "Webhook
</div>
## 在 Honeycomb 中配置
----
以下步骤需要能编辑 **Team Settings** 中集成的 Honeycomb 账号。Trigger 在所有套餐中可用;SLO 和 Burn Alert 需要 Pro 或 Enterprise 套餐。
@@ -156,7 +155,6 @@ Trigger 和 Burn Alert 的 **Test** 会发送 `is_test` 为 `true` 的测试通
</Steps>
## Alert Key
----
Flashduty 直接使用 `instance_id`(`.Alert.InstanceID`)作为 Alert Key。Honeycomb 在模板变量说明中将它定义为一次 Trigger 或 Burn Alert 触发的唯一标识,可用于去重和关联告警;Honeycomb 官方的 incident.io 模板也用它作为 `deduplication_key`,在 `OK` 时解决对应告警。
@@ -167,7 +165,6 @@ Flashduty 直接使用 `instance_id`(`.Alert.InstanceID`)作为 Alert Key。
使用 **Group resolution alerts** 时,Flashduty 同样按 `instance_id` 合并通知,收到 `status` 为 `OK` 的通知时恢复告警;告警描述列出当前越过阈值的分组。
## 状态和告警等级
----
Flashduty 根据 `status` 判断触发或恢复,根据 `severity` 变量确定告警等级。
@@ -181,7 +178,6 @@ Flashduty 根据 `status` 判断触发或恢复,根据 `severity` 变量确定
`status` 为 `OK` 时,Flashduty 恢复原告警,并保留最后一次的告警等级。空值或其他 `status` 会被拒绝。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -199,7 +195,6 @@ Flashduty 根据 `status` 判断触发或恢复,根据 `severity` 变量确定
| `slo_id`、`slo_url` | 关联 SLO 的 ID 和链接(仅 Burn Alert) |
## 排查问题
----
- **Honeycomb 中选不到 Flashduty 接收方**:确认 **Payload** 页签中对应的告警类型已启用并填写了模板
- **Flashduty 返回参数错误**:确认模板与上文一致,`instance_id` 和 `status` 非空;Honeycomb 对 4xx 响应不会重试
diff --git a/zh/on-call/integration/alert-integration/alert-sources/hookdeck.mdx b/zh/on-call/integration/alert-integration/alert-sources/hookdeck.mdx
index ac7e9f75..e3fa4a40 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/hookdeck.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/hookdeck.mdx
@@ -1,5 +1,6 @@
---
title: "Hookdeck 告警集成"
+sidebarTitle: "Hookdeck"
description: "通过 Hookdeck 项目的 Webhook 通知将 Hookdeck Issue(投递失败、请求被拒、转换错误、队列积压)同步到 Flashduty On-call,Issue 解决时自动恢复。"
keywords: ["告警集成", "Hookdeck", "Issue", "Webhook 通知", "投递失败"]
---
@@ -9,7 +10,6 @@ Hookdeck 在投递失败、请求被来源拒绝、转换(Transformation)出
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Hookdeck 在投递失败、请求被来源拒绝、转换(Transformation)出
</div>
## 在 Hookdeck 中配置
----
Hookdeck 的 Webhook 通知先发到项目中的一个来源(Source),再由连接(Connection)转发到目的地(Destination)。因此先建一条把通知转发到 Flashduty 的连接,再在项目设置中打开 Webhook 通知。
@@ -69,11 +68,11 @@ Hookdeck 的 Webhook 通知先发到项目中的一个来源(Source),再
1. 新建一个测试连接,目的地 URL 填 `https://mock.hookdeck.com?status=500`(Hookdeck 的模拟接口,总是返回 HTTP 500),向该连接的来源 URL(在 Hookdeck 中打开来源即可看到)发送一个请求:
-```bash
-curl -X POST '<来源 URL>' \
- -H 'Content-Type: application/json' \
- -d '{"type":"flashduty.test"}'
-```
+ ```bash
+ curl -X POST '<来源 URL>' \
+ -H 'Content-Type: application/json' \
+ -d '{"type":"flashduty.test"}'
+ ```
2. 在 Hookdeck **Issues** 页面看到新的投递 Issue 后,确认 Flashduty 收到一条 Critical 告警
3. 在 Issues 页面将该 Issue 的状态改为 **Resolved**,确认原告警恢复
@@ -83,14 +82,12 @@ curl -X POST '<来源 URL>' \
</Steps>
## Alert Key
----
Flashduty 使用 Hookdeck 的 Issue ID(`issue.id`,形如 `iss_...`)作为 Alert Key。同一个 Issue 在打开、确认、解决、重新打开时 ID 不变,因此状态更新通知会作用于打开时创建的告警。
Issue 的错误码、响应状态码、首次/最近出现时间、连接名称等变化不会改变 Alert Key。缺少 `issue.id` 的请求会被拒绝。
## 状态和告警等级
----
告警等级由 Issue 类型(`issue.type`)决定:
@@ -114,7 +111,6 @@ Issue 的错误码、响应状态码、首次/最近出现时间、连接名称
其他状态值会被拒绝并返回参数错误。只有 `issue.opened` 和 `issue.updated` 两个主题会生成告警,其他主题(如 `event.successful`)会被接收并忽略。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -134,7 +130,6 @@ Issue 的错误码、响应状态码、首次/最近出现时间、连接名称
通知中附带的失败请求内容(请求头、请求体)不会写入标签。
## 排查问题
----
- **收不到告警**:确认项目设置中 Webhook 通知已打开且选择了正确的来源,`flashduty` 连接没有被暂停;在 Hookdeck 中查看该连接的事件,确认 Flashduty 返回 200
- **告警没有恢复**:确认 Webhook topics 勾选了 `issue.updated`,并在 Hookdeck 中将 Issue 标记为 Resolved 或 Ignored。只关闭(Dismiss)Issue 不会改变其状态
diff --git a/zh/on-call/integration/alert-integration/alert-sources/hosted-graphite.mdx b/zh/on-call/integration/alert-integration/alert-sources/hosted-graphite.mdx
index aa2cb6cf..9bb7b53d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/hosted-graphite.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/hosted-graphite.mdx
@@ -1,5 +1,6 @@
---
title: "Hosted Graphite 告警集成"
+sidebarTitle: "Hosted Graphite"
description: "通过 Hosted Graphite 告警的 Webhook 通知渠道,将阈值告警的触发和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Hosted Graphite", "Graphite", "Webhook", "Notification Channel", "指标告警"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Hosted Graphite", "Graphite", "Webhook", "Notificati
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Hosted Graphite", "Graphite", "Webhook", "Notificati
</div>
## 在 Hosted Graphite 中配置
----
<Steps>
<Step title="创建 Webhook 通知渠道">
@@ -57,7 +56,6 @@ Hosted Graphite 的通知里没有告警 ID,Flashduty 用「告警名称 + 指
</Warning>
## 推送内容
----
Hosted Graphite 以 `application/json` POST 以下字段,Flashduty 直接解析,无需配置模板:
@@ -73,14 +71,12 @@ Hosted Graphite 以 `application/json` POST 以下字段,Flashduty 直接解
| `timestamp`、`backoff_minutes` | 发送时间、退避设置 | 不保存 |
## Alert Key
----
Flashduty 用告警名称和指标名计算 Alert Key(两者以分隔符拼接后取 MD5)。同一条告警在同一个指标上的触发和恢复通知携带相同的名称和指标,因此落在同一条告警上;名称不同或指标不同的告警互不影响。修改判定条件、当前值不会改变 Alert Key。
Hosted Graphite 未提供告警 ID,这一组合是推断得出的标识:如果两条告警的名称和指标都相同,它们会合并。请求中缺少 `name` 时,Flashduty 返回参数错误。
## 状态和告警等级
----
Hosted Graphite 的通知不带告警等级,Flashduty 统一按 Warning 处理。
@@ -92,7 +88,6 @@ Hosted Graphite 的通知不带告警等级,Flashduty 统一按 Warning 处理
`status` 为空或为其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="Hosted Graphite 重试会产生重复告警吗?">
@@ -109,7 +104,6 @@ Hosted Graphite 的通知不带告警等级,Flashduty 统一按 Warning 处理
</AccordionGroup>
## 排查问题
----
- **Hosted Graphite 推送失败**:确认 URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求体是 JSON,且 `name` 非空、`status` 为 `alerting` 或 `recovered`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/http-pull.mdx b/zh/on-call/integration/alert-integration/alert-sources/http-pull.mdx
index cc4b37d2..b3cbe2a1 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/http-pull.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/http-pull.mdx
@@ -1,5 +1,6 @@
---
title: "HTTP 拉取告警 (HTTP Pull)"
+sidebarTitle: "HTTP 拉取 (HTTP Pull)"
description: "Flashduty 主动按周期访问外部 HTTP 接口,将返回的告警事件拉取入库;适用于无法主动推送告警的系统,或希望将拉取与推送解耦的场景。"
keywords: ["告警集成", "HTTP Pull", "拉取", "轮询", "Polling", "数据接入"]
---
@@ -13,12 +14,11 @@ HTTP 拉取适合 **无法主动 webhook**、**接口本身就是查询型** 或
<div className="hide">
## 操作步骤
----
### 在 Flashduty
<AccordionGroup>
-<Accordion title="使用专属集成">
+<Accordion title="查看专属集成的配置步骤">
当您不需要根据告警内容路由到不同的协作空间时,优先选择此方式,更简单。
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面。
@@ -27,7 +27,7 @@ HTTP 拉取适合 **无法主动 webhook**、**接口本身就是查询型** 或
4. 按下文「配置项」说明填写表单,点击 **保存**。
</Accordion>
-<Accordion title="使用共享集成">
+<Accordion title="查看共享集成的配置步骤">
当您需要根据告警事件的 Payload 信息,将告警路由到不同协作空间时,优先选择此方式。
1. 进入 Flashduty 控制台,选择 **集成中心 ⇒ 告警事件**,进入集成选择页面。
@@ -40,7 +40,6 @@ HTTP 拉取适合 **无法主动 webhook**、**接口本身就是查询型** 或
</div>
## 配置项
----
### HTTP 请求
@@ -93,14 +92,12 @@ HTTP 拉取适合 **无法主动 webhook**、**接口本身就是查询型** 或
```
## 默认路由
----
新增「共享集成」(即在 **集成中心 ⇒ 告警事件** 中创建)时,必须配置默认路由,否则新拉取到的事件将被丢弃。集成创建后可在 **路由** 中追加更细粒度的规则。
「专属集成」(在某个协作空间的 **配置 → 集成数据 → 专属集成** 中创建)会自动绑定到所在空间,不需要单独配置默认路由。
## 模板变量
----
URL 与请求体支持 Go 模板语法。当前仅有 **一个** 内置变量:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/huawei-aom.mdx b/zh/on-call/integration/alert-integration/alert-sources/huawei-aom.mdx
index ce85188b..7d1e8ab2 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/huawei-aom.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/huawei-aom.mdx
@@ -1,5 +1,6 @@
---
title: "华为云 AOM 告警集成"
+sidebarTitle: "华为云 AOM"
description: "通过 SMN 通知或 AOM Webhook 数据订阅,将华为云 AOM 告警事件同步到 Flashduty On-call"
keywords: ["告警集成", "华为云 AOM", "SMN", "Webhook", "数据接入"]
---
@@ -21,7 +22,7 @@ keywords: ["告警集成", "华为云 AOM", "SMN", "Webhook", "数据接入"]
当您不需要将告警事件路由到不同的协作空间时,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入目标协作空间。
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**。
3. 选择 **华为云 AOM** 集成,单击 **保存**。
@@ -34,8 +35,8 @@ keywords: ["告警集成", "华为云 AOM", "SMN", "Webhook", "数据接入"]
当您需要根据告警 Payload 将事件路由到不同的协作空间时,选择此方式。
<AccordionGroup>
- <Accordion title="展开">
- 1. 进入 Flashduty 控制台,选择 **集成中心 > 告警事件**。
+ <Accordion title="查看共享集成的配置步骤">
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**。
2. 选择 **华为云 AOM** 集成并填写集成名称。
3. 配置默认路由并选择协作空间。创建后可在 **路由** 中继续配置路由规则。
4. 单击 **保存**,复制生成的 **推送地址**。
@@ -58,7 +59,7 @@ keywords: ["告警集成", "华为云 AOM", "SMN", "Webhook", "数据接入"]
<Steps>
<Step title="创建 SMN 主题">
1. 登录华为云控制台,进入 **消息通知服务 SMN**。
-2. 选择 **主题管理 > 主题**,单击 **创建主题**。
+2. 选择 **主题管理 → 主题**,单击 **创建主题**。
3. 将主题名称设置为 **Flashduty**,然后保存。
<Frame>
@@ -81,7 +82,7 @@ keywords: ["告警集成", "华为云 AOM", "SMN", "Webhook", "数据接入"]
### 配置 AOM 消息模板
-在 AOM 2.0 控制台进入 **告警中心 > 告警通知 > 消息模板**。部分控制台版本中的入口名称为 **告警 > 告警行动规则 > 消息模板**。
+在 AOM 2.0 控制台进入 **告警中心 → 告警通知 → 消息模板**。部分控制台版本中的入口名称为 **告警 → 告警行动规则 → 消息模板**。
创建消息模板时,通知方式选择 **HTTP/HTTPS**。Flashduty 支持以下两种正文格式:
@@ -151,7 +152,7 @@ keywords: ["告警集成", "华为云 AOM", "SMN", "Webhook", "数据接入"]
<Steps>
<Step title="关联 SMN 主题与消息模板">
-1. 在 AOM 2.0 控制台进入 **告警中心 > 告警通知**。
+1. 在 AOM 2.0 控制台进入 **告警中心 → 告警通知**。
2. 在 **通知规则管理** 中创建告警通知规则。
3. 选择前面创建的 **Flashduty** SMN 主题和 AOM 消息模板。
</Step>
@@ -171,7 +172,7 @@ keywords: ["告警集成", "华为云 AOM", "SMN", "Webhook", "数据接入"]
AOM Webhook 数据订阅目前受限开放。如果控制台没有 Webhook 告警订阅选项,请提交华为云工单申请开通,或使用上面的 SMN 方式。
</Warning>
-账号已开通该能力时,可在 AOM 2.0 控制台进入 **设置 > 全局设置 > 数据订阅**,创建 Webhook 告警订阅规则,并将目标地址设置为同一个 Flashduty AOM 集成推送地址。
+账号已开通该能力时,可在 AOM 2.0 控制台进入 **设置 → 全局设置 → 数据订阅**,创建 Webhook 告警订阅规则,并将目标地址设置为同一个 Flashduty AOM 集成推送地址。
Webhook 请求需要使用 AOM 官方的结构化事件格式:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/huawei-apm.mdx b/zh/on-call/integration/alert-integration/alert-sources/huawei-apm.mdx
index 7b53b6be..a263ce6d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/huawei-apm.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/huawei-apm.mdx
@@ -1,5 +1,6 @@
---
title: "华为云 APM 告警事件"
+sidebarTitle: "华为云 APM"
description: "通过 webhook 的方式同步华为云 APM 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "华为云 APM 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "华为云 APM 告警事件", "监控告警", "数据
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "华为云 APM 告警事件", "监控告警", "数据
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "华为云 APM 告警事件", "监控告警", "数据
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **华为云 APM** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,27 +45,25 @@ keywords: ["告警集成", "华为云 APM 告警事件", "监控告警", "数据
</div>
## 在华为云 APM
----
<div className="md-block">
-## 一、华为云 APM 告警推送配置
### 创建 Flashduty 告警通道
1. 登录您的华为云控制台,检索 `SMN` 消息通知服务产品,并进入对应产品控制台。
2. 在左侧导航栏选择 `主题管理=>主题`。
3. 点击 `创建主题`,在编辑页面中的主题名称处输入 `Flashduty` 并点击确认。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-1.png" />
4. 回到主题列表后,在刚创建的 Flashduty 主题中点击 `添加订阅`。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-2.png" />
5. 在编辑页面中,协议选择 `HTTPS`,订阅终端填写 **集成推送地址** 并点击确认。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-3.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-3.png" />
6. 添加完成后,可以在订阅列表中查看已添加的订阅状态是否为 **已确认**。
@@ -93,7 +91,7 @@ keywords: ["告警集成", "华为云 APM 告警事件", "监控告警", "数据
**注意:** 当前集成配置仅支持应用监控告警,还未完全兼容前端监控、链路追踪、App监控告警。
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/huawei-ces.mdx b/zh/on-call/integration/alert-integration/alert-sources/huawei-ces.mdx
index 3dd35c0f..8cf81b42 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/huawei-ces.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/huawei-ces.mdx
@@ -1,5 +1,6 @@
---
-title: "华为云监控 CES集成"
+title: "华为云监控 CES 集成"
+sidebarTitle: "华为云监控 CES"
description: 通过 webhook 的方式同步华为云监控 CES 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "华为云监控 CES集成", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "华为云监控 CES集成", "监控告警", "数据
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "华为云监控 CES集成", "监控告警", "数据
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "华为云监控 CES集成", "监控告警", "数据
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **华为云监控CES** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,7 +45,6 @@ keywords: ["告警集成", "华为云监控 CES集成", "监控告警", "数据
</div>
## 在华为云监控 CES
----
<div className="md-block">
1. 登录您的 华为云 控制台,检索 `云监控` 产品,并进入对应产品控制台
@@ -53,20 +52,20 @@ keywords: ["告警集成", "华为云监控 CES集成", "监控告警", "数据
3. 协议选择 `HTTPS`,名称填写 `flashduty`,终端填写集成地址(当前页面填写集成名称,保存后即可生成地址)
4. 点击 `确定` 按钮,完成通知对象创建
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/huawei-ces-create-notify-obj.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/huawei-ces-create-notify-obj.png" />
5. 进入 `告警-告警通知-通知组` 页面,单击 `创建通知组` 按钮
6. 组名称填写 `Flashduty`,通知对象勾选前边创建的 `flashduty`
7. 点击 `确定` 按钮,完成通知组创建
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/huawei-ces-create-notify-group.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/huawei-ces-create-notify-group.png" />
-注意,创建通知组时,华为云会发起请求到 Flashduty On-call,验证推送地址,查看通知组的通知对象列表,仅当通知对象状态为 `已确认` 时,才会正常推送告警
+ 注意,创建通知组时,华为云会发起请求到 Flashduty On-call,验证推送地址,查看通知组的通知对象列表,仅当通知对象状态为 `已确认` 时,才会正常推送告警
8. 进入 `告警-告警规则` 页面,选择已有的告警规则进行编辑,或者创建新的告警规则,打开 `告警规则详情` 页面
9. 其中 `通知组` 选择 `Flashduty`,触发条件勾选 `出现告警` 和 `恢复正常`。点击 `确定` 按钮,保存修改
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/huawei-ces-create-alarm.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/huawei-ces-create-alarm.png" />
10. 回到 Flashduty 控制台集成列表页面,如果展示了最新事件时间,说明配置成功且收到事件
11. 完成
@@ -74,7 +73,6 @@ keywords: ["告警集成", "华为云监控 CES集成", "监控告警", "数据
</div>
## 状态对照
----
<div className="md-block">
华为云监控到 Flashduty 告警等级映射关系:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/huawei-lts.mdx b/zh/on-call/integration/alert-integration/alert-sources/huawei-lts.mdx
index c0dedabe..5bc62d4f 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/huawei-lts.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/huawei-lts.mdx
@@ -1,5 +1,6 @@
---
title: "华为云日志服务 LTS 告警事件"
+sidebarTitle: "华为云日志服务 LTS"
description: "通过 webhook 的方式同步华为云日志服务 LTS 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理。"
keywords: ["告警集成", "华为云日志服务 LTS 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "华为云日志服务 LTS 告警事件", "监控告
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "华为云日志服务 LTS 告警事件", "监控告
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "华为云日志服务 LTS 告警事件", "监控告
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **华为云日志服务 LTS** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,26 +46,24 @@ keywords: ["告警集成", "华为云日志服务 LTS 告警事件", "监控告
</div>
## 在华为云
----
<div className="md-block">
-## 一、华为云日志服务 LTS 告警推送配置
### 步骤1:创建 Flashduty 告警通道
1. 登录您的华为云控制台,检索 `SMN` 消息通知服务产品,并进入对应产品控制台。
2. 在左侧导航栏选择 `主题管理=>主题`。
3. 点击 `创建主题`,在编辑页面中的主题名称处输入 `Flashduty` 并点击确认。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-1.png" />
4. 回到主题列表后,在刚创建的 Flashduty 主题中点击 `添加订阅`。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-2.png" />
5. 在编辑页面中,协议选择 `HTTPS`,订阅终端填写 **集成推送地址** 并点击确认。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-3.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-3.png" />
6. 添加完成后,可以在订阅列表中查看已添加的订阅状态是否为 **已确认**。
@@ -76,13 +74,13 @@ keywords: ["告警集成", "华为云日志服务 LTS 告警事件", "监控告
1. 登录您的华为云控制台,检索 `LTS` 云日志服务产品,并进入对应产品控制台。
2. 在左侧导航栏选择 `日志告警=>告警行动规则=>消息模版` 并点击 `创建`。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-5.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-5.png" />
3. 在模版编辑页面中,名称填写 **Flashduty**,消息头语言选择 `英文`。
4. 通知类型选择 `HTTP/HTTPS`,数据类型选择 `JSON`。
5. 点击 `确认` 保存。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-6.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/huawei-lts-6.png" />
6. 回到 `告警行动规则` 列表,点击 `创建`。
7. 规则名称填写 **Flashduty** ,主题和消息模版都选择已创建的 **Flashduty** 主题和模版。
@@ -103,7 +101,7 @@ keywords: ["告警集成", "华为云日志服务 LTS 告警事件", "监控告
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/hund.mdx b/zh/on-call/integration/alert-integration/alert-sources/hund.mdx
index cf7259eb..b9c7e5b5 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/hund.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/hund.mdx
@@ -1,5 +1,6 @@
---
title: "Hund 告警集成"
+sidebarTitle: "Hund"
description: "通过 Hund 状态页的 Webhook,把状态页上的事件(Issue)和组件可用性变化同步到 Flashduty On-call。"
keywords: ["告警集成", "Hund", "状态页", "Webhook", "组件状态"]
---
@@ -12,7 +13,6 @@ keywords: ["告警集成", "Hund", "状态页", "Webhook", "组件状态"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -33,7 +33,6 @@ keywords: ["告警集成", "Hund", "状态页", "Webhook", "组件状态"]
</div>
## 在 Hund 中
----
<Steps>
<Step title="启用 Webhooks 通知方式">
@@ -67,7 +66,6 @@ Hund 默认订阅除 **Issue Updated** 以外的大部分通知。要让事件
</Steps>
## 推送内容
----
Hund 推送 JSON,`event.kind` 是通知类型:
@@ -108,7 +106,6 @@ Hund 推送 JSON,`event.kind` 是通知类型:
每条告警还带有标签 `source=hund` 和 `event`(推送的通知类型)。
## Alert Key
----
- 事件:事件 ID。同一事件从创建、更新到解决的每次推送落在同一条告警上
- 组件:组件 ID。Hund 在每次状态变化时都会生成新的状态对象(降级和恢复各一个 ID),所以组件告警以组件本身为准,同一组件从 `degraded` 到 `restored` 的推送落在同一条告警上
@@ -116,7 +113,6 @@ Hund 推送 JSON,`event.kind` 是通知类型:
事件告警和组件告警互不影响:状态页上的事件会影响多个组件,同时可能有多条组件告警,可以用协作空间的[告警聚合](/zh/on-call/channel/noise-reduction)把它们合并到同一个故障。修改事件标题、组件名称不会改变 Alert Key。
## 状态和告警等级
----
| Hund 推送 | Flashduty 状态或等级 |
| :--- | :--- |
@@ -132,7 +128,6 @@ Hund 推送 JSON,`event.kind` 是通知类型:
有 `state_override` 的更新以更新为准,没有时取事件本身的值。
## 常见问题
----
<AccordionGroup>
<Accordion title="事件更新没有同步到 Flashduty?">
@@ -155,7 +150,6 @@ Hund 订阅默认不推送 Issue Updated。把订阅的通知级别调整为包
</AccordionGroup>
## 排查问题
----
- **Flashduty 返回参数错误**:推送内容缺少 `event.eventable.id`(事件)或 `event.contexts.component.id`(组件状态)
- **事件告警没有恢复**:确认事件已在 Hund 中标记为已解决或已结束,且订阅包含对应通知
diff --git a/zh/on-call/integration/alert-integration/alert-sources/hyperdx.mdx b/zh/on-call/integration/alert-integration/alert-sources/hyperdx.mdx
index 3a5680b5..633757d3 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/hyperdx.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/hyperdx.mdx
@@ -1,5 +1,6 @@
---
title: "HyperDX 告警集成"
+sidebarTitle: "HyperDX"
description: "通过 Generic Webhook 和固定的 Body 模板,将 HyperDX(ClickStack)搜索告警和图表告警的触发与恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "HyperDX", "ClickStack", "ClickHouse", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "HyperDX", "ClickStack", "ClickHouse", "Webhook"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "HyperDX", "ClickStack", "ClickHouse", "Webhook"]
</div>
## 在 HyperDX 中配置
----
开源版 HyperDX 和 ClickHouse Cloud 中的托管 ClickStack 都支持 Generic Webhook。自建 HyperDX 需要能访问 Flashduty 推送地址所在的公网域名。
@@ -43,18 +42,18 @@ keywords: ["告警集成", "HyperDX", "ClickStack", "ClickHouse", "Webhook"]
4. **Webhook Headers** 留空即可,HyperDX 默认发送 `Content-Type: application/json`
5. **Webhook Body** 粘贴下面的模板
-```json
-{
- "event_id": "{{eventId}}",
- "state": "{{state}}",
- "severity": "Warning",
- "title": "{{title}}",
- "body": "{{body}}",
- "link": "{{link}}",
- "alert_id": "{{alertId}}",
- "group": "{{groupKey}}"
-}
-```
+ ```json
+ {
+ "event_id": "{{eventId}}",
+ "state": "{{state}}",
+ "severity": "Warning",
+ "title": "{{title}}",
+ "body": "{{body}}",
+ "link": "{{link}}",
+ "alert_id": "{{alertId}}",
+ "group": "{{groupKey}}"
+ }
+ ```
6. 点击 **Test Webhook** 确认推送地址可达,再点击 **Add Webhook** 保存
@@ -94,7 +93,6 @@ keywords: ["告警集成", "HyperDX", "ClickStack", "ClickHouse", "Webhook"]
</Steps>
## Alert Key
----
Flashduty 直接使用 `event_id`(`{{eventId}}`)作为 Alert Key。HyperDX 在 Webhook 模板变量文档中说明,`{{eventId}}` 对同一条告警、同一个分组和同一个 Webhook 保持不变,覆盖从触发到恢复的全过程,官方的 incident.io 模板也用它作为去重键。
@@ -104,7 +102,6 @@ Flashduty 直接使用 `event_id`(`{{eventId}}`)作为 Alert Key。HyperDX
- 修改告警的 **grouped by**,或删除后重新创建 Webhook,会产生新的 `event_id`。修改前已在 Flashduty 中触发的告警不会再收到恢复通知,需要手动关闭
## 状态和告警等级
----
Flashduty 根据 `state` 判断触发或恢复,根据 `severity` 确定告警等级。
@@ -124,7 +121,6 @@ Flashduty 根据 `state` 判断触发或恢复,根据 `severity` 确定告警
`severity` 不区分大小写。HyperDX 只在告警之前发送过触发通知时才发送恢复通知;告警处于静默期间既不发送触发通知,也不发送恢复通知。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -137,7 +133,6 @@ Flashduty 根据 `state` 判断触发或恢复,根据 `severity` 确定告警
告警标题取自 `{{title}}`,去掉 HyperDX 添加的 🚨 和 ✅ 前缀;告警描述取自 `{{body}}`。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 Webhook Body 与上文模板一致,`event_id` 和 `state` 非空,字符串变量外层保留了双引号
- **Test Webhook 成功但没有告警**:这是预期行为,测试数据不会生成告警
diff --git a/zh/on-call/integration/alert-integration/alert-sources/hyperping.mdx b/zh/on-call/integration/alert-integration/alert-sources/hyperping.mdx
index 93d9d4eb..1ad037c5 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/hyperping.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/hyperping.mdx
@@ -1,5 +1,6 @@
---
title: "Hyperping 告警集成"
+sidebarTitle: "Hyperping"
description: "通过 Webhook 集成将 Hyperping 监控的宕机和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Hyperping", "Uptime", "Webhook", "check.down", "check.up"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Hyperping", "Uptime", "Webhook", "check.down", "chec
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Hyperping", "Uptime", "Webhook", "check.down", "chec
</div>
## 在 Hyperping 中配置
----
<Steps>
<Step title="连接 Webhooks 集成">
@@ -53,7 +52,6 @@ Hyperping 官方建议用一个会返回错误的监控(例如指向一个返
Integrations 页面上的 Webhook 卡片标有 Pro,仅 Pro 及以上付费套餐可用;在免费试用期内点击该卡片会跳转到 Billing 页面。如果无法打开配置,请先升级套餐。
## 推送内容
----
Hyperping 以 JSON 格式 POST 事件,Flashduty 直接解析,无需配置模板:
@@ -69,14 +67,12 @@ Hyperping 以 JSON 格式 POST 事件,Flashduty 直接解析,无需配置模
告警标题使用被监控地址;地址为空时使用 `Hyperping monitor <监控 ID>`。
## Alert Key
----
使用 `check.monitorUuid` 作为 Alert Key。Hyperping 文档中 `check.down` 和 `check.up` 的示例使用同一个 `monitorUuid`,同一个监控的宕机和恢复通知落在同一条告警上;不同监控会生成不同的告警。修改地址、状态码、时间或检查区域不会改变 Alert Key。
请求中缺少 `check.monitorUuid` 时,Flashduty 会返回参数错误,因为无法可靠地把恢复通知关联到原告警。`event` 不是 `check.down` 或 `check.up` 的通知(例如 Hyperping 以后新增的事件类型)会被忽略并返回成功,不会创建告警。
## 状态和告警等级
----
Hyperping 的通知不区分告警等级,宕机按 Critical 处理。
@@ -88,7 +84,6 @@ Hyperping 的通知不区分告警等级,宕机按 Critical 处理。
`event` 为空或为其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="Webhook 测试按钮会创建告警吗?">
@@ -105,7 +100,6 @@ Hyperping 在 webhook URL 输入框下方提供测试按钮,官方文档没有
</AccordionGroup>
## 排查问题
----
- **Hyperping 推送失败**:确认 webhook URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求为 Hyperping 的 JSON 通知,且 `event`、`check.monitorUuid` 非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/ibm-qradar.mdx b/zh/on-call/integration/alert-integration/alert-sources/ibm-qradar.mdx
index 16b8285a..25a5a6d6 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/ibm-qradar.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/ibm-qradar.mdx
@@ -1,5 +1,6 @@
---
title: "IBM QRadar 告警集成"
+sidebarTitle: "IBM QRadar"
description: "IBM QRadar 的规则响应可以发送邮件,使用 Flashduty 的邮件集成按规则接收 QRadar 告警。"
keywords: ["告警集成", "IBM QRadar", "QRadar", "SIEM", "邮件", "Email", "安全告警"]
---
@@ -9,7 +10,6 @@ IBM QRadar 的规则触发后可以执行邮件响应,并且邮件的主题和
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成邮件地址,任选其一即可。**集成类型都选择邮件 Email**,不是 IBM QRadar。
@@ -30,7 +30,6 @@ IBM QRadar 的规则触发后可以执行邮件响应,并且邮件的主题和
</div>
## 在 QRadar 中配置
----
规则的邮件响应使用 `alert-config.xml` 里的事件或流量(event / flow)模板。QRadar 官方文档说明了修改方法,见 [Configuring event and flow custom email notifications](https://www.ibm.com/docs/en/qsip/7.4.0?topic=notifications-configuring-event-flow-custom-email)。下面是让邮件适配 Flashduty 规则的最小改动。
@@ -93,7 +92,6 @@ cp /store/configservices/staging/globalconfig/templates/custom_alerts/*.* <direc
</Steps>
## 在 Flashduty 中配置推送规则
----
QRadar 的规则邮件没有恢复邮件,一封邮件对应一次规则触发。因此只需要一条触发规则,Alert Key 从邮件标题提取「规则名 + 来源 IP」。
@@ -111,7 +109,6 @@ QRadar 的规则邮件没有恢复邮件,一封邮件对应一次规则触发
默认规则选丢弃,是为了让不带 `[QRadar]` 前缀的邮件(例如系统通知)不生成告警。
## 恢复与去重
----
- QRadar 规则响应不会在条件恢复时再发邮件,Flashduty 不会自动关闭这些告警。请在接收该集成的协作空间开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时;也可以处理完成后手动关闭。
- 同一规则、同一来源 IP 再次触发时,标题相同,Alert Key 相同,Flashduty 更新同一条告警。想按目的 IP 或用户区分,就把对应参数(如 `${DestinationIP}`、`${UserName}`)加进 `<subject>`。
@@ -119,7 +116,6 @@ QRadar 的规则邮件没有恢复邮件,一封邮件对应一次规则触发
- 邮件正文超过 128 KB 会被截断,附件会被丢弃,详情见 [邮件集成](/zh/on-call/integration/alert-integration/alert-sources/email)。
## 排查问题
----
- **没有收到告警**:确认已执行 **Deploy Full Configuration**,规则的邮件响应使用了新模板,QRadar 邮件服务器能把邮件发到 Flashduty 邮件地址
- **告警都被丢弃**:邮件标题不以 `[QRadar] ` 开头,说明规则没有使用新模板;用一封实际收到的邮件核对标题
diff --git a/zh/on-call/integration/alert-integration/alert-sources/icinga.mdx b/zh/on-call/integration/alert-integration/alert-sources/icinga.mdx
index e48140d9..6f4f190c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/icinga.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/icinga.mdx
@@ -1,5 +1,6 @@
---
title: "Icinga 2 告警集成"
+sidebarTitle: "Icinga 2"
description: "通过通知命令将 Icinga 2 主机和服务的告警通知同步到 Flashduty On-call,问题恢复时自动关闭告警。"
keywords: ["告警集成", "Icinga", "Icinga 2", "NotificationCommand", "通知命令", "Nagios"]
---
@@ -9,7 +10,6 @@ Icinga 2 没有内置的 Webhook 通知方式。本集成提供一段 Icinga 2
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Icinga 2 没有内置的 Webhook 通知方式。本集成提供一段 Icinga 2
</div>
## 在 Icinga 2 中配置
----
以下配置适用于 Icinga 2.11 及以上版本。通知命令只依赖 `curl`,需要安装在执行通知的 Icinga 2 节点上,并且该节点能访问 Flashduty 推送地址。
@@ -131,7 +130,6 @@ systemctl reload icinga2
<Warning>Icinga 2 会为通知中的每个用户各执行一次通知命令。`users` 或 `user_groups` 中包含多个用户时,同一条通知会推送多次;这些推送落在同一条告警上,但会产生重复事件。因此 Flashduty 通知只配置 `flashduty` 这一个用户。</Warning>
## Alert Key
----
Flashduty 用主机名 `host_name` 加服务名 `service_name` 计算 Alert Key;主机通知的服务名为空。Icinga 2 的服务对象以 `主机名!服务名` 作为完整名称,同一主机下服务名唯一,因此同一个主机或服务的问题和恢复通知落在同一条告警上。
@@ -140,7 +138,6 @@ Flashduty 用主机名 `host_name` 加服务名 `service_name` 计算 Alert Key
请求缺少 `host_name` 或 `notification_type`,主机通知缺少 `host_state`,或服务通知缺少 `service_state` 时,Flashduty 会拒绝该请求。
## 告警生命周期
----
Icinga 2 只在发出过问题通知之后才会发送恢复通知。确认、维护、抖动和自定义通知如果用来打开告警,之后可能没有恢复通知来关闭。因此只有问题通知会打开告警,Flashduty 按通知类型 `notification_type` 处理:
@@ -157,7 +154,6 @@ Icinga 2 只在发出过问题通知之后才会发送恢复通知。确认、
配置中的 `apply Notification` 没有设置 `types` 和 `states`,Icinga 2 默认发送全部通知类型。维护期被移除时 Icinga 2 发送的类型是 `DOWNTIMECANCELLED`。被忽略的通知返回成功。
## 告警等级
----
告警等级来自当前状态:服务通知取 `service_state`,主机通知取 `host_state`。
@@ -173,14 +169,12 @@ Icinga 2 只在发出过问题通知之后才会发送恢复通知。确认、
恢复事件的等级取恢复前的状态(`service_last_state` 或 `host_last_state`)。
## 告警内容
----
- **标题**:服务通知为 `<服务显示名称> on <主机显示名称>`,主机通知为 `Host <主机显示名称>`;未设置显示名称时使用对象名称
- **描述**:插件输出 `service_output` 或 `host_output`
- **标签**:`host`、`resource`(主机名)、`service`、`check`(服务名,仅服务通知)、`notification_type`、`state`、`host_display_name`、`host_address`、`host_groups`、`service_display_name` 和 `service_groups`(仅服务通知)。多个分组以英文逗号连接
## 排查问题
----
- **通知没有发出**:在 Icinga Web 中查看对象的通知历史,确认 `flashduty` 通知对象存在(先执行 `icinga2 daemon -C --dump-objects` 生成对象缓存,再执行 `icinga2 object list --type Notification --name '*flashduty'`),并确认主机或服务没有关闭通知
- **Icinga 2 日志出现 `exit code 22`**:`curl` 收到了 HTTP 4xx/5xx。确认 `vars.flashduty_push_url` 是完整推送地址且包含 `integration_key`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/image-upload.mdx b/zh/on-call/integration/alert-integration/alert-sources/image-upload.mdx
index de280d65..4d3b24c0 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/image-upload.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/image-upload.mdx
@@ -4,7 +4,7 @@ description: "通过图片上传接口上传图片并获得 image_key,可在
keywords: ["图片上传", "image_key", "标准告警", "告警图片", "integration_key", "Flashduty"]
---
-## 一、功能概述
+## 功能概述
上报告警时,您可以在 [标准告警](/zh/on-call/integration/alert-integration/alert-sources/standard-alert) 的 `images` 字段中携带图片,用于在前端及飞书、钉钉应用通知中展示告警相关截图。`images` 中每张图片的 `src` 支持两种取值:
@@ -21,7 +21,7 @@ keywords: ["图片上传", "image_key", "标准告警", "告警图片", "integra
图片上传与标准告警上报共用同一个集成秘钥(`integration_key`)。请使用您在 [标准告警](/zh/on-call/integration/alert-integration/alert-sources/standard-alert) 等集成中获取的推送秘钥,无需单独申请。
</Note>
-## 二、接口说明
+## 接口说明
### 请求方式
@@ -111,7 +111,7 @@ Code:
超过限制时返回 `RequestTooFrequently`(HTTP 429)。
-## 三、请求示例
+## 请求示例
请求:
@@ -131,7 +131,7 @@ curl -X POST '{api_host}/push/image/upload?integration_key={integration_key}' \
}
```
-## 四、在告警中引用图片
+## 在告警中引用图片
拿到 `image_key` 后,在上报 [标准告警](/zh/on-call/integration/alert-integration/alert-sources/standard-alert) 时,将其填入 `images` 数组中某张图片的 `src` 字段即可:
@@ -158,7 +158,7 @@ curl -X POST '{api_host}/push/image/upload?integration_key={integration_key}' \
- 上传后的图片先临时存储,被告警引用后才会转为长期存储。请在上传后及时将 `image_key` 用于告警上报。
</Note>
-## 五、常见问题
+## 常见问题
1. **重复上传同一张图片会怎样?**
diff --git a/zh/on-call/integration/alert-integration/alert-sources/imperva.mdx b/zh/on-call/integration/alert-integration/alert-sources/imperva.mdx
index f3361070..1c093811 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/imperva.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/imperva.mdx
@@ -1,5 +1,6 @@
---
title: "Imperva 告警集成"
+sidebarTitle: "Imperva"
description: "通过 Imperva 的 Webhook Connection 将 DDoS 攻击开始与结束、BGP 连接中断与恢复、连接性能劣化等事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Imperva", "Thales", "DDoS", "BGP", "Webhook", "网络防护"]
---
@@ -9,7 +10,6 @@ Imperva(Thales)云端应用与网络安全控制台提供 Webhook Connection
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Imperva(Thales)云端应用与网络安全控制台提供 Webhook Connection
</div>
## 在 Imperva 中配置
----
<Steps>
<Step title="新增 Webhook Connection">
@@ -61,7 +60,6 @@ Imperva(Thales)云端应用与网络安全控制台提供 Webhook Connection
Imperva 的 Webhook 载荷是固定格式,不能自定义模板。Imperva 可能重复投递同一事件,Flashduty 按同一 Alert Key 合并,不会产生重复告警。
## 事件与恢复
----
| 通知子类型 | 开始事件 | 结束事件 | Flashduty 等级 |
| :--- | :--- | :--- | :--- |
@@ -80,7 +78,6 @@ Imperva 的 Webhook 载荷是固定格式,不能自定义模板。Imperva 可
- 账号、站点、账单、订阅、策略变更、IP 段状态变化等其他通知类型不会产生告警,Flashduty 收到后直接返回成功
## Alert Key
----
Alert Key 由事件类别、Imperva 账号 ID 和对象标识计算,开始事件和结束事件使用相同的字段:
@@ -95,7 +92,6 @@ Alert Key 由事件类别、Imperva 账号 ID 和对象标识计算,开始事
标题、事件时间、载荷中的账号名和 Webhook ID 不参与计算。缺少事件类型(`event_type`)或缺少所属类别的对象标识时,请求会被拒绝并返回错误,错误信息指出缺失的字段。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -111,7 +107,6 @@ Alert Key 由事件类别、Imperva 账号 ID 和对象标识计算,开始事
告警标题取自 `event_title`,描述取自 `event_details.event_body`。
## 排查问题
----
- **Test Webhook 报失败**:Imperva 要求接收端返回 200 或 201。确认推送地址完整、`integration_key` 有效,且集成类型为 Imperva
- **没有收到告警**:确认通知策略的 Recipients 选择了这个 Webhook Connection,且事件类型在上表中。表外的事件类型不会产生告警
diff --git a/zh/on-call/integration/alert-integration/alert-sources/infisical.mdx b/zh/on-call/integration/alert-integration/alert-sources/infisical.mdx
index c271ce4d..68e53d3d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/infisical.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/infisical.mdx
@@ -1,5 +1,6 @@
---
title: "Infisical 告警集成"
+sidebarTitle: "Infisical"
description: "通过 Infisical 项目 Webhook,把密钥轮换失败和蜜罐令牌(Honey Token)被触发的事件推送到 Flashduty On-call。"
keywords: ["告警集成", "Infisical", "密钥管理", "Secret Rotation", "Honey Token", "Webhook"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "Infisical", "密钥管理", "Secret Rotation", "Hone
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ keywords: ["告警集成", "Infisical", "密钥管理", "Secret Rotation", "Hone
</div>
## 在 Infisical 中配置
----
<Steps>
<Step title="创建 Webhook">
@@ -61,7 +60,6 @@ keywords: ["告警集成", "Infisical", "密钥管理", "Secret Rotation", "Hone
</Steps>
## Alert Key
----
Infisical 的请求体里没有告警 ID,Flashduty 用被监控的对象本身作为 Alert Key:
@@ -71,7 +69,6 @@ Infisical 的请求体里没有告警 ID,Flashduty 用被监控的对象本身
同一个轮换连续失败(包括手动触发和重试),或同一个蜜罐令牌从不同 IP 被多次触发,都合并到同一条告警。错误信息、项目名称、来源 IP、时间戳的变化不会改变 Alert Key。缺少 `project.projectId`、`project.environment`、`project.rotationName` 或 `honeyToken.name` 的请求会被拒绝。
## 状态和告警等级
----
| Infisical 事件 | Flashduty 等级 | 说明 |
| :--- | :--- | :--- |
@@ -83,7 +80,6 @@ Infisical 的请求体里没有告警 ID,Flashduty 用被监控的对象本身
两类告警都没有对应的恢复事件。
## 排查问题
----
- **Infisical 提示 Webhook 失败**:确认推送地址完整并包含 `integration_key`,Webhook 类型是 **General**(Slack 和 Microsoft Teams 类型发送的是各自的消息格式)
- **轮换失败后没有收到告警**:确认 Webhook 的 **Environment** 与轮换所在环境一致,**Secret Path** 能匹配轮换所在文件夹(例如 `/**`),且勾选了 **Secret Rotation Failed**
diff --git a/zh/on-call/integration/alert-integration/alert-sources/influxdata.mdx b/zh/on-call/integration/alert-integration/alert-sources/influxdata.mdx
index b174b3b9..670e8bf8 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/influxdata.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/influxdata.mdx
@@ -1,5 +1,6 @@
---
title: "Influxdata 集成"
+sidebarTitle: "Influxdata"
description: "通过 webhook 的方式同步 Influxdata 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "Influxdata 集成", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "Influxdata 集成", "监控告警", "数据接入"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "Influxdata 集成", "监控告警", "数据接入"]
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "Influxdata 集成", "监控告警", "数据接入"]
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Influxdata** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,14 +45,13 @@ keywords: ["告警集成", "Influxdata 集成", "监控告警", "数据接入"]
</div>
## 在 Influxdata
----
支持 Influxdata 1.x ~ 2.x 版本,不同版本配置有差异,详看下文
- [2.x 版本](#v2)
- [1.x 版本](#v1)
-## 一、Influxdata 配置
+## Influxdata 配置
<span id="v2"></span>
@@ -71,7 +70,7 @@ keywords: ["告警集成", "Influxdata 集成", "监控告警", "数据接入"]
3. `About` 和 `Conditions` 按需配置即可。
4. `Message` 选择步骤1创建的 `Flashduty`。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/influxdb-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/influxdb-2.png" />
5. 完成。
@@ -84,7 +83,7 @@ keywords: ["告警集成", "Influxdata 集成", "监控告警", "数据接入"]
2. 点击需要同步事件的告警规则,进入 `Alert Rule Builder` 页面,开始编辑规则
3. `Alert Handlers` 部分,选择 `Add Another Handler`,类型选择 `post,HTTP endpoint` 填入集成的推送地址,如下图所示:
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/influxdb-alert-rule.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/influxdb-alert-rule.png" />
4. 点击 `Save Rule` 按钮,保存。等待事件触发,如果在集成列表展示了最新事件时间,说明配置成功且收到事件
5. 完成
@@ -95,7 +94,7 @@ keywords: ["告警集成", "Influxdata 集成", "监控告警", "数据接入"]
Chronograf 的 `post` 处理器就是 Kapacitor 的 `post` 事件处理器,直接使用 Kapacitor 时,可以在 TICKscript 的 `alert()` 节点上添加 `.post('<推送地址>')`,或用 topic 处理器(`kind: post`,`options.url` 填推送地址)。完整步骤见 [Kapacitor 告警集成](/zh/on-call/integration/alert-integration/alert-sources/kapacitor)。
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/insightidr.mdx b/zh/on-call/integration/alert-integration/alert-sources/insightidr.mdx
index 751d67e1..501b91f3 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/insightidr.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/insightidr.mdx
@@ -1,5 +1,6 @@
---
title: "Rapid7 InsightIDR 告警集成"
+sidebarTitle: "Rapid7 InsightIDR"
description: "通过 Universal Webhook 数据导出器,将 Rapid7 InsightIDR 生成的调查(Investigation)同步到 Flashduty On-call。"
keywords: ["告警集成", "Rapid7", "InsightIDR", "Universal Webhook", "SIEM", "安全调查"]
---
@@ -11,7 +12,6 @@ InsightIDR 只推送"调查已创建",不推送调查的更新或关闭,所
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ InsightIDR 只推送"调查已创建",不推送调查的更新或关闭,所
</div>
## 在 Rapid7 InsightIDR 中配置
----
<Steps>
<Step title="添加 Universal Webhook 数据导出器">
@@ -57,7 +56,6 @@ InsightIDR 只推送"调查已创建",不推送调查的更新或关闭,所
</Steps>
## 事件类型
----
| `X-Rapid7-Event` | 在 Flashduty 中的效果 |
| :--- | :--- |
@@ -66,17 +64,14 @@ InsightIDR 只推送"调查已创建",不推送调查的更新或关闭,所
| 其他值 | 请求被拒绝,返回参数错误 |
## Alert Key
----
Flashduty 使用 `investigationId`(InsightIDR 为每个调查分配的固定编号)作为 Alert Key。标题、描述、时间的变化不会改变它,缺少 `investigationId` 的请求会被拒绝。
## 状态和告警等级
----
InsightIDR 的推送内容不含严重程度,所有调查都按 Warning 处理。需要区分等级时,可在集成的 **告警处理** 中按标题或标签调整。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -89,12 +84,10 @@ InsightIDR 的推送内容不含严重程度,所有调查都按 Warning 处理
用户邮箱和 AD 可分辨名(`distinguishedName`)不会写入标签。
## 关于签名
----
InsightIDR 用 Secret 对请求体做 HMAC 签名(`X-Rapid7-Signature`)。Flashduty 不校验签名,推送地址中的 `integration_key` 是唯一的凭证,请妥善保管。也可以在 **Custom headers** 中添加自定义请求头,Flashduty 不要求它们。
## 排查问题
----
- **Flashduty 没有收到推送**:收集器由您自行部署,确认它能访问公网,并且 URL 完整且包含 `integration_key`
- **返回参数错误**:提示缺少 `investigationId` 时,说明推送的不是调查;提示事件类型不支持时,说明 `X-Rapid7-Event` 不是 `idr_investigation_created` 或 `test`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/instana.mdx b/zh/on-call/integration/alert-integration/alert-sources/instana.mdx
index f0ce97c8..e7029c80 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/instana.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/instana.mdx
@@ -1,5 +1,6 @@
---
title: "IBM Instana 告警集成"
+sidebarTitle: "IBM Instana"
description: "通过 Generic webhook 告警通道将 IBM Instana 的问题、事件和变更同步到 Flashduty On-call。"
keywords: ["告警集成", "Instana", "IBM Instana", "Webhook", "Generic webhook", "告警通道"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Instana", "IBM Instana", "Webhook", "Generic webhook
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Instana", "IBM Instana", "Webhook", "Generic webhook
</div>
## 在 Instana 中配置
----
需要 Instana 中配置告警通道和告警的权限。先创建指向 Flashduty 的告警通道,再在告警配置中选择这个通道。
@@ -52,15 +51,15 @@ keywords: ["告警集成", "Instana", "IBM Instana", "Webhook", "Generic webhook
1. 点击 **Settings** → **Alerts** → **New alert**,填写告警名称
2. 在 **Events** 下拉框中选择 **Alert on event type(s)**,再打开需要推送的事件类型:
-| Instana 事件类型 | 推送内容 | 在 Flashduty 中的效果 |
-| :--- | :--- | :--- |
-| Incidents | `type` 为 `incident`,带 `OPEN` / `CLOSED` 状态 | 打开时触发,关闭时恢复 |
-| Critical issues / Warning issues | `type` 为 `issue`,带 `OPEN` / `CLOSED` 状态 | 打开时触发,关闭时恢复 |
-| Monitoring issues | `type` 为 `monitoringIssue`,带 `OPEN` / `CLOSED` 状态 | 打开时触发,关闭时恢复 |
-| Changes | `type` 为 `change`,没有状态 | 每次推送生成一条 Info 告警,不会自动恢复 |
-| Online / Offline | `type` 为 `presence`,没有状态 | 每次推送生成一条 Info 告警,不会自动恢复 |
+ | Instana 事件类型 | 推送内容 | 在 Flashduty 中的效果 |
+ | :--- | :--- | :--- |
+ | Incidents | `type` 为 `incident`,带 `OPEN` / `CLOSED` 状态 | 打开时触发,关闭时恢复 |
+ | Critical issues / Warning issues | `type` 为 `issue`,带 `OPEN` / `CLOSED` 状态 | 打开时触发,关闭时恢复 |
+ | Monitoring issues | `type` 为 `monitoringIssue`,带 `OPEN` / `CLOSED` 状态 | 打开时触发,关闭时恢复 |
+ | Changes | `type` 为 `change`,没有状态 | 每次推送生成一条 Info 告警,不会自动恢复 |
+ | Online / Offline | `type` 为 `presence`,没有状态 | 每次推送生成一条 Info 告警,不会自动恢复 |
-变更和上下线事件数量较多且不会自动恢复,一般只打开 **Incidents**、**Critical issues** 和 **Warning issues**。
+ 变更和上下线事件数量较多且不会自动恢复,一般只打开 **Incidents**、**Critical issues** 和 **Warning issues**。
3. 在 **Scope** 的 **Apply on**(必填)中选择范围:应用视图(Application perspective)、Dynamic Focus 查询(Selected entities only),或全部实体(All available entities)
4. 在 **Alerting** 中点击 **Add alert channels**,选择上一步创建的通道
@@ -75,11 +74,11 @@ keywords: ["告警集成", "Instana", "IBM Instana", "Webhook", "Generic webhook
1. 触发一个 Instana 问题,确认 Flashduty 收到活动告警。可以在装有 Instana agent 的主机上通过 agent 的 Event SDK 发送一个带持续时间的严重事件:
-```bash
-curl -X POST http://localhost:42699/com.instana.plugin.generic.event \
- -H 'Content-Type: application/json' \
- -d '{"title":"Flashduty test","text":"Flashduty test","severity":10,"duration":300000}'
-```
+ ```bash
+ curl -X POST http://localhost:42699/com.instana.plugin.generic.event \
+ -H 'Content-Type: application/json' \
+ -d '{"title":"Flashduty test","text":"Flashduty test","severity":10,"duration":300000}'
+ ```
2. 等问题在 Instana 中关闭(上例为 5 分钟后),确认原告警恢复
@@ -89,14 +88,12 @@ curl -X POST http://localhost:42699/com.instana.plugin.generic.event \
</Steps>
## Alert Key
----
Flashduty 使用 Instana 的问题 ID(`issue.id`)作为 Alert Key。同一个问题或事件打开和关闭时推送的 `issue.id` 相同,因此关闭通知会恢复打开时创建的告警。
问题标题、严重程度、开始时间、标签的变化不会改变 Alert Key。缺少 `issue.id` 的请求会被拒绝。
## 状态和告警等级
----
Flashduty 按问题的严重程度(`issue.severity`)确定告警等级:
@@ -117,7 +114,6 @@ Flashduty 按问题的严重程度(`issue.severity`)确定告警等级:
其他状态值会被拒绝并返回参数错误。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -138,7 +134,6 @@ Flashduty 按问题的严重程度(`issue.severity`)确定告警等级:
Instana 在不适用的字段中填写 `not available`,这些字段不会生成标签。
## 排查问题
----
- **Test channel 提示域名不被允许**:Instana SaaS 可能限制告警通道的外发域名,请联系 IBM Instana 支持将 Flashduty 推送地址的域名加入允许列表
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/instatus.mdx b/zh/on-call/integration/alert-integration/alert-sources/instatus.mdx
index 4f7cea37..b3e6ab36 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/instatus.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/instatus.mdx
@@ -1,5 +1,6 @@
---
title: "Instatus 告警集成"
+sidebarTitle: "Instatus"
description: "通过 Webhook 订阅 Instatus 状态页,把事件(Incident)和组件故障同步到 Flashduty On-call。"
keywords: ["告警集成", "Instatus", "状态页", "第三方服务状态", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Instatus", "状态页", "第三方服务状态", "We
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Instatus", "状态页", "第三方服务状态", "We
</div>
## 在 Instatus 中添加 Webhook 订阅者
----
<Steps>
<Step title="打开 Webhook 订阅者列表">
@@ -67,7 +66,6 @@ keywords: ["告警集成", "Instatus", "状态页", "第三方服务状态", "We
</Steps>
## 推送内容
----
Instatus 在事件新增或更新、组件状态变化、计划维护新增或更新时各推送一次 JSON。Flashduty 处理前两类:
@@ -98,7 +96,6 @@ Instatus 在事件新增或更新、组件状态变化、计划维护新增或
组件告警的标题形如 `Website: major outage`。每条告警还带有标签 `source=instatus`,以及 `page_url`、`page_status`。推送中的退订链接(`meta.unsubscribe`)含有订阅凭据,Flashduty 不会把它写入告警。
## Alert Key
----
Flashduty 按推送类型分别生成 Alert Key:
@@ -110,7 +107,6 @@ Flashduty 按推送类型分别生成 Alert Key:
修改事件名称、组件名称或影响程度不会改变 Alert Key。等级升高时(例如组件从 `PARTIALOUTAGE` 变为 `MAJOROUTAGE`),Flashduty 会新建一条更高等级的告警,原告警保持触发;恢复推送会同时关闭这两条告警。上一条告警恢复后,同一组件再次故障会生成一条新告警。
## 状态和告警等级
----
**组件状态**
@@ -144,7 +140,6 @@ Flashduty 按推送类型分别生成 Alert Key:
计划维护(`maintenance` 推送,状态为 `NOTSTARTEDYET`、`INPROGRESS`、`COMPLETED`)属于计划内变更,Flashduty 返回成功但不生成告警。
## 常见问题
----
<AccordionGroup>
<Accordion title="事件处于 MONITORING 状态时告警会恢复吗?">
@@ -173,7 +168,6 @@ Flashduty 按推送类型分别生成 Alert Key:
</AccordionGroup>
## 排查问题
----
- **Flashduty 中没有告警**:确认发布事件或更新时通知了订阅者;计划维护和 `UNDERMAINTENANCE` 状态本来就不会生成告警
- **Flashduty 返回参数错误**:确认推送地址完整(包含 `integration_key`),且订阅者使用默认推送格式;推送内容缺少 `page.id`、事件 ID 或组件 ID 时会被拒绝
diff --git a/zh/on-call/integration/alert-integration/alert-sources/intersight.mdx b/zh/on-call/integration/alert-integration/alert-sources/intersight.mdx
index dfa9708c..9f2047b0 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/intersight.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/intersight.mdx
@@ -1,5 +1,6 @@
---
title: "Cisco Intersight 告警集成"
+sidebarTitle: "Cisco Intersight"
description: "通过 Webhook 订阅,将 Cisco Intersight 中服务器、存储和超融合设备的告警(Alarm)同步到 Flashduty On-call。"
keywords: ["告警集成", "Cisco Intersight", "Intersight", "Webhook", "UCS", "HyperFlex", "基础设施"]
---
@@ -9,7 +10,6 @@ Cisco Intersight 是 Cisco 的云端基础设施管理平台,管理 UCS、Hype
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Cisco Intersight 是 Cisco 的云端基础设施管理平台,管理 UCS、Hype
</div>
## 在 Cisco Intersight 中配置
----
<Steps>
<Step title="创建 Webhook">
@@ -58,7 +57,6 @@ Cisco Intersight 是 Cisco 的云端基础设施管理平台,管理 UCS、Hype
</Steps>
## 事件类型
----
| 推送内容 | 在 Flashduty 中的效果 |
| :--- | :--- |
@@ -67,12 +65,10 @@ Cisco Intersight 是 Cisco 的云端基础设施管理平台,管理 UCS、Hype
| 不带告警的请求(`Operation` 为 `None`、`Event` 为 null) | 创建一条独立的 Info 告警,不会恢复 |
## Alert Key
----
Flashduty 使用告警对象的 `Moid`(Intersight 为每个告警分配的固定编号)作为 Alert Key。同一个告警的创建、更新、清除使用相同的 Alert Key;名称、描述、严重程度、时间的变化不会改变它,缺少 `Moid` 的请求会被拒绝。
## 状态和告警等级
----
| Intersight `Severity` | Flashduty 等级 |
| :--- | :--- |
@@ -82,7 +78,6 @@ Flashduty 使用告警对象的 `Moid`(Intersight 为每个告警分配的固
| Cleared | 恢复(等级取 `OrigSeverity`,无有效值时为 Info) |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -96,12 +91,10 @@ Flashduty 使用告警对象的 `Moid`(Intersight 为每个告警分配的固
| `create_time` / `last_transition` | 告警创建时间和最近一次严重程度变化时间 |
## 关于签名
----
Intersight 使用您设置的 Secret 对请求做 HMAC 签名(`Authorization` 和 `Digest` 请求头)。Flashduty 不校验签名,推送地址中的 `integration_key` 是唯一的凭证,请妥善保管。
## 排查问题
----
- **Flashduty 没有收到推送**:确认 Webhook URL 完整且包含 `integration_key`,并且 Intersight 能访问公网
- **返回参数错误**:提示对象类型不支持时,说明订阅了 `cond.Alarm` 以外的对象;提示缺少 `Moid` 时,说明推送的不是告警对象
diff --git a/zh/on-call/integration/alert-integration/alert-sources/jdcloud.mdx b/zh/on-call/integration/alert-integration/alert-sources/jdcloud.mdx
index c0d6ed7a..853ed6fb 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/jdcloud.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/jdcloud.mdx
@@ -1,5 +1,6 @@
---
title: "京东云监控集成"
+sidebarTitle: "京东云监控"
description: "通过 webhook 的方式同步京东云监控告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "京东云监控集成", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "京东云监控集成", "监控告警", "数据接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "京东云监控集成", "监控告警", "数据接
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "京东云监控集成", "监控告警", "数据接
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **京东云监控** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,7 +45,6 @@ keywords: ["告警集成", "京东云监控集成", "监控告警", "数据接
</div>
## 在京东云
----
<Steps>
<Step title="创建通知模版">
@@ -55,29 +54,29 @@ keywords: ["告警集成", "京东云监控集成", "监控告警", "数据接
3. 勾选 **告警回调**,在 `URL` 中输入集成的推送地址
4. 在 `POST` 编辑框中输入以下模版内容:
-```json
-{
- "resource_id": "${resourceId}",
- "request_id": "${requestId}",
- "metric": "${metric}",
- "current_value": "${currentValue}",
- "times": "${times}",
- "tags": "${tags}",
- "alert_time": "${alertTime}",
- "region": "${region}",
- "threshold": "${threshold}",
- "service_code": "${serviceCode}",
- "as_group_id": "${asGroupId}",
- "unhealthy_instance": "${unhealthyInstance}",
- "rule_policy_id": "${rulePolicyId}",
- "service_code_en": "${serviceCodeEN}",
- "service_code_cn": "${serviceCodeCN}",
- "level": "${level}",
- "resource_name": "${resourceName}",
- "ip_address": "${ipAddress}",
- "status": "${status}"
-}
-```
+ ```json
+ {
+ "resource_id": "${resourceId}",
+ "request_id": "${requestId}",
+ "metric": "${metric}",
+ "current_value": "${currentValue}",
+ "times": "${times}",
+ "tags": "${tags}",
+ "alert_time": "${alertTime}",
+ "region": "${region}",
+ "threshold": "${threshold}",
+ "service_code": "${serviceCode}",
+ "as_group_id": "${asGroupId}",
+ "unhealthy_instance": "${unhealthyInstance}",
+ "rule_policy_id": "${rulePolicyId}",
+ "service_code_en": "${serviceCodeEN}",
+ "service_code_cn": "${serviceCodeCN}",
+ "level": "${level}",
+ "resource_name": "${resourceName}",
+ "ip_address": "${ipAddress}",
+ "status": "${status}"
+ }
+ ```
5. 其他选项按需配置,点击 **保存** 完成
@@ -99,7 +98,6 @@ keywords: ["告警集成", "京东云监控集成", "监控告警", "数据接
</Steps>
## 状态对照
----
<div className="md-block">
京东云监控到 Flashduty 告警等级映射关系:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/jfrog-xray.mdx b/zh/on-call/integration/alert-integration/alert-sources/jfrog-xray.mdx
index b897ab2a..eefa7688 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/jfrog-xray.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/jfrog-xray.mdx
@@ -1,5 +1,6 @@
---
title: "JFrog Xray 告警集成"
+sidebarTitle: "JFrog Xray"
description: "通过 Xray Webhook 将 JFrog Xray 监视(Watch)扫描出的安全、许可证和运营风险违规同步到 Flashduty On-call。"
keywords: ["告警集成", "JFrog", "Xray", "Webhook", "漏洞", "许可证", "策略违规", "软件供应链"]
---
@@ -11,7 +12,6 @@ Xray 只在扫描发现违规时推送,问题修复后不会发恢复通知,
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Xray 只在扫描发现违规时推送,问题修复后不会发恢复通知,
</div>
## 在 JFrog Xray 中配置
----
<Steps>
<Step title="创建 Webhook">
@@ -67,14 +66,12 @@ Xray 的 Webhook 页面没有测试按钮。向被监视的仓库上传一个带
</Steps>
## 告警恢复和自动关闭
----
Xray 的违规 Webhook 只在扫描发现违规时发送,请求体中没有表示违规已修复或已忽略的字段,所以 Flashduty 中的告警不会自动恢复。
每次推送对应一条独立的 Flashduty 告警,需要手动关闭,或在接收该集成的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),时长按团队处理漏洞的时效设定,例如 7 天。
## Alert Key
----
Xray 每次扫描监视时生成一个 `alert_id`。一次扫描命中多个策略规则时(例如同一个监视上的安全策略和许可证策略),Xray 为每个规则各发一次 Webhook,它们的 `alert_id` 相同。因此 Flashduty 用 `alert_id`、监视名称 `watch_name`、策略名称 `policy_name` 和规则名称 `policy_rule` 组合出 Alert Key(各部分之间用不可见分隔符连接后取 MD5):
@@ -84,7 +81,6 @@ Xray 每次扫描监视时生成一个 `alert_id`。一次扫描命中多个策
- 请求体缺少 `watch_name` 时,Flashduty 返回 400 并指出缺少的字段
## 状态和告警等级
----
告警的状态等于告警等级,不会恢复。等级取请求体中的最高严重程度 `top_severity`;它缺失或不是下表中的值时,取各问题中最严重的一个。
@@ -95,7 +91,6 @@ Xray 每次扫描监视时生成一个 `alert_id`。一次扫描命中多个策
| `Low`、`Information`、`Unknown`、缺失或其他值 | Info |
## 告警内容
----
一次 Webhook 包含该次扫描在这个规则下的全部问题(`issues`)。
@@ -114,7 +109,6 @@ Xray 每次扫描监视时生成一个 `alert_id`。一次扫描命中多个策
| `artifacts` | 受影响的组件,按严重程度排序,最多 20 个 |
## 排查问题
----
- **Flashduty 没有收到推送**:确认策略规则的 **Then** 中勾选了 **Trigger webhook** 并选择了该 Webhook,且策略已分配给监视、监视处于启用状态。Xray 只为新发现的违规推送,已经产生过的违规不会因为保存规则而重新推送,在监视的操作菜单中选择 **Apply on Existing Content** 也不会重新推送。可以向被监视的仓库上传一个新的带漏洞组件来验证
- **Flashduty 返回参数错误**:请求体不是 JSON,或缺少 `watch_name`。请直接使用 Xray 的违规 Webhook,不要经过会改写请求体的中转
diff --git a/zh/on-call/integration/alert-integration/alert-sources/jiankongbao.mdx b/zh/on-call/integration/alert-integration/alert-sources/jiankongbao.mdx
index 90044868..8137227c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/jiankongbao.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/jiankongbao.mdx
@@ -1,5 +1,6 @@
---
title: "监控宝告警事件"
+sidebarTitle: "监控宝"
description: "通过 webhook 的方式同步监控宝告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "监控宝告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "监控宝告警事件", "监控告警", "数据接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "监控宝告警事件", "监控告警", "数据接
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "监控宝告警事件", "监控告警", "数据接
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **监控宝** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,29 +46,28 @@ keywords: ["告警集成", "监控宝告警事件", "监控告警", "数据接
</div>
## 在监控宝
----
本集成同样适用于云智慧监控宝(含监控宝6)的 URL 回调通知。
<div className="md-block">
-## 一、监控宝告警推送配置
+## 监控宝告警推送配置
### 步骤1:配置告警通道
1. 登录监控宝控制台。
2. 点击右上方的个人配置。
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-1.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-1.png" />
3. 点击左侧导航栏中的 Webhooks 设置,并点击添加以及选择 URL 回调。
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-2.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-2.png" />
4. 自定义名称输入 Flashduty,回调 URL 输入复制集成的推送地址。
5. 回调方式选择 **POST**,数据格式选择 **JSON**。
6. 勾选**开启 URL 回调**,其他按需选择即可,参考下图配置。
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-3.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-3.png" />
7. 点击保存。
@@ -78,13 +77,13 @@ keywords: ["告警集成", "监控宝告警事件", "监控告警", "数据接
2. 此处省略其他告警配置。
3. 在 Webhook 通知处,选择 Flashduty 通道。
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-4.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/jkb-4.png" />
4. 保存监控任务即可。
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/jumpcloud.mdx b/zh/on-call/integration/alert-integration/alert-sources/jumpcloud.mdx
index 87ed0f86..db37e791 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/jumpcloud.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/jumpcloud.mdx
@@ -1,5 +1,6 @@
---
title: "JumpCloud 告警集成"
+sidebarTitle: "JumpCloud"
description: "通过 Webhook 通知渠道将 JumpCloud Insights 告警同步到 Flashduty On-call。"
keywords: ["告警集成", "JumpCloud", "Webhook", "Insights", "身份安全", "MDM"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "JumpCloud", "Webhook", "Insights", "身份安全", "
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "JumpCloud", "Webhook", "Insights", "身份安全", "
</div>
## 在 JumpCloud 中配置
----
<Steps>
<Step title="创建 Webhook 通知渠道">
@@ -62,14 +61,12 @@ keywords: ["告警集成", "JumpCloud", "Webhook", "Insights", "身份安全", "
</Steps>
## Alert Key
----
Flashduty 用 `alert_id`(JumpCloud 告警的 ID)生成 Alert Key。同一条 JumpCloud 告警在每次状态变化(Open、Acknowledged、Resolved、Auto-Resolved)时推送的都是同一个 `alert_id`,所以触发和恢复落在同一条 Flashduty 告警上。标题、优先级、描述、更新时间等字段变化不会改变 Alert Key。缺少 `alert_id` 的请求会被拒绝。
JumpCloud 文档规定同一条告警在阈值达到后的新事件会更新已有告警,这些更新都归入同一条 Flashduty 告警。
## 状态和告警等级
----
| JumpCloud `status` | Flashduty 状态 |
| :--- | :--- |
@@ -86,7 +83,6 @@ JumpCloud 文档规定同一条告警在阈值达到后的新事件会更新已
恢复事件保留该告警最后一次推送的等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -103,7 +99,6 @@ JumpCloud 文档规定同一条告警在阈值达到后的新事件会更新已
告警标题取自 `alert_title`,描述取自 `description`。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,并确认请求体是 JSON
- **告警没有恢复**:确认规则中勾选了 Alert Resolution,并且渠道处于启用状态
diff --git a/zh/on-call/integration/alert-integration/alert-sources/juniper-mist.mdx b/zh/on-call/integration/alert-integration/alert-sources/juniper-mist.mdx
index 05ca9024..67bf156b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/juniper-mist.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/juniper-mist.mdx
@@ -1,5 +1,6 @@
---
title: "Juniper Mist 告警集成"
+sidebarTitle: "Juniper Mist"
description: "通过 Webhook 将 Juniper Mist 的告警(alarms)触发和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Juniper Mist", "Mist", "Marvis", "无线网络", "Webhook", "alarms"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Juniper Mist", "Mist", "Marvis", "无线网络", "We
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Juniper Mist", "Mist", "Marvis", "无线网络", "We
</div>
## 在 Juniper Mist 中配置
----
<Steps>
<Step title="创建 Webhook">
@@ -76,7 +75,6 @@ Webhook 只推送已启用的告警类型。在 Mist 的告警(Alerts)配置
</Steps>
## Alert Key
----
一次推送可以包含多个告警事件(`events` 数组),Flashduty 为每个事件分别处理。
@@ -93,7 +91,6 @@ DHCP、DNS、ARP 类(`infra_dhcp_failure` / `infra_dhcp_success` 等)没有
同一台交换机或网关上,多个端口的关键端口告警共用同一个 Alert Key;HA 集群的两个节点也共用同一个 Alert Key。
## 状态和告警等级
----
| 事件 | 状态 |
| :--- | :--- |
@@ -115,7 +112,6 @@ DHCP、DNS、ARP 类(`infra_dhcp_failure` / `infra_dhcp_success` 等)没有
恢复事件保留其自身的等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -132,7 +128,6 @@ DHCP、DNS、ARP 类(`infra_dhcp_failure` / `infra_dhcp_success` 等)没有
告警标题为 `类型: 设备或主机名`,例如 `device down: d420b02000fa`。描述取自 `reasons`、`text`、`suggestion` 和 `count`。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,并且请求体是 Mist 的 `alarms` 主题格式
- **告警没有恢复**:确认对应的恢复类型也已在 Mist 中启用(例如启用了 AP offline,也要启用 AP reconnected)。恢复类型的默认启用状态可以在 `alarm_defs` 中查看
diff --git a/zh/on-call/integration/alert-integration/alert-sources/kapacitor.mdx b/zh/on-call/integration/alert-integration/alert-sources/kapacitor.mdx
index 6d5c0e7a..2410eef9 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/kapacitor.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/kapacitor.mdx
@@ -1,5 +1,6 @@
---
title: "Kapacitor 告警集成"
+sidebarTitle: "Kapacitor"
description: "通过 Kapacitor 的 post 事件处理器,使用 Flashduty 的 InfluxData 集成接收 Kapacitor 告警,恢复时自动关闭告警。"
keywords: ["告警集成", "Kapacitor", "InfluxData", "TICKscript", "post 事件处理器", "时序数据告警"]
---
@@ -9,7 +10,6 @@ Kapacitor 的 [post 事件处理器](https://docs.influxdata.com/kapacitor/v1/re
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 InfluxData**。
@@ -30,7 +30,6 @@ Kapacitor 的 [post 事件处理器](https://docs.influxdata.com/kapacitor/v1/re
</div>
## 在 Kapacitor 中配置
----
以下三种方式任选其一,推送地址都要填写完整(包含 `?integration_key=...`)。
@@ -90,7 +89,6 @@ options:
通过 Chronograf 1.x 的 Alert Rule Builder 添加 `post` 处理器,实际使用的就是同一个 Kapacitor 处理器,配置方法见 [InfluxData 集成](/zh/on-call/integration/alert-integration/alert-sources/influxdata)。
## 字段映射
----
| Kapacitor 字段 | Flashduty |
| :--- | :--- |
@@ -105,14 +103,12 @@ options:
`level` 不是以上取值时,Flashduty 返回 `level ... is not supported` 并拒绝该事件。
## 恢复与去重
----
- Kapacitor 在级别回到 `OK` 时发送 `level` 为 `OK` 的事件,Flashduty 按相同的 `id` 关闭告警。不要在 `alert()` 上使用 `.noRecoveries()`,否则 Kapacitor 不发送恢复事件。
- `id` 默认是 `{{ .Name }}:{{ .Group }}`(测量名称和分组)。用 `.id()` 自定义时,请保证同一个对象的触发和恢复使用相同的值。
- 需要在 Kapacitor 日志中看到 Flashduty 返回的错误时,给 `.post()` 加 `.captureResponse()`(topic 处理器为 `capture-response: true`),响应状态码不是 2xx 时会记录响应内容。
## 排查问题
----
- **Flashduty 返回 `Invalid parameters`**:推送地址不完整,缺少 `integration_key`,或集成类型不是 InfluxData
- **返回 `level ... is not supported`**:请求体的 `level` 不是 `CRITICAL`、`WARNING`、`INFO`、`OK`;请确认发送的是 Kapacitor 原始的告警数据,而不是经过转发或改写的内容
diff --git a/zh/on-call/integration/alert-integration/alert-sources/keep.mdx b/zh/on-call/integration/alert-integration/alert-sources/keep.mdx
index bde41516..b82febb6 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/keep.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/keep.mdx
@@ -1,5 +1,6 @@
---
title: "Keep 告警集成指引"
+sidebarTitle: "Keep"
description: "通过 Keep 的 Provider 将告警事件推送到 Flashduty On-call,实现告警事件自动化降噪处理。"
keywords: ["告警集成", "Keep 告警集成指引", "监控告警", "数据接入"]
---
@@ -10,12 +11,12 @@ keywords: ["告警集成", "Keep 告警集成指引", "监控告警", "数据接
您可通过以下2种方式,获取一个集成秘钥,任选其一即可。
-#### 使用专属集成
+### 使用专属集成
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -25,14 +26,14 @@ keywords: ["告警集成", "Keep 告警集成指引", "监控告警", "数据接
</Accordion>
</AccordionGroup>
-#### 使用共享集成
+### 使用共享集成
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Keep** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,7 +46,6 @@ keywords: ["告警集成", "Keep 告警集成指引", "监控告警", "数据接
## 在 Keep
----
### 字段释义
@@ -55,7 +55,7 @@ keywords: ["告警集成", "Keep 告警集成指引", "监控告警", "数据接
| event_status | 是 | string | 告警状态。<br /><br />枚举值(`首字母大写`):*Critical*:严重,*Warning*:警告,*Info*:提醒,*Ok*:恢复。<br /><br />当指定为Ok时,意味着对告警进行自动恢复。
| alert_key | 否 | string | 告警标识,用于对已经存在的告警进行更新或自动恢复。<br /><br />您可以自定义此值,但不可超过`255`个字符。您也可以依赖系统自动生成,该值会在响应中返回。<br /><br />如果您上报的是恢复事件,则此值必须存在。
| description | 否 | string | 告警描述,不超过`2048`个字符,超出后将自动截断。
-| labels | 否 | map | 告警标签集合,key 为标签名称,value 为标签值:<br /><br />1. 标签的 key 和 value 均为 string 类型,区分大小写。<br />2. 标签的 key 不要超过`128`个字符,遵循Prometheus标签命名规范。value 不超过`8192`字节(即 8 KB),超出后将自动截断,截断会回退到 UTF-8 字符边界,不会截出半个汉字。<br />3. 至多传入`50`个标签。请参考[标准告警最佳实践](/zh/on-call/integration/alert-integration/alert-sources/standard-alert#四、最佳实践)。<br /><br />示例:"resource": "171.26.23.22", "check": "api latency > 500ms"
+| labels | 否 | map | 告警标签集合,key 为标签名称,value 为标签值:<br /><br />1. 标签的 key 和 value 均为 string 类型,区分大小写。<br />2. 标签的 key 不要超过`128`个字符,遵循Prometheus标签命名规范。value 不超过`8192`字节(即 8 KB),超出后将自动截断,截断会回退到 UTF-8 字符边界,不会截出半个汉字。<br />3. 至多传入`50`个标签。请参考[标准告警最佳实践](/zh/on-call/integration/alert-integration/alert-sources/standard-alert#最佳实践)。<br /><br />示例:"resource": "171.26.23.22", "check": "api latency > 500ms"
diff --git a/zh/on-call/integration/alert-integration/alert-sources/kener.mdx b/zh/on-call/integration/alert-integration/alert-sources/kener.mdx
index 10de1e39..5ec0209c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/kener.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/kener.mdx
@@ -1,5 +1,6 @@
---
title: "Kener 告警集成"
+sidebarTitle: "Kener"
description: "通过 Webhook 触发器将 Kener 监控的宕机、延迟和可用率告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Kener", "Webhook", "状态页", "监控", "自托管"]
---
@@ -11,7 +12,6 @@ Kener 的 Webhook 请求体由您在触发器的模板里编写,本页提供
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Kener 的 Webhook 请求体由您在触发器的模板里编写,本页提供
</div>
## 在 Kener 中配置
----
需要 Kener 4.x,并使用有权限管理触发器和告警配置的账号登录管理后台。Kener 所在的服务器需要能访问 Flashduty 的推送地址。
@@ -44,22 +43,22 @@ Kener 的 Webhook 请求体由您在触发器的模板里编写,本页提供
3. **Headers** 保持为空,Flashduty 通过地址中的 `integration_key` 认证
4. 将 **Webhook Body** 替换为下面的模板:
-```json
-{
- "alert_id": {{alert_id}},
- "alert_name": "{{alert_name}}",
- "alert_for": "{{alert_for}}",
- "alert_value": "{{alert_value}}",
- "alert_status": "{{alert_status}}",
- "alert_severity": "{{alert_severity}}",
- "alert_cta_url": "{{alert_cta_url}}",
- "alert_incident_id": {{#alert_incident_id}}{{alert_incident_id}}{{/alert_incident_id}}{{^alert_incident_id}}null{{/alert_incident_id}},
- "alert_failure_threshold": {{alert_failure_threshold}},
- "alert_success_threshold": {{alert_success_threshold}},
- "is_resolved": {{is_resolved}},
- "is_triggered": {{is_triggered}}
-}
-```
+ ```json
+ {
+ "alert_id": {{alert_id}},
+ "alert_name": "{{alert_name}}",
+ "alert_for": "{{alert_for}}",
+ "alert_value": "{{alert_value}}",
+ "alert_status": "{{alert_status}}",
+ "alert_severity": "{{alert_severity}}",
+ "alert_cta_url": "{{alert_cta_url}}",
+ "alert_incident_id": {{#alert_incident_id}}{{alert_incident_id}}{{/alert_incident_id}}{{^alert_incident_id}}null{{/alert_incident_id}},
+ "alert_failure_threshold": {{alert_failure_threshold}},
+ "alert_success_threshold": {{alert_success_threshold}},
+ "is_resolved": {{is_resolved}},
+ "is_triggered": {{is_triggered}}
+ }
+ ```
5. 保存触发器
@@ -87,14 +86,12 @@ Kener 渲染模板时不做 JSON 转义。内置默认模板包含 `alert_messag
</Steps>
## Alert Key
----
Flashduty 使用 Kener 的 `alert_id` 作为 Alert Key。Kener 在监控达到失败阈值时创建一条告警记录,恢复时更新同一条记录的状态,因此触发和恢复的 `alert_id` 相同;同一个监控再次宕机会生成新的 `alert_id`,对应 Flashduty 的新告警。
监控名称、等级、状态、取值等字段变化不会改变 Alert Key。请求中缺少 `alert_id` 会被拒绝。`alert_id` 只在同一个 Kener 实例内唯一,一个 Flashduty 集成请只接收一个 Kener 实例的推送。
## 状态和告警等级
----
| `alert_status` | Flashduty 状态 |
| :--- | :--- |
@@ -110,7 +107,6 @@ Flashduty 使用 Kener 的 `alert_id` 作为 Alert Key。Kener 在监控达到
告警标题由监控标识、告警类型和取值拼成,例如 `my-api STATUS: DOWN`。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -124,7 +120,6 @@ Flashduty 使用 Kener 的 `alert_id` 作为 Alert Key。Kener 在监控达到
| `alert_url` | Kener 中该监控页面的链接 |
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,并确认触发器使用了本页的模板;响应信息会指出缺少的字段
- **Kener 触发器测试失败**:测试结果里会显示 HTTP 状态码或网络错误,确认 Kener 所在服务器能访问 Flashduty 推送地址
diff --git a/zh/on-call/integration/alert-integration/alert-sources/kentik.mdx b/zh/on-call/integration/alert-integration/alert-sources/kentik.mdx
index d47bb025..62dc7f65 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/kentik.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/kentik.mdx
@@ -1,5 +1,6 @@
---
title: "Kentik 告警集成"
+sidebarTitle: "Kentik"
description: "通过 Custom Webhook 通知渠道将 Kentik 告警策略和合成监测(Synthetics)告警同步到 Flashduty On-call,告警清除时自动恢复。"
keywords: ["告警集成", "Kentik", "Custom Webhook", "通知渠道", "Synthetics"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Kentik", "Custom Webhook", "通知渠道", "Syntheti
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Kentik", "Custom Webhook", "通知渠道", "Syntheti
</div>
## 在 Kentik 中配置
----
创建通知渠道需要 Kentik 的 Administrator 权限,Member 只能查看。
@@ -41,39 +40,39 @@ keywords: ["告警集成", "Kentik", "Custom Webhook", "通知渠道", "Syntheti
2. 点击 **Add Notification Channel**,类型(Type)选择 **Webhook**(列表中显示为 Custom Webhook)。请不要选择 **JSON** 类型,Flashduty 解析的是下面模板的输出
3. 按下表填写:
-| 配置项 | 填写内容 |
-| :--- | :--- |
-| **Name** | 便于识别的名称,如 `Flashduty` |
-| **Status** | 开启 |
-| **URL** | Flashduty 集成的完整推送地址,需包含 `integration_key` |
-| **Custom Headers** | 无需填写 |
-| **Custom Template** | 点击 **Go to Notification Template Setup**,在 **Template & Preview** 标签页的 **TEMPLATE** 中粘贴下方模板,不要修改字段名 |
-| **Uglify JSON** | 保持默认即可 |
-
-```go-template
-{
- "CompanyID": "{{ .CompanyID }}",
- "Events": [
- {{- range $index, $event := .Events -}}
- {{- join $index }}
- {
- "Type": {{ .Type | toJSON }},
- "AlarmID": "{{ with .Details.GetValue "AlarmID" }}{{ . }}{{ end }}",
- "IsActive": {{ .IsActive | toJSON }},
- "Importance": {{ .Importance | toJSON }},
- "Description": {{ .Description | toJSON }},
- "CurrentState": {{ .CurrentState | toJSON }},
- "PreviousState": {{ .PreviousState | toJSON }},
- "StartTime": {{ .StartTime | toJSON }},
- "EndTime": {{ .EndTime | toJSON }},
- "Details": {{ .Details.General.ToMap | toJSON }},
- "Dimensions": {{ (.Details.WithTag "dimension").ToMap | toJSON }},
- "Links": {{ (.Details.WithTag "url").ToMap | toJSON }}
- }
- {{- end }}
- ]
-}
-```
+ | 配置项 | 填写内容 |
+ | :--- | :--- |
+ | **Name** | 便于识别的名称,如 `Flashduty` |
+ | **Status** | 开启 |
+ | **URL** | Flashduty 集成的完整推送地址,需包含 `integration_key` |
+ | **Custom Headers** | 无需填写 |
+ | **Custom Template** | 点击 **Go to Notification Template Setup**,在 **Template & Preview** 标签页的 **TEMPLATE** 中粘贴下方模板,不要修改字段名 |
+ | **Uglify JSON** | 保持默认即可 |
+
+ ```go-template
+ {
+ "CompanyID": "{{ .CompanyID }}",
+ "Events": [
+ {{- range $index, $event := .Events -}}
+ {{- join $index }}
+ {
+ "Type": {{ .Type | toJSON }},
+ "AlarmID": "{{ with .Details.GetValue "AlarmID" }}{{ . }}{{ end }}",
+ "IsActive": {{ .IsActive | toJSON }},
+ "Importance": {{ .Importance | toJSON }},
+ "Description": {{ .Description | toJSON }},
+ "CurrentState": {{ .CurrentState | toJSON }},
+ "PreviousState": {{ .PreviousState | toJSON }},
+ "StartTime": {{ .StartTime | toJSON }},
+ "EndTime": {{ .EndTime | toJSON }},
+ "Details": {{ .Details.General.ToMap | toJSON }},
+ "Dimensions": {{ (.Details.WithTag "dimension").ToMap | toJSON }},
+ "Links": {{ (.Details.WithTag "url").ToMap | toJSON }}
+ }
+ {{- end }}
+ ]
+ }
+ ```
4. 点击 **Save** 保存
@@ -97,7 +96,6 @@ keywords: ["告警集成", "Kentik", "Custom Webhook", "通知渠道", "Syntheti
</Steps>
## Alert Key
----
Flashduty 使用 Kentik 的告警 ID(`AlarmID`,Kentik 界面中的 **Alert ID**)作为 Alert Key。同一条 Kentik 告警从 Active 到 Cleared 的每次状态变化通知都携带同一个告警 ID,因此会合并到同一条告警,并由清除通知关闭。
@@ -107,7 +105,6 @@ Flashduty 使用 Kentik 的告警 ID(`AlarmID`,Kentik 界面中的 **Alert I
- 一次推送包含多个事件时,每个事件各自对应一条告警;没有事件的推送会返回成功,但不会创建告警
## 状态和告警等级
----
状态由 `IsActive` 决定:
@@ -129,7 +126,6 @@ Flashduty 使用 Kentik 的告警 ID(`AlarmID`,Kentik 界面中的 **Alert I
| 其他或为空 | - | Info |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -145,7 +141,6 @@ Flashduty 使用 Kentik 的告警 ID(`AlarmID`,Kentik 界面中的 **Alert I
告警标题为 Kentik 的事件描述(`Description`),如 `Alarm for DDoS Protect Policy Active`。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,渠道类型是 **Custom Webhook**,并且模板与上文一致
- **提示 `AlarmID is required`**:该渠道被用于缓解或洞察通知,或模板被修改。只把该渠道用于告警策略和合成监测测试
diff --git a/zh/on-call/integration/alert-integration/alert-sources/komodor.mdx b/zh/on-call/integration/alert-integration/alert-sources/komodor.mdx
index 4b857d15..7dd34058 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/komodor.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/komodor.mdx
@@ -1,5 +1,6 @@
---
title: "Komodor 告警集成"
+sidebarTitle: "Komodor"
description: "通过 Komodor 实时健康监控(Realtime Health Monitors)的 Webhook 通知,将 Kubernetes 工作负载、节点、PVC 和 Job 的问题及恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Komodor", "Kubernetes", "Realtime Health Monitors", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Komodor", "Kubernetes", "Realtime Health Monitors",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -18,7 +18,7 @@ keywords: ["告警集成", "Komodor", "Kubernetes", "Realtime Health Monitors",
当您不需要将告警路由到不同的协作空间时,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,打开一个协作空间
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**
@@ -33,7 +33,7 @@ keywords: ["告警集成", "Komodor", "Kubernetes", "Realtime Health Monitors",
当您需要根据 Payload 将告警路由到不同的协作空间时,选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**
2. 选择 **Komodor**,填写集成名称
@@ -46,13 +46,11 @@ keywords: ["告警集成", "Komodor", "Kubernetes", "Realtime Health Monitors",
</div>
## 前提条件
----
- 已在 Kubernetes 集群中安装 Komodor Agent,并能在 Komodor 控制台看到该集群。
- 当前账号有权限编辑 Komodor 的 **Health Policies**。
## 在 Komodor 中配置
----
<Steps>
<Step title="打开监控">
@@ -89,7 +87,6 @@ Deploy 监控的通知只描述一次发布(成功或失败),不是健康
</Note>
## Alert Key
----
Flashduty 使用 `monitorType`、`cluster`、`namespace` 和 `resourceName` 四个字段共同生成 Alert Key。同一个资源的同一类问题,`open` 和 `closed` 消息的这四个字段相同,因此会合并到同一条告警并由 `closed` 消息恢复。
@@ -98,7 +95,6 @@ Flashduty 使用 `monitorType`、`cluster`、`namespace` 和 `resourceName` 四
- 节点(Node)问题没有命名空间,`namespace` 为空时同样可以生成 Alert Key。
## 状态和告警等级
----
Komodor 的 Webhook 通知不带告警等级字段,Flashduty 统一按 Critical 处理。
@@ -110,7 +106,6 @@ Komodor 的 Webhook 通知不带告警等级字段,Flashduty 统一按 Critica
`status` 为其他值,或缺少 `monitorType`、`cluster`、`resourceName` 时,Flashduty 返回错误,Komodor 会记为推送失败。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -126,7 +121,6 @@ Komodor 的 Webhook 通知不带告警等级字段,Flashduty 统一按 Critica
告警标题为 `<监控类型> issue on <资源名称> (<集群>/<命名空间>)`,告警描述包含问题详情和 Komodor 链接。
## 常见问题
----
<AccordionGroup>
<Accordion title="支持 Komodor Agentic Operation Platform 的 Notification sinks 吗?">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/kscloud-monitor.mdx b/zh/on-call/integration/alert-integration/alert-sources/kscloud-monitor.mdx
index 6a5db5a4..e676526e 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/kscloud-monitor.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/kscloud-monitor.mdx
@@ -1,5 +1,6 @@
---
title: "金山云监控集成"
+sidebarTitle: "金山云监控"
description: "通过 webhook 将金山云监控告警事件同步到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "金山云监控集成", "监控告警", "数据接入"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "金山云监控集成", "监控告警", "数据接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下 2 种方式获取集成推送地址,任选其一即可。
### 使用专属集成
@@ -17,7 +17,7 @@ keywords: ["告警集成", "金山云监控集成", "监控告警", "数据接
当您不需要将告警事件路由到不同的协作空间时,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**
@@ -32,7 +32,7 @@ keywords: ["告警集成", "金山云监控集成", "监控告警", "数据接
当您需要根据告警事件的 Payload 将告警路由到不同的协作空间时,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**
2. 选择 **金山云监控** 集成,并设置集成名称
@@ -44,7 +44,6 @@ keywords: ["告警集成", "金山云监控集成", "监控告警", "数据接
</div>
## 在金山云
----
<Steps>
<Step title="配置告警回调">
@@ -64,7 +63,6 @@ keywords: ["告警集成", "金山云监控集成", "监控告警", "数据接
</Steps>
## 状态和等级
----
指标告警支持触发和恢复;事件告警只有触发事件,没有对应的恢复事件。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/kuvasz.mdx b/zh/on-call/integration/alert-integration/alert-sources/kuvasz.mdx
index c69d7e72..a6a4d1a0 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/kuvasz.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/kuvasz.mdx
@@ -1,5 +1,6 @@
---
title: "Kuvasz 告警集成"
+sidebarTitle: "Kuvasz"
description: "通过 Kuvasz 的 Webhook 集成将网站、端口、DNS、容器和 SSL 证书监控告警同步到 Flashduty On-call,监控恢复时自动关闭告警。"
keywords: ["告警集成", "Kuvasz", "Webhook", "网站监控", "SSL 证书监控", "开源监控"]
---
@@ -9,7 +10,6 @@ Kuvasz 是开源、可自建的可用性与 SSL 证书监控服务。它的 **We
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Kuvasz 是开源、可自建的可用性与 SSL 证书监控服务。它的 **We
</div>
## 在 Kuvasz 中配置
----
Kuvasz 的集成只能通过 YAML 配置文件设置,修改后需要重启 Kuvasz 容器才会生效。
@@ -68,7 +67,6 @@ integrations:
</Steps>
## Alert Key
----
Flashduty 使用 `monitorId`(监控编号)加监控类型作为 Alert Key。Kuvasz 的每个监控有固定的编号,同一个监控的宕机(`*_DOWN`)和恢复(`*_UP`)消息带有相同的 `monitorId`,因此落在同一条 Flashduty 告警上。
@@ -79,7 +77,6 @@ Flashduty 使用 `monitorId`(监控编号)加监控类型作为 Alert Key。
请求缺少 `monitorId` 时,Flashduty 会拒绝该请求。
## 告警生命周期
----
Flashduty 按 `type` 字段处理消息:
@@ -96,19 +93,16 @@ Flashduty 按 `type` 字段处理消息:
其他类型同样被忽略。`DNS_RECORDS_CHANGED` 没有对应的恢复消息,建议在协作空间开启[超时自动关闭](/zh/on-call/channel/create-edit),超时计时起点选 **故障触发**,超时时长建议 24 小时。
## 告警等级
----
Kuvasz 的消息没有等级字段。宕机类事件和 `SSL_INVALID` 表示服务不可用,固定为 **Critical**;`SSL_WILL_EXPIRE` 和 `DNS_RECORDS_CHANGED` 固定为 **Warning**。恢复事件保留原告警的等级。
## 告警内容
----
- **标题**:监控名称
- **描述**:Kuvasz 生成的事件说明(`eventDetails`)
- **标签**:`check`(监控名称)、`monitor_id`、`monitor_type`(监控类型)、`monitor_name`、`monitor_urn`、`monitor_detail`(监控详情页的相对路径)、`event_type`(Kuvasz 的 `type`)、`source`(固定为 `kuvasz`)
## 排查问题
----
- **测试事件没有产生告警**:这是预期行为,测试事件只用于验证连通性
- **提示 `integration_key` 无效或返回 4xx**:确认 `url` 是完整的推送地址,并且集成没有被停用
diff --git a/zh/on-call/integration/alert-integration/alert-sources/label-mapping-api.mdx b/zh/on-call/integration/alert-integration/alert-sources/label-mapping-api.mdx
index a5ac1f4f..e6a03e30 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/label-mapping-api.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/label-mapping-api.mdx
@@ -5,7 +5,7 @@ keywords: ["标签映射", "API", "告警增强", "CMDB", "标签丰富", "外
---
-## 一、功能概述
+## 功能概述
标签映射 API 允许您构建自定义的外部服务来增强告警标签。工作流程如下:
@@ -17,7 +17,7 @@ keywords: ["标签映射", "API", "告警增强", "CMDB", "标签丰富", "外
<span id="ApiSpec"></span>
-## 二、API 规范
+## API 规范
### 请求方式
@@ -132,7 +132,7 @@ POST, Content-Type:"application/json"
<span id="ServiceConfig"></span>
-## 三、配置映射服务
+## 配置映射服务
在 Flashduty 中配置标签映射时,您需要先创建一个映射服务,然后在标签增强规则中引用该服务。
@@ -162,7 +162,7 @@ POST, Content-Type:"application/json"
<span id="HeaderBlacklist"></span>
-## 四、Header 安全约束
+## Header 安全约束
为了防止安全绕过、请求走私、IP 伪造及缓存污染,在自定义 API 请求头时,**禁止**使用以下 Header。系统网关将自动过滤或拒绝包含这些 Header 的请求。
@@ -183,7 +183,7 @@ POST, Content-Type:"application/json"
2. **长度限制**:单个 Header 的 Key 或 Value 长度不应超过 1024 字节
3. **格式校验**:Header 的 Value 严禁包含换行符(`\r`、`\n`),以防止 Header 注入攻击
-## 五、最佳实践
+## 最佳实践
1. **性能优先:** 此 API 位于告警处理的关键路径上,必须保证低延迟。对外部数据源的查询应尽可能快,建议实现缓存机制。
@@ -193,7 +193,7 @@ POST, Content-Type:"application/json"
4. **安全性:** API 必须通过认证和授权机制进行保护,推荐使用自定义 Header(如 `X-Custom-Auth`)传递认证信息。
-## 六、常见问题
+## 常见问题
1. **服务是否有响应超时时间?**
diff --git a/zh/on-call/integration/alert-integration/alert-sources/lacework.mdx b/zh/on-call/integration/alert-integration/alert-sources/lacework.mdx
index 9a010b07..d8b9e352 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/lacework.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/lacework.mdx
@@ -1,5 +1,6 @@
---
title: "Lacework FortiCNAPP 告警集成"
+sidebarTitle: "Lacework FortiCNAPP"
description: "通过 FortiCNAPP(原 Lacework)的自定义 Webhook 告警通道,将云安全告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Lacework", "FortiCNAPP", "Fortinet", "Webhook", "CNAPP", "云安全告警"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Lacework", "FortiCNAPP", "Fortinet", "Webhook", "CNA
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,13 +30,12 @@ keywords: ["告警集成", "Lacework", "FortiCNAPP", "Fortinet", "Webhook", "CNA
</div>
## 在 FortiCNAPP 中配置
----
<Steps>
<Step title="创建 Webhook 告警通道">
1. 使用管理员账号登录 FortiCNAPP 控制台
-2. 进入 **Settings > Notifications > Channels**,点击 **+ Add new**
+2. 进入 **Settings → Notifications → Channels**,点击 **+ Add new**
3. 选择 **Webhook**,点击 **Next**
4. 填写通道名称,例如 `Flashduty`
5. 在 **Webhook URL** 中粘贴 Flashduty 集成的完整推送地址(必须是 `https` 地址,`integration_key` 保留在查询参数中)
@@ -48,7 +47,7 @@ FortiCNAPP 对 Webhook 发送 HTTP `POST` 的 JSON 请求,请求体字段固
<Step title="创建告警规则">
-在 **Settings > Notifications > Alert rules** 中点击 **+ Add New**,选择上一步创建的通道,再按需选择告警等级、资源组和告警类别。只有命中告警规则的告警才会推送到 Flashduty。
+在 **Settings → Notifications → Alert rules** 中点击 **+ Add New**,选择上一步创建的通道,再按需选择告警等级、资源组和告警类别。只有命中告警规则的告警才会推送到 Flashduty。
</Step>
@@ -66,14 +65,12 @@ FortiCNAPP 对 Webhook 发送 HTTP `POST` 的 JSON 请求,请求体字段固
</Steps>
## Alert Key
----
Flashduty 使用请求体中的 `lacework_account` 与 `event_id` 生成 Alert Key。FortiCNAPP 文档对 `event_id` 的说明是 “The FortiCNAPP ID for the event”。同一事件的重复推送(例如告警通道按资源分组时每个资源一条通知)会落在同一条 Flashduty 告警上,不同事件各自产生告警。
标题、等级、描述、时间等字段的变化不会改变 Alert Key。请求缺少 `event_id` 时,Flashduty 为该请求单独生成一条告警;请求中 `event_id`、`event_title` 与 `event_description` 都缺失时返回参数错误。
## 状态和告警等级
----
FortiCNAPP 的 Webhook 没有状态字段,Flashduty 每次收到的都是触发事件。`event_severity` 取值 1 到 5,1 最高。
@@ -87,7 +84,6 @@ FortiCNAPP 的 Webhook 没有状态字段,Flashduty 每次收到的都是触
告警标题取 `event_title`,描述取 `event_description`。告警标签包含 Lacework 账号(`lacework_account`)、事件来源(`event_source`)、事件类型(`event_type`)、事件 ID、原始等级、合规建议 ID(`rec_id`,仅合规事件有)、事件时间和事件链接。
## 排查问题
----
- **没有收到告警**:确认告警规则选择了该通道,且规则的等级、资源组和告警类别覆盖了该告警;被禁用的通道不会投递
- **保存通道失败**:Webhook URL 必须是 `https`,并包含完整的 `integration_key` 查询参数
diff --git a/zh/on-call/integration/alert-integration/alert-sources/langsmith.mdx b/zh/on-call/integration/alert-integration/alert-sources/langsmith.mdx
index 6516d315..19837f21 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/langsmith.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/langsmith.mdx
@@ -1,5 +1,6 @@
---
title: "LangSmith 告警集成"
+sidebarTitle: "LangSmith"
description: "通过 LangSmith 告警规则的 Webhook,把 LLM 应用的错误数、延迟、成本等阈值告警同步到 Flashduty On-call。"
keywords: ["告警集成", "LangSmith", "LangChain", "Webhook", "alert_rule_id", "LLM 可观测"]
---
@@ -11,7 +12,6 @@ LangSmith 的文档没有描述"已恢复"通知:指标回落到阈值以内
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ LangSmith 的文档没有描述"已恢复"通知:指标回落到阈值以内
</div>
## 在 LangSmith 中配置
----
<Steps>
<Step title="创建告警规则并添加 Webhook">
@@ -60,7 +59,6 @@ LangSmith 的 Webhook 没有恢复通知:指标回落后不会再收到任何
</Steps>
## 推送内容
----
LangSmith 以 `application/json` POST 以下字段,Flashduty 直接解析:
@@ -82,19 +80,16 @@ LangSmith 以 `application/json` POST 以下字段,Flashduty 直接解析:
告警标题使用规则名称;规则名称为空时使用 `LangSmith alert <alert_rule_id>`。
## Alert Key
----
Flashduty 使用 `alert_rule_id` 作为 Alert Key。LangSmith 文档把它定义为标识告警的 UUID,同一条规则每次触发都带相同的 `alert_rule_id`,因此持续超阈值期间的重复通知合并到同一条告警,不同规则各自独立。修改规则名称、阈值或指标值不会改变 Alert Key。
请求中没有 `alert_rule_id`,或 `alert_rule_id` 为全零 UUID(LangSmith 测试通知使用)时,Flashduty 视为测试通知,返回成功且不创建告警。
## 状态和告警等级
----
LangSmith 的通知不带告警等级,Flashduty 统一按 Warning 处理;该阈值告警不代表服务已经中断,因此不默认为 Critical。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么告警不会自动恢复?">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/lark-alert.mdx b/zh/on-call/integration/alert-integration/alert-sources/lark-alert.mdx
index c2103b90..375ccb5d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/lark-alert.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/lark-alert.mdx
@@ -1,5 +1,6 @@
---
title: "飞书机器人兼容集成"
+sidebarTitle: "飞书机器人兼容"
description: "Flashduty 生成飞书自定义机器人格式的 Webhook 地址。已在向飞书自定义机器人推送告警的工具,把地址改为它即可将告警的发生与恢复接入 Flashduty。"
keywords: ["告警集成", "飞书", "监控告警", "数据接入", "飞书机器人兼容", "飞书自定义机器人"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "飞书", "监控告警", "数据接入", "飞书机
<div className="hide">
## 操作步骤
----
### 创建飞书机器人兼容集成
@@ -18,7 +18,7 @@ keywords: ["告警集成", "飞书", "监控告警", "数据接入", "飞书机
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -33,9 +33,9 @@ keywords: ["告警集成", "飞书", "监控告警", "数据接入", "飞书机
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **飞书机器人兼容** 集成:
- **集成名称**:为当前集成定义一个名称。
- **消息类型**:选择飞书告警消息类型,目前仅支持文本(Text)、富文本(Post)。
@@ -76,12 +76,10 @@ keywords: ["告警集成", "飞书", "监控告警", "数据接入", "飞书机
- 当飞书消息类型是Text 时,Flashduty On-call 会生成默认告警标题 “飞书告警”。
## 严重程度映射关系
----
当前飞书机器人兼容集成推送到 Flashduty 的严重程度均为 Warning,但您可以通过[告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines) 来自定义严重程度。
## 阿里云账号消息中心
----
<div className="md-block">
阿里云账号消息中心的"机器人接收"支持将账户、产品、安全等通知推送到自定义 Webhook,其数据格式可以复用飞书机器人协议,能直接对接本页的飞书机器人兼容集成。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/last9.mdx b/zh/on-call/integration/alert-integration/alert-sources/last9.mdx
index 6f994e1a..6a107d45 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/last9.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/last9.mdx
@@ -1,15 +1,15 @@
---
title: "Last9 告警集成"
+sidebarTitle: "Last9"
description: "通过 Last9 的 Webhook 通知渠道,使用 Flashduty 的 PagerDuty 兼容集成接收 Last9 告警,恢复通知自动关闭告警。"
keywords: ["告警集成", "Last9", "Webhook", "PagerDuty", "可观测性"]
---
-Last9 的 Webhook 通知渠道向你填写的 URL 发送 PagerDuty Events API v2 格式的 JSON,字段包括 `event_action`、`dedup_key` 和 `payload`。Flashduty 的 [PagerDuty 兼容集成](/zh/on-call/integration/alert-integration/alert-sources/pagerduty) 与该格式兼容,因此不需要单独的 Last9 集成:在 Flashduty 创建 PagerDuty 兼容集成,把它的推送地址填进 Last9 即可。
+Last9 的 Webhook 通知渠道向您填写的 URL 发送 PagerDuty Events API v2 格式的 JSON,字段包括 `event_action`、`dedup_key` 和 `payload`。Flashduty 的 [PagerDuty 兼容集成](/zh/on-call/integration/alert-integration/alert-sources/pagerduty) 与该格式兼容,因此不需要单独的 Last9 集成:在 Flashduty 创建 PagerDuty 兼容集成,把它的推送地址填进 Last9 即可。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 PagerDuty 兼容**,不是 Last9。
@@ -30,7 +30,6 @@ Last9 的 Webhook 通知渠道向你填写的 URL 发送 PagerDuty Events API v2
</div>
## 在 Last9 中配置
----
1. 进入 Last9 的 **Notification Channels**,点击 **Add Channel** → **Webhook**
2. 在 webhook URL 中填入上一步复制的完整推送地址(包含 `?integration_key=...`)
@@ -39,7 +38,6 @@ Last9 的 Webhook 通知渠道向你填写的 URL 发送 PagerDuty Events API v2
Last9 会对 Microsoft Teams、Flock、Google Chat、Telegram、Jira 和 Zenduty 的 URL 自动识别并改用各自的格式;Flashduty 的推送地址不在其列,按上面的通用格式发送。
## 字段映射
----
| Last9 字段 | Flashduty |
| :--- | :--- |
@@ -53,7 +51,6 @@ Last9 会对 Microsoft Teams、Flock、Google Chat、Telegram、Jira 和 Zenduty
| `links`、`images` | 以链接文字(或 `link_N`、`img_N`)为键的标签 |
## 恢复与去重
----
- Last9 发送 `event_action` 为 `resolve` 的通知时,Flashduty 按相同的 `dedup_key` 关闭对应告警。
- `severity` 只能是 `critical`、`error`、`warning`、`info`,其他取值会被 Flashduty 拒绝。
@@ -61,7 +58,6 @@ Last9 会对 Microsoft Teams、Flock、Google Chat、Telegram、Jira 和 Zenduty
- Last9 官方文档没有说明测试按钮的行为。首次配置后,用一条真实告警验证触发与恢复是否都出现在 Flashduty 中。
## 排查问题
----
- **Flashduty 返回 `Invalid parameters`**:推送地址不完整,缺少 `integration_key`,或集成类型不是 PagerDuty 兼容
- **告警没有恢复**:确认 Last9 发出了 `resolve` 通知,且其 `dedup_key` 与触发时一致
diff --git a/zh/on-call/integration/alert-integration/alert-sources/level.mdx b/zh/on-call/integration/alert-integration/alert-sources/level.mdx
index 6a840868..3e238b84 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/level.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/level.mdx
@@ -1,5 +1,6 @@
---
title: "Level 告警集成"
+sidebarTitle: "Level"
description: "通过 Webhook 将 Level 设备告警的触发和解决同步到 Flashduty On-call。"
keywords: ["告警集成", "Level", "level.io", "RMM", "Webhook", "设备告警"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Level", "level.io", "RMM", "Webhook", "设备告警"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Level", "level.io", "RMM", "Webhook", "设备告警"
</div>
## 在 Level 中配置
----
<Steps>
<Step title="添加 Webhook">
@@ -55,12 +54,10 @@ Level 文档没有说明 Webhook 是否提供测试按钮,以及测试请求
</Steps>
## Alert Key
----
Flashduty 使用告警数据中的 `data.id`(Level 的告警 ID)作为 Alert Key,同一个告警的 `alert_active` 和 `alert_resolved` 使用同一个 Alert Key。告警名称、描述、等级、设备主机名等字段变化不会改变 Alert Key。Level 的 `event_id` 是事件的唯一标识,重试和手动重新发送时保持不变,Flashduty 不把它作为 Alert Key。缺少 `data.id` 的请求会被拒绝。
## 状态和告警等级
----
| 事件类型 | 状态 |
| :--- | :--- |
@@ -82,7 +79,6 @@ Flashduty 使用告警数据中的 `data.id`(Level 的告警 ID)作为 Alert
恢复事件保留告警原有的等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -98,7 +94,6 @@ Flashduty 使用告警数据中的 `data.id`(Level 的告警 ID)作为 Alert
告警标题为 `主机名: 告警名称`,描述取自 `data.description` 和 `data.payload`。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,并且请求体是 Level 的 Webhook 格式
- **告警没有恢复**:确认 Webhook 勾选了 `alert_resolved`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/librenms.mdx b/zh/on-call/integration/alert-integration/alert-sources/librenms.mdx
index 866f823d..77857ccc 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/librenms.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/librenms.mdx
@@ -1,5 +1,6 @@
---
title: "LibreNMS 告警集成"
+sidebarTitle: "LibreNMS"
description: "通过 LibreNMS 的 API 告警通道将设备告警同步到 Flashduty On-call,告警规则恢复时自动关闭告警。"
keywords: ["告警集成", "LibreNMS", "API transport", "网络监控", "SNMP"]
---
@@ -9,7 +10,6 @@ LibreNMS 通过 **API** 类型的告警通道(Alert Transport)推送告警
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ LibreNMS 通过 **API** 类型的告警通道(Alert Transport)推送告警
</div>
## 在 LibreNMS 中配置
----
以下步骤需要 LibreNMS 25.7.0 或更高版本:请求体模板用 `json_encode` 过滤器转义文本字段,这个过滤器从 25.7.0 开始提供。
@@ -106,7 +105,6 @@ LibreNMS 26.4.0 起,告警规则通过 **Operation** 指定通知通道;更
</Steps>
## Alert Key
----
Flashduty 使用 `alert_id` 作为 Alert Key。`alert_id` 是 LibreNMS `alerts` 表中的行 ID,每个「设备 + 告警规则」只有一行,触发、变化和恢复通知都携带同一个值;LibreNMS 自带的 PagerDuty 通道也用它作为去重键。因此同一台设备上同一条规则的通知落在同一条告警上,规则恢复后再次触发会打开一条新告警。
@@ -115,7 +113,6 @@ Flashduty 使用 `alert_id` 作为 Alert Key。`alert_id` 是 LibreNMS `alerts`
请求缺少 `alert_id` 或 `state` 时,Flashduty 会拒绝该请求。
## 告警生命周期
----
Flashduty 按 `state` 字段处理通知:
@@ -133,7 +130,6 @@ Flashduty 按 `state` 字段处理通知:
规则开启 **Acknowledgement alerts** 后,LibreNMS 会在告警被确认时发送 `state` 为 `2` 的通知。确认不会打开或关闭 Flashduty 告警,被忽略的通知返回成功。
## 告警等级
----
告警等级取自告警规则的 **Severity**:
@@ -147,7 +143,6 @@ Flashduty 按 `state` 字段处理通知:
恢复通知携带同一条规则的 Severity,恢复事件保留该等级。
## 告警内容
----
- **标题**:`<规则名称> on <主机名>`;规则名称为空时用 `LibreNMS rule <rule_id>` 代替
- **描述**:LibreNMS 告警模板渲染出的正文 `msg`,默认模板包含标题、等级、时间和故障对象
@@ -156,7 +151,6 @@ Flashduty 按 `state` 字段处理通知:
值为空的字段不会写入标签。
## 排查问题
----
- **测试时 LibreNMS 报 `Transport delivery failed with 401`,返回内容含 `integration_key is required`**:`integration_key` 要填在 **Options** 中,不能写在 **API URL** 里
- **测试时 LibreNMS 报 `Transport delivery failed with 400`**:如果返回内容中出现原样的 `{{ $name|json_encode }}`,说明 LibreNMS 低于 25.7.0,不认识 `json_encode` 过滤器,请升级;否则检查模板中带 `|json_encode` 的字段是否额外加了引号,以及 **Send as form** 是否未勾选
diff --git a/zh/on-call/integration/alert-integration/alert-sources/limacharlie.mdx b/zh/on-call/integration/alert-integration/alert-sources/limacharlie.mdx
index 2da1cf4c..7ad40bc9 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/limacharlie.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/limacharlie.mdx
@@ -1,5 +1,6 @@
---
title: "LimaCharlie 告警集成"
+sidebarTitle: "LimaCharlie"
description: "通过 Webhook 输出将 LimaCharlie 检测与响应(D&R)规则产生的检测事件同步到 Flashduty On-call。"
keywords: ["告警集成", "LimaCharlie", "EDR", "D&R", "Detection", "Webhook", "detect_id"]
---
@@ -11,7 +12,6 @@ LimaCharlie 检测只在命中时发送一次,没有对应的恢复通知,
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ LimaCharlie 检测只在命中时发送一次,没有对应的恢复通知,
</div>
## 在 LimaCharlie 中配置
----
<Steps>
<Step title="新增 Webhook 输出">
@@ -63,14 +62,12 @@ Webhook 输出只转发检测。请确认组织中已启用会产生检测的 D&
</Steps>
## Alert Key
----
Flashduty 使用检测的 `detect_id` 作为 Alert Key。LimaCharlie 官方文档将其定义为唯一的检测标识;同一条检测被重发时 `detect_id` 不变,会合并到同一条告警,不同检测各自成为独立告警。
`cat`(检测名称)、`priority` 和时间不参与 Alert Key。请求中没有 `detect_id` 但有 `cat` 时,Flashduty 会返回参数错误。
## 告警等级
----
LimaCharlie 只提供可选的整数 `priority`(0 到 10),没有等级定义,下表是 Flashduty 的划分:
@@ -82,7 +79,6 @@ LimaCharlie 只提供可选的整数 `priority`(0 到 10),没有等级定
| 0、缺省或非数字 | Warning |
## 字段映射
----
| Flashduty | LimaCharlie 字段 |
| :--- | :--- |
@@ -93,12 +89,10 @@ LimaCharlie 只提供可选的整数 `priority`(0 到 10),没有等级定
命中的原始事件(`detect`)和提取的 IOC(`detect_data`)不写入标签。
## 告警不会恢复
----
检测是一次性事件,LimaCharlie 不会发送恢复通知。请在接收该集成的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时,并按团队处理检测的时效调整。
## 排查问题
----
<AccordionGroup>
<Accordion title="LimaCharlie 提示输出失败或被临时停用">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/loadster.mdx b/zh/on-call/integration/alert-integration/alert-sources/loadster.mdx
index 959c0f47..08952db5 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/loadster.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/loadster.mdx
@@ -1,5 +1,6 @@
---
title: "Loadster 告警集成"
+sidebarTitle: "Loadster"
description: "通过 Loadster 的 Webhook 集成,将监控项(Monitor)的失败和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Loadster", "Synthetic Monitoring", "拨测", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Loadster", "Synthetic Monitoring", "拨测", "Webhoo
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Loadster", "Synthetic Monitoring", "拨测", "Webhoo
</div>
## 在 Loadster 中配置
----
<Steps>
<Step title="启用 Webhooks">
@@ -60,7 +59,6 @@ Webhook 为账号级配置,对账号下所有监控项生效。Loadster 在监
</Steps>
## 推送内容
----
Loadster 以 JSON 格式 POST 以下字段,Flashduty 直接解析,无需配置模板:
@@ -76,12 +74,10 @@ Loadster 以 JSON 格式 POST 以下字段,Flashduty 直接解析,无需配
监控项名称为空时,告警标题使用 `Loadster monitor <monitor.id>`。
## Alert Key
----
Flashduty 使用 `monitor.id` 作为 Alert Key。同一个监控项的失败和恢复通知携带相同的 `monitor.id`,因此会落在同一条告警上;修改监控项名称不会改变 Alert Key。请求顶层的 `id` 是每次通知新生成的 UUID,不参与 Alert Key。
## 状态和告警等级
----
Loadster 的通知不区分告警等级,Flashduty 按下表处理:
@@ -93,7 +89,6 @@ Loadster 的通知不区分告警等级,Flashduty 按下表处理:
不包含 `monitor.id` 的通知(例如压测开始、结束通知)会被确认并忽略,不创建告警。Loadster 的 Webhook 没有测试按钮。
## 常见问题
----
<AccordionGroup>
<Accordion title="监控项持续失败时会重复收到通知吗?">
@@ -110,7 +105,6 @@ Loadster 的 Webhook 对整个账号生效。需要按监控项区分时,可
</AccordionGroup>
## 排查问题
----
- **Loadster 没有推送**:确认 **Account → Integrations → Webhooks** 已启用并保存,且两个 URL 是包含 `integration_key` 的完整推送地址
- **Flashduty 返回参数错误**:确认请求体包含 `monitor.id` 和 `cycle.status`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/loggly.mdx b/zh/on-call/integration/alert-integration/alert-sources/loggly.mdx
index e4f9a09d..010242a1 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/loggly.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/loggly.mdx
@@ -1,5 +1,6 @@
---
title: "Loggly 告警集成"
+sidebarTitle: "Loggly"
description: "通过 HTTP Endpoints 将 Loggly(SolarWinds 旗下)的日志告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Loggly", "SolarWinds", "HTTP Endpoints", "日志告警", "Webhook"]
---
@@ -13,7 +14,6 @@ Loggly 的告警功能仅在付费套餐(Standard、Pro)中提供;免费
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -34,7 +34,6 @@ Loggly 的告警功能仅在付费套餐(Standard、Pro)中提供;免费
</div>
## 在 Loggly 中配置
----
<Steps>
<Step title="创建或编辑一条告警">
@@ -89,7 +88,6 @@ Loggly 的 HTTP Endpoints 没有单独的测试推送按钮。请让保存的搜
</Steps>
## Alert Key
----
Flashduty 使用「Loggly 账号子域名(`owner_subdomain`)+ 告警定义 ID」的组合作为 Alert Key。告警定义 ID 从 `edit_alert_link`(该告警的编辑页面地址)中解析,即 URL 中 `/alerts/edit/` 后面的数字,例如 `.../alerts/edit/8188` 中的 `8188`。
@@ -98,12 +96,10 @@ Flashduty 使用「Loggly 账号子域名(`owner_subdomain`)+ 告警定义 I
同一条告警定义在条件持续期间反复推送的多次通知,会合并到同一条 Flashduty 告警里,而不是各自开出新告警;告警名称、命中数、时间范围、查询语句等字段的变化不影响 Alert Key。
## 告警等级
----
Loggly 的 HTTP Endpoints 通知不携带严重程度字段,所有告警都以 **Warning** 等级触发。日志搜索命中数超过阈值本身不代表故障,如果某条保存搜索确实需要更高优先级,可在 Flashduty 的告警规则中调整。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -118,7 +114,6 @@ Loggly 的 HTTP Endpoints 通知不携带严重程度字段,所有告警都以
| `num_hits` | 本次检查窗口内命中的日志条数 |
## 常见问题
----
<AccordionGroup>
diff --git a/zh/on-call/integration/alert-integration/alert-sources/logicmonitor.mdx b/zh/on-call/integration/alert-integration/alert-sources/logicmonitor.mdx
index cf7b49b7..dacf00ff 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/logicmonitor.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/logicmonitor.mdx
@@ -1,5 +1,6 @@
---
title: "LogicMonitor 告警集成"
+sidebarTitle: "LogicMonitor"
description: "通过 LogicMonitor 的 Custom HTTP Delivery 集成将告警同步到 Flashduty On-call,告警清除时自动关闭告警。"
keywords: ["告警集成", "LogicMonitor", "Custom HTTP Delivery", "Webhook", "基础设施监控"]
---
@@ -9,7 +10,6 @@ LogicMonitor 通过 **Custom HTTP Delivery** 集成推送告警:告警产生
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ LogicMonitor 通过 **Custom HTTP Delivery** 集成推送告警:告警产生
</div>
## 在 LogicMonitor 中配置
----
以下操作需要可以管理 **Integrations**、**Escalation Chains** 和 **Alert Rules** 的 LogicMonitor 账号。
@@ -112,7 +111,6 @@ LogicMonitor 按优先级从小到大匹配告警规则,一条告警只命中
</Steps>
## Alert Key
----
Flashduty 使用 `alert_id`(`##ALERTID##`,形如 `LMD12345`)作为 Alert Key。LogicMonitor 文档说明,同一个「资源(或网站)+ LogicModule + 实例 + 数据点」组合上的告警都使用同一个告警 ID,因此告警产生、等级变化和清除通知落在同一条 Flashduty 告警上;告警清除后再次产生会打开一条新告警。
@@ -121,7 +119,6 @@ Flashduty 使用 `alert_id`(`##ALERTID##`,形如 `LMD12345`)作为 Alert K
请求缺少 `alert_id` 或 `alert_status`,或这两个字段仍是未替换的 `##ALERTID##`、`##ALERTSTATUS##` 时,Flashduty 会拒绝该请求。
## 告警生命周期
----
Flashduty 按 `alert_status` 字段(`##ALERTSTATUS##`)处理通知:
@@ -136,7 +133,6 @@ Flashduty 按 `alert_status` 字段(`##ALERTSTATUS##`)处理通知:
在集成中勾选 **Acknowledged** 后,LogicMonitor 会在告警被确认时发送 `ack` 通知。确认不会打开或关闭 Flashduty 告警,被忽略的通知返回成功。
## 告警等级
----
告警等级取自 `level` 字段(`##LEVEL##`),不区分大小写:
@@ -150,7 +146,6 @@ Flashduty 按 `alert_status` 字段(`##ALERTSTATUS##`)处理通知:
清除通知携带被清除告警的等级,恢复事件保留该等级。
## 告警内容
----
- **标题**:`<DataSource> <数据点> on <资源>`;资源为主机名,网站告警为网站名称。缺少 DataSource 和数据点时只用资源名称,全部缺少时为 `LogicMonitor alert <alert_id>`
- **描述**:`##MESSAGE##` 渲染出的告警正文,即 LogicModule 中配置的告警消息
@@ -159,7 +154,6 @@ Flashduty 按 `alert_status` 字段(`##ALERTSTATUS##`)处理通知:
值为空的字段不会写入标签。某些字段不适用于当前告警类型时(例如网站告警没有数据点),LogicMonitor 可能原样保留 `##DATAPOINT##` 这样的占位符,Flashduty 会把它当作空值处理。
## 排查问题
----
- **Test Alert Delivery 失败**:确认 **URL** 是完整的推送地址,包含 `integration_key` 参数,且 **HTTP Method** 为 `HTTP Post`
- **Flashduty 提示请求体不是合法 JSON**:确认 **Alert Data** 选择了 **Raw** 和 **JSON** 格式,模板中的每个 `##TOKEN##` 都在双引号内
diff --git a/zh/on-call/integration/alert-integration/alert-sources/logpoint.mdx b/zh/on-call/integration/alert-integration/alert-sources/logpoint.mdx
index fb347b86..e0ffd88f 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/logpoint.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/logpoint.mdx
@@ -1,5 +1,6 @@
---
title: "Logpoint 告警集成"
+sidebarTitle: "Logpoint"
description: "通过 Logpoint(Guardsix)告警规则的 HTTP Notification 将触发的告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Logpoint", "Guardsix", "SIEM", "HTTP Notification", "alertrule_id"]
---
@@ -11,7 +12,6 @@ Logpoint 只在规则触发时发送通知,没有对应的恢复通知,因
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Logpoint 只在规则触发时发送通知,没有对应的恢复通知,因
</div>
## 在 Logpoint 中配置
----
Logpoint 的 HTTP Notification 没有固定报文,Body 由您填写的 Jinja 模板决定。Flashduty 只解析下面的模板。
@@ -83,12 +82,10 @@ Logpoint 的 HTTP Notification 没有固定报文,Body 由您填写的 Jinja
</Steps>
## Alert Key
----
Flashduty 使用 `alertrule_id`(`{{alertrule_id}}`)作为 Alert Key。Logpoint 文档将其定义为“告警的 ID”。同一条规则再次触发会合并到仍未关闭的同一条告警;`incident_id` 每次触发都会变化,只作为标签。规则名称、风险等级和命中数量的变化不会改变 Alert Key。
## 状态和告警等级
----
Flashduty 按 `risk_level`(`{{risk_level}}`)映射等级:
@@ -102,12 +99,10 @@ Flashduty 按 `risk_level`(`{{risk_level}}`)映射等级:
Logpoint 文档未列出 `risk_level` 的完整取值,其示例使用 `medium` 和 `high`,`critical` 与 `low` 按规则编辑页的风险选项推断。
## 告警不会恢复
----
Logpoint 触发后不会发送恢复通知。请在接收该集成的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时,并按团队处理告警的时效调整。
## 排查问题
----
- **Logpoint 没有发出请求**:确认通知的 Notification Trigger 为 **Automatic**,且规则已启用并真正命中
- **Flashduty 返回参数错误**:确认 Body 是有效 JSON 且保留了 `alertrule_id`;日志源或规则名称含双引号时会破坏 JSON
diff --git a/zh/on-call/integration/alert-integration/alert-sources/logrocket.mdx b/zh/on-call/integration/alert-integration/alert-sources/logrocket.mdx
index b7f21d04..e46e6c79 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/logrocket.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/logrocket.mdx
@@ -1,5 +1,6 @@
---
title: "LogRocket 告警集成"
+sidebarTitle: "LogRocket"
description: "通过 Webhook 将 LogRocket 时间序列图表(Timeseries)告警同步到 Flashduty On-call。"
keywords: ["告警集成", "LogRocket", "Webhook", "前端监控", "Timeseries"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "LogRocket", "Webhook", "前端监控", "Timeseries"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "LogRocket", "Webhook", "前端监控", "Timeseries"]
</div>
## 在 LogRocket 中配置
----
<Steps>
<Step title="为时间序列图表添加 Webhook 告警">
@@ -54,12 +53,10 @@ keywords: ["告警集成", "LogRocket", "Webhook", "前端监控", "Timeseries"]
Issues Alerts(新增严重问题)的 Webhook 使用另一种消息格式,且不带告警 ID,无法关联恢复,Flashduty 收到后直接返回成功,不创建告警。
## Alert Key
----
Alert Key 使用 LogRocket 推送的 `alert_id`。LogRocket 说明该 ID 在同一条告警多次触发和恢复之间保持不变,因此触发和恢复事件使用同一个 Alert Key。修改告警的阈值、时间间隔或图表位置不会改变 Alert Key。缺少 `alert_id` 的请求会被拒绝。
## 状态和告警等级
----
| LogRocket `status` | Flashduty 状态 | Flashduty 等级 |
| :--- | :--- | :--- |
@@ -69,7 +66,6 @@ Alert Key 使用 LogRocket 推送的 `alert_id`。LogRocket 说明该 ID 在同
LogRocket 的 Webhook 不携带等级,指标越过阈值不等同于服务中断,因此统一按 Warning 处理。其他 `status` 值会被拒绝。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -86,7 +82,6 @@ LogRocket 的 Webhook 不携带等级,指标越过阈值不等同于服务中
告警标题和描述取自 `reason`(LogRocket 会填入您设置的告警名称);缺少 `reason` 时标题为 `LogRocket alert <alert_id>`。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`;确认推送来自 Timeseries 图表告警而非 Issues Alerts
- **告警没有恢复**:确认恢复通知也推送到了同一个 URL,且 Flashduty 收到的 `alert_id` 与触发时一致
diff --git a/zh/on-call/integration/alert-integration/alert-sources/logz-io.mdx b/zh/on-call/integration/alert-integration/alert-sources/logz-io.mdx
index 76b47250..6c064a58 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/logz-io.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/logz-io.mdx
@@ -1,5 +1,6 @@
---
title: "Logz.io 告警集成"
+sidebarTitle: "Logz.io"
description: "通过 Logz.io 的 Custom Endpoint,把日志告警的触发事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Logz.io", "Custom Endpoint", "Webhook", "alert_definition_id"]
---
@@ -11,7 +12,6 @@ Logz.io 的 Custom Endpoint 只在告警条件满足时发送通知,没有"已
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Logz.io 的 Custom Endpoint 只在告警条件满足时发送通知,没有"已
</div>
## 在 Logz.io 中配置
----
<Steps>
<Step title="创建 Custom Endpoint">
@@ -87,7 +86,6 @@ Logz.io 的 Custom Endpoint 没有恢复事件:告警条件恢复正常后不
</Steps>
## Alert Key
----
Flashduty 使用 `alert_definition_id` 作为 Alert Key。Logz.io 官方文档把它定义为"Unique alert ID"(告警定义的唯一 ID),与之相对的 `alert_event_id` 是"Unique ID of the triggered alert instance"(每次触发实例的唯一 ID,每次通知都不同)。因此同一个告警定义反复触发(包括等待期结束后的重复通知、跨严重度阈值的升级通知)会落在同一条 Flashduty 告警上,而不同的告警定义各自独立。
@@ -96,7 +94,6 @@ Logz.io 的 Custom Endpoint 变量中不包含分组(Group By)字段的取
标题、描述、严重度、时间范围的变化都不会改变 Alert Key;请求缺少 `alert_definition_id` 时,Flashduty 会拒绝该请求。
## 告警等级
----
| Logz.io `alert_severity` | Flashduty 等级 |
| :--- | :--- |
@@ -109,14 +106,12 @@ Logz.io 的 Custom Endpoint 变量中不包含分组(Group By)字段的取
`alert_severity` 对应 Logz.io 告警配置中的 Severity Threshold(`severityThresholdTiers`),取值不区分大小写。空值或未列出的取值会被拒绝。由于 Custom Endpoint 没有恢复事件,告警状态始终等于上表中的等级,不会出现"恢复"状态。
## 告警内容
----
- **标题**:`alert_title`;为空时使用 `Logz.io alert`
- **描述**:`alert_description`
- **标签**:`check`(标题)、`source`(固定为 `logz_io`)、`alert_definition_id`、`alert_event_id`、`account_id`、`account_name`、`alert_tags`、`alert_timeframe_start`、`alert_timeframe_end`、`alert_app_url`、`vendor_severity`(原始 `alert_severity` 取值)
## 排查问题
----
- **Flashduty 返回参数错误**:确认消息体是合法 JSON,且 `alert_definition_id`、`alert_severity` 非空;确认 Headers 中已添加 `Content-Type: application/json`
- **真实告警没有收到(测试按钮显示失败属预期)**:确认告警的 **Notification endpoints** 中勾选了该 Custom Endpoint,且告警条件确实被触发
diff --git a/zh/on-call/integration/alert-integration/alert-sources/mackerel.mdx b/zh/on-call/integration/alert-integration/alert-sources/mackerel.mdx
index 1882dfc9..bda8b516 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/mackerel.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/mackerel.mdx
@@ -1,5 +1,6 @@
---
title: "Mackerel 告警集成"
+sidebarTitle: "Mackerel"
description: "通过 Webhook 通知渠道将 Mackerel 告警同步到 Flashduty On-call,告警关闭时自动恢复。"
keywords: ["告警集成", "Mackerel", "Webhook", "服务器监控", "外形监控"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Mackerel", "Webhook", "服务器监控", "外形监
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Mackerel", "Webhook", "服务器监控", "外形监
</div>
## 在 Mackerel 中配置
----
<Steps>
<Step title="添加 Webhook 通知渠道">
@@ -60,14 +59,12 @@ keywords: ["告警集成", "Mackerel", "Webhook", "服务器监控", "外形监
</Steps>
## Alert Key
----
Flashduty 使用 Mackerel 告警的 `alert.id` 作为 Alert Key。同一条 Mackerel 告警从发生、状态变化到关闭使用同一个 ID,因此这些通知会合并到同一条 Flashduty 告警。
同一监控规则在告警关闭后再次触发时,Mackerel 会生成新的告警 ID,Flashduty 也会创建新的告警。监控规则名称、消息、指标值和主机状态的变化不会改变 Alert Key。缺少 `alert.id` 的告警通知会被拒绝。
## 状态和告警等级
----
| Mackerel `alert.status` | `alert.isOpen` | 状态 | Flashduty 等级 |
| :--- | :--- | :--- | :--- |
@@ -80,7 +77,6 @@ Flashduty 使用 Mackerel 告警的 `alert.id` 作为 Alert Key。同一条 Mack
Mackerel 把 Unknown 与 Critical 视为同一级别,Flashduty 也将其映射为 Critical。手动关闭、删除监控规则、主机退役或删除服务都会关闭告警(`alert.isOpen` 为 `false`),Flashduty 会随之恢复告警。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -101,7 +97,6 @@ Mackerel 把 Unknown 与 Critical 视为同一级别,Flashduty 也将其映射
告警的消息 `message` 和监控规则的备注 `memo` 会写入告警描述。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`
- **没有收到告警**:确认渠道勾选了告警(`alert`)事件、渠道所在的通知分组包含该监控规则,并且主机状态为 `working`(Mackerel 不为 `standby`、`maintenance`、`poweroff` 状态的主机发送告警通知),监控规则的通知没有被静音
diff --git a/zh/on-call/integration/alert-integration/alert-sources/meraki.mdx b/zh/on-call/integration/alert-integration/alert-sources/meraki.mdx
index c227f23a..d7d7f83c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/meraki.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/meraki.mdx
@@ -1,5 +1,6 @@
---
title: "Meraki 告警事件"
+sidebarTitle: "Meraki"
description: "通过 webhook 的方式同步 Meraki 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "Meraki 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "Meraki 告警事件", "监控告警", "数据接入"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "Meraki 告警事件", "监控告警", "数据接入"
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "Meraki 告警事件", "监控告警", "数据接入"
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Meraki** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,11 +45,9 @@ keywords: ["告警集成", "Meraki 告警事件", "监控告警", "数据接入"
</div>
## 在 Meraki
----
<div className="md-block">
-## 一、Meraki 告警推送配置
1. 登录您的 `Meraki` 控制台,选择需要配置告警的设备。
2. 在 `Alerts` 页面中,按需配置 `Cellular gateway` 和其他部分。
@@ -62,7 +60,7 @@ keywords: ["告警集成", "Meraki 告警事件", "监控告警", "数据接入"
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/metoro.mdx b/zh/on-call/integration/alert-integration/alert-sources/metoro.mdx
index bc94324b..8f567f39 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/metoro.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/metoro.mdx
@@ -1,5 +1,6 @@
---
title: "Metoro 告警集成"
+sidebarTitle: "Metoro"
description: "通过 Metoro 的 Webhook 目的地,将告警的触发和恢复事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Metoro", "Kubernetes", "Webhook", "可观测性"]
---
@@ -11,7 +12,6 @@ Metoro 的 Webhook 请求体由您在 **Body Template** 里书写,Metoro 会
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Metoro 的 Webhook 请求体由您在 **Body Template** 里书写,Metoro 会
</div>
## 在 Metoro 中配置
----
<Steps>
<Step title="添加 Webhook">
@@ -79,7 +78,6 @@ Metoro 没有独立的测试按钮。让一条以该 Webhook 为目的地的告
</Steps>
## Alert Key
----
Flashduty 用 `alert_fire_uuid`(Metoro 的 `$alert_fire_uuid`,即某一次触发实例的 UUID)作为 Alert Key。Metoro 官方的 Rootly 集成指南用同一个字段配对触发和恢复通知(identifier 为 `$.metoro_alert_fire_uuid`,状态字段为 `resolved`),并说明带 group by 的告警里,每个分组值有各自的 `$alert_fire_uuid`,而 `$alert_uuid` 对所有分组相同。
@@ -88,7 +86,6 @@ Flashduty 用 `alert_fire_uuid`(Metoro 的 `$alert_fire_uuid`,即某一次
- `description`、`value` 等字段的变化不会改变 Alert Key
## 状态和告警等级
----
| Metoro `$alert_state` | Flashduty 状态或等级 |
| :--- | :--- |
@@ -98,7 +95,6 @@ Flashduty 用 `alert_fire_uuid`(Metoro 的 `$alert_fire_uuid`,即某一次
Metoro 告警没有等级字段,统一按 Warning 处理。空值或其他状态值会被拒绝。如需区分等级,可在 Flashduty 协作空间里用规则调整。
## 排查问题
----
- **Metoro 提示 Webhook 发送失败(400)**:确认 Body Template 是有效 JSON,且 `alert_fire_uuid`、`state` 非空。变量在 JSON 请求下会自动转义,不要自己再加转义
- **返回 404 或 401**:确认推送地址完整并包含 `integration_key`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/mezmo.mdx b/zh/on-call/integration/alert-integration/alert-sources/mezmo.mdx
index af53497b..0d05addd 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/mezmo.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/mezmo.mdx
@@ -1,5 +1,6 @@
---
title: "Mezmo 告警集成"
+sidebarTitle: "Mezmo"
description: "通过 Webhook Alert 把 Mezmo(原 LogDNA)日志视图的匹配结果同步到 Flashduty On-call。"
keywords: ["告警集成", "Mezmo", "LogDNA", "日志告警", "Webhook", "View", "Alert"]
---
@@ -13,7 +14,6 @@ Mezmo 官方文档明确 `autoresolve`(自动恢复)"只适用于 PagerDuty"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -34,7 +34,6 @@ Mezmo 官方文档明确 `autoresolve`(自动恢复)"只适用于 PagerDuty"
</div>
## 在 Mezmo 中配置
----
<Steps>
<Step title="创建或编辑一个 View">
@@ -89,12 +88,10 @@ Mezmo 的 Webhook Alert 没有恢复事件([Update Alert API](https://docs.mez
</Steps>
## Alert Key
----
Mezmo 的 Webhook Alert 请求体里没有告警 ID、View ID 或去重键——[Body Tokens 列表](https://docs.mezmo.com/docs/webhook-alert-integration#body-tokens) 里的 12 个 token(`name`、`matches`、`lines`、`level`、`url`、`query`、`app`、`host`、`tag`、`line`、`line_objects`、`first_line_object`)都不是标识符。View 名称和它运行的查询条件是这个检查项在多次匹配之间不变的身份——官方文档把 `query` 定义为"the query of the View to which this alert is attached"(该告警所关联 View 的查询条件)——因此 Flashduty 用 `MD5(view_name, query)` 作为 Alert Key:同一个 View、同一条查询条件的多次匹配会合并进同一条告警(首行匹配日志、匹配行数、级别等字段变化不影响这个 Key);不同的 View,或者同一 View 但查询条件被改过,会各自开出自己的告警。
## 告警等级
----
Mezmo 官方文档对 `{{ level }}` 的说明是"Severity level (info, warn, error, etc)"(首行匹配日志的日志级别),并未给出完整枚举。Flashduty 按下表映射,未出现在表中的值(包括空值,即日志没有解析出级别)按 **Warning** 处理:
@@ -106,7 +103,6 @@ Mezmo 官方文档对 `{{ level }}` 的说明是"Severity level (info, warn, err
| 空值或其他未识别的值 | Warning |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -122,7 +118,6 @@ Mezmo 官方文档对 `{{ level }}` 的说明是"Severity level (info, warn, err
告警标题为 View 名称;描述内容优先展示首行匹配日志的原文(`{{ line }}`),并附上查询条件。
## 常见问题
----
<AccordionGroup>
diff --git a/zh/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud.mdx b/zh/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud.mdx
index 7e6cc60a..1856ac7c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud.mdx
@@ -1,5 +1,6 @@
---
title: "Microsoft Defender for Cloud 告警集成"
+sidebarTitle: "Microsoft Defender for Cloud"
description: "通过 Defender for Cloud 的工作流自动化运行 Logic App,用 HTTP 操作把安全警报推送到 Flashduty 标准告警事件集成。"
keywords: ["告警集成", "Microsoft Defender for Cloud", "Azure Security Center", "Logic App", "工作流自动化", "云安全", "标准告警事件"]
---
@@ -11,7 +12,6 @@ Microsoft Defender for Cloud 的 **Workflow automation**(工作流自动化)
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择标准告警事件**,不是 Microsoft Defender for Cloud。
@@ -32,7 +32,6 @@ Microsoft Defender for Cloud 的 **Workflow automation**(工作流自动化)
</div>
## 在 Microsoft Defender for Cloud 中配置
----
需要 **Security admin** 角色或资源组的 **Owner** 权限;创建和修改 Logic App 需要 **Logic App Contributor** 权限。
@@ -54,7 +53,6 @@ Microsoft Defender for Cloud 的 **Workflow automation**(工作流自动化)
也可以在某条安全警报的页面上点击 **Trigger logic app**,手动对这一条警报运行 Logic App。
## HTTP 操作
----
HTTP 操作各字段:
@@ -107,7 +105,6 @@ HTTP 操作各字段:
| 标签 `product_name`、`vendor_name` | Product Name、Vendor Name | `ProductName`、`VendorName` |
## 字段映射
----
| Defender for Cloud 字段 | Flashduty |
| :--- | :--- |
@@ -119,12 +116,10 @@ HTTP 操作各字段:
| Alert Uri | 标签 `alert_url`,在 Azure 门户中打开警报详情 |
## 恢复与去重
----
Defender for Cloud 工作流自动化只在警报产生(created or triggered)时运行 Logic App,不会在警报解除时再发通知,所以这个集成的告警不会自动恢复。请在接收该集成的协作空间开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 3 天,或按团队处理警报的周期调整;也可以在 Flashduty 中手动关闭。
## 排查问题
----
- **Flashduty 返回 `InvalidParameter`**:检查 `event_status` 是否为首字母大写的 `Critical`、`Warning`、`Info` 之一,`title_rule` 是否为空
- **工作流自动化的下拉列表里没有 Logic App**:列表只显示带有 Defender for Cloud 连接器的 Consumption Logic App,创建后点击 **Refresh**
diff --git a/zh/on-call/integration/alert-integration/alert-sources/microsoft-sentinel.mdx b/zh/on-call/integration/alert-integration/alert-sources/microsoft-sentinel.mdx
index b34683bf..dd41087c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/microsoft-sentinel.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/microsoft-sentinel.mdx
@@ -1,5 +1,6 @@
---
title: "Microsoft Sentinel 告警集成"
+sidebarTitle: "Microsoft Sentinel"
description: "通过 Microsoft Sentinel 自动化规则运行 Logic App,用 HTTP 操作把事件推送到 Flashduty 标准告警事件集成,事件关闭时自动恢复告警。"
keywords: ["告警集成", "Microsoft Sentinel", "Azure Sentinel", "Logic App", "SIEM", "自动化规则", "标准告警事件"]
---
@@ -11,7 +12,6 @@ Sentinel 的事件也包含 Microsoft Entra ID Protection、Microsoft Defender f
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择标准告警事件**,不是 Microsoft Sentinel。
@@ -32,7 +32,6 @@ Sentinel 的事件也包含 Microsoft Entra ID Protection、Microsoft Defender f
</div>
## 在 Microsoft Sentinel 中配置
----
整个流程分两步:先创建一个以 **Microsoft Sentinel incident** 触发器开头的 Logic App(Sentinel 里叫 playbook),再创建自动化规则去运行它。
@@ -54,7 +53,6 @@ Sentinel 的事件也包含 Microsoft Entra ID Protection、Microsoft Defender f
如果 playbook 在下拉列表中显示为灰色,说明 Sentinel 对它所在的资源组没有权限:点击 **Manage playbook permissions**,勾选对应资源组并点击 **Apply**(需要该资源组的 **Owner** 权限)。
## HTTP 操作
----
HTTP 操作各字段:
@@ -105,7 +103,6 @@ HTTP 操作各字段:
| 标签 `workspace`、`resource_group` | Workspace Name、Resource Group Name | `workspaceInfo.WorkspaceName`、`workspaceInfo.ResourceGroupName` |
## 字段映射
----
| Sentinel 字段 | Flashduty |
| :--- | :--- |
@@ -117,7 +114,6 @@ HTTP 操作各字段:
| Incident URL 等 | 同名标签,`incident_url` 可在告警详情中直接打开事件 |
## 恢复与去重
----
- 事件被关闭(**Status** 变为 `Closed`)时,Logic App 发送 `event_status` 为 `Ok` 的事件,Flashduty 按相同的 Alert Key 关闭告警。
- Sentinel 在事件新增告警、评论、标签等更新时也会触发 **When incident is updated**。上表的更新规则只在状态或严重程度变化时运行;如果去掉这些条件,每次更新都会推送一次,同一 Alert Key 的重复事件会合并到原告警。
@@ -125,7 +121,6 @@ HTTP 操作各字段:
- 一个事件包含多条 Sentinel 告警时,只推送一条 Flashduty 告警,标题和描述取自事件本身。
## 排查问题
----
- **Flashduty 返回 `InvalidParameter`**:检查 `event_status` 取值是否为首字母大写的四个枚举值之一,`title_rule` 是否为空
- **HTTP 操作返回 4xx 且提示认证或路由失败**:推送地址缺少 `integration_key`,或复制的不是标准告警事件集成的推送地址
diff --git a/zh/on-call/integration/alert-integration/alert-sources/moesif.mdx b/zh/on-call/integration/alert-integration/alert-sources/moesif.mdx
index c9d661e0..3b95d2ce 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/moesif.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/moesif.mdx
@@ -1,5 +1,6 @@
---
title: "Moesif 告警集成"
+sidebarTitle: "Moesif"
description: "通过 Moesif 的 Webhook 通知渠道,把 API 监控告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Moesif", "API 监控", "API 分析", "Webhook"]
---
@@ -11,7 +12,6 @@ Moesif 只在告警触发时发送通知,没有恢复通知,Flashduty 中的
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Moesif 只在告警触发时发送通知,没有恢复通知,Flashduty 中的
</div>
## 在 Moesif 中配置
----
<Steps>
<Step title="创建 Webhook 通知渠道">
@@ -65,26 +64,22 @@ Moesif 只在告警触发时发送通知,没有恢复通知,Flashduty 中的
</Note>
## 告警恢复和自动关闭
----
Moesif 只在规则触发时发送通知,请求体中没有告警 ID,也没有表示恢复的字段,所以 Flashduty 中的告警不会自动恢复。
Moesif 的每次通知对应一条独立的 Flashduty 告警,需要手动关闭,或在接收该集成的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit)。建议设为告警规则评估周期的 2 倍,例如 15 分钟的规则设为 30 分钟。
## Alert Key
----
请求中没有可以标识同一告警的字段,Flashduty 为每次通知生成随机 Alert Key,不同通知不会合并为同一条告警。
## 状态和告警等级
----
Moesif 告警没有严重程度字段。Flashduty 中的告警等级固定为 **Warning**,状态等于告警等级,不会恢复。
请求中 `type` 不是 `alert` 的通知(例如同一渠道收到的其他类型通知)会被忽略,不产生告警。
## 告警内容
----
- **标题**:告警规则名称 `name`;规则只有一个分组值时,追加该分组值,例如 `Latency per user: user-1`。缺少规则名称时为 `Moesif alert`
- **描述**:规则条件 `metric`,以及每个分组值的当前取值和变化方向(动态告警),最多列出 20 个
@@ -100,7 +95,6 @@ Moesif 告警没有严重程度字段。Flashduty 中的告警等级固定为 **
| `feature_count` | 通知包含多个分组值时,分组值的数量 |
## 排查问题
----
- **Flashduty 没有收到告警**:确认告警规则的 **Send To** 中选择了该渠道,规则处于开启状态;确认渠道的 Webhook URL 是完整的推送地址,包含 `integration_key`;在 Moesif 的 **Alert History** 中确认规则已经触发,且没有被 Throttle 或 Silencing 抑制
- **Flashduty 返回参数错误**:请求体不是 JSON,或既没有 `name` 也没有 `metric_values`。请使用 Moesif 自带的 Webhook 渠道,不要改写请求体
diff --git a/zh/on-call/integration/alert-integration/alert-sources/mongodb-atlas.mdx b/zh/on-call/integration/alert-integration/alert-sources/mongodb-atlas.mdx
index f85480b2..6816eded 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/mongodb-atlas.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/mongodb-atlas.mdx
@@ -1,5 +1,6 @@
---
title: "MongoDB Atlas 告警集成"
+sidebarTitle: "MongoDB Atlas"
description: "通过 Webhook 将 MongoDB Atlas 项目告警同步到 Flashduty On-call,告警关闭时自动恢复。"
keywords: ["告警集成", "MongoDB", "MongoDB Atlas", "Atlas", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "MongoDB", "MongoDB Atlas", "Atlas", "Webhook"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "MongoDB", "MongoDB Atlas", "Atlas", "Webhook"]
</div>
## 在 MongoDB Atlas 中配置
----
需要项目的 `Project Owner` 或组织的 `Organization Owner` 权限配置 Webhook 集成;编辑告警设置需要 `Project Owner` 或 `Project Alerts Manager` 权限。
@@ -74,14 +73,12 @@ Atlas 要求 Webhook 地址可从公网访问并返回 2xx。连续投递失败
</Tip>
## Alert Key
----
Flashduty 使用请求体中的告警 `id` 作为 Alert Key。Atlas 文档将 `id` 定义为告警的唯一标识,同一条告警的打开、更新、确认、关闭和取消通知携带相同的 `id`,因此会落在同一条 Flashduty 告警上。
`status`、`currentValue`、`humanReadable` 和时间字段的变化都不会改变 Alert Key。请求缺少 `id` 时 Flashduty 会拒绝,因为无法关联后续恢复。
## 状态和告警等级
----
Atlas 在请求头 `X-MMS-Event` 中标明告警状态:
@@ -112,7 +109,6 @@ Atlas 对副本集的每个节点分别判断主机类条件,每个节点的
信息类告警是一次性事件,每次通知带有新的 `id`,Atlas 不会发送关闭通知。这类告警在 Flashduty 中不会自动恢复,需要手动关闭,或开启协作空间的[超时自动关闭](/zh/on-call/channel/create-edit)。
## 告警内容
----
- **标题**:`metricName`,为空时使用 `eventTypeName`;能取到资源时追加 ` on <资源>`,例如 `CONNECTIONS on Cluster0`
- **描述**:`humanReadable`,包含项目名、组织名和告警详情
@@ -121,7 +117,6 @@ Atlas 对副本集的每个节点分别判断主机类条件,每个节点的
确认人 `acknowledgingUsername` 和确认备注不会写入标签。
## 排查问题
----
- **Atlas Activity Feed 显示投递失败**:确认 **Webhook URL** 是完整推送地址且包含 `integration_key`
- **Flashduty 返回参数错误**:确认没有配置 **Webhook Body Template**,请求体中有 `id`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/monit.mdx b/zh/on-call/integration/alert-integration/alert-sources/monit.mdx
index e91d88d8..e115bf68 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/monit.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/monit.mdx
@@ -1,5 +1,6 @@
---
title: "Monit 告警集成"
+sidebarTitle: "Monit"
description: "Flashduty Monit 告警集成,Monit 服务通过此集成上报告警"
keywords: ["告警集成", "Monit ", "监控告警", "数据接入"]
---
@@ -14,6 +15,6 @@ keywords: ["告警集成", "Monit ", "监控告警", "数据接入"]
前往`Monit`-`告警规则`-`规则详情`页面,配置监控指标和阈值等条件,并开启告警。您可以选择将告警投递至多个协作空间。告警的通知规则遵循协作空间下的分派策略,您可以为团队设定值班人员,在告警发生时分派给值班人。
-
+
某些情况下,您可能希望将同一个告警规则产生的告警,按条件路由到不同的协作空间,这个时候您可以选择将告警直接投递到集成,而非协作空间列表。并在当前集成下,设置路由规则。
\ No newline at end of file
diff --git a/zh/on-call/integration/alert-integration/alert-sources/monitive.mdx b/zh/on-call/integration/alert-integration/alert-sources/monitive.mdx
index 201ea8e6..a7ca6e21 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/monitive.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/monitive.mdx
@@ -1,5 +1,6 @@
---
title: "Monitive 告警集成"
+sidebarTitle: "Monitive"
description: "通过监控项 Webhook 将 Monitive(uptimemonitoring.com)的宕机、抖动和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Monitive", "uptimemonitoring.com", "Uptime", "Webhook", "monitor_id"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Monitive", "uptimemonitoring.com", "Uptime", "Webhoo
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Monitive", "uptimemonitoring.com", "Uptime", "Webhoo
</div>
## 在 Monitive 中配置
----
Monitive 的 Webhook 按监控项配置,每个监控项只有一个 Webhook 位置,需要对每个要接入的监控项分别设置。
@@ -65,7 +64,6 @@ Monitive 每次投递都带 `X-UptimeMonitoring-Signature`(HMAC-SHA256)请
</Note>
## 推送内容
----
Monitive 以 `application/json` 格式 POST 以下字段,Flashduty 直接解析,无需配置模板:
@@ -82,14 +80,12 @@ Monitive 以 `application/json` 格式 POST 以下字段,Flashduty 直接解
告警标题使用监控项名称;名称为空时依次使用被监控地址、`Monitive monitor <monitor_id>`。
## Alert Key
----
Flashduty 使用 `monitor_id` 作为 Alert Key。同一个监控项的宕机、抖动和恢复通知携带相同的 `monitor_id`,因此落在同一条告警上;不同监控项即使名称和地址相同,也会生成不同的告警。重命名监控项、修改地址或原因不会改变 Alert Key。`delivery_id` 每次状态变化都不同,因此不参与 Alert Key。
请求中缺少 `monitor_id` 时,Flashduty 会返回参数错误,因为无法可靠地把恢复通知关联到原告警。`event` 不是上述三个值的请求会被确认并忽略,不创建告警。
## 状态和告警等级
----
Monitive 的通知不带告警等级。宕机属于服务中断信号,按 Critical 处理;抖动按 Warning 处理。
@@ -100,7 +96,6 @@ Monitive 的通知不带告警等级。宕机属于服务中断信号,按 Crit
| `monitor.up` | 恢复,原等级沿用告警上一次的等级 |
## 常见问题
----
<AccordionGroup>
<Accordion title="抖动告警什么时候恢复?">
@@ -123,7 +118,6 @@ Webhook 包含在免费版中,每个监控项一个 Webhook,免费版最多
</AccordionGroup>
## 排查问题
----
- **Flashduty 没有收到告警**:在 Monitive 中查询 `GET /api/v1/webhook-deliveries?monitor_id=<id>`,确认投递状态和响应码
- **Flashduty 返回参数错误**:确认请求体是 Monitive 的 JSON,且 `monitor_id` 非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/monte-carlo.mdx b/zh/on-call/integration/alert-integration/alert-sources/monte-carlo.mdx
index 9ae3916f..e2deb4c0 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/monte-carlo.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/monte-carlo.mdx
@@ -1,5 +1,6 @@
---
title: "Monte Carlo 告警集成"
+sidebarTitle: "Monte Carlo"
description: "通过 Webhook 将 Monte Carlo 数据可观测性平台的异常事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Monte Carlo", "数据可观测性", "Webhook", "incident_id"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Monte Carlo", "数据可观测性", "Webhook", "inci
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Monte Carlo", "数据可观测性", "Webhook", "inci
</div>
## 在 Monte Carlo 中配置
----
<Steps>
<Step title="创建 Webhook Audience">
@@ -61,12 +60,10 @@ Monte Carlo 官方文档未公开 Webhook 的连通性测试按钮,也未给
</Steps>
## Alert Key
----
Flashduty 使用 `payload.incident_id` 作为 Alert Key。Monte Carlo 官方文档给出的两个示例 payload(自定义规则触发、数据量异常)中都携带该字段;同一 payload 中的 `payload.url` 固定为 `https://getmontecarlo.com/incidents/<incident_id>`,是 Monte Carlo 控制台中定位该 Incident 的地址,据此推测该字段在 Incident 生命周期中保持不变。缺少 `incident_id` 的请求会被拒绝。
## 状态和告警等级
----
告警状态由 `payload.alert_feedback` 决定:取值为 `fixed`、`expected`、`no_action_needed`、`false_positive` 时恢复,其余取值(`investigating`、`no_status`、`work_in_progress` 等)保持活动。
@@ -81,7 +78,6 @@ Flashduty 使用 `payload.incident_id` 作为 Alert Key。Monte Carlo 官方文
| 空值或未标记(默认) | Warning |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -100,7 +96,6 @@ Flashduty 使用 `payload.incident_id` 作为 Alert Key。Monte Carlo 官方文
Monte Carlo 官方文档将 Audience 负责人(assigned owner)描述为一个邮箱地址;出于隐私考虑,Flashduty 不会把邮箱写入标签。
## 排查问题
----
- **Monte Carlo 提示 Webhook 调用失败**:确认推送地址完整且包含 `integration_key`
- **Flashduty 返回参数错误**:确认 Audience 已正确配置为 Webhook 渠道,且 Monte Carlo 没有发送自定义 Payload(Flashduty 只解析官方固定格式)
diff --git a/zh/on-call/integration/alert-integration/alert-sources/nagios.mdx b/zh/on-call/integration/alert-integration/alert-sources/nagios.mdx
index e284b5f2..1cfef85b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/nagios.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/nagios.mdx
@@ -1,5 +1,6 @@
---
title: "Nagios 告警事件"
+sidebarTitle: "Nagios"
description: "通过 webhook 的方式同步 Nagios 告警事件到 Flashduty,实现告警事件自动化降噪处理"
keywords: ["告警集成", "Nagios 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "Nagios 告警事件", "监控告警", "数据接入"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "Nagios 告警事件", "监控告警", "数据接入"
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -30,9 +30,9 @@ keywords: ["告警集成", "Nagios 告警事件", "监控告警", "数据接入"
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Nagios** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -44,13 +44,12 @@ keywords: ["告警集成", "Nagios 告警事件", "监控告警", "数据接入"
</div>
## 在 Nagios
----
<div className="md-block">
不同的系统和安装方式,Nagios 的安装路径可能不同,请根据实际情况调整以下配置中的路径。
-### 一、下载通知脚本
+### 下载通知脚本
登录 Nagios Server 所在服务器,下载通知脚本到 Nagios 插件目录:
@@ -80,7 +79,7 @@ chmod +x send_to_flashduty.sh
<Note>脚本中使用了 `curl` 命令,请确保 Nagios Server 上已安装 curl。</Note>
-### 二、创建 Flashduty 配置文件
+### 创建 Flashduty 配置文件
下载 Flashduty 配置文件到 Nagios 配置目录:
@@ -105,12 +104,12 @@ cd /usr/local/nagios/etc/objects/
wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/nagios/flashduty.cfg
```
-### 三、修改配置文件
+### 修改配置文件
编辑下载的 `flashduty.cfg` 文件,修改以下内容:
-1. 将 `pager` 字段的值替换为你在 Flashduty 控制台获取的集成推送地址
-2. 根据你的 Nagios 安装路径,修改 `command_line` 中脚本的路径
+1. 将 `pager` 字段的值替换为您在 Flashduty 控制台获取的集成推送地址
+2. 根据您的 Nagios 安装路径,修改 `command_line` 中脚本的路径
配置文件内容示例:
@@ -139,16 +138,16 @@ define command {
```
参数说明:
-- `pager`:Flashduty 推送地址,即你在 Flashduty 控制台获取的集成推送地址
+- `pager`:Flashduty 推送地址,即您在 Flashduty 控制台获取的集成推送地址
- `<NAGIOS_PLUGIN_PATH>`:需要替换为实际的脚本路径,如 `/usr/local/nagios/libexec`
- `service_notification_options`:服务告警通知选项,w=警告,u=未知,c=严重,r=恢复
- `host_notification_options`:主机告警通知选项,d=宕机,u=不可达,r=恢复
<Tip>如需在告警中携带更多信息,可以在 `command_line` 末尾按照 `key=value` 格式追加参数,例如:`environment="production" region="$_HOSTREGION$"`。这些参数将作为标签(labels)推送到 Flashduty。</Tip>
-### 四、引入配置文件
+### 引入配置文件
-如果你使用的是 **RHEL/CentOS 系统** 或 **源码安装**,需要在 Nagios 主配置文件中引入 Flashduty 配置文件。
+如果您使用的是 **RHEL/CentOS 系统** 或 **源码安装**,需要在 Nagios 主配置文件中引入 Flashduty 配置文件。
- **RHEL/CentOS 系统**:编辑 `/etc/nagios/nagios.cfg`,添加:
@@ -164,9 +163,9 @@ cfg_file=/usr/local/nagios/etc/objects/flashduty.cfg
<Note>Debian/Ubuntu 系统通常会自动加载 `/etc/nagios3/conf.d/` 目录下的所有配置文件,无需手动引入。</Note>
-### 五、将 Flashduty 添加到联系人组
+### 将 Flashduty 添加到联系人组
-编辑联系人配置文件,将 Flashduty 联系人添加到 `admins` 联系人组(或你使用的其他联系人组):
+编辑联系人配置文件,将 Flashduty 联系人添加到 `admins` 联系人组(或您使用的其他联系人组):
- **Debian/Ubuntu 系统**:编辑 `/etc/nagios3/conf.d/contacts_nagios2.cfg`
- **RHEL/CentOS 系统**:编辑 `/etc/nagios/objects/contacts.cfg`
@@ -182,27 +181,27 @@ define contactgroup {
}
```
-### 六、验证配置并重启服务
+### 验证配置并重启服务
1. 验证 Nagios 配置文件:
-- **Debian/Ubuntu 系统**:
+ - **Debian/Ubuntu 系统**:
-```bash
-/usr/sbin/nagios3 -v /etc/nagios3/nagios.cfg
-```
+ ```bash
+ /usr/sbin/nagios3 -v /etc/nagios3/nagios.cfg
+ ```
-- **RHEL/CentOS 系统**:
+ - **RHEL/CentOS 系统**:
-```bash
-/usr/sbin/nagios -v /etc/nagios/nagios.cfg
-```
+ ```bash
+ /usr/sbin/nagios -v /etc/nagios/nagios.cfg
+ ```
-- **源码安装**:
+ - **源码安装**:
-```bash
-/usr/local/nagios/bin/nagios -v /usr/local/nagios/etc/nagios.cfg
-```
+ ```bash
+ /usr/local/nagios/bin/nagios -v /usr/local/nagios/etc/nagios.cfg
+ ```
2. 如果验证通过,重启 Nagios 服务:
@@ -219,7 +218,6 @@ systemctl restart nagios
</div>
## 状态对照
----
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/netbeez.mdx b/zh/on-call/integration/alert-integration/alert-sources/netbeez.mdx
index f653bced..31f008b2 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/netbeez.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/netbeez.mdx
@@ -1,5 +1,6 @@
---
title: "NetBeez 告警集成"
+sidebarTitle: "NetBeez"
description: "通过 NetBeez Webhook 将网络监控的告警(Alert)和故障(Incident)通知同步到 Flashduty On-call。"
keywords: ["告警集成", "NetBeez", "网络监控", "Webhook", "alert_dedup_id", "incident_id"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "NetBeez", "网络监控", "Webhook", "alert_dedup_id
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "NetBeez", "网络监控", "Webhook", "alert_dedup_id
</div>
## 在 NetBeez 中配置
----
<Steps>
<Step title="启用 Webhook 集成">
@@ -60,7 +59,6 @@ keywords: ["告警集成", "NetBeez", "网络监控", "Webhook", "alert_dedup_id
</Steps>
## 推送内容
----
NetBeez 以 `application/json` POST 一个只有 `data` 字段的对象:单条通知时 `data` 是对象,聚合通知时是数组。Flashduty 直接解析,无需配置模板。
@@ -78,10 +76,9 @@ NetBeez 以 `application/json` POST 一个只有 `data` 字段的对象:单条
| `message` | 说明文字 | 告警标题和描述 |
| `url` | 故障在 NetBeez 界面中的链接 | 标签 `url` |
-告警标题为“对象名称: 说明文字”,对象名称依次取 `target`、`wifi_profile`、`agent`、`destination`。
+告警标题为“对象名称:说明文字”,对象名称依次取 `target`、`wifi_profile`、`agent`、`destination`。
## Alert Key
----
- 告警类通知使用 `alert_dedup_id`。NetBeez 文档说明同一个告警的打开和清除通知共享它,按它归并即可。
- 故障类通知使用“对象类型 + 对象 ID + `incident_ts`”。`incident_ts` 始终是故障开始时间,打开和清除通知一致。NetBeez 文档也建议按 `incident_id` 关联故障,但文档中的清除通知示例带了与打开通知不同的 `incident_id`,所以 Flashduty 不依赖它,`incident_id` 只作为标签保留。
@@ -90,7 +87,6 @@ NetBeez 以 `application/json` POST 一个只有 `data` 字段的对象:单条
告警类通知缺少 `alert_dedup_id`,或故障类通知缺少对象 ID 或 `incident_ts` 时,Flashduty 返回参数错误,因为无法可靠地把清除通知关联到原告警。
## 状态和告警等级
----
| NetBeez 通知 | Flashduty 状态或等级 |
| :--- | :--- |
@@ -103,7 +99,6 @@ NetBeez 以 `application/json` POST 一个只有 `data` 字段的对象:单条
NetBeez 文档只说明打开的告警 `severity` 不大于 5,等级名称形如 `alert`、`critical`,没有给出完整对照表,因此只把 1 和 2 映射为 Critical。需要调整时,可在协作空间的 **配置** 中用规则改写等级。
## 常见问题
----
<AccordionGroup>
<Accordion title="聚合通知里同时有打开和清除事件,会怎样?">
@@ -126,7 +121,6 @@ NetBeez 的测试发送示例数据。Flashduty 只把含 `event_type` 或 `even
</AccordionGroup>
## 排查问题
----
- **NetBeez 推送失败**:确认 Webhook URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求体包含 `data`,告警带 `alert_dedup_id`,故障带对象 ID 和 `incident_ts`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/netdata.mdx b/zh/on-call/integration/alert-integration/alert-sources/netdata.mdx
index 39b7adac..a12f2dca 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/netdata.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/netdata.mdx
@@ -1,5 +1,6 @@
---
title: "Netdata 告警集成"
+sidebarTitle: "Netdata"
description: "通过 Netdata Agent 的自定义通知(custom_sender)将 Netdata 告警的触发、升级和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Netdata", "Netdata Agent", "health_alarm_notify.conf", "custom_sender", "Webhook"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "Netdata", "Netdata Agent", "health_alarm_notify.conf
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -20,7 +20,7 @@ keywords: ["告警集成", "Netdata", "Netdata Agent", "health_alarm_notify.conf
当您不需要将告警路由到不同的协作空间时,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,打开一个协作空间
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**
@@ -35,7 +35,7 @@ keywords: ["告警集成", "Netdata", "Netdata Agent", "health_alarm_notify.conf
当您需要根据 Payload 将告警路由到不同的协作空间时,选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**
2. 选择 **Netdata**,填写集成名称
@@ -48,14 +48,12 @@ keywords: ["告警集成", "Netdata", "Netdata Agent", "health_alarm_notify.conf
</div>
## 前提条件
----
- **网络**:运行 Netdata Agent 的主机需要能访问 Flashduty 推送地址(如 `https://api.flashcat.cloud`)。
- **curl**:通知脚本使用 `curl` 发送请求。Netdata 的官方安装包和 Docker 镜像已自带 `curl`。
- **权限**:需要能编辑 Netdata 配置目录(通常是 `/etc/netdata`)中的文件。
## 在 Netdata 中配置
----
<Steps>
<Step title="打开通知配置文件">
@@ -148,7 +146,6 @@ docker exec -u netdata netdata /usr/libexec/netdata/plugins.d/alarm-notify.sh te
</Steps>
## Alert Key
----
Flashduty 使用 `host`、`chart` 和 `alarm` 三个字段共同生成 Alert Key。
@@ -161,7 +158,6 @@ Flashduty 使用 `host`、`chart` 和 `alarm` 三个字段共同生成 Alert Key
Netdata 通知中的 `alarm_id` 只在单个 Agent 内唯一(例如测试命令发送的 `alarm_id` 在所有 Agent 上都是 `1`),因此 Flashduty 不使用它。
## 状态和告警等级
----
Netdata 只对 WARNING、CRITICAL、CLEAR 三种状态发送通知。
@@ -176,7 +172,6 @@ Netdata 只对 WARNING、CRITICAL、CLEAR 三种状态发送通知。
Netdata 只在告警从 WARNING 或 CRITICAL 变为 CLEAR 时发送 CLEAR 通知。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -193,7 +188,6 @@ Netdata 只在告警从 WARNING 或 CRITICAL 变为 CLEAR 时发送 CLEAR 通知
告警标题为 `<host>: <summary>`;较早版本的 Netdata 没有 `summary` 时,使用告警名称。
## 常见问题
----
<AccordionGroup>
<Accordion title="支持 Netdata Cloud 的 Webhook 通知吗?">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/new-relic.mdx b/zh/on-call/integration/alert-integration/alert-sources/new-relic.mdx
index e421e295..24f10c7a 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/new-relic.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/new-relic.mdx
@@ -1,5 +1,6 @@
---
title: "New Relic 告警集成"
+sidebarTitle: "New Relic"
description: "通过 Workflow Webhook 将 New Relic Issue 同步到 Flashduty On-call,并关联激活、更新和关闭事件。"
keywords: ["告警集成", "New Relic", "Workflow", "Webhook", "Issue"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "New Relic", "Workflow", "Webhook", "Issue"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
### 使用专属集成
@@ -29,7 +29,6 @@ keywords: ["告警集成", "New Relic", "Workflow", "Webhook", "Issue"]
</div>
## 在 New Relic 中配置
----
<Steps>
<Step title="创建 Webhook Destination">
@@ -92,7 +91,6 @@ New Relic 的测试通知只能验证 Webhook 可达。Alert Key、更新和恢
</Steps>
## Alert Key 与 Issue 合并
----
Flashduty 直接使用 `issue_id`(New Relic 变量 `issueId`)作为 Alert Key。标题、优先级、Policy、Condition、实体和 `incident_ids` 的变化都不会改变 Alert Key。
@@ -101,7 +99,6 @@ Flashduty 直接使用 `issue_id`(New Relic 变量 `issueId`)作为 Alert Ke
当 `trigger_event=MERGE_REQUEST` 时,Flashduty 将请求视为合并后目标 Issue 的一次普通更新,并继续使用 Payload 中的 `issue_id`。当前版本不调用 Flashduty 内部的告警合并能力,也不会推断或关闭来源 Issue。
## 状态和告警等级
----
恢复只根据 `state` 判断,与 `trigger_event` 和等级映射相互独立。
@@ -117,7 +114,6 @@ Flashduty 直接使用 `issue_id`(New Relic 变量 `issueId`)作为 Alert Ke
New Relic 的 Warning 阈值会生成 `HIGH` 优先级 Alert Event,因此 `HIGH` 映射为 Flashduty Warning。如需其他映射,可通过[告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines)调整。
## 增加自定义标签
----
如果需要传递更多 Workflow 变量,在默认 Payload 顶层增加 `custom_labels`:
@@ -143,7 +139,6 @@ New Relic 的 Warning 阈值会生成 `HIGH` 优先级 Alert Event,因此 `HIG
- 不要传递 API Key、Token、密码、Cookie 或其他敏感信息
## 排查问题
----
- **只收到测试通知,真实告警没有通知**:确认 Workflow 已启用,并且过滤条件能够命中真实 Issue
- **Flashduty 返回参数错误**:确认 Payload 是有效 JSON,且包含非空的 `issue_id` 和支持的 `state`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/nobl9.mdx b/zh/on-call/integration/alert-integration/alert-sources/nobl9.mdx
index 3114ed0a..3b417adc 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/nobl9.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/nobl9.mdx
@@ -1,5 +1,6 @@
---
title: "Nobl9 告警集成"
+sidebarTitle: "Nobl9"
description: "通过 Nobl9 Webhook 告警方法,将 SLO 告警策略触发的告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Nobl9", "SLO", "Alert Method", "Webhook", "alert_id"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Nobl9", "SLO", "Alert Method", "Webhook", "alert_id"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Nobl9", "SLO", "Alert Method", "Webhook", "alert_id"
</div>
## 在 Nobl9 中配置
----
<Steps>
<Step title="创建 Webhook 告警方法">
@@ -77,7 +76,6 @@ keywords: ["告警集成", "Nobl9", "SLO", "Alert Method", "Webhook", "alert_id"
</Warning>
## 推送内容
----
| 字段 | 含义 | 在 Flashduty 中 |
| :--- | :--- | :--- |
@@ -89,12 +87,10 @@ keywords: ["告警集成", "Nobl9", "SLO", "Alert Method", "Webhook", "alert_id"
| `alert_policy_conditions_text`、`slo_details_link` | 触发条件、SLO 详情链接 | 描述 |
## Alert Key
----
Flashduty 使用 `alert_id`(Nobl9 文档:Unique identifier of the alert)作为 Alert Key。同一个 Nobl9 告警重复推送时合并到同一条 Flashduty 告警。
## 告警等级
----
| Nobl9 `severity` | Flashduty 等级 |
| :--- | :--- |
@@ -104,7 +100,6 @@ Flashduty 使用 `alert_id`(Nobl9 文档:Unique identifier of the alert)
| 其他或为空 | Warning |
## 常见问题
----
<AccordionGroup>
<Accordion title="告警会自动恢复吗?">
@@ -115,7 +110,6 @@ Flashduty 使用 `alert_id`(Nobl9 文档:Unique identifier of the alert)
</AccordionGroup>
## 排查问题
----
- **Nobl9 测试失败**:测试请求不含 `alert_id` 时会被拒绝,属预期;其余情况确认 URL 是以 `https://` 开头的完整推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认模板包含 `"alert_id": "$alert_id"`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/nodeping.mdx b/zh/on-call/integration/alert-integration/alert-sources/nodeping.mdx
index f5b083f1..b15ffe12 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/nodeping.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/nodeping.mdx
@@ -1,5 +1,6 @@
---
title: "NodePing 告警集成"
+sidebarTitle: "NodePing"
description: "通过 Webhook 联系方式将 NodePing 检查的宕机和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "NodePing", "Uptime", "Webhook", "Contact", "uuid"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "NodePing", "Uptime", "Webhook", "Contact", "uuid"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "NodePing", "Uptime", "Webhook", "Contact", "uuid"]
</div>
## 在 NodePing 中配置
----
<Steps>
<Step title="添加 Webhook 联系方式">
@@ -65,7 +64,6 @@ NodePing 的 Webhook 通知仅在 Professional 和 Premiere 套餐中提供(
</Warning>
## 推送内容
----
NodePing 以 GET 请求把以下字段追加到推送地址的查询字符串中,Flashduty 直接解析,无需配置模板:
@@ -86,14 +84,12 @@ NodePing 以 GET 请求把以下字段追加到推送地址的查询字符串中
告警标题使用检查名称;检查名称为空时依次使用检查目标、`NodePing check <uuid>`。
## Alert Key
----
Flashduty 使用检查的 `uuid` 作为 Alert Key。同一个检查的宕机和恢复通知携带相同的 `uuid`,因此会落在同一条告警上;不同检查即使名称和目标相同,也会生成不同的告警。修改检查名称、目标或结果码不会改变 Alert Key。
`_id` 是单次检查结果的 ID,每次通知都会变化,所以不用于关联告警。请求中缺少 `uuid` 时,Flashduty 会返回参数错误,因为无法可靠地把恢复通知关联到原告警。
## 状态和告警等级
----
NodePing 的通知不区分告警等级,Flashduty 统一按 Critical 处理。
@@ -106,7 +102,6 @@ NodePing 的通知不区分告警等级,Flashduty 统一按 Critical 处理。
`first` 表示监控已开始、这个 Webhook 已登记为通知目标,与故障无关,所以 Flashduty 只返回成功。`event` 为空或为其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么选择 GET,而不是像其他集成一样用 POST 和 JSON 模板?">
@@ -129,7 +124,6 @@ NodePing 按联系方式上的延迟(Delay)和时间窗(Schedule)决定
</AccordionGroup>
## 排查问题
----
- **NodePing 推送失败**:确认 URL 是完整的推送地址,且包含 `integration_key`;请求方法为 GET
- **Flashduty 返回参数错误**:确认没有自定义 Query Strings 或 Body,请求中的 `uuid`、`event` 非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/ns1.mdx b/zh/on-call/integration/alert-integration/alert-sources/ns1.mdx
index 9956058e..7c7edafa 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/ns1.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/ns1.mdx
@@ -1,5 +1,6 @@
---
title: "NS1 Connect 告警集成"
+sidebarTitle: "NS1 Connect"
description: "通过 Webhook 通知器将 IBM NS1 Connect 监控任务的宕机和恢复事件同步到 Flashduty On-call。"
keywords: ["告警集成", "NS1", "IBM NS1 Connect", "Webhook", "Notifier", "监控任务"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "NS1", "IBM NS1 Connect", "Webhook", "Notifier", "监
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "NS1", "IBM NS1 Connect", "Webhook", "Notifier", "监
</div>
## 在 NS1 Connect 中配置
----
<Steps>
<Step title="创建 Webhook 通知器">
@@ -63,7 +62,6 @@ keywords: ["告警集成", "NS1", "IBM NS1 Connect", "Webhook", "Notifier", "监
</Steps>
## Alert Key
----
Flashduty 使用监控任务 ID `job_document.id` 作为 Alert Key。NS1 官方示例的 `down` 请求体包含完整的 `job_document`,其中 `id` 是任务 ID;同一任务的宕机、重复通知和恢复共用这个 ID。
@@ -76,7 +74,6 @@ NS1 官方文档只完整展示了 `down` 请求体,`up` 示例在 `since` 之
</Note>
## 状态和告警等级
----
NS1 不发送告警等级。
@@ -89,12 +86,10 @@ NS1 不发送告警等级。
`state` 不区分大小写。
## 标签
----
Flashduty 会保留 `check`(任务名称)、`resource`(`config` 中的 `host`、`url` 或 `domain`)、`job_id`、`job_type`、`region`、`state` 和 `notify_list` 标签,便于在告警页排查与路由。
## 排查问题
----
- **告警没有恢复**:确认监控任务开启了 **Notify failback**;如果无法开启,请在协作空间开启[超时自动关闭](/zh/on-call/channel/create-edit),建议超时时长 1 小时,计时起点选择 **故障触发**
- **NS1 报告 Webhook 失败**:确认推送地址完整并包含 `integration_key`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/ntopng.mdx b/zh/on-call/integration/alert-integration/alert-sources/ntopng.mdx
index 3dfd9f56..bd158073 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/ntopng.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/ntopng.mdx
@@ -1,5 +1,6 @@
---
title: "ntopng 告警集成"
+sidebarTitle: "ntopng"
description: "通过 ntopng 的 Webhook Endpoint 将主机、接口和流量告警的触发与释放事件同步到 Flashduty On-call。"
keywords: ["告警集成", "ntopng", "Webhook", "Endpoint", "Recipient", "流量监控"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "ntopng", "Webhook", "Endpoint", "Recipient", "流量
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "ntopng", "Webhook", "Endpoint", "Recipient", "流量
</div>
## 在 ntopng 中配置
----
<Steps>
<Step title="创建 Webhook Endpoint">
@@ -61,7 +60,6 @@ keywords: ["告警集成", "ntopng", "Webhook", "Endpoint", "Recipient", "流量
</Steps>
## Alert Key
----
ntopng 在 `engage` 和 `release` 消息里携带相同的接口 ID(`ifid`)、实体类型(`entity_id`)、实体值(`entity_val`)、告警类型(`alert_id`)和子类型(`subtype`),Flashduty 用这五项生成 Alert Key。ntopng 自身也用实体值、告警类型和子类型来区分已触发的告警。分值(`score`)、时间戳、主机名和检查周期会随消息变化,不参与 Alert Key。
@@ -70,7 +68,6 @@ ntopng 在 `engage` 和 `release` 消息里携带相同的接口 ID(`ifid`)
`engage`、`release` 消息缺少 `alert_id`、`entity_id` 或 `entity_val` 时,Flashduty 会返回参数错误并指出字段名。
## 告警等级
----
ntopng 的告警等级由 `score` 决定,Flashduty 按下表映射。`score` 缺失或不是数字时按 Info 处理。
@@ -81,7 +78,6 @@ ntopng 的告警等级由 `score` 决定,Flashduty 按下表映射。`score`
| 50 以下 | None、Info、Notice | Info |
## 恢复与测试
----
- **`release`**:按 Alert Key 关闭对应告警,并保留释放前的告警等级。
- **`store`(流量告警)和其他没有释放消息的告警**:不会自动恢复。请在 Flashduty 集成或协作空间中开启 **超时自动关闭**,建议设置为 24 小时。
@@ -90,7 +86,6 @@ ntopng 的告警等级由 `score` 决定,Flashduty 按下表映射。`score`
一个请求最多包含 10 条告警(ntopng 的单次发送上限)。Flashduty 为每条告警创建一个事件,并保持请求中的顺序。
## 排查问题
----
- **ntopng 提示发送失败**:确认 Webhook URL 完整,包含 `integration_key`,并且 ntopng 所在服务器能访问 `api.flashcat.cloud`。ntopng 在失败时会重试 3 次
- **Flashduty 返回参数错误**:检查请求体是否为 JSON,且每条 `engage`、`release` 告警都有 `alert_id`、`entity_id`、`entity_val`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/nut.mdx b/zh/on-call/integration/alert-integration/alert-sources/nut.mdx
index da01d2f0..808483e8 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/nut.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/nut.mdx
@@ -1,5 +1,6 @@
---
title: "NUT (Network UPS Tools) 告警集成"
+sidebarTitle: "NUT (Network UPS Tools)"
description: "通过 upsmon 的 NOTIFYCMD 脚本把 UPS 断电、低电量、通信中断等事件推送到 Flashduty 的标准告警事件集成,恢复事件自动关闭告警。"
keywords: ["告警集成", "NUT", "Network UPS Tools", "upsmon", "UPS", "断电告警", "标准告警事件"]
---
@@ -9,7 +10,6 @@ NUT(Network UPS Tools)的 `upsmon` 在 UPS 状态变化时可以执行 `NOTI
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 标准告警事件**,不是 NUT。
@@ -30,7 +30,6 @@ NUT(Network UPS Tools)的 `upsmon` 在 UPS 状态变化时可以执行 `NOTI
</div>
## 在 NUT 中配置
----
### 步骤 1:创建通知脚本
@@ -120,7 +119,6 @@ NOTIFYTYPE=ONLINE UPSNAME=ups@localhost /usr/local/bin/nut-flashduty.sh "UPS ups
在 Flashduty 中应先看到告警 `UPS ups@localhost: on battery`,随后被恢复。
## 恢复与去重
----
- `ONBATT`、`LOWBATT`、`ONLINE` 共用 Alert Key `nut:<UPS 名称>:power`:`ONBATT` 触发告警,随后的 `LOWBATT` 把它升级为 Critical,`ONLINE` 恢复它
- `COMMBAD`、`NOCOMM` 与 `COMMOK` 共用 `comm`;`ALARM` 与 `NOTALARM`、`OVER` 与 `NOTOVER`、`BYPASS` 与 `NOTBYPASS` 也各自成对
@@ -128,7 +126,6 @@ NOTIFYTYPE=ONLINE UPSNAME=ups@localhost /usr/local/bin/nut-flashduty.sh "UPS ups
- 多台 UPS 的告警互不影响:Alert Key 中带有 `UPSNAME`
## 排查问题
----
- **没有收到告警**:确认 `upsmon.conf` 中对应事件类型的 `NOTIFYFLAG` 含有 `EXEC`,且已执行 `upsmon -c reload`
- **脚本手动运行成功,但 upsmon 触发时没有告警**:`NOTIFYCMD` 必须是脚本的完整路径,且 `upsmon` 的运行用户能执行它;失败原因由 `curl -fsS` 打印到 stderr,`upsmon` 不一定记录,排查时手动运行脚本查看
diff --git a/zh/on-call/integration/alert-integration/alert-sources/obkio.mdx b/zh/on-call/integration/alert-integration/alert-sources/obkio.mdx
index 03fbea99..9b32f0c1 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/obkio.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/obkio.mdx
@@ -1,5 +1,6 @@
---
title: "Obkio 告警集成"
+sidebarTitle: "Obkio"
description: "通过 Obkio 的 Webhook 通知,将网络监控产生的告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Obkio", "网络监控", "Webhook", "延迟", "丢包"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Obkio", "网络监控", "Webhook", "延迟", "丢包
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Obkio", "网络监控", "Webhook", "延迟", "丢包
</div>
## 在 Obkio 中配置
----
Webhook 在组织级别配置,需要有修改组织高级参数的权限。
@@ -63,14 +62,12 @@ Obkio 文档没有描述测试推送。Flashduty 只处理 `type` 为 `alert_not
</Steps>
## Alert Key
----
Flashduty 使用 Webhook 中的 `data.alert_id` 作为 Alert Key。Obkio 的推送示例把 `alert_id`(告警)与 `notification_id`(本次通知)分开列出,通知 ID 每次不同,因此不参与 Alert Key。Obkio 文档没有说明 `alert_id` 在同一告警多次通知间是否保持不变;若发生变化,每次通知会各自成为一条告警,由超时自动关闭收敛。
事件类型、等级、描述的变化都不会改变 Alert Key。缺少 `data.alert_id` 的推送会被拒绝。
## 状态和告警等级
----
Flashduty 按 `data.severity`(Obkio 的等级,见[通知说明](https://obkio.com/docs/notifications/))设置告警等级:
@@ -86,7 +83,6 @@ Flashduty 按 `data.severity`(Obkio 的等级,见[通知说明](https://obki
Obkio 文档没有说明是否会推送 `ok` 等级;如果推送,对应 `alert_id` 的告警恢复。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -101,7 +97,6 @@ Obkio 文档没有说明是否会推送 `ok` 等级;如果推送,对应 `ale
标题取自 `event_description`(如 `High latency: 118.32 ms`)。
## 排查问题
----
- **Flashduty 返回参数错误**:错误信息会指出缺少的字段(`data.alert_id`)。确认 Webhook Type 选择的是 `Obkio`
- **Obkio 重试推送**:确认 URL 完整且包含 `integration_key`,返回 2xx 后 Obkio 才停止重试
diff --git a/zh/on-call/integration/alert-integration/alert-sources/observium.mdx b/zh/on-call/integration/alert-integration/alert-sources/observium.mdx
index d72d9653..5222b43e 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/observium.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/observium.mdx
@@ -1,5 +1,6 @@
---
title: "Observium 告警集成"
+sidebarTitle: "Observium"
description: "通过 Observium 的 Webhook JSON 通知通道将告警检查器和 Syslog 告警同步到 Flashduty On-call,检查器恢复时自动关闭告警。"
keywords: ["告警集成", "Observium", "Webhook JSON", "网络监控", "SNMP"]
---
@@ -9,7 +10,6 @@ Observium 通过 **Webhook JSON** 类型的联系人(Contact)推送告警:
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Observium 通过 **Webhook JSON** 类型的联系人(Contact)推送告警:
</div>
## 在 Observium 中配置
----
Observium 社区版(Community Edition)即自带 **Webhook JSON** 通道,无需订阅版。以下界面名称以 Observium CE 26.1 为准。
@@ -125,7 +124,6 @@ Observium 社区版的网页界面没有联系人测试按钮,请在 Observium
</Steps>
## Alert Key
----
Flashduty 使用 `ALERT_ID` 作为检查器告警的 Alert Key。`ALERT_ID` 是 Observium `alert_table` 表中的行 ID,每个「告警检查器 + 监控对象」只有一行,告警、重复提醒和恢复通知都携带同一个值。因此同一对象上同一检查器的通知落在同一条告警上,恢复后再次失败会打开一条新告警。
@@ -136,7 +134,6 @@ Syslog 告警的 `ALERT_ID` 是 Syslog 规则的 ID,且 Syslog 告警没有恢
请求缺少 `ALERT_STATE` 或 `ALERT_ID`,或 `ALERT_STATE` 不是下表中的值时,Flashduty 会拒绝该请求。
## 告警生命周期
----
Flashduty 按 `ALERT_STATE` 字段处理通知:
@@ -150,7 +147,6 @@ Flashduty 按 `ALERT_STATE` 字段处理通知:
`ALERT_STATE` 是 Observium 的固定状态名,不受 `$config['alerts']['status_name']` 自定义影响;自定义名称体现在 `ALERT_STATE_NAME` 中,Flashduty 不读取它。
## 告警等级
----
告警等级取自 `ALERT_SEVERITY`:
@@ -164,7 +160,6 @@ Flashduty 按 `ALERT_STATE` 字段处理通知:
检查器告警的等级是检查器的 **Severity**(`Critical` 或 `Warning`);Syslog 告警的等级是该条日志的 Syslog 优先级。恢复通知携带同一个检查器的等级,恢复事件保留该等级。
## 告警内容
----
- **标题**:`<检查器消息> on <对象名称>`;对象不是设备本身(例如端口、传感器)时,末尾追加 `(<主机名>)`。检查器消息为空时用 `Observium alert <ALERT_ID>` 代替
- **描述**:`CONDITIONS`(未满足的条件)、`METRICS`(当前指标值)和 `DURATION`(持续时间),各占一行
@@ -173,7 +168,6 @@ Flashduty 按 `ALERT_STATE` 字段处理通知:
值为空的字段,以及模板中未被替换的 `%TAG%` 占位符(例如 Syslog 通知中的 `ENTITY_*`),不会写入标签。
## 排查问题
----
- **Observium 把通知记为发送失败、Flashduty 收到重复事件**:联系人的 **Transport** 选成了 **Webhook**,请改为 **Webhook JSON**
- **Flashduty 返回 400,提示 `ALERT_STATE is required` 或 `ALERT_ID is required`**:联系人的 JSON 模板缺少对应字段,恢复为默认模板
diff --git a/zh/on-call/integration/alert-integration/alert-sources/oceanbase.mdx b/zh/on-call/integration/alert-integration/alert-sources/oceanbase.mdx
index 83f54602..0073b046 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/oceanbase.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/oceanbase.mdx
@@ -1,5 +1,6 @@
---
title: "OceanBase 告警事件"
+sidebarTitle: "OceanBase"
description: "通过 webhook 的方式同步 OceanBase 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "OceanBase 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "OceanBase 告警事件", "监控告警", "数据接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "OceanBase 告警事件", "监控告警", "数据接
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "OceanBase 告警事件", "监控告警", "数据接
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **OceanBase** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,11 +46,9 @@ keywords: ["告警集成", "OceanBase 告警事件", "监控告警", "数据接
## 在 OceanBase
----
<div className="md-block">
-## 一、OceanBase告警推送配置
### 步骤1:配置告警通道
1. 登录您的OceanBase控制台,选择告警中心。
@@ -58,7 +56,7 @@ keywords: ["告警集成", "OceanBase 告警事件", "监控告警", "数据接
3. 通道类型选择 **自定义脚本** 。
4. 基本配置内容,如下图所示:
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/oceanbase-1.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/oceanbase-1.png" />
5. 配置通道中复制以下脚本内容,同时**请将脚本中的 integration_key 参数补充上 Flashduty 推送地址中的 integration_key 值**。
@@ -167,11 +165,11 @@ OCP告警通知-单条告警
### 步骤2:配置告警推送
-1. 新建推送配置,路径:**告警中心=>告警推送=>新建推送配置**。
+1. 新建推送配置,路径:**告警中心 → 告警推送 → 新建推送配置**。
2. 推送类型、指定对象按需配置即可。
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/oceanbase-2.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/oceanbase-2.png" />
3. 推送语言选择 **简体中文**。
4. 告警通道选择 **Flashduty** 。
@@ -183,7 +181,7 @@ OCP告警通知-单条告警
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
@@ -197,17 +195,3 @@ OCP告警通知-单条告警
</div>
-
-## 状态对照
----
-<div className="md-block">
-
-|OceanBase| Flashduty|状态|
-|---|---|---|
-|停服|Critical|严重|
-|严重|Warning|严重|
-|警告|Warning|警告|
-|注意|Info|提醒|
-|提醒|Info|提醒|
-
-</div>
diff --git a/zh/on-call/integration/alert-integration/alert-sources/oci-monitoring.mdx b/zh/on-call/integration/alert-integration/alert-sources/oci-monitoring.mdx
index e845c0f8..8fb52cea 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/oci-monitoring.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/oci-monitoring.mdx
@@ -1,5 +1,6 @@
---
title: "OCI Monitoring 告警集成"
+sidebarTitle: "OCI Monitoring"
description: "通过 OCI Notifications 的 HTTPS 订阅,将 Oracle Cloud Infrastructure Monitoring 告警的触发和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Oracle Cloud", "OCI", "Monitoring", "Alarm", "Notifications", "dedupeKey"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Oracle Cloud", "OCI", "Monitoring", "Alarm", "Notifi
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -34,7 +34,6 @@ OCI 的 HTTPS 订阅地址不允许带查询参数,所以本集成的推送地
</Note>
## 在 OCI 中配置
----
<Steps>
<Step title="创建主题">
@@ -75,14 +74,12 @@ OCI 的 HTTPS 订阅地址不允许带查询参数,所以本集成的推送地
</Steps>
## Alert Key
----
Flashduty 直接使用告警消息中的 `dedupeKey` 作为 Alert Key。OCI 官方将 `dedupeKey` 定义为告警(汇总消息)或告警中某条指标流(拆分消息)的唯一标识,并说明同一告警的消息用它归组。同一告警的 `OK_TO_FIRING`、`REPEAT`、`FIRING_TO_OK` 和 `RESET` 消息携带相同的 `dedupeKey`,所以会更新同一条 Flashduty 告警。
标题、正文、等级、时间和指标值的变化都不会改变 Alert Key。缺少 `dedupeKey` 的告警消息会被拒绝。
## 状态和告警等级
----
| OCI `type` | Flashduty 状态 |
| :--- | :--- |
@@ -101,7 +98,6 @@ Flashduty 直接使用告警消息中的 `dedupeKey` 作为 Alert Key。OCI 官
恢复时保留告警原有等级。空值或未知的 `severity` 按 Warning 处理;未知的 `type` 会被拒绝。
## 告警标签
----
Flashduty 会把以下字段写入告警标签,便于路由和排查:
@@ -112,7 +108,6 @@ Flashduty 会把以下字段写入告警标签,便于路由和排查:
告警正文 `body` 和告警摘要 `alarmSummary` 写入告警描述。
## 排查问题
----
- **订阅一直是 Pending**:确认 URL 是完整推送地址,集成 key 在路径里且没有查询参数;然后删除这个订阅,用正确的地址重新创建。确认链接 3 天内有效,过期后同样需要重新创建订阅
- **Flashduty 返回 ConfirmationURL 错误**:Flashduty 只访问 Oracle Cloud 域名(如 `oraclecloud.com`)上的 https 确认链接,请确认请求来自 OCI Notifications
diff --git a/zh/on-call/integration/alert-integration/alert-sources/odown.mdx b/zh/on-call/integration/alert-integration/alert-sources/odown.mdx
index e2060836..bdd9b92d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/odown.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/odown.mdx
@@ -1,5 +1,6 @@
---
title: "Odown 告警集成"
+sidebarTitle: "Odown"
description: "通过 Webhook 通道将 Odown 监控的宕机、恢复和 SSL 证书到期通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Odown", "Uptime", "Webhook", "SSL", "ALERT_FAILURE", "ALERT_RECOVERY"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Odown", "Uptime", "Webhook", "SSL", "ALERT_FAILURE",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Odown", "Uptime", "Webhook", "SSL", "ALERT_FAILURE",
</div>
## 在 Odown 中配置
----
<Steps>
<Step title="添加 Webhook 通道">
@@ -57,7 +56,6 @@ Webhook 通道是全局的:保存后账号下所有监控都会订阅它(通
</Steps>
## 推送内容
----
Odown 以 JSON 格式 POST 事件,Flashduty 直接解析,无需配置模板:
@@ -78,7 +76,6 @@ Odown 以 JSON 格式 POST 事件,Flashduty 直接解析,无需配置模板
告警标题使用监控名称;监控名称为空时使用被监控地址。SSL 到期告警的标题以 `SSL certificate expiring:` 开头。
## Alert Key
----
- 宕机和恢复:使用 `check.id` 作为 Alert Key。同一个监控的 `ALERT_FAILURE` 和 `ALERT_RECOVERY` 携带相同的 `check.id`,落在同一条告警上;不同监控会生成不同的告警。修改监控名称、状态码或检查区域不会改变 Alert Key。
- SSL 到期:使用 `check.id` 加 `:ssl_expiry` 作为 Alert Key,与该监控的宕机告警分开,因此监控恢复不会关闭证书告警,同一监控重复的到期通知会合并到同一条告警。
@@ -86,7 +83,6 @@ Odown 以 JSON 格式 POST 事件,Flashduty 直接解析,无需配置模板
请求中缺少 `check.id` 时,Flashduty 会返回参数错误,因为无法可靠地把恢复通知关联到原告警。
## 状态和告警等级
----
Odown 的通知不区分告警等级。
@@ -99,12 +95,10 @@ Odown 的通知不区分告警等级。
`event` 为空或为其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 一次性告警需要开启超时自动关闭
----
SSL 到期通知没有对应的关闭通知,这类告警在 Flashduty 中不会自动恢复。请开启协作空间的[超时自动关闭](/zh/on-call/channel/create-edit),建议设置为 7 天;也可以在续期证书后手动关闭。
## 常见问题
----
<AccordionGroup>
<Accordion title="Webhook 测试按钮会创建告警吗?">
@@ -121,7 +115,6 @@ SSL 到期通知没有对应的关闭通知,这类告警在 Flashduty 中不
</AccordionGroup>
## 排查问题
----
- **Odown 推送失败**:确认 Webhook URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求为 Odown 的 JSON 通知,且 `check.id`、`event` 非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/ofelia.mdx b/zh/on-call/integration/alert-integration/alert-sources/ofelia.mdx
index 3edd6947..a0ed8d24 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/ofelia.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/ofelia.mdx
@@ -1,5 +1,6 @@
---
title: "Ofelia 告警集成"
+sidebarTitle: "Ofelia"
description: "通过 Ofelia 的 Webhook 将定时任务的失败和恢复事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Ofelia", "定时任务", "Docker", "Webhook", "cron"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "Ofelia", "定时任务", "Docker", "Webhook", "cron"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ keywords: ["告警集成", "Ofelia", "定时任务", "Docker", "Webhook", "cron"
</div>
## 在 Ofelia 中配置
----
Ofelia 通过 Docker API 工作,即使只运行 `job-local` 任务也是如此,所以运行 Ofelia 的容器必须挂载 `/var/run/docker.sock`;缺少它时,Ofelia 启动即退出。使用 `docker run` 时加 `-v /var/run/docker.sock:/var/run/docker.sock:ro`。
@@ -101,7 +100,6 @@ Flashduty 用主机名区分不同机器上的同名任务。Ofelia 运行在容
</Steps>
## Alert Key
----
Flashduty 用 `host.hostname` 与 `job.name` 组合出 Alert Key,两者之间用不可见分隔符连接后取 MD5。在我们的真实验证中,同一任务的失败与成功执行携带相同的主机名和任务名;而 `execution.id` 每次执行都不同,因此只作为排查参考,不参与 Alert Key。
@@ -111,7 +109,6 @@ Flashduty 用 `host.hostname` 与 `job.name` 组合出 Alert Key,两者之间
- `job.name` 缺失时 Flashduty 返回 400,避免把失败和恢复写进错误的告警
## 状态和告警等级
----
| Ofelia `execution.status` | Flashduty 处理 |
| :--- | :--- |
@@ -124,7 +121,6 @@ Flashduty 用 `host.hostname` 与 `job.name` 组合出 Alert Key,两者之间
任务失败后重复失败,会更新同一条告警,不会新建。若同一任务长期不再执行(任务被删除或停用),告警不会自动恢复,需要手动关闭,或开启协作空间的[超时自动关闭](/zh/on-call/channel/create-edit)。
## 告警内容
----
- **标题**:`Ofelia job "<任务名>" failed`,恢复时为 `Ofelia job "<任务名>" succeeded`
- **描述**:`execution.error`,换行后追加 `execution.stderr`
@@ -133,7 +129,6 @@ Flashduty 用 `host.hostname` 与 `job.name` 组合出 Alert Key,两者之间
任务命令和标准输出不会进入标签或描述,因为命令里可能带有凭据。
## 排查问题
----
- **Flashduty 没有收到任何请求**:确认任务上写了 `webhooks = flashduty`,查看 Ofelia 日志里的 `Webhook error`;Ofelia 对失败的 Webhook 默认重试 3 次,间隔 5 秒
- **只收到失败,没有恢复**:确认 Webhook 设置了 `trigger = always`,并确认主机名在两次执行之间没有变化
diff --git a/zh/on-call/integration/alert-integration/alert-sources/ohdear.mdx b/zh/on-call/integration/alert-integration/alert-sources/ohdear.mdx
index 93c059c8..9a3b53f8 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/ohdear.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/ohdear.mdx
@@ -1,5 +1,6 @@
---
title: "Oh Dear 告警集成"
+sidebarTitle: "Oh Dear"
description: "通过团队 Webhook 将 Oh Dear 的可用性、性能、证书、DNS、定时任务等监控事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Oh Dear", "Webhook", "可用性监控", "证书监控", "定时任务监控"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Oh Dear", "Webhook", "可用性监控", "证书监
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Oh Dear", "Webhook", "可用性监控", "证书监
</div>
## 在 Oh Dear 中配置
----
Oh Dear 的 Webhook 按团队配置,团队内所有监控的事件都会推送到同一个地址。
@@ -56,7 +55,6 @@ Oh Dear 只把 HTTP 200 视为投递成功,其他状态码(包括 301、302
</Steps>
## 事件和告警的对应关系
----
Oh Dear 会推送所有事件,无法在 Oh Dear 侧筛选事件类型。Flashduty 的处理方式如下:
@@ -84,7 +82,6 @@ Oh Dear 会推送所有事件,无法在 Oh Dear 侧筛选事件类型。Flashd
</Warning>
## Alert Key
----
- 有恢复事件的检查项:Alert Key 由 `run.check_id`(Oh Dear 中该监控下某一类检查的 ID)计算,同一检查项的触发和恢复事件使用同一个 Alert Key,不同监控或同一监控的不同检查项互不合并
- 没有恢复事件的事件:Alert Key 由事件的 `uuid` 计算。Oh Dear 重试同一事件时 `uuid` 不变,因此重试不会产生重复告警,新事件则各自创建告警
@@ -92,7 +89,6 @@ Oh Dear 会推送所有事件,无法在 Oh Dear 侧筛选事件类型。Flashd
监控名称、地址、时间、运行 ID 等字段变化不会改变 Alert Key。缺少 `run.check_id`(有恢复事件的检查项)或 `uuid`(无恢复事件的事件)的推送会被拒绝。
## 状态和告警等级
----
Oh Dear 事件不携带等级,Flashduty 按事件确定:
@@ -105,7 +101,6 @@ Oh Dear 事件不携带等级,Flashduty 按事件确定:
可用性的 `...UptimeCheckRecovered` 事件在 `run.result` 为 `warning` 时表示部分连通(主检查节点失败、备用节点成功,网站仍视为在线),Flashduty 同样按恢复处理。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -118,7 +113,6 @@ Oh Dear 事件不携带等级,Flashduty 按事件确定:
| `url` | Oh Dear 中对应报告的链接 |
## 排查问题
----
- **收不到告警**:确认地址中的 `integration_key` 正确,并在 Oh Dear 的 Webhook 日志中查看该请求的响应状态
- **告警没有恢复**:确认 Oh Dear 已发出对应的恢复事件;证书即将过期、DNS 记录变更、定时任务等事件没有恢复事件,需要手动关闭
diff --git a/zh/on-call/integration/alert-integration/alert-sources/okta.mdx b/zh/on-call/integration/alert-integration/alert-sources/okta.mdx
index 80d88263..471ee185 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/okta.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/okta.mdx
@@ -1,5 +1,6 @@
---
title: "Okta 告警集成"
+sidebarTitle: "Okta"
description: "通过 Okta Event Hooks 将账户锁定、泄露凭据和用户上报的可疑活动同步到 Flashduty On-call。"
keywords: ["告警集成", "Okta", "Event Hooks", "账户锁定", "身份安全"]
---
@@ -14,7 +15,6 @@ keywords: ["告警集成", "Okta", "Event Hooks", "账户锁定", "身份安全"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -35,7 +35,6 @@ keywords: ["告警集成", "Okta", "Event Hooks", "账户锁定", "身份安全"
</div>
## 在 Okta 中配置
----
<Steps>
<Step title="创建 Event Hook">
@@ -87,14 +86,12 @@ Preview 发送的是组织 System Log 中的真实事件,Flashduty 无法把
</Steps>
## 配置超时自动关闭
----
泄露凭据和可疑活动告警没有恢复通知,不会自动关闭。请在接收这些告警的协作空间中开启[超时自动关闭](/zh/on-call/channel/create-edit),**超时计时起点**选择**故障触发**,**超时时长**建议设为 24 小时:处理人有一个工作日确认和重置凭据,未处理的故障也不会一直处于打开状态。
账户锁定告警由解锁事件关闭,不依赖这项设置。
## 推送内容
----
每次推送的 `data.events` 数组中可能包含多个事件,Flashduty 按事件的 `published` 时间顺序逐条处理。每个事件是一条 Okta System Log 记录,Flashduty 使用以下字段:
@@ -112,7 +109,6 @@ Preview 发送的是组织 System Log 中的真实事件,Flashduty 无法把
告警标题的格式为 `<事件名称>: <用户显示名>`,例如 `Okta account locked: Jane Doe`。每条告警还带有标签 `source=okta`。
## Alert Key
----
Flashduty 使用事件类别和用户 ID 生成 Alert Key:
@@ -122,7 +118,6 @@ Flashduty 使用事件类别和用户 ID 生成 Alert Key:
- 同一用户在告警未关闭时再次发生泄露凭据或可疑活动事件,合并到同一条告警中
## 状态和告警等级
----
Okta 事件自带的 `severity` 不反映处理的紧急程度(例如账户锁定记录为 `DEBUG`),Flashduty 按事件类型映射等级:
@@ -135,7 +130,6 @@ Okta 事件自带的 `severity` 不反映处理的紧急程度(例如账户锁
| 其他事件类型 | 忽略,不生成告警 |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么不支持 security.threat.detected(ThreatInsight)?">
@@ -158,7 +152,6 @@ Okta 的超时时间为 3 秒,返回 5xx 或超时时最多重试一次;返
</AccordionGroup>
## 排查问题
----
- **Verify 失败**:确认 URL 是完整的推送地址(包含 `integration_key`)
- **Flashduty 返回参数错误**:推送中需要生成告警的事件缺少用户信息(`target` 和 `actor` 中都没有类型为 `User` 的对象)。常见于在 Preview 中使用示例数据
diff --git a/zh/on-call/integration/alert-integration/alert-sources/open-falcon.mdx b/zh/on-call/integration/alert-integration/alert-sources/open-falcon.mdx
index 9c46ec84..14b97978 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/open-falcon.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/open-falcon.mdx
@@ -1,5 +1,6 @@
---
-title: "Open Falcon集成"
+title: "Open Falcon 集成"
+sidebarTitle: "Open Falcon"
description: "通过 webhook 的方式同步 Open-Falcon 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "Open Falcon集成", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "Open Falcon集成", "监控告警", "数据接入"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "Open Falcon集成", "监控告警", "数据接入"]
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "Open Falcon集成", "监控告警", "数据接入"]
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Falcon** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,21 +45,20 @@ keywords: ["告警集成", "Open Falcon集成", "监控告警", "数据接入"]
</div>
-## 在 Falcon
----
+## 在 Falcon
选择告警规则,逐一配置 webhook。
<div className="md-block">
1. 登录您的 Falcon 控制台,选择 Templates,进入告警规则模板列表页面
2. 打开任意一个告警规则模板,填写回调地址为当前集成对应的推送地址
-3. 点击 Save 按钮,保存告警规则
+3. 点击 **Save** 按钮,保存告警规则
4. 针对所有要发送事件的告警规则模板,重复步骤2和3
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/open-falcon-tmpls.png" />
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/saas-open-falcon-rule.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/open-falcon-tmpls.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/saas-open-falcon-rule.png" />
-同样的,针对 Expressions 告警规则,也可以配置相同的推送地址。
+ 同样的,针对 Expressions 告警规则,也可以配置相同的推送地址。
5. 回到集成列表,如果展示了最新事件时间,说明配置成功且收到事件
6. 完成
@@ -67,7 +66,6 @@ keywords: ["告警集成", "Open Falcon集成", "监控告警", "数据接入"]
</div>
## 状态对照
----
<div className="md-block">
Open-Falcon 到 Flashduty 告警等级映射关系:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/opennms.mdx b/zh/on-call/integration/alert-integration/alert-sources/opennms.mdx
index 6a030c48..ecf0da8b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/opennms.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/opennms.mdx
@@ -1,5 +1,6 @@
---
title: "OpenNMS 告警集成"
+sidebarTitle: "OpenNMS"
description: "通过 OpenNMS Horizon 的 Webhook 通知命令将节点、接口和服务中断通知同步到 Flashduty On-call,中断恢复时自动关闭告警。"
keywords: ["告警集成", "OpenNMS", "OpenNMS Horizon", "Webhook", "通知命令", "notificationCommands.xml", "网络监控"]
---
@@ -9,7 +10,6 @@ OpenNMS Horizon 通过通知(notice)告知运维人员网络中发生的事
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ OpenNMS Horizon 通过通知(notice)告知运维人员网络中发生的事
</div>
## 在 OpenNMS 中配置
----
本集成使用 OpenNMS 的 Webhook 通知策略 `WebhookNotificationStrategy`,需要 **OpenNMS Horizon 36.0.3 及以上版本**。更早的版本没有该策略,请先升级。以下 `$OPENNMS_HOME` 指 OpenNMS 的安装目录,官方容器镜像中为 `/opt/opennms`。OpenNMS 服务器需要能访问 Flashduty 推送地址。
@@ -149,7 +148,6 @@ OpenNMS 没有单独测试通知命令的按钮。
</Steps>
## Alert Key
----
Flashduty 使用 OpenNMS 的通知编号 `notice_id`(`${noticeid}`)作为 Alert Key。同一条通知在升级(escalation)时重发,或被恢复事件自动确认后发送恢复通知时,通知编号都不变,因此落在同一条告警上。
@@ -160,7 +158,6 @@ Flashduty 使用 OpenNMS 的通知编号 `notice_id`(`${noticeid}`)作为 Al
请求缺少 `notice_id` 时,Flashduty 会拒绝该请求,OpenNMS 在 `notifd.log` 中记录推送失败。
## 告警生命周期
----
OpenNMS 在 `notifd-configuration.xml` 中为中断事件配置了自动确认(`auto-acknowledge`):恢复事件到达时,OpenNMS 确认对应的中断通知,并把原通知再次发送给原来的接收人,主题和正文前加上 `RESOLVED: `。Flashduty 按主题是否以 `RESOLVED:` 开头处理:
@@ -183,7 +180,6 @@ OpenNMS 在 `notifd-configuration.xml` 中为中断事件配置了自动确认
事件的告警(alarm)被对应的清除事件清除时,OpenNMS 会确认该通知并发送恢复通知。修改后按第一步的方法让 Notifd 重新加载配置。仍然没有恢复通知的,请在接收该集成告警的协作空间中开启[超时自动关闭](/zh/on-call/channel/create-edit),**超时计时起点**选择**故障触发**,**超时时长**建议设为 24 小时。
## 告警等级
----
告警等级来自请求中的 `severity`,即可选步骤中 `%severity%` 取到的 OpenNMS 事件等级:
@@ -201,14 +197,12 @@ OpenNMS 在 `notifd-configuration.xml` 中为中断事件配置了自动确认
恢复通知中的 `severity` 是 OpenNMS 保存的数字等级编号(例如 `5` 表示 `Minor`、`6` 表示 `Major`),Flashduty 会把编号 1–7 换算回等级名称,因此恢复事件的等级与告警触发时一致。
## 告警内容
----
- **标题**:通知主题 `subject`,去掉 `RESOLVED: ` 前缀;主题为空时为 `OpenNMS notice #<通知编号>`
- **描述**:通知正文 `message`,去掉 `RESOLVED: ` 前缀
- **标签**:`notice_id`、`event_id`、`event_uei`、`node_id`、`interface`、`service`、`severity`(等级名称,恢复通知中的数字编号会换算为名称)。值为空的标签不会添加
## 排查问题
----
以下日志位于 `$OPENNMS_HOME/logs/notifd.log`。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/openobserve.mdx b/zh/on-call/integration/alert-integration/alert-sources/openobserve.mdx
index b4ddadbd..134ee627 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/openobserve.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/openobserve.mdx
@@ -1,5 +1,6 @@
---
title: "OpenObserve 告警集成"
+sidebarTitle: "OpenObserve"
description: "通过 OpenObserve 告警目的地的 Webhook 模板,将 OpenObserve 告警同步到 Flashduty On-call。"
keywords: ["告警集成", "OpenObserve", "Webhook", "日志告警", "可观测性"]
---
@@ -9,7 +10,6 @@ OpenObserve 的 Webhook 目的地没有固定的请求体,请求体就是您
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ OpenObserve 的 Webhook 目的地没有固定的请求体,请求体就是您
</div>
## 在 OpenObserve 中配置
----
需要能管理告警模板和目的地的权限。
@@ -84,14 +83,12 @@ OpenObserve 的 Webhook 目的地没有固定的请求体,请求体就是您
</Steps>
## Alert Key
----
Flashduty 用 `org_name`、`stream_type`、`stream_name` 和 `alert_name` 共同计算 Alert Key,同一个 OpenObserve 告警的触发、持续触发和恢复使用同一个 Alert Key。告警等级、查询结果数、阈值、触发时间和 `episode_id` 的变化不会改变 Alert Key;`stream_type` 为空时按空值参与计算。缺少 `org_name`、`stream_name` 或 `alert_name` 的请求会被拒绝。
重命名 OpenObserve 告警、数据流或组织会产生新的 Alert Key。
## 状态和告警等级
----
| `alert_level` | Flashduty 等级 |
| :--- | :--- |
@@ -101,12 +98,10 @@ Flashduty 用 `org_name`、`stream_type`、`stream_name` 和 `alert_name` 共同
`alert_status` 为 `resolved` 时告警恢复,其余情况为触发。OpenObserve 1.1 之前不识别 `{alert_status}`、`{alert_level}` 和 `{episode_id}`,这些字段会以原样的模板文本到达,Flashduty 将其视为空值,告警按 Warning 触发。
## 恢复
----
只有 OpenObserve 1.1 及以上、并为告警开启恢复通知时,Flashduty 才会收到恢复请求并自动关闭告警。其余情况每次触发都是独立的一次性通知,没有恢复请求。请在 Flashduty 的集成或协作空间中为这类告警配置 **超时自动关闭**,并设置合适的时长,否则告警会一直保持活动。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -123,7 +118,6 @@ Flashduty 用 `org_name`、`stream_type`、`stream_name` 和 `alert_name` 共同
模板中没有 `{rows}`,Flashduty 不会收到查询返回的日志内容。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,模板中包含 `org_name`、`stream_name` 和 `alert_name`,并且模板是合法的 JSON
- **告警没有恢复**:确认 OpenObserve 版本不低于 1.1,且告警已开启恢复通知;否则请配置超时自动关闭
diff --git a/zh/on-call/integration/alert-integration/alert-sources/opensearch.mdx b/zh/on-call/integration/alert-integration/alert-sources/opensearch.mdx
index 13148050..edd9b894 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/opensearch.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/opensearch.mdx
@@ -1,5 +1,6 @@
---
title: "OpenSearch 告警集成"
+sidebarTitle: "OpenSearch"
description: "通过 Alerting 插件的自定义 Webhook 通知渠道,将 OpenSearch 监控的触发通知同步到 Flashduty On-call。"
keywords: ["告警集成", "OpenSearch", "Alerting", "Notifications", "Webhook", "日志监控"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "OpenSearch", "Alerting", "Notifications", "Webhook",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ keywords: ["告警集成", "OpenSearch", "Alerting", "Notifications", "Webhook",
</div>
## 在 OpenSearch 中配置
----
需要安装 Alerting 和 Notifications 插件(OpenSearch 默认自带),并有创建通知渠道和 Monitor 的权限。
@@ -57,19 +56,19 @@ keywords: ["告警集成", "OpenSearch", "Alerting", "Notifications", "Webhook",
3. 在触发器下点击 **Add action**,**Notification channel** 选择上一步创建的渠道
4. 将下面的模板完整粘贴到 **Message**,不要改动引号和字段名:
-```text
-{
- "monitor_id": "{{ctx.monitor._id}}",
- "monitor_name": "{{ctx.monitor.name}}",
- "trigger_id": "{{ctx.trigger.id}}",
- "trigger_name": "{{ctx.trigger.name}}",
- "severity": "{{ctx.trigger.severity}}",
- "period_start": "{{ctx.periodStart}}",
- "period_end": "{{ctx.periodEnd}}",
- "hit_count": "{{ctx.results.0.hits.total.value}}",
- "error": "{{ctx.error}}"
-}
-```
+ ```text
+ {
+ "monitor_id": "{{ctx.monitor._id}}",
+ "monitor_name": "{{ctx.monitor.name}}",
+ "trigger_id": "{{ctx.trigger.id}}",
+ "trigger_name": "{{ctx.trigger.name}}",
+ "severity": "{{ctx.trigger.severity}}",
+ "period_start": "{{ctx.periodStart}}",
+ "period_end": "{{ctx.periodEnd}}",
+ "hit_count": "{{ctx.results.0.hits.total.value}}",
+ "error": "{{ctx.error}}"
+ }
+ ```
5. 保存 Monitor
@@ -95,14 +94,12 @@ Per query 和 Per cluster metrics 的触发器只在条件成立时执行动作
</Steps>
## Alert Key
----
Flashduty 用 Monitor ID 和触发器 ID 计算 Alert Key,即模板中的 `monitor_id` 和 `trigger_id`。同一个 Monitor 的同一个触发器,每次通知使用同一个 Alert Key,因此合并为一条告警;不同的触发器、不同的 Monitor 各有各的告警。Monitor 名称、触发器名称、等级、命中数和时间段的变化不会改变 Alert Key。`monitor_id` 或 `trigger_id` 为空的通知会被拒绝并返回参数错误。
模板中没有使用 `ctx.alert.id`:触发器第一次执行动作时,OpenSearch 还没有创建告警,这个变量为空。
## 状态和告警等级
----
OpenSearch 触发器的 **Severity level** 取值 1(最高)到 5(最低),Flashduty 按下表映射:
@@ -116,7 +113,6 @@ OpenSearch 触发器的 **Severity level** 取值 1(最高)到 5(最低)
每条通知都是触发状态,Flashduty 不会因为 OpenSearch 的通知而自动恢复告警,恢复由超时自动关闭完成,也可以在 Flashduty 中手动关闭。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -129,7 +125,6 @@ OpenSearch 触发器的 **Severity level** 取值 1(最高)到 5(最低)
| `error` | 触发器无法取得结果或无法计算条件时的错误信息 |
## 排查问题
----
- **Flashduty 返回参数错误**:确认 Message 是完整的模板,`monitor_id` 和 `trigger_id` 都有值;确认 URL 完整且包含 `integration_key`
- **OpenSearch 中通知发送失败**:在 **Notifications → Channels** 中对该渠道点击 **Send test message** 查看错误,常见原因是集群无法访问 `api.flashcat.cloud` 或该域名在 `host_deny_list` 中
diff --git a/zh/on-call/integration/alert-integration/alert-sources/openstatus.mdx b/zh/on-call/integration/alert-integration/alert-sources/openstatus.mdx
index 3c6901d1..9e84ff33 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/openstatus.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/openstatus.mdx
@@ -1,5 +1,6 @@
---
title: "OpenStatus 告警集成"
+sidebarTitle: "OpenStatus"
description: "通过 Webhook 通知渠道将 OpenStatus 监控的故障、降级和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "OpenStatus", "Webhook", "拨测", "可用性监控"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "OpenStatus", "Webhook", "拨测", "可用性监控"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "OpenStatus", "Webhook", "拨测", "可用性监控"]
</div>
## 在 OpenStatus 中配置
----
<Steps>
<Step title="创建 Webhook 通知渠道">
@@ -65,7 +64,6 @@ OpenStatus 在至少一半探测区域报错时才发送 `error` 通知,恢复
</Tip>
## Alert Key
----
Flashduty 用 `monitor.id`(OpenStatus 监控 ID)计算 Alert Key。同一个监控的 `error`、`degraded` 和 `recovered` 通知携带相同的 `monitor.id`,因此会落在同一条告警上:监控从报错变为降级时,原告警更新为 Warning,监控恢复后告警关闭。
@@ -76,7 +74,6 @@ Flashduty 用 `monitor.id`(OpenStatus 监控 ID)计算 Alert Key。同一个
</Note>
## 状态和告警等级
----
| OpenStatus `status` | Flashduty 处理 | 告警等级 |
| :--- | :--- | :--- |
@@ -88,14 +85,12 @@ Flashduty 用 `monitor.id`(OpenStatus 监控 ID)计算 Alert Key。同一个
空值或其他 `status` 会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 告警内容
----
- **标题**:监控名称 `monitor.name`,为空时使用 `OpenStatus monitor <monitor.id>`
- **描述**:`errorMessage`
- **标签**:`check`(监控名称)、`resource`(监控地址 `monitor.url`)、`source`(固定为 `openstatus`)、`monitor_id`、`status`、`status_code`、`latency_ms`
## 排查问题
----
- **Send Test 失败**:确认 **Webhook URL** 是完整推送地址且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求中有 `monitor.id` 和 `status`;本集成只接收 OpenStatus Webhook 渠道的 JSON 格式
diff --git a/zh/on-call/integration/alert-integration/alert-sources/opmanager.mdx b/zh/on-call/integration/alert-integration/alert-sources/opmanager.mdx
index ac06113c..753d6cb2 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/opmanager.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/opmanager.mdx
@@ -1,5 +1,6 @@
---
title: "Opmanager 告警事件"
+sidebarTitle: "Opmanager"
description: "通过 webhook 的方式同步 Opmanager 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "Opmanager 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "Opmanager 告警事件", "监控告警", "数据接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "Opmanager 告警事件", "监控告警", "数据接
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "Opmanager 告警事件", "监控告警", "数据接
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **OpManager** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,15 +45,13 @@ keywords: ["告警集成", "Opmanager 告警事件", "监控告警", "数据接
</div>
## 在 OpManager
----
<div className="md-block">
-## 一、OpManager 告警推送配置
1. 登录您的 `OpManager` 控制台,在导航菜单中选择 `Settings => Notification Profiles`。
2. 在 `Notifications` 页面中,点击 `Add` 后选择 `Invoke a Webhook` 添加配置文件。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/opm-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/opm-1.png" />
3. 开始在 Webhook 编辑页面进行配置具体内容。
4. `Hook URL` 中的请求方法选择 `POST`,`URL` 填写**告警集成的推送地址**。
@@ -108,11 +106,11 @@ keywords: ["告警集成", "Opmanager 告警事件", "监控告警", "数据接
7. `Request Headers` 保持默认的即可。
8. `Time Out` 填写 1-300 之间的任意值,并点击下一步。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/opm-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/opm-2.png" />
9. 在 `Choose the criteria` 配置条件页面中勾选 `Notify when the alarm is cleared`,其他按需配置即可。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/opm-3.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/opm-3.png" />
10. 选择希望应用此配置文件的设备,使用右箭头将它们移动到选定设备窗口,然后点击下一步。
11. Time Window/Delayed Trigger/Recurring Trigger 可按需配置,然后点击下一步。
@@ -120,7 +118,7 @@ keywords: ["告警集成", "Opmanager 告警事件", "监控告警", "数据接
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/opnsense.mdx b/zh/on-call/integration/alert-integration/alert-sources/opnsense.mdx
index f4a2c7d0..4ee3a39f 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/opnsense.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/opnsense.mdx
@@ -1,5 +1,6 @@
---
title: "OPNsense 告警集成"
+sidebarTitle: "OPNsense"
description: "OPNsense 的 Monit 模块通过邮件发送服务告警,使用 Flashduty 的邮件集成按规则触发和关闭 OPNsense 告警。"
keywords: ["告警集成", "OPNsense", "Monit", "防火墙", "邮件", "Email"]
---
@@ -9,7 +10,6 @@ OPNsense 的服务监控由 **Monit** 模块(**Services → Monit**)完成
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成邮件地址,任选其一即可。**集成类型都选择邮件 Email**,不是 OPNsense。
@@ -30,20 +30,18 @@ OPNsense 的服务监控由 **Monit** 模块(**Services → Monit**)完成
</div>
## 在 OPNsense 中配置
----
1. **SMTP**:进入 **Services → Monit → Settings**,在 **General Settings** 中启用 Monit,填写 SMTP 服务器的地址、端口和凭据
2. **收件人**:在 **Alert Settings** 中新增一条告警,**Recipient** 填 Flashduty 邮件集成的地址
3. **邮件格式**:在这条告警的 **Mail format** 中填入下面一行。默认标题里没有主机名,且服务名与事件之间没有固定分隔,规则难以稳定提取 Alert Key,固定成这种格式后才可以按规则处理
-```
-Subject: [$HOST] [$SERVICE] $EVENT
-```
+ ```
+ Subject: [$HOST] [$SERVICE] $EVENT
+ ```
4. **恢复通知**:Monit 在服务恢复时会发送同一格式的恢复邮件。**Not on** 保持关闭,使所有事件(包括恢复)都发送邮件
## 在 Flashduty 中配置推送规则
----
标题 `[$HOST] [$SERVICE] $EVENT` 中,`$HOST` 和 `$SERVICE` 在故障邮件和恢复邮件里相同,只有 `$EVENT` 不同,规则把前两段作为 Alert Key,因此恢复邮件可以关闭对应的告警。
@@ -68,7 +66,6 @@ Subject: [$HOST] [$SERVICE] $EVENT
关闭规则排在触发规则前面。Alert Key 由主机名和服务名组成,同一主机上同一服务的多次故障合并到同一条告警。默认规则选丢弃,是为了让没有按上面格式发出的邮件(例如未设置 **Mail format** 的其他告警)不生成无法自动关闭的告警。
## 邮件标题中的事件
----
`$EVENT` 是 Monit 对事件的描述,故障和恢复成对出现:
@@ -81,7 +78,6 @@ Subject: [$HOST] [$SERVICE] $EVENT
| nonexist | `Does not exist` | `Exists` |
## 限制
----
- **类型与严重程度**:告警在 Flashduty 中显示的集成类型是邮件 Email;严重程度统一为 Warning,可以通过 [告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines) 按标题调整。
- **其他事件**:上表之外的 Monit 事件会作为触发告警处理;如果某类事件没有对应的恢复邮件,请在接收该集成的协作空间开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/opsgenie.mdx b/zh/on-call/integration/alert-integration/alert-sources/opsgenie.mdx
index 1d733ba9..639d8235 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/opsgenie.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/opsgenie.mdx
@@ -1,5 +1,6 @@
---
title: "Opsgenie 兼容告警集成"
+sidebarTitle: "Opsgenie 兼容"
description: "使用兼容 Opsgenie Alert API 的协议向 Flashduty On-call 推送告警,已对接 Opsgenie 的工具只需修改 API 地址。"
keywords: ["告警集成", "Opsgenie", "Alert API", "Alertmanager", "Grafana", "迁移"]
---
@@ -9,7 +10,6 @@ Flashduty 实现了 Opsgenie Alert API 中告警的创建与关闭,请求和
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Flashduty 实现了 Opsgenie Alert API 中告警的创建与关闭,请求和
</div>
## 推送地址
----
推送地址的格式如下,`integration_key` 是路径的一部分:
@@ -51,7 +50,6 @@ Opsgenie 客户端会在 API 地址后拼接 `v2/alerts`、`v2/alerts/<alias>/cl
成功的请求返回 HTTP 202 和 `{"result": "Request will be processed", "took": 0, "requestId": "..."}`,与 Opsgenie 相同。
## 在 Prometheus Alertmanager 中配置
----
在 `alertmanager.yml` 的接收器中添加 `opsgenie_configs`,`api_url` 填写推送地址:
@@ -75,7 +73,6 @@ receivers:
- `update_alerts: true` 发送的 Update Message、Update Description 请求会被接受但不做处理;标题与描述随下一次 Create 请求更新
## 在 Grafana 中配置
----
<Steps>
<Step title="创建 OpsGenie 联络点">
@@ -112,7 +109,6 @@ Grafana 把告警标签以 `key:value` 形式放在 `tags` 中,Flashduty 会
联络点的 **Test** 按钮每次都会使用新的 alias,在 Flashduty 中产生一条独立的 Warning 告警,且不会自动恢复,请手动关闭。
## 其他工具
----
任何能修改 Opsgenie API 地址、并通过 alias 关闭告警的工具都可以使用此集成:把 API 地址替换为推送地址(按工具的拼接方式决定是否带 `v2/alerts`),Close 请求带上 `identifierType=alias`。
@@ -123,14 +119,12 @@ Grafana 把告警标签以 `key:value` 形式放在 `tags` 中,Flashduty 会
- **包含 `/` 的 alias**:alias 出现在 URL 路径中,含 `/` 时无法匹配接口
## Alert Key
----
使用请求中的 `alias` 作为 Alert Key。Opsgenie 官方将 alias 定义为「客户端定义的告警标识,也是告警去重的关键字段」([Alert API](https://docs.opsgenie.com/docs/alert-api#create-alert))。同一个 alias 的多次 Create 请求合并为同一条告警,Close 请求按 alias 恢复这条告警。Alertmanager 和 Grafana 都以告警分组的哈希作为 alias,同一分组在触发与恢复时保持不变。
请求中没有 `alias` 时,每次 Create 都会产生一条新告警,且无法通过 Close 恢复。
## 字段映射
----
| Opsgenie 字段 | 在 Flashduty 中 |
| :--- | :--- |
@@ -146,7 +140,6 @@ Grafana 把告警标签以 `key:value` 形式放在 `tags` 中,Flashduty 会
`responders`、`visibleTo`、`actions`、`user`、`note` 不做处理,分派与通知按 Flashduty 协作空间的配置执行。
## 告警等级
----
| Opsgenie `priority` | Flashduty 告警等级 |
| :--- | :--- |
@@ -157,7 +150,6 @@ Grafana 把告警标签以 `key:value` 形式放在 `tags` 中,Flashduty 会
其他取值返回 422。恢复由 Close 请求触发,与 `priority` 无关。
## 排查问题
----
- **返回 404**:Alertmanager 的 `api_url` 缺少结尾的 `/`,或 Grafana 的 Alert API URL 缺少 `/v2/alerts`
- **返回 401**:推送地址中的 `integration_key` 错误,或集成已被禁用
diff --git a/zh/on-call/integration/alert-integration/alert-sources/opsview.mdx b/zh/on-call/integration/alert-integration/alert-sources/opsview.mdx
index 082aa5c7..8e403cb3 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/opsview.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/opsview.mdx
@@ -1,15 +1,15 @@
---
title: "Opsview 告警集成"
+sidebarTitle: "Opsview"
description: "通过 Opsview 的自定义通知方法脚本把主机和服务告警推送到 Flashduty 的标准告警事件集成,恢复通知自动关闭告警。"
keywords: ["告警集成", "Opsview", "ITRS Opsview", "Notification Method", "自定义通知", "标准告警事件"]
---
-Opsview 支持添加自定义通知方法(Custom Notification Method):Opsview 在通知时执行你安装的脚本,并把告警内容通过 `NAGIOS_` 开头的环境变量(`NAGIOS_HOSTNAME`、`NAGIOS_SERVICEDESC`、`NAGIOS_NOTIFICATIONTYPE` 等)传给它。用一个脚本把这些内容以 [标准告警事件](/zh/on-call/integration/alert-integration/alert-sources/standard-alert) 格式推送给 Flashduty 即可:问题通知触发告警,恢复通知关闭告警。
+Opsview 支持添加自定义通知方法(Custom Notification Method):Opsview 在通知时执行您安装的脚本,并把告警内容通过 `NAGIOS_` 开头的环境变量(`NAGIOS_HOSTNAME`、`NAGIOS_SERVICEDESC`、`NAGIOS_NOTIFICATIONTYPE` 等)传给它。用一个脚本把这些内容以 [标准告警事件](/zh/on-call/integration/alert-integration/alert-sources/standard-alert) 格式推送给 Flashduty 即可:问题通知触发告警,恢复通知关闭告警。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 标准告警事件**,不是 Opsview。
@@ -30,7 +30,6 @@ Opsview 支持添加自定义通知方法(Custom Notification Method):Opsv
</div>
## 在 Opsview 中配置
----
### 步骤 1:创建通知脚本
@@ -136,14 +135,12 @@ Opsview 的通知由用户的 Notification Profile 决定,每个要接收 Flas
也可以在 Shared Notification Profiles 中创建共享配置,分配给多个用户。
## 恢复与去重
----
- 同一台主机或同一个服务始终使用同一个 Alert Key,重复的问题通知(例如 Opsview 的重复通知间隔)只更新同一条告警,`RECOVERY` 通知恢复它
- 服务从 WARNING 变为 CRITICAL 时,等级在同一条告警上更新
- 确认(`ACKNOWLEDGEMENT`)、抖动(`FLAPPING*`)和停机维护(`DOWNTIME*`)通知被脚本忽略,不会在 Flashduty 产生事件
## 排查问题
----
- **没有收到告警**:确认 Notification Profile 中选择了 `Flashduty` 且已执行 **Apply Changes**;在 Opsview 的 **Notifications View** 查看通知是否已发送;用 `test_notifications` 单独测试脚本
- **测试成功但真实告警没有推送**:脚本在真实通知中读取的是 Opsview 传入的环境变量;在脚本开头加入 `{ date; echo "Called with $@"; env; echo; } >> /tmp/env.txt`(Opsview 文档给出的排查方法)查看实际收到的变量
diff --git a/zh/on-call/integration/alert-integration/alert-sources/ossec.mdx b/zh/on-call/integration/alert-integration/alert-sources/ossec.mdx
index 9f413496..91f2ec6d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/ossec.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/ossec.mdx
@@ -1,5 +1,6 @@
---
title: "OSSEC 告警集成"
+sidebarTitle: "OSSEC"
description: "OSSEC 通过邮件发送告警通知,使用 Flashduty 的邮件集成将 OSSEC 告警同步到 Flashduty On-call。"
keywords: ["告警集成", "OSSEC", "OSSEC HIDS", "HIDS", "入侵检测", "邮件", "Email", "安全告警"]
---
@@ -9,7 +10,6 @@ OSSEC 服务端(ossec-maild)可以把告警通过邮件发送到指定收件
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成邮件地址,任选其一即可。**集成类型都选择邮件 Email**,不是 OSSEC。
@@ -30,7 +30,6 @@ OSSEC 服务端(ossec-maild)可以把告警通过邮件发送到指定收件
</div>
## 在 Flashduty 中配置推送模式
----
OSSEC 只在告警产生时发一封邮件,没有恢复邮件,因此不需要「关闭告警」规则。**推送模式** 选择 **根据邮件标题触发或更新告警**:同一台主机、同一日志来源、同一等级、同一条规则描述的邮件标题相同,会合并到同一条未关闭的告警上;标题不同的邮件各自产生一条告警。
@@ -39,7 +38,6 @@ OSSEC 只在告警产生时发一封邮件,没有恢复邮件,因此不需
OSSEC 不会发送恢复通知,请在接收该集成的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时;也可以处理完成后手动关闭。
## 在 OSSEC 中配置
----
以下配置在 OSSEC 服务端(server)的 `/var/ossec/etc/ossec.conf` 中完成,Agent 上不需要配置(告警只在服务端生成)。
@@ -110,7 +108,6 @@ OSSEC 默认会把短时间内的多条告警合并到一封邮件,邮件标
</Steps>
## 邮件标题格式
----
OSSEC 邮件默认使用完整标题(内部选项 `maild.full_subject=0`,默认值),格式为:
@@ -129,7 +126,6 @@ OSSEC Alert - (slacker) 192.168.2.0 - Level 3 - SSHD authentication success.
邮件正文以 `OSSEC HIDS Notification.` 开头,依次是告警时间、`Received From`(告警来源)、`Rule: <规则 ID> fired (level <等级>) -> "<规则描述>"`、来源 IP / 用户(存在时)以及触发告警的原始日志片段(`Portion of the log(s)`)。在 Flashduty 中,告警的标题是邮件标题,描述是邮件正文。
## 限制
----
- **没有恢复**:OSSEC 告警是一次性事件,Flashduty 中的告警不会自动恢复,依赖 [超时自动关闭](/zh/on-call/channel/create-edit) 或手动关闭。
- **严重程度**:邮件集成推送的告警严重程度统一为 Warning。标题中包含 OSSEC 等级(`Level N`),可以通过 [告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines) 按等级调整。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/pagerduty.mdx b/zh/on-call/integration/alert-integration/alert-sources/pagerduty.mdx
index 94f85cd2..53904c4a 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/pagerduty.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/pagerduty.mdx
@@ -1,17 +1,17 @@
---
title: "PagerDuty 兼容集成"
+sidebarTitle: "PagerDuty 兼容"
description: "Flashduty 实现了 PagerDuty Events API v1/v2。已支持推送到 PagerDuty 的工具,把推送地址改为 Flashduty 即可接入告警。"
keywords: ["告警集成", "PagerDuty", "PagerDuty 兼容", "Events API v2", "routing_key"]
---
Flashduty 实现了 PagerDuty Events API,输入和响应完全兼容。因此您可以通过 PagerDuty 协议推送告警事件到 Flashduty On-call,实现告警事件自动化降噪处理。
-同样的,对于已经支持推送事件到 PagerDuty 的告警系统(如 ElastAlert),你仅需要修改目的推送地址,即可利用 PagerDuty 协议推送事件到 Flashduty 。
+同样的,对于已经支持推送事件到 PagerDuty 的告警系统(如 ElastAlert),您仅需要修改目的推送地址,即可利用 PagerDuty 协议推送事件到 Flashduty 。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -19,7 +19,7 @@ keywords: ["告警集成", "PagerDuty", "PagerDuty 兼容", "Events API v2", "ro
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -35,9 +35,9 @@ keywords: ["告警集成", "PagerDuty", "PagerDuty 兼容", "Events API v2", "ro
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **PagerDuty 兼容** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -50,7 +50,6 @@ keywords: ["告警集成", "PagerDuty", "PagerDuty 兼容", "Events API v2", "ro
</div>
## 在告警系统中配置
----
### 请求地址
```
@@ -95,23 +94,23 @@ keywords: ["告警集成", "PagerDuty", "PagerDuty 兼容", "Events API v2", "ro
### 配置示例
-以 [ElastAlert2](https://github.com/jertel/elastalert2) 为例:
+以 [ElastAlert2](https://github.com/jertel/elastalert2) 为例:
<div className="md-block">
1. 步骤 1:获得推送地址
-在当前页面填写集成名称并保存,重新打开集成详情,复制推送地址,如:
+ 在当前页面填写集成名称并保存,重新打开集成详情,复制推送地址,如:
-```
-{api_host}/event/push/alert/pagerduty?integration_key=xxx
-```
+ ```
+ {api_host}/event/push/alert/pagerduty?integration_key=xxx
+ ```
2. 步骤 2:修改推送地址
-修改已经部署好的 ElastAlert 实例对应源码,[查看 diff ](https://github.com/jertel/elastalert2/commit/e815a62a6b1eecef6e1fef13afd99d905b67fc34):
+ 修改已经部署好的 ElastAlert 实例对应源码,[查看 diff ](https://github.com/jertel/elastalert2/commit/e815a62a6b1eecef6e1fef13afd99d905b67fc34):
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/pagerduty-replace-endpoint.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/pagerduty-replace-endpoint.png" />
3. 步骤 3:上报告警事件
diff --git a/zh/on-call/integration/alert-integration/alert-sources/pandora-fms.mdx b/zh/on-call/integration/alert-integration/alert-sources/pandora-fms.mdx
index 634dff6d..84d59a9a 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/pandora-fms.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/pandora-fms.mdx
@@ -1,5 +1,6 @@
---
title: "Pandora FMS 告警集成"
+sidebarTitle: "Pandora FMS"
description: "通过自定义告警命令将 Pandora FMS 模块告警的触发和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Pandora FMS", "Alert command", "告警命令", "Alert recovery", "_id_alert_", "curl"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Pandora FMS", "Alert command", "告警命令", "Aler
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Pandora FMS", "Alert command", "告警命令", "Aler
</div>
## 在 Pandora FMS 中配置
----
Pandora FMS 的告警动作在 Pandora FMS 服务器上执行命令。下面的配置新建一个用 `curl` 推送的告警命令,再新建一个使用该命令的动作,最后把动作加到模块告警上。
@@ -45,16 +44,16 @@ Pandora FMS 的告警动作在 Pandora FMS 服务器上执行命令。下面的
2. **Name** 填写 `Flashduty`
3. **Command** 填写下方命令,保持为一行,不要修改字段名:
-```text
-curl -sS -m 10 "_field1_" --data-urlencode "event=_field2_" --data-urlencode "id_alert=_id_alert_" --data-urlencode "alert_name=_alert_name_" --data-urlencode "alert_priority=_alert_priority_" --data-urlencode "alert_times_fired=_alert_times_fired_" --data-urlencode "agent=_agent_" --data-urlencode "id_agent=_id_agent_" --data-urlencode "address=_address_" --data-urlencode "agent_group=_agentgroup_" --data-urlencode "module=_module_" --data-urlencode "id_module=_id_module_" --data-urlencode "module_description=_moduledescription_" --data-urlencode "module_status=_modulestatus_" --data-urlencode "data=_data_" --data-urlencode "timestamp=_timestamp_"
-```
+ ```text
+ curl -sS -m 10 "_field1_" --data-urlencode "event=_field2_" --data-urlencode "id_alert=_id_alert_" --data-urlencode "alert_name=_alert_name_" --data-urlencode "alert_priority=_alert_priority_" --data-urlencode "alert_times_fired=_alert_times_fired_" --data-urlencode "agent=_agent_" --data-urlencode "id_agent=_id_agent_" --data-urlencode "address=_address_" --data-urlencode "agent_group=_agentgroup_" --data-urlencode "module=_module_" --data-urlencode "id_module=_id_module_" --data-urlencode "module_description=_moduledescription_" --data-urlencode "module_status=_modulestatus_" --data-urlencode "data=_data_" --data-urlencode "timestamp=_timestamp_"
+ ```
4. 按下表填写字段说明和可选值:
-| 字段 | Description | Values |
-| :--- | :--- | :--- |
-| **Field 1** | `Flashduty push URL` | 留空 |
-| **Field 2** | `Event` | `alert_fired,Alert fired;alert_recovered,Alert recovered` |
+ | 字段 | Description | Values |
+ | :--- | :--- | :--- |
+ | **Field 1** | `Flashduty push URL` | 留空 |
+ | **Field 2** | `Event` | `alert_fired,Alert fired;alert_recovered,Alert recovered` |
5. 点击 **Create** 保存
@@ -68,10 +67,10 @@ curl -sS -m 10 "_field1_" --data-urlencode "event=_field2_" --data-urlencode "id
2. **Name** 填写 `Flashduty`,**Group** 选择需要使用该动作的组(所有组选 **All**),**Command** 选择上一步的 `Flashduty`
3. 按下表填写字段,**Triggering** 和 **Recovery** 两列都要填:
-| 字段 | Triggering | Recovery |
-| :--- | :--- | :--- |
-| **Field 1**(Flashduty push URL) | Flashduty 集成的完整推送地址 | Flashduty 集成的完整推送地址 |
-| **Field 2**(Event) | `Alert fired`(`alert_fired`) | `Alert recovered`(`alert_recovered`) |
+ | 字段 | Triggering | Recovery |
+ | :--- | :--- | :--- |
+ | **Field 1**(Flashduty push URL) | Flashduty 集成的完整推送地址 | Flashduty 集成的完整推送地址 |
+ | **Field 2**(Event) | `Alert fired`(`alert_fired`) | `Alert recovered`(`alert_recovered`) |
4. 点击 **Create** 保存
@@ -105,7 +104,6 @@ curl -sS -m 10 "_field1_" --data-urlencode "event=_field2_" --data-urlencode "id
</Warning>
## 推送内容
----
命令以 `application/x-www-form-urlencoded` 表单格式 POST 以下字段:
@@ -130,7 +128,6 @@ curl -sS -m 10 "_field1_" --data-urlencode "event=_field2_" --data-urlencode "id
告警标题为 `<模板名称>: <代理> / <模块>`;缺少部分字段时使用其余字段,全部为空时使用 `Pandora FMS alert <id_alert>`。
## Alert Key
----
Flashduty 使用 `id_alert`(Pandora FMS 宏 `_id_alert_`)作为 Alert Key。Pandora FMS 文档对该宏的说明是 “Alert identifier, useful for correlating the alert in third-party tools”:它是模板分配到某个模块后的模块告警 ID,同一条模块告警的触发、重复触发和恢复携带相同的 ID,因此会落在同一条 Flashduty 告警上。同一个模板分配到两个模块时是两条模块告警,ID 不同,会生成不同的 Flashduty 告警。修改模板名称、优先级、代理别名或数据不会改变 Alert Key。
@@ -139,7 +136,6 @@ Flashduty 使用 `id_alert`(Pandora FMS 宏 `_id_alert_`)作为 Alert Key。
只有模块告警带有 `_id_alert_`。事件告警、日志告警和关联告警没有模块告警 ID,Flashduty 会以参数错误拒绝,请不要把 `Flashduty` 动作加到这类告警上。
## 状态和告警等级
----
`event` 决定告警触发还是恢复,`alert_priority`(告警模板的 **Priority**)决定告警等级:
@@ -155,7 +151,6 @@ Flashduty 使用 `id_alert`(Pandora FMS 宏 `_id_alert_`)作为 Alert Key。
`event` 为 `alert_recovered` 时关闭告警,告警等级仍取模板优先级。`event` 为空或为其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么要在动作里填写 Event?">
@@ -184,7 +179,6 @@ Pandora FMS 在告警触发和恢复时执行同一个动作,没有宏能说
</AccordionGroup>
## 排查问题
----
- **Pandora FMS 没有推送**:在 Pandora FMS 服务器上执行 `curl -sS <推送地址>` 确认网络可达;确认动作的 **Group** 覆盖了代理所在组
- **Flashduty 返回参数错误**:确认命令完整粘贴、保持为一行;确认动作 **Field 2** 两列分别为 `alert_fired` 和 `alert_recovered`;确认动作只加在模块告警上
diff --git a/zh/on-call/integration/alert-integration/alert-sources/panther.mdx b/zh/on-call/integration/alert-integration/alert-sources/panther.mdx
index 9b2967a5..9db4bad9 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/panther.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/panther.mdx
@@ -1,5 +1,6 @@
---
title: "Panther 告警集成"
+sidebarTitle: "Panther"
description: "通过 Panther 的 Custom Webhook 告警目的地,将 Panther 检测告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Panther", "Webhook", "SIEM", "安全告警", "检测"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Panther", "Webhook", "SIEM", "安全告警", "检测
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Panther", "Webhook", "SIEM", "安全告警", "检测
</div>
## 在 Panther 中配置
----
<Steps>
<Step title="创建 Custom Webhook 目的地">
@@ -69,14 +68,12 @@ Panther 对 Custom Webhook 发送 HTTP `POST` 的 JSON 请求,期望返回 `2X
</Steps>
## Alert Key
----
Flashduty 使用请求体中的 `alertId` 作为 Alert Key。Panther 文档对该字段的说明是 “Identifier of the alert in Panther Backend”。同一个 Panther 告警从告警详情页手动重新发送时,会落在同一条 Flashduty 告警上。
标题、等级、描述等字段的变化不会改变 Alert Key。请求缺少 `alertId` 时 Flashduty 会返回参数错误。
## 状态和告警等级
----
Panther 的 Custom Webhook 没有状态字段,Flashduty 每次收到的都是触发事件。
@@ -90,7 +87,6 @@ Panther 的 Custom Webhook 没有状态字段,Flashduty 每次收到的都是
告警标签包含检测名称、检测 ID(`id`)、告警 ID、告警类型、原始等级、告警链接和标签(`tags`)。`alertContext` 由检测规则的作者定义,可能包含原始日志字段,不会写入告警;`runbook` 同样不写入。
## 排查问题
----
- **Panther 显示投递失败**:确认推送地址完整且包含 `integration_key`,Flashduty 返回非 `2XX` 时 Panther 会重试最多 10 次
- **没有收到告警**:确认目的地的 **Severity Levels**、**Default Alert Types** 与 **Log Types** 覆盖了该告警,并检查检测规则的目的地路由
diff --git a/zh/on-call/integration/alert-integration/alert-sources/papertrail.mdx b/zh/on-call/integration/alert-integration/alert-sources/papertrail.mdx
index 97d49c96..260d8f49 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/papertrail.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/papertrail.mdx
@@ -1,5 +1,6 @@
---
title: "Papertrail 告警集成"
+sidebarTitle: "Papertrail"
description: "通过 Webhook 将 Papertrail 保存搜索命中的日志同步到 Flashduty On-call。"
keywords: ["告警集成", "Papertrail", "SolarWinds", "Saved Search", "Webhook", "日志告警"]
---
@@ -13,7 +14,6 @@ Papertrail(SolarWinds 旗下的日志聚合服务)用 **Saved Search(保
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -34,7 +34,6 @@ Papertrail(SolarWinds 旗下的日志聚合服务)用 **Saved Search(保
</div>
## 在 Papertrail 中配置
----
<Steps>
<Step title="创建保存搜索并附加告警">
@@ -67,7 +66,6 @@ Papertrail 官方文档没有提到 Webhook 的测试发送按钮。请让保存
</Steps>
## 推送内容
----
Flashduty 按 Papertrail 官方文档的固定格式解析请求:请求体为 `application/x-www-form-urlencoded`,只有一个表单字段 `payload`,值是一段 JSON:
@@ -108,7 +106,6 @@ Flashduty 按 Papertrail 官方文档的固定格式解析请求:请求体为
| `counts[]`("Send only counts" 模式) | 按来源分组的计数,不包含具体日志和 ID | 不支持,收到时 Flashduty 拒绝请求,请在 Papertrail 中关闭该选项 |
## Alert Key
----
Flashduty 直接使用 `saved_search.id` 作为 Alert Key。官方文档将其定义为保存搜索的稳定标识,在同一个保存搜索的每次推送中都不会变化,因此同一个保存搜索反复命中新日志时,每次推送都会合并进同一条告警,视为同一个问题在持续发生;不同的保存搜索产生不同的 Alert Key,各自开出独立的告警。
@@ -117,12 +114,10 @@ Flashduty 直接使用 `saved_search.id` 作为 Alert Key。官方文档将其
缺少 `saved_search.id` 的推送会被拒绝。
## 告警等级
----
Papertrail 的保存搜索告警没有严重程度字段,所有命中都以 **Warning** 等级触发。请求体里每条日志自带的 `severity`(如 `Info`、`Error`)是该条日志本身的 syslog 级别,同一次推送里可能包含多种取值,不代表这条告警的紧急程度,因此不参与等级判断,仅体现在告警描述里摘录的日志内容中。
## 常见问题
----
<AccordionGroup>
diff --git a/zh/on-call/integration/alert-integration/alert-sources/peekaping.mdx b/zh/on-call/integration/alert-integration/alert-sources/peekaping.mdx
index c8fc9ee9..36244bc0 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/peekaping.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/peekaping.mdx
@@ -1,5 +1,6 @@
---
title: "Peekaping 告警集成"
+sidebarTitle: "Peekaping"
description: "通过 Webhook 通知渠道将 Peekaping 监控的宕机与恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Peekaping", "Webhook", "拨测", "监控", "自托管"]
---
@@ -9,7 +10,6 @@ Peekaping 是开源的自托管监控系统。通过 Peekaping 的 Webhook 通
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Peekaping 是开源的自托管监控系统。通过 Peekaping 的 Webhook 通
</div>
## 在 Peekaping 中配置
----
需要 Peekaping 0.0.46 或更高版本,并使用有权限管理通知渠道和监控的账号登录。Peekaping 所在的服务器需要能访问 Flashduty 的推送地址。
@@ -60,14 +59,12 @@ Peekaping 是开源的自托管监控系统。通过 Peekaping 的 Webhook 通
</Steps>
## Alert Key
----
Flashduty 使用请求中的 `monitor.id`(监控 ID)作为 Alert Key。同一个监控宕机和恢复时的 `monitor.id` 相同,因此恢复会关闭对应的告警;`heartbeat.id` 每次心跳都不同,不参与 Alert Key。
监控名称、状态消息、时间等字段变化不会改变 Alert Key。请求中缺少 `monitor.id` 会被拒绝。`monitor.id` 只在同一个 Peekaping 实例内唯一,一个 Flashduty 集成请只接收一个 Peekaping 实例的推送。
## 状态和告警等级
----
| `heartbeat.status` | 含义 | Flashduty 处理 |
| :--- | :--- | :--- |
@@ -79,7 +76,6 @@ Flashduty 使用请求中的 `monitor.id`(监控 ID)作为 Alert Key。同
Peekaping 本身没有告警等级,宕机统一映射为 Critical。告警标题为监控名称,描述为心跳消息(例如 `TCP connection failed: ...`)。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -91,7 +87,6 @@ Peekaping 本身没有告警等级,宕机统一映射为 Critical。告警标
监控的 `config`(包含主机、凭据等)和 `push_token` 不会进入标签或描述。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,并确认通知渠道的 **请求体** 为 `application/json`;响应信息会指出缺少的字段
- **Peekaping 测试失败**:确认 Peekaping 所在服务器能访问 Flashduty 推送地址,并查看 Peekaping 日志中的 HTTP 状态码
diff --git a/zh/on-call/integration/alert-integration/alert-sources/pgdash.mdx b/zh/on-call/integration/alert-integration/alert-sources/pgdash.mdx
index 9f79fa92..13374d66 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/pgdash.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/pgdash.mdx
@@ -1,5 +1,6 @@
---
title: "pgDash 告警集成"
+sidebarTitle: "pgDash"
description: "通过 Webhook 将 pgDash 的 PostgreSQL 监控告警同步到 Flashduty On-call。"
keywords: ["告警集成", "pgDash", "PostgreSQL", "数据库监控", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "pgDash", "PostgreSQL", "数据库监控", "Webhook"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "pgDash", "PostgreSQL", "数据库监控", "Webhook"]
</div>
## 在 pgDash 中配置
----
pgDash SaaS 版和自托管版的配置方式相同,Webhook 需要 pgDash 2.4.11 及以上版本。
@@ -60,7 +59,6 @@ Webhook 按服务器设置。需要接入多个服务器时,请为每个服务
</Warning>
## 告警生命周期
----
pgDash 的 Webhook 是边沿触发的:只有服务器的告警状态发生变化时才发送通知,每次通知都带上该服务器当前全部的告警项(`alerts` 数组);所有告警消除时,发送一次 `alerts` 为空的通知。
@@ -76,7 +74,6 @@ pgDash 的 Webhook 是边沿触发的:只有服务器的告警状态发生变
</Tip>
## 告警等级
----
| pgDash 告警项 | Flashduty 等级 |
| :--- | :--- |
@@ -85,14 +82,12 @@ pgDash 的 Webhook 是边沿触发的:只有服务器的告警状态发生变
| `alerts` 为空 | 恢复 |
## 告警内容
----
- **标题**:`服务器名: 告警规则描述`,取第一条 `crit` 告警项(没有时取第一条告警项);有多条告警项时附加 `(+N more)`
- **描述**:pgmetrics 报告时间(UTC),以及每条告警项的等级、规则描述、当前值、对象名称、链接;查询级别告警附带 SQL 文本(截断到 500 字符)。最多列出 50 条告警项
- **标签**:`server`、`check`(标题所取告警项的规则描述)、`resource`(该告警项的对象名称)、`link`(该告警项的 pgDash 链接)、`alert_count`(当前告警项数量)、`source`(固定为 `pgdash`)
## 排查问题
----
- **pgDash 没有发送通知**:pgDash 只在告警状态变化时发送;状态不变不会重复发送。确认告警规则已触发,且 Webhook 设置在 **Alerts** 页面而不是 **Change Alerts** 页面
- **投递超时**:pgDash 要求 3 秒内响应,超时后最多重试 3 次;请确认 pgDash 服务器(自托管版)可以访问推送地址
diff --git a/zh/on-call/integration/alert-integration/alert-sources/phare.mdx b/zh/on-call/integration/alert-integration/alert-sources/phare.mdx
index 3c5dc2f5..640c62cc 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/phare.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/phare.mdx
@@ -1,5 +1,6 @@
---
title: "Phare Uptime 告警集成"
+sidebarTitle: "Phare Uptime"
description: "通过 Phare 的 Outgoing Webhook 将 Uptime 事件(Incident)的创建和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Phare", "Phare Uptime", "Outgoing Webhook", "Incident", "Uptime"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Phare", "Phare Uptime", "Outgoing Webhook", "Inciden
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Phare", "Phare Uptime", "Outgoing Webhook", "Inciden
</div>
## 在 Phare 中配置
----
Phare 的 Webhook 请求体由您用占位符编写,因此下面给出需要粘贴的模板,Flashduty 按这份模板解析。
@@ -101,12 +100,10 @@ Phare 的 Webhook 请求体由您用占位符编写,因此下面给出需要
</Steps>
## Alert Key
----
Flashduty 使用 `incident.id` 作为 Alert Key。Phare 的创建、扩散、部分恢复和恢复事件都暴露同一个事件(Incident)实体,`{{ incident.id }}` 是该事件的编号,因此同一个事件的所有通知得到相同的 Alert Key。标题、描述、状态、影响程度、受影响监控项的变化不会改变 Alert Key。
## 状态和告警等级
----
事件类型由 `X-Phare-Request-Event` 请求头决定:
@@ -129,7 +126,6 @@ Flashduty 使用 `incident.id` 作为 Alert Key。Phare 的创建、扩散、部
事件是监控项探测失败产生的,因此无法判断影响程度时按 Critical 处理。恢复事件保留 `impact` 对应的等级,状态变为恢复。
## 排查问题
----
- **Flashduty 返回参数错误**:确认模板是有效 JSON,`incident.id` 非空,并且请求带有 `X-Phare-Request-Event` 或 `event` 字段
- **告警没有恢复**:确认创建了 **Incident recovered** 规则,且使用了同一份模板
diff --git a/zh/on-call/integration/alert-integration/alert-sources/pingdom.mdx b/zh/on-call/integration/alert-integration/alert-sources/pingdom.mdx
index e428326f..f9cd06ab 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/pingdom.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/pingdom.mdx
@@ -1,5 +1,6 @@
---
title: "Pingdom 告警集成"
+sidebarTitle: "Pingdom"
description: "通过 Webhook 将 Pingdom Uptime 检查和 Transaction 检查的状态变化同步到 Flashduty On-call。"
keywords: ["告警集成", "Pingdom", "SolarWinds", "Uptime", "Transaction", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Pingdom", "SolarWinds", "Uptime", "Transaction", "We
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Pingdom", "SolarWinds", "Uptime", "Transaction", "We
</div>
## 在 Pingdom 中配置
----
<Steps>
<Step title="创建 Webhook 集成">
@@ -68,14 +67,12 @@ Pingdom 只在检查状态变化时发送 Webhook:Uptime 检查在 `UP` 与 `D
</Tip>
## Alert Key
----
Flashduty 用检查类别(Uptime 或 Transaction)加 `check_id` 计算 Alert Key。同一个检查的失败和恢复 Webhook 携带相同的 `check_id`,因此会落在同一条告警上。Uptime 检查与 Transaction 检查分属不同的检查列表,加入类别后,即使两者数字 ID 相同也不会互相覆盖。
检查名称、`importance_level`、状态、时间、错误描述和探测节点的变化都不会改变 Alert Key。请求缺少 `check_id` 时 Flashduty 会拒绝,因为无法关联后续恢复。
## 状态和告警等级
----
| Pingdom `current_state` | Flashduty 状态 |
| :--- | :--- |
@@ -97,7 +94,6 @@ Flashduty 用检查类别(Uptime 或 Transaction)加 `check_id` 计算 Alert
恢复事件保留原告警等级。
## 告警内容
----
- **标题**:检查名称 `check_name`
- **描述**:`long_description`,为空时使用 `description`
@@ -106,7 +102,6 @@ Flashduty 用检查类别(Uptime 或 Transaction)加 `check_id` 计算 Alert
`check_params` 中的请求头和认证设置不会写入标签。
## 排查问题
----
- **Pingdom 返回非 2xx**:确认 URL 是完整推送地址且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求中有 `check_id` 和 `current_state`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/postman.mdx b/zh/on-call/integration/alert-integration/alert-sources/postman.mdx
index f167e4ae..b1cbf123 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/postman.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/postman.mdx
@@ -1,5 +1,6 @@
---
title: "Postman 告警集成"
+sidebarTitle: "Postman"
description: "通过 Postman 的自定义 Webhook 将 Postman Monitor 的运行结果同步到 Flashduty On-call。"
keywords: ["告警集成", "Postman", "Monitor", "Webhook", "API 监控", "接口测试"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Postman", "Monitor", "Webhook", "API 监控", "接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Postman", "Monitor", "Webhook", "API 监控", "接
</div>
## 在 Postman 中配置
----
<Steps>
<Step title="添加 Webhook 集成">
@@ -43,7 +42,7 @@ keywords: ["告警集成", "Postman", "Monitor", "Webhook", "API 监控", "接
- **Notify for all completed monitor runs**(请选择这一项):每次运行都推送。失败的运行触发告警,通过的运行恢复告警
- **Notify for 3 failures and then first success**:Postman 只按选项名称描述其行为,没有说明具体推送哪些运行,通过的运行是否推送、何时推送无法保证,告警可能无法恢复,也会晚触发
-Postman 的推送里没有状态字段,Flashduty 依靠通过的运行来恢复告警,所以只有选择 **Notify for all completed monitor runs**,恢复才能可靠生效。
+ Postman 的推送里没有状态字段,Flashduty 依靠通过的运行来恢复告警,所以只有选择 **Notify for all completed monitor runs**,恢复才能可靠生效。
6. 点击 **Add Integration**
每个 Monitor 需要单独添加一条 Webhook 集成。
@@ -62,12 +61,10 @@ Postman 文档未提供 Webhook 的测试推送功能。
</Steps>
## Alert Key
----
Flashduty 使用 `monitor_uid`(Monitor 的唯一 ID)作为 Alert Key,同一个 Monitor 的失败和恢复推送使用同一个 Alert Key。修改 Monitor 名称、测试数量、耗时等字段不会改变 Alert Key。缺少 `monitor_uid` 的请求会被拒绝。
## 状态和告警等级
----
Postman 的推送内容里没有状态字段,Flashduty 根据 `metrics` 中的计数判断本次运行的结果:
@@ -80,7 +77,6 @@ Postman 的推送内容里没有状态字段,Flashduty 根据 `metrics` 中的
`metrics` 对象缺失,或 `errorCount`、`failedTestCount` 任一缺失、不是非负整数的请求会被拒绝,不会被当作通过的运行。没有活动告警的 Monitor 收到通过的运行时,不会创建新告警。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -96,7 +92,6 @@ Postman 的推送内容里没有状态字段,Flashduty 根据 `metrics` 中的
触发推送的用户信息(`user_id`、`user_name`)不会写入标签。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`
- **告警没有恢复**:确认 Monitor 之后有一次所有测试都通过且没有请求错误的运行;请确认通知方式选择的是 **Notify for all completed monitor runs**
diff --git a/zh/on-call/integration/alert-integration/alert-sources/powerjob.mdx b/zh/on-call/integration/alert-integration/alert-sources/powerjob.mdx
index c4e3e8be..e70551ee 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/powerjob.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/powerjob.mdx
@@ -1,5 +1,6 @@
---
title: "PowerJob 告警集成"
+sidebarTitle: "PowerJob"
description: "通过 PowerJob 用户的 WebHook 报警,把任务实例和工作流实例的执行失败同步到 Flashduty On-call。"
keywords: ["告警集成", "PowerJob", "定时任务", "工作流", "Webhook", "任务调度"]
---
@@ -11,7 +12,6 @@ PowerJob 只在执行失败时报警,执行成功不会通知,因此告警
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ PowerJob 只在执行失败时报警,执行成功不会通知,因此告警
</div>
## 在 PowerJob 中配置
----
PowerJob 的报警对象是用户:先在用户上设置 WebHook 地址,再在任务或工作流上选择要通知的用户。本集成基于 PowerJob 5.1.7 验证。
@@ -63,14 +62,12 @@ PowerJob 没有“发送测试通知”按钮。让一个任务失败,例如
</Steps>
## 告警不会自动恢复
----
PowerJob 不发送恢复通知,也不在任务后来执行成功时报警。在接收该集成的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 12 小时,并按团队处理失败任务的时效调整。
每一次失败的执行都是一条独立告警。高频调度的任务(例如每分钟一次)连续失败时,会产生大量告警,可以配合 Flashduty 的告警聚合降噪。
## 任务失败和工作流失败
----
本集成按请求内容区分两种报警:
@@ -82,7 +79,6 @@ PowerJob 不发送恢复通知,也不在任务后来执行成功时报警。
告警描述中包含 PowerJob 报告的执行结果 `result`(超过 1000 字节会被截断)。任务参数、实例参数和处理器信息(例如 Shell 脚本内容)可能包含敏感信息,Flashduty 不读取这些字段。
## Alert Key
----
| 报警类型 | Alert Key |
| :--- | :--- |
@@ -94,12 +90,10 @@ PowerJob 不发送恢复通知,也不在任务后来执行成功时报警。
实例 ID 是超过 2^53 的长整数,Flashduty 按原文保留每一位数字。
## 状态和告警等级
----
PowerJob 的报警没有等级字段,且只在执行失败时发送,所以所有告警都是触发状态、Critical 等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -114,7 +108,6 @@ PowerJob 的报警没有等级字段,且只在执行失败时发送,所以
| `task_tracker_address` | 执行该任务的 TaskTracker 地址(任务失败) |
## 排查问题
----
- **Flashduty 没有收到事件**:确认执行失败的任务或工作流选了报警通知人员,且该用户填写了 WebHook;确认 PowerJob 服务端能访问 Flashduty,推送地址完整且包含 `integration_key`。PowerJob 发送失败时只在服务端日志中记录一条 `[WebHookAlarmService] invoke webhook ... failed`,不会重试
- **Flashduty 返回参数错误**:请求缺少 Alert Key 一节所列的字段,或不是 PowerJob 的 JSON 报警
diff --git a/zh/on-call/integration/alert-integration/alert-sources/projectdiscovery.mdx b/zh/on-call/integration/alert-integration/alert-sources/projectdiscovery.mdx
index c9967604..5d63cc64 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/projectdiscovery.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/projectdiscovery.mdx
@@ -1,5 +1,6 @@
---
title: "ProjectDiscovery Cloud 告警集成"
+sidebarTitle: "ProjectDiscovery Cloud"
description: "通过 ProjectDiscovery Cloud 的 Webhook 告警,把扫描发现的新漏洞和扫描、资产发现的失败通知同步到 Flashduty On-call。"
keywords: ["告警集成", "ProjectDiscovery", "Nuclei", "漏洞扫描", "资产发现", "Webhook", "scan_id"]
---
@@ -11,7 +12,6 @@ ProjectDiscovery 不会推送“漏洞已修复”或“失败已解决”的通
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ ProjectDiscovery 不会推送“漏洞已修复”或“失败已解决”的通
</div>
## 在 ProjectDiscovery Cloud 中配置
----
<Steps>
<Step title="添加 Webhook 告警配置">
@@ -62,7 +61,6 @@ ProjectDiscovery 不会推送“漏洞已修复”或“失败已解决”的通
</Note>
## 推送内容
----
ProjectDiscovery 以 `application/json` POST 通知,Flashduty 直接解析,无需配置模板。扫描通知携带 `scan_name`、`scan_id`,资产发现通知携带 `enumeration_name`、`enumeration_id`。
@@ -81,14 +79,12 @@ ProjectDiscovery 以 `application/json` POST 通知,Flashduty 直接解析,
告警标题:新漏洞为 `<名称>: new vulnerabilities`,失败为 `<名称> failed`。
## Alert Key
----
Flashduty 使用 `scan_id`(资产发现使用 `enumeration_id`)作为 Alert Key。ProjectDiscovery 文档将其定义为执行的唯一标识。同一个 ID 的多次通知合并到同一条告警;不同扫描或资产发现生成不同的告警。修改名称、数量或时间不会改变 Alert Key。
新漏洞和失败通知缺少对应 ID 时,Flashduty 返回参数错误,并指出缺少的字段。
## 状态和告警等级
----
| ProjectDiscovery 事件 | Flashduty 等级 |
| :--- | :--- |
@@ -101,17 +97,14 @@ Flashduty 使用 `scan_id`(资产发现使用 `enumeration_id`)作为 Alert
`new_vuln` 优先按 `rescan_vulns_list` 中最高的严重程度判定;列表为空时改用 `severity_breakdown` 中数量大于 0 的最高级别。扫描失败意味着覆盖缺口,不是服务中断,因此按 Warning 处理。
## 超时自动关闭
----
ProjectDiscovery 不推送恢复通知,这两类告警会一直保持活动。请在接收这些告警的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议时长 24 小时,可按扫描频率调整。
## 关于签名
----
ProjectDiscovery 的 Webhook 支持可选的自定义认证头。Flashduty 不校验该头,鉴权依靠推送地址中的 `integration_key`,请妥善保管推送地址。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么扫描完成通知没有产生告警?">
@@ -134,7 +127,6 @@ ProjectDiscovery 只在重复扫描(rescan)时发送 `new_vuln`,首次扫
</AccordionGroup>
## 排查问题
----
- **ProjectDiscovery 推送失败**:确认 Webhook URL 是包含 `integration_key` 的完整 HTTPS 推送地址
- **Flashduty 返回参数错误**:确认请求体是 ProjectDiscovery 的 JSON 通知,且 `new_vuln`、`failed_stopped` 带有 `scan_id` 或 `enumeration_id`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/prometheus.mdx b/zh/on-call/integration/alert-integration/alert-sources/prometheus.mdx
index 8b9f23e4..f8ee0ef0 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/prometheus.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/prometheus.mdx
@@ -1,5 +1,6 @@
---
-title: "Prometheus告警集成"
+title: "Prometheus 告警集成"
+sidebarTitle: "Prometheus"
description: "通过 webhook 的方式将 Prometheus 告警事件通过 AlertManager 推送到 Flashduty On-call"
keywords: ["告警集成", "Prometheus", "监控告警", "数据接入"]
---
@@ -8,20 +9,17 @@ keywords: ["告警集成", "Prometheus", "监控告警", "数据接入"]
<div className="hide">
## 使用限制
----
### 在 AlertManager
- 您必须拥有修改 AlertManager 配置文件的权限。
-- 您的 AlertManager server 必须能够访问域名 api.flascat.cloud,将告警推送到外网。
+- 您的 AlertManager server 必须能够访问域名 api.flashcat.cloud,将告警推送到外网。
## 支持版本
----
本文适配 **Alertmanager 0.16.0 及以上** 版本。
## 操作步骤
----
### 在 Flashduty On-call
@@ -32,7 +30,7 @@ keywords: ["告警集成", "Prometheus", "监控告警", "数据接入"]
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -47,10 +45,10 @@ keywords: ["告警集成", "Prometheus", "监控告警", "数据接入"]
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
- 2. 选择 ** Prometheus** 集成:
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
+ 2. 选择 **Prometheus** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
4. 点击 **保存** 后,复制当前页面的新生成的 **推送地址** 备用。
@@ -162,11 +160,10 @@ VMP 的 `alertname` 标签是告警规则的 UUID,默认生成的告警标题
</Tip>
## 严重程度映射关系
----
系统依次提取告警事件标签中的 `severity`、`priority`和 `level`,对应值将作为 Prometheus 自身的告警等级。如果都没有提取到,再读取 VMP 的 `internal_label_alert_level` 标签:`P0` 对应 Critical,`P1` 对应 Warning,`P2` 对应 Info。仍未提取到时,系统自动设置 Prometheus 告警等级为 `Warning`。
-Promtheus 到 Flashduty On-call 告警等级映射关系:
+Prometheus 到 Flashduty On-call 告警等级映射关系:
| Prometheus | Flashduty | 状态 |
| ------------ | -------- | ---- |
@@ -180,7 +177,6 @@ Promtheus 到 Flashduty On-call 告警等级映射关系:
| ok | Ok | 恢复 |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么在Flashduty没有收到告警?">
@@ -192,7 +188,7 @@ Promtheus 到 Flashduty On-call 告警等级映射关系:
#### 在 AlertManager
- 1. 首先确认 AlertManager 测是否产生了新的告警。如没有产生新告警,请继续等待新告警触发后重新验证。
+ 1. 首先确认 AlertManager 侧是否产生了新的告警。如没有产生新告警,请继续等待新告警触发后重新验证。
2. 打开 AlertManager 配置文件,如果您设置了子路由,请确保您的路由设置正确(比如前边的路由设置了 continue,AlertManager 会跳过匹配后续子路由。我们推荐您永远仅设置一个默认路由到 Flashduty On-call)。同时验证,目标回调地址是否和集成推送地址完全匹配。如果不匹配,请修改 **告警规则**后重新验证。
3. 如果匹配,请继续确认 AlertManager 实例可以访问外网 api.flashcat.cloud 域名。如果不可以,您首先需要为其开通外网,或单独针对 Flashduty On-call 的域名开通外网访问。
4. 如果网络无问题,您需要继续排查 AlertManager,查找是否存在相关的错误日志。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/prtg.mdx b/zh/on-call/integration/alert-integration/alert-sources/prtg.mdx
index 7cab1511..19592ab8 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/prtg.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/prtg.mdx
@@ -1,5 +1,6 @@
---
title: "PRTG 告警集成"
+sidebarTitle: "PRTG"
description: "通过 Execute HTTP Action 通知模板将 PRTG Network Monitor 传感器的告警和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "PRTG", "Paessler", "PRTG Network Monitor", "PRTG Hosted Monitor", "Execute HTTP Action", "通知模板", "sensorid"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "PRTG", "Paessler", "PRTG Network Monitor", "PRTG Hos
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "PRTG", "Paessler", "PRTG Network Monitor", "PRTG Hos
</div>
## 在 PRTG 中配置
----
PRTG 需要两个通知模板:一个在传感器进入告警状态时发送(`event=trigger`),一个在传感器离开该状态时发送(`event=resolve`)。两个模板的推送地址和字段完全相同,只有开头的 `event` 不同。
@@ -41,19 +40,19 @@ PRTG 需要两个通知模板:一个在传感器进入告警状态时发送(
2. **Template Name** 填写 `Flashduty 告警`
3. 勾选 **Execute HTTP Action**,按下表填写:
-| 设置项 | 值 |
-| :--- | :--- |
-| **URL** | Flashduty 集成的完整推送地址 |
-| **SNI Handling** | **Send SNI** |
-| **SNI Name** | 推送地址中的域名,例如 `api.flashcat.cloud` |
-| **HTTP Method** | **POST** |
-| **Payload** | 下方的告警模板,保持为一行 |
+ | 设置项 | 值 |
+ | :--- | :--- |
+ | **URL** | Flashduty 集成的完整推送地址 |
+ | **SNI Handling** | **Send SNI** |
+ | **SNI Name** | 推送地址中的域名,例如 `api.flashcat.cloud` |
+ | **HTTP Method** | **POST** |
+ | **Payload** | 下方的告警模板,保持为一行 |
-告警模板:
+ 告警模板:
-```text
-event=trigger&sensorid=%sensorid&laststatus=%laststatus&sensor=%sensor&device=%device&deviceid=%deviceid&group=%group&probe=%probe&host=%host&priority=%priority&linksensor=%linksensor&tags=%tags&sitename=%sitename&lastvalue=%lastvalue&message=%message
-```
+ ```text
+ event=trigger&sensorid=%sensorid&laststatus=%laststatus&sensor=%sensor&device=%device&deviceid=%deviceid&group=%group&probe=%probe&host=%host&priority=%priority&linksensor=%linksensor&tags=%tags&sitename=%sitename&lastvalue=%lastvalue&message=%message
+ ```
4. 点击 **Create** 保存
@@ -76,11 +75,11 @@ event=resolve&sensorid=%sensorid&laststatus=%laststatus&sensor=%sensor&device=%d
1. 打开要接入的对象(根组 Root、某个组、设备或传感器),进入 **Notification Triggers** 标签页,选择 **Add State Trigger**
2. 按下表填写:
-| 设置项 | 值 |
-| :--- | :--- |
-| **When sensor status is** | **Down**,**for at least** `60` **seconds** |
-| **perform** | `Flashduty 告警` |
-| **When sensor status is no longer Down, perform** | `Flashduty 恢复` |
+ | 设置项 | 值 |
+ | :--- | :--- |
+ | **When sensor status is** | **Down**,**for at least** `60` **seconds** |
+ | **perform** | `Flashduty 告警` |
+ | **When sensor status is no longer Down, perform** | `Flashduty 恢复` |
3. 保存触发器。下级的组、设备和传感器会继承这个触发器
@@ -100,7 +99,6 @@ event=resolve&sensorid=%sensorid&laststatus=%laststatus&sensor=%sensor&device=%d
</Warning>
## 推送内容
----
PRTG 以 `application/x-www-form-urlencoded` 表单格式 POST 模板中的字段,每个字段名对应同名的 PRTG 占位符:
@@ -125,14 +123,12 @@ PRTG 以 `application/x-www-form-urlencoded` 表单格式 POST 模板中的字
告警标题为 `<设备名称>: <传感器名称>`;设备名称为空时只用传感器名称,两者都为空时使用 `PRTG sensor <sensorid>`。
## Alert Key
----
Flashduty 使用 `sensorid` 作为 Alert Key。同一个传感器的告警、升级通知和恢复通知携带相同的传感器 ID,因此会落在同一条告警上;同一设备上名称相同的两个传感器 ID 不同,会生成不同的告警。修改传感器名称、设备名称、状态或消息不会改变 Alert Key。
传感器 ID 只在一台 PRTG 服务器内唯一。多台 PRTG 服务器请分别使用不同的 Flashduty 集成,避免不同服务器上相同 ID 的传感器合并到同一条告警。
## 状态和告警等级
----
`event` 决定告警触发还是恢复,`laststatus` 决定告警等级:
@@ -147,7 +143,6 @@ Flashduty 使用 `sensorid` 作为 Alert Key。同一个传感器的告警、升
`event` 为空或为其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么需要两个通知模板?">
@@ -182,7 +177,6 @@ PRTG 不认识的占位符会原样发送。`%laststatus` 需要 PRTG 20.1.57
</AccordionGroup>
## 排查问题
----
- **PRTG 推送失败**:确认 URL 是完整的推送地址,且包含 `integration_key`;HTTP Method 为 POST
- **Flashduty 返回参数错误**:确认 Payload 完整粘贴了模板,`event` 和 `sensorid` 都在,且模板保持为一行
diff --git a/zh/on-call/integration/alert-integration/alert-sources/pulsetic.mdx b/zh/on-call/integration/alert-integration/alert-sources/pulsetic.mdx
index 7b54ea76..79525976 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/pulsetic.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/pulsetic.mdx
@@ -1,5 +1,6 @@
---
title: "Pulsetic 告警集成"
+sidebarTitle: "Pulsetic"
description: "通过 Pulsetic 监控项的 Webhook 通知,将网站宕机、恢复和 SSL 证书即将过期的告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Pulsetic", "Uptime", "网站监控", "Webhook", "monitor_offline", "monitor_online"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Pulsetic", "Uptime", "网站监控", "Webhook", "mon
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Pulsetic", "Uptime", "网站监控", "Webhook", "mon
</div>
## 在 Pulsetic 中配置
----
<Steps>
<Step title="打开监控项的 Webhook 设置">
@@ -61,7 +60,6 @@ keywords: ["告警集成", "Pulsetic", "Uptime", "网站监控", "Webhook", "mon
</Steps>
## 推送内容
----
Pulsetic 以 JSON 格式 POST 以下字段,Flashduty 直接解析,无需配置模板:
@@ -80,7 +78,6 @@ Pulsetic 以 JSON 格式 POST 以下字段,Flashduty 直接解析,无需配
告警标题使用监控项名称;名称为空时使用被监控地址。
## Alert Key
----
Flashduty 使用 `monitor.id` 作为宕机和恢复告警的 Alert Key。同一个监控项的宕机、重复宕机和恢复通知携带相同的 `monitor.id`,因此会落在同一条告警上;修改监控项的名称、地址或标签不会改变 Alert Key。
@@ -89,7 +86,6 @@ SSL 证书即将过期通知使用 `alert_type` 加 `monitor.id` 生成独立的
请求中缺少 `monitor.id` 时,Flashduty 会返回参数错误,因为无法把恢复通知关联到原告警。
## 状态和告警等级
----
Pulsetic 的通知不区分告警等级,Flashduty 按下表处理:
@@ -102,7 +98,6 @@ Pulsetic 的通知不区分告警等级,Flashduty 按下表处理:
其他 `alert_type`(例如 Pulsetic 日后新增的类型)会被确认并忽略,不创建告警。
## 常见问题
----
<AccordionGroup>
<Accordion title="SSL 证书过期告警不会自动关闭吗?">
@@ -125,7 +120,6 @@ Pulsetic 按监控项设置的检查间隔探测,并可在 **Intervals** 中
</AccordionGroup>
## 排查问题
----
- **Pulsetic 没有推送**:确认监控项的 Alerts → Webhook 已保存,且 Webhook URL 是包含 `integration_key` 的完整推送地址
- **Flashduty 返回参数错误**:确认请求体包含 `alert_type` 和 `monitor.id`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/pulseway.mdx b/zh/on-call/integration/alert-integration/alert-sources/pulseway.mdx
index edc80b7e..4b9e5f0c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/pulseway.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/pulseway.mdx
@@ -1,5 +1,6 @@
---
title: "Pulseway 告警集成"
+sidebarTitle: "Pulseway"
description: "通过 Pulseway 通知 Webhook 将 RMM 设备通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Pulseway", "RMM", "远程监控", "通知 Webhook", "Webhook"]
---
@@ -9,7 +10,6 @@ Pulseway 是面向 IT 团队和 MSP 的远程监控与管理(RMM)平台。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Pulseway 是面向 IT 团队和 MSP 的远程监控与管理(RMM)平台。
</div>
## 在 Pulseway 中配置
----
Pulseway 的通知 Webhook 通过 REST API 创建,一个 Webhook 覆盖所选组织下的全部设备,无需在设备上安装任何组件。
@@ -85,12 +84,10 @@ Pulseway 通知是一次性事件:问题消除后 Pulseway 不会推送恢复
</Steps>
## Alert Key
----
Flashduty 使用通知的 `Id` 作为 Alert Key,每条通知各自产生一条告警。同一问题持续存在时,Pulseway 会再次发出通知,新的通知有新的 `Id`,因此会产生新的告警;这些告警可以在协作空间中按规则聚合到同一个故障。设备恢复在线等情况在 Pulseway 中是另一条通知,不会关闭之前的告警。
## 告警等级
----
| Pulseway `Priority` | Flashduty 告警等级 |
| :--- | :--- |
@@ -103,7 +100,6 @@ Flashduty 使用通知的 `Id` 作为 Alert Key,每条通知各自产生一条
优先级不区分大小写。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -117,7 +113,6 @@ Flashduty 使用通知的 `Id` 作为 Alert Key,每条通知各自产生一条
告警标题为通知的 `Title`,描述为通知的 `Message`。
## 常见问题
----
<AccordionGroup>
diff --git a/zh/on-call/integration/alert-integration/alert-sources/raritan-px.mdx b/zh/on-call/integration/alert-integration/alert-sources/raritan-px.mdx
index 98456a52..760a62da 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/raritan-px.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/raritan-px.mdx
@@ -1,5 +1,6 @@
---
title: "Raritan PX PDU 告警集成"
+sidebarTitle: "Raritan PX PDU"
description: "Raritan PX 系列 PDU 通过事件规则发送邮件通知,使用 Flashduty 的邮件集成按规则触发和关闭 PDU 告警。"
keywords: ["告警集成", "Raritan", "Raritan PX", "PX3", "PDU", "邮件", "Email", "机房环境监控"]
---
@@ -9,7 +10,6 @@ Raritan PX 系列 PDU 通过事件规则中的 **Send email** 动作发送邮件
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成邮件地址,任选其一即可。**集成类型都选择邮件 Email**,不是 Raritan。
@@ -30,7 +30,6 @@ Raritan PX 系列 PDU 通过事件规则中的 **Send email** 动作发送邮件
</div>
## 在 Flashduty 中配置推送规则
----
下面的主题格式把设备名、事件规则名和断言标志放进标题。断言标志 `1` 表示事件条件成立,`0` 表示事件条件解除。规则从标题提取设备名和事件规则名作为 Alert Key,触发和恢复邮件的这两部分相同,恢复邮件因此能关闭对应的告警。
@@ -55,7 +54,6 @@ Raritan PX 系列 PDU 通过事件规则中的 **Send email** 动作发送邮件
关闭规则排在触发规则前面。默认规则选丢弃,是为了让不符合主题格式的邮件(例如其他事件规则发出的默认邮件)不生成无法自动关闭的告警。
## 在 Raritan PX 中配置
----
以下路径来自 Raritan PX-Series PDU 用户指南(固件 4.3.11),在 PDU 的 Web 界面中操作。
@@ -63,21 +61,20 @@ Raritan PX 系列 PDU 通过事件规则中的 **Send email** 动作发送邮件
2. **创建动作**:进入 **Device Settings** → **Event Rules**,新建动作,**Action** 选择 **Send email**,在 **Recipient email addresses** 填 Flashduty 邮件集成的地址
3. **邮件主题**:勾选 **Custom subject**,填入:
-```
-Raritan PX | [DEVICENAME] | [EVENTRULENAME] | [ISASSERTED]
-```
+ ```
+ Raritan PX | [DEVICENAME] | [EVENTRULENAME] | [ISASSERTED]
+ ```
-`[DEVICENAME]`(事件发生的设备名)、`[EVENTRULENAME]`(匹配的事件规则名)、`[ISASSERTED]`(事件条件变为成立时为 1,解除时为 0)是用户指南列出的占位符,发送时会替换成实际值。渲染后的主题形如:
+ `[DEVICENAME]`(事件发生的设备名)、`[EVENTRULENAME]`(匹配的事件规则名)、`[ISASSERTED]`(事件条件变为成立时为 1,解除时为 0)是用户指南列出的占位符,发送时会替换成实际值。渲染后的主题形如:
-```
-Raritan PX | PX3-rack12 | Rack12 temperature high | 1
-```
+ ```
+ Raritan PX | PX3-rack12 | Rack12 temperature high | 1
+ ```
4. **创建事件规则**:进入 **Device Settings** → **Event Rules**,新建规则,选择要监控的事件(例如温度传感器的 **Above upper critical threshold**),**Trigger condition** 选择 **Both**,使事件发生和解除时都触发动作;在 **Available actions** 里选中第 2 步创建的 Send email 动作
5. **邮件正文**:规则只读取邮件标题,正文用默认内容或自定义内容都可以
## 限制
----
- **事件规则名要唯一**:Alert Key 由设备名和事件规则名组成,多个事件共用同一个规则名时会合并到同一条告警。每个要监控的事件建一条独立的事件规则,并起不同的规则名。
- **触发条件**:**Trigger condition** 选择 **Asserted** 时只有触发邮件,没有恢复邮件,告警不会自动关闭。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/raygun.mdx b/zh/on-call/integration/alert-integration/alert-sources/raygun.mdx
index 176d876b..22432ac9 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/raygun.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/raygun.mdx
@@ -1,5 +1,6 @@
---
title: "Raygun 告警集成"
+sidebarTitle: "Raygun"
description: "通过 Webhook 将 Raygun Crash Reporting 应用的错误通知和状态变更同步到 Flashduty On-call。"
keywords: ["告警集成", "Raygun", "Webhook", "错误监控", "Crash Reporting"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Raygun", "Webhook", "错误监控", "Crash Reporting
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Raygun", "Webhook", "错误监控", "Crash Reporting
</div>
## 在 Raygun 中配置
----
Webhook 集成按应用配置,只有 Raygun 的 Team 及更高套餐提供。多个应用需要分别配置,可以使用同一个推送地址。
@@ -75,14 +74,12 @@ Webhooks 集成没有测试按钮,请用真实错误验证:
</Note>
## Alert Key
----
Flashduty 按 Raygun 错误组聚合告警:同一错误组的新增、复发、跟进和解决通知归入同一条告警。
Alert Key 由事件中的 `error.url`(Raygun 中错误组页面的链接)计算,只取链接的路径,协议、域名、末尾斜杠和查询参数都不参与计算。错误消息、发生次数、影响用户数和标签变化不会改变 Alert Key。缺少 `error.url` 的事件会被拒绝。
## 状态和告警等级
----
Raygun 的错误不携带等级,Flashduty 统一使用 Warning:
@@ -92,7 +89,6 @@ Raygun 的错误不携带等级,Flashduty 统一使用 Warning:
| `StatusChanged`,`status` 为 `resolved` 或 `archived`(不区分大小写) | 恢复 | - |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -108,7 +104,6 @@ Raygun 的错误不携带等级,Flashduty 统一使用 Warning:
受影响用户的标识、自定义数据(`customData`)和操作人姓名不会写入标签。
## 排查问题
----
- **集成列表中没有 Webhooks**:确认账号的套餐为 Team 或更高,或处于试用期
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,并且配置的是应用级 Webhook,而不是 Alerting 中的 Webhook
diff --git a/zh/on-call/integration/alert-integration/alert-sources/rbltracker.mdx b/zh/on-call/integration/alert-integration/alert-sources/rbltracker.mdx
index db89640e..a6561ed9 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/rbltracker.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/rbltracker.mdx
@@ -1,5 +1,6 @@
---
title: "RBLTracker 告警集成"
+sidebarTitle: "RBLTracker"
description: "通过 Webhook 将 RBLTracker(Generator Labs)的黑名单收录、证书到期与异常、监控探针超时事件同步到 Flashduty On-call。"
keywords: ["告警集成", "RBLTracker", "Generator Labs", "黑名单", "RBL", "证书监控", "Webhook"]
---
@@ -15,7 +16,6 @@ RBLTracker(Generator Labs)监控邮件服务器 IP 或域名是否被收录
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -36,7 +36,6 @@ RBLTracker(Generator Labs)监控邮件服务器 IP 或域名是否被收录
</div>
## 在 RBLTracker 中配置
----
<Steps>
<Step title="添加 Webhook">
@@ -80,7 +79,6 @@ Send Test 会用占位对象(主机 `Test Host`、地址 `127.0.0.2`,证书
</Steps>
## Alert Key
----
Flashduty 用 RBLTracker 事件中对象的 SID 作为 Alert Key,并按事件类别加前缀:
@@ -98,7 +96,6 @@ RBLTracker 官方 API 文档中,同一台主机的 `rbl.host.listed` 与 `rbl.
主机名称、命中的黑名单数量、检查 SID(`check_sid`)和事件 SID(`event_sid`)的变化都不会改变 Alert Key。缺少对应 SID 的事件会被拒绝。
## 状态和告警等级
----
告警状态由事件类型决定,恢复事件见上表。RBLTracker 不发送告警等级,Flashduty 按事件类型设置:
@@ -113,12 +110,10 @@ RBLTracker 官方 API 文档中,同一台主机的 `rbl.host.listed` 与 `rbl.
| `agent.timeout` | Warning | 探针停止上报,监控出现盲区 |
## 一次性事件的自动关闭
----
`cert.changed` 是单次通知,RBLTracker 不会发送对应的恢复事件。同一监控项每次证书替换都会产生一条独立告警,这些告警不会自动恢复。请开启协作空间的[超时自动关闭](/zh/on-call/channel/create-edit),建议设置为 **24 小时**。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -140,14 +135,12 @@ RBLTracker 官方 API 文档中,同一台主机的 `rbl.host.listed` 与 `rbl.
| `instances` | 超时的探针实例标识 |
## 推送与重试
----
RBLTracker 以 `application/json` POST 推送,Flashduty 返回 2xx 视为成功。推送失败(非 2xx、超时或连接错误)会在 30 秒和 2 分钟后各重试一次,重试使用相同的事件 SID,不会产生重复告警。连续失败达到 10、20、30 次时 RBLTracker 会分别暂停推送 1 小时、6 小时、1 天,达到 40 次会停用该 Webhook,需要在 **Development → Webhooks** 中重新启用。
RBLTracker 会在每次推送中带上 `X-Webhook-Signature` 签名头。Flashduty 通过推送地址中的 `integration_key` 鉴权,不校验该签名头。
## 排查问题
----
- **RBLTracker 显示推送失败**:确认 URL 完整且包含 `integration_key`,并在 **Send Test** 的结果中查看响应状态码
- **Flashduty 返回参数错误**:请求体必须是 RBLTracker 的 JSON 推送,缺少 `host.sid`、`monitor.sid` 或 `agent.sid` 的事件会被拒绝
diff --git a/zh/on-call/integration/alert-integration/alert-sources/red-hat-openshift.mdx b/zh/on-call/integration/alert-integration/alert-sources/red-hat-openshift.mdx
index 188fa267..af5c6b2a 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/red-hat-openshift.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/red-hat-openshift.mdx
@@ -1,15 +1,15 @@
---
title: "Red Hat OpenShift 告警集成"
+sidebarTitle: "Red Hat OpenShift"
description: "通过 OpenShift 监控内置 Alertmanager 的 Webhook 接收器,使用 Flashduty 的 Prometheus 集成接收 OpenShift 集群告警,恢复时自动关闭告警。"
keywords: ["告警集成", "Red Hat OpenShift", "OpenShift", "Alertmanager", "Webhook", "Prometheus", "Kubernetes"]
---
-OpenShift Container Platform 的监控栈自带 Alertmanager(`openshift-monitoring` 项目中的 `alertmanager-main`)。官方文档列出的接收器类型包括 PagerDuty、Webhook、Email、Slack 和 Microsoft Teams,并说明上游 Alertmanager 支持的配置项在 OpenShift 中同样支持。Webhook 接收器向你填写的地址发送 Alertmanager 格式的 JSON(`version` 为 `4`,每条告警带 `status`、`labels`、`annotations`、`startsAt`、`endsAt`、`generatorURL`、`fingerprint`)。Flashduty 的 [Prometheus 集成](/zh/on-call/integration/alert-integration/alert-sources/prometheus) 与该格式兼容,因此不需要单独的 OpenShift 集成:在 Flashduty 创建 Prometheus 集成,把它的推送地址配置为 OpenShift Alertmanager 的 Webhook 接收器。
+OpenShift Container Platform 的监控栈自带 Alertmanager(`openshift-monitoring` 项目中的 `alertmanager-main`)。官方文档列出的接收器类型包括 PagerDuty、Webhook、Email、Slack 和 Microsoft Teams,并说明上游 Alertmanager 支持的配置项在 OpenShift 中同样支持。Webhook 接收器向您填写的地址发送 Alertmanager 格式的 JSON(`version` 为 `4`,每条告警带 `status`、`labels`、`annotations`、`startsAt`、`endsAt`、`generatorURL`、`fingerprint`)。Flashduty 的 [Prometheus 集成](/zh/on-call/integration/alert-integration/alert-sources/prometheus) 与该格式兼容,因此不需要单独的 OpenShift 集成:在 Flashduty 创建 Prometheus 集成,把它的推送地址配置为 OpenShift Alertmanager 的 Webhook 接收器。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 Prometheus**,不是 Red Hat OpenShift。
@@ -30,7 +30,6 @@ OpenShift Container Platform 的监控栈自带 Alertmanager(`openshift-monito
</div>
## 在 OpenShift 中配置
----
OpenShift 官方文档提供两种方式配置接收器,任选其一。操作需要 `cluster-admin` 权限。
@@ -57,26 +56,26 @@ OpenShift 官方文档提供两种方式配置接收器,任选其一。操作
2. 在 `alertmanager.yaml` 中加入接收器和路由。下面的示例在默认配置的基础上增加 `flashduty` 接收器,并把 `severity` 为 `critical` 或 `warning` 的告警路由到它;`send_resolved` 在 Alertmanager 的 Webhook 配置中默认为 `true`,写出来是为了保证恢复通知不被关闭:
-```yaml
-receivers:
-- name: default
-- name: watchdog
-- name: flashduty
- webhook_configs:
- - url: https://api.flashcat.cloud/event/push/alert/prometheus?integration_key=<集成密钥>
- send_resolved: true
-route:
- routes:
- - matchers:
- - "alertname=Watchdog"
- repeat_interval: 2m
- receiver: watchdog
- - matchers:
- - "severity=~critical|warning"
- receiver: flashduty
-```
-
- 把 `<集成密钥>` 换成你的 Flashduty 集成密钥。新增路由放在 `Watchdog` 路由之后:Watchdog 是持续触发的心跳告警,OpenShift 文档说明它用于检查通知链路,不应作为故障告警进入 Flashduty。
+ ```yaml
+ receivers:
+ - name: default
+ - name: watchdog
+ - name: flashduty
+ webhook_configs:
+ - url: https://api.flashcat.cloud/event/push/alert/prometheus?integration_key=<集成密钥>
+ send_resolved: true
+ route:
+ routes:
+ - matchers:
+ - "alertname=Watchdog"
+ repeat_interval: 2m
+ receiver: watchdog
+ - matchers:
+ - "severity=~critical|warning"
+ receiver: flashduty
+ ```
+
+ 把 `<集成密钥>` 换成您的 Flashduty 集成密钥。新增路由放在 `Watchdog` 路由之后:Watchdog 是持续触发的心跳告警,OpenShift 文档说明它用于检查通知链路,不应作为故障告警进入 Flashduty。
3. 用修改后的文件替换 Secret:
@@ -94,7 +93,6 @@ route:
</Steps>
## 字段映射
----
| OpenShift Alertmanager 字段 | Flashduty |
| :--- | :--- |
@@ -109,14 +107,12 @@ route:
一次通知可以包含多条告警,Flashduty 逐条处理(单次最多 100 条)。
## 恢复与去重
----
- Alertmanager 的 Webhook 接收器 `send_resolved` 默认为 `true`。恢复时发送 `status` 为 `resolved` 的通知,Flashduty 按相同的 `fingerprint` 关闭对应告警。
- 如果在 **Show advanced configuration** 中关闭了恢复通知(或在 YAML 中设置 `send_resolved: false`),Flashduty 不会收到恢复请求,请在协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit)。
- Alertmanager 会按 `repeat_interval` 重复发送仍在触发的告警,Flashduty 按 `fingerprint` 去重,不会产生重复告警。
## 排查问题
----
- **Flashduty 返回 `Invalid parameters`**:推送地址不完整,缺少 `integration_key`,或集成类型不是 Prometheus
- **告警没有恢复**:确认接收器没有关闭 `send_resolved`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/redash.mdx b/zh/on-call/integration/alert-integration/alert-sources/redash.mdx
index f3a1bd45..5d62030c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/redash.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/redash.mdx
@@ -1,5 +1,6 @@
---
title: "Redash 告警集成"
+sidebarTitle: "Redash"
description: "通过 Redash 的 Webhook 告警目的地,将查询告警的触发和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Redash", "Webhook", "查询告警", "数据分析"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Redash", "Webhook", "查询告警", "数据分析"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Redash", "Webhook", "查询告警", "数据分析"]
</div>
## 在 Redash 中配置
----
需要 Redash 管理员权限创建告警目的地,Redash 服务器需要能访问 Flashduty 推送地址。
@@ -66,14 +65,12 @@ Redash 的 Webhook 目的地没有测试按钮。
</Steps>
## Alert Key
----
Flashduty 使用 Redash 告警的 ID(`alert.id`)作为 Alert Key,同一个 Redash 告警的触发、重复通知和恢复使用同一个 Alert Key。告警名称、条件、阈值、状态等字段变化不会改变 Alert Key。缺少 `alert.id` 的请求会被拒绝。
同一个 Flashduty 集成请只接入一个 Redash 实例;不同 Redash 实例的告警 ID 会重复,请分别创建集成。
## 状态和告警等级
----
Redash 的通知不携带等级,Flashduty 按告警状态处理:
@@ -86,7 +83,6 @@ Redash 的通知不携带等级,Flashduty 按告警状态处理:
`unknown` 表示查询暂无数据可供评估。Redash 只在状态变化,或触发状态下超过重复通知间隔时发送通知;告警第一次评估就是 `OK` 时不发送通知。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -98,7 +94,6 @@ Redash 的通知不携带等级,Flashduty 按告警状态处理:
| `alert_url` / `query_url` | Redash 中告警和查询页面的链接 |
## 排查问题
----
- **Flashduty 没收到告警**:确认告警已添加 Webhook 目的地、告警没有被静音(Muted),查询已发布且按刷新计划运行(自建时 worker 需要消费 `periodic` 和 `scheduled_queries` 队列,默认配置已包含);Redash 请求超时为 5 秒,失败后不重试,只在 Redash 日志中记录
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor.mdx b/zh/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor.mdx
index 099764a7..3b1c6988 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor.mdx
@@ -1,5 +1,6 @@
---
title: "Redgate SQL Monitor 告警集成"
+sidebarTitle: "Redgate SQL Monitor"
description: "通过 Webhook 将 Redgate Monitor(原 SQL Monitor)的告警同步到 Flashduty On-call,告警结束时自动恢复。"
keywords: ["告警集成", "Redgate", "SQL Monitor", "Redgate Monitor", "SQL Server", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Redgate", "SQL Monitor", "Redgate Monitor", "SQL Ser
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Redgate", "SQL Monitor", "Redgate Monitor", "SQL Ser
</div>
## 在 Redgate Monitor 中配置
----
Webhook 通知在 Redgate Monitor 的 Web 控制台中配置,对该 Base Monitor 产生的所有告警生效,需要管理员权限。Base Monitor 服务所在的机器需要能访问 Flashduty 的推送地址。
@@ -65,12 +64,10 @@ Webhook 通知在 Redgate Monitor 的 Web 控制台中配置,对该 Base Monit
</Note>
## Alert Key
----
Redgate Monitor 的告警 ID(`id`)只在单个 Base Monitor 内唯一,因此 Flashduty 使用 Base Monitor 标识(`baseMonitorGuid`)和告警 ID(`id`)共同计算 Alert Key。同一条告警的 Raised、Escalated、DeEscalated、Ended 消息使用同一个 Alert Key,多个 Base Monitor 推送到同一个集成时也不会互相合并。告警名称、等级、描述、时间等字段变化不会改变 Alert Key。缺少 `id` 或 `baseMonitorGuid` 的消息会被拒绝。
## 状态和告警等级
----
| `statusChange` | 含义 | Flashduty 状态 |
| :--- | :--- | :--- |
@@ -88,7 +85,6 @@ Redgate Monitor 的告警 ID(`id`)只在单个 Base Monitor 内唯一,因
`Ended` 消息的 `severity` 为 `None`,Flashduty 使用 `previousSeverity`(告警结束前的等级)作为恢复事件的等级。等级为空或无法识别时按 Warning 处理。`messageType` 不是 `AlertNotification` 的消息不会创建告警,Flashduty 收到后直接返回成功。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -109,7 +105,6 @@ Redgate Monitor 的告警 ID(`id`)只在单个 Base Monitor 内唯一,因
告警描述为 Redgate Monitor 的告警类型说明;自定义指标配置了辅助查询时,附带其返回的详细信息(`alertDetailText`)。
## 排查问题
----
- **测试消息发送失败**:确认 Base Monitor 所在机器能访问 Flashduty 推送地址,需要代理时按上文配置代理
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,并且消息格式选择的是默认消息
diff --git a/zh/on-call/integration/alert-integration/alert-sources/rizhiyi.mdx b/zh/on-call/integration/alert-integration/alert-sources/rizhiyi.mdx
index 18f5f708..3f05a9fc 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/rizhiyi.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/rizhiyi.mdx
@@ -1,5 +1,6 @@
---
title: "日志易告警集成"
+sidebarTitle: "日志易"
description: "通过自定义告警插件将日志易告警事件推送到 Flashduty,实现告警事件自动化降噪处理"
keywords: ["告警集成", "日志易", "日志监控", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "日志易", "日志监控", "监控告警", "数据
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
@@ -16,7 +16,7 @@ keywords: ["告警集成", "日志易", "日志监控", "监控告警", "数据
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "日志易", "日志监控", "监控告警", "数据
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **日志易** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,7 +45,6 @@ keywords: ["告警集成", "日志易", "日志监控", "监控告警", "数据
</div>
## 在日志易
----
日志易告警支持邮件、syslog、告警转发和自定义告警插件等通知方式。其中「告警转发」推送的 JSON 结构是日志易的固定格式,与 Flashduty 要求的事件格式不一致,因此请通过 **自定义告警插件**(Python 脚本)将告警转换为标准格式后推送到 Flashduty。
@@ -136,7 +135,6 @@ def execute_reply(params, alert):
</Note>
## 严重程度映射关系
----
<div className="md-block">
@@ -154,7 +152,6 @@ def execute_reply(params, alert):
</div>
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么在 Flashduty 没有收到告警?">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/robotalp.mdx b/zh/on-call/integration/alert-integration/alert-sources/robotalp.mdx
index 8b747fb9..cc31f926 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/robotalp.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/robotalp.mdx
@@ -1,5 +1,6 @@
---
title: "Robotalp 告警集成"
+sidebarTitle: "Robotalp"
description: "通过 Robotalp 的自定义 Webhook,把监控项的宕机和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Robotalp", "网站监控", "Uptime", "Webhook"]
---
@@ -9,7 +10,6 @@ Robotalp 是在线监控服务。监控项检测到宕机或恢复时,可以
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Robotalp 是在线监控服务。监控项检测到宕机或恢复时,可以
</div>
## 在 Robotalp 中配置
----
<Steps>
<Step title="添加自定义 Webhook 集成">
@@ -67,7 +66,6 @@ Robotalp 是在线监控服务。监控项检测到宕机或恢复时,可以
</Steps>
## Alert Key
----
Flashduty 用请求体里的 `incident_id` 作为 Alert Key。Robotalp 对同一次宕机的宕机通知和恢复通知发送相同的 `incident_id`,我们在真实的 Robotalp 上验证过:同一个监控项先宕机、后恢复,两次推送的 `incident_id` 一致。
@@ -76,7 +74,6 @@ Flashduty 用请求体里的 `incident_id` 作为 Alert Key。Robotalp 对同一
- 缺少 `incident_id` 的请求会被拒绝,因为无法可靠关联后续恢复
## 状态和告警等级
----
Robotalp 的请求体没有告警等级字段,只有 `status`。
@@ -88,7 +85,6 @@ Robotalp 的请求体没有告警等级字段,只有 `status`。
其他值会被拒绝。恢复事件会带上 `resolved_at` 和 `downtime_seconds`,Flashduty 将它们和宕机原因 `result_message` 一起保存为标签。
## 排查问题
----
- **Flashduty 没有收到事件**:确认 Webhook 已在监控项的 **Notification Preferences** 中启用,且推送地址完整并包含 `integration_key`
- **告警没有恢复**:确认没有在 **Custom payload** 中覆盖 `incident_id` 或 `status`;如果监控项被暂停或删除,Robotalp 不会发送恢复通知,需要手动关闭告警,也可以在协作空间中开启告警自动关闭作为兜底
diff --git a/zh/on-call/integration/alert-integration/alert-sources/robusta.mdx b/zh/on-call/integration/alert-integration/alert-sources/robusta.mdx
index fa7bdf82..c30d58cd 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/robusta.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/robusta.mdx
@@ -1,5 +1,6 @@
---
title: "Robusta 告警集成"
+sidebarTitle: "Robusta"
description: "通过 Robusta 的 Webhook Sink 将 Kubernetes 集群中的 Robusta 告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Robusta", "Kubernetes", "K8s", "Prometheus", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Robusta", "Kubernetes", "K8s", "Prometheus", "Webhoo
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Robusta", "Kubernetes", "K8s", "Prometheus", "Webhoo
</div>
## 在 Robusta 中配置
----
<Steps>
<Step title="添加 Webhook Sink">
@@ -74,7 +73,6 @@ Robusta 自己检测到的问题(`source` 为 `KUBERNETES_API_SERVER` 等)
</Tip>
## Alert Key
----
Flashduty 用 `cluster_name` 加 `fingerprint` 计算 Alert Key。
@@ -84,7 +82,6 @@ Flashduty 用 `cluster_name` 加 `fingerprint` 计算 Alert Key。
标题、描述、等级、时间和事件 ID 的变化都不会改变 Alert Key。请求缺少 `fingerprint` 时 Flashduty 会拒绝,因为无法关联后续通知。
## 状态和告警等级
----
当请求中的 `ends_at` 不为空,或标题以 `[RESOLVED] ` 开头时,Flashduty 将告警标记为恢复。Robusta 只为 Alertmanager 已恢复的 Prometheus 告警发送这类通知,请确认 Alertmanager 中 Robusta 接收器的 `send_resolved` 为 `true`(Robusta 自带的 Prometheus 默认已开启)。
@@ -98,14 +95,12 @@ Flashduty 用 `cluster_name` 加 `fingerprint` 计算 Alert Key。
Robusta 转发 Prometheus 告警时按告警的 `severity` 标签换算等级:`critical`、`high`、`medium`、`error` 为 `HIGH`,`warning`、`low` 为 `LOW`,`info` 和其他值为 `INFO`,`debug` 为 `DEBUG`。恢复通知保留最后一次的等级。
## 告警内容
----
- **标题**:`title`,恢复通知会去掉 `[RESOLVED] ` 前缀
- **描述**:`description`,`links` 中的链接(如 Prometheus 图表),以及恢复时间 `ends_at`
- **标签**:`cluster`、`fingerprint`、`aggregation_key`(告警名或问题类型)、`finding_source`(如 `PROMETHEUS`、`KUBERNETES_API_SERVER`)、`finding_type`、`severity`(Robusta 原始等级)、`resource`(`类型/命名空间/名称`)、`kind`、`namespace`、`node`、`container`、`source`(固定为 `robusta`),以及 `subject.labels` 中的资源标签和 Prometheus 告警标签(如 `alertname`、`pod`)
## 排查问题
----
- **Flashduty 返回 request body is not Robusta JSON**:`webhook_sink` 没有设置 `format: json`
- **Flashduty 返回 fingerprint is required**:确认没有开启 `slack_webhook`,且没有把 `size_limit` 调得过小
diff --git a/zh/on-call/integration/alert-integration/alert-sources/rollbar.mdx b/zh/on-call/integration/alert-integration/alert-sources/rollbar.mdx
index f1fe0140..c24628b5 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/rollbar.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/rollbar.mdx
@@ -1,5 +1,6 @@
---
title: "Rollbar 告警集成"
+sidebarTitle: "Rollbar"
description: "通过 Webhook 将 Rollbar 项目中错误条目(Item)的出现、重新激活和解决事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Rollbar", "Item", "Webhook", "错误监控"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Rollbar", "Item", "Webhook", "错误监控"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Rollbar", "Item", "Webhook", "错误监控"]
</div>
## 在 Rollbar 中配置
----
Webhook 按项目配置。需要在 Rollbar 项目中拥有修改通知设置的权限。
@@ -76,14 +75,12 @@ Webhook 设置页的 **Send Test Notification** 只验证地址可达:Flashdut
</Steps>
## Alert Key
----
Flashduty 使用 Item 的 `id`(Webhook 中的 `data.item.id`)作为 Alert Key。Rollbar 官方 Webhook 示例中,同一个 Item 的 `new_item`、`item_velocity`、`exp_repeat_item` 与 `resolved_item` 事件携带相同的 `id`;它也是 Rollbar API 中定位 Item 的 ID。
Item 地址中的数字(如 `.../items/40`)是项目内计数器 `counter`,只作为标签保留。标题、等级、环境和发生次数的变化都不会改变 Alert Key。缺少 `data.item.id` 的 Item 事件会被拒绝。
## 状态和告警等级
----
告警状态由事件名决定:`resolved_item` 为恢复,其他 Item 事件为触发。告警等级由 Item 的等级(`data.item.level`)决定:
@@ -99,7 +96,6 @@ Item 地址中的数字(如 `.../items/40`)是项目内计数器 `counter`
Rollbar 中新 Item 默认等级为 `error`。如需让某类错误以 Critical 通知,可在 Rollbar 中将 Item 等级改为 `critical`,或在 SDK 中为其指定等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -117,7 +113,6 @@ Rollbar 中新 Item 默认等级为 `error`。如需让某类错误以 Critical
| `window` / `threshold` | `item_velocity` 的时间窗口和阈值 |
## 排查问题
----
- **Rollbar 显示推送失败**:确认 URL 完整且包含 `integration_key`,并在规则的 **History** 中查看每次推送的结果。Rollbar 会对失败的推送重试,持续失败的规则会被自动停用,修复后需在 Webhook 设置页重新启用
- **Flashduty 返回参数错误**:确认规则的 Payload 格式为 JSON
diff --git a/zh/on-call/integration/alert-integration/alert-sources/rum-alert.mdx b/zh/on-call/integration/alert-integration/alert-sources/rum-alert.mdx
index 42729cb2..b41cd6bc 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/rum-alert.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/rum-alert.mdx
@@ -1,5 +1,6 @@
---
title: "RUM 告警集成"
+sidebarTitle: "RUM"
description: "Flashduty RUM 告警集成,RUM 服务通过此集成上报告警"
keywords: ["告警集成", "RUM ", "监控告警", "数据接入"]
---
@@ -14,6 +15,6 @@ keywords: ["告警集成", "RUM ", "监控告警", "数据接入"]
前往`RUM`-`应用详情`-`告警设置`页面,开启告警。您可以选择将告警投递至多个协作空间。告警的通知规则遵循协作空间下的分派策略,您可以为团队设定值班人员,在告警发生时分派给值班人。
-
+
-更多内容,请您参考 [RUM Issue 告警](https://docs.flashduty.com/zh/flashduty/rum/issue-alerting)。
+更多内容,请您参考 [RUM Issue 告警](/zh/rum/error-tracking/issue-alerts)。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/searchstax.mdx b/zh/on-call/integration/alert-integration/alert-sources/searchstax.mdx
index d8f4dd17..451a6620 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/searchstax.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/searchstax.mdx
@@ -1,5 +1,6 @@
---
title: "SearchStax 告警集成"
+sidebarTitle: "SearchStax"
description: "通过 SearchStax Managed Search 的 Webhook 将指标告警同步到 Flashduty On-call,告警关闭时自动关闭 Flashduty 告警。"
keywords: ["告警集成", "SearchStax", "Managed Search", "Solr", "Webhook", "搜索服务"]
---
@@ -9,7 +10,6 @@ SearchStax Managed Search 的 Webhook 由您定义请求体:在 Webhook 的 **
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ SearchStax Managed Search 的 Webhook 由您定义请求体:在 Webhook 的 **
</div>
## 在 SearchStax 中配置
----
Webhook 和告警的管理需要 SearchStax 账号的所有者(Account Owner)、管理员(Admin)或技术联系人(Technical Contact)权限。
@@ -84,7 +83,6 @@ Payload 模板:
</Steps>
## Alert Key
----
Flashduty 使用 `alert_id`(`$ALERT_ID`)作为 Alert Key。SearchStax 把它描述为告警的内部编号,触发和关闭使用同一个 Webhook 模板,因此 `OPEN` 和 `CLOSED` 消息落在同一条 Flashduty 告警上。
@@ -93,7 +91,6 @@ SearchStax 的告警是部署级规则:一条 `host` 为 `*` 的告警规则
告警标题、指标值和时间的变化不会改变 Alert Key。请求缺少 `alert_id` 或 `alert_status`,或这两个字段仍是未替换的 `$...` 变量时,Flashduty 会拒绝该请求。
## 告警生命周期
----
Flashduty 按 `alert_status` 字段(`$ALERT_STATUS`,不区分大小写)处理消息:
@@ -105,12 +102,10 @@ Flashduty 按 `alert_status` 字段(`$ALERT_STATUS`,不区分大小写)处
其他值会被拒绝。
## 告警等级
----
SearchStax 的告警没有等级,所有告警默认为 **Warning**。如需其他等级,在推送地址后追加 `&severity=Critical`(或 `Info`)。恢复事件保留原告警的等级。
## 告警内容
----
- **标题**:告警名称(`$ALERT_TITLE`);缺少时为 `SearchStax alert <alert_id>`
- **描述**:`指标 当前值 比较符 阈值`,例如 `os.SystemCpuLoad 0.01 > 10.0`
@@ -119,7 +114,6 @@ SearchStax 的告警没有等级,所有告警默认为 **Warning**。如需其
值为空的字段不会写入标签。
## 排查问题
----
- **Flashduty 提示请求体不是合法 JSON**:确认 Payload 与模板一致,且没有开启表单编码
- **告警没有发出**:确认告警的 Webhook 下拉框已选择该 Webhook,且 Webhook 没有被 **Paused**;URL 使用 `https`,证书为自签名时才需要勾选 **Ignore SSL Validation**
diff --git a/zh/on-call/integration/alert-integration/alert-sources/securityscorecard.mdx b/zh/on-call/integration/alert-integration/alert-sources/securityscorecard.mdx
index 036ba059..7462c6c6 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/securityscorecard.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/securityscorecard.mdx
@@ -1,5 +1,6 @@
---
title: "SecurityScorecard 告警集成"
+sidebarTitle: "SecurityScorecard"
description: "通过 Rule Builder 的 Send a web request 动作,将 SecurityScorecard 的评分变化、新问题和数据泄露事件同步到 Flashduty On-call。"
keywords: ["告警集成", "SecurityScorecard", "安全评级", "Rule Builder", "Webhook", "execution_id"]
---
@@ -11,7 +12,6 @@ SecurityScorecard 的事件只在发生时发送一次,没有对应的恢复
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ SecurityScorecard 的事件只在发生时发送一次,没有对应的恢复
</div>
## 在 SecurityScorecard 中配置
----
Rule Builder 需要 SecurityScorecard 付费套餐,每个用户最多创建 25 条规则。
@@ -65,14 +64,12 @@ Rule Builder 没有发送测试请求的按钮。SecurityScorecard 每天评估
</Steps>
## Alert Key
----
Flashduty 使用 `execution_id`、`scorecard_id` 和 `trigger.type` 计算 Alert Key。SecurityScorecard 的 [Rule Builder: Webhooks](https://support.securityscorecard.com/hc/en-us/articles/360058429271-Rule-Builder-Webhooks) 说明,`execution_id` 是一次规则执行的唯一标识,请求失败重试时保持不变。因此同一次执行的重试会合并到同一条告警,不同的规则执行各自成为独立告警。
请求中缺少 `execution_id` 时,Flashduty 生成随机 Alert Key,每个请求都是一条新告警。缺少 `trigger.type` 时返回参数错误。
## 告警等级
----
| 事件(`trigger.type`) | 条件 | Flashduty 等级 |
| :--- | :--- | :--- |
@@ -83,7 +80,6 @@ Flashduty 使用 `execution_id`、`scorecard_id` 和 `trigger.type` 计算 Alert
| 评分变化(`grade_drop`)及其他事件类型 | | Warning |
## 字段映射
----
| Flashduty | SecurityScorecard 字段 |
| :--- | :--- |
@@ -94,12 +90,10 @@ Flashduty 使用 `execution_id`、`scorecard_id` 和 `trigger.type` 计算 Alert
请求中的 `retries` 和 `webhooks`(前序 Webhook 的响应)不写入告警。SecurityScorecard 将该请求体标注为 beta,问题和泄露详情的结构变化时,Flashduty 忽略无法解析的部分,仍然创建告警。
## 告警不会恢复
----
评分变化、新问题和数据泄露都是一次性事件,SecurityScorecard 不会发送恢复通知。请在接收该集成的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时,并按团队处理安全评级事件的时效调整。
## 排查问题
----
<AccordionGroup>
<Accordion title="规则触发了但没有收到告警">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/sematext.mdx b/zh/on-call/integration/alert-integration/alert-sources/sematext.mdx
index 2f900937..ef4d4c14 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/sematext.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/sematext.mdx
@@ -1,5 +1,6 @@
---
title: "Sematext 告警集成"
+sidebarTitle: "Sematext"
description: "通过 Sematext Cloud 的 Custom 通知钩子(Notification Hook),将指标、日志、Heartbeat、Experience 和 Synthetics 告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Sematext", "Webhook", "Notification Hook", "监控"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Sematext", "Webhook", "Notification Hook", "监控"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Sematext", "Webhook", "Notification Hook", "监控"]
</div>
## 在 Sematext 中配置
----
<Steps>
<Step title="创建 Custom 通知钩子">
@@ -42,29 +41,29 @@ keywords: ["告警集成", "Sematext", "Webhook", "Notification Hook", "监控"]
5. **Send data as** 选择 **Json**,**HTTP method** 选择 **Post**
6. 点击 **Add parameter**,逐行添加下表中的参数。左列是参数名,右列是值,值中的 `$` 变量由 Sematext 在发送时替换
-| 参数名 | 值 |
-| :--- | :--- |
-| `backToNormal` | `$backToNormal` |
-| `priority` | `$priority` |
-| `ruleType` | `$ruleType` |
-| `description` | `$description` |
-| `applicationId` | `$applicationId` |
-| `createTimestamp` | `$createTimestamp` |
-| `troubleshootUrl` | `$troubleshootUrl` |
-
-添加完成后,**Preview** 中的请求体应为:
-
-```json
-{
- "backToNormal": "$backToNormal",
- "priority": "$priority",
- "ruleType": "$ruleType",
- "description": "$description",
- "applicationId": "$applicationId",
- "createTimestamp": "$createTimestamp",
- "troubleshootUrl": "$troubleshootUrl"
-}
-```
+ | 参数名 | 值 |
+ | :--- | :--- |
+ | `backToNormal` | `$backToNormal` |
+ | `priority` | `$priority` |
+ | `ruleType` | `$ruleType` |
+ | `description` | `$description` |
+ | `applicationId` | `$applicationId` |
+ | `createTimestamp` | `$createTimestamp` |
+ | `troubleshootUrl` | `$troubleshootUrl` |
+
+ 添加完成后,**Preview** 中的请求体应为:
+
+ ```json
+ {
+ "backToNormal": "$backToNormal",
+ "priority": "$priority",
+ "ruleType": "$ruleType",
+ "description": "$description",
+ "applicationId": "$applicationId",
+ "createTimestamp": "$createTimestamp",
+ "troubleshootUrl": "$troubleshootUrl"
+ }
+ ```
7. 点击 **Send Test Notification**,确认请求成功,然后点击 **Save Notification Hook**
@@ -101,7 +100,6 @@ keywords: ["告警集成", "Sematext", "Webhook", "Notification Hook", "监控"]
</Note>
## Alert Key
----
Sematext 在每条告警通知中都会自动带上告警规则 ID(`ruleId`)、规则名称(`alertName`),规则设置了 Group by 时还会带上触发告警的分组标签值(`filters`,例如 `{os.host=web-01}`)。这些字段不需要在通知钩子中配置。
@@ -114,7 +112,6 @@ Alert Key 由 `ruleId` 和 `filters` 中的全部分组标签计算,标签的
带有 `alertName` 但缺少 `ruleId` 的请求会被拒绝。
## 状态和告警等级
----
`backToNormal` 为 `true` 时告警恢复,其余情况均视为触发。告警等级来自告警规则的优先级(`$priority`):
@@ -129,7 +126,6 @@ Alert Key 由 `ruleId` 和 `filters` 中的全部分组标签计算,标签的
匹配时不区分大小写。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -144,7 +140,6 @@ Alert Key 由 `ruleId` 和 `filters` 中的全部分组标签计算,标签的
| `create_timestamp` | 本次告警通知的创建时间,Unix 毫秒时间戳 |
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,**Send data as** 选择的是 **Json**
- **告警没有恢复**:确认告警规则 **Notifications** 页签中打开了 **Alert me when the value goes back to non-alert level**,通知钩子中添加了 `backToNormal` 参数且值为 `$backToNormal`,并且该分组仍在上报数据
diff --git a/zh/on-call/integration/alert-integration/alert-sources/semgrep.mdx b/zh/on-call/integration/alert-integration/alert-sources/semgrep.mdx
index d4826f38..8a8d7471 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/semgrep.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/semgrep.mdx
@@ -1,5 +1,6 @@
---
title: "Semgrep 告警集成"
+sidebarTitle: "Semgrep"
description: "通过 Webhook 将 Semgrep AppSec Platform 的新增代码扫描发现和供应链安全事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Semgrep", "Webhook", "SAST", "SCA", "代码安全", "供应链安全"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Semgrep", "Webhook", "SAST", "SCA", "代码安全",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Semgrep", "Webhook", "SAST", "SCA", "代码安全",
</div>
## 在 Semgrep 中配置
----
需要 Semgrep AppSec Platform 的管理权限。
@@ -62,7 +61,6 @@ keywords: ["告警集成", "Semgrep", "Webhook", "SAST", "SCA", "代码安全",
</Steps>
## 推送内容和告警恢复
----
Semgrep 推送三类对象,一次请求可以包含多个:
@@ -75,7 +73,6 @@ Semgrep 推送三类对象,一次请求可以包含多个:
Semgrep 只在发现首次出现时推送一次,不推送更新或已修复通知,因此 Flashduty 告警不会自动恢复。请在协作空间中开启[超时自动关闭](/zh/on-call/channel/create-edit),建议 7 天;也可以在问题修复后手动关闭。
## Alert Key
----
| 对象 | 使用的字段 |
| :--- | :--- |
@@ -85,7 +82,6 @@ Semgrep 只在发现首次出现时推送一次,不推送更新或已修复通
Alert Key 由对象类型和上表中的 ID 共同计算,同一发现重复投递会合并,数字相同的发现 ID 和事件 ID 不会互相合并。规则名称、严重程度等字段变化不会改变 Alert Key。缺少对应 ID 的对象会导致整个请求被拒绝。
## 告警等级
----
发现的 `severity` 为数字,由规则严重程度换算:
@@ -101,7 +97,6 @@ Alert Key 由对象类型和上表中的 ID 共同计算,同一发现重复投
影响到您项目的供应链事件固定为 Critical。
## 标签
----
发现:
@@ -128,7 +123,6 @@ Alert Key 由对象类型和上表中的 ID 共同计算,同一发现重复投
所有告警都带有 `source=semgrep` 和 `event_type`(`finding` 或 `supply_chain_incident`)。告警描述为规则的 `message`,不会推送代码片段。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 Webhook URL 完整且包含 `integration_key`;发现缺少 `numeric_id` 或事件缺少 `incident_id` 时也会返回该错误
- **没有收到告警**:确认策略中已添加 **Call a webhook** 动作;Semgrep 只在发现首次出现时推送,已有的发现不会重复通知
diff --git a/zh/on-call/integration/alert-integration/alert-sources/sensu.mdx b/zh/on-call/integration/alert-integration/alert-sources/sensu.mdx
index 0586330b..24b5d1ea 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/sensu.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/sensu.mdx
@@ -1,5 +1,6 @@
---
title: "Sensu Go 告警集成"
+sidebarTitle: "Sensu Go"
description: "通过 pipe 处理器将 Sensu Go 的检查事件同步到 Flashduty On-call,检查恢复时自动关闭告警。"
keywords: ["告警集成", "Sensu", "Sensu Go", "pipe handler", "处理器", "pipeline"]
---
@@ -9,7 +10,6 @@ Sensu Go 没有内置的 HTTP 处理器。本集成使用一个 pipe 处理器
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Sensu Go 没有内置的 HTTP 处理器。本集成使用一个 pipe 处理器
</div>
## 在 Sensu Go 中配置
----
以下步骤基于 Sensu Go 6.x,使用 `sensuctl` 完成,需要能在目标命名空间创建处理器、管道并修改检查的权限。
@@ -144,7 +143,6 @@ Sensu Go 没有「发送测试通知」按钮。让一个检查真正进入 WARN
</Steps>
## Alert Key
----
Flashduty 用实体所在的命名空间 `entity.metadata.namespace`、实体名 `entity.metadata.name` 和检查名 `check.metadata.name` 计算 Alert Key。同一个实体上同一个检查的触发、重复和恢复事件携带相同的这三个字段,因此落在同一条告警上。代理检查(`proxy_entity_name`)的事件以代理实体为实体,每个代理实体各自对应一条告警。
@@ -153,7 +151,6 @@ Flashduty 用实体所在的命名空间 `entity.metadata.namespace`、实体名
请求缺少 `entity` 或 `check`(例如只含指标的事件)、缺少命名空间、实体名、检查名或 `check.status` 时,Flashduty 会拒绝该请求,`curl` 以非 0 退出码结束,Sensu 后端日志中会记录处理器失败。
## 告警生命周期
----
| Sensu 事件 | Flashduty 处理 |
| :--- | :--- |
@@ -164,7 +161,6 @@ Flashduty 用实体所在的命名空间 `entity.metadata.namespace`、实体名
使用 `is_incident` 过滤器时,检查保持非 0 状态期间每次执行都会推送一次,这些事件合并到同一条告警上。
## 告警等级
----
| `check.status` | Sensu 含义 | Flashduty 等级 |
| :--- | :--- | :--- |
@@ -176,7 +172,6 @@ Flashduty 用实体所在的命名空间 `entity.metadata.namespace`、实体名
恢复事件的等级取 `check.history` 中最近一次非 0 状态对应的等级。
## 告警内容
----
- **标题**:`<实体名>: <检查名>`
- **描述**:检查输出 `check.output`,后附命名空间、状态码、`check.state` 和 `occurrences`
@@ -185,7 +180,6 @@ Flashduty 用实体所在的命名空间 `entity.metadata.namespace`、实体名
检查命令、密钥和实体的 `redact` 字段不会写入标签。
## 排查问题
----
- **Flashduty 没有收到告警**:在后端日志中搜索 `flashduty` 处理器的执行记录(`journalctl -u sensu-backend`),确认检查的 `pipelines` 中有 `flashduty`,且事件状态非 0
- **处理器报 `curl: not found`**:后端机器或容器没有安装 `curl`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/sentry.mdx b/zh/on-call/integration/alert-integration/alert-sources/sentry.mdx
index 5887d90a..7bb5e472 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/sentry.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/sentry.mdx
@@ -1,5 +1,6 @@
---
title: "Sentry 告警事件"
+sidebarTitle: "Sentry"
description: "通过 webhook 的方式同步 Sentry 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "Sentry 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "Sentry 告警事件", "监控告警", "数据接入"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "Sentry 告警事件", "监控告警", "数据接入"
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "Sentry 告警事件", "监控告警", "数据接入"
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Sentry** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,26 +46,25 @@ keywords: ["告警集成", "Sentry 告警事件", "监控告警", "数据接入"
</div>
## 在 Sentry
----
<div className="md-block">
-## 一、前置说明
+### 前置说明
Sentry 提供了两类告警机制:Issue Alerts 和 Metric Alerts。Issue Alerts 支持通过 Integrations 中的 WebHooks 实现通知功能,而 Metric Alerts 则限定于使用 Internal Integration 进行告警通知。值得注意的是 Internal Integration 不仅适用于 Metric Alerts,也兼容 Issue Alerts。鉴于 Internal Integration 的广泛适用性,我们决定统一采用这一方式,不再单独依赖 WebHooks,以此来简化告警通知的配置。
-## 二、Sentry 告警推送配置
+### Sentry 告警推送配置
-### 步骤1:添加 Flashduty Custom Integrations
+#### 步骤1:添加 Flashduty Custom Integrations
1. 登录 Sentry 管理控制台。
-2. 在左侧导航栏,找到 **Settings => Custom Integrations**。
+2. 在左侧导航栏,找到 **Settings → Custom Integrations**。
3. 点击 Create New Integration 并选择 **Internal Integration**。
4. 在编辑页面。**Name 处填写 Flashduty,WebhookURL 处复制写入集成的推送地址**。
5. 开启 **Alert Rule Action**,参考如下图配置:
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-1.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-1.png" />
-5. 在 PERMISSIONS 配置中为 **Issue & Event 配置 Read 权限** 。
+ 5. 在 PERMISSIONS 配置中为 **Issue & Event 配置 Read 权限** 。
6. 在 WEBHOOKS 配置中,勾选 **issue** ,**请不要勾选 error 和 comment**。
7. 配置完成后,点击 Save Changes 完成创建。
@@ -76,17 +75,17 @@ Sentry 提供了两类告警机制:Issue Alerts 和 Metric Alerts。Issue Aler
2. 不支持 issue 的其他事件,如 create、assigned、archived 和 unresolved。
3. 如果同时勾选了 error 和 comment ,Flashduty 并不会接收和处理这类事件。
-### 步骤2:在 Alerts 中使用 Flashduty Integration
-1. 在左侧导航栏,找到 **Alerts => Create Alert**。
+#### 步骤2:在 Alerts 中使用 Flashduty Integration
+1. 在左侧导航栏,找到 **Alerts → Create Alert**。
2. 选择要创建的 Alert 类型,如 Issue 。
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-3.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-3.png" />
3. 触发条件请按需配置。
4. 在 **THEN perform these actions 处 Add action** 并选择 **Send a notification via**。
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-4.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/doc/sentry-4.png" />
5. 通知渠道选择上面添加的 **Flashduty**。
@@ -97,7 +96,7 @@ Sentry 提供了两类告警机制:Issue Alerts 和 Metric Alerts。Issue Aler
</div>
-## 三、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/sevone.mdx b/zh/on-call/integration/alert-integration/alert-sources/sevone.mdx
index 2897c9d8..1d3d3d9b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/sevone.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/sevone.mdx
@@ -1,5 +1,6 @@
---
title: "IBM SevOne NPM 告警集成"
+sidebarTitle: "IBM SevOne NPM"
description: "通过 SevOne NPM 的 Webhook Definition 把策略告警的触发和清除同步到 Flashduty On-call。"
keywords: ["告警集成", "IBM SevOne", "SevOne NPM", "Webhook Definition", "Policy", "alertId"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "IBM SevOne", "SevOne NPM", "Webhook Definition", "Po
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "IBM SevOne", "SevOne NPM", "Webhook Definition", "Po
</div>
## 在 SevOne NPM 中配置
----
需要创建两个 Webhook Definition:一个在告警触发时发送,一个在告警清除时发送。
@@ -43,9 +42,9 @@ keywords: ["告警集成", "IBM SevOne", "SevOne NPM", "Webhook Definition", "Po
4. **Request Method** 选择 **POST**,**Content Type** 选择 **application/json**
5. 在 **Body** 中粘贴下面的模板:
-```json
-{"event":"trigger","alert_id":"$alertId","severity":"$alertState","message":"$alertMessage","alert_type":"$alertType","occurrences":"$occurrences","device_id":"$deviceId","device_name":"$deviceName","device_ip":"$deviceIp","device_group":"$groupName","policy_id":"$policyId","policy_name":"$policyName","threshold_name":"$thresholdName","object_name":"$objectName","plugin":"$pluginName","cluster":"$clusterName"}
-```
+ ```json
+ {"event":"trigger","alert_id":"$alertId","severity":"$alertState","message":"$alertMessage","alert_type":"$alertType","occurrences":"$occurrences","device_id":"$deviceId","device_name":"$deviceName","device_ip":"$deviceIp","device_group":"$groupName","policy_id":"$policyId","policy_name":"$policyName","threshold_name":"$thresholdName","object_name":"$objectName","plugin":"$pluginName","cluster":"$clusterName"}
+ ```
6. 点击 **Test Definition** 检查请求能否发出,然后点击 **Save**
@@ -83,7 +82,6 @@ keywords: ["告警集成", "IBM SevOne", "SevOne NPM", "Webhook Definition", "Po
</Warning>
## 推送内容
----
模板中的每个字段都是一个 SevOne 变量的替换结果(变量说明见 IBM 文档 [Webhook Definition Manager](https://www.ibm.com/docs/en/SSUWLY_8.0/nms/Webhook_Definition_Manager.html)):
@@ -105,14 +103,12 @@ keywords: ["告警集成", "IBM SevOne", "SevOne NPM", "Webhook Definition", "Po
SevOne 对不支持的变量输出 `n/a`(例如流量策略的 `$pluginName`),Flashduty 会忽略 `n/a`。
## Alert Key
----
Flashduty 使用 `alert_id`(`$alertId`,IBM 文档描述为 "The id of the triggered alert")作为 Alert Key。同一条 SevOne 告警的多次触发和清除携带相同的 `alert_id`,会落在同一条 Flashduty 告警上;修改策略名称、等级或消息不会改变 Alert Key。
请求中 `alert_id` 为空、为 `n/a` 或仍是未替换的 `$alertId` 时,Flashduty 返回参数错误。
## 状态和告警等级
----
`$alertState` 是策略的等级。清除事件沿用该告警的等级,状态变为恢复。
@@ -124,7 +120,6 @@ Flashduty 使用 `alert_id`(`$alertId`,IBM 文档描述为 "The id of the tr
| 为空或其他值 | Warning |
## 常见问题
----
<AccordionGroup>
<Accordion title="Test Definition 会在 Flashduty 创建告警吗?">
@@ -153,7 +148,6 @@ IBM 文档只说明 Test Definition 会返回状态码、响应头和响应体
</AccordionGroup>
## 排查问题
----
- **SevOne 推送失败**:确认 Destination URL 是完整的推送地址;自签名 TLS 证书需要勾选 **Allow insecure webhook connection**,且证书需使用 SAN 而不是仅 Common Name
- **Flashduty 返回参数错误**:确认 Content Type 为 application/json,`event` 为 `trigger` 或 `clear`,且 `alert_id` 有值
diff --git a/zh/on-call/integration/alert-integration/alert-sources/signoz.mdx b/zh/on-call/integration/alert-integration/alert-sources/signoz.mdx
index 726386c6..805205bc 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/signoz.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/signoz.mdx
@@ -1,15 +1,15 @@
---
title: "SigNoz 告警集成"
+sidebarTitle: "SigNoz"
description: "通过 SigNoz 的 Webhook 通知渠道,使用 Flashduty 的 Prometheus 集成接收 SigNoz 告警,恢复通知自动关闭告警。"
keywords: ["告警集成", "SigNoz", "Webhook", "Prometheus", "Alertmanager", "可观测性"]
---
-SigNoz 的 Webhook 通知渠道向你填写的 URL 发送 Prometheus Alertmanager 格式的 JSON(`status`、`alerts`、`fingerprint`、`labels`、`annotations`、`startsAt`、`endsAt`)。Flashduty 的 [Prometheus 集成](/zh/on-call/integration/alert-integration/alert-sources/prometheus) 与该格式兼容,因此不需要单独的 SigNoz 集成:在 Flashduty 创建 Prometheus 集成,把它的推送地址填进 SigNoz 即可。
+SigNoz 的 Webhook 通知渠道向您填写的 URL 发送 Prometheus Alertmanager 格式的 JSON(`status`、`alerts`、`fingerprint`、`labels`、`annotations`、`startsAt`、`endsAt`)。Flashduty 的 [Prometheus 集成](/zh/on-call/integration/alert-integration/alert-sources/prometheus) 与该格式兼容,因此不需要单独的 SigNoz 集成:在 Flashduty 创建 Prometheus 集成,把它的推送地址填进 SigNoz 即可。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 Prometheus**,不是 SigNoz。
@@ -30,7 +30,6 @@ SigNoz 的 Webhook 通知渠道向你填写的 URL 发送 Prometheus Alertmanage
</div>
## 在 SigNoz 中配置
----
1. 进入 SigNoz 的 **Settings** → **Notification Channels**(也可从 **Alerts** 页的 **Notification Channels** 标签进入),点击 **New Channel**
2. 填写渠道名称,类型选择 **Webhook**,在 endpoint URL 中填入上一步复制的完整推送地址(包含 `?integration_key=...`)
@@ -38,7 +37,6 @@ SigNoz 的 Webhook 通知渠道向你填写的 URL 发送 Prometheus Alertmanage
4. 保存,然后在 SigNoz 告警规则的阈值行(**send to**)中选择该渠道
## 字段映射
----
| SigNoz 字段 | Flashduty |
| :--- | :--- |
@@ -53,7 +51,6 @@ SigNoz 的 Webhook 通知渠道向你填写的 URL 发送 Prometheus Alertmanage
SigNoz 按规则(`ruleId`)分组发送通知,一次通知可包含多条告警;Flashduty 逐条处理(单次最多 100 条)。规则触发通常在 1 分钟内送达。
## 恢复与去重
----
- SigNoz 发送 `status` 为 `resolved` 的通知时,Flashduty 按相同的 `fingerprint` 关闭对应告警。
- 新版 SigNoz 规则的 `severity` 标签取自阈值行的名称(例如阈值名 `critical`、`warning`),同时写入 `threshold.name` 标签。如果使用了 `error` 等未内置的取值,请在 Prometheus 集成中配置自定义严重程度映射,否则按 Warning 处理。
@@ -61,7 +58,6 @@ SigNoz 按规则(`ruleId`)分组发送通知,一次通知可包含多条
- 渠道的 **Test** 按钮会发送一条 `status` 为 `firing` 的测试告警,标题为 `Test Alert (<渠道名称>)`,`severity` 为 `critical`。它会在 Flashduty 产生一条 Critical 告警,且不会有对应的恢复通知,请手动关闭该告警。
## 排查问题
----
- **Flashduty 返回 `Invalid parameters`**:推送地址不完整,缺少 `integration_key`,或集成类型不是 Prometheus
- **告警没有恢复**:确认 SigNoz 渠道的 **Send resolved alerts** 已开启,且恢复通知的 `fingerprint` 与触发时一致
diff --git a/zh/on-call/integration/alert-integration/alert-sources/simple-observability.mdx b/zh/on-call/integration/alert-integration/alert-sources/simple-observability.mdx
index 61d9ddd2..76a9cb29 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/simple-observability.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/simple-observability.mdx
@@ -1,5 +1,6 @@
---
title: "Simple Observability 告警集成"
+sidebarTitle: "Simple Observability"
description: "通过 Webhook 通知渠道,将 Simple Observability 的规则、服务器、任务和端点告警及其恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Simple Observability", "Webhook", "服务器监控", "端点监控", "定时任务监控"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Simple Observability", "Webhook", "服务器监控",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Simple Observability", "Webhook", "服务器监控",
</div>
## 在 Simple Observability 中配置
----
<Steps>
<Step title="添加 Webhook 渠道">
@@ -61,7 +60,6 @@ Simple Observability 要求接收端返回 2xx 状态码,否则 Simple Observa
</Warning>
## 推送内容
----
Webhook 以 JSON 格式 POST,Flashduty 直接解析,无需配置模板。`event_type` 决定告警属于哪类对象:
@@ -88,18 +86,16 @@ Webhook 以 JSON 格式 POST,Flashduty 直接解析,无需配置模板。`ev
| 任务的 `server`、`schedule` | 标签 `job_server`、`job_schedule` |
## Alert Key
----
Flashduty 使用「对象类型 + 对象 ID」作为 Alert Key,例如 `endpoint:<data.endpoint.id>`。同一个规则、服务器、端点或任务的触发和恢复通知落在同一条告警上;不同对象生成不同告警,即使 ID 相同但类型不同也不会互相影响。修改名称、等级、描述或时间不会改变 Alert Key。
请求中缺少对应的对象 ID 时,Flashduty 返回参数错误,因为无法可靠地把恢复关联到原告警。`event_type` 或 `status` 不在上表中时同样被拒绝。
<Note>
-Simple Observability 官方文档只给出了各类型的触发示例,没有逐条说明恢复通知携带相同的对象 ID。Flashduty 按各类型统一的数据结构关联触发与恢复;如果你发现恢复后告警没有关闭,请联系我们并附上恢复通知的请求体。
+Simple Observability 官方文档只给出了各类型的触发示例,没有逐条说明恢复通知携带相同的对象 ID。Flashduty 按各类型统一的数据结构关联触发与恢复;如果您发现恢复后告警没有关闭,请联系我们并附上恢复通知的请求体。
</Note>
## 状态和告警等级
----
| Simple Observability `severity` | Flashduty 等级 |
| :--- | :--- |
@@ -111,12 +107,11 @@ Simple Observability 官方文档只给出了各类型的触发示例,没有
规则和任务告警的 `severity` 为空,因此按 Warning 处理。恢复通知(`RESOLVED`、`SERVER_UP`、`ENDPOINT_UP`、`SUCCESS`)会关闭同一 Alert Key 的告警。
## 常见问题
----
<AccordionGroup>
<Accordion title="任务每次成功运行都会推送吗?">
-取决于你在 Simple Observability 中的通知设置。`JOB_ALERT` 的 `SUCCESS` 被当作恢复通知:任务此前失败过,则关闭原告警。如果不希望收到成功通知,在 Simple Observability 中关闭任务成功的通知即可。
+取决于您在 Simple Observability 中的通知设置。`JOB_ALERT` 的 `SUCCESS` 被当作恢复通知:任务此前失败过,则关闭原告警。如果不希望收到成功通知,在 Simple Observability 中关闭任务成功的通知即可。
</Accordion>
@@ -134,7 +129,6 @@ Simple Observability 官方文档只给出了各类型的触发示例,没有
</AccordionGroup>
## 排查问题
----
- **Simple Observability 报错**:确认 Webhook URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:错误信息会指出缺少的对象 ID 或不支持的 `event_type`、`status`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/site24x7.mdx b/zh/on-call/integration/alert-integration/alert-sources/site24x7.mdx
index bb7b2a34..e8e59399 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/site24x7.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/site24x7.mdx
@@ -1,5 +1,6 @@
---
title: "Site24x7 告警集成"
+sidebarTitle: "Site24x7"
description: "通过 Webhook 将 Site24x7 监控的状态变化同步到 Flashduty On-call,监控恢复为 Up 时自动恢复告警。"
keywords: ["告警集成", "Site24x7", "Webhook", "Incident Parameters", "MONITOR_ID"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Site24x7", "Webhook", "Incident Parameters", "MONITO
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Site24x7", "Webhook", "Incident Parameters", "MONITO
</div>
## 在 Site24x7 中配置
----
<Steps>
<Step title="添加 Webhooks 集成">
@@ -76,14 +75,12 @@ keywords: ["告警集成", "Site24x7", "Webhook", "Incident Parameters", "MONITO
</Steps>
## Alert Key
----
Flashduty 使用 Site24x7 的监控 ID 作为 Alert Key:优先取 `MONITOR_ID`,没有时从 `MONITOR_DASHBOARD_LINK`(形如 `.../home/monitors/<监控 ID>/Summary`)中提取。同一个监控的 Down、Trouble、Critical 和 Up 通知都携带同一个监控 ID,因此会合并到同一条告警,并由 Up 通知恢复。
`STATUS`、监控名称、故障原因、故障地点和时间的变化都不会改变 Alert Key。
## 状态和告警等级
----
| Site24x7 `STATUS` | Flashduty 状态或等级 |
| :--- | :--- |
@@ -96,7 +93,6 @@ Flashduty 使用 Site24x7 的监控 ID 作为 Alert Key:优先取 `MONITOR_ID`
`STATUS` 为空的请求会被拒绝。
## 告警标签
----
Flashduty 会把以下事件参数写入告警标签,便于筛选和排查:
@@ -118,7 +114,6 @@ Flashduty 会把以下事件参数写入告警标签,便于筛选和排查:
告警标题取 `MONITORNAME`,告警描述取 `INCIDENT_REASON`。
## 排查问题
----
- **Site24x7 提示集成失败**:确认 Hook URL 完整且包含 `integration_key`,HTTP Method 为 POST
- **Flashduty 返回参数错误**:确认勾选了 **Post as JSON** 和 **Send Incident Parameters**,请求体中有 `MONITOR_ID` 和 `STATUS`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/skywalking.mdx b/zh/on-call/integration/alert-integration/alert-sources/skywalking.mdx
index 36f020c6..cdbf13e1 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/skywalking.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/skywalking.mdx
@@ -1,5 +1,6 @@
---
title: "Skywalking 告警事件"
+sidebarTitle: "Skywalking"
description: "通过 webhook 的方式同步 Skywalking 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "Skywalking 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "Skywalking 告警事件", "监控告警", "数据接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "Skywalking 告警事件", "监控告警", "数据接
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "Skywalking 告警事件", "监控告警", "数据接
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Skywalking** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,10 +45,9 @@ keywords: ["告警集成", "Skywalking 告警事件", "监控告警", "数据接
</div>
## 在 Skywalking
----
<div className="md-block">
-## 一、修改 Skywalking 服务的配置文件
+### 修改 Skywalking 服务的配置文件
1. 登录 Skywalking 服务器。
2. 找到 Skywalking 的配置文件 ./config/alarm-settings.yml。
@@ -88,7 +87,7 @@ hooks:
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/snyk.mdx b/zh/on-call/integration/alert-integration/alert-sources/snyk.mdx
index 49609157..302693c1 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/snyk.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/snyk.mdx
@@ -1,5 +1,6 @@
---
title: "Snyk 告警集成"
+sidebarTitle: "Snyk"
description: "通过 Snyk Webhook 将开源依赖和容器镜像的新增、消除漏洞同步到 Flashduty On-call。"
keywords: ["告警集成", "Snyk", "Webhook", "漏洞", "安全告警", "SCA"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "Snyk", "Webhook", "漏洞", "安全告警", "SCA"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ keywords: ["告警集成", "Snyk", "Webhook", "漏洞", "安全告警", "SCA"]
</div>
## 在 Snyk 中配置
----
Snyk 只能通过 API 创建 Webhook,控制台界面没有对应入口。
@@ -81,19 +80,16 @@ curl -X POST "https://api.snyk.io/v1/org/<ORG_ID>/webhooks/<WEBHOOK_ID>/ping" \
</Steps>
## 关于签名
----
Snyk 会在请求头 `X-Hub-Signature`(格式 `sha256=<HMAC 十六进制摘要>`,密钥为创建 Webhook 时填写的 `secret`)中带上签名。Flashduty 不校验该签名,`secret` 可以填任意随机字符串;推送地址中的 `integration_key` 是唯一的凭证,请妥善保管。
## Alert Key
----
Flashduty 用 **项目 ID(`project.id`)加漏洞 ID(`id`)** 生成 Alert Key,即同一项目中的同一个漏洞对应一条告警。`newIssues` 和 `removedIssues` 中的漏洞使用相同的结构和 `id`,所以新增和消除落在同一条告警上。
项目名称、分支、严重等级的变化不会改变 Alert Key。同一个漏洞在同一项目的多个依赖路径中重复出现时只生成一条告警。不同项目中的同一个漏洞是不同的告警。
## 状态和告警等级
----
| 来源 | Flashduty 处理 |
| :--- | :--- |
@@ -117,7 +113,6 @@ Flashduty 只处理 `newIssues` 和 `removedIssues` 中列出的漏洞;漏洞
告警标签包含项目 ID 和名称、项目类型、分支、组织、漏洞 ID、依赖包名称和版本、CVE、CWE、CVSS 分数和修复版本。导入用户的姓名和邮箱不会写入告警。
## 排查问题
----
- **创建 Webhook 时返回错误**:确认 `url` 是 HTTPS 地址,Token 有该组织权限,组织位于 Snyk 支持 Webhook 的区域,且套餐包含 API 访问权限(Free 套餐会返回 `not entitled for api access`)
- **没有收到告警**:Snyk 只在项目复测且漏洞发生变化时发送事件;项目刚导入时不会发送。请确认项目的扫描类型是开源依赖或容器
diff --git a/zh/on-call/integration/alert-integration/alert-sources/solarwinds-orion.mdx b/zh/on-call/integration/alert-integration/alert-sources/solarwinds-orion.mdx
index 97b546a2..abede1c0 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/solarwinds-orion.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/solarwinds-orion.mdx
@@ -1,5 +1,6 @@
---
title: "SolarWinds Platform (Orion) 告警集成"
+sidebarTitle: "SolarWinds Platform (Orion)"
description: "通过 SolarWinds Platform(Orion)告警的 HTTP 请求动作将告警同步到 Flashduty On-call,告警重置时自动关闭告警。"
keywords: ["告警集成", "SolarWinds", "Orion", "SolarWinds Platform", "NPM", "SAM", "网络监控"]
---
@@ -11,7 +12,6 @@ SolarWinds Platform(原 Orion Platform,本地部署,包括 NPM、SAM 等
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ SolarWinds Platform(原 Orion Platform,本地部署,包括 NPM、SAM 等
</div>
## 在 SolarWinds Platform 中配置
----
以下操作需要有 **Allow Alert Management Rights** 权限的 SolarWinds Platform 账号。SolarWinds 服务器需要能访问 Flashduty 推送地址所在的域名(HTTPS,443 端口)。
@@ -118,7 +117,6 @@ SolarWinds Platform(原 Orion Platform,本地部署,包括 NPM、SAM 等
</Steps>
## Alert Key
----
Flashduty 使用 `alert_object_id`(`${N=Alerting;M=AlertObjectID}`)作为 Alert Key。SolarWinds 为每个「告警定义 + 触发对象」(例如「Node is down」+ 某台交换机)分配一个固定的 AlertObjectID,同一对象上的触发、重复通知和重置都使用这个 ID,因此它们落在同一条 Flashduty 告警上;告警重置后再次触发会打开一条新告警。同一个告警定义在不同对象上触发时,AlertObjectID 不同,会生成不同的告警。
@@ -127,7 +125,6 @@ Flashduty 使用 `alert_object_id`(`${N=Alerting;M=AlertObjectID}`)作为 Al
请求缺少 `action` 或 `alert_object_id`,或 `alert_object_id` 仍是未替换的 `${N=Alerting;M=AlertObjectID}` 时,Flashduty 会拒绝该请求。
## 告警生命周期
----
Flashduty 按 `action` 字段处理通知(不区分大小写):
@@ -139,7 +136,6 @@ Flashduty 按 `action` 字段处理通知(不区分大小写):
在 SolarWinds 中确认(Acknowledge)告警不会执行动作,Flashduty 中的告警状态不变。
## 告警等级
----
告警等级取自告警定义的 **Severity of Alert**(`${N=Alerting;M=Severity}`),不区分大小写:
@@ -155,7 +151,6 @@ Flashduty 按 `action` 字段处理通知(不区分大小写):
重置通知携带告警定义的严重级别,恢复事件保留该等级。
## 告警内容
----
- **标题**:`<告警名称> on <对象名称>`;缺少对象名称时只用告警名称,全部缺少时为 `SolarWinds alert <alert_object_id>`
- **描述**:`${N=Alerting;M=AlertMessage}` 渲染出的告警消息,即告警 **Trigger Actions** 中 **Message displayed when this alert is triggered** 的内容
@@ -164,7 +159,6 @@ Flashduty 按 `action` 字段处理通知(不区分大小写):
SolarWinds 不会对变量值做 JSON 转义,对象名称、告警消息等值中含有双引号、反斜杠或换行时,Flashduty 仍按模板字段原样读取这些值。值为空的字段不会写入标签。变量不适用于当前对象类型时,SolarWinds 可能原样保留 `${...}` 这样的变量,Flashduty 会把它当作空值处理。
## 排查问题
----
- **Simulate 提示 Failed to execute HTTP request**:确认 **URL** 是完整的推送地址,包含 `integration_key` 参数;确认 SolarWinds 服务器可以访问该地址(代理、防火墙)
- **Flashduty 提示请求体不是合法 JSON**:请求体不是本文的模板。确认模板完整粘贴,花括号、每个字段的 `"字段名": "` 和结尾的 `"` 都在
diff --git a/zh/on-call/integration/alert-integration/alert-sources/solarwinds.mdx b/zh/on-call/integration/alert-integration/alert-sources/solarwinds.mdx
index ced47fc3..f93c0030 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/solarwinds.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/solarwinds.mdx
@@ -1,5 +1,6 @@
---
title: "SolarWinds 告警事件"
+sidebarTitle: "SolarWinds"
description: "通过 webhook 的方式同步 SolarWinds 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "SolarWinds 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "SolarWinds 告警事件", "监控告警", "数据接
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "SolarWinds 告警事件", "监控告警", "数据接
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "SolarWinds 告警事件", "监控告警", "数据接
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **SolarWinds** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,13 +46,11 @@ keywords: ["告警集成", "SolarWinds 告警事件", "监控告警", "数据接
</div>
## 在 SolarWinds
----
<div className="md-block">
-## 一、SolarWinds 告警推送配置
-### 步骤1:配置 FlashDudy 告警通道
+### 步骤1:配置 Flashduty 告警通道
**前提说明**
1. SolarWinds 的告警类型有五种(Anomaly、Entity、Event、Log、Metric Group),每种类型对应不同的告警通道,所以需要创建五个告警通道,以便在不同告警类型中使用。
@@ -63,7 +61,7 @@ keywords: ["告警集成", "SolarWinds 告警事件", "监控告警", "数据接
1. 登录您的 SolarWinds 控制台。
2. 在左侧导航栏找到 `Settings` ,选择 `Notification Services` 并点击 `Webhook` 进入到新建告警通道页面。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/sw-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/sw-1.png" />
3. 点击 `CREATE CONFIGURATION` 进行创建相应的告警通道。
4. 在 `Method` 处选择 **POST** ,`Name` 处可以根据前提说明中的建议进行命名,例如:Anomaly_Flashduty。
@@ -73,7 +71,7 @@ keywords: ["告警集成", "SolarWinds 告警事件", "监控告警", "数据接
8. `HTTP POST Body` 不需要修改,使用系统默认生成的即可。
9. 配置完成后,点击 `CREATE` 保存即可。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/sw-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/sw-2.png" />
10. 如需创建其他类型的 Webhook 通道,重复以上步骤即可。
@@ -85,13 +83,13 @@ keywords: ["告警集成", "SolarWinds 告警事件", "监控告警", "数据接
4. `Configuration` 选择步骤1创建的 Anomaly_Flashduty 通道。
5. `Send an additional notification when the Alert is cleared` 保持开启状态。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/sw-4.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/sw-4.png" />
6. 其他配置完成后,点击 `Save` 保存即可。
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/sonarqube.mdx b/zh/on-call/integration/alert-integration/alert-sources/sonarqube.mdx
index 8551a8f7..7c647273 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/sonarqube.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/sonarqube.mdx
@@ -1,5 +1,6 @@
---
title: "SonarQube 告警集成"
+sidebarTitle: "SonarQube"
description: "通过 Webhook 将 SonarQube Server 或 SonarQube Cloud 的质量门禁(Quality Gate)结果同步到 Flashduty On-call。"
keywords: ["告警集成", "SonarQube", "SonarQube Cloud", "Webhook", "质量门禁", "Quality Gate", "代码质量"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "SonarQube", "SonarQube Cloud", "Webhook", "质量门
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "SonarQube", "SonarQube Cloud", "Webhook", "质量门
</div>
## 在 SonarQube 中配置
----
<Steps>
<Step title="创建 Webhook">
@@ -63,7 +62,6 @@ SonarQube 没有提供 Webhook 的测试按钮,Server 版可在 Webhooks 页
</Steps>
## Alert Key
----
Alert Key 由项目 Key(`project.key`)、分支类型(`branch.type`,如 `BRANCH` 或 `PULL_REQUEST`)和分支名(`branch.name`)共同计算,因此:
@@ -75,7 +73,6 @@ Alert Key 由项目 Key(`project.key`)、分支类型(`branch.type`,如
缺少 `project.key` 的请求会被拒绝。
## 状态和告警等级
----
SonarQube 的 Webhook 不携带等级,质量门禁失败是代码质量信号而不是服务中断,因此统一使用 Warning。可以在 Flashduty 中通过路由或告警管理调整等级。
@@ -90,7 +87,6 @@ SonarQube 的 Webhook 不携带等级,质量门禁失败是代码质量信号
每次门禁通过的分析都会推送一次 `OK`,该事件只用于恢复同一项目和分支的活动告警。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -105,7 +101,6 @@ SonarQube 的 Webhook 不携带等级,质量门禁失败是代码质量信号
告警描述中列出每个未通过的条件:指标、当前值和阈值。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`
- **没有收到告警**:确认分析确实包含质量门禁结果;Server 版在 Webhooks 页面查看 **Last delivery** 的状态码,SonarQube Cloud 需要付费方案
diff --git a/zh/on-call/integration/alert-integration/alert-sources/split-io.mdx b/zh/on-call/integration/alert-integration/alert-sources/split-io.mdx
index 42d63d9f..953e0ce2 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/split-io.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/split-io.mdx
@@ -1,5 +1,6 @@
---
title: "Split 告警集成"
+sidebarTitle: "Split"
description: "通过 Metric Alert Webhook 将 Split(Harness FME)的指标劣化告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Split", "Harness FME", "功能开关", "指标告警", "Webhook"]
---
@@ -9,7 +10,6 @@ Split 现已并入 Harness,产品名为 Harness Feature Management & Experimen
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Split 现已并入 Harness,产品名为 Harness Feature Management & Experimen
</div>
## 在 Harness FME 中配置
----
<Steps>
<Step title="确认权限">
@@ -70,7 +69,6 @@ FME 只在告警触发时推送,告警被忽略(dismiss)或自动解除(
</Steps>
## 推送内容
----
FME 每次推送一个 `type` 为 `METRIC_ALERT` 的 JSON 对象。Flashduty 使用以下字段:
@@ -93,7 +91,6 @@ FME 每次推送一个 `type` 为 `METRIC_ALERT` 的 JSON 对象。Flashduty 使
告警标题为 `<功能开关或实验名称> degraded <指标名称> in <环境名称>`。每条告警还带有标签 `source=split-io`。
## Alert Key
----
Flashduty 用功能开关或实验 ID、环境 ID 和指标 ID 一起生成 Alert Key:
@@ -105,7 +102,6 @@ Flashduty 用功能开关或实验 ID、环境 ID 和指标 ID 一起生成 Aler
修改功能开关、指标、环境或告警策略的名称不会改变 Alert Key。
## 告警等级
----
| `data.alertType` | Flashduty 告警等级 |
| :--- | :--- |
@@ -121,7 +117,6 @@ Flashduty 用功能开关或实验 ID、环境 ID 和指标 ID 一起生成 Aler
`METRIC_ALERT` 推送缺少 `source.id`、`data.environment.id` 或 `data.metric.id` 时,请求会被拒绝。
## 常见问题
----
<AccordionGroup>
<Accordion title="FME 中告警已自动解除,Flashduty 告警为什么没有关闭?">
@@ -144,7 +139,6 @@ FME 也可以把告警邮件发到任意地址。Webhook 推送结构化字段
</AccordionGroup>
## 排查问题
----
- **Flashduty 返回参数错误**:确认推送地址完整(包含 `integration_key`)
- **FME 中有告警但 Flashduty 没有**:确认 Webhook 选中了该环境和该告警类型;指标改善(`DESIRED`)不生成告警
diff --git a/zh/on-call/integration/alert-integration/alert-sources/splunk-observability.mdx b/zh/on-call/integration/alert-integration/alert-sources/splunk-observability.mdx
index a0b8b194..a4c9d18f 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/splunk-observability.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/splunk-observability.mdx
@@ -1,5 +1,6 @@
---
title: "Splunk Observability Cloud 告警集成"
+sidebarTitle: "Splunk Observability Cloud"
description: "通过 Webhook 将 Splunk Observability Cloud(原 SignalFx)探测器告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Splunk Observability Cloud", "SignalFx", "探测器", "Detector", "Webhook"]
---
@@ -13,7 +14,6 @@ keywords: ["告警集成", "Splunk Observability Cloud", "SignalFx", "探测器"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -34,7 +34,6 @@ keywords: ["告警集成", "Splunk Observability Cloud", "SignalFx", "探测器"
</div>
## 在 Splunk Observability Cloud 中配置
----
<Steps>
<Step title="创建 Webhook 集成">
@@ -79,14 +78,12 @@ keywords: ["告警集成", "Splunk Observability Cloud", "SignalFx", "探测器"
</Warning>
## Alert Key
----
Flashduty 使用 `incidentId` 作为 Alert Key。Splunk 文档说明,同一个告警的触发通知和清除通知携带相同的 `incidentId`,因此两者会落在同一条 Flashduty 告警上。
规则名称、严重程度、状态、时间、消息内容和维度取值的变化都不会改变 Alert Key。
## 状态和告警等级
----
Flashduty 读取 `statusExtended`;该字段为空时读取 `status`:
@@ -115,7 +112,6 @@ Flashduty 读取 `statusExtended`;该字段为空时读取 `status`:
恢复事件保留原告警等级。
## 告警内容
----
- **标题**:规则名称 `rule`,为空时使用探测器名称 `detector`
- **描述**:`messageBody`,为空时使用 `description`
@@ -127,7 +123,6 @@ Flashduty 读取 `statusExtended`;该字段为空时读取 `status`:
`orgId`、`imageUrl`、`inputs` 不会写入标签。
## 排查问题
----
- **Splunk 显示通知发送失败**:确认 URL 是完整推送地址且包含 `integration_key`。Splunk 在未收到 `200` 响应时会重试,最长 24 小时
- **Flashduty 返回参数错误**:确认模板中保留了 `incidentId` 和 `statusExtended`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/splunk.mdx b/zh/on-call/integration/alert-integration/alert-sources/splunk.mdx
index a6b6c836..c291b956 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/splunk.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/splunk.mdx
@@ -1,5 +1,6 @@
---
title: "Splunk 告警事件"
+sidebarTitle: "Splunk"
description: "通过 webhook 的方式同步 Splunk 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "Splunk 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "Splunk 告警事件", "监控告警", "数据接入"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "Splunk 告警事件", "监控告警", "数据接入"
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "Splunk 告警事件", "监控告警", "数据接入"
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Splunk** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,22 +46,20 @@ keywords: ["告警集成", "Splunk 告警事件", "监控告警", "数据接入"
</div>
## 在 Splunk
----
<div className="md-block">
-## 一、Splunk 告警推送配置
1. 登录您的 Splunk 控制台。
2. 在 `Search adn Report` 应用中,搜索想要监控的关键字,比如 error 关键字。
3. 在右上角的另存为处,选择 `Alerts`,将搜索的关键字配置为监控项。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/splunk-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/splunk-1.png" />
4. 在弹出的配置框中输入相关信息,`set up` 和 `Triggering conditions` 部分,按实际情况配置。
5. 在 `Trigger Action` 部分,点击 `Add Action` 并选择 `Webhook`。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/splunk-2.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/splunk-2.png" />
6. 在 `Webhook` 中的 `URL` 处填写集成的推送地址(当前页面填写集成名称,保存后即可生成地址)并保存,即可完成告警配置。
@@ -69,7 +67,7 @@ keywords: ["告警集成", "Splunk 告警事件", "监控告警", "数据接入"
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
由于 Splunk 的告警事件没有区分严重程度,所以 Splunk 推送到 Flashduty的所有告警事件状态都为 Warning 且没有恢复事件。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/stackrox.mdx b/zh/on-call/integration/alert-integration/alert-sources/stackrox.mdx
index 258f1a88..e4323516 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/stackrox.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/stackrox.mdx
@@ -1,5 +1,6 @@
---
title: "StackRox 告警集成"
+sidebarTitle: "StackRox"
description: "通过 Generic Webhook 将 StackRox(Red Hat Advanced Cluster Security for Kubernetes)的策略违规告警同步到 Flashduty On-call。"
keywords: ["告警集成", "StackRox", "Red Hat ACS", "RHACS", "Kubernetes", "容器安全", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "StackRox", "Red Hat ACS", "RHACS", "Kubernetes", "
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "StackRox", "Red Hat ACS", "RHACS", "Kubernetes", "
</div>
## 在 StackRox 中配置
----
需要在 RHACS 中拥有创建通知集成和修改策略的权限。Central 必须能通过 HTTPS 访问 Flashduty 推送地址。
@@ -71,14 +70,12 @@ Generic Webhook 集成页面上的 **Test** 按钮会发送一条 ID 为 `testal
</Steps>
## Alert Key
----
Flashduty 使用 StackRox 告警的 ID(请求体中的 `alert.id`)作为 Alert Key。StackRox 官方文档说明每条告警只推送一次:违规首次出现在某个部署上,或者该部署上此前的运行时告警被解决后再次出现时,才会产生新的推送。因此每次推送对应一条独立的告警,不同告警的 Alert Key 不同;如果 StackRox 对同一条告警重复推送,这些推送会合并到同一条 Flashduty 告警。
策略名称、严重程度、违规内容和时间的变化都不会改变 Alert Key。缺少 `alert.id` 的请求会被拒绝。
## 状态和告警等级
----
Flashduty 按策略的严重程度(`alert.policy.severity`)映射告警等级:
@@ -93,7 +90,6 @@ Flashduty 按策略的严重程度(`alert.policy.severity`)映射告警等
如需让高危策略也以 Critical 通知,可以在 Flashduty 中通过路由或告警处理规则按 `policy_severity` 标签调整。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -110,7 +106,6 @@ Flashduty 按策略的严重程度(`alert.policy.severity`)映射告警等
违规详情(`alert.violations[].message`)写入告警描述。
## 排查问题
----
- **Central 显示推送失败**:确认 Endpoint 完整且包含 `integration_key`,Central 所在网络能访问 Flashduty
- **Test 成功但没有告警**:Test 发送的是 `testalert`,不会创建告警;请确认策略已启用通知渠道,并制造一次真实违规
diff --git a/zh/on-call/integration/alert-integration/alert-sources/standard-alert.mdx b/zh/on-call/integration/alert-integration/alert-sources/standard-alert.mdx
index a2e3c53e..1e76ff19 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/standard-alert.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/standard-alert.mdx
@@ -1,25 +1,25 @@
---
title: "标准告警事件"
+sidebarTitle: "标准告警事件"
description: "通过标准协议推送自有系统告警事件到 Flashduty,实现告警事件自动化降噪处理。"
---
通过标准协议推送自有系统告警事件到 Flashduty,实现告警事件自动化降噪处理。
<Tip>
-Flashduty 已经适配了大部分常用告警系统的 webhook 协议,对于这些系统您应该首先使用对应的集成,更加简单方便。本集成提供了一个标准的 HTTP 接口,需要您开发适配。好处是您可以推送任何你想进行oncall的告警事件。
+Flashduty 已经适配了大部分常用告警系统的 webhook 协议,对于这些系统您应该首先使用对应的集成,更加简单方便。本集成提供了一个标准的 HTTP 接口,需要您开发适配。好处是您可以推送任何您想进行oncall的告警事件。
</Tip>
<div class="hide">
## 操作步骤
----
### 在 Flashduty
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
<AccordionGroup>
-<Accordion title="使用专属集成">
+<Accordion title="查看专属集成的配置步骤">
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
@@ -28,10 +28,10 @@ Flashduty 已经适配了大部分常用告警系统的 webhook 协议,对于
4. 点击生成的卡片,可以查看到 **推送地址**,复制备用,完成。
</Accordion>
-<Accordion title="使用共享集成">
+<Accordion title="查看共享集成的配置步骤">
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
-1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **标准告警事件** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -42,8 +42,7 @@ Flashduty 已经适配了大部分常用告警系统的 webhook 协议,对于
</div>
-## 一、请求描述
----
+## 请求描述
### 请求方式
@@ -71,7 +70,7 @@ POST, Content-Type:"application/json"
字段|必含|类型|释义
:-:|:-:|:-:|:---
-| title_rule | 是 | string | 告警标题,不超过`512`个字符,超出后将自动截断。支持根据告警内容动态生成标题,生成规则请参考 [定制故障标题](https://docs.flashduty.com/zh/on-call/integration/alert-integration/alert-pipelines)。
+| title_rule | 是 | string | 告警标题,不超过`512`个字符,超出后将自动截断。支持根据告警内容动态生成标题,生成规则请参考 [定制故障标题](/zh/on-call/integration/alert-integration/alert-pipelines)。
| event_status | 是 | string | 告警状态。枚举值(`首字母大写`):*Critical*:严重,*Warning*:警告,*Info*:提醒,*Ok*:恢复。当指定为Ok时,意味着对告警进行自动恢复。
| alert_key | 否 | string | 告警标识,用于对已经存在的告警进行更新或自动恢复。您可以自定义此值,但不可超过`255`个字符。您也可以依赖系统自动生成,该值会在响应中返回。如果您上报的是恢复事件,则此值必须存在。
| description | 否 | string | 告警描述,不超过`2048`个字符,超出后将自动截断。
@@ -82,7 +81,7 @@ POST, Content-Type:"application/json"
字段|必含|类型|释义
:-:|:-:|:-:|:---
-| alt | 否 | string | 图片的替代文本, 长度限制 128 字符,超长截断。
+| alt | 否 | string | 图片的替代文本,长度限制 128 字符,超长截断。
| src | 是 | string | 图片来源,值:http/https 开头的图片链接地址 或 [图片上传接口](/zh/on-call/integration/alert-integration/alert-sources/image-upload)返回的image_key,长度限制 256 字符,超长会被丢弃
| href | 否 | string | 超链接引用路径,长度限制 256 字符,超长截断
@@ -128,8 +127,7 @@ Code:
| InternalError | 500 | 内部或未知错误 |
-### 二、请求示例
----
+### 请求示例
请求:
@@ -173,8 +171,7 @@ curl -X POST '{api_host}/event/push/alert/standard?integration_key={integration_
}
```
-## 三、字段映射与值映射
----
+## 字段映射与值映射
如果您的系统推送的 JSON 格式无法直接匹配上述标准 Payload 结构,可以在集成设置中配置 **字段映射** 和 **值映射**,让 Flashduty 自动将任意格式的 JSON 转换为标准告警事件。
@@ -274,8 +271,7 @@ curl -X POST '{api_host}/event/push/alert/standard?integration_key={integration_
| **检测时间(分钟)** | 指定时间内未收到有效事件,即生成一条 Warning 告警。取值须为整数,范围为 10 分钟 ~ 48 小时(默认 10 分钟) |
| **收到新事件后自动恢复** | 开关,默认开启。收到下一条有效事件时,自动恢复静默检测产生的告警 |
-## 四、最佳实践 <span id="最佳实践"></span>
----
+## 最佳实践 <span id="最佳实践"></span>
1. 当告警状态发生变更时,向 Flashduty发送事件
2. 当告警恢复时,发送一个 status 为 Ok 的事件,来关闭告警。否则,告警将一直处于打开状态。如果您的告警系统没有恢复事件,建议您手动发送恢复事件
@@ -285,8 +281,7 @@ curl -X POST '{api_host}/event/push/alert/standard?integration_key={integration_
- 告警的类别信息,如 class(api,db,net)
-## 五、常见问题
----
+## 常见问题
<AccordionGroup>
<Accordion title="为什么在Flashduty没有收到告警?">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/statuscake.mdx b/zh/on-call/integration/alert-integration/alert-sources/statuscake.mdx
index a288a6c6..fb03d91d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/statuscake.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/statuscake.mdx
@@ -1,5 +1,6 @@
---
title: "StatusCake 告警集成"
+sidebarTitle: "StatusCake"
description: "通过通知组 Webhook 将 StatusCake Uptime 测试的宕机和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "StatusCake", "Uptime", "Notification Group", "Contact Group", "Webhook", "TestID"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "StatusCake", "Uptime", "Notification Group", "Contac
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "StatusCake", "Uptime", "Notification Group", "Contac
</div>
## 在 StatusCake 中配置
----
<Steps>
<Step title="创建通知组">
@@ -66,7 +65,6 @@ Webhook Method 必须选择 **POST**。选择 GET 时 StatusCake 只会请求 UR
</Warning>
## 推送内容
----
StatusCake 以 `application/x-www-form-urlencoded` 表单格式 POST 以下字段,Flashduty 直接解析,无需配置模板:
@@ -85,14 +83,12 @@ StatusCake 以 `application/x-www-form-urlencoded` 表单格式 POST 以下字
告警标题使用测试名称;测试名称为空时依次使用被测地址、`StatusCake test <TestID>`。
## Alert Key
----
Flashduty 使用 `TestID` 作为 Alert Key。同一个测试的宕机、重复宕机和恢复通知携带相同的 `TestID`,因此会落在同一条告警上;不同测试即使名称和被测地址相同,也会生成不同的告警。修改测试名称、状态码或标签不会改变 Alert Key。
请求中缺少 `TestID` 时,Flashduty 会返回参数错误,因为无法可靠地把恢复通知关联到原告警。
## 状态和告警等级
----
StatusCake 的通知不区分告警等级,Flashduty 统一按 Critical 处理。
@@ -104,7 +100,6 @@ StatusCake 的通知不区分告警等级,Flashduty 统一按 Critical 处理
`Status` 为空或为其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="重复告警会产生多条 Flashduty 告警吗?">
@@ -127,7 +122,6 @@ StatusCake 的通知不区分告警等级,Flashduty 统一按 Critical 处理
</AccordionGroup>
## 排查问题
----
- **StatusCake 推送失败**:确认 Webhook URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认 Webhook Method 为 POST,且请求中的 `TestID`、`Status` 非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/statusgator.mdx b/zh/on-call/integration/alert-integration/alert-sources/statusgator.mdx
index 50a9c085..24518068 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/statusgator.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/statusgator.mdx
@@ -1,5 +1,6 @@
---
title: "StatusGator 告警集成"
+sidebarTitle: "StatusGator"
description: "通过 Webhook 集成将 StatusGator 监控的第三方服务状态变化和早期预警同步到 Flashduty On-call。"
keywords: ["告警集成", "StatusGator", "状态页监控", "Webhook", "StatusChange", "EarlyWarningSignal"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "StatusGator", "状态页监控", "Webhook", "StatusC
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "StatusGator", "状态页监控", "Webhook", "StatusC
</div>
## 在 StatusGator 中配置
----
<Steps>
<Step title="添加 Webhook 集成">
@@ -53,7 +52,6 @@ keywords: ["告警集成", "StatusGator", "状态页监控", "Webhook", "StatusC
Webhook 集成在 Business 和 Education 的所有套餐(包括 Free)中可用。StatusGator 连续 5 次收不到 200 响应会停用该 Webhook,请到 **Integrations** 页面修正地址后重新启用。
## 推送内容
----
StatusGator 以 JSON 格式 POST 事件,请求体固定,不可自定义,Flashduty 直接解析,无需配置模板:
@@ -73,7 +71,6 @@ StatusGator 以 JSON 格式 POST 事件,请求体固定,不可自定义,Fl
告警标题为 `<监控名称>: <message>`;`message` 为空时为 `<监控名称> is <status>`。
## Alert Key
----
`StatusChange` 使用 `monitor.id` 作为 Alert Key。StatusGator 的请求体没有事件或故障 ID,监控是唯一稳定的业务对象:同一个监控的 down、warn、up 通知落在同一条告警上,不同监控生成不同的告警。修改消息、组件、名称或时间不会改变 Alert Key。
@@ -82,7 +79,6 @@ StatusGator 以 JSON 格式 POST 事件,请求体固定,不可自定义,Fl
请求中缺少 `monitor.id` 时,Flashduty 会返回参数错误,因为无法可靠地把恢复通知关联到原告警。
## 状态和告警等级
----
| StatusGator `status` | Flashduty 状态或等级 |
| :--- | :--- |
@@ -95,12 +91,10 @@ StatusGator 以 JSON 格式 POST 事件,请求体固定,不可自定义,Fl
`type` 或 `status` 为空或为其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 早期预警不会自动恢复
----
`EarlyWarningSignal` 是单次通知,StatusGator 不会发送对应的恢复事件,Flashduty 也不会在服务恢复时关闭它。请开启协作空间的[超时自动关闭](/zh/on-call/channel/create-edit),建议设置为 **1 小时**。
## 常见问题
----
<AccordionGroup>
<Accordion title="测试通知会创建告警吗?">
@@ -123,7 +117,6 @@ StatusGator 以 JSON 格式 POST 事件,请求体固定,不可自定义,Fl
</AccordionGroup>
## 排查问题
----
- **StatusGator 显示投递失败或停用了 Webhook**:确认 Webhook URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求是 3.0 版本的 JSON 通知,且 `type`、`monitor.id`、`status` 符合上文要求
diff --git a/zh/on-call/integration/alert-integration/alert-sources/statuspage.mdx b/zh/on-call/integration/alert-integration/alert-sources/statuspage.mdx
index 36deb66c..6b019ab9 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/statuspage.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/statuspage.mdx
@@ -1,5 +1,6 @@
---
title: "Atlassian Statuspage 告警集成"
+sidebarTitle: "Atlassian Statuspage"
description: "通过 Webhook 订阅任意 Atlassian Statuspage 状态页,把组件故障和事件(Incident)同步到 Flashduty On-call。"
keywords: ["告警集成", "Statuspage", "Atlassian", "状态页", "第三方服务状态", "Webhook"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "Statuspage", "Atlassian", "状态页", "第三方服
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ keywords: ["告警集成", "Statuspage", "Atlassian", "状态页", "第三方服
</div>
## 在 Statuspage 状态页上订阅
----
<Steps>
<Step title="打开订阅入口">
@@ -69,7 +68,6 @@ Statuspage 没有发送测试通知的按钮,订阅后要等状态页出现下
</Steps>
## 推送内容
----
Statuspage 在组件状态变化和事件每次更新时推送一次 JSON,分为两类:
@@ -101,7 +99,6 @@ Statuspage 在组件状态变化和事件每次更新时推送一次 JSON,分
每条告警还带有标签 `source=statuspage`。推送中的退订链接(`meta.unsubscribe`)含有订阅凭据,Flashduty 不会把它写入告警。
## Alert Key
----
Flashduty 按推送类型分别生成 Alert Key:
@@ -113,7 +110,6 @@ Flashduty 按推送类型分别生成 Alert Key:
修改组件名称、事件名称或影响程度不会改变 Alert Key。等级升高时(例如事件的影响程度从 `none` 改为 `critical`),Flashduty 会新建一条更高等级的告警,原告警保持触发;恢复推送会同时关闭这两条告警。上一条告警恢复后,同一组件再次故障会生成一条新告警。
## 状态和告警等级
----
**组件状态**
@@ -145,7 +141,6 @@ Flashduty 按推送类型分别生成 Alert Key:
计划维护(状态为 `scheduled`、`in_progress`、`verifying`、`completed`,或影响程度为 `maintenance`)属于计划内变更,Flashduty 返回成功但不生成告警。
## 常见问题
----
<AccordionGroup>
<Accordion title="事件处于 monitoring 状态时告警会恢复吗?">
@@ -168,7 +163,6 @@ Statuspage 的退订链接只出现在推送内容中,Flashduty 不保存它
</AccordionGroup>
## 排查问题
----
- **状态页上没有 Webhook 订阅选项**:状态页所有者没有开启 Webhook 订阅,无法通过本集成订阅
- **Flashduty 返回参数错误**:确认推送地址完整(包含 `integration_key`);推送内容缺少 `page.id`、组件 ID 或事件 ID 时会被拒绝
diff --git a/zh/on-call/integration/alert-integration/alert-sources/statuspal.mdx b/zh/on-call/integration/alert-integration/alert-sources/statuspal.mdx
index 08a3169a..39264e5c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/statuspal.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/statuspal.mdx
@@ -1,5 +1,6 @@
---
title: "Statuspal 告警集成"
+sidebarTitle: "Statuspal"
description: "通过 Statuspal Webhook,把状态页事件(Incident)和 Statuspal 监控的服务上下线同步到 Flashduty On-call。"
keywords: ["告警集成", "Statuspal", "状态页", "Webhook", "服务监控"]
---
@@ -12,7 +13,6 @@ keywords: ["告警集成", "Statuspal", "状态页", "Webhook", "服务监控"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -33,7 +33,6 @@ keywords: ["告警集成", "Statuspal", "状态页", "Webhook", "服务监控"]
</div>
## 在 Statuspal 中
----
<Steps>
<Step title="新建 Webhook">
@@ -69,7 +68,6 @@ keywords: ["告警集成", "Statuspal", "状态页", "Webhook", "服务监控"]
</Steps>
## 推送内容
----
Statuspal 推送 JSON,`event` 字段是事件类型,`data.object` 是对应的事件或服务:
@@ -97,7 +95,6 @@ Statuspal 推送 JSON,`event` 字段是事件类型,`data.object` 是对应
服务告警的标题形如 `API is down`。每条告警还带有标签 `source=statuspal` 和 `event`(推送的事件类型)。
## Alert Key
----
- 事件:事件 ID。同一事件从创建、更新到结束的每次推送落在同一条告警上
- 服务:服务 ID。同一服务的 `down` 和 `up` 推送落在同一条告警上,重复的 `down` 推送也合并到这条告警
@@ -105,7 +102,6 @@ Statuspal 推送 JSON,`event` 字段是事件类型,`data.object` 是对应
事件告警和服务告警互不影响:服务设置里开启 **Automatically create incident** 后,服务下线时 Statuspal 会创建一个事件(`incident.created`,标题形如 `Service API seems to be down`),它是一条独立的 Warning 告警,服务恢复后不会自动结束;需要在 Statuspal 中把该事件标记为已解决(`incident.updated`,`ends_at` 有值),这条告警才会恢复。服务下线时会同时产生一条服务告警和一条事件告警,可以用协作空间的[告警聚合](/zh/on-call/channel/noise-reduction)把它们合并到同一个故障。修改事件标题或服务名称不会改变 Alert Key。
## 状态和告警等级
----
Statuspal 的推送内容不包含事件的类型(major、minor)或严重程度,所以事件告警统一为 Warning。
@@ -122,7 +118,6 @@ Statuspal 的推送内容不包含事件的类型(major、minor)或严重程
计划维护(Maintenance)创建时就带有结束时间,Flashduty 把它的推送当作恢复处理;没有对应的触发告警,所以不会生成告警。
## 常见问题
----
<AccordionGroup>
<Accordion title="事件处于 Monitoring 状态时告警会恢复吗?">
@@ -145,7 +140,6 @@ Statuspal 的 Webhook 不推送事件类型和严重程度。如需按服务调
</AccordionGroup>
## 排查问题
----
- **Send test request 显示错误**:确认推送地址完整(包含 `integration_key`),且集成没有被删除
- **Flashduty 返回参数错误**:推送内容缺少 `data.object.id`,或 `monitored_status` 不是 `up`、`down`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/stripe.mdx b/zh/on-call/integration/alert-integration/alert-sources/stripe.mdx
index a2f5e850..7eb6a139 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/stripe.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/stripe.mdx
@@ -1,5 +1,6 @@
---
title: "Stripe 告警集成"
+sidebarTitle: "Stripe"
description: "通过 Webhook 将 Stripe 的拒付(Dispute)、提现失败和早期欺诈预警事件同步到 Flashduty On-call,拒付结案时自动关闭告警。"
keywords: ["告警集成", "Stripe", "拒付", "Dispute", "提现失败", "Payout", "早期欺诈预警", "Radar", "Webhook"]
---
@@ -15,7 +16,6 @@ Stripe 的所有账户都可以创建 Webhook 端点,每个账户最多 16 个
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -36,7 +36,6 @@ Stripe 的所有账户都可以创建 Webhook 端点,每个账户最多 16 个
</div>
## 在 Stripe 中配置
----
<Steps>
<Step title="创建事件目的地">
@@ -100,7 +99,6 @@ Stripe 的所有账户都可以创建 Webhook 端点,每个账户最多 16 个
</Steps>
## 推送内容
----
Stripe 每次推送一个事件(Event 对象),事件内容在 `data.object` 中:
@@ -124,7 +122,6 @@ Stripe 每次推送一个事件(Event 对象),事件内容在 `data.object
每条告警还带有标签 `source=stripe`。标题示例:`Stripe dispute needs response: fraudulent`、`Stripe inquiry under review: general`、`Stripe payout failed: account_closed`、`Stripe early fraud warning: made_with_stolen_card`。
## Alert Key
----
Flashduty 用 `data.object.id`(拒付、提现或预警本身的 ID)作为 Alert Key,不使用事件 ID:
@@ -134,7 +131,6 @@ Flashduty 用 `data.object.id`(拒付、提现或预警本身的 ID)作为 A
- Stripe 投递失败会重试(正式环境最长 3 天),偶尔也会为同一变化发送两个事件;这些事件都合并到原告警,不会生成重复告警
## 状态和告警等级
----
| Stripe 事件或状态 | Flashduty 状态或等级 |
| :--- | :--- |
@@ -149,7 +145,6 @@ Flashduty 用 `data.object.id`(拒付、提现或预警本身的 ID)作为 A
会生成告警的事件缺少 `data.object.id` 时,请求会被拒绝。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么有的拒付没有生成告警?">
@@ -172,7 +167,6 @@ Flashduty 用 `data.object.id`(拒付、提现或预警本身的 ID)作为 A
</AccordionGroup>
## 排查问题
----
- **Stripe 显示投递失败(4xx)**:确认推送地址完整(包含 `integration_key`),并且事件格式为 Snapshot
- **投递成功但没有告警**:确认事件类型在上表中;其他事件类型不生成告警
diff --git a/zh/on-call/integration/alert-integration/alert-sources/sublime.mdx b/zh/on-call/integration/alert-integration/alert-sources/sublime.mdx
index e37f8f85..35e7f83b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/sublime.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/sublime.mdx
@@ -1,5 +1,6 @@
---
title: "Sublime Security 告警集成"
+sidebarTitle: "Sublime Security"
description: "通过 Webhook Action 将 Sublime Security 标记的可疑邮件同步到 Flashduty On-call,每个邮件组一条告警。"
keywords: ["告警集成", "Sublime Security", "Sublime", "邮件安全", "钓鱼邮件", "Webhook"]
---
@@ -11,7 +12,6 @@ Sublime 只在邮件被标记时推送,没有解决或恢复通知,因此 Fl
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Sublime 只在邮件被标记时推送,没有解决或恢复通知,因此 Fl
</div>
## 在 Sublime Security 中配置
----
<Steps>
<Step title="创建 Webhook Action">
@@ -59,7 +58,6 @@ Webhook 的 **Scope** 有三个选项:**Flagged Messages**(邮件组内收
</Steps>
## 事件和恢复
----
| Sublime `type` | 含义 | 在 Flashduty 中的效果 |
| :--- | :--- | :--- |
@@ -70,12 +68,10 @@ Webhook 的 **Scope** 有三个选项:**Flagged Messages**(邮件组内收
Sublime 不推送解决通知,请在协作空间中开启[超时自动关闭](/zh/on-call/channel/create-edit),建议 7 天;也可以在处理完邮件后手动关闭告警。
## Alert Key
----
Alert Key 取 `data.message.canonical_id`,没有时取 `data.message.id`。Sublime 文档说明 `canonical_id` 是邮件所属邮件组的标识,同一封邮件投递到多个邮箱时共用。标识、分类、规则名称和严重程度的变化不会改变 Alert Key。两个字段都缺失的推送会被拒绝,错误信息指出字段名。
## 告警等级
----
取 `flagged_rules` 中严重程度最高的一条:
@@ -87,7 +83,6 @@ Alert Key 取 `data.message.canonical_id`,没有时取 `data.message.id`。Sub
| 无规则或未知值 | Warning |
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -105,12 +100,10 @@ Alert Key 取 `data.message.canonical_id`,没有时取 `data.message.id`。Sub
推送中不包含邮件主题和正文,需要详情时用 `message_id` 在 Sublime 中查看。Flashduty 不保存 `actor` 中的用户邮箱。
## 签名头
----
Sublime 会为每次推送附带 `X-Sublime-Signature` 请求头,格式为 `t=<Unix 时间戳>,v0=<HMAC 签名>`。Flashduty 推送地址通过 `integration_key` 鉴权,不校验该签名头,无需额外配置。
## 排查问题
----
- **没有收到告警**:确认 Action 已关联到规则,并检查 Action 的邮件组范围设置
- **Flashduty 返回参数错误**:推送缺少 `data.message.canonical_id` 和 `data.message.id`,手动触发且未选中邮件时会出现这种情况
diff --git a/zh/on-call/integration/alert-integration/alert-sources/sumo-logic.mdx b/zh/on-call/integration/alert-integration/alert-sources/sumo-logic.mdx
index 83ae78c9..d2e87cdb 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/sumo-logic.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/sumo-logic.mdx
@@ -1,5 +1,6 @@
---
title: "Sumo Logic 告警集成"
+sidebarTitle: "Sumo Logic"
description: "通过 Webhook 将 Sumo Logic Monitor 的触发和恢复事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Sumo Logic", "Monitor", "Webhook", "AlertResponseId"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Sumo Logic", "Monitor", "Webhook", "AlertResponseId"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Sumo Logic", "Monitor", "Webhook", "AlertResponseId"
</div>
## 在 Sumo Logic 中配置
----
<Steps>
<Step title="创建 Webhook Connection">
@@ -88,14 +87,12 @@ keywords: ["告警集成", "Sumo Logic", "Monitor", "Webhook", "AlertResponseId"
</Steps>
## Alert Key
----
Flashduty 直接使用 `AlertResponseId` 作为 Alert Key。Sumo Logic 官方将其定义为已触发告警的唯一标识;我们的真实 Monitor 验证也确认,`Critical` 触发与对应的 `ResolvedCritical` 恢复携带相同的 `AlertResponseId`。
`Id` 是 Monitor ID,一个 Monitor 在告警分组启用时可以产生多个独立告警,因此 `Id` 只作为标签,不能单独作为 Alert Key。标题、等级、时间范围、触发值和 `AlertGroup` 的变化都不会改变 Alert Key。
## 状态和告警等级
----
| Sumo Logic `TriggerType` | Flashduty 状态或等级 |
| :--- | :--- |
@@ -110,7 +107,6 @@ Flashduty 直接使用 `AlertResponseId` 作为 Alert Key。Sumo Logic 官方将
空值或未知 `TriggerType` 会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 排查问题
----
- **Sumo Logic 返回非 2xx**:确认 Push URL 完整且包含 `integration_key`
- **Flashduty 返回参数错误**:确认 Payload 是有效 JSON,且 `alert_response_id`、`trigger_type` 非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/suricata.mdx b/zh/on-call/integration/alert-integration/alert-sources/suricata.mdx
index 1edb4f73..1e5485fe 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/suricata.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/suricata.mdx
@@ -1,5 +1,6 @@
---
title: "Suricata 告警集成"
+sidebarTitle: "Suricata"
description: "Suricata 没有 Webhook 输出,通过 Wazuh 采集 Suricata 的 eve.json 日志,再用 Flashduty 的 Wazuh 集成接收 Suricata 告警。"
keywords: ["告警集成", "Suricata", "IDS", "入侵检测", "Wazuh", "eve.json", "网络安全"]
---
@@ -9,7 +10,6 @@ Suricata 只把事件写到 EVE JSON 日志,本身不能向外发 HTTP 请求
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。**集成类型都选择 Wazuh**,不是 Suricata。
@@ -30,7 +30,6 @@ Suricata 只把事件写到 EVE JSON 日志,本身不能向外发 HTTP 请求
</div>
## 数据流
----
1. Suricata 把事件以 JSON 写入 `/var/log/suricata/eve.json`
2. 装在同一台主机上的 Wazuh Agent 读取该文件
@@ -40,7 +39,6 @@ Suricata 只把事件写到 EVE JSON 日志,本身不能向外发 HTTP 请求
规则 `86601` 只匹配 Suricata 的告警事件;同一份 `eve.json` 里的 `http`、`dns`、`tls` 等事件对应的规则等级是 0,不会产生告警。
## 在 Wazuh Agent 上采集 Suricata 日志
----
在运行 Suricata 的主机的 Wazuh Agent 配置 `/var/ossec/etc/ossec.conf` 中加入:
@@ -60,7 +58,6 @@ sudo systemctl restart wazuh-agent
确认 Suricata 已开启 EVE JSON 输出,且文件路径与上面的 `location` 一致。
## 在 Wazuh 管理节点上推送到 Flashduty
----
在管理节点的 `/var/ossec/etc/ossec.conf` 中加入 `shuffle` 集成,只转发 Suricata 告警规则,并把 `hook_url` 换成 Flashduty 推送地址:
@@ -86,7 +83,6 @@ systemctl restart wazuh-manager
Docker 部署时重启 manager 容器。Wazuh 集成的完整说明、字段映射和排查方法见 [Wazuh 集成](/zh/on-call/integration/alert-integration/alert-sources/wazuh)。
## 触发并验证
----
Wazuh 官方 Suricata 示例用从另一台主机向被监控主机发 ICMP 来触发 Suricata 规则:
@@ -97,19 +93,16 @@ ping -c 20 <运行 Suricata 的主机 IP>
能否触发取决于 Suricata 是否加载了匹配 ICMP 的规则。触发后,在 Wazuh 控制台可用 `rule.groups:suricata` 过滤看到告警,Flashduty 中应出现标题为 `Suricata: Alert - <签名>` 的告警。没有收到时,查看管理节点的 `/var/ossec/logs/integrations.log` 和 `/var/ossec/logs/ossec.log`。
## 事件与恢复
----
Suricata 和 Wazuh 都只在事件发生时产生一次告警,没有恢复通知。每条 Wazuh 告警有唯一 ID,Flashduty 以它作为 Alert Key,因此每条 Suricata 告警对应一条独立的 Flashduty 告警,不会自动关闭。
请在接收该集成的协作空间开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时;同一签名反复触发时,可以在协作空间中配置降噪规则合并成一个故障。
## 告警等级
----
规则 `86601` 的等级是 3,Flashduty 按 Wazuh 规则等级映射为 Info(0-6 为 Info,7-11 为 Warning,12-15 为 Critical)。Flashduty 不读取 Suricata 自己的 `alert.severity`,如果需要区分严重程度,用 [告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines) 按标题中的签名或 `rule_id` 标签调整。
## 注意事项
----
- Suricata 事件包含源、目的 IP 和可能的载荷内容。Flashduty 不读取也不保存原始日志(`full_log`),但 `shuffle` 会把整条 Wazuh 告警发到 `hook_url`,请只转发需要人工响应的规则。
- 想只转发特定签名或类别时,在 Wazuh 中为它们写自定义规则并提高等级,再用 `<rule_id>` 或 `<level>` 过滤。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/sysdig.mdx b/zh/on-call/integration/alert-integration/alert-sources/sysdig.mdx
index 6560788b..46117ec8 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/sysdig.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/sysdig.mdx
@@ -1,5 +1,6 @@
---
title: "Sysdig 告警集成"
+sidebarTitle: "Sysdig"
description: "通过 Webhook 通知渠道将 Sysdig Monitor 告警同步到 Flashduty On-call,告警恢复时自动关闭。"
keywords: ["告警集成", "Sysdig", "Sysdig Monitor", "Webhook", "通知渠道"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Sysdig", "Sysdig Monitor", "Webhook", "通知渠道"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Sysdig", "Sysdig Monitor", "Webhook", "通知渠道"
</div>
## 在 Sysdig Monitor 中配置
----
创建通知渠道需要 Sysdig Monitor 的管理员权限。
@@ -41,16 +40,16 @@ keywords: ["告警集成", "Sysdig", "Sysdig Monitor", "Webhook", "通知渠道"
2. 点击 **Add Notification Channel**,选择 **Webhook**。请不要选择 **Custom Webhook**,Flashduty 解析的是 Webhook 渠道的固定格式
3. 按下表填写:
-| 配置项 | 填写内容 |
-| :--- | :--- |
-| **URL** | Flashduty 集成的完整推送地址,需包含 `integration_key` |
-| **Channel Name** | 便于识别的名称,如 `Flashduty` |
-| **Enabled** | 开启 |
-| **Notify when Resolved** | 开启。关闭后 Sysdig 不推送恢复通知,Flashduty 中的告警不会自动恢复 |
-| **Notify when Acknowledged** | 建议关闭。Flashduty 不同步 Sysdig 的确认状态 |
-| **Test notification** | 开启后保存时会发送一条测试通知,用于验证地址可达 |
-| **Shared With** | 按需选择 **All Teams** 或当前团队 |
-| **Custom headers** / **Custom data** | 无需填写 |
+ | 配置项 | 填写内容 |
+ | :--- | :--- |
+ | **URL** | Flashduty 集成的完整推送地址,需包含 `integration_key` |
+ | **Channel Name** | 便于识别的名称,如 `Flashduty` |
+ | **Enabled** | 开启 |
+ | **Notify when Resolved** | 开启。关闭后 Sysdig 不推送恢复通知,Flashduty 中的告警不会自动恢复 |
+ | **Notify when Acknowledged** | 建议关闭。Flashduty 不同步 Sysdig 的确认状态 |
+ | **Test notification** | 开启后保存时会发送一条测试通知,用于验证地址可达 |
+ | **Shared With** | 按需选择 **All Teams** 或当前团队 |
+ | **Custom headers** / **Custom data** | 无需填写 |
4. 点击 **Save**
@@ -75,7 +74,6 @@ keywords: ["告警集成", "Sysdig", "Sysdig Monitor", "Webhook", "通知渠道"
</Steps>
## Alert Key
----
Flashduty 使用 Sysdig 的事件 ID(`event.id`)作为 Alert Key。Sysdig 为每次告警触发生成一个事件,同一次触发的首次通知、重复通知(Renotification)和恢复通知都携带同一个事件 ID,因此会合并到同一条告警,并由恢复通知关闭。
@@ -84,7 +82,6 @@ Flashduty 使用 Sysdig 的事件 ID(`event.id`)作为 Alert Key。Sysdig
- 告警名称、严重程度、指标值和时间的变化不会改变 Alert Key。缺少 `event.id` 的请求会被拒绝
## 状态和告警等级
----
状态由 `state` 决定:
@@ -106,7 +103,6 @@ Flashduty 使用 Sysdig 的事件 ID(`event.id`)作为 Alert Key。Sysdig
告警恢复时保留最后一次触发时的等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -124,7 +120,6 @@ Flashduty 使用 Sysdig 的事件 ID(`event.id`)作为 Alert Key。Sysdig
告警描述为 Sysdig 通知正文(`alert.body`),包含指标值、分段和触发时间。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,并且渠道类型是 **Webhook** 而不是 **Custom Webhook**
- **保存渠道后没有告警**:这是预期行为,测试通知不会创建告警;请用真实告警验证
diff --git a/zh/on-call/integration/alert-integration/alert-sources/tactical-rmm.mdx b/zh/on-call/integration/alert-integration/alert-sources/tactical-rmm.mdx
index ff5dc75a..f2e12f58 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/tactical-rmm.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/tactical-rmm.mdx
@@ -1,5 +1,6 @@
---
title: "Tactical RMM 告警集成"
+sidebarTitle: "Tactical RMM"
description: "通过 Tactical RMM 告警模板的 Webhook(URL Action)将代理离线、检查和任务失败告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Tactical RMM", "Webhook", "RMM", "MSP", "远程监控管理"]
---
@@ -11,7 +12,6 @@ Tactical RMM 没有固定的 Webhook 报文格式,请求体由您在 Webhook
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Tactical RMM 没有固定的 Webhook 报文格式,请求体由您在 Webhook
</div>
## 在 Tactical RMM 中配置
----
需要创建两个 Webhook(失败一个、恢复一个),再把它们绑定到告警模板。两个 Webhook 的 URL 都是 Flashduty 推送地址,请求体只有 `status` 不同。
@@ -43,9 +42,9 @@ Tactical RMM 没有固定的 Webhook 报文格式,请求体由您在 Webhook
2. **URL Pattern** 填写 Flashduty 的完整推送地址(含 `integration_key`),请求方法选择 **POST**
3. **Request Headers** 填写:
-```json
-{ "Content-Type": "application/json" }
-```
+ ```json
+ { "Content-Type": "application/json" }
+ ```
4. **Request Body** 填写:
@@ -91,7 +90,6 @@ Tactical RMM 默认只对 Error 级别(如代理离线)和 Warning 级别的
</Steps>
## 事件类型
----
| 请求体 | 在 Flashduty 中的效果 |
| :--- | :--- |
@@ -100,14 +98,12 @@ Tactical RMM 默认只对 Error 级别(如代理离线)和 Warning 级别的
| Test 按钮(`alert_id` 和 `alert_type` 仍是未替换的 `{{alert.id}}`、`{{alert.alert_type}}`) | 创建一条独立的 Info 告警,不会恢复 |
## Alert Key
----
Flashduty 使用 `alert_id`(即 `{{alert.id}}`,Tactical RMM 中这条告警记录的编号)计算 Alert Key。同一条告警的失败和恢复 Webhook 渲染自同一条记录,编号相同。同一对象在恢复后再次失败会产生新的告警记录,因此在 Flashduty 中是一条新告警。严重程度、消息、主机名变化不会改变 Alert Key,缺少 `alert_id` 的请求会被拒绝。
一个 Flashduty 集成对应一个 Tactical RMM 实例。多个 Tactical RMM 实例的告警编号可能重复,请为每个实例创建各自的集成。
## 状态和告警等级
----
| Tactical RMM `severity` | Flashduty 等级 |
| :--- | :--- |
@@ -119,7 +115,6 @@ Flashduty 使用 `alert_id`(即 `{{alert.id}}`,Tactical RMM 中这条告警
`status` 为 `resolved` 时告警恢复,保留最后一次的告警等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -131,7 +126,6 @@ Flashduty 使用 `alert_id`(即 `{{alert.id}}`,Tactical RMM 中这条告警
| `client` / `site` | 代理所属客户和站点 |
## 排查问题
----
- **Flashduty 返回参数错误**:错误信息会指出问题字段。常见原因是请求体缺少 `alert_id`,或 `alert_type` 不是 `availability`、`check`、`task`、`custom` 之一(例如用 Test 按钮时选择了测试对象)
- **告警没有恢复**:确认已配置“恢复”Webhook 并绑定到告警模板的 Resolved Web Hook,且其 `status` 为 `resolved`;可在 Tactical RMM 的告警详情中查看动作的返回结果
diff --git a/zh/on-call/integration/alert-integration/alert-sources/tailscale.mdx b/zh/on-call/integration/alert-integration/alert-sources/tailscale.mdx
index 20aa9931..1ea1d79c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/tailscale.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/tailscale.mdx
@@ -1,5 +1,6 @@
---
title: "Tailscale 告警集成"
+sidebarTitle: "Tailscale"
description: "通过 Webhook 将 Tailscale 节点密钥过期、设备待审批和子网路由/出口节点配置错误等事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Tailscale", "tailnet", "节点密钥过期", "设备审批", "Webhook"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "Tailscale", "tailnet", "节点密钥过期", "设备
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ keywords: ["告警集成", "Tailscale", "tailnet", "节点密钥过期", "设备
</div>
## 在 Tailscale 中配置
----
<Steps>
<Step title="添加 Webhook 端点">
@@ -85,7 +84,6 @@ keywords: ["告警集成", "Tailscale", "tailnet", "节点密钥过期", "设备
</Steps>
## 推送内容
----
Tailscale 每次推送一个 JSON 数组,一个数组可包含多个事件。Flashduty 对每个会生成告警的事件分别处理:
@@ -103,7 +101,6 @@ Tailscale 每次推送一个 JSON 数组,一个数组可包含多个事件。F
每条告警还带有标签 `source=tailscale` 和 `check`(取值 `key_expiry`、`approval`、`signature`、`user_approval`、`exit_node_ip_forwarding`、`subnet_ip_forwarding`)。`message` 为空时,标题为 `Tailscale <事件类型>: <设备名或用户>`。
## Alert Key
----
Flashduty 用对象(设备的 `nodeID` 或用户的 `user`)和检查项(`check`)一起生成 Alert Key:
@@ -115,7 +112,6 @@ Flashduty 用对象(设备的 `nodeID` 或用户的 `user`)和检查项(`c
修改设备名或 tailnet 名称不会改变 Alert Key。
## 状态和告警等级
----
| Tailscale 事件 | Flashduty 状态或等级 |
| :--- | :--- |
@@ -134,7 +130,6 @@ Flashduty 用对象(设备的 `nodeID` 或用户的 `user`)和检查项(`c
会生成告警的设备事件缺少 `data.nodeID`,或用户事件缺少 `data.user` 时,整个请求会被拒绝。
## 常见问题
----
<AccordionGroup>
<Accordion title="续期节点密钥后告警为什么没有关闭?">
@@ -151,7 +146,6 @@ Tailscale 没有“密钥已续期”事件。请开启协作空间的超时自
</AccordionGroup>
## 排查问题
----
- **Flashduty 返回参数错误**:确认 **Destination** 为 **None**,推送地址完整(包含 `integration_key`)
- **测试事件成功但没有告警**:`test` 事件不生成告警;请确认端点订阅了上表中的事件
diff --git a/zh/on-call/integration/alert-integration/alert-sources/tencent-cls.mdx b/zh/on-call/integration/alert-integration/alert-sources/tencent-cls.mdx
index 1059a93d..d9bcc30c 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/tencent-cls.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/tencent-cls.mdx
@@ -1,5 +1,6 @@
---
-title: "腾讯云日志服务CLS集成"
+title: "腾讯云日志服务CLS 集成"
+sidebarTitle: "腾讯云日志服务CLS"
description: "通过 webhook 的方式同步腾讯云日志服务 CLS 监控告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "腾讯云日志服务CLS集成", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "腾讯云日志服务CLS集成", "监控告警", "
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "腾讯云日志服务CLS集成", "监控告警", "
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "腾讯云日志服务CLS集成", "监控告警", "
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **腾讯云CLS** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -44,17 +44,16 @@ keywords: ["告警集成", "腾讯云日志服务CLS集成", "监控告警", "
</AccordionGroup>
</div>
-## 在腾讯云的 CLS
----
+## 在腾讯云的 CLS
-**步骤 1:配置 通知渠道组**
+**步骤 1:配置通知渠道组**
<div className="md-block">
1. 登录您的腾讯云控制台,选择日志服务 CLS 产品,进入 监控告警 - 通知渠道组
2. 单击 `新建` 开始新建
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/integration/tencent-cls/tencent-cls-notify.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/integration/tencent-cls/tencent-cls-notify.png" />
3. 如图,`名称` 填写具体的渠道组名称,`渠道类型`选择“自定义接口回调”,`回调地址` 填写集成的推送地址,`请求方法` 选择POST
@@ -62,7 +61,7 @@ keywords: ["告警集成", "腾讯云日志服务CLS集成", "监控告警", "
</div>
-**步骤 2:配置 告警策略**
+**步骤 2:配置告警策略**
<div className="md-block">
@@ -70,7 +69,7 @@ keywords: ["告警集成", "腾讯云日志服务CLS集成", "监控告警", "
1. 登录您的腾讯云控制台,选择日志服务 CLS 产品,进入 监控告警 - 告警策略
2. 单击 `新建` 开始新建
-<img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/integration/tencent-cls/tencent-cls-alert.png" />
+ <img alt="drawing" width="600" src="https://fcpub-1301667576.cos.ap-nanjing.myqcloud.com/flashduty/integration/tencent-cls/tencent-cls-alert.png" />
3. 如图,`告警名称`填写具体的告警名称,日志主题选择具体的日志主题
@@ -85,7 +84,7 @@ keywords: ["告警集成", "腾讯云日志服务CLS集成", "监控告警", "
</div>
-**步骤 3:配置 自定义回调**
+**步骤 3:配置自定义回调**
<div className="md-block">
@@ -131,7 +130,6 @@ keywords: ["告警集成", "腾讯云日志服务CLS集成", "监控告警", "
## 状态对照
----
<div className="md-block">
腾讯云CLS监控告警级别到 Flashduty 映射关系:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/tencent-cm.mdx b/zh/on-call/integration/alert-integration/alert-sources/tencent-cm.mdx
index 178c97f4..f83e62a1 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/tencent-cm.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/tencent-cm.mdx
@@ -1,5 +1,6 @@
---
-title: "腾讯云监控 CM集成"
+title: "腾讯云监控 CM 集成"
+sidebarTitle: "腾讯云监控 CM"
description: "通过 webhook 的方式同步腾讯云监控 CM 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "腾讯云监控 CM集成", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "腾讯云监控 CM集成", "监控告警", "数据
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "腾讯云监控 CM集成", "监控告警", "数据
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "腾讯云监控 CM集成", "监控告警", "数据
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **腾讯云监控CM** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,19 +45,18 @@ keywords: ["告警集成", "腾讯云监控 CM集成", "监控告警", "数据
</div>
## 在腾讯云监控 CM
----
<div className="md-block">
1. 登录您的腾讯云控制台,选择云监控产品
-2. 进入 告警管理 -> 通知模板 页面,单击 新建 按钮,开始编辑通知模板
+2. 进入 **告警管理 → 通知模板** 页面,单击 **新建** 按钮,开始编辑通知模板
3. 填写回调地址为集成的推送地址,通知语言选择 英文
-4. 点击 保存 按钮,保存模板
+4. 点击 **保存** 按钮,保存模板
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/saas-tecent-cm-template.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/saas-tecent-cm-template.png" />
-5. 进入 告警配置 -> 告警策略 页面,选择针对所有要发送事件的告警策略,进入详情,添加上步新建的通知模板
+5. 进入 **告警配置 → 告警策略** 页面,选择针对所有要发送事件的告警策略,进入详情,添加上步新建的通知模板
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/tecent-cm-rule.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/tecent-cm-rule.png" />
6. 回到集成列表,如果展示了最新事件时间,说明配置成功且收到事件
7. 完成
@@ -65,7 +64,6 @@ keywords: ["告警集成", "腾讯云监控 CM集成", "监控告警", "数据
</div>
## 状态对照
----
<div className="md-block">
`alarmLevel` 存在时,按以下规则映射到 Flashduty 告警级别:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/tencent-css.mdx b/zh/on-call/integration/alert-integration/alert-sources/tencent-css.mdx
index cf02ff3a..e87a0792 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/tencent-css.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/tencent-css.mdx
@@ -1,5 +1,6 @@
---
title: "腾讯云直播告警集成"
+sidebarTitle: "腾讯云直播"
description: "通过直播回调把腾讯云直播(CSS)的推流中断同步到 Flashduty On-call,推流恢复或主播正常停播时自动关闭告警。"
keywords: ["告警集成", "腾讯云直播", "云直播", "CSS", "直播回调", "推流回调", "断流回调"]
---
@@ -11,7 +12,6 @@ keywords: ["告警集成", "腾讯云直播", "云直播", "CSS", "直播回调"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,14 +32,13 @@ keywords: ["告警集成", "腾讯云直播", "云直播", "CSS", "直播回调"
</div>
## 在腾讯云直播中配置
----
回调通过「回调模板」配置,模板需要绑定到推流域名后才会生效。
<Steps>
<Step title="创建回调模板">
-1. 登录 [云直播控制台](https://console.cloud.tencent.com/live),选择 **功能配置 > 直播回调**
+1. 登录 [云直播控制台](https://console.cloud.tencent.com/live),选择 **功能配置 → 直播回调**
2. 点击 **创建模板**,填写 **模板名称**
3. **回调密钥** 可以留空,也可以沿用已有设置。Flashduty 通过推送地址中的 `integration_key` 识别集成,不校验回调中的 `sign` 字段
4. 在 **回调类型** 中,在 **推流回调** 和 **断流回调** 两项填写 Flashduty 的推送地址。两项都要填写:只填断流回调时,告警不会在推流恢复后自动关闭
@@ -72,7 +71,6 @@ keywords: ["告警集成", "腾讯云直播", "云直播", "CSS", "直播回调"
</Steps>
## Alert Key
----
Flashduty 用账号 APPID `appid`、推流域名 `app`、推流路径 `appname` 和流名称 `stream_id` 计算 Alert Key。同一路流的推流回调和断流回调携带相同的这四个字段,因此落在同一条告警上。
@@ -81,7 +79,6 @@ Flashduty 用账号 APPID `appid`、推流域名 `app`、推流路径 `appname`
推流回调或断流回调缺少 `appid`、`app`、`appname` 或 `stream_id`,或回调没有 `event_type` 时,Flashduty 会拒绝该请求并返回错误,云直播会按回调重试规则重试。
## 告警生命周期
----
| 云直播回调 | Flashduty 处理 |
| :--- | :--- |
@@ -99,12 +96,10 @@ Flashduty 用账号 APPID `appid`、推流域名 `app`、推流路径 `appname`
</Warning>
## 告警等级
----
回调中没有等级字段。异常断流触发的告警一律为 **Critical**。`errcode` 表示断流原因,会写入标签和描述,含义请参阅云直播文档中的错误码表。
## 告警内容
----
- **标题**:异常断流时为 `Live stream interrupted: <推流域名>/<推流路径>/<流名称>`
- **描述**:错误描述 `errmsg`,后附错误码、推流节点 IP、推流端 IP 和推流时长(毫秒)
@@ -113,7 +108,6 @@ Flashduty 用账号 APPID `appid`、推流域名 `app`、推流路径 `appname`
回调中的 `stream_param`(推流 URL 参数,可能包含推流鉴权的 `txSecret`)、`sign` 和 `t` 不会写入标签。
## 排查问题
----
- **Flashduty 没有收到回调**:确认回调模板已绑定到实际推流的域名,且绑定后已等待 5 到 10 分钟;确认模板中的推流回调和断流回调填写的是完整推送地址,包含 `integration_key`
- **主播停播后产生了告警**:只有推流端主动停止推流时 `errcode` 才为 `1`。推流端被强制结束(例如进程退出或网络中断)时,断流回调的 `errcode` 通常不为 `1`,Flashduty 按异常断流触发告警。可以在告警标签 `errcode` 和 `errmsg` 中查看云直播给出的断流原因
diff --git a/zh/on-call/integration/alert-integration/alert-sources/tencent-eventbridge.mdx b/zh/on-call/integration/alert-integration/alert-sources/tencent-eventbridge.mdx
index 2d4c8671..38906584 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/tencent-eventbridge.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/tencent-eventbridge.mdx
@@ -1,5 +1,6 @@
---
-title: "腾讯云EventBridge"
+title: "腾讯云 EventBridge"
+sidebarTitle: "腾讯云 EventBridge"
description: "通过 webhook 的方式同步腾讯云事件总线 EB 事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "腾讯云EventBridge", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "腾讯云EventBridge", "监控告警", "数据接入
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "腾讯云EventBridge", "监控告警", "数据接入
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "腾讯云EventBridge", "监控告警", "数据接入
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **腾讯云EventBridge** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,38 +45,37 @@ keywords: ["告警集成", "腾讯云EventBridge", "监控告警", "数据接入
</div>
## 在腾讯云 EventBridge
----
<div className="md-block">
1. 登录您的腾讯云控制台,选择事件总线产品
-2. 进入 事件规则 页面,单击 新建 按钮,开始编辑规则
+2. 进入 **事件规则** 页面,单击 **新建** 按钮,开始编辑规则
3. 填写名称为 Flashduty,如下图所示:
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-new-rule.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-new-rule.png" />
4. 事件匹配部分可以通过表单模式选择特定事件,也可以自定义填写以下 JSON 内容,匹配全部事件:
-```
-{
- "source": [
- {
- "suffix": ".cloud.tencent"
- }
- ]
-}
-```
+ ```
+ {
+ "source": [
+ {
+ "suffix": ".cloud.tencent"
+ }
+ ]
+ }
+ ```
-图示如下:
+ 图示如下:
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-match-rule.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-match-rule.png" />
5. 下一步,配置事件目标,分别选择”消息推送“、”通用通知模板“、”英文“,”接口回调“和”自定义 webhook“,webhook 地址填写集成的推送地址
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-target-webhook.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-target-webhook.png" />
-6. 点击 保存 按钮,回到 事件集 页面,选择一个事件集,点击 发送事件,进行测试
+6. 点击 **保存** 按钮,回到 事件集 页面,选择一个事件集,点击 发送事件,进行测试
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-test-send.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/tencent-eb-test-send.png" />
7. 回到集成列表,如果展示了最新事件时间,说明配置成功且收到事件
8. 完成
@@ -84,7 +83,6 @@ keywords: ["告警集成", "腾讯云EventBridge", "监控告警", "数据接入
</div>
## 状态对照
----
<div className="md-block">
腾讯云事件总线所有事件均对应到 Flashduty On-call “警告(warning)”级别告警。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/thinkst-canary.mdx b/zh/on-call/integration/alert-integration/alert-sources/thinkst-canary.mdx
index 88e8fc32..c4fd8898 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/thinkst-canary.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/thinkst-canary.mdx
@@ -1,5 +1,6 @@
---
title: "Thinkst Canary 告警集成"
+sidebarTitle: "Thinkst Canary"
description: "通过 Thinkst Canary 控制台的通用 Webhook 将蜜罐设备和 Canarytoken 的入侵事件同步到 Flashduty On-call,每个事件生成一条告警。"
keywords: ["告警集成", "Thinkst Canary", "Canarytoken", "Webhook", "蜜罐", "入侵检测"]
---
@@ -9,7 +10,6 @@ Thinkst Canary 是蜜罐与蜜标(Canarytoken)产品。有人访问诱饵设
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Thinkst Canary 是蜜罐与蜜标(Canarytoken)产品。有人访问诱饵设
</div>
## 在 Thinkst Canary 中配置
----
<Steps>
<Step title="添加通用 Webhook">
@@ -53,22 +52,18 @@ Canary 也可以把控制台审计事件(`{"type":"console-audit"}`,例如
</Steps>
## Alert Key
----
Flashduty 使用事件中的 `IncidentHash`(事件哈希)作为 Alert Key。Canary 设备事件和 Canarytoken 事件都带有该字段,相同的事件哈希会合并到同一条告警;请求缺少 `IncidentHash` 时,Flashduty 会拒绝该请求(测试事件除外)。
## 告警生命周期
----
Canary 只发送事件触发消息,没有恢复消息。请在协作空间开启[超时自动关闭](/zh/on-call/channel/create-edit),超时计时起点选 **故障触发**,超时时长建议 24 小时,也可以按响应流程调整。
## 告警等级
----
Canary 的消息没有等级字段。`AlertType` 为 `CanaryIncident`(设备事件)或 `CanarytokenIncident`(蜜标事件)时为 **Critical**,因为任何对诱饵的访问都是入侵信号;其他取值为 **Warning**。需要调整时,可在协作空间的告警处理规则中按 `alert_type` 或 `log_type` 标签重设等级。
## 告警内容
----
- **标题**:事件类型(`Description`)
- **描述**:事件摘要(`Intro`)
@@ -77,12 +72,10 @@ Canary 的消息没有等级字段。`AlertType` 为 `CanaryIncident`(设备
`AdditionalDetails`(请求明细,可能含用户名等)和蜜标的 Token 值不会写入告警。
## 关于签名
----
Canary 通用 Webhook 的文档没有说明请求签名,Flashduty 通过推送地址中的 `integration_key` 识别集成。
## 排查问题
----
- **没有收到告警**:确认 Webhook 地址是完整的推送地址,且集成没有被停用;控制台需要能访问公网地址
- **只看到 Info 告警**:这是保存 Webhook 时的测试事件,真实事件在设备或蜜标被触发后才会发送
diff --git a/zh/on-call/integration/alert-integration/alert-sources/thousandeyes.mdx b/zh/on-call/integration/alert-integration/alert-sources/thousandeyes.mdx
index cd7127de..7991d965 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/thousandeyes.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/thousandeyes.mdx
@@ -1,5 +1,6 @@
---
title: "ThousandEyes 告警集成"
+sidebarTitle: "ThousandEyes"
description: "通过 Classic Webhook 将 Cisco ThousandEyes 告警同步到 Flashduty On-call,告警清除时自动恢复。"
keywords: ["告警集成", "ThousandEyes", "Cisco ThousandEyes", "Webhook", "Classic Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "ThousandEyes", "Cisco ThousandEyes", "Webhook", "Cla
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "ThousandEyes", "Cisco ThousandEyes", "Webhook", "Cla
</div>
## 在 ThousandEyes 中配置
----
编辑告警规则和 Webhook 需要 ThousandEyes 中管理告警规则的权限。ThousandEyes for Government 实例不支持 Webhook 告警通知。
@@ -42,11 +41,11 @@ keywords: ["告警集成", "ThousandEyes", "Cisco ThousandEyes", "Webhook", "Cla
3. 在 **Webhooks** 区域点击 **Configure Webhooks**(已有 Webhook 时为 **Edit webhooks**),然后点击 **Add New Webhook**
4. 按下表填写:
-| 配置项 | 填写内容 |
-| :--- | :--- |
-| **Name** | 便于识别的名称,如 `Flashduty` |
-| **URL** | Flashduty 集成的完整推送地址,需包含 `integration_key`。请粘贴未经 URL 编码的原始地址。ThousandEyes 不跟随 HTTP 重定向,请使用复制得到的最终地址 |
-| **Auth Type** | 选择 **None**,Flashduty 通过地址中的 `integration_key` 认证 |
+ | 配置项 | 填写内容 |
+ | :--- | :--- |
+ | **Name** | 便于识别的名称,如 `Flashduty` |
+ | **URL** | Flashduty 集成的完整推送地址,需包含 `integration_key`。请粘贴未经 URL 编码的原始地址。ThousandEyes 不跟随 HTTP 重定向,请使用复制得到的最终地址 |
+ | **Auth Type** | 选择 **None**,Flashduty 通过地址中的 `integration_key` 认证 |
5. 点击 **Test**,看到 **Webhook test completed successfully** 即表示地址可达
6. 保存该 Webhook
@@ -75,7 +74,6 @@ keywords: ["告警集成", "ThousandEyes", "Cisco ThousandEyes", "Webhook", "Cla
</Steps>
## Alert Key
----
Flashduty 使用 ThousandEyes 的告警 ID(`alert.alertId`)作为 Alert Key。ThousandEyes 为每个生成的告警分配唯一的 `alertId`,同一个告警的触发通知和清除通知携带相同的 `alertId`,因此清除通知会恢复对应的 Flashduty 告警。
@@ -84,7 +82,6 @@ Flashduty 使用 ThousandEyes 的告警 ID(`alert.alertId`)作为 Alert Key
- 每次推送的 `eventId` 都不同,不参与 Alert Key。规则名称、严重程度、指标值和时间的变化也不会改变 Alert Key。缺少 `alert.alertId` 的请求会被拒绝
## 状态和告警等级
----
状态由 `eventType` 决定:
@@ -107,7 +104,6 @@ Flashduty 使用 ThousandEyes 的告警 ID(`alert.alertId`)作为 Alert Key
在 ThousandEyes 中用 **Add New Alert Rule** 新建的告警规则默认严重程度是 **Info**,这类告警在 Flashduty 中是 Info 等级;内置的默认告警规则(Default Alert Rules)默认是 **Minor**。需要更高等级时,请在 ThousandEyes 中修改告警规则的 **Severity**。告警恢复时保留触发时的等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -123,10 +119,9 @@ Flashduty 使用 ThousandEyes 的告警 ID(`alert.alertId`)作为 Alert Key
| `agents` | 触发告警的代理名称,逗号分隔(测试告警) |
| `agent_id` / `agent_name` / `host` / `ip_address` | 代理 ID、名称、主机名和 IP(代理通知) |
-告警标题为「告警规则名称: 测试名称」,代理通知为「告警规则名称: 代理名称」。告警描述包含告警条件和各代理触发时的指标。
+告警标题为「告警规则名称:测试名称」,代理通知为「告警规则名称:代理名称」。告警描述包含告警条件和各代理触发时的指标。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整、未经编码且包含 `integration_key`,并且使用的是告警规则里的 Classic Webhook,而不是 Custom Webhook
- **点击 Test 后没有告警**:这是预期行为,测试事件不会创建告警;请用真实告警验证
diff --git a/zh/on-call/integration/alert-integration/alert-sources/tideways.mdx b/zh/on-call/integration/alert-integration/alert-sources/tideways.mdx
index 81d23815..90f2fdb9 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/tideways.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/tideways.mdx
@@ -1,5 +1,6 @@
---
title: "Tideways 告警集成"
+sidebarTitle: "Tideways"
description: "通过 Webhook 将 Tideways 的响应时间、错误率、数据中断、异常和慢 SQL 通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Tideways", "PHP", "APM", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Tideways", "PHP", "APM", "Webhook"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Tideways", "PHP", "APM", "Webhook"]
</div>
## 在 Tideways 中配置
----
需要组织的管理权限。Tideways 的 Webhook 只支持 HTTPS 地址,且请求不带签名和自定义请求头,Flashduty 通过推送地址中的 `integration_key` 识别集成,请勿泄露该地址。
@@ -71,7 +70,6 @@ keywords: ["告警集成", "Tideways", "PHP", "APM", "Webhook"]
</Steps>
## Alert Key
----
响应时间、失败率和事务响应时间 Incident 使用 Incident ID(`notification.incident_id`)与通知类型、组织、应用一起计算 Alert Key。Tideways 文档说明,这三类通知的 `status` 为 `opened`、`ongoing` 或 `closed`,对应同一个 Incident 的不同阶段;`incidient_id` 是 `incident_id` 的历史拼写副本,值相同,Flashduty 在缺少 `incident_id` 时读取它。缺少两者的 Incident 通知会被拒绝,未知的 `status` 同样会被拒绝。
@@ -83,7 +81,6 @@ keywords: ["告警集成", "Tideways", "PHP", "APM", "Webhook"]
数值、时间、阈值和分组的出现次数变化都不会改变 Alert Key。错误分组状态为 `resolved`、`not_error` 或 `ignored` 的通知会恢复该分组对应的告警。异常规则只在错误首次出现、再次出现(发布后)、重新打开和未确认时通知,因此分组被标记为已解决时实际不会产生通知;重新打开的分组会合并到原告警。
## 状态和告警等级
----
Tideways 通知不带告警等级,Flashduty 按类型设置:
@@ -97,14 +94,12 @@ Tideways 通知不带告警等级,Flashduty 按类型设置:
`status` 为 `closed`,或错误分组状态为 `resolved`、`not_error`、`ignored` 时告警恢复,恢复事件保留最近一次的告警等级。
## 告警不会自动恢复的情况
----
事务失败率和数据中断只在出现时发送一次,Tideways 没有对应的恢复通知,告警不会自动恢复。异常和慢 SQL 告警在错误分组被标记为已解决或已忽略后仍保持活动,因为 Tideways 不会为此发送通知。
建议在协作空间开启[超时自动关闭](/zh/on-call/channel/create-edit),超时计时起点选 **故障触发**,超时时长建议 24 小时。数据中断和新异常一般在一个工作日内确认处理;如果协作空间只接收响应时间和失败率通知,可以不开启。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -117,7 +112,6 @@ Tideways 通知不带告警等级,Flashduty 按类型设置:
| `error_group_id` / `exception_type` / `source_location` / `occurrences` | 错误分组 ID、异常类型、来源位置和累计次数,仅异常和慢 SQL |
## 排查问题
----
- **Tideways 显示推送失败**:确认地址使用 HTTPS 且包含 `integration_key`。Tideways 不重试,返回 400 及以上状态码的推送只记录在集成页的错误日志中
- **Flashduty 返回参数错误**:错误信息会指出缺少的字段(如 `notification.incident_id`)或不支持的 `type`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/tracee.mdx b/zh/on-call/integration/alert-integration/alert-sources/tracee.mdx
index a76f05ef..c33d2dbd 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/tracee.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/tracee.mdx
@@ -1,5 +1,6 @@
---
title: "Aqua Tracee 告警集成"
+sidebarTitle: "Aqua Tracee"
description: "通过 Tracee 的 Webhook 输出目的地,将运行时安全检测事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Aqua Tracee", "Tracee", "eBPF", "运行时安全", "Webhook"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Aqua Tracee", "Tracee", "eBPF", "运行时安全", "
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Aqua Tracee", "Tracee", "eBPF", "运行时安全", "
</div>
## 在 Tracee 中配置
----
<Steps>
<Step title="添加 Webhook 输出目的地">
@@ -109,7 +108,6 @@ curl -X POST 'https://api.flashcat.cloud/event/push/alert/tracee?integration_key
</Steps>
## Alert Key
----
Tracee 的事件没有唯一 ID。Flashduty 用规则标识加运行位置组成 Alert Key(对 `"tracee"`、规则标识、运行位置用 NUL 分隔后取 MD5):
@@ -123,7 +121,6 @@ Tracee 的事件没有唯一 ID。Flashduty 用规则标识加运行位置组成
</Note>
## 告警等级
----
Tracee 的 `threat.severity` 在默认 JSON 中为数字(`INFO`=0 到 `CRITICAL`=4):
@@ -135,12 +132,10 @@ Tracee 的 `threat.severity` 在默认 JSON 中为数字(`INFO`=0 到 `CRITICA
| 空值或未知值 | Warning |
## 标签
----
Flashduty 写入以下标签(有值才写入):`rule_id`、`signature_id`、`event_name`、`category`、`threat_severity`、`mitre_tactic`、`mitre_technique_id`、`mitre_technique`、`container_id`、`container_name`、`image`、`pod`、`namespace`、`process`、`executable`、`pid`、`host_pid`、`policies`、`detected_from`。事件的 `data` 数组(文件路径、命令参数等)不会写入标签。
## 排查问题
----
- **Tracee 日志出现 `Error sending webhook, http status`**:确认 URL 完整且包含 `integration_key`
- **没有收到告警**:确认事件带有 `threat` 字段;普通事件不会产生告警,且 stream 的 `events` 需要包含该检测事件
diff --git a/zh/on-call/integration/alert-integration/alert-sources/trigger-dev.mdx b/zh/on-call/integration/alert-integration/alert-sources/trigger-dev.mdx
index 9034d080..4ce41f51 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/trigger-dev.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/trigger-dev.mdx
@@ -1,5 +1,6 @@
---
title: "Trigger.dev 告警集成"
+sidebarTitle: "Trigger.dev"
description: "通过 Webhook 告警渠道将 Trigger.dev 的任务运行失败、错误分组和部署失败事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Trigger.dev", "Webhook", "后台任务", "部署失败"]
---
@@ -13,7 +14,6 @@ keywords: ["告警集成", "Trigger.dev", "Webhook", "后台任务", "部署失
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -34,7 +34,6 @@ keywords: ["告警集成", "Trigger.dev", "Webhook", "后台任务", "部署失
</div>
## 在 Trigger.dev 中配置
----
Webhook 渠道按项目和环境创建。云服务的免费套餐包含 1 个告警渠道(Webhook、邮件、Slack 合计),套餐用量用完后需要升级或删除已有渠道。
@@ -67,14 +66,12 @@ Trigger.dev 的告警渠道没有测试按钮。触发一个会失败的任务
Trigger.dev 会为每个 Webhook 渠道生成一个签名密钥,并在请求头 `x-trigger-signature-hmacsha256` 中携带签名。Flashduty 不校验该签名,访问凭据是推送地址中的 `integration_key`。
## 运行失败和错误分组不会恢复
----
这两类告警没有恢复通知。在接收该集成的协作空间中开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议运行失败 12 小时、错误分组 24 小时,并按团队处理失败任务的时效调整。每个失败的运行是一条独立告警;同一错误分组在被标记为已解决(或忽略条件被突破)后再次推送,会更新同一条告警,告警被关闭后再次推送则创建新的告警。
Trigger.dev 的错误分组告警只在状态变化时推送:处于 Unresolved 的分组不会重复推送。如果需要知道每一次运行失败,请使用运行失败告警。
## Alert Key
----
| 事件类型 | Alert Key |
| :--- | :--- |
@@ -85,7 +82,6 @@ Trigger.dev 的错误分组告警只在状态变化时推送:处于 Unresolved
请求最外层的 `id` 是每次推送的投递 ID,不参与 Alert Key。部署的 `deployment.id` 每次部署都不同,所以失败与成功用环境区分:同一环境下,成功的部署恢复该环境的部署失败告警。标题、错误信息、发生次数、`classification` 的变化都不会改变 Alert Key。缺少上述字段的事件会被拒绝;`type` 不是上表中的取值时也会被拒绝。
## 状态和告警等级
----
| 事件类型 | 状态 | Flashduty 等级 |
| :--- | :--- | :--- |
@@ -97,7 +93,6 @@ Trigger.dev 的错误分组告警只在状态变化时推送:处于 Unresolved
Trigger.dev 的告警不带严重级别,失败类事件统一按 Critical 处理。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -114,7 +109,6 @@ Trigger.dev 的告警不带严重级别,失败类事件统一按 Critical 处
| `organization` / `project` / `project_ref` | 组织名称、项目名称和引用 |
## 排查问题
----
- **Flashduty 没有收到事件**:运行失败告警要等任务重试耗尽后才推送;确认渠道创建在发生失败的环境中,并勾选了对应的告警类型。Trigger.dev 要求 Webhook 地址为公网可访问的地址
- **Flashduty 返回参数错误**:确认请求体包含 `type` 和 `object` 字段(实际推送中运行和部署事件的 `webhookVersion` 为 `v1`,错误分组事件为 `2025-01-01`),并且勾选的是上述支持的告警类型。旧版 Webhook 渠道的请求体没有 `type` 和 `object` 字段,不被支持,请删除后重新创建渠道
diff --git a/zh/on-call/integration/alert-integration/alert-sources/trivy-operator.mdx b/zh/on-call/integration/alert-integration/alert-sources/trivy-operator.mdx
index 0e04cdf4..0b0c97c4 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/trivy-operator.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/trivy-operator.mdx
@@ -1,5 +1,6 @@
---
title: "Trivy Operator 告警集成"
+sidebarTitle: "Trivy Operator"
description: "通过 Webhook 广播将 Aqua Trivy Operator 生成的漏洞、暴露密钥和配置审计报告同步到 Flashduty On-call。"
keywords: ["告警集成", "Trivy Operator", "Aqua Security", "Trivy", "Kubernetes", "漏洞扫描", "容器安全", "Webhook"]
---
@@ -9,7 +10,6 @@ Trivy Operator 是 Aqua Security 开源的 Kubernetes 安全扫描组件,会
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Trivy Operator 是 Aqua Security 开源的 Kubernetes 安全扫描组件,会
</div>
## 在 Trivy Operator 中配置
----
需要有修改 Trivy Operator 部署配置的权限,且 Operator 所在网络能通过 HTTPS 访问 Flashduty 推送地址。
@@ -66,14 +65,12 @@ Trivy Operator 没有测试按钮。重启或等待 Operator 完成一次扫描
</Steps>
## Alert Key
----
Flashduty 使用报告对象的 UID(请求体中的 `metadata.uid`)作为 Alert Key。Trivy Operator 会在报告变化时重新推送同一个对象,UID 保持不变,这些推送会合并到同一条告警;不同的工作负载、容器或报告类型对应不同的 UID,互不影响。工作负载被重建、报告对象被删除后重新生成时会得到新的 UID,对应一条新的告警。
报告名称、镜像标签、扫描器版本和摘要数量的变化都不会改变 Alert Key。缺少 `metadata.uid` 的请求会被拒绝。请求体超过 4 MiB 时会返回参数错误;描述最多列出最严重的 10 条发现,大报告不会让告警变大。
## 状态和告警等级
----
Flashduty 按报告摘要(`report.summary`)中的数量映射告警等级:
@@ -89,7 +86,6 @@ Flashduty 按报告摘要(`report.summary`)中的数量映射告警等级:
没有严重程度摘要的报告(SBOM 报告、合规报告)以及报告被删除的消息,Flashduty 返回成功但不创建告警。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -107,7 +103,6 @@ Flashduty 按报告摘要(`report.summary`)中的数量映射告警等级:
告警描述包含摘要数量,以及最严重的前 10 条问题。暴露密钥只列出规则 ID 和文件路径,不包含匹配到的内容。完整报告可用 `kubectl get vulnerabilityreports -n <namespace> -o yaml` 查看。
## 排查问题
----
- **没有收到告警**:确认 `operator.webhookBroadcastURL` 已生效(查看 Operator Pod 的环境变量 `OPERATOR_WEBHOOK_BROADCAST_URL`),Operator 日志中没有推送失败;Operator 不检查响应状态,也不重试失败的请求
- **没有恢复**:Operator 不发送“已解决”通知;只有报告重新扫描且摘要全为 0 才会恢复,其余情况请开启协作空间的超时自动关闭
diff --git a/zh/on-call/integration/alert-integration/alert-sources/twilio.mdx b/zh/on-call/integration/alert-integration/alert-sources/twilio.mdx
index 269e9e7b..b37fec78 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/twilio.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/twilio.mdx
@@ -1,5 +1,6 @@
---
title: "Twilio 告警集成"
+sidebarTitle: "Twilio"
description: "通过 Error webhook 将 Twilio Debugger 中的 Error 级别事件同步到 Flashduty On-call,同一账户的同一错误码合并为一条告警。"
keywords: ["告警集成", "Twilio", "Debugger", "Error webhook", "错误码", "Webhook"]
---
@@ -14,7 +15,6 @@ Error webhook 在 Twilio 的所有区域(US1、IE、AU)都可以使用。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -35,7 +35,6 @@ Error webhook 在 Twilio 的所有区域(US1、IE、AU)都可以使用。
</div>
## 在 Twilio 中配置
----
<Steps>
<Step title="填写 Error webhook">
@@ -65,7 +64,6 @@ Debugger 事件是一次性的日志,Twilio 不会在错误消失后再发送
</Steps>
## 推送内容
----
Twilio 每次推送一个 Debugger 事件,请求体为 `application/x-www-form-urlencoded`,其中 `Payload` 是 JSON:
@@ -86,7 +84,6 @@ Twilio 每次推送一个 Debugger 事件,请求体为 `application/x-www-form
每条告警还带有标签 `source=twilio`,描述中附有该错误码在 Twilio 错误字典中的链接(`https://www.twilio.com/docs/errors/<错误码>`)。标题示例:`Twilio error 11200: An attempt to retrieve content from https://app.example.com/voice returned the HTTP status code 404`。
## Alert Key
----
Flashduty 用 `AccountSid` 和 `Payload.error_code` 共同计算 Alert Key,不使用事件 ID `Sid`:
@@ -95,7 +92,6 @@ Flashduty 用 `AccountSid` 和 `Payload.error_code` 共同计算 Alert Key,不
- 这与 Twilio [Alarms](https://www.twilio.com/docs/usage/troubleshooting/alarms) 按账户、按错误码统计错误的方式一致
## 状态和告警等级
----
| Twilio 事件级别 | Flashduty 状态或等级 |
| :--- | :--- |
@@ -105,7 +101,6 @@ Flashduty 用 `AccountSid` 和 `Payload.error_code` 共同计算 Alert Key,不
Error 事件缺少 `AccountSid` 或 `Payload.error_code`,或 `Payload` 不是合法的 JSON 时,请求会被拒绝。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么 Warning 事件没有生成告警?">
@@ -128,7 +123,6 @@ Twilio 把请求仍能被处理的问题记为 Warning,例如 TwiML 校验警
</AccordionGroup>
## 排查问题
----
- **Twilio 的 Debugger 中出现错误但 Flashduty 没有告警**:确认 **Monitor** → **Error webhook** 中的地址完整(包含 `integration_key`),并且事件级别为 Error
- **请求被拒绝(4xx)**:确认推送地址是 Twilio 集成的地址,不是其他集成的地址
diff --git a/zh/on-call/integration/alert-integration/alert-sources/twingate.mdx b/zh/on-call/integration/alert-integration/alert-sources/twingate.mdx
index f5efde32..4f211d7e 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/twingate.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/twingate.mdx
@@ -1,5 +1,6 @@
---
title: "Twingate 告警集成"
+sidebarTitle: "Twingate"
description: "通过通知 Webhook 将 Twingate 连接器离线、事件同步和集成错误、密钥到期等通知同步到 Flashduty On-call,可恢复的通知会自动关闭告警。"
keywords: ["告警集成", "Twingate", "零信任", "Connector", "Webhook"]
---
@@ -9,7 +10,6 @@ Twingate 管理控制台的通知支持发送到 Webhook。本集成接收这些
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Twingate 管理控制台的通知支持发送到 Webhook。本集成接收这些
</div>
## 在 Twingate 中配置
----
<Steps>
<Step title="添加 Webhook">
@@ -51,7 +50,6 @@ Twingate 管理控制台的通知支持发送到 Webhook。本集成接收这些
<Note>Twingate 通知 Webhook 没有签名头,也不需要配置密钥。推送地址中的 `integration_key` 相当于凭证,请勿公开。</Note>
## Alert Key
----
Twingate 的通知没有独立的告警编号,Flashduty 按通知类型分组计算 Alert Key(同时包含租户 `tenant`):
@@ -71,7 +69,6 @@ Twingate 的通知没有独立的告警编号,Flashduty 按通知类型分组
以下通知不产生告警,Flashduty 返回成功:`CLIENT_UPDATE_RECOMMENDED`、`CLIENT_UPDATE_REQUIRED`、`CONNECTOR_UPGRADE_AVAILABLE`。
## 告警等级
----
Twingate 通知没有等级字段,Flashduty 按通知类型设置:
@@ -84,19 +81,16 @@ Twingate 通知没有等级字段,Flashduty 按通知类型设置:
恢复通知沿用对应触发通知的等级。
## 告警内容
----
- **标题**:通知的 `message`;没有时为 `Twingate <type>`
- **描述**:访问请求的申请理由 `reason`,以及 `table` 中每一行的键值(最多 20 行;名称里含 key、token、secret 的字段不写入)
- **标签**:`tenant`、`type`、`check`(通知分组)、`integration`、`sync_type`、`platform`、`days_remaining`、`request_id`、`user_name`、`resource_name`、`approval_mode`、`request_type`
## 不会恢复的通知
----
密钥和令牌到期、Google Workspace 同步错误、访问请求都是单次通知,Twingate 不会发送恢复通知。请在协作空间中开启[超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时;同一对象重复通知会合并到同一条告警。
## 排查问题
----
- **Twingate 提示 Webhook 报错**:Twingate 要求接收端接受 POST 和 JSON。确认填写的是完整推送地址且包含 `integration_key`
- **连接器上线后告警没有关闭**:确认勾选了 Connectors online 通知;Flashduty 按远程网络加连接器名称匹配上线通知;连接器改名后,旧名称的告警需要手动关闭
diff --git a/zh/on-call/integration/alert-integration/alert-sources/ucloud-cloudwatch.mdx b/zh/on-call/integration/alert-integration/alert-sources/ucloud-cloudwatch.mdx
index 9bf13e32..5c229f8e 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/ucloud-cloudwatch.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/ucloud-cloudwatch.mdx
@@ -1,53 +1,52 @@
---
title: "UCloud CloudWatch 告警集成"
+sidebarTitle: "UCloud CloudWatch"
description: "通过 webhook 的方式同步 UCloud CloudWatch 的告警事件到 Flashduty,实现告警事件自动化降噪处理"
keywords: ["UCloud", "CloudWatch", "告警集成", "webhook", "云监控"]
---
-通过 webhook 的方式同步 Ucloud CloudWatch 的告警事件到 Flashduty,实现告警事件自动化降噪处理。
+通过 webhook 的方式同步 UCloud CloudWatch 的告警事件到 Flashduty,实现告警事件自动化降噪处理。
<div class="hide">
## 在 Flashduty
----
-
-### 创建 Ucloud CloudWatch 告警集成
-您可通过以下2种方式,获取一个企微机器人告警集成地址,任选其一即可。
+您可通过以下两种方式获取一个UCloud CloudWatch 告警集成地址,任选其一即可。
-#### 使用专属集成
+### 使用专属集成
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
-<details>
- <summary>展开</summary>
+<AccordionGroup>
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
- 3. 选择 **Ucloud CloudWatch** 集成,点击 **保存**,生成卡片。
- 4. 点击生成的卡片,可以查看到 **火山引擎 RTC 告警集成地址**,复制备用,完成。
+ 3. 选择 **UCloud CloudWatch** 集成,点击 **保存**,生成卡片。
+ 4. 点击生成的卡片,可以查看到 **UCloud CloudWatch 告警集成地址**,复制备用,完成。
-</details>
+</Accordion>
+</AccordionGroup>
-#### 使用共享集成
+### 使用共享集成
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
-<details>
- <summary>展开</summary>
+<AccordionGroup>
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
- 2. 选择 **Ucloud CloudWatch** 集成:
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
+ 2. 选择 **UCloud CloudWatch** 集成:
- **集成名称**:为当前集成定义一个名称。
- - **推送模式**:选择企微告警在何种情况下触发或恢复告警。
- 3. 复制当前页面的 **Ucloud CloudWatch 告警集成地址** 备用。
+ - **推送模式**:选择 UCloud CloudWatch 告警在何种情况下触发或恢复 Flashduty 告警。
+ 3. 复制当前页面的 **UCloud CloudWatch 告警集成地址** 备用。
4. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
5. 完成。
-</details>
+</Accordion>
+</AccordionGroup>
-## 在 Ucloud
----
+## 在 UCloud
</div>
@@ -61,7 +60,7 @@ keywords: ["UCloud", "CloudWatch", "告警集成", "webhook", "云监控"]
6. 其他选项按需配置。
7. 点击 `提交` 完成配置。
-
+
### 步骤2:配置告警策略
1. 登录您的 Ucloud 控制台,检索 `CloudWatch` 产品,并进入对应产品控制台。
@@ -72,5 +71,4 @@ keywords: ["UCloud", "CloudWatch", "告警集成", "webhook", "云监控"]
## 严重程度映射关系
----
-当前 Ucloud CloudWatch 告警集成推送到 Flashduty 的严重程度均为 Warning,但您可以通过[告警处理 Pipeline](https://docs.flashduty.com/zh/on-call/integration/alert-integration/alert-pipelines) 来自定义严重程度。
+当前 UCloud CloudWatch 告警集成推送到 Flashduty 的严重程度均为 Warning,但您可以通过[告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines) 来自定义严重程度。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/updown.mdx b/zh/on-call/integration/alert-integration/alert-sources/updown.mdx
index ddf09858..87d5c61b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/updown.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/updown.mdx
@@ -1,5 +1,6 @@
---
title: "updown.io 告警集成"
+sidebarTitle: "updown.io"
description: "通过 Webhook 将 updown.io 的宕机、恢复、SSL 证书异常和性能下降通知同步到 Flashduty On-call。"
keywords: ["告警集成", "updown.io", "Updown", "Uptime", "Webhook", "SSL", "check.down", "check.up"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "updown.io", "Updown", "Uptime", "Webhook", "SSL", "c
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "updown.io", "Updown", "Uptime", "Webhook", "SSL", "c
</div>
## 在 updown.io 中配置
----
<Steps>
<Step title="添加 Webhook 地址">
@@ -51,7 +50,6 @@ updown.io 对该地址的要求只有返回 2xx;非 2xx 会被重试最多 25
</Steps>
## 推送内容
----
updown.io 以 JSON 数组 POST 事件(同一请求可能包含多个事件),Flashduty 直接解析,无需配置模板:
@@ -72,7 +70,6 @@ updown.io 以 JSON 数组 POST 事件(同一请求可能包含多个事件)
updown.io 之后新增的事件类型会被忽略并返回成功,不会创建告警。
## Alert Key
----
- 宕机和恢复:使用 `check.token` 作为 Alert Key。同一个监控的 `check.down` 与 `check.up` 携带相同的 `check.token`,落在同一条告警上;不同监控生成不同的告警。修改监控别名、状态码或错误信息不会改变 Alert Key。
- 证书无效:`check.token` 加 `:ssl_invalid`,由 `check.ssl_valid` 恢复。
@@ -82,7 +79,6 @@ updown.io 之后新增的事件类型会被忽略并返回成功,不会创建
各类事件的 Alert Key 互不相同,因此监控恢复不会关闭证书或性能告警。事件缺少 `check.token` 时无法可靠地把恢复通知关联到原告警,Flashduty 会跳过该事件,同一请求中的其他有效事件照常处理;请求里没有任何有效事件时才返回参数错误。
## 状态和告警等级
----
updown.io 的通知不区分告警等级。
@@ -97,12 +93,10 @@ updown.io 的通知不区分告警等级。
| `check.performance_drop` | Warning |
## 一次性告警需要开启超时自动关闭
----
性能下降(`check.performance_drop`)没有对应的关闭通知,这类告警不会自动恢复。请开启协作空间的[超时自动关闭](/zh/on-call/channel/create-edit),建议设置为 6 小时;也可以手动关闭。
## 常见问题
----
<AccordionGroup>
<Accordion title="测试 Webhook 会创建告警吗?">
@@ -119,7 +113,6 @@ updown.io 的通知不区分告警等级。
</AccordionGroup>
## 排查问题
----
- **updown.io 提示投递失败**:确认 Webhook 地址是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求体是 updown.io 的 JSON 数组,且事件的 `check.token` 非空(缺少 `check.token` 的事件会被跳过,全部无效时才返回错误)
diff --git a/zh/on-call/integration/alert-integration/alert-sources/upguard.mdx b/zh/on-call/integration/alert-integration/alert-sources/upguard.mdx
index 0546f131..026d0269 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/upguard.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/upguard.mdx
@@ -1,5 +1,6 @@
---
title: "UpGuard 告警集成"
+sidebarTitle: "UpGuard"
description: "通过 UpGuard 的 Webhook 集成,将安全评分下降、新的数据泄露等风险通知同步到 Flashduty On-call。"
keywords: ["告警集成", "UpGuard", "Webhook", "安全评分", "数据泄露", "供应商风险", "攻击面"]
---
@@ -9,7 +10,6 @@ UpGuard 是第三方风险与攻击面管理平台。在 UpGuard 中创建 Webho
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ UpGuard 是第三方风险与攻击面管理平台。在 UpGuard 中创建 Webho
</div>
## 在 UpGuard 中配置
----
<Steps>
<Step title="新增 Webhook 集成">
@@ -81,24 +80,20 @@ UpGuard 用 Liquid 模板生成请求体,Flashduty 解析下面这个模板渲
</Steps>
## 事件类型
----
| 推送内容 | 在 Flashduty 中的效果 |
| :--- | :--- |
| 任意触发条件产生的通知 | 创建一条告警,严重程度为 Warning |
## Alert Key
----
Flashduty 使用 `notification.id` 作为 Alert Key:`id` 不同的通知各自对应一条告警,`id` 相同的重复投递合并到同一条告警;缺少 `notification.id` 的请求会被拒绝。UpGuard 的文档没有说明该编号的唯一性范围,上线前建议用测试消息和一次真实触发确认两条通知的 `id` 不同。
## 状态和告警等级
----
UpGuard 的通知不带严重程度,所有通知都按 Warning 创建。需要区分时,可在协作空间的告警处理规则中按 `notification_type` 标签调整等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -112,14 +107,12 @@ UpGuard 的通知不带严重程度,所有通知都按 Warning 创建。需要
告警标题取自 `description`(例如 `The score for 'Example Company' dropped below 600 with a score of 599`),为空时使用通知类型。
## 注意事项
----
- UpGuard 的通知可能包含泄露、身份等敏感信息,模板里只填写上文列出的字段即可,不要添加凭证或个人数据
- UpGuard 从固定的一组 IP 发起请求,列表见 [webhook-ips.json](https://cdn.cyber-risk.upguard.com/webhook-ips.json),如果 Flashduty 前置了 IP 白名单,请放行
- 如果 `description` 中出现双引号,渲染出的 JSON 会不合法,请求会被拒绝为参数错误
## 排查问题
----
- **Flashduty 没有收到推送**:确认 Webhook 地址完整且包含 `integration_key`,集成已启用
- **返回参数错误**:提示缺少 `notification.id` 时,检查请求体模板是否保留了 `id`;提示 JSON 不合法时,检查字符串字段是否带引号
diff --git a/zh/on-call/integration/alert-integration/alert-sources/uptime-com.mdx b/zh/on-call/integration/alert-integration/alert-sources/uptime-com.mdx
index f5237b80..04df9c70 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/uptime-com.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/uptime-com.mdx
@@ -1,5 +1,6 @@
---
title: "Uptime.com 告警集成"
+sidebarTitle: "Uptime.com"
description: "通过 Custom Postback URL (Webhook) 将 Uptime.com 检查的宕机和恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "Uptime.com", "Custom Postback URL", "Webhook", "可用性监控"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Uptime.com", "Custom Postback URL", "Webhook", "可
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Uptime.com", "Custom Postback URL", "Webhook", "可
</div>
## 在 Uptime.com 中配置
----
<Steps>
<Step title="创建 Custom Postback URL 集成">
@@ -68,14 +67,12 @@ Uptime.com 按联系人投递告警:只有分配了该联系人的检查才会
</Tip>
## Alert Key
----
Flashduty 用 `data.service.id`(Uptime.com 检查 ID)计算 Alert Key。同一个检查的 `alert_raised` 和 `alert_cleared` 携带相同的 `data.service.id`,因此会落在同一条告警上;持续宕机期间的重复通知也会合并到这条告警。
`data.alert.id` 是每个探测位置的一条检测记录,恢复时会变化,因此不参与 Alert Key。检查名称、标签、状态、输出、时间和宕机位置的变化都不会改变 Alert Key。请求缺少 `data.service.id` 时 Flashduty 会拒绝,因为无法关联后续恢复。
## 状态和告警等级
----
| Uptime.com `event` | Flashduty 处理 |
| :--- | :--- |
@@ -96,7 +93,6 @@ Flashduty 用 `data.service.id`(Uptime.com 检查 ID)计算 Alert Key。同
恢复事件保留原告警等级。
## 告警内容
----
- **标题**:检查的 `display_name`,为空时使用 `name`
- **描述**:`data.alert.output`,为空时使用 `data.alert.short_output`
@@ -105,7 +101,6 @@ Flashduty 用 `data.service.id`(Uptime.com 检查 ID)计算 Alert Key。同
`data.integration` 中的推送地址和自定义请求头不会写入标签。
## 排查问题
----
- **集成显示错误或 Uptime.com 投递失败**:确认 URL 是完整推送地址且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求中有 `event` 和 `data.service.id`;本集成只接收 Custom Postback URL 的 JSON 格式
diff --git a/zh/on-call/integration/alert-integration/alert-sources/uptime-kuma.mdx b/zh/on-call/integration/alert-integration/alert-sources/uptime-kuma.mdx
index 1335c0c9..90132037 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/uptime-kuma.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/uptime-kuma.mdx
@@ -1,12 +1,12 @@
---
title: "Uptime Kuma 集成"
+sidebarTitle: "Uptime Kuma"
description: "通过 webhook 的方式同步 Uptime Kuma 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "Uptime Kuma 集成", "监控告警", "数据接入"]
---
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -14,11 +14,11 @@ keywords: ["告警集成", "Uptime Kuma 集成", "监控告警", "数据接入"]
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
- 3. 选择 **Uptime Kunma** 集成,点击 **保存**,生成卡片。
+ 3. 选择 **Uptime Kuma** 集成,点击 **保存**,生成卡片。
4. 点击生成的卡片,可以查看到 **推送地址**,复制备用,完成。
@@ -30,10 +30,10 @@ keywords: ["告警集成", "Uptime Kuma 集成", "监控告警", "数据接入"]
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
- 2. 选择 **Uptime Kunma** 集成:
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
+ 2. 选择 **Uptime Kuma** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
4. 点击 **保存** 后,复制当前页面的新生成的 **推送地址** 备用。
@@ -45,7 +45,6 @@ keywords: ["告警集成", "Uptime Kuma 集成", "监控告警", "数据接入"]
</div>
## 在 Uptime Kuma
----
**步骤 1:设置通知渠道**
1. 进入 `Settings -> Notifications` 页面,单击 Setup 进行编辑,如下图所示;
@@ -70,7 +69,6 @@ keywords: ["告警集成", "Uptime Kuma 集成", "监控告警", "数据接入"]
</div>
## 状态对照
----
<div className="md-block">
Uptime Kuma 到 Flashduty 告警等级映射关系:
diff --git a/zh/on-call/integration/alert-integration/alert-sources/uptimeobserver.mdx b/zh/on-call/integration/alert-integration/alert-sources/uptimeobserver.mdx
index fe820373..e296f5a2 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/uptimeobserver.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/uptimeobserver.mdx
@@ -1,5 +1,6 @@
---
title: "UptimeObserver 告警集成"
+sidebarTitle: "UptimeObserver"
description: "通过 Incident 和 Resolution 两个 Webhook 将 UptimeObserver 的故障与恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "UptimeObserver", "Webhook", "拨测", "incident_id"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "UptimeObserver", "Webhook", "拨测", "incident_id"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "UptimeObserver", "Webhook", "拨测", "incident_id"]
</div>
## 在 UptimeObserver 中配置
----
UptimeObserver 没有固定的 Webhook 报文,报文由您填写的模板决定。Flashduty 只解析下面两个模板,需要创建两个 Webhook:一个用于故障,一个用于恢复。
@@ -92,14 +91,12 @@ UptimeObserver 没有固定的 Webhook 报文,报文由您填写的模板决
</Steps>
## Alert Key
----
Flashduty 使用 `incident_id`(`__INCIDENT_ID__`)作为 Alert Key。UptimeObserver 文档将其定义为数字型 Incident 标识,并在故障与恢复两个示例模板中都使用它。文档没有明确写出两个 Webhook 对同一 Incident 返回相同的值,这一点属于推断,请在首次接入时按上一节的方法用真实故障验证。
`monitor_id` 只作为标签。监控名称、根因和 `incident_status` 的变化不会改变 Alert Key;同一监控的下一次故障会产生新的 Incident,因此是一条新的告警。
## 状态和告警等级
----
| `event_type` | Flashduty 状态或等级 |
| :--- | :--- |
@@ -109,7 +106,6 @@ Flashduty 使用 `incident_id`(`__INCIDENT_ID__`)作为 Alert Key。UptimeOb
`event_type` 为空或其他值会被拒绝。请求体为空对象 `{}` 时返回 200 且不创建告警。
## 排查问题
----
- **UptimeObserver 返回非 2xx**:确认 URL 完整且包含 `integration_key`
- **Flashduty 返回参数错误**:确认 Body 是有效 JSON。`__INCIDENT_ROOT_CAUSE__` 或监控名称含双引号时,UptimeObserver 直接替换文本,可能破坏 JSON,可删除 `root_cause` 字段或改用不含引号的监控名称
diff --git a/zh/on-call/integration/alert-integration/alert-sources/uptimerobot.mdx b/zh/on-call/integration/alert-integration/alert-sources/uptimerobot.mdx
index 3c06c732..c97b53b1 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/uptimerobot.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/uptimerobot.mdx
@@ -1,5 +1,6 @@
---
title: "UptimeRobot 告警集成"
+sidebarTitle: "UptimeRobot"
description: "通过 Webhook 将 UptimeRobot Monitor 的宕机和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "UptimeRobot", "Monitor", "Webhook", "可用性监控"]
---
@@ -13,7 +14,6 @@ UptimeRobot 仅在 Team 及以上付费套餐(如 Team、Scale、Enterprise)
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -34,7 +34,6 @@ UptimeRobot 仅在 Team 及以上付费套餐(如 Team、Scale、Enterprise)
</div>
## 在 UptimeRobot 中配置
----
<Steps>
<Step title="添加 Webhook 集成">
@@ -100,14 +99,12 @@ UptimeRobot 仅在 Team 及以上付费套餐(如 Team、Scale、Enterprise)
</Steps>
## Alert Key
----
Flashduty 使用 `*monitorID*`(即 `monitor_id`)作为 Alert Key。UptimeRobot 的 Down 和 Up 通知都携带同一个 Monitor ID,因此同一个 Monitor 的宕机、重复提醒和恢复会落在同一条告警上;不同 Monitor 生成不同的告警。
Monitor 名称、URL、告警详情、HTTP 状态码和时间的变化都不会改变 Alert Key。删除后重新创建的 Monitor 会得到新的 Monitor ID,与旧告警不再关联。
## 状态和告警等级
----
| UptimeRobot `*alertType*` | 含义 | Flashduty 状态或等级 |
| :--- | :--- | :--- |
@@ -120,13 +117,11 @@ Monitor 名称、URL、告警详情、HTTP 状态码和时间的变化都不会
SSL 证书和域名到期提醒没有对应的恢复通知,每条提醒都会生成一条独立的 Warning 告警,不会自动恢复,处理后请手动关闭。
## 投递说明
----
- UptimeRobot 对 Down 和 Up 通知只发送一次:请求超时、连接失败或返回非 2xx 时不会重试。如果 Up 通知未送达,对应告警会保持活动状态,需要手动关闭
- 在 Monitor 设置中配置的重复提醒(recurring notifications)会以相同的 Monitor ID 再次发送 Down 通知,Flashduty 将其合并到已有告警
## 排查问题
----
- **Flashduty 返回参数错误**:确认已勾选 **Send as JSON (application/json)**,且 POST value 是有效 JSON,`monitor_id` 和 `alert_type` 保留原样
- **JSON 解析失败**:检查 Monitor 名称或告警详情是否包含双引号或反斜杠,这类字符可能让渲染后的 POST value 不再是合法 JSON
diff --git a/zh/on-call/integration/alert-integration/alert-sources/uptimia.mdx b/zh/on-call/integration/alert-integration/alert-sources/uptimia.mdx
index 446264e7..d4257039 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/uptimia.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/uptimia.mdx
@@ -1,5 +1,6 @@
---
title: "Uptimia 告警集成"
+sidebarTitle: "Uptimia"
description: "通过 Webhook 联系人将 Uptimia 监控的宕机和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Uptimia", "Uptime", "Webhook", "监控", "宕机"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Uptimia", "Uptime", "Webhook", "监控", "宕机"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Uptimia", "Uptime", "Webhook", "监控", "宕机"]
</div>
## 在 Uptimia 中配置
----
<Steps>
<Step title="创建 Webhook 集成">
@@ -60,7 +59,6 @@ Uptimia 集成列表中 **Actions → Test** 发送的测试请求(`monitor_st
</Note>
## 推送内容
----
Uptimia 以 `application/json` POST 固定的 11 个字段,Flashduty 直接解析,无需配置模板:
@@ -81,14 +79,12 @@ Uptimia 以 `application/json` POST 固定的 11 个字段,Flashduty 直接解
开启告警分组时,Uptimia 会在同样的 11 个字段上附加 `group` 对象(字段描述分组内第一个故障的监控)。Flashduty 按这 11 个字段处理,并把 `group.id` 和 `group.size` 记为标签 `group_id`、`group_size`。
## Alert Key
----
Flashduty 使用 `monitor_type` 加 `id` 作为 Alert Key。Uptimia 的 `id` 在每种监控类型内各自编号,所以必须与 `monitor_type` 一起使用;Uptimia 的载荷里没有故障 ID。同一个监控的宕机、严重程度变化、重复通知和恢复携带相同的两个字段,会落在同一条告警上;修改监控名称、备注、严重程度或时间不会改变 Alert Key。
请求中缺少 `monitor_type` 或 `id` 时,Flashduty 会返回参数错误,因为无法可靠地把恢复通知关联到原告警。
## 状态和告警等级
----
| Uptimia 字段 | Flashduty 状态或等级 |
| :--- | :--- |
@@ -100,7 +96,6 @@ Flashduty 使用 `monitor_type` 加 `id` 作为 Alert Key。Uptimia 的 `id` 在
`monitor_status` 为空或为其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="重复投递会产生多条 Flashduty 告警吗?">
@@ -123,7 +118,6 @@ Uptimia 在分组内最后一个成员恢复时发送一条恢复通知,字段
</AccordionGroup>
## 排查问题
----
- **Uptimia 推送失败**:确认 Webhook URL 是完整的推送地址,Flashduty 成功时返回 2xx
- **Flashduty 返回参数错误**:确认请求体包含 `monitor_type`、`id`,且 `monitor_status` 为 `down` 或 `up`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/uptrends.mdx b/zh/on-call/integration/alert-integration/alert-sources/uptrends.mdx
index eb52371e..235c8fd6 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/uptrends.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/uptrends.mdx
@@ -1,5 +1,6 @@
---
title: "Uptrends 告警集成"
+sidebarTitle: "Uptrends"
description: "通过 Uptrends 的自定义集成将监控告警同步到 Flashduty On-call,监控恢复时自动关闭告警。"
keywords: ["告警集成", "Uptrends", "自定义集成", "Webhook", "网站监控", "拨测"]
---
@@ -9,7 +10,6 @@ Uptrends 通过**自定义集成**(Uptrends integration)推送告警:监
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Uptrends 通过**自定义集成**(Uptrends integration)推送告警:监
</div>
## 在 Uptrends 中配置
----
以下操作需要可以管理 **Integrations** 和 **Alert definitions** 的 Uptrends 账号。
@@ -103,7 +102,6 @@ Uptrends 默认用同一个请求发送 **Error**、**Reminder** 和 **Ok** 三
</Steps>
## Alert Key
----
Flashduty 使用 `incident_key`(`{{@incident.key}}`)作为 Alert Key。Uptrends 文档说明,同一次故障的出错告警和恢复告警使用相同的 incident key,每次新的故障使用新的 key,因此出错、提醒和恢复消息落在同一条 Flashduty 告警上;监控恢复后再次出错会打开一条新告警。
@@ -112,7 +110,6 @@ Flashduty 使用 `incident_key`(`{{@incident.key}}`)作为 Alert Key。Uptre
请求缺少 `incident_key` 或 `alert_type`,或这两个字段仍是未替换的 `{{@...}}` 变量时,Flashduty 会拒绝该请求。
## 告警生命周期
----
Flashduty 按 `alert_type` 字段(`{{@alert.type}}`,不区分大小写)处理消息:
@@ -125,12 +122,10 @@ Flashduty 按 `alert_type` 字段(`{{@alert.type}}`,不区分大小写)处
其他值会被拒绝。
## 告警等级
----
Uptrends 的告警没有等级,所有告警默认为 **Critical**。如需其他等级,在推送地址后追加 `&severity=Warning`(或 `Info`)。恢复事件保留原告警的等级。
## 告警内容
----
- **标题**:监控名称;缺少监控名称时为 `Uptrends incident <incident_key>`
- **描述**:错误描述(`{{@alert.description}}`),多步骤监控会包含出错的步骤编号
@@ -139,7 +134,6 @@ Uptrends 的告警没有等级,所有告警默认为 **Critical**。如需其
值为空的字段不会写入标签。
## 排查问题
----
- **测试告警返回失败**:确认 **ApiUrl** 是完整的推送地址,包含 `integration_key` 参数,且 **Method** 为 `POST`
- **Flashduty 提示请求体不是合法 JSON**:确认请求体与模板一致,文本字段使用了 `@JsonEncode`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/veeam-one.mdx b/zh/on-call/integration/alert-integration/alert-sources/veeam-one.mdx
index aa56712f..f3ba1f5f 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/veeam-one.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/veeam-one.mdx
@@ -1,5 +1,6 @@
---
title: "Veeam ONE 告警集成"
+sidebarTitle: "Veeam ONE"
description: "Veeam ONE 通过邮件发送告警通知,使用 Flashduty 的邮件集成按规则触发和关闭 Veeam ONE 告警。"
keywords: ["告警集成", "Veeam ONE", "Veeam", "邮件", "Email", "备份监控"]
---
@@ -9,7 +10,6 @@ Veeam ONE 的告警通知只能通过邮件(以及 SNMP、syslog、脚本)
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成邮件地址,任选其一即可。**集成类型都选择邮件 Email**,不是 Veeam ONE。
@@ -30,7 +30,6 @@ Veeam ONE 的告警通知只能通过邮件(以及 SNMP、syslog、脚本)
</div>
## 在 Flashduty 中配置推送规则
----
Veeam ONE 的邮件里没有告警 ID,一条告警由「告警名 + 对象」确定,规则从邮件标题提取这两部分作为 Alert Key。触发和恢复邮件提取出的 Key 相同,恢复邮件因此能关闭对应的告警。
@@ -71,7 +70,6 @@ Veeam ONE 的邮件里没有告警 ID,一条告警由「告警名 + 对象」
默认规则选丢弃,是为了让汇总邮件(见 [限制](#限制))不生成无法自动关闭的告警。如果您改过主题模板又不想漏掉邮件,可以把默认规则改为 **新建一条告警**,代价是这些邮件按标题生成的告警不会自动恢复。
## 在 Veeam ONE 中配置
----
以下路径以 Veeam ONE v13 为准,均在 Veeam ONE Client 中操作。
@@ -82,7 +80,6 @@ Veeam ONE 的邮件里没有告警 ID,一条告警由「告警名 + 对象」
5. **邮件格式**:HTML 或 Plain Text 都可以,规则只读取邮件标题
## 邮件标题格式
----
Mission Critical 单条告警邮件的标题由 **Notification Policy** → **Mission Critical** → **Edit template** 中的 **Email subject template** 决定。不同版本的默认值有两种写法:
@@ -102,7 +99,6 @@ Mission Critical 单条告警邮件的标题由 **Notification Policy** → **Mi
如果您修改了主题模板,请同步修改规则中的正则。也可以在 **Edit template** 中把主题显式设为写法 A 的模板,此时只需要规则 1 和规则 3。
## 限制
----
- **手动解决**:在 Veeam ONE 中手动解决告警时,发出的是汇总邮件(标题 `Alarm resolve notification`),一封可以列出多条告警,规则无法逐条关闭,会被默认规则丢弃。这类告警需要在 Flashduty 中手动关闭,或在接收该集成的协作空间开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时。
- **确认与汇总**:确认告警(`Alarm acknowledgement notification`)和 Other 策略的汇总(`Alarm summary notification`)同样是汇总邮件,被默认规则丢弃。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console.mdx b/zh/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console.mdx
index 6b24939c..47c36dc4 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console.mdx
@@ -1,5 +1,6 @@
---
title: "Veeam Service Provider Console 告警集成"
+sidebarTitle: "Veeam Service Provider Console"
description: "Veeam Service Provider Console 通过邮件发送告警通知,使用 Flashduty 的邮件集成按规则触发 VSPC 告警。"
keywords: ["告警集成", "Veeam Service Provider Console", "VSPC", "Veeam", "邮件", "Email", "备份监控"]
---
@@ -9,7 +10,6 @@ Veeam Service Provider Console(VSPC)的告警通知通过邮件发送,Flas
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成邮件地址,任选其一即可。**集成类型都选择邮件 Email**,不是 Veeam Service Provider Console。
@@ -30,7 +30,6 @@ Veeam Service Provider Console(VSPC)的告警通知通过邮件发送,Flas
</div>
## 在 Flashduty 中配置推送规则
----
VSPC 的邮件里没有告警 ID。下面的主题格式把公司、站点和告警名放进标题,规则从标题提取这三项作为 Alert Key,同一公司、同一站点、同一告警名的邮件合并到同一条告警;告警状态不参与 Alert Key,因此同一告警从 Warning 变为 Error 时更新原有告警,不会新建。
@@ -48,7 +47,6 @@ VSPC 的邮件里没有告警 ID。下面的主题格式把公司、站点和告
默认规则选丢弃,是为了让状态为 Information 的邮件不生成告警。
## 在 Veeam Service Provider Console 中配置
----
以下路径来自 VSPC 官方文档,需要管理员权限。
@@ -56,21 +54,20 @@ VSPC 的邮件里没有告警 ID。下面的主题格式把公司、站点和告
2. **通知频率**:在 **Alarms** 区域把通知频率滑块设为 **Emails on every event**。**Summary emails only** 只发每日汇总,规则无法逐条处理
3. **主题**:在 **Alarms** 区域的 **Subject** 中填写:
-```
-VSPC %alarmStatus% | %company% | %location% | %alarmName%
-```
+ ```
+ VSPC %alarmStatus% | %company% | %location% | %alarmName%
+ ```
-`%alarmStatus%`、`%company%`、`%location%`、`%alarmName%` 是 VSPC 告警通知主题支持的变量。渲染后的主题形如:
+ `%alarmStatus%`、`%company%`、`%location%`、`%alarmName%` 是 VSPC 告警通知主题支持的变量。渲染后的主题形如:
-```
-VSPC Error | Contoso | London | Backup job failed
-```
+ ```
+ VSPC Error | Contoso | London | Backup job failed
+ ```
4. **收件人**:VSPC 默认把告警邮件发给站点管理员和公司管理员。要发给 Flashduty,进入 **Configuration** → **Templates** → **Predefined Alarms** 选项卡,选中告警后点击 **Edit**,在 **Actions** 步骤点击 **Add**,**Action** 选 **Send email notification**,**Value** 填 Flashduty 邮件集成的地址,条件选 **Errors and warnings**
5. **邮件格式**:规则只读取邮件标题,正文格式不影响匹配
## 限制
----
- **没有恢复邮件**:VSPC 默认只在新告警产生,或已有告警状态变为 Error 或 Warning 时发邮件,规则不会自动关闭告警。请在接收该集成的协作空间开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时,或在 Flashduty 中手动关闭。
- **对象合并**:主题变量里没有对象名,同一公司、同一站点下同名告警作用在不同对象上时,会合并到同一条 Flashduty 告警。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/veracode-sca.mdx b/zh/on-call/integration/alert-integration/alert-sources/veracode-sca.mdx
index c3a5610f..f7254c96 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/veracode-sca.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/veracode-sca.mdx
@@ -1,5 +1,6 @@
---
title: "Veracode SCA 告警集成"
+sidebarTitle: "Veracode SCA"
description: "通过项目 Webhook 将 Veracode SCA(基于 Agent 的扫描)发现的漏洞问题同步到 Flashduty On-call,问题解决后自动恢复。"
keywords: ["告警集成", "Veracode", "SCA", "软件成分分析", "漏洞", "Webhook"]
---
@@ -13,7 +14,6 @@ keywords: ["告警集成", "Veracode", "SCA", "软件成分分析", "漏洞", "W
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -34,7 +34,6 @@ keywords: ["告警集成", "Veracode", "SCA", "软件成分分析", "漏洞", "W
</div>
## 在 Veracode 中配置
----
Webhook 按项目(project)配置。需要 Security Lead、Workspace Administrator 或 Workspace Editor 角色。
@@ -68,7 +67,6 @@ Veracode 文档没有描述 Webhook 的测试推送按钮,请在有新漏洞
</Steps>
## 事件和恢复
----
| Veracode 事件 | `issues[].status` | 在 Flashduty 中的效果 |
| :--- | :--- | :--- |
@@ -81,12 +79,10 @@ Veracode 文档没有描述 Webhook 的测试推送按钮,请在有新漏洞
一次推送可能包含多个问题,Flashduty 按问题编号排序后逐个处理,每次推送最多处理 200 个问题,超出部分忽略。
## Alert Key
----
Alert Key 由项目编号(`project.id`)和问题编号(`issues[].id`)共同计算。Veracode 文档示例中,同一个问题在发现和变更事件里的编号相同,所以恢复会落到同一条告警上。漏洞标题、评分和项目名称变化不会改变 Alert Key。缺少 `project.id`、`issues[].id` 或 `issues[].status` 的推送会被拒绝,并在错误信息中指出字段名。
## 告警等级
----
Veracode 的 payload 不直接携带等级,Flashduty 按漏洞的 CVSS 评分映射,优先使用 CVSS v3 评分,没有时使用 CVSS v2 评分:
@@ -100,7 +96,6 @@ Veracode 的 payload 不直接携带等级,Flashduty 按漏洞的 CVSS 评分
恢复时状态变为已恢复,等级保持为最后一次的等级。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -118,7 +113,6 @@ Veracode 的 payload 不直接携带等级,Flashduty 按漏洞的 CVSS 评分
Flashduty 不保存推送中的组织信息和用户信息。
## 排查问题
----
- **Veracode 保存 Webhook 失败**:确认推送地址可从公网访问,并包含 `integration_key`
- **Flashduty 返回参数错误**:错误信息会指出缺少的字段,或不支持的事件名称
diff --git a/zh/on-call/integration/alert-integration/alert-sources/vigil.mdx b/zh/on-call/integration/alert-integration/alert-sources/vigil.mdx
index 075e1e1f..63e58fdf 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/vigil.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/vigil.mdx
@@ -1,5 +1,6 @@
---
title: "Vigil 告警集成"
+sidebarTitle: "Vigil"
description: "通过 Vigil 的 Webhook 通知器将状态页的整体状态变化(异常、降级、恢复)同步到 Flashduty On-call。"
keywords: ["告警集成", "Vigil", "Webhook", "状态页", "监控", "自托管"]
---
@@ -11,7 +12,6 @@ Vigil 的 Webhook 请求体是固定格式,无需编写模板。
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -32,7 +32,6 @@ Vigil 的 Webhook 请求体是固定格式,无需编写模板。
</div>
## 在 Vigil 中配置
----
需要 Vigil 1.29.x,并能修改 Vigil 的配置文件(`config.cfg`)。Vigil 所在的服务器需要能访问 Flashduty 的推送地址。
@@ -72,7 +71,6 @@ Vigil 没有测试按钮。验证方法:
</Steps>
## Alert Key
----
Flashduty 使用状态页地址 `page.url` 作为 Alert Key。Vigil 的通知只描述整个状态页的聚合状态,没有单个告警的 ID,因此一个 Vigil 状态页对应一条 Flashduty 告警:状态变为 `dead` 或 `sick` 时创建或更新,变为 `healthy` 时恢复。
@@ -82,7 +80,6 @@ Flashduty 使用状态页地址 `page.url` 作为 Alert Key。Vigil 的通知只
- `page.url` 来自 `config.cfg` 的 `[branding]` `page_url`,只在同一个 Vigil 实例内唯一。请不要让多个 Vigil 实例使用相同的 `page_url`,一个 Flashduty 集成也请只接收一个 Vigil 实例的推送
## 状态和告警等级
----
| 通知 `type` | Flashduty 处理 |
| :--- | :--- |
@@ -103,7 +100,6 @@ Vigil 只在状态变为 `dead`、离开 `dead`(变为 `sick` 或 `healthy`)
告警标题形如 `Vigil: Example Status is dead`,由状态页标题(为空时用状态页地址)和状态拼成;告警描述按字母序列出异常节点,格式为 `服务ID:节点ID:探测地址`。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -115,7 +111,6 @@ Vigil 只在状态变为 `dead`、离开 `dead`(变为 `sick` 或 `healthy`)
| `replicas` | 异常节点列表,按字母序用逗号连接 |
## 排查问题
----
- **Flashduty 返回参数错误**:确认 `hook_url` 完整且包含 `integration_key`;响应信息会指出缺少的字段或不支持的状态
- **没有收到告警**:确认已重启 Vigil,`[notify.webhook]` 的 `hook_url` 正确,并且 Vigil 判定的整体状态确实变为 `dead` 或 `sick`;Vigil 只在状态变化和提醒间隔到期时发送通知
diff --git a/zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-event.mdx b/zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-event.mdx
index 146217d9..2302c970 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-event.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-event.mdx
@@ -1,12 +1,12 @@
---
title: "火山引擎云监控事件中心告警事件"
+sidebarTitle: "火山引擎云监控事件中心"
description: "通过 webhook 的方式同步火山引擎云监控事件中心告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "火山引擎云监控事件中心告警事件", "监控告警", "数据接入"]
---
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -14,7 +14,7 @@ keywords: ["告警集成", "火山引擎云监控事件中心告警事件", "监
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -30,10 +30,10 @@ keywords: ["告警集成", "火山引擎云监控事件中心告警事件", "监
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
- 2. 选择 **火山引擎CM 指标** 集成:
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
+ 2. 选择 **火山引擎CM 事件** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
4. 点击 **保存** 后,复制当前页面的新生成的 **推送地址** 备用。
@@ -45,18 +45,16 @@ keywords: ["告警集成", "火山引擎云监控事件中心告警事件", "监
</div>
## 在火山引擎
----
<div className="md-block">
-## 一、火山引擎云监控事件中心告警推送配置
### 步骤1:创建 Flashduty 告警通道
1. 登录您的火山引擎控制台,检索 `云监控` 产品,并进入对应产品控制台。
2. 在左侧导航栏选择 `通知组=>回调`。
3. 点击 `创建回调地址`。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/ve-m-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/ve-m-1.png" />
4. 在编辑页面中填写相应的信息,回调地址名称填写 `Flashduty_Event`。
5. 回调地址类型选择 `通用回调地址`。
@@ -76,7 +74,7 @@ keywords: ["告警集成", "火山引擎云监控事件中心告警事件", "监
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics.mdx b/zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics.mdx
index 621b731f..b8658d69 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics.mdx
@@ -1,5 +1,6 @@
---
title: "火山引擎云监控告警事件"
+sidebarTitle: "火山引擎云监控"
description: "通过 webhook 的方式同步火山引擎云监控告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "火山引擎云监控告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "火山引擎云监控告警事件", "监控告警",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "火山引擎云监控告警事件", "监控告警",
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "火山引擎云监控告警事件", "监控告警",
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **火山引擎CM 指标** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,18 +46,16 @@ keywords: ["告警集成", "火山引擎云监控告警事件", "监控告警",
</div>
## 在火山引擎
----
<div className="md-block">
-## 一、火山引擎云监控告警推送配置
### 步骤1:创建 Flashduty 告警通道
1. 登录您的火山引擎控制台,检索 `云监控` 产品,并进入对应产品控制台。
2. 在左侧导航栏选择 `通知组=>回调`。
3. 点击 `创建回调地址`。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/ve-m-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/ve-m-1.png" />
4. 在编辑页面中填写相应的信息,回调地址名称填写 `Flashduty_Metric`。
5. 回调地址类型选择 `通用回调地址`。
@@ -79,7 +77,7 @@ keywords: ["告警集成", "火山引擎云监控告警事件", "监控告警",
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/volcengine-dial.mdx b/zh/on-call/integration/alert-integration/alert-sources/volcengine-dial.mdx
index 1049b66d..add4798e 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/volcengine-dial.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/volcengine-dial.mdx
@@ -1,5 +1,6 @@
---
title: "火山引擎云拨测告警事件"
+sidebarTitle: "火山引擎云拨测"
description: "通过 webhook 的方式同步 火山引擎云拨测的告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "火山引擎云拨测告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "火山引擎云拨测告警事件", "监控告警",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "火山引擎云拨测告警事件", "监控告警",
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "火山引擎云拨测告警事件", "监控告警",
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **火山引擎云拨测** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -44,12 +44,10 @@ keywords: ["告警集成", "火山引擎云拨测告警事件", "监控告警",
</AccordionGroup>
</div>
-## 在 火山引擎
----
+## 在火山引擎
<div className="md-block">
-## 一、告警推送配置
### 步骤1:创建通知对象
@@ -73,7 +71,7 @@ keywords: ["告警集成", "火山引擎云拨测告警事件", "监控告警",
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/volcengine-rtc.mdx b/zh/on-call/integration/alert-integration/alert-sources/volcengine-rtc.mdx
index c0406a6e..9324da9b 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/volcengine-rtc.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/volcengine-rtc.mdx
@@ -1,5 +1,6 @@
---
title: "火山引擎 RTC 告警集成"
+sidebarTitle: "火山引擎 RTC"
description: "通过 webhook 的方式同步火山引擎 RTC 的告警事件到 Flashduty,实现告警事件自动化降噪处理"
keywords: ["火山引擎", "RTC", "告警集成", "webhook", "实时音视频"]
---
@@ -9,45 +10,43 @@ keywords: ["火山引擎", "RTC", "告警集成", "webhook", "实时音视频"]
<div class="hide">
## 在 Flashduty
----
-
-### 创建火山引擎 RTC 告警集成
-您可通过以下2种方式,获取一个企微机器人告警集成地址,任选其一即可。
+您可通过以下两种方式获取一个火山引擎 RTC 告警集成地址,任选其一即可。
-#### 使用专属集成
+### 使用专属集成
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
-<details>
- <summary>展开</summary>
+<AccordionGroup>
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
3. 选择 **火山引擎 RTC** 集成,点击 **保存**,生成卡片。
4. 点击生成的卡片,可以查看到 **火山引擎 RTC 告警集成地址**,复制备用,完成。
-</details>
+</Accordion>
+</AccordionGroup>
-#### 使用共享集成
+### 使用共享集成
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
-<details>
- <summary>展开</summary>
+<AccordionGroup>
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **火山引擎 RTC** 集成:
- **集成名称**:为当前集成定义一个名称。
- - **推送模式**:选择企微告警在何种情况下触发或恢复告警。
+ - **推送模式**:选择火山引擎 RTC 告警在何种情况下触发或恢复 Flashduty 告警。
3. 复制当前页面的 **火山引擎 RTC 告警集成地址** 备用。
4. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
5. 完成。
-</details>
+</Accordion>
+</AccordionGroup>
## 在火山引擎
----
</div>
@@ -59,10 +58,9 @@ keywords: ["火山引擎", "RTC", "告警集成", "webhook", "实时音视频"]
4. 其他选项按需配置。
5. 点击 `确定` 完成配置。
-
+
## 严重程度映射关系
----
|火山引擎RTC| Flashduty|状态|
|---|---|---|
|严重|Critical|严重|
diff --git a/zh/on-call/integration/alert-integration/alert-sources/volcengine-tls.mdx b/zh/on-call/integration/alert-integration/alert-sources/volcengine-tls.mdx
index 49eed2bb..9513db18 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/volcengine-tls.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/volcengine-tls.mdx
@@ -1,5 +1,6 @@
---
title: "火山引擎日志服务 TLS 告警事件"
+sidebarTitle: "火山引擎日志服务 TLS"
description: "通过 webhook 的方式同步火山引擎日志服务 TLS 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "火山引擎日志服务 TLS 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "火山引擎日志服务 TLS 告警事件", "监控
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "火山引擎日志服务 TLS 告警事件", "监控
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "火山引擎日志服务 TLS 告警事件", "监控
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **火山引擎 TLS** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -46,18 +46,16 @@ keywords: ["告警集成", "火山引擎日志服务 TLS 告警事件", "监控
</div>
## 在火山引擎
----
<div className="md-block">
-## 一、火山引擎日志服务 TLS 告警推送配置
### 步骤1:创建 Flashduty 告警通道
1. 登录您的火山引擎控制台,检索 `TLS`日志服务产品,并进入对应产品控制台。
2. 在左侧导航栏选择 `日志告警=>通知管理`。
3. 选择 `webhook 告警集成`,并点击 `创建 webhook 告警集成`。
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/ve-tls-1.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/ve-tls-1.png" />
4. 在弹出的编辑框中填写相应的信息,名称填写 `Flashduty`。
5. 类型选择 `自定义 Webhook`,请求方法选择 `POST`。
@@ -73,28 +71,28 @@ keywords: ["告警集成", "火山引擎日志服务 TLS 告警事件", "监控
3. 在创建模版页面中填写相关信息,模版名称填写 `Flashduty`。
4. 其他类型的通道内容可为空,在 `自定义Webhook` 的通知内容处,填写以下模版内容。
-```
-{
- "AccountID":"{{AccountID}}",
- "ProjectName":"{{ProjectName}}",
- "AlarmTopicName":"{{AlarmTopicName}}",
- "Region":"{{Region}}",
- "Alarm":"{{Alarm}}",
- "AlarmID":"{{AlarmID}}",
- "Duration":"{{Duration}}",
- "Condition":"{{Condition}}",
- "HappenThreshold":"{{HappenThreshold}}",
- "Topics":"{{Topics|join:','}}",
- "NotifyTimeUnix":"{{NotifyTimeUnix}}",
- "NotifyType":"{{NotifyType}}",
- "Severity":"{{Severity}}",
- "ConsecutiveAlertNums":"{{ConsecutiveAlertNums}}",
- "TriggerParams":{{toJson(TriggerParams)|safe}},
- "ExecuteQuery":{{toJson(ExecuteQuery)|safe}},
- "DetailUrl":"{{DetailUrl}}",
- "FireResultsCount":"{{FireResultsCount}}"
-}
-```
+ ```
+ {
+ "AccountID":"{{AccountID}}",
+ "ProjectName":"{{ProjectName}}",
+ "AlarmTopicName":"{{AlarmTopicName}}",
+ "Region":"{{Region}}",
+ "Alarm":"{{Alarm}}",
+ "AlarmID":"{{AlarmID}}",
+ "Duration":"{{Duration}}",
+ "Condition":"{{Condition}}",
+ "HappenThreshold":"{{HappenThreshold}}",
+ "Topics":"{{Topics|join:','}}",
+ "NotifyTimeUnix":"{{NotifyTimeUnix}}",
+ "NotifyType":"{{NotifyType}}",
+ "Severity":"{{Severity}}",
+ "ConsecutiveAlertNums":"{{ConsecutiveAlertNums}}",
+ "TriggerParams":{{toJson(TriggerParams)|safe}},
+ "ExecuteQuery":{{toJson(ExecuteQuery)|safe}},
+ "DetailUrl":"{{DetailUrl}}",
+ "FireResultsCount":"{{FireResultsCount}}"
+ }
+ ```
5. 点击 `确认` 即可完成内容模版的创建。
<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/ve-tls-3.png" />
@@ -125,7 +123,7 @@ keywords: ["告警集成", "火山引擎日志服务 TLS 告警事件", "监控
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/wazuh.mdx b/zh/on-call/integration/alert-integration/alert-sources/wazuh.mdx
index e1a0f101..63b962a8 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/wazuh.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/wazuh.mdx
@@ -1,5 +1,6 @@
---
title: "Wazuh 告警集成"
+sidebarTitle: "Wazuh"
description: "通过 Wazuh 管理节点内置的 Shuffle 集成,将 Wazuh 告警同步到 Flashduty On-call。"
keywords: ["告警集成", "Wazuh", "SIEM", "XDR", "安全告警", "Shuffle", "integratord"]
---
@@ -9,7 +10,6 @@ Wazuh 管理节点的 Integrator 模块(integratord)内置 `shuffle` 集成
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ Wazuh 管理节点的 Integrator 模块(integratord)内置 `shuffle` 集成
</div>
## 在 Wazuh 中配置
----
Integrator 模块只在 Wazuh 管理节点(manager)上运行,配置文件为 `/var/ossec/etc/ossec.conf`,需要管理节点的 root 权限。
@@ -77,19 +76,16 @@ Wazuh 没有“发送测试通知”功能。shuffle 脚本会跳过 5710、8600
</Steps>
## 事件与恢复
----
Wazuh 每生成一条告警只推送一次,不会推送更新或恢复通知。每条 Wazuh 告警都有唯一的告警 ID,Flashduty 用它作为 Alert Key,因此同一条告警重复投递会合并,不同的告警各自产生一条 Flashduty 告警,不会自动恢复。
请在协作空间中开启[超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时;也可以处理完成后手动关闭。同一规则在同一主机上反复触发时,可以在协作空间中配置降噪规则,把它们合并成一个故障。
## Alert Key
----
Alert Key 由 Wazuh 告警的 `id` 字段计算(形如 `1790000101.123456`)。缺少 `id` 的请求会被拒绝并返回参数错误,包括 Slack 集成格式的请求:Flashduty 只支持 `shuffle` 集成。
## 告警等级
----
按 `all_fields.rule.level`(Wazuh 规则等级 0-15)映射:
@@ -102,7 +98,6 @@ Alert Key 由 Wazuh 告警的 `id` 字段计算(形如 `1790000101.123456`)
`all_fields.rule.level` 缺失时,按 shuffle 脚本的 `severity` 字段映射:`3`(规则等级 8 及以上)为 Warning,`1` 和 `2` 为 Info;两者都缺失时为 Warning。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -120,7 +115,6 @@ Alert Key 由 Wazuh 告警的 `id` 字段计算(形如 `1790000101.123456`)
Flashduty 不读取也不保存原始日志(`text` 和 `full_log`)。但 shuffle 脚本会把整条告警发到 `hook_url`,其中可能包含用户名、IP、文件路径和命令行,请通过 `<level>`、`<rule_id>`、`<group>` 过滤,避免转发认证类原始日志。
## 排查问题
----
- **Flashduty 返回参数错误**:确认使用的是 `shuffle` 集成且 `<alert_format>` 为 `json`,并检查 `hook_url` 中的 `integration_key`
- **没有收到告警**:确认已重启 manager,告警等级不低于 `<level>`,规则不在上述跳过列表中,并查看 `integrations.log`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/wecom-alert.mdx b/zh/on-call/integration/alert-integration/alert-sources/wecom-alert.mdx
index de278a74..94cecdf9 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/wecom-alert.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/wecom-alert.mdx
@@ -1,5 +1,6 @@
---
title: "企微机器人兼容集成"
+sidebarTitle: "企微机器人兼容"
description: "Flashduty 生成企业微信群机器人格式的 Webhook 地址。已在向企业微信群机器人推送告警的工具,把地址改为它即可将告警的发生与恢复接入 Flashduty。"
keywords: ["告警集成", "企微", "监控告警", "数据接入", "企微机器人兼容", "企业微信群机器人"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "企微", "监控告警", "数据接入", "企微机
<div className="hide">
## 操作步骤
----
### 创建企微机器人兼容集成
@@ -18,7 +18,7 @@ keywords: ["告警集成", "企微", "监控告警", "数据接入", "企微机
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -33,9 +33,9 @@ keywords: ["告警集成", "企微", "监控告警", "数据接入", "企微机
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **企微机器人兼容** 集成:
- **集成名称**:为当前集成定义一个名称。
- **消息类型**:选择企微告警消息类型,目前仅支持文本(Text)、富文本(Post)。
@@ -89,6 +89,5 @@ keywords: ["告警集成", "企微", "监控告警", "数据接入", "企微机
- Flashduty On-call 会生成默认告警标题: “企微机器人告警”,如果您需要更改标题,可以通过[告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines) 来自定义标题。
## 严重程度映射关系
----
当前企微机器人兼容集成推送到 Flashduty 的严重程度均为Warning,但您可以通过[告警处理 Pipeline](/zh/on-call/integration/alert-integration/alert-pipelines) 来自定义严重程度。
\ No newline at end of file
diff --git a/zh/on-call/integration/alert-integration/alert-sources/whatap.mdx b/zh/on-call/integration/alert-integration/alert-sources/whatap.mdx
index b344b297..556a879d 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/whatap.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/whatap.mdx
@@ -1,5 +1,6 @@
---
title: "WhaTap 告警集成"
+sidebarTitle: "WhaTap"
description: "通过第三方插件(Webhook JSON)将 WhaTap 的事件告警与恢复同步到 Flashduty On-call。"
keywords: ["告警集成", "WhaTap", "监控", "Webhook", "事件告警"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "WhaTap", "监控", "Webhook", "事件告警"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "WhaTap", "监控", "Webhook", "事件告警"]
</div>
## 在 WhaTap 中配置
----
以下界面名称为 WhaTap 英文界面。
@@ -59,7 +58,6 @@ keywords: ["告警集成", "WhaTap", "监控", "Webhook", "事件告警"]
</Steps>
## 推送内容
----
WhaTap 以 `application/json` 格式 POST 通知,所有字段均为字符串,Flashduty 直接解析,无需配置模板:
@@ -78,14 +76,12 @@ WhaTap 以 `application/json` 格式 POST 通知,所有字段均为字符串
数值字段可能带有千位分隔符(例如 `55,223.0`),Flashduty 原样保存为文本标签,不做数值解析。
## Alert Key
----
使用 `uuid` 作为 Alert Key。WhaTap 同一个事件的触发通知和恢复通知携带相同的 `uuid`,落在同一条 Flashduty 告警上。同一对象、同一规则的等级发生变化时(例如 Critical 恢复后又触发 Warning),WhaTap 会生成新的事件和新的 `uuid`,在 Flashduty 中是各自独立的告警。标题、等级、数值和时间的变化不会改变 Alert Key。
请求中缺少 `uuid` 时,Flashduty 会返回参数错误,因为无法可靠地把恢复通知关联到原告警。
## 状态和告警等级
----
先按 `status` 判断是否恢复,再读取 `level`:WhaTap 的恢复通知固定带 `level` 为 `Info`。
@@ -100,7 +96,6 @@ WhaTap 以 `application/json` 格式 POST 通知,所有字段均为字符串
`status` 既不是 `on` 也不是 `off` 的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="持续超过阈值时会重复产生告警吗?">
@@ -117,7 +112,6 @@ WhaTap 以 `application/json` 格式 POST 通知,所有字段均为字符串
</AccordionGroup>
## 排查问题
----
- **测试通知产生了一条 Info 告警**:点击 **Test alert** 发送的测试通知没有 `uuid`。Flashduty 按其全部固定内容识别(`oid` 为 `123456789`、`oname` 为 `sample-name`、标题为 `[Test] Alert reception test`、消息为 `This is a test of WhaTap alert message`、等级 `Info`、状态 `on`,指标与 `okind`、`onode` 字段为空),并产生一条独立的 Info 告警,不会自动恢复,请手动关闭。其他缺少 `uuid` 的请求仍会被拒绝
- **WhaTap 推送失败**:确认 Webhook URL 是完整的推送地址,且包含 `integration_key`
diff --git a/zh/on-call/integration/alert-integration/alert-sources/whatsup-gold.mdx b/zh/on-call/integration/alert-integration/alert-sources/whatsup-gold.mdx
index b20fd14a..bcb05b1e 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/whatsup-gold.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/whatsup-gold.mdx
@@ -1,5 +1,6 @@
---
title: "WhatsUp Gold 告警集成"
+sidebarTitle: "WhatsUp Gold"
description: "WhatsUp Gold 通过邮件动作发送设备的宕机与恢复通知,使用 Flashduty 的邮件集成按规则触发和关闭 WhatsUp Gold 告警。"
keywords: ["告警集成", "WhatsUp Gold", "Progress", "WUG", "邮件", "Email", "网络监控"]
---
@@ -9,7 +10,6 @@ WhatsUp Gold 通过动作策略(Action Policy)里的 E-mail 动作发送设
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成邮件地址,任选其一即可。**集成类型都选择邮件 Email**,不是 WhatsUp Gold。
@@ -30,7 +30,6 @@ WhatsUp Gold 通过动作策略(Action Policy)里的 E-mail 动作发送设
</div>
## 在 WhatsUp Gold 中配置
----
WhatsUp Gold 的邮件没有告警 ID,下文让主题里带上设备显示名,Flashduty 从主题提取它作为 Alert Key。宕机邮件和恢复邮件只有前缀不同,提取出的 Key 相同,恢复邮件因此能关闭对应的告警。
@@ -52,7 +51,6 @@ WhatsUp Gold 的邮件没有告警 ID,下文让主题里带上设备显示名
如果希望按监视器区分告警,把动作策略绑定到具体的主动监视器(active monitor)上,并在两个动作的主题末尾都加上 `- %ActiveMonitor.Name`。`%ActiveMonitor.Name` 只在动作直接关联到主动监视器时才有值,不能用于整台设备的动作策略。
## 在 Flashduty 中配置推送规则
----
1. **推送模式** 选择 **根据规则触发或关闭告警**
2. 按顺序添加下面 2 条规则。每条规则的条件都是 **邮件标题** **匹配** 给出的正则,Alert Key **提取自** **邮件标题**
@@ -77,7 +75,6 @@ WhatsUp Gold 的邮件没有告警 ID,下文让主题里带上设备显示名
默认规则选丢弃,是为了不让 WhatsUp Gold 的其他邮件(例如您自己创建的其他 E-mail 动作)生成无法自动关闭的告警。
## 限制
----
- **恢复邮件依赖恢复动作**:只有动作策略里配置了 Up 状态变化的动作,Flashduty 才会收到恢复邮件。没有配置时,请在接收该集成的协作空间开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时。
- **重复通知**:动作策略勾选 **Repeat action** 后,宕机邮件会按间隔重复发送,它们标题相同,合并到同一条告警。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/wormly.mdx b/zh/on-call/integration/alert-integration/alert-sources/wormly.mdx
index 1806f2a8..74237191 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/wormly.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/wormly.mdx
@@ -1,5 +1,6 @@
---
title: "Wormly 告警集成"
+sidebarTitle: "Wormly"
description: "通过联系人的 Webhook 通道将 Wormly 主机的宕机、升级和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Wormly", "Uptime", "Webhook", "Alert Group", "hostid"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Wormly", "Uptime", "Webhook", "Alert Group", "hostid
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,7 +30,6 @@ keywords: ["告警集成", "Wormly", "Uptime", "Webhook", "Alert Group", "hostid
</div>
## 在 Wormly 中配置
----
<Steps>
<Step title="创建 Webhook 联系人">
@@ -61,7 +60,6 @@ Wormly 要求接收端与被监控的服务器不在同一台服务器上,请
</Note>
## 推送内容
----
Wormly 每次通知发送一个 JSON 对象,Flashduty 直接解析,无需配置模板:
@@ -78,14 +76,12 @@ Wormly 每次通知发送一个 JSON 对象,Flashduty 直接解析,无需配
告警标题使用主机名称;主机名称为空时使用 `Wormly host <hostid>`。请求既可以是 JSON 请求体,也可以是把 JSON 放在表单字段 `wormlyalert` 中的 urlencoded 或 multipart 表单。
## Alert Key
----
Flashduty 使用 `hostid` 作为 Alert Key。Wormly 文档将它定义为触发告警的 Wormly 主机的唯一 ID。同一个主机的故障、升级重复通知和恢复通知携带相同的 `hostid`,因此会落在同一条告警上;不同主机即使名称相同,也会生成不同的告警。修改主机名称、升级级别或传感器不会改变 Alert Key。
请求缺少 `hostid` 时,Flashduty 会返回参数错误,因为无法可靠地把恢复通知关联到原告警。
## 状态和告警等级
----
Wormly 的通知不区分告警等级,`alertlevel` 表示升级步骤而不是严重程度,Flashduty 对所有故障统一按 Critical 处理。
@@ -97,7 +93,6 @@ Wormly 的通知不区分告警等级,`alertlevel` 表示升级步骤而不是
`isrecovery` 缺失或不是 `0`、`1` 的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="持续故障时会产生多条 Flashduty 告警吗?">
@@ -120,7 +115,6 @@ Wormly 的通知不区分告警等级,`alertlevel` 表示升级步骤而不是
</AccordionGroup>
## 排查问题
----
- **Wormly 推送失败**:确认 URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认 Webhook 类型是 JSON,且请求中的 `hostid`、`isrecovery` 非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/xitoring.mdx b/zh/on-call/integration/alert-integration/alert-sources/xitoring.mdx
index 41cdbb01..0b9b5ba7 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/xitoring.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/xitoring.mdx
@@ -1,5 +1,6 @@
---
title: "Xitoring 告警集成"
+sidebarTitle: "Xitoring"
description: "通过通知角色的 Webhook 将 Xitoring 的宕机和恢复通知同步到 Flashduty On-call。"
keywords: ["告警集成", "Xitoring", "Notification Role", "Webhook", "Uptime", "服务器监控"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Xitoring", "Notification Role", "Webhook", "Uptime",
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,14 +30,13 @@ keywords: ["告警集成", "Xitoring", "Notification Role", "Webhook", "Uptime",
</div>
## 在 Xitoring 中配置
----
<Steps>
<Step title="创建通知角色">
1. 登录 Xitoring,进入 **Notification Roles** 页面,新建一个通知角色,或编辑已有角色
2. 打开角色的 **Automation & webhooks** 标签页,打开 **Webhook** 开关,把 Flashduty 集成的完整推送地址粘贴到 **Webhook URL**
-3. 点击 **Save changes**,再点击 **Send test** 并在弹窗中确认,验证地址:Flashduty 返回成功,不会创建告警。Send test 会通知所有角色的所有渠道,请使用只有你自己接收的角色
+3. 点击 **Save changes**,再点击 **Send test** 并在弹窗中确认,验证地址:Flashduty 返回成功,不会创建告警。Send test 会通知所有角色的所有渠道,请使用只有您自己接收的角色
<Note>
试用版只允许一个通知角色(`default`),请直接编辑它,而不是新建。
@@ -59,7 +58,6 @@ keywords: ["告警集成", "Xitoring", "Notification Role", "Webhook", "Uptime",
</Steps>
## 推送内容
----
Xitoring 以 `application/x-www-form-urlencoded` 表单格式 POST 以下字段,Flashduty 直接解析,无需配置模板:
@@ -79,14 +77,12 @@ Xitoring 以 `application/x-www-form-urlencoded` 表单格式 POST 以下字段
| `incident_time` | 事件时间 | 不保存 |
## Alert Key
----
Xitoring 文档把 `id` 定义为事件 ID,但没有说明恢复通知是否沿用同一个 `id`。因此 Flashduty 不用 `id`,而是把每次通知都携带的资源字段 `server_id`、`check_id`、`type`、`name` 用分隔符拼接后取 MD5 作为 Alert Key。同一个检查项或指标触发器的宕机、重复宕机和恢复通知得到相同的 Alert Key,落在同一条告警上;不同检查项、服务器或触发器得到不同的告警。修改名称、分组、指标值、`id` 或时间不会改变 Alert Key。
`server_id` 和 `check_id` 都为空,或 `type` 为空时,Flashduty 返回参数错误,因为无法可靠地把恢复通知关联到原告警。
## 状态和告警等级
----
Xitoring 的通知不携带告警等级,Flashduty 按检查类型判断:
@@ -103,7 +99,6 @@ Xitoring 的通知不携带告警等级,Flashduty 按检查类型判断:
`status` 为空或为其他值的请求会被拒绝,避免把无法判断状态的请求写入错误的告警生命周期。
## 常见问题
----
<AccordionGroup>
<Accordion title="测试通知会创建告警吗?">
@@ -126,7 +121,6 @@ Xitoring 的通知不携带告警等级,Flashduty 按检查类型判断:
</AccordionGroup>
## 排查问题
----
- **Xitoring 推送失败**:确认 Webhook URL 是完整的推送地址,且包含 `integration_key`
- **Flashduty 返回参数错误**:确认请求中 `status` 为 `0` 或 `1`,`type` 非空,且 `server_id` 或 `check_id` 至少一个非空
diff --git a/zh/on-call/integration/alert-integration/alert-sources/zabbix.mdx b/zh/on-call/integration/alert-integration/alert-sources/zabbix.mdx
index 8f4fe310..f9d7da88 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/zabbix.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/zabbix.mdx
@@ -1,5 +1,6 @@
---
-title: "Zabbix集成"
+title: "Zabbix 集成"
+sidebarTitle: "Zabbix"
description: "通过 webhook 的方式同步 Zabbix 告警事件到 Flashduty(支持 Zabbix 3.x ~ 6.x 版本,不同版本配置有差异),实现告警事件自动化降噪处理"
keywords: ["告警集成", "Zabbix集成", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "Zabbix集成", "监控告警", "数据接入"]
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "Zabbix集成", "监控告警", "数据接入"]
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "Zabbix集成", "监控告警", "数据接入"]
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **Zabbix** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -44,15 +44,12 @@ keywords: ["告警集成", "Zabbix集成", "监控告警", "数据接入"]
</AccordionGroup>
</div>
-## 在 Zabbix
----
+## 在 Zabbix
- [7.x 版本](#v7)
- [5.x~6.x 版本](#v5)
- [3.x~4.x 版本](#v4)
-## 一、Zabbix 配置
-
<span id="v7"></span>
### 7.x 版本
@@ -62,11 +59,11 @@ keywords: ["告警集成", "Zabbix集成", "监控告警", "数据接入"]
1. media type 是 Zabbix 中用于发送通知和告警的传输通道。进入终端,通过以下命令,下载完整配置
-```
-wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/zbx_mediatype_flashcat_v7.yml
+ ```
+ wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/zbx_mediatype_flashcat_v7.yml
-```
-2. 登录 Zabbix 控制台,选择 `Alert > Media Types`,点击右上角 Import 按钮,进入编辑页面,选择上边下载的配置文件,点击 Import 按钮完成导入
+ ```
+2. 登录 Zabbix 控制台,选择 `Alert > Media Types`,点击右上角 Import 按钮,进入编辑页面,选择上边下载的配置文件,点击 **Import** 按钮完成导入
3. 回到 Media Types 页面,可以看到已经导入的 media type。点击名称,进入编辑页面,补全 URL、zabbix_url 以及 HTTPProxy 等内容:
- `URL`:webhook 推送请求地址,复制集成的推送地址即可
@@ -87,14 +84,14 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
1. 登录 Zabbix 控制台,选择 `Users > Users`,选择 Admin 用户,选择 media,选择 Add,进入编辑窗口:
-- Type: 选择以上创建的 Flashduty media type
-- Send To:填写 Flashduty
-- 其他配置使用默认配置,保持不变
+ - Type: 选择以上创建的 Flashduty media type
+ - Send To:填写 Flashduty
+ - 其他配置使用默认配置,保持不变
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/zabbix-3.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/zabbix-3.png" />
-2. 点击 Add 按钮,退出添加 media 窗口
-3. 点击 Update 按钮,退出编辑 user 页面
+2. 点击 **Add** 按钮,退出添加 media 窗口
+3. 点击 **Update** 按钮,退出编辑 user 页面
</div>
@@ -106,15 +103,15 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
1. 点击 `Create action`,进入 action 编辑页面
-- Name:填写为“Send To Flashduty”
+ - Name:填写为“Send To Flashduty”
2. 选择 `Operations`,分别添加三种场景的通知发送配置:
-- 在 Operations 配置项,点击 Add 按钮,进入配置窗口
+- 在 Operations 配置项,点击 **Add** 按钮,进入配置窗口
- Send to users:选择以上新建或配置的 user
- Send only to:选择 Flashduty media type
- 其他配置保持默认
-- 点击 Add 按钮,完成该配置项配置
+- 点击 **Add** 按钮,完成该配置项配置
- 重复以上步骤,完成对 `Recovery operations` 和 `Update operations` 的配置
<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/zabbix-5.png" />
@@ -132,7 +129,7 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
1. 点击 Actions,弹窗内可以看到消息通知结果
2. 找到 Flashduty 对应日志,如果 Status 为 `Sent`,代表通知成功。否则根据提示排查原因
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/zabbix-6.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/doc/zabbix-6.png" />
3. 回到集成列表,如果展示了最新事件时间,说明配置成功且收到事件
4. 完成
@@ -150,15 +147,15 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
1. media type 是 Zabbix 中用于发送通知和告警的传输通道。进入终端,通过以下命令,下载完整配置
-```
-// 5.x版本 XML配置:
-wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/zbx_mediatype_flashcat_v5.xml
+ ```
+ // 5.x版本 XML配置:
+ wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/zbx_mediatype_flashcat_v5.xml
-// 6.x 版本 YAML 配置:
-wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/zbx_mediatype_flashcat_v6.yml
-```
+ // 6.x 版本 YAML 配置:
+ wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/zbx_mediatype_flashcat_v6.yml
+ ```
-2. 登录 Zabbix 控制台,选择 `Administration > Media Types`,点击右上角 Import 按钮,进入编辑页面,选择上边下载的配置文件,点击 Import 按钮完成导入
+2. 登录 Zabbix 控制台,选择 `Administration > Media Types`,点击右上角 Import 按钮,进入编辑页面,选择上边下载的配置文件,点击 **Import** 按钮完成导入
3. 回到 Media Types 页面,可以看到已经导入的 media type。点击名称,进入编辑页面,补全 URL、zabbix_url 以及 HTTPProxy 等内容:
- `URL`:webhook 推送请求地址,复制集成的推送地址即可
@@ -179,14 +176,14 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
1. 登录 Zabbix 控制台,选择 `Administration > Users`,选择 Admin 用户,选择 media,选择 Add,进入编辑窗口:
-- Type: 选择以上创建的 Flashduty media type
-- Send To:填写 N/A
-- 其他配置使用默认配置,保持不变
+ - Type: 选择以上创建的 Flashduty media type
+ - Send To:填写 N/A
+ - 其他配置使用默认配置,保持不变
<img alt="drawing" width="600" src="https://download.flashcat.cloud/user.png" />
-2. 点击 Add 按钮,退出添加 media 窗口
-3. 点击 Update 按钮,退出编辑 user 页面
+2. 点击 **Add** 按钮,退出添加 media 窗口
+3. 点击 **Update** 按钮,退出编辑 user 页面
</div>
@@ -198,15 +195,15 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
1. 点击 `Create action`,进入 action 编辑页面
-- Name:填写为“Send To Flashduty”
+ - Name:填写为“Send To Flashduty”
2. 选择 `Operations`,分别添加三种场景的通知发送配置:
-- 在 Operations 配置项,点击 Add 按钮,进入配置窗口
+- 在 Operations 配置项,点击 **Add** 按钮,进入配置窗口
- Send to users:选择以上新建或配置的 user
- Send only to:选择 Flashduty media type
- 其他配置保持默认
-- 点击 Add 按钮,完成该配置项配置
+- 点击 **Add** 按钮,完成该配置项配置
- 重复以上步骤,完成对 `Recovery operations` 和 `Update operations` 的配置
<img alt="drawing" width="600" src="https://download.flashcat.cloud/action-1.png" />
@@ -223,7 +220,7 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
1. 点击 Actions,弹窗内可以看到消息通知结果
2. 找到 Flashduty 对应日志,如果 Status 为 `Sent`,代表通知成功。否则根据提示排查原因
-<img alt="drawing" width="600" src="https://download.flashcat.cloud/problem.png" />
+ <img alt="drawing" width="600" src="https://download.flashcat.cloud/problem.png" />
3. 回到集成列表,如果展示了最新事件时间,说明配置成功且收到事件
4. 完成
@@ -241,12 +238,11 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
1. 登录 Zabbix 控制台,选择 `Administration > Media Types`,点击右上角 `Create media type` 按钮,进入编辑页面
2. 在编辑页面,Type 选择`Script`,Parameter 依次填写以下内容(不要调整顺序,没有值的也要留空,脚本按顺序获取参数值):
-- `{ALERT.SUBJECT}`:告警标题,保持在第一个参数
-- `{ALERT.MESSAGE}`:告警信息,保持在第二个参数
-
- - `Flashduty webhook 推送请求地址`,复制集成的推送地址即可,保持在第三个参数
- - `Zabbix 控制台地址`,直接复制即可(如果您的页面配置了 tomcat/nginx 转发路径,请同时携带),用于生成告警详情页面连接。如果没有空着即可,保持在第四个参数
- - `HTTPProxy`:如果您的 Zabbix Server 不能直接访问 Flashduty 服务,可以将该参数设置为一个代理地址。如果没有空着即可,保持在第五个参数
+ - `{ALERT.SUBJECT}`:告警标题,保持在第一个参数
+ - `{ALERT.MESSAGE}`:告警信息,保持在第二个参数
+ - `Flashduty webhook 推送请求地址`,复制集成的推送地址即可,保持在第三个参数
+ - `Zabbix 控制台地址`,直接复制即可(如果您的页面配置了 tomcat/nginx 转发路径,请同时携带),用于生成告警详情页面连接。如果没有空着即可,保持在第四个参数
+ - `HTTPProxy`:如果您的 Zabbix Server 不能直接访问 Flashduty 服务,可以将该参数设置为一个代理地址。如果没有空着即可,保持在第五个参数
<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/zabbix/v4_create_fd_media_type.jpg"/>
@@ -254,18 +250,18 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
4. 点击 Update,保存配置
5. 登录 Zabbix server 所在服务器,执行以下命令:
-```
+ ```
-#1. 进入告警脚本加载目录(具体地址配置在 Zabbix Server 配置文件中 `AlertScriptsPath` 变量,一般为`/usr/lib/zabbix/alertscripts`)
-cd /usr/lib/zabbix/alertscripts
+ #1. 进入告警脚本加载目录(具体地址配置在 Zabbix Server 配置文件中 `AlertScriptsPath` 变量,一般为`/usr/lib/zabbix/alertscripts`)
+ cd /usr/lib/zabbix/alertscripts
-#2. 下载脚本
-wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/send-to-flashduty.sh
+ #2. 下载脚本
+ wget --header="Referer: https://console.flashcat.cloud" https://download.flashcat.cloud/flashduty/integration/zabbix/send-to-flashduty.sh
-#3. 更改脚本为可执行状态
-chmod +x send-to-flashduty.sh
+ #3. 更改脚本为可执行状态
+ chmod +x send-to-flashduty.sh
-```
+ ```
6. 注意,`脚本中使用了 curl 和 jq 命令`,确保这个 Zabbix server 进程可以找到并执行这两个命令,如果没有您需要根据情况安装
@@ -285,8 +281,8 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/zabbix/v4_bind_media_type.jpg" />
-2. 点击 Add 按钮,退出添加 media 窗口
-3. 点击 Update 按钮,退出编辑 user 页面
+2. 点击 **Add** 按钮,退出添加 media 窗口
+3. 点击 **Update** 按钮,退出编辑 user 页面
</div>
@@ -302,11 +298,11 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
2. 选择 `Operations`,分别更新三种场景的通知用户配置:
- - 在 Operations 配置项,点击 Add 按钮,进入配置窗口
+ - 在 Operations 配置项,点击 **Add** 按钮,进入配置窗口
- Send to users:选择以上新建或配置的 user
- Send only to:选择 Flashduty media type
- 其他配置保持默认
- - 点击 Add 按钮,完成该配置项配置
+ - 点击 **Add** 按钮,完成该配置项配置
- 重复以上步骤,完成对 `Recovery operations` 和 `Update operations` 的配置
<img alt="drawing" width="600" src="https://download.flashcat.cloud/flashduty/integration/zabbix/v4_create_action_operation_add.jpg" />
@@ -331,7 +327,7 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
<div className="md-block">
-登录 Zabbix 控制台,选择 Monitoring > Problems,查看最新的告警列表。
+登录 Zabbix 控制台,选择 Monitoring → Problems,查看最新的告警列表。
1. 点击 Actions,弹窗内可以看到消息通知结果
2. 找到 Flashduty 对应日志,如果 Status 为 Sent,代表通知成功。否则根据提示排查原因
@@ -343,7 +339,7 @@ media type 必须关联至某个 user 才能发送事件。user 至少拥有对
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/zeek.mdx b/zh/on-call/integration/alert-integration/alert-sources/zeek.mdx
index 3c15a6d9..584347b6 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/zeek.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/zeek.mdx
@@ -1,5 +1,6 @@
---
title: "Zeek 告警集成"
+sidebarTitle: "Zeek"
description: "Zeek 的 Notice 框架可以把通知以邮件发出,使用 Flashduty 的邮件集成将 Zeek 通知接入 Flashduty。"
keywords: ["告警集成", "Zeek", "Bro", "Notice", "邮件", "Email", "网络安全监控", "NDR"]
---
@@ -9,7 +10,6 @@ Zeek 通过 Notice 框架把检测结果记为通知(notice),并可以用
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成邮件地址,任选其一即可。**集成类型都选择邮件 Email**,不是 Zeek。
@@ -30,7 +30,6 @@ Zeek 通过 Notice 框架把检测结果记为通知(notice),并可以用
</div>
## 在 Flashduty 中配置推送模式
----
Zeek 的通知邮件只有触发,没有恢复邮件,所以不需要按规则关闭告警,**推送模式** 选择 **总是触发新告警**(新建集成时页面可能预选了其他模式,请确认):每封邮件新建一条告警。
@@ -41,7 +40,6 @@ Zeek 的通知邮件只有触发,没有恢复邮件,所以不需要按规则
Zeek 已经会在 `suppress_for`(默认 1 小时)内压制同一通知的重复发送,一般不需要再在 Flashduty 合并。如果希望同一通知类型合并为一条告警,可以把推送模式改为 **根据邮件标题触发或更新告警**,代价是标题只含通知类型,不同主机的同类通知会合并到一起。
## 在 Zeek 中配置
----
### 配置收件人和发信程序(ZeekControl)
@@ -83,7 +81,6 @@ hook Notice::policy(n: Notice::Info)
修改后重新部署 Zeek(`zeekctl deploy`)使其生效。
## 邮件格式
----
单条通知邮件(`Notice::ACTION_EMAIL`)的标题是 `Notice::mail_subject_prefix`(默认 `[Zeek]`)加空格加通知类型,正文由下列部分组成:
@@ -103,7 +100,6 @@ Connection uid: CXWv6p3arKYeMETxOg
- 脚本通过 `email_body_sections` 扩展的内容会附在正文末尾
## 限制
----
- **只有触发,没有恢复**:Zeek 不会发送恢复邮件。请在接收该集成的协作空间开启 [超时自动关闭](/zh/on-call/channel/create-edit),建议 24 小时,否则告警需要手动关闭。
- **汇总邮件**:`Notice::ACTION_ALARM` 不发单条邮件,而是把 `notice_alarm` 日志按周期(ZeekControl 的 `MailAlarmsInterval`,默认 86400 秒)打包成一封汇总邮件,标题形如 `[Zeek] Log Contents: ...`,一封包含多条通知,只会生成一条告警。需要逐条告警时请使用 `Notice::ACTION_EMAIL`。
diff --git a/zh/on-call/integration/alert-integration/alert-sources/zenoss.mdx b/zh/on-call/integration/alert-integration/alert-sources/zenoss.mdx
index 8c7cd371..e1e03a84 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/zenoss.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/zenoss.mdx
@@ -1,5 +1,6 @@
---
title: "Zenoss 告警集成"
+sidebarTitle: "Zenoss"
description: "通过 Webhook 目的地将 Zenoss Cloud(Virtana Service Observability)的事件同步到 Flashduty On-call。"
keywords: ["告警集成", "Zenoss", "Virtana", "Service Observability", "Webhook", "基础设施监控"]
---
@@ -9,7 +10,6 @@ keywords: ["告警集成", "Zenoss", "Virtana", "Service Observability", "Webhoo
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下两种方式获取集成推送地址,任选其一即可。
@@ -30,14 +30,13 @@ keywords: ["告警集成", "Zenoss", "Virtana", "Service Observability", "Webhoo
</div>
## 在 Zenoss 中配置
----
Zenoss 通过 **目的地(Destination)**、**触发器(Trigger)** 和 **规则(Rule)** 三部分发送通知。创建规则需要 Manager 角色。
<Steps>
<Step title="添加 Webhook 目的地">
-1. 进入 **ADMIN > Actions**,打开 **DESTINATIONS** 标签,点击 **ADD DESTINATION**
+1. 进入 **ADMIN → Actions**,打开 **DESTINATIONS** 标签,点击 **ADD DESTINATION**
2. 目的地类型选择 **Webhook**,填写 **Destination name**
3. 将 Flashduty 集成的完整推送地址粘贴到 **URL**,地址中需包含 `integration_key`
4. **Headers** 留空,**Custom Payload** 保持关闭:Flashduty 解析 Zenoss 的默认消息,自定义 JSON 会导致无法识别事件
@@ -73,14 +72,12 @@ Zenoss 通过 **目的地(Destination)**、**触发器(Trigger)** 和 **
</Steps>
## Alert Key
----
Flashduty 用事件的 ID(消息中 `context.Context.Event.id`)生成 Alert Key。Zenoss 用事件名称加维度(dimensions)确定一个事件,并把事件 ID 作为查询该事件的键,因此同一个事件的重复通知、更新和关闭应当带同一个 ID,对应同一个 Alert Key。Zenoss 文档没有明确写出关闭通知沿用同一个 ID:上线前请关闭一个测试事件,确认对应告警变为已恢复,而不是新开一条告警。严重程度、摘要、状态和时间变化不会改变 Alert Key。
消息最外层的 `id` 是通知 ID,每次发送都不同,不参与计算。缺少事件 ID 的消息会被拒绝。
## 状态和告警等级
----
| Zenoss 状态(`status`) | Flashduty 状态 |
| :--- | :--- |
@@ -98,7 +95,6 @@ Flashduty 用事件的 ID(消息中 `context.Context.Event.id`)生成 Alert
消息里没有事件内容的通知(例如非事件类触发器)不会创建告警,Flashduty 收到后直接返回成功。
## 标签
----
| 标签 | 来源 |
| :--- | :--- |
@@ -112,7 +108,6 @@ Flashduty 用事件的 ID(消息中 `context.Context.Event.id`)生成 Alert
事件摘要(`summary`)作为告警描述。
## 排查问题
----
- **Flashduty 返回参数错误**:确认 URL 完整且包含 `integration_key`,并且目的地没有开启 Custom Payload
- **告警没有恢复**:确认规则已开启 **Send updates**,并且触发器没有把 Closed 事件排除在外
diff --git a/zh/on-call/integration/alert-integration/alert-sources/zilliz.mdx b/zh/on-call/integration/alert-integration/alert-sources/zilliz.mdx
index e3e4f1c6..8f21e015 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/zilliz.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/zilliz.mdx
@@ -1,5 +1,6 @@
---
title: "zilliz 告警事件"
+sidebarTitle: "zilliz"
description: "通过 webhook 的方式同步 zilliz 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "zilliz 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "zilliz 告警事件", "监控告警", "数据接入"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "zilliz 告警事件", "监控告警", "数据接入"
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "zilliz 告警事件", "监控告警", "数据接入"
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **zilliz** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,11 +45,9 @@ keywords: ["告警集成", "zilliz 告警事件", "监控告警", "数据接入"
</div>
## 在 zilliz
----
<div className="md-block">
-## 一、告警推送配置
1. 登录您的 `zilliz` 控制台,在 `Project Alerts` 中,创建或修改 `Alert`。
2. 在 `Alert` 编辑页面中的 `Send to` 部分,选择 `Webhook`,Webhook URL 填写告警集成的<span class='integration_url'>推送地址</span>。
@@ -60,7 +58,7 @@ keywords: ["告警集成", "zilliz 告警事件", "监控告警", "数据接入"
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/alert-sources/zstack.mdx b/zh/on-call/integration/alert-integration/alert-sources/zstack.mdx
index 1ebe5882..e0e0e0dc 100644
--- a/zh/on-call/integration/alert-integration/alert-sources/zstack.mdx
+++ b/zh/on-call/integration/alert-integration/alert-sources/zstack.mdx
@@ -1,5 +1,6 @@
---
title: "zstack 告警事件"
+sidebarTitle: "zstack"
description: "通过 webhook 的方式同步 zstack 告警事件到 Flashduty On-call,实现告警事件自动化降噪处理"
keywords: ["告警集成", "zstack 告警事件", "监控告警", "数据接入"]
---
@@ -7,7 +8,6 @@ keywords: ["告警集成", "zstack 告警事件", "监控告警", "数据接入"
<div className="hide">
## 在 Flashduty On-call
----
您可通过以下2种方式,获取一个集成推送地址,任选其一即可。
### 使用专属集成
@@ -15,7 +15,7 @@ keywords: ["告警集成", "zstack 告警事件", "监控告警", "数据接入"
当您不需要将告警事件路由到不同的协作空间,优先选择此方式,更简单。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看专属集成的配置步骤">
1. 进入 Flashduty 控制台,选择 **协作空间**,进入某个空间的详情页面
2. 选择 **配置** → **集成数据** → **专属集成**,点击 **新增一个集成**,进入添加集成页面
@@ -31,9 +31,9 @@ keywords: ["告警集成", "zstack 告警事件", "监控告警", "数据接入"
当您需要根据告警事件的 Payload 信息,将告警路由到不同的协作空间,优先选择此方式。
<AccordionGroup>
- <Accordion title="展开">
+ <Accordion title="查看共享集成的配置步骤">
- 1. 进入 Flashduty 控制台,选择 **集成中心=>告警事件**,进入集成选择页面。
+ 1. 进入 Flashduty 控制台,选择 **集成中心 → 告警事件**,进入集成选择页面。
2. 选择 **ZStack** 集成:
- **集成名称**:为当前集成定义一个名称。
3. 配置默认路由,并选择对应的协作空间(集成创建后可以前往 `路由` 进行更多路由规则的配置)。
@@ -45,11 +45,9 @@ keywords: ["告警集成", "zstack 告警事件", "监控告警", "数据接入"
</div>
## 在 ZStack
----
<div className="md-block">
-## 一、告警推送配置
### 步骤1:创建通知对象
@@ -74,7 +72,7 @@ keywords: ["告警集成", "zstack 告警事件", "监控告警", "数据接入"
</div>
-## 二、状态对照
+## 状态对照
<div className="md-block">
diff --git a/zh/on-call/integration/alert-integration/label-enhancement.mdx b/zh/on-call/integration/alert-integration/label-enhancement.mdx
index 6d291bb2..cc4a4c50 100644
--- a/zh/on-call/integration/alert-integration/label-enhancement.mdx
+++ b/zh/on-call/integration/alert-integration/label-enhancement.mdx
@@ -17,22 +17,14 @@ keywords: ["标签增强", "自动标签", "数据提取", "字段映射", "告
*/}
## 核心用途
-标签贯穿 Flashduty On-call 的告警处理全流程:
-
-| 场景 | 用途 |
-| :--- | :--- |
-| **故障筛选** | 在故障列表按标签快速过滤 |
-| **路由分发** | 根据标签将告警路由到不同协作空间 |
-| **分派通知** | 按标签匹配不同的分派策略 |
-| **告警聚合** | 按标签维度聚合相似告警 |
-| **静默/抑制** | 按标签匹配需要静默或抑制的告警 |
+标签贯穿告警处理全流程:故障列表按标签筛选,路由规则按标签分发到协作空间,分派策略按标签匹配,降噪按标签聚合,静默与抑制按标签匹配。标签增强让这些环节可以用上源数据里没有直接提供的信息。
## 配置标签增强
进入 集成详情 → **标签增强** → **添加规则**。
<Note>
-**空规则列表 = 不启用标签增强**:标签增强规则允许保存为空列表。删除全部规则并保存后,该集成不再执行任何标签增强,与集成初始状态一致;该行为对告警事件和变更事件均适用。删除最后一条规则后,编辑页显示 **暂无标签规则** 空态,点击 **添加标签规则** 即可重新配置。
+删除全部规则并保存,即可关闭该集成的标签增强(对告警事件和变更事件均生效)。此时编辑页显示 **暂无标签规则**,点击 **添加标签规则** 可重新配置。
</Note>
### 增强类型
@@ -48,6 +40,15 @@ keywords: ["标签增强", "自动标签", "数据提取", "字段映射", "告
<img src="https://docs-cdn.flashcat.cloud/images/png/c833e4ac159c9abaea755bad701d95ac.png" alt="标签增强类型" />
</Frame>
+#### 映射方式
+
+源标签的值不固定或含义不直观时,可以用映射把它转换为新的标签和值。添加映射规则时,可选择 **元数据表** 或 **API** 两种方式:
+
+| 映射类型 | 说明 | 适用场景 |
+| :--- | :--- | :--- |
+| **元数据表(Schema)** | 通过预定义的 CSV 映射表进行静态映射 | 映射关系相对固定,数据量有限 |
+| **API(接口映射)** | 通过调用外部 API 服务进行动态映射 | 需要查询外部系统(如 mapping api)获取实时数据 |
+
### 配置选项
| 选项 | 说明 |
@@ -131,18 +132,7 @@ keywords: ["标签增强", "自动标签", "数据提取", "字段映射", "告
</Steps>
</Tab>
-<Tab title="标签映射">
-**场景**:当源告警信息中的标签值不固定且不能直观定位其含义时,可以通过映射的方式将源标签映射为新定义的标签和值。
-
-标签映射支持两种映射方式,在添加映射规则时通过内联单选切换选择 **元数据表** 或 **API**:
-
-| 映射类型 | 说明 | 适用场景 |
-| :--- | :--- | :--- |
-| **元数据表(Schema)** | 通过预定义的 CSV 映射表进行静态映射 | 映射关系相对固定,数据量有限 |
-| **API(接口映射)** | 通过调用外部 API 服务进行动态映射 | 需要查询外部系统(如 mapping api)获取实时数据 |
-
-<Tabs>
-<Tab title="Schema 映射">
+<Tab title="映射:元数据表">
**示例**:源告警中只有资源类型 ID 信息,希望将每个 ID 对应的资源类型名称也体现出来。
<Steps>
@@ -159,11 +149,11 @@ keywords: ["标签增强", "自动标签", "数据提取", "字段映射", "告
</Step>
<Step title="创建映射表">
-1. 进入 `配置中心` → `映射数据` → `元数据表` → `创建映射表`
+1. 进入 **配置中心** → **映射数据** → **元数据表** → **创建映射表**
2. 填写基本信息,如名称、描述、管理团队等
3. 在 `映射表数据` 处,上传准备好的 CSV 文件(如果数量较少,创建完成后可以在映射详情页面中编辑添加)
4. 选择 `源标签`(如 `ID`),选择 `目标标签`(如 `Type`)
-5. 点击 `创建`,完成映射表创建
+5. 点击 **创建**,完成映射表创建
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/95bc8cdf3d3dcb60a52d11cdad4c386b.png" alt="创建映射表" />
@@ -192,22 +182,22 @@ keywords: ["标签增强", "自动标签", "数据提取", "字段映射", "告
</Steps>
</Tab>
-<Tab title="API 映射">
+<Tab title="映射:API">
**示例**:需要根据告警中的主机信息从 mapping api 系统查询负责团队、服务等级等动态数据。
<Steps>
<Step title="创建映射服务">
-1. 进入 `配置中心` → `映射数据` → `API` → `创建API`
+1. 进入 **配置中心** → **映射数据** → **API** → **创建API**
2. 填写服务配置信息:
-| 配置项 | 说明 | 示例 |
-| :--- | :--- | :--- |
-| 服务名称 | 服务的可读名称 | Mapping api 资产查询服务 |
-| 描述 | 服务用途说明 | 根据主机 IP 查询资产信息 |
-| 请求 URL | API 的请求地址 | `https://mapping-api.example.com/v1/enrich-event` |
-| 请求头 | HTTP 请求头配置 | `X-Auth-Token: your-token` |
-| 超时时间 | 请求超时时间,1-3 秒,默认 2 秒 | 1 |
-| 重试次数 | 请求失败后的重试次数,0-1 次,默认 0 次 | 1 |
+ | 配置项 | 说明 | 示例 |
+ | :--- | :--- | :--- |
+ | 服务名称 | 服务的可读名称 | Mapping api 资产查询服务 |
+ | 描述 | 服务用途说明 | 根据主机 IP 查询资产信息 |
+ | 请求 URL | API 的请求地址 | `https://mapping-api.example.com/v1/enrich-event` |
+ | 请求头 | HTTP 请求头配置 | `X-Auth-Token: your-token` |
+ | 超时时间 | 请求超时时间,1-3 秒,默认 2 秒 | 1 |
+ | 重试次数 | 请求失败后的重试次数,0-1 次,默认 0 次 | 1 |
<Tip>
如果 API 使用 HTTPS 且证书不受信任,可开启 `跳过证书验证` 选项。
@@ -227,8 +217,6 @@ keywords: ["标签增强", "自动标签", "数据提取", "字段映射", "告
</Steps>
</Tab>
</Tabs>
-</Tab>
-</Tabs>
## 映射数据管理
@@ -337,7 +325,7 @@ API 需要返回以下格式的 JSON 响应:
#### 最佳实践
-1. **性能优先**:API 位于告警处理的关键路径,必须保证低延迟(建议 < 1s)
+1. **性能优先**:API 位于告警处理的关键路径,必须保证低延迟(建议 < 500ms)
2. **实现缓存**:对于相同的查询条件,建议实现缓存以提高性能
3. **幂等设计**:对于同一个事件,多次调用应返回相同的结果
4. **安全认证**:API 必须通过认证机制保护,防止未授权访问
diff --git a/zh/on-call/integration/alert-integration/overview.mdx b/zh/on-call/integration/alert-integration/overview.mdx
new file mode 100644
index 00000000..dfe8fde1
--- /dev/null
+++ b/zh/on-call/integration/alert-integration/overview.mdx
@@ -0,0 +1,128 @@
+---
+title: "告警集成总览"
+sidebarTitle: "总览"
+description: "按名称查找监控工具、云平台和其他告警源的接入文档,并了解通用接入方式"
+---
+
+Flashduty On-call 通过告警集成接收外部系统推送或拉取的告警。下面先列出不依赖具体工具的通用接入方式,再按名称首字母列出全部告警集成。也可以按 Ctrl K 搜索工具名称。
+
+## 接入前先了解
+
+每个集成都可以用 **专属集成**(告警直接进入一个协作空间)或 **共享集成**(通过路由规则分发到多个协作空间)两种方式接入,区别见[集成数据](/zh/on-call/channel/integrate-data)和[路由规则](/zh/on-call/integration/alert-integration/routing-rules)。
+
+## 通用接入方式
+
+<CardGroup cols={2}>
+ <Card title="标准告警事件" href="/zh/on-call/integration/alert-integration/alert-sources/standard-alert">
+ 按 Flashduty 标准格式推送告警,适合自研系统或未单独适配的工具
+ </Card>
+ <Card title="邮件(Email)" href="/zh/on-call/integration/alert-integration/alert-sources/email">
+ 生成专属邮箱地址,通过邮件同步告警的发生与恢复
+ </Card>
+ <Card title="HTTP 拉取 (HTTP Pull)" href="/zh/on-call/integration/alert-integration/alert-sources/http-pull">
+ 由 Flashduty 定时拉取 HTTP 接口中的告警
+ </Card>
+ <Card title="数据库拉取 (DB Pull)" href="/zh/on-call/integration/alert-integration/alert-sources/db-pull">
+ 由 Flashduty 定时查询数据库中的告警记录
+ </Card>
+</CardGroup>
+
+## 全部告警集成(按名称排序)
+
+当前共 290 个告警集成文档。
+
+### A
+
+[Aikido Security](/zh/on-call/integration/alert-integration/alert-sources/aikido) · [Airbrake](/zh/on-call/integration/alert-integration/alert-sources/airbrake) · [SmartBear AlertSite](/zh/on-call/integration/alert-integration/alert-sources/alertsite) · [阿里云 ARMS](/zh/on-call/integration/alert-integration/alert-sources/aliyun-arms) · [阿里云监控 CM 事件](/zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-event) · [阿里云监控 CM 指标](/zh/on-call/integration/alert-integration/alert-sources/aliyun-cm-metrics) · [DataWorks 运维中心](/zh/on-call/integration/alert-integration/alert-sources/aliyun-dataworks-op) · [阿里云 Prometheus 监控](/zh/on-call/integration/alert-integration/alert-sources/aliyun-prometheus) · [阿里云 SLS](/zh/on-call/integration/alert-integration/alert-sources/aliyun-sls) · [Amazon Inspector](/zh/on-call/integration/alert-integration/alert-sources/amazon-inspector) · [apcupsd](/zh/on-call/integration/alert-integration/alert-sources/apcupsd) · [APIContext(APImetrics)](/zh/on-call/integration/alert-integration/alert-sources/apimetrics) · [AppDynamics](/zh/on-call/integration/alert-integration/alert-sources/appdynamics) · [AppSignal](/zh/on-call/integration/alert-integration/alert-sources/appsignal) · [Argo CD](/zh/on-call/integration/alert-integration/alert-sources/argocd) · [Atatus](/zh/on-call/integration/alert-integration/alert-sources/atatus) · [Auth0](/zh/on-call/integration/alert-integration/alert-sources/auth0) · [Auvik](/zh/on-call/integration/alert-integration/alert-sources/auvik) · [AWS CloudWatch](/zh/on-call/integration/alert-integration/alert-sources/aws-cloudwatch) · [AWS EventBridge](/zh/on-call/integration/alert-integration/alert-sources/aws-eventbridge) · [AWS Health](/zh/on-call/integration/alert-integration/alert-sources/aws-health) · [AWS Security Hub](/zh/on-call/integration/alert-integration/alert-sources/aws-security-hub) · [Axiom](/zh/on-call/integration/alert-integration/alert-sources/axiom) · [Azure Monitor](/zh/on-call/integration/alert-integration/alert-sources/azure-monitor) · [Azure Service Health](/zh/on-call/integration/alert-integration/alert-sources/azure-service-health)
+
+### B
+
+[百度云BCM监控](/zh/on-call/integration/alert-integration/alert-sources/baidu-bcm) · [BGPalerter](/zh/on-call/integration/alert-integration/alert-sources/bgpalerter) · [BigPanda](/zh/on-call/integration/alert-integration/alert-sources/bigpanda) · [Bitdefender GravityZone](/zh/on-call/integration/alert-integration/alert-sources/bitdefender) · [Bleemeo](/zh/on-call/integration/alert-integration/alert-sources/bleemeo) · [蓝鲸智云](/zh/on-call/integration/alert-integration/alert-sources/blueking) · [Blumira](/zh/on-call/integration/alert-integration/alert-sources/blumira) · [BugSnag](/zh/on-call/integration/alert-integration/alert-sources/bugsnag)
+
+### C
+
+[Calibre](/zh/on-call/integration/alert-integration/alert-sources/calibre) · [Canarytokens](/zh/on-call/integration/alert-integration/alert-sources/canarytokens) · [Catchpoint](/zh/on-call/integration/alert-integration/alert-sources/catchpoint) · [Cato Networks](/zh/on-call/integration/alert-integration/alert-sources/cato) · [Censys](/zh/on-call/integration/alert-integration/alert-sources/censys) · [Centreon](/zh/on-call/integration/alert-integration/alert-sources/centreon) · [Cert Spotter](/zh/on-call/integration/alert-integration/alert-sources/cert-spotter) · [CFEngine](/zh/on-call/integration/alert-integration/alert-sources/cfengine) · [Check Point SmartEvent](/zh/on-call/integration/alert-integration/alert-sources/check-point-smartevent) · [Checkly](/zh/on-call/integration/alert-integration/alert-sources/checkly) · [Checkmk](/zh/on-call/integration/alert-integration/alert-sources/checkmk) · [Chronosphere](/zh/on-call/integration/alert-integration/alert-sources/chronosphere) · [Circonus](/zh/on-call/integration/alert-integration/alert-sources/circonus) · [CloudAMQP](/zh/on-call/integration/alert-integration/alert-sources/cloudamqp) · [Cloudflare](/zh/on-call/integration/alert-integration/alert-sources/cloudflare) · [ClusterControl](/zh/on-call/integration/alert-integration/alert-sources/clustercontrol) · [HashiCorp Consul](/zh/on-call/integration/alert-integration/alert-sources/consul) · [Contrast Security](/zh/on-call/integration/alert-integration/alert-sources/contrast) · [Coralogix](/zh/on-call/integration/alert-integration/alert-sources/coralogix) · [Coroot](/zh/on-call/integration/alert-integration/alert-sources/coroot) · [Cronicle](/zh/on-call/integration/alert-integration/alert-sources/cronicle) · [Cronitor](/zh/on-call/integration/alert-integration/alert-sources/cronitor) · [CrowdSec](/zh/on-call/integration/alert-integration/alert-sources/crowdsec) · [CrowdStrike Falcon](/zh/on-call/integration/alert-integration/alert-sources/crowdstrike) · [CrowdStrike Falcon LogScale](/zh/on-call/integration/alert-integration/alert-sources/crowdstrike-logscale) · [天翼云](/zh/on-call/integration/alert-integration/alert-sources/ctyun) · [CubeAPM](/zh/on-call/integration/alert-integration/alert-sources/cubeapm)
+
+### D
+
+[Dash0](/zh/on-call/integration/alert-integration/alert-sources/dash0) · [Datadog](/zh/on-call/integration/alert-integration/alert-sources/datadog) · [Datto RMM](/zh/on-call/integration/alert-integration/alert-sources/datto-rmm) · [DBmarlin](/zh/on-call/integration/alert-integration/alert-sources/dbmarlin) · [Dead Man's Snitch](/zh/on-call/integration/alert-integration/alert-sources/dead-mans-snitch) · [Dependency-Track](/zh/on-call/integration/alert-integration/alert-sources/dependency-track) · [钉钉机器人兼容](/zh/on-call/integration/alert-integration/alert-sources/dingtalk-alert) · [Dkron](/zh/on-call/integration/alert-integration/alert-sources/dkron) · [Apache DolphinScheduler](/zh/on-call/integration/alert-integration/alert-sources/dolphinscheduler) · [Domotz](/zh/on-call/integration/alert-integration/alert-sources/domotz) · [Dotcom-Monitor](/zh/on-call/integration/alert-integration/alert-sources/dotcom-monitor) · [Duplicati](/zh/on-call/integration/alert-integration/alert-sources/duplicati) · [Dynatrace](/zh/on-call/integration/alert-integration/alert-sources/dynatrace)
+
+### E
+
+[移动云云监控](/zh/on-call/integration/alert-integration/alert-sources/ecloud-cm) · [Edge Delta](/zh/on-call/integration/alert-integration/alert-sources/edge-delta) · [ElastAlert2](/zh/on-call/integration/alert-integration/alert-sources/elastalert2) · [Elastic](/zh/on-call/integration/alert-integration/alert-sources/elastic) · [EMQX](/zh/on-call/integration/alert-integration/alert-sources/emqx) · [ExtraHop](/zh/on-call/integration/alert-integration/alert-sources/extrahop)
+
+### F
+
+[Fail2ban](/zh/on-call/integration/alert-integration/alert-sources/fail2ban) · [Falco](/zh/on-call/integration/alert-integration/alert-sources/falco) · [FastNetMon](/zh/on-call/integration/alert-integration/alert-sources/fastnetmon) · [Firebase Crashlytics](/zh/on-call/integration/alert-integration/alert-sources/firebase-crashlytics) · [Firefly](/zh/on-call/integration/alert-integration/alert-sources/firefly) · [Fivetran](/zh/on-call/integration/alert-integration/alert-sources/fivetran) · [夜莺/Flashcat](/zh/on-call/integration/alert-integration/alert-sources/flashcat) · [Fleet](/zh/on-call/integration/alert-integration/alert-sources/fleet) · [Flowmon ADS](/zh/on-call/integration/alert-integration/alert-sources/flowmon-ads) · [Flowtriq](/zh/on-call/integration/alert-integration/alert-sources/flowtriq) · [Flux CD](/zh/on-call/integration/alert-integration/alert-sources/fluxcd) · [Formant](/zh/on-call/integration/alert-integration/alert-sources/formant) · [FortiMonitor](/zh/on-call/integration/alert-integration/alert-sources/fortimonitor) · [FortiSIEM](/zh/on-call/integration/alert-integration/alert-sources/fortisiem)
+
+### G
+
+[Gatus](/zh/on-call/integration/alert-integration/alert-sources/gatus) · [Google Cloud Personalized Service Health](/zh/on-call/integration/alert-integration/alert-sources/gcp-personalized-service-health) · [Ghost Inspector](/zh/on-call/integration/alert-integration/alert-sources/ghost-inspector) · [GitGuardian](/zh/on-call/integration/alert-integration/alert-sources/gitguardian) · [GitHub](/zh/on-call/integration/alert-integration/alert-sources/github) · [GitLab](/zh/on-call/integration/alert-integration/alert-sources/gitlab) · [GoogleCloudMonitoring](/zh/on-call/integration/alert-integration/alert-sources/google-cloud-monitoring) · [Google Security Command Center](/zh/on-call/integration/alert-integration/alert-sources/google-scc) · [Grafana](/zh/on-call/integration/alert-integration/alert-sources/grafana) · [Graylog](/zh/on-call/integration/alert-integration/alert-sources/graylog) · [观测云](/zh/on-call/integration/alert-integration/alert-sources/guance)
+
+### H
+
+[HackerOne](/zh/on-call/integration/alert-integration/alert-sources/hackerone) · [Harbor](/zh/on-call/integration/alert-integration/alert-sources/harbor) · [Harness](/zh/on-call/integration/alert-integration/alert-sources/harness) · [Healthchecks.io](/zh/on-call/integration/alert-integration/alert-sources/healthchecks-io) · [Apache HertzBeat](/zh/on-call/integration/alert-integration/alert-sources/hertzbeat) · [HetrixTools](/zh/on-call/integration/alert-integration/alert-sources/hetrixtools) · [Honeybadger](/zh/on-call/integration/alert-integration/alert-sources/honeybadger) · [Honeycomb](/zh/on-call/integration/alert-integration/alert-sources/honeycomb) · [Hookdeck](/zh/on-call/integration/alert-integration/alert-sources/hookdeck) · [Hosted Graphite](/zh/on-call/integration/alert-integration/alert-sources/hosted-graphite) · [华为云 AOM](/zh/on-call/integration/alert-integration/alert-sources/huawei-aom) · [华为云 APM](/zh/on-call/integration/alert-integration/alert-sources/huawei-apm) · [华为云监控 CES](/zh/on-call/integration/alert-integration/alert-sources/huawei-ces) · [华为云日志服务 LTS](/zh/on-call/integration/alert-integration/alert-sources/huawei-lts) · [Hund](/zh/on-call/integration/alert-integration/alert-sources/hund) · [HyperDX](/zh/on-call/integration/alert-integration/alert-sources/hyperdx) · [Hyperping](/zh/on-call/integration/alert-integration/alert-sources/hyperping)
+
+### I
+
+[IBM QRadar](/zh/on-call/integration/alert-integration/alert-sources/ibm-qradar) · [Icinga 2](/zh/on-call/integration/alert-integration/alert-sources/icinga) · [Imperva](/zh/on-call/integration/alert-integration/alert-sources/imperva) · [Infisical](/zh/on-call/integration/alert-integration/alert-sources/infisical) · [Influxdata](/zh/on-call/integration/alert-integration/alert-sources/influxdata) · [Rapid7 InsightIDR](/zh/on-call/integration/alert-integration/alert-sources/insightidr) · [IBM Instana](/zh/on-call/integration/alert-integration/alert-sources/instana) · [Instatus](/zh/on-call/integration/alert-integration/alert-sources/instatus) · [Cisco Intersight](/zh/on-call/integration/alert-integration/alert-sources/intersight)
+
+### J
+
+[京东云监控](/zh/on-call/integration/alert-integration/alert-sources/jdcloud) · [JFrog Xray](/zh/on-call/integration/alert-integration/alert-sources/jfrog-xray) · [监控宝](/zh/on-call/integration/alert-integration/alert-sources/jiankongbao) · [JumpCloud](/zh/on-call/integration/alert-integration/alert-sources/jumpcloud) · [Juniper Mist](/zh/on-call/integration/alert-integration/alert-sources/juniper-mist)
+
+### K
+
+[Kapacitor](/zh/on-call/integration/alert-integration/alert-sources/kapacitor) · [Keep](/zh/on-call/integration/alert-integration/alert-sources/keep) · [Kener](/zh/on-call/integration/alert-integration/alert-sources/kener) · [Kentik](/zh/on-call/integration/alert-integration/alert-sources/kentik) · [Komodor](/zh/on-call/integration/alert-integration/alert-sources/komodor) · [金山云监控](/zh/on-call/integration/alert-integration/alert-sources/kscloud-monitor) · [Kuvasz](/zh/on-call/integration/alert-integration/alert-sources/kuvasz)
+
+### L
+
+[Lacework FortiCNAPP](/zh/on-call/integration/alert-integration/alert-sources/lacework) · [LangSmith](/zh/on-call/integration/alert-integration/alert-sources/langsmith) · [飞书机器人兼容](/zh/on-call/integration/alert-integration/alert-sources/lark-alert) · [Last9](/zh/on-call/integration/alert-integration/alert-sources/last9) · [Level](/zh/on-call/integration/alert-integration/alert-sources/level) · [LibreNMS](/zh/on-call/integration/alert-integration/alert-sources/librenms) · [LimaCharlie](/zh/on-call/integration/alert-integration/alert-sources/limacharlie) · [Loadster](/zh/on-call/integration/alert-integration/alert-sources/loadster) · [Loggly](/zh/on-call/integration/alert-integration/alert-sources/loggly) · [LogicMonitor](/zh/on-call/integration/alert-integration/alert-sources/logicmonitor) · [Logpoint](/zh/on-call/integration/alert-integration/alert-sources/logpoint) · [LogRocket](/zh/on-call/integration/alert-integration/alert-sources/logrocket) · [Logz.io](/zh/on-call/integration/alert-integration/alert-sources/logz-io)
+
+### M
+
+[Mackerel](/zh/on-call/integration/alert-integration/alert-sources/mackerel) · [Meraki](/zh/on-call/integration/alert-integration/alert-sources/meraki) · [Metoro](/zh/on-call/integration/alert-integration/alert-sources/metoro) · [Mezmo](/zh/on-call/integration/alert-integration/alert-sources/mezmo) · [Microsoft Defender for Cloud](/zh/on-call/integration/alert-integration/alert-sources/microsoft-defender-for-cloud) · [Microsoft Sentinel](/zh/on-call/integration/alert-integration/alert-sources/microsoft-sentinel) · [Moesif](/zh/on-call/integration/alert-integration/alert-sources/moesif) · [MongoDB Atlas](/zh/on-call/integration/alert-integration/alert-sources/mongodb-atlas) · [Monit](/zh/on-call/integration/alert-integration/alert-sources/monit) · [Monitive](/zh/on-call/integration/alert-integration/alert-sources/monitive) · [Monte Carlo](/zh/on-call/integration/alert-integration/alert-sources/monte-carlo)
+
+### N
+
+[Nagios](/zh/on-call/integration/alert-integration/alert-sources/nagios) · [NetBeez](/zh/on-call/integration/alert-integration/alert-sources/netbeez) · [Netdata](/zh/on-call/integration/alert-integration/alert-sources/netdata) · [New Relic](/zh/on-call/integration/alert-integration/alert-sources/new-relic) · [Nobl9](/zh/on-call/integration/alert-integration/alert-sources/nobl9) · [NodePing](/zh/on-call/integration/alert-integration/alert-sources/nodeping) · [NS1 Connect](/zh/on-call/integration/alert-integration/alert-sources/ns1) · [ntopng](/zh/on-call/integration/alert-integration/alert-sources/ntopng) · [NUT (Network UPS Tools)](/zh/on-call/integration/alert-integration/alert-sources/nut)
+
+### O
+
+[Obkio](/zh/on-call/integration/alert-integration/alert-sources/obkio) · [Observium](/zh/on-call/integration/alert-integration/alert-sources/observium) · [OceanBase](/zh/on-call/integration/alert-integration/alert-sources/oceanbase) · [OCI Monitoring](/zh/on-call/integration/alert-integration/alert-sources/oci-monitoring) · [Odown](/zh/on-call/integration/alert-integration/alert-sources/odown) · [Ofelia](/zh/on-call/integration/alert-integration/alert-sources/ofelia) · [Oh Dear](/zh/on-call/integration/alert-integration/alert-sources/ohdear) · [Okta](/zh/on-call/integration/alert-integration/alert-sources/okta) · [Open Falcon](/zh/on-call/integration/alert-integration/alert-sources/open-falcon) · [OpenNMS](/zh/on-call/integration/alert-integration/alert-sources/opennms) · [OpenObserve](/zh/on-call/integration/alert-integration/alert-sources/openobserve) · [OpenSearch](/zh/on-call/integration/alert-integration/alert-sources/opensearch) · [OpenStatus](/zh/on-call/integration/alert-integration/alert-sources/openstatus) · [Opmanager](/zh/on-call/integration/alert-integration/alert-sources/opmanager) · [OPNsense](/zh/on-call/integration/alert-integration/alert-sources/opnsense) · [Opsgenie 兼容](/zh/on-call/integration/alert-integration/alert-sources/opsgenie) · [Opsview](/zh/on-call/integration/alert-integration/alert-sources/opsview) · [OSSEC](/zh/on-call/integration/alert-integration/alert-sources/ossec)
+
+### P
+
+[PagerDuty 兼容](/zh/on-call/integration/alert-integration/alert-sources/pagerduty) · [Pandora FMS](/zh/on-call/integration/alert-integration/alert-sources/pandora-fms) · [Panther](/zh/on-call/integration/alert-integration/alert-sources/panther) · [Papertrail](/zh/on-call/integration/alert-integration/alert-sources/papertrail) · [Peekaping](/zh/on-call/integration/alert-integration/alert-sources/peekaping) · [pgDash](/zh/on-call/integration/alert-integration/alert-sources/pgdash) · [Phare Uptime](/zh/on-call/integration/alert-integration/alert-sources/phare) · [Pingdom](/zh/on-call/integration/alert-integration/alert-sources/pingdom) · [Postman](/zh/on-call/integration/alert-integration/alert-sources/postman) · [PowerJob](/zh/on-call/integration/alert-integration/alert-sources/powerjob) · [ProjectDiscovery Cloud](/zh/on-call/integration/alert-integration/alert-sources/projectdiscovery) · [Prometheus](/zh/on-call/integration/alert-integration/alert-sources/prometheus) · [PRTG](/zh/on-call/integration/alert-integration/alert-sources/prtg) · [Pulsetic](/zh/on-call/integration/alert-integration/alert-sources/pulsetic) · [Pulseway](/zh/on-call/integration/alert-integration/alert-sources/pulseway)
+
+### R
+
+[Raritan PX PDU](/zh/on-call/integration/alert-integration/alert-sources/raritan-px) · [Raygun](/zh/on-call/integration/alert-integration/alert-sources/raygun) · [RBLTracker](/zh/on-call/integration/alert-integration/alert-sources/rbltracker) · [Red Hat OpenShift](/zh/on-call/integration/alert-integration/alert-sources/red-hat-openshift) · [Redash](/zh/on-call/integration/alert-integration/alert-sources/redash) · [Redgate SQL Monitor](/zh/on-call/integration/alert-integration/alert-sources/redgate-sql-monitor) · [日志易](/zh/on-call/integration/alert-integration/alert-sources/rizhiyi) · [Robotalp](/zh/on-call/integration/alert-integration/alert-sources/robotalp) · [Robusta](/zh/on-call/integration/alert-integration/alert-sources/robusta) · [Rollbar](/zh/on-call/integration/alert-integration/alert-sources/rollbar) · [RUM](/zh/on-call/integration/alert-integration/alert-sources/rum-alert)
+
+### S
+
+[SearchStax](/zh/on-call/integration/alert-integration/alert-sources/searchstax) · [SecurityScorecard](/zh/on-call/integration/alert-integration/alert-sources/securityscorecard) · [Sematext](/zh/on-call/integration/alert-integration/alert-sources/sematext) · [Semgrep](/zh/on-call/integration/alert-integration/alert-sources/semgrep) · [Sensu Go](/zh/on-call/integration/alert-integration/alert-sources/sensu) · [Sentry](/zh/on-call/integration/alert-integration/alert-sources/sentry) · [IBM SevOne NPM](/zh/on-call/integration/alert-integration/alert-sources/sevone) · [SigNoz](/zh/on-call/integration/alert-integration/alert-sources/signoz) · [Simple Observability](/zh/on-call/integration/alert-integration/alert-sources/simple-observability) · [Site24x7](/zh/on-call/integration/alert-integration/alert-sources/site24x7) · [Skywalking](/zh/on-call/integration/alert-integration/alert-sources/skywalking) · [Snyk](/zh/on-call/integration/alert-integration/alert-sources/snyk) · [SolarWinds](/zh/on-call/integration/alert-integration/alert-sources/solarwinds) · [SolarWinds Platform (Orion)](/zh/on-call/integration/alert-integration/alert-sources/solarwinds-orion) · [SonarQube](/zh/on-call/integration/alert-integration/alert-sources/sonarqube) · [Split](/zh/on-call/integration/alert-integration/alert-sources/split-io) · [Splunk](/zh/on-call/integration/alert-integration/alert-sources/splunk) · [Splunk Observability Cloud](/zh/on-call/integration/alert-integration/alert-sources/splunk-observability) · [StackRox](/zh/on-call/integration/alert-integration/alert-sources/stackrox) · [StatusCake](/zh/on-call/integration/alert-integration/alert-sources/statuscake) · [StatusGator](/zh/on-call/integration/alert-integration/alert-sources/statusgator) · [Atlassian Statuspage](/zh/on-call/integration/alert-integration/alert-sources/statuspage) · [Statuspal](/zh/on-call/integration/alert-integration/alert-sources/statuspal) · [Stripe](/zh/on-call/integration/alert-integration/alert-sources/stripe) · [Sublime Security](/zh/on-call/integration/alert-integration/alert-sources/sublime) · [Sumo Logic](/zh/on-call/integration/alert-integration/alert-sources/sumo-logic) · [Suricata](/zh/on-call/integration/alert-integration/alert-sources/suricata) · [Sysdig](/zh/on-call/integration/alert-integration/alert-sources/sysdig)
+
+### T
+
+[Tactical RMM](/zh/on-call/integration/alert-integration/alert-sources/tactical-rmm) · [Tailscale](/zh/on-call/integration/alert-integration/alert-sources/tailscale) · [腾讯云日志服务CLS](/zh/on-call/integration/alert-integration/alert-sources/tencent-cls) · [腾讯云监控 CM](/zh/on-call/integration/alert-integration/alert-sources/tencent-cm) · [腾讯云直播](/zh/on-call/integration/alert-integration/alert-sources/tencent-css) · [腾讯云 EventBridge](/zh/on-call/integration/alert-integration/alert-sources/tencent-eventbridge) · [Thinkst Canary](/zh/on-call/integration/alert-integration/alert-sources/thinkst-canary) · [ThousandEyes](/zh/on-call/integration/alert-integration/alert-sources/thousandeyes) · [Tideways](/zh/on-call/integration/alert-integration/alert-sources/tideways) · [Aqua Tracee](/zh/on-call/integration/alert-integration/alert-sources/tracee) · [Trigger.dev](/zh/on-call/integration/alert-integration/alert-sources/trigger-dev) · [Trivy Operator](/zh/on-call/integration/alert-integration/alert-sources/trivy-operator) · [Twilio](/zh/on-call/integration/alert-integration/alert-sources/twilio) · [Twingate](/zh/on-call/integration/alert-integration/alert-sources/twingate)
+
+### U
+
+[UCloud CloudWatch](/zh/on-call/integration/alert-integration/alert-sources/ucloud-cloudwatch) · [updown.io](/zh/on-call/integration/alert-integration/alert-sources/updown) · [UpGuard](/zh/on-call/integration/alert-integration/alert-sources/upguard) · [Uptime.com](/zh/on-call/integration/alert-integration/alert-sources/uptime-com) · [Uptime Kuma](/zh/on-call/integration/alert-integration/alert-sources/uptime-kuma) · [UptimeObserver](/zh/on-call/integration/alert-integration/alert-sources/uptimeobserver) · [UptimeRobot](/zh/on-call/integration/alert-integration/alert-sources/uptimerobot) · [Uptimia](/zh/on-call/integration/alert-integration/alert-sources/uptimia) · [Uptrends](/zh/on-call/integration/alert-integration/alert-sources/uptrends)
+
+### V
+
+[Veeam ONE](/zh/on-call/integration/alert-integration/alert-sources/veeam-one) · [Veeam Service Provider Console](/zh/on-call/integration/alert-integration/alert-sources/veeam-service-provider-console) · [Veracode SCA](/zh/on-call/integration/alert-integration/alert-sources/veracode-sca) · [Vigil](/zh/on-call/integration/alert-integration/alert-sources/vigil) · [火山引擎云监控事件中心](/zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-event) · [火山引擎云监控](/zh/on-call/integration/alert-integration/alert-sources/volcengine-cm-metrics) · [火山引擎云拨测](/zh/on-call/integration/alert-integration/alert-sources/volcengine-dial) · [火山引擎 RTC](/zh/on-call/integration/alert-integration/alert-sources/volcengine-rtc) · [火山引擎日志服务 TLS](/zh/on-call/integration/alert-integration/alert-sources/volcengine-tls)
+
+### W
+
+[Wazuh](/zh/on-call/integration/alert-integration/alert-sources/wazuh) · [企微机器人兼容](/zh/on-call/integration/alert-integration/alert-sources/wecom-alert) · [WhaTap](/zh/on-call/integration/alert-integration/alert-sources/whatap) · [WhatsUp Gold](/zh/on-call/integration/alert-integration/alert-sources/whatsup-gold) · [Wormly](/zh/on-call/integration/alert-integration/alert-sources/wormly)
+
+### X
+
+[Xitoring](/zh/on-call/integration/alert-integration/alert-sources/xitoring)
+
+### Z
+
+[Zabbix](/zh/on-call/integration/alert-integration/alert-sources/zabbix) · [Zeek](/zh/on-call/integration/alert-integration/alert-sources/zeek) · [Zenoss](/zh/on-call/integration/alert-integration/alert-sources/zenoss) · [zilliz](/zh/on-call/integration/alert-integration/alert-sources/zilliz) · [zstack](/zh/on-call/integration/alert-integration/alert-sources/zstack)
diff --git a/zh/on-call/integration/alert-integration/routing-rules.mdx b/zh/on-call/integration/alert-integration/routing-rules.mdx
index c5092e96..26072033 100644
--- a/zh/on-call/integration/alert-integration/routing-rules.mdx
+++ b/zh/on-call/integration/alert-integration/routing-rules.mdx
@@ -56,11 +56,11 @@ keywords: ["路由规则", "告警路由", "分发策略", "协作空间", "分
### 编辑历史
-路由规则支持查看编辑历史,帮助你追踪配置变更并在需要时快速回滚。
+路由规则支持查看编辑历史,帮助您追踪配置变更并在需要时快速回滚。
点击路由配置页面中的 **编辑历史** 按钮,打开对话框(左侧为历史版本列表,右侧为差异对比区)。历史记录按日期分组显示,每条记录包含版本号、操作人和修改时间。当前生效的版本会标注为 **当前版本**。
-你可以执行以下操作:
+您可以执行以下操作:
| 操作 | 说明 |
| :--- | :--- |
diff --git a/zh/on-call/integration/change-integration/apollo.mdx b/zh/on-call/integration/change-integration/apollo.mdx
index 8e660cfe..273bebbc 100644
--- a/zh/on-call/integration/change-integration/apollo.mdx
+++ b/zh/on-call/integration/change-integration/apollo.mdx
@@ -1,5 +1,6 @@
---
title: "Apollo 配置中心变更集成"
+sidebarTitle: "Apollo 配置中心"
description: "通过 Apollo Portal 的配置发布 Webhook,将每次配置发布、回滚、灰度发布和全量发布同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Apollo", "携程 Apollo", "配置中心", "配置发布", "Webhook"]
---
@@ -15,7 +16,6 @@ Apollo 只在操作完成后推送,没有开始事件,因此变更没有 Pro
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Apollo**,填写集成名称
@@ -25,7 +25,6 @@ Apollo 只在操作完成后推送,没有开始事件,因此变更没有 Pro
</div>
## 在 Apollo 中配置
----
Apollo 从 1.8.0 版本开始支持配置发布 Webhook。配置项存放在 `ApolloPortalDB.ServerConfig` 表中,也可以在 Apollo Portal 的 **管理员工具 → 系统参数** 页面修改,修改后约一分钟生效。
@@ -64,7 +63,6 @@ Apollo 没有测试推送:在 Portal 中对任一已开启 Webhook 的环境
</Steps>
## 一条变更是什么
----
一条变更对应 Apollo 的一次发布操作,变更标识(change_key)为 `<环境>/<发布历史 ID>`,例如 `PRO/1234`。
@@ -75,7 +73,6 @@ Apollo 没有测试推送:在 Portal 中对任一已开启 Webhook 的环境
同一个命名空间的两次发布是两条变更;发布后回滚也是两条变更。
## 状态映射
----
Apollo 推送的 `operation` 决定变更的类型,状态为 Done(废弃的发布除外,见表后说明):
@@ -91,7 +88,6 @@ Apollo 推送的 `operation` 决定变更的类型,状态为 Done(废弃的
出现以上四种之外的 `operation` 值时,推送返回 InvalidParameter,不生成变更。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -116,7 +112,6 @@ Apollo 推送的 `operation` 决定变更的类型,状态为 Done(废弃的
| `emergency` | 紧急发布时为 `true` |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么看不到配置项的内容?">
diff --git a/zh/on-call/integration/change-integration/argo-rollouts.mdx b/zh/on-call/integration/change-integration/argo-rollouts.mdx
index 59a38707..339eead0 100644
--- a/zh/on-call/integration/change-integration/argo-rollouts.mdx
+++ b/zh/on-call/integration/change-integration/argo-rollouts.mdx
@@ -1,5 +1,6 @@
---
title: "Argo Rollouts 变更集成"
+sidebarTitle: "Argo Rollouts"
description: "通过 Argo Rollouts 内置的 Notifications Webhook 将 Rollout 的发布版本同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Argo Rollouts", "Rollout", "金丝雀发布", "蓝绿发布", "渐进式交付", "Notifications", "Webhook", "部署事件"]
---
@@ -13,7 +14,6 @@ Argo Rollouts 控制器内置 **Notifications**(基于 Argo 的 notifications-
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Argo Rollouts**,填写集成名称
@@ -23,7 +23,6 @@ Argo Rollouts 控制器内置 **Notifications**(基于 Argo 的 notifications-
</div>
## 在 Argo Rollouts 中配置
----
以下操作需要能修改 Argo Rollouts 控制器所在命名空间(默认 `argo-rollouts`)中 ConfigMap 的 Kubernetes 权限,以及修改 Rollout 注解的权限。Argo Rollouts 控制器需要能访问推送地址所在的域名。
@@ -189,7 +188,6 @@ Argo Rollouts 没有发送测试消息的功能。修改一个已订阅的 Rollo
</Steps>
## 一条变更是什么
----
一条变更对应一个 Rollout 的一个发布版本,变更标识(change_key)为 `<rollout_uid>/<revision>`:
@@ -201,7 +199,6 @@ Argo Rollouts 没有发送测试消息的功能。修改一个已订阅的 Rollo
请求缺少 `event`、`rollout_uid`、`revision` 或 `event_time` 时,Flashduty 会拒绝该请求。
## 状态映射
----
| 触发器 | 事件(`event`) | 含义 | Flashduty 变更状态 |
|---|---|---|---|
@@ -217,7 +214,6 @@ Done 和 Failed 是结束状态,Flashduty 会记录变更结束时间。`event
- 中止后执行 `kubectl argo rollouts retry`,发布最终完成时同一条变更会从 Failed 更新为 Done
## 变更内容
----
- **标题**:`<命名空间>/<Rollout 名称>: rollout revision <修订号> (<镜像>)`,多个容器的镜像用逗号分隔,没有镜像时省略括号部分
- **链接**:Argo Rollouts 没有对应每次发布的网页,变更没有链接
@@ -235,7 +231,6 @@ Done 和 Failed 是结束状态,Flashduty 会记录变更结束时间。`event
| `event` | 最新一次事件:`updated`、`completed`、`skip_steps` 或 `aborted` |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到变更?">
diff --git a/zh/on-call/integration/change-integration/argocd.mdx b/zh/on-call/integration/change-integration/argocd.mdx
index 7f4794b4..0bf8bb3f 100644
--- a/zh/on-call/integration/change-integration/argocd.mdx
+++ b/zh/on-call/integration/change-integration/argocd.mdx
@@ -1,5 +1,6 @@
---
title: "Argo CD 变更集成"
+sidebarTitle: "Argo CD"
description: "通过 Argo CD Notifications 的 Webhook 服务将应用同步(Sync)操作同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Argo CD", "ArgoCD", "GitOps", "Sync", "Notifications", "Webhook", "部署事件"]
---
@@ -13,7 +14,6 @@ Argo CD 通过内置的 **Notifications**(`argocd-notifications-controller`)
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Argo CD**,填写集成名称
@@ -23,7 +23,6 @@ Argo CD 通过内置的 **Notifications**(`argocd-notifications-controller`)
</div>
## 在 Argo CD 中配置
----
以下操作需要能修改 Argo CD 所在命名空间(默认 `argocd`)中 ConfigMap 的 Kubernetes 权限,以及修改 Application 或 AppProject 注解的权限。Argo CD 集群需要能访问推送地址所在的域名。
@@ -137,7 +136,6 @@ kubectl exec -n argocd deploy/argocd-notifications-controller -- \
</Steps>
## 一条变更是什么
----
一条变更对应一个应用的一次同步操作,变更标识(change_key)为 `<app_uid>/<started_at>`:
@@ -149,7 +147,6 @@ kubectl exec -n argocd deploy/argocd-notifications-controller -- \
请求缺少 `app_uid` 或 `started_at`,或者时间不是 RFC 3339 格式时,Flashduty 会拒绝该请求。
## 状态映射
----
| Argo CD 同步阶段(`phase`) | Flashduty 变更状态 |
|---|---|
@@ -165,7 +162,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
同步开始时记录的时间是 `started_at`,结束时是 `finished_at`。Argo CD 失败后自动重试期间,同步阶段保持 `Running`,不会提前记为 Failed。
## 变更内容
----
- **标题**:`<应用名>: sync <版本> to <目标命名空间>`。版本为 Git 提交时显示前 7 位,Helm Chart 版本等其他值原样显示;没有版本或目标命名空间时省略对应部分
- **链接**:`<argocdUrl>/applications/<应用名>`,配置了 `context.argocdUrl` 时才有
@@ -188,7 +184,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
值为空的字段不会写入标签。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到变更?">
diff --git a/zh/on-call/integration/change-integration/awx.mdx b/zh/on-call/integration/change-integration/awx.mdx
index a8bcb6a3..9adedafb 100644
--- a/zh/on-call/integration/change-integration/awx.mdx
+++ b/zh/on-call/integration/change-integration/awx.mdx
@@ -1,5 +1,6 @@
---
title: "AWX / Ansible Automation Platform 变更集成"
+sidebarTitle: "AWX / Ansible Automation Platform"
description: "通过 AWX 或 Ansible Automation Platform 的 Webhook 通知,将作业模板和工作流作业的每次运行同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "AWX", "Ansible", "Ansible Automation Platform", "Webhook 通知", "作业模板", "运维自动化"]
---
@@ -13,7 +14,6 @@ AWX 无法区分一个作业模板是否会改变线上环境,因此只需在*
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **AWX / Ansible Automation Platform**,填写集成名称
@@ -23,7 +23,6 @@ AWX 无法区分一个作业模板是否会改变线上环境,因此只需在*
</div>
## 在 AWX 中配置
----
<Steps>
<Step title="创建 Webhook 通知模板">
@@ -55,7 +54,6 @@ AWX 无法区分一个作业模板是否会改变线上环境,因此只需在*
</Steps>
## 一条变更是什么
----
每一次作业模板或工作流作业的运行是一条变更,变更标识(change_key)为 AWX 的作业 ID(`id`),例如 `4711`。
@@ -65,7 +63,6 @@ AWX 无法区分一个作业模板是否会改变线上环境,因此只需在*
- 作业 ID 在一个 AWX 实例内唯一。多个 AWX 实例请分别创建集成,否则不同实例上相同的作业 ID 会被合并为一条变更
## 状态映射
----
| 通知 | 作业状态(status) | Flashduty 变更状态 |
|---|---|---|
@@ -80,7 +77,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
自定义消息体时,`new` 映射为 Planned,`pending` 和 `waiting` 映射为 Ready;默认消息体不会发送这三个状态。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -104,7 +100,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
额外变量(extra_vars)、凭据和各主机的执行结果可能包含敏感信息,不会被记录。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到变更?">
diff --git a/zh/on-call/integration/change-integration/azure-devops.mdx b/zh/on-call/integration/change-integration/azure-devops.mdx
index 8600c79a..cc0f9903 100644
--- a/zh/on-call/integration/change-integration/azure-devops.mdx
+++ b/zh/on-call/integration/change-integration/azure-devops.mdx
@@ -1,5 +1,6 @@
---
title: "Azure DevOps 变更集成"
+sidebarTitle: "Azure DevOps"
description: "通过 Azure DevOps Service Hooks 将流水线运行(Pipelines run)和经典发布(Release)阶段部署同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Azure DevOps", "Pipelines", "Release", "Service Hooks", "Webhook"]
---
@@ -14,7 +15,6 @@ keywords: ["变更集成", "Azure DevOps", "Pipelines", "Release", "Service Hook
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Azure DevOps**,填写集成名称
@@ -24,7 +24,6 @@ keywords: ["变更集成", "Azure DevOps", "Pipelines", "Release", "Service Hook
</div>
## 在 Azure DevOps 中配置
----
<Steps>
<Step title="创建 Service Hooks 订阅">
@@ -64,7 +63,6 @@ keywords: ["变更集成", "Azure DevOps", "Pipelines", "Release", "Service Hook
点击 **Test** 发送的是示例推送,Flashduty 返回成功但不生成变更。
## 一条变更是什么
----
| Azure DevOps 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -74,7 +72,6 @@ keywords: ["变更集成", "Azure DevOps", "Pipelines", "Release", "Service Hook
<Note>Azure DevOps 的运行 ID 只在组织内唯一。多个 Azure DevOps 组织请分别创建 Flashduty 集成。</Note>
## 状态映射
----
**流水线运行**(Run state changed)
@@ -105,7 +102,6 @@ keywords: ["变更集成", "Azure DevOps", "Pipelines", "Release", "Service Hook
- Service Hooks 的 **Test** 推送
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -126,7 +122,6 @@ keywords: ["变更集成", "Azure DevOps", "Pipelines", "Release", "Service Hook
流水线运行的事件不包含项目名称,因此没有 `project` 标签。
## 常见问题
----
<AccordionGroup>
<Accordion title="重复推送会重复记录吗?">
diff --git a/zh/on-call/integration/change-integration/bitbucket.mdx b/zh/on-call/integration/change-integration/bitbucket.mdx
index 9657d3d8..76f26dbc 100644
--- a/zh/on-call/integration/change-integration/bitbucket.mdx
+++ b/zh/on-call/integration/change-integration/bitbucket.mdx
@@ -1,5 +1,6 @@
---
title: "Bitbucket 变更集成"
+sidebarTitle: "Bitbucket"
description: "通过 Bitbucket Cloud 仓库 Webhook 将提交的构建状态(Pipelines 及第三方 CI)同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Bitbucket", "Bitbucket Pipelines", "构建状态", "部署", "Webhook", "CI/CD"]
---
@@ -13,7 +14,6 @@ Bitbucket 没有独立的部署事件,构建状态是流水线结果的推送
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Bitbucket**,填写集成名称
@@ -23,7 +23,6 @@ Bitbucket 没有独立的部署事件,构建状态是流水线结果的推送
</div>
## 在 Bitbucket 中配置
----
<Steps>
<Step title="添加 Webhook">
@@ -50,7 +49,6 @@ Bitbucket 没有独立的部署事件,构建状态是流水线结果的推送
</Steps>
## 一条变更是什么
----
Bitbucket 的构建状态没有单独的 ID,它由“仓库 + 提交 + 状态 key”三个值唯一确定(对应 API 路径 `/commit/<hash>/statuses/build/<key>`)。Flashduty 的变更标识(change_key)是 `<仓库 uuid>/<提交哈希>/<状态 key>`,同一构建状态的 created 和 updated 事件更新同一条变更。
@@ -59,7 +57,6 @@ Bitbucket 的构建状态没有单独的 ID,它由“仓库 + 提交 + 状态
- 第三方 CI 若在同一提交上反复使用同一个 key(例如重新运行),Bitbucket 会覆盖原状态,Flashduty 中表现为同一条变更重新回到进行中,再次结束时更新为新的最终状态
## 状态映射
----
Flashduty 按推送内容中的 `commit_status.state` 确定状态:
@@ -75,7 +72,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
以下推送返回成功但不生成变更:`repo:push`、Pull Request、评论等非构建状态事件,以及类型不是 `build` 的状态。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -94,7 +90,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
| `state` | 最新的 Bitbucket 构建状态 |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到构建变更?">
diff --git a/zh/on-call/integration/change-integration/buildkite.mdx b/zh/on-call/integration/change-integration/buildkite.mdx
index 85abb94b..02704f6b 100644
--- a/zh/on-call/integration/change-integration/buildkite.mdx
+++ b/zh/on-call/integration/change-integration/buildkite.mdx
@@ -1,5 +1,6 @@
---
title: "Buildkite 变更集成"
+sidebarTitle: "Buildkite"
description: "通过 Buildkite Webhook 将流水线构建同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Buildkite", "构建", "部署", "Webhook", "CI/CD"]
---
@@ -13,7 +14,6 @@ keywords: ["变更集成", "Buildkite", "构建", "部署", "Webhook", "CI/CD"]
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Buildkite**,填写集成名称
@@ -23,7 +23,6 @@ keywords: ["变更集成", "Buildkite", "构建", "部署", "Webhook", "CI/CD"]
</div>
## 在 Buildkite 中配置
----
<Steps>
<Step title="添加 Webhook 通知服务">
@@ -51,12 +50,10 @@ keywords: ["变更集成", "Buildkite", "构建", "部署", "Webhook", "CI/CD"]
</Steps>
## 一条变更是什么
----
一次构建是一条变更,变更标识(change_key)是构建的 `build.id`(Buildkite 平台内唯一的 UUID)。同一次构建的所有 `build.*` 事件更新同一条变更;同一流水线、同一分支的两次构建是两条变更,重新构建(Rebuild)也会产生新的构建和新的变更。
## 状态映射
----
Flashduty 按推送内容中的 `build.state` 确定状态:
@@ -74,7 +71,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
以下推送返回成功但不生成变更:`ping`、`job.*`、`agent.*`、`cluster_token.*` 等非构建事件。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -97,7 +93,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
| `state` | 最新的 Buildkite 构建状态,等待 block step 时为 `blocked` |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到构建变更?">
diff --git a/zh/on-call/integration/change-integration/circleci.mdx b/zh/on-call/integration/change-integration/circleci.mdx
index 5995c595..c05d39d8 100644
--- a/zh/on-call/integration/change-integration/circleci.mdx
+++ b/zh/on-call/integration/change-integration/circleci.mdx
@@ -1,5 +1,6 @@
---
title: "CircleCI 变更集成"
+sidebarTitle: "CircleCI"
description: "通过 CircleCI 出站 Webhook 将 Workflow 的执行结果同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "CircleCI", "Workflow", "CI/CD", "Webhook"]
---
@@ -13,7 +14,6 @@ CircleCI 只在 Workflow 结束时推送 `workflow-completed` 事件,没有开
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **CircleCI**,填写集成名称
@@ -23,7 +23,6 @@ CircleCI 只在 Workflow 结束时推送 `workflow-completed` 事件,没有开
</div>
## 在 CircleCI 中配置
----
<Steps>
<Step title="打开项目的 Webhooks 设置">
@@ -55,14 +54,12 @@ Webhook 按项目配置,每个项目最多 5 个。需要为每个要同步的
</Steps>
## 一条变更是什么
----
| CircleCI 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
| Workflow | `workflow.id` | 每次 Pipeline 运行中的每个 Workflow 有独立的 ID,对应一条 Flashduty 变更;同一项目、同一分支上的两次运行是两条变更 |
## 状态映射
----
| CircleCI `workflow.status` | Flashduty 变更状态 |
|---|---|
@@ -79,7 +76,6 @@ Webhook 按项目配置,每个项目最多 5 个。需要为每个要同步的
- 其他事件类型
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -105,7 +101,6 @@ Webhook 按项目配置,每个项目最多 5 个。需要为每个要同步的
| `circleci_state` | CircleCI 的 Workflow 状态原值 |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么看不到 Workflow 的运行中状态?">
diff --git a/zh/on-call/integration/change-integration/coolify.mdx b/zh/on-call/integration/change-integration/coolify.mdx
index 374a7df8..4e219203 100644
--- a/zh/on-call/integration/change-integration/coolify.mdx
+++ b/zh/on-call/integration/change-integration/coolify.mdx
@@ -1,5 +1,6 @@
---
title: "Coolify 变更集成"
+sidebarTitle: "Coolify"
description: "通过 Coolify 的 Webhook 通知渠道将应用部署结果同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Coolify", "部署", "PaaS", "Webhook"]
---
@@ -13,7 +14,6 @@ Coolify 只在部署结束时发送通知,没有开始事件,因此变更没
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Coolify**,填写集成名称
@@ -23,7 +23,6 @@ Coolify 只在部署结束时发送通知,没有开始事件,因此变更没
</div>
## 在 Coolify 中配置
----
<Steps>
<Step title="打开 Webhook 通知渠道">
@@ -52,7 +51,6 @@ Coolify 的通知按团队(Team)配置,该团队下所有项目的部署
</Steps>
## 一条变更是什么
----
| Coolify 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -61,7 +59,6 @@ Coolify 的通知按团队(Team)配置,该团队下所有项目的部署
多服务器部署时,Coolify 在所有服务器部署结束后只发送一条通知:全部成功时使用主部署的 UUID,有失败时使用第一个未成功的部署的 UUID。
## 状态映射
----
| Coolify `event` | Flashduty 变更状态 |
|---|---|
@@ -75,7 +72,6 @@ Coolify 的通知按团队(Team)配置,该团队下所有项目的部署
- 备份、定时任务、Docker 清理、服务器和容器相关的事件
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -99,7 +95,6 @@ Coolify 的通知按团队(Team)配置,该团队下所有项目的部署
| `coolify_event` | Coolify 的事件名原值 |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么看不到部署的运行中状态?">
diff --git a/zh/on-call/integration/change-integration/custom-event.mdx b/zh/on-call/integration/change-integration/custom-event.mdx
index 892016f2..c042adc9 100644
--- a/zh/on-call/integration/change-integration/custom-event.mdx
+++ b/zh/on-call/integration/change-integration/custom-event.mdx
@@ -1,5 +1,6 @@
---
title: "自定义变更事件"
+sidebarTitle: "自定义"
description: "通过标准协议推送自有系统变更事件到 Flashduty On-call,大部分故障由变更导致,变更和告警事件联动有助于快速定位故障原因"
keywords: ["变更事件", "变更管理", "故障关联", "变更追踪", "事件联动"]
---
@@ -14,7 +15,7 @@ Flashduty On-call 已适配部分常用工单、部署系统的 webhook 协议
<Steps>
<Step title="进入集成中心">
-进入 Flashduty 控制台,选择 **集成中心 => 变更事件**,进入集成选择页面。
+进入 Flashduty 控制台,选择 **集成中心 → 变更事件**,进入集成选择页面。
</Step>
<Step title="创建集成">
diff --git a/zh/on-call/integration/change-integration/env0.mdx b/zh/on-call/integration/change-integration/env0.mdx
index 840a9ac1..9bced824 100644
--- a/zh/on-call/integration/change-integration/env0.mdx
+++ b/zh/on-call/integration/change-integration/env0.mdx
@@ -1,5 +1,6 @@
---
title: "env0 变更集成"
+sidebarTitle: "env0"
description: "通过 env0 Webhook 通知目标将环境的部署(Deploy)和销毁(Destroy)同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "env0", "env zero", "Deployment", "Destroy", "Terraform", "Webhook"]
---
@@ -11,7 +12,6 @@ keywords: ["变更集成", "env0", "env zero", "Deployment", "Destroy", "Terrafo
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **env0**,填写集成名称
@@ -21,7 +21,6 @@ keywords: ["变更集成", "env0", "env zero", "Deployment", "Destroy", "Terrafo
</div>
## 在 env0 中配置
----
<Steps>
<Step title="添加 Webhook 通知目标">
@@ -53,7 +52,6 @@ keywords: ["变更集成", "env0", "env zero", "Deployment", "Destroy", "Terrafo
env0 的 Webhook 发送失败时不重试,超时时间为 10 秒。
## 一条变更是什么
----
| env0 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -62,7 +60,6 @@ env0 的 Webhook 发送失败时不重试,超时时间为 10 秒。
变更标识不是环境 ID:同一个环境会有多次运行,每次运行对应各自的 deployment log。
## 状态映射
----
| env0 事件 | Flashduty 变更状态 |
|---|---|
@@ -78,7 +75,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
以下推送返回成功但不生成变更:`com.env0.webhook.test`、`com.env0.pr_plan.failed`、`com.env0.environment.*`、`com.env0.drift.*`、`com.env0.budget.exceeded` 以及其他不属于部署或销毁运行的事件类型。
## 变更内容
----
| 字段 | 说明 |
|---|---|
@@ -99,7 +95,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
| `actor` | 启动运行的用户名称;定时或自动运行时没有此标签 |
## 常见问题
----
<AccordionGroup>
<Accordion title="env0 重复推送会重复记录吗?">
diff --git a/zh/on-call/integration/change-integration/expo-eas.mdx b/zh/on-call/integration/change-integration/expo-eas.mdx
index 839a5cca..2954ddc3 100644
--- a/zh/on-call/integration/change-integration/expo-eas.mdx
+++ b/zh/on-call/integration/change-integration/expo-eas.mdx
@@ -1,5 +1,6 @@
---
title: "Expo EAS 变更集成"
+sidebarTitle: "Expo EAS"
description: "通过 EAS Webhook 将 Expo EAS Build 构建和 EAS Submit 提交的结果同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Expo", "EAS", "EAS Build", "EAS Submit", "Webhook"]
---
@@ -13,7 +14,6 @@ EAS 只在构建或提交结束时推送,没有开始事件,因此变更没
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Expo EAS**,填写集成名称
@@ -23,7 +23,6 @@ EAS 只在构建或提交结束时推送,没有开始事件,因此变更没
</div>
## 在 Expo EAS 中配置
----
<Steps>
<Step title="为构建创建 Webhook">
@@ -60,7 +59,6 @@ Webhook 按项目配置,需要在每个要同步的项目中分别创建,可
</Steps>
## 一条变更是什么
----
| EAS 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -68,7 +66,6 @@ Webhook 按项目配置,需要在每个要同步的项目中分别创建,可
| 提交(Submit) | `submission:<id>` | `id` 为提交 ID(UUID)。构建和提交的 ID 即使相同也不会合并 |
## 状态映射
----
| EAS `status` | Flashduty 变更状态 |
|---|---|
@@ -79,7 +76,6 @@ Webhook 按项目配置,需要在每个要同步的项目中分别创建,可
EAS 文档只列出这三种结束状态。出现其他状态值时推送返回 InvalidParameter,不生成变更。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -107,7 +103,6 @@ EAS 文档只列出这三种结束状态。出现其他状态值时推送返回
| `expo_state` | EAS 的 `status` 原值 |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么看不到构建的运行中状态?">
diff --git a/zh/on-call/integration/change-integration/flagsmith.mdx b/zh/on-call/integration/change-integration/flagsmith.mdx
index a6e023fc..56b66de9 100644
--- a/zh/on-call/integration/change-integration/flagsmith.mdx
+++ b/zh/on-call/integration/change-integration/flagsmith.mdx
@@ -1,5 +1,6 @@
---
title: "Flagsmith 变更集成"
+sidebarTitle: "Flagsmith"
description: "通过 Flagsmith 审计日志 Webhook 将功能开关(Flag)、Segment 等的变更同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Flagsmith", "Feature Flag", "功能开关", "审计日志", "Webhook"]
---
@@ -13,7 +14,6 @@ Flagsmith 推送的是已经生效的变更,因此每条变更都直接记录
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Flagsmith**,填写集成名称
@@ -23,7 +23,6 @@ Flagsmith 推送的是已经生效的变更,因此每条变更都直接记录
</div>
## 在 Flagsmith 中配置
----
<Steps>
<Step title="创建组织级 Webhook">
@@ -47,7 +46,6 @@ Flagsmith 推送的是已经生效的变更,因此每条变更都直接记录
Flagsmith 会把组织下所有项目的审计日志推送到该地址,之后在任一开关上做一次变更,即可在 Flashduty 变更列表中看到记录。Webhook 对话框中的 **Test your webhook** 按钮可发送测试推送,Flashduty 收到后返回成功,不生成变更。
## 一条变更是什么
----
| Flagsmith 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -56,7 +54,6 @@ Flagsmith 会把组织下所有项目的审计日志推送到该地址,之后
审计日志记录的 `data.id` 在一个 Flagsmith 实例内递增。请为每个 Flagsmith 实例单独创建一个集成;多个实例共用一个集成时,不同实例的相同 `id` 会被当作同一条变更。
## 状态映射
----
| Flagsmith 审计日志记录(`related_object_type`) | Flashduty 变更状态 |
|---|---|
@@ -71,7 +68,6 @@ Flagsmith 会把组织下所有项目的审计日志推送到该地址,之后
- Flagsmith 的测试推送
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -90,7 +86,6 @@ Flagsmith 会把组织下所有项目的审计日志推送到该地址,之后
| `audit_log_id` | 审计日志记录 ID |
## 常见问题
----
<AccordionGroup>
<Accordion title="Flagsmith 重试推送会重复记录吗?">
diff --git a/zh/on-call/integration/change-integration/fluxcd.mdx b/zh/on-call/integration/change-integration/fluxcd.mdx
index 7d5a9099..90b94ebb 100644
--- a/zh/on-call/integration/change-integration/fluxcd.mdx
+++ b/zh/on-call/integration/change-integration/fluxcd.mdx
@@ -1,5 +1,6 @@
---
title: "Flux CD 变更集成"
+sidebarTitle: "Flux CD"
description: "通过 Flux notification-controller 的 generic Provider,将 Kustomization 和 HelmRelease 应用的每个版本同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Flux CD", "Flux", "GitOps", "Kustomization", "HelmRelease", "notification-controller", "Provider", "Alert", "部署事件"]
---
@@ -16,7 +17,6 @@ GitRepository、HelmChart、ImageUpdateAutomation 等其他类型的事件,以
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Flux CD**,填写集成名称
@@ -26,9 +26,8 @@ GitRepository、HelmChart、ImageUpdateAutomation 等其他类型的事件,以
</div>
## 在 Flux 中配置
----
-以下操作需要能在 Flux 的 `flux-system` 命名空间(或你放置通知配置的命名空间)创建 Provider、Alert 和 Secret 的 Kubernetes 权限。notification-controller 需要能访问推送地址所在的域名。
+以下操作需要能在 Flux 的 `flux-system` 命名空间(或您放置通知配置的命名空间)创建 Provider、Alert 和 Secret 的 Kubernetes 权限。notification-controller 需要能访问推送地址所在的域名。
<Steps>
<Step title="创建保存推送地址的 Secret">
@@ -97,7 +96,6 @@ kubectl -n flux-system describe alert flashduty-change
</Steps>
## 一条变更是什么
----
一条变更对应一个 Flux 对象应用的一个版本,变更标识(change_key)为 `<对象 UID>/<版本>`:
@@ -114,7 +112,6 @@ Flux 的事件没有操作编号,所以有两种情况会更新已有的变更
事件缺少 `involvedObject.uid` 时,Flashduty 会拒绝该请求。
## 状态映射
----
**Kustomization**
@@ -134,7 +131,6 @@ Flux 的事件没有操作编号,所以有两种情况会更新已有的变更
Done 和 Failed 是结束状态,Flashduty 会记录变更结束时间。以下事件返回成功但不记录:`severity` 为 `trace`;Kustomization 的 `DependencyNotReady`、`HealthCheckCanceled`;HelmRelease 的 `PendingRelease`(解锁卡住的发布)、`DriftCorrected`、`DriftCorrectionFailed`(修复漂移)、`HealthCheckCanceled`;以及所有没有版本号的事件。其他未列出的 `reason` 或 `severity` 会被拒绝。
## 变更内容
----
- **标题**:`<命名空间>/<对象名称>: apply <版本> (<类型>)`,例如 `apps/webapp: apply main@sha1:731f7ea (Kustomization)`;HelmRelease 卸载为 `uninstall`。Git 提交 ID 在标题中缩短为 7 位
- **链接**:Flux 事件不带网页地址,变更没有链接
@@ -158,7 +154,6 @@ Done 和 Failed 是结束状态,Flashduty 会记录变更结束时间。以下
同一个版本的所有事件都应带有相同的路由标签:所有 Alert 请使用相同的 `eventMetadata`,否则后续事件可能进入另一个协作空间,形成另一条变更。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到变更?">
diff --git a/zh/on-call/integration/change-integration/gitea.mdx b/zh/on-call/integration/change-integration/gitea.mdx
index 7409ea8a..fcfc1e16 100644
--- a/zh/on-call/integration/change-integration/gitea.mdx
+++ b/zh/on-call/integration/change-integration/gitea.mdx
@@ -1,5 +1,6 @@
---
title: "Gitea 变更集成"
+sidebarTitle: "Gitea"
description: "通过 Gitea Webhook 将 Gitea Actions 工作流运行和 Release 发布同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Gitea", "Gitea Actions", "工作流", "Release", "Webhook", "部署事件"]
---
@@ -15,7 +16,6 @@ Gitea 的 Webhook 不能按工作流或分支过滤工作流运行(**分支过
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Gitea**,填写集成名称
@@ -25,7 +25,6 @@ Gitea 的 Webhook 不能按工作流或分支过滤工作流运行(**分支过
</div>
## 在 Gitea 中配置
----
<Steps>
<Step title="打开 Webhook 设置">
@@ -59,7 +58,6 @@ Gitea 的 Webhook 不能按工作流或分支过滤工作流运行(**分支过
Gitea 的 **测试推送事件(Test Push Event)** 发送的是模拟的 `push` 事件,Flashduty 返回成功但不会生成变更。
## 一条变更是什么
----
| Gitea 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -67,7 +65,6 @@ Gitea 的 **测试推送事件(Test Push Event)** 发送的是模拟的 `pus
| Release | `release:<release.id>` | 发布、删除同一个 Release 更新同一条变更 |
## 状态映射
----
| Gitea 事件 | Gitea 状态 | Flashduty 变更状态 |
|---|---|---|
@@ -85,7 +82,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
以下推送返回成功但不生成变更:Gitea 的其他事件类型(包括 `workflow_job` 和测试推送事件产生的 `push`)、Release 的 `updated` 动作、草稿状态的 Release,以及排队中的运行(状态为 `queued`、`pending` 或 `requested` 的 `requested` 事件;变更从运行开始时才产生)。
## 变更内容
----
| 字段 | 工作流运行 | Release |
|---|---|---|
@@ -110,7 +106,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
| `prerelease` | — | 预发布时为 `true` |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到工作流变更?">
diff --git a/zh/on-call/integration/change-integration/gitee.mdx b/zh/on-call/integration/change-integration/gitee.mdx
index f5c6df3f..2c1ddc21 100644
--- a/zh/on-call/integration/change-integration/gitee.mdx
+++ b/zh/on-call/integration/change-integration/gitee.mdx
@@ -1,5 +1,6 @@
---
title: "Gitee 变更集成"
+sidebarTitle: "Gitee"
description: "通过 Gitee WebHook 将分支推送、Tag 推送和 Pull Request 合并同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Gitee", "码云", "WebHook", "Push", "Tag", "Pull Request", "合并"]
---
@@ -13,7 +14,6 @@ Gitee 的 WebHook 不能按分支过滤推送:勾选 **Push** 后,仓库中
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Gitee**,填写集成名称
@@ -23,7 +23,6 @@ Gitee 的 WebHook 不能按分支过滤推送:勾选 **Push** 后,仓库中
</div>
## 在 Gitee 中配置
----
<Steps>
<Step title="添加 WebHook">
@@ -55,7 +54,6 @@ Gitee 的 WebHook 不能按分支过滤推送:勾选 **Push** 后,仓库中
合并 Pull Request 会向目标分支产生一次提交。同时勾选 **Push** 和 **Pull Request** 时,同一次合并可能生成两条变更:一条是目标分支的推送,一条是 Pull Request 合并。只关心其中一类时,只勾选对应的钩子。
## 一条变更是什么
----
| Gitee 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -66,7 +64,6 @@ Gitee 的 WebHook 不能按分支过滤推送:勾选 **Push** 后,仓库中
同一个提交被推送到两个分支,是两条变更。
## 状态映射
----
| Gitee 钩子 | 条件 | Flashduty 变更状态 |
|---|---|---|
@@ -79,7 +76,6 @@ Done 是结束状态,Flashduty 会记录变更结束时间。
以下推送返回成功但不生成变更:Issue 和评论钩子、删除分支或 Tag 的推送、`action` 不是 `merge` 的 Pull Request 钩子(`open`、`update`、`approved`、`close`、`tested` 等),以及无法识别的钩子类型。
## 变更内容
----
| 字段 | 分支推送 | Tag 推送 | Pull Request 合并 |
|---|---|---|---|
@@ -102,7 +98,6 @@ Done 是结束状态,Flashduty 会记录变更结束时间。
| `pull_request_id` / `pull_request_number` | Pull Request 的 `id` / `number`(仅 Pull Request 合并) |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么所有分支的推送都变成了变更?">
diff --git a/zh/on-call/integration/change-integration/github.mdx b/zh/on-call/integration/change-integration/github.mdx
index 080a48ed..b9a9bbf8 100644
--- a/zh/on-call/integration/change-integration/github.mdx
+++ b/zh/on-call/integration/change-integration/github.mdx
@@ -1,5 +1,6 @@
---
title: "GitHub 变更集成"
+sidebarTitle: "GitHub"
description: "通过 GitHub Webhook 将 Deployment 部署和 Release 发布同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "GitHub", "Deployment", "Release", "Webhook", "部署事件"]
---
@@ -13,7 +14,6 @@ GitHub Actions 中声明了 `environment` 的任务会自动创建 Deployment,
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **GitHub**,填写集成名称
@@ -23,7 +23,6 @@ GitHub Actions 中声明了 `environment` 的任务会自动创建 Deployment,
</div>
## 在 GitHub 中配置
----
<Steps>
<Step title="打开 Webhook 设置">
@@ -55,7 +54,6 @@ GitHub Actions 中声明了 `environment` 的任务会自动创建 Deployment,
</Steps>
## 一条变更是什么
----
| GitHub 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -63,7 +61,6 @@ GitHub Actions 中声明了 `environment` 的任务会自动创建 Deployment,
| Release | `release:<release.id>` | 发布、取消发布、删除同一个 Release 更新同一条变更 |
## 状态映射
----
| GitHub 事件 | GitHub 状态 | Flashduty 变更状态 |
|---|---|---|
@@ -82,7 +79,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
以下推送返回成功但不生成变更:`ping`、未列出的其他事件类型、Release 的 `created`、`edited`、`released`、`prereleased` 动作(发布时 GitHub 会同时发送 `published`,以 `published` 为准)、部署状态 `inactive`(旧部署被新部署取代,不改变旧部署已有的结果)。
## 变更内容
----
| 字段 | Deployment | Release |
|---|---|---|
@@ -106,7 +102,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
| `prerelease` | — | 预发布时为 `true` |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到部署变更?">
diff --git a/zh/on-call/integration/change-integration/gitlab.mdx b/zh/on-call/integration/change-integration/gitlab.mdx
index 35041c70..3fb337fe 100644
--- a/zh/on-call/integration/change-integration/gitlab.mdx
+++ b/zh/on-call/integration/change-integration/gitlab.mdx
@@ -1,5 +1,6 @@
---
title: "GitLab 变更集成"
+sidebarTitle: "GitLab"
description: "通过 GitLab Webhook 将部署(Deployment)同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "GitLab", "Deployment", "Webhook", "部署事件"]
---
@@ -13,7 +14,6 @@ GitLab CI/CD 中声明了 `environment` 的任务会自动创建部署,因此
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **GitLab**,填写集成名称
@@ -23,7 +23,6 @@ GitLab CI/CD 中声明了 `environment` 的任务会自动创建部署,因此
</div>
## 在 GitLab 中配置
----
<Steps>
<Step title="打开 Webhook 设置">
@@ -53,7 +52,6 @@ GitLab 的 **Test** 功能不能发送部署事件;用 Test 发送的其他事
</Steps>
## 一条变更是什么
----
| GitLab 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -62,7 +60,6 @@ GitLab 的 **Test** 功能不能发送部署事件;用 Test 发送的其他事
`deployment_id` 在同一个 GitLab 实例内唯一。如果要接入多个 GitLab 实例(例如 GitLab.com 和自托管实例),请为每个实例创建一个集成。
## 状态映射
----
| GitLab 部署状态 | Flashduty 变更状态 |
|---|---|
@@ -78,7 +75,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
以下推送返回成功但不生成变更:Deployment 以外的事件类型(Push、Pipeline 等)、受保护环境的审批事件 `approved` 和 `rejected`。审批事件描述的是审批记录而不是部署本身:批准后 GitLab 会在部署开始时推送 `running`,拒绝后会推送 `failed`,变更状态以这些部署事件为准。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -101,7 +97,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
| `state` | 最新的 GitLab 部署状态 |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到部署变更?">
diff --git a/zh/on-call/integration/change-integration/growthbook.mdx b/zh/on-call/integration/change-integration/growthbook.mdx
index 25e474fb..65291d30 100644
--- a/zh/on-call/integration/change-integration/growthbook.mdx
+++ b/zh/on-call/integration/change-integration/growthbook.mdx
@@ -1,5 +1,6 @@
---
title: "GrowthBook 变更集成"
+sidebarTitle: "GrowthBook"
description: "通过 GrowthBook Event Webhook 将功能开关(Feature)修订(Revision)的审核、发布、回滚同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "GrowthBook", "Feature Flag", "功能开关", "Webhook", "Event Webhook"]
---
@@ -11,7 +12,6 @@ keywords: ["变更集成", "GrowthBook", "Feature Flag", "功能开关", "Webhoo
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **GrowthBook**,填写集成名称
@@ -21,7 +21,6 @@ keywords: ["变更集成", "GrowthBook", "Feature Flag", "功能开关", "Webhoo
</div>
## 在 GrowthBook 中配置
----
<Steps>
<Step title="新建 Event Webhook">
@@ -57,7 +56,6 @@ keywords: ["变更集成", "GrowthBook", "Feature Flag", "功能开关", "Webhoo
需要所用的 GrowthBook 版本支持 `feature.revision.*` 事件。保存前可在创建窗口中点击 **Test Connection**:它发送不含 `event` 字段的请求体,Flashduty 返回 200 且不生成变更。当前版本中,已保存的 Webhook 没有 Test 按钮。之后在任一 Feature 上发布一次修订,即可在 Flashduty 变更列表中看到记录。
## 一条变更是什么
----
| GrowthBook 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -66,7 +64,6 @@ keywords: ["变更集成", "GrowthBook", "Feature Flag", "功能开关", "Webhoo
Feature ID 创建后不可修改,修订版本号在同一个 Feature 内递增。如果删除某个 Feature 后又用相同的 ID 重新创建,版本号会从头开始,新的修订会与旧 Feature 中版本号相同的变更合并。
## 状态映射
----
| GrowthBook 事件 | 含义 | Flashduty 变更状态 |
|---|---|---|
@@ -89,7 +86,6 @@ Feature ID 创建后不可修改,修订版本号在同一个 Feature 内递增
GrowthBook 后续新增的 `feature.revision.*` 事件,在加入上表之前会返回 `InvalidParameter`,不会生成变更。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -110,7 +106,6 @@ GrowthBook 后续新增的 `feature.revision.*` 事件,在加入上表之前
`state`、`actor`、`event_type` 会随每个事件更新,不要用它们做路由;请使用每个事件都有的 `feature_id`。项目、环境等范围因事件而异,Flashduty 不记录。
## 常见问题
----
<AccordionGroup>
<Accordion title="GrowthBook 重试推送会重复记录吗?">
diff --git a/zh/on-call/integration/change-integration/harness-fme.mdx b/zh/on-call/integration/change-integration/harness-fme.mdx
index 647323ed..33d2366d 100644
--- a/zh/on-call/integration/change-integration/harness-fme.mdx
+++ b/zh/on-call/integration/change-integration/harness-fme.mdx
@@ -1,5 +1,6 @@
---
title: "Harness FME 变更集成"
+sidebarTitle: "Harness FME"
description: "通过 Harness FME(原 Split)的 Audit log Outgoing Webhook,将功能开关(Feature Flag)的变更同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Harness FME", "Split", "Feature Flag", "功能开关", "Webhook"]
---
@@ -15,7 +16,6 @@ FME 推送的是已经生效的变更,因此每条变更都直接记录为 **D
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Harness FME**,填写集成名称
@@ -25,7 +25,6 @@ FME 推送的是已经生效的变更,因此每条变更都直接记录为 **D
</div>
## 在 Harness FME 中配置
----
<Steps>
<Step title="添加 Outgoing webhook (Audit log)">
@@ -52,7 +51,6 @@ FME 推送的是已经生效的变更,因此每条变更都直接记录为 **D
FME 没有测试推送按钮。保存后在任一已勾选环境中修改一个 Flag 并保存,即可在 Flashduty 变更列表中看到记录。
## 一条变更是什么
----
| FME 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -61,7 +59,6 @@ FME 没有测试推送按钮。保存后在任一已勾选环境中修改一个
推送内容里没有单独的变更 ID,因此用环境名、Flag 名和版本号组合。如果在 FME 中重命名环境,之后的修改会以新环境名记录。推送内容不含项目名:只有不同项目中的同名 Flag、环境名相同且版本号也相同时,才会被当作同一条变更。
## 状态映射
----
| FME 推送 | Flashduty 变更状态 |
|---|---|
@@ -70,7 +67,6 @@ FME 没有测试推送按钮。保存后在任一已勾选环境中修改一个
以下推送返回成功但不生成变更:`type` 不是 `split` 的推送。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -89,7 +85,6 @@ FME 没有测试推送按钮。保存后在任一已勾选环境中修改一个
| `actor` | 修改人(`editor`);如果 `editor` 是邮箱地址则不写入 |
## 常见问题
----
<AccordionGroup>
<Accordion title="FME 重试推送会重复记录吗?">
diff --git a/zh/on-call/integration/change-integration/hcp-terraform.mdx b/zh/on-call/integration/change-integration/hcp-terraform.mdx
index 988c3c4b..47938061 100644
--- a/zh/on-call/integration/change-integration/hcp-terraform.mdx
+++ b/zh/on-call/integration/change-integration/hcp-terraform.mdx
@@ -1,5 +1,6 @@
---
title: "HCP Terraform 变更集成"
+sidebarTitle: "HCP Terraform"
description: "通过 HCP Terraform 工作区通知将 Terraform Run 同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "HCP Terraform", "Terraform Cloud", "Run", "Webhook", "基础设施变更"]
---
@@ -11,7 +12,6 @@ keywords: ["变更集成", "HCP Terraform", "Terraform Cloud", "Run", "Webhook",
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **HCP Terraform**,填写集成名称
@@ -21,7 +21,6 @@ keywords: ["变更集成", "HCP Terraform", "Terraform Cloud", "Run", "Webhook",
</div>
## 在 HCP Terraform 中配置
----
通知按工作区配置,每个需要接入的工作区配置一次。需要该工作区的管理员权限。
@@ -55,14 +54,12 @@ keywords: ["变更集成", "HCP Terraform", "Terraform Cloud", "Run", "Webhook",
也可以使用 Terraform 的 `tfe` Provider 管理这项配置:`tfe_notification_configuration` 资源设置 `destination_type = "generic"`、`url` 为推送地址、`triggers` 为 `["run:created", "run:planning", "run:needs_attention", "run:applying", "run:completed", "run:errored"]`。
## 一条变更是什么
----
| HCP Terraform 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
| Run | `run_id`,例如 `run-FwnENkvDnrpyFC7M` | 同一个 Run 的所有通知更新同一条变更;同一工作区的两次 Run 是两条变更 |
## 状态映射
----
| 通知触发事件(trigger) | Run 状态(run_status) | Flashduty 变更状态 |
|---|---|---|
@@ -82,7 +79,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
以下推送返回成功但不生成变更:保存配置或 **Send a test** 时的验证请求(trigger 为 `verification`)、健康评估通知(`assessment:drifted`、`assessment:check_failure`、`assessment:failed`)和工作区通知(`workspace:auto_destroy_reminder`、`workspace:auto_destroy_run_results`、`workspace:deleted`)。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -102,7 +98,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
| `actor` | 创建 Run 的用户 |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到变更?">
diff --git a/zh/on-call/integration/change-integration/heroku.mdx b/zh/on-call/integration/change-integration/heroku.mdx
index f5e3b47e..ef3e63ce 100644
--- a/zh/on-call/integration/change-integration/heroku.mdx
+++ b/zh/on-call/integration/change-integration/heroku.mdx
@@ -1,5 +1,6 @@
---
title: "Heroku 变更集成"
+sidebarTitle: "Heroku"
description: "通过 Heroku 应用 Webhook 将应用的发布(Release)同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Heroku", "发布", "Release", "Webhook"]
---
@@ -11,7 +12,6 @@ keywords: ["变更集成", "Heroku", "发布", "Release", "Webhook"]
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Heroku**,填写集成名称
@@ -21,7 +21,6 @@ keywords: ["变更集成", "Heroku", "发布", "Release", "Webhook"]
</div>
## 在 Heroku 中配置
----
<Steps>
<Step title="创建应用 Webhook">
@@ -50,7 +49,6 @@ Heroku 没有测试推送。执行一次 `git push heroku main`,或修改一
</Steps>
## 一条变更是什么
----
| Heroku 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -59,7 +57,6 @@ Heroku 没有测试推送。执行一次 `git push heroku main`,或修改一
Release 的版本号(`v12`)只在应用内唯一,不作为标识,仅出现在标题和 `version` 标签中。
## 状态映射
----
| Heroku `data.status` | Flashduty 变更状态 |
|---|---|
@@ -77,7 +74,6 @@ Release 的版本号(`v12`)只在应用内唯一,不作为标识,仅出
`data.status` 为上表之外的值时,推送返回 `InvalidParameter`(见常见问题)。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -101,7 +97,6 @@ Release 的版本号(`v12`)只在应用内唯一,不作为标识,仅出
Heroku 推送只用邮箱标识触发 Release 的用户,邮箱不会写入标签,因此没有 `actor` 标签。
## 常见问题
----
<AccordionGroup>
<Accordion title="Heroku 重试推送会重复记录吗?">
diff --git a/zh/on-call/integration/change-integration/jenkins.mdx b/zh/on-call/integration/change-integration/jenkins.mdx
index 742ed7ed..be17f9bb 100644
--- a/zh/on-call/integration/change-integration/jenkins.mdx
+++ b/zh/on-call/integration/change-integration/jenkins.mdx
@@ -1,5 +1,6 @@
---
title: "Jenkins 变更集成"
+sidebarTitle: "Jenkins"
description: "通过 Jenkins Notification 插件将部署任务的每次构建同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Jenkins", "Notification 插件", "构建", "部署事件"]
---
@@ -13,7 +14,6 @@ Jenkins 无法区分一次构建是否发布了变更,因此只需在**执行
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Jenkins**,填写集成名称
@@ -23,7 +23,6 @@ Jenkins 无法区分一次构建是否发布了变更,因此只需在**执行
</div>
## 在 Jenkins 中配置
----
<Steps>
<Step title="确认 Jenkins URL">
@@ -61,7 +60,6 @@ Jenkins 无法区分一次构建是否发布了变更,因此只需在**执行
</Steps>
## 一条变更是什么
----
每一次构建是一条变更,变更标识(change_key)为 `<构建完整地址>#<队列 ID>`,例如 `https://jenkins.example.com/job/deploy/18/#4711`。
@@ -71,7 +69,6 @@ Jenkins 无法区分一次构建是否发布了变更,因此只需在**执行
- 多个 Jenkins 实例推送到同一个集成时,构建地址不同,不会混淆
## 状态映射
----
| 构建阶段(phase) | 构建结果(status) | Flashduty 变更状态 |
|---|---|---|
@@ -90,7 +87,6 @@ UNSTABLE 表示构建步骤全部执行完成,但测试或质量检查报告
在流水线中调用 `notifyEndpoints` 步骤且 `phase` 为 `NONE` 时,推送返回成功但不生成变更。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -112,7 +108,6 @@ UNSTABLE 表示构建步骤全部执行完成,但测试或质量检查报告
只有在 **Source Code Management** 中配置了 Git 的自由风格任务才会推送 `branch` 和 `commit`;流水线(Pipeline)任务用 `git` 步骤检出时,推送中不含这两个字段。构建开始时的推送可能带着本次检出之前的值,请以构建结束时的值为准。请按 `job` 配置路由规则,否则同一次构建的前后事件可能进入不同的协作空间。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到变更?">
diff --git a/zh/on-call/integration/change-integration/jfrog-artifactory.mdx b/zh/on-call/integration/change-integration/jfrog-artifactory.mdx
index 1f53828d..d32709b3 100644
--- a/zh/on-call/integration/change-integration/jfrog-artifactory.mdx
+++ b/zh/on-call/integration/change-integration/jfrog-artifactory.mdx
@@ -1,5 +1,6 @@
---
title: "JFrog Artifactory 变更集成"
+sidebarTitle: "JFrog Artifactory"
description: "通过 JFrog Artifactory Webhook 将制品的上传、删除、移动和复制同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "JFrog", "Artifactory", "制品", "Webhook", "变更事件"]
---
@@ -11,7 +12,6 @@ keywords: ["变更集成", "JFrog", "Artifactory", "制品", "Webhook", "变更
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **JFrog Artifactory**,填写集成名称
@@ -21,7 +21,6 @@ keywords: ["变更集成", "JFrog", "Artifactory", "制品", "Webhook", "变更
</div>
## 在 JFrog Artifactory 中配置
----
<Steps>
<Step title="新建 Webhook">
@@ -54,7 +53,6 @@ keywords: ["变更集成", "JFrog", "Artifactory", "制品", "Webhook", "变更
</Steps>
## 一条变更是什么
----
JFrog 的推送内容里没有变更 ID,Flashduty 用制品所在位置加内容校验和标识一个制品:
@@ -67,7 +65,6 @@ JFrog 的推送内容里没有变更 ID,Flashduty 用制品所在位置加内
对 moved 和 copied,`<仓库>/<路径>` 是制品原来的位置,`<目标>` 是推送中的 `target_repo_path`。
## 状态映射
----
| Artifactory 事件(event_type) | Flashduty 变更状态 |
|---|---|
@@ -81,7 +78,6 @@ Artifactory 的制品事件都在操作完成后推送,因此每条变更收
以下推送返回成功但不生成变更:制品以外的事件域(Artifact Properties、Docker、Builds、Release Bundles 等)、`cached`(远程仓库缓存了一个下载的制品,不是变更)、**Test** 按钮发送的示例数据。
## 变更内容
----
| 字段 | deployed、deleted | moved、copied |
|---|---|---|
@@ -105,7 +101,6 @@ Artifactory 的制品事件都在操作完成后推送,因此每条变更收
| `event_type` | Artifactory 事件:`deployed`、`deleted`、`moved` 或 `copied` |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到变更?">
diff --git a/zh/on-call/integration/change-integration/jira.mdx b/zh/on-call/integration/change-integration/jira.mdx
index 071c02fb..1920d706 100644
--- a/zh/on-call/integration/change-integration/jira.mdx
+++ b/zh/on-call/integration/change-integration/jira.mdx
@@ -1,5 +1,6 @@
---
title: "Jira 变更集成"
+sidebarTitle: "Jira"
description: "通过 Jira Webhook 将 Issue 的创建、更新和删除同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Jira", "Issue", "Webhook", "变更单"]
---
@@ -17,7 +18,6 @@ keywords: ["变更集成", "Jira", "Issue", "Webhook", "变更单"]
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Jira**,填写集成名称
@@ -27,7 +27,6 @@ keywords: ["变更集成", "Jira", "Issue", "Webhook", "变更单"]
</div>
## 在 Jira 中配置
----
<Steps>
<Step title="确认权限与网络">
@@ -58,7 +57,6 @@ Flashduty 通过推送地址中的 `integration_key` 鉴权,Webhook 的密钥
</Steps>
## 一条变更是什么
----
| Jira 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -69,7 +67,6 @@ Issue 已更新推送不区分更新类型(`issue_event_type_name`):状态
以下推送返回成功但不生成变更:Issue 的创建、更新、删除之外的事件,例如评论、工作日志、Sprint、版本、项目事件。
## 状态映射
----
Flashduty 读取推送中 Issue 的 `status.name`,不区分大小写,按下表转换:
@@ -86,7 +83,6 @@ Flashduty 读取推送中 Issue 的 `status.name`,不区分大小写,按下
Issue 被删除时,Flashduty 按推送中 Issue 删除前的状态更新变更,不会自动将变更置为已取消。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -110,7 +106,6 @@ Issue 被删除时,Flashduty 按推送中 Issue 删除前的状态更新变更
| `<Jira 标签>` | Issue 的每个标签(labels)各生成一个标签,值为 `true` |
## 常见问题
----
<AccordionGroup>
<Accordion title="修改 Issue 状态后没有看到变更更新?">
diff --git a/zh/on-call/integration/change-integration/launchdarkly.mdx b/zh/on-call/integration/change-integration/launchdarkly.mdx
index 20cd7b9d..a99b880d 100644
--- a/zh/on-call/integration/change-integration/launchdarkly.mdx
+++ b/zh/on-call/integration/change-integration/launchdarkly.mdx
@@ -1,5 +1,6 @@
---
title: "LaunchDarkly 变更集成"
+sidebarTitle: "LaunchDarkly"
description: "通过 LaunchDarkly Webhook 将功能开关(Feature Flag)和用户分群(Segment)的变更同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "LaunchDarkly", "Feature Flag", "功能开关", "Webhook"]
---
@@ -13,7 +14,6 @@ LaunchDarkly 推送的是已经生效的变更,因此每条变更都直接记
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **LaunchDarkly**,填写集成名称
@@ -23,7 +23,6 @@ LaunchDarkly 推送的是已经生效的变更,因此每条变更都直接记
</div>
## 在 LaunchDarkly 中配置
----
<Steps>
<Step title="打开 Webhooks 集成">
@@ -70,14 +69,12 @@ LaunchDarkly 推送的是已经生效的变更,因此每条变更都直接记
LaunchDarkly 没有测试推送按钮。保存后在任一 Flag 上做一次变更,即可在 Flashduty 变更列表中看到记录。
## 一条变更是什么
----
| LaunchDarkly 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
| 变更历史记录(Change history entry) | 记录的 `_id` | 每次保存 Flag 或 Segment 产生一条记录,对应一条 Flashduty 变更;同一个开关先打开再关闭是两条变更 |
## 状态映射
----
| LaunchDarkly 记录 | Flashduty 变更状态 |
|---|---|
@@ -92,7 +89,6 @@ LaunchDarkly 没有测试推送按钮。保存后在任一 Flag 上做一次变
- 名称、描述、标签、维护者、临时标记、弃用标记、自定义属性、规则描述、代码引用、Flag 链接、关注者、Segment 导出
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -114,7 +110,6 @@ LaunchDarkly 没有测试推送按钮。保存后在任一 Flag 上做一次变
| `audit_log_id` | 变更历史记录 ID |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到 staging 等环境或 Segment 的变更?">
diff --git a/zh/on-call/integration/change-integration/nautobot.mdx b/zh/on-call/integration/change-integration/nautobot.mdx
index ac985e5d..9156fbc3 100644
--- a/zh/on-call/integration/change-integration/nautobot.mdx
+++ b/zh/on-call/integration/change-integration/nautobot.mdx
@@ -1,5 +1,6 @@
---
title: "Nautobot 变更集成"
+sidebarTitle: "Nautobot"
description: "通过 Nautobot 的 Webhook,将网络与基础设施数据(设备、IP 地址、站点等)的新增、修改、删除同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Nautobot", "Webhook", "网络自动化", "配置变更", "源数据管理"]
---
@@ -13,7 +14,6 @@ Nautobot 的 Webhook 只在对象保存后发送一次,没有"开始、结束"
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Nautobot**,填写集成名称
@@ -23,7 +23,6 @@ Nautobot 的 Webhook 只在对象保存后发送一次,没有"开始、结束"
</div>
## 在 Nautobot 中配置
----
<Steps>
<Step title="创建 Webhook">
@@ -53,7 +52,6 @@ Nautobot 的 Webhook 只在对象保存后发送一次,没有"开始、结束"
<Warning>Nautobot 默认拒绝回环地址和链路本地地址的推送地址;Flashduty 的推送地址是公网地址,不受影响。Nautobot 的 Webhook 由 Celery worker 发送,请确认 worker 已运行且能访问外网。</Warning>
## 一条变更是什么
----
变更标识(change_key)由三部分组成:`<model>:<对象 id>:<请求 id>`,例如 `location:a16ea2bb-…:db6c8eb8-…`。
@@ -62,7 +60,6 @@ Nautobot 的 Webhook 只在对象保存后发送一次,没有"开始、结束"
- 批量修改(一个请求改多个对象)中,每个对象各是一条变更,它们的 `request_id` 标签相同,可以据此把同一批修改关联在一起
## 状态映射
----
| Webhook 事件(`event`) | Flashduty 变更状态 |
|---|---|
@@ -73,7 +70,6 @@ Nautobot 的 Webhook 只在对象保存后发送一次,没有"开始、结束"
事件不是以上三个值时(例如在 Body template 中自定义了内容),Flashduty 拒绝推送,见下方常见问题。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -97,7 +93,6 @@ Nautobot 的 Webhook 只在对象保存后发送一次,没有"开始、结束"
对象的字段内容和修改前后的快照(`snapshots`)可能包含敏感信息,不会被记录。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到变更?">
diff --git a/zh/on-call/integration/change-integration/netbox.mdx b/zh/on-call/integration/change-integration/netbox.mdx
index 307e3519..25ed98e8 100644
--- a/zh/on-call/integration/change-integration/netbox.mdx
+++ b/zh/on-call/integration/change-integration/netbox.mdx
@@ -1,5 +1,6 @@
---
title: "NetBox 变更集成"
+sidebarTitle: "NetBox"
description: "通过 NetBox 事件规则(Event Rule)的 Webhook 动作,将站点、设备、IP 前缀等基础设施配置的新增、修改、删除同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "NetBox", "DCIM", "IPAM", "事件规则", "Webhook"]
---
@@ -13,7 +14,6 @@ NetBox 推送的是已经保存的变更,因此每条变更都直接记录为
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **NetBox**,填写集成名称
@@ -23,7 +23,6 @@ NetBox 推送的是已经保存的变更,因此每条变更都直接记录为
</div>
## 在 NetBox 中配置
----
本文基于 NetBox 4.7 的默认 Webhook 请求体。
@@ -54,7 +53,6 @@ NetBox 推送的是已经保存的变更,因此每条变更都直接记录为
NetBox 没有测试推送按钮。保存后在已选对象类型下新增或修改一个对象,即可在 Flashduty 变更列表中看到记录。NetBox 通过后台任务(RQ worker)发送 Webhook,需要 `rqworker` 进程在运行。
## 一条变更是什么
----
| NetBox 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -63,7 +61,6 @@ NetBox 没有测试推送按钮。保存后在已选对象类型下新增或修
批量操作(批量导入、批量编辑、批量删除)在一个请求里改动多个对象,每个对象各生成一条变更,它们的 `request_id` 标签相同,可据此在变更列表中找到同一次操作改动的全部对象。
## 状态映射
----
| NetBox 事件(`event`) | Flashduty 变更状态 |
|---|---|
@@ -78,7 +75,6 @@ NetBox 没有测试推送按钮。保存后在已选对象类型下新增或修
NetBox 的 Webhook 只在变更保存后推送,没有"失败"或"取消"状态。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -97,7 +93,6 @@ NetBox 的 Webhook 只在变更保存后推送,没有"失败"或"取消"状态
| `request_id` | NetBox 请求 ID;同一次批量操作的变更相同 |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到变更?">
diff --git a/zh/on-call/integration/change-integration/netlify.mdx b/zh/on-call/integration/change-integration/netlify.mdx
index 5730e9ad..cbafa3b6 100644
--- a/zh/on-call/integration/change-integration/netlify.mdx
+++ b/zh/on-call/integration/change-integration/netlify.mdx
@@ -1,5 +1,6 @@
---
title: "Netlify 变更集成"
+sidebarTitle: "Netlify"
description: "通过 Netlify 部署通知(HTTP POST request)将部署同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Netlify", "部署通知", "Deploy notifications", "Webhook", "部署事件"]
---
@@ -13,7 +14,6 @@ keywords: ["变更集成", "Netlify", "部署通知", "Deploy notifications", "W
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Netlify**,填写集成名称
@@ -23,7 +23,6 @@ keywords: ["变更集成", "Netlify", "部署通知", "Deploy notifications", "W
</div>
## 在 Netlify 中配置
----
Netlify 的每条通知只监听一个事件,需要为下表中的每个事件各添加一条通知,推送地址相同。
@@ -59,7 +58,6 @@ Netlify 的每条通知只监听一个事件,需要为下表中的每个事件
</Steps>
## 一条变更是什么
----
| Netlify 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -68,7 +66,6 @@ Netlify 的每条通知只监听一个事件,需要为下表中的每个事件
回滚(Deploy restored)重新发布的是一次已有的部署,因此会更新那次部署对应的变更,状态为 Done。回滚通知不带回滚时间,事件时间为 Flashduty 收到通知的时间。
## 状态映射
----
| Netlify 事件 | Flashduty 变更状态 |
|---|---|
@@ -83,7 +80,6 @@ Netlify 的每条通知只监听一个事件,需要为下表中的每个事件
Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时间。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -106,7 +102,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
| `error_message` | 部署失败时 Netlify 给出的错误信息 |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么只看到开始或只看到结束?">
diff --git a/zh/on-call/integration/change-integration/octopus-deploy.mdx b/zh/on-call/integration/change-integration/octopus-deploy.mdx
index f7c13a50..edfe18bc 100644
--- a/zh/on-call/integration/change-integration/octopus-deploy.mdx
+++ b/zh/on-call/integration/change-integration/octopus-deploy.mdx
@@ -1,5 +1,6 @@
---
title: "Octopus Deploy 变更集成"
+sidebarTitle: "Octopus Deploy"
description: "通过 Octopus Deploy 订阅(Subscription)的 Webhook,将部署的排队、开始、成功、失败和取消同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Octopus Deploy", "部署", "Subscription", "Webhook"]
---
@@ -11,7 +12,6 @@ keywords: ["变更集成", "Octopus Deploy", "部署", "Subscription", "Webhook"
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Octopus Deploy**,填写集成名称
@@ -21,7 +21,6 @@ keywords: ["变更集成", "Octopus Deploy", "部署", "Subscription", "Webhook"
</div>
## 在 Octopus Deploy 中配置
----
<Steps>
<Step title="创建订阅">
@@ -57,14 +56,12 @@ keywords: ["变更集成", "Octopus Deploy", "部署", "Subscription", "Webhook"
Octopus Deploy 没有测试推送按钮。保存后触发一次部署,即可在 Flashduty 变更列表中看到记录。变更链接依赖推送内容中的 Octopus 服务器地址。Octopus Cloud 会自动带上;自托管实例需在 **Configuration → Nodes → Configuration Settings** 中设置对外访问地址,否则变更没有链接。
## 一条变更是什么
----
| Octopus 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
| 部署(Deployment) | 部署 ID,例如 `Deployments-12519` | 同一部署的排队、开始、结束事件是同一条变更;同一发布版本再次部署到同一环境是另一个部署,即另一条变更 |
## 状态映射
----
| Octopus 事件类别 | Flashduty 变更状态 |
|---|---|
@@ -82,7 +79,6 @@ Octopus Deploy 没有测试推送按钮。保存后触发一次部署,即可
Flashduty 不认识的 `Deployment` 开头的事件类别返回 `InvalidParameter`,并在错误信息中给出类别名,其他事件不受影响。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -106,7 +102,6 @@ Flashduty 不认识的 `Deployment` 开头的事件类别返回 `InvalidParamete
名称从事件消息中读取,读不到时对应标签为空,标题改用 ID。
## 常见问题
----
<AccordionGroup>
<Accordion title="Octopus 重复推送会重复记录吗?">
diff --git a/zh/on-call/integration/change-integration/pulumi.mdx b/zh/on-call/integration/change-integration/pulumi.mdx
index 7e4da3c0..c9fb7565 100644
--- a/zh/on-call/integration/change-integration/pulumi.mdx
+++ b/zh/on-call/integration/change-integration/pulumi.mdx
@@ -1,5 +1,6 @@
---
title: "Pulumi Cloud 变更集成"
+sidebarTitle: "Pulumi Cloud"
description: "通过 Pulumi Cloud Webhook 将 Stack 更新和 Pulumi Deployments 部署同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Pulumi", "Pulumi Cloud", "Webhook", "Stack 更新", "Pulumi Deployments", "基础设施变更"]
---
@@ -20,7 +21,6 @@ Webhook 可以建在组织上(接收组织内所有 Stack 的事件),也
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Pulumi**,填写集成名称
@@ -30,7 +30,6 @@ Webhook 可以建在组织上(接收组织内所有 Stack 的事件),也
</div>
## 在 Pulumi Cloud 中配置
----
<Steps>
<Step title="创建 Webhook">
@@ -64,7 +63,6 @@ Webhook 可以建在组织上(接收组织内所有 Stack 的事件),也
</Steps>
## 一条变更是什么
----
| Pulumi 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -76,7 +74,6 @@ Webhook 可以建在组织上(接收组织内所有 Stack 的事件),也
同一个 Stack 的两次更新是两条变更。更新编号和部署版本是 Pulumi 按 Stack 递增的编号,在同一个 Stack 内不会重复。
## 状态映射
----
Stack 更新(`result`):
@@ -99,7 +96,6 @@ Deployments 部署(`status`):
Pulumi 会把被取消的更新或部署报告为 `failed`,因此记录为 Failed。Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时间。Pulumi 的 `result` 和 `status` 还可能出现 `not started`、`requested`、`running` 等值,Flashduty 分别记为 Ready 和 Processing;遇到其他值时推送返回错误。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -123,7 +119,6 @@ Pulumi 会把被取消的更新或部署报告为 `failed`,因此记录为 Fai
`actor` 和 `operation` 在同一条变更的不同通知里可能不一致,不要用它们做路由;路由请使用 `organization`、`project`、`stack`。
## 常见问题
----
<AccordionGroup>
<Accordion title="事件时间是什么?重复推送会重复记录吗?">
diff --git a/zh/on-call/integration/change-integration/railway.mdx b/zh/on-call/integration/change-integration/railway.mdx
index 11f316e0..a8d0ddf8 100644
--- a/zh/on-call/integration/change-integration/railway.mdx
+++ b/zh/on-call/integration/change-integration/railway.mdx
@@ -1,5 +1,6 @@
---
title: "Railway 变更集成"
+sidebarTitle: "Railway"
description: "通过 Railway 项目 Webhook 将服务的部署过程同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Railway", "部署", "Deployment", "Webhook"]
---
@@ -13,7 +14,6 @@ Railway 的 Webhook 按项目配置,项目内所有环境、所有服务的部
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Railway**,填写集成名称
@@ -23,7 +23,6 @@ Railway 的 Webhook 按项目配置,项目内所有环境、所有服务的部
</div>
## 在 Railway 中配置
----
<Steps>
<Step title="打开项目的 Webhooks 设置">
@@ -51,14 +50,12 @@ Railway 的 Webhook 不签名,Flashduty 通过推送地址中的 `integration_
</Steps>
## 一条变更是什么
----
| Railway 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
| Deployment | `resource.deployment.id`(缺失时用 `details.id`) | 每次部署有独立的 ID,同一次部署的所有状态推送属于同一条变更;同一服务、同一环境的两次部署是两条变更 |
## 状态映射
----
Flashduty 以推送中的 `type`(`Deployment.<状态>`)为准判断状态,不读取 `details.status`。Railway 官方 Webhook 文档本身存在不一致:`Deployment.failed` 的示例里 `details.status` 却是 `SUCCESS`。Railway 实际发出的推送中,`Deployment.failed` 对应的是 `FAILED`,但既然文档示例显示两个字段可能互相矛盾,仍只以 `type` 为准。
@@ -80,7 +77,6 @@ Flashduty 以推送中的 `type`(`Deployment.<状态>`)为准判断状态,
`Deployment.` 开头但不在上表和上述列表中的 `type`,推送返回 `InvalidParameter`(见常见问题)。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -109,7 +105,6 @@ Flashduty 以推送中的 `type`(`Deployment.<状态>`)为准判断状态,
`ref`、`sha`、`actor` 并非每次推送都有,按它们路由可能把同一次部署的后续状态分到其他协作空间。路由请使用 `workspace`、`project`、`service`、`environment`。
## 常见问题
----
<AccordionGroup>
<Accordion title="Railway 重试推送会重复记录吗?">
diff --git a/zh/on-call/integration/change-integration/rundeck.mdx b/zh/on-call/integration/change-integration/rundeck.mdx
index 6ae1dc4f..99447a2d 100644
--- a/zh/on-call/integration/change-integration/rundeck.mdx
+++ b/zh/on-call/integration/change-integration/rundeck.mdx
@@ -1,5 +1,6 @@
---
title: "Rundeck 变更集成"
+sidebarTitle: "Rundeck"
description: "通过 Rundeck 的 Webhook 通知将作业(Job)的每次执行同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Rundeck", "Webhook 通知", "作业执行", "运维自动化"]
---
@@ -13,7 +14,6 @@ Rundeck 无法区分一个作业是否会改变线上环境,因此只需在**
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Rundeck**,填写集成名称
@@ -23,7 +23,6 @@ Rundeck 无法区分一个作业是否会改变线上环境,因此只需在**
</div>
## 在 Rundeck 中配置
----
<Steps>
<Step title="打开作业的通知设置">
@@ -54,7 +53,6 @@ Rundeck 无法区分一个作业是否会改变线上环境,因此只需在**
</Steps>
## 一条变更是什么
----
每一次作业执行是一条变更,变更标识(change_key)为 Rundeck 的执行 ID(execution id),例如 `4711`。
@@ -64,7 +62,6 @@ Rundeck 无法区分一个作业是否会改变线上环境,因此只需在**
- 执行 ID 在一个 Rundeck 服务内唯一。多个 Rundeck 服务请分别创建集成,否则不同服务上相同的执行 ID 会被合并为一条变更
## 状态映射
----
| 触发点 | 执行状态(status) | Flashduty 变更状态 |
|---|---|---|
@@ -81,7 +78,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
`On Average Duration Exceeded` 报告的是仍在运行的执行,不是新的阶段,Flashduty 接收但不记录。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -105,7 +101,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
作业选项(Option)的值可能包含敏感信息,不会被记录。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到变更?">
diff --git a/zh/on-call/integration/change-integration/scalr.mdx b/zh/on-call/integration/change-integration/scalr.mdx
index a60d36a1..b5461046 100644
--- a/zh/on-call/integration/change-integration/scalr.mdx
+++ b/zh/on-call/integration/change-integration/scalr.mdx
@@ -1,5 +1,6 @@
---
title: "Scalr 变更集成"
+sidebarTitle: "Scalr"
description: "通过 Scalr Webhook 将 Terraform / OpenTofu Run 同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Scalr", "Terraform", "OpenTofu", "Run", "Webhook", "基础设施变更"]
---
@@ -11,7 +12,6 @@ keywords: ["变更集成", "Scalr", "Terraform", "OpenTofu", "Run", "Webhook", "
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Scalr**,填写集成名称
@@ -21,7 +21,6 @@ keywords: ["变更集成", "Scalr", "Terraform", "OpenTofu", "Run", "Webhook", "
</div>
## 在 Scalr 中配置
----
Webhook 在 Account 范围创建,再分配给 Environment;分配后,该 Environment 下所有 Workspace 的 Run 都会触发它。
@@ -44,7 +43,6 @@ Webhook 在 Account 范围创建,再分配给 Environment;分配后,该 En
</Steps>
## 一条变更是什么
----
| Scalr 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -53,7 +51,6 @@ Webhook 在 Account 范围创建,再分配给 Environment;分配后,该 En
Scalr 只在三种时刻推送:Run 需要人工确认、Run 成功结束、Run 出错。取消 Run、或在确认步骤放弃(Discard)Run 不会推送任何内容,这样的 Run 变更会停留在 Planned(或根本不会创建)。因此变更没有 Ready、Processing 状态,最早出现的状态是 Planned(等待确认)或结束状态。自动 Apply 的 Run 只会在结束时产生一条记录。
## 状态映射
----
| 推送事件(event_name) | Run 状态(run.status) | Flashduty 变更状态 |
|---|---|---|
@@ -66,7 +63,6 @@ Scalr 只在三种时刻推送:Run 需要人工确认、Run 成功结束、Run
以下推送返回成功但不生成变更:Run 状态为 `planned_and_finished` 的结束事件(只做了 Plan 或没有资源变更,没有内容被应用),以及不属于 `run:` 系列的其他事件。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -90,7 +86,6 @@ Scalr 只在三种时刻推送:Run 需要人工确认、Run 成功结束、Run
Run 的变量(`variables`)和用户邮箱不会记录。
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么没有收到变更?">
diff --git a/zh/on-call/integration/change-integration/semaphore.mdx b/zh/on-call/integration/change-integration/semaphore.mdx
index c03c80c0..b8eed65a 100644
--- a/zh/on-call/integration/change-integration/semaphore.mdx
+++ b/zh/on-call/integration/change-integration/semaphore.mdx
@@ -1,5 +1,6 @@
---
title: "Semaphore 变更集成"
+sidebarTitle: "Semaphore"
description: "通过 Semaphore 的 Webhook 通知将 Pipeline 的执行结果同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Semaphore", "Pipeline", "CI/CD", "Webhook"]
---
@@ -13,7 +14,6 @@ Semaphore 只在 Pipeline 结束(state 为 `done`)时推送通知,没有
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Semaphore**,填写集成名称
@@ -23,7 +23,6 @@ Semaphore 只在 Pipeline 结束(state 为 `done`)时推送通知,没有
</div>
## 在 Semaphore 中配置
----
<Steps>
<Step title="创建通知">
@@ -66,14 +65,12 @@ Semaphore 没有测试推送。在配置了通知的项目上运行一次 Pipeli
</Steps>
## 一条变更是什么
----
| Semaphore 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
| Pipeline | `pipeline.id` | 每次运行的每个 Pipeline 有独立的 ID,对应一条 Flashduty 变更。同一分支上的两次运行是两条变更;一个 Workflow 中通过 Promotion 触发的后续 Pipeline 也是各自独立的变更 |
## 状态映射
----
| Semaphore `pipeline.result` | Flashduty 变更状态 |
|---|---|
@@ -87,7 +84,6 @@ Semaphore 没有测试推送。在配置了通知的项目上运行一次 Pipeli
- `pipeline.state` 不是 `done` 的推送
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -114,7 +110,6 @@ Semaphore 没有测试推送。在配置了通知的项目上运行一次 Pipeli
| `semaphore_result` | Semaphore 的 Pipeline 结果原值 |
## 常见问题
----
<AccordionGroup>
<Accordion title="为什么看不到 Pipeline 的运行中状态?">
diff --git a/zh/on-call/integration/change-integration/teamcity.mdx b/zh/on-call/integration/change-integration/teamcity.mdx
index d588de4c..42409390 100644
--- a/zh/on-call/integration/change-integration/teamcity.mdx
+++ b/zh/on-call/integration/change-integration/teamcity.mdx
@@ -1,5 +1,6 @@
---
title: "TeamCity 变更集成"
+sidebarTitle: "TeamCity"
description: "通过 TeamCity 服务器的内置 Webhook 将构建的排队、开始和结束状态同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "TeamCity", "构建", "部署", "CI/CD", "Webhook"]
---
@@ -13,7 +14,6 @@ TeamCity 的 Webhook 在服务器级别配置,推送的是项目下所有构
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **TeamCity**,填写集成名称
@@ -23,7 +23,6 @@ TeamCity 的 Webhook 在服务器级别配置,推送的是项目下所有构
</div>
## 在 TeamCity 中配置
----
<Steps>
<Step title="添加 Webhook 参数">
@@ -60,14 +59,12 @@ TeamCity 没有测试推送。在配置了 Webhook 的项目下运行一次构
</Steps>
## 一条变更是什么
----
| TeamCity 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
| 构建(Build) | `id` | 构建的 ID 在整个 TeamCity 服务器内唯一,排队、运行、结束各事件都携带同一个 ID。同一构建配置、同一分支的两次构建是两条变更。不要使用构建号(`number`):它按构建配置计数,排队时为空,取消的构建显示为 `N/A` |
## 状态映射
----
| TeamCity 事件 | `status` | Flashduty 变更状态 |
|---|---|---|
@@ -86,7 +83,6 @@ TeamCity 取消运行中的构建触发 `BUILD_INTERRUPTED`,取消仍在排队
- 其他事件类型,例如 `AGENT_REGISTERED`、`AGENT_UNREGISTERED`、`AGENT_REMOVED`、`CHANGES_LOADED`、`BUILD_PROBLEMS_CHANGED`
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -111,7 +107,6 @@ TeamCity 取消运行中的构建触发 `BUILD_INTERRUPTED`,取消仍在排队
| `teamcity_status` | 构建状态原值。排队时没有,不要用它做路由 |
## 常见问题
----
<AccordionGroup>
<Accordion title="TeamCity 重发推送会重复记录吗?">
diff --git a/zh/on-call/integration/change-integration/unleash.mdx b/zh/on-call/integration/change-integration/unleash.mdx
index 68eabb5d..de5a3067 100644
--- a/zh/on-call/integration/change-integration/unleash.mdx
+++ b/zh/on-call/integration/change-integration/unleash.mdx
@@ -1,5 +1,6 @@
---
title: "Unleash 变更集成"
+sidebarTitle: "Unleash"
description: "通过 Unleash Webhook 集成将功能开关(Feature Flag)的变更同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Unleash", "Feature Flag", "功能开关", "Webhook"]
---
@@ -13,7 +14,6 @@ Unleash 推送的是已经生效的变更,因此每条变更都直接记录为
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Unleash**,填写集成名称
@@ -23,7 +23,6 @@ Unleash 推送的是已经生效的变更,因此每条变更都直接记录为
</div>
## 在 Unleash 中配置
----
<Steps>
<Step title="新建 Webhook 集成">
@@ -60,7 +59,6 @@ Unleash 推送的是已经生效的变更,因此每条变更都直接记录为
Unleash 没有测试推送按钮。保存后在任一 Flag 上做一次变更(例如打开某个环境),即可在 Flashduty 变更列表中看到记录。
## 一条变更是什么
----
| Unleash 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -69,7 +67,6 @@ Unleash 没有测试推送按钮。保存后在任一 Flag 上做一次变更(
事件 `id` 在一个 Unleash 实例内递增。请为每个 Unleash 实例单独创建一个集成;多个实例共用一个集成时,不同实例的相同 `id` 会被当作同一条变更。
## 状态映射
----
| Unleash 事件 | Flashduty 变更状态 |
|---|---|
@@ -82,7 +79,6 @@ Unleash 没有测试推送按钮。保存后在任一 Flag 上做一次变更(
- 项目、环境、用户、分群等其他资源的事件,以及缺少 `type` 的推送
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -103,7 +99,6 @@ Unleash 没有测试推送按钮。保存后在任一 Flag 上做一次变更(
| `event_id` | Unleash 事件 ID |
## 常见问题
----
<AccordionGroup>
<Accordion title="Unleash 重试推送会重复记录吗?">
diff --git a/zh/on-call/integration/change-integration/vercel.mdx b/zh/on-call/integration/change-integration/vercel.mdx
index d616b904..96b28e0c 100644
--- a/zh/on-call/integration/change-integration/vercel.mdx
+++ b/zh/on-call/integration/change-integration/vercel.mdx
@@ -1,5 +1,6 @@
---
title: "Vercel 变更集成"
+sidebarTitle: "Vercel"
description: "通过 Vercel 团队 Webhook 将部署、上线和回滚同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Vercel", "Deployment", "部署事件", "Instant Rollback", "Webhook"]
---
@@ -13,7 +14,6 @@ keywords: ["变更集成", "Vercel", "Deployment", "部署事件", "Instant Roll
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Vercel**,填写集成名称
@@ -23,7 +23,6 @@ keywords: ["变更集成", "Vercel", "Deployment", "部署事件", "Instant Roll
</div>
## 在 Vercel 中配置
----
<Steps>
<Step title="打开 Webhook 设置">
@@ -59,7 +58,6 @@ Vercel 创建后会显示一个 Secret,Flashduty 不需要它,通过推送
</Steps>
## 一条变更是什么
----
| Vercel 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -67,7 +65,6 @@ Vercel 创建后会显示一个 Secret,Flashduty 不需要它,通过推送
| 回滚 | `rollback:<fromDeploymentId>:<toDeploymentId>` | 一次 Instant Rollback 是一条独立变更,不修改被替换或被恢复的部署的记录 |
## 状态映射
----
| Vercel 事件 | Flashduty 变更状态 |
|---|---|
@@ -84,7 +81,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
以下推送返回成功但不生成变更:非 `deployment.` 开头的事件类型(Project、Feature Flag、Firewall 等);与 Checks、集成动作相关的部署事件;`deployment.cleanup`(部署在保留期结束后被永久删除,不改变该部署已有的结果)。
## 变更内容
----
| 字段 | 部署 | 回滚 |
|---|---|---|
@@ -109,7 +105,6 @@ Done、Failed 和 Canceled 是结束状态,Flashduty 会记录变更结束时
`ref`、`sha`、`actor` 来自连接 GitHub、GitLab 或 Bitbucket 仓库时的部署元数据,通过 CLI 直接部署时没有这些标签。
## 常见问题
----
<AccordionGroup>
<Accordion title="生产部署为什么先 Done 再收到一次 Done?">
diff --git a/zh/on-call/integration/change-integration/yunxiao-appstack.mdx b/zh/on-call/integration/change-integration/yunxiao-appstack.mdx
index 19548664..6f30537d 100644
--- a/zh/on-call/integration/change-integration/yunxiao-appstack.mdx
+++ b/zh/on-call/integration/change-integration/yunxiao-appstack.mdx
@@ -1,5 +1,6 @@
---
title: "阿里云云效 AppStack 变更集成"
+sidebarTitle: "阿里云云效 AppStack"
description: "通过云效应用交付 AppStack 的 Webhook,将部署单的准备、运行、成功、失败和取消同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "阿里云云效", "云效", "AppStack", "应用交付", "部署单", "Webhook"]
---
@@ -11,7 +12,6 @@ keywords: ["变更集成", "阿里云云效", "云效", "AppStack", "应用交
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **阿里云云效 AppStack**,填写集成名称
@@ -21,7 +21,6 @@ keywords: ["变更集成", "阿里云云效", "云效", "AppStack", "应用交
</div>
## 在云效 AppStack 中配置
----
<Steps>
<Step title="新建 Webhook">
@@ -47,7 +46,6 @@ keywords: ["变更集成", "阿里云云效", "云效", "AppStack", "应用交
云效的 **测试 Webhook** 按钮会发送一条模拟的“新建应用”事件,Flashduty 返回成功但不生成变更,只用于确认地址可达。要看到变更记录,需要实际执行一次部署。
## 一条变更是什么
----
| 云效对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -56,7 +54,6 @@ keywords: ["变更集成", "阿里云云效", "云效", "AppStack", "应用交
请求体顶层的 `id` 是每次推送的事件记录 ID,不是部署单 ID,不参与变更标识。
## 状态映射
----
| 云效部署单状态(`objectAttributes.state`) | Flashduty 变更状态 |
|---|---|
@@ -75,7 +72,6 @@ keywords: ["变更集成", "阿里云云效", "云效", "AppStack", "应用交
云效文档列出的部署单状态以上七种。出现其他状态时返回 `InvalidParameter`,并在错误信息中给出状态值,该部署单之后的其他状态更新不受影响。
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -100,7 +96,6 @@ keywords: ["变更集成", "阿里云云效", "云效", "AppStack", "应用交
环境名称取自部署单中的作业(jobs)。
## 常见问题
----
<AccordionGroup>
<Accordion title="云效重复推送会重复记录吗?">
diff --git a/zh/on-call/integration/change-integration/zadig.mdx b/zh/on-call/integration/change-integration/zadig.mdx
index 30e2d38e..2604cba3 100644
--- a/zh/on-call/integration/change-integration/zadig.mdx
+++ b/zh/on-call/integration/change-integration/zadig.mdx
@@ -1,5 +1,6 @@
---
title: "Zadig 变更集成"
+sidebarTitle: "Zadig"
description: "通过 Zadig 的系统钩子或工作流 Webhook 通知,将工作流任务的开始与结果同步到 Flashduty On-call,作为变更事件与告警、故障关联。"
keywords: ["变更集成", "Zadig", "工作流", "CI/CD", "Webhook"]
---
@@ -16,7 +17,6 @@ Zadig 有两种 Webhook 可用,推送内容相同:
<div className="hide">
## 在 Flashduty On-call
----
1. 进入 Flashduty 控制台,选择 **集成中心 → 变更事件**
2. 选择 **Zadig**,填写集成名称
@@ -26,7 +26,6 @@ Zadig 有两种 Webhook 可用,推送内容相同:
</div>
## 在 Zadig 中配置
----
### 方式一:系统钩子
@@ -60,7 +59,6 @@ Zadig 有两种 Webhook 可用,推送内容相同:
同时配置两种方式不会产生重复变更:同一个任务的同一状态只记录一次。
## 一条变更是什么
----
| Zadig 对象 | 变更标识(change_key) | 说明 |
|---|---|---|
@@ -69,7 +67,6 @@ Zadig 有两种 Webhook 可用,推送内容相同:
对已有任务点击 **重试** 会重新开始同一个任务(任务 ID 不变),因此重试会重新打开原来的变更,状态回到 Ready 并随后更新。
## 状态映射
----
| Zadig `workflow.status` | Flashduty 变更状态 |
|---|---|
@@ -89,7 +86,6 @@ Zadig 有两种 Webhook 可用,推送内容相同:
- 其他 `object_kind` 的推送
## 变更内容
----
| 字段 | 内容 |
|---|---|
@@ -111,7 +107,6 @@ Zadig 有两种 Webhook 可用,推送内容相同:
| `release_plan_id` | 发布计划 ID(由发布计划触发时) |
## 常见问题
----
<AccordionGroup>
<Accordion title="只构建、不部署的工作流也会生成变更吗?">
diff --git a/zh/on-call/integration/instant-messaging/dingtalk.mdx b/zh/on-call/integration/instant-messaging/dingtalk.mdx
index 3efa7055..e899a14a 100644
--- a/zh/on-call/integration/instant-messaging/dingtalk.mdx
+++ b/zh/on-call/integration/instant-messaging/dingtalk.mdx
@@ -13,9 +13,9 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
<span id="aisre-permissions"></span>
<span id="war-room-scope"></span>
-## AISRE 所需权限
+## 所需权限
-以下为钉钉 IM 集成在开启 AISRE(包含基础通知、作战室、AI SRE 对话和 AI 生成复盘)时需要授予的完整权限清单。进入钉钉开放平台 **权限管理** 页面时,请逐项申请以下官方权限名称。
+在钉钉开放平台 **权限管理** 页面按需申请以下权限。基础通知需要前两项;作战室再加第 3–5 项(第 5 项也用于一键关联用户);启用钉钉 AI 流式卡片模板时再加最后两项。
| 官方权限名称 | 用途 |
| :--- | :--- |
@@ -31,7 +31,7 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
如果未配置钉钉 AI 流式卡片模板,AI SRE 会降级使用普通版互动卡片或会话机器人消息回复,此时仍需要保留 `qyapi_robot_sendmsg`。
</Note>
-## 一、创建钉钉应用与添加钉钉集成
+## 创建钉钉应用与添加钉钉集成
### 1. 创建自建应用
@@ -39,7 +39,7 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
详见钉钉开发文档 [创建企业内部应用-H5 微应用](https://open.dingtalk.com/document/orgapp/microapplication-creation-and-release-process#title-ovn-666-1ty)。
-
+
应用图标可使用 [Flashduty 官方 icon](https://flashduty-public.oss-cn-beijing.aliyuncs.com/icons/flashduty-20251216.png)。
@@ -47,7 +47,7 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
点击页面右上角企业头像,在下拉菜单中复制 `CorpId`。
-
+
回到 Flashduty On-call 集成配置页面,在表单中填入对应的 `CorpId`。
@@ -55,7 +55,7 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
进入创建的应用详情界面,通过左侧菜单栏前往 应用能力 → **凭证与基础信息** 页面,复制 `AgentId`、`Client ID` 和 `Client Secret`。
-
+
回到 Flashduty On-call 集成配置页面,在表单中填入对应的 `AgentId`、 `Client ID` 和 `Client Secret`。
@@ -63,7 +63,7 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
前往 开发配置 → **事件与回调** 页面。设置推送方式为 `HTTP推送`,然后点击按钮生成 `加密 aes_key` 和 `签名 Token`,并复制保存。
-
+
回到 Flashduty On-call 集成配置页面,在表单中填入对应的 `加密 aes_key` 和 `签名 Token`,点击 **保存** 按钮。
@@ -73,11 +73,11 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
根据 Flashduty 集成详情中的 `事件订阅请求地址`,配置 **事件订阅请求网址**。配置完成后 **保存**。
-
+
在 **保存** 按钮下方,选中 `群会话更换群名称`、`群内安装酷应用` 和 `群内卸载酷应用` 三种群会话事件,配置完成后点击 **保存**。
-
+
### 6. 添加应用能力
@@ -87,11 +87,11 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
1. 填写基本信息。图标可使用 [Flashduty 官方 icon](https://flashduty-public.oss-cn-beijing.aliyuncs.com/icons/flashduty-20251216.png)。
-
+ 
2. 配置功能设计。在左侧选中 **群快捷入口** 和 **消息卡片**。群快捷入口图标可使用 [Flashduty 官方 icon](https://flashduty-public.oss-cn-beijing.aliyuncs.com/icons/flashduty-20251216.png),桌面和移动端访问地址请复制集成详情里的 **酷应用网页地址**。
-
+ 
3. 跳过第三步功能开发,进入第四步 **预览发布**,点击 **发布** 按钮并确认。
@@ -99,7 +99,7 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
进入 应用能力 → **机器人** 页面,打开机器人配置,填写名称并上传图标,然后点击 **保存**。图标可使用 [Flashduty 官方 icon](https://flashduty-public.oss-cn-beijing.aliyuncs.com/icons/flashduty-20251216.png)。
-
+
### 8. 配置应用地址
@@ -107,40 +107,29 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
根据 Flashduty 集成详情中的 `应用首页地址` 和 `PC 端首页地址`,配置 **应用首页地址** 和 **PC 端首页地址**。完成后点击 **保存**。
-
+
### 9. 申请应用权限
-进入 开发配置 → **权限管理** 页面,为先前步骤创建的群应用申请以下权限:
+进入 开发配置 → **权限管理** 页面,申请 `qyapi_chat_manage` 和 `qyapi_robot_sendmsg`。需要作战室或 AI SRE 流式卡片时,一并申请[所需权限](#aisre-permissions)中的其余权限。
-- `qyapi_chat_manage`:获取群聊信息
-- `qyapi_robot_sendmsg`:向群聊或个人发送消息
-
-如果需要开启 AISRE,请同时确认页面开头的 [AISRE 所需权限](#aisre-permissions) 已全部申请。
-
-
+
<Note>
如果需要继续配置作战室,请先发布一次自建应用。应用发布后,才能在场景群的 **可选应用** 列表中选择该应用。发布路径请参考 [应用发布与使用](#publish)。
</Note>
-## 二、配置作战室
+## 配置作战室
<Tip>
若您无需配置作战室功能,可跳过本步骤,直接进入 [**应用发布与使用**](#publish)。
</Tip>
-> 配置作战室前,请确认应用已获得页面开头列出的 [AISRE 所需权限](#aisre-permissions)。
-
### 1. 申请应用权限
-进入 开发配置 → **权限管理** 页面,为先前步骤创建的群应用申请以下权限:
+进入 开发配置 → **权限管理** 页面,申请 `qyapi_chat_read`、`qyapi_chat_base_read` 和 `qyapi_get_member_by_mobile`(用途见[所需权限](#aisre-permissions))。
-- `qyapi_chat_read`:获取群聊信息
-- `qyapi_chat_base_read`:获取群聊信息
-- `qyapi_get_member_by_mobile`:允许当前应用根据手机号获取钉钉用户以便邀请用户加入群聊
-
-
+
### 2. 配置群模板
@@ -148,15 +137,15 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
1. 配置 **群机器人**。在左侧菜单栏中选择 **机器人**,然后点击 **创建群机器人**。
-<Note>
-本步骤中配置的 **群机器人** 和 **应用机器人** 是两个不同的概念。群机器人被用于在生成群聊时自动创建群机器人。群机器人和应用机器人拥有不同的 **机器人 ID**。若要为钉钉开启作战室功能,必须额外配置 **群机器人**。
-</Note>
+ <Note>
+ 这里的 **群机器人** 与上文的 **应用机器人** 不同,会在创建作战室群聊时自动加入群,二者的 **机器人 ID** 也不同。开启作战室必须额外配置群机器人。
+ </Note>
-填写群机器人配置。若需要使用 AISRE,请按下表配置 **消息回调地址**、**消息回调 token** 和 **信息来源网站**。这三项用于 AISRE 的钉钉消息回调。
+ 填写群机器人配置。若需要使用 AI SRE,请按下表配置 **消息回调地址**、**消息回调 token** 和 **信息来源网站**。这三项用于 AI SRE 的钉钉消息回调。
-<Note>
-钉钉当前对消息回调地址的证书校验不兼容 `api.flashcat.cloud` 使用的 ACME 自动签发证书。为保证钉钉能够正常校验并回调消息,请将 Flashduty 集成配置页提供的消息地址中的域名替换为 `dingtalk-message.flashcat.cloud`。
-</Note>
+ <Note>
+ 钉钉的证书校验不兼容 `api.flashcat.cloud` 的 ACME 证书,因此消息回调地址需把域名换成 `dingtalk-message.flashcat.cloud`(见下表)。
+ </Note>
**示例配置**:
@@ -173,7 +162,7 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
完成配置后,点击 **创建**,然后点击 **审批**。右上角弹出 “提交成功” 后,钉钉已自动完成群机器人的审批。
- 
+ 
2. 配置 **群模板**。在左侧菜单栏中选择 **群模板**,点击 **创建群模板**。
@@ -194,8 +183,8 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
在 **选择机器人** 配置项中,点击 **选择已创建的机器人**,选择上一步骤中创建的群机器人。其他配置项保持默认。最后点击 **保存编辑**。
- 
- 
+ 
+ 
在 **填写灰度群** 步骤中,点击 **创建灰度群**,然后点击 **发布灰度**。
@@ -203,15 +192,15 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
3. 在已经发布的群模板详细信息页,复制 **模板 ID** 和 **机器人 ID**。
- 
+ 
回到 Flashduty On-call 集成配置页面,在表单中填入对应的 `模版 ID` 和 `机器人 ID`,点击 **保存** 按钮。
<Warning>
-同一时间仅支持在一个 IM 集成中开启作战室功能。如果你已在其他 IM 集成(如飞书、Slack、企业微信)中启用了作战室,需要先在该集成中关闭后,才能在当前钉钉集成中开启。
+同一时间仅支持在一个 IM 集成中开启作战室功能。如果您已在其他 IM 集成(如飞书、Slack、企业微信)中启用了作战室,需要先在该集成中关闭后,才能在当前钉钉集成中开启。
</Warning>
-### AI SRE 控制项
+## AI SRE 控制项
在 **增强功能** 中配置以下 AI SRE 控制项,默认均为开启:
@@ -222,7 +211,7 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
<span id="publish"></span>
-## 三、应用发布与使用
+## 应用发布与使用
完成上述步骤后,请确认自建应用已发布最新版本。若尚未发布,或发布后又调整了应用配置,请前往 应用发布 → **版本管理与发布**,创建新版本并发布。
@@ -230,35 +219,19 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
为了确保所有人可以使用应用,需将应用 **可见范围** 调整为全部员工,再进行应用发布。
</Note>
-
+
应用发布后,即可通过 **手机端** 或 **PC 端** 访问应用。首次访问需要登录并关联钉钉与 Flashduty 账号,后续可以免登录使用。
-<Tabs>
-<Tab title="手机端">
-钉钉 → 工作台 → 搜索应用名称 → **打开应用**
-</Tab>
-
-<Tab title="PC 端">
-钉钉 → 工作台 → 搜索应用名称 → **打开应用**
-</Tab>
-</Tabs>
+手机端和 PC 端的入口相同:钉钉 → 工作台 → 搜索应用名称 → **打开应用**。
-## 四、关联用户
+## 关联用户
-在集成详情页的 **关联用户** 页签中,你可以查看团队成员与钉钉账号的关联状态,并快速完成批量关联。
+在集成详情页的 **关联用户** 页签中,您可以查看团队成员与钉钉账号的关联状态,并快速完成批量关联。
### 查看关联状态
-关联用户列表展示所有团队成员及其关联状态。你可以通过以下方式筛选:
-
-| 筛选项 | 说明 |
-| :--- | :--- |
-| **全部** | 查看所有团队成员 |
-| **已关联** | 仅查看已完成钉钉账号关联的成员 |
-| **未关联** | 仅查看尚未关联钉钉账号的成员 |
-
-支持通过名称或邮箱搜索成员。
+列表展示所有团队成员及其关联状态,可按 **全部 / 已关联 / 未关联** 筛选,也可按名称或邮箱搜索。
### 一键关联
@@ -268,7 +241,7 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
成员完成关联后,系统才能向其推送钉钉消息通知。如果关联失败,请确认成员的手机号是否与钉钉账号一致。
</Tip>
-## 五、常见问题
+## 常见问题
<AccordionGroup>
<Accordion title="消息无法投递到个人,操作记录提示「未关联应用」?">
@@ -283,12 +256,12 @@ keywords: ["钉钉", "即时消息", "告警通知", "IM集成", "钉钉机器
<Accordion title="分派策略钉钉群聊列表为空?">
1. 前往钉钉,选择群聊会话安装酷应用,否则无法获取群聊列表
-
+ 
-
+ 
2. 回到分派策略配置页面,刷新后重新选择群聊列表
-3. 如果仍然无法获取群聊列表,请尝试在群内卸载酷应用后,重试以上步骤。如果问题依旧,请联系客户或专属技术支持
+3. 如果仍然无法获取群聊列表,请尝试在群内卸载酷应用后,重试以上步骤。如果问题依旧,请联系客服或专属技术支持
</Accordion>
<Accordion title="为什么作战室功能未按预期工作?">
diff --git a/zh/on-call/integration/instant-messaging/lark.mdx b/zh/on-call/integration/instant-messaging/lark.mdx
index e6201233..d71c46fc 100644
--- a/zh/on-call/integration/instant-messaging/lark.mdx
+++ b/zh/on-call/integration/instant-messaging/lark.mdx
@@ -9,9 +9,9 @@ keywords: ["飞书", "Lark", "即时消息", "告警通知", "IM集成"]
<span id="aisre-permissions"></span>
<span id="war-room-scope"></span>
-## AISRE 所需权限
+## 所需权限
-以下为飞书/Lark IM 集成在开启 AISRE(包含基础通知、作战室、AI SRE 对话和 AI 生成复盘)时需要授予的完整权限清单。进入飞书/Lark 开放平台 **权限管理** 页面时,请逐项申请以下官方权限名称。
+在飞书/Lark 开放平台 **权限管理** 页面申请以下全部权限(覆盖基础通知、作战室、AI SRE 对话和 AI 生成复盘),具体步骤见下文 [申请应用权限](#request-permissions)。
| 官方权限名称 | 用途 |
| :--- | :--- |
@@ -33,14 +33,12 @@ keywords: ["飞书", "Lark", "即时消息", "告警通知", "IM集成"]
<div className="hide">
{/*
## 视频介绍
----
<Video src="https://download.flashcat.cloud/flashduty/video/feishu.mp4"></Video>
*/}
</div>
-## 一、创建飞书应用
----
+## 创建飞书应用
### 1. 创建自建应用
@@ -48,23 +46,21 @@ keywords: ["飞书", "Lark", "即时消息", "告警通知", "IM集成"]
详见飞书开发文档 [创建企业自建应用](https://open.feishu.cn/document/uYjL24iN/uMTMuMTMuMTM/development-guide/step1#132c1aac)。
-
+
### 2. 复制凭证信息
前往 **凭证与基础信息** 页面,复制 `App ID` 和 `App Secret` 备用。
-
-
+
### 3. 复制事件回调的 Token 信息
前往 开发配置 → 事件与回调 → **加密策略** 页面,生成并复制 `Encrypt Key`(推荐启用,更安全)和 `Verification Token` 备用。
-
+
-## 二、添加飞书集成
----
+## 添加飞书集成
回到 Flashduty On-call **集成中心** 页面,选择 即时消息 → **飞书**,在表单中填入 `名称` 以及上一步复制的 `App ID`、`App Secret`、`Verification Token` 和 `Encrypt Key` 后,点击 **保存** 完成创建。
@@ -72,34 +68,33 @@ keywords: ["飞书", "Lark", "即时消息", "告警通知", "IM集成"]
创建成功后,您将在列表中看到已添加的飞书集成。点击其名称进入详情页面,即可查看 **网页配置** 地址、**重定向 URL** 和 **消息卡片请求网址**,这些信息将在后续步骤中使用。
-
+
-## 三、配置飞书应用
----
+## 配置飞书应用
### 1. 开通并配置应用能力
1. 回到飞书开发者后台,进入刚才创建的飞书应用,进入 添加应用能力 → **按能力添加** 页面,同时开通 **网页应用** 和 **机器人** 能力。
-
+ 
2. 前往 **网页应用** 页面,配置 `桌面端主页` 和 `移动端主页`,内容均为集成详情中的 **网页配置** 地址。详见飞书开发文档 [配置应用主页地址](https://open.feishu.cn/document/uYjL24iN/uMTMuMTMuMTM/development-guide/step1#8366b844)。
-
+ 
3. 前往 事件回调 → **事件配置** 页面,配置 `订阅方式`(内容为集成详情中的 **消息卡片请求网址**)。然后,添加以下事件:
-- `im.message.receive_v1`
-- `im.chat.disbanded_v1`(可选订阅,当前无消费逻辑)
+ - `im.message.receive_v1`
+ - `im.chat.disbanded_v1`(可选订阅,当前无消费逻辑)
-
+ 
4. 前往 事件回调 → **回调配置** 页面,配置 `订阅方式`(内容为集成详情中的 **消息卡片请求网址**)。然后,订阅以下两项回调:
-- `card.action.trigger`
-- `card.action.trigger_v1`
+ - `card.action.trigger`
+ - `card.action.trigger_v1`
-
+ 
### 2. 添加重定向 URL 到飞书应用
@@ -107,15 +102,17 @@ keywords: ["飞书", "Lark", "即时消息", "告警通知", "IM集成"]
详见飞书开发文档 [配置重定向 URL](https://open.feishu.cn/document/uYjL24iN/uYjN3QjL2YzN04iN2cDN?lang=zh-CN#c863e533)。
-
+
+
+<span id="request-permissions"></span>
### 3. 申请应用权限
-进入 **权限管理** 页面,为先前步骤创建的应用申请页面开头 [AISRE 所需权限](#aisre-permissions) 中列出的全部权限。请特别确认已开通 `im:message.p2p_msg:readonly` 和 `im:message.group_at_msg:readonly`,否则飞书不会向 Flashduty 推送单聊消息或群聊 @ 机器人消息。权限或事件配置变更后,需要重新发布应用后才会在线上生效。
+进入 **权限管理** 页面,为先前步骤创建的应用申请页面开头 [所需权限](#aisre-permissions) 中列出的全部权限。请特别确认已开通 `im:message.p2p_msg:readonly` 和 `im:message.group_at_msg:readonly`,否则飞书不会向 Flashduty 推送单聊消息或群聊 @ 机器人消息。权限或事件配置变更后,需要重新发布应用后才会在线上生效。
-
+
-## 四、应用发布与使用
+## 应用发布与使用
完成上述所有配置后,请发布应用。待管理员审核通过后即可使用。详见飞书开发文档 [应用发布与使用](https://open.feishu.cn/document/uYjL24iN/uMTMuMTMuMTM/development-guide/step-4)。
@@ -123,33 +120,23 @@ keywords: ["飞书", "Lark", "即时消息", "告警通知", "IM集成"]
为了确保所有人可以使用应用,需将应用 **可见范围** 调整为全部员工,再进行应用发布。
</Note>
-
+
应用发布后,即可通过 **手机端** 或 **PC 端** 访问应用。首次访问需要登录并关联飞书与 Flashduty 账号,后续可以免登录使用。
-<Tabs>
-<Tab title="手机端">
-飞书 → 工作台 → 搜索应用名称 → **打开应用**
-</Tab>
+手机端和 PC 端的入口相同:飞书 → 工作台 → 搜索应用名称 → **打开应用**。
-<Tab title="PC 端">
-飞书 → 工作台 → 搜索应用名称 → **打开应用**
-</Tab>
-</Tabs>
+
-
-
-## 五、配置作战室
-
-> 确保应用已被授权使用页面开头列出的 [AISRE 所需权限](#aisre-permissions)。
+## 配置作战室
完成先前步骤后,在 Flashduty On-call 集成配置页面的 **增强功能** 模块,勾选 **开启作战室** 即可启用该功能,无需额外配置。
<Warning>
-同一时间仅支持在一个 IM 集成中开启作战室功能。如果你已在其他 IM 集成(如钉钉、Slack、企业微信)中启用了作战室,需要先在该集成中关闭后,才能在当前飞书集成中开启。
+同一时间仅支持在一个 IM 集成中开启作战室功能。如果您已在其他 IM 集成(如钉钉、Slack、企业微信)中启用了作战室,需要先在该集成中关闭后,才能在当前飞书集成中开启。
</Warning>
-### AI SRE 控制项
+## AI SRE 控制项
在 **增强功能** 中分别配置以下 AI SRE 控制项,默认均为开启:
@@ -159,21 +146,13 @@ keywords: ["飞书", "Lark", "即时消息", "告警通知", "IM集成"]
如果账户尚未启用 AI SRE,以上配置暂不生效。
-## 六、关联用户
+## 关联用户
-在集成详情页的 **关联用户** 页签中,你可以查看团队成员与飞书账号的关联状态,并快速完成批量关联。
+在集成详情页的 **关联用户** 页签中,您可以查看团队成员与飞书账号的关联状态,并快速完成批量关联。
### 查看关联状态
-关联用户列表展示所有团队成员及其关联状态。你可以通过以下方式筛选:
-
-| 筛选项 | 说明 |
-| :--- | :--- |
-| **全部** | 查看所有团队成员 |
-| **已关联** | 仅查看已完成飞书账号关联的成员 |
-| **未关联** | 仅查看尚未关联飞书账号的成员 |
-
-支持通过名称或邮箱搜索成员。
+列表展示所有团队成员及其关联状态,可按 **全部 / 已关联 / 未关联** 筛选,也可按名称或邮箱搜索。
### 一键关联
@@ -183,7 +162,7 @@ keywords: ["飞书", "Lark", "即时消息", "告警通知", "IM集成"]
成员完成关联后,系统才能向其推送飞书消息通知。如果关联失败,请确认成员的手机号或邮箱是否与飞书账号一致。
</Tip>
-## 七、常见问题
+## 常见问题
<AccordionGroup>
<Accordion title="消息无法投递到个人,操作记录提示「未关联应用」?">
@@ -199,25 +178,25 @@ keywords: ["飞书", "Lark", "即时消息", "告警通知", "IM集成"]
- 前往飞书,在指定群聊会话中添加已创建的 Flashduty 机器人
- 回到分派策略配置页面,刷新后重新选择群聊列表
-
+
</Accordion>
<Accordion title="飞书自建应用 API 限制?">
**调用量限制:**
- | **飞书版本** | **调用总量/月** | **刷新时间** |
- | :---: | :---: | :---: |
- | 基础免费版 | 10,000 次 | 每月 1 日 |
- | 其他版本 | 不限制 | - |
+| **飞书版本** | **调用总量/月** | **刷新时间** |
+| :---: | :---: | :---: |
+| 基础免费版 | 10,000 次 | 每月 1 日 |
+| 其他版本 | 不限制 | - |
**频控限制:**
- | **场景** | **限制** |
- | :---: | :--- |
- | 所有接口 | 每个应用最高频率 50 次/秒 |
- | 发消息接口 | 每个应用最高频率 1000 次/分钟 |
- | 群机器人 Webhook | 最高频率 100 次/分钟 |
- | 给同一个用户或同一个群发消息 | 最高频率 5 次/秒 |
+| **场景** | **限制** |
+| :---: | :--- |
+| 所有接口 | 每个应用最高频率 50 次/秒 |
+| 发消息接口 | 每个应用最高频率 1000 次/分钟 |
+| 群机器人 Webhook | 最高频率 100 次/分钟 |
+| 给同一个用户或同一个群发消息 | 最高频率 5 次/秒 |
<Warning>
超出 API 调用量限制后,飞书应用将无法正常推送消息,建议合理使用通知渠道。详见 [飞书官方文档](https://open.feishu.cn/document/uAjLw4CM/ugTN1YjL4UTN24CO1UjN/platform-updates-/custom-app-api-call-limit)。
@@ -225,7 +204,7 @@ keywords: ["飞书", "Lark", "即时消息", "告警通知", "IM集成"]
</Accordion>
<Accordion title="为什么作战室功能未按预期工作?">
-- 请再次检查是否为应用配置了页面开头列出的 [AISRE 所需权限](#aisre-permissions)
+- 请再次检查是否为应用配置了页面开头列出的 [所需权限](#aisre-permissions)
- 请参考 [作战室介绍文档](/zh/on-call/advanced/war-room) 的 **常见问题** 部分
</Accordion>
</AccordionGroup>
diff --git a/zh/on-call/integration/instant-messaging/microsoft-teams.mdx b/zh/on-call/integration/instant-messaging/microsoft-teams.mdx
index f0f252cf..f756ba75 100644
--- a/zh/on-call/integration/instant-messaging/microsoft-teams.mdx
+++ b/zh/on-call/integration/instant-messaging/microsoft-teams.mdx
@@ -7,31 +7,10 @@ keywords: ["Microsoft Teams", "Teams", "即时消息", "告警通知", "IM集成
<Tip>**版本要求**:IM 集成需要 On-call 专业版及以上订阅。[了解更多](https://flashcat.cloud/flashduty/price/)</Tip>
<Warning>
-如果您的组织限制第三方应用,请先联系 Microsoft Teams 管理员允许使用 Flashduty。
+如果您的组织限制第三方应用,或在后续步骤中找不到、无法添加 Flashduty,请联系 Microsoft Teams 管理员。
</Warning>
-<Note>
-如需了解 Teams 应用处理 Teams 用户、团队、频道、群聊和故障卡片数据的规则,请参阅《[Flashduty Microsoft Teams 应用隐私政策](/zh/compliance/microsoft-teams-app-privacy-policy)》和《[Flashduty Microsoft Teams 应用使用条款](/zh/compliance/microsoft-teams-app-terms-of-use)》。
-</Note>
-
-## 一、数据和权限说明
-
-Flashduty Teams 应用只在发送告警通知、完成关联配置和处理故障卡片操作所需的范围内处理 Teams 数据。
-
-| 数据或能力 | 使用场景 |
-| --- | --- |
-| Teams 用户 ID、Microsoft Entra ID(AAD Object ID) | 关联 Teams 用户与 Flashduty 用户;校验故障卡片操作人;向关联用户发送个人通知或操作反馈 |
-| Team ID、Team 名称、Channel ID | 关联 Teams 团队或频道;把告警和故障通知发送到指定 Teams 频道;查询指定 Team 的详情和频道列表 |
-| Group Chat ID、用户输入的 Chat 名称 | 关联 Teams 群聊;把告警和故障通知发送到指定群聊 |
-| Conversation ID、Activity ID、Bot Framework 会话引用 | 在应用安装后发送、更新或回复 Teams 通知卡片 |
-| Bot 指令和卡片动作 | 处理 `help`、`linkUser`、`linkTeam`、`linkChat` 指令,以及认领、解决、暂缓、自定义操作等卡片按钮 |
-| Flashduty 告警和故障卡片数据 | 在 Teams 中展示告警或故障详情,并把卡片操作结果同步回 Flashduty |
-
-Flashduty Teams 应用不会读取与 Flashduty 功能无关的普通 Teams 聊天内容。它只处理个人聊天中发送给 bot 的消息、团队或群聊中 @ bot 的消息、卡片按钮动作、应用安装和会话所需的引用信息,以及发送或更新 Flashduty 通知所需的数据。
-
-当前应用包不申请用于读取全组织聊天内容的 Microsoft Graph 权限。如后续版本引入新的 Teams 权限或数据处理场景,Flashduty 将更新本文档和相关隐私说明。
-
-## 二、从 Microsoft Teams 获取应用
+## 从 Microsoft Teams 获取应用
<Steps>
<Step title="查找 Flashduty">
@@ -47,15 +26,11 @@ Flashduty Teams 应用不会读取与 Flashduty 功能无关的普通 Teams 聊
以下指令中的 `{ID}` 请替换为 Flashduty Microsoft Teams 集成 ID;`{ChatName}` 请替换为群聊名称。
</Note>
-## 三、关联团队 (Team)
+## 关联团队 (Team)
<Steps>
<Step title="查找应用">
在 Teams 中打开 **Apps**,找到 **Flashduty**,然后选择 **Add to a team**。
-
-<Note>
-如果无法找到或添加应用,请联系 Microsoft Teams 管理员。
-</Note>
</Step>
<Step title="添加到团队">
@@ -65,13 +40,13 @@ Flashduty Teams 应用不会读取与 Flashduty 功能无关的普通 Teams 聊
此步骤必须选择目标 Team 的 General Channel,否则将无法发送故障到 Team 中。
</Warning>
-
+
</Step>
<Step title="发送关联指令">
在 Team 的 General Channel 中 @Flashduty 并发送 `linkTeam {ID}`,然后选择 **立即关联**。
-
+
</Step>
<Step title="解除团队关联">
@@ -79,27 +54,23 @@ Flashduty Teams 应用不会读取与 Flashduty 功能无关的普通 Teams 聊
</Step>
</Steps>
-## 四、关联群聊 (Chat)
+## 关联群聊 (Chat)
<Steps>
<Step title="查找应用">
在 Teams 中打开 **Apps**,找到 **Flashduty**,然后选择 **Add to a chat**。
-
-<Note>
-如果无法找到或添加应用,请联系 Microsoft Teams 管理员。
-</Note>
</Step>
<Step title="添加到群聊">
将应用添加到目标 Chat。
-
+
</Step>
<Step title="发送关联指令">
在群聊中 @Flashduty 并发送 `linkChat {ID} {ChatName}`,然后选择 **立即关联**。
-
+
</Step>
<Step title="解除群聊关联">
@@ -107,7 +78,7 @@ Flashduty Teams 应用不会读取与 Flashduty 功能无关的普通 Teams 聊
</Step>
</Steps>
-## 五、消息卡片操作
+## 消息卡片操作
当故障通知推送到 Microsoft Teams 后,通知卡片可包含以下交互操作;具体可用按钮以您收到的 Flashduty 卡片和后台配置为准:
@@ -120,27 +91,23 @@ Flashduty Teams 应用不会读取与 Flashduty 功能无关的普通 Teams 聊
作战室(War Room)功能目前不支持 Microsoft Teams。如果您需要使用作战室功能,请考虑使用 Slack、飞书、钉钉或企业微信集成。
</Note>
-## 六、关联用户
+## 关联用户
<Steps>
<Step title="查找应用">
在 Teams 中打开 **Apps**,找到 **Flashduty**,然后选择 **Open**。
-
-<Note>
-如果无法找到或打开应用,请联系 Microsoft Teams 管理员。
-</Note>
</Step>
<Step title="打开应用">
点击 **打开应用**。
-
+
</Step>
<Step title="发送关联指令">
在与 Flashduty 的个人聊天中发送 `linkUser {ID}`,然后选择 **立即关联**。
-
+
</Step>
<Step title="解除个人账号关联">
@@ -148,7 +115,26 @@ Flashduty Teams 应用不会读取与 Flashduty 功能无关的普通 Teams 聊
</Step>
</Steps>
-## 七、常见问题
+## 数据和权限说明
+
+如需了解 Teams 应用处理 Teams 用户、团队、频道、群聊和故障卡片数据的规则,请参阅《[Flashduty Microsoft Teams 应用隐私政策](/zh/compliance/microsoft-teams-app-privacy-policy)》和《[Flashduty Microsoft Teams 应用使用条款](/zh/compliance/microsoft-teams-app-terms-of-use)》。
+
+Flashduty Teams 应用只在发送告警通知、完成关联配置和处理故障卡片操作所需的范围内处理 Teams 数据。
+
+| 数据或能力 | 使用场景 |
+| --- | --- |
+| Teams 用户 ID、Microsoft Entra ID(AAD Object ID) | 关联 Teams 用户与 Flashduty 用户;校验故障卡片操作人;向关联用户发送个人通知或操作反馈 |
+| Team ID、Team 名称、Channel ID | 关联 Teams 团队或频道;把告警和故障通知发送到指定 Teams 频道;查询指定 Team 的详情和频道列表 |
+| Group Chat ID、用户输入的 Chat 名称 | 关联 Teams 群聊;把告警和故障通知发送到指定群聊 |
+| Conversation ID、Activity ID、Bot Framework 会话引用 | 在应用安装后发送、更新或回复 Teams 通知卡片 |
+| Bot 指令和卡片动作 | 处理 `help`、`linkUser`、`linkTeam`、`linkChat` 指令,以及认领、解决、暂缓、自定义操作等卡片按钮 |
+| Flashduty 告警和故障卡片数据 | 在 Teams 中展示告警或故障详情,并把卡片操作结果同步回 Flashduty |
+
+Flashduty Teams 应用不会读取与 Flashduty 功能无关的普通 Teams 聊天内容。它只处理个人聊天中发送给 bot 的消息、团队或群聊中 @ bot 的消息、卡片按钮动作、应用安装和会话所需的引用信息,以及发送或更新 Flashduty 通知所需的数据。
+
+当前应用包不申请用于读取全组织聊天内容的 Microsoft Graph 权限。如后续版本引入新的 Teams 权限或数据处理场景,Flashduty 将更新本文档和相关隐私说明。
+
+## 常见问题
<AccordionGroup>
<Accordion title="团队或个人收不到消息?">
diff --git a/zh/on-call/integration/instant-messaging/slack.mdx b/zh/on-call/integration/instant-messaging/slack.mdx
index dbf52699..12d871aa 100644
--- a/zh/on-call/integration/instant-messaging/slack.mdx
+++ b/zh/on-call/integration/instant-messaging/slack.mdx
@@ -6,13 +6,62 @@ keywords: ["Slack", "即时消息", "告警通知", "IM集成", "协作工具"]
<Tip>**版本要求**:IM 集成需要 On-call 专业版及以上订阅。[了解更多](https://flashcat.cloud/flashduty/price/)</Tip>
+<span id="install-app"></span>
+
+## 安装应用
+
+<Steps>
+<Step title="添加集成">
+访问 Flashduty On-call 集成中心 → 即时消息 → **Slack**,点击 **添加**。
+</Step>
+
+<Step title="授权应用">
+在跳转的 Slack 页面,于右上角选择 **工作区**,然后点击 **允许**。
+
+
+</Step>
+
+<Step title="保存配置">
+输入数据源名称,点击 **保存**。
+</Step>
+</Steps>
+
+## 配置作战室
+
+完成先前步骤后,在 Flashduty On-call 集成配置页面的 **增强功能** 模块,勾选 **开启作战室** 即可启用该功能,无需额外配置。
+
+## AI SRE 控制项
+
+在 **增强功能** 中分别配置以下 AI SRE 控制项,默认均为开启:
+
+- **自动发起 AI 故障分析**:开启作战室后可配置;作战室创建成功后,自动发起一次 AI 故障分析。
+- **允许在 IM 中使用 AI SRE**:无需开启作战室即可配置。开启后,可在已接入的 Slack 群聊中 @ AI SRE、使用 `/fd` 命令,或在机器人私聊中直接发起对话;关闭后这三种入口都不会触发 AI SRE 回复。
+- **普通群聊中 AI SRE 使用话题回复**:无需开启作战室即可配置。开启后,普通群聊中的每个话题对应一个独立 Session;作战室仍直接在群内回复。
+
+如果账户尚未启用 AI SRE,以上配置暂不生效。
+
+## 关联用户
+
+在集成详情页的 **关联用户** 页签中,您可以查看团队成员与 Slack 账号的关联状态,并快速完成批量关联。
+
+### 查看关联状态
+
+列表展示所有团队成员及其关联状态,可按 **全部 / 已关联 / 未关联** 筛选,也可按名称或邮箱搜索。
+
+### 一键关联
+
+当存在未关联的成员时,可以点击 **一键关联** 按钮。系统将尝试通过手机号或邮箱换取 Slack 开放平台的账号 ID 并自动关联,效果等同于成员使用相同信息在 Slack 平台登录 Flashduty。
+
+<Tip>
+成员完成关联后,系统才能向其推送 Slack 消息通知。如果关联失败,请确认成员的邮箱是否与 Slack 账号一致。
+</Tip>
+
<span id="aisre-permissions"></span>
<span id="war-room-scope"></span>
-<span id="install-app"></span>
-## AISRE 所需权限
+## 所需权限
-以下为 Slack IM 集成在开启 AISRE(包含基础通知、作战室、AI SRE 对话、AI 生成复盘和故障通知分派)时需要授予的完整权限清单。进入 Slack 应用 **OAuth & Permissions** 页面时,请确认已授权以下官方 scope 名称。对于已授权的 Slack 集成,如缺少权限,请重新授权。
+安装应用时,Flashduty 会通过 OAuth 一次性请求以下 scope,覆盖基础通知、作战室、AI SRE 对话、AI 生成复盘和故障通知分派,通常无需手动配置。较早授权的集成如缺少权限,请在集成配置页 **重新授权**。
### Bot Token Scopes
@@ -76,71 +125,13 @@ keywords: ["Slack", "即时消息", "告警通知", "IM集成", "协作工具"]
如果您使用的是 Slack Incoming Webhook 方式的 Slack 机器人通知,而不是本页的 Slack App 集成,请在对应 Slack 应用中开启 Incoming Webhooks,并在 OAuth 流程中包含 `incoming-webhook` scope。
</Note>
-## 一、安装应用
-
-<Steps>
-<Step title="添加集成">
-访问 Flashduty On-call 集成中心 → 即时消息 → **Slack**,点击 **添加**。
-</Step>
-
-<Step title="授权应用">
-在跳转的 Slack 页面,于右上角选择 **工作区**,然后点击 **允许**。
-
-
-</Step>
-
-<Step title="保存配置">
-输入数据源名称,点击 **保存**。
-</Step>
-</Steps>
-
-## 二、配置作战室
-
-> 确保应用已被授权使用页面开头列出的 [AISRE 所需权限](#aisre-permissions)。
-
-完成先前步骤后,在 Flashduty On-call 集成配置页面的 **增强功能** 模块,勾选 **开启作战室** 即可启用该功能,无需额外配置。
-
-### AI SRE 控制项
-
-在 **增强功能** 中分别配置以下 AI SRE 控制项,默认均为开启:
-
-- **自动发起 AI 故障分析**:开启作战室后可配置;作战室创建成功后,自动发起一次 AI 故障分析。
-- **允许在 IM 中使用 AI SRE**:无需开启作战室即可配置。开启后,可在已接入的 Slack 群聊中 @ AI SRE、使用 `/fd` 命令,或在机器人私聊中直接发起对话;关闭后这三种入口都不会触发 AI SRE 回复。
-- **普通群聊中 AI SRE 使用话题回复**:无需开启作战室即可配置。开启后,普通群聊中的每个话题对应一个独立 Session;作战室仍直接在群内回复。
-
-如果账户尚未启用 AI SRE,以上配置暂不生效。
-
-## 三、关联用户
-
-在集成详情页的 **关联用户** 页签中,你可以查看团队成员与 Slack 账号的关联状态,并快速完成批量关联。
-
-### 查看关联状态
-
-关联用户列表展示所有团队成员及其关联状态。你可以通过以下方式筛选:
-
-| 筛选项 | 说明 |
-| :--- | :--- |
-| **全部** | 查看所有团队成员 |
-| **已关联** | 仅查看已完成 Slack 账号关联的成员 |
-| **未关联** | 仅查看尚未关联 Slack 账号的成员 |
-
-支持通过名称或邮箱搜索成员。
-
-### 一键关联
-
-当存在未关联的成员时,可以点击 **一键关联** 按钮。系统将尝试通过手机号或邮箱换取 Slack 开放平台的账号 ID 并自动关联,效果等同于成员使用相同信息在 Slack 平台登录 Flashduty。
-
-<Tip>
-成员完成关联后,系统才能向其推送 Slack 消息通知。如果关联失败,请确认成员的邮箱是否与 Slack 账号一致。
-</Tip>
-
-## 四、常见问题
+## 常见问题
<AccordionGroup>
<Accordion title="作战室功能的注意事项?">
- 同一时间仅支持在一个 IM 集成中开启作战室功能。如果您已在其他 IM 集成(如钉钉、飞书、企业微信)中启用了作战室,需要先在该集成中关闭后,才能在当前 Slack 集成中开启
- 开启作战室时,系统会自动验证当前 Slack 应用是否具备作战室所需的全部权限。如果检测到缺少必要权限,页面会显示一条警告提示,并提供 **重新授权** 链接
-- 点击 **重新授权** 链接后,系统会跳转到 Slack 授权页面,请求页面开头列出的 [AISRE 所需权限](#aisre-permissions)。完成授权后,页面会自动返回 Flashduty
+- 点击 **重新授权** 链接后,系统会跳转到 Slack 授权页面,请求[所需权限](#aisre-permissions)。完成授权后,页面会自动返回 Flashduty
- 如果您的 Slack 集成是在作战室功能上线之前完成授权的,首次开启时通常需要重新授权以补充新增权限。重新授权不会影响已有的集成配置和用户关联
</Accordion>
@@ -155,33 +146,22 @@ keywords: ["Slack", "即时消息", "告警通知", "IM集成", "协作工具"]
- 参考上一问题的方法,将应用添加到频道中
</Accordion>
-<Accordion title="点击授权时的「允许」按钮后报错?">
-请重新操作。这可能是由于服务器与 Slack 通信异常导致授权失败。请返回添加数据源页面重试。如果重试后仍然报错,请联系客服。
-</Accordion>
-
-<Accordion title="点击「保存」按钮后报错?">
-请重新操作。这可能是由于 Flashduty 服务器在获取永久授权码时与 Slack 通信异常。请返回添加数据源页面重试。如果重试后仍然报错,请联系客服。
-</Accordion>
-
-<Accordion title="Slack App 提示 not_authed 错误?">
-请重新操作,这可能是 Slack 服务暂时出现问题。如果重试后仍然报错,请联系客服。
-</Accordion>
-
-<Accordion title="Slack App 提示 Operation timed out 错误?">
-请重新操作。这可能是服务器与 Slack 通信超时。如果重试后仍然报错,请联系客服。
-</Accordion>
+<Accordion title="授权、保存或使用 Slack App 时报错?">
+先重试一次;仍报错请联系客服。常见原因:
-<Accordion title="Slack App 提示 Status Code 500 错误?">
-请重新操作。这可能是 Flashduty On-call 服务端出现错误(例如,数据源被关闭)。如果重试后仍然报错,请联系客服。
-</Accordion>
-
-<Accordion title="Slack App 提示其他未知错误?">
-请重新操作。如果重试后仍然报错,请联系客服以记录和解决新问题。
+| 报错场景 | 可能原因 |
+| :--- | :--- |
+| 点击授权页的 **允许** 后报错 | 服务器与 Slack 通信异常导致授权失败,请返回添加数据源页面重试 |
+| 点击 **保存** 后报错 | Flashduty 获取永久授权码时与 Slack 通信异常,请返回添加数据源页面重试 |
+| `not_authed` | Slack 服务暂时异常 |
+| `Operation timed out` | 服务器与 Slack 通信超时 |
+| `Status Code 500` | Flashduty On-call 服务端错误(例如数据源被关闭) |
+| 其他未知错误 | 请联系客服记录并解决 |
</Accordion>
<Accordion title="为什么作战室功能未按预期工作?">
-- 请再次检查是否为应用配置了页面开头列出的 [AISRE 所需权限](#aisre-permissions)
-- 对于之前授权的 Slack IM 集成,需要您在 Flashduty On-call 集成配置页中对 Slack 手动进行重新授权,以使应用获得 AISRE 所需权限
+- 请再次检查是否为应用配置了[所需权限](#aisre-permissions)
+- 对于之前授权的 Slack IM 集成,需要您在 Flashduty On-call 集成配置页中对 Slack 手动进行重新授权,以使应用获得 AI SRE 所需权限
- 请参考 [作战室介绍文档](/zh/on-call/advanced/war-room) 的 **常见问题** 部分
</Accordion>
</AccordionGroup>
diff --git a/zh/on-call/integration/instant-messaging/wecom.mdx b/zh/on-call/integration/instant-messaging/wecom.mdx
index d492e893..044f5b6e 100644
--- a/zh/on-call/integration/instant-messaging/wecom.mdx
+++ b/zh/on-call/integration/instant-messaging/wecom.mdx
@@ -6,27 +6,21 @@ keywords: ["企业微信", "WeCom", "即时消息", "告警通知", "IM集成"]
<Tip>**版本要求**:IM 集成需要 On-call 专业版及以上订阅。[了解更多](https://flashcat.cloud/flashduty/price/)</Tip>
-本文档支持 [集成第三方应用](#third-party) 或 [集成企业自建应用](#self) 两种方式。
+支持 [集成第三方应用](#third-party) 和 [集成企业自建应用](#self) 两种方式,按需选择其一即可。作战室和群聊 @ AI SRE 仅支持企业自建应用。
<div className="hide">
{/*
## 视频介绍
----
-
<Video src="https://download.flashcat.cloud/flashduty/video/wechat.mp4"></Video>
*/}
</div>
-<Note>
-**集成第三方应用** 和 **集成自建应用** 两种方式只需按需配置其中一种。
-</Note>
-
<span id="third-party"></span>
-## 一、集成第三方应用
+## 集成第三方应用
<Info>
Flashduty 作为企业微信服务商,为您提供 Flashduty 应用的长期免费版本。该应用需要获得企业微信接口调用许可才能使用(免密登录 + 消息发送)。该许可目前支持 **最多 60 天** 免费,超出该使用时长后,Flashduty 需要为您购买企业微信许可,您方可继续使用。
@@ -34,33 +28,33 @@ Flashduty 作为企业微信服务商,为您提供 Flashduty 应用的长期
1. 访问 [企业微信管理后台](https://work.weixin.qq.com/wework_admin/frame#apps),进入 应用管理 → **应用** 页面,点击 **添加第三方应用**。
- 
+ 
2. 在搜索栏输入 `Flashduty`,检索到应用后,点击 **添加** 按钮。
- 
+ 
3. 修改应用 **可见范围**,推荐选择全员或具体部门节点,以避免新增企业成员时仍需修改。然后,点击 **同意以上授权并添加** 完成安装。
- 
+ 
4. 访问 [企业微信管理后台](https://work.weixin.qq.com/wework_admin/frame#apps),进入 **我的企业** 页面,获取 `企业 ID`。
- 
+ 
5. 返回 Flashduty On-call 集成配置页面,填写上一步获取的 `企业 ID`,点击 **保存** 完成集成。
<span id="self"></span>
-## 二、集成企业自建应用
+## 集成企业自建应用
1. 访问 [企业微信管理后台](https://work.weixin.qq.com/wework_admin/frame#apps),进入 应用管理 → **应用** 页面,点击 **创建应用**。
- 
+ 
2. 配置 **应用 Logo**、**应用名称** 和 **应用可见范围**。
- 
+ 
3. 返回 Flashduty On-call 集成配置页面,根据您的实际情况选择企业微信是否为 `非私有化部署版本`。
@@ -72,41 +66,47 @@ Flashduty 作为企业微信服务商,为您提供 Flashduty 应用的长期
6. 在应用详情页,获取 `Secret`,并将其填写至 Flashduty On-call 集成配置页面。
-7. 在应用详情页,进入 **网页授权及 JS-SDK** 页面,点击 **设置可信域名**,并按要求配置。
+7. 在应用详情页,进入 **网页授权及 JS-SDK** 页面,点击 **设置可信域名**。该域名需指向 Flashduty On-call 的后端地址 `{api_host}`(可通过 CNAME 或代理转发实现),要求详见企业微信官方文档 [《企业内部开发配置域名指引》](https://open.work.weixin.qq.com/wwopen/common/readDocument/40754)。
-<Note>
-可信域名需要指向 Flashduty On-call 的后端地址 `{api_host}`(可通过 CNAME 或代理转发实现)。关于可信域名的要求,详见企业微信官方文档 [《企业内部开发配置域名指引》](https://open.work.weixin.qq.com/wwopen/common/readDocument/40754)。
-</Note>
-
-
+ 
返回 Flashduty On-call 集成配置页面,填写该域名,并完成验证。
8. 在应用详情页,进入 **接收消息** 页面,并 **设置 API 接收**。分别对 `Token` 和 `EncodingAESKey` 点击 **随机获取**,然后复制并保存所生成的值。
- 
+ 
返回 Flashduty On-call 集成配置页面,填写已保存的 `Token` 和 `EncodingAESKey`,点击 **保存** 完成集成。
9. 复制 Flashduty On-call 集成详情页中的 `回调地址`,返回企业微信刚才的 **接收消息** 页面。在 **API 接收** 设置中,填入该 `回调地址` 以及上一步保存的 `Token` 和 `EncodingAESKey`,然后点击 **保存**。
- 
+ 
-10. 配置**前端可信域名**
+10. 配置 **前端可信域名**,指向 Flashduty On-call 的前端地址 `console.flashcat.cloud`(可通过 CNAME 或代理转发实现)。校验通过后,将生成的 **主页地址** 配置为企业微信应用的 **工作台应用主页**。
-<Note>
-可信域名需要指向 Flashduty On-call 的前端地址 `console.flashcat.cloud`(可通过 CNAME 或代理转发实现)。关于可信域名的要求,详见企业微信官方文档 [《企业内部开发配置域名指引》](https://open.work.weixin.qq.com/wwopen/common/readDocument/40754)。
-</Note>
+ 
+
+11. 配置 **可信 IP 地址**:`47.93.12.134`。
+
+ 
+
+## 关联用户
-前端可信域名校验通过后将生成的**主页地址**配置到企微应用的**工作台应用主页**
+在集成详情页的 **关联用户** 页签中,您可以查看团队成员与企业微信账号的关联状态,并快速完成批量关联。
-
+### 查看关联状态
+
+列表展示所有团队成员及其关联状态,可按 **全部 / 已关联 / 未关联** 筛选,也可按名称或邮箱搜索。
+
+### 一键关联
-11. 配置**可信 IP 地址**:`47.93.12.134`
+当存在未关联的成员时,可以点击 **一键关联** 按钮。系统将尝试通过手机号或邮箱换取企业微信开放平台的账号 ID 并自动关联,效果等同于成员使用相同信息在企业微信平台登录 Flashduty。
-
+<Tip>
+成员完成关联后,系统才能向其推送企业微信消息通知。如果关联失败,请确认成员的手机号或邮箱是否与企业微信账号一致。
+</Tip>
-## 三、配置作战室
+## 配置作战室
<Warning>
作战室功能仅支持在 **企业自建应用** 模式下开启。
@@ -115,10 +115,10 @@ Flashduty 作为企业微信服务商,为您提供 Flashduty 应用的长期
完成先前步骤后,在 Flashduty On-call 集成配置页面的 **增强功能** 模块,勾选 **开启作战室** 即可启用该功能,无需额外配置。
<Warning>
-同一时间仅支持在一个 IM 集成中开启作战室功能。如果你已在其他 IM 集成(如钉钉、飞书、Slack)中启用了作战室,需要先在该集成中关闭后,才能在当前企业微信集成中开启。
+同一时间仅支持在一个 IM 集成中开启作战室功能。如果您已在其他 IM 集成(如钉钉、飞书、Slack)中启用了作战室,需要先在该集成中关闭后,才能在当前企业微信集成中开启。
</Warning>
-### AI SRE 控制项
+## AI SRE 控制项
以下 AI SRE 控制项在集成配置页面的 **增强功能** 模块中配置,默认均为开启:
@@ -132,109 +132,48 @@ Flashduty 作为企业微信服务商,为您提供 Flashduty 应用的长期
| **企业自建应用** | 支持 | 支持 |
| **第三方应用** | 不支持,需切换为 **企业自建应用** 模式 | 支持 |
-第三方应用模式下,该开关的说明文案为「开启后,可在机器人私聊中直接发起对话;群聊 @ AI SRE 仅企业自建应用支持」。
-
如果账户尚未启用 AI SRE,以上配置暂不生效。
-## 四、配置 AISRE
+## 配置 AI SRE 智能机器人
-如需在企业微信中使用 AISRE,请在 Flashduty 企业微信集成中确认 **允许在 IM 中使用 AI SRE** 已开启(无需开启作战室),然后额外创建一个智能机器人,并使用 API 模式接入 Flashduty。智能机器人的凭据在 **企业自建应用** 模式的集成配置页面填写。
-
-1. 在企业微信应用左侧进入 **工作台**,找到 **智能机器人**,进入机器人管理页面。
-2. 创建一个新的智能机器人,创建方式选择 **手动创建**,然后选择 **使用 API 模式创建**。
+在企业微信单聊或群聊中 @ 智能机器人,即可发起 AI SRE 排障会话,无需离开企业微信。智能机器人只能在 **企业自建应用** 模式下配置。
<Note>
-建议由企业内部成员创建智能机器人。即使可见范围设置为 **企业内部全体成员**,其他成员仍需要创建者通过分享后才能看到该机器人。
+- 账户需已开通 AI SRE,且 Flashduty 企业微信集成中的 **允许在 IM 中使用 AI SRE** 已开启(无需开启作战室)。未开通时,机器人收到消息后不会响应。
+- 集成配置页的 **可信域名** 需先填写并校验通过,页面才会生成智能机器人的回调 URL。
</Note>
-3. 在智能机器人的 **API 配置** 页面,连接方式选择 **使用 URL 回调**,并填入 Flashduty 集成配置页提供的 `URL`。
-4. 在企业微信智能机器人的 API 配置页中生成 `Token` 和 `Encoding-AESKey`,并将相同的值填写到 Flashduty 企业微信集成配置页。请确保企业微信和 Flashduty 中的 `Token`、`Encoding-AESKey` 完全一致,然后分别保存两边配置。
-
<Warning>
-企业微信暂不支持在创建作战室后自动将智能机器人拉入群聊。使用 AISRE 时,需要手动将智能机器人添加到对应作战室群聊中。
+智能机器人使用**独立的一套凭据**(Token 和 Encoding-AESKey),与 [集成企业自建应用](#self) 中 **接收消息** 的 Token / EncodingAESKey 不同。两套凭据混用会导致签名验证失败。
</Warning>
-## 五、关联用户
-
-在集成详情页的 **关联用户** 页签中,你可以查看团队成员与企业微信账号的关联状态,并快速完成批量关联。
-
-### 查看关联状态
-
-关联用户列表展示所有团队成员及其关联状态。你可以通过以下方式筛选:
-
-| 筛选项 | 说明 |
-| :--- | :--- |
-| **全部** | 查看所有团队成员 |
-| **已关联** | 仅查看已完成企业微信账号关联的成员 |
-| **未关联** | 仅查看尚未关联企业微信账号的成员 |
-
-支持通过名称或邮箱搜索成员。
-
-### 一键关联
-
-当存在未关联的成员时,可以点击 **一键关联** 按钮。系统将尝试通过手机号或邮箱换取企业微信开放平台的账号 ID 并自动关联,效果等同于成员使用相同信息在企业微信平台登录 Flashduty。
-
-<Tip>
-成员完成关联后,系统才能向其推送企业微信消息通知。如果关联失败,请确认成员的手机号或邮箱是否与企业微信账号一致。
-</Tip>
-
-## 六、集成企微智能体(AI SRE)
-
-企微智能体(AI Bot)是企业微信提供的 AI 对话机器人功能。通过将 Flashduty AI SRE 与企微智能体对接,您的团队可以在企微单聊或群聊中直接通过 @ 智能体发起 AI 故障排查会话,无需离开企业微信。
+<Steps>
+ <Step title="在企业微信中创建智能机器人">
+ 在企业微信应用左侧进入 **工作台**,找到 **智能机器人**,进入机器人管理页面。新建一个智能机器人,创建方式选择 **手动创建**,然后选择 **使用 API 模式创建**。
+
+ 建议由企业内部成员创建:即使可见范围设为 **企业内部全体成员**,其他成员也要等创建者分享后才能看到该机器人。
+ </Step>
+ <Step title="填写回调 URL">
+ 在智能机器人的 **API 配置** 页面,连接方式选择 **使用 URL 回调**,填入 Flashduty 企业微信集成配置页 **智能机器人配置** 区域提供的 `URL`,格式为:
+
+ ```
+ https://<可信域名>/event/push/wecom/bot?integration_key=<integration_key>
+ ```
+
+ 企业微信会向该地址发送一次 GET 请求做 URL 验证(echostr 校验),Flashduty 会自动完成应答。
+ </Step>
+ <Step title="同步 Token 和 Encoding-AESKey">
+ 在企业微信智能机器人的 API 配置页中生成 `Token` 和 `Encoding-AESKey`,将相同的值填写到 Flashduty 集成配置页的 **智能机器人配置** 区域。确保两边的值完全一致,然后分别保存两边配置。
+ </Step>
+</Steps>
<Warning>
-智能体集成使用**独立于普通应用的凭据**(Bot Token 和 Bot EncodingAESKey)。请勿将 [集成企业自建应用](#self) 步骤 8 中生成的 Token / EncodingAESKey 填入此处——两套凭据彼此独立,混用将导致签名验证失败。
+企业微信暂不支持在创建作战室后自动将智能机器人拉入群聊。要在作战室中使用 AI SRE,需要手动将智能机器人添加到对应群聊。
</Warning>
-<Note>
-AI SRE 功能需要账户开通对应权限。如未开通,企微智能体收到消息后将不作任何响应。
-</Note>
-
-### 配置步骤
-
-<Steps>
-
-<Step title="在企业微信管理后台创建智能体">
-
-访问 [企业微信管理后台](https://work.weixin.qq.com/wework_admin/frame#apps),进入 **应用管理 → AI 助理** 页面,点击 **创建 AI 助理**(智能体),完成基础信息配置(名称、头像、可见范围)。
-
-</Step>
-
-<Step title="获取 Bot Token 和 EncodingAESKey">
-
-进入已创建智能体的详情页,找到 **接收消息** 配置区域,分别对 `Token` 和 `EncodingAESKey` 点击 **随机生成**,然后复制并妥善保存这两个值。
-
-这两个值仅属于该智能体,与您在企业微信自建应用中配置的 Token / EncodingAESKey **完全不同**。
-
-</Step>
-
-<Step title="在 Flashduty 集成配置页填写智能体凭据">
-
-返回 Flashduty On-call 企业微信集成详情页,在 **AI SRE 智能体** 配置区域,将上一步获得的 `Bot Token` 和 `Bot EncodingAESKey` 分别填入对应字段,点击 **保存**。
-
-保存成功后,页面会显示该集成的 `integration_key`(即集成密钥)。
-
-</Step>
-
-<Step title="配置智能体的回调地址">
-
-复制 Flashduty On-call 集成详情页中的 **智能体回调地址**,格式为:
-
-```
-https://<your-api-host>/event/push/wecom/bot?integration_key=<integration_key>
-```
-
-返回企业微信管理后台,进入该智能体的 **接收消息** 设置,将回调地址、Token 和 EncodingAESKey 填入对应字段,点击 **保存**。
-
-企业微信会向该地址发送一次 GET 请求进行 URL 验证(echostr 校验),Flashduty 服务器会自动完成验证应答。
-
-</Step>
-
-</Steps>
-
### 使用方式
-配置完成后,在企微单聊或群聊中 **@ 您的智能体**,输入问题或故障描述,即可触发 AI SRE 会话。智能体支持以下消息类型:
+配置完成后,在企微单聊或群聊中 **@ 智能机器人**,输入问题或故障描述,即可触发 AI SRE 会话。支持以下消息类型:
| 类型 | 说明 |
| :--- | :--- |
@@ -244,34 +183,34 @@ https://<your-api-host>/event/push/wecom/bot?integration_key=<integration_key>
| **引用回复** | 引用上一条消息追问,AI 会结合上下文作答 |
<Note>
-企业微信智能体采用**拉取式流式响应**(stream polling):AI 生成回复时,企业微信客户端会定期向回调地址发送 `msgtype=stream` 请求拉取最新内容,直到 AI 回复完成。这是企业微信智能体的平台机制,用户无需额外配置。
+企业微信智能机器人采用**拉取式流式响应**(stream polling):AI 生成回复时,企业微信客户端会定期向回调地址发送 `msgtype=stream` 请求拉取最新内容,直到回复完成。这是企业微信的平台机制,无需额外配置。
</Note>
-### 常见问题
+### 排查问题
<AccordionGroup>
-<Accordion title="智能体收到消息后没有任何响应">
+<Accordion title="机器人收到消息后没有任何响应">
请按以下顺序排查:
-1. 确认账户已开通 AI SRE 功能权限
-2. 确认回调地址中的 `integration_key` 与 Flashduty 集成详情页显示的值完全一致
-3. 确认 Flashduty 集成配置页中填写的 `Bot Token` 和 `Bot EncodingAESKey` 与智能体详情页 **接收消息** 中的值一致,而非来自企业微信自建应用
-4. 在企业微信管理后台查看智能体的回调日志,确认请求是否到达以及是否有错误码
+1. 确认账户已开通 AI SRE,且集成中的 **允许在 IM 中使用 AI SRE** 已开启
+2. 确认回调 URL 中的 `integration_key` 与 Flashduty 集成详情页显示的值完全一致
+3. 确认 Flashduty 中填写的 `Token` 和 `Encoding-AESKey` 来自智能机器人的 **API 配置** 页,而非企业自建应用的 **接收消息**
+4. 在企业微信中查看该机器人的回调记录(如有),确认请求是否到达以及是否有错误码
</Accordion>
-<Accordion title="配置回调地址时提示「URL 验证失败」">
-- 确认 Flashduty 服务能够被企业微信服务器正常访问(公网可达)
-- 确认填写的 `Token` 和 `EncodingAESKey` 与 Flashduty 集成配置页中保存的值完全一致
-- 确认回调地址中的 `integration_key` 参数正确,且对应的集成处于启用状态
+<Accordion title="配置回调 URL 时提示「URL 验证失败」">
+- 确认 Flashduty 服务能够被企业微信服务器正常访问(公网可达),且可信域名已校验通过
+- 确认填写的 `Token` 和 `Encoding-AESKey` 与 Flashduty 集成配置页中保存的值完全一致
+- 确认回调 URL 中的 `integration_key` 参数正确,且对应的集成处于启用状态
</Accordion>
-<Accordion title="智能体签名验证失败(invalid signature)">
-这通常意味着 Bot Token 或 Bot EncodingAESKey 填写有误。请注意:智能体的 Token / EncodingAESKey 与企业微信自建应用(普通 IM 集成)的 Token / EncodingAESKey **是两套独立凭据**,请在智能体详情页的 **接收消息** 区域重新生成并更新至 Flashduty 集成配置。
+<Accordion title="签名验证失败(invalid signature)">
+通常是 `Token` 或 `Encoding-AESKey` 填写有误。智能机器人的凭据与企业自建应用 **接收消息** 的凭据是**两套独立凭据**,请在智能机器人的 **API 配置** 页重新生成,并同步更新到 Flashduty 集成配置。
</Accordion>
</AccordionGroup>
-## 七、常见问题
+## 常见问题
<AccordionGroup>
<Accordion title="点击集成保存按钮后,系统报错「authorize app first」?">
@@ -294,7 +233,7 @@ https://<your-api-host>/event/push/wecom/bot?integration_key=<integration_key>
自定义区域最多可展示 8 行,超出部分将被企业微信截断。
</Note>
-
+
</Accordion>
<Accordion title="如何在企业微信内处理告警?">
diff --git a/zh/on-call/integration/sso/keycloak.mdx b/zh/on-call/integration/sso/keycloak.mdx
index d95a999f..1d2ac83c 100644
--- a/zh/on-call/integration/sso/keycloak.mdx
+++ b/zh/on-call/integration/sso/keycloak.mdx
@@ -19,13 +19,13 @@ Keycloak 是一个开源的身份和访问管理解决方案,提供了一套
登录 Flashduty 控制台,获取 ACS 地址(后续步骤会用到)。
-路径:**访问控制 => 单点登录 => SAML2.0 协议 => Flashduty 服务提供商信息 => Assertion Consumer Service URL**
+路径:**访问控制 → 单点登录 → SAML2.0 协议 → Flashduty 服务提供商信息 → Assertion Consumer Service URL**

### 2. 创建 Client
-登录 Keycloak 控制台,路径:**Clients => Create client**
+登录 Keycloak 控制台,路径:**Clients → Create client**
- **Client Type**:选择 SAML 协议
- **Client ID**:填写 `flashcat.cloud`(固定值,不可更改)
@@ -80,7 +80,7 @@ Keycloak 是一个开源的身份和访问管理解决方案,提供了一套
下载的文件是一个压缩包,在本地解压后会有两个 xml 文件,只需要 `idp-metadata.xml` 文件即可。
</Note>
-在 **Client => Action** 中下载到本地:
+在 **Client → Action** 中下载到本地:

@@ -106,7 +106,7 @@ Keycloak 是一个开源的身份和访问管理解决方案,提供了一套
登录 Flashduty 控制台,获取 Redirect URL(后续步骤会用到)。
-路径:**访问控制 => 单点登录 => OIDC 协议 => Flashduty 服务提供商信息 => Redirect URL**
+路径:**访问控制 → 单点登录 → OIDC 协议 → Flashduty 服务提供商信息 → Redirect URL**

@@ -130,11 +130,11 @@ Keycloak 是一个开源的身份和访问管理解决方案,提供了一套
### 3. 获取 Client 相关信息
- **Client ID**:创建 Client 时填写的 ID
-- **Client Secret**:在 **Client 详情 => Credentials** 卡片中查看
+- **Client Secret**:在 **Client 详情 → Credentials** 卡片中查看

-- **Issuer**:在 **Realm settings => Endpoints => OpenID Endpoint Configuration** 中查看
+- **Issuer**:在 **Realm settings → Endpoints → OpenID Endpoint Configuration** 中查看

diff --git a/zh/on-call/integration/sso/openldap.mdx b/zh/on-call/integration/sso/openldap.mdx
index b97f83fb..00e2a207 100644
--- a/zh/on-call/integration/sso/openldap.mdx
+++ b/zh/on-call/integration/sso/openldap.mdx
@@ -122,7 +122,7 @@ docker compose down

<Note>
-在 **用户路径**(例如上图 `ou=people` 下的 `cn=flash duty`)=> **Add new attribute** => 选择 **Email**,为用户添加 Email 属性。若已存在请忽略。
+在 **用户路径**(例如上图 `ou=people` 下的 `cn=flash duty`) → **Add new attribute** → 选择 **Email**,为用户添加 Email 属性。若已存在请忽略。
</Note>
## Flashduty 集成
diff --git a/zh/on-call/integration/sso/role-team-sync.mdx b/zh/on-call/integration/sso/role-team-sync.mdx
index 167dbfe1..0558b09a 100644
--- a/zh/on-call/integration/sso/role-team-sync.mdx
+++ b/zh/on-call/integration/sso/role-team-sync.mdx
@@ -6,17 +6,25 @@ keywords: ["SSO", "单点登录", "角色同步", "团队同步", "同步配置"
在 **平台管理 → 单点登录** 的设置页面中,「同步配置」分区决定成员通过 SSO 登录时如何获得 Flashduty 中的角色与团队:
-- **SAML2.0 / OIDC / CAS**:按身份提供商返回的**角色名称 / 团队名称**进行匹配(claim / 属性名方式)。名称未匹配时,只有本次登录实际新建的成员使用**默认角色 / 默认团队**兜底,已有成员保持原值。
+- **SAML2.0 / OIDC / CAS**:按身份提供商返回的**角色名称 / 团队名称**进行匹配(claim / 属性名方式),本文介绍这三种协议。
- **LDAP**:不使用名称匹配,而是按用户所属 **LDAP Group** 的 DN 与映射规则匹配,详见 [LDAP 角色和团队同步](/zh/platform/configure-sso#ldap-角色和团队同步)。
-同步在成员**每次通过 SSO 登录**时触发。本文描述 SAML2.0 / OIDC / CAS 协议的同步配置与匹配规则。
-
<Warning>
**绝大多数情况下,默认角色和默认团队应保持为空,不启用默认兜底。**
-默认值只用于本次登录实际创建、且对应名称未匹配的新成员,不会修改已有成员。但它们是整份 SSO 配置的统一规则:所有符合这些条件的新成员都会获得相同的默认角色或加入相同的默认团队。不要为了登录测试配置通用管理员权限或敏感团队。
+默认值是整份 SSO 配置的统一规则:所有符合条件的新成员都会获得相同的默认角色、加入相同的默认团队。不要为了登录测试配置通用管理员权限或敏感团队。
</Warning>
+## 生效时机与覆盖语义
+
+- 同步开启且名称匹配成功时,成员**每次通过 SSO 登录**都会使用有效映射更新对应角色或团队。
+- 有效映射为**覆盖式**,不是追加:会替换对应的现有数据,包括手工分配的角色或团队,不会与已有数据合并。
+- 没有名称匹配时,只有本次登录实际新建的成员使用有效默认值;已有成员的对应角色或团队保持不变。
+- 没有名称匹配,也没有有效默认值时,不执行该维度的同步:新建成员沿用原有创建流程,已有成员不会被清空角色或团队。
+- 两个同步开关都关闭时,登录不会改动成员的角色与团队。
+
+**首次 SSO 登录不等于新建成员。** 管理员已经创建或邀请的成员,以及首次通过稳定用户 ID 关联到已有成员的情况,都不会使用默认值;只有本次登录通过自动创建成员(JIT)实际新增成员记录时才使用。修改默认值也不会重新分配已有成员的角色或团队。
+
## 同步配置字段
「同步配置」分区包含以下字段:
@@ -27,11 +35,11 @@ keywords: ["SSO", "单点登录", "角色同步", "团队同步", "同步配置"
| 同步团队(`sync_team_enabled`) | 开关。开启后按名称同步团队;关闭时成员登录不会改动团队 |
| 角色字段(`roles`) | 身份提供商返回的**角色名称**所在的 claim / 属性名,如 `roles`。支持字符串或字符串数组;按名称精确匹配 |
| 团队字段(`teams`) | 身份提供商返回的**团队名称**所在的 claim / 属性名,如 `teams`。支持字符串或字符串数组;按名称精确匹配 |
-| 默认角色(`default_role_ids`) | 多选角色(下拉仅列出启用状态的角色)。开启角色同步且返回名称未匹配到任何可用角色时,**仅本次登录新建的成员**同步这些默认角色;已有成员不受影响。**通常留空** |
-| 默认团队(`default_team_ids`) | 多选团队。开启团队同步且返回名称未匹配到任何可用团队时,**仅本次登录新建的成员**同步这些默认团队;已有成员不受影响。**通常留空** |
+| 默认角色(`default_role_ids`) | 多选角色(下拉仅列出启用状态的角色)。仅在开启角色同步、名称未匹配且本次登录新建成员时使用。**通常留空** |
+| 默认团队(`default_team_ids`) | 多选团队。仅在开启团队同步、名称未匹配且本次登录新建成员时使用。**通常留空** |
<Note>
-**角色字段 / 团队字段留空**时不会匹配任何名称:若对应的同步开关已开启,只有本次新建成员可以使用该维度的有效默认值;已有成员保持原值。没有有效默认值时,不执行该维度的同步,不会清空已有角色或团队(见下方 [生效时机与覆盖语义](#生效时机与覆盖语义))。
+**角色字段 / 团队字段留空**时不会匹配任何名称,效果等同于“名称未匹配”,见 [生效时机与覆盖语义](#生效时机与覆盖语义)。
</Note>
默认值没有独立开关,清空对应默认值即可关闭兜底。若不希望 SSO 管理角色或团队,应关闭对应同步开关;仅清空默认值不会阻止有效映射在每次登录时覆盖现有数据。
@@ -61,15 +69,15 @@ keywords: ["SSO", "单点登录", "角色同步", "团队同步", "同步配置"
### 默认角色 / 默认团队兜底
-- 仅当本次登录**实际创建新成员**,且该维度没有任何名称匹配时,才应用有效默认值;角色与团队**各自独立**判断,互不影响。已有成员登录不使用默认值。
+- 角色与团队**各自独立**判断是否兜底;适用条件见 [生效时机与覆盖语义](#生效时机与覆盖语义)。
- 默认角色:预设角色(`Admin` / `Responder` / `Viewer`)始终可用;自定义默认角色必须**存在且处于启用状态**,否则跳过并记录告警日志。
- 默认团队:必须**存在且未被删除**,否则跳过。
- 最终解析出的角色 ID / 团队 ID 会去重并按 ID 升序排列。
<Warning>
-**被选为默认角色或默认团队的角色或团队无法删除。** 删除请求会返回 `ReferenceExist`(该资源仍被其他实体引用,无法删除)错误:角色删除在检查成员绑定之前即被拦截,勾选强制删除(`is_force`)也不会绕过——强制删除仅解除成员绑定,SSO 默认引用必须先取消。须先在该 SSO 配置的**默认角色 / 默认团队**选项中取消选择目标角色或团队并保存,才能删除。
+**被选为默认角色或默认团队的角色或团队无法删除。** 删除会返回 `ReferenceExist` 错误,强制删除(`is_force`)也无法绕过。请先在 SSO 配置的**默认角色 / 默认团队**中取消选择并保存,再删除。
-该检查针对**已保存**的默认值:即使 SSO 或对应同步开关当前关闭,只要配置里仍保留 `default_role_ids` / `default_team_ids`,引用就依然存在——重新启用配置后不能出现悬空的 ID。
+即使 SSO 或对应同步开关当前关闭,只要配置里仍保存着这些默认值,引用就依然存在。
</Warning>
## 各协议取值来源
@@ -88,16 +96,6 @@ keywords: ["SSO", "单点登录", "角色同步", "团队同步", "同步配置"
- **LDAP**:保留 Group 字段、Group DN 映射规则(`role_team_mapping`)与默认角色;`roles`、`teams`、`default_team_ids` 不会被保存。
- **SAML2.0 / OIDC / CAS**:保留 `roles`、`teams`、`default_role_ids`、`default_team_ids`;`group` 与映射规则不会被保存。
-## 生效时机与覆盖语义
-
-- 同步开启且名称匹配成功时,成员**每次通过 SSO 登录**都会使用有效映射更新对应角色或团队。
-- 有效映射为**覆盖式**,不是追加:会替换对应的现有数据,包括手工分配的角色或团队,不会与已有数据合并。
-- 没有名称匹配时,只有本次登录实际新建的成员使用有效默认值;已有成员的对应角色或团队保持不变。
-- 没有名称匹配,也没有有效默认值时,不执行该维度的同步:新建成员沿用原有创建流程,已有成员不会被清空角色或团队。
-- 两个同步开关都关闭时,登录不会改动成员的角色与团队。
-
-**首次 SSO 登录不等于新建成员。** 管理员已经创建或邀请的成员,以及首次通过稳定用户 ID 关联到已有成员的情况,都不会使用默认值;只有本次登录通过自动创建成员(JIT)实际新增成员记录时才使用。修改默认值也不会重新分配已有成员的角色或团队。
-
<CardGroup cols={4}>
<Card title="单点登录配置" icon="shield-check" href="/zh/platform/configure-sso">
各协议接入的整体配置指引
diff --git a/zh/on-call/integration/webhooks/alert-webhook.mdx b/zh/on-call/integration/webhooks/alert-webhook.mdx
index 0eb9096f..6ff7c295 100644
--- a/zh/on-call/integration/webhooks/alert-webhook.mdx
+++ b/zh/on-call/integration/webhooks/alert-webhook.mdx
@@ -10,7 +10,7 @@ keywords: ["告警Webhook", "HTTP回调", "事件通知", "系统集成", "自
<span id="EventTypes"></span>
-## 一、事件类型
+## 事件类型
目前支持以下事件类型,未来可能会增加。
@@ -28,7 +28,7 @@ keywords: ["告警Webhook", "HTTP回调", "事件通知", "系统集成", "自
手动关闭告警当前不会触发 Webhook 回调。
</Note>
-## 二、推送描述
+## 推送描述
### 请求方式
@@ -187,7 +187,7 @@ curl -X POST 'https://example.com/alert/webhook?a=a' \
}' -v
```
-## 三、配置指南
+## 配置指南
进入 **集成中心** → **Webhook** → 添加或编辑 **告警 Webhook** 集成。
@@ -214,9 +214,9 @@ curl -X POST 'https://example.com/alert/webhook?a=a' \
**自定义请求体** 与 **值映射** 仅 **故障 Webhook** 支持,**告警 Webhook** 的推送内容固定为上述 [Payload 结构](#请求-payload),不能重新组织。详见 [故障 Webhook](/zh/on-call/integration/webhooks/incident-webhook) 的 **自定义请求体** 与 **值映射** 章节。
</Note>
-## 四、调用历史
+## 调用历史
-告警 Webhook 提供完整的调用历史记录,方便你排查推送是否成功以及调试回调接口。
+告警 Webhook 提供完整的调用历史记录,方便您排查推送是否成功以及调试回调接口。
### 查看调用历史
@@ -250,7 +250,7 @@ curl -X POST 'https://example.com/alert/webhook?a=a' \
- **Request**:包括 Endpoint、Request Headers 和 Request Payload
- **Response**:成功时显示 Response Headers 和 Response Body;失败时显示 Error Message
-## 五、常见问题
+## 常见问题
1. **服务是否有响应超时时间?**
@@ -258,7 +258,7 @@ curl -X POST 'https://example.com/alert/webhook?a=a' \
2. **推送失败后是否会持续推送?**
- 针对特定的网络错误,会进行重试,最多重试1次:
+ 针对特定的网络错误,会进行重试,最多重试1次:
- context deadline exceeded (排除 awaiting headers)
- i/o timeout
- eof
diff --git a/zh/on-call/integration/webhooks/custom-actions.mdx b/zh/on-call/integration/webhooks/custom-actions.mdx
index 8f9c03d9..76bddd52 100644
--- a/zh/on-call/integration/webhooks/custom-actions.mdx
+++ b/zh/on-call/integration/webhooks/custom-actions.mdx
@@ -1,12 +1,12 @@
---
title: "Webhook 自定义操作"
-sidebarTitle: "自定义操作"
+sidebarTitle: "Webhook 自定义操作"
description: "配置自定义操作,当故障发生特定操作时,系统通过 HTTP 回调您配置的地址"
keywords: ["自定义操作", "HTTP回调", "事件通知", "系统集成", "自动化"]
---
配置故障 自定义操作,允许您在故障排查期间,快速调用外部接口,实现故障自愈、信息丰富等任何自定义操作。
-## 一、创建操作
+## 创建操作
1. 登录 Flashduty 控制台,进入【集成中心-Webhook】
2. 点击添加 自定义操作 集成
@@ -16,7 +16,7 @@ keywords: ["自定义操作", "HTTP回调", "事件通知", "系统集成", "自
6. 配置 Endpoint、自定义 Headers
7. 保存,完成
-## 二、推送描述
+## 推送描述
### 请求方式
@@ -337,7 +337,7 @@ curl -X POST 'https://example.com/incident/action?a=a' \
}' -v
```
-## 三、自定义请求体与值映射
+## 自定义请求体与值映射
### 自定义请求体
@@ -388,7 +388,7 @@ curl -X POST 'https://example.com/incident/action?a=a' \
配合自定义请求体中的 `"severity": "{{incident.incident_severity}}"` 使用,当故障严重程度为 `Critical` 时,推送结果中 `severity` 字段的值为 `P0`。未匹配到映射的值将保持原样。
-## 四、使用场景
+## 使用场景
### 重启主机
@@ -406,7 +406,7 @@ curl -X POST 'https://example.com/incident/action?a=a' \
当确定故障影响到线上服务,可以触发外部 status page 更新,及时的通知到您的客户或上下游。
-## 五、常见问题
+## 常见问题
1. **服务是否有响应超时时间?**
@@ -414,7 +414,7 @@ curl -X POST 'https://example.com/incident/action?a=a' \
2. **推送失败后是否会持续推送?**
- 针对特定的网络错误,会进行重试,最多重试1次:
+ 针对特定的网络错误,会进行重试,最多重试1次:
- context deadline exceeded (排除 awaiting headers)
- i/o timeout
- eof
diff --git a/zh/on-call/integration/webhooks/incident-webhook.mdx b/zh/on-call/integration/webhooks/incident-webhook.mdx
index 3fcbb779..3fa8d202 100644
--- a/zh/on-call/integration/webhooks/incident-webhook.mdx
+++ b/zh/on-call/integration/webhooks/incident-webhook.mdx
@@ -8,7 +8,7 @@ keywords: ["故障Webhook", "HTTP回调", "事件通知", "系统集成", "自
<span id="EventTypes"></span>
-## 一、事件类型
+## 事件类型
目前支持以下事件类型,未来可能会增加。
@@ -43,7 +43,7 @@ keywords: ["故障Webhook", "HTTP回调", "事件通知", "系统集成", "自
</div>
-## 二、推送描述
+## 推送描述
### 请求方式
@@ -425,7 +425,7 @@ curl -X POST 'https://example.com/incident/webhook?a=a' \
}' -v
```
-## 三、配置指南
+## 配置指南
进入 **集成中心** → **Webhook** → 添加或编辑 **故障 Webhook** 集成。
@@ -450,7 +450,7 @@ curl -X POST 'https://example.com/incident/webhook?a=a' \
### 自定义请求体
-默认情况下,系统会按照上述 [Payload 结构](#请求-payload)推送完整的 JSON 数据。如果你的接收方对数据格式有特殊要求,可以通过**自定义请求体**来重新组织推送内容。
+默认情况下,系统会按照上述 [Payload 结构](#请求-payload)推送完整的 JSON 数据。如果您的接收方对数据格式有特殊要求,可以通过**自定义请求体**来重新组织推送内容。
使用 `{{字段路径}}` 语法引用默认 Payload 中的任意字段,系统会在推送时将变量替换为实际值。
@@ -523,9 +523,9 @@ curl -X POST 'https://example.com/incident/webhook?a=a' \
当故障严重程度为 `Critical` 时,推送结果中 `severity` 字段的值为 `P0`。未匹配到映射的值将保持原样。
-## 四、调用历史
+## 调用历史
-故障 Webhook 提供完整的调用历史记录,方便你排查推送是否成功以及调试回调接口。
+故障 Webhook 提供完整的调用历史记录,方便您排查推送是否成功以及调试回调接口。
### 查看调用历史
@@ -559,7 +559,7 @@ curl -X POST 'https://example.com/incident/webhook?a=a' \
- **Request**:包括 Endpoint、Request Headers 和 Request Payload
- **Response**:成功时显示 Response Headers 和 Response Body;失败时显示 Error Message
-## 五、常见问题
+## 常见问题
1. **服务是否有响应超时时间?**
@@ -567,7 +567,7 @@ curl -X POST 'https://example.com/incident/webhook?a=a' \
2. **推送失败后是否会持续推送?**
- 针对特定的网络错误,会进行重试,最多重试1次:
+ 针对特定的网络错误,会进行重试,最多重试1次:
- context deadline exceeded (排除 awaiting headers)
- i/o timeout
- eof
diff --git a/zh/on-call/integration/webhooks/servicedesk-plus-sync.mdx b/zh/on-call/integration/webhooks/servicedesk-plus-sync.mdx
index 34e738f9..b27c4e84 100644
--- a/zh/on-call/integration/webhooks/servicedesk-plus-sync.mdx
+++ b/zh/on-call/integration/webhooks/servicedesk-plus-sync.mdx
@@ -27,10 +27,12 @@ keywords: ["ServiceDesk Plus", "工单同步", "Webhook", "ITSM", "故障关联"
3. `Time Duration` 选择最大的 **10 minutes**,`Scope Description` 填写内容可自定义,比如: Flashduty 同步使用,并创建。
4. 将生成的 **Code** 和 **Client ID** 以及 **Client Secret** 复制备用。
-
-
+
+
-###### 注意:Code 的有效期只有 10 分钟且只能使用一次,所以在获取到 Code 后,请在有效期内尽快完成[集成授权](#集成授权)
+<Note>
+Code 的有效期只有 10 分钟且只能使用一次,所以在获取到 Code 后,请在有效期内尽快完成[集成授权](#集成授权)
+</Note>
### 在 Flashduty On-call
#### 步骤2 集成授权 <span id="集成授权"></span>
@@ -45,7 +47,9 @@ keywords: ["ServiceDesk Plus", "工单同步", "Webhook", "ITSM", "故障关联"
1. 登录 ServiceDesk Plus 控制台,在个人中心点击 `生成 API 密钥`。
2. `令牌过期时间` 选择 **永不过期**,将生成的 **Token** 复制备用,并完成[集成授权](#私有化版本集成授权)。
-###### 注意:生成 API 密钥的用户需要具备相关权限,比如创建/更新请求、获取模版/优先级/自定义字段列表等权限,如果权限不足,会导致无法完成集成配置,建议使用管理员角色生成。
+<Note>
+生成 API 密钥的用户需要具备相关权限,比如创建/更新请求、获取模版/优先级/自定义字段列表等权限,如果权限不足,会导致无法完成集成配置,建议使用管理员角色生成。
+</Note>
### 在 Flashduty On-call
#### 步骤2 集成授权 <span id="私有化版本集成授权"></span>
@@ -121,7 +125,7 @@ keywords: ["ServiceDesk Plus", "工单同步", "Webhook", "ITSM", "故障关联"
```
7. 点击 `Save` 完成配置。
-
+
##### 步骤3 创建触发器
1. 登录 ServiceDesk Plus 控制台,找到 `Setup` 配置页面。
@@ -133,7 +137,7 @@ keywords: ["ServiceDesk Plus", "工单同步", "Webhook", "ITSM", "故障关联"
7. 在 `Actions` 中选择 **Webhook** 并勾选 **to_Flashduty** 通道。
8. 点击 `Save` 完成配置。
-
+
## 同步信息映射关系
@@ -166,7 +170,7 @@ keywords: ["ServiceDesk Plus", "工单同步", "Webhook", "ITSM", "故障关联"
## 调用历史
-ServiceDesk Plus 同步集成提供完整的调用历史记录,方便你排查同步是否成功以及调试接口问题。
+ServiceDesk Plus 同步集成提供完整的调用历史记录,方便您排查同步是否成功以及调试接口问题。
### 查看调用历史
diff --git a/zh/on-call/integration/webhooks/servicenow-sync.mdx b/zh/on-call/integration/webhooks/servicenow-sync.mdx
index e08b378b..526fe4a6 100644
--- a/zh/on-call/integration/webhooks/servicenow-sync.mdx
+++ b/zh/on-call/integration/webhooks/servicenow-sync.mdx
@@ -19,7 +19,7 @@ keywords: ["ServiceNow", "工单同步", "Webhook", "ITSM", "故障关联"]
4. `Password needs reset` 和 `Web service access only` 以及 `Internal Integration User` 保持取消勾选状态。
5. 提交保存。
-
+
### 配置用户
@@ -35,8 +35,8 @@ keywords: ["ServiceNow", "工单同步", "Webhook", "ITSM", "故障关联"]
3. 点击 `Roles` 添加 **personalize_dictionary 和 itil** 角色(如果不需要配置自定义字段映射关系,可以不授予 personalize_dictionary 权限)。
4. 点击 `Update` 更新配置。
-
-
+
+
## 在 Flashduty On-call
diff --git a/zh/on-call/post-mortem/ai-generate-post-mortem.mdx b/zh/on-call/post-mortem/ai-generate-post-mortem.mdx
index 8ed4a9f3..1ced2baa 100644
--- a/zh/on-call/post-mortem/ai-generate-post-mortem.mdx
+++ b/zh/on-call/post-mortem/ai-generate-post-mortem.mdx
@@ -4,11 +4,11 @@ description: "让 AI 根据故障数据自动生成复盘报告初稿,大幅
keywords: ["AI 生成", "智能复盘", "自动生成", "故障分析", "AI 辅助"]
---
-## 让 AI 帮你打初稿
+## 让 AI 帮您打初稿
写复盘报告最难的部分往往是开头:面对空白页面,不知道从哪里下笔。
-Flashduty 的 AI 辅助生成功能可以帮你跨过这一步。它会分析关联故障的所有上下文数据,按照模板的章节结构,自动生成一份内容完整的初稿。你要做的只是在此基础上调整措辞、补充细节、加入团队的讨论结论。
+Flashduty 的 AI 辅助生成功能可以帮您跨过这一步。它会分析关联故障的所有上下文数据,按照模板的章节结构,自动生成一份内容完整的初稿。您要做的只是在此基础上调整措辞、补充细节、加入团队的讨论结论。
<Tip>**版本要求**:此功能需要 On-call 专业版及以上订阅。[了解更多](https://flashcat.cloud/flashduty/price/)</Tip>
@@ -20,7 +20,7 @@ Flashduty 的 AI 辅助生成功能可以帮你跨过这一步。它会分析关
</Step>
<Step title="在初稿基础上完善">
-生成完成后,你可以直接在编辑器中修改、删减或补充内容。团队其他成员也可以同时参与编辑。
+生成完成后,您可以直接在编辑器中修改、删减或补充内容。团队其他成员也可以同时参与编辑。
</Step>
</Steps>
@@ -30,7 +30,7 @@ AI 不是凭空写作,它会深入分析以下数据来生成报告:
| 数据来源 | 说明 |
| :--- | :--- |
-| 模板结构 | 按照你选择的模板章节来组织内容 |
+| 模板结构 | 按照您选择的模板章节来组织内容 |
| 故障详情 | 标签、自定义字段、严重程度、响应人员等 |
| 处理时间线 | 故障处理过程中的操作记录和状态变更|
| 作战室聊天记录 | 飞书或 Slack 群聊中与故障相关的讨论内容 |
@@ -64,4 +64,4 @@ AI 不是凭空写作,它会深入分析以下数据来生成报告:
## 时间显示
-故障复盘报告中涉及的时间信息会自动适配你的时区设置,确保不同地区的团队成员看到的都是本地时间。
+故障复盘报告中涉及的时间信息会自动适配您的时区设置,确保不同地区的团队成员看到的都是本地时间。
diff --git a/zh/on-call/post-mortem/create-edit-post-mortem.mdx b/zh/on-call/post-mortem/create-edit-post-mortem.mdx
index 69535c83..4c778134 100644
--- a/zh/on-call/post-mortem/create-edit-post-mortem.mdx
+++ b/zh/on-call/post-mortem/create-edit-post-mortem.mdx
@@ -16,7 +16,7 @@ keywords: ["创建复盘", "编辑复盘", "协作编辑", "发布复盘", "删
</Step>
<Step title="选择模板">
-选择一个复盘模板来确定报告的章节结构。系统提供中英文内置模板,你也可以选择团队创建的自定义模板。
+选择一个复盘模板来确定报告的章节结构。系统提供中英文内置模板,您也可以选择团队创建的自定义模板。
</Step>
<Step title="一键创建">
@@ -30,15 +30,15 @@ keywords: ["创建复盘", "编辑复盘", "协作编辑", "发布复盘", "删
## 在线协作编辑
-打开报告后,你会进入一个在线协作编辑器。如果你用过 Google Docs、Notion 或飞书文档,会感到非常熟悉:多位团队成员可以同时编辑同一份报告,所有修改实时可见。
+打开报告后,您会进入一个在线协作编辑器。如果您用过 Google Docs、Notion 或飞书文档,会感到非常熟悉:多位团队成员可以同时编辑同一份报告,所有修改实时可见。
-编辑器会自动保存你的修改,无需手动点击保存按钮。
+编辑器会自动保存您的修改,无需手动点击保存按钮。
-在报告正文中 @ 提及成员时,被提及的成员会收到一条个人通知(包含提及内容的摘录和报告信息),方便你邀请相关人员补充或评审报告。
+在报告正文中 @ 提及成员时,被提及的成员会收到一条个人通知(包含提及内容的摘录和报告信息),方便您邀请相关人员补充或评审报告。
### 插入图片
-编辑过程中,你可以直接粘贴或拖拽图片到编辑器中:比如监控大盘截图、架构拓扑图或故障现场的关键信息。
+编辑过程中,您可以直接粘贴或拖拽图片到编辑器中:比如监控大盘截图、架构拓扑图或故障现场的关键信息。
| 限制项 | 说明 |
| :--- | :--- |
@@ -52,11 +52,11 @@ keywords: ["创建复盘", "编辑复盘", "协作编辑", "发布复盘", "删
### 标题
-系统会根据关联故障的标题自动生成一个默认标题。你可以直接在编辑器顶部修改为更精准的描述,比如"2026-03-15 支付服务超时导致订单失败"。标题最长支持 256 个字符。
+系统会根据关联故障的标题自动生成一个默认标题。您可以直接在编辑器顶部修改为更精准的描述,比如"2026-03-15 支付服务超时导致订单失败"。标题最长支持 256 个字符。
### 基本信息
-基本信息面板展示了这次故障的关键指标,你可以根据实际情况调整:
+基本信息面板展示了这次故障的关键指标,您可以根据实际情况调整:
| 字段 | 说明 |
| :--- | :--- |
@@ -84,7 +84,7 @@ keywords: ["创建复盘", "编辑复盘", "协作编辑", "发布复盘", "删
### 查找报告
-在复盘报告列表中,你可以按状态、团队、协作空间和创建时间范围来筛选报告,支持按创建时间或更新时间排序。
+在复盘报告列表中,您可以按状态、团队、协作空间和创建时间范围来筛选报告,支持按创建时间或更新时间排序。
### 删除报告
diff --git a/zh/on-call/post-mortem/manage-templates.mdx b/zh/on-call/post-mortem/manage-templates.mdx
index 425adba9..18160389 100644
--- a/zh/on-call/post-mortem/manage-templates.mdx
+++ b/zh/on-call/post-mortem/manage-templates.mdx
@@ -6,7 +6,7 @@ keywords: ["复盘模板", "模板管理", "自定义模板", "内置模板", "
## 为什么需要模板
-每次复盘都要从零开始思考“应该写哪些内容”,既费时又容易遗漏关键信息。模板帮你解决这个问题:预先定义好章节结构和填写指引,让每份复盘报告都遵循统一的规范,也让 AI 生成内容时有章可循。
+每次复盘都要从零开始思考“应该写哪些内容”,既费时又容易遗漏关键信息。模板帮您解决这个问题:预先定义好章节结构和填写指引,让每份复盘报告都遵循统一的规范,也让 AI 生成内容时有章可循。
<Tip>**版本要求**:此功能需要 On-call 专业版及以上订阅。[了解更多](https://flashcat.cloud/flashduty/price/)</Tip>
@@ -19,7 +19,7 @@ keywords: ["复盘模板", "模板管理", "自定义模板", "内置模板", "
| 默认故障复盘报告模板 | 中文 | 综述、根因分析、影响范围、处理时间线、改进措施、经验教训 |
| Default Post Mortem Report Template | 英文 | Summary, Root Cause, Impact, Timeline, Corrective Actions, Lessons Learned |
-这两个模板覆盖了故障复盘中最常见的章节,适用于大多数场景。如果你的团队有特殊需求,可以在此基础上创建自定义模板。
+这两个模板覆盖了故障复盘中最常见的章节,适用于大多数场景。如果您的团队有特殊需求,可以在此基础上创建自定义模板。
<Note>
内置模板不可修改或删除。
@@ -38,7 +38,7 @@ keywords: ["复盘模板", "模板管理", "自定义模板", "内置模板", "
## 创建自定义模板
-如果内置模板不能完全满足你的需求——比如你的团队需要增加“客户沟通记录”或“成本影响评估”章节,可以创建自定义模板。
+如果内置模板不能完全满足您的需求——比如您的团队需要增加“客户沟通记录”或“成本影响评估”章节,可以创建自定义模板。
<Steps>
<Step title="进入模板管理">
diff --git a/zh/on-call/post-mortem/what-is-post-mortem.mdx b/zh/on-call/post-mortem/what-is-post-mortem.mdx
index e00f9da2..ab2726f0 100644
--- a/zh/on-call/post-mortem/what-is-post-mortem.mdx
+++ b/zh/on-call/post-mortem/what-is-post-mortem.mdx
@@ -10,7 +10,7 @@ keywords: ["故障复盘", "Post-Mortem", "事后分析", "复盘报告", "持
但如果不及时回顾和总结,同样的问题很可能会以不同的面貌再次出现。故障复盘(Post-Mortem)就是帮助团队在故障平息后冷静下来,系统性地回答三个问题:**发生了什么、为什么发生、怎样避免再次发生**。
-Flashduty 将故障复盘融入了故障处理流程——从故障详情页一键创建复盘报告,AI 帮你打底稿,团队成员在线协作完善,最终形成一份可归档、可追溯的复盘报告。
+Flashduty 将故障复盘融入了故障处理流程——从故障详情页一键创建复盘报告,AI 帮您打底稿,团队成员在线协作完善,最终形成一份可归档、可追溯的复盘报告。
<Tip>**版本要求**:此功能需要 On-call 专业版及以上订阅。[了解更多](https://flashcat.cloud/flashduty/price/)</Tip>
@@ -43,9 +43,9 @@ Flashduty 将故障复盘融入了故障处理流程——从故障详情页一
## Flashduty 复盘有什么不同
-### AI 帮你写初稿
+### AI 帮您写初稿
-不用对着空白页面发愁。点击**生成复盘报告**,系统会分析关联故障的告警数据、处理时间线、甚至作战室中的讨论记录,自动生成一份结构完整的报告初稿。你要做的只是在此基础上调整和补充。
+不用对着空白页面发愁。点击**生成复盘报告**,系统会分析关联故障的告警数据、处理时间线、甚至作战室中的讨论记录,自动生成一份结构完整的报告初稿。您要做的只是在此基础上调整和补充。
### 像编辑在线文档一样协作
@@ -53,11 +53,11 @@ Flashduty 将故障复盘融入了故障处理流程——从故障详情页一
### 用模板规范复盘流程
-系统提供中英文内置模板,你也可以创建适合自己团队的自定义模板。统一的模板确保每次复盘都不会遗漏关键章节。
+系统提供中英文内置模板,您也可以创建适合自己团队的自定义模板。统一的模板确保每次复盘都不会遗漏关键章节。
### 图文并茂
-编辑器支持直接粘贴或拖拽图片,方便你在报告中插入监控截图、架构图或故障现场的关键信息。
+编辑器支持直接粘贴或拖拽图片,方便您在报告中插入监控截图、架构图或故障现场的关键信息。
## 一次完整的复盘流程
diff --git a/zh/on-call/quickstart/faq.mdx b/zh/on-call/quickstart/faq.mdx
index e0198255..d56280ba 100644
--- a/zh/on-call/quickstart/faq.mdx
+++ b/zh/on-call/quickstart/faq.mdx
@@ -5,88 +5,67 @@ description: "了解使用 Flashduty On-call 中最常见的问题"
keywords: ["常见问题", "FAQ", "On-call", "故障排查", "使用帮助"]
---
-## 产品介绍
+按主题查找:[产品介绍](#产品介绍) · [收费与订阅](#收费与订阅) · [通知渠道](#通知渠道) · [收不到通知](#收不到通知) · [功能与集成](#功能与集成) · [安全与稳定](#安全与稳定)
----
+## 产品介绍
<AccordionGroup>
- <Accordion title="什么是 Flashduty On-call?">
- Flashduty On-call 的定位是一站式告警响应平台。我们为 IT 从业者提供值班、告警降噪、升级和自动化能力,加速企业故障响应,减少损失。
+ <Accordion id="what-is-on-call" title="什么是 Flashduty On-call?">
+ Flashduty On-call 是一站式告警响应平台,为 IT 团队提供值班、告警降噪、升级和自动化能力,加速故障响应,减少损失。
</Accordion>
- <Accordion title="我是否适合使用 Flashduty On-call?">
- 如果您的组织或团队存在以下情况,您应该使用 Flashduty On-call:
-
+ <Accordion id="is-it-for-me" title="我是否适合使用 Flashduty On-call?">
+ 如果您的团队有以下需求,Flashduty On-call 会很合适:
+
- 需要一个地方收集公司内所有来源的告警,统一处理、跟踪和分析
- - 需要将告警分级,使用不同通道动态通知到关键人员,需要自动升级流程避免告警无人处理
- - 日常处理告警占用大部分精力,需要告警降噪解决告警疲劳问题
+ - 需要按严重程度分级,用不同渠道通知关键人员,并自动升级,避免告警无人处理
+ - 日常处理告警占用大部分精力,需要降噪来解决告警疲劳
</Accordion>
- <Accordion title="Flashduty On-call 相比其他平台有什么优势?">
- 1. 我们提供更灵活易用的功能
- 2. 我们提供更专业的贴心服务
- 3. 我们提供更合理的产品价格
-
- 欢迎您联系我们,获取专业的采购指南。
+ <Accordion id="advantages" title="Flashduty On-call 相比其他平台有什么优势?">
+ 功能更灵活易用、服务更专业、价格更合理。欢迎联系我们获取采购指南,或查看与 [PagerDuty](/zh/on-call/comparison/vs-pagerduty)、[Opsgenie](/zh/on-call/comparison/vs-opsgenie) 的对比。
</Accordion>
</AccordionGroup>
## 收费与订阅
----
-
<AccordionGroup>
- <Accordion title="Flashduty On-call 的收费模式">
- Flashduty On-call 的收费模式是基于购买的 License 数量,每个 License 可以对应一个账户成员。
-
- 例如,您只购买了一个 License,则仅有一个成员可以使用 Flashduty On-call 的全部功能。不过您仍然可以邀请更多成员加入,但只有拥有 License 的成员才能对平台进行操作配置,其他成员则**无法使用平台任何功能**(仅限于接收故障通知)。
-
- ### License 分配方式
-
- 管理者可以通过主动分配的方式,将 License 分配给不同成员。在分配时可以设置 License 的类型:
-
+ <Accordion id="pricing" title="Flashduty On-call 如何收费?">
+ 按活跃用户收费,提供免费版、标准版和商业版三个版本,详细对比见[价格页面](https://flashcat.cloud/flashduty/price/)。
+
+ - 当月使用了商业化功能的用户即为活跃用户,必须持有 License 才能使用。
+ - 每个 License 对应一个账户成员。例如只购买了一个 License,就只有一个成员能使用全部功能;其他成员仍可被邀请加入,但只能接收故障通知。
+ - 每个月度周期结束后,固定 License 保持有效,临时 License 被释放;成员被删除时,其 License 自动释放。
+
+ **License 类型**:管理员分配 License 时可选择类型。
+
| 类型 | 说明 |
| --- | --- |
- | **固定类型** | 在购买有效期内长期有效,不会被抢占,适用于需要参与处理故障、参与配置业务的场景 |
- | **临时类型** | 每个周期结束时自动释放,在有足够 License 的情况下,可以通过分配或抢占的模式占用 |
-
- ### 无 License 的成员
-
- - 不能使用任何功能,包括查看故障列表/详情,**只能被动接收告警消息**
- - 在配置分派策略时可以选择将故障消息通知给没有 License 的成员
- - 没有 License 的成员,即使接收到故障消息,也无法对其进行查看、关闭等操作
- - 没有 License 的成员共享租户的邮件、短信、电话套餐额度
- - 没有 License 的成员在登录控制台进行查看/处理等操作时,会提示没有权限
- </Accordion>
+ | **固定** | 在购买有效期内长期有效,不会被抢占,适合需要处理故障、参与配置的成员 |
+ | **临时** | 每个周期结束时自动释放;License 充足时,可通过分配或抢占占用 |
+
+ **没有 License 的成员**:
- <Accordion title="Flashduty On-call 如何收费?">
- 我们按照活跃用户收费,并提供三个不同的版本:免费版、标准版和商业版。
-
- 详细对比请访问:[价格页面](https://flashcat.cloud/flashduty/price/)
-
- - 我们将当月使用商业化功能的用户界定为活跃用户,该用户必须取得 License 才能使用
- - 每个月度周期结束后,活跃用户持有的固定 License 将保持有效,临时 License 将被释放
- - 一个成员被删除时,其 License 自动释放
- - 查看告警需要 License,仅被动接收通知不需要 License
+ - 只能被动接收告警消息;分派策略中可以选择通知他们
+ - 不能查看故障列表或详情,也不能认领、关闭故障;登录控制台时会提示没有权限
+ - 与其他成员共享租户的邮件、短信、电话套餐额度
</Accordion>
- <Accordion title="On-call 订阅过期后会怎样?">
+ <Accordion id="subscription-expired" title="On-call 订阅过期后会怎样?">
订阅过期后,平台冻结**新建**类操作,已有的数据和配置不受影响:
- - **告警停止接入**:所有集成不再接收新的告警事件,也不会再产生新故障
- - **历史数据仍可用**:历史告警仍可查看与处理,已有故障仍可正常处理
- - **新建入口被冻结**:新建协作空间、值班表、手动创建故障、创建作战室等入口会被禁用,悬停可查看原因
- - **页面常驻提示**:告警列表、故障列表与侧边栏会常驻显示订阅过期提示
+ - **告警停止接入**:所有集成不再接收新的告警事件,也不会产生新故障
+ - **历史数据仍可用**:历史告警和已有故障仍可查看与处理
+ - **新建入口被冻结**:新建协作空间、值班表、手动创建故障、创建作战室等入口被禁用
+ - **页面常驻提示**:告警列表、故障列表与侧边栏常驻显示订阅过期提示
- **续费后自动恢复**:续费成功后自动恢复告警接入,无需重新配置
</Accordion>
</AccordionGroup>
## 通知渠道
----
-
<AccordionGroup>
- <Accordion title="Flashduty On-call 支持哪些通知方式?">
+ <Accordion id="notification-channels" title="Flashduty On-call 支持哪些通知方式?">
| 通道 | 单聊 | 群聊 |
| --- | :---: | :---: |
| 语音 | ✅ | |
@@ -104,280 +83,119 @@ keywords: ["常见问题", "FAQ", "On-call", "故障排查", "使用帮助"]
| Telegram 机器人 | | ✅ |
</Accordion>
- <Accordion title="如何确保 Flashduty On-call 通知到我?">
- Flashduty On-call 尽力确保每一个通道的可用性:
-
- - **语音、短信和邮件**:我们使用多家云厂商提供的高可用服务,可以在某家出问题后迅速切换到另一家
- - **IM 应用消息**:单聊消息发送失败时,系统会使用短信和邮件进行兜底提醒
- - **分派策略设置**:建议您设置循环通知,如果故障没有被认领,系统循环进行多次通知;或设置升级环节,如果当前环节的人员没有及时处理,故障将升级分派给下一环节的人员
+ <Accordion id="delivery-reliability" title="如何确保 Flashduty On-call 通知到我?">
+ - **语音、短信和邮件**:使用多家云厂商的高可用服务,一家出问题时可迅速切换到另一家
+ - **IM 应用消息**:单聊消息发送失败时,系统用短信和邮件兜底提醒
+ - **分派策略**:建议设置循环通知(故障未被认领时多次通知),或设置升级环节(当前环节未及时处理时升级给下一环节)
</Accordion>
- <Accordion title="Flashduty On-call 是否使用固定号码进行语音通知?">
- 是的,我们使用固定号码进行语音通知。您可下载 Flashduty On-call App 并授权自动同步联系方式到通讯录,避免漏接电话。
-
- <Tabs>
- <Tab title="🇨🇳 中国">
- | 号码 | 归属地 |
- | :--- | :--- |
- | (010) 21364727 | 北京 |
- | (010) 21364713 | 北京 |
- | (010) 21364708 | 北京 |
- | (021) 32017538 | 上海 |
- | (0571) 23675454 | 杭州 |
- | (0571) 23675496 | 杭州 |
- | +1 6465861127 | 香港 |
- | +1 6465861127 | 台湾 |
- </Tab>
- <Tab title="🌏 亚太地区">
- <CardGroup cols={3}>
- <Card title="🇸🇬 新加坡" icon="phone">
- +65 6531297878
- </Card>
- <Card title="🇯🇵 日本" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇰🇷 韩国" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇦🇺 澳大利亚" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇮🇳 印度" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇲🇾 马来西亚" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇹🇭 泰国" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇻🇳 越南" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇮🇩 印度尼西亚" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇵🇭 菲律宾" icon="phone">
- +1 6465861127
- </Card>
- </CardGroup>
- </Tab>
- <Tab title="🌎 欧美地区">
- <CardGroup cols={3}>
- <Card title="🇺🇸 美国" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇨🇦 加拿大" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇬🇧 英国" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇩🇪 德国" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇫🇷 法国" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇳🇱 荷兰" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇮🇹 意大利" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇪🇸 西班牙" icon="phone">
- +1 6465861127
- </Card>
- <Card title="🇧🇷 巴西" icon="phone">
- +1 6465861127
- </Card>
- </CardGroup>
- </Tab>
- <Tab title="🌍 其他地区">
- 除上述列出的国家和地区外,我们还支持全球 **200+** 个国家和地区的语音通知:
-
- <CardGroup cols={4}>
- <Card title="🇦🇪 阿联酋" icon="phone">+1 6465861127</Card>
- <Card title="🇸🇦 沙特阿拉伯" icon="phone">+1 6465861127</Card>
- <Card title="🇮🇱 以色列" icon="phone">+1 6465861127</Card>
- <Card title="🇹🇷 土耳其" icon="phone">+1 6465861127</Card>
- <Card title="🇿🇦 南非" icon="phone">+1 6465861127</Card>
- <Card title="🇪🇬 埃及" icon="phone">+1 6465861127</Card>
- <Card title="🇳🇿 新西兰" icon="phone">+1 6465861127</Card>
- <Card title="🇷🇺 俄罗斯" icon="phone">+1 6465861127</Card>
- <Card title="🇵🇱 波兰" icon="phone">+1 6465861127</Card>
- <Card title="🇸🇪 瑞典" icon="phone">+1 6465861127</Card>
- <Card title="🇨🇭 瑞士" icon="phone">+1 6465861127</Card>
- <Card title="🇦🇹 奥地利" icon="phone">+1 6465861127</Card>
- </CardGroup>
-
- <Note>
- 如果您所在地区无法收到语音通知,请联系我们:[support@flashcat.cloud](mailto:support@flashcat.cloud)
- </Note>
- </Tab>
- </Tabs>
+ <Accordion id="voice-numbers" title="语音通知使用哪些号码?">
+ 语音通知使用固定号码。建议下载 Flashduty On-call App 并授权同步联系方式到通讯录,避免漏接电话。
+
+ | 地区 | 号码 |
+ | :--- | :--- |
+ | 中国大陆 · 北京 | (010) 21364727、(010) 21364713、(010) 21364708 |
+ | 中国大陆 · 上海 | (021) 32017538 |
+ | 中国大陆 · 杭州 | (0571) 23675454、(0571) 23675496 |
+ | 新加坡 | +65 6531297878 |
+ | 中国香港、中国台湾,以及日本、韩国、澳大利亚、印度、马来西亚、泰国、越南、印度尼西亚、菲律宾、美国、加拿大、英国、德国、法国、荷兰、意大利、西班牙、巴西、阿联酋、沙特阿拉伯、以色列、土耳其、南非、埃及、新西兰、俄罗斯、波兰、瑞典、瑞士、奥地利等 | +1 6465861127 |
+
+ 语音通知覆盖全球 **200+** 个国家和地区。如果您所在地区无法收到语音通知,请联系 [support@flashcat.cloud](mailto:support@flashcat.cloud)。
</Accordion>
- <Accordion title="Flashduty On-call 短信通知支持哪些地区?">
- 短信通知支持全球几乎大部分的地区。目前开放的地区:
-
- <Tabs>
- <Tab title="🇨🇳 中国">
- <CardGroup cols={4}>
- <Card title="🇨🇳 中国大陆" icon="message" />
- <Card title="🇲🇴 中国澳门" icon="message" />
- <Card title="中国台湾" icon="message" />
- <Card title="🇭🇰 中国香港" icon="message" />
- </CardGroup>
- </Tab>
- <Tab title="🌏 亚太地区">
- <CardGroup cols={4}>
- <Card title="🇬🇺 关岛" icon="message" />
- <Card title="🇰🇷 韩国" icon="message" />
- <Card title="🇲🇾 马来西亚" icon="message" />
- <Card title="🇯🇵 日本" icon="message" />
- <Card title="🇹🇭 泰国" icon="message" />
- <Card title="🇧🇳 文莱" icon="message" />
- <Card title="🇸🇬 新加坡" icon="message" />
- <Card title="🇮🇳 印度" icon="message" />
- <Card title="🇮🇩 印度尼西亚" icon="message" />
- </CardGroup>
- </Tab>
- <Tab title="🌎 欧美地区">
- <CardGroup cols={4}>
- <Card title="🇮🇪 爱尔兰" icon="message" />
- <Card title="🇪🇪 爱沙尼亚" icon="message" />
- <Card title="🇧🇸 巴哈马" icon="message" />
- <Card title="🇧🇷 巴西" icon="message" />
- <Card title="🇵🇱 波兰" icon="message" />
- <Card title="🇩🇰 丹麦" icon="message" />
- <Card title="🇩🇪 德国" icon="message" />
- <Card title="🇫🇷 法国" icon="message" />
- <Card title="🇨🇴 哥伦比亚" icon="message" />
- <Card title="🇨🇿 捷克" icon="message" />
- <Card title="🇱🇻 拉脱维亚" icon="message" />
- <Card title="🇱🇹 立陶宛" icon="message" />
- <Card title="🇷🇴 罗马尼亚" icon="message" />
- <Card title="🇲🇹 马耳他" icon="message" />
- <Card title="🇲🇰 马其顿" icon="message" />
- <Card title="🇲🇽 墨西哥" icon="message" />
- <Card title="🇳🇴 挪威" icon="message" />
- <Card title="🇵🇹 葡萄牙" icon="message" />
- <Card title="🇨🇭 瑞士" icon="message" />
- <Card title="🇸🇰 斯洛伐克" icon="message" />
- <Card title="🇺🇾 乌拉圭" icon="message" />
- <Card title="🇪🇸 西班牙" icon="message" />
- <Card title="🇮🇹 意大利" icon="message" />
- <Card title="🇬🇧 英国" icon="message" />
- <Card title="🇨🇱 智利" icon="message" />
- </CardGroup>
- </Tab>
- <Tab title="🌍 其他地区">
- <CardGroup cols={4}>
- <Card title="🇦🇺 澳大利亚" icon="message" />
- <Card title="🇧🇭 巴林" icon="message" />
- <Card title="🇰🇮 基里巴斯" icon="message" />
- <Card title="🇹🇷 土耳其" icon="message" />
- <Card title="🇳🇿 新西兰" icon="message" />
- </CardGroup>
- </Tab>
- </Tabs>
-
- <Note>
- 如果您所在地区无法收到短信通知,请联系我们:[support@flashcat.cloud](mailto:support@flashcat.cloud)
- </Note>
+ <Accordion id="sms-regions" title="短信通知支持哪些地区?">
+ | 区域 | 国家和地区 |
+ | :--- | :--- |
+ | 中国 | 中国大陆、中国香港、中国澳门、中国台湾 |
+ | 亚太 | 关岛、韩国、马来西亚、日本、泰国、文莱、新加坡、印度、印度尼西亚 |
+ | 欧美 | 爱尔兰、爱沙尼亚、巴哈马、巴西、波兰、丹麦、德国、法国、哥伦比亚、捷克、拉脱维亚、立陶宛、罗马尼亚、马耳他、马其顿、墨西哥、挪威、葡萄牙、瑞士、斯洛伐克、乌拉圭、西班牙、意大利、英国、智利 |
+ | 其他 | 澳大利亚、巴林、基里巴斯、土耳其、新西兰 |
+
+ 如果您所在地区无法收到短信通知,请联系 [support@flashcat.cloud](mailto:support@flashcat.cloud)。
</Accordion>
- <Accordion title="为什么我无法收到语音通知?">
- 语音电话与终端信号以及设置有很大关系,如果您持续无法收到语音通知,建议尝试下述操作:
+ <Accordion id="custom-bot-notifications" title="我没有飞书/钉钉/企微/Telegram,如何接收机器人通知?">
+ Flashduty 不会校验机器人 Webhook 地址的域名,因此您可以:
- 1. 如果您使用的是中国大陆以外地区注册的手机号,请检查我们支持的地域范围
- 2. 检查手机的黑名单或者通话记录是否有拦截,通常是 010xxx 或 021xx 等固话号码,如果有,请解除黑名单并加白
- 3. 如手机没看到黑名单,可能是手机号开通了拦截服务等功能:
- - **移动**:通过微信公众号"中国移动高频骚扰电话防护"检查
- - **电信**:关注公众号"天翼防骚扰"检查
- - **联通**:关注公众号"沃助理"检查,或咨询客服电话
- 4. 如果您的手机号参与过携号转网,请同时查询多家运营商的拦截情况
- 5. 尝试重启手机、重新插入手机卡,将手机卡插入其他手机,依次排除终端或手机卡问题
+ 1. 在分派策略中选择任意一种机器人类型(如钉钉机器人)
+ 2. 将 Webhook 地址填写为您自己开发的服务端 URL
+ 3. 在服务端按该 IM 平台的消息格式解析请求体
- 如果您仍然没有找到原因,请联系我们。
+ Flashduty 会以该平台的消息格式把告警通知推送到您的服务端,您可以自行处理后转发到任意渠道。
</Accordion>
+</AccordionGroup>
- <Accordion title="为什么我无法收到邮件通知?">
- 建议尝试下述操作:
+## 收不到通知
- 1. 检查邮件客户端内的垃圾邮件,如果有,请主动移出,保持正常接收
- 2. 检查邮件客户端是否设置了自动删除,如果有,请修改规则
- 3. 联系公司企业邮箱管理员,后台检查是否被拦截(Gmail 等企业邮箱限制较严格,邮件发送过多会导致拦截)。如果有,请针对邮件来源设置白名单
+<AccordionGroup>
+ <Accordion id="no-voice-call" title="为什么我收不到语音通知?">
+ 语音电话与终端信号和手机设置关系很大。如果持续收不到,请依次排查:
- 如果您仍然没有找到原因,请联系我们。
- </Accordion>
+ 1. 中国大陆以外注册的手机号,先确认所在地区在[支持范围](#voice-numbers)内
+ 2. 检查手机黑名单或通话记录中是否拦截了来电(通常是 010、021 等开头的固话号码),如有请解除拦截并加入白名单
+ 3. 手机上没有拦截记录时,可能是运营商开通了拦截服务:
+ - **移动**:通过微信公众号「中国移动高频骚扰电话防护」检查
+ - **电信**:通过公众号「天翼防骚扰」检查
+ - **联通**:通过公众号「沃助理」检查,或咨询客服电话
+ 4. 手机号做过携号转网的,请同时查询多家运营商的拦截情况
+ 5. 尝试重启手机、重新插卡,或把手机卡插到其他手机上,排除终端或手机卡问题
- <Accordion id="custom-bot-notifications" title="我没有飞书/钉钉/企微/Telegram,如何接收机器人通知?">
- 如果您不使用上述任何 IM 平台,仍然可以利用机器人通知能力。Flashduty 不会校验机器人 Webhook 地址的域名,您可以:
+ 仍未找到原因,请联系我们。
+ </Accordion>
- 1. 在分派策略中选择任意一种机器人类型(如钉钉机器人)
- 2. 将 Webhook 地址填写为您自己开发的服务端 URL
- 3. 在您的服务端实现对应 IM 平台的消息推送协议(即按照该平台的消息格式解析请求体)
+ <Accordion id="no-email" title="为什么我收不到邮件通知?">
+ 1. 检查垃圾邮件文件夹,如有请移出
+ 2. 检查邮件客户端是否设置了自动删除规则,如有请修改
+ 3. 联系企业邮箱管理员,确认后台是否拦截(Gmail 等企业邮箱限制较严,发送过多会被拦截),如有请将发件来源加入白名单
- 这样,Flashduty 会将告警通知以该 IM 平台的消息格式推送到您的服务端,您可以自行处理后转发到任意通知渠道。
+ 仍未找到原因,请联系我们。
</Accordion>
</AccordionGroup>
## 功能与集成
----
-
<AccordionGroup>
- <Accordion title="Flashduty On-call 可以针对告警的字段设置路由吗?">
- 可以。Flashduty On-call 支持您根据告警事件的标签、严重程度、标题和描述等多个维度信息进行匹配,并路由到不同的协作空间。
-
- 详见:集成中心 → 集成详情 → 路由配置
+ <Accordion id="routing-by-fields" title="Flashduty On-call 可以针对告警的字段设置路由吗?">
+ 可以。您可以按告警事件的标签、严重程度、标题和描述等多个维度匹配,路由到不同的协作空间。详见[路由规则](/zh/on-call/integration/alert-integration/routing-rules)。
</Accordion>
- <Accordion title="Flashduty On-call 支持集成哪些告警系统?">
- - **通用集成**:邮件告警(几乎适用所有告警系统)、自定义事件标准(使用自研监控系统)
- - **开源集成**:Zabbix、Prometheus、夜莺等常见的开源监控
+ <Accordion id="supported-alert-sources" title="Flashduty On-call 支持集成哪些告警系统?">
+ - **通用集成**:邮件告警(几乎适用所有告警系统)、自定义事件标准(适用于自研监控系统)
+ - **开源集成**:Zabbix、Prometheus、夜莺等常见开源监控
- **商业集成**:阿里云、腾讯云、华为云、AWS、Azure 等商业云监控
-
- 如果您有其他需求,欢迎随时联系我们。
+
+ 完整列表见[告警集成概览](/zh/on-call/integration/alert-integration/overview)。如有其他需求,欢迎联系我们。
</Accordion>
</AccordionGroup>
## 安全与稳定
----
-
<AccordionGroup>
- <Accordion title="Flashduty On-call 如何确保自身稳定?">
+ <Accordion id="stability" title="Flashduty On-call 如何确保自身稳定?">
**SLA 承诺**:
- - **功能可用**:确保核心功能在 99.95% 的时间内是可用的
- - **投递时效**:确保 99.95% 的告警在触发后 5 分钟内完成投递
-
- **如何保证 SLA**:
- 1. **同城多活**:基础设施构建在多个数据中心之上,有状态组件均为同城多活
- 2. **异步处理**:告警上报后会立即进入异步流程,出错有重试,减少告警丢失风险
- 3. **冗余告警**:对于重要告警,提供冗余通知机制,客户可选择多个渠道循环通知,确保通知可达
- 4. **全球加速**:已针对 api.flashcat.cloud 域名开启全球加速,确保各地上报链路稳定
- 5. **持续监控**:全面采集系统各方面指标,定期进行压测,及时或提前发现系统问题
- </Accordion>
- <Accordion title="Flashduty On-call 如何确保数据安全?">
- 1. 全栈 HTTPS,数据传输确保安全
- 2. 敏感信息加密存储,日志脱敏后落盘
- 3. 重要数据修改需 MFA 校验,支持操作审计
- 4. 定期参加国际国内认可的第三方权威机构安全认证审核(ISO27001,ISO9001)
- 5. 对于有需要的客户,可以签署保密协议
+ - **功能可用**:核心功能 99.95% 的时间可用
+ - **投递时效**:99.95% 的告警在触发后 5 分钟内完成投递
+
+ **如何保证**:
+
+ 1. **同城多活**:基础设施构建在多个数据中心之上,有状态组件均为同城多活
+ 2. **异步处理**:告警上报后立即进入异步流程,出错有重试,减少告警丢失风险
+ 3. **冗余通知**:重要告警可选择多个渠道循环通知,确保送达
+ 4. **全球加速**:api.flashcat.cloud 已开启全球加速,确保各地上报链路稳定
+ 5. **持续监控**:全面采集系统指标,定期压测,及时甚至提前发现问题
+ </Accordion>
+
+ <Accordion id="data-security" title="Flashduty On-call 如何确保数据安全?">
+ 1. 全栈 HTTPS,确保数据传输安全
+ 2. 敏感信息加密存储,日志脱敏后落盘
+ 3. 重要数据修改需 MFA 校验,支持操作审计
+ 4. 定期参加国际国内认可的第三方安全认证审核(ISO27001、ISO9001)
+ 5. 有需要的客户可以签署保密协议
6. 隐私协议:[查看隐私政策](/zh/compliance/data-security)
</Accordion>
- <Accordion title="Flashduty On-call 是否支持私有化部署?">
- 支持。Flashduty On-call 提供与 SaaS 服务几乎一致的私有化版本。
-
- <Warning>
- 由于私有化部署有较高的维护成本,收费模式与 SaaS 服务不同。如无必要,我们都推荐您使用云服务。
- </Warning>
-
- 如果您需要私有化版本,请联系我们。
+ <Accordion id="private-deployment" title="Flashduty On-call 是否支持私有化部署?">
+ 支持。Flashduty On-call 提供与 SaaS 服务几乎一致的私有化版本;由于维护成本较高,收费模式与 SaaS 不同。如无必要,推荐使用云服务。如需私有化版本,请联系我们。
</Accordion>
</AccordionGroup>
diff --git a/zh/on-call/quickstart/mobile-app.mdx b/zh/on-call/quickstart/mobile-app.mdx
index d4621b54..70ab621f 100644
--- a/zh/on-call/quickstart/mobile-app.mdx
+++ b/zh/on-call/quickstart/mobile-app.mdx
@@ -9,16 +9,12 @@ Flashduty 提供覆盖 **iOS、Android 和移动 H5** 的移动端能力。无
## 下载与安装
----
-
下载与安装方式(App Store、各大安卓应用市场、扫码下载安装包)请参见 [个人设置 - Flashduty APP](/zh/on-call/configuration/personal-settings#flashduty-app)。
安装完成后,首次登录成功即会自动完成设备与账户的关联,此后即可接收 App 推送。您可以在控制台 **个人中心 → Flashduty APP** 页面查看和管理已关联的设备。
## 登录方式
----
-
<Tabs>
<Tab title="App 登录">
App 登录页提供两种方式:
@@ -44,8 +40,6 @@ Flashduty 提供覆盖 **iOS、Android 和移动 H5** 的移动端能力。无
## 故障处理
----
-
### 故障列表与筛选
App 首页即故障列表,分为 **分派给我**(带故障数量角标)和 **全部** 两个页签。在列表卡片上左滑,可以快捷 **认领** 或 **关闭** 故障。
@@ -96,8 +90,6 @@ App 首页即故障列表,分为 **分派给我**(带故障数量角标)
## 推送通知
----
-
App 登录成功后,当前设备会自动与账户绑定并接收推送。**点击通知可直接打开对应的故障详情页**。
<Tabs>
@@ -124,8 +116,6 @@ App 登录成功后,当前设备会自动与账户绑定并接收推送。**
## 实用设置
----
-
在故障列表页点击右上角 **设置图标** 进入设置页:
| 设置项 | 说明 |
@@ -139,8 +129,6 @@ App 登录成功后,当前设备会自动与账户绑定并接收推送。**
## 移动 H5
----
-
**m.console.flashcat.cloud** 是与 App 同一代码库构建的 Web 端,能力与 App 一致:
- **通知链接的落地页**:短信、IM 中的故障相关链接(如评论 @提及 通知)会在移动端打开 H5 的故障详情页
@@ -149,8 +137,6 @@ App 登录成功后,当前设备会自动与账户绑定并接收推送。**
## 能力边界
----
-
移动端聚焦 **接收通知与处理故障**。以下配置类能力需要前往 PC 控制台完成:
- 值班排班、分派策略、集成接入与路由规则
@@ -163,8 +149,6 @@ App 推送仅用于故障分派场景;评论 @提及、工作项指派等协
## 延伸阅读
----
-
<CardGroup cols={3}>
<Card title="处理与更新故障" icon="wrench" href="/zh/on-call/incident/handle-update-incident">
了解控制台、IM、语音等全部故障处理方式
diff --git a/zh/on-call/quickstart/quickstart.mdx b/zh/on-call/quickstart/quickstart.mdx
index d25ca9f8..24a5881f 100644
--- a/zh/on-call/quickstart/quickstart.mdx
+++ b/zh/on-call/quickstart/quickstart.mdx
@@ -10,17 +10,13 @@ keywords: ["入门指南", "快速开始", "告警接入", "On-call", "电话通
{ /*
## 视频演示
----
-
<Video src="https://download.flashcat.cloud/%e6%95%b4%e4%bd%93%e6%bc%94%e7%a4%ba.mp4"></Video>
*/}
## 核心流程
----
-
-Flashduty On-call 的工作流非常直观:**告警** 通过 **集成** 进入 **协作空间**,然后根据 **分派策略** 通知到具体的 **人**。
+Flashduty On-call 的核心流程:告警通过集成进入协作空间,再根据分派策略通知到具体的人。
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/d20b719be99f451c938f70ce9c0f8889.png" alt="Flashduty On-call" />
@@ -29,9 +25,7 @@ Flashduty On-call 的工作流非常直观:**告警** 通过 **集成** 进入
## 步骤一:创建协作空间
----
-
-**协作空间** 是管理故障的"作战室"。建议按照业务线(如"支付中心")或组件(如"MySQL")来划分。
+**协作空间** 是团队接收和处理故障的工作空间。建议按照业务线(如"支付中心")或组件(如"MySQL")来划分。
<Steps>
<Step title="进入协作空间列表">
@@ -50,8 +44,6 @@ Flashduty On-call 的工作流非常直观:**告警** 通过 **集成** 进入
## 步骤二:接入告警数据
----
-
现在,我们把监控系统的告警接入到系统中。Flashduty On-call 提供两种接入模式:
<Tabs>
@@ -77,8 +69,6 @@ Flashduty On-call 的工作流非常直观:**告警** 通过 **集成** 进入
## 步骤三:配置分派策略
----
-
告警进来后,该通知谁?这由 **分派策略** 决定。
<Warning>
@@ -109,8 +99,6 @@ Flashduty On-call 的工作流非常直观:**告警** 通过 **集成** 进入
## 进阶配置
----
-
恭喜!您已经跑通了最核心的流程。接下来,您可以尝试更多高级功能:
<CardGroup cols={3}>
@@ -120,15 +108,13 @@ Flashduty On-call 的工作流非常直观:**告警** 通过 **集成** 进入
<Card title="告警降噪" icon="filter" href="/zh/on-call/channel/noise-reduction">
将 100 条相同告警合并为 1 条
</Card>
- <Card title="路由规则" icon="route" href="/zh/on-call/channel/integrate-data">
+ <Card title="路由规则" icon="route" href="/zh/on-call/integration/alert-integration/routing-rules">
根据告警内容自动分发到不同空间
</Card>
</CardGroup>
## 常见问题
----
-
<AccordionGroup>
<Accordion title="收不到电话/短信通知?">
请前往 **我的 → 个人信息** 检查手机号是否已验证,并在 **我的 → 通知偏好** 的 **故障分派** 中确认已开启电话/短信渠道。
diff --git a/zh/on-call/statuspage/comparison.mdx b/zh/on-call/statuspage/comparison.mdx
index 28714e29..3079acaa 100644
--- a/zh/on-call/statuspage/comparison.mdx
+++ b/zh/on-call/statuspage/comparison.mdx
@@ -6,8 +6,6 @@ keywords: ["状态页对比", "Atlassian Statuspage", "功能对比", "价格对
## 前言
----
-
**状态页**是企业与用户之间建立服务透明度和信任的关键桥梁。当服务出现故障或计划维护时,一个清晰、及时、可订阅的状态页能够大幅降低客户焦虑、减少支持工单,并展现专业的事件沟通能力。
Flashduty 状态页和 Atlassian Statuspage 是市场上两款主流的状态页产品,但两者的**产品定位有本质区别**:
@@ -25,8 +23,6 @@ Flashduty 状态页和 Atlassian Statuspage 是市场上两款主流的状态页
## 为什么选择第三方状态页?
----
-
在评估具体产品之前,首先需要回答一个更根本的问题:**状态页应该自建还是使用第三方服务?**
<AccordionGroup>
@@ -52,8 +48,6 @@ Flashduty 状态页和 Atlassian Statuspage 是市场上两款主流的状态页
## 产品功能对比
----
-
### 状态页类型
| 核心能力 | Flashduty | Atlassian Statuspage |
@@ -124,8 +118,6 @@ Flashduty 状态页和 Atlassian Statuspage 是市场上两款主流的状态页
## 价格对比
----
-
Atlassian Statuspage 作为独立产品收费,价格随订阅者、组件、团队成员等维度分档递增。Flashduty 状态页**包含在 On-call 模块中,无需单独采购**。
| 对比维度 | Flashduty 状态页 | Atlassian Statuspage |
@@ -156,8 +148,6 @@ Flashduty 状态页的额外成本为零——它是 On-call 订阅的内置能
## Flashduty 状态页的可靠性
----
-
作为第三方状态页服务,Flashduty 自身的可靠性至关重要——您需要确信在您的服务故障时,状态页依然正常运行。
<CardGroup cols={2}>
@@ -188,8 +178,6 @@ Flashduty 状态页的额外成本为零——它是 On-call 订阅的内置能
## 从 Atlassian Statuspage 迁移
----
-
Flashduty CLI 支持将 Atlassian Statuspage 的组件、分组、历史事件和邮件订阅者一键迁移到 Flashduty 状态页(迁移功能需专业版),同时兼容 `history.rss` 和 `history.atom` 链接格式,现有 RSS/Atom 订阅者无需修改订阅地址。
<Steps>
@@ -215,8 +203,6 @@ Flashduty CLI 支持将 Atlassian Statuspage 的组件、分组、历史事件
## 总结
----
-
<CardGroup cols={3}>
<Card title="功能更全面" icon="layer-group">
事件订阅、组件展示控制、维护不计入可用性统计、原生 IM 通知等**差异化能力**
diff --git a/zh/on-call/statuspage/components-sections.mdx b/zh/on-call/statuspage/components-sections.mdx
index 8d66b565..4d70724a 100644
--- a/zh/on-call/statuspage/components-sections.mdx
+++ b/zh/on-call/statuspage/components-sections.mdx
@@ -21,12 +21,12 @@ description: "了解如何在状态页中创建和管理服务组件与分组,
| **排序** | 否 | 控制组件在状态页中的显示顺序 |
<Note>
-新创建的组件默认从创建时刻开始计算可用性。如果你需要从更早的时间点开始统计,可以自定义可用起始时间。
+新创建的组件默认从创建时刻开始计算可用性。如果您需要从更早的时间点开始统计,可以自定义可用起始时间。
</Note>
### 编辑组件
-你可以随时修改组件的名称、描述、分组归属和排序。修改名称时需确保在同一状态页内不与其他组件重名。
+您可以随时修改组件的名称、描述、分组归属和排序。修改名称时需确保在同一状态页内不与其他组件重名。
### 删除组件
@@ -42,14 +42,14 @@ description: "了解如何在状态页中创建和管理服务组件与分组,
| **完全隐藏** | 组件不在状态页上展示,也不参与可用性统计 |
<Tip>
-如果你有仅供内部参考的服务组件,不希望在状态页上暴露给访客,可以使用"完全隐藏"选项。隐藏后,该组件仍然可以在事件中被关联。
+如果您有仅供内部参考的服务组件,不希望在状态页上暴露给访客,可以使用"完全隐藏"选项。隐藏后,该组件仍然可以在事件中被关联。
</Tip>
---
## 分组
-分组用于将相关联的组件归类展示,使状态页结构更清晰。例如,你可以将"Web 应用"、"API 服务"和"数据库"归入"核心服务"分组。
+分组用于将相关联的组件归类展示,使状态页结构更清晰。例如,您可以将"Web 应用"、"API 服务"和"数据库"归入"核心服务"分组。
### 创建分组
@@ -63,7 +63,7 @@ description: "了解如何在状态页中创建和管理服务组件与分组,
### 编辑分组
-你可以随时修改分组的名称、描述和排序。
+您可以随时修改分组的名称、描述和排序。
### 删除分组
diff --git a/zh/on-call/statuspage/create-manage-page.mdx b/zh/on-call/statuspage/create-manage-page.mdx
index 4026ce99..88b62706 100644
--- a/zh/on-call/statuspage/create-manage-page.mdx
+++ b/zh/on-call/statuspage/create-manage-page.mdx
@@ -5,19 +5,19 @@ description: "了解如何配置状态页的品牌、自定义域名、显示设
本文面向已经创建或迁移完成的状态页,介绍如何配置基础属性和显示设置。
-如果你还没有状态页,先阅读[接入 Flashduty 状态页](/zh/on-call/statuspage/get-started),完成创建或迁移。
+如果您还没有状态页,先阅读[接入 Flashduty 状态页](/zh/on-call/statuspage/get-started),完成创建或迁移。
---
## 基础信息
-你可以随时编辑状态页名称、URL 标识和基础说明。状态页名称通常使用公司名、产品名或服务名,方便访客识别当前页面代表的服务范围。
+您可以随时编辑状态页名称、URL 标识和基础说明。状态页名称通常使用公司名、产品名或服务名,方便访客识别当前页面代表的服务范围。
### URL 标识
URL 标识是状态页访问地址中的唯一路径段。创建后可以修改,但同一账户内同类型状态页的 URL 标识不能重复。
-系统会将名称自动转换为 URL 安全格式(小写化、非字母数字字符替换为连字符)。你也可以手动指定。
+系统会将名称自动转换为 URL 安全格式(小写化、非字母数字字符替换为连字符)。您也可以手动指定。
<Warning>
修改 URL 标识后,原访问地址将失效。正式对外发布的状态页建议提前规划 URL 标识,避免后续变更影响外部链接。
@@ -27,7 +27,7 @@ URL 标识是状态页访问地址中的唯一路径段。创建后可以修改
## 外观设置
-你可以自定义状态页的品牌外观,使其与你的企业形象保持一致。
+您可以自定义状态页的品牌外观,使其与您的企业形象保持一致。
### Logo 与图标
@@ -51,14 +51,14 @@ URL 标识是状态页访问地址中的唯一路径段。创建后可以修改
## 自定义域名
-默认情况下,状态页通过 Flashduty 提供的子域名访问。如果你希望使用自有域名(如 `status.yourcompany.com`),可以配置自定义域名。
+默认情况下,状态页通过 Flashduty 提供的子域名访问。如果您希望使用自有域名(如 `status.yourcompany.com`),可以配置自定义域名。
<Steps>
<Step title="添加 CNAME 记录">
- 在你的 DNS 服务商中,为目标域名添加一条 CNAME 记录,指向 Flashduty 提供的状态页地址。
+ 在您的 DNS 服务商中,为目标域名添加一条 CNAME 记录,指向 Flashduty 提供的状态页地址。
</Step>
<Step title="配置自定义域名">
- 在状态页设置中填入自定义域名。系统会验证域名唯一性,同一域名不能被多个状态页使用。
+ 在状态页设置中填入自定义域名。
</Step>
</Steps>
@@ -71,7 +71,7 @@ URL 标识是状态页访问地址中的唯一路径段。创建后可以修改
| 记录 | 类型 | 说明 |
| --- | --- | --- |
| **访问入口记录** | CNAME | 将域名指向 Flashduty 托管访问入口:大陆访问入口为 `cn.statuspage.flashduty.com`,国际访问入口为 `statuspage.flashduty.com`。如果 DNS 服务商支持 GeoDNS,可为同一域名同时配置国内与海外解析;不支持时选择其中一个入口即可 |
-| **证书托管记录**(dns-01 委派) | CNAME | 在 `_acme-challenge` 前缀下添加 dns-01 委派记录,将 ACME 证书校验委派给 Flashcat 托管 DNS,用于证明你拥有该域名。记录名称与目标值以**检查配置**显示为准 |
+| **证书托管记录**(dns-01 委派) | CNAME | 在 `_acme-challenge` 前缀下添加 dns-01 委派记录,将 ACME 证书校验委派给 Flashcat 托管 DNS,用于证明您拥有该域名。记录名称与目标值以**检查配置**显示为准 |
两类记录均校验通过后,系统开始签发证书,并在签发完成后自动发布到边缘节点,自定义域名即可通过 HTTPS 访问。
@@ -84,7 +84,7 @@ URL 标识是状态页访问地址中的唯一路径段。创建后可以修改
<Note>
**按完整 CNAME 链识别入口**
-系统按完整 CNAME 链校验访问入口:你可以通过自己的中间记录链式指向托管入口,链上任一跳与托管入口匹配即视为已接入。域名被识别后,边缘节点即按需(on-demand)为其提供 HTTPS 访问。
+系统按完整 CNAME 链校验访问入口:您可以通过自己的中间记录链式指向托管入口,链上任一跳与托管入口匹配即视为已接入。域名被识别后,边缘节点即按需(on-demand)为其提供 HTTPS 访问。
</Note>
---
@@ -106,7 +106,7 @@ URL 标识是状态页访问地址中的唯一路径段。创建后可以修改
### 可用性统计展示
-你可以控制组件可用性统计信息的展示方式:
+您可以控制组件可用性统计信息的展示方式:
| 展示模式 | 说明 |
| --- | --- |
@@ -118,6 +118,6 @@ URL 标识是状态页访问地址中的唯一路径段。创建后可以修改
## 编辑与删除
-你可以随时编辑状态页的名称、URL 标识、外观设置和显示配置。
+您可以随时编辑状态页的名称、URL 标识、外观设置和显示配置。
删除状态页将同时清除其下的关联数据,此操作不可恢复。
diff --git a/zh/on-call/statuspage/get-started.mdx b/zh/on-call/statuspage/get-started.mdx
index 331d4a47..717e6fe7 100644
--- a/zh/on-call/statuspage/get-started.mdx
+++ b/zh/on-call/statuspage/get-started.mdx
@@ -4,11 +4,11 @@ description: "了解如何从零创建或从 Atlassian Statuspage 迁移到 Flas
keywords: ["状态页接入", "状态页入门", "Atlassian Statuspage 迁移", "公开状态页", "内部状态页"]
---
-首次接入 Flashduty 状态页时,你可以从零创建一个新状态页,也可以从 Atlassian Statuspage 迁移到 Flashduty 状态页。本文分别说明这两种接入路径的必要步骤。
+首次接入 Flashduty 状态页时,您可以从零创建一个新状态页,也可以从 Atlassian Statuspage 迁移到 Flashduty 状态页。本文分别说明这两种接入路径的必要步骤。
-状态页创建或迁移完成后,组件、分组、事件模板、订阅和事件发布都属于后续配置。你可以在本文末尾跳转到对应文档。
+状态页创建或迁移完成后,组件、分组、事件模板、订阅和事件发布都属于后续配置。您可以在本文末尾跳转到对应文档。
-如果你还不了解状态页的基本概念,先阅读[什么是状态页](/zh/on-call/statuspage/statuspage)。
+如果您还不了解状态页的基本概念,先阅读[什么是状态页](/zh/on-call/statuspage/statuspage)。
---
@@ -19,7 +19,7 @@ keywords: ["状态页接入", "状态页入门", "Atlassian Statuspage 迁移",
| 还没有正式状态页 | 从零创建 Flashduty 状态页 | [从零创建状态页](#从零创建状态页) |
| 已经使用 Atlassian Statuspage | 迁移结构、历史事件和订阅者 | [从 Atlassian Statuspage 迁移](#从-atlassian-statuspage-迁移) |
-如果你正在评估是否替换 Atlassian Statuspage,可以先阅读[状态页对比](/zh/on-call/statuspage/comparison)。
+如果您正在评估是否替换 Atlassian Statuspage,可以先阅读[状态页对比](/zh/on-call/statuspage/comparison)。
---
@@ -55,7 +55,7 @@ keywords: ["状态页接入", "状态页入门", "Atlassian Statuspage 迁移",
## 从 Atlassian Statuspage 迁移
-如果你已经在使用 Atlassian Statuspage,可以使用 Flashduty CLI 将**组件、分组、历史事件和邮件订阅者**迁移到 Flashduty 状态页。
+如果您已经在使用 Atlassian Statuspage,可以使用 Flashduty CLI 将**组件、分组、历史事件和邮件订阅者**迁移到 Flashduty 状态页。
<Tip>
**版本要求**:迁移功能(结构与历史迁移、邮件订阅者迁移)需要 Flashduty **专业版**。
@@ -66,10 +66,10 @@ keywords: ["状态页接入", "状态页入门", "Atlassian Statuspage 迁移",
1. **迁移结构与历史**:导入组件、分组、历史事件、维护记录和通知模板。
2. **迁移邮件订阅者**:导入订阅者列表及其订阅偏好。
-两步分离的原因是:迁移结构时**不会**向订阅者发送通知。你可以先检查导入内容是否正确,再决定是否导入订阅者。导入的订阅者会直接变为活跃状态,无需重新邮件验证。
+两步分离的原因是:迁移结构时**不会**向订阅者发送通知。您可以先检查导入内容是否正确,再决定是否导入订阅者。导入的订阅者会直接变为活跃状态,无需重新邮件验证。
<Tip>
-如果你使用 Codex、Claude Code、Cursor 等 AI 编程代理,也可以先按 [flashduty-cli README](https://github.com/flashcatcloud/flashduty-cli/blob/main/README_zh.md) 中的 Agent Skills 指引安装技能。安装后,`flashduty-statuspage` skill 会向代理提供 Atlassian Statuspage 迁移命令和注意事项,你可以让代理在本地终端协助执行迁移。
+如果您使用 Codex、Claude Code、Cursor 等 AI 编程代理,也可以先按 [flashduty-cli README](https://github.com/flashcatcloud/flashduty-cli/blob/main/README_zh.md) 中的 Agent Skills 指引安装技能。安装后,`flashduty-statuspage` skill 会向代理提供 Atlassian Statuspage 迁移命令和注意事项,您可以让代理在本地终端协助执行迁移。
</Tip>
### 准备工作
@@ -100,12 +100,12 @@ irm https://static.flashcat.cloud/flashduty-cli/install.ps1 | iex
flashduty login
```
-按提示输入 APP Key。获取方式:登录 [Flashduty 控制台](https://console.flashcat.cloud),进入 **个人中心 > 个人信息**,复制 APP Key。
+按提示输入 APP Key。获取方式:登录 [Flashduty 控制台](https://console.flashcat.cloud),进入 **个人中心 → 个人信息**,复制 APP Key。
#### 获取 Atlassian Statuspage API Key
1. 登录 [Atlassian Statuspage 管理面板](https://manage.statuspage.io/)
-2. 进入 **User icon > API info**,复制 API Key
+2. 进入 **User icon → API info**,复制 API Key
3. 设置环境变量:
```bash
@@ -178,7 +178,7 @@ export ATLASSIAN_STATUSPAGE_API_KEY="your_api_key_here"
flashduty status-page change-list <target_page_id> --type incident --status resolved
```
- 你也可以登录 [Flashduty 控制台](https://console.flashcat.cloud),在状态页管理界面中检查组件、分组和历史事件是否完整。
+ 您也可以登录 [Flashduty 控制台](https://console.flashcat.cloud),在状态页管理界面中检查组件、分组和历史事件是否完整。
</Step>
<Step title="迁移邮件订阅者">
diff --git a/zh/on-call/statuspage/publish-events.mdx b/zh/on-call/statuspage/publish-events.mdx
index 734f5237..c90717c7 100644
--- a/zh/on-call/statuspage/publish-events.mdx
+++ b/zh/on-call/statuspage/publish-events.mdx
@@ -59,7 +59,7 @@ description: "了解如何在状态页中发布故障和维护事件,管理事
</Note>
</Step>
<Step title="添加初始更新">
- 每个事件至少包含一条时间线更新。系统会根据你填写的信息自动生成初始更新记录。
+ 每个事件至少包含一条时间线更新。系统会根据您填写的信息自动生成初始更新记录。
</Step>
<Step title="发布事件">
确认信息后,点击 **发布故障** 或 **发布维护** 完成事件创建。
@@ -68,7 +68,7 @@ description: "了解如何在状态页中发布故障和维护事件,管理事
### 组件影响状态
-发布事件时,你需要为每个受影响组件指定当前的服务状态:
+发布事件时,您需要为每个受影响组件指定当前的服务状态:
<Tabs>
<Tab title="故障影响状态">
@@ -116,7 +116,7 @@ description: "了解如何在状态页中发布故障和维护事件,管理事
## 时间线更新
-事件发布后,你可以通过添加**时间线更新**来记录事件的进展,让订阅者持续了解最新情况。
+事件发布后,您可以通过添加**时间线更新**来记录事件的进展,让订阅者持续了解最新情况。
每条时间线更新可以包含:
@@ -154,7 +154,7 @@ description: "了解如何在状态页中发布故障和维护事件,管理事
## 维护自动调度
-对于维护事件,你可以设置**计划开始时间**和**计划结束时间**,并启用**按计划自动更新**功能。系统将在指定时间自动推进维护状态:
+对于维护事件,您可以设置**计划开始时间**和**计划结束时间**,并启用**按计划自动更新**功能。系统将在指定时间自动推进维护状态:
- **计划开始时间**到达时:自动将状态从"已排期"更新为"进行中"
- **计划结束时间**到达时:自动将状态从"进行中"更新为"已完成"
@@ -165,10 +165,10 @@ description: "了解如何在状态页中发布故障和维护事件,管理事
### 手动覆盖
-即使启用了自动调度,你仍然可以随时手动更新维护状态:
+即使启用了自动调度,您仍然可以随时手动更新维护状态:
-- 如果你手动将维护推进为"进行中",系统会取消待执行的自动开始任务
-- 如果你手动将维护标记为"已完成",系统会取消待执行的自动结束任务
+- 如果您手动将维护推进为"进行中",系统会取消待执行的自动开始任务
+- 如果您手动将维护标记为"已完成",系统会取消待执行的自动结束任务
删除已启用自动调度的维护事件时,系统会自动取消所有待执行的调度任务。
@@ -176,9 +176,9 @@ description: "了解如何在状态页中发布故障和维护事件,管理事
## 回溯事件
-当服务状态变化未能及时发布时,你可以创建**回溯事件**(Retrospective Event)来补充历史记录。
+当服务状态变化未能及时发布时,您可以创建**回溯事件**(Retrospective Event)来补充历史记录。
-回溯事件允许你:
+回溯事件允许您:
- 声明一次已经发生的故障或维护
- 精确设置事件的发生时间和结束时间
diff --git a/zh/on-call/statuspage/statuspage.mdx b/zh/on-call/statuspage/statuspage.mdx
index 86e24864..6f4324f1 100644
--- a/zh/on-call/statuspage/statuspage.mdx
+++ b/zh/on-call/statuspage/statuspage.mdx
@@ -7,12 +7,12 @@ keywords: ["状态页", "服务状态", "可用性", "故障通报", "外部沟
<Tip>**版本要求**:所有版本均可创建公开状态页(免费版和标准版最多 1 个,专业版最多 5 个)。内部状态页仅在专业版中提供(最多 20 个)。[了解更多](https://flashcat.cloud/flashduty/price/)</Tip>
<Note>
-**创建状态页的两条准入规则**:列表页入口与创建页本身都会校验,直接访问创建页也绕不过去。
+以下情况无法新建状态页(已创建的状态页不受影响,仍可编辑和发布事件):
-- **订阅过期或被停用时不能新建**:列表页的创建按钮被禁用;直接打开创建页会返回一个空状态页,标题为「订阅已过期,暂时无法新建」,正文为「续费后即可继续创建状态页。」与「已创建的状态页仍在正常对外展示,可随时编辑。」,主按钮变为 **立即续费**(另有 **返回列表**)。已创建的状态页仍正常对外展示,发布事件、编辑与订阅通知都不受影响,续费后即可继续创建。
-- **内部状态页要求专业版及以上**:创建页可被直接访问(`/status-page/create?type=internal`),所以除列表页入口上的版本门槛外,创建页内会再校验一次版本;版本不足时同样返回空状态页,标题为「暂无权限」,正文为「内部状态页仅向专业版及以上版本用户开放。」与「已创建的状态页仍在正常对外展示,可随时编辑。」,主按钮为 **去升级**(另有 **返回列表**)。
+- 订阅过期或被停用:续费后可继续创建。
+- 内部状态页:需专业版及以上。
-订阅过期对其他功能的影响见[订阅过期后会发生什么](/zh/platform/pricing#订阅过期后会发生什么)。
+详见[订阅过期后会发生什么](/zh/platform/pricing#订阅过期后会发生什么)。
</Note>
服务中断不可避免,但沟通效率可以系统性提升。
@@ -71,7 +71,7 @@ keywords: ["状态页", "服务状态", "可用性", "故障通报", "外部沟
### 组件与分组
-状态页通过**组件**(Component)来组织和呈现不同的服务,相关联的组件可进行**分组**(Grouping),使状态页结构更加清晰。
+状态页通过**组件**(Component)来组织和呈现不同的服务。一个组件代表系统中的一个功能模块,事件会标明影响了哪些组件,影响范围因此一目了然。相关联的组件可进行**分组**(Grouping)。
### 事件类型
@@ -122,61 +122,32 @@ keywords: ["状态页", "服务状态", "可用性", "故障通报", "外部沟
- 公开状态页:对所有公网用户开放,无需登录即可访问。
-- 内部状态页:仅限组织内部用户访问,需使用对应的 Flashduty 账号登录。
+- 内部状态页:仅限组织内部用户访问,需使用对应的 Flashduty 账号登录。
**管理权限**
-Flashduty 状态页的管理遵循 Flashduty 的 RBAC 权限模型。管理员可为账户成员分配以下两类角色:
+Flashduty 状态页的管理遵循 Flashduty 的 RBAC 权限模型。管理员可为账户成员分配以下两类角色:
- **状态页管理**:创建、编辑和删除状态页,管理订阅。
- **状态页事件管理**:在状态页中发布、编辑和删除事件。
</Accordion>
-<Accordion title="状态页支持发布哪些事件?" defaultClose>
-Flashduty 状态页支持两类事件:**故障**(Incident)和**维护**(Maintenance)。
-
-- 故障是意外发生的影响服务可用性的事件。
-
-- 维护是计划之内的事件,用于提前通知用户可能的服务可用性变动。
-</Accordion>
-
-
<Accordion title="如何向状态页中发布事件?" defaultClose>
-目前,向 Flashduty 状态页中发布事件需要在状态页管理页面中手动声明。为了简化事件的发布流程,Flashduty 状态页支持事件模板,让技术团队能够通过模板快速发布故障或计划维护,只需少量操作即可生成完整的状态更新。
+目前,向 Flashduty 状态页中发布事件需要在状态页管理页面中手动声明。为了简化事件的发布流程,Flashduty 状态页支持事件模板,让技术团队能够通过模板快速发布故障或计划维护,只需少量操作即可生成完整的状态更新。
-在不久的将来,我们还将为 Flashduty Oncall 的故障管理部分提供 Workflow 支持。届时,Flashduty 将支持通过编写预设规则,为推送到平台的故障自动在相关状态页上发布对应事件,实现 Oncall 故障与状态页的无缝衔接。
+在不久的将来,我们还将为 Flashduty On-call 的故障管理部分提供 Workflow 支持。届时,Flashduty 将支持通过编写预设规则,为推送到平台的故障自动在相关状态页上发布对应事件,实现 On-call 故障与状态页的无缝衔接。
</Accordion>
-<Accordion title="状态页中的服务是如何划分的?" defaultClose>
-Flashduty 状态页通过**组件**(Component)来组织和呈现不同的服务。组件代表系统或服务中的具体功能模块,基于组件的状态页架构可以将整体服务拆分为多个独立的功能单元,从而清晰地界定事件对不同服务的影响范围。相关联的组件可进行**分组**(Grouping),使状态页结构更加清晰有序。
-
-故障对组件的影响状态可按严重程度进行划分:
-
-- **运行正常**(Operational)
-
-- **性能下降**(Degraded performance)
-
-- **部分中断**(Partial Outage)
-
-- **完全中断**(Full outage)
-
-维护对组件的影响状态可按严重程度进行划分:
-
-- **运行正常**(Operational)
-
-- **维护中**(Under maintenance)
-</Accordion>
-
<Accordion title="用户如何订阅状态页更新?" defaultClose>
-Flashduty 状态页允许用户主动订阅服务状态更新。在向状态页内发布事件时,可以选择是否为该事件向订阅者发送通知,从而灵活控制信息推送。
+Flashduty 状态页允许用户主动订阅服务状态更新。在向状态页内发布事件时,可以选择是否为该事件向订阅者发送通知,从而灵活控制信息推送。
- 对于公开状态页,用户可通过电子邮件接收事件更新。

-- 对于内部状态页,用户可在 Flashduty 的通知配置中绑定偏好的 IM 集成,实现 IM 平台内的单聊通知的实时推送。Flashduty 目前实现了对飞书、钉钉、企业微信、Slack 的通知支持。
+- 对于内部状态页,用户可在 Flashduty 的通知配置中绑定偏好的 IM 集成,接收单聊推送。目前支持飞书、钉钉、企业微信和 Slack。公开状态页只支持邮件订阅,不支持 IM 订阅。

</Accordion>
@@ -185,19 +156,19 @@ Flashduty 状态页允许用户主动订阅服务状态更新。在向状态页
</Accordion>
<Accordion title="状态页的服务可用性统计指标的计算原理?" defaultClose>
-组件的**部分中断**(Partial outage)或**完全中断**(Full outage)会计入该组件的不可用时间(Downtime)。虽然维护可能对服务产生影响,但其影响时间不计入服务可用性统计(Service uptime)。
+组件的**部分中断**(Partial outage)或**完全中断**(Full outage)会计入该组件的不可用时间(Downtime)。虽然维护可能对服务产生影响,但其影响时间不计入服务可用性统计(Service uptime)。
-组件的服务可用性统计基于最近一个季度的数据窗口计算,其值等于组件的可用时间(Uptime) 和总存在时间(Available time)的比值。
+组件的服务可用性统计基于最近一个季度的数据窗口计算,其值等于组件的可用时间(Uptime) 和总存在时间(Available time)的比值。
分组的可用性统计同样以季度为单位计算,其值等于该分组下所有组件的可用时间之和与总存在时间之和的比值。
-系统通过回放事件时间线中的组件状态变更来精确计算每个组件的影响时段。**维护**事件遵循独立的计算规则:组件仅在维护实际执行窗口内(状态变为"进行中"到关闭)被标记为"维护中",尚未开始的计划维护不会影响可用性图表与日历展示。被设为"完全隐藏"的组件和分组不参与可用性统计;被设为"隐藏可用性"的组件和分组参与计算但不对外展示统计结果。你可以在状态页设置中选择可用性统计的展示模式:同时展示图表与百分比、仅展示图表、或完全不展示。
+系统通过回放事件时间线中的组件状态变更来精确计算每个组件的影响时段。**维护**事件遵循独立的计算规则:组件仅在维护实际执行窗口内(状态变为"进行中"到关闭)被标记为"维护中",尚未开始的计划维护不会影响可用性图表与日历展示。被设为"完全隐藏"的组件和分组不参与可用性统计;被设为"隐藏可用性"的组件和分组参与计算但不对外展示统计结果。您可以在状态页设置中选择可用性统计的展示模式:同时展示图表与百分比、仅展示图表、或完全不展示。
</Accordion>
<Accordion title="状态页是否支持上传历史服务可用性数据?" defaultClose>
有时,技术团队往往需要优先投入资源进行排查和修复,无法同步、完整地更新状态页;在系统迁移时,也需要将既有的可用性记录呈现在状态页中。
-Flashduty 状态页提供发布**回溯事件**(Retrospective event)能力,用于补充已发生但未能及时对外发布的服务状态变化。
+Flashduty 状态页提供发布**回溯事件**(Retrospective event)能力,用于补充已发生但未能及时对外发布的服务状态变化。
通过回溯事件,用户可以事后声明一次已经发生的故障或维护,并准确设置事件的发生时间、结束时间以及受影响的组件。和普通事件相同,用户同样可以按真实时间顺序构建事件更新的时间线,清晰呈现服务在整个事件周期内的状态变化。
@@ -205,11 +176,11 @@ Flashduty 状态页提供发布**回溯事件**(Retrospective event)能力
</Accordion>
<Accordion title="状态页是否支持暗色模式?" defaultClose>
-Flashduty 状态页支持暗色模式。你可以分别上传**标准 Logo** 和**暗色 Logo**,系统会根据用户的浏览器主题自动切换对应的 Logo。如果仅上传了标准 Logo,暗色模式下也会使用标准 Logo。
+Flashduty 状态页支持暗色模式。您可以分别上传**标准 Logo** 和**暗色 Logo**,系统会根据用户的浏览器主题自动切换对应的 Logo。如果仅上传了标准 Logo,暗色模式下也会使用标准 Logo。
</Accordion>
<Accordion title="状态页是否支持自定义域名?" defaultClose>
-支持。你可以为状态页配置自定义域名(如 `status.yourcompany.com`),只需在 DNS 服务商中添加 CNAME 记录指向 Flashduty 提供的状态页地址,并在状态页设置中填写自定义域名。自定义域名在全平台范围内必须唯一,不能被多个状态页共用。
+支持。您可以为状态页配置自定义域名(如 `status.yourcompany.com`),只需在 DNS 服务商中添加 CNAME 记录指向 Flashduty 提供的状态页地址,并在状态页设置中填写自定义域名。自定义域名在全平台范围内必须唯一,不能被多个状态页共用。
</Accordion>
<Accordion title="自定义域名如何获得 HTTPS 证书?" defaultClose>
@@ -223,24 +194,20 @@ Flashduty 状态页支持暗色模式。你可以分别上传**标准 Logo** 和
如果域名仍指向旧兼容入口 `statuspage.flashcat.cloud`,只要证书托管记录校验通过,系统也会提前签发并发布证书,之后将 DNS 切换到托管访问入口时不会出现 HTTPS 中断。
</Accordion>
-<Accordion title="内部状态页支持哪些 IM 通知渠道?" defaultClose>
-内部状态页支持通过 IM 集成向组织内部用户发送事件通知。用户需在 Flashduty 的通知配置中绑定 IM 账号后即可接收单聊推送。目前支持的 IM 平台包括飞书(Lark)、钉钉、企业微信和 Slack。公开状态页不支持 IM 订阅,仅支持邮件订阅。
-</Accordion>
-
<Accordion title="状态页如何收费?" defaultClose>
-Flashduty 状态页是 **Oncall 模块** 的一部分,不单独进行售卖。不同版本的 Flashduty 账户在状态页数量上的支持如下:
+Flashduty 状态页是 **On-call 模块** 的一部分,不单独进行售卖。不同版本的 Flashduty 账户在状态页数量上的支持如下:
-- Flashduty 免费版、标准版:支持创建 1 个公开状态页
+- Flashduty 免费版、标准版:支持创建 1 个公开状态页
-- Flashduty 专业版、私有化:支持创建 5 个公开状态页,支持创建 20 个内部状态页。
+- Flashduty 专业版、私有化:支持创建 5 个公开状态页,支持创建 20 个内部状态页。
-我们推荐客户按照业务线或者大平台维度来规划和管理内部状态页。如您对状态页数量有特殊的需求,欢迎联系 Flashduty 客服或技术支持进行咨询。
+我们推荐客户按照业务线或者大平台维度来规划和管理内部状态页。如您对状态页数量有特殊的需求,欢迎联系 Flashduty 客服或技术支持进行咨询。
在通知用量和访问控制方面:
-- 公开状态页的邮件通知受[不同 Flashduty 版本](https://flashcat.cloud/flashduty/price/)的邮件用量约束。
+- 公开状态页的邮件通知受[不同 Flashduty 版本](https://flashcat.cloud/flashduty/price/)的邮件用量约束。
-- 内部状态页的 IM 推送通知受不同 IM 平台的 API 调用限额约束,通常和组织使用的 IM 定价方案有关。
+- 内部状态页的 IM 推送通知受不同 IM 平台的 API 调用限额约束,通常和组织使用的 IM 定价方案有关。
- 所有类型的状态页的访问流量均无上限。
</Accordion>
diff --git a/zh/on-call/statuspage/subscriptions.mdx b/zh/on-call/statuspage/subscriptions.mdx
index a0f321cb..dcf3fffe 100644
--- a/zh/on-call/statuspage/subscriptions.mdx
+++ b/zh/on-call/statuspage/subscriptions.mdx
@@ -3,7 +3,7 @@ title: "订阅管理"
description: "了解如何管理状态页订阅者,包括邮件确认、组件级订阅和批量导入导出"
---
-Flashduty 状态页允许用户主动订阅服务状态更新。当状态页中有新事件发布或事件状态变更时,你可以选择向订阅者推送通知。
+Flashduty 状态页允许用户主动订阅服务状态更新。当状态页中有新事件发布或事件状态变更时,您可以选择向订阅者推送通知。
---
@@ -72,7 +72,7 @@ Feed 仅对**公开状态页**开放。对内部状态页或不存在的状态
</Note>
<Tip>
-如果你正在从 Atlassian Statuspage 迁移,可以直接把原有的 `history.rss` / `history.atom` 订阅地址替换为 Flashduty 状态页地址,无需修改订阅者配置。
+如果您正在从 Atlassian Statuspage 迁移,可以直接把原有的 `history.rss` / `history.atom` 订阅地址替换为 Flashduty 状态页地址,无需修改订阅者配置。
</Tip>
---
@@ -100,7 +100,7 @@ Feed 仅对**公开状态页**开放。对内部状态页或不存在的状态
订阅通知的用量规则:
- **邮件(公开状态页)**:事件通知邮件计入 Flashduty 账户的邮件用量。免费版账户的邮件用量超出限额后,事件通知邮件将暂停发送;付费版账户超出限额的邮件将单独计费,仅当账户欠费时暂停发送。
-- **IM(内部状态页)**:事件通知计入对应 IM 平台的 API 调用用量,超出 IM 平台的限额时通知将暂停发送。API 调用限额通常与你的组织使用的 IM 平台定价方案有关。
+- **IM(内部状态页)**:事件通知计入对应 IM 平台的 API 调用用量,超出 IM 平台的限额时通知将暂停发送。API 调用限额通常与您的组织使用的 IM 平台定价方案有关。
### 查看订阅者
@@ -156,6 +156,6 @@ Feed 仅对**公开状态页**开放。对内部状态页或不存在的状态
## 订阅与组件的关系
-当你删除一个组件时,系统会自动清除该组件相关的所有订阅记录。订阅了该组件的用户将不再收到相关通知。
+当您删除一个组件时,系统会自动清除该组件相关的所有订阅记录。订阅了该组件的用户将不再收到相关通知。
-同样,当你删除一个事件时,系统会自动清除该事件相关的所有订阅记录。
+同样,当您删除一个事件时,系统会自动清除该事件相关的所有订阅记录。
diff --git a/zh/on-call/statuspage/templates.mdx b/zh/on-call/statuspage/templates.mdx
index 1409479b..e74617c1 100644
--- a/zh/on-call/statuspage/templates.mdx
+++ b/zh/on-call/statuspage/templates.mdx
@@ -3,7 +3,7 @@ title: "事件模板"
description: "了解如何使用完整状态更新和状态描述模板快速发布状态页事件"
---
-手动填写事件信息耗时且容易遗漏关键内容。Flashduty 状态页提供**事件模板**功能,让你通过预设的内容快速发布事件,减少重复操作。
+手动填写事件信息耗时且容易遗漏关键内容。Flashduty 状态页提供**事件模板**功能,让您通过预设的内容快速发布事件,减少重复操作。
状态页支持两种模板类型:**完整状态更新**(预定义模板)和**状态描述**(消息模板)。
@@ -34,10 +34,10 @@ description: "了解如何使用完整状态更新和状态描述模板快速发
在状态页设置的 **事件模板** 页签中,选择 **完整状态更新**,点击 **创建模板**,填写标题、类型、状态和描述。
</Step>
<Step title="使用模板">
- 在发布事件时,选择一个完整状态更新模板。系统会自动填充模板中的字段,你可以在此基础上进行调整。
+ 在发布事件时,选择一个完整状态更新模板。系统会自动填充模板中的字段,您可以在此基础上进行调整。
</Step>
<Step title="编辑或删除">
- 你可以随时修改模板的标题、描述和状态,或删除不再使用的模板。
+ 您可以随时修改模板的标题、描述和状态,或删除不再使用的模板。
</Step>
</Steps>
@@ -91,7 +91,7 @@ description: "了解如何使用完整状态更新和状态描述模板快速发
在添加事件时间线更新时,选择一个状态描述模板。系统会根据当前的事件状态自动填充对应的消息文本。
</Step>
<Step title="编辑或删除">
- 你可以随时更新模板的标题、类型和消息内容,或删除不再使用的模板。
+ 您可以随时更新模板的标题、类型和消息内容,或删除不再使用的模板。
</Step>
</Steps>
@@ -99,4 +99,4 @@ description: "了解如何使用完整状态更新和状态描述模板快速发
## 模板偏好设置
-你可以在状态页设置的 **事件模板** 页签顶部选择默认模板类型(**状态描述** 或 **完整状态更新**),发布事件时将优先展示对应类型的模板列表。此偏好设置不影响你切换到其他类型的模板。
+您可以在状态页设置的 **事件模板** 页签顶部选择默认模板类型(**状态描述** 或 **完整状态更新**),发布事件时将优先展示对应类型的模板列表。此偏好设置不影响您切换到其他类型的模板。
diff --git a/zh/on-call/statuspage/widgets.mdx b/zh/on-call/statuspage/widgets.mdx
index 1812890d..a8c83357 100644
--- a/zh/on-call/statuspage/widgets.mdx
+++ b/zh/on-call/statuspage/widgets.mdx
@@ -3,23 +3,25 @@ title: "嵌入组件(Widget)"
description: "将状态页的实时状态以状态徽标或事件横幅嵌入你的网站,或通过公开 JSON 接口自行集成"
---
-Flashduty 状态页提供**嵌入组件(Widget)**:一段可以直接粘贴到任意网站 HTML 中的代码,把状态页的实时状态展示在你的官网、帮助中心或内部系统里。Widget 以 Web Component 形式运行(`<flashduty-status-widget>`),样式与宿主页面隔离,不会相互影响。
+Flashduty 状态页提供**嵌入组件(Widget)**:一段可以直接粘贴到任意网站 HTML 中的代码,把状态页的实时状态展示在您的官网、帮助中心或内部系统里。Widget 以 Web Component 形式运行(`<flashduty-status-widget>`),样式与宿主页面隔离,不会相互影响。
<Warning>
嵌入组件仅适用于**公开状态页**。内部状态页的「嵌入组件」设置页不可用。
</Warning>
+<Tip>
+Widget 功能默认开启,您无需任何配置即可使用。私有化部署环境中,部署管理员可通过 `deploy.widgetEnabled` 开关整体关闭该功能(关闭后接口返回 404)。
+</Tip>
+
## 两种形态
| 形态 | 说明 | 适用场景 |
| --- | --- | --- |
-| **状态徽标**(Badge) | 始终显示当前整体状态,点击跳转到你的状态页 | 页脚、帮助中心等需要常显服务状态的位置 |
+| **状态徽标**(Badge) | 始终显示当前整体状态,点击跳转到您的状态页 | 页脚、帮助中心等需要常显服务状态的位置 |
| **事件横幅**(Banner) | 仅在发生故障或维护时显示,固定在页面顶部或底部,访客可关闭 | 官网、控制台等需要在故障期间主动告知访客的位置 |
两种形态都支持主题(自动 / 亮色 / 暗色)与语言(中文 / English)配置,徽标额外支持尺寸选择,横幅额外支持位置选择。
----
-
## 在控制台生成嵌入代码
<Steps>
@@ -30,7 +32,7 @@ Flashduty 状态页提供**嵌入组件(Widget)**:一段可以直接粘贴
在对应页签下调整主题、语言、尺寸(徽标)或位置(横幅),右侧**实时预览**会同步更新。预览仅用于查看效果,不会修改真实状态页;横幅还可以切换「运行正常 / 服务故障 / 已计划的维护」三种预览场景。
</Step>
<Step title="复制嵌入代码">
- 点击 **复制代码**,将嵌入代码粘贴到你网站的 HTML 中即可。嵌入代码中的脚本版本与你的状态页部署实际提供的版本保持一致,无需手工维护。
+ 点击 **复制代码**,将嵌入代码粘贴到您网站的 HTML 中即可。嵌入代码中的脚本版本与您的状态页部署实际提供的版本保持一致,无需手工维护。
</Step>
</Steps>
@@ -63,7 +65,7 @@ Flashduty 状态页提供**嵌入组件(Widget)**:一段可以直接粘贴
</CodeGroup>
<Note>
-脚本标签带有 `integrity`(SRI 校验)与 `crossorigin="anonymous"` 属性,请整段复制,不要只拷贝 `<flashduty-status-widget>` 标签。示例中的 `https://status.example.com` 请替换为你状态页的实际地址(控制台生成的代码中已是真实地址)。
+脚本标签带有 `integrity`(SRI 校验)与 `crossorigin="anonymous"` 属性,请整段复制,不要只拷贝 `<flashduty-status-widget>` 标签。示例中的 `https://status.example.com` 请替换为您状态页的实际地址(控制台生成的代码中已是真实地址)。
</Note>
### 属性参考
@@ -80,8 +82,6 @@ Flashduty 状态页提供**嵌入组件(Widget)**:一段可以直接粘贴
| `position` | `top` / `bottom` | `top` | 仅横幅 | 横幅固定在页面顶部或底部 |
| `show-upcoming-maintenance` | `true` / `false` | `true` | 仅横幅 | 计划维护是否在开始前 24 小时自动显示 |
----
-
## 行为说明
### 数据刷新
@@ -118,11 +118,9 @@ Flashduty 状态页提供**嵌入组件(Widget)**:一段可以直接粘贴
状态页中被设置为**隐藏**的组件不会出现在 Widget 数据中——快照只包含对外可见组件的故障与维护事件。
</Note>
----
-
## 公开接口 summary.json
-如果你不想使用现成的 Web Component,可以直接调用每个公开状态页自带的 JSON 快照接口,自行渲染或集成到你的监控体系中。控制台「嵌入组件 → API」页签展示了该地址。
+如果您不想使用现成的 Web Component,可以直接调用每个公开状态页自带的 JSON 快照接口,自行渲染或集成到您的监控体系中。控制台「嵌入组件 → API」页签展示了该地址。
```
GET {状态页地址}/api/widget/v1/summary.json
@@ -131,10 +129,10 @@ GET {状态页地址}/api/widget/v1/summary.json
- **公开访问**:无需鉴权、无需 API Key
- **跨域**:响应携带 `Access-Control-Allow-Origin: *`,浏览器可直接调用;支持 `GET`、`HEAD` 与 `OPTIONS`(预检)
- **缓存**:响应头 `Cache-Control: public, max-age=30, s-maxage=30, stale-while-revalidate=120, stale-if-error=3600`,并返回 `ETag`——携带 `If-None-Match` 且数据未变化时返回 `304`
-- **时效**:响应头 `X-Status-Validated-At` 表示快照最近一次从后端成功校验的时间,可据此判断数据是否过期
+- **时效**:响应头 `X-Status-Validated-At` 表示快照最近一次成功校验的时间,可据此判断数据是否过期
<Warning>
-该接口面向浏览器端低频轮询设计。**高流量场景下请通过你的服务端代理并缓存响应**,不要让大量客户端直连该地址。
+该接口面向浏览器端低频轮询设计。**高流量场景下请通过您的服务端代理并缓存响应**,不要让大量客户端直连该地址。
</Warning>
### 响应字段
@@ -231,7 +229,3 @@ GET {状态页地址}/api/widget/v1/summary.json
| --- | --- | --- |
| `404` | `{"error": "status_page_not_found"}` | 状态页不存在、非公开,或部署侧关闭了 Widget 功能 |
| `503` | `{"error": "widget_summary_unavailable"}` | 状态数据暂时不可用,请稍后重试 |
-
-<Tip>
-Widget 功能默认开启,你无需任何配置即可使用。私有化部署环境中,部署管理员可通过 `deploy.widgetEnabled` 开关整体关闭该功能(关闭后接口返回 404)。
-</Tip>
diff --git a/zh/openapi.mdx b/zh/openapi.mdx
index 20129407..c1067cc7 100644
--- a/zh/openapi.mdx
+++ b/zh/openapi.mdx
@@ -1,6 +1,6 @@
---
title: API 文档
-description: "Flashduty Open API 文档,用于访问和操作 FlashDuty 的实体数据"
+description: "Flashduty Open API 文档,用于访问和操作 Flashduty 的实体数据"
keywords: ["API", "Open API", "接口文档", "开发者"]
url: /zh/openapi/introduction
---
diff --git a/zh/openapi/go-sdk.mdx b/zh/openapi/go-sdk.mdx
deleted file mode 100644
index 95f7e87f..00000000
--- a/zh/openapi/go-sdk.mdx
+++ /dev/null
@@ -1,171 +0,0 @@
----
-title: "OpenAPI Go SDK"
-sidebarTitle: "Go SDK"
-description: "go-flashduty —— Flashduty Open API 官方 Go 客户端"
-keywords: ["Go SDK", "go-flashduty", "Golang", "Open API", "客户端", "SDK"]
----
-
-[`go-flashduty`](https://github.com/flashcatcloud/go-flashduty) 是 Flashduty Open API 的官方 Go 客户端:一个轻量、强类型的 SDK。它由本文档所依据的 OpenAPI 规范自动生成,覆盖全部 Open API 接口,并经过单元测试与线上环境端到端校验。
-
-如果你的服务使用 Go 编写,推荐用该 SDK 调用 Flashduty,而不是手写 HTTP 请求 —— 你可以直接拿到类型化的请求参数、响应结构和错误码,省去手动拼装 JSON 和解析响应的工作。
-
-<Tip>
-SDK 与 Open API 共用一套接口语义。本文档每个接口的请求/响应结构,都能在 SDK 中找到对应的类型。鉴权同样使用 [APP Key](/zh/openapi/introduction#认证方式),也可以改用 OAuth 访问令牌,见[配置选项](#配置选项)。
-</Tip>
-
-## 安装
-
-需要 Go 1.24 及以上版本。
-
-```bash
-go get github.com/flashcatcloud/go-flashduty
-```
-
-## 快速开始
-
-用 APP Key 创建客户端,按服务(`client.Incidents`、`client.Alerts`……)调用对应接口。每个方法对应一次 HTTP 调用,返回 `(*T, *Response, error)`:
-
-```go
-package main
-
-import (
- "context"
- "fmt"
- "log"
-
- flashduty "github.com/flashcatcloud/go-flashduty"
-)
-
-func main() {
- client, err := flashduty.NewClient("YOUR_APP_KEY")
- if err != nil {
- log.Fatal(err)
- }
-
- list, resp, err := client.Incidents.List(context.Background(), &flashduty.ListIncidentsRequest{
- Progress: "Triggered",
- ListOptions: flashduty.ListOptions{Limit: 20},
- })
- if err != nil {
- log.Fatal(err)
- }
-
- fmt.Printf("request_id=%s total=%d has_next=%t\n", resp.RequestID, resp.Total, resp.HasNextPage)
- for _, inc := range list.Items {
- fmt.Printf("[%s] %s\n", inc.IncidentSeverity, inc.Title)
- }
-}
-```
-
-## 设计理念
-
-<CardGroup cols={2}>
- <Card title="轻量、强类型" icon="feather">
- 每个方法只映射一次 HTTP 调用,返回 `(*T, *Response, error)`,不做跨接口的隐式数据拼装。
- </Card>
- <Card title="按服务分组" icon="layer-group">
- 所有接口按服务挂在客户端上(`client.Incidents`、`client.Alerts`……),由 OpenAPI 规范生成。
- </Card>
- <Card title="可组合传输层" icon="puzzle-piece">
- 重试、缓存、链路追踪、限流处理等横切能力,通过 `http.RoundTripper` 中间件用 `WithTransport` 组合。
- </Card>
- <Card title="可读的时间戳" icon="clock">
- 响应中的时间字段类型为 `Timestamp` / `TimestampMilli`,JSON、日志和 LLM 输出中呈现为 RFC3339,原始 epoch 仍可一键取回。
- </Card>
-</CardGroup>
-
-## 配置选项
-
-`NewClient` 接受一组可选项:
-
-```go
-client, err := flashduty.NewClient("YOUR_APP_KEY",
- flashduty.WithBaseURL("https://api.flashcat.cloud"),
- flashduty.WithTimeout(10*time.Second),
- flashduty.WithUserAgent("my-app/1.0"),
- flashduty.WithHTTPClient(customHTTPClient),
- flashduty.WithTransport(customRoundTripper),
- flashduty.WithLogger(myLogger),
- flashduty.WithRequestHeaders(staticHeaders),
- flashduty.WithRequestHook(func(req *http.Request) { /* 例如注入 traceparent */ }),
-)
-```
-
-### OAuth 访问令牌
-
-除 `NewClient` 外,SDK 还提供 `NewClientWithAccessToken(accessToken, opts...)`:它用 OAuth 访问令牌鉴权,在 JSON、GET 与文件上传请求上发送 `Authorization: Bearer <token>`,不再注入 `app_key` 查询参数;令牌为空直接返回错误,可选项与 `NewClient` 完全相同。令牌由 Flashduty 的 OAuth 授权服务器签发(地址即 API 基础地址),且只在签发它的部署上有效。
-
-```go
-client, err := flashduty.NewClientWithAccessToken(accessToken,
- flashduty.WithTimeout(10*time.Second),
-)
-```
-
-## 错误与限流
-
-SDK 返回类型化的错误,可用 `errors.As` 解析,也提供便捷断言函数(自动穿透被包装的错误):
-
-```go
-_, _, err := client.Incidents.Info(ctx, &flashduty.IncidentInfoRequest{IncidentID: "does-not-exist"})
-
-var apiErr *flashduty.ErrorResponse
-if errors.As(err, &apiErr) {
- fmt.Println(apiErr.Code, apiErr.RequestID)
-}
-
-var rl *flashduty.RateLimitError
-if errors.As(err, &rl) {
- time.Sleep(rl.RetryAfter)
-}
-
-// 便捷断言
-if flashduty.IsNotFound(err) { /* ... */ }
-if flashduty.IsRateLimited(err) { /* ... */ }
-switch flashduty.ErrorCodeOf(err) {
-case flashduty.ErrorCodeAccessDenied, flashduty.ErrorCodeUnauthorized:
- // 处理鉴权失败
-}
-```
-
-错误码与 [错误码列表](/zh/openapi/introduction#错误码列表) 一一对应。
-
-## 时间戳
-
-响应中的时间字段类型为 `Timestamp`(Unix 秒)或 `TimestampMilli`(毫秒)。它们序列化为本地时区的 RFC3339 字符串,反序列化时既接受数字 epoch 也接受 RFC3339 字符串,可无损往返。零值保持数字 `0`(不会变成 1970 年),并被 `omitempty` 丢弃。
-
-```go
-inc := list.Items[0]
-fmt.Println(inc.StartTime) // 2026-05-30T14:37:11+08:00 (String / fmt / TOON)
-b, _ := json.Marshal(inc.StartTime) // "2026-05-30T14:37:11+08:00"
-epoch := inc.StartTime.Unix() // 1779514631 (原始 wire 值)
-t := inc.StartTime.Time() // time.Time
-```
-
-<Note>
-请求中的时间字段仍为普通 `int64` —— API 在 wire 上期望数字 epoch。多数接口使用**秒**,但 RUM 和 webhook 历史类接口使用**毫秒**。
-</Note>
-
-## 重试
-
-核心库默认**不**内置重试。可用可选的 `retry` 子包在传输层组合:一个安全默认的重试 `http.RoundTripper`(对 429 和 5xx 重试,遵循 `Retry-After`,确定性指数退避,仅重放 body 可重放的请求 —— SDK 的请求都满足):
-
-```go
-import "github.com/flashcatcloud/go-flashduty/retry"
-
-client, err := flashduty.NewClient("YOUR_APP_KEY",
- flashduty.WithTransport(retry.New(
- retry.WithMaxRetries(3),
- )),
-)
-```
-
-## 相关资源
-
-<CardGroup cols={2}>
- <Card title="GitHub 仓库" icon="github" href="https://github.com/flashcatcloud/go-flashduty">
- 源码、完整 README 与 Issue。开源协议 Apache-2.0。
- </Card>
- <Card title="API 总览" icon="list" href="/zh/openapi/api-catalog">
- 浏览全部接口 —— 每个接口都能在 SDK 中找到对应的类型化方法。
- </Card>
-</CardGroup>
diff --git a/zh/openapi/introduction.mdx b/zh/openapi/introduction.mdx
index a526db01..9998035f 100644
--- a/zh/openapi/introduction.mdx
+++ b/zh/openapi/introduction.mdx
@@ -64,7 +64,7 @@ Content-Type: application/json
APP Key 的实际可访问范围同时受其权限范围和创建者当前角色权限限制。创建成功后请立即妥善保存完整密钥;离开创建页面后无法再次查看。
</Warning>
-你可以在 APP Key 列表中编辑已有密钥的名称和权限范围。
+您可以在 APP Key 列表中编辑已有密钥的名称和权限范围。
### 使用示例
@@ -77,7 +77,7 @@ curl -X POST 'https://api.flashcat.cloud/your/api/path?app_key=YOUR_APP_KEY' \
```
<Note>
-使用 Go?推荐用官方 [Go SDK](/zh/openapi/go-sdk) 调用 Flashduty,直接获得类型化的请求参数、响应结构和错误码,无需手写 HTTP 请求。
+使用 Go?推荐用官方 [Go SDK](/zh/developer/go-sdk) 调用 Flashduty,直接获得类型化的请求参数、响应结构和错误码,无需手写 HTTP 请求。
</Note>
---
@@ -218,17 +218,7 @@ curl -X POST 'https://api.flashcat.cloud/your/api/path?app_key=YOUR_APP_KEY' \
## 最佳实践
-<CardGroup cols={2}>
- <Card title="实现重试机制" icon="rotate">
- 对于网络错误和 5xx 错误,建议实现指数退避重试,初始间隔 1 秒,最大重试 3 次。
- </Card>
- <Card title="记录 request_id" icon="clipboard-list">
- 保存每次请求返回的 `request_id`,便于问题排查和技术支持。
- </Card>
- <Card title="保护 APP Key" icon="shield-check">
- 不要在客户端代码中硬编码 APP Key,建议通过环境变量或配置中心管理。
- </Card>
- <Card title="定期轮换密钥" icon="key">
- 定期更换 APP Key,及时删除不再使用的密钥,降低泄露风险。
- </Card>
-</CardGroup>
+- **实现重试机制**:对于网络错误和 5xx 错误,建议实现指数退避重试,初始间隔 1 秒,最大重试 3 次。
+- **记录 request_id**:保存每次请求返回的 `request_id`,便于问题排查和技术支持。
+- **保护 APP Key**:不要在客户端代码中硬编码 APP Key,建议通过环境变量或配置中心管理。
+- **定期轮换密钥**:定期更换 APP Key,及时删除不再使用的密钥,降低泄露风险。
diff --git a/zh/openapi/pagination.mdx b/zh/openapi/pagination.mdx
index 7365879a..48eb839f 100644
--- a/zh/openapi/pagination.mdx
+++ b/zh/openapi/pagination.mdx
@@ -8,8 +8,6 @@ keywords: ["API分页", "游标分页", "传统分页", "OFFSET", "LIMIT", "SEAR
## 传统分页
----
-
我们把基于 OFFSET 和 LIMIT 查询的分页技术定义为传统分页。在大多数 Flashduty 列表查询 API 中,您可以看到以下参数定义:
### 请求参数
@@ -72,8 +70,6 @@ keywords: ["API分页", "游标分页", "传统分页", "OFFSET", "LIMIT", "SEAR
## 游标分页
----
-
我们把基于 SEARCH_AFTER_CTX 分页的技术定义为游标分页。游标分页技术可以更好地处理大数据集和高性能要求,并提供更稳定和高效的分页查询体验。
### 支持的 API
@@ -124,8 +120,6 @@ keywords: ["API分页", "游标分页", "传统分页", "OFFSET", "LIMIT", "SEAR
## 关于 TOTAL
----
-
无论使用哪种分页技术,Flashduty 都会给您返回 `total` 和 `has_next_page` 参数。但是,请注意,`total` 值并不始终准确,为了保证系统可以快速响应,我们增加了以下限制:
<Warning>
diff --git a/zh/openapi/rate-limits.mdx b/zh/openapi/rate-limits.mdx
index 70075b2d..78c0bbd2 100644
--- a/zh/openapi/rate-limits.mdx
+++ b/zh/openapi/rate-limits.mdx
@@ -6,8 +6,6 @@ keywords: ["API限流", "错误码", "频率限制", "权限限制", "最佳实
## 请求限制
----
-
### 频率限制
为保证服务稳定性,API 对请求频率有一定限制。当请求过于频繁时,将返回 `429` 状态码和 `RequestTooFrequently` 错误。
@@ -27,8 +25,6 @@ keywords: ["API限流", "错误码", "频率限制", "权限限制", "最佳实
## 错误码列表
----
-
| 错误码 | HTTP Status | 描述 |
| --- | :---: | --- |
| `InvalidParameter` | 400 | 参数错误,请检查请求参数是否正确 |
@@ -46,8 +42,6 @@ keywords: ["API限流", "错误码", "频率限制", "权限限制", "最佳实
## 错误处理建议
----
-
<AccordionGroup>
<Accordion title="400 参数错误">
**可能原因**:
@@ -102,19 +96,7 @@ keywords: ["API限流", "错误码", "频率限制", "权限限制", "最佳实
## 最佳实践
----
-
-<CardGroup cols={2}>
- <Card title="实现重试机制" icon="rotate">
- 对于网络错误和 5xx 错误,建议实现指数退避重试,初始间隔 1 秒,最大重试 3 次。
- </Card>
- <Card title="记录 request_id" icon="clipboard-list">
- 保存每次请求返回的 `request_id`,便于问题排查和技术支持。
- </Card>
- <Card title="保护 APP Key" icon="shield-check">
- 不要在客户端代码中硬编码 APP Key,建议通过环境变量或配置中心管理。
- </Card>
- <Card title="定期轮换密钥" icon="key">
- 定期更换 APP Key,及时删除不再使用的密钥,降低泄露风险。
- </Card>
-</CardGroup>
+- **实现重试机制**:对于网络错误和 5xx 错误,建议实现指数退避重试,初始间隔 1 秒,最大重试 3 次。
+- **记录 request_id**:保存每次请求返回的 `request_id`,便于问题排查和技术支持。
+- **保护 APP Key**:不要在客户端代码中硬编码 APP Key,建议通过环境变量或配置中心管理。
+- **定期轮换密钥**:定期更换 APP Key,及时删除不再使用的密钥,降低泄露风险。
diff --git a/zh/platform/audit-log.mdx b/zh/platform/audit-log.mdx
index 01b6b1b3..60ba73da 100644
--- a/zh/platform/audit-log.mdx
+++ b/zh/platform/audit-log.mdx
@@ -4,12 +4,10 @@ description: 查询和审查主体内所有成员的操作记录,追踪系统
keywords: ["审计日志", "操作审计", "安全合规", "操作记录"]
---
-审计日志记录了主体内所有成员的操作行为,帮助你追踪系统变更、排查异常操作、满足安全合规要求。你可以按时间范围、操作人、事件类型等条件灵活检索日志。
+审计日志记录了主体内所有成员的操作行为,帮助您追踪系统变更、排查异常操作、满足安全合规要求。您可以按时间范围、操作人、事件类型等条件灵活检索日志。
## 查看审计日志
----
-
**配置路径**:平台管理 → 审计日志
审计日志以表格形式展示,每条记录包含以下信息:
@@ -26,9 +24,7 @@ keywords: ["审计日志", "操作审计", "安全合规", "操作记录"]
## 筛选与检索
----
-
-审计日志提供多种筛选条件,帮助你快速定位目标操作:
+审计日志提供多种筛选条件,帮助您快速定位目标操作:
| 筛选条件 | 说明 |
| --- | --- |
@@ -38,14 +34,12 @@ keywords: ["审计日志", "操作审计", "安全合规", "操作记录"]
| **事件 ID** | 输入事件 ID 精确匹配特定操作记录 |
<Tip>
-多个筛选条件可以组合使用。例如,你可以同时指定时间范围和操作人,快速查找某位成员在特定时段内的所有操作。
+多个筛选条件可以组合使用。例如,您可以同时指定时间范围和操作人,快速查找某位成员在特定时段内的所有操作。
</Tip>
## 日志翻页
----
-
审计日志每页展示 10 条记录,通过页面底部的翻页按钮浏览更多记录。页面底部会显示当前页码和总页数。
<Note>
@@ -54,8 +48,6 @@ keywords: ["审计日志", "操作审计", "安全合规", "操作记录"]
## 常见问题
----
-
<AccordionGroup>
<Accordion title="审计日志可以导出吗?">
当前控制台不支持直接导出审计日志。如有导出需求,请联系技术支持。
diff --git a/zh/platform/configure-sso.mdx b/zh/platform/configure-sso.mdx
index 5991fd09..d02425f9 100644
--- a/zh/platform/configure-sso.mdx
+++ b/zh/platform/configure-sso.mdx
@@ -8,8 +8,6 @@ Flashduty 支持 SAML2.0、OIDC、CAS 和 LDAP(仅私有化版本)协议的
## 网络访问要求
----
-
不同协议对身份提供商(IdP)的网络可达性要求不同,配置前建议先确认,避免因网络不通导致登录失败:
| 协议 | 是否需要 Flashduty 访问身份提供商 | 说明 |
@@ -30,8 +28,6 @@ Flashduty 支持 SAML2.0、OIDC、CAS 和 LDAP(仅私有化版本)协议的
## 配置 SAML 协议
----
-
**配置路径**:平台管理 → 单点登录 → 开启 → 设置 → 选中 SAML2.0 协议类型
| 字段 | 描述 |
@@ -48,8 +44,6 @@ Flashduty 支持 SAML2.0、OIDC、CAS 和 LDAP(仅私有化版本)协议的
## 配置 OIDC 协议
----
-
**配置路径**:平台管理 → 单点登录 → 开启 → 设置 → 选中 OIDC 协议类型
| 字段 | 描述 |
@@ -73,8 +67,6 @@ Scopes 为必填字段。默认值 `openid`、`profile`、`email`、`phone` 是
## 配置 CAS 协议
----
-
**配置路径**:平台管理 → 单点登录 → 开启 → 设置 → 选中 CAS 协议类型
| 字段 | 描述 |
@@ -91,19 +83,75 @@ Scopes 为必填字段。默认值 `openid`、`profile`、`email`、`phone` 是
角色和团队可按身份提供商返回的名称同步,详见 [角色和团队映射](#角色和团队映射)。**默认角色和默认团队通常应留空,不启用默认兜底。**
-## 角色和团队映射
+## 配置 LDAP 协议
-OIDC、SAML2.0 和 CAS 支持按身份提供商返回的**角色名称、团队名称**同步成员权限和团队归属。LDAP 仍使用 [Group DN 映射](#ldap-角色和团队同步),不使用本节的名称映射。
+<Note>
+LDAP 单点登录仅**私有化版本**支持。
+</Note>
-**字段映射每次登录生效,默认值仅用于新建成员。** 开启对应同步并配置角色字段或团队字段后,每次 SSO 登录都会用有效匹配结果覆盖成员现有的角色或团队,包括手工分配的数据。没有匹配结果时,已有成员的对应数据保持不变;只有本次登录实际新建的成员才会使用已配置的有效默认值。角色与团队分别处理。
+**配置路径**:平台管理 → 单点登录 → 开启 → 设置 → 选中 LDAP 协议类型
-<Warning>
-**绝大多数情况下,请不要启用默认角色和默认团队兜底,保持两项默认值为空。**
+| 字段 | 描述 |
+| --- | --- |
+| 协议类型 | 选择 LDAP 协议 |
+| LDAP 链接 | LDAP 服务地址,如:`ldap://10.10.10.10:389` |
+| BIND DN | 用于连接 LDAP 的用户名,如:`cn=admin,dc=flashduty,dc=com` |
+| BIND DN 密码 | 用于连接 LDAP 的密码,将加密存储到数据库中 |
+| 加密机制 | 支持 **TLS** 和 **StartTLS** 两种加密方式(二者互斥,只能启用一种)。启用任一加密方式后,可选择 **跳过 SSL/TLS 证书验证**;如不跳过,可选填写 SSL/TLS 证书路径 |
+| 用户 DN | 定义从哪个目录开始搜索用户,如:`ou=people,dc=flashduty,dc=com` |
+| 认证过滤 | 用于检索用户 DN 信息的自定义 filter 表达式,基本形式为:`(&(mail=%s))`。注意:开始和结束的括号是必须的 |
+| 字段映射 | Flashduty 通过映射字段从身份提供商提取用户邮箱、用户名、手机和 Group 信息。邮箱为必填映射字段,Group 字段默认值为 `memberOf`,用于角色和团队同步 |
+| 稳定用户 ID 字段(`user_id`) | 可选。用于识别同一成员的用户唯一标识属性,邮箱或手机号变更不影响识别;留空时按下方邮箱/手机号字段匹配成员。建议值为 `uid`,也可使用 `entryUUID` 等稳定属性。详见下文 [成员关联方式](#成员关联方式) |
+| 登录即创建账号 | 默认开启,关闭后需要先邀请成员才可登录 |
+| 成员仅支持 SSO 登录(`force_sso`) | 默认开启。开启后,账户内所有成员仅能通过 SSO 登录,密码与验证码登录将被拒绝。详见下文 [强制 SSO 登录](#强制-sso-登录) |
-默认值**仅在本次 SSO 登录实际创建新成员、且对应角色或团队没有匹配结果时生效**。已有成员登录不会应用默认值,也不会因修改默认值而被重新分配权限。
+<Tip>
+字段映射需要和身份提供商的配置保持一致,否则会导致异常。具体配置可参考 [OpenLDAP 集成指引](/zh/on-call/integration/sso/openldap)。
+</Tip>
-默认值仍是这份 SSO 配置的统一规则,不是针对某个成员的单独设置。如果映射字段未填写、填写错误,或身份提供商未返回可匹配的名称,**所有通过该 SSO 新建且未匹配的成员都会获得相同的默认角色或加入相同的默认团队**。不要为了让登录测试通过而随意选择默认值,尤其不要将管理员等高权限角色或敏感团队设为通用默认值。
-</Warning>
+### LDAP 连接检测
+
+配置 LDAP 连接信息后,您可以在 **协议与连接** 分区的 LDAP 表单下方点击 **连接检测**,验证 Flashduty 能否成功连接到您的 LDAP 服务器。系统会使用当前填写的 LDAP 链接、BIND DN 和密码尝试建立连接,并返回连接成功或失败的结果。
+
+<Tip>
+建议在保存配置前先执行连接检测,确保连接参数正确无误,避免因配置错误导致成员无法通过 LDAP 登录。
+</Tip>
+
+### LDAP 角色和团队同步
+
+当您使用 LDAP 协议时,可以根据用户所属的 LDAP Group 自动同步 Flashduty 中的角色和团队。
+
+**配置路径**:LDAP 设置页面 → 同步配置
+
+<Steps>
+ <Step title="启用同步">
+ 在同步配置区域,分别开启 **同步角色** 和/或 **同步团队** 开关。
+ </Step>
+ <Step title="添加映射规则">
+ 点击 **添加映射规则**,为每条规则配置以下内容:
+
+ | 字段 | 说明 |
+ | --- | --- |
+ | **Group DN** | LDAP 中 Group 的完整 Distinguished Name,如 `cn=devops,ou=groups,dc=example,dc=com` |
+ | **映射角色** | 当同步角色开启时可选,选择该 Group 对应的 Flashduty 角色 |
+ | **映射团队** | 当同步团队开启时可选,选择该 Group 对应的 Flashduty 团队 |
+ </Step>
+ <Step title="配置默认角色">
+ 当同步角色开启时,您可以配置 **默认角色**。当用户的 LDAP Group 未匹配到任何映射规则时,系统将赋予这些默认角色。
+ </Step>
+</Steps>
+
+<Note>
+- 您可以添加多条映射规则,每条规则对应一个 LDAP Group
+- 用户登录时,系统会根据其 LDAP Group 成员关系自动匹配并同步对应的角色和团队
+- 映射规则中的 Group DN 必须是 LDAP 中 Group 的完整路径
+</Note>
+
+## 角色和团队映射
+
+OIDC、SAML2.0 和 CAS 支持按身份提供商返回的**角色名称、团队名称**同步成员权限和团队归属。LDAP 仍使用 [Group DN 映射](#ldap-角色和团队同步),不使用本节的名称映射。
+
+**字段映射每次登录生效,默认值仅用于新建成员。** 开启对应同步并配置角色字段或团队字段后,每次 SSO 登录都会用有效匹配结果覆盖成员现有的角色或团队,包括手工分配的数据。没有匹配结果时,已有成员的对应数据保持不变;只有本次登录实际新建的成员才会使用已配置的有效默认值。角色与团队分别处理。
### 配置字段
@@ -111,10 +159,10 @@ OIDC、SAML2.0 和 CAS 支持按身份提供商返回的**角色名称、团队
| 字段 | 配置方式 |
| --- | --- |
-| 同步角色(`sync_role_enabled`) | 开启后,每次 SSO 登录按有效映射结果更新角色;无匹配时,仅新建成员可使用默认角色。关闭则不执行角色同步 |
+| 同步角色(`sync_role_enabled`) | 开启后每次 SSO 登录按映射结果更新角色;关闭则不同步角色 |
| 角色字段(`roles`) | 填写返回角色名称的字段名,例如 `roles`,不是角色名称或 ID。开启角色同步后,**每次登录**按匹配结果覆盖现有角色,包括手工分配的角色 |
| 默认角色(`default_role_ids`) | 可多选。开启角色同步后,若返回的角色名称未匹配到任何可用角色,**仅本次登录新建的成员**会同步这些默认角色;已有成员不受影响。**通常保持为空** |
-| 同步团队(`sync_team_enabled`) | 开启后,每次 SSO 登录按有效映射结果更新团队归属;无匹配时,仅新建成员可使用默认团队。关闭则不执行团队同步 |
+| 同步团队(`sync_team_enabled`) | 开启后每次 SSO 登录按映射结果更新团队归属;关闭则不同步团队 |
| 团队字段(`teams`) | 填写返回团队名称的字段名,例如 `teams`,不是团队名称或 ID。开启团队同步后,**每次登录**按匹配结果覆盖现有团队,包括手工加入的团队 |
| 默认团队(`default_team_ids`) | 可多选。开启团队同步后,若返回的团队名称未匹配到任何可用团队,**仅本次登录新建的成员**会同步这些默认团队;已有成员不受影响。**通常保持为空** |
@@ -157,7 +205,7 @@ OIDC、SAML2.0 和 CAS 支持按身份提供商返回的**角色名称、团队
</Note>
<Warning>
-**有效映射是覆盖更新,不是追加。** 已有成员在下次 SSO 登录时,手工分配的角色或团队仍可能被有效映射结果替换;没有匹配结果的那一项保持不变。若完全由管理员维护角色或团队,请关闭对应同步开关,而不是仅清空默认值。
+**绝大多数情况下,请保持默认角色和默认团队为空。** 默认值是这份 SSO 配置的统一规则:映射字段未填写、填写错误,或身份提供商未返回可匹配的名称时,**所有通过该 SSO 新建且未匹配的成员都会获得相同的默认角色或加入相同的默认团队**。不要为了让登录测试通过而随意选择默认值,尤其不要将管理员等高权限角色或敏感团队设为通用默认值。
</Warning>
### 建议的配置顺序
@@ -178,76 +226,8 @@ OIDC、SAML2.0 和 CAS 支持按身份提供商返回的**角色名称、团队
各协议的名称取值来源、匹配规则与字段保留方式详见 [角色与团队同步](/zh/on-call/integration/sso/role-team-sync)。LDAP 使用 Group DN 映射规则,不使用本节的名称映射与新成员默认值规则。
</Note>
-## 配置 LDAP 协议
-
----
-
-<Note>
-LDAP 单点登录仅**私有化版本**支持。
-</Note>
-
-**配置路径**:平台管理 → 单点登录 → 开启 → 设置 → 选中 LDAP 协议类型
-
-| 字段 | 描述 |
-| --- | --- |
-| 协议类型 | 选择 LDAP 协议 |
-| LDAP 链接 | LDAP 服务地址,如:`ldap://10.10.10.10:389` |
-| BIND DN | 用于连接 LDAP 的用户名,如:`cn=admin,dc=flashduty,dc=com` |
-| BIND DN 密码 | 用于连接 LDAP 的密码,将加密存储到数据库中 |
-| 加密机制 | 支持 **TLS** 和 **StartTLS** 两种加密方式(二者互斥,只能启用一种)。启用任一加密方式后,可选择 **跳过 SSL/TLS 证书验证**;如不跳过,可选填写 SSL/TLS 证书路径 |
-| 用户 DN | 定义从哪个目录开始搜索用户,如:`ou=people,dc=flashduty,dc=com` |
-| 认证过滤 | 用于检索用户 DN 信息的自定义 filter 表达式,基本形式为:`(&(mail=%s))`。注意:开始和结束的括号是必须的 |
-| 字段映射 | Flashduty 通过映射字段从身份提供商提取用户邮箱、用户名、手机和 Group 信息。邮箱为必填映射字段,Group 字段默认值为 `memberOf`,用于角色和团队同步 |
-| 稳定用户 ID 字段(`user_id`) | 可选。用于识别同一成员的用户唯一标识属性,邮箱或手机号变更不影响识别;留空时按下方邮箱/手机号字段匹配成员。建议值为 `uid`,也可使用 `entryUUID` 等稳定属性。详见下文 [成员关联方式](#成员关联方式) |
-| 登录即创建账号 | 默认开启,关闭后需要先邀请成员才可登录 |
-| 成员仅支持 SSO 登录(`force_sso`) | 默认开启。开启后,账户内所有成员仅能通过 SSO 登录,密码与验证码登录将被拒绝。详见下文 [强制 SSO 登录](#强制-sso-登录) |
-
-<Tip>
-字段映射需要和身份提供商的配置保持一致,否则会导致异常。具体配置可参考 [OpenLDAP 集成指引](/zh/on-call/integration/sso/openldap)。
-</Tip>
-
-### LDAP 连接检测
-
-配置 LDAP 连接信息后,你可以在 **协议与连接** 分区的 LDAP 表单下方点击 **连接检测**,验证 Flashduty 能否成功连接到你的 LDAP 服务器。系统会使用当前填写的 LDAP 链接、BIND DN 和密码尝试建立连接,并返回连接成功或失败的结果。
-
-<Tip>
-建议在保存配置前先执行连接检测,确保连接参数正确无误,避免因配置错误导致成员无法通过 LDAP 登录。
-</Tip>
-
-### LDAP 角色和团队同步
-
-当你使用 LDAP 协议时,可以根据用户所属的 LDAP Group 自动同步 Flashduty 中的角色和团队。
-
-**配置路径**:LDAP 设置页面 → 同步配置
-
-<Steps>
- <Step title="启用同步">
- 在同步配置区域,分别开启 **同步角色** 和/或 **同步团队** 开关。
- </Step>
- <Step title="添加映射规则">
- 点击 **添加映射规则**,为每条规则配置以下内容:
-
- | 字段 | 说明 |
- | --- | --- |
- | **Group DN** | LDAP 中 Group 的完整 Distinguished Name,如 `cn=devops,ou=groups,dc=example,dc=com` |
- | **映射角色** | 当同步角色开启时可选,选择该 Group 对应的 Flashduty 角色 |
- | **映射团队** | 当同步团队开启时可选,选择该 Group 对应的 Flashduty 团队 |
- </Step>
- <Step title="配置默认角色">
- 当同步角色开启时,你可以配置 **默认角色**。当用户的 LDAP Group 未匹配到任何映射规则时,系统将赋予这些默认角色。
- </Step>
-</Steps>
-
-<Note>
-- 你可以添加多条映射规则,每条规则对应一个 LDAP Group
-- 用户登录时,系统会根据其 LDAP Group 成员关系自动匹配并同步对应的角色和团队
-- 映射规则中的 Group DN 必须是 LDAP 中 Group 的完整路径
-</Note>
-
## 成员关联方式
----
-
单点登录时,系统需要将身份提供商返回的用户与账户内成员进行关联,关联方式取决于 SSO 配置是否设置了**稳定用户 ID 字段**,对新建与既有配置均适用:
| 配置 | 关联方式 |
@@ -265,8 +245,6 @@ LDAP 单点登录仅**私有化版本**支持。
## 强制 SSO 登录
----
-
`force_sso` 选项用于强制账户内所有成员仅能通过 SSO 登录,从而把身份验证完全收敛到身份提供商。
**配置路径**:平台管理 → 单点登录 → 开启 → 设置 → **成员仅支持 SSO 登录**
@@ -301,8 +279,6 @@ This account requires SSO login. Password/code login is disabled.
## 外部成员管理
----
-
当您启用单点登录后,通过 SSO 首次登录并自动创建的成员会被标记为**外部成员**。您可以在 SSO 设置中开启**禁止编辑外部成员**选项(默认关闭),启用后,这些外部成员在 Flashduty 中将变为只读状态——无法在 Flashduty 中修改其角色或删除该成员,所有成员信息的管理只能通过身份提供商完成。
此功能适用于需要统一在身份提供商中管理用户权限的场景,确保 Flashduty 中的成员信息始终与身份提供商保持一致。
@@ -314,8 +290,6 @@ This account requires SSO login. Password/code login is disabled.
## 登录域名管理
----
-
登录域名是识别您的主体账号的重要依据,用于单点登录时定位到正确的 SSO 配置。每个主体的登录域名全局唯一。
配置登录域名后,成员可以通过 `{域名}.sso.flashcat.cloud` 地址直接发起单点登录,无需手动选择身份提供商。
@@ -338,8 +312,6 @@ This account requires SSO login. Password/code login is disabled.
## 最佳实践
----
-
<CardGroup cols={4}>
<Card title="角色与团队同步" icon="users" href="/zh/on-call/integration/sso/role-team-sync">
SAML2.0/OIDC/CAS 每次登录按名称同步,未匹配时仅新建成员使用默认配置
diff --git a/zh/platform/organization-info.mdx b/zh/platform/organization-info.mdx
index a604843b..fd649fd6 100644
--- a/zh/platform/organization-info.mdx
+++ b/zh/platform/organization-info.mdx
@@ -6,8 +6,6 @@ keywords: ["组织信息", "组织资料", "加入限制", "邮箱域名白名
## 组织信息
----
-
**组织信息** 页面集中展示组织身份与组织级默认配置,所有成员均可访问。入口为 **平台管理 → 组织 → 组织信息**,也可以点击个人中心名片上的 **组织信息** 按钮直达。
页面包含以下区块:
@@ -26,17 +24,13 @@ keywords: ["组织信息", "组织资料", "加入限制", "邮箱域名白名
## 组织资料
----
-
-组织资料区块维护组织的身份信息,仅主体账户或 Account.Admin 可以修改,其余成员只读。
-
| 配置项 | 说明 |
| --- | --- |
| **Logo** | 组织的 Logo 图片,通过 **Logo URL** 设置,须为可访问的 http/https 地址;点击 **重置为默认 Logo** 可清除自定义 Logo,恢复为默认 Logo |
| **名称** | 组织名称,展示在邀请成员的邮件和短信中 |
| **ID** | 组织的唯一标识,对接 API 或联系技术支持时提供 |
| **域名** | 用于登录和邮件集成推送的专属子域名 |
-| **时区** | 组织时区,未单独设置个人时区的成员按此时区看到所有时间。仅主体账号或 Account.Admin 可修改 |
+| **时区** | 组织时区,未单独设置个人时区的成员按此时区看到所有时间 |
### 组织时区
@@ -65,9 +59,7 @@ keywords: ["组织信息", "组织资料", "加入限制", "邮箱域名白名
## 加入限制
----
-
-加入限制区块控制**谁可以通过邀请加入组织**。目前提供邮箱域名白名单:只有邮箱域名在白名单内的人才能加入。仅主体账户或 Account.Admin 可以修改,其余成员以只读文本查看当前配置。
+加入限制区块控制**谁可以通过邀请加入组织**。目前提供邮箱域名白名单:只有邮箱域名在白名单内的人才能加入。
| 配置项 | 说明 |
| --- | --- |
@@ -75,33 +67,28 @@ keywords: ["组织信息", "组织资料", "加入限制", "邮箱域名白名
| **允许子域名** | 仅在白名单中已有一个有效域名时出现,默认关闭。开启后,白名单域名 `corp.com` 同时覆盖 `mail.corp.com` 等子域邮箱 |
<Note>
-- 白名单**不区分大小写**:`Corp.com` 与 `corp.com` 视为同一个域名
-- 域名须是完整域名(至少含一个点,如 `corp.com`),不能以点或连字符开头、结尾,也不能出现连续的点或紧邻点的连字符
-- 保存时会检查**你自己的邮箱域名**是否也在白名单内,不在名单内会被拒绝并提示把该域名补充进去
+- 填写完整域名(如 `corp.com`),不区分大小写
+- 白名单必须包含**您自己的邮箱域名**,否则无法保存
</Note>
### 生效范围
-邮箱域名白名单只在**邀请加入**这条路径上校验(逐个邀请,以及通过邀请链接 / 二维码加入,含带邀请令牌的登录),**不参与普通登录与鉴权**:
+白名单只在**加入组织**时生效,不影响日常登录:
-| 场景 | 是否校验白名单 |
+| 场景 | 是否受白名单限制 |
| --- | --- |
-| 逐个邀请(填写邮箱) | 校验。邮箱域名不在白名单时,邀请对话框内直接报错,后端也会拒绝 |
-| 通过邀请链接 / 二维码加入 | 校验。按被邀请人登录时使用的邮箱域名判定 |
-| 只填手机号的逐个邀请 | **不校验**。手机号邀请由管理员背书,成员可正常加入 |
-| 普通登录与授权 | 不校验。白名单不参与登录与鉴权 |
-| 已加入的成员、主体账户 | 不受影响。即使域名不在白名单内,仍可正常登录与使用,再次通过邀请链接加入也会直接放行 |
+| 邮箱邀请 | 是。域名不在白名单内的邮箱无法邀请 |
+| 通过邀请链接 / 二维码加入 | 是。按被邀请人登录所用的邮箱判断,且必须是已验证的邮箱 |
+| 手机号邀请 | 否 |
+| 已加入的成员、主体账户 | 否,即使域名不在白名单内也可正常使用 |
<Note>
-- 白名单开启后,**通过邀请链接 / 二维码加入的人必须提供已验证的邮箱**:只填了手机号、没有已验证邮箱的人会被拒绝,并提示先验证邮箱。这种情况下邀请登录页也只提供邮箱登录,并提示「该组织仅允许白名单内的邮箱加入,请使用邮箱登录」
-- 启用[强制 SSO 登录](/zh/platform/configure-sso#强制-sso-登录)的组织**无法通过邀请链接 / 二维码加入**:成员身份由身份提供方管理,链接加入会被拒绝,并提示请管理员通过 SSO 授予访问
+启用了[强制 SSO 登录](/zh/platform/configure-sso#强制-sso-登录)的组织无法通过邀请链接 / 二维码加入,成员需由管理员通过 SSO 授予访问。
</Note>
## 通知设置
----
-
-通知设置区块维护组织内系统通知的内容与语言,对所有成员生效。仅主体账户或 Account.Admin 可以修改,其余成员以只读文本查看当前配置。
+通知设置区块维护组织内系统通知的内容与语言,对所有成员生效。
### 默认通知语言
@@ -122,23 +109,21 @@ keywords: ["组织信息", "组织资料", "加入限制", "邮箱域名白名
| **开启** | 故障告警短信不再截断,超长内容可能被运营商拆分为多条,并按多条计费 |
| **关闭** | 故障告警短信按单条长度截断 |
-开启时需要二次确认:开启后国内和国际故障告警短信将不再截断,超长内容可能被运营商拆分为多条短信并按多条计费。
-
<Note>
验证码、邀请、值班短信**不受该开关影响**,始终按原有逻辑发送。
</Note>
### 免费通知额度提醒
-免费通知额度(短信 / 语音 / 邮件)快用完时,系统会发邮件提醒组织管理员,避免额度耗尽后通知中断。该区块**仅在 SaaS 版提供**,私有化部署不展示。两个开关默认**开启**,可以独立关闭;仅主体账户或 Account.Admin 可以修改,其余成员以只读文本查看。
+免费通知额度(短信 / 语音 / 邮件)快用完时,系统会发邮件提醒组织管理员,避免额度耗尽后通知中断。该区块**仅在 SaaS 版提供**,私有化部署不展示。两个开关默认**开启**,可以独立关闭。
-| 开关 | 字段 | 触发条件 |
-| --- | --- | --- |
-| **剩余 20% 时提醒** | `free_quota_20_reminder_enabled` | 免费额度降至 20% 或以下、且仍大于 0 时 |
-| **额度耗尽时提醒** | `free_quota_exhausted_reminder_enabled` | 免费额度首次降至 0 时 |
+| 开关 | 触发条件 |
+| --- | --- |
+| **剩余 20% 时提醒** | 免费额度降至 20% 或以下、且仍大于 0 时 |
+| **额度耗尽时提醒** | 免费额度首次降至 0 时 |
<Note>
-- 两个开关默认开启,重新打开**不会补发**:关闭期间跨过的阈值不再提醒
+- 关闭期间跨过的阈值,重新打开后**不会补发**
- 只统计**付费版账户**(标准版 / 专业版、非试用、未过期)**实际发送成功并计入用量**的短信、语音和邮件;免费版账户不发送该类提醒
- 短信、语音、邮件**分别统计、分别提醒**,每个额度周期、每种渠道最多提醒一次
- 提醒**只发邮件**,不会发短信或打电话:收件人是主体账户自己的邮箱,加上当前启用中的 **Admin 成员已验证的邮箱地址**(最多 20 个)
@@ -148,8 +133,6 @@ keywords: ["组织信息", "组织资料", "加入限制", "邮箱域名白名
## 故障处理
----
-
故障处理区块维护故障处理操作的组织级默认值,**对控制台和 IM 告警卡片生效**。
### 暂缓时间快捷选项
@@ -161,24 +144,22 @@ keywords: ["组织信息", "组织资料", "加入限制", "邮箱域名白名
- 快捷选项**不能重复**
- 默认值为 **2 小时 / 4 小时 / 12 小时**,点击 **恢复默认** 可快速还原
-修改后点击 **保存** 提交,立即对控制台与 IM 告警卡片生效。仅主体账户或 Account.Admin 可以修改,其余成员以只读文本查看当前预设。更多故障暂缓操作请参阅 [暂缓处理](/zh/on-call/incident/handle-update-incident)。
+保存后立即对控制台与 IM 告警卡片生效。更多故障暂缓操作请参阅 [暂缓处理](/zh/on-call/incident/handle-update-incident)。
### 快速静默标签排除规则
创建[快速静默](/zh/on-call/channel/noise-reduction#快速静默)时,匹配条件由故障的严重程度和标签自动生成。命中排除规则的标签不参与匹配条件,避免把每次取值都不同的标签(如触发值、当前值、链接等)写进条件,导致同类告警无法被静默。
-**配置入口**:组织信息 → 故障处理 → **快速静默排除标签**(配置对话框标题为「快速静默标签排除规则」)。仅主体账户或 Account.Admin 可以修改,其余成员可以打开查看当前规则(排除规则影响他们创建的静默,需要可见)。修改保存后,仅对之后创建的快速静默生效。
+**配置入口**:组织信息 → 故障处理 → **快速静默排除标签**。修改仅对之后创建的快速静默生效。
配置内容:
- **按集成维护排除列表**:为每个集成分别维护被排除的标签列表。创建快速静默时,命中任一排除列表的标签即被排除
- **系统格式规则开关**:`json`(JSON 类型)、`datetime`(时间格式)、`numeric`(纯数字)三个开关,默认全部开启;标签值长度超过 235 个字符时也会被自动排除(不可关闭)
-- **全局黑名单**:约 95 个系统内置标签(如 `trigger_value`、`current_value`、`detail_url`、`query` 等)始终被排除,由前端常量维护,不可配置
+- **全局黑名单**:约 95 个系统内置标签(如 `trigger_value`、`current_value`、`detail_url`、`query` 等)始终被排除,由系统内置,不可配置
## 延伸阅读
----
-
<CardGroup cols={2}>
<Card title="单点登录配置" icon="shield-check" href="/zh/platform/configure-sso">
登录域名与 SSO 单点登录
diff --git a/zh/platform/permission-design.mdx b/zh/platform/permission-design.mdx
index 9464a86a..c5741201 100644
--- a/zh/platform/permission-design.mdx
+++ b/zh/platform/permission-design.mdx
@@ -77,8 +77,8 @@ Flashduty 的权限点分为两类:
**自定义菜单权限与预置角色的继承规则不同:**
- **Admin**:自动继承账户内所有自定义菜单的访问权限,无需任何额外配置。
-- **Responder**:会自动包含当前账户中 `admin_only=0` 的权限点。因此,非管理员专用的自定义菜单访问权限无需额外角色绑定;标记为管理员专用的权限会从 Responder 预置角色中排除。
-- **Viewer**:不会自动继承自定义菜单权限。Viewer 的权限位图只包含系统预定义的权限点(`id < 100000`),而自定义菜单权限点的 ID 由 Snowflake 算法生成,远超该阈值,因此会被过滤掉。如需让 Viewer 成员访问某个自定义菜单,必须在该菜单的角色绑定配置(`role_ids` 字段)中显式添加 Viewer。
+- **Responder**:自动包含非管理员专用的自定义菜单权限;标记为管理员专用的菜单不包含在内。
+- **Viewer**:不会自动获得自定义菜单权限。如需让 Viewer 成员访问某个自定义菜单,请在该菜单的角色绑定中显式添加 Viewer。
- **自定义角色**:自定义角色同样不会自动继承自定义菜单权限,需在菜单的角色绑定中显式授权。
</Warning>
@@ -170,19 +170,19 @@ Flashduty 的权限点分为两类:
### 自定义角色
-除了预置角色外,你可以创建自定义角色以满足更精细的权限控制需求。
+除了预置角色外,您可以创建自定义角色以满足更精细的权限控制需求。
**配置路径**:平台管理 → 角色管理
<Steps>
<Step title="创建角色">
- 进入角色管理页面,点击 **创建角色** 按钮,填写角色名称和描述。你也可以通过复制已有角色快速创建。
+ 进入角色管理页面,点击 **创建角色** 按钮,填写角色名称和描述。您也可以通过复制已有角色快速创建。
</Step>
<Step title="编辑角色信息">
在角色详情页中,点击角色名称或描述旁的 **编辑图标(笔形图标)** 即可直接内联编辑角色名称和描述,修改后自动保存。
</Step>
<Step title="配置权限">
- 在角色详情页的 **权限列表** 标签下,点击 **编辑** 进入编辑模式。在编辑模式中,你可以通过批量勾选的方式一次性授予或撤销多个权限点,完成后点击 **保存** 即可。
+ 在角色详情页的 **权限列表** 标签下,点击 **编辑** 进入编辑模式。在编辑模式中,您可以通过批量勾选的方式一次性授予或撤销多个权限点,完成后点击 **保存** 即可。
</Step>
<Step title="分配成员">
在角色详情页的 **授权成员** 标签下,点击 **编辑** 进入编辑模式,通过批量勾选的方式添加或移除该角色的授权成员,完成后点击 **保存**。
@@ -192,7 +192,7 @@ Flashduty 的权限点分为两类:
<Note>
- 系统预置角色(Admin、Responder、Viewer)不可修改或删除
- 自定义角色支持编辑、复制、启用/禁用和删除操作
-- 被任一已保存的 SAML2.0 / OIDC / CAS SSO 配置选为**默认角色**(`default_role_ids`)的自定义角色无法删除:删除会返回 `ReferenceExist`(该资源仍被其他实体引用,无法删除)错误,强制删除(`is_force`)也不会绕过——强制删除仅解除成员绑定,SSO 默认引用须先取消。须先在对应的单点登录配置的默认角色选项中取消选择该角色;该限制在 SSO 或角色同步开关关闭时同样生效
+- 被任一 SSO 配置(SAML2.0 / OIDC / CAS)选为**默认角色**的自定义角色不能删除,强制删除也不行(强制删除只解除成员绑定)。请先在对应的单点登录配置中取消该默认角色;即使 SSO 或角色同步已关闭,也需要先取消
- 一个成员可以同时拥有多个角色,其权限为所有角色权限的并集
</Note>
@@ -247,8 +247,8 @@ Flashduty **基于团队来控制数据权限**,并应用于以下场景:
- **功能权限**:专属集成的启停、删除与保存配置,除「集成管理」外,「协作空间管理」也可以操作——两者有其一即可。这是因为「协作空间管理」本身就包含其空间内集成的创建、编辑、删除、启停与轮换 Key。
- **数据权限**:专属集成按协作空间的**管理团队**判定;协作空间未配置管理团队时按协作空间所属团队判定。共享集成按集成自身的创建者与负责团队判定。
-- **权限不足时的提示不同**:专属集成为「您没有操作权限。仅账户管理员、协作空间创建者或管理团队允许操作。」,共享集成为「您没有操作权限。仅账户管理员、集成创建者或管理团队允许操作。」。
-- 只有 `ref_id` 形如 `c_<channel_id>` 的集成才算专属集成:从集成详情带着 `channel_id` 查询参数打开的共享集成,仍按共享集成判定。
+- **权限不足时**:专属集成仅账户管理员、协作空间创建者或管理团队可以操作;共享集成仅账户管理员、集成创建者或管理团队可以操作。
+- 只有在协作空间中创建的集成才是专属集成;从协作空间打开的共享集成仍按共享集成判定。
</Note>
当您没有对应资源的数据权限时,系统会显示以下提示:
diff --git a/zh/platform/pricing.mdx b/zh/platform/pricing.mdx
index bc6866b9..3ca80821 100644
--- a/zh/platform/pricing.mdx
+++ b/zh/platform/pricing.mdx
@@ -6,8 +6,6 @@ keywords: ["产品定价", "License订阅", "按量付费", "收费模式", "版
## On-call 定价
----
-
On-call 采用 **License 订阅制**收费,按活跃用户数量计费。
### 收费模式
@@ -100,7 +98,7 @@ On-call 采用 **License 订阅制**收费,按活跃用户数量计费。
免费额度快用完时,系统会向账户发送**提醒邮件**(仅邮件渠道,不会发短信或打电话):
-- **触发时点**:某个渠道的免费额度剩余不超过 **20%** 时,发一封「[额度提醒] X 免费额度剩余不超过 20%」(账户设置项 `free_quota_20_reminder_enabled`);该渠道额度**耗尽**时,再发一封「[额度提醒] X 免费额度已耗尽」(账户设置项 `free_quota_exhausted_reminder_enabled`)。短信、电话、邮件三个渠道分别统计、分别提醒。
+- **触发时点**:某个渠道的免费额度剩余不超过 **20%** 时提醒一次,**耗尽**时再提醒一次。短信、电话、邮件三个渠道分别统计、分别提醒。
- **收件人**:账户邮箱,以及账户内**已启用且邮箱已验证**的管理员邮箱,最多 20 位。
- **频率**:每个额度周期内、每个渠道最多提醒一次。
- 提醒邮件本身**不计入**账户的通知额度,也不会反过来消耗免费额度。
@@ -108,7 +106,7 @@ On-call 采用 **License 订阅制**收费,按活跃用户数量计费。
两个开关默认开启,位于 **平台管理 → 组织 → 组织信息 → 通知设置 → 免费通知额度提醒**,可按需关闭,详见[组织信息](/zh/platform/organization-info#免费通知额度提醒)。
<Note>
-「额度提醒」针对的是**各通知渠道的免费额度**;「[余额不足提醒](/zh/platform/pricing#余额不足提醒)」针对的是**账户余额**低于自设阈值——后者可自设阈值(不小于 1 元)并以短信 + 邮件发送。两者相互独立:触发条件不同,且只有「余额不足提醒」需要自设阈值。
+额度提醒针对**各通知渠道的免费额度**;[余额不足提醒](#余额不足提醒)针对**账户余额**低于您设置的阈值,两者相互独立。
</Note>
### 客户支持
@@ -187,8 +185,6 @@ Flashduty 的 License 模式将**故障处理能力**和**通知接收能力**
## RUM 定价
----
-
RUM 采用 **按量付费**模式,根据实际使用的会话数量计费。
### 版本对比
@@ -232,8 +228,6 @@ RUM 采用 **按量付费**模式,根据实际使用的会话数量计费。
## 付款与充值
----
-
费用中心仅对 SaaS 版本开放,私有化部署不提供该入口。在左侧菜单进入 **费用中心**,页面标题为 **账单**,下设 **充值** 与 **收支明细** 两个页签;菜单中还可以进入 **订阅**——页面标题为「您的订阅」,按产品分为 **On-Call**、**AI SRE** 与 **RUM** 三个页签,AI SRE 的开通、关闭与计费都在 **AI SRE** 页签内管理,计费规则见 [AI SRE 产品概述](/zh/ai-sre/overview#开通与计费)。
### 可用余额的构成
@@ -253,8 +247,7 @@ RUM 采用 **按量付费**模式,根据实际使用的会话数量计费。
**在线充值** 中可选 **支付宝**(人民币结算,可任选金额)或 **Stripe**(国际信用卡、借记卡等)。
- **支付宝**:预设面额 ¥100 / ¥300 / ¥500 / ¥1,000 / ¥3,000 / ¥5,000,也可自定义金额,范围 0.01–100,000 元,最多两位小数。
-- **Stripe**:以美元结算,可选面额由服务端下发(默认 $50 / $100 / $200 / $500 / $1,000),自定义金额范围 0.5–10,000 美元,最多两位小数。充值金额按**固定汇率**折算为人民币余额入账(默认 1 USD = 7 CNY,由部署配置决定),每个美元面额下方会直接显示精确折算后的人民币金额,不是估算值。
-- Stripe 渠道需要在服务端配置支付密钥才会出现;未配置时账户只见支付宝。
+- **Stripe**:以美元结算,可选面额默认为 $50 / $100 / $200 / $500 / $1,000,自定义金额范围 0.5–10,000 美元,最多两位小数。充值金额按**固定汇率**折算为人民币余额入账(默认 1 USD = 7 CNY,由部署配置决定),每个美元面额下方会直接显示精确折算后的人民币金额,不是估算值。
- **默认选中的渠道跟随界面语言**:中文界面默认支付宝,非中文界面默认 Stripe。两者都可在提交前手动切换。
### 绑定银行卡与自动扣款
@@ -264,9 +257,8 @@ RUM 采用 **按量付费**模式,根据实际使用的会话数量计费。
- **没有独立的开关**:只要账户上保存了有效的卡,且未触发停止条件,续费余额不足时就会自动扣款
- **扣款金额**:等于本次续费询价的差额(应付费用减去当前余额,含用量导致的负余额),向上取整为整美元
- **频率上限**:每个账户每 24 小时最多自动扣款一次
-- **停止条件**:连续扣款失败达到 3 次即停止自动扣款,页面会提示「已连续失败 N 次,已停止自动扣款」。用 Stripe 重新充值一次即可更换银行卡
+- **停止条件**:连续扣款失败 3 次后停止自动扣款。用 Stripe 重新充值一次即可更换银行卡
- **删除卡片**:在 **可用余额 → 自动化 → 自动扣款** 中点击 **删除卡片**,删除后续费不再自动扣款,需重新用 Stripe 充值绑定。该操作需要 **费用管理** 权限
-- 中文界面在尚未绑定卡片时不展示「自动扣款」这一行,英文界面始终展示并提供绑定入口
### 余额不足提醒
@@ -278,10 +270,10 @@ RUM 采用 **按量付费**模式,根据实际使用的会话数量计费。
<Steps>
<Step title="获取账户 ID">
- 在充值页复制你的 **账户 ID**。
+ 在充值页复制您的 **账户 ID**。
</Step>
<Step title="去云市场下单">
- **下单时必须把账户 ID 填进订单备注**,这是平台把这笔订单认回你账户的唯一依据,漏填会导致额度无法入账。
+ **下单时必须把账户 ID 填进订单备注**,这是平台把这笔订单认回您账户的唯一依据,漏填会导致额度无法入账。
</Step>
<Step title="等待生效">
订单通常在 1 个工作日内生效,额度到账后会出现在 **收支明细** 里。
@@ -294,13 +286,13 @@ RUM 采用 **按量付费**模式,根据实际使用的会话数量计费。
### 对公转账
-选择 **对公转账** 后,页面展示收款账户名称、开户银行与银行账号。汇款时**必须把账户 ID 填在备注里**,否则款项无法认回你的账户。汇款通常在 1 个工作日内入账。
+选择 **对公转账** 后,页面展示收款账户名称、开户银行与银行账号。汇款时**必须把账户 ID 填在备注里**,否则款项无法认回您的账户。汇款通常在 1 个工作日内入账。
### 收支明细与发票
**收支明细** 页签逐条列出 **时间**、**类型**、**描述**、**交易金额**、**发票** 与 **余额**,其中余额区分 **现金** 与 **赠送金**。收入包含 **充值**,支出包含 **下单**、**消耗**、**退货** 与 **提现**。
-- 系统自动从银行卡扣款的流水,描述会标注为自动充值(Auto top-up),与你手动发起的 Stripe 充值区分开
+- 系统自动从银行卡扣款的流水,描述会标注为自动充值(Auto top-up),与您手动发起的 Stripe 充值区分开
- **发票** 列仅对已开具的 Stripe 充值订单显示直链;支付宝、对公转账与云市场等渠道需提交开票申请单,默认开具电子专票
- 需要加急或开票时,可通过 **可用余额** 下方的 **申请开票** 入口提交
@@ -308,24 +300,22 @@ RUM 采用 **按量付费**模式,根据实际使用的会话数量计费。
## 私有化部署的 License 到期与续签
----
-
私有化部署的 License 由 Flashduty 签发,带固定到期日。到期前平台会向部署方在合同中登记的联系人发送提醒;到期后平台**停止接收数据**。私有化部署不提供费用中心入口(见[付款与充值](#付款与充值)),续签需联系销售。
### 到期提醒
提醒面向合同中登记的联系人:每位联系人的**邮箱**都会收到提醒邮件,登记了**有效中国大陆手机号**的联系人还会收到**短信**。
-- **提醒时点**:License 剩余 **10 天、3 天、1 天** 时各发送一次,每张 License 最多三次。剩余天数按天向上取整,到期时刻归入「1 天」那一次,因此到期后不会补发;License 登记时剩余天数已不足 10 天,则只会收到其中一次。
-- **发送时段**:仅在北京时间 **08:00–22:00** 之间发送(按小时判定,落在区间外的小时不发送)。
+- **提醒时点**:License 剩余 **10 天、3 天、1 天** 时各发送一次,每张 License 最多三次;到期后不再补发。
+- **发送时段**:仅在北京时间 **08:00–22:00** 之间发送。
- **不再提醒**:已到期超过 **7 天** 的 License 不再发送提醒。
-- **文案**:提醒邮件为**固定中文文案**(私有化客户均在国内)。到期前主题为「[License 提醒] Flashduty 私有化 License 还剩 N 天到期」,副标题为「到期后将停止接收数据。」,正文含 **到期日** 与 **剩余天数**;到期当天的主题与标题改为「[License 提醒] Flashduty 私有化 License 已到期」,副标题为「数据已停止接收。」。短信文案为「您的 Flashduty 私有化部署(客户名称)License 将于 到期日 到期,还剩 N 天。到期后将停止接收数据,请尽快联系我们续签」,已到期时改为「……已于 到期日 到期,数据已停止接收,请尽快联系我们续签」。
+- 提醒邮件和短信均为中文,内容包含到期日与剩余天数。
### 到期后的影响与续签
License 到期后平台**停止接收数据**,请尽快续签,避免数据接收长时间中断。
-拿到新的 License 后,在控制台**侧边栏的 License 提示中粘贴并激活**,激活成功后控制台提示「License 已更新,将在五分钟内生效」,**无需重启服务**;到期日随之更新,提醒按新的到期日重新开始。(提醒邮件中写的生效时长是约 1–2 分钟,以控制台提示为准。)
+拿到新的 License 后,在控制台**侧边栏的 License 提示中粘贴并激活**,新 License 在五分钟内生效,**无需重启服务**;到期日随之更新,提醒按新的到期日重新开始。
<Note>
「[额度提醒](#额度提醒)」与「[余额不足提醒](#余额不足提醒)」面向 **SaaS** 账户;本节针对**私有化部署**的 License 到期与续签,两者相互独立。
@@ -333,72 +323,46 @@ License 到期后平台**停止接收数据**,请尽快续签,避免数据
---
----
-
## 订阅过期后会发生什么
On-call 订阅**已过期或被停用**后,平台会做两件事:**停止接收新的告警事件**,并**冻结所有新建入口**。已有配置和历史数据不会被删除,续费后自动恢复。
### 什么算订阅过期
-以下任一条件成立,全站即按「已过期」处理:
+订阅**被停用**或**已到期**,满足任一条件即算过期。私有化部署不做订阅管控,不会过期。
-| 条件 | 说明 |
-| --- | --- |
-| **订阅被停用** | 订阅资源的状态不是 `enabled` |
-| **订阅已到期** | 当前时间已达到订阅的到期时间(`expired_at`) |
-
-只看到期时间会漏掉「资源已停用但到期时间未到」这类后端会拒绝、前端却放行的情况,因此两者任一成立即算过期,私有化部署不做订阅管控、永远不会被判为过期。
-
-### 到期提醒与续费入口
+### 到期提醒与续费
-- **左侧导航的订阅入口**在到期前不足 **10 天**时变黄并显示「X 后到期」(X 为剩余时长),悬停提示「订阅将在 X 后到期,到期后告警将停止接入」;过期后转为红色并显示「订阅已到期 X」(X 为已过期时长),悬停提示「订阅已到期 X,告警已停止接入,点击续费」。点击该入口直接进入 **订阅** 页面(`/wallet/plan`)。
-- **主体账号**可以在页面提示条上点击 **立即续费**;**成员账号**没有续费权限,看到的是「请联系账户主体续费。」。
+- 到期前不足 **10 天**,左侧导航底部的订阅入口变黄并显示剩余时长;过期后变红。点击该入口进入 **订阅** 页面续费。
+- 只有**主体账号**可以续费;成员账号需联系主体账号。
-### 告警接入与列表页提示
+### 过期期间的影响
-订阅过期后告警停止接入,告警列表、故障列表、集成中心与分析看板顶部会各常驻一条**不可关闭**的提示条,说清该页受到的具体影响:
+**告警停止接入**。告警列表、故障列表、集成中心和分析看板顶部会显示提示条,说明该页受到的影响:
-| 页面 | 提示条文案 |
+| 页面 | 影响 |
| --- | --- |
-| 告警列表 | 「订阅已过期,新的告警事件已停止接入。历史告警仍可查看与处理,续费后自动恢复接入。」 |
-| 故障列表 | 「订阅已过期,新的告警事件已停止接入,不会再产生新故障。已有故障仍可正常处理。」 |
-| 集成中心 | 「订阅已过期,所有集成已停止接收告警事件。已配置的集成不会被删除,续费后自动恢复接入,无需重新配置。」 |
-| 分析看板 | 「订阅已过期,告警已停止接入,此后不再产生新的统计数据。历史数据不受影响,仍可查看与导出。」 |
-
-集成中心里每个集成卡片同时变为不可点击,悬停提示「订阅已过期,无法新建集成。续费后立即恢复,已有集成不受影响。」;分析看板因为不再产生新数据,默认时间窗内自然是空的,这不是数据丢失,详见[分析看板](/zh/on-call/analytics/insights)。
-
-### 被冻结的新建入口
+| 告警列表 | 不再接入新告警,历史告警仍可查看与处理 |
+| 故障列表 | 不再产生新故障,已有故障仍可正常处理 |
+| 集成中心 | 所有集成停止接收告警;已配置的集成不会被删除,续费后无需重新配置 |
+| 分析看板 | 不再产生新的统计数据,因此默认时间窗内可能为空,这不是数据丢失;历史数据仍可查看与导出。详见[分析看板](/zh/on-call/analytics/insights) |
-订阅过期后以下新建入口被禁用。鼠标悬停时的提示为「订阅已过期,无法新建〈对象〉。续费后立即恢复,已有〈对象〉不受影响。」——其中的「对象」是本列的对象名,例如协作空间入口的提示是「订阅已过期,无法新建协作空间。续费后立即恢复,已有协作空间不受影响。」;提示里同时给出续费路径:主体账号为 **立即续费**,成员账号为「请联系账户主体续费。」。
+**新建入口被冻结**。以下对象在过期期间无法新建:
-| 对象 | 被禁用的入口 |
-| --- | --- |
-| 协作空间 | 协作空间列表的 **创建协作空间** |
-| 值班表 | 值班表页面的 **创建值班** |
-| 故障 | 故障列表的 **创建故障** |
-| 作战室 | 故障详情中的 **创建作战室** |
-| 状态页 | 状态页列表的 **创建公开页面** / **创建内部页面**,以及创建页本身 |
-| 成员 | 成员管理的 **邀请成员** |
-| 自定义字段 | 自定义字段页面的 **创建自定义字段** |
-| 通知模板 | 通知模板页面的新建入口 |
-| 服务日历 | 服务日历页面的 **新增日历** |
-| 复盘报告 | 复盘面板的 **创建复盘报告** |
+协作空间、值班表、故障、作战室、状态页、成员(邀请成员)、集成、自定义字段、通知模板、服务日历、复盘报告。
<Note>
-过期只冻结**新建**。已有对象的**编辑、启停、删除**等存量操作不受订阅过期影响:已有协作空间的降噪配置、分派策略仍可正常编辑,已创建的状态页仍正常对外展示且可随时编辑。
+过期只冻结**新建**。已有对象仍可编辑、启停和删除,例如协作空间的降噪配置和分派策略,已创建的状态页也照常对外展示。
</Note>
### 续费后如何恢复
-续费或重新启用订阅后**不需要重新配置**:告警事件恢复接入、被冻结的新建入口立即恢复可用,已配置的集成、已有故障、历史告警与历史统计数据都保持原样。AI SRE 也会随 On-call 订阅失效而暂停、随续费自动恢复,规则见 [AI SRE 产品概述 · 订阅失效与恢复](/zh/ai-sre/overview#订阅失效与恢复)。
+续费或重新启用订阅后**无需重新配置**:告警恢复接入,新建入口立即可用,已有集成、故障、历史告警和统计数据保持不变。AI SRE 会随 On-call 订阅失效而暂停、随续费自动恢复,见 [AI SRE 产品概述 · 订阅失效与恢复](/zh/ai-sre/overview#订阅失效与恢复)。
---
## 常见问题
----
-
<AccordionGroup>
<Accordion title="On-call 如何计算活跃用户?">
当月使用商业化功能(查看或处理故障)的用户即为活跃用户。**仅接收告警通知不算作活跃用户**。每个月度周期结束后:
@@ -454,8 +418,6 @@ On-call 订阅**已过期或被停用**后,平台会做两件事:**停止接
## 联系销售
----
-
<Card title="获取专业采购指南" icon="headset" href="mailto:contact-us@flashcat.cloud">
如需了解更多定价细节或获取企业报价,欢迎联系我们的销售团队。
diff --git a/zh/platform/team-members.mdx b/zh/platform/team-members.mdx
index c13ec69b..ce6f1b2f 100644
--- a/zh/platform/team-members.mdx
+++ b/zh/platform/team-members.mdx
@@ -1,19 +1,15 @@
---
-title: "组织管理"
+title: "团队管理"
description: "团队和成员的创建、配置与管理"
keywords: ["团队管理", "成员管理", "邀请成员", "组织架构", "角色权限"]
---
## 团队介绍
----
-
团队是成员的集合,可以将不同职责或项目的成员归纳到一个团队里,用于管理**协作空间、分派通知、值班安排以及服务日历**等场景。
## 团队管理
----
-
### 团队查询
- 默认展示全部团队,可以选择只显示"我"的团队
@@ -41,37 +37,29 @@ keywords: ["团队管理", "成员管理", "邀请成员", "组织架构", "角
### 团队详情
-点击团队名称即可进入团队详情页,在详情页中你可以:
+点击团队名称即可进入团队详情页,在详情页中您可以:
- **查看成员**:查看该团队下的所有成员列表
- **添加成员**:点击 **添加成员** 按钮,从组织成员中选择并添加到该团队
- **移除成员**:在成员列表中点击对应成员的 **移除** 按钮,将其从团队中移除
-- **退出团队**:如果你是该团队的成员,可以点击 **退出团队** 主动退出
+- **退出团队**:如果您是该团队的成员,可以点击 **退出团队** 主动退出
- **删除团队**:拥有团队管理权限的成员可以在详情页中删除团队
### 删除团队
<Warning>
- 删除前请先确认是否有协作空间、分派策略等与该团队有关联
- - 被任一已保存的 SAML2.0 / OIDC / CAS SSO 配置选为**默认团队**(`default_team_ids`)的团队无法删除:删除会返回 `ReferenceExist`(该资源仍被其他实体引用,无法删除)错误,须先在对应单点登录配置的默认团队选项中取消选择该团队;该限制在 SSO 或团队同步开关关闭时同样生效
+ - 被 SSO(SAML2.0 / OIDC / CAS)配置选为**默认团队**的团队无法删除,须先在该 SSO 配置中取消选择;即使 SSO 或团队同步已关闭也是如此
- 删除后关联的配置将即刻失效且不可恢复,请谨慎操作
</Warning>
## 成员管理
----
-
成员列表中,未验证的邮箱或手机号旁会显示警告图标。未验证的联系方式无法接收告警通知,请提醒成员及时完成验证。列表同时展示每位成员的**时区**:未单独设置个人时区的成员显示为跟随组织,按组织时区生效,详见[组织信息](/zh/platform/organization-info)与[个人设置](/zh/on-call/configuration/personal-settings)。
### 成员搜索
-成员列表的搜索框对以下条件做 **OR** 匹配,命中任一条件即返回:
-
-- **姓名或邮箱**:包含关键字的模糊匹配
-- **手机号**:输入可解析为有效电话号码时精确匹配
-- **成员 ID**:输入为纯数字时,额外精确匹配成员 ID(`member_id`)
-
-例如输入某成员的 ID(纯数字)即可直接定位该成员,无需知道姓名、邮箱或手机号。
+搜索框支持按以下任一条件查找成员:姓名或邮箱(模糊匹配)、手机号(精确匹配)、成员 ID(输入纯数字时精确匹配)。
### 邀请方式
@@ -84,45 +72,21 @@ keywords: ["团队管理", "成员管理", "邀请成员", "组织架构", "角
3. 按需调整**加入后默认角色(可多选)**,默认为 Viewer
4. 点击**复制链接**;二维码页签可点击**保存二维码**或**复制二维码**
- 链接与二维码的规则:
-
- - **仅主体账户或 Account.Admin 可管理**:其他成员看不到这两个页签,自定义角色即使拥有成员管理权限,也只能逐个邀请
- - **一个组织只有一份链接**:打开邀请成员对话框时自动生成,有效期固定 **42 天**,页签内会显示链接 / 二维码的失效时间
- - 点击**重置**会轮换链接并重新计时,此前发出去的链接与二维码**立即失效**,已配置的默认角色不受影响
- - **复制链接**复制出去的是一段可直接转发的邀请文案,含组织名、链接,以及(组织配置了[加入限制](/zh/platform/organization-info#加入限制)时)允许加入的邮箱域名提示;**保存二维码** / **复制二维码**得到的是带组织名称与有效期的海报图
- - 把默认角色改为 **Account.Admin** 等管理员角色时会二次确认——拿到链接的人都会直接获得该角色
- - 配置的默认角色在成员加入时若已被删除,会自动退回 **Viewer**
-
- 被邀请人打开 `{控制台域名}/invite/{token}` 后:
-
- 1. 未登录时先看到组织卡片(头像与名称),点击**登录后加入**去登录;登录页已带上邀请令牌,不会再让对方选择登录哪个组织
- 2. 登录成功后自动加入组织并进入控制台
+ 须知:
- - 已经是该组织成员,或该组织的主体账户,再打开链接会直接进入,**角色保持不变**
- - 通过链接加入的成员只获得配置的默认角色,**不会自动加入任何团队**
- - 链接被重置或过期后,落地页会提示**该邀请已失效**,需要联系管理员重新获取
+ - 只有**主体账号**或 **Account.Admin** 能使用邀请链接和二维码,其他角色只能逐个邀请
+ - 每个组织只有一份链接,有效期 **42 天**;点击 **重置** 会让之前发出的链接和二维码立即失效
+ - 默认角色包含管理员角色时需要二次确认,因为拿到链接的人都会获得该角色;若默认角色已被删除,新成员会获得 **Viewer**
+ - 通过链接加入的成员**不会自动加入任何团队**;已是组织成员的人打开链接,角色不变
+ - 被邀请人打开链接并登录后即加入组织;链接过期或重置后需向管理员重新获取
</Tab>
- <Tab title="邮件邀请">
- 在**邮箱或手机号**页签中填写邮箱地址即可邀请,用户昵称默认为邮箱前缀,可在激活后修改。
-
- 1. 进入成员管理页面
- 2. 点击**邀请成员**
- 3. 切换到**邮箱或手机号**页签,填写邮箱地址
- 4. 输入成员名称
- 5. 选择角色(可选)
- 6. 发送邀请
+ <Tab title="邮箱或手机号邀请">
+ 1. 进入成员管理页面,点击**邀请成员**
+ 2. 在**邮箱或手机号**页签中填写邮箱地址或手机号(支持国际区号)
+ 3. 输入成员名称(邮箱邀请时默认为邮箱前缀,激活后可修改),按需选择角色
+ 4. 发送邀请
- 你可以在同一次操作中添加多个邀请成员条目,一次性批量邀请。
- </Tab>
- <Tab title="手机号邀请">
- 在同一个**邮箱或手机号**页签中填写手机号即可邀请成员。
-
- 1. 进入成员管理页面
- 2. 点击**邀请成员**
- 3. 切换到**邮箱或手机号**页签,填写手机号(支持选择国际区号)
- 4. 输入成员名称
- 5. 选择角色(可选)
- 6. 发送邀请
+ 一次可以添加多个条目,批量邀请。
</Tab>
<Tab title="API 邀请">
通过 [Open API](/zh/api-reference/platform/members/member-invite) 进行邀请,支持邮箱和手机号邀请。
@@ -136,12 +100,8 @@ keywords: ["团队管理", "成员管理", "邀请成员", "组织架构", "角
- 系统会向被邀请人发送短信或邮件通知
- 每天邀请上限为 200 人,单次邀请至多 20 人,重新发送邀请每天至多 5 次
- 未激活账号无法接收告警相关通知
- - 组织在[加入限制](/zh/platform/organization-info#加入限制)中配置邮箱域名白名单后,逐个邀请只能填写白名单内的邮箱域名(邀请对话框内会直接标出允许的域名);手机号邀请不受该限制,通过邀请链接加入则按登录邮箱域名校验
- - 订阅过期或被停用后,**邀请成员** 入口被禁用,悬停提示「订阅已过期,无法新建成员。已有成员不受影响。」——主体账号可点击 **立即续费**,成员账号提示「请联系账户主体续费。」;续费后入口立即恢复,已有成员不受影响。详见[订阅过期后会发生什么](/zh/platform/pricing#订阅过期后会发生什么)
-</Note>
-
-<Note>
-邀请新成员需要有效的订阅。订阅过期后,成员管理页的**邀请成员**按钮为禁用状态,悬停提示「订阅已过期,无法新建成员。已有成员不受影响。」,已有成员可继续正常使用。
+ - 组织配置了[加入限制](/zh/platform/organization-info#加入限制)的邮箱域名白名单后,邮箱邀请和邀请链接都只接受白名单内的域名;手机号邀请不受限制
+ - 订阅过期或被停用期间无法邀请新成员,已有成员不受影响,详见[订阅过期后会发生什么](/zh/platform/pricing#订阅过期后会发生什么)
</Note>
### 变更角色
@@ -153,7 +113,7 @@ keywords: ["团队管理", "成员管理", "邀请成员", "组织架构", "角
### License 管理
-License 决定了成员是否可以查看和处理故障。在成员管理列表中,你可以查看和管理每位成员的 License 状态。
+License 决定了成员是否可以查看和处理故障。在成员管理列表中,您可以查看和管理每位成员的 License 状态。
| License 类型 | 说明 |
| --- | --- |
@@ -161,13 +121,13 @@ License 决定了成员是否可以查看和处理故障。在成员管理列表
| **临时** | 每个计费周期结束时自动释放,新周期开始时重新抢占分配 |
| **无** | 该成员未持有 License,无法查看和处理故障。如果存在空闲 License,可在下一周期重新抢占 |
-你可以在成员列表的 License 列中执行以下操作:
+您可以在成员列表的 License 列中执行以下操作:
- **授予固定 License**:为成员分配一个固定 License,前提是当前仍有可用 License 额度
- **取消 License**:释放成员的 License,释放后该成员将无法查看和处理故障
<Note>
-License 总数取决于你的订阅版本。当所有 License 已分配完毕时,需要先释放其他成员的 License 或升级订阅才能为新成员分配。
+License 总数取决于您的订阅版本。当所有 License 已分配完毕时,需要先释放其他成员的 License 或升级订阅才能为新成员分配。
</Note>
### 成员详情
@@ -195,8 +155,6 @@ License 总数取决于你的订阅版本。当所有 License 已分配完毕时
## 常见问题
----
-
<AccordionGroup>
<Accordion title="邮件邀请成员未收到验证邮件">
请依次检查:
@@ -228,8 +186,6 @@ License 总数取决于你的订阅版本。当所有 License 已分配完毕时
## 延伸阅读
----
-
<CardGroup cols={2}>
<Card title="权限设计" icon="shield-check" href="/zh/platform/permission-design">
了解功能权限和数据权限的设计
diff --git a/zh/rum.mdx b/zh/rum.mdx
index 10ad159f..0a4ce530 100644
--- a/zh/rum.mdx
+++ b/zh/rum.mdx
@@ -7,21 +7,17 @@ sidebarTitle: "RUM"
## 什么是真实用户监控?
----
-
真实用户监控(RUM)是一项创新技术,它能够追踪并分析真实用户在使用您 Web 应用时的实际体验。与传统的模拟测试不同,RUM 直接从用户浏览器采集数据,为您呈现应用在真实环境中的运行状况。
Flashduty RUM 让开发人员、运维工程师和业务相关方能够直观地了解应用性能,及时发现问题并持续优化用户体验。
## 核心能力
----
-
<AccordionGroup>
<Accordion title="性能监控" icon="gauge-high">
实时掌握页面加载时间、资源加载效率和 JavaScript 运行状况等关键性能指标,快速定位影响用户体验的瓶颈。
- - **页面性能**:LCP、FID、CLS 等核心 Web 指标
+ - **页面性能**:LCP、INP、CLS 等核心 Web 指标
- **资源分析**:图片、脚本、样式表加载耗时
- **接口监控**:API 请求响应时间和成功率
</Accordion>
@@ -50,8 +46,6 @@ Flashduty RUM 让开发人员、运维工程师和业务相关方能够直观地
## 为什么选择 Flashduty RUM?
----
-
<CardGroup cols={2}>
<Card title="全方位可视化" icon="eye">
从用户视角出发,全面了解应用在不同浏览器、设备和地域下的性能表现
@@ -73,8 +67,6 @@ Flashduty RUM 让开发人员、运维工程师和业务相关方能够直观地
## 工作原理
----
-
Flashduty RUM 通过在您的 Web 应用中植入轻量级 JavaScript SDK 来实现数据采集:
<Steps>
@@ -102,9 +94,14 @@ Flashduty RUM 通过在您的 Web 应用中植入轻量级 JavaScript SDK 来实
| 异常信息 | JavaScript 异常、网络故障、控制台错误 |
| 长任务 | 可能造成页面卡顿的耗时 JavaScript 任务 |
-## 快速开始
+## 适用场景
----
+- 监控 Web 应用的核心性能指标(LCP、INP、CLS)
+- 追踪和分析前端错误,提升应用稳定性
+- 分析用户行为路径,优化产品体验
+- 关联后端 Trace,实现全链路可观测
+
+## 快速开始
<CardGroup cols={2}>
<Card title="快速入门" icon="rocket" href="/zh/rum/quickstart/quickstart">
diff --git a/zh/rum/analytics/miniprogram.mdx b/zh/rum/analytics/miniprogram.mdx
index 39bd7b07..fc56edd0 100644
--- a/zh/rum/analytics/miniprogram.mdx
+++ b/zh/rum/analytics/miniprogram.mdx
@@ -10,17 +10,17 @@ Flashduty 微信小程序 RUM 分析看板提供开箱即用的可视化仪表
分析看板包含 2 个核心分析维度:**概览**、**性能分析**
</Info>
-## 概览 — 关键指标一目了然
+## 概览
概览模块聚焦于小程序多维度的核心指标,帮助您快速把握整体健康状况。
-#### 流量与会话
+### 流量与会话
- **UV**:去重后的独立访客数。结合趋势图可洞察用户活跃规律。
- **会话数**:小程序被打开使用的会话总数,点击卡片可下钻查看具体会话列表。
- **用户访问趋势**:以时序图同时展示 UV 与 Session 的变化趋势,识别访问高峰与异常波动。
-#### 核心指标
+### 核心指标
- **错误数(error_count)**:监控小程序错误事件的总数与时序趋势,及时发现异常峰值。
- **会话错误率(session error rate)**:发生错误的会话占总会话的比例,反映小程序整体稳定性。
@@ -29,15 +29,15 @@ Flashduty 微信小程序 RUM 分析看板提供开箱即用的可视化仪表
- **setData 调用次数(setDataCount 平均值)**:监控页面平均每次访问的 `setData` 调用次数。过高的调用频次会增加 JS 与渲染线程的通信开销。
- **setData 耗时 P75(setDataDuration P75)**:监控单次 `setData` 调用耗时的 P75 分位值。
-#### 会话分析
+### 会话分析
- **平均会话时长**:会话总时长除以会话总数,评估用户粘性与使用深度。结合时序图可识别活跃用户行为变化。
-## 性能分析 — 全面掌控小程序体验
+## 性能分析
性能分析模块专注于小程序启动、页面渲染、`setData` 等核心体验指标的全链路监控。
-#### 核心性能指标
+### 核心性能指标
顶部展示 5 个关键性能指标卡片,点击任一卡片可切换下方趋势图与样本分布的统计维度:
@@ -51,7 +51,7 @@ Flashduty 微信小程序 RUM 分析看板提供开箱即用的可视化仪表
每个卡片左上角显示健康状态徽标(良好 / 中等 / 差),基于内置阈值评估当前指标。
-#### 趋势分析
+### 趋势分析
下方的趋势图支持选择 **趋势模式**,按不同维度展开当前指标:
@@ -67,11 +67,11 @@ Flashduty 微信小程序 RUM 分析看板提供开箱即用的可视化仪表
切换 **按版本** 时可对比新版本灰度阶段的性能数据,验证发版质量;切换 **按加载类型** 时可单独观察冷启动(`initial_load`)和热启动(`route_change`)的耗时差异。
</Tip>
-#### 样本分布
+### 样本分布
样本分布柱状图按时间区间统计当前指标的样本数量分布,识别长尾问题。例如观察应用启动时长时,分布图能清晰展示有多少用户的启动耗时落在 1s 以内、1-2s、2s 以上等区间。
-#### 页面性能明细
+### 页面性能明细
按页面(视图名称)统计各项性能指标,识别加载缓慢或 `setData` 过于频繁的页面:
@@ -89,7 +89,7 @@ Flashduty 微信小程序 RUM 分析看板提供开箱即用的可视化仪表
点击表格中的任一行可跳转到该页面的详细分析视图。
-#### 启动类型趋势
+### 启动类型趋势
底部两张图分别展示冷启动(`initial_load`)与热启动(`route_change`)的对比情况:
diff --git a/zh/rum/analytics/native.mdx b/zh/rum/analytics/native.mdx
index d2609f80..20e56144 100644
--- a/zh/rum/analytics/native.mdx
+++ b/zh/rum/analytics/native.mdx
@@ -20,7 +20,7 @@ Native 看板适用于 Android、iOS、HarmonyOS、Flutter 和 React Native 应
- **Electron**:不使用 Native 看板——Electron 应用复用 **Web 分析看板**,但 UV 改用匿名 ID 口径(Electron SDK 不上报 `usr_id`),详见下方「指标口径参考」。
</Note>
-## 概览 — 关键指标一目了然
+## 概览
<Frame>
<img src="https://docs-cdn.flashcat.cloud/imges/png/84bd82ffe44022ebeaab64a56a1e9ed1.png" alt="Native RUM 分析看板概览界面,展示 UV、会话数、崩溃率等核心健康指标" />
@@ -35,7 +35,7 @@ Native 看板适用于 Android、iOS、HarmonyOS、Flutter 和 React Native 应
- **会话分析** - 统计会话平均时长分布趋势,评估用户粘性与使用深度
- **版本分布** - 监控不同系统版本(Android/iOS)和应用版本的用户占比,为兼容性优化与版本迭代提供数据支撑
-## 性能分析 — 全面掌控应用体验
+## 性能分析
<Frame>
<img src="https://docs-cdn.flashcat.cloud/imges/png/ad17864ce4854b7ded905a7a88bdbc87.png" alt="性能分析看板展示启动时间、帧率、CPU 和内存使用等关键性能指标" />
@@ -43,7 +43,7 @@ Native 看板适用于 Android、iOS、HarmonyOS、Flutter 和 React Native 应
性能分析模块专注于应用启动、页面渲染、交互流畅度等核心体验指标的全链路监控。
-#### 核心性能指标
+### 核心性能指标
顶部展示四个关键性能指标的 P75 分位值:
@@ -53,12 +53,12 @@ Native 看板适用于 Android、iOS、HarmonyOS、Flutter 和 React Native 应
- **内存使用(P75)**:监控应用内存占用的 P75 分位数,及时发现内存泄漏或异常增长。
- **JS 线程帧率(P75)**:监控 React Native JS 线程帧率的 P75 分位数(FPS)。相比原生帧率,它更直接反映业务 JavaScript 造成的卡顿(重渲染、桥上的同步工作)。仅 React Native SDK 上报。
-#### APP 启动时间分析
+### APP 启动时间分析
- **启动时间趋势图**:展示应用启动时间随时间的变化趋势,帮助您评估启动优化效果,及时发现性能退化。
- **样本分布柱状图**:按时间区间统计启动耗时的分布情况(如 0.9425s-0.9642s、1.1162s-1.1379s 等),了解用户真实启动体验的分布特征,识别性能长尾问题。
-#### 视图性能明细
+### 视图性能明细
按视图名称(页面/Activity/ViewController)统计各项性能指标:
@@ -69,7 +69,7 @@ Native 看板适用于 Android、iOS、HarmonyOS、Flutter 和 React Native 应
- **CPU 消耗**:统计各视图的 CPU 占用情况,优化计算密集型页面。
- **内存使用**:监控各视图的内存占用,发现内存泄漏风险。
-#### 流畅度分析
+### 流畅度分析
按视图名称统计应用流畅度相关指标:
@@ -85,14 +85,14 @@ Native 看板适用于 Android、iOS、HarmonyOS、Flutter 和 React Native 应
慢帧占比走的是另一条独立链路,关闭长任务采集不影响它。所以「慢帧占比有数值、其余三列全为 0」是关闭长任务采集后的预期现象,不是数据丢失。
-如果你关闭长任务采集是为了减少事件量,更好的做法是**调高阈值而不是关闭**,详见 [Android 性能影响](/zh/rum/sdk/android/performance-impact)。
+如果您关闭长任务采集是为了减少事件量,更好的做法是**调高阈值而不是关闭**,详见 [Android 性能影响](/zh/rum/sdk/android/performance-impact)。
</Warning>
<Note>
**慢帧占比不能跨平台横比。** 分子都是慢帧耗时,但分母不同:Android 除以渲染总耗时,iOS 除以视图停留时长。同一种用户体验在 Android 上的数值通常明显更高,因为静止界面几乎不产生帧,分母很小,而首帧本身又必然是慢帧。请在同一平台内部做纵向对比。
</Note>
-#### 内存分析
+### 内存分析
按视图名称统计内存使用详情:
@@ -100,7 +100,7 @@ Native 看板适用于 Android、iOS、HarmonyOS、Flutter 和 React Native 应
- **峰值内存**:记录各视图运行期间的内存使用峰值,识别内存压力高峰,预防因内存不足导致的系统终止(OOM)。
- **P75 内存**:显示内存占用的 P75 分位数,反映大部分用户的内存使用情况,比平均值更能代表真实体验。
-## 异常分析 — 快速定位与诊断错误
+## 异常分析
<Frame>
<img src="https://docs-cdn.flashcat.cloud/imges/png/b5868b87e52ddc7b82c61f685b2d0bd9.png" alt="异常分析看板展示崩溃次数、无崩溃率、ANR 率和无响应时长率" />
@@ -108,60 +108,51 @@ Native 看板适用于 Android、iOS、HarmonyOS、Flutter 和 React Native 应
异常分析模块为您提供全方位的错误监控与诊断能力。
-#### 核心稳定性指标
+### 核心稳定性指标
- **崩溃次数**:监控应用崩溃的发生总数和趋势,及时发现异常峰值。崩溃会导致应用强制退出,严重影响用户体验。
- **无崩溃率**:跟踪无崩溃会话占比,评估应用整体稳定性表现。行业标准建议无崩溃率应保持在 99.5% 以上。
- **ANR 率**:统计 Android 应用无响应(Application Not Responding)的发生比例。ANR 表示应用主线程被阻塞超过 5 秒,用户会看到"应用无响应"对话框。
- **无响应时长率**:每小时视图时长内主线程处于无响应状态的秒数(秒/小时),按视图时长加权平均,且仅统计 SDK 已完成测量的视图。**该卡片只在 iOS 和 Flutter 应用中展示**,纯 Android 应用对应展示的是上方的 ANR 率。详见下方「如何降低无响应时长率?」。
-#### 错误数据统计
+### 错误数据统计
- **错误数**:展示错误总数和时序趋势,了解应用健康状况的整体变化。
- **错误类型分布趋势图**:通过堆叠柱状图展示崩溃错误(crash_count)与非崩溃错误(non_crash_count)随时间的分布变化,快速识别异常时段和错误类型变化趋势。
- **崩溃错误(crash_count)**:导致应用强制退出的严重错误
- **非崩溃错误(non_crash_count)**:被捕获的异常,应用可继续运行但功能可能受影响
-#### 页面 Crash 排行(Top10)
+### 页面 Crash 排行与热门 Issue(Top10)
-列出崩溃次数最多的页面或视图控制器,每条记录包含:
+两个排行列出相同的字段:
-- **错误类型**:崩溃的异常类型(如 java.lang.RuntimeException、SIGTRAP 等)
-- **错误信息**:错误的详细描述,帮助快速定位问题
-- **错误数**:该错误在该页面发生的总次数
-- **会话数**:受该错误影响的会话(用户访问)数量
+| 字段 | 页面 Crash 排行 | 热门 Issue |
+| --- | --- | --- |
+| **错误类型** | 崩溃的异常类型(如 java.lang.RuntimeException、SIGTRAP) | Issue 的主要错误类型(如 java.lang.RuntimeException、TypeError) |
+| **错误信息** | 错误描述 | 典型错误描述,点击查看堆栈和会话 |
+| **错误数** | 该错误在该页面发生的次数 | 该 Issue 包含的错误次数 |
+| **会话数** | 受影响的会话数 | 受影响的会话数 |
-此排行帮助您优先处理影响最大的页面崩溃问题。
+页面 Crash 排行按页面或视图控制器统计崩溃最多的错误;热门 Issue 按影响用户数排列,每个 Issue 聚合了同一根因的多次错误,见[异常聚合](/zh/rum/error-tracking/error-aggregation)。
-#### 热门 Issue(Top10)
-
-展示影响用户最多的问题排行,每个 Issue 是经过聚合的错误集合,包含:
-
-- **错误类型**:Issue 的主要错误类型(如 java.lang.RuntimeException、TypeError、ReferenceError 等)
-- **错误信息**:Issue 的典型错误描述,点击可查看详细堆栈和会话信息
-- **错误数**:该 Issue 包含的错误总次数
-- **会话数**:受该 Issue 影响的会话数量
-
-**注意**:一个 Issue 可能聚合了多次相同根因的错误。关于 Issue 聚合策略,可查看[异常聚合](https://docs.flashduty.com/zh/flashduty/rum/error-grouping)。
-
-#### 错误类型分布
+### 错误类型分布
- **错误类型占比(饼图)**:展示不同错误类型的占比(如 ReferenceError、java.lang.RuntimeException 等),快速识别主要错误来源。
- **错误类型分布趋势(堆叠柱状图)**:监控各错误类型随时间的变化趋势,及时发现新增错误类型或某类错误的异常增长。
-#### 版本 Crash 分布
+### 版本 Crash 分布
- **版本 Crash 分布(饼图)**:统计不同应用版本的崩溃分布情况,识别高风险版本。
- **版本 Crash 分布趋势(堆叠柱状图)**:监控各版本崩溃随时间的变化,评估新版本质量,必要时进行热修复或回滚。
-#### 系统版本异常分布
+### 系统版本异常分布
- **系统版本异常分布(饼图)**:统计不同操作系统版本(如 Android 11、Android 12、iOS 15 等)的异常分布情况,识别系统兼容性问题。
- **系统版本异常趋势(堆叠柱状图)**:监控各系统版本异常随时间的变化,为系统兼容性优化提供数据支撑。
-如需深入分析具体错误,可参阅[错误跟踪](https://docs.flashduty.com/zh/flashduty/rum/error-tracking)了解如何调查关键错误、查看错误堆栈、追踪新错误的出现,以及如何在问题修复后验证效果。
+如需深入分析具体错误,可参阅[错误跟踪](/zh/rum/error-tracking/overview)了解如何调查关键错误、查看错误堆栈、追踪新错误的出现,以及如何在问题修复后验证效果。
-## 资源分析 — 精细化网络性能优化
+## 资源分析
<Frame>
<img src="https://docs-cdn.flashcat.cloud/imges/png/97a80ff169a3c3e625e1c2e6d9d6a5b8.png" alt="资源分析看板展示请求数、成功率、响应时间和资源耗时排行" />
@@ -223,7 +214,7 @@ Issue 数量:5 个
- 追踪修复效果:修复一个 Issue 后,可观察该 Issue 下所有错误是否消失
</Check>
-详细了解 [异常聚合策略](https://docs.flashduty.com/zh/flashduty/rum/error-grouping)。
+详细了解 [异常聚合策略](/zh/rum/error-tracking/error-aggregation)。
</Accordion>
@@ -531,7 +522,7 @@ Flashduty RUM 通常在数据产生后的 **1-3 分钟**内完成采集和展示
| 指标 | 计算方式 | 说明 |
|------|---------|------|
| 崩溃次数 | 直接统计 | 由未处理的异常或信号引起的崩溃总次数 |
-| 无崩溃率 | 按会话统计:1 减去「至少发生一次崩溃的会话数 ÷ 总会话数」 | 建议保持在 99% 以上;一个会话崩溃多次只计一次。Android ANR 不属于崩溃,不影响该指标 |
+| 无崩溃率 | 按会话统计:1 减去「至少发生一次崩溃的会话数 ÷ 总会话数」 | 建议保持在 99.5% 以上;一个会话崩溃多次只计一次。Android ANR 不属于崩溃,不影响该指标 |
| ANR 率 | ANR 会话数除以总会话数 | UI 线程阻塞超过 5 秒时触发(Android) |
| 无响应时长率 | 主线程无响应总时长除以视图总时长,换算为秒/小时 | iOS 统计 App Hang,需配置 appHangThreshold;Android 统计达到 5 秒的主线程冻结 |
diff --git a/zh/rum/best-practices/alert-noise-reduction.mdx b/zh/rum/best-practices/alert-noise-reduction.mdx
index ec558980..7827acde 100644
--- a/zh/rum/best-practices/alert-noise-reduction.mdx
+++ b/zh/rum/best-practices/alert-noise-reduction.mdx
@@ -14,7 +14,7 @@ Flashduty RUM 提供了从数据过滤、告警分级到 Flashduty 告警处理
[Issue 告警](/zh/rum/error-tracking/issue-alerts)。
</Info>
-
+
## 告警处理链路
diff --git a/zh/rum/best-practices/distributed-tracing.mdx b/zh/rum/best-practices/distributed-tracing.mdx
index 38efbf6d..8b3cc6db 100644
--- a/zh/rum/best-practices/distributed-tracing.mdx
+++ b/zh/rum/best-practices/distributed-tracing.mdx
@@ -246,6 +246,15 @@ allowedTracingUrls: [
- 监控追踪数据的存储和查询性能
- 根据业务需求调整追踪策略
+## 注意事项
+
+<Warning>
+- **隐私合规**:确保 trace 数据收集符合相关隐私法规要求
+- **性能影响**:合理设置采样率,避免对应用性能造成显著影响
+- **数据安全**:避免在 trace 数据中包含敏感信息
+- **跨域配置**:确保后端服务正确配置 CORS 以支持追踪头信息
+</Warning>
+
## 常见问题
<AccordionGroup>
@@ -267,11 +276,3 @@ allowedTracingUrls: [
</Accordion>
</AccordionGroup>
-## 注意事项
-
-<Warning>
-- **隐私合规**:确保 trace 数据收集符合相关隐私法规要求
-- **性能影响**:合理设置采样率,避免对应用性能造成显著影响
-- **数据安全**:避免在 trace 数据中包含敏感信息
-- **跨域配置**:确保后端服务正确配置 CORS 以支持追踪头信息
-</Warning>
diff --git a/zh/rum/error-tracking/erro-reporting/android.mdx b/zh/rum/error-tracking/error-reporting/android.mdx
similarity index 96%
rename from zh/rum/error-tracking/erro-reporting/android.mdx
rename to zh/rum/error-tracking/error-reporting/android.mdx
index 035cd50f..76fbc056 100644
--- a/zh/rum/error-tracking/erro-reporting/android.mdx
+++ b/zh/rum/error-tracking/error-reporting/android.mdx
@@ -39,7 +39,7 @@ SDK 可以检测并报告 ANR 问题,帮助您发现主线程阻塞导致的
### 基础配置
<Note>
-崩溃报告功能默认启用。确保您已按照 [SDK 接入指南](https://docs.flashduty.com/zh/flashduty/rum/android-sdk-integration) 完成基础 SDK 集成后,SDK 会自动捕获应用中的未处理异常。
+崩溃报告功能默认启用。确保您已按照 [SDK 接入指南](/zh/rum/sdk/android/sdk-integration) 完成基础 SDK 集成后,SDK 会自动捕获应用中的未处理异常。
</Note>
### 添加 NDK 崩溃报告
@@ -273,11 +273,11 @@ val rumConfig = RumConfiguration.Builder(applicationId)
1. 在应用中添加测试代码触发崩溃:
-```kotlin
-fun onEvent() {
- throw RuntimeException("测试崩溃")
-}
-```
+ ```kotlin
+ fun onEvent() {
+ throw RuntimeException("测试崩溃")
+ }
+ ```
2. 运行应用并触发崩溃
3. 重启应用,等待 SDK 上传崩溃报告
@@ -287,12 +287,12 @@ fun onEvent() {
1. 在原生代码中添加测试崩溃:
-```cpp
-void crash() {
- int* ptr = nullptr;
- *ptr = 42; // 触发空指针崩溃
-}
-```
+ ```cpp
+ void crash() {
+ int* ptr = nullptr;
+ *ptr = 42; // 触发空指针崩溃
+ }
+ ```
2. 从 Java/Kotlin 代码调用该原生方法
3. 重启应用,等待 SDK 上传崩溃报告
@@ -302,11 +302,11 @@ void crash() {
1. 在主线程执行耗时操作:
-```kotlin
-fun blockMainThread() {
- Thread.sleep(10000) // 阻塞主线程 10 秒
-}
-```
+ ```kotlin
+ fun blockMainThread() {
+ Thread.sleep(10000) // 阻塞主线程 10 秒
+ }
+ ```
2. 触发该操作后尝试与应用交互
3. 检查 Flashcat 控制台是否收到 ANR 报告
diff --git a/zh/rum/error-tracking/erro-reporting/ios.mdx b/zh/rum/error-tracking/error-reporting/ios.mdx
similarity index 98%
rename from zh/rum/error-tracking/erro-reporting/ios.mdx
rename to zh/rum/error-tracking/error-reporting/ios.mdx
index ab1f987b..5a044221 100644
--- a/zh/rum/error-tracking/erro-reporting/ios.mdx
+++ b/zh/rum/error-tracking/error-reporting/ios.mdx
@@ -334,11 +334,11 @@ RUM.enable(
2. **触发测试崩溃**:
-```swift
-func triggerTestCrash() {
- fatalError("测试崩溃")
-}
-```
+ ```swift
+ func triggerTestCrash() {
+ fatalError("测试崩溃")
+ }
+ ```
3. **重启应用**:崩溃发生后,从设备上重新启动应用,等待 SDK 上传崩溃报告。
@@ -348,11 +348,11 @@ func triggerTestCrash() {
1. 在主线程执行耗时操作:
-```swift
-func blockMainThread() {
- Thread.sleep(forTimeInterval: 5) // 阻塞主线程 5 秒
-}
-```
+ ```swift
+ func blockMainThread() {
+ Thread.sleep(forTimeInterval: 5) // 阻塞主线程 5 秒
+ }
+ ```
2. 触发该操作后尝试与应用交互。
diff --git a/zh/rum/error-tracking/erro-reporting/web.mdx b/zh/rum/error-tracking/error-reporting/web.mdx
similarity index 89%
rename from zh/rum/error-tracking/erro-reporting/web.mdx
rename to zh/rum/error-tracking/error-reporting/web.mdx
index 1d5f6dec..e14ef95b 100644
--- a/zh/rum/error-tracking/erro-reporting/web.mdx
+++ b/zh/rum/error-tracking/error-reporting/web.mdx
@@ -194,6 +194,13 @@ window.FC_RUM.init({
});
```
+## 最佳实践
+
+- **丰富上下文信息**:在 `addError` 中附加业务相关上下文(如用户 ID、操作类型),便于问题定位。示例:`{ userId: "12345", action: "submit_form" }`
+- **优化错误边界**:为关键 React 组件配置错误边界,确保渲染错误被捕获。记录组件名称和版本,便于追踪问题。
+- **控制错误量**:使用采样率或 `beforeSend` 过滤低价值错误,避免数据过载。优先监控影响用户体验的关键错误。
+- **分析与可视化**:在「分析看板」-「异常分析」Tab 查看错误数据趋势和分布,解决重点异常问题。
+
## 常见问题
<AccordionGroup>
@@ -217,25 +224,6 @@ window.FC_RUM.init({
</Accordion>
</AccordionGroup>
-## 最佳实践
-
-<CardGroup cols={2}>
- <Card title="丰富上下文信息" icon="info-circle">
- 在 `addError` 中附加业务相关上下文(如用户 ID、操作类型),便于问题定位。
-
- 示例:`{ userId: "12345", action: "submit_form" }`
- </Card>
- <Card title="优化错误边界" icon="shield">
- 为关键 React 组件配置错误边界,确保渲染错误被捕获。记录组件名称和版本,便于追踪问题。
- </Card>
- <Card title="控制错误量" icon="filter">
- 使用采样率或 `beforeSend` 过滤低价值错误,避免数据过载。优先监控影响用户体验的关键错误。
- </Card>
- <Card title="分析与可视化" icon="chart-line">
- 在「分析看板」-「异常分析」Tab 查看错误数据趋势和分布,解决重点异常问题。
- </Card>
-</CardGroup>
-
## 下一步
<Card title="查看异常" icon="eye" href="/zh/rum/error-tracking/error-viewing">
diff --git a/zh/rum/error-tracking/error-viewing.mdx b/zh/rum/error-tracking/error-viewing.mdx
index d4493ea7..2354bdbb 100644
--- a/zh/rum/error-tracking/error-viewing.mdx
+++ b/zh/rum/error-tracking/error-viewing.mdx
@@ -101,7 +101,7 @@ Issue 有 4 种状态,流转方式如下:
Issue 列表右上角提供 **CSV** 导出按钮,导出内容与当前列表的筛选、排序条件保持一致。
-点击 CSV 按钮后,可在弹层中选择导出内容:
+点击 **CSV** 按钮后,可在弹层中选择导出内容:
| 选项 | 默认值 | 说明 |
|------|--------|------|
@@ -115,7 +115,7 @@ Issue 列表右上角提供 **CSV** 导出按钮,导出内容与当前列表
导出文件始终包含 Issue 的 18 个字段(问题 ID、问题链接、应用、服务、错误类型、错误信息、状态、优先级、是否崩溃、错误数、影响会话数、首次出现、首次出现版本、最近出现、最近出现版本、涉及版本、疑似原因、解决时间),样例列在「包含错误样例」开启后附加。
<Warning>
-- 单次最多导出 **100 条**。匹配数量超过 100 时,按钮上方会提示「最多可导出 100 条,请缩小时间范围或增加筛选条件」;导出完成后若文件被截断,页面会再次提示已导出的条数。
+- 单次最多导出 **100 条**。超过时请缩小时间范围或增加筛选条件。
- 时间列(首次出现 / 最近出现 / 解决时间 / 样例发生时间)的列头会附加时区标识(如 `首次出现 (Asia/Shanghai)`),列内值为该时区下的 `YYYY-MM-DD HH:mm:ss` 文本,便于电子表格按日期排序。
- 样例堆栈截取前 20 行。完整堆栈可在 Issue 详情页查看(那里会按平台做符号化还原);导出不做符号化,给出的是上报的原始帧。
- 为防止公式注入,以 `=`、`+`、`-`、`@` 开头的单元格会被加上引号前缀。
@@ -202,7 +202,7 @@ Issue 列表支持两种查看模式:侧栏模式和全屏模式。默认以
<Accordion title="错误样例">
默认展示当前 Issue 发生期间最近一次上报的错误信息作为错误样例,您也可通过导航条进行切换。
- 对于 Native 崩溃,样例导航列表中的每条样例都会标注符号化状态(「已解析」/「未解析」徽标)。当最新一条样例尚未解析、而更早的样例可以符号化时,详情会自动切换到可符号化的样例,并提示「已自动切换到可符号化的样例(最新一条尚未解析)」;点击「回到最新」可切回最新上报的样例。自动切换最多尝试 5 条更早的样例,若这些样例均无法符号化,详情会切回最新一条样例,不再继续自动切换。
+ Native 崩溃的每条样例都会标注是否已符号化。如果最新一条样例尚未解析,详情会自动切换到更早的、可符号化的样例(最多尝试 5 条),点击 **回到最新** 可切回。
</Accordion>
<Accordion title="错误堆栈与源码映射">
查看错误的上下文信息和堆栈信息。如果已上传对应的 SourceMap、Android mapping 文件、iOS dSYM 文件或 Flutter 符号文件,您可以看到映射还原后的原始源码位置和代码片段。
@@ -242,13 +242,11 @@ Issue 列表支持两种查看模式:侧栏模式和全屏模式。默认以
**本条崩溃所需符号(非系统库)**
- 当崩溃事件携带非系统二进制镜像时(iOS、Electron 等通过二进制镜像还原地址的 Native 崩溃,含 Flutter 的 iOS 原生崩溃),堆栈上方会展示「本条崩溃所需符号(非系统库)」区块,列出本条崩溃引用的所有非系统二进制镜像及其符号化状态:
+ iOS、Electron 等 Native 崩溃(含 Flutter 的 iOS 原生崩溃)会在堆栈上方列出本条崩溃引用的非系统二进制镜像,每个镜像显示名称、UUID 和是否已解析(存在未解析镜像时默认展开)。您可以:
- - 区块标题汇总为「已解析数/总数 已解析」;全部已解析时默认折叠为一行摘要,存在未解析镜像时默认展开
- - 每个镜像一行,展示镜像名称、UUID 以及「已解析」/「未解析」徽标,并提供复制 UUID 的按钮
- - 点击「在符号表中查找」跳转到「源码映射」页面,并按该镜像的 UUID 预筛选符号表
- - 未解析的镜像提供「去上传」链接,直达「源码映射」页面的上传入口
- - 未解析时也可以点击区块中的「重新解析」按钮,强制重新符号化并刷新堆栈
+ - 复制 UUID,或点击 **在符号表中查找** 打开按该 UUID 筛选的源码映射页面;
+ - 对未解析的镜像点击 **去上传** 上传符号文件;
+ - 上传后点击 **重新解析** 刷新堆栈。
**Flutter 支持**
@@ -308,26 +306,12 @@ Issue 列表支持两种查看模式:侧栏模式和全屏模式。默认以
## 最佳实践
-<CardGroup cols={2}>
- <Card title="配置源码映射" icon="code">
- 便于在生产环境定位问题
- </Card>
- <Card title="添加用户信息" icon="user">
- 配置用户相关信息,提供更好的错误上下文
- </Card>
- <Card title="设置告警策略" icon="bell">
- 为错误配置合理的协作空间和分派策略
- </Card>
- <Card title="定期错误分析" icon="chart-line">
- 定期检查错误报告,发现潜在问题
- </Card>
- <Card title="团队协作" icon="users">
- 利用团队所有权功能确保问题能够快速分配给相关团队
- </Card>
- <Card title="监控回归" icon="rotate">
- 密切关注已解决问题的潜在回归
- </Card>
-</CardGroup>
+- **配置源码映射**:便于在生产环境定位问题
+- **添加用户信息**:配置用户相关信息,提供更好的错误上下文
+- **设置告警策略**:为错误配置合理的协作空间和分派策略
+- **定期错误分析**:定期检查错误报告,发现潜在问题
+- **团队协作**:利用团队所有权功能确保问题能够快速分配给相关团队
+- **监控回归**:密切关注已解决问题的潜在回归
## 下一步
diff --git a/zh/rum/error-tracking/issue-status.mdx b/zh/rum/error-tracking/issue-status.mdx
index 8ac24080..eca50faf 100644
--- a/zh/rum/error-tracking/issue-status.mdx
+++ b/zh/rum/error-tracking/issue-status.mdx
@@ -38,7 +38,7 @@ Flashduty 会自动将不活跃或已解决的 Issue 标记为**已解决(reso
## 自动重新打开 Issue
-Flashduty 具备 Issue 检测功能,当已解决的 Issue 再次出现时,系统会自动重新打开并标记为**待处理(for_review)**状态,同时在活动时间线中记录该事件为「问题复现」状态。
+Flashduty 具备 Issue 检测功能,当已解决的 Issue 再次出现时,系统会自动重新打开并标记为<strong>待处理(for_review)</strong>状态,同时在活动时间线中记录该事件为「问题复现」状态。
### 什么是问题复现?
@@ -48,8 +48,8 @@ Flashduty 具备 Issue 检测功能,当已解决的 Issue 再次出现时,
<Warning>
当满足以下任一条件时,复现检测将被触发:
-- 如果**已解决(resolved)**的错误在代码的更新版本中重新出现
-- 如果在未设置版本标签的情况下,**已解决(resolved)**状态的错误再次出现
+- 如果<strong>已解决(resolved)</strong>的错误在代码的更新版本中重新出现
+- 如果在未设置版本标签的情况下,<strong>已解决(resolved)</strong>状态的错误再次出现
</Warning>
一旦检测到问题复现,Flashduty 会:
@@ -65,7 +65,7 @@ Flashduty 具备 Issue 检测功能,当已解决的 Issue 再次出现时,
### 关联版本配置
-复现检测会考虑错误发生的服务版本信息,只有在 Issue 标记为**已解决(resolved)**后的新版本中才会触发检测。
+复现检测会考虑错误发生的服务版本信息,只有在 Issue 标记为<strong>已解决(resolved)</strong>后的新版本中才会触发检测。
```javascript
window.FLASHCAT_RUM.init({
@@ -91,14 +91,8 @@ window.FLASHCAT_RUM.init({
## 最佳实践
-<CardGroup cols={2}>
- <Card title="持续监控" icon="eye">
- 定期检查**待处理(for_review)**状态的 Issue,确保新问题和回归问题得到及时处理
- </Card>
- <Card title="版本管理" icon="code-branch">
- 始终为应用程序配置正确的版本标签,以便系统能准确识别已解决的问题
- </Card>
-</CardGroup>
+- **持续监控**:定期检查<strong>待处理(for_review)</strong>状态的 Issue,确保新问题和回归问题得到及时处理
+- **版本管理**:始终为应用程序配置正确的版本标签,以便系统能准确识别已解决的问题
<Tip>
通过有效管理 Issue 状态,您的团队可以更专注于解决重要问题,减少处理噪声的时间,提升整体开发效率。
diff --git a/zh/rum/error-tracking/overview.mdx b/zh/rum/error-tracking/overview.mdx
index 4387d0a5..9e6451fe 100644
--- a/zh/rum/error-tracking/overview.mdx
+++ b/zh/rum/error-tracking/overview.mdx
@@ -113,7 +113,7 @@ Flashduty RUM 的异常追踪分为两个关键阶段:**问题发现** 和 **
## 下一步
<CardGroup cols={2}>
- <Card title="异常上报" icon="upload" href="/zh/rum/error-tracking/erro-reporting/web">
+ <Card title="异常上报" icon="upload" href="/zh/rum/error-tracking/error-reporting/web">
了解异常上报规则和方式
</Card>
<Card title="异常查看" icon="eye" href="./error-viewing">
diff --git a/zh/rum/error-tracking/source-mapping.mdx b/zh/rum/error-tracking/source-mapping.mdx
index 678f1adb..7f54c0f0 100644
--- a/zh/rum/error-tracking/source-mapping.mdx
+++ b/zh/rum/error-tracking/source-mapping.mdx
@@ -142,7 +142,7 @@ Flashduty 支持多平台的符号文件上传与源码映射,帮助开发者
## 上传微信小程序 SourceMap
-微信小程序发布后,线上错误堆栈通常只包含转换后的文件路径和行列号。你可以先使用 `miniprogram-ci get-dev-source-map` 生成 `sourcemap.zip`,再通过 Flashduty CLI 上传。上传后,Flashduty 会按服务名、版本和文件路径匹配小程序错误堆栈,并在异常详情中展示还原后的源码位置。
+微信小程序发布后,线上错误堆栈通常只包含转换后的文件路径和行列号。您可以先使用 `miniprogram-ci get-dev-source-map` 生成 `sourcemap.zip`,再通过 Flashduty CLI 上传。上传后,Flashduty 会按服务名、版本和文件路径匹配小程序错误堆栈,并在异常详情中展示还原后的源码位置。
<Steps>
<Step title="生成小程序 SourceMap 压缩包">
@@ -207,7 +207,7 @@ HarmonyOS 崩溃栈可能同时包含 **ArkTS / JS 帧** 和 **Native `.so` 帧*
- `nameCache.json`:可选,用于还原混淆后的标识符名称
- 未 strip 的 Native `.so`:用于符号化 C/C++ 崩溃栈
-控制台的 **应用管理 → 源码管理 → HarmonyOS** 上传面板会要求你填写 **Service**、**Version** 和 **API Key**,并生成对应的 `hvigor` 配置和上传命令。`service` 与 `version` 必须和应用实际上报的值保持一致,否则服务端无法匹配到对应符号文件。
+控制台的 **应用管理 → 源码管理 → HarmonyOS** 上传面板会要求您填写 **Service**、**Version** 和 **API Key**,并生成对应的 `hvigor` 配置和上传命令。`service` 与 `version` 必须和应用实际上报的值保持一致,否则服务端无法匹配到对应符号文件。
<Steps>
<Step title="安装 hvigor 插件">
@@ -257,7 +257,7 @@ HarmonyOS 崩溃栈可能同时包含 **ArkTS / JS 帧** 和 **Native `.so` 帧*
<Warning>
- 请使用 **0.1.5 及以上**版本:0.1.3 注册任务时会声明不存在的 `assembleHar` 依赖,导致构建直接失败;0.1.4 已从 npm 撤回,装不到
- 公有云省略 `endpoint` 时,**hvigor-plugin ≥ 0.1.3** 默认上传到 `https://ci.flashcat.cloud`。不要用 RUM 上报域名 `browser.flashcat.cloud`(会 404)。私有化设置 `FLASHCAT_SOURCEMAP_INTAKE_URL`(需 ≥ 0.1.3)或显式传 `endpoint`
-- Native `.so` 需要保留 GNU build-id;HarmonyOS NDK 默认开启,如你的构建链路关闭了它,请显式添加 `-Wl,--build-id`
+- Native `.so` 需要保留 GNU build-id;HarmonyOS NDK 默认开启,如您的构建链路关闭了它,请显式添加 `-Wl,--build-id`
- 更完整的 HarmonyOS 接入、符号上传和兼容性说明,请继续阅读 [HarmonyOS SDK 高级配置](/zh/rum/sdk/harmony/advanced-config)
</Warning>
@@ -461,7 +461,7 @@ Flutter 应用使用 `--obfuscate` 混淆构建后,Dart 异常堆栈中的符
<Warning>
**iOS 的 Dart 堆栈暂不支持符号化。** Flutter 为 Apple 平台生成的符号文件是 Mach-O 格式,平台当前只能解析 Android 侧的 ELF 格式,因此 iOS 的 `.symbols` 上传会被拒绝。iOS 原生崩溃(Objective-C / Swift / C / C++)不受影响,与原生 iOS 应用一样上传 dSYM 即可符号化。
-如果你的应用同时发布 iOS 和 Android,`--obfuscate` 仍可开启:Android 的 Dart 堆栈会正常还原,iOS 的 Dart 堆栈则保持混淆状态。若 iOS 的可读堆栈更重要,则该端构建时不要开启 `--obfuscate`。
+如果您的应用同时发布 iOS 和 Android,`--obfuscate` 仍可开启:Android 的 Dart 堆栈会正常还原,iOS 的 Dart 堆栈则保持混淆状态。若 iOS 的可读堆栈更重要,则该端构建时不要开启 `--obfuscate`。
</Warning>
<Note>
diff --git a/zh/rum/explorer/analytics.mdx b/zh/rum/explorer/analytics.mdx
index c855e700..c7354d9b 100644
--- a/zh/rum/explorer/analytics.mdx
+++ b/zh/rum/explorer/analytics.mdx
@@ -9,14 +9,7 @@ RUM 查看器提供**列表**与**分析**两种查看方式。**分析**视图
## 列表与分析
-查看器顶部有两个页签:**列表**逐条展示事件,**分析**把事件汇总成图表。两者共用同一套事件类型、查询条件和时间范围,切换页签不会丢失当前的筛选条件。
-
-分析视图记录在 URL 的 `mode` 参数中:`mode=analytics` 打开分析,省略 `mode` 则打开列表,因此已有的查看器链接仍然指向列表。复制分析视图的链接即可与他人分享同一张图表。
-
-| 页签 | `mode` 取值 | 展示内容 |
-|------|-------------|----------|
-| **列表** | 省略 | 事件趋势图与事件表格,逐条下钻事件详情 |
-| **分析** | `analytics` | 按统计方式与分组聚合后的图表 |
+查看器顶部有两个页签:**列表**逐条展示事件,**分析**把事件汇总成图表。两者共用同一套事件类型、查询条件和时间范围,切换页签不会丢失筛选条件。分析视图的状态保存在链接中,复制链接即可分享同一张图表(参数见[URL 参数](#url-参数))。
## 选择统计方式与字段
@@ -24,98 +17,83 @@ RUM 查看器提供**列表**与**分析**两种查看方式。**分析**视图
### 统计方式
-| 统计方式 | `agg` 取值 | 说明 |
-|----------|-----------|------|
-| **计数** | `count` | 事件条数,不需要字段 |
-| **去重计数** | `count_distinct` | 字段去重后的取值个数 |
-| **平均值** | `avg` | 数值字段的平均值 |
-| **求和** | `sum` | 数值字段的合计 |
-| **最小值** | `min` | 数值字段的最小值 |
-| **最大值** | `max` | 数值字段的最大值 |
-| **P50 / P75 / P90 / P95 / P99** | `p50` / `p75` / `p90` / `p95` / `p99` | 数值字段的近似分位数,用于观察长尾 |
+| 统计方式 | 说明 |
+|----------|------|
+| **计数** | 事件条数,不需要字段 |
+| **去重计数** | 字段去重后的取值个数 |
+| **平均值** | 数值字段的平均值 |
+| **求和** | 数值字段的合计 |
+| **最小值** | 数值字段的最小值 |
+| **最大值** | 数值字段的最大值 |
+| **P50 / P75 / P90 / P95 / P99** | 数值字段的近似分位数,用于观察长尾 |
-除**计数**外,所有统计方式都需要先选择**统计字段**。选择平均值、求和、最小值、最大值或任一分位数时,字段选择器只列出数值类型字段;时间戳字段(单位 `unix_millisecond`)不参与数值统计,因此不在候选之列。选择**去重计数**时,字段选择器列出可作为分组的标量 facet 字段。切换事件类型后,如果原字段在新的事件类型上不存在,选择器会提示重新选择字段,而不会把问题悄悄变成计数。
+除**计数**外,所有统计方式都需要选择**统计字段**:
-图例、表格列与 CSV 表头使用同一套命名:**计数**与**分布图**的统计值显示为「事件数」,其他统计方式显示为「统计方式(字段名)」,例如「平均值(view_loading_time)」。
+- 平均值、求和、最小值、最大值和分位数只能选数值字段(时间戳字段除外)。
+- 去重计数可以选任一可分组的字段。
+- 切换事件类型后,如果原字段在新类型上不存在,需要重新选择。
-### 分组字段
+图例、表格和 CSV 中,计数和分布图的统计值显示为「事件数」,其他统计方式显示为「统计方式(字段名)」,如「平均值(view_loading_time)」。
-**分组字段**决定按什么拆开。选定后,图表为每个分组取值单独展示,并在旁边出现**取前**选择器,可选 `5`、`10`、`20`、`50` 组,默认 `10` 组。分组字段可以清空(占位文案为「不分组」),清空后结果汇总为单个数值。分组字段只列出标量 facet 字段;数组字段一条事件持有多个取值,无法作为分组依据。
+### 分组字段
-**分布图**不使用分组字段,该选择器不显示。
+**分组字段**决定按什么拆开,每个取值单独展示。可以用**取前**选择保留前 `5`、`10`(默认)、`20` 或 `50` 组;不选分组字段时,结果汇总为单个数值。数组字段不能用于分组,**分布图**不使用分组。
## 图表类型
分析视图提供五种图表类型:
-| 图表类型 | `viz` 取值 | 说明 |
-|----------|-----------|------|
-| **时序图** | `timeseries` | 按时间桶展示统计值随时间的走势,为默认图表类型 |
-| **排行** | `toplist` | 各分组的统计值从大到小排行 |
-| **饼图** | `pie` | 各分组的占比,需满足下方适用范围 |
-| **表格** | `table` | 分组与统计值两列明细 |
-| **分布图** | `distribution` | 一个数值字段按区间分桶后的事件数直方图 |
-
-**时序图**额外提供**画法**选择器,可在**折线**(`line`)与**柱状**(`bar`)之间切换,默认柱状。选择分组字段、画法为柱状、且统计方式为**计数**或**求和**时,柱状图按分组堆叠,柱高即为合计值;其他统计方式(平均值、分位数、去重计数)不能堆叠,因为各分组的值不可相加。
+| 图表类型 | 说明 |
+|----------|------|
+| **时序图** | 统计值随时间的走势(默认) |
+| **排行** | 各分组按统计值从大到小排列 |
+| **饼图** | 各分组的占比。需要选择分组字段,且统计方式为**计数**或**求和**(只有这两种可以相加为整体) |
+| **表格** | 分组与统计值两列明细 |
+| **分布图** | 一个数值字段按区间分桶后的事件数直方图,见[分布图](#分布图) |
-未选择分组字段时,**排行**与**表格**直接展示该统计值本身,而不是画一根柱子;**时序图**仍按时间展示一条曲线。
+**时序图**可以选择**柱状**(默认)或**折线**。有分组且统计方式为计数或求和时,柱状图按分组堆叠,柱高即合计值;其他统计方式的分组值不能相加,因此不堆叠。
## 点击下钻
-点击图上的元素会弹出下钻菜单,用于从聚合结果回到明细事件:时序图的某个时间点、排行或表格的某一行、饼图的某个扇区、分布图的某个区间。
+点击图上的时间点、行、扇区或区间,可以从聚合结果下钻到明细事件:
| 菜单项 | 作用 |
|--------|------|
| **在列表中查看** | 切换到列表页签,只展示该元素背后的事件 |
-| **拆分「值」** | 只保留点击的分组取值,并打开分组字段选择器,以便继续按下一层字段拆分;分布图的区间没有分组,此时该项为**筛选为「区间」**,只保留落在该区间的事件 |
+| **拆分「值」** | 只保留该取值,并选择下一层分组字段继续拆分(分布图中为**筛选为「区间」**) |
| **排除「值」** | 从结果中排除点击的分组取值 |
-下钻写入的是与左侧 facet 列表相同的筛选条件,因此搜索框中会显示这些条件,也可以按同样的方式撤销。时序图的时间点下钻会把列表的时间范围收敛到该时间桶,分布图的区间下钻会把列表按该数值区间筛选。
-
-从**在列表中查看**进入列表后,列表顶部出现**返回分析**条,提示「列表已按下钻的条件筛选,返回时恢复原来的条件」。点击即可回到分析视图,并恢复下钻前的查询条件。手动切换页签会结束这次下钻,返回条随之消失。
+下钻会添加普通的筛选条件(时间点下钻会缩小时间范围),可以在搜索框中查看和撤销。通过**在列表中查看**进入列表后,点击顶部的**返回分析**即可回到下钻前的分析视图。
<Note>
-图上显示为「(空值)」的空值分组暂不支持下钻筛选,对它的**拆分**与**排除**均不可用。
+空值分组(显示为「(空值)」)暂不支持拆分和排除。
</Note>
## 缩放时序图
-在**时序图**上拖选一段时间即可放大到该时间窗。缩放只作用于这张图,查看器自身的时间范围保持不变。放大后图表右上角显示**已放大**徽标与当前窗口范围,点击其中的关闭按钮(**重置缩放**)恢复全量时间范围。切换事件类型、修改查询条件或调整查看器时间范围都会重置缩放。
+在**时序图**上拖选一段时间即可放大,只影响这张图,不改变查看器的时间范围。点击**已放大**标记上的关闭按钮恢复;切换事件类型、修改查询条件或时间范围也会重置缩放。
## 下载图片与导出 CSV
-图表右上角提供两个导出按钮:
-
-| 按钮 | 说明 |
-|------|------|
-| **下载图片** | 将当前图表导出为 PNG,以 2 倍像素密度渲染。表格类型与未选择分组字段的单个数值没有图形可导出,此时按钮不可用 |
-| **CSV** | 将当前图表的数据导出为 CSV,文件名形如 `rum-<事件类型>-analytics-<时间戳>.csv`。时序图按「时间、分组、统计值」逐行导出(长表格式);其他图表每个分组一行 |
+图表右上角可以:
-结果为空时两个按钮均不可用。
+- **下载图片**:导出为 2 倍清晰度的 PNG。表格和不分组的单个数值不支持。
+- **CSV**:导出图表数据。时序图每行是「时间、分组、统计值」,其他图表每个分组一行。
## 分布图
-**分布图**按一个数值字段的取值区间分桶,展示每个区间内的事件数,不使用统计方式与分组字段。
-
-- 分桶范围从字段的最小值一直覆盖到 `P99`:RUM 的耗时类数据长尾很长(几千次 1 秒的加载中夹着一次 46 秒),若一直分到最大值,绝大多数取值会被挤进第一根柱子。
-- 分桶宽度自动取 `1`、`2` 或 `5` 乘以 10 的幂,使区间边界落在整齐的数值上,整体约切分 40 个桶。
-- 高于 `P99` 的取值全部并入最后一个开放区间,图上与 CSV 中显示为「≥ 边界值」。
-- 区间按字段自身的单位显示,例如耗时字段的 `1s–1.5s`。
-
-## 饼图的适用范围
-
-饼图必须同时满足两个条件,否则图表区域提示「饼图需要分组,且只适用于计数和求和」:
+**分布图**按一个数值字段的取值区间分桶,展示每个区间的事件数,不使用统计方式和分组。
-- 选择了**分组字段**;
-- 统计方式为**计数**或**求和**——只有这两种统计方式的分组值可以相加为整体,去重计数、平均值与分位数都不满足这一前提。
+- 分桶覆盖最小值到 `P99`,约 40 个桶,边界取整齐的数值;高于 `P99` 的取值并入最后一个「≥ 边界值」区间,避免长尾把大多数数据挤进第一根柱子。
+- 区间按字段单位显示,如 `1s–1.5s`。
## 采样估算
-当数据量较大、结果由抽样数据估算得到时,图表右上角显示**采样估算**徽标,悬停提示「数据量较大,结果按抽样数据估算」。
+数据量较大时,结果按抽样数据估算,图表右上角会显示**采样估算**标记。
## URL 参数
-分析视图的状态保存在 URL 中,复制链接即可复现同一次分析。参数取值非法时会回退到默认值。
+分析视图的状态保存在 URL 中,复制链接即可复现同一次分析,也可以按下表拼出链接。非法取值会回退到默认值。
| 参数 | 含义 | 取值 | 默认值 |
|------|------|------|--------|
diff --git a/zh/rum/explorer/data-query.mdx b/zh/rum/explorer/data-query.mdx
index 638923ed..2ab56340 100644
--- a/zh/rum/explorer/data-query.mdx
+++ b/zh/rum/explorer/data-query.mdx
@@ -4,18 +4,15 @@ description: "掌握 Flashduty RUM 查看器的搜索语法,通过灵活的查
keywords: ["RUM", "数据查看器", "用户监控", "前端监控"]
---
-Flashduty RUM 查看器提供了强大的检索能力,允许您通过灵活的查询语法快速定位和分析 RUM 数据。查询由**词项**(terms)和**操作符**(operators)组成,支持复杂的搜索条件组合。
+RUM 查看器的查询由**词项**(terms)和**操作符**(operators)组成,可以组合出复杂的检索条件;不熟悉语法时也可以用自然语言查询。
## AI 自然语言查询
-如果您还不熟悉查询语法,可以直接用自然语言描述想要查找的数据,AI 会自动将其转换为查询语句。
+不熟悉查询语法时,可以直接用自然语言(中英文均可)描述要找的数据,AI 会将其转换为标准查询语句(DQL),字段与语法与手动查询完全一致。点击查询框左侧的 **AI 自然语言查询**(魔法棒)图标进入,或在普通查询模式下按 <kbd>⌘</kbd> + <kbd>Enter</kbd>(Windows 和 Linux 为 <kbd>Ctrl</kbd> + <kbd>Enter</kbd>);进入后输入框边框会高亮。
<Steps>
- <Step title="进入 AI 查询">
- 点击查询输入框中的**魔法棒**图标进入 AI 自然语言查询模式。进入后输入框边框会高亮,与普通查询模式明确区分。
- </Step>
<Step title="描述查询意图">
- 用自然语言描述您想查找的数据(支持中英文),然后按**回车**转换。例如:
+ 用自然语言描述您想查找的数据,按 <kbd>Enter</kbd> 生成预览。例如:
```
来自 Chrome 浏览器、耗时超过 2 秒的 5xx 资源请求
@@ -26,24 +23,28 @@ Flashduty RUM 查看器提供了强大的检索能力,允许您通过灵活的
```
browser_name:Chrome resource_status_code:>=500 resource_duration:>2s
```
+
+ 您无需记住字段名,AI 会按当前事件类型选择可查询的字段。
</Step>
- <Step title="预览并应用">
- AI 生成对应的查询语句并展示预览。确认无误后点击**应用**,查询立即生效;若结果不理想,可继续修改描述后再次回车重新生成,或点击**撤销**回退到应用前的状态。
+ <Step title="查看变更预览">
+ 预览显示将要加入的 DQL 条件;当请求更适合其他事件类型(如提示「将切换事件类型为 错误」)或时间范围时,也会显示相应变更。结果不理想时,修改描述后再次回车即可重新生成。
+ </Step>
+ <Step title="应用或撤销">
+ 点击 **应用**、**追加到查询** 或 **切换并应用** 确认变更。应用后,提示消息中提供 **撤销**,可恢复应用前的查询、事件类型和时间范围。
</Step>
</Steps>
-<Note>
-AI 生成的是标准查询语句(DQL),使用的字段与语法与手动查询完全一致(详见下文)。您无需记住字段名称,AI 会根据当前事件类型自动选择可查询的字段。
-</Note>
-
### 追加而非替换
-当输入框中已有查询条件时,AI 生成的条件会**追加**到现有查询之后,而不会覆盖它。因此您可以在已有查询的基础上,用自然语言逐步补充筛选条件。若当前为空查询,则直接应用生成结果。
+输入框中已有查询条件时,AI 生成的条件会**追加**到现有查询之后,不会覆盖,因此可以用自然语言逐步补充筛选条件;空查询时直接应用生成结果。
-如果您的描述更适合其他事件类型,AI 会提示切换(如「将切换事件类型为 错误」),并在该事件类型的可查询字段范围内生成查询。
+<Note>
+- “最近 1 小时”“昨天”“过去 7 天”等时间表达会更新查看器的时间选择器,不会被写成 `client_time` 等 DQL 条件;性能时长条件仍属于 DQL,例如 `view_loading_time:>2s`。
+- 时间范围最长 **14 天**。请求的范围更长时,预览会提示已截取最近 14 天:相对时间范围改为过去 14 天,绝对时间范围保留请求的结束时间并向前取 14 天。
+</Note>
<Tip>
-在 AI 输入框中用**自然语言**描述意图即可,无需手写查询语句(如 `browser_name:Chrome`)——直接输入查询语法反而会降低转换准确率。需要精确控制查询条件时,请改用下方的查询语法。
+在 AI 输入框中用**自然语言**描述即可,直接输入查询语法(如 `browser_name:Chrome`)反而会降低转换准确率。需要精确控制条件时,请使用下方的查询语法。
</Tip>
## 查询基础
@@ -63,30 +64,6 @@ AI 生成的是标准查询语句(DQL),使用的字段与语法与手动
| `OR` | 并集:任一词项包含在选定的视图中,需要使用 `()` 包裹起来 | `(error OR warning)` |
| `-` | 排除:后面的词项不在视图中 | `error -timeout` |
-## AI 自然语言查询
-
-如果你不想手写 DQL,可以让 AI 将自然语言请求转换为查询条件。在 RUM 查看器的查询框左侧点击 **AI 自然语言查询** 图标;也可以在普通查询模式下按 <kbd>⌘</kbd> + <kbd>Enter</kbd>(Windows 和 Linux 为 <kbd>Ctrl</kbd> + <kbd>Enter</kbd>)。
-
-<Steps>
- <Step title="输入查询意图">
- 用自然语言描述你想查看的数据,例如“Chrome 浏览器上的报错”“耗时超过 2 秒的资源请求”或“过去 24 小时的 checkout 页面”。按 <kbd>Enter</kbd> 生成预览。
- </Step>
- <Step title="查看变更预览">
- 预览会显示将要加入的 DQL 条件;当请求更适合其他事件类型或时间范围时,也会显示事件类型或时间范围的变更。
- </Step>
- <Step title="应用或撤销">
- 点击 **应用**、**追加到查询** 或 **切换并应用** 确认变更。应用后,提示消息中会提供 **撤销**,用于恢复应用前的查询、事件类型和时间范围。
- </Step>
-</Steps>
-
-<Note>
-“最近 1 小时”“昨天”“过去 7 天”等时间表达会更新查看器的时间选择器,不会被写成 `client_time` 等 DQL 条件。性能时长条件仍然属于 DQL,例如 `view_loading_time:>2s`。
-</Note>
-
-<Note>
-AI 自然语言查询的时间范围最长为 **14 天**。如果请求的范围更长,预览会提示已截取最近 14 天;应用后时间选择器会使用截取后的范围。相对时间范围会改为过去 14 天,绝对时间范围会保留请求的结束时间,并向前取 14 天。
-</Note>
-
## 全文检索
<Warning>
@@ -241,24 +218,11 @@ session_sampled_for_error:true
## 最佳实践
-<CardGroup cols={2}>
- <Card title="使用引号包围短语" icon="quote-left">
- 确保多词短语的精确匹配
- </Card>
- <Card title="合理使用通配符" icon="asterisk">
- 避免过于宽泛的检索条件
- </Card>
- <Card title="组合多个条件" icon="layer-group">
- 通过 AND/OR 操作符构建精确查询
- </Card>
- <Card title="利用自动补全" icon="keyboard">
- 减少输入错误,提高检索准确性
- </Card>
-</CardGroup>
-
-<Tip>
-保存常用检索条件,提高重复查询的效率。
-</Tip>
+- 多词短语用双引号包围,确保精确匹配。
+- 谨慎使用通配符,避免条件过于宽泛。
+- 用 `AND` / `OR` 组合多个条件,构建精确查询。
+- 借助自动补全减少输入错误。
+- 保存常用检索条件,方便重复查询。
## 下一步
diff --git a/zh/rum/explorer/overview.mdx b/zh/rum/explorer/overview.mdx
index 0e8677c6..3a55b961 100644
--- a/zh/rum/explorer/overview.mdx
+++ b/zh/rum/explorer/overview.mdx
@@ -1,86 +1,36 @@
---
title: "RUM 查看器功能概览"
sidebarTitle: "功能概览"
-description: "掌握 Flashduty RUM 查看器的强大功能,通过可视化界面深入分析用户数据、性能指标和应用行为。"
+description: "使用 RUM 查看器检索和分析 RUM 事件:选择应用、搜索过滤、查看事件详情、保存视图与导出 CSV。"
keywords: ["RUM", "数据查看器", "用户监控", "前端监控"]
---
-Flashduty RUM **查看器**(RUM Explorer)是一款强大的数据分析工具,旨在帮助开发者深入检查从应用程序收集的数据,并获取关于 RUM 事件的详细信息。通过直观的可视化界面,您可以全面了解用户行为、应用性能和系统健康状况。
+RUM **查看器**(RUM Explorer)用来检索和分析应用上报的 RUM 事件:浏览用户的完整会话路径,调查影响页面、资源或操作的性能问题,排查错误和长任务,并把事件聚合成图表(见 [聚合分析](./analytics))。
-## 核心功能
+## 选择应用
-<CardGroup cols={2}>
- <Card title="用户会话导航" icon="route">
- 浏览和分析用户的完整会话路径,了解用户在应用中的行为模式
- </Card>
- <Card title="性能问题调查" icon="gauge-high">
- 深入分析影响页面视图、资源加载或用户操作的性能问题
- </Card>
- <Card title="应用错误排查" icon="bug">
- 快速定位和诊断应用程序错误以及长时间运行的任务
- </Card>
- <Card title="数据搜索过滤" icon="filter">
- 通过搜索栏和可视化类型选择,对 RUM 事件进行精确过滤和筛选
- </Card>
- <Card title="聚合分析" icon="chart-line" href="./analytics">
- 按统计方式与分组把 RUM 事件汇总成图表,并从聚合结果下钻到原始事件
- </Card>
-</CardGroup>
+使用顶部导航栏的应用选择器选择应用,查看器只显示该应用的 RUM 数据;切换应用即可切换数据视图。
-## 价值与优势
+## 搜索与过滤
-| 优势 | 描述 |
-|------|------|
-| **数据驱动决策** | 基于真实用户数据做出产品优化和性能改进决策 |
-| **问题快速定位** | 通过可视化界面快速识别性能瓶颈和用户体验问题 |
-| **用户行为洞察** | 深入了解用户如何与您的应用交互,发现改进机会 |
-| **全面监控覆盖** | 从页面加载到用户操作的全链路监控和分析 |
-
-## 使用场景
-
-<AccordionGroup>
- <Accordion title="性能优化">
- 分析页面加载时间、资源加载效率,识别性能瓶颈。
- </Accordion>
- <Accordion title="用户体验改进">
- 了解用户操作路径,发现交互设计中的问题。
- </Accordion>
- <Accordion title="错误排查">
- 快速定位应用错误发生的具体场景和上下文。
- </Accordion>
- <Accordion title="业务分析">
- 分析用户行为模式,为产品功能优化提供数据支持。
- </Accordion>
-</AccordionGroup>
-
-## 主要功能详解
-
-<Tabs>
- <Tab title="按应用查看">
- 使用顶部导航栏的应用选择器,可以选择特定应用程序并查看其所有 RUM 数据。
-
- 通过应用选择器,您可以快速切换不同应用的数据视图,专注于特定应用的性能和用户行为分析。
- </Tab>
- <Tab title="搜索与过滤">
- 在 RUM 查看器中,您可以通过在搜索栏输入查询条件并选择可视化类型来搜索和过滤 RUM 事件。
-
- <Frame>
- <img src="https://docs-cdn.flashcat.cloud/imges/png/bbe48a6dbfeb660ec86ba1e56d580ced.png" alt="搜索与过滤" />
- </Frame>
- </Tab>
- <Tab title="查看详情">
- 点击数据项可查看数据详情,可将 RUM 事件以各种角度展示,帮助您发现关键信息。
-
- - 查看数据关系,进行数据下钻或者查看数据父节点详情
- - 通过查看资源的 trace,和已有的监控系统进行 trace 关联
-
- 对于 Electron 会话,事件列表会为来自主进程的事件显示「主进程」徽标(无徽标的行即渲染进程事件),事件详情面板的 Other 属性组还会增加一个虚拟 `process` 属性(`main` / `renderer`),用于区分事件来自主进程还是渲染进程。
-
- <Frame>
- <img src="https://docs-cdn.flashcat.cloud/imges/png/4e22a5803c1fb290de7093c9ffab7dc6.png" alt="数据详情" />
- </Frame>
- </Tab>
-</Tabs>
+在搜索栏输入查询条件并选择可视化类型,即可搜索和过滤 RUM 事件。查询语法见 [数据查询指南](./data-query)。
+
+<Frame>
+ <img src="https://docs-cdn.flashcat.cloud/imges/png/bbe48a6dbfeb660ec86ba1e56d580ced.png" alt="搜索与过滤" />
+</Frame>
+
+## 查看事件详情
+
+点击数据项可查看事件详情,从多个角度展示 RUM 事件:
+
+- 查看数据关系,进行数据下钻或者查看数据父节点详情
+- 通过查看资源的 trace,和已有的监控系统进行 trace 关联
+
+对于 Electron 会话,事件列表会为来自主进程的事件显示「主进程」徽标(无徽标的行即渲染进程事件),事件详情面板的 Other 属性组还会增加一个虚拟 `process` 属性(`main` / `renderer`),用于区分事件来自主进程还是渲染进程。
+
+<Frame>
+ <img src="https://docs-cdn.flashcat.cloud/imges/png/4e22a5803c1fb290de7093c9ffab7dc6.png" alt="数据详情" />
+</Frame>
## 按平台显示的视图指标
@@ -97,16 +47,14 @@ Flashduty RUM **查看器**(RUM Explorer)是一款强大的数据分析工
平台由 View 事件自身的 `source` 字段决定,无需手动切换。微信小程序场景下,`onload_to_onshow` 和 `onshow_to_onready` 对应小程序页面生命周期的两段耗时,可用于排查页面冷启动慢的原因。
</Note>
-EventTable 的列选择器也已经支持以下小程序专属字段作为可查询列:`view_first_render`、`view_onload_to_onshow`、`view_onshow_to_onready`。
+事件表格的列选择器还可以添加以下小程序专属字段:`view_first_render`、`view_onload_to_onshow`、`view_onshow_to_onready`。
## 保存视图
-保存视图功能允许您将当前的查询状态保存为可复用的视图,方便快速切换不同的分析场景。每个账户最多可创建 **20 个**保存视图,视图仅您自己可见。
+把当前查询状态保存为视图,就能在不同分析场景之间快速切换。每个账户最多可创建 **20 个**保存视图,视图仅您自己可见。
### 视图保存的内容
-每个保存视图包含以下信息:
-
| 保存项 | 说明 |
|--------|------|
| **时间范围** | 当前选择的时间筛选条件 |
@@ -116,26 +64,14 @@ EventTable 的列选择器也已经支持以下小程序专属字段作为可查
### 视图操作
-<Tabs>
- <Tab title="创建视图">
- 点击查看器顶部的视图菜单,选择「保存为新视图」,输入视图名称后确认即可创建。视图名称不可重复。
- </Tab>
- <Tab title="切换视图">
- 点击视图菜单,在视图列表中点击目标视图即可切换。切换后,查看器会自动恢复该视图保存的时间范围、查询类型、查询语句和列配置。
- </Tab>
- <Tab title="编辑视图">
- 在视图列表中,点击目标视图右侧的操作菜单,选择「编辑视图」可修改视图名称。如果您修改了当前视图的查询条件,还可以通过「保存修改」将最新状态更新到视图中。
- </Tab>
- <Tab title="删除视图">
- 在视图列表或操作菜单中选择「删除视图」,确认后即可删除。删除当前正在使用的视图后,查看器会自动切换回默认视图。
- </Tab>
- <Tab title="复制分享链接">
- 在视图列表中,点击目标视图右侧的操作菜单,选择「复制链接」可获取该视图的分享链接。将链接分享给团队成员后,他们可以直接打开相同的查询视图。
- </Tab>
- <Tab title="重置为默认视图">
- 通过操作菜单选择「切换默认视图」,查看器会清空所有筛选条件,恢复到初始状态。
- </Tab>
-</Tabs>
+| 操作 | 方法 |
+|------|------|
+| **创建** | 点击查看器顶部的视图菜单,选择「保存为新视图」并输入名称(不可重复) |
+| **切换** | 在视图菜单中点击目标视图,查看器会恢复其时间范围、查询类型、查询语句和列配置 |
+| **编辑** | 在目标视图右侧的操作菜单选择「编辑视图」修改名称;修改了当前视图的查询条件后,可用「保存修改」更新视图 |
+| **删除** | 在视图列表或操作菜单中选择「删除视图」;删除当前视图后会切换回默认视图 |
+| **分享** | 在操作菜单选择「复制链接」,团队成员打开链接即可看到相同的查询视图 |
+| **重置** | 在操作菜单选择「切换默认视图」,清空所有筛选条件 |
## 事件导出
diff --git a/zh/rum/others/compliance-guide.mdx b/zh/rum/others/compliance-guide.mdx
index c9e2226b..dae74a3f 100644
--- a/zh/rum/others/compliance-guide.mdx
+++ b/zh/rum/others/compliance-guide.mdx
@@ -129,7 +129,7 @@ SDK 提供方:北京快猫星云科技有限公司
网络信息(网络状态、网络接口类型、上行/下行带宽、信号强度)、应用运行与崩溃日志信息、
应用使用过程中的页面访问与操作行为、随机生成的会话标识
官网:https://flashcat.cloud
-隐私政策:https://docs.flashduty.com/zh/compliance/data-security
+隐私政策:/zh/compliance/data-security
```
</CodeGroup>
diff --git a/zh/rum/others/data-security.mdx b/zh/rum/others/data-security.mdx
index 23fdc031..bed3483e 100644
--- a/zh/rum/others/data-security.mdx
+++ b/zh/rum/others/data-security.mdx
@@ -67,14 +67,14 @@ RUM 中可能出现 PII 的场景包括:
初始化 RUM 应用程序后,您可以在**用户数据收集**选项卡中选择是否要包含 IP 或地理位置数据。
<Note>
- 禁用 IP 数据收集后,更改将立即生效。在禁用之前收集的任何事件不会删除 IP 数据。这是在后端执行的,浏览器 SDK 仍在发送数据,但 IP 地址在处理时会被 Flashduty 后端管道省略和丢弃。
+ 禁用 IP 数据收集后,更改将立即生效。在禁用之前收集的任何事件不会删除 IP 数据。浏览器 SDK 仍会上报数据,IP 地址会在 Flashduty 服务端处理时被丢弃。
</Note>
</Tab>
<Tab title="地理位置">
除了删除客户端 IP 外,您还可以选择禁用从所有未来收集的数据中收集地理位置(国家、城市、县)或 GeoIP 信息。
<Note>
- 如果取消选中**收集地理位置数据**框,更改将立即生效。在禁用之前收集的任何事件不会删除相应的地理位置数据。数据省略在后端级别完成。
+ 如果取消选中**收集地理位置数据**框,更改将立即生效。在禁用之前收集的任何事件不会删除相应的地理位置数据。地理位置数据会在 Flashduty 服务端处理时被丢弃。
</Note>
</Tab>
</Tabs>
diff --git a/zh/rum/performance/diagnosis-optimization.mdx b/zh/rum/performance/diagnosis-optimization.mdx
index 0e3ba037..6e2a32c9 100644
--- a/zh/rum/performance/diagnosis-optimization.mdx
+++ b/zh/rum/performance/diagnosis-optimization.mdx
@@ -1,16 +1,14 @@
---
title: "诊断指南"
-description: "本文档详细介绍如何使用 Flashduty RUM 进行性能问题诊断和优化。"
+description: "用优化页面按真实用户数据定位页面加载慢的原因:选指标、看分布、查资源与错误、分析事件样本。"
keywords: ["RUM", "性能监控", "用户监控", "前端监控"]
---
-优化页面有助于根据真实用户流量数据识别浏览器性能问题的根本原因。通过浏览器指标(如核心网页指标和 Flashduty 自定义加载时间指标)排查页面加载缓慢的原因,这些指标可以从用户的角度评估完整页面的加载时间。
-
-为了进行更深入的分析,优化页面提供了按用户人口统计(例如浏览器、地区和应用版本)的核心网页指标的详细拆分。您可以利用这些信息跟踪性能趋势,了解受影响最多的用户群体,精准优化。
+优化页面基于真实用户流量,用核心网页指标和 Flashduty 自定义加载时间指标,从用户视角排查页面加载慢的根因。指标可按浏览器、地区、应用版本等维度拆分,帮助您跟踪趋势、找到受影响最多的用户群体。
## 诊断优化流程
-您可导航至优化页面,该页面位于性能监控菜单下,选取待洞察的指标即可。您也可以通过在分析看板中查看对应的性能数据跳转至此功能。
+在 **性能监控** 菜单下进入优化页面,或从分析看板中的性能数据跳转过来。
<Steps>
<Step title="指标选择">
@@ -28,11 +26,11 @@ keywords: ["RUM", "性能监控", "用户监控", "前端监控"]
| **微信小程序** | `first_render`(首次渲染)、`lcp`、`fcp`、`onload_to_onshow`、`onshow_to_onready` |
<Note>
- 平台由应用本身的类型决定,无需手动切换。`first_render`、`onload_to_onshow`、`onshow_to_onready` 来自微信小程序 SDK:`first_render` 为首次渲染耗时,`onload_to_onshow` 与 `onshow_to_onready` 对应小程序页面生命周期的两段耗时,可用于排查页面冷启动慢的原因。切换应用后指标卡片会随新平台的指标集合刷新,树图(指标视角)的指标下拉同样只列出当前应用平台可选的指标。
+ 平台由应用类型决定,切换应用后指标卡片和树图(指标视角)的指标下拉会随之刷新。小程序的 `onload_to_onshow` 与 `onshow_to_onready` 对应页面生命周期的两段耗时,可用于排查冷启动慢。
</Note>
</Step>
<Step title="数据查看">
- 您可通过调整数据聚合方式或修改筛选条件,查看该指标在不同条件下的数据表现情况,从而推进诊断优化工作。
+ 调整聚合方式或筛选条件,比较该指标在不同条件下的表现。
<Frame>
<img src="https://docs-cdn.flashcat.cloud/images/png/65dd3ca92d67ae9175955502d91552dc.png" alt="数据查看" />
@@ -79,12 +77,14 @@ keywords: ["RUM", "性能监控", "用户监控", "前端监控"]
| AVG START TIME | 平均开始加载时间 |
| AVG DURATION | 平均加载耗时,并以色条按真实时间偏移展示各加载阶段:重定向、Service Worker、排队等待、DNS 解析、建立连接(含 TLS 握手)、等待响应(首字节)与下载 |
+ 悬停在耗时色条上可查看各阶段耗时。某一阶段占比达到 50% 及以上时,卡片会标出 **主要耗时** 阶段并给出优化建议,帮助判断慢在网络连接、服务器响应还是资源大小(TLS 握手属于建立连接阶段,不会单独成为主要耗时)。
+
<Tip>
- 将鼠标悬停在耗时色条上,可查看各阶段的具体耗时数值;当某一阶段耗时占比达到 50% 及以上时,卡片会给出「主要耗时」阶段的说明与优化建议(TLS 握手嵌套在建立连接阶段内,不会单独成为主要耗时),帮助您判断是网络连接、服务器响应还是资源大小导致的加载缓慢。已配置 [Link 集成 - 内置 Tracing](/zh/rum/quickstart/app-management#link-集成) 且资源带有 trace_id 时,还可一键下钻到对应的链路。若浏览器未暴露阶段耗时(常见于跨域资源缺少 `Timing-Allow-Origin` 响应头),色条区域会显示「阶段耗时不可用」提示。
+ 已配置 [Link 集成 - 内置 Tracing](/zh/rum/quickstart/app-management#link-集成) 且资源带有 trace_id 时,还可一键下钻到对应的链路。若浏览器未暴露阶段耗时(常见于跨域资源缺少 `Timing-Allow-Origin` 响应头),色条区域会显示 **阶段耗时不可用**。
</Tip>
</Tab>
<Tab title="解决错误">
- - 关注可能导致问题的重复错误,这些异常也会影响页面性能
+ 关注反复出现的错误,这些异常同样会拖慢页面性能。
</Tab>
<Tab title="瀑布图分析">
- 瀑布图显示了在捕获指标时事件的时间线
diff --git a/zh/rum/performance/overview.mdx b/zh/rum/performance/overview.mdx
index a3560df4..9121a928 100644
--- a/zh/rum/performance/overview.mdx
+++ b/zh/rum/performance/overview.mdx
@@ -10,7 +10,7 @@ Flashduty RUM(真实用户监控)提供强大的工具,帮助您快速诊
<CardGroup cols={2}>
<Card title="性能指标监控" icon="gauge-high">
- 自动收集并分析关键性能指标(如 FCP、LCP、CLS、FID 等),提供全面的性能数据视图
+ 自动收集并分析关键性能指标(如 FCP、LCP、CLS、INP 等),提供全面的性能数据视图
</Card>
<Card title="资源加载分析" icon="download">
监控和分析静态资源(如 JS、CSS、图片等)的加载性能,识别加载缓慢的资源
@@ -94,9 +94,9 @@ Flashduty RUM 的性能优化分为三个关键阶段:
|----------|----------|----------|----------|
| **页面加载缓慢** | 白屏时间长、首屏渲染慢 | 资源体积过大、阻塞渲染的脚本或 CSS、服务器响应慢 | LCP, FCP, TTI |
| **交互响应延迟** | 点击无反应、操作卡顿 | JavaScript 执行时间长、事件监听过多、DOM 操作频繁 | FID, INP, TBT |
-| **资源加载异常** | 图片/脚本加载失败、超时 | CDN 配置错误、网络不稳定、资源路径错误 | 资源加载时间, 失败率 |
-| **JavaScript 错误** | 功能失效、控制台报错 | 代码逻辑错误、浏览器兼容性问题、内存泄漏 | 错误率, 内存使用 |
-| **网络连接问题** | 请求超时、连接中断 | API 响应慢、网络质量差、跨域配置错误 | 请求延迟, 连接成功率 |
+| **资源加载异常** | 图片/脚本加载失败、超时 | CDN 配置错误、网络不稳定、资源路径错误 | 资源加载时间、失败率 |
+| **JavaScript 错误** | 功能失效、控制台报错 | 代码逻辑错误、浏览器兼容性问题、内存泄漏 | 错误率、内存使用 |
+| **网络连接问题** | 请求超时、连接中断 | API 响应慢、网络质量差、跨域配置错误 | 请求延迟、连接成功率 |
## 问题定位工具
@@ -142,20 +142,10 @@ Flashduty RUM 的性能优化分为三个关键阶段:
定位问题根因后,您可以根据分析结果实施优化:
-<CardGroup cols={2}>
- <Card title="页面加载缓慢" icon="hourglass">
- 压缩资源、优化 critical CSS、启用 CDN
- </Card>
- <Card title="交互响应延迟" icon="hand-pointer">
- 减少 JavaScript 执行时间、优化事件监听器
- </Card>
- <Card title="资源加载异常" icon="image">
- 检查 CDN 配置、确保资源路径正确
- </Card>
- <Card title="JavaScript 错误" icon="bug">
- 修复代码逻辑、添加错误边界、优化内存使用
- </Card>
-</CardGroup>
+- **页面加载缓慢**:压缩资源、优化 critical CSS、启用 CDN
+- **交互响应延迟**:减少 JavaScript 执行时间、优化事件监听器
+- **资源加载异常**:检查 CDN 配置、确保资源路径正确
+- **JavaScript 错误**:修复代码逻辑、添加错误边界、优化内存使用
## 下一步
diff --git a/zh/rum/quickstart/app-management.mdx b/zh/rum/quickstart/app-management.mdx
index 5264f1fc..81c7dcae 100644
--- a/zh/rum/quickstart/app-management.mdx
+++ b/zh/rum/quickstart/app-management.mdx
@@ -69,7 +69,7 @@ RUM 应用是承载前端性能监控数据的容器,用于采集、存储和
src="https://docs-cdn.flashcat.cloud/videos/app-sdk-config.mov"
></video>
-您可以在 **应用配置 > SDK 配置** 中修改参数并实时预览初始化代码,以便快速接入 SDK。
+您可以在 **应用配置 → SDK 配置** 中修改参数并实时预览初始化代码,以便快速接入 SDK。
控制台为不同平台提供了详细的集成引导:
@@ -125,7 +125,7 @@ flashcatRum.init({
### 微信小程序 SDK 配置助手
-当应用类型选择为「微信小程序」时,**应用配置 > SDK 配置** 会展示专门的小程序集成向导:左侧填写表单参数,右侧实时生成可直接复制的初始化代码。
+当应用类型选择为「微信小程序」时,**应用配置 → SDK 配置** 会展示专门的小程序集成向导:左侧填写表单参数,右侧实时生成可直接复制的初始化代码。
#### 表单字段
@@ -341,13 +341,13 @@ Link 集成会从当前事件上下文中提取变量并替换到 URL 模板中
### 与 AI SRE 的关系
- 关联仓库本身**不授予任何访问权限**。云端沙箱里的 AI 会话只能读取账户 GitHub App 安装所授权的仓库;手动填写的仓库只对使用宿主机自带凭证的 [BYOC](/zh/ai-sre/environments) 会话有意义。
-- 账户尚未连接任何 GitHub App 安装时,页面顶部提示「尚未连接 GitHub App:手动填写的仓库只能供本地 AI 使用,云端 AI 会话读取不到代码。」,并提供 **去连接** 入口跳转到 **插件 → Apps**。
-- 已连接 GitHub App 时,不在授权范围内的条目旁会出现警告标记,提示「不在 GitHub App 授权范围内,云端 AI 会话读取不到该仓库。」:有 **Apps 插件访问** 权限的成员点击标记可到 **插件 → Apps** 为该安装授权更多仓库,其他成员看到的是「请联系管理员在 GitHub App 中授权该仓库」。
-- 若部署中查询不到 GitHub App 授权信息(例如纯 RUM 的私有化环境),页面不显示「尚未连接」提示,只保留手动填写。
+- 账户尚未连接 GitHub App 时,页面顶部会提醒您,云端 AI 会话读取不到手动填写的仓库,并提供 **去连接** 入口(**插件 → Apps**)。
+- 已连接 GitHub App 时,不在授权范围内的仓库会带警告标记,云端 AI 会话读取不到它。有 **Apps 插件访问** 权限的成员可以点击标记到 **插件 → Apps** 授权更多仓库,其他成员需联系管理员。
+- 没有 GitHub App 的部署(例如纯 RUM 的私有化环境)只能手动填写仓库,不显示连接提醒。
## 远程配置
-「远程配置」页签允许你在线调整采集与隐私参数,而无需改代码、重新发版。启用后,本页配置覆盖 SDK 初始化设置;停用后,各端恢复使用 SDK 初始化设置,数据采集不会停止。
+「远程配置」页签允许您在线调整采集与隐私参数,而无需改代码、重新发版。启用后,本页配置覆盖 SDK 初始化设置;停用后,各端恢复使用 SDK 初始化设置,数据采集不会停止。
<Note>
- 远程配置目前支持 **Browser**、**iOS**、**Android**、**Flutter** 与**微信小程序**类型应用,其他平台类型将随各端 SDK 发布逐步开放。
@@ -393,7 +393,7 @@ iOS、Android、Flutter 与微信小程序应用同样展示「远程配置」
### 版本历史与采用情况
-- 变更历史保留最近 50 个版本,更早的版本将自动清理且无法回滚。每条历史展示操作人与变更说明(如填写)。你可以将任一保留中的历史版本回滚为当前配置,回滚同样会生成新版本。
+- 变更历史保留最近 50 个版本,更早的版本将自动清理且无法回滚。每条历史展示操作人与变更说明(如填写)。您可以将任一保留中的历史版本回滚为当前配置,回滚同样会生成新版本。
- 回滚产生的新版本带内容等价标注:若其配置内容与历史上某个更早版本完全相同,历史列表会标注该版本与那个最早相同内容的版本等价——版本号跳变不代表配置内容发生了变化。
- 发布面板按最近到达的采样会话展示**采用情况**:方格图以 10×10 共 100 格表示各版本的会话占比,每格代表 1% 的会话(按各版本采样率估算),右侧明细表逐组列出**版本**、**占比**与**会话数**。上方数字区展示**活跃会话**、**已上报**、**未上报**与**当前版本采用率**四项统计,其中当前版本采用率在窗口内到达的会话全部切换后附带勾选的「最近会话已切换」标记。各组按以下规则归并:当前版本单独一组并标注「当前版本」,占比最高的两个旧版本各自一组,其余旧版本合并为「更早版本」,未上报配置版本的会话单独列为「未上报」(SDK 版本过低或尚未拉取过配置)。状态标签为「等待新会话」(刚发布,尚无会话按当前版本开始)、「生效中」(部分会话已切换)、「最近会话已切换」(窗口内到达的会话均已在当前版本)、「未收到配置」(最近会话均未上报配置版本,常见为 SDK 未开启远程配置或版本过低)、「暂无数据」(窗口内暂无新会话)、「未检测到生效」(发布已超过约 8 小时仍未切到当前版本)。点击**查看会话明细**可跳转到事件浏览器查看这批样本会话;在版本卡片上点击**查看配置**可展开当前生效版本的完整内容,再次点击**收起配置**收起。窗口内采样会话少于 20 条时,面板不画方格图、只展示各组的实际会话数、不估算占比(占比由采样率放大估算,样本过少时结果没有意义)。
diff --git a/zh/rum/sdk/android/advanced-config.mdx b/zh/rum/sdk/android/advanced-config.mdx
index 20d15873..e504d2db 100644
--- a/zh/rum/sdk/android/advanced-config.mdx
+++ b/zh/rum/sdk/android/advanced-config.mdx
@@ -214,7 +214,7 @@ GlobalRumMonitor.get().addError(
</Tabs>
<Note>
-更多错误上报详情,请参阅 [Android 异常上报](/zh/rum/error-tracking/erro-reporting/android)。
+更多错误上报详情,请参阅 [Android 异常上报](/zh/rum/error-tracking/error-reporting/android)。
</Note>
### 自定义计时
diff --git a/zh/rum/sdk/android/data-collection.mdx b/zh/rum/sdk/android/data-collection.mdx
index 187c794f..3ebee5cb 100644
--- a/zh/rum/sdk/android/data-collection.mdx
+++ b/zh/rum/sdk/android/data-collection.mdx
@@ -110,13 +110,13 @@ RUM SDK 为所有事件自动附加默认属性,帮助您了解用户设备、
| `application.name` | string | 应用包名(例如 `com.example.app`)。 |
| `application.version` | string | 应用版本名称。 |
| `application.build` | string | 应用构建版本号。 |
-| `session.id` | string | 唯一会话 ID,用于将用户旅程中的事件分组。 |
+| `session.id` | string | 唯一会话 ID,用于将用户旅程中的事件分组。 |
| `session.type` | string | 会话类型:`user`。 |
| `view.id` | string | 为每个 View 生成的唯一 ID。 |
| `view.url` | string | View 的规范化 URL(Activity 或 Fragment 的类名)。 |
| `view.name` | string | 可自定义的 View 名称。 |
| `env` | string | 应用的环境名称(例如 `prod`、`dev`)。 |
-| `service` | string | 服务名称,用于区分应用的不同模块或微服务。 |
+| `service` | string | 服务名称,用于区分应用的不同模块或微服务。 |
| `version` | string | 应用版本。 |
| `sdk_version` | string | Flashduty SDK 版本。 |
| `date` | number | 事件发生的时间戳(epoch 毫秒) |
@@ -130,7 +130,7 @@ RUM SDK 为所有事件自动附加默认属性,帮助您了解用户设备、
| 属性名 | 类型 | 描述 |
| ----------------------- | ------ | ----------------------------------------- |
-| `device.type` | string | 设备类型,如 `mobile`、`tablet`、`tv` 等。 |
+| `device.type` | string | 设备类型,如 `mobile`、`tablet`、`tv` 等。 |
| `device.name` | string | 设备商业名称(例如 `Samsung Galaxy S21`)。 |
| `device.model` | string | 设备型号(例如 `SM-G991B`)。 |
| `device.brand` | string | 设备品牌(例如 `Samsung`)。 |
@@ -254,11 +254,11 @@ Resource 事件表示应用中的网络请求。收集的属性包括:
| `resource.size` | number | 资源大小(字节)。 |
| `resource.dns.duration` | number(ns) | DNS 解析时间(`domainLookupEnd - domainLookupStart`)。 |
| `resource.connect.duration` | number(ns) | 建立连接的时间(`connectEnd - connectStart`)。 |
-| `resource.ssl.duration` | number(ns) | TLS 握手时间(`connectEnd - secureConnectionStart`),仅适用于 HTTPS。 |
+| `resource.ssl.duration` | number(ns) | TLS 握手时间(`connectEnd - secureConnectionStart`),仅适用于 HTTPS。 |
| `resource.first_byte.duration` | number(ns) | 等待首字节响应的时间(`responseStart - requestStart`)。 |
| `resource.download.duration` | number(ns) | 下载响应的时间(`responseEnd - responseStart`)。 |
| `resource.redirect.duration` | number(ns) | 后续 HTTP 重定向所花费的时间(`redirectEnd - redirectStart`)。 |
-| `resource.provider.name` | string | 资源提供商名称,默认为 `unknown`。 |
+| `resource.provider.name` | string | 资源提供商名称,默认为 `unknown`。 |
| `resource.provider.domain` | string | 资源提供商域名 |
| `resource.provider.type` | string | 资源提供商类型(如 `first-party`、`cdn`、`ad`、`analytics`) |
@@ -275,7 +275,7 @@ Resource 事件表示应用中的网络请求。收集的属性包括:
| `error.message` | string | 简洁、人类可读的单行错误消息。 |
| `error.stack` | string | 堆栈跟踪或错误的补充信息。 |
| `error.issue_id` | string | 错误问题的唯一标识符。 |
-| `error.category` | string | 错误的高级分类,可能的值:`ANR`(应用无响应)、`Exception`(异常)。 |
+| `error.category` | string | 错误的高级分类,可能的值:`ANR`(应用无响应)、`Exception`(异常)。 |
| `error.file` | string | 发生错误的文件名(用于错误追踪问题)。 |
| `error.line` | number | 发生错误的行号 |
| `error.is_crash` | bool | 指示该错误是否导致应用崩溃 |
@@ -289,7 +289,7 @@ Resource 事件表示应用中的网络请求。收集的属性包括:
| `error.resource.status_code` | number | HTTP 响应状态码。 |
| `error.resource.method` | string | HTTP 方法(例如 `POST`、`GET`)。 |
| `error.resource.url` | string | 资源 URL。 |
-| `error.resource.provider.name` | string | 资源提供商名称,默认为 `unknown`。 |
+| `error.resource.provider.name` | string | 资源提供商名称,默认为 `unknown`。 |
| `error.resource.provider.domain` | string | 资源提供商域名 |
| `error.resource.provider.type` | string | 资源提供商类型(如 `first-party`、`cdn`、`ad`、`analytics`) |
diff --git a/zh/rum/sdk/android/performance-impact.mdx b/zh/rum/sdk/android/performance-impact.mdx
index 7c306960..29868090 100644
--- a/zh/rum/sdk/android/performance-impact.mdx
+++ b/zh/rum/sdk/android/performance-impact.mdx
@@ -131,7 +131,7 @@ val rumConfig = RumConfiguration.Builder(applicationId)
**`trackLongTasks(0)` 的代价比字面意思大。** 冻结帧并不是从渲染帧里统计出来的,而是「耗时超过 700ms 的长任务」这一子集,卡顿频率又由冻结帧数算得。所以关闭长任务采集后,看板「流畅度分析」里的**长任务数、冻结帧数、卡顿频率会同时恒为 0**——看起来像「应用毫无卡顿」,实际是没采集。慢帧占比走独立链路,不受影响。
-如果你的目的是减少事件量,**建议调高阈值而不是关闭**:`trackLongTasks(500)` 能保留全部冻结帧(判据是 700ms,高于 500ms),同时把长任务事件量比默认 100ms 降低一个量级。但请注意,阈值只决定「上报什么」,不减少插桩本身的开销——监听器挂在主线程 Looper 上,每条消息都会回调。**若你是为了降低运行时开销**,那只有 `trackLongTasks(0)` 有效,此时请接受上述三个指标不可用。
+如果您的目的是减少事件量,**建议调高阈值而不是关闭**:`trackLongTasks(500)` 能保留全部冻结帧(判据是 700ms,高于 500ms),同时把长任务事件量比默认 100ms 降低一个量级。但请注意,阈值只决定「上报什么」,不减少插桩本身的开销——监听器挂在主线程 Looper 上,每条消息都会回调。**若您是为了降低运行时开销**,那只有 `trackLongTasks(0)` 有效,此时请接受上述三个指标不可用。
</Warning>
</Step>
diff --git a/zh/rum/sdk/android/sdk-integration.mdx b/zh/rum/sdk/android/sdk-integration.mdx
index f927277d..3e6f05a6 100644
--- a/zh/rum/sdk/android/sdk-integration.mdx
+++ b/zh/rum/sdk/android/sdk-integration.mdx
@@ -93,7 +93,7 @@ class SampleApplication : Application() {
**参数说明:**
- `environmentName` - 环境名称(如 production、staging)
- `appVariantName` - 应用变体名称,用于区分不同构建版本的数据
-- 更多配置选项请参阅 [高级配置](https://docs.flashduty.com/zh/flashduty/rum/android-advanced-configuration)
+- 更多配置选项请参阅 [高级配置](/zh/rum/sdk/android/advanced-config)
</Note>
</Step>
diff --git a/zh/rum/sdk/electron/advanced-config.mdx b/zh/rum/sdk/electron/advanced-config.mdx
index 2fdcab2c..3456dbfc 100644
--- a/zh/rum/sdk/electron/advanced-config.mdx
+++ b/zh/rum/sdk/electron/advanced-config.mdx
@@ -84,7 +84,7 @@ await init({
});
```
-这里的 `proxy` 是由你提供的 **RUM 转发地址**,不是操作系统或 Electron 的网络代理设置。主进程会在请求中附加目标路径信息;转发服务需要保留请求体和 `DD-API-KEY` 请求头,并将请求发送到 Flashduty 数据接收端。
+这里的 `proxy` 是由您提供的 **RUM 转发地址**,不是操作系统或 Electron 的网络代理设置。主进程会在请求中附加目标路径信息;转发服务需要保留请求体和 `DD-API-KEY` 请求头,并将请求发送到 Flashduty 数据接收端。
设置 `proxy` 后,主进程不再使用 `site` 生成上报地址。
@@ -131,7 +131,7 @@ flashcatRum.init({
## 采集第三方页面
-当前窗口加载的页面始终可以使用桥接,无需配置 `allowedWebViewHosts`。只有当你需要采集 `<webview>` 或 `BrowserView` 中加载的第三方页面时,才添加额外 host:
+当前窗口加载的页面始终可以使用桥接,无需配置 `allowedWebViewHosts`。只有当您需要采集 `<webview>` 或 `BrowserView` 中加载的第三方页面时,才添加额外 host:
```ts main.ts
await init({
@@ -171,7 +171,7 @@ clearUser();
## 手动上报错误
-主进程中被 `try/catch` 捕获的异常不会作为未处理异常自动上报。你可以调用 `addError()` 记录它:
+主进程中被 `try/catch` 捕获的异常不会作为未处理异常自动上报。您可以调用 `addError()` 记录它:
```ts main.ts
import { addError } from '@flashcatcloud/electron-sdk';
@@ -206,7 +206,7 @@ stopSession();
Electron 应用可能先创建隐藏的 `BrowserWindow`,完成页面加载后再显示。SDK 默认会将这类窗口的 FCP 和 LCP 校正到窗口首次可见的时间,避免把预热等待时间计入页面性能。
-如果你希望保留页面原始的 Paint Timing 数值,可以关闭校正:
+如果您希望保留页面原始的 Paint Timing 数值,可以关闭校正:
```ts main.ts
await init({
diff --git a/zh/rum/sdk/electron/compatible.mdx b/zh/rum/sdk/electron/compatible.mdx
index a0dc4f10..5e7033ea 100644
--- a/zh/rum/sdk/electron/compatible.mdx
+++ b/zh/rum/sdk/electron/compatible.mdx
@@ -4,7 +4,7 @@ description: "查看 Electron RUM SDK 支持的版本、操作系统、打包工
keywords: ["RUM", "Electron SDK", "兼容性", "打包工具", "已知限制"]
---
-接入前,请确认你的 Electron 版本和构建方式在支持范围内。
+接入前,请确认您的 Electron 版本和构建方式在支持范围内。
## 支持范围
diff --git a/zh/rum/sdk/electron/data-collection.mdx b/zh/rum/sdk/electron/data-collection.mdx
index fdace3b5..6202549c 100644
--- a/zh/rum/sdk/electron/data-collection.mdx
+++ b/zh/rum/sdk/electron/data-collection.mdx
@@ -4,7 +4,7 @@ description: "了解 Electron RUM SDK 在主进程和渲染进程中采集的数
keywords: ["RUM", "Electron SDK", "数据收集", "主进程", "渲染进程", "崩溃"]
---
-Electron SDK 将主进程和渲染进程的数据关联到同一条会话,帮助你同时分析桌面应用运行状态和页面体验。
+Electron SDK 将主进程和渲染进程的数据关联到同一条会话,帮助您同时分析桌面应用运行状态和页面体验。
## 采集概览
diff --git a/zh/rum/sdk/electron/error-symbolication.mdx b/zh/rum/sdk/electron/error-symbolication.mdx
index 5e113d2a..7bb87b9b 100644
--- a/zh/rum/sdk/electron/error-symbolication.mdx
+++ b/zh/rum/sdk/electron/error-symbolication.mdx
@@ -137,7 +137,7 @@ await init({
### 1. 准备符号文件
-从 [Electron releases](https://github.com/electron/electron/releases) 下载与你实际发布的 Electron **版本、操作系统和 CPU 架构**完全一致的符号包:
+从 [Electron releases](https://github.com/electron/electron/releases) 下载与您实际发布的 Electron **版本、操作系统和 CPU 架构**完全一致的符号包:
```text
electron-v<version>-<platform>-<arch>-symbols.zip
@@ -167,11 +167,11 @@ flashcat-cli electron-symbols upload ./breakpad_symbols \
每次升级 Electron 或重新构建原生模块后,模块 ID 都可能变化。请为实际发布的每个操作系统和 CPU 架构上传对应符号。
-未上传符号不会阻止崩溃事件上报。你可以先收到地址形式的崩溃栈,再补传符号;历史崩溃会在查看时重新还原。
+未上传符号不会阻止崩溃事件上报。您可以先收到地址形式的崩溃栈,再补传符号;历史崩溃会在查看时重新还原。
### 在控制台上传 Electron 符号
-除了命令行,你也可以在控制台完成原生符号的上传。进入 **应用管理 → 源码管理 → Electron**,该页签列出已上传的 Electron 符号:每个原生模块一行,展示模块、Debug ID、架构、服务、版本、大小和上传时间。列表支持按 **Debug ID** 自由搜索(该值即崩溃事件 `binary_images` 携带的模块 Debug ID),并可添加服务、版本和 build_id 筛选条件。
+除了命令行,您也可以在控制台完成原生符号的上传。进入 **应用管理 → 源码管理 → Electron**,该页签列出已上传的 Electron 符号:每个原生模块一行,展示模块、Debug ID、架构、服务、版本、大小和上传时间。列表支持按 **Debug ID** 自由搜索(该值即崩溃事件 `binary_images` 携带的模块 Debug ID),并可添加服务、版本和 build_id 筛选条件。
点击 **上传 Electron 符号** 打开上传面板,填写以下参数后,面板会生成对应的上传命令:
diff --git a/zh/rum/sdk/electron/faq.mdx b/zh/rum/sdk/electron/faq.mdx
index 280774e9..64817902 100644
--- a/zh/rum/sdk/electron/faq.mdx
+++ b/zh/rum/sdk/electron/faq.mdx
@@ -4,7 +4,7 @@ description: "排查 Electron RUM SDK 的数据缺失、进程桥接、会话回
keywords: ["RUM", "Electron SDK", "问题排查", "会话回放", "桥接", "sourcemap"]
---
-本页按照你在应用或 Flashduty 控制台中看到的现象,提供对应的检查方法。
+本页按照您在应用或 Flashduty 控制台中看到的现象,提供对应的检查方法。
<AccordionGroup>
<Accordion title="为什么控制台中没有任何数据?">
@@ -12,7 +12,7 @@ keywords: ["RUM", "Electron SDK", "问题排查", "会话回放", "桥接", "sou
1. 确认主进程 `init()` 返回 `true`,并查看主进程控制台是否有配置错误
2. 确认 `applicationId`、`clientToken` 和 `service` 为非空字符串
-3. 确认应用可以访问 `https://browser.flashcat.cloud/api/v2/rum` 或你配置的私有化地址
+3. 确认应用可以访问 `https://browser.flashcat.cloud/api/v2/rum` 或您配置的私有化地址
4. 等待一个上报周期;默认每 10 秒上报一批普通 RUM 事件
5. 在查看器中使用 `source:electron OR container.source:electron` 筛选
@@ -99,7 +99,7 @@ Flashduty 使用 `service`、`version` 和压缩文件路径匹配 sourcemap。
</Accordion>
<Accordion title="为什么原生崩溃栈只有地址?">
-原生 minidump 不使用 JavaScript sourcemap。你需要上传与应用实际发布版本、操作系统和 CPU 架构匹配的 Breakpad 符号文件。
+原生 minidump 不使用 JavaScript sourcemap。您需要上传与应用实际发布版本、操作系统和 CPU 架构匹配的 Breakpad 符号文件。
建议先上传对应 Electron 版本的官方符号包;如果应用包含自己的原生模块或 `.node` 插件,也需要为这些模块生成并上传 `.sym` 文件。
diff --git a/zh/rum/sdk/electron/sdk-integration.mdx b/zh/rum/sdk/electron/sdk-integration.mdx
index 5771c906..3224225d 100644
--- a/zh/rum/sdk/electron/sdk-integration.mdx
+++ b/zh/rum/sdk/electron/sdk-integration.mdx
@@ -4,14 +4,14 @@ description: "在 Electron 应用中接入 Flashduty RUM,采集主进程和渲
keywords: ["RUM", "Electron SDK", "桌面应用监控", "主进程", "渲染进程"]
---
-Electron 应用包含主进程和渲染进程。完成两侧接入后,你可以在同一条 RUM 会话中查看桌面应用的运行状态和页面体验。
+Electron 应用包含主进程和渲染进程。完成两侧接入后,您可以在同一条 RUM 会话中查看桌面应用的运行状态和页面体验。
| 进程 | SDK | 主要采集内容 |
|------|-----|--------------|
| 主进程 | `@flashcatcloud/electron-sdk` | 会话、主进程错误、原生崩溃、主进程网络请求 |
| 渲染进程 | `@flashcatcloud/browser-rum` | 页面访问、用户操作、前端资源、JavaScript 错误、Web Vitals |
-普通渲染进程事件会自动转发到主进程,由主进程统一上报。你不需要编写额外的 IPC 转发代码。
+普通渲染进程事件会自动转发到主进程,由主进程统一上报。您不需要编写额外的 IPC 转发代码。
## 前提条件
@@ -149,7 +149,7 @@ flashcatRum.init({
建议让两个进程使用相同的 `applicationId`、`clientToken`、`service`、`env` 和 `version`,避免同一个应用的数据被拆到不同维度。
-主进程配置正确后,SDK 会自动注入 preload 并建立桥接。你不需要修改应用自己的 preload,也不需要编写 `ipcRenderer` / `ipcMain` 转发代码。`allowedWebViewHosts` 仅用于采集 `<webview>` 或 `BrowserView` 中加载的第三方页面。
+主进程配置正确后,SDK 会自动注入 preload 并建立桥接。您不需要修改应用自己的 preload,也不需要编写 `ipcRenderer` / `ipcMain` 转发代码。`allowedWebViewHosts` 仅用于采集 `<webview>` 或 `BrowserView` 中加载的第三方页面。
</Step>
<Step title="验证接入">
diff --git a/zh/rum/sdk/flutter/advanced-config.mdx b/zh/rum/sdk/flutter/advanced-config.mdx
index 0b6ca563..81a71289 100644
--- a/zh/rum/sdk/flutter/advanced-config.mdx
+++ b/zh/rum/sdk/flutter/advanced-config.mdx
@@ -18,7 +18,7 @@ DatadogRumConfiguration(
## 远程配置
-`flashcat_flutter_plugin` 0.2.0 起,会话采样率可以在控制台 **应用管理 > 远程配置** 页签在线调整,无需改代码、重新发版。该功能默认关闭,需要在初始化时开启:
+`flashcat_flutter_plugin` 0.2.0 起,会话采样率可以在控制台 **应用管理 → 远程配置** 页签在线调整,无需改代码、重新发版。该功能默认关闭,需要在初始化时开启:
```dart
DatadogRumConfiguration(
@@ -184,7 +184,7 @@ final webViewController = WebViewController()
<Warning>
**iOS 的 Dart 堆栈暂不支持符号化。** Flutter 为 Apple 平台生成的符号文件是 Mach-O 格式,平台当前只能解析 Android 侧的 ELF 格式,因此 iOS 的 `.symbols` 上传会被拒绝。iOS 原生崩溃不受影响,上传 dSYM 即可符号化。
-如果你的应用同时发布 iOS 和 Android,`--obfuscate` 仍可开启:Android 的 Dart 堆栈会正常还原,iOS 的 Dart 堆栈则保持混淆状态。若 iOS 的可读堆栈更重要,则该端构建时不要开启 `--obfuscate`。
+如果您的应用同时发布 iOS 和 Android,`--obfuscate` 仍可开启:Android 的 Dart 堆栈会正常还原,iOS 的 Dart 堆栈则保持混淆状态。若 iOS 的可读堆栈更重要,则该端构建时不要开启 `--obfuscate`。
</Warning>
使用 FlashCat CLI 上传符号文件:
diff --git a/zh/rum/sdk/flutter/compatible.mdx b/zh/rum/sdk/flutter/compatible.mdx
index 27ad5d3a..fa096c5f 100644
--- a/zh/rum/sdk/flutter/compatible.mdx
+++ b/zh/rum/sdk/flutter/compatible.mdx
@@ -4,7 +4,7 @@ description: "了解 Flutter RUM SDK 支持的平台、Flutter 版本、伴生
keywords: ["RUM", "Flutter SDK", "兼容性", "Dart", "iOS", "Android"]
---
-本文说明 Flutter SDK 的支持范围和当前限制,帮助你在接入前判断工程是否满足要求。
+本文说明 Flutter SDK 的支持范围和当前限制,帮助您在接入前判断工程是否满足要求。
## 支持范围
@@ -69,7 +69,7 @@ Flutter 崩溃栈可能同时包含 Dart 帧与原生(iOS / Android)帧。
<Warning>
**iOS 的 Dart 堆栈暂不支持符号化。** Flutter 为 Apple 平台生成的符号文件是 Mach-O 格式,平台当前只能解析 Android 侧的 ELF 格式,因此 iOS 的 `.symbols` 上传会被拒绝。iOS 原生崩溃不受影响,上传 dSYM 即可符号化。
-如果你的应用同时发布 iOS 和 Android,`--obfuscate` 仍可开启:Android 的 Dart 堆栈会正常还原,iOS 的 Dart 堆栈则保持混淆状态。若 iOS 的可读堆栈更重要,则该端构建时不要开启 `--obfuscate`。
+如果您的应用同时发布 iOS 和 Android,`--obfuscate` 仍可开启:Android 的 Dart 堆栈会正常还原,iOS 的 Dart 堆栈则保持混淆状态。若 iOS 的可读堆栈更重要,则该端构建时不要开启 `--obfuscate`。
</Warning>
<Tip>
diff --git a/zh/rum/sdk/flutter/data-collection.mdx b/zh/rum/sdk/flutter/data-collection.mdx
index 3a0816b7..4887da13 100644
--- a/zh/rum/sdk/flutter/data-collection.mdx
+++ b/zh/rum/sdk/flutter/data-collection.mdx
@@ -43,7 +43,7 @@ keywords: ["RUM", "Flutter SDK", "数据收集", "view", "action", "resource", "
## 手动埋点
-除了自动采集,你可以手动记录事件与属性。
+除了自动采集,您可以手动记录事件与属性。
```dart
final rum = DatadogSdk.instance.rum;
diff --git a/zh/rum/sdk/flutter/sdk-integration.mdx b/zh/rum/sdk/flutter/sdk-integration.mdx
index 42051358..e8482026 100644
--- a/zh/rum/sdk/flutter/sdk-integration.mdx
+++ b/zh/rum/sdk/flutter/sdk-integration.mdx
@@ -65,7 +65,7 @@ Future<void> main() async {
请不要在客户端代码中使用服务端密钥。`clientToken` 只用于客户端 RUM 数据上报,`applicationId` 用于归属 RUM 应用数据。
</Warning>
-如果你需要在 `runApp` 之外自行控制启动流程,也可以手动初始化,但需要自己接线错误采集:
+如果您需要在 `runApp` 之外自行控制启动流程,也可以手动初始化,但需要自己接线错误采集:
```dart
import 'dart:ui';
@@ -114,7 +114,7 @@ MaterialApp(
## 采集用户操作
-在 RUM 配置中 `trackFrustrations` 默认开启。用 `RumUserActionDetector` 包裹应用子树后,SDK 会自动识别点击等交互并生成 action 事件;你也可以手动记录操作。
+在 RUM 配置中 `trackFrustrations` 默认开启。用 `RumUserActionDetector` 包裹应用子树后,SDK 会自动识别点击等交互并生成 action 事件;您也可以手动记录操作。
```dart
// 自动识别子树内的用户交互
@@ -151,7 +151,7 @@ final configuration = DatadogConfiguration(
## 关联用户信息
-登录后,你可以设置当前用户。SDK 会把用户字段写入后续 RUM 事件的 `usr` 对象。
+登录后,您可以设置当前用户。SDK 会把用户字段写入后续 RUM 事件的 `usr` 对象。
```dart
DatadogSdk.instance.setUserInfo(
@@ -169,7 +169,7 @@ DatadogSdk.instance.setUserInfo();
## 上报错误
-使用 `DatadogSdk.runApp` 时未处理异常会被自动采集。你也可以手动上报捕获到的异常:
+使用 `DatadogSdk.runApp` 时未处理异常会被自动采集。您也可以手动上报捕获到的异常:
```dart
try {
diff --git a/zh/rum/sdk/harmony/advanced-config.mdx b/zh/rum/sdk/harmony/advanced-config.mdx
index 27fad476..fb86b23d 100644
--- a/zh/rum/sdk/harmony/advanced-config.mdx
+++ b/zh/rum/sdk/harmony/advanced-config.mdx
@@ -104,10 +104,10 @@ HarmonyOS SDK 在其他平台需要额外关闭的几项上天然没有开销,
### 应用是同意状态的唯一权威
-**每次启动都以你传给 `Flashcat.initialize` 的值为准。** SDK 不会用历史状态覆盖它——这一点与 Android、iOS SDK 完全一致。你的应用负责保存用户的选择,并在每次初始化时传回给 SDK。
+**每次启动都以您传给 `Flashcat.initialize` 的值为准。** SDK 不会用历史状态覆盖它——这一点与 Android、iOS SDK 完全一致。您的应用负责保存用户的选择,并在每次初始化时传回给 SDK。
<Warning>
-如果你的应用在每次启动时都用固定值(例如 `GRANTED`)初始化 SDK,那么用户撤销授权后重启,采集会重新开启。请在用户做出选择的那一刻调用 `setTrackingConsent`,并把该选择保存下来、下次启动时传给 `initialize`。
+如果您的应用在每次启动时都用固定值(例如 `GRANTED`)初始化 SDK,那么用户撤销授权后重启,采集会重新开启。请在用户做出选择的那一刻调用 `setTrackingConsent`,并把该选择保存下来、下次启动时传给 `initialize`。
</Warning>
同意状态同时会被持久化到本地,但**只服务于一个用途**:后台上传使用的 `WorkSchedulerExtensionAbility` 是独立进程,它面前没有用户、也拿不到应用的判断,只能读取主进程最后一次记录的决定。详见[后台和延迟上传](#后台和延迟上传)。
@@ -320,7 +320,7 @@ FlashcatCrash.enable(
| `setCrashLoopCooldownMs(cooldownMs)` | number | `300000` | 已触发保护后,重置持久化记录所需的无崩溃时长,单位为毫秒;小于 `1` 的值按 `1` 处理 |
<Warning>
-从 `0.2.0` 开始,默认策略由旧版的进程存活行为改为 `REPORT_THEN_EXIT`。仅初始化旧版 SDK 会在未捕获 ArkTS 异常后抑制宿主应用退出,使应用在业务状态未定义的情况下继续运行。新默认行为会同步保存崩溃并恢复平台退出语义。如需恢复旧行为,请显式设置 `JsCrashPolicy.OBSERVE_ONLY`,并确认保留受损进程符合你的业务预期。
+从 `0.2.0` 开始,默认策略由旧版的进程存活行为改为 `REPORT_THEN_EXIT`。仅初始化旧版 SDK 会在未捕获 ArkTS 异常后抑制宿主应用退出,使应用在业务状态未定义的情况下继续运行。新默认行为会同步保存崩溃并恢复平台退出语义。如需恢复旧行为,请显式设置 `JsCrashPolicy.OBSERVE_ONLY`,并确认保留受损进程符合您的业务预期。
</Warning>
### `REPORT_THEN_EXIT`
@@ -417,7 +417,7 @@ async onWorkStart(workInfo: workScheduler.WorkInfo): Promise<void> {
- **只读。** 它不会写回同意状态、设备标识或任务注册信息。HarmonyOS Preferences 是按进程的整文件缓存,扩展进程的写入可能覆盖主进程正在进行的撤销操作。
<Warning>
-不要在扩展进程里调用 `Flashcat.initialize()`。它会用你传入的字面值覆盖持久化的同意状态,从而在用户已经撤销授权后仍然上传数据。`setTrackingConsent` 在扩展进程中也会被忽略并打印错误日志。
+不要在扩展进程里调用 `Flashcat.initialize()`。它会用您传入的字面值覆盖持久化的同意状态,从而在用户已经撤销授权后仍然上传数据。`setTrackingConsent` 在扩展进程中也会被忽略并打印错误日志。
</Warning>
## 上传 HarmonyOS 崩溃符号
@@ -484,7 +484,7 @@ FLASHCAT_API_KEY=*** \
```
<Warning>
-用环境变量配置插件时,`--no-daemon` 不是可选项。hvigor 默认通过常驻的守护进程构建,该进程**只在创建时拷贝一次环境变量**,之后仅刷新固定白名单(`DEVECO_SDK_HOME`、`OHOS_BASE_SDK_HOME` 及两个增量构建开关)。因此复用守护进程时,插件读到的是**启动那个守护进程的人**的环境变量——可能来自 IDE 构建,也可能来自你上一条命令——而不是你刚敲进去的这份。
+用环境变量配置插件时,`--no-daemon` 不是可选项。hvigor 默认通过常驻的守护进程构建,该进程**只在创建时拷贝一次环境变量**,之后仅刷新固定白名单(`DEVECO_SDK_HOME`、`OHOS_BASE_SDK_HOME` 及两个增量构建开关)。因此复用守护进程时,插件读到的是**启动那个守护进程的人**的环境变量——可能来自 IDE 构建,也可能来自您上一条命令——而不是您刚敲进去的这份。
失败是静默的:`FLASHCAT_API_KEY` 读不到就跳过上传(只打一行日志),旧的 Key 则会以 401 结束——两种情况构建都照样成功。直接写在 `hvigorfile.ts` 里的值不受影响。
</Warning>
@@ -505,5 +505,5 @@ FLASHCAT_API_KEY=*** \
| `harmony_symbol_file` | `event`、`symbol_file` |
<Tip>
-Native 符号依赖 `.so` 的 GNU build-id。HarmonyOS NDK 默认会生成 build-id;如果你的构建链路关闭了该能力,请为 `.so` 增加 `-Wl,--build-id`。
+Native 符号依赖 `.so` 的 GNU build-id。HarmonyOS NDK 默认会生成 build-id;如果您的构建链路关闭了该能力,请为 `.so` 增加 `-Wl,--build-id`。
</Tip>
diff --git a/zh/rum/sdk/harmony/compatible.mdx b/zh/rum/sdk/harmony/compatible.mdx
index aa2638e1..f097413d 100644
--- a/zh/rum/sdk/harmony/compatible.mdx
+++ b/zh/rum/sdk/harmony/compatible.mdx
@@ -4,7 +4,7 @@ description: "了解 HarmonyOS RUM SDK 支持的工程类型、设备类型、
keywords: ["RUM", "HarmonyOS SDK", "兼容性", "ArkTS", "Stage 模型"]
---
-本文说明 HarmonyOS SDK 的支持范围和当前限制,帮助你在接入前判断工程是否满足要求。
+本文说明 HarmonyOS SDK 的支持范围和当前限制,帮助您在接入前判断工程是否满足要求。
## 支持范围
@@ -43,7 +43,7 @@ keywords: ["RUM", "HarmonyOS SDK", "兼容性", "ArkTS", "Stage 模型"]
}
```
-如果你的应用自身需要读取网络状态,也可以声明 `ohos.permission.GET_NETWORK_INFO`。当前 SDK 的事件上下文尚未自动订阅网络状态变化,因此该权限不是 RUM 上报的必需条件。
+如果您的应用自身需要读取网络状态,也可以声明 `ohos.permission.GET_NETWORK_INFO`。当前 SDK 的事件上下文尚未自动订阅网络状态变化,因此该权限不是 RUM 上报的必需条件。
## Kit 依赖
@@ -88,7 +88,7 @@ Crash 事件通过 RUM feature 写入。请不要在未启用 RUM 的情况下
| 限制 | 说明 |
|------|------|
| 导航范围 | 自动 view 当前监听 ArkUI `routerPageUpdate`;`Navigation` / `NavDestination` 需要手动 view 或额外封装 |
-| 点击范围 | SDK 不会自动遍历所有组件;你需要在按钮或公共点击处理器中调用 `FlashcatRum.trackTap()` |
+| 点击范围 | SDK 不会自动遍历所有组件;您需要在按钮或公共点击处理器中调用 `FlashcatRum.trackTap()` |
| 网络范围 | 只有使用 `rcp` 拦截器、`FlashcatHttp` 或手动 resource API 的请求会被采集 |
| Resource 生命周期 | resource 需要在活跃 view 内结束;view 关闭时仍未结束的 resource 会被丢弃 |
| 并发 resource | 单个 view 最多保留 100 个进行中的 resource |
diff --git a/zh/rum/sdk/harmony/data-collection.mdx b/zh/rum/sdk/harmony/data-collection.mdx
index 896a4e5f..d804f63a 100644
--- a/zh/rum/sdk/harmony/data-collection.mdx
+++ b/zh/rum/sdk/harmony/data-collection.mdx
@@ -43,7 +43,7 @@ SDK 按会话进行采样和生命周期管理。
## View 事件
-View 表示用户正在查看的页面或业务视图。你可以通过自动路由追踪或手动 API 生成 view。
+View 表示用户正在查看的页面或业务视图。您可以通过自动路由追踪或手动 API 生成 view。
```ts
import { GlobalRumMonitor } from '@flashcatcloud/rum';
diff --git a/zh/rum/sdk/harmony/sdk-integration.mdx b/zh/rum/sdk/harmony/sdk-integration.mdx
index 2981d654..379fdaba 100644
--- a/zh/rum/sdk/harmony/sdk-integration.mdx
+++ b/zh/rum/sdk/harmony/sdk-integration.mdx
@@ -119,7 +119,7 @@ struct Index {
| `ON_PAGE_SHOW` | 生成 `startView`,视图名称优先使用路由名称,缺省时使用路径最后一段 |
| `ON_PAGE_HIDE` | 生成 `stopView`,关闭当前视图并刷新停留时长 |
-如果你的页面没有使用 `router`,可以使用手动 API 管理视图。
+如果您的页面没有使用 `router`,可以使用手动 API 管理视图。
```ts
import { GlobalRumMonitor } from '@flashcatcloud/rum';
@@ -132,7 +132,7 @@ monitor.stopView('checkout');
## 采集用户操作
-启用 `setTrackUserInteractions(true)` 后,可以通过 `FlashcatRum.trackTap()` 在统一点击处理器中记录点击事件。该方法不会自动遍历所有组件,你需要在按钮或公共事件封装处显式调用。
+启用 `setTrackUserInteractions(true)` 后,可以通过 `FlashcatRum.trackTap()` 在统一点击处理器中记录点击事件。该方法不会自动遍历所有组件,您需要在按钮或公共事件封装处显式调用。
```ts
import { FlashcatRum } from '@flashcatcloud/rum';
@@ -144,7 +144,7 @@ Button('Pay')
});
```
-你也可以通过 `GlobalRumMonitor` 手动记录即时操作或带耗时的操作。
+您也可以通过 `GlobalRumMonitor` 手动记录即时操作或带耗时的操作。
```ts
import {
@@ -216,7 +216,7 @@ const apiClient = axios.create({ baseURL: 'https://api.example.com' });
trackAxios(apiClient);
```
-放在你已经创建 axios 实例的地方即可,通常是统一封装 token 和错误处理的那个文件。
+放在您已经创建 axios 实例的地方即可,通常是统一封装 token 和错误处理的那个文件。
<Warning>
拦截器是**按实例**注册的:`axios` 默认导出和 `axios.create()` 创建的实例互不共享。每个需要上报的实例都要调用一次,且**只调一次**——重复调用会导致同一请求上报两次。
@@ -249,7 +249,7 @@ try {
## 关联用户信息
-登录后,你可以设置当前用户。SDK 会把用户字段写入后续 RUM 事件的 `usr` 对象。
+登录后,您可以设置当前用户。SDK 会把用户字段写入后续 RUM 事件的 `usr` 对象。
```ts
import { Flashcat } from '@flashcatcloud/core';
diff --git a/zh/rum/sdk/ios/advanced-config.mdx b/zh/rum/sdk/ios/advanced-config.mdx
index 3cfe2ae4..32fbabf1 100644
--- a/zh/rum/sdk/ios/advanced-config.mdx
+++ b/zh/rum/sdk/ios/advanced-config.mdx
@@ -4,23 +4,12 @@ description: "深入配置 iOS RUM SDK 的高级功能,包括自定义事件
keywords: ["RUM", "iOS SDK", "用户监控", "前端监控"]
---
-<Note>
-**关于依赖和包名的说明**
-
-Flashduty iOS SDK 完全兼容 Datadog 开源协议。在 Swift Package Manager 或 CocoaPods 中添加依赖时使用 `FlashcatCore`、`FlashcatRUM` 等名称,但在代码中 import 时使用 `DatadogCore`、`DatadogRUM` 等模块名。您可以无缝复用 Datadog 生态的文档、示例和最佳实践,同时享受 Flashduty 平台的服务。
+本文介绍 iOS RUM SDK 的高级用法:手动追踪视图、操作、资源和错误,添加全局属性和用户信息,修改或丢弃事件,采样与远程配置,以及关联分布式追踪。
+<Note>
+SDK 兼容 Datadog 开源协议:在 Swift Package Manager 或 CocoaPods 中添加依赖时使用 `FlashcatCore`、`FlashcatRUM` 等名称,代码中 import 时使用 `DatadogCore`、`DatadogRUM` 等模块名,因此可以直接参考 Datadog 生态的文档和示例。
</Note>
-Flashduty iOS RUM SDK 提供丰富的高级配置选项,帮助您根据业务需求定制数据收集和上下文信息。
-
-<Info>
-**支持的配置场景:**
-- 保护敏感数据 - 屏蔽个人身份信息等敏感数据
-- 关联用户会话 - 将用户会话与内部用户标识关联
-- 减少数据量 - 通过采样降低 RUM 数据收集量,优化成本
-- 增强上下文 - 为数据添加自定义属性
-</Info>
-
## 丰富用户会话
### 自定义视图
@@ -206,21 +195,12 @@ RUMMonitor.shared().addError(
</Tabs>
<Note>
-更多错误上报详情,请参阅 [iOS 异常上报](/zh/rum/error-tracking/erro-reporting/ios)。
+更多错误上报详情,请参阅 [iOS 异常上报](/zh/rum/error-tracking/error-reporting/ios)。
</Note>
## 追踪自定义全局属性
-iOS SDK 会自动捕获默认 RUM 属性。您还可以向 RUM 事件添加额外的上下文信息,例如自定义属性。
-
-<Check>
-**自定义属性的用途:**
-- 根据业务信息(如购物车价值、用户等级、广告活动)过滤和分组用户行为
-- 跟踪特定用户群体的性能表现
-- 了解不同用户群体的错误分布
-</Check>
-
-### 设置自定义全局属性
+除 SDK 自动采集的默认属性外,您可以为所有 RUM 事件添加自定义全局属性,用于按业务信息(如购物车价值、用户等级、广告活动)过滤和分组,对比不同用户群体的性能与错误分布。
<Tabs>
<Tab title="Swift">
@@ -255,14 +235,7 @@ RUMMonitor.shared().removeAttribute(forKey: "user_plan")
## 追踪用户会话
-为 RUM 会话添加用户信息,帮助您更好地了解用户行为和问题影响。
-
-<Check>
-**用户信息的用途:**
-- 跟踪特定用户的浏览路径
-- 了解哪些用户受错误影响最大
-- 监控关键用户的性能表现
-</Check>
+为 RUM 会话添加用户信息后,可以跟踪特定用户的浏览路径,了解哪些用户受错误影响最大。
<Tabs>
<Tab title="Swift">
@@ -361,7 +334,7 @@ configuration.trackBackgroundEvents = YES;
| 参数 | 类型 | 必填 | 说明 |
| ------------------------- | -------------------------- | ---- | ----------------------------------------------------------------- |
| `applicationID` | String | 是 | RUM 应用 ID |
-| `sessionSampleRate` | Float | 否 | 会话采样率 (0-100),默认 100 |
+| `sessionSampleRate` | Float | 否 | 会话采样率 (0-100),默认 100 |
| `uiKitViewsPredicate` | UIKitRUMViewsPredicate | 否 | UIKit 视图追踪策略 |
| `uiKitActionsPredicate` | UIKitRUMActionsPredicate | 否 | UIKit 操作追踪策略 |
| `swiftUIViewsPredicate` | SwiftUIRUMViewsPredicate | 否 | SwiftUI 视图追踪策略 |
@@ -405,9 +378,9 @@ RUM.enable(
### 自动追踪视图
-要启用视图自动追踪,在初始化 RUM 时设置 `uiKitViewsPredicate` 或 `swiftUIViewsPredicate`。
+要启用视图自动追踪,在初始化 RUM 时设置 `uiKitViewsPredicate` 或 `swiftUIViewsPredicate`。
-对于 **UIKit**,使用 `DefaultUIKitRUMViewsPredicate` 类:
+对于 **UIKit**,使用 `DefaultUIKitRUMViewsPredicate` 类:
```swift
import DatadogRUM
@@ -420,7 +393,7 @@ RUM.enable(
)
```
-对于 **SwiftUI**,使用 `DefaultSwiftUIRUMViewsPredicate` 类:
+对于 **SwiftUI**,使用 `DefaultSwiftUIRUMViewsPredicate` 类:
```swift
import DatadogRUM
@@ -437,9 +410,9 @@ RUM.enable(
### 自动追踪用户操作
-要启用用户操作自动追踪,在初始化 RUM 时设置 `uiKitActionsPredicate` 或 `swiftUIActionsPredicate`。
+要启用用户操作自动追踪,在初始化 RUM 时设置 `uiKitActionsPredicate` 或 `swiftUIActionsPredicate`。
-对于 **UIKit**:
+对于 **UIKit**:
```swift
import DatadogRUM
@@ -452,7 +425,7 @@ RUM.enable(
)
```
-对于 **SwiftUI**:
+对于 **SwiftUI**:
```swift
import DatadogRUM
@@ -467,7 +440,7 @@ RUM.enable(
### 自动追踪网络请求
-要启用网络请求自动追踪(资源和错误),在初始化 RUM 时设置 `urlSessionTracking` 并启用 `URLSessionInstrumentation`:
+要启用网络请求自动追踪(资源和错误),在初始化 RUM 时设置 `urlSessionTracking` 并启用 `URLSessionInstrumentation`:
```swift
import DatadogRUM
@@ -486,26 +459,13 @@ URLSessionInstrumentation.enable(
)
```
-您还可以配置 `firstPartyHostsTracing` 以启用分布式追踪,将 RUM 资源与后端 traces 关联:
-
-```swift
-import DatadogRUM
-
-RUM.enable(
- with: RUM.Configuration(
- applicationID: "<RUM_APPLICATION_ID>",
- urlSessionTracking: RUM.Configuration.URLSessionTracking(
- firstPartyHostsTracing: .trace(hosts: ["example.com", "api.example.com"])
- )
- )
-)
-```
+如需把 RUM 资源与后端 trace 关联,请配置 `firstPartyHostsTracing`,详见 [集成 RUM 与分布式追踪](#集成-rum-与分布式追踪)。
### 自动追踪错误
所有"致命"和"非致命"的 iOS 错误都会自动收集并附加当前 RUM 视图的完整错误详情和元数据。
-致命错误包括应用崩溃。非致命错误包括:
+致命错误包括应用崩溃。非致命错误包括:
- **Swift errors**: Swift `throw` 的错误
- **Objective-C exceptions**: Objective-C 异常
@@ -514,9 +474,9 @@ RUM.enable(
## 修改或丢弃 RUM 事件
-在 RUM 事件发送到 Flashduty 之前,您可以通过事件映射器(Event Mappers)对其进行修改或完全丢弃。
+在 RUM 事件发送到 Flashduty 之前,您可以通过事件映射器(Event Mappers)对其进行修改或完全丢弃。
-事件映射器在创建 RUM 配置时设置:
+事件映射器在创建 RUM 配置时设置:
```swift
import DatadogRUM
@@ -569,9 +529,9 @@ DDRUMConfiguration *configuration = [[DDRUMConfiguration alloc] initWithApplicat
}];
```
-每个映射器都是一个签名为 `(T) -> T?` 的 Swift 闭包,其中 `T` 是具体的 RUM 事件类型。这允许在事件发送之前更改部分事件。
+每个映射器都是一个签名为 `(T) -> T?` 的 Swift 闭包,其中 `T` 是具体的 RUM 事件类型。这允许在事件发送之前更改部分事件。
-例如,要屏蔽 RUM Resource 的 `url` 中的敏感信息,实现一个自定义的 `redacted(_:) -> String` 函数并在 `resourceEventMapper` 中使用它:
+例如,要屏蔽 RUM Resource 的 `url` 中的敏感信息,实现一个自定义的 `redacted(_:) -> String` 函数并在 `resourceEventMapper` 中使用它:
```swift
let configuration = RUM.Configuration(
@@ -592,9 +552,9 @@ DDRUMConfiguration *configuration = [[DDRUMConfiguration alloc] initWithApplicat
}];
```
-从 error、resource 或 action 映射器返回 `nil` 将完全丢弃该事件;该事件不会发送到 Flashduty。从 view 事件映射器返回的值不能为 `nil`(要丢弃视图,请自定义 `UIKitRUMViewsPredicate` 的实现;详见[追踪视图自动化](https://docs.flashduty.com/zh/flashduty/rum/ios-sdk-integration#自动追踪视图))。
+从 error、resource 或 action 映射器返回 `nil` 将完全丢弃该事件;该事件不会发送到 Flashduty。从 view 事件映射器返回的值不能为 `nil`(要丢弃视图,请自定义 `UIKitRUMViewsPredicate` 的实现;详见[追踪视图自动化](#自动追踪视图))。
-根据事件的类型,只有某些特定的属性可以被修改:
+根据事件的类型,只有某些特定的属性可以被修改:
| 事件类型 | 属性键 | 说明 |
| ---------------- | ------------------------------------ | ------------------------ |
@@ -612,9 +572,9 @@ DDRUMConfiguration *configuration = [[DDRUMConfiguration alloc] initWithApplicat
## 获取 RUM 会话 ID
-检索 RUM 会话 ID 对于故障排查非常有用。例如,您可以将会话 ID 附加到支持请求、电子邮件或错误报告中,以便您的支持团队稍后在 Flashduty 中找到用户会话。
+检索 RUM 会话 ID 对于故障排查非常有用。例如,您可以将会话 ID 附加到支持请求、电子邮件或错误报告中,以便您的支持团队稍后在 Flashduty 中找到用户会话。
-您可以在运行时访问 RUM 会话 ID,无需等待 `sessionStarted` 事件:
+您可以在运行时访问 RUM 会话 ID,无需等待 `sessionStarted` 事件:
```swift
import DatadogRUM
@@ -634,20 +594,18 @@ RUMMonitor.shared().currentSessionID(completion: { sessionId in
## 设置追踪同意(GDPR 合规)
-为符合 GDPR 法规,Flashduty iOS SDK 在初始化时需要追踪同意值。
-
-`trackingConsent` 设置可以是以下值之一:
-
-1. `.pending`: Flashduty iOS SDK 开始收集和批处理数据,但不发送到 Flashduty。SDK 等待新的追踪同意值来决定如何处理批处理的数据。
-2. `.granted`: Flashduty iOS SDK 开始收集数据并发送到 Flashduty。
-3. `.notGranted`: iOS SDK 不收集任何数据。不会发送日志、traces 或 RUM 事件。
+为符合 GDPR 法规,iOS SDK 在初始化时需要追踪同意值 `trackingConsent`:
-在 SDK 初始化后更改追踪同意值,请使用 `Datadog.set(trackingConsent:)` API 调用。SDK 会根据新值更改其行为。
+| 值 | 行为 |
+| --- | --- |
+| `.pending` | 收集并批处理数据,但不发送到 Flashduty,等待新的同意值再决定如何处理已批处理的数据 |
+| `.granted` | 收集数据并发送到 Flashduty |
+| `.notGranted` | 不收集任何数据,不发送日志、trace 或 RUM 事件 |
-例如,如果当前追踪同意是 `.pending`:
+初始化后可调用 `Datadog.set(trackingConsent:)` 更改同意值,SDK 会随之调整行为。例如当前为 `.pending` 时:
-- 如果您将值更改为 `.granted`,SDK 将发送所有当前和未来的数据到 Flashduty;
-- 如果您将值更改为 `.notGranted`,SDK 将清除所有当前数据并且不收集未来的数据。
+- 改为 `.granted`,SDK 会发送所有当前和未来的数据;
+- 改为 `.notGranted`,SDK 会清除所有当前数据,且不再收集。
```swift
import DatadogCore
@@ -661,15 +619,11 @@ Datadog.set(trackingConsent: .granted)
[DDDatadog setWithTrackingConsent:DDTrackingConsentGranted];
```
-## 添加用户属性
-
-当前仅支持设置用户标准字段:`id`、`name`、`email`、`anonymous_id`;其他用户属性不支持。如有需求,可以在 `context` 字段进行配置。
-
## 数据管理
### 清除所有数据
-您可以选择删除 SDK 存储的所有未发送数据,使用 `Datadog.clearAllData()` API:
+您可以选择删除 SDK 存储的所有未发送数据,使用 `Datadog.clearAllData()` API:
```swift
import DatadogCore
@@ -699,11 +653,11 @@ Datadog.stopInstance()
[DDDatadog stopInstance];
```
-调用此方法会禁用 SDK 和所有活跃的功能,如 RUM。要恢复数据收集,您必须重新初始化 SDK。如果您想动态更改配置,可以使用此 API。
+调用此方法会禁用 SDK 和所有活跃的功能,如 RUM。要恢复数据收集,您必须重新初始化 SDK。如果您想动态更改配置,可以使用此 API。
## 采样
-默认情况下,RUM 会收集所有会话的数据。您可以通过 `sessionSampleRate` 参数设置采样率(百分比)来减少收集的会话数量。例如,采集 90% 的会话:
+默认情况下,RUM 会收集所有会话的数据。您可以通过 `sessionSampleRate` 参数设置采样率(百分比)来减少收集的会话数量。例如,采集 90% 的会话:
```swift
import DatadogRUM
@@ -729,7 +683,7 @@ configuration.sessionSampleRate = 90;
## 远程配置
-SDK 0.6.0 起,会话采样率可以在控制台 **应用管理 > 远程配置** 页签在线调整,无需改代码、重新发版。该功能默认关闭,需要在初始化时开启:
+SDK 0.6.0 起,会话采样率可以在控制台 **应用管理 → 远程配置** 页签在线调整,无需改代码、重新发版。该功能默认关闭,需要在初始化时开启:
```swift
import DatadogRUM
@@ -780,13 +734,11 @@ RUM.enable(
## 集成 RUM 与分布式追踪
-集成 RUM 与分布式追踪,可让您将 iOS 应用程序的请求与其对应的后端跟踪关联起来。这种组合让您能够一目了然地查看完整的前端和后端数据。
-
-使用来自 RUM 的前端数据以及来自 trace ID 注入的后端、基础设施和日志信息来定位堆栈中任何地方的问题并了解用户的体验。
+把 iOS 应用发出的请求与对应的后端 trace 关联起来,就能在一处同时看到前端体验和后端、基础设施、日志信息,快速定位问题所在。
### 配置方法
-初始化 RUM SDK,使用 `firstPartyHostsTracing` 来配置当前应用的 API 服务域名:
+初始化 RUM SDK,使用 `firstPartyHostsTracing` 来配置当前应用的 API 服务域名:
```swift
import DatadogRUM
@@ -828,32 +780,32 @@ configuration.urlSessionTracking = urlSessionTracking;
[DDURLSessionInstrumentation enableWithConfiguration:[DDURLSessionInstrumentationConfiguration alloc] initWithDelegateClass:[SessionDelegate class]]];
```
-**参数说明:**
+**参数说明:**
-- `hosts`: 需要追踪的域名列表
-- `sampleRate`: 要追踪的请求百分比(0-100),默认 100
+- `hosts`:需要追踪的域名列表
+- `sampleRate`:要追踪的请求百分比(0-100),默认 100
### 如何关联
-分布式追踪协议通过在 HTTP Header 上添加对应的头部字段(`traceparent`、`tracestate`)实现,以下是对相应 header 的说明:
+分布式追踪协议通过在 HTTP Header 上添加对应的头部字段(`traceparent`、`tracestate`)实现,以下是对相应 header 的说明:
```
traceparent: [version]-[trace id]-[parent id]-[trace flags]
```
-- `version`: 当前为 `00`
+- `version`:当前为 `00`
- `trace id`: 128 bits 的 trace ID 通过 16 进制处理后变成 32 个字符
- `parent id`: 64 bits 的 span ID,16 进制处理后为 16 个字符
-- `trace flags`: 代表是否有降采样,`01` 代表命中采样,`00` 代表非采样
+- `trace flags`:代表是否有降采样,`01` 代表命中采样,`00` 代表非采样
```
tracestate: dd=s:[sampling priority];o:[origin]
```
- `sampling priority`: `1` 代表 trace 被采样
-- `origin`: 始终为 `rum`,代表通过 RUM SDK 采集
+- `origin`:始终为 `rum`,代表通过 RUM SDK 采集
-**示例:**
+**示例:**
```
traceparent: 00-00000000000000008448eb211c80319c-b7ad6b7169203331-01
@@ -862,29 +814,14 @@ tracestate: dd=s:1;o:rum
### 如何验证
-添加配置后,可在 Xcode 的网络调试工具或代理工具(如 Charles、Proxyman)中查看从应用中发送的请求,如能正确携带对应的 header 则说明配置无误。
+添加配置后,可在 Xcode 的网络调试工具或代理工具(如 Charles、Proxyman)中查看从应用中发送的请求,如能正确携带对应的 header 则说明配置无误。
## 最佳实践
-<AccordionGroup>
-
-<Accordion title="配置验证">
-确保正确配置 `applicationID` 和 `clientToken`,以避免数据上传失败。
-</Accordion>
-
-<Accordion title="采样和隐私">
-根据应用需求调整采样率和隐私设置,平衡数据量与合规性。
-</Accordion>
-
-<Accordion title="事件修改">
-事件映射器中修改的属性应遵循允许修改的属性列表,避免修改保留属性。
-</Accordion>
-
-<Accordion title="视图追踪">
-对于复杂的视图追踪场景,建议实现自定义的 `ViewsPredicate`。
-</Accordion>
-
-</AccordionGroup>
+- 确认 `applicationID` 和 `clientToken` 配置正确,否则数据无法上传。
+- 根据应用需求调整采样率和隐私设置,平衡数据量与合规性。
+- 事件映射器只修改上表中允许修改的属性。
+- 复杂的视图追踪场景,建议实现自定义的 `ViewsPredicate`。
## 相关文档
diff --git a/zh/rum/sdk/ios/data-collection.mdx b/zh/rum/sdk/ios/data-collection.mdx
index 576fee70..cad8b929 100644
--- a/zh/rum/sdk/ios/data-collection.mdx
+++ b/zh/rum/sdk/ios/data-collection.mdx
@@ -275,13 +275,12 @@ iOS RUM SDK 为所有事件自动附加默认属性,帮助您了解用户设
### 本地存储机制
-在上传到 Flashduty 之前,数据以明文形式存储在应用沙盒的缓存目录(`Library/Caches`)中。
+在上传到 Flashduty 之前,数据以明文形式存储在应用沙盒的缓存目录(`Library/Caches`)中。该目录受 iOS 应用沙盒保护,设备上的其他应用无法读取。
-<Check>
-**安全保护:**
-- 缓存目录受 iOS 应用沙盒保护
-- 设备上安装的其他应用无法读取此目录
-</Check>
+<Warning>
+- 如果设备已越狱,存储的数据可能被读取
+- 不要在 RUM 事件中包含敏感数据,或在发送前通过事件映射器(Event Mapper)混淆或过滤
+</Warning>
### 数据管理策略
@@ -293,9 +292,7 @@ iOS RUM SDK 为所有事件自动附加默认属性,帮助您了解用户设
| **失败重试** | 如果网络不可用或上传失败,批次会被保留直到成功发送 |
| **自动清理** | 超过一定时限的数据会被自动清理 |
-<Note>
-即使用户在离线时使用应用,数据也会被保留并在网络恢复后上传,不会丢失任何监控数据。
-</Note>
+用户离线时采集的数据会保留,并在网络恢复后上传,不会丢失。
## 相关文档
diff --git a/zh/rum/sdk/ios/sdk-integration.mdx b/zh/rum/sdk/ios/sdk-integration.mdx
index aeed6790..a40cabc3 100644
--- a/zh/rum/sdk/ios/sdk-integration.mdx
+++ b/zh/rum/sdk/ios/sdk-integration.mdx
@@ -25,7 +25,7 @@ Flashduty iOS SDK 支持 Swift Package Manager 和 CocoaPods 两种安装方式
<Tabs>
<Tab title="Swift Package Manager">
-1. 在 Xcode 中,打开您的项目,选择 **File > Add Package Dependencies**
+1. 在 Xcode 中,打开您的项目,选择 **File → Add Package Dependencies**
2. 在搜索栏中输入 Flashduty SDK 的 Git 仓库 URL:
```
@@ -390,7 +390,7 @@ RUMMonitor.shared().addError(
</Check>
<Note>
-详细的异常上报配置请参阅 [iOS 异常上报](/zh/rum/error-tracking/erro-reporting/ios)。
+详细的异常上报配置请参阅 [iOS 异常上报](/zh/rum/error-tracking/error-reporting/ios)。
</Note>
### 追踪后台事件
diff --git a/zh/rum/sdk/react-native/advanced-config.mdx b/zh/rum/sdk/react-native/advanced-config.mdx
index 24113e6f..63d2f226 100644
--- a/zh/rum/sdk/react-native/advanced-config.mdx
+++ b/zh/rum/sdk/react-native/advanced-config.mdx
@@ -112,7 +112,7 @@ import { WebView } from '@flashcatcloud/mobile-react-native-webview';
- `injectedJavaScript`
- `injectedJavaScriptBeforeContentLoaded`
-你仍可以传入自己的 `onMessage` 和注入脚本:组件会把非 RUM 消息交给你的处理函数,并在包装后执行注入脚本;自定义 `nativeConfig` 会被组件覆盖。设置 `logUserCodeErrors={true}` 可以把注入的用户脚本错误记录为日志,默认 `false`。由于 Logs 当前只在 Android 生效,这类错误不会从 iOS 上报。
+您仍可以传入自己的 `onMessage` 和注入脚本:组件会把非 RUM 消息交给您的处理函数,并在包装后执行注入脚本;自定义 `nativeConfig` 会被组件覆盖。设置 `logUserCodeErrors={true}` 可以把注入的用户脚本错误记录为日志,默认 `false`。由于 Logs 当前只在 Android 生效,这类错误不会从 iOS 上报。
```tsx
<WebView
diff --git a/zh/rum/sdk/react-native/compatible.mdx b/zh/rum/sdk/react-native/compatible.mdx
index a7c57a3a..e9c9cff0 100644
--- a/zh/rum/sdk/react-native/compatible.mdx
+++ b/zh/rum/sdk/react-native/compatible.mdx
@@ -4,7 +4,7 @@ description: "了解 React Native RUM SDK 支持的平台、React Native 版本
keywords: ["RUM", "React Native SDK", "兼容性", "iOS", "Android", "新架构"]
---
-本文说明 React Native SDK 的支持范围和当前限制,帮助你在接入前判断工程是否满足要求。
+本文说明 React Native SDK 的支持范围和当前限制,帮助您在接入前判断工程是否满足要求。
## 支持范围
diff --git a/zh/rum/sdk/react-native/data-collection.mdx b/zh/rum/sdk/react-native/data-collection.mdx
index 84381182..0a2db2dc 100644
--- a/zh/rum/sdk/react-native/data-collection.mdx
+++ b/zh/rum/sdk/react-native/data-collection.mdx
@@ -65,7 +65,7 @@ SDK 的资源采集只有一个入口:JavaScript 层的 `XMLHttpRequest` 代
## 手动埋点
-除了自动采集,你可以手动记录事件与属性。
+除了自动采集,您可以手动记录事件与属性。
```typescript
import { DdRum, DdSdkReactNative, ErrorSource, RumActionType } from '@flashcatcloud/mobile-react-native';
diff --git a/zh/rum/sdk/react-native/sdk-integration.mdx b/zh/rum/sdk/react-native/sdk-integration.mdx
index 0509c118..01420c87 100644
--- a/zh/rum/sdk/react-native/sdk-integration.mdx
+++ b/zh/rum/sdk/react-native/sdk-integration.mdx
@@ -22,7 +22,7 @@ React Native SDK 基于原生 iOS / Android SDK 封装,通过 `@flashcatcloud/
## 安装 SDK
-安装核心包,并按你使用的导航库安装对应的视图采集包。原生模块通过 autolinking 自动接入,iOS 端还需要执行 `pod install`。
+安装核心包,并按您使用的导航库安装对应的视图采集包。原生模块通过 autolinking 自动接入,iOS 端还需要执行 `pod install`。
```bash
npm install @flashcatcloud/mobile-react-native
@@ -99,7 +99,7 @@ export default function App() {
请不要在客户端代码中使用服务端密钥。`clientToken` 只用于客户端 RUM 数据上报,`applicationId` 用于归属 RUM 应用数据。
</Warning>
-私有化部署时,通过 `customEndpoints` 把各类数据指向你自己的上报地址:
+私有化部署时,通过 `customEndpoints` 把各类数据指向您自己的上报地址:
```typescript
config.customEndpoints = {
@@ -110,7 +110,7 @@ config.customEndpoints = {
## 采集页面视图
-SDK 不会自动识别路由,需要按你使用的导航库接入视图采集。
+SDK 不会自动识别路由,需要按您使用的导航库接入视图采集。
<Tabs>
<Tab title="react-navigation">
@@ -196,7 +196,7 @@ DdRum.stopView('checkout');
</TouchableOpacity>
```
-你也可以手动记录一次操作:
+您也可以手动记录一次操作:
```typescript
import { DdRum, RumActionType } from '@flashcatcloud/mobile-react-native';
@@ -228,7 +228,7 @@ DdSdkReactNative.setUserInfo({
## 上报错误
-初始化时 `trackErrors` 为 `true`,SDK 会自动采集未处理的 JS 异常;`nativeCrashReportEnabled` 为 `true` 时还会采集原生 Android / iOS 崩溃。你也可以手动上报捕获到的异常:
+初始化时 `trackErrors` 为 `true`,SDK 会自动采集未处理的 JS 异常;`nativeCrashReportEnabled` 为 `true` 时还会采集原生 Android / iOS 崩溃。您也可以手动上报捕获到的异常:
```typescript
import { DdRum, ErrorSource } from '@flashcatcloud/mobile-react-native';
diff --git a/zh/rum/sdk/web/advanced-config.mdx b/zh/rum/sdk/web/advanced-config.mdx
index ee43e38c..667ca062 100644
--- a/zh/rum/sdk/web/advanced-config.mdx
+++ b/zh/rum/sdk/web/advanced-config.mdx
@@ -135,7 +135,7 @@ flashcatRum.setViewName("Checkout");
Web SDK 默认在初始加载视图中采集 Web Vitals 和首屏性能指标,包括 FCP、LCP、FID 和加载时间。这些指标会以页面导航开始时间为基准计算,适用于真实用户直接打开页面的场景。
-如果页面会在用户可见前提前加载,例如被浏览器预渲染、在后台标签页打开,或由宿主容器提前初始化,首屏指标可能会从不相关的导航开始时间计算,导致 FCP、LCP 或加载时间异常偏大。你可以在初始化时将 `trackWebVitals` 设置为 `false`,只关闭初始加载视图的 Web Vitals 和首屏性能指标采集。
+如果页面会在用户可见前提前加载,例如被浏览器预渲染、在后台标签页打开,或由宿主容器提前初始化,首屏指标可能会从不相关的导航开始时间计算,导致 FCP、LCP 或加载时间异常偏大。您可以在初始化时将 `trackWebVitals` 设置为 `false`,只关闭初始加载视图的 Web Vitals 和首屏性能指标采集。
```javascript rum-init.js
import { flashcatRum } from "@flashcatcloud/browser-rum";
@@ -614,15 +614,15 @@ flashcatRum.init({
<Info>
**traceparent**: `[version]-[trace id]-[parent id]-[trace flags]`
-- `version`: 当前为 00
+- `version`:当前为 00
- `trace id`: 128 bits 的 trace ID,16 进制处理后为 32 个字符
- `parent id`: 64 bits 的 span ID,16 进制处理后为 16 个字符
-- `trace flags`: 代表是否有降采样,01 代表命中采样,00 代表非采样
+- `trace flags`:代表是否有降采样,01 代表命中采样,00 代表非采样
**tracestate**: `dd=s:[sampling priority];o:[origin]`
- `sampling priority`: 1 代表 trace 被采样
-- `origin`: 始终为 RUM,代表通过 RUM SDK 采集
+- `origin`:始终为 RUM,代表通过 RUM SDK 采集
</Info>
**示例**:
diff --git a/zh/rum/sdk/web/data-collection.mdx b/zh/rum/sdk/web/data-collection.mdx
index 4054f9c6..ee531d07 100644
--- a/zh/rum/sdk/web/data-collection.mdx
+++ b/zh/rum/sdk/web/data-collection.mdx
@@ -381,20 +381,10 @@ Web RUM SDK 会将收集到的事件以批次形式上传到服务器,以优
## 隐私和合规
-<CardGroup cols={2}>
-<Card title="IP 地址匿名化" icon="eye-slash">
- 可配置 SDK 对 IP 地址进行匿名化处理
-</Card>
-<Card title="敏感数据过滤" icon="filter">
- 使用 `beforeSend` 回调过滤或混淆敏感信息
-</Card>
-<Card title="Cookie 和存储控制" icon="cookie">
- 可配置是否使用 Cookie 和本地存储
-</Card>
-<Card title="GDPR/CCPA 合规" icon="shield-check">
- 支持用户隐私选择退出机制
-</Card>
-</CardGroup>
+- **IP 地址匿名化**:可配置 SDK 对 IP 地址进行匿名化处理
+- **敏感数据过滤**:使用 `beforeSend` 回调过滤或混淆敏感信息
+- **Cookie 和存储控制**:可配置是否使用 Cookie 和本地存储
+- **GDPR/CCPA 合规**:支持用户隐私选择退出机制
<Tip>
有关隐私配置的详细信息,请参阅 [高级配置](/zh/rum/sdk/web/advanced-config#用户跟踪同意)。
diff --git a/zh/rum/sdk/web/faq.mdx b/zh/rum/sdk/web/faq.mdx
index c30f8b90..5ff91100 100644
--- a/zh/rum/sdk/web/faq.mdx
+++ b/zh/rum/sdk/web/faq.mdx
@@ -103,12 +103,12 @@ flashcatRum.init({
3. **检查采样率**:确认采样率设置合理
-```javascript
-flashcatRum.init({
- // ... 其他配置
- sessionSampleRate: 100 // 设为 100 表示采集所有会话
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... 其他配置
+ sessionSampleRate: 100 // 设为 100 表示采集所有会话
+ });
+ ```
4. **检查用户授权**:确认用户跟踪授权状态
@@ -124,18 +124,18 @@ flashcatRum.setTrackingConsent("granted");
1. **启用行为跟踪**:
-```javascript
-flashcatRum.init({
- // ... 其他配置
- trackUserInteractions: true
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... 其他配置
+ trackUserInteractions: true
+ });
+ ```
2. **为自定义元素添加标记**:
-```html
-<button data-action-name="提交表单">提交</button>
-```
+ ```html
+ <button data-action-name="提交表单">提交</button>
+ ```
3. **手动记录复杂交互**:
@@ -151,23 +151,23 @@ flashcatRum.addAction("click", "自定义按钮点击");
1. **启用异常跟踪**:
-```javascript
-flashcatRum.init({
- // ... 其他配置
- trackErrors: true
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... 其他配置
+ trackErrors: true
+ });
+ ```
2. **手动上报 try-catch 中的异常**:
-```javascript
-try {
- // 可能出错的代码
-} catch (error) {
- console.error(error);
- flashcatRum.addError(error);
-}
-```
+ ```javascript
+ try {
+ // 可能出错的代码
+ } catch (error) {
+ console.error(error);
+ flashcatRum.addError(error);
+ }
+ ```
3. **配置 Source Map**:便于定位生产环境的问题,详见 [Source Mapping](/zh/rum/error-tracking/source-mapping)
</Accordion>
@@ -179,24 +179,24 @@ try {
1. **只启用必要的功能**:
-```javascript
-flashcatRum.init({
- // ... 其他配置
- trackResources: true,
- trackLongTasks: false, // 关闭不需要的功能
- trackErrors: true,
- trackUserInteractions: true
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... 其他配置
+ trackResources: true,
+ trackLongTasks: false, // 关闭不需要的功能
+ trackErrors: true,
+ trackUserInteractions: true
+ });
+ ```
2. **调整采样率**:
-```javascript
-flashcatRum.init({
- // ... 其他配置
- sessionSampleRate: 50 // 只采集 50% 的会话
-});
-```
+ ```javascript
+ flashcatRum.init({
+ // ... 其他配置
+ sessionSampleRate: 50 // 只采集 50% 的会话
+ });
+ ```
3. **过滤非关键资源**:
diff --git a/zh/rum/sdk/web/sdk-integration.mdx b/zh/rum/sdk/web/sdk-integration.mdx
index 72021b83..e058fd2a 100644
--- a/zh/rum/sdk/web/sdk-integration.mdx
+++ b/zh/rum/sdk/web/sdk-integration.mdx
@@ -4,13 +4,9 @@ description: "快速了解如何在 Web 应用中集成 Web RUM SDK,包括 NPM
keywords: ["RUM", "Web SDK", "用户监控", "前端监控"]
---
-<Info>
-RUM SDK 支持多种接入方式,您可以根据项目需求选择最适合的方案。
-</Info>
-
## 接入方式
-我们提供三种接入方式:
+根据项目需求选择以下三种接入方式之一:
| 接入方式 | 推荐场景 | 特点 |
|----------|----------|------|
diff --git a/zh/rum/sdk/wechat-miniprogram/advanced-config.mdx b/zh/rum/sdk/wechat-miniprogram/advanced-config.mdx
index 402ed025..b2525972 100644
--- a/zh/rum/sdk/wechat-miniprogram/advanced-config.mdx
+++ b/zh/rum/sdk/wechat-miniprogram/advanced-config.mdx
@@ -4,11 +4,11 @@ description: "配置微信小程序 RUM SDK 的代理、分布式追踪、会话
keywords: ["RUM", "微信小程序", "高级配置", "分布式追踪", "代理"]
---
-微信小程序 RUM SDK 的高级配置用于处理网络转发、链路追踪、会话控制、上下文补充和手动埋点。你可以在初始化时设置采集行为,也可以在运行时通过公开 API 补充事件。
+微信小程序 RUM SDK 的高级配置用于处理网络转发、链路追踪、会话控制、上下文补充和手动埋点。您可以在初始化时设置采集行为,也可以在运行时通过公开 API 补充事件。
## 上报地址和代理
-SDK 默认将 RUM 数据发送到 `https://browser.flashcat.cloud/api/v2/rum`。如果小程序无法直接访问默认地址,或你需要先经过自己的网关,可以使用 `proxy`。
+SDK 默认将 RUM 数据发送到 `https://browser.flashcat.cloud/api/v2/rum`。如果小程序无法直接访问默认地址,或您需要先经过自己的网关,可以使用 `proxy`。
### 使用字符串代理
@@ -24,7 +24,7 @@ flashcatRum.init({
### 使用函数代理
-当 `proxy` 是函数时,SDK 会把 `path` 和 `parameters` 交给你拼接完整 URL。`path` 固定为 `/api/v2/rum`,`parameters` 包含 `ddsource`、`ddtags`、`dd-api-key`、SDK 版本和批次时间等上报参数。
+当 `proxy` 是函数时,SDK 会把 `path` 和 `parameters` 交给您拼接完整 URL。`path` 固定为 `/api/v2/rum`,`parameters` 包含 `ddsource`、`ddtags`、`dd-api-key`、SDK 版本和批次时间等上报参数。
```javascript app.js
flashcatRum.init({
@@ -82,7 +82,7 @@ SDK 使用小程序存储保存当前会话,并把会话 ID 写入每个 RUM
| 会话扩展节流 | 1 分钟 | SDK 最多每分钟扩展一次会话过期时间 |
| 匿名用户 | 默认开启 | 未调用 `setUser()` 时,SDK 会为会话生成匿名 ID |
-你可以在退出登录、切换账号或需要切分会话时调用 `stopSession()`。调用后,SDK 会清除当前会话;下一次事件会创建新的会话。
+您可以在退出登录、切换账号或需要切分会话时调用 `stopSession()`。调用后,SDK 会清除当前会话;下一次事件会创建新的会话。
```javascript app.js
flashcatRum.stopSession();
@@ -101,12 +101,12 @@ flashcatRum.init({
```
<Tip>
-如果你在短时间内主动上报大量自定义事件,请根据实际流量调整 `eventRateLimiterThreshold`,避免业务事件被限流。
+如果您在短时间内主动上报大量自定义事件,请根据实际流量调整 `eventRateLimiterThreshold`,避免业务事件被限流。
</Tip>
## 发送前处理
-`beforeSend` 会在 RUM 事件发送前执行。你可以在这里补充字段、脱敏上下文,或返回 `false` 丢弃当前事件。
+`beforeSend` 会在 RUM 事件发送前执行。您可以在这里补充字段、脱敏上下文,或返回 `false` 丢弃当前事件。
```javascript app.js
flashcatRum.init({
@@ -127,7 +127,7 @@ flashcatRum.init({
## 用户和全局上下文
-`setUser()` 设置当前用户信息。启用 `trackAnonymousUser` 且用户上下文为空时,SDK 会自动将匿名 ID 写入 `usr.id` 和 `usr.anonymous_id`;如果你设置了用户信息,SDK 会保留你的用户字段,并补充 `usr.anonymous_id`。
+`setUser()` 设置当前用户信息。启用 `trackAnonymousUser` 且用户上下文为空时,SDK 会自动将匿名 ID 写入 `usr.id` 和 `usr.anonymous_id`;如果您设置了用户信息,SDK 会保留您的用户字段,并补充 `usr.anonymous_id`。
```javascript app.js
flashcatRum.setUser({
@@ -148,7 +148,7 @@ flashcatRum.setGlobalContext({
## 手动页面和自定义耗时
-自动页面名称来自页面实例的 `route`。如果你需要记录虚拟页面,或希望用业务名称覆盖当前页面,可以调用 `startPage()`。
+自动页面名称来自页面实例的 `route`。如果您需要记录虚拟页面,或希望用业务名称覆盖当前页面,可以调用 `startPage()`。
```javascript pages/product/detail.js
flashcatRum.startPage("product_detail");
diff --git a/zh/rum/sdk/wechat-miniprogram/compatible.mdx b/zh/rum/sdk/wechat-miniprogram/compatible.mdx
index 59febfe8..255cfb4c 100644
--- a/zh/rum/sdk/wechat-miniprogram/compatible.mdx
+++ b/zh/rum/sdk/wechat-miniprogram/compatible.mdx
@@ -12,7 +12,7 @@ keywords: ["RUM", "微信小程序", "兼容性", "基础库"]
|------|------|------|
| 小程序基础库 | `2.10.0+` | SDK 初始化会注册 `wx.onUnhandledRejection`,低于该版本的运行时不建议接入 |
| 推荐基础库 | `2.12.0+` | 可完整采集页面渲染、启动、脚本执行和 setData 更新耗时 |
-| 微信开发者工具 | 使用近期稳定版 | 需要支持 npm 安装依赖并执行 **工具 > 构建 npm** |
+| 微信开发者工具 | 使用近期稳定版 | 需要支持 npm 安装依赖并执行 **工具 → 构建 npm** |
| npm 包 | `@flashcatcloud/miniprogram-rum` | 包含核心能力、平台适配层和 RUM 入口 |
<Warning>
@@ -51,7 +51,7 @@ keywords: ["RUM", "微信小程序", "兼容性", "基础库"]
1. 在小程序项目根目录执行 `npm install @flashcatcloud/miniprogram-rum`
2. 在微信开发者工具中打开项目
-3. 执行 **工具 > 构建 npm**
+3. 执行 **工具 → 构建 npm**
4. 确认生成的 `miniprogram_npm` 可以被小程序代码引用
<Tip>
diff --git a/zh/rum/sdk/wechat-miniprogram/data-collection.mdx b/zh/rum/sdk/wechat-miniprogram/data-collection.mdx
index 39dde5a1..51fd4a7f 100644
--- a/zh/rum/sdk/wechat-miniprogram/data-collection.mdx
+++ b/zh/rum/sdk/wechat-miniprogram/data-collection.mdx
@@ -5,7 +5,7 @@ description: "了解微信小程序 RUM SDK 自动采集的页面、操作、请
keywords: ["RUM", "微信小程序", "数据收集", "小程序监控"]
---
-微信小程序 RUM SDK 初始化后,会通过小程序运行时 API 自动采集用户体验数据。你可以通过初始化参数关闭某类采集,也可以用手动 API 补充业务事件。
+微信小程序 RUM SDK 初始化后,会通过小程序运行时 API 自动采集用户体验数据。您可以通过初始化参数关闭某类采集,也可以用手动 API 补充业务事件。
## 采集概览
@@ -108,7 +108,7 @@ SDK 每 3 秒更新一次活跃页面的停留时长。页面进入后台、隐
| `wx.onPageNotFound` | `page-not-found` | 打开的页面不存在 |
| `wx.onLazyLoadError` | `lazy-load` | 分包懒加载失败 |
| 网络请求失败 | `network` | 请求失败时,SDK 在 resource 事件之外额外生成一条错误事件 |
-| `addError()` | `custom` | 你手动上报的业务错误 |
+| `addError()` | `custom` | 您手动上报的业务错误 |
错误事件会包含错误消息、可选堆栈和来源。手动上报错误时,可以把 `error.stack` 作为第三个参数传入 `addError()`。
@@ -131,7 +131,7 @@ SDK 每 3 秒更新一次活跃页面的停留时长。页面进入后台、隐
## 自定义事件
-调用 `addCustomEvent(name, context?)` 会生成 custom 事件。你可以用它记录无法从页面生命周期、操作或请求中自动推断的业务事件。
+调用 `addCustomEvent(name, context?)` 会生成 custom 事件。您可以用它记录无法从页面生命周期、操作或请求中自动推断的业务事件。
| 字段 | 说明 |
|------|------|
@@ -158,7 +158,7 @@ SDK 会把非 view 事件关联到事件发生时间对应的页面和会话:
## 关闭某类自动采集
-你可以在初始化时关闭不需要的采集类型:
+您可以在初始化时关闭不需要的采集类型:
```javascript app.js
import { flashcatRum } from "@flashcatcloud/miniprogram-rum";
@@ -172,7 +172,7 @@ flashcatRum.init({
});
```
-关闭某类自动采集只影响对应的自动监听逻辑。手动 API 仍可使用,例如关闭 `trackActions` 后,你仍然可以调用 `addAction()` 上报自定义操作。
+关闭某类自动采集只影响对应的自动监听逻辑。手动 API 仍可使用,例如关闭 `trackActions` 后,您仍然可以调用 `addAction()` 上报自定义操作。
## 上报批次
diff --git a/zh/rum/sdk/wechat-miniprogram/sdk-integration.mdx b/zh/rum/sdk/wechat-miniprogram/sdk-integration.mdx
index 3e240b12..fda95dc8 100644
--- a/zh/rum/sdk/wechat-miniprogram/sdk-integration.mdx
+++ b/zh/rum/sdk/wechat-miniprogram/sdk-integration.mdx
@@ -11,8 +11,8 @@ keywords: ["RUM", "微信小程序 SDK", "小程序监控", "用户监控", "@fl
在接入 SDK 前,请先完成以下准备:
- 在 Flashduty 控制台创建或选择一个 RUM 应用,并获取 **Application ID** 和 **Client Token**
-- 确认小程序可以访问 RUM 数据上报地址。默认地址为 `https://browser.flashcat.cloud/api/v2/rum`;如果你的网络策略需要转发,请配置 `proxy`
-- 在微信公众平台配置 request 合法域名:进入 **开发 > 开发管理 > 开发设置 > 服务器域名**,将 `https://browser.flashcat.cloud`(或你的代理域名)添加到 **request 合法域名**。未配置时,真机上的所有上报请求会被微信拦截;开发调试阶段可临时勾选微信开发者工具的「不校验合法域名」选项
+- 确认小程序可以访问 RUM 数据上报地址。默认地址为 `https://browser.flashcat.cloud/api/v2/rum`;如果您的网络策略需要转发,请配置 `proxy`
+- 在微信公众平台配置 request 合法域名:进入 **开发 → 开发管理 → 开发设置 → 服务器域名**,将 `https://browser.flashcat.cloud`(或您的代理域名)添加到 **request 合法域名**。未配置时,真机上的所有上报请求会被微信拦截;开发调试阶段可临时勾选微信开发者工具的「不校验合法域名」选项
- 如果使用微信开发者工具,请在工具中构建 npm,使 `miniprogram_npm` 可以引用 SDK 包
## 安装 SDK
@@ -23,7 +23,7 @@ keywords: ["RUM", "微信小程序 SDK", "小程序监控", "用户监控", "@fl
npm install @flashcatcloud/miniprogram-rum
```
-安装后,在微信开发者工具中执行 **工具 > 构建 npm**。
+安装后,在微信开发者工具中执行 **工具 → 构建 npm**。
## 初始化 SDK
@@ -118,7 +118,7 @@ RUM 数据接收站点。未配置 `proxy` 时,SDK 会将事件发送到 `http
## 使用用户信息和全局上下文
-登录后,你可以使用 `setUser()` 关联当前用户。SDK 会把这些字段写入后续 RUM 事件的 `usr` 对象。
+登录后,您可以使用 `setUser()` 关联当前用户。SDK 会把这些字段写入后续 RUM 事件的 `usr` 对象。
```javascript app.js
flashcatRum.setUser({
@@ -128,7 +128,7 @@ flashcatRum.setUser({
});
```
-你也可以使用 `setGlobalContext()` 添加业务上下文。全局上下文会写入后续事件的 `context` 字段。
+您也可以使用 `setGlobalContext()` 添加业务上下文。全局上下文会写入后续事件的 `context` 字段。
```javascript app.js
flashcatRum.setGlobalContext({
@@ -139,7 +139,7 @@ flashcatRum.setGlobalContext({
## 手动上报事件
-除了自动采集,你还可以主动补充业务事件、错误、操作和自定义耗时。
+除了自动采集,您还可以主动补充业务事件、错误、操作和自定义耗时。
```javascript pages/order/detail.js
import { flashcatRum } from "@flashcatcloud/miniprogram-rum";
diff --git a/zh/stsatuspage.mdx b/zh/statuspage.mdx
similarity index 86%
rename from zh/stsatuspage.mdx
rename to zh/statuspage.mdx
index c5a50534..5e9fa3ae 100644
--- a/zh/stsatuspage.mdx
+++ b/zh/statuspage.mdx
@@ -1,5 +1,5 @@
---
-title: 状态页
+title: "Flashduty 服务状态"
description: "查看 Flashduty 各服务组件的实时运行状态和历史可用性记录"
keywords: ["状态页", "服务状态", "可用性", "运行状态"]
url: https://status.flashcat.cloud