





HBB2OBB converts horizontal (axis-aligned) bounding boxes (HBBs) into oriented (rotated) bounding boxes (OBBs) by using your existing HBB annotations as prompts for segmentation models from the SAM (Segment Anything Model) family. It targets object detection tasks where objects appear at arbitrary orientations, such as aerial imagery, satellite data, or traffic monitoring, producing OBBs that tightly encapsulate non-upright objects. Beyond conversion, it ships evaluation, hyperparameter optimization, and annotation format-conversion tools, with both a command-line interface and a Python API.
- 🎯 Accurate OBBs from HBBs: prompts SAM-family segmentation models with your existing horizontal boxes to fit tight oriented boxes around non-upright objects, with no re-annotation required.
- 🚗 No HBBs? Detect them:
hbb2obb-detectruns an Ultralytics detector over your images and writes the horizontal boxes the conversion consumes, confidence column included (details). - 🧩 Model ensemble: combines masks from multiple SAM variants through majority voting for more robust, accurate results (see Usage).
- 🛡️ Spatially constrained & safe: region-specific masking and contour refinement keep segmentation inside the object, a mask split by an occluder is fitted back together, and a fallback keeps the original HBB when no valid mask is found, counted and reported rather than left to be discovered afterwards.
- 🔎 Confidence-scored output: every OBB gets a quality score in
[0, 1]that flags silent fallbacks and low-confidence conversions, so you know which boxes to trust; your detector's own confidence can be carried through instead of, or on top of, that score (see Confidence scores). - 📐 Flexible scaling: positive or negative scale factors (optionally different for the short and long sides) recover cropped object parts or tighten overly conservative annotations.
- 📊 Evaluate & optimize: evaluation against ground truth on IoU, orientation error and the share of boxes above a high IoU bar, plus
hbb2obb-optimize, a hyperparameter search over SAM inference resolution × scale factors × opening kernel, driven by a config file so a whole benchmark is one reproducible command (details). - 🔬 Where the score comes from:
hbb2obb-analyzebreaks one evaluation down by the ground truth's orientation, size, frame edge, difficulty and class, and scores the conversion against emitting the horizontal prompt unchanged (details). - 🔄 Five annotation formats: read and write YOLO, DOTA, Pascal VOC, COCO and LabelMe, for horizontal and oriented boxes alike, with a check that proves every format encodes the same boxes (details).
- 🔍 Interactive viewer:
hbb2obb-viewpans and zooms over your annotations, in any format, coloring boxes by confidence and overlaying predictions against ground truth (details). - ⚙️ CLI + Python API:
hbb2obb,hbb2obb-detect,hbb2obb-eval,hbb2obb-analyze,hbb2obb-convert,hbb2obb-viewandhbb2obb-optimizecommands plus an importable API, with transparent visualizations of every step.
📋 Full Feature Overview
- HBB to OBB conversion: converts YOLO-format horizontal bounding boxes to oriented bounding boxes, in absolute px or, with
--normalize, relative to[0, 1]for Ultralytics training (details). - HBB detection: produce the horizontal boxes in the first place with any Ultralytics detector, local, from the Ultralytics catalogue, or from Hugging Face (details).
- Segmentation-based: uses state-of-the-art SAM models for accurate object boundary detection.
- Multiple model support: SAM, SAM2, SAM2.1, SAM3, Mobile SAM, and FastSAM families (details).
- Model ensemble: combine multiple models via majority voting for enhanced accuracy.
- Confidence scoring: a per-OBB quality score flags fallbacks and low-confidence conversions for triage, optionally combined with the detector confidence from the input, written as an extra column or to a side-car directory that leaves the label files standard (details).
- Polygon output: optionally save the segmentation contour behind each OBB, row-aligned with the OBB file, as a tighter object outline for downstream masking (details).
- Evaluation tools: assess OBB accuracy against ground truth on mean and median IoU, orientation error, and the share of matched boxes above IoU 0.5, 0.75, 0.85 and 0.9, overall and per class.
- Accuracy breakdown: cut one evaluation by ground-truth orientation, size, frame edge,
difficultflag and class, beside an identity baseline and the converted-to-reference side ratios, as a report, a YAML and a figure. - Hyperparameter optimization: search SAM inference resolutions, HBB scale factors and opening kernels for the best settings on your data, one sweep at a time or a whole benchmark from a config file.
- Provenance records:
--save_provenancewrites the command, the versions, a digest of the source that ran, the SHA-256 of every checkpoint and how many boxes fell back to their HBB, so a released annotation set can be regenerated rather than trusted. - Visualization tools: render HBBs, segmentation masks, derived contours, and resulting OBBs.
- Interactive viewer: pan and zoom over annotated frames, toggle each layer, and compare two annotation sets side by side.
- Format conversion utilities: convert between YOLO, DOTA, Pascal VOC, COCO and LabelMe annotations, in either direction, for both box kinds.
🚀 Planned Enhancements
- Improved morphological operations: more advanced operations for better mask refinement, beyond the signed opening/closing kernel.
- Support for other segmentation models: extend compatibility beyond the SAM/FastSAM families.
🔗 Related Projects
HBB2OBB integrates with and complements several specialized tools:
-
Geo-trax 🚀: georeferenced vehicle trajectory extraction pipeline for high-altitude drone imagery, built on YOLO detection and multi-object tracking. Its vehicle detector supplies the HBB inputs for vehicle use cases (car, bus, truck, motorcycle), and
hbb2obb-detectruns it by default (details). -
Stabilo ⚖️: Python library for video and trajectory stabilization using robust homography transformations. Supports various feature detectors, RANSAC algorithms, and user-defined masks.
-
Stabilo-Optimize 🎯: benchmarking and hyperparameter optimization framework for Stabilo. Evaluates stabilization performance through ground truth-free assessment using random perturbations.
Create and activate a Python virtual environment (Python 3.9–3.13), then install from PyPI:
python3.11 -m venv .venv
source .venv/bin/activate  # On Windows: .venv\Scripts\activate
pip install hbb2obb
Also works with uv (uv pip install hbb2obb) and conda.
Note
SAM model weights are downloaded automatically by Ultralytics on first use into a models/ directory relative to your current working directory. Detector weights for hbb2obb-detect land there too. To keep one copy wherever you run from, set HBB2OBB_MODELS_DIR once (e.g. export HBB2OBB_MODELS_DIR=~/.cache/hbb2obb), or pass --models_dir to hbb2obb, hbb2obb-detect or hbb2obb-optimize; the flag wins over the variable. The one exception is SAM 3, which must be downloaded manually (see below).
Every command checks PyPI once a day, in the background, for a newer HBB2OBB release and prints a one-line notice if one exists. The check never blocks, never fails a run, and is silent when offline. Set HBB2OBB_DISABLE_UPDATE_CHECK=1 to turn it off.
Alternatives: conda or uv
conda create -n hbb2obb python=3.11 -y
conda activate hbb2obb
uv (fastest; then uv pip install hbb2obb):
uv venv --python 3.11
source .venv/bin/activate  # On Windows: .venv\Scripts\activate
Install from source (development / editable)
git clone https://github.com/rfonod/hbb2obb.git
cd hbb2obb && pip install -e '.[dev]'
The -e flag makes your local changes take effect without reinstalling; the [dev] extra adds pytest and ruff. For a plain install, use pip install . instead.
SAM 3 model weights (manual download required)
Unlike other SAM models, SAM 3 weights (sam3.pt) are not auto-downloaded by Ultralytics. To use SAM 3:
- Request access on the SAM 3 model page on Hugging Face.
- Once approved, download
sam3.pt. - Place
sam3.ptin the models directory (models/relative to where you run the conversion, orHBB2OBB_MODELS_DIR/--models_dirif you set one).
See the Ultralytics SAM 3 documentation for more.
A small sample dataset ships in data/. From the repository root:
# The sample already ships with detected HBBs, so start here. To redo that step yourself:
#   hbb2obb-detect data/images --overwrite

# Convert the sample HBBs to OBBs (default single model) and save visualizations
hbb2obb data/images --save_img

# Higher accuracy with a model ensemble
hbb2obb data/images --sam_models sam_b sam_l sam2_b sam2.1_b

# Evaluate the converted OBBs against ground truth
hbb2obb-eval data/labels_obb_gt data/labels_obb -mp data/classes.yaml

# Break that score down by what the ground-truth box looks like
hbb2obb-analyze data/labels_obb_gt data/labels_obb -mp data/classes.yaml

# Look at the result: pan, zoom, step through frames, q to quit
hbb2obb-view data/images --compare data/labels_obb_gt
Converted OBB annotations are written to data/labels_obb/. Every command takes --help, and the Quick start walks through every step with the output to expect. For your own data you need only the images and horizontal boxes for them; data/README.md walks through what each file in the sample is and the command that produced it.
The documentation site has a guide per command, pages on how the conversion works, the metrics and troubleshooting, an end-to-end workflow from someone else's annotation format to a release, and a CLI reference and API reference generated from the code.
# Default single model (sam_b), HBBs read from <img_source>/../labels_hbb
hbb2obb /path/to/images --hbb_dir /path/to/hbb/annotations

# Model ensemble (majority voting across models)
hbb2obb /path/to/images --sam_models sam_b sam_l sam2_b sam2.1_b

# Scale HBBs: expand to recover cropped parts, or shrink conservative boxes
hbb2obb /path/to/images --scale_factors 0.1      # expand uniformly
hbb2obb /path/to/images --scale_factors -0.02    # shrink uniformly
hbb2obb /path/to/images --scale_factors 0.1 0.05 # short side / long side

# Save visualization images of the conversion
hbb2obb /path/to/images --save_img

# Also save the segmentation polygon of each object, a tighter outline than its OBB
hbb2obb /path/to/images --save_polygon --polygon_dir /path/to/save/polygons
The conversion guide covers the key arguments (morphological kernel, fragment merging, normalized output, fallback reporting) and the Python API:
from pathlib import Path
from hbb2obb.converter import hbb2obb, save_obb_annotations

img_path = Path("/path/to/images/img1.jpg")
obb_annotations = hbb2obb(img_path=img_path, sam_models=["sam_b", "sam_l"], scale_factors=0.05)
save_obb_annotations(obb_annotations, "/path/to/labels_obb", img_path)hbb2obb-eval /path/to/ground_truth /path/to/predictionsPredictions are paired with ground truth by oriented IoU and scored on mean and median IoU, the share of pairs above each IoU rung, and orientation error, overall and per class:
Average IoU: 0.89642 ± 0.06834 (SEM 0.00483)
Median IoU: 0.91080
Matched Boxes Above Threshold: IoU>=0.50: 100.0%  IoU>=0.75: 98.0%  IoU>=0.85: 80.5%  IoU>=0.90: 57.0%
Orientation Error: p90 4.40°, median 1.04°, mean 2.11° ± 4.88°

=== Results by Class ===
     Class  GT  Pred  Matches IoU (mean ± std) IoU (median) IoU>=0.9 Angle p90 (°) Angle p50 (°)
       Car 185   186      185  0.8982 ± 0.0606       0.9106    57.3%          4.36          1.00
       Bus   6     6        6  0.9358 ± 0.0353       0.9390    66.7%          1.66          1.33
     Truck   8     8        8  0.8533 ± 0.1469       0.8884    50.0%         13.87          1.56
Motorcycle   2     1        1  0.6746 ± 0.0000       0.6746     0.0%          9.95          9.95
Mean IoU saturates on tight boxes; the ladder and the orientation error do not. The evaluation guide explains each number and the matching options.
hbb2obb-eval gives one number per metric. hbb2obb-analyze says where it came from, cutting the same matched pairs by ground-truth orientation, size, frame edge, difficult flag and class, and scoring the conversion against emitting the horizontal prompt unchanged:
hbb2obb-analyze /path/to/ground_truth /path/to/predictions -hd /path/to/labels_hbb -i /path/to/images -o /path/to/analysisSee the analysis guide for every table, with an example from Songdo Vision OBB.
No HBBs yet? hbb2obb-detect runs an Ultralytics detector over your images and writes exactly the YOLO TXT the conversion reads, with the detector confidence in the 6th column:
# geo-trax is the default detector, tuned for vehicles in high-altitude drone imagery (weights downloaded on first use)
hbb2obb-detect /path/to/images

# Any other Hugging Face model: all three parts, '<user>/<repo>/<file>.pt' (no "huggingface.co/" prefix)
hbb2obb-detect /path/to/images --model rfonod/geo-trax/geotrax_hbb_yolov8s_1920_v1.pt

# Then convert, carrying the detector confidence into the OBBs alongside the conversion score
hbb2obb /path/to/images --save_confidence --confidence_source combined
The detection guide covers every form --model takes, renumbering classes with --class_map, passing predictor arguments through, and scoring hand-drawn boxes with --merge_with.
hbb2obb-view opens your annotations over the images they belong to, in a window that pans and zooms:
# Defaults: images in <dir>, boxes from ../labels_obb and ../labels_hbb
hbb2obb-view data/images

# Color the OBBs by confidence and print the score, to find the boxes worth checking
hbb2obb-view data/images --show_confidence

# Overlay ground truth in blue over the converted boxes in green
hbb2obb-view data/images --compare data/labels_obb_gt

# Pin the format to read, or write annotated images instead of opening a window
hbb2obb-view data/images --obb_format dota
hbb2obb-view data/images -o /path/to/annotated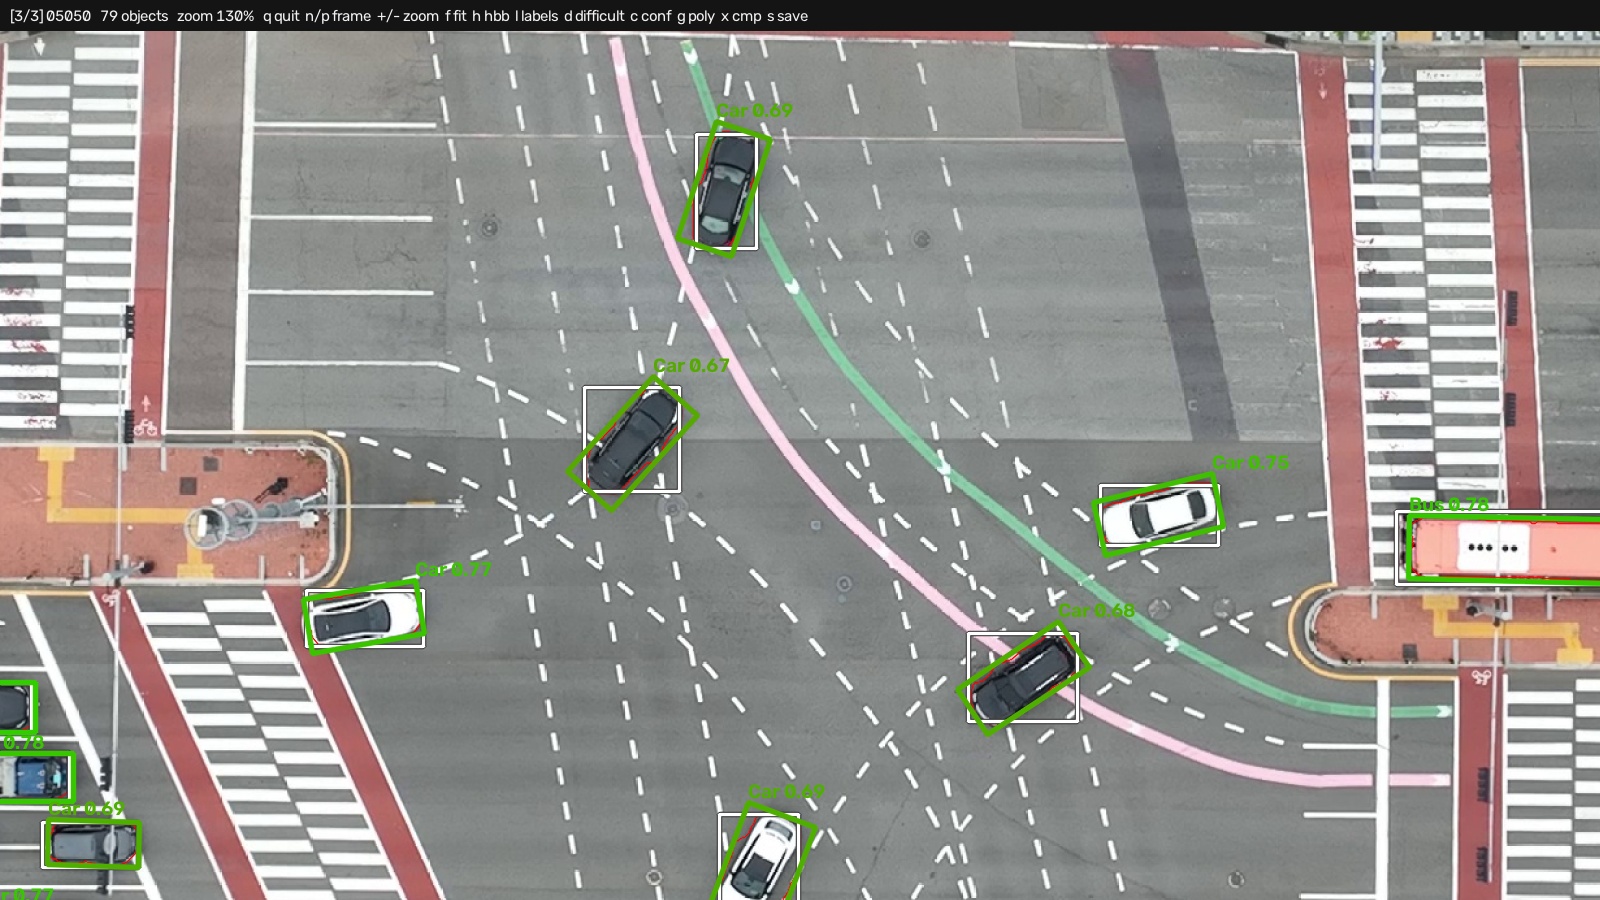
The viewer guide has the color legend and the keyboard shortcuts.
hbb2obb-convert moves annotations between the five formats below, in either direction, for horizontal and oriented boxes alike:
| Format | HBB | OBB | Shape |
|---|---|---|---|
yolo |
✅ | ✅ | one .txt per frame, with an optional trailing confidence column |
dota |
✅ | one file per frame, x1 y1 … x4 y4 name difficult, integer px |
|
voc |
✅ | one Pascal VOC .xml per frame, integer px |
|
coco |
✅ | ✅ | one .json for the whole set; the quad goes in segmentation, a confidence in score |
labelme |
✅ | ✅ | one LabelMe .json per frame |
# Write several formats in one pass; --from is detected from the files if omitted
hbb2obb-convert /path/to/labels_obb --to dota coco voc -o /path/to/release -mp label_map.yaml

# The reverse, into the YOLO TXT the tool consumes
hbb2obb-convert /path/to/instances.json --from coco --to yolo -o /path/to/labels_hbb --normalize

# Check that every format present under a directory encodes the same boxes
hbb2obb-convert /path/to/dataset --verify -mp label_map.yaml
The format guide covers rounding, the difficult flag, image dimensions and COCO identifiers.
hbb2obb-optimize grid-searches inference resolution x scale factor x opening kernel for a set of SAM models, ranking each point by average IoU against ground-truth OBBs:
hbb2obb-optimize /path/to/images /path/to/ground_truth -sm sam_b sam_l sam2_b sam2.1_b -n multi_samA run writes its grid, a summary and a plot into <output_folder>/<name>. The tuning guide covers the grid axes and their cost, the outputs, and plotting a metric other than the one being optimized.
A YAML lists the runs, and one command produces all of them:
hbb2obb-optimize -c benchmark.yaml --dry_run   # the runs, the grid size, the total cost
hbb2obb-optimize -c benchmark.yaml             # all runs in benchmark.yaml
hbb2obb-optimize -c benchmark.yaml --resume    # continue one that was interrupted
hbb2obb-optimize -c benchmark.yaml --refresh   # only redraw the plots, the summary and the LaTeX table
data/benchmark.yaml is a working example: it is the file behind data/benchmark_results/. The config format is in the tuning guide.
--save_provenance records what a run actually did, so a release can be regenerated rather than taken on trust: the exact command, the versions, a digest of the source that ran, the SHA-256 of every checkpoint and how many boxes fell back to their HBB.
hbb2obb /path/to/images --sam_models sam_l sam_b sam2_b sam2.1_b --save_confidence --save_provenanceThe file lands one level above the label directory: --obb_dir train/labels leaves train/PROVENANCE_obb.txt. hbb2obb-detect writes PROVENANCE_hbb.txt there instead, and hbb2obb-optimize writes PROVENANCE.txt inside its output folder. See the provenance guide for everything recorded.
HBB annotations (input): YOLO TXT, one file per image; coordinates relative (0–1) or absolute px, with an optional 6th column holding the detector confidence:
class_id x_center y_center width height [confidence]
OBB annotations (output): YOLO TXT, one file per image; four corners in absolute px, or relative to [0, 1] with --normalize, which Ultralytics requires for training. With --save_confidence, a 10th column holds the per-OBB confidence score:
class_id x1 y1 x2 y2 x3 y3 x4 y4 [confidence]
With --save_polygon, the segmentation contour behind each OBB goes to a parallel, row-aligned directory. The annotation format guide has the polygon layout, the precision of normalized output and the label map.
HBB2OBB fits each OBB by prompting SAM with your HBBs, combining the masks of an ensemble by majority vote, clipping the mask to the scaled HBB, refining it with a signed morphological kernel, and wrapping its largest contour (plus any piece of the same object an occluder split off) in a minimum-area rotated box. If no valid mask is found inside an HBB, the original HBB is kept, and the run reports how many boxes this happened to. OBBs inherit the class of their source HBB. How the conversion works describes each step.
Each OBB carries a heuristic quality score in [0, 1] that helps triage a converted dataset: high scores are trustworthy SAM fits, low scores warrant a look, and 0.0 marks a fallback where the original HBB was kept. The detail crop below shows the score that --show_confidence prints next to each converted box.
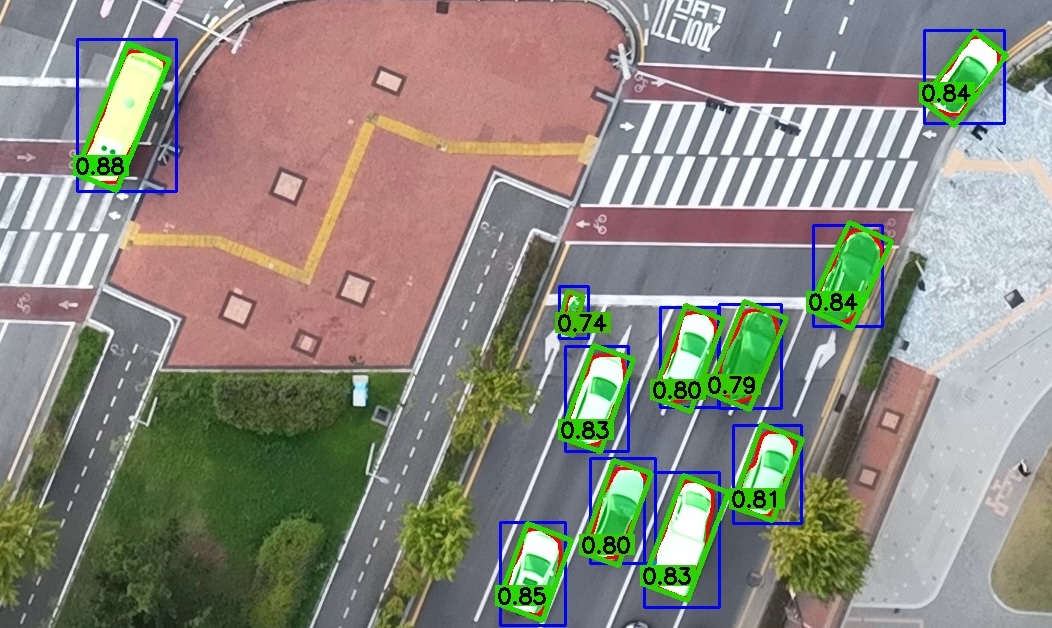
The score is the product of the rectangularity of the fitted contour and the ensemble consensus of the SAM models. --save_confidence writes it as a 10th column, --confidence_dir to a side-car directory that keeps the label files standard, and --confidence_source swaps it for, or multiplies it by, the detector confidence from the HBB input. See the confidence guide.
- Try one strong model before an ensemble. On the 495-grid-point Songdo Vision OBB study, measured over 4,245 reference boxes, a single
sam_ltied a five-model ensemble on mean IoU and beat it on the two scores that describe how a converted set fails, at 39% of the compute. - If you do ensemble, choose the vote threshold before the members. Masks are combined at
len // 2 + 1, so an even-sized set must be unanimous and behaves as an intersection, which can only erode the extent the box is fitted to. A weak member in a pair holds a veto; in a triple it is outvoted and costs almost nothing. - Experiment with scale factors and inference resolutions based on your dataset.
- Run
hbb2obb-optimizeto find the best settings for your data, and--save_provenanceto record the ones you settled on. - Use class-agnostic evaluation when comparing against manually annotated ground truth with different class labels.
- Visualize the conversion to understand how the model interprets your HBBs.
- Results depend on the quality of the input HBBs and the SAM models used; poor annotations or weak segmentation lead to inaccurate OBBs.
- Highly occluded or complex objects, where the HBB gives insufficient context, may not convert well.
- The error from a bad prompt is one-sided. The mask is clipped to the scaled prompt, so a prompt smaller than the object truncates it permanently, while one that is too large is trimmed back by the mask. On the same study, moving the scale factor from 0.02 to -0.01, which is 6% of prompt area, costs 0.033 mean IoU and drops the share of boxes above IoU 0.9 from 61.5% to 15.7% without producing a single gross failure. Note that the factor moves each edge by that fraction of its own side, so it changes each dimension by twice the factor. When in doubt, prompt loose.
- Small objects convert poorly. Below about 20 px across the shorter side there are too few pixels of width to fit an axis to.
HBB2OBB produced Songdo Vision OBB, the oriented-box release of the Songdo Vision v2 aerial vehicle dataset: 274,190 oriented boxes over 5,419 frames of 4K drone imagery from Songdo, South Korea, one per horizontal box in the source dataset and carrying its class and identifier.
The hyperparameters were selected by hbb2obb-optimize against 50 manually annotated frames that
share no image with the converted set: 11 SAM model sets over 495 grid points, 30.2 h on one 24 GB
card.
| Songdo Vision OBB | |
|---|---|
| 🎯 Selected configuration | sam_l alone, --imgsz 1024 -sf 0.02 -okp -0.1 -fr 0.1 |
| 📐 Mean / median IoU vs. manual OBBs | 0.88679 / 0.91759 |
| 📊 Share at IoU >= 0.75 / 0.90 | 92.06% / 61.51% |
| 🧭 Orientation error, 90th percentile | 3.50 deg |
| 🔁 Fallbacks to the source HBB | 0 of 4,245 on the validation frames, 0 of 274,190 in the release |
Two findings from that search are worth carrying to another dataset. Closing the mask beat both
alternatives in 165 of 165 comparable cells, on mean IoU and on the share above IoU 0.9 alike, so
-okp is worth setting negative before it is worth tuning. And majority-vote ensembling of SAM
variants did not improve the conversion: the objective could not separate five checkpoints from
one, and the accuracy-against-compute front had two points on it rather than a curve.
The full study, every grid point and the figures behind it ship with the dataset as
hbb2obb_benchmark/, and re-run from the config beside them without this repository.
If you use HBB2OBB in your research or software, please cite the archived release:
@software{fonod2026hbb2obb,
  author  = {Fonod, Robert},
  title   = {HBB2OBB: Horizontal to Oriented Bounding Box Conversion and Evaluation Tool},
  year    = {2026},
  license = {MIT},
  doi     = {10.5281/zenodo.15151143},
  url     = {https://github.com/rfonod/hbb2obb}
}
Each GitHub release is automatically archived to Zenodo via the Zenodo–GitHub integration; see CITATION.cff for the latest version and DOI.
Contributions are welcome! If you encounter issues or have suggestions, please open a GitHub Issue or submit a pull request.
This project is distributed under the MIT License. See the LICENSE file for details.